Tag: Automation

  • How to Choose a Robotics SEO Agency for Search and AI

    How to Choose a Robotics SEO Agency for Search and AI

    You are not hiring someone to make a robotics blog busier. You are choosing who will translate technical products, applications, integrations, and proof into pages that engineers trust, buyers can navigate, and search systems can understand.

    The right agency depends less on a league-table position than on your actual constraint. You may need deeper robotics fluency, stronger search execution, an AI visibility program, a new industrial website, or a broader B2B marketing partner. Identify that constraint first, then make every finalist prove it can remove it.

    Key takeaways

    • Choose an agency model before choosing an agency. SEO/GEO specialists, engineering marketing firms, full-service B2B agencies, and industrial web firms solve different problems.
    • Test technical accuracy with a paid assignment based on a real product or application. A polished generic sample does not show whether the team can handle your terminology, evidence, and commercial intent.
    • Score search performance and robotics expertise separately. High rankings do not prove that an agency can produce content your engineers will approve or your prospects will use.
    • Require distinct SEO and generative engine optimization measurements. The work can share a content plan, but rankings, qualified organic conversions, AI mentions, citations, and referral traffic are not interchangeable metrics.
    • Put roles, review responsibilities, account access, content ownership, correction procedures, and reporting definitions into the agreement before production begins.

    Choose the agency model before you compare agencies
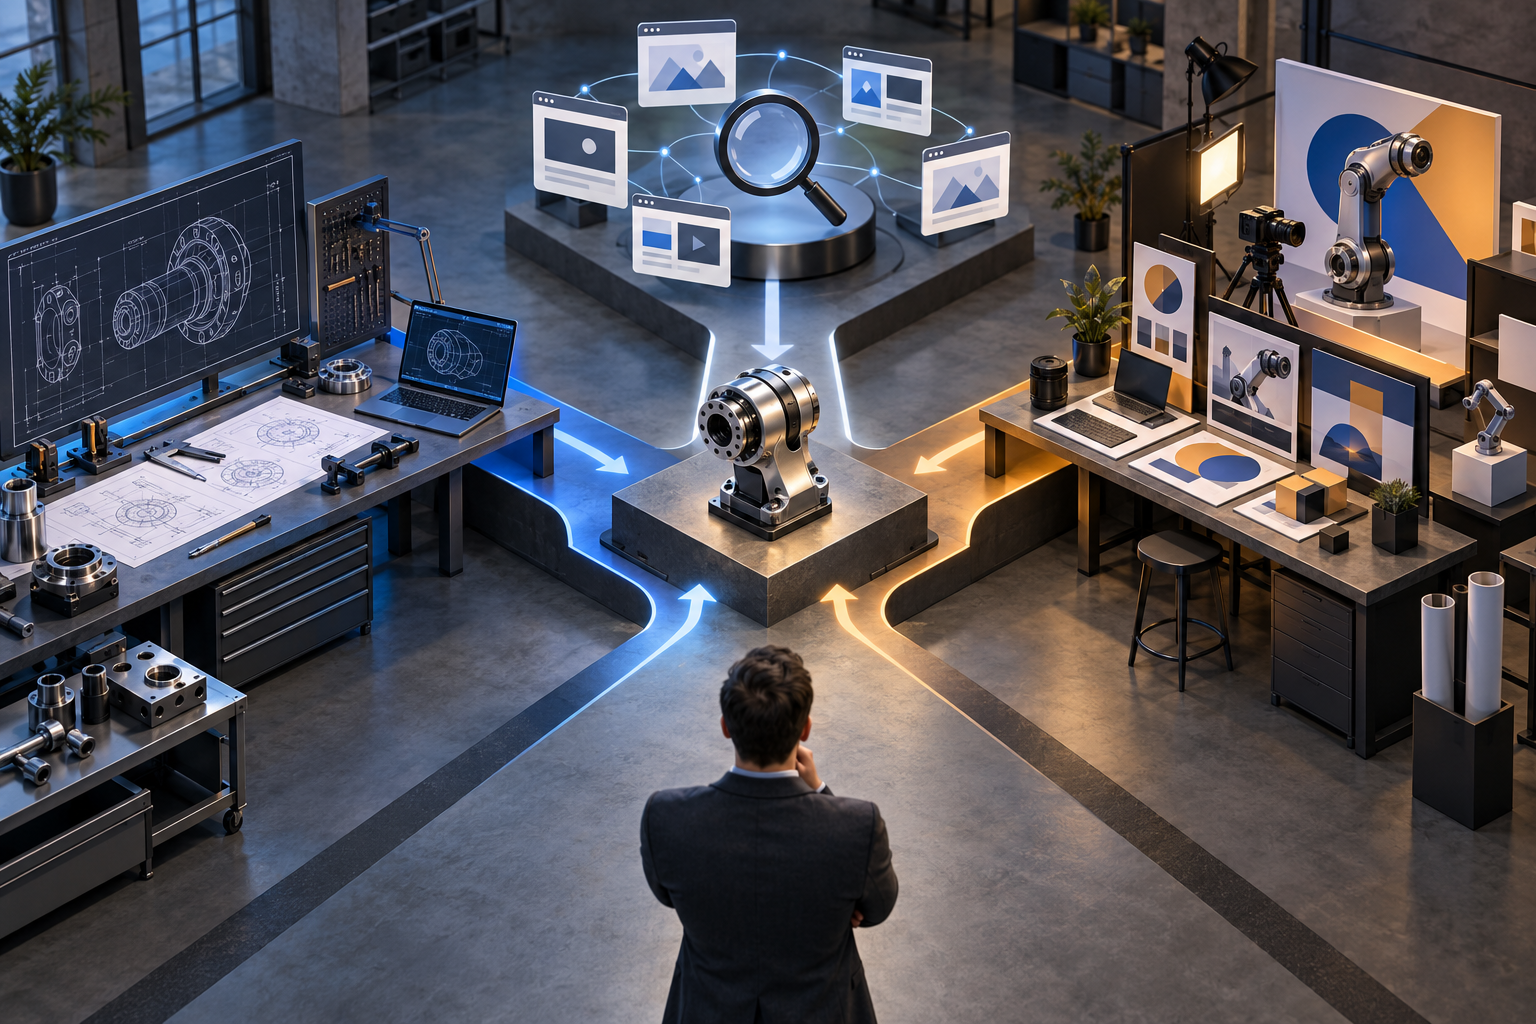
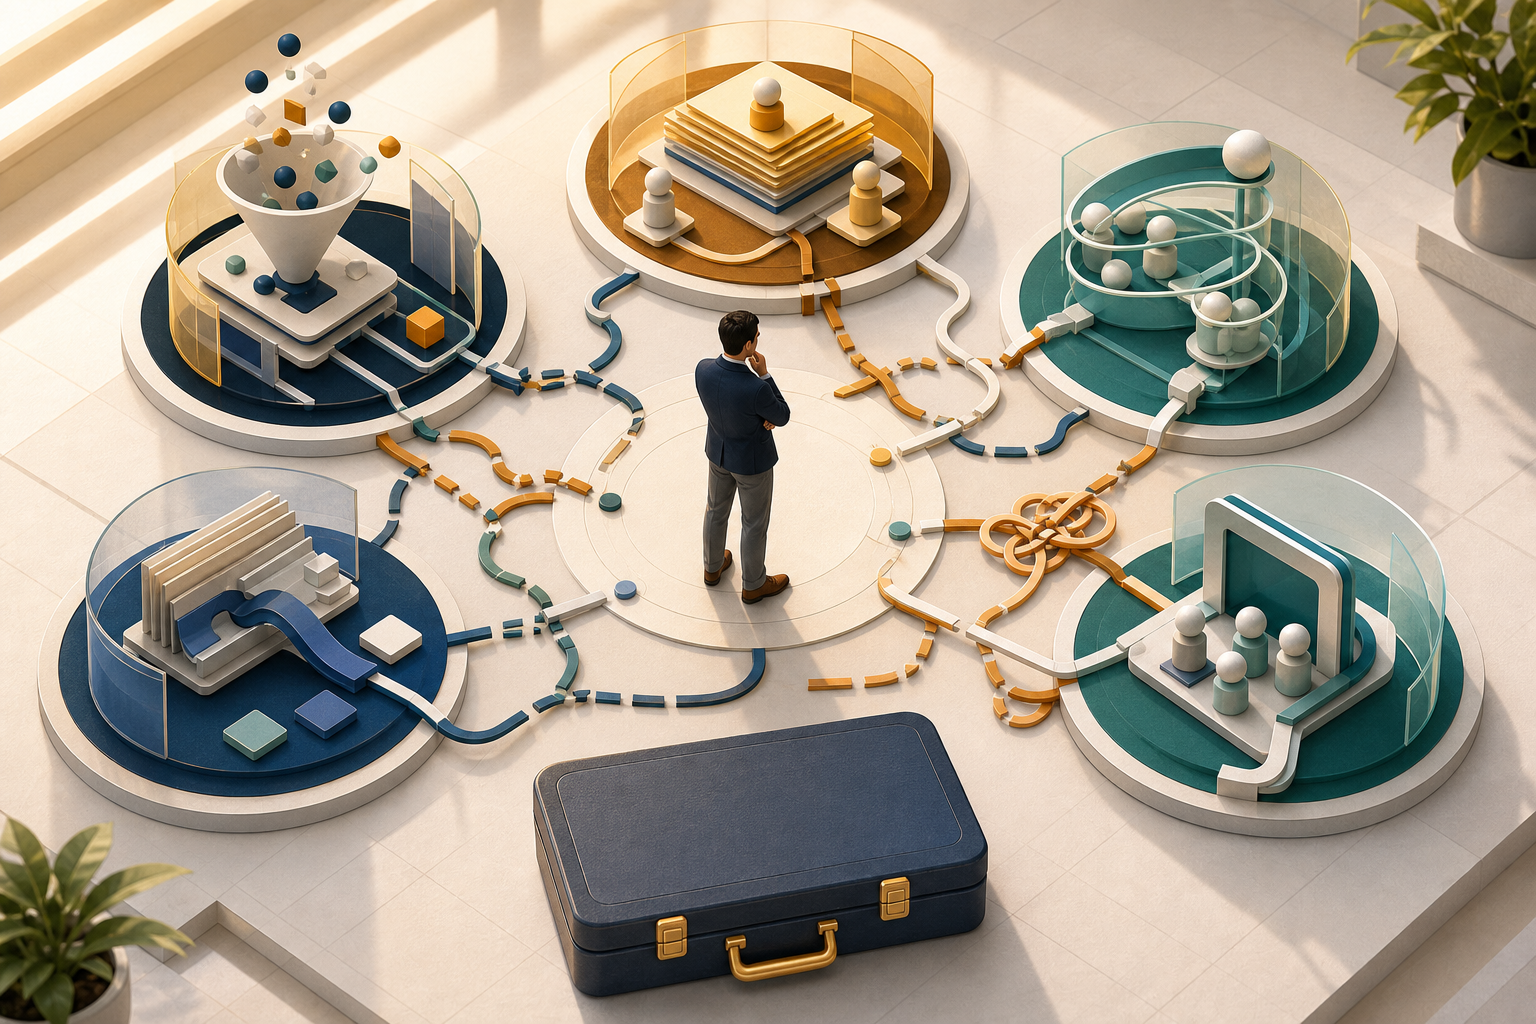
    A decision-maker compares three visual pathways leading to a robot component, representing technical, search-focused, and integrated agency models.

    Your practical options fall into four models. The named 2026 field includes eight agencies, but their operating models matter more than their order.

    Agency modelCandidates to investigatePut this model on your shortlist whenWhat you must verify
    SEO and GEO specialistFirst Page Sage, Driven Metrics, GenevateOrganic discovery across conventional search and generative platforms is the central assignment.Robotics fluency, writer credentials, technical review requirements, and evidence connecting visibility to qualified pipeline.
    Engineering or industrial marketing specialistTREW Marketing, Gorilla 76Your team needs technical content and wider industrial positioning, branding, or demand-generation support.Who owns technical SEO, search-intent analysis, authority development, structured data, and AI visibility measurement.
    Full-service or regional B2B agencyWalker Sands, Motion MarketingYou need a broader B2B program, or regional fit in the UK and Europe is a meaningful requirement.Whether SEO has dedicated leadership and resources rather than being a small component inside a larger account.
    Industrial web and positioning partnerWindmill StrategyA website rebuild, industrial user experience, and market positioning are tied to the search project.The content, authority, conversion, and measurement program that continues after the new site launches.

    Start with the bottleneck. If engineering spends most of its time correcting outsourced copy, favor technical specialization. If good technical material already exists but qualified prospects cannot find it, favor search execution. If the website cannot express product relationships or route different buyers to the right next step, address information architecture before funding a large publishing schedule.

    Do not treat GEO as a decorative add-on. If AI discovery matters to your buyers, the agency should be able to explain which questions it will monitor, which pages should become citable answers, how it will record mentions and cited URLs, and how that activity connects to your commercial funnel. A logo slide that lists ChatGPT or AI search is not a strategy.

    One conflict deserves explicit treatment: First Page Sage created the ranking that places First Page Sage first. Its grades and review snippets are useful for finding candidates, but they are not independent validation. Apply the same evidence request to every firm, including the evaluator.

    Test whether the team can support a technical buying decision

    Robotics search is not one market. A company may need to reach people researching industrial robots, collaborative robots, machine vision, robotic components, automation applications, autonomous navigation, or AI-powered robotics. Those are not interchangeable keyword groups. Each can involve different buyers, technical questions, objections, evidence, and conversion paths.

    This is where generic content programs break. An agency can produce grammatically clean pages while confusing a component with a complete system, overlooking an integration constraint, mixing educational and transactional intent, or sending an engineer to a call-to-action meant for an executive buyer. Traffic does not repair that mismatch.

    Require a product-to-query map

    Before approving a content calendar, ask the agency to map your real offer into page roles. The map should show how a prospect moves from a problem or application to a technology, a product, credible proof, and an appropriate next step.

    • Product and category pages should establish what you sell, who it is for, where it fits, and which technical claims can be supported.
    • Application pages should connect a real operating problem to the relevant system without pretending that every deployment has the same requirements.
    • Technology pages should explain important mechanisms, components, software, sensing, navigation, or integration concepts in language that remains technically defensible.
    • Evaluation pages should help a buyer compare approaches, specifications, implementation requirements, and tradeoffs without manufacturing a false winner.
    • Proof pages should make case evidence, technical documentation, certifications, test information, and deployment details easy to locate when those materials exist.
    • Conversion paths should match intent. A buyer who needs documentation, an integration discussion, or a system assessment should not be forced through the same generic contact form.

    Reject a proposal that turns this architecture into a pile of loosely related blog topics. Informational content can create discovery, but the program also needs pages that explain the offer, resolve evaluation questions, establish evidence, and let a qualified prospect act.

    Run a paid proof-of-work assignment

    Portfolio samples show what survived another client’s approval process. They do not reveal how the agency handles your technology. A contained paid assignment is a fairer test for both sides.

    1. Select a commercially important product, category, or application page. Use something technical enough to expose weak reasoning, but remove confidential material.
    2. Give every finalist the same brief, approved terminology, existing evidence, target audience, and business objective.
    3. Ask for a search-intent assessment, proposed outline, representative passage, internal-link recommendations, conversion step, and a list of questions or unsupported claims that require expert review.
    4. Have marketing, product, engineering, and sales review the work independently. Each group should mark factual errors, missing buyer questions, unclear positioning, and commercially irrelevant material.
    5. Compare not only the finished prose but also the questions each agency asked. A team that identifies uncertainty is safer than one that fills knowledge gaps with confident language.

    Use hard gates. An invented capability, altered specification, unsupported performance claim, or fabricated customer outcome should fail the test. So should a page with no identifiable audience or next step. Minor editing is normal; rebuilding the technical logic is evidence that your subject-matter experts will become unpaid ghostwriters for the agency.

    Score SEO and GEO as connected but different jobs
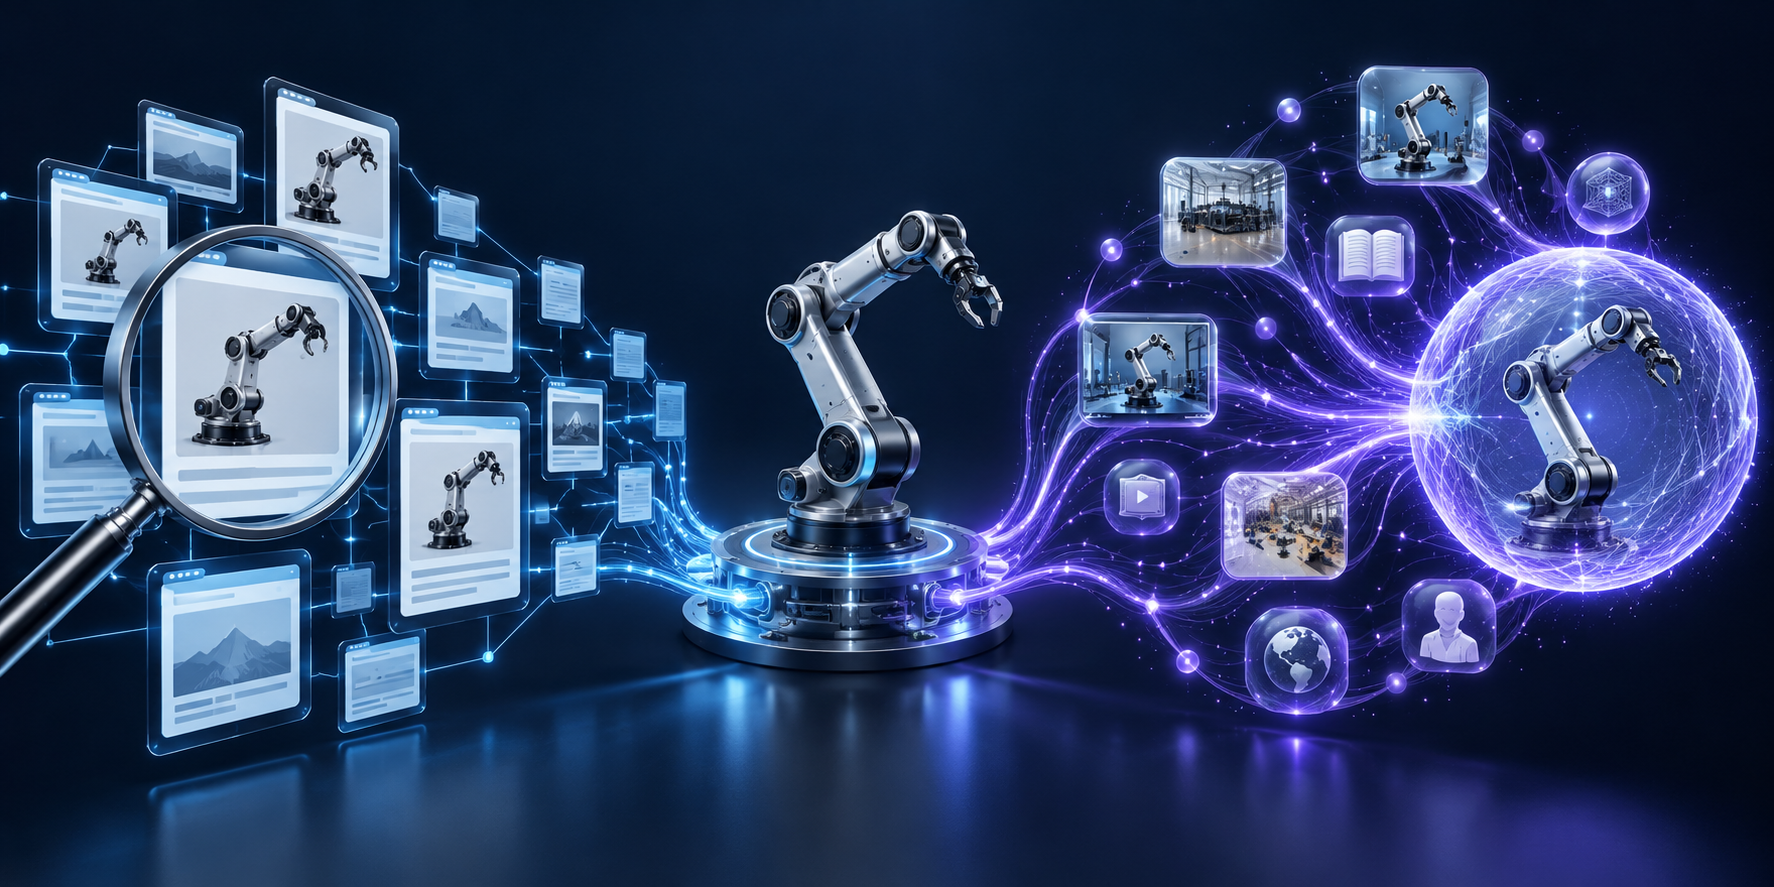
    A robot connects to a search network on one side and an AI source network on the other through a shared technical knowledge core.

    You can borrow a transparent starting scorecard from the market: ranking proficiency at 25%, robotics expertise at 20%, content execution at 20%, client ratings at 15%, SEO specialization at 10%, and a GEO offering at 10%. Those dimensions expose useful differences, but they should not make the decision for you.

    • Ranking proficiency asks whether the agency can earn meaningful search visibility, not merely publish optimized pages.
    • Robotics expertise asks how quickly the team can understand your technology, language, ecosystem, and buyer concerns.
    • Content execution asks whether the agency can turn that understanding into accurate, useful, discoverable material.
    • Client ratings can surface communication and delivery patterns, but references should be checked directly and matched to work similar to yours.
    • SEO specialization indicates whether organic search is a central discipline or one service inside a much broader portfolio.
    • GEO capability asks whether the agency has a defined approach to discovery and citation in generative platforms rather than a newly relabeled content package.

    Add four pass-or-fail criteria before you total any score: commercial relevance, measurement quality, operating fit, and ownership. A highly rated firm is still the wrong choice if it cannot connect work to your ideal customer profile, fit your expert-review capacity, expose how results are measured, or leave you in control of your assets.

    Demand separate measurement plans

    SEO and GEO can use the same underlying knowledge, pages, proof, and authority signals. They should not be collapsed into a single visibility number.

    • For SEO, require reporting by query family and landing-page group. Track relevant visibility, qualified organic actions, sales acceptance, opportunity creation, and pipeline where your systems allow it.
    • For AI discovery, define a repeatable set of buyer questions. Record the platform, prompt, date, brand mention, cited domain, cited landing page, competitor presence, referral traffic when identifiable, and any resulting qualified action.
    • For technical health, monitor whether important pages can be crawled, indexed, understood, internally linked, and kept aligned with the site’s visible structured information.
    • For content operations, monitor approval delays, substantive factual corrections, revision causes, and the amount of subject-matter-expert effort required for each deliverable.

    Ask to see how reporting changes a decision. If a dashboard cannot tell the team what to update, consolidate, expand, stop, or promote, it is record-keeping rather than management.

    Keep schema in its proper role

    A robotics SEO agency should understand structured data, but schema markup cannot rescue vague positioning or unsupported technical claims. Ask how the agency will keep company names, product relationships, applications, specifications, authorship, and other visible facts consistent between page copy, structured data, internal links, and external profiles.

    Reject promises that markup alone will create rankings or AI recommendations. The useful test is whether structured data accurately represents visible, maintained content and makes important entities and relationships less ambiguous. It should be part of technical implementation and governance, not a substitute for evidence-rich pages.

    Contract for the operating model, not the pitch

    The sales team can sound technically fluent while the delivery team operates very differently. Before signing, ask for the proposed strategist, project lead, writer, editor, technical SEO owner, analytics owner, and backup coverage. If names are not yet available, require role descriptions, relevant backgrounds, allocation expectations, and the process for approving replacements.

    Define the review workflow

    • State who interviews subject-matter experts, prepares questions, records approved terminology, and maintains the factual brief.
    • Separate factual approval from brand editing. Engineers should not have to rewrite tone, headings, metadata, calls to action, or basic page structure.
    • Define what counts as a deliverable: a draft in a document is different from a published, internally linked, quality-checked page with appropriate metadata and structured information.
    • Create a correction path for technical errors. Specify who pauses publication, who approves the correction, and how related pages are checked for the same mistake.
    • Agree on how changes in products, specifications, positioning, regulations, or supporting evidence reach the content team and trigger updates.

    Your internal capacity should influence the choice. A search specialist that expects substantial client expertise may work well when product marketers and engineers can support it. The same arrangement will stall if experts are unavailable or if every draft becomes a reconstruction project. Make that workload visible in the proposal rather than discovering it after the content calendar starts.

    Protect access, ownership, and continuity

    Confirm in the agreement who owns commissioned content, keyword and prompt maps, reporting files, creative assets, analytics configurations, structured-data work, and any custom tooling. Keep company-controlled access to the CMS, analytics, search accounts, tag management, domain, hosting, and relevant AI-monitoring systems. Losing those assets or permissions can make an agency transition expensive and slow, so have the appropriate internal or legal reviewer check the final terms.

    Also define what happens when performance disappoints. The agency should be able to diagnose whether the constraint is technical, competitive, editorial, authoritative, commercial, or operational. A useful review ends with a decision and an owner, not another month of unchanged production.

    Before your next agency call, choose a real commercial page and a real family of buyer questions. Send the same sanitized assignment to each finalist and compare the returned reasoning, not just the presentation. The strongest candidate will expose uncertainty, protect technical accuracy, connect discovery to a buying decision, and define measurement before promising growth.

    References


  • How to Fill Google Ads Conversion Gaps With Offline Data

    How to Fill Google Ads Conversion Gaps With Offline Data

    Your website tag records the purchase at checkout, but your backend may hold the version of the transaction you actually want Google Ads to learn from: more complete customer information and the amount after an upsell, refund, or final order adjustment.

    If both records carry the same transaction ID, Google Ads can use the backend record to improve the tagged conversion instead of forcing you to accept whatever was available in the browser. The implementation is less about uploading more data than establishing a reliable join between two versions of the same business event.

    What offline gap filling changes – and what it does not

    Google Ads’ multi-source conversions beta can match an offline record to a website conversion through its transaction ID. Once Google finds that match, the offline record can supply user-provided data that the tag did not capture, including an email address, phone number, or address.

    The same mechanism can correct the conversion value. If the tag sent an initial amount and your backend later has the finalized order total, upsell, or refund adjustment, the uploaded amount replaces the value attached to the matching tagged transaction.

    Think of this as a database join, not a second copy of the sale. One conversion action can receive information from the website tag and the offline system. That distinction helps you avoid three common implementation mistakes:

    • Do not assume every offline row enriches a tagged event. The gap-filling path depends on Google finding the corresponding transaction ID. An unmatched record cannot fill fields on a tagged conversion it has not been connected to.
    • Do not expect the offline row to overwrite every tag field. The supplemental data is primarily used for missing user-provided information and conversion-value updates.
    • Do not use an uploaded GCLID as a repair mechanism for a matched transaction. Google ignores GCLIDs from the supplemental record in this scenario, so they do not replace the information associated with the tag event.

    Multi-source reporting may also contain additional conversions from the offline source. Treat those separately in your validation plan. “Conversions added” and “tagged conversions supplemented” are different outcomes, even if they appear under the same conversion action.

    The capability is documented as a beta. Confirm that it is available in your account before making it a dependency of your measurement design.

    Make the transaction ID your dependable join key

    Two digital transaction records with identical geometric identifiers lock together through a central connector.

    The transaction ID is the bridge between the browser event and the backend record. If the two systems generate unrelated identifiers, drop the value, or transform it differently, the rest of the upload can be accurate and still fail to improve the original conversion.

    A clean data path should work in this order:

    1. Your site completes the conversion and assigns its transaction ID.
    2. The Google tag sends the conversion with that ID and the data available at that moment.
    3. Your order system, CRM, or other backend retains the identical ID while customer details and the final value are confirmed.
    4. Google Ads Data Manager or the Data Manager API sends the supplemental record.
    5. Google uses the shared ID to associate the offline information with the tagged transaction.

    Rules for a durable transaction ID

    • Generate the ID once and persist it across the browser, order database, CRM, and upload pipeline.
    • Use an ID that represents the actual conversion rather than creating a separate Google Ads-only identifier later.
    • Keep it unique to the business event. Reusing an ID across orders makes reconciliation ambiguous.
    • Do not embed an email address, phone number, or other personal data in the ID.
    • Retain the ID in your integration logs so you can trace a reported mismatch back to the tag payload and backend record.
    • Avoid trimming, reformatting, or replacing the ID in only one part of the pipeline.

    Before connecting an offline source, take a sample of real conversions and trace each transaction ID from the site event to the backend export. If you cannot follow the same value across that entire path, fix the ID lineage first. Adding more customer fields will not repair an uncertain join.

    User-provided data also deserves a separate governance check. Confirm that the information is accurate, that your organization is permitted to send it, and that access to the upload pipeline is appropriately controlled. Matching performance does not justify sending data your business should not use.

    Build the offline feed around information that arrives later

    Your offline feed should have a narrow job: supplement the browser event with authoritative information that became available elsewhere. It should not become an undifferentiated export of every field in your CRM.

    The following controls belong in the internal feed design. Some are upload fields; others are operational metadata that helps you decide whether a record is ready to send.

    Data itemPreferred internal originControl to apply
    Transaction IDThe system that created or persisted the conversionConfirm that it is identical to the ID sent by the website tag.
    Email, phone number, or addressThe approved backend customer or order recordSend only accurate, permitted information intended to fill a field the tag missed.
    Conversion valueThe authoritative order, billing, or CRM recordPublish the amount your business treats as final for that update, including applicable upsell or refund changes.
    Record statusYour order or revenue workflowUse it internally to prevent provisional records from being presented as finalized value corrections.
    Ready and upload timestampsYour integration logMeasure the delay between backend availability and delivery to Google Ads.

    Conversion value requires the tightest control because the uploaded value replaces the tag’s value for the matching transaction. It is not merely attached as an alternative value. A stale amount in the offline feed can therefore replace a better amount captured on the site.

    Define which backend system is authoritative and what “final” means in your business process. Then make that rule part of the integration. Do not label a provisional amount as final simply to make the upload run sooner.

    At the same time, delivery speed matters. Google recommends sending the supplemental data within 24 hours for the best Enhanced Conversions matching and bidding performance. Track two intervals separately: how long the backend takes to make the record ready and how long your integration takes to upload it. That separation tells you whether the delay belongs to the business process or the data pipeline.

    The 24-hour window is an optimization recommendation, not a promise that every record will match. If your integration routinely misses it, shorten unnecessary batch, approval, and transfer delays. Preserve data accuracy while doing so; faster uploads of unreliable values are not an improvement.

    Use the 14-day trial to validate the pipeline, not bidding

    An analyst monitors purchase records moving through matching and validation checkpoints in a controlled data pipeline.

    You can connect the additional source through Google Ads Data Manager or the Data Manager API. A newly connected source then enters a 14-day trial period.

    The trial creates an important split between what you can see and what Google uses. Additional conversions may appear in reporting and diagnostics during those 14 days, but they are not used for bidding. Conversion-value updates are also disabled during the trial.

    That means a reporting change during the trial is not evidence that Smart Bidding has learned from the new source. It is also not a valid test of whether finalized offline values are replacing the original tag values. Changing campaign targets or budgets solely because trial-period reporting moved could make you react to information the bidding system is not yet using.

    Structure the rollout in three phases:

    1. Before connection: preserve a baseline of tag counts, values, transaction-ID coverage, upload latency, and relevant campaign reporting. Save enough internal detail to explain differences later.
    2. During the 14-day trial: confirm that records arrive, inspect diagnostics, investigate unmatched or duplicated internal IDs, and verify that the correct conversion action and backend source are involved. Do not score bidding or value correction while those functions are inactive.
    3. After the trial: verify that the source has left trial status, check value behavior against the authoritative backend output, and annotate the activation date in your performance analysis.

    A practical validation checklist

    • Identity coverage: for sampled transaction IDs, confirm that a field missing from the tag is present in the approved backend record.
    • ID overlap: compare the set of IDs sent by the tag with the set prepared for upload. Investigate unexpected gaps before looking for a Google Ads explanation.
    • Uniqueness: ensure your internal export does not present unrelated transactions under the same ID.
    • Value authority: compare the outbound value with the finalized amount in the designated system of record before it reaches Google.
    • Delivery latency: count the records sent inside and outside the recommended 24-hour window. Monitor the trend instead of relying on an average that can hide delayed batches.
    • Trial separation: label trial-period reporting so nobody mistakes visible additional conversions for bidding inputs or completed value corrections.
    • Post-trial monitoring: watch diagnostics and reporting after activation rather than assuming that a successful upload guarantees a successful match.

    When numbers differ, debug in the order the data travels: tag execution, transaction-ID persistence, backend record readiness, export construction, upload delivery, matching, and finally reporting. Starting with campaign performance makes a pipeline problem much harder to isolate.

    Key takeaways

    • Google Ads offline gap filling uses the transaction ID to connect backend information with the corresponding website-tag conversion.
    • A matched upload can add missing user-provided data such as an email address, phone number, or address.
    • An uploaded conversion value replaces the original value on the matching tagged transaction, so only an authoritative system should publish value corrections.
    • An uploaded GCLID is ignored for matched transactions and should not be treated as a way to overwrite the tag’s attribution information.
    • Send supplemental data within 24 hours when possible to support Enhanced Conversions matching and bidding performance.
    • During a new source’s 14-day trial, additional conversions may be visible but are not used for bidding, while value updates remain disabled.

    Start with one conversion action whose transaction IDs are already stable. Trace a sample from the tag to the backend, name the system that owns the final value, and define your trial acceptance checks before connecting the source. If that lineage is clean, the offline feed can close specific measurement gaps without turning your conversion setup into two competing versions of the truth.

    References

  • Google Data Manager Audience Updates: A Practical Playbook

    Google Data Manager Audience Updates: A Practical Playbook

    If you own a Customer Match sync, the dangerous outcome is no longer only a failed request. The Data Manager API can now process valid records while warning about invalid optional fields, and one audience operation can clear an entire list. Those capabilities reduce manual cleanup, but they also expose integrations that reduce every run to a simple green or red status.

    For you, this is an operating-model change as much as an API change. Build observability first, put destructive audience actions behind explicit controls, and only then widen the user-provided data you send. That order gives you evidence and a recovery path before the higher-risk capabilities go live.

    Key takeaways

    • Audience refreshes are simpler but more consequential: RemoveAllAudienceMembers can clear a list in one operation or remove members added before a supplied timestamp. Treat full clearing and cutoff-based clearing as separate modes with separate safeguards.
    • A successful request may still contain data-quality problems: invalid optional fields can produce field-level warnings while valid records continue through ingestion. Your monitoring needs a completed-with-warnings state.
    • Address support has widened for Google Analytics destinations: street address, city, and state or province can accompany previously supported information such as name, postal code, and region. This is not a reason to collect or transmit fields without a defined purpose.
    • User-provided data has a conditional identifier role: it can satisfy identifier requirements for certain multi-source events when other identifiers are unavailable. Do not generalize that fallback to every event type.
    • AI-assisted implementation has official scaffolding: Google has added Data Manager API agent skills to its Google Skills GitHub repository, but generated code still needs human review around audience selection, timestamps, privacy, and warning handling.

    Make audience replacement a controlled operation

    A technician monitors two audience-data containers connected by a guarded transfer system with a separate rollback reservoir.

    The RemoveAllAudienceMembers method supports both complete clearing and timestamp-based removal. Do not expose those behaviors through one vaguely named refresh command. Give each mode an explicit name in your own integration so an operator, scheduler, or AI coding agent cannot confuse them.

    Internal operationUse it whenRequired safeguard
    Full clearYou intend to rebuild every current membership from an authoritative dataset.Validate the exact audience target and retain the input, query, or export required to rebuild it.
    Remove before timestampYou intend to retire memberships added before a defined boundary.Record the serialized cutoff and its timezone, then calculate the expected cohort in your own system before making the call.

    A full clear should begin only after the replacement dataset is ready. If extraction fails and returns no rows, an automatic clear-first workflow can turn an upstream outage into an empty audience. Your job must distinguish between a valid business result of no qualifying members and a technical failure that merely produced an empty file.

    1. Build the replacement input first. Finish the source query or export before touching existing membership.
    2. Check whether the result is plausible. Compare its volume and partition coverage with your own recent successful runs. Use a business-specific baseline rather than an arbitrary universal threshold.
    3. Resolve the target from controlled configuration. Record the account, destination, and audience identifier. Avoid accepting an unverified free-text audience name at execution time.
    4. Declare the removal mode. Require either full clear or before timestamp. If a timestamp is supplied, store the exact value used by the request.
    5. Preserve the rebuild path. Retain the source query version, input reference, and run identifier under your normal data-retention controls.
    6. Remove, rebuild, and verify as one runbook. Do not declare the refresh complete merely because the removal call succeeded; the replacement ingestion and its warnings are part of the same operational outcome.

    The cutoff has a narrow meaning: it targets members added before the timestamp. It is not automatically a proxy for last purchase, last site visit, consent expiry, or customer inactivity. If your business rule depends on one of those events, calculate eligibility upstream instead of assuming membership age represents it.

    Boundary behavior deserves a fixture test before production. Place known test members before, at, and after a chosen cutoff, run the operation against a disposable test audience where your environment supports one, and inspect the result. Also verify how your integration treats members that were updated or re-added; do not build a retention policy on an untested timestamp assumption.

    Treat ingestion warnings as a real pipeline outcome

    A validation machine sends most record packets into storage while diverting malformed fragments into an amber inspection channel.

    Field-level warnings change the meaning of success. When an optional field is invalid, the API can continue processing valid records and return details about the field and validation problem. A 2-state dashboard that shows only succeeded or failed will hide exactly the defects this behavior was designed to reveal.

    Represent at least three states in your own monitoring, even if your internal labels differ:

    • Failed: the requested ingestion did not complete successfully.
    • Completed with warnings: processing continued, but one or more fields failed validation.
    • Completed without detected warnings: the run completed and no warning was returned to your handler.

    Persist enough context to diagnose a warning without copying raw customer data into general application logs. A useful warning record contains the internal run identifier, destination, field name, validation reason, occurrence count, deployment version, and first-seen time. If record-level correlation is available in your integration, use a restricted internal reference rather than a name, street address, or complete payload.

    Your alerting should focus on changes in the data contract, not merely the existence of any warning:

    • Escalate a warning reason that appears for the first time after a mapping or formatter release.
    • Investigate a material increase in a known warning relative to that feed’s normal baseline.
    • Route recurring warnings to the team that owns the source field, not only the team that operates the API client.
    • Keep the run visibly degraded until the warning has been classified, even when usable records reached the destination.

    Do not blindly retry the identical batch. An invalid optional value will remain invalid, and valid data may already have been processed. Correct the mapping, normalization, or source value first, then send the corrected data through your normal controlled ingestion path. This makes the next warning result evidence of whether the repair worked.

    Expand address data only where the destination and purpose match

    For Google Analytics destinations, the API now accepts street address, city, and state or province alongside fields such as name, postal code, and region. Keep that destination qualifier in your schema. Support in a Google Analytics path does not establish that every Data Manager destination should receive the same payload.

    • Newly supported for the stated Google Analytics use: street address, city, and state or province.
    • Already supported in the described address data: name, postal code, and region.

    Do not collapse state or province and region into one source column merely because the labels appear related. Define what each field means in your data model, preserve country-specific semantics, and document the transformation applied before transmission. Missing values should remain missing; fabricated placeholders create a payload that may be syntactically complete but semantically false.

    Before adding any address field, require a small data-contract record that answers five questions:

    1. Where did the value come from? Name the source system and field, not just the downstream JSON property.
    2. Which destination may receive it? Use a destination allowlist so the Analytics mapping cannot leak into an unintended advertising or analytics path.
    3. What transformation is applied? Document trimming, formatting, or country mapping in code and tests.
    4. What authorizes its use? Confirm that your collection notice, consent or other applicable control, and internal data policy cover sending the finer-grained address data to the configured destination. If they do not, leave the fields disabled until your privacy or legal owner approves the change.
    5. How will you observe quality without exposing values? Track populated-field counts and validation-warning categories rather than logging raw addresses.

    User-provided data can also satisfy identifier requirements for certain multi-source events when other identifiers are unavailable. The word certain matters. Encode the fallback as an eligibility decision: use the usual identifier path when it is available, use user-provided data only for event and destination combinations that support it, and hold records that satisfy neither condition. Never synthesize an identifier merely to make an event pass validation.

    API acceptance is not a performance guarantee. A field passing validation does not prove that it improved audience size, attribution, or campaign results. Measure those outcomes separately, and keep the expanded payload only when it has a defined operational purpose and remains within your data-governance rules.

    Roll out the changes in a sequence you can reverse

    Do not combine destructive audience controls, new warning behavior, and additional user-provided address fields in one production release. Separate deployments make it possible to identify which change caused a data-quality or audience-maintenance problem.

    1. Inventory each integration path. Mark whether it maintains a Customer Match list, sends data to Google Analytics, or performs both jobs. Record the actual Google Ads, Display & Video 360, or Google Analytics destination rather than assuming all Data Manager paths have identical needs.
    2. Capture warnings on the existing payload. Deploy warning persistence and the completed-with-warnings status before altering deletion or field mappings. This gives you a baseline for current data defects.
    3. Add a guarded removal wrapper. Expose full clear and before timestamp as distinct internal operations. Require a target, mode, recovery input, and explicit cutoff where applicable.
    4. Exercise a fixed test matrix. Test a full clear followed by rebuilding, members before and around a cutoff boundary, a mixed payload containing an invalid optional field, and a warning response that must reach monitoring.
    5. Add address fields by destination. Enable only approved Google Analytics mappings, preferably one mapped field at a time, so warnings can be traced to a specific change.
    6. Test identifier fallback separately. Cover an eligible multi-source event with another identifier, an eligible event without one, and a configuration that is not eligible for the user-provided-data fallback.

    Use Google’s agent skills as scaffolding, not authority

    Google has also released Data Manager API skills in the Google Skills GitHub repository for AI-assisted coding environments. They can help an agent start an integration, but the agent should not decide which audience to clear, choose a business cutoff, approve new address use, or determine whether warnings are acceptable.

    Give the coding agent a narrow implementation brief. For example: create an internal wrapper around RemoveAllAudienceMembers; require an explicit audience identifier and either a full-clear or before-timestamp mode; reject a missing cutoff in the second mode; emit structured warning data without raw user-provided fields; and add fixture tests for clearing, rebuilding, cutoff boundaries, and partial-warning ingestion. Then review the generated client types, request construction, authentication handling, and tests against the API materials and dependency versions actually installed in your environment.

    Set production acceptance criteria

    • A scheduled full clear cannot run unless its replacement dataset and rebuild job are ready.
    • Every cutoff-based operation records the exact timestamp and timezone used by your integration.
    • Completed-with-warnings runs are visible in dashboards and alert routing.
    • Ordinary logs exclude raw names, addresses, and complete user-provided-data payloads.
    • Destination controls prevent expanded address fields from entering an unapproved path.
    • The recovery runbook has been exercised against a controlled audience fixture, not merely written down.

    Start by capturing warnings from the payload you already send. Once that signal is reliable, introduce timestamp-based cleanup behind an explicit approval path, then prove the full-clear rebuild process with controlled data. Expand Analytics address mappings last. You will gain the automation benefits without making a destructive audience action or a sensitive-data change your first live test.

    References

  • Python Keyword Clustering for an Actionable Content Plan

    Python Keyword Clustering for an Actionable Content Plan

    You do not have a keyword-volume problem. You have a page-decision problem. A long query export leaves you deciding which phrases belong on one page, which deserve separate pages, which match existing content, and which should be ignored.

    A practical Python workflow can reduce that list to reviewable topic groups. The useful pattern is simple: clean the queries, represent them with TF-IDF, find natural groups with HDBSCAN, and apply editorial judgment before any cluster becomes a content brief. The algorithm handles repetition and scale; you retain control over intent, page scope, and priorities.

    Decide what a keyword cluster is allowed to mean

    Treat a cluster as a candidate content decision, not an automatic page recommendation. HDBSCAN can tell you that a collection of queries is densely related in the feature space. It cannot tell you whether those queries belong on a new page, an existing page, a product page, a comparison, or several separate assets.

    This distinction prevents the most expensive clustering mistake: turning every machine-generated group into a URL. A useful cluster should support one dominant reader need for one recognizable audience. If the group contains people trying to learn, compare, buy, and troubleshoot, it is probably too broad even when the vocabulary overlaps.

    Key takeaways

    • Use clustering to reduce the review workload, not to replace search-intent analysis.
    • Keep the original query beside its cleaned version so every assignment remains auditable.
    • Choose TF-IDF plus HDBSCAN when you do not know the number of topics in advance.
    • Expose cluster sensitivity and minimum cluster size as configuration, then tune them against editorially useful groups.
    • Retain the noise label. Outliers can reveal valuable long-tail ideas, data contamination, or terms that need a different taxonomy.

    Define the deliverable before writing the pipeline. For content planning, each output row should eventually answer four questions: Which cluster contains this query? What need does that cluster represent? What content action should you take? Which URL, if any, owns the topic?

    That definition gives you a better quality test than cluster count. The best run is not necessarily the one with the most groups or the least noise. It is the run that makes page-level decisions clearer without concealing meaningful differences between queries.

    Build a clean input without erasing useful meaning

    Your clustering quality is bounded by the query list you feed it. If a Google Search Console property exports to BigQuery, you can work with query data that is not restricted to the interface’s 1,000-row export cap and is not sampled. The Search Console interface remains usable for a smaller exercise. In either case, the clustering input can be a text file containing one keyword per line.

    Do not overwrite the raw phrases during cleaning. Create a working table with an original-query field and a separate normalized-query field. Cluster the normalized text, but carry the original wording into the final workbook. When a group looks wrong, this lets you determine whether the problem came from the data, the cleaning rule, or the clustering settings.

    A defensible preprocessing sequence looks like this:

    1. Load one query per row and remove blank records.
    2. Preserve the exact original phrase in a read-only column.
    3. Standardize superficial differences such as surrounding whitespace and inconsistent case in a separate working column.
    4. Remove characters that are genuinely irrelevant to your dataset.
    5. Apply stopword handling only after checking what those words mean in your niche.
    6. Separate languages before clustering when the content operation serves them separately.
    7. Deduplicate normalized phrases while retaining a path back to every original row.
    8. Write excluded or unprocessable rows to a rejection log instead of silently dropping them.

    Cleaning rules need editorial scrutiny. A blanket non-ASCII filter may be appropriate for a deliberately English-only run, but it can also erase valid names, accented terms, or entire languages. Stopwords can be equally treacherous. Removing a common preposition may have little effect in one dataset and destroy an important distinction in another. Test the cleaned output by reading actual before-and-after pairs.

    Keep each run linguistically and operationally coherent. Combining unrelated markets, languages, or business lines forces the model to find density across data that your team would never plan together. Separate runs also make parameter tuning easier because the expected topic granularity is more consistent.

    If you have useful fields beyond the query itself, retain them outside the clustering feature text and join them back afterward. A metric or business classification can help prioritize a cluster, but inserting it into the phrase changes what the text model is comparing.

    Use TF-IDF and HDBSCAN when the topic count is unknown

    Abstract geometric tokens forming several uneven colored clusters with a few isolated outliers.

    Keyword planning rarely begins with a trustworthy answer to, “How many topics are in this file?” That makes a fixed-cluster method awkward. K-means requires you to choose the number of groups before clustering, which turns an unknown editorial outcome into a required input.

    TF-IDF and HDBSCAN solve different parts of the problem. TF-IDF converts each cleaned query into a numerical feature vector. Terms that distinguish a phrase within the dataset receive more influence, while terms appearing throughout the list receive less. HDBSCAN then searches those vectors for dense neighborhoods. This pairing can discover groups without a predetermined cluster count and isolate queries that do not fit.

    Organize the Python workflow into explicit stages rather than one opaque function:

    1. Read and validate the flat keyword file.
    2. Create raw and cleaned query fields.
    3. Transform the cleaned phrases into TF-IDF vectors.
    4. Pass those vectors to HDBSCAN with configurable clustering settings.
    5. Attach the returned cluster identifier to every original query.
    6. Generate a provisional label from the cluster’s most distinctive terms.
    7. Export a cluster summary and a complete keyword-level table.

    Keep configuration at the top of the notebook or script. Input path, language rules, stopword behavior, sensitivity, minimum cluster size, and output path should not be buried inside processing logic. You will rerun the model several times, and editable configuration makes those runs comparable.

    HDBSCAN commonly represents unassigned queries with cluster ID -1. Do not translate that value to “bad keyword.” It means the query did not belong to a sufficiently dense group under the current settings. That can describe an unusual but valuable long-tail question just as easily as it can describe irrelevant input.

    TF-IDF also has an important boundary: it is a lexical representation. It is good at identifying distinctive term patterns, but it does not automatically understand every paraphrase that uses entirely different vocabulary. Human review is still needed to reunite synonyms, separate ambiguous terms, and detect intent differences hidden behind similar words.

    Your detailed export should preserve enough context to support that review:

    FieldPurpose
    Original queryShows the language a searcher actually used.
    Cleaned queryMakes preprocessing decisions visible and debuggable.
    Cluster IDSupports grouping, filtering, and rerun comparisons.
    Provisional cluster labelProvides a quick navigation aid based on distinctive terms.
    Review statusSeparates unreviewed machine output from approved editorial decisions.
    Content actionRecords whether to create, update, consolidate, support, or defer content.
    Target URLAssigns ownership when an existing or planned page should cover the need.

    Provisional labels are for orientation, not publication. A label made from prominent terms may name the subject while missing the searcher’s actual job. Rewrite it as a plain editorial topic only after examining representative queries.

    Tune the model against recognizable content boundaries

    There is no universally correct parameter set. Cluster sensitivity and minimum cluster size behave differently when the input contains 50 keywords instead of 50,000. Copying a setting without considering dataset scale and topic diversity can produce neat-looking output that is useless for planning.

    Minimum cluster size controls how much local support a group needs. A larger requirement favors broader, well-supported themes and can leave niche phrases as noise. A smaller requirement allows compact long-tail groups to survive, but it can also fragment one viable topic into many tiny clusters.

    Sensitivity controls how readily your implementation treats nearby phrases as one group. The exact direction and name can depend on how the notebook exposes the setting, so document what a higher or lower value does in your implementation. What matters editorially is the tradeoff: permissive grouping risks mixed intent, while strict grouping risks unnecessary fragmentation.

    Use a controlled tuning loop:

    1. Save the initial configuration as a named run rather than overwriting it.
    2. Review the largest clusters, middle-sized clusters, smallest non-noise clusters, and a selection of -1 rows.
    3. Mark groups that are coherent, too broad, unnecessarily split, or dominated by irrelevant data.
    4. Change one setting at a time so you can attribute the effect.
    5. Rerun the same cleaned dataset and compare assignments, not just the total number of clusters.
    6. Stop when additional tuning shifts labels without improving page decisions.

    A giant cluster built around a broad noun usually signals that the run is grouping too permissively or that the dataset needs to be segmented first. Several clusters differing only by minor wording usually signal excessive fragmentation. A large noise pool may mean the minimum group requirement is suppressing legitimate long-tail topics, but it can also reveal a messy source list. Read the rows before changing the model.

    Do not optimize for zero noise. Forcing every query into a cluster removes one of HDBSCAN’s main advantages. The -1 set protects stronger groups from being diluted by phrases with no natural home. It also gives you a focused queue for manual classification.

    Record the settings with every export. Without that record, you cannot explain why a keyword moved, reproduce an approved run, or compare whether a preprocessing change improved the result. A compact run log should identify the input file, cleaning configuration, clustering configuration, and output filename.

    Convert machine groups into page-level content decisions

    A strategist's hands organize colored blank keyword cards into separate page-planning boards and a review tray.

    The content plan begins after clustering. Open each candidate group and read its queries as a set of needs, not a bag of terms. Identify the dominant question, the audience implied by the modifiers, and any phrases that change the expected answer or page type.

    For every important cluster, make the following decisions:

    1. Write a human topic label that describes the reader’s need rather than repeating the most frequent words.
    2. Select representative queries that express the center and the boundaries of the group.
    3. Check whether the queries imply one intent and one plausible content experience.
    4. Inspect current search results for representative variants before committing them to one URL. If the result types or intended audiences diverge materially, split the group.
    5. Compare the approved topic with existing site coverage.
    6. Choose a content action: create a page, refresh an existing page, consolidate overlapping pages, add a supporting section, or defer the topic.
    7. Assign one target URL when the site should have a clear owner for the cluster.
    8. Record exclusions so a writer knows which adjacent needs the page should not try to satisfy.

    A cluster should strengthen a brief, not become the brief. Give the writer a primary reader question, supporting subquestions, scope boundaries, relevant terminology, the intended content action, and internal-link relationships. A pasted column of keywords leaves the hardest planning work unresolved.

    Use the cluster summary and keyword-level export for different jobs. The summary is the planning board: one row per reviewed topic, with its action and owner. The detailed view is the evidence: every query, its machine assignment, its cleaned form, and any editorial override. Keeping both views makes it possible to move quickly without losing traceability.

    Review noise separately rather than at the end of an already long cluster sheet. Some -1 queries will be irrelevant and can be excluded. Others will be highly specific questions worth adding to an existing page, and a few may be early members of topics that need more data before they form stable groups. Record which outcome applies.

    Do not let cluster size become the only priority signal. A large group may describe a broad topic your site already covers well, while a compact group may align closely with a valuable product, service, or audience need. Use the model to organize topical evidence, then prioritize with your site’s existing coverage and business goals.

    Start with one coherent dataset and keep the first run deliberately provisional. Review the broadest clusters and the -1 queue, adjust one setting, and rerun. Once the groups consistently support clear page decisions, convert one approved cluster into a pilot brief. That brief will tell you more about the usefulness of the pipeline than a polished visualization ever will.

    References


  • Scalable SEO Delivery: A Practical System for Scope Control

    Scalable SEO Delivery: A Practical System for Scope Control

    Your SEO engagement can look profitable until quick page reviews, extra competitor checks, implementation help, and custom reporting start consuming the capacity reserved for scheduled work. At the same time, pressure to move faster can encourage broad content rewrites that put existing rankings at risk.

    Those problems share a cause: the unit of work is unclear. Scalable SEO delivery starts when you can see exactly what was promised, move each request through the same controlled workflow, and adjust the price or schedule when the work changes.

    Turn the scope into countable work units

    A goal such as improving organic visibility belongs in the strategy. It does not define the service. If a statement of work promises technical SEO, content optimization, or ongoing support without defining the deliverables, the client and delivery team can hold completely different expectations while both believe they are reading the agreement correctly.

    Scope creep begins when work is added after the agreement without a matching change to cost or timeline. The practical defense is to describe SEO as a catalogue of countable work units rather than a collection of broad intentions.

    For every unit, define:

    • Object: The URL, page group, template, keyword cluster, market, language, report, or system being worked on.
    • Action: Whether you will inspect, diagnose, recommend, brief, write, implement, publish, validate, or measure.
    • Quantity: The exact number of pages, briefs, templates, reports, or other objects included.
    • Depth: The issues or data dimensions covered. A technical audit might include crawlability and indexing without including Core Web Vitals, structured data, internal linking, or competitive analysis.
    • Cadence: When the unit is delivered and whether unused capacity expires, rolls forward, or can be reassigned.
    • Artifact: What the recipient gets, such as an annotated audit, delta brief, implementation ticket, dashboard, or test report.
    • Completion rule: The approval, QA check, deployment state, or measurement event that marks the unit as done.

    The verb matters as much as the quantity. Review is not rewrite. Recommend is not implement. Validate is not repair. When the verb changes, the skill, access, risk, and time requirement usually change with it.

    Strategy and execution therefore need separate line items, even when the same person handles both. A strategy unit can finish with a prioritized recommendation and implementation specification. An execution unit finishes only after the agreed changes are made and checked. Without that distinction, a clear recommendation can quietly turn into an obligation to configure the CMS, coordinate developers, rewrite copy, publish the page, and investigate the result.

    SEO work unitWhat the base unit can includeWhat changes the scope
    Technical auditNamed pages or templates, specified checks, findings, and prioritized recommendationsAdditional templates, implementation, development tickets, deployment, or post-fix validation not listed in the agreement
    Content refreshBaseline review, section diagnosis, and a delta brief for the agreed URLsA full rewrite, a new page, another language or market, CMS publishing, or new creative assets
    Content strategyAgreed query set, intent analysis, page recommendations, and prioritized roadmapWriting briefs, producing copy, interviewing subject experts, or implementing the roadmap
    AI and GEO researchDefined personas, synthetic query exploration, answer-gap analysis, and recommendationsOngoing visibility monitoring, new persona sets, content production, schema implementation, or additional platforms
    Performance reportingNamed data sources, scheduled format, commentary, and a decision-focused meetingNew data cuts, extra competitors, historical investigations, custom dashboards, or unscheduled analysis

    Then write a definition of done for each recurring unit. A strategy-only content refresh might be done when the baseline is captured, every section is classified, the delta brief is delivered, and the client approves it. If implementation is included, the same unit remains open until the specified changes are published and pass QA. Measurement can be another unit with its own window and completion rule.

    This prevents a common accounting mistake: treating a recommendation, its implementation, and the eventual performance analysis as one deliverable even though they happen at different times and require different resources.

    Run every page through one visible delivery pipeline

    Abstract webpage cards move through connected trays for inspection, adjustment, approval, and completion on a modular worktable.

    You do not scale SEO by making every specialist work faster. You scale it by making the recurring decisions consistent. Each page or work package should pass through a visible sequence with required inputs, an owner, an approval state, and a controlled release point.

    1. Capture the request. Record the objective, affected URLs or templates, market, requester, desired timing, and reason the work matters. A message in a chat channel is not a sufficient production brief.
    2. Check entitlement and capacity. Match the request to a contracted unit before anyone starts diagnosing it. If it does not match, route it to substitution, change control, or the backlog.
    3. Lock the baseline. Select the pre-change window, metrics, query groups, and comparison method before editing. For a seasonal travel marketplace, a 56-day Search Console baseline matched an eight-week test period while avoiding a comparison that blended distant seasons. That duration is not a universal rule. The transferable rule is to use comparable before-and-after windows and account for seasonality before drawing a conclusion.
    4. Diagnose the existing asset. Inspect its leading queries and classify its sections as keep, fix, remove, or add. Keep protects material that remains accurate and performs a useful search function. Fix preserves the idea while correcting stale execution. Remove requires an explicit reason. Add addresses a demonstrated gap.
    5. Write the delta brief. Specify only what changes, why it changes, which query or persona supports the decision, and what must remain untouched. Do not commission a new-page brief for a live URL unless a full replacement is genuinely the approved scope.
    6. Approve the intervention. Confirm the delta, implementation owner, dependencies, publishing access, QA requirements, and delivery slot. Approval should precede production, not merely acknowledge it afterward.
    7. Implement and validate. Apply the agreed changes, check the preserved sections, verify relevant internal links and structured data, and confirm that the published result matches the approved brief.
    8. Measure against the locked baseline. Wait for the agreed test window, report the preselected metrics, and distinguish observed movement from assumptions about causation.

    Query diagnosis needs the same discipline. Top queries should be protected, positions 5–20 with weak click-through rates can identify striking-distance opportunities, and high-impression queries with almost no clicks can reveal an unanswered intent. These are prioritization signals, not automatic rewrite instructions. You still need to inspect whether the page is the right asset for the query and whether the proposed change fits its commercial purpose.

    For AEO and GEO work, keep observed and synthetic demand visibly separate. A scalable persona method can combine a 16-month sitewide Search Console query set with synthetic, LLM-style query fan-out. The first dataset reflects recorded search behavior. The second proposes plausible questions that may surface in conversational systems. Synthetic queries can expose answer gaps, but they are hypotheses rather than proof of demand. Labeling them prevents an attractive AI-generated cluster from outranking actual audience evidence in your decisions.

    The keep decision is especially important. A ranking page is not a blank document: internal links already point to it, structured data may already be deployed, and its historical performance provides a baseline. Rewriting a decaying page from top to bottom can erase useful search equity even when the intention is to refresh it. The delta brief makes restraint part of production instead of leaving it to the writer’s memory.

    Automation should enter after this workflow is stable. Claude Code or another automation layer can prepare exports, populate brief templates, apply required labels, and flag missing fields. It should not quietly turn a diagnostic signal into published copy. Keep approval and release as explicit states because the cost of a careless bulk change is carried by live pages, not by the automation queue.

    Use operational statuses that reveal where work is blocked: requested, scoped, scheduled, in progress, awaiting approval, ready to publish, measuring, and complete. A page cannot be both awaiting approval and counted as completed production. That distinction gives account leads and delivery managers a shared view of real capacity.

    Make capacity and change control the same system

    A transparent container filled with work blocks directs one new amber block toward rescheduling, replacement, or an expanded boundary.

    Scope control fails when the contract lives in one place and the delivery queue lives in another. The contract defines entitlement, but the queue shows consumption. You need both views on the same work item.

    Maintain a capacity ledger for each client, department, or SEO program. It should show:

    • The contracted work unit and its quantity.
    • The unit’s current status and owner.
    • The intended delivery window.
    • Dependencies and approvals still outstanding.
    • Actual effort and the reason for material variance.
    • Approved changes added to the plan.
    • Unplanned requests waiting for a decision.

    Track variance by cause, not merely as extra time. A refresh may overrun because the original page count was wrong, implementation access was missing, review cycles were undefined, data had to be rebuilt, or a new stakeholder changed the target. Those causes require different fixes. Historical effort alone cannot tell you whether to adjust the estimate, the intake gate, the contract language, or the approval process.

    Small requests deserve particular attention. A twenty-minute page review, keyword check, or competitor investigation can feel too minor to route formally. Repeated across reporting cycles and a full client roster, those requests become unscheduled production. Their cost also includes context switching, communication, documentation, and the work displaced from the committed queue.

    Give every new request one of these destinations:

    • Substitute it. The requester replaces an existing deliverable with the new one, and the displaced item is explicitly rescheduled or removed.
    • Approve a change. The work receives additional budget, capacity, and a revised delivery date.
    • Defer it. The request enters a prioritized backlog for a future scope or planning cycle.

    There is no invisible fourth destination in which the team absorbs the work while every existing promise remains unchanged.

    A change order does not need to be elaborate. Its minimum useful fields are the estimated hours, additional cost, and revised timeline. Add the affected deliverables, assumptions, dependencies, acceptance criteria, and named approver when they help eliminate ambiguity. Introduce the process during kickoff so it is a normal delivery mechanism rather than a policy unveiled during a disagreement.

    A useful boundary response is direct and gives the requester a choice: Yes, we can take that on. It is not included in the current deliverable. We can scope it as an added change, or replace the planned item and move that work to the backlog. Which route fits your priority?

    This is not a refusal. It makes the tradeoff visible. The requester can still choose speed, breadth, or cost, but the delivery team does not pretend all three are unchanged.

    You can often detect scope drift by watching the grammar of a request:

    • A new noun: Another URL, template, competitor, market, language, dashboard, persona, or data source has appeared.
    • A stronger verb: Review became rewrite, recommend became implement, or validate became repair.
    • A deeper question: A scheduled performance explanation became a new investigation requiring additional exports or analysis.
    • A different cadence: A recurring monthly deliverable is now expected on demand or more frequently.
    • A new dependency: The work now requires development, design, legal review, localization, subject-matter input, or publishing access.

    Each signal should trigger a scope check before production begins. If you want to include a flexible support allowance, define its size, eligible request types, approval path, and rollover rule in advance. An unnamed allowance becomes unlimited support in practice because nobody can tell when it has been consumed.

    Assign one commercial owner to approve changes and one delivery owner to confirm capacity. Specialists can estimate the work, but they should not have to renegotiate the engagement every time a request reaches them. That separation also prevents a casual message to a writer or analyst from bypassing the queue.

    Use reporting to close decisions, not open side projects

    Reporting is part of delivery, not an unlimited analysis channel. A dashboard full of unexplained numbers invites follow-up questions because the reader still has to determine what changed, whether it matters, and what to do. If every answer requires a fresh investigation, a scheduled reporting unit can expand into hours of unplanned analysis.

    Design each report around decisions. Include:

    • The agreed objective: The outcome this workstream is intended to influence.
    • The committed outputs: What was delivered, deferred, substituted, or blocked during the reporting period.
    • The preselected metrics: The measures chosen before implementation, with the applicable baseline and comparison window.
    • The interpretation: What the data establishes, what remains uncertain, and which changes are plausible explanations rather than proven causes.
    • The recommended action: Continue, stop, revise, investigate, or wait for the measurement window to close.
    • The decision required: The person who must decide and the consequence for scope, timing, or priority.
    • The investigation queue: Questions that require new work, with their scope status clearly shown.

    This format still allows questions. It simply separates explanation of the agreed report from a new analytical deliverable. A question that can be answered from the prepared analysis belongs in the meeting. A request for another competitor, query segment, attribution view, language, or historical window should return to intake.

    Reports that present numbers without enough context tend to generate additional analysis and investigation. Budget context into the reporting unit itself, then state the boundary. Define the format, cadence, included commentary, meeting length, supported data views, and route for deeper questions in the statement of work.

    Keep output acceptance separate from performance evaluation. A strategy unit can be complete when the agreed recommendations and roadmap are approved. An execution unit can be complete when specified changes are published and pass QA. A measurement unit can be complete when its window closes and the selected metrics are reported. None of those definitions guarantees a ranking or traffic result.

    That separation does not weaken accountability. It makes accountability precise. Delivery owns the agreed process, quality checks, evidence, and response to the result. Search performance remains an observed outcome affected by factors beyond whether a document was delivered on time.

    For a content refresh, report both tracks:

    • Delivery track: Baseline captured, sections classified, delta approved, changes published, internal links and structured data checked, and test started.
    • Performance track: Movement in the protected top queries, striking-distance query group, click-through rate, clicks, impressions, and average position during the agreed comparison window.

    If the page underperforms, the next diagnostic is a new decision point. It should not silently reopen every preceding deliverable. Decide whether the response is included optimization, a substituted work unit, an approved change, or a backlog item.

    Key takeaways

    • Define SEO services by object, action, quantity, depth, cadence, artifact, and completion rule. Goals belong in the strategy; they do not replace deliverables.
    • Price and schedule strategy, implementation, validation, and measurement as distinct work, even when the same team performs them.
    • Refresh live pages with a locked baseline, keep-fix-remove-add diagnosis, and delta brief. Preserve useful sections instead of treating every update as a full rewrite.
    • Route every additional request to substitution, a priced change, or the backlog. Do not leave silent absorption available as an operating choice.
    • Keep observed search behavior separate from synthetic LLM-style queries so plausible questions do not masquerade as measured demand.
    • Build reports around decisions and preselected metrics. Route new data cuts and investigations back through intake.
    • Automate repeatable preparation and validation only after the workflow has clear inputs, states, approval gates, and stop conditions.

    Start with one active statement of work and one recurring SEO workflow. Circle every vague object and verb, then replace each with a countable unit and a definition of done. Put the next unplanned request through the substitution, change, or backlog decision before anyone starts it. If the request has nowhere to go, you have found the exact gap your delivery system needs to close.

    References


  • How to Choose a HubSpot Revenue Operations Consulting Firm

    How to Choose a HubSpot Revenue Operations Consulting Firm

    If your HubSpot portal is messy, the tempting brief is simple: fix HubSpot. That brief is usually too small. A consultant can clean fields and rebuild workflows while leaving lead ownership, lifecycle definitions, forecasting, and customer handoffs just as fragmented as they were before.

    Your real decision is whether you need a HubSpot specialist, a Revenue Operations operator, or a firm that can do both. The framework below will help you define the job, build a relevant shortlist, test delivery depth, and contract for a system your team can operate after the consultants leave.

    Key takeaways

    • Hire a HubSpot specialist when the main problem is platform architecture, migration, integration, or configuration. Hire a RevOps firm when ownership, definitions, incentives, and handoffs are broken across marketing, sales, and customer success.
    • Use a hybrid firm when the operating model and the HubSpot build must change together. Confirm that it supplies both a senior process owner and a hands-on technical lead.
    • Shortlist firms by engagement shape, platform coverage, functional depth, and execution model. Partner tier, awards, reviews, and client logos are useful filters, not substitutes for fit.
    • Require concrete artifacts: a lifecycle map, data dictionary, automation inventory, integration design, migration controls, reporting definitions, enablement plan, and administrator runbook.
    • Ask who will work in the portal, how destructive changes will be tested, and what happens when an integration or automation fails.
    • If AI is included, insist on a named workflow, approved data inputs, human-review rules, logging, and a fallback path. An AI label is not an operating design.

    Decide which problem you are actually paying to solve

    A revenue operations specialist inspects broken and duplicated connections among five stages of a business process before opening a toolkit.

    Revenue Operations treats marketing operations, sales operations, and customer success operations as connected parts of the same revenue system. HubSpot is one place where that system can be implemented, but the platform cannot decide what your teams mean by qualified, who owns an idle opportunity, or when sales should return a lead to marketing.

    Automation encodes operating decisions. If those decisions are unresolved, faster automation produces faster confusion. Start with the failure you can observe, then choose the engagement that addresses its cause.

    What you can observeLikely engagementWhat completion should look like
    Duplicate properties, unreliable syncs, brittle workflows, or an incomplete migrationHubSpot implementation, integration, or platform optimizationA documented data model, tested integrations, controlled migration, monitored automation, and an administrator handoff
    Marketing and sales disagree about qualification, ownership, attribution, or pipeline stagesCross-functional RevOps design with CRM implementationAgreed definitions, entry and exit rules, named owners, exception paths, and corresponding HubSpot configuration
    The roadmap is understood, but nobody has the capacity or authority to operate itFractional RevOps or marketing operationsA prioritized operating backlog, a clear decision cadence, hands-on system ownership, and a plan for eventual internal ownership
    The portal is configured, but representatives work around it or managers maintain shadow spreadsheetsSales enablement, process redesign, and role-based adoption workFewer duplicate paths, usable views, manager inspection routines, role-specific training, and an explicit feedback process
    Ticketing, help desk work, renewals, and customer health are disconnected from the sales lifecycleService Hub and customer operations implementationDocumented support and escalation flows, connected customer records, ownership rules, and lifecycle reporting across the handoff

    Several rows may describe your situation. That does not automatically mean you need the broadest firm. It means one person must own the end-to-end architecture while specialists handle bounded work beneath it. Without that owner, a marketing workflow, sales process, customer service design, and integration can each be locally correct while the complete system remains incoherent.

    Write down the disputed operating decisions before you discuss software. Define your lifecycle stages, qualification rules, record ownership, system of record, revenue metrics, and exception paths. Mark any unresolved item as a decision the engagement must facilitate. Do not let an implementation team silently convert its preferred defaults into company policy.

    Build a shortlist around the work, not the badges

    The labels agency, consultancy, solutions partner, and fractional operator do not tell you who will design the process or touch the configuration. Look through the label to the firm’s actual operating model.

    For HubSpot work, leadership experience, customer reviews, partner tier, and HubSpot awards can narrow the market. For broader RevOps work, GTM platform breadth, experienced leadership, customer evidence, and complex-account experience add useful context. None of those signals tells you whether the proposed team has solved your type of handoff, whether its senior architect will remain involved, or whether it will perform the keyboard-level work.

    The following firms are useful names to investigate for particular engagement shapes. This is a starting map, not a universal ranking. Your scope, stack, industry constraints, internal capability, and desired working model determine the fit.

    Firm to investigateRelevant engagement shapeWhat to pressure-test
    DomestiqueFractional RevOps and marketing operations across the customer lifecycle, including migrations, technical implementation, funnel work, and a multi-platform GTM stackWhich senior operator owns cross-functional decisions, who performs weekly system work, and how knowledge transfers to your team
    Aptitude 8Complex HubSpot implementations, custom integrations, multi-hub architecture, platform optimization, and extensions beyond standard configurationArchitecture ownership after launch, integration monitoring, failure handling, and the boundary between custom development and maintainable native configuration
    SmartBug MediaService Hub, customer experience workflows, CRM implementation or migration, and sales coaching or trainingHow ticketing, service, sales, and customer-success data will share definitions and ownership rather than becoming separate HubSpot projects
    New BreedSales Hub and broader HubSpot migrations or implementations, including complex sales motions and integration workData reconciliation, sales-stage governance, representative adoption, manager inspection, and the post-launch administration model
    Six & FlowHubSpot-first RevOps, sales and marketing alignment, sales enablement, and AI or CRM enablementWhether a HubSpot-first recommendation matches your actual architecture, especially if Salesforce or multiple CRMs remain in scope
    SkaledOutbound performance, technology migration and support, sales alignment, and AI-enabled go-to-market executionWhich result depends on process, data, staffing, tooling, or message changes, and which part of the program the firm will directly own
    Go NimblyEmbedded RevOps work, revenue and technical architecture, fractional support, coaching, and AI-ready GTM foundations for SaaS or technology teamsThe embedded consultant’s decision rights, delivery cadence, technical contribution, and relationship with your functional leaders
    Winning by DesignRevenue architecture, GTM training, and methodology work built around the SPICED Framework and Bowtie ModelWhether you need methodology and enablement, system implementation, or both – and who translates the method into CRM fields, workflows, and reporting
    OperatusSalesforce CPQ, MuleSoft, RevOps as a service, and a stack spanning HubSpot, Salesforce, outbound, routing, and marketing automation toolsWhich platform is authoritative for each entity, how cross-platform changes are governed, and who supports the integration layer

    Apply hard gates before you debate presentation quality. A candidate should understand every critical platform in scope, have delivered the same shape of engagement, cover the functions affected by the change, and agree to an explicit execution model. It should also name the people who will do the work, not just the executives who join the sales call.

    • Platform gate: Can the team safely operate your real stack, including the systems that will remain outside HubSpot?
    • Engagement-shape gate: Has it handled a migration, fractional operating role, Service Hub build, outbound redesign, or custom integration comparable to yours?
    • Functional gate: Can it work with every team whose definitions or behavior must change?
    • Execution gate: Will it configure, test, document, and train, or will it stop at recommendations?
    • Accountability gate: Is there one named owner for architecture, decisions, risks, and acceptance?
    • Handoff gate: Will your internal team be able to diagnose, maintain, and extend the system at the end?

    A firm that fails a hard gate should not advance because it has a higher partner tier or a more recognizable client list. Those credentials may break a tie after delivery fit has been established.

    Turn the brief into a measurable engagement

    A vague request for HubSpot optimization invites vague proposals. Give every candidate the same one-page brief so differences in approach become visible.

    1. State the business failure. Describe what is happening in operational language: leads have no clear owner, managers cannot explain stage movement, renewals are missing from the customer record, or an integration creates conflicting values.
    2. Attach current-state evidence. Include the relevant portal inventory, object and property lists, workflow inventory, integration list, sample records, reports, process documents, and known data-quality problems. Remove or protect sensitive data before sharing it during procurement.
    3. Name the affected functions. Identify which marketing, sales, service, finance, operations, and technical owners must approve definitions or change their behavior.
    4. Set the system boundary. List what is moving into HubSpot, what remains elsewhere, which system should govern each important record type, and which integrations are in or out of scope.
    5. Expose unresolved decisions. Separate missing configuration from missing policy. If leadership has not agreed on qualification, attribution, ownership, or stage criteria, say so explicitly.
    6. Define done. Specify the artifacts, configured behavior, validation evidence, training, documentation, and ownership transfer required for acceptance.

    Use your own baselines and business targets. A consultancy can help validate how a metric is calculated, but it should not invent a success threshold merely because procurement expects a number. If your baseline is not trustworthy, establishing one is part of the work.

    Require artifacts that survive the engagement

    Strategy becomes operable when it is expressed as maintained artifacts, configured behavior, and acceptance evidence. The exact package will vary, but the following deliverables prevent essential knowledge from remaining in meeting notes or in a consultant’s head.

    DeliverableMinimum acceptance test
    Current-state and future-state lifecycle mapEach stage has a definition, entry rule, exit rule, owner, handoff, exception path, and corresponding system behavior
    CRM data model and dictionaryObjects, properties, associations, allowed values, naming rules, required fields, owners, and systems of record are documented
    Automation and routing inventoryEvery active workflow has a purpose, trigger, conditions, exclusions, owner, failure path, and retirement rule
    Integration architectureData direction, identity matching, overwrite behavior, conflict handling, permissions, monitoring, and support ownership are explicit
    Migration and cleanup planMapping, deduplication rules, test imports, approvals, reconciliation, backup, rollback, and exception handling are defined before production changes
    Reporting specificationEvery key metric has a plain-language definition, calculation logic, filters, data origin, refresh behavior, and accountable owner
    AI-assisted workflow specification, if applicableThe approved inputs, intended output or action, model and tool boundary, permission scope, human-review rule, logging, error handling, and fallback path are documented
    Enablement and administrator handoffRole-based instructions, governance rules, troubleshooting steps, open risks, credentials ownership, and the post-launch backlog are transferred to named internal owners

    Weak scope: Implement HubSpot for marketing and sales.

    Stronger scope: Facilitate agreement on the lead and opportunity lifecycle, map the approved CRM data model, migrate agreed records, configure ownership and routing, validate integrations and reporting, train each operating role, and deliver an administrator runbook with unresolved risks.

    If the lifecycle, data model, and system boundaries are still uncertain, make discovery an explicit deliverable before committing to the complete build. Discovery should finish with decisions, maps, risks, assumptions, a prioritized backlog, and an implementable scope. A slide deck that merely confirms the original ambiguity is not enough.

    Ask candidates to label assumptions and dependencies in their proposal. This reveals where pricing and timing could change: unavailable internal owners, undocumented integrations, poor data quality, conflicting executive definitions, limited API access, or a separate vendor that controls part of the stack. Change is easier to govern when the trigger is visible before the contract is signed.

    Interview and contract for a safe handoff

    A consultant transfers a key, an unmarked binder, and a toolkit to an internal administrator beside a completed modular business system.

    A polished sales presentation shows that a firm can sell an engagement. Your interview must show how it diagnoses, decides, builds, tests, escalates, and hands over the result.

    Ask questions that expose the delivery model

    1. Walk us through a comparable handoff from beginning to end. Listen for definitions, decision owners, system behavior, exceptions, testing, adoption, and measurement – not just a list of HubSpot features.
    2. Who will lead our work, who will configure the portal, and who reviews the configuration? Ask for named roles and expected involvement. Clarify what happens if a proposed team member is replaced.
    3. Show us an anonymized example of the artifacts we will receive. A lifecycle map, data dictionary, integration design, test plan, or administrator runbook reveals more than a general methodology diagram.
    4. How do you handle disagreement between marketing, sales, and customer success? A strong answer should explain facilitation, decision rights, documentation, and escalation. The consultant should not disguise an unresolved leadership decision as a software setting.
    5. How do you choose between native configuration, custom code, and another tool? Look for attention to maintainability, permissions, failure modes, administrator skill, and total operational burden.
    6. How will you test a migration or destructive cleanup? Require a staged approach, backup, reconciliation method, approval point, exception log, rollback path, and named decision-maker.
    7. What happens when a sync or workflow fails after launch? The answer should identify monitoring, alert ownership, triage, remediation, documentation, and the boundary between project support and ongoing operations.
    8. How will you establish the baseline and connect the work to an outcome? Listen for metric definitions and data validation. Be cautious if a firm promises a business result before it understands your baseline, dependencies, and adoption risks.
    9. How will users and managers change their behavior? Training alone is not adoption. Ask about role-specific processes, manager inspection, feedback, documentation, and who owns reinforcement after launch.
    10. What exactly does AI do in the proposed solution? Ask which decision or task it supports, which CRM data it can access, where data is sent, how output is reviewed, how errors are logged, and what happens when the model or external service is unavailable.
    11. What can our administrator operate without you at the end? The answer should connect system complexity to your team’s actual skills and identify any continuing dependency clearly.

    Watch for signals that the engagement will drift

    • The firm recommends a new tool or major reimplementation before inspecting your process, portal, data, and integration boundaries.
    • The senior operator runs discovery and then disappears, leaving an implementation team with no authority to resolve cross-functional decisions.
    • Every problem is described as a HubSpot configuration issue even when ownership, incentives, definitions, or management routines are clearly involved.
    • The proposal promises dashboards before defining the lifecycle, metric logic, required fields, and data-quality controls beneath them.
    • Migration language covers importing records but not matching identities, reconciling totals, logging exceptions, obtaining approval, or rolling back.
    • AI is presented as a general capability rather than a bounded workflow with approved data, evaluation, human oversight, logging, and fallback behavior.
    • Partner tier, certification volume, awards, or client logos are used in place of showing the proposed team’s relevant work products.
    • Post-launch ownership is vague. Nobody is named to monitor integrations, approve changes, maintain documentation, or manage the backlog.

    Put acceptance, control, and ownership in the contract

    • Named delivery team: Identify the engagement owner, architect, implementers, reviewers, trainers, and escalation contact, along with the process for substitutions.
    • Phases and acceptance: Tie each phase to deliverables, review responsibilities, approval criteria, and the consequence of rejected or incomplete work.
    • Decision rights: Record which decisions the consultant may make, which require client approval, and who resolves cross-functional disputes.
    • Assumptions and dependencies: Make access, internal participation, third-party vendors, data condition, and technical constraints visible.
    • Change control: Define how new requirements, unexpected data conditions, or platform limitations change scope, cost, sequencing, or delivery expectations.
    • Security and access: Require least-privilege access, approved handling of sensitive data, credential ownership, access removal, and disclosure of relevant subcontractors or external systems.
    • Configuration and data ownership: Confirm that your organization retains its portal, data, custom assets, configuration documentation, and administrator access.
    • Operational support: Define what is covered after launch, how issues are reported, who monitors failures, and what becomes a separate managed-service engagement.
    • Exit package: Require final diagrams, inventories, decision records, test evidence, unresolved risks, training materials, and the prioritized backlog.

    Do not approve property deletion, irreversible deduplication, workflow retirement, association changes, or a production migration without a recoverable backup, a controlled test, reconciliation evidence, an approval point, and a rollback owner. The downside is not merely a delayed project. It can be permanent data loss, incorrect routing, broken reporting, or customer-facing automation triggered from bad records.

    Give each finalist the same brief and ask for the same response structure: problem interpretation, approach, named team, assumptions, dependencies, risks, deliverables, acceptance process, and support model. This makes omissions visible. Then speak with references whose engagement resembles yours and ask what broke, how scope changes were handled, whether senior people stayed involved, and whether the internal team could operate the system afterward.

    Start by writing the failing lifecycle or handoff in one sentence and attach the evidence behind it. Send that brief to firms selected for the shape of the work. The right HubSpot and RevOps consulting firm will make the process, data, ownership, risks, and handoff more specific before it asks you to trust its brand.

    References

  • Google Ads Shopping Defaults and Lead Form Access: An Audit Plan

    Google Ads Shopping Defaults and Lead Form Access: An Audit Plan

    Two Google Ads changes can put the same account at risk in opposite ways. Beginning August 31, Shopping campaigns gain local-inventory reach by default. At the same time, Lead Form assets may become accessible to advertisers previously excluded by a large spend requirement.

    Treat both as access-control changes. One changes what your campaigns may serve; the other changes who may use a lead format. Neither removes the need for deliberate targeting, verified eligibility, and a reliable data handoff.

    Key takeaways

    Replace the local-inventory toggle with an explicit scope

    A generic campaign control panel connects through adjustable gates to an online warehouse and several local storefronts on a simplified city map.

    The old Shopping control was simple: an integration could set Campaign.ShoppingSetting.enable_local to false. That value is becoming ineffective. Google will treat the setting as true for every Shopping campaign, regardless of the value an integration submits.

    The dangerous case is not necessarily a visible campaign failure. It is false confidence. A configuration file may still contain enable_local=false, leading your team to believe that local inventory is excluded when Google is enforcing a different result.

    • With Google Ads API v25.1 or later, attempting to set enable_local to false returns ContextError.OPERATION_NOT_PERMITTED_FOR_CONTEXT.
    • With versions earlier than v25.1, existing code may continue to run, but the false value is ignored and Google treats the setting as true.
    • The change applies to Shopping campaigns. Do not automatically rewrite configurations for other supported campaign types: enable_local continues to function for Performance Max and Demand Gen.

    Audit the intent of each campaign before changing code. A clean migration follows five steps:

    1. Classify every Shopping campaign. Mark it as online only, local and online, or intentionally separated by inventory and budget. Do not infer intent from the current value of enable_local; that value may be an inherited template default.
    2. Find every place that writes the old field. Check API integrations, campaign builders, bulk-operation scripts, internal templates, and automated account provisioning. Record the API version used by each workflow.
    3. Move online-only enforcement into listing scope. Use CampaignCriterionService to create a listing scope with product_channel set to ONLINE. This makes the inventory boundary explicit instead of relying on a campaign setting Google will ignore.
    4. Use the Inventory filter where campaign-level separation is easier to manage. Exclude local inventory there when a campaign must remain online only. If online and local products require separate budgets, preserve that separation through campaign structure and inventory filtering.
    5. Validate the result, not merely the deployment. Confirm that each campaign’s effective inventory scope matches its classification. For v25.1 or later, also verify that no automation is generating the context error.

    This is more than an API cleanup. Google is moving the meaningful control from a Boolean switch to inventory selection. Your campaign documentation, approval process, and automated tests should name the selected product channel directly.

    Treat Lead Form access as provisional until the account confirms it

    The disappearance of the $50,000 Google Ads spend requirement materially lowers the stated barrier to Lead Form assets. It does not prove that every qualifying smaller account has already received access. Do not promise the format in a media plan, client scope, or launch schedule until the intended account can create and attach the asset.

    The remaining eligibility route centers on advertiser reputation and Advertiser Verification. The spend levels associated with that route are more than $1,000 per account or $15,000 across accounts. Treat those amounts as eligibility checks, not campaign objectives. Increasing spend solely to cross a threshold is not a sound substitute for confirming access.

    Use this pre-launch check for each account:

    1. Confirm Advertiser Verification. Identify whether it is complete and whether any unresolved account-status issue could affect reputation-based eligibility.
    2. Test actual asset access. Have an authorized account user verify that the Lead Form asset is available in the account. A removed requirement is not the same thing as a universal rollout guarantee.
    3. Confirm the campaign type. Search and Performance Max are the two currently listed options. Video is no longer listed. Display is also omitted from the supported overview, although a separate requirements passage still references it. Treat Display as unresolved until the account interface and current requirements agree.
    4. Check each target country. Eligibility has expanded into more than two dozen additional countries, including Bahrain, Croatia, Estonia, Jordan, Kuwait, Morocco, Qatar, Serbia, Slovenia, and Tunisia. A multi-country account should validate availability market by market instead of reusing an old eligibility list.
    5. Decide whether to use OTP verification. It is available as a lead-quality control. Measure its effect on both completed submissions and accepted leads rather than assuming that adding verification automatically improves the final pipeline.

    This distinction prevents a common planning error: lower eligibility friction does not remove implementation constraints. Your account still needs the right status, a supported campaign type, an eligible country, and a lead-delivery process that works after the form is submitted.

    Design the lead handoff before you activate the asset

    Anonymous lead-profile tokens move through secure validation checkpoints into a customer-management system and an encrypted archive while an operator monitors the handoff.

    Lead access is only useful when a submission reaches the person or system responsible for follow-up. Google supports manual CSV downloads, email notifications, Zapier, webhooks, and the Google Ads API. Choose a primary delivery method and a recovery path before the first live submission.

    Delivery methodBest fitControl to put in place
    Email notificationsA straightforward alert for a low-complexity workflowUse a monitored inbox and name the person responsible for missed or delayed notifications.
    ZapierNo-code routing into CRM platforms and other business applicationsMonitor connection status and failed automation runs; access to thousands of applications does not guarantee that a particular field mapping is correct.
    WebhookDirect delivery into a system you controlMonitor endpoint failures, authentication, field validation, and retry handling.
    Google Ads APIManaged exports and account-scale workflowsTrack credentials, scheduled-job health, and the 60-day export limit.
    CSV downloadManual review, reconciliation, or short-term recoveryDownload within 30 days; the manual window is shorter than Google’s 60-day storage period.

    Google stores Lead Form data for 60 days, but manual CSV downloads remain available for only 30 days. API exports can access up to 60 days. Those are operational deadlines, not archival guarantees. Your CRM or another controlled business system should become the durable system of record.

    Run a controlled handoff test before activation:

    1. Submit a test through each campaign type and country configuration you intend to use.
    2. Verify that every required field arrives in the correct destination and maps to the expected CRM field.
    3. Confirm that the lead receives an owner and enters the intended follow-up workflow.
    4. Document who investigates a failed email, Zapier run, webhook request, or API export.
    5. Schedule reconciliation frequently enough that a failure cannot remain hidden beyond the 30-day manual-download window.

    A notification is not the same as successful ingestion. Your acceptance test should end only when the submission appears in the destination system with the correct fields and owner.

    Build one control sheet for defaults, eligibility, and retention

    The durable fix is an account-level record of intended behavior. Keep it alongside your campaign launch checklist and include:

    • Campaign name, type, market, and accountable owner.
    • Intended Shopping inventory: online, local, or both.
    • The enforcement layer: an ONLINE listing scope, an Inventory filter, or a documented mixed-inventory decision.
    • Google Ads API version, integration owner, and the location of any remaining enable_local write operation.
    • Advertiser Verification status and the date Lead Form access was confirmed in the account.
    • The supported campaign type and country used for each Lead Form asset.
    • Primary lead-delivery method, fallback method, and failure-monitoring owner.
    • The 30-day CSV deadline, 60-day storage limit, and date of the latest successful handoff test.

    Finish the Shopping review before August 31: remove unexplained uses of enable_local=false and replace every intentional online-only rule with an enforceable scope or filter. Then test Lead Form eligibility separately in each account. If access is present, activate it only after a complete submission reaches its assigned destination.

    References