Tag: Automation

  • Semantic Programmatic SEO: A Practical Blueprint for Scale

    Semantic Programmatic SEO: A Practical Blueprint for Scale

    You have a spreadsheet full of locations, services, products, or audience segments, and a template that could turn those rows into hundreds of URLs. The uncomfortable question is whether you are building a useful search asset or manufacturing near-duplicates.

    The answer is settled before generation begins. Semantic programmatic SEO works when every URL represents a distinct combination of entity, intent, context, and evidence. This blueprint shows you how to find those combinations, decide which deserve pages, govern AI output, connect the resulting pages, and stop weak page families before they spread.

    Prove your authority and page opportunity before you scale

    Programmatic SEO is a production method, not a reason to publish. It lets you address a large set of related needs through structured data, reusable components, and repeatable rules. Semantic SEO supplies the meaning: the entities involved, their relationships, the user’s situation, the criteria behind the decision, and the answer that changes with the context.

    That distinction matters because mass-producing unoriginal pages solely to influence rankings is a spam tactic, not a scale strategy. A new URL needs a reason to exist beyond a substituted place name or product label.

    Use Search Console as an authority map

    Start with the territory your domain has already earned. Google Search Console can show which subjects, entities, and needs are producing impressions, clicks, and recognized landing pages. You are not looking only for high-volume keywords. You are looking for evidence that search engines already connect your site with the broader topic.

    1. Export the queries and landing pages related to the proposed page family.
    2. Group queries by the need behind them, not merely by repeated words. Separate comparison, eligibility, availability, price, location, suitability, and troubleshooting intents where they genuinely differ.
    3. Mark the clusters for which your site already has a relevant page, those receiving visibility without a strong landing page, and those with no visible connection to the domain.
    4. Identify the nearest credible expansion. A cluster adjacent to existing authority is a better starting point than a large but disconnected keyword set.
    5. Record which current page should act as the hub. If you cannot identify a natural parent page, the proposed family may sit outside your present site structure.

    This audit prevents a common strategic error: interpreting a large keyword universe as permission to publish a large URL universe. Demand tells you that a topic exists. Existing authority, useful proprietary or curated data, and a coherent place in the site tell you whether your domain should build it.

    Give every candidate URL an eligibility test

    Create one record for every proposed entity-intent combination before you create any prose. The record should answer these questions:

    • Distinct need: What question does this combination answer that its parent and sibling pages do not?
    • Meaningful variables: Which facts alter the answer, recommendation, order of information, or next action?
    • Evidence: Which reliable fields support those differences?
    • User consequence: What can the visitor decide or do after reading this page?
    • Site relationship: Which hub, sibling, and next-step pages connect naturally to it?
    • Maintenance: Who or what will detect when its underlying information becomes incomplete or stale?

    If the only meaningful field is the keyword in the title, do not generate the URL. If several proposed pages lead to the same answer, consolidate them into a stronger hub or filtered experience. If the answer changes because of real local, seasonal, product, or audience conditions, you may have a viable page family.

    Use this as your semantic-delta rule: a page becomes eligible only when its data changes the substance of the answer. Different wording is not a semantic difference. Different constraints, priorities, evidence, recommendations, or actions are.

    Design a semantic page system, not a word-swapping template
    A modular framework supports several webpage structures with shared components but distinct symbols, evidence blocks, and layouts.

    A template normally starts with visible sections: introduction, benefits, frequently asked questions, and call to action. A semantic system starts one layer earlier. It defines what the page knows, which relationships matter, and under what conditions each component should appear.

    Consider searches for the best hotel in Las Vegas and the best hotel in Orlando. The grammatical pattern is identical, but the relevant priorities and amenities can differ by destination. Replacing one city name with another preserves the syntax while ignoring the reason a traveler is making the search.

    Build an intent record for each page

    Your content model should hold the information needed to produce a useful answer without asking the generator to invent missing facts. A practical intent record includes:

    • Primary entity: The place, service, product, category, institution, or other subject represented by the page.
    • User job: The decision or task the visitor is trying to complete.
    • Audience or situation: The conditions that materially change the answer.
    • Decision criteria: The attributes that deserve emphasis for this combination.
    • Local or contextual facts: Information that distinguishes this entity from sibling entities.
    • Seasonal conditions: Time-dependent information that changes relevance, availability, or recommendations.
    • Evidence and provenance: Where each factual field came from and whether it is safe to publish.
    • Recommended next step: The action that follows logically from the answer.
    • Related entities: Parent, sibling, alternative, and supporting pages that genuinely help the visitor continue.

    Keep factual data separate from generated prose. That separation lets you validate the facts, update a single field without rewriting the entire page, and prevent a language model from filling a data gap with plausible-sounding copy.

    Make components conditional on evidence

    A scalable page should not contain every possible module. It should assemble only the modules justified by the record. A seasonal section appears when current seasonal data exists. A comparison appears when the alternatives and comparison criteria are known. A local recommendation appears when the local facts actually change that recommendation.

    Write a rule for every optional block:

    • Which fields must be present before the block can render?
    • Which claim is the block allowed to make?
    • What happens when a required field is missing or stale?
    • Does the page remain useful without the block?
    • Should the page stay unpublished when the missing field is central to its promise?

    The safe default is to omit an unsupported optional block and reject a page whose core answer is unsupported. A generic fallback paragraph may keep a layout full, but it does not preserve usefulness.

    Write the page promise before the page copy

    Give every page family a one-sentence contract: “This page helps [audience] decide [job] for [entity] using [distinct evidence].” Then test every module against that sentence.

    If a section does not help fulfill the promise, remove it. If the same contract describes every sibling without any change in evidence, your model is probably too broad. If the contract changes only because the entity label changes, you have a templating plan but not yet a semantic one.

    This contract is also a better quality check than raw word count. A short page with a precise answer and entity-specific evidence can justify itself. A long page assembled from generic explanations can still be thin.

    Use AI inside a governed production pipeline
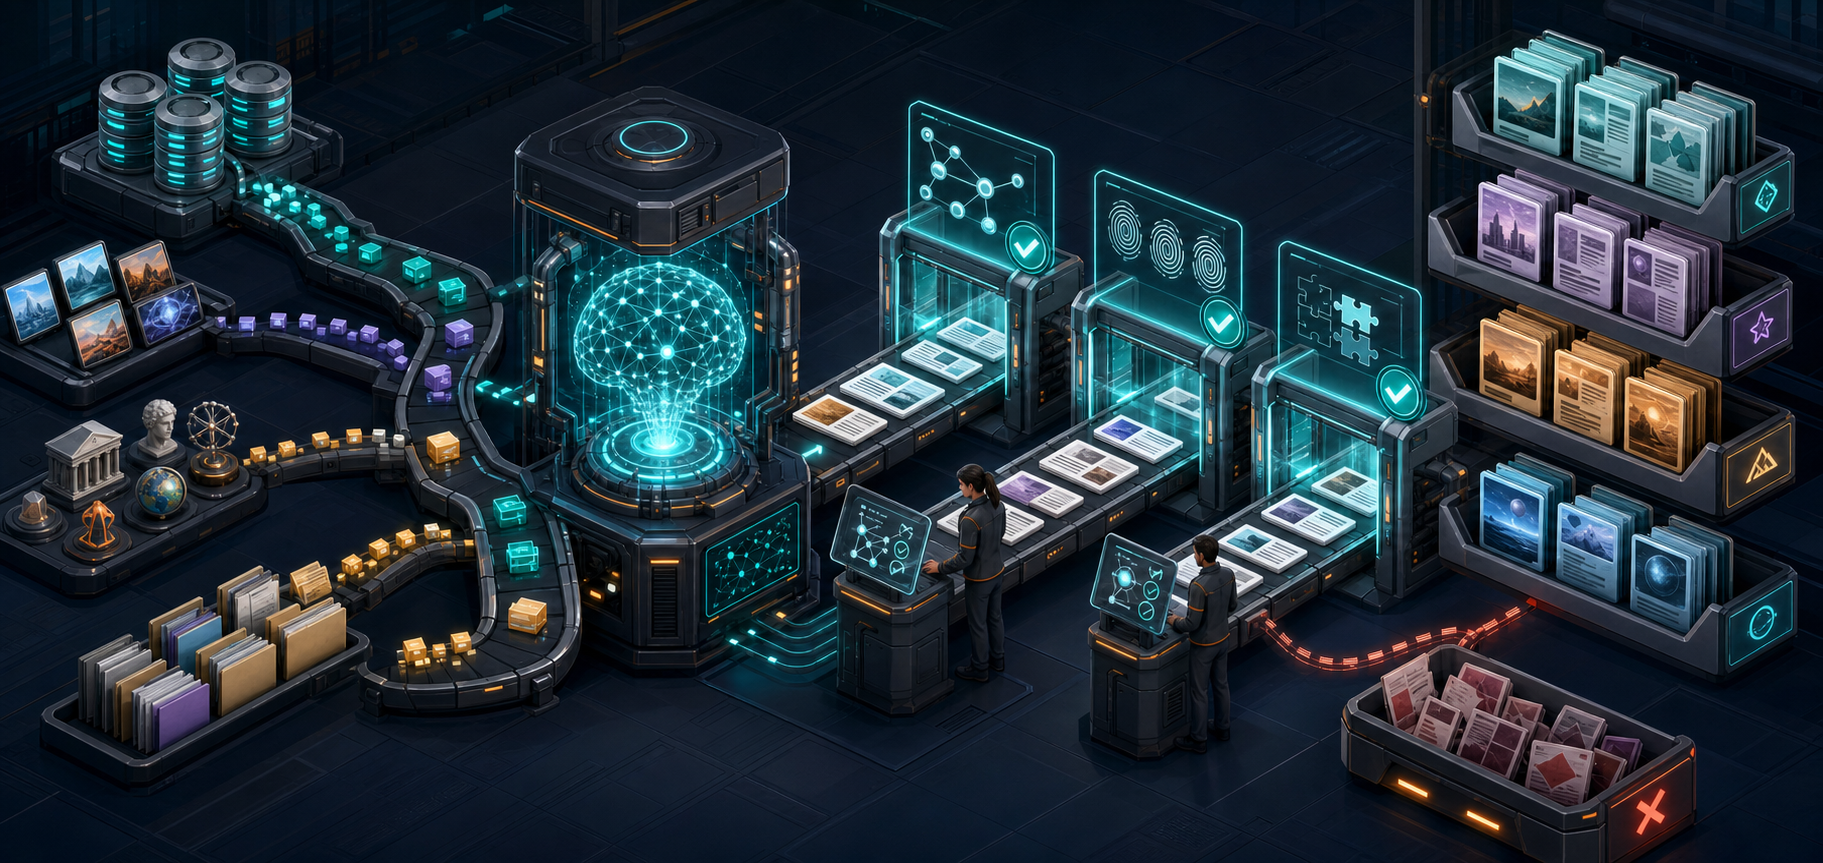
    Structured inputs move through an AI content pipeline, human review gates, and quality checks before approved pages are sorted into families.

    AI is useful for transforming structured facts into readable explanations, adapting emphasis to an intent, and producing consistent components. It should not decide whether a page deserves to exist, invent regional facts, or quietly repair missing data.

    Supply context as rules, not a loose brand prompt

    A prompt that says “write in our brand voice” leaves too much unresolved. Context governance should give the model a constrained working environment:

    • The intended reader and the decision they need to make.
    • The page promise and search intent.
    • Approved factual fields, with explicit instructions not to infer missing values.
    • Preferred terminology, reading level, tone, and point of view.
    • Claims the brand can make and claims it must avoid.
    • Required components and the conditions that activate optional components.
    • Examples of acceptable structure and phrasing without requiring the model to copy them.
    • Rules for uncertainty, unavailable information, and conflicting fields.
    • Allowed internal links and the relationship each link represents.

    Version this context alongside the template and data model. Otherwise, a voice change, legal restriction, or terminology update can affect some pages but not others, leaving the family internally inconsistent.

    Validate meaning before style

    Run generated pages through checks in a deliberate order. A polished sentence cannot rescue an unsupported answer.

    1. Data validation: Confirm that required fields exist, use the expected format, and come from an approved source.
    2. Claim validation: Match factual statements in the copy back to their structured fields. Reject claims that cannot be traced.
    3. Intent validation: Confirm that the page answers the job defined in its record rather than drifting into a generic topic overview.
    4. Differentiation validation: Compare the page with nearby siblings. Look for the same recommendations, examples, section order, and conclusions appearing despite different inputs.
    5. Brand validation: Check terminology, tone, prohibited claims, and required qualifications.
    6. Technical validation: Verify the intended URL, status, canonical target, robots handling, sitemap inclusion, rendered content, and internal links.

    Review every page in the first pilot manually. Once you understand the recurring failure modes, automate deterministic checks and direct human attention toward exceptions: missing regional evidence, conflicting inputs, unusually similar siblings, sensitive claims, and outputs that fail the page promise.

    Treat regionalization and seasonality as data

    Do not ask AI to “make the page feel local.” Give it verified local variables that alter the answer. The same rule applies to seasonality. A date in a heading does not make a page current; the underlying availability, priorities, conditions, and recommendations need a maintained validity window.

    For each time-sensitive field, store when it was observed, when it should be reviewed, and what the system should do if it expires. Depending on the importance of the field, the system can suppress one module, hold the page for review, or remove the page from the publication queue. Do not let the generator disguise stale or absent data with fluent language.

    Build the semantic mesh, then operate by page family

    Publishing is the midpoint. Programmatic pages fail as a collection when they are technically reachable but semantically isolated, or when nobody notices that one template defect has affected an entire family.

    Make every link express a useful relationship

    A semantic mesh connects pages according to how a visitor moves through the subject. The goal is not to maximize links per page. It is to make the site’s understanding of the topic visible while preventing dead ends.

    • Upward: Link each detail page to the hub that explains the broader category or decision.
    • Downward: Let hubs expose eligible detail pages in meaningful groups rather than dumping every generated URL into one directory.
    • Laterally: Connect siblings only when the relationship helps the same user compare, substitute, narrow, or continue.
    • Supportively: Link to explanatory pages when a visitor needs background before acting on the page’s answer.
    • Forward: Offer the logical next step after the immediate question is resolved.

    Anchor text should name that relationship. “Compare nearby options,” “check eligibility requirements,” or “see the parent category” carries more meaning than a repeated exact-match keyword inserted into every sibling.

    Before launch, inspect each candidate page from the visitor’s perspective. Can you tell where it belongs, how it differs from the surrounding pages, what evidence supports it, and where to go next? If not, adding more links will not solve the structural problem.

    Launch a family as a controlled pilot

    Start with the smallest page family that contains enough variation to test your model. Include straightforward records, records with optional fields, and edge cases with missing or time-sensitive information. This exposes whether the rules work across the family instead of proving only that the cleanest example looks good.

    Track page states explicitly: candidate, data-ready, generated, validated, index-eligible, published, and held for maintenance. A URL should move forward only when it passes the requirements for the next state. This makes publication a controlled decision instead of an automatic side effect of adding a row.

    Monitor patterns, not just totals

    Aggregate traffic can hide a weak program. A few strong URLs may carry a family while the rest remain unindexed, answer the same queries, or deliver no meaningful next action. Break reporting down by page family, template version, intent type, region, and data-completeness state.

    • Indexing behavior: Are eligible pages being indexed consistently, or is one family being skipped?
    • Query alignment: Are pages earning visibility for their intended needs, or are several siblings competing for the same query?
    • Semantic coverage: Are impressions expanding into the planned intent gaps, or only repeating visibility already owned by the hub?
    • Engagement with the answer: Do visitors take the next action the page was built to support?
    • Data health: Which pages have missing, conflicting, or expired fields?
    • Technical health: Are crawlability, canonical handling, rendering, internal links, and Largest Contentful Paint behaving consistently across the family?
    • Content drift: Did a prompt, model, template, or data change make recent pages less distinct or less faithful to the brand rules?

    Automated technical monitoring can surface indexing and performance problems as the site scales, but alerts still need family-level context. One broken field mapping can produce a content defect across many URLs; one conditional component can create a layout-performance problem only on pages where it appears.

    Define pause conditions before launch. Hold further publication when essential regional fields are empty, siblings converge on the same answer, multiple pages compete for the same intent, indexing problems cluster around one template, or technical defects repeat across the family. Diagnose the model, data, or rule first. Generating more URLs only multiplies the uncertainty.

    Key takeaways

    • Use programmatic SEO to serve many distinct needs, not to manufacture keyword permutations.
    • Expand from topical territory your domain can already support, using Search Console queries and landing pages as evidence.
    • Require a semantic delta: the entity-intent combination must change the answer, evidence, recommendation, or next action.
    • Store facts separately from prose, and render page components only when their required evidence exists.
    • Use AI as a constrained transformation layer governed by page promises, approved data, brand rules, and validation.
    • Connect pages through parent, comparison, support, and next-step relationships instead of indiscriminate cross-linking.
    • Launch by page family, monitor family-level patterns, and pause generation when a repeated defect appears.

    Take one candidate page family and complete the eligibility record by hand for its hub, a typical detail page, and its hardest edge case. If you can prove a distinct need, distinct evidence, and a distinct next step for each, you have the beginning of a scalable semantic system. If you cannot, consolidate the idea before a template turns the ambiguity into URLs.
    References

  • How to Give AI Agents Live Marketing Data Without Losing Control

    How to Give AI Agents Live Marketing Data Without Losing Control

    If your AI workflow begins with exporting campaign data, pasting it into a chat, and explaining the same business context again, you do not have an agent. You have a capable analyst waiting for a manual data delivery.

    The fix is not a longer prompt. You need a controlled path from your marketing systems to the agent, with enough current context to support a decision and enough guardrails to stop a bad decision from becoming an expensive action.

    Live means decision-ready, not merely connected

    Live marketing data does not have to mean that every event reaches the agent within milliseconds. It means the information is refreshed before the decision it supports becomes stale. A pacing decision may need current spend and budget data. A lead-quality decision may need the latest CRM disposition. A promotion may need inventory availability before the agent recommends sending more traffic to it.

    That distinction matters because access alone is not enough. An agent can be connected to Google Ads and still make a poor decision if it cannot see what happened after a conversion. It can be connected to a CRM and still misread performance if campaign identifiers do not match. It can see inventory data and still act on an item whose availability record is old.

    A familiar failure starts with a keyword that appears healthy inside the ad platform. It has useful volume and an acceptable cost per acquisition. The CRM, however, shows that the resulting leads are being disqualified. Without that downstream outcome, the agent will keep treating the keyword as successful and may continue spending until a person reconciles the systems. Repeated exports and delayed cross-checks preserve this blind spot; they do not create automation.

    SystemWhat the agent can learnDecision it can improve
    Ad platformSpend, conversions, volume, and campaign performanceWhere traffic appears efficient
    CRMQualification, sales progression, and lead dispositionWhether reported conversions have business value
    Inventory systemAvailability and stock constraintsWhether demand should be increased for a product

    Before integrating anything, write down the decision the agent will support and how fresh each input must be for that decision. If you cannot define when the data becomes too old to trust, the word live is doing no useful work.

    Build a decision context, not a giant data dump

    Raw marketing inputs pass through filtering and verification stages before a compact bundle of relevant context reaches an AI reasoning system.

    An agent rarely needs unrestricted access to every field in every marketing system. It needs a compact, reliable view of the variables that determine one decision. Sending more data without defining its meaning can make the workflow harder to inspect and easier to misconfigure.

    Build that view from the decision backward:

    1. Name the decision. Be precise: recommend a bid change, flag a lead-quality problem, pause promotion of unavailable inventory, or produce a daily exception list.
    2. List the evidence required. Separate platform metrics from business outcomes. A conversion count is not the same thing as a qualified lead, a sale, or an item that can still be fulfilled.
    3. Choose the join keys. Decide how campaign, ad group, keyword, click, lead, customer, product, and order records connect. If systems use different identifiers, define the mapping before the agent sees the data.
    4. Normalize time and meaning. Record the reporting window, timezone, attribution context, currency, and status definitions relevant to the decision. The agent should not have to infer whether two similarly named fields measure the same event.
    5. Attach provenance and freshness. Return the originating system and update time with the value. The agent needs to distinguish a current zero from a missing or stale record.
    6. Define conflict behavior. Decide which system controls when records disagree. If the CRM says a lead is disqualified while the ad platform counts a conversion, the workflow should preserve both facts and use the business outcome for the decision you defined.

    This turns integration into a data contract. Each input has a source, definition, identity, update time, and permitted use. That contract also gives your team something concrete to test when the agent behaves unexpectedly.

    Use MCP as the connection layer, not the policy

    The Model Context Protocol, or MCP, provides a standardized way for an AI client to connect to external tools and data sources. In a marketing workflow, an MCP implementation can expose ad performance, CRM outcomes, and inventory information through a consistent interface instead of forcing you to create a separate conversational integration for every system. This can remove much of the manual handoff that keeps an agent from working with current data.

    MCP does not decide what a qualified lead means, repair broken campaign identifiers, choose a safe budget policy, or determine whether the agent should be allowed to change a bid. It is the connection layer. Your data contract and control layer still carry the business logic.

    Expose narrow tools that correspond to real tasks. A useful initial tool set might let the agent read campaign performance, retrieve CRM dispositions, check product availability, and generate a recommendation. A later tool could execute a preapproved campaign rule. A generic tool with unrestricted account access is harder to audit and creates a much larger failure surface.

    The tool description should also tell the agent what the result does not prove. For example, ad-platform conversions describe recorded conversion events; they do not by themselves establish lead quality. Inventory availability can constrain promotion; it does not establish campaign profitability. Clear boundaries reduce the chance that the model treats one system’s partial view as the complete business outcome.

    Put enforceable guardrails between reasoning and action

    Proposed AI actions pass through layered permission, validation, spending-limit, audit, and human-approval controls before reaching marketing systems.

    Read access and write access are different risk decisions. A mistaken read may produce a bad recommendation. A mistaken write can change bids, pause campaigns, redirect spend, or promote stock that is not available. Do not grant unrestricted write access merely because the agent has produced sensible analysis in a chat window.

    A prompt is not a permission system. Instructions such as be careful or do not overspend can influence behavior, but they do not enforce account boundaries. Operational constraints need to sit around the agent, where the integration can reject an action that falls outside policy.

    Define every write-capable action with these controls:

    • Permission: Specify whether the agent can read, recommend, or execute. Default new workflows to read-only.
    • Scope: Restrict access to the relevant accounts, campaigns, markets, products, and action types.
    • Preconditions: Require the necessary data sources to be available and fresh before an action can run.
    • Policy limits: Encode the budget, bid, status, and inventory rules the action must satisfy. The surrounding system, not the model’s prose, should enforce them.
    • Approval: Route high-impact or ambiguous changes to a person. The agent should return the proposed action, supporting evidence, and reason for escalation.
    • Auditability: Record the inputs, tool calls, decision, approver when applicable, and resulting change.
    • Recovery: Preserve enough prior state to reverse a change when the platform and action type allow it.

    Roll out those permissions in stages. Begin with read-only analysis and verify that the agent retrieves the right records. Next, let it recommend actions while a person compares those recommendations with actual decisions. Then allow only bounded, reversible writes with enforced preconditions. Expand the scope after the data and control layers have proved reliable, not merely after the model has written persuasive explanations.

    Test the data path before judging the agent

    When an agent produces a questionable answer, teams often adjust the prompt first. That is useful only if the required evidence reached the model correctly. A polished prompt cannot recover a missing CRM record, an incorrect join, or inventory data that failed to refresh.

    Test the pipeline with cases that reveal those failures:

    • Freshness: Can you see when each source last updated, and does the workflow stop when a required input is stale?
    • Coverage: Are all in-scope campaigns, leads, products, and accounts represented, or does the connector silently omit some records?
    • Identity: Can a conversion be connected to the correct lead or order and then traced back to the responsible campaign entity?
    • Semantics: Do conversion, qualified lead, sale, availability, and revenue have explicit definitions in the systems that provide them?
    • Missing data: Does the agent distinguish no activity from unavailable data? Treating both as zero can trigger the wrong action.
    • Conflicts: What happens when two systems disagree? The workflow should surface the disagreement rather than silently choosing whichever value arrived first.
    • Failure mode: If the CRM or inventory service is unavailable, does the agent stop, fall back to recommendation-only mode, or request review? Continuing with partial context should be an explicit policy choice.

    Evaluate the system against the decision it was built to improve. For a lead-quality workflow, inspect whether it identifies campaigns producing disqualified leads. For an inventory-aware workflow, inspect whether it avoids recommending more demand for unavailable products. Fluent explanations are useful for review, but they are not evidence that the underlying joins and controls work.

    Key takeaways

    • Live data is data that arrives before the supported decision becomes stale; it is not simply data behind an API.
    • An agent needs business outcomes from systems such as the CRM and inventory platform, not only the conversion view inside an ad platform.
    • Start with one decision and build a defined data contract for its evidence, identifiers, timing, provenance, and conflict rules.
    • MCP can standardize how AI clients reach tools and data, but it does not replace data modeling, permissions, or business policy.
    • Keep new agents read-only until you have validated retrieval, joins, freshness, and failure behavior.
    • Enforce write limits outside the prompt, and log the evidence and action so a person can inspect what happened.

    Choose one recurring marketing decision that still depends on an export or spreadsheet reconciliation. Map the platform metric, downstream business outcome, join key, freshness requirement, and permitted action. That small, inspectable workflow is the right place to prove live data access before you give an agent broader reach.

    References

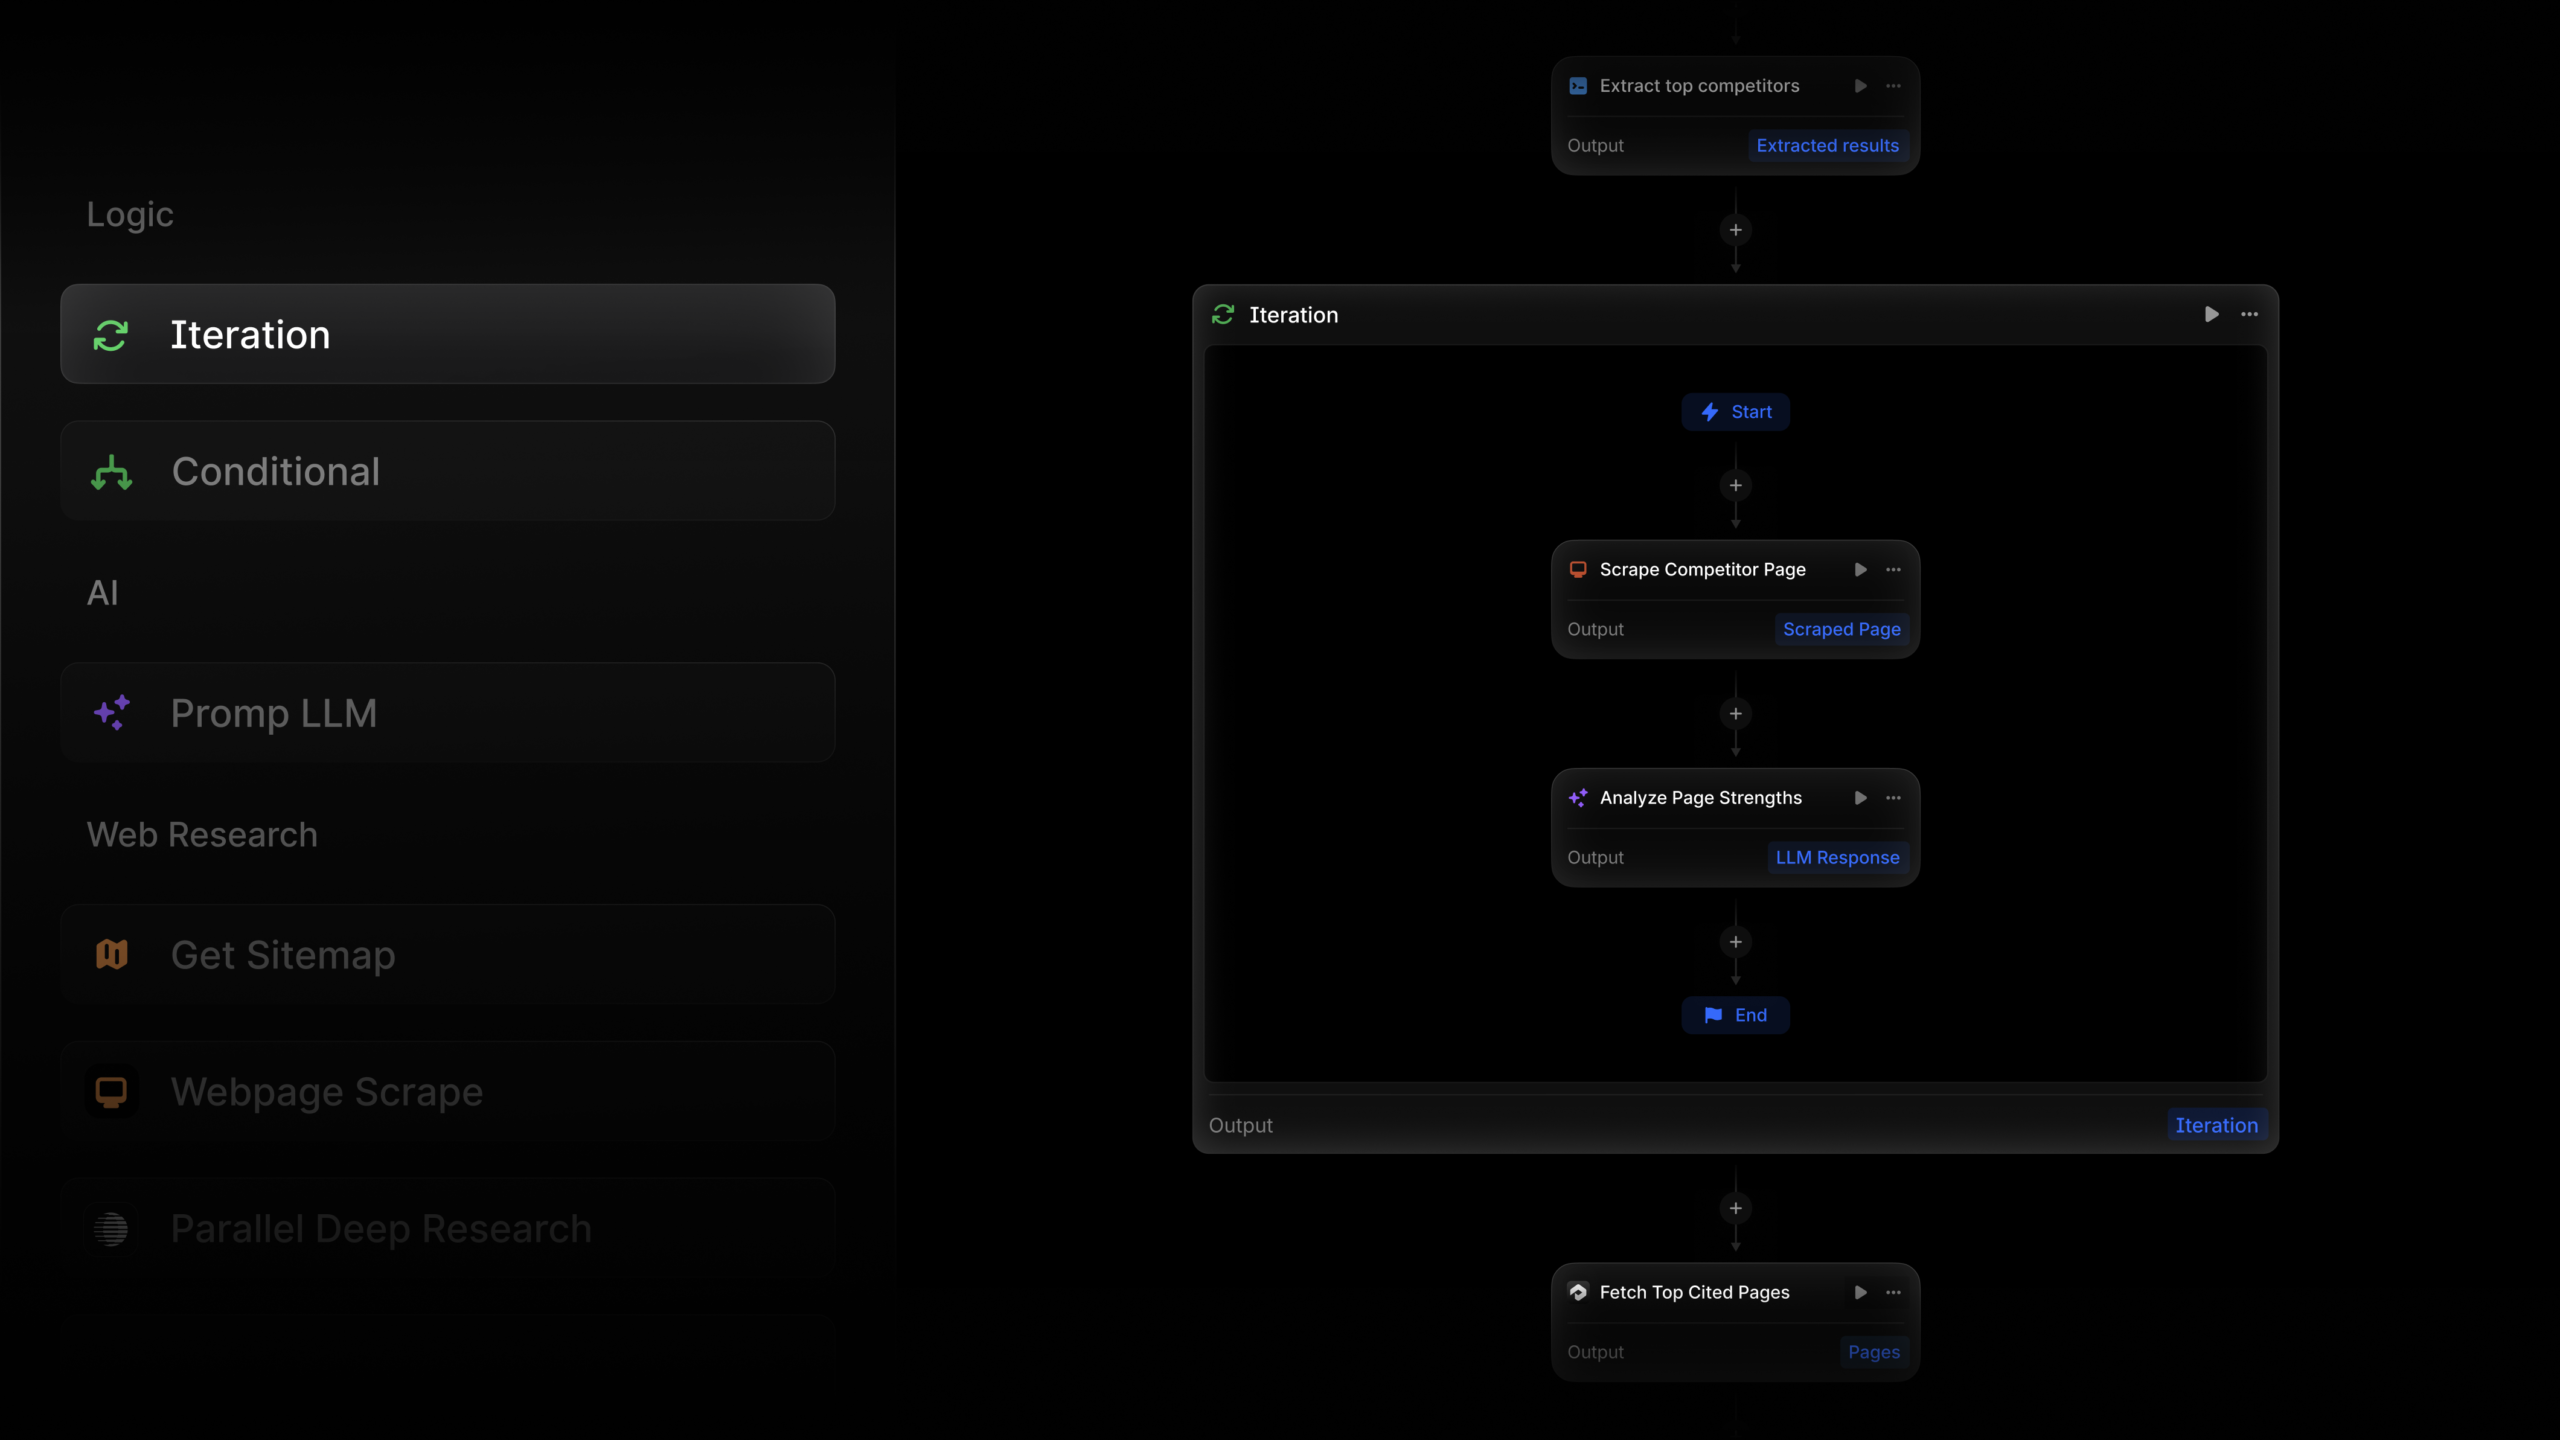
  • Unlock Efficiency with Iteration Nodes in Profound Agents

    Unlock Efficiency with Iteration Nodes in Profound Agents

    I’m excited to introduce you to the innovative iteration nodes in Profound Agents, designed to revolutionize the way we manage complex workflows.

    The beauty of the iteration node lies in its ability to encapsulate a series of steps within your Agent. By setting up these steps just once, I can easily pass in a list of items, and watch as each item seamlessly progresses through the specified sequence, simultaneously.


    Inspired by this post on Try Profound Blog.


    crushpress.ai community screenshot
  • Modern Marketing Analytics and Reporting That Drives Action

    Modern Marketing Analytics and Reporting That Drives Action

    Your dashboard is green, the meeting starts soon, and you still cannot answer the question that matters: what changed, why did it change, and what should the team do next?

    That is a reporting-system problem, not a chart problem. Modern marketing analytics should connect business outcomes to channel activity, preserve the definitions behind every metric, expose uncertainty, and deliver the next decision without forcing someone to reconstruct the analysis during the meeting.

    Start with the decision, not the available data

    Most bloated reports begin with a harmless question: what data can we pull? Every available metric gets added, the dashboard becomes comprehensive, and the decision it was meant to support disappears.

    Reverse the sequence. Before choosing a connector, chart, or reporting platform, write a one-sentence measurement brief:

    This report helps [owner] decide [action] at [cadence] by comparing [outcome] with [baseline], using [drivers] to explain the result and [guardrails] to prevent a bad trade-off.

    A paid media lead might need to reallocate campaign budget each week. A content lead might need to decide which topics deserve an update, expansion, or new format. An SEO lead might need to distinguish a visibility problem from a conversion problem. These decisions require different evidence even when they draw from the same underlying data.

    Assign every metric a role. If a metric has no role, remove it from the primary report.

    Metric roleQuestion it answersMarketing exampleHow it should affect action
    OutcomeDid the work produce the intended business result?Qualified conversions, pipeline, revenue, retained customersDetermines whether the strategy is working
    DriverWhat directly influenced the outcome?Qualified traffic, landing-page conversion rate, lead acceptanceIdentifies where to intervene
    DiagnosticWhere did performance change?Campaign, query group, page type, audience, device, videoNarrows the investigation
    GuardrailWhat must not deteriorate while the team optimizes?Acquisition cost, lead quality, unsubscribe rate, brand demandPrevents a local gain from becoming a business loss

    This hierarchy corrects a common reporting mistake. Impressions, views, clicks, and engagement can be useful drivers or diagnostics, but they do not automatically become business outcomes because they are easy to retrieve. Likewise, a channel-level return figure is not trustworthy unless the report states what counts as a conversion, which costs are included, and how credit is assigned.

    Record five items beside every primary outcome: its definition, owner, data system, update cadence, and attribution rule. If attribution is involved, also state the model, lookback window, reporting timezone, currency treatment, and whether the metric uses event time or processing time. There is no universally correct attribution model. There is only a model that is explicit enough to interpret and consistent enough to compare.

    Set action rules before looking at the latest result. The rule does not need an invented universal threshold. It can be operational: investigate when an outcome moves outside its expected range, when a guardrail worsens, when the data is stale, or when two systems no longer reconcile. Precommitting to the rule reduces the temptation to invent a convenient explanation after seeing the chart.

    Standardize the data before you visualize it

    Different shapes of marketing data pass through a modular processing system and emerge as standardized units for visualization.

    A polished dashboard cannot repair inconsistent definitions underneath it. If paid media uses platform-reported conversions, analytics uses attributed sessions, sales uses accepted opportunities, and finance uses recognized revenue, placing the figures on one page does not make them comparable.

    Create a small data contract for each reporting dataset. It should specify:

    • Grain: what one row represents, such as one campaign-day, page-query-day, video-day, lead, opportunity, or order.
    • Keys: the fields that uniquely identify a row and connect it to other datasets.
    • Dimensions: the controlled names for channel, campaign, market, device, content type, audience, and funnel stage.
    • Metric definitions: the exact event or business state counted by each field.
    • Time rules: timezone, date field, reporting window, and treatment of late-arriving records.
    • Freshness: when the data should be available and how the report signals a delayed refresh.
    • Ownership: who approves definition changes and who responds when a pipeline fails.
    • Lineage: where the data originated and which transformations changed it.

    Grain is the detail most likely to prevent a silent reporting error. Joining campaign-day costs to lead-level conversions can multiply spend when several leads share the same campaign and date. Aggregate both datasets to a compatible grain before joining them, or model the relationship so the cost appears only once. After every join, compare row counts and totals with the inputs.

    Separate period reporting from cohort reporting. A period view answers what happened during a selected date range. A cohort view follows people, accounts, campaigns, or content acquired in a particular period through later outcomes. A recent acquisition cohort may look weak simply because its conversions have not had time to mature. Label incomplete cohorts instead of presenting them as final.

    Run a compact quality checklist before publishing any result:

    • Reconcile source totals using the same date range, timezone, filters, and conversion definition.
    • Test whether fields declared unique are actually unique.
    • Check for missing dates, unexpected nulls, duplicate records, and values outside possible ranges.
    • Compare current dimensions with the approved taxonomy so renamed campaigns or channels do not create false categories.
    • Display the latest successful refresh time in the report itself.
    • Mark provisional data and document whether upstream systems can restate earlier periods.
    • Preserve raw extracts or reproducible snapshots so a changed connector does not rewrite history without explanation.

    Do not hide a reconciliation gap with a calculated adjustment. If two systems answer different questions, label the difference. If they should match and do not, hold the affected conclusion until you know why. A visible limitation is manageable; an invisible one becomes a decision error.

    Give dashboards, code, APIs, and AI separate jobs

    A modern reporting stack does not require one tool to extract, clean, model, visualize, explain, and distribute everything. It works better when each layer has a narrow responsibility:

    1. Source layer: advertising platforms, analytics products, CRM records, commerce systems, search data, video analytics, and approved research inputs.
    2. Ingestion layer: connectors, APIs, exports, or controlled uploads that retrieve data without changing its business meaning.
    3. Raw layer: immutable or reproducible copies of the retrieved records.
    4. Transformation layer: code or managed queries that clean names, join datasets, apply definitions, and create tested calculations.
    5. Semantic layer: approved dimensions, metrics, relationships, and attribution labels shared across reports.
    6. Presentation layer: dashboards, tables, charts, written analysis, and exported snapshots designed for a specific audience.
    7. Delivery layer: scheduled distribution, access controls, alerts, meeting workflows, and an archive of what stakeholders received.

    Dashboards are effective presentation surfaces when stakeholders need filters, recurring monitoring, and a shared view without access to every backend system. A Looker Studio report can, for example, connect YouTube Analytics data, support customized views, and distribute scheduled PDF snapshots. That makes it useful for a channel owner who needs repeatable visibility rather than a custom analysis every morning.

    Keep the dashboard when its data volume is manageable, the transformations are simple, refreshes complete reliably, and an analyst can trace a wrong number back to its origin. Move complex logic upstream when the same calculated field is copied across pages, manual updates recur, refreshes become fragile, or debugging requires a long sequence of interface clicks. Broad datasets and accumulated business logic can make a dashboard slow to change, difficult to debug, and vulnerable to dataset limits.

    Code is a better home for repeatable extraction, normalization, backfills, joins, tests, and calculations that need review. It gives you files that can be compared, versioned, and rerun. That does not mean every marketing team needs to replace every dashboard. A practical architecture keeps a familiar dashboard at the front while moving fragile transformations into a controlled pipeline behind it.

    APIs are retrieval mechanisms, not guarantees of completeness. For every API connection, record the account or property queried, requested fields, filters, pagination behavior, expected refresh schedule, and the response received when data is unavailable. Keep credentials outside report code, grant only the access required, and plan for permission revocation. A successful request proves that data arrived; reconciliation proves that the right data arrived.

    AI coding assistants can reduce the effort required to scaffold connectors, transformations, tests, and report components. Natural-language specifications can help tools such as Claude Code and OpenAI Codex assemble multistep reporting workflows. Treat the generated work as a draft implementation. Review the query grain, inspect joins, run tests, protect secrets, and compare outputs with authoritative systems before a generated number reaches a stakeholder.

    Use AI differently in the analysis layer. Ask it to identify anomalies worth investigating, draft plain-language explanations from approved metrics, or translate a validated analysis for different audiences. Do not let it infer causation from a correlated chart or invent a reason for a movement that the data cannot explain. The final narrative should distinguish among a measured fact, an analyst interpretation, and a proposed test.

    Design separate views for decisions, operations, and diagnosis

    Three connected analytics workspaces show separate areas for executive decisions, operational monitoring, and detailed diagnosis.

    One dashboard should not try to answer every question for every person. An executive wants to know whether the business outcome changed and whether intervention is needed. A channel operator needs enough detail to choose the intervention. An analyst needs access to definitions, segments, and reconciliation evidence.

    Build three layers, even if they live in the same reporting product:

    • Decision view: the primary outcome, comparison period or baseline, guardrails, material changes, confidence limits, and the requested decision.
    • Operating view: the drivers a channel owner can change, organized by campaign, content group, market, audience, or other actionable unit.
    • Diagnostic view: deeper segments, data-quality checks, metric definitions, lineage, and enough detail to reproduce the conclusion.

    Put context next to the metric it qualifies. A global note at the bottom of a long report will not protect a chart at the top from misinterpretation. Each primary view should show its date range, comparison basis, filters, timezone, attribution label, refresh timestamp, and any material gap in coverage.

    Add a short narrative block to every decision view:

    • Result: what changed in the outcome.
    • Driver: which measured movement best explains the change.
    • Confidence: what is known, what remains uncertain, and whether the data is complete.
    • Action: the decision or test now recommended.
    • Ownership: who will act and when the result will be reviewed.

    Be strict about causal language. If a campaign change and a conversion change occurred together, say they coincided unless the measurement design supports a stronger claim. If an experiment or another credible identification method isolates the effect, explain that method. Precision in the wording is part of analytics quality.

    Annotations should capture business events that a chart cannot know: a campaign launch, budget change, tracking migration, site release, promotion, pricing change, consent update, or outage. Store the event date, owner, affected scope, and a brief description. An annotation is a lead for investigation, not automatic proof that the event caused the movement.

    Distribution needs the same discipline as analysis. A scheduled PDF is a fixed snapshot, so include its reporting window and data cutoff. Link it to the interactive view when recipients may need filters or diagnostics. Archive material snapshots used for recurring business decisions; otherwise a later refresh can leave the team debating a number that no longer appears on screen.

    Access is part of report design. Stakeholders should not need administrative access to every marketing platform simply to read an approved result. The reporting team, however, must document which account and permission power each connection. With YouTube Analytics, a report builder who does not own the channel may need Manager permission and the Channel ID entered through the connector’s advanced settings. Test delegated access with the actual reporting identity instead of assuming that a visible channel in YouTube Studio will automatically appear in the reporting connector.

    Migrate one recurring report and operate it like a product

    A wholesale reporting rebuild creates too many simultaneous unknowns. Start with one recurring workflow that consumes meaningful time, has a known audience, and regularly produces a decision. A pre-meeting channel report, weekly SEO performance brief, or campaign pacing view is a better migration candidate than an enterprise-wide measurement platform.

    1. Freeze the current output. Save the existing report, its filters, definitions, recipients, delivery timing, and a few representative reporting periods. This becomes your comparison set.
    2. Write the decision contract. Identify the decision, owner, cadence, outcome, drivers, guardrails, and action rules. Remove fields that do not support them.
    3. Inventory data and permissions. Record every account, property, channel, connector, export, credential owner, and approval dependency. Confirm access using the service identity that will run the production workflow.
    4. Build reproducible ingestion. Preserve raw data, log retrieval times, handle pagination and empty responses, and make reruns safe.
    5. Encode transformations once. Normalize taxonomies, define joins, centralize calculations, and add tests for uniqueness, completeness, freshness, and reconciliation.
    6. Rebuild the three reporting views. Keep the decision page concise, give operators actionable detail, and retain diagnostic evidence for analysts.
    7. Run old and new systems in parallel. Investigate differences using matched definitions, filters, and time rules. Do not retire the old workflow until material discrepancies are explained and the team has a rollback path.
    8. Document production ownership. Assign responsibility for data failures, definition changes, access reviews, report delivery, and stakeholder questions.

    The parallel run matters because two reports can display plausible but different numbers. A discrepancy may come from timezone boundaries, attribution logic, late-arriving conversions, deduplication, renamed dimensions, incomplete pagination, or a genuine bug. Matching the old number is not always the goal if the old logic was wrong, but every difference should have an explanation.

    Give the finished workflow a runbook. It should tell another qualified person how to trigger a refresh, locate logs, rerun a failed period, backfill data, rotate credentials, verify source totals, publish the output, and roll back a breaking change. Include the last known successful run and the owner of each upstream dependency.

    Measure the reporting system itself. Track whether scheduled runs complete, whether data meets its freshness expectation, whether reconciliation tests pass, whether recipients receive the right artifact, and whether decisions and owners are captured. The point is not to create a dashboard about dashboards. It is to notice reliability problems before they become meeting problems.

    Key takeaways

    • Define the decision, owner, cadence, outcome, drivers, guardrails, and action rule before selecting metrics.
    • Standardize grain, keys, definitions, time rules, freshness, ownership, and lineage before building charts.
    • Keep dashboards for accessible presentation; move repeatable extraction, complex transformations, tests, and backfills into code when interface logic becomes fragile.
    • Use AI to accelerate implementation and explanation, but validate grain, joins, permissions, calculations, and source reconciliation before publication.
    • Separate decision, operating, and diagnostic views so each audience gets enough detail without inheriting everyone else’s dashboard.
    • Migrate one recurring workflow, run it beside the existing report, explain every material discrepancy, and preserve a rollback path.

    Choose the recurring report that causes the most avoidable pre-meeting work. Write its decision contract, mark every metric as an outcome, driver, diagnostic, or guardrail, and remove anything that serves no decision. That small redesign will show you exactly where the next improvement belongs: the definition, the data pipeline, the analysis, or the delivery.

    References


  • How to Reuse Digital PR Pitches Without Sounding Recycled

    How to Reuse Digital PR Pitches Without Sounding Recycled

    Your last successful pitch should not disappear into a sent folder after the coverage lands. It contains a useful asset: a sequence of editorial decisions that persuaded a particular journalist to keep reading, understand the news value, and respond.

    The mistake is to copy that email and swap a few nouns. That preserves the most disposable part of the pitch while carrying stale claims, irrelevant personalization, and familiar phrasing into a new campaign. Effective pitch reuse works at a deeper level. You preserve the reasoning structure, replace every campaign-specific input, and make the new email earn its relevance on its own.

    Reuse the decision path, not the surface copy

    A reusable pitch is a framework for making decisions. It tells you what the subject line must accomplish, how the opening establishes relevance, where the strongest evidence appears, how the facts build an angle, and what the call to action offers the journalist’s audience.

    That distinction matters because almost half of journalists receive six or more pitches a day. When attention is already scarce, faster production isn’t much of an advantage. A pitch still has to be relevant, credible, and easy to evaluate.

    Reuse the parts that govern clarity. Rebuild the parts that determine whether this campaign belongs in this journalist’s inbox.

    Pitch layerWhat you can preserveWhat you must rebuild
    Subject lineThe type of promise, level of specificity, and relationship to the readerThe claim, consequence, wording, and any reference to the recipient
    OpeningThe function it performs, such as establishing editorial relevance before presenting the campaignThe observation, context, and reason this journalist is a fit
    AngleThe logical progression from finding to consequenceThe actual news, audience implication, and timing
    EvidenceThe order in which proof becomes usefulEvery fact, figure, comparison, method note, and supporting asset
    Call to actionA low-friction decision focused on editorial valueThe deliverable, access, expert, visual, dataset, or next step being offered

    Personalization deserves particular care. You can reuse the principle that the opening should feel written for one recipient. You cannot reuse the personal detail itself. A reference to someone’s interests, work, or public comments should be accurate, current, proportionate, and connected to the pitch. If the detail has no editorial purpose, it can feel ornamental or intrusive rather than thoughtful.

    The same rule applies to tone. Preserve your recognizable voice, but don’t preserve sentences simply because they once worked. Voice is a set of choices about directness, rhythm, detail, and restraint. Copy is the temporary expression of those choices.

    Extract the reusable pattern from a proven pitch

    A blank pitch page is separated into symbolic modules for news value, evidence, relevance, and a next step on a worktable.

    A reply or placement tells you that the whole combination worked in one situation. It doesn’t prove that the subject line, personal opening, evidence order, or call to action caused the result by itself. The story’s strength, the journalist’s schedule, an existing relationship, and timing may also have mattered.

    Treat the first extraction as a hypothesis, not a universal template. Your job is to identify the likely functions inside the pitch and then see whether those functions remain useful in another campaign.

    1. Save the complete context. Keep the final subject line and body alongside the campaign brief, recipient, outlet, send timing, supporting materials, response, and eventual outcome. A winning email without its context is easy to misread.
    2. Label each unit by its job. Mark the subject line, relevance cue, transition, central claim, proof sequence, reader consequence, asset offer, and call to action. A sentence may perform more than one job, but every sentence should have one clear primary purpose.
    3. Separate structure from content. Replace names, topics, findings, figures, links, and personal details with functional placeholders. If the remaining framework still makes sense, you have found something reusable.
    4. Explain why the order worked. Don’t record only that evidence appeared before the ask. Record why: the recipient needed enough proof to assess the claim before deciding whether the supporting asset was worth opening.
    5. Mark uncertain elements. If you don’t know whether the rapport-building opening contributed to the response, say so in the template notes. This prevents a guess from hardening into a team rule.
    6. Test the pattern in a different context. Keep it provisional until it helps produce a clear, relevant pitch for another campaign. If the structure survives while the topic, evidence, and recipient change, it is more likely to be genuinely reusable.

    The resulting blueprint might look like this:

    • Subject: Express the audience consequence and the fresh evidence or asset behind it.
    • Opening: Establish a truthful reason the journalist may care.
    • Bridge: Move from that relevance cue to the campaign without forcing the connection.
    • News: State the central finding or announcement in plain language.
    • Proof sequence: Lead with the strongest verified evidence, then add only the context needed to interpret it.
    • Reader value: Explain what the finding helps the publication’s audience understand, decide, or notice.
    • Offer: Name the useful material available, such as methodology, visuals, underlying data, an expert, or a product demonstration.
    • Call to action: Ask whether that specific material would help with a relevant story.

    This is more useful than a fill-in-the-blank email. It preserves editorial logic without encouraging the sender to treat a journalist’s name as the only variable.

    Use AI as a constrained adapter

    AI is well suited to mapping sentence functions, proposing alternative phrasing, and adapting a proven sequence to a new brief. It is poorly suited to deciding what is true, whether a personal reference is appropriate, or whether the angle genuinely fits a journalist. Those decisions need verified inputs and human judgment.

    Give the model a controlled packet rather than asking it to write a pitch from the campaign name alone. That packet should contain the approved campaign brief, verified fact sheet, methodology notes where relevant, available assets, audience definition, house-voice constraints, and a short recipient profile based on public professional information. Clearly distinguish confirmed facts from working ideas.

    Reusable prompt: Analyze the successful pitch below by sentence function, not by wording. Create a structural map that explains the purpose of each part. Then adapt that structure to the new campaign brief and recipient profile. Use only facts supplied in the verified fact sheet. Do not carry over names, claims, figures, personal details, examples, or distinctive phrases from the successful pitch. If the new material cannot support a structural element, mark it as [NEEDS INPUT] instead of inventing content. Return the structural map, a concise draft, alternative subject lines, a substitution ledger showing which supplied input supports each factual statement, and a list of relevance or accuracy risks for human review.

    The substitution ledger is the important part. It turns review from a vague question about whether the email sounds good into a traceable check: where did this claim come from, is it approved, and does it mean what the draft says it means?

    Keep generation and personalization separate. First ask AI to build the cleanest version of the campaign argument. Then add recipient-specific context after checking the journalist’s current beat and work. This makes it easier to remove generic flattery and prevents an attractive personal hook from concealing a weak editorial match.

    Before keeping a personalized opening, apply a simple relevance gate:

    • Is the detail accurate and drawn from public professional context?
    • Does it explain why this campaign may suit the journalist’s coverage?
    • Can you connect it to the news without an abrupt or artificial transition?
    • Would you be comfortable explaining why you used it if the recipient asked?
    • Could the same sentence be sent unchanged to a large list? If so, it is probably generic rather than personal.

    AI can also help challenge the blueprint. Ask it to identify sections that depend on the old campaign, places where the logic no longer holds, and phrases likely to sound mass-produced. The goal isn’t to force every new pitch through the old shape. It is to notice when the proven structure helps and when the new story needs a different route.

    Review reused pitches at the fact, recipient, and system levels

    A blank pitch document passes through three inspection stations for evidence, recipient fit, and outreach-system checks.

    A polished draft can still fail in three different ways: it can misstate the campaign, mismatch the recipient, or reveal that your template is spreading stale language across the outreach program. Review each level separately.

    Check the campaign truth

    • Trace every factual statement to an approved input.
    • Confirm that figures retain their original denominator, comparison, scope, and qualification.
    • Make sure the headline claim is supported by the methodology, not merely adjacent to it.
    • Verify that every offered asset, interview, dataset, image, demonstration, or sample is actually available.
    • Remove claims inherited from the old pitch, including subtle carryovers such as timing language or audience assumptions.

    Check the recipient fit

    • Confirm that the journalist covers the subject at the level your angle requires.
    • Read the opening without the recipient’s name. If it now sounds universal, it hasn’t established real relevance.
    • Check that the evidence supports a story for this publication’s audience, not merely a message your organization wants repeated.
    • Make the call to action answerable. Offer a specific editorial resource instead of asking vaguely whether the recipient is interested.
    • Delete rapport-building language that delays the news or relies on a strained connection.

    Check the reuse system

    • Compare the new draft with the successful original and other pitches created from the same blueprint. Shared logic may be intentional; shared distinctive wording usually isn’t.
    • Store the blueprint separately from campaign facts so old evidence cannot be mistaken for reusable copy.
    • Record which structural elements were kept, changed, or removed and why.
    • Track replies, requests for supporting material, declines, placements, and no response without treating any single outcome as conclusive.
    • Revise the blueprint when the same friction appears repeatedly, such as unanswered calls to action or requests for context that should have been supplied initially.

    A good pitch library therefore contains more than examples labeled successful. It contains versioned patterns, the situations in which they were used, the evidence available at the time, and notes about what remains uncertain. That context is what allows a team to learn instead of merely imitate.

    It also protects your voice. If different team members can see the reasoning behind a pitch, they don’t need to mimic one person’s sentences. They can make the same kind of editorial choices in language that suits the new campaign.

    Key takeaways

    • Reuse a successful pitch’s decision structure, not its campaign-specific copy.
    • Preserve functions such as relevance, evidence order, reader consequence, and a low-friction call to action.
    • Replace every claim, figure, personal detail, example, link, and distinctive phrase.
    • Treat one successful send as a useful hypothesis, not proof that every element caused the result.
    • Give AI verified inputs, explicit no-invention rules, and a requirement to flag missing information.
    • Review the output for factual support, recipient fit, and accidental duplication across campaigns.
    • Keep outcome context with each blueprint so your reuse system improves as more pitches are sent.

    Before your next campaign, open the last pitch that earned a meaningful response and replace its sentences with labels describing what each one did. Save that map beside the original, then build the new outreach from verified inputs. You will start with something your team has learned from without making the recipient feel that they have seen it before.

    References


  • Google Ads Security and Conversion Infrastructure Runbook

    Google Ads Security and Conversion Infrastructure Runbook

    Your Google Ads stack can fail in two opposite ways: access becomes too loose to trust, or security controls become so brittle that the people and automations responsible for measurement are locked out. Meanwhile, a conversion tag can deploy cleanly and still measure the wrong action.

    The practical goal is not merely to enable multi-factor authentication or create a Google Tag Manager tag. You need a traceable path from an authorized identity to a tested conversion event, with an owner and a recovery route at every handoff. This runbook shows you how to build that path without turning an access change or tagging shortcut into a campaign outage.

    Key takeaways

    • MFA enforcement matters most when someone creates a new OAuth 2.0 refresh token. An integration that works now can still fail during reconnection, onboarding, or credential replacement.
    • Service accounts remain the better fit for supported automated or offline workflows, but they still need explicit ownership, limited access, and a tested handoff process.
    • A pre-filled Google Tag Manager configuration can remove transcription work. It cannot decide whether you selected the right container, conversion action, trigger, or counting logic.
    • Never revoke a working credential or remove a working conversion tag until its replacement has passed a controlled test. Otherwise, your rollback path disappears at the moment you need it.
    • Security and measurement should share one release record: identity owner, authentication method, Ads account, conversion action, GTM container, test evidence, publisher, and rollback decision.

    Map authentication before MFA exposes a hidden dependency

    A cutaway security system shows human, automated, and recovery access routes converging on one gateway, with one route blocked and a backup route remaining open.

    Google’s announced rollout made MFA mandatory for new user-based Google Ads API authentication from April 21, with enforcement expanding over the following weeks. The important boundary is token creation: OAuth 2.0 refresh tokens that were already in use were not invalidated by the change, but fresh authentication requires the additional identity check.

    That boundary explains why an account can look healthy until a routine maintenance task causes a failure. A scheduled process may continue using its existing refresh token, while a new employee, replacement integration, revoked credential, or reconnection attempt reaches the MFA gate. Passing today’s automated run is therefore not proof that your recovery workflow is ready.

    Start with an authentication inventory. Do not begin by changing credentials. For every connection that can read from or act on a Google Ads account, record:

    • Workflow: the API job, reporting transfer, desktop tool, script, dashboard, or application that depends on access.
    • Authentication pattern: user-based OAuth or a service account.
    • Named owner: the person responsible for approving access, completing MFA, and handling recovery.
    • Operational owner: the person who can prove the workflow still runs correctly after an authentication change.
    • Credential event: what would force a new authorization flow, such as onboarding a user, replacing a connection, or rebuilding an integration.
    • Recovery route: who can restore access if the primary owner is unavailable, without sharing a personal password or MFA prompt.
    • Evidence: the last successful controlled authentication and the workflow result it enabled.

    For user authentication, make the MFA rehearsal realistic. Use the same consent and token-generation path that the production workflow expects. Confirm that the designated person can complete the second factor, which may be a phone prompt or an authenticator app. Then verify that the resulting credential reaches the intended account and supports the intended workflow. A successful Google sign-in alone is not enough.

    Choose user authentication or a service account deliberately

    Keep user-based OAuth when the workflow is genuinely tied to a person’s authorization and an interactive sign-in is acceptable. Use a service account for a supported automated or offline workload when the connection should survive staff changes and should not depend on a person responding to an MFA prompt. Google left service-account workflows outside the new MFA requirement and recommends them for automated or offline scenarios.

    Do not migrate to a service account merely to avoid MFA. A service account is a machine identity, not an exemption from governance. Confirm that the application supports it, grant only the access the workflow needs, document who owns that identity, and test what happens when its permissions or connection must be replaced.

    Expand the inventory beyond custom API code. The same security change reaches authentication used by Google Ads Editor, Scripts, BigQuery Data Transfer, and Data Studio. If those tools are owned by different teams, give one person responsibility for the complete dependency map. Otherwise, each team may believe another team owns the failing sign-in.

    Most importantly, do not revoke the working refresh token while you are only testing its replacement. Prove the new path first, record the result, and then retire the old credential through a reviewed change. Revoking first can stop reporting or automation without leaving you a quick way back.

    Use direct GTM setup to remove copying, not judgment

    Google Ads has tested a Set up in Google Tag Manager option inside the conversion setup flow. Where the option is available, you can select a GTM container and open a suggested, pre-filled tag configuration instead of manually carrying the conversion ID and label between products.

    Treat this as a safer handoff, not an automatic implementation. It reduces opportunities for transcription errors, but it does not know whether your chosen website action represents a qualified lead, a completed sale, an internal test, or an accidental page view. It also cannot resolve a poor container naming convention or decide whether an existing tag will overlap with the new one.

    The integration is described as a test, so do not make a launch deadline depend on the button appearing in your account. If it is absent, continue with the established manual setup and apply the same review process. Availability and implementation correctness are separate questions.

    1. Confirm the conversion definition. Write down the user action that should count, where it occurs, and what must not count. Do this before opening GTM.
    2. Match the account and container. Verify the Google Ads account, conversion action, website, GTM account, and container as one set. Similar client or environment names are not proof of a match.
    3. Inspect the pre-filled values. Check the conversion ID and label against the intended conversion action even when Google populated them. Automation should reduce copying, not eliminate review.
    4. Review the trigger separately. The tag configuration identifies where data should go; the trigger determines when it goes there. Confirm that the trigger represents the business event you defined in the first step.
    5. Check for an existing implementation. Search the container for tags and triggers that already send the same action. Publishing a second path may produce duplicate events or conflicting behavior.
    6. Test before publishing. Use GTM’s preview process and complete a controlled conversion path. Confirm that the tag fires on the intended action and remains silent on nearby actions that should not count.
    7. Publish a traceable version. Record the conversion action, reason for the change, reviewer, test performed, and rollback instruction in the version description or release record.
    8. Verify both ends. Confirm the expected firing behavior in GTM and then confirm that Google Ads recognizes the intended conversion setup. A passing browser-side test proves the trigger ran; it does not by itself prove that the account mapping is correct.

    Avoid deleting the old tag before the new configuration has been verified. At the same time, do not publish two equivalent live paths and hope to compare them later. Modify the existing implementation when that is the cleanest route, or make the old and new triggers mutually controlled during the release. Your rollback should restore a known configuration, not create a second unknown one.

    Operate access and tagging as one controlled release

    Two specialists approve access and inspect a digital event as it passes through secure testing, monitored release, and rollback stages.

    Authentication and conversion tracking are often assigned to different specialists, but they meet at the same operational boundary. The person publishing a tag needs reliable account access. The automation consuming conversion data needs a stable identity. The campaign owner needs confidence that the event still means what its name claims.

    Use one release record for both sides. In a larger team, assign an access owner, GTM implementer, independent reviewer, and business owner for the conversion definition. In a smaller team, one person may hold several roles, but the checkpoints should remain separate. Pause between configuring, reviewing, publishing, and validating so that familiarity does not replace evidence.

    1. Freeze unrelated changes. Keep other credential, container, and conversion-action edits out of the same release so a failure has a narrow set of possible causes.
    2. Capture the known-good state. Record which automation currently succeeds, which tag and trigger currently fire, and which conversion action they serve.
    3. Prove recovery access. Confirm that the named owner can complete a fresh user-authentication flow with MFA, or that the supported service-account workflow can be restored by its documented owner.
    4. Stage the measurement change. Build or review the pre-filled GTM configuration without publishing it. Confirm the account, action, ID, label, trigger, and duplication check.
    5. Run the controlled path. Exercise the actual conversion behavior and preserve enough evidence for another person to understand what was tested.
    6. Publish and validate. Confirm the container version, the live firing conditions, the Google Ads destination, and the next successful dependent automation run.
    7. Retire only what has been replaced. Revoke an old credential or remove an old tag only after the new path is proven and the rollback decision is documented.

    Use the failure layer to choose your first check

    When something breaks, identify whether the failure occurs at identity, authorization, container configuration, trigger logic, publishing, or destination mapping. Rolling back everything at once can hide the actual defect.

    SymptomLikely layerFirst check
    An existing API job runs, but a new connection cannot generate a refresh tokenUser authentication and MFARepeat the fresh consent flow with the named owner and confirm that the second factor can be completed.
    A connection succeeds for one person but cannot be recovered by the teamOwnership and recoveryCheck whether the workflow depends on one personal identity and whether a supported service-account pattern is more appropriate.
    Editor, Scripts, a transfer, or a dashboard fails during sign-inShared authentication policyIdentify the actual Google identity behind the tool instead of treating it as an isolated application error.
    The direct GTM option does not appearFeature availabilityUse the manual tag setup rather than delaying the release; the integration is being tested and may not be available in every flow.
    The tag does not fire during previewContainer or trigger logicConfirm the selected container, preview environment, trigger conditions, and exact user action.
    The tag fires, but it points to the wrong conversion actionDestination mappingCompare the conversion ID and label with the intended Google Ads action and account.
    More than one tag fires for a single intended actionDuplicate implementationSearch for older tags, overlapping triggers, and parallel containers before changing the conversion definition.
    The browser-side test passes, but the dependent automation failsAPI authorization or workflow logicTest the automation separately with its own identity and permissions; the GTM test does not validate API access.

    At your next planned change window, exercise one fresh authentication flow and trace one controlled conversion from the user action through GTM to the intended Google Ads action. If either path lacks a named owner, test evidence, or a safe rollback, fix that gap before you scale the campaign or add another integration. Your infrastructure is ready when another authorized person can understand it, test it, and recover it without guessing.

    References


  • How to Align Ad Tools, Formats, and Conversion Tracking

    How to Align Ad Tools, Formats, and Conversion Tracking

    Your campaign can be configured correctly inside every advertising platform and still produce a measurement mess. The ad attracts an interaction, the tag records an event, analytics classifies it differently, and the bidding system optimizes toward something nobody intended.

    The fix is not another dashboard or another tag. You need one traceable chain from the format a person sees to the business outcome you want, with a clear role and a test at every handoff.

    Key takeaways

    • Define each conversion in business terms before configuring it in Google, Meta, Google Tag Manager, or an analytics property.
    • Give ad formats, tagging, measurement, and automation separate jobs and separate acceptance tests.
    • Treat every new ad format as a new measurement surface, especially when one unit presents several locations or choices.
    • Reuse an established data layer through official platform templates where supported, but verify mappings and duplicate events before publishing.
    • Do not increase spend until you can trace one test action from the page or app through the tag, platform, report, and optimization setting.

    Build one conversion contract before touching platform settings

    Five symbolic tiles for an ad, user action, event, analytics step, and business outcome connect in a tested sequence on a tabletop.

    Advertising platforms encourage you to start with their menus: choose an objective, install a tag, select an event, and launch. That sequence is convenient, but it lets each platform define your measurement model. The same customer action can then become a primary conversion in one account, a secondary event in another, and an analytics event with a third meaning.

    Start with a conversion contract instead. This is a short specification for what happened, why it matters, and how every system should represent it. For each event, record:

    <!– wp:list {
  • Google Ads AI Video: A Practical Workflow for Better Creative

    Google Ads AI Video: A Practical Workflow for Better Creative

    If your Google Ads account has plenty of product images but little usable video, Veo gives you a practical way to close that gap. You can turn existing visual assets into short YouTube ads without waiting for a conventional production cycle.

    The useful question isn’t whether AI can make a video. It can. The question is whether you can give it the right inputs, catch the wrong outputs, and measure the result without confusing generated creative with video your team produced. This workflow covers all three.

    What Veo changes inside Google Ads

    Veo reduces the smallest viable video project. Inside Google Ads Asset Studio, you can upload as many as three static images and generate a video of up to 10 seconds. The model adds motion, and customizable templates help turn the result into an ad suitable for YouTube.

    That is a meaningful capability, but it is a narrow one. Veo is well suited to a concise product demonstration, a visual benefit, or a single promotional idea. A 10-second output is not a substitute for a customer story, a detailed explanation, or a campaign concept that depends on dialogue and multiple narrative beats.

    Treat the tool as a creative multiplier, not a strategy generator. It can add movement to an idea you have already clarified. It cannot decide which customer problem matters, which claim is credible, or what the viewer should do next.

    The accompanying Nano Banana integration expands the editing layer. You can change backgrounds, adjust text, and tailor creative for different audience interests. That makes iteration faster, but each edit still needs the same brand, product, and claim review you would apply to work from a designer.

    Choose images that give the model a clear job

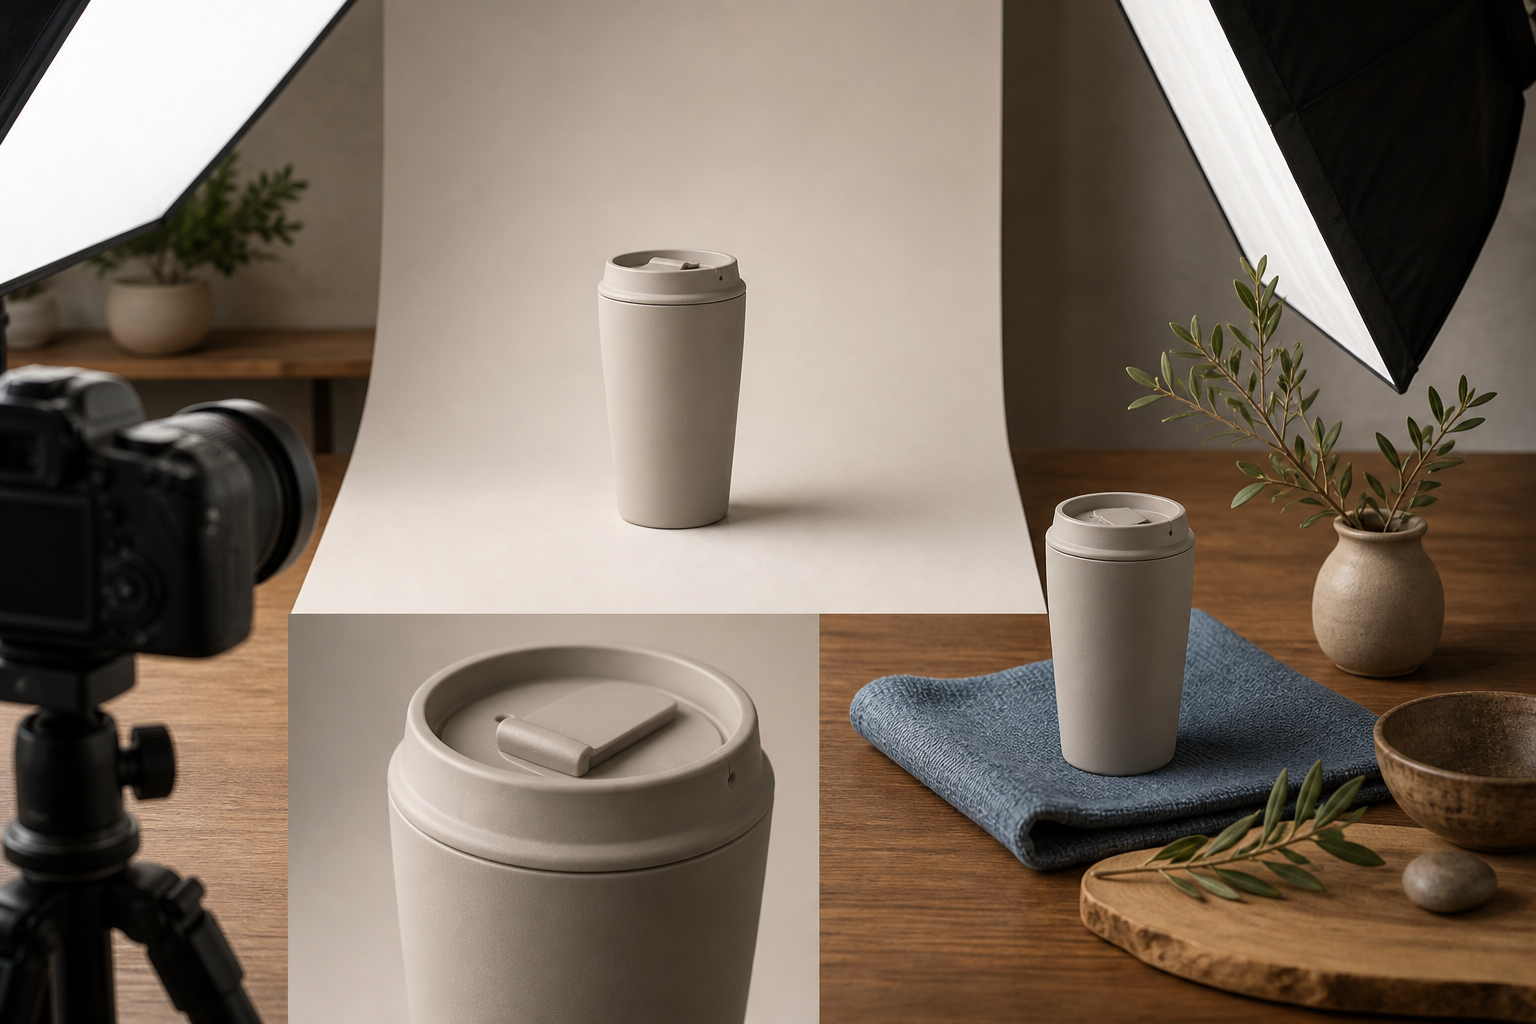
    An unbranded travel cup is photographed from multiple angles in a tabletop studio with a camera and soft lighting.

    The quality of the source images determines how much ambiguity the model must resolve. A clean product shot with an obvious foreground, stable proportions, and a plausible type of movement gives it a constrained problem. A dense collage with several focal points, embedded copy, and conflicting perspectives gives it several problems at once.

    Before uploading anything, score each candidate image against these criteria:

    • One unmistakable subject: A viewer should know what the ad is about without studying the frame.
    • Clear separation: The product, person, or focal object should be visually distinct from the background.
    • Plausible movement: You should be able to describe what could move in one sentence, such as a package rotating, fabric flowing, or a camera pushing toward a product.
    • Consistent product details: Packaging, colors, proportions, and visible features should agree across the images.
    • Minimal baked-in text: Important copy is easier to inspect and revise when it is handled as an ad element instead of being embedded in a busy image.
    • Enough visual space: Leave room for template copy, branding, or a call to action without covering the subject.
    • Accurate context: The setting must not imply a use, feature, size, or outcome the product cannot support.

    Do not upload three images merely because three are allowed. Every image should have a role. One might establish the product, another might show the relevant detail, and a third might place it in context. If two images contradict each other or compete for attention, use the stronger one and remove the ambiguity.

    Clean consumer-product imagery is a particularly sensible starting point. Early testing shared by Ameet Khabra indicated that brands with clean images and an obvious logic for movement may benefit most. That is an early practitioner observation, not a universal performance rule, so use it to select an initial test rather than to predict a result.

    Build a repeatable generation and review workflow

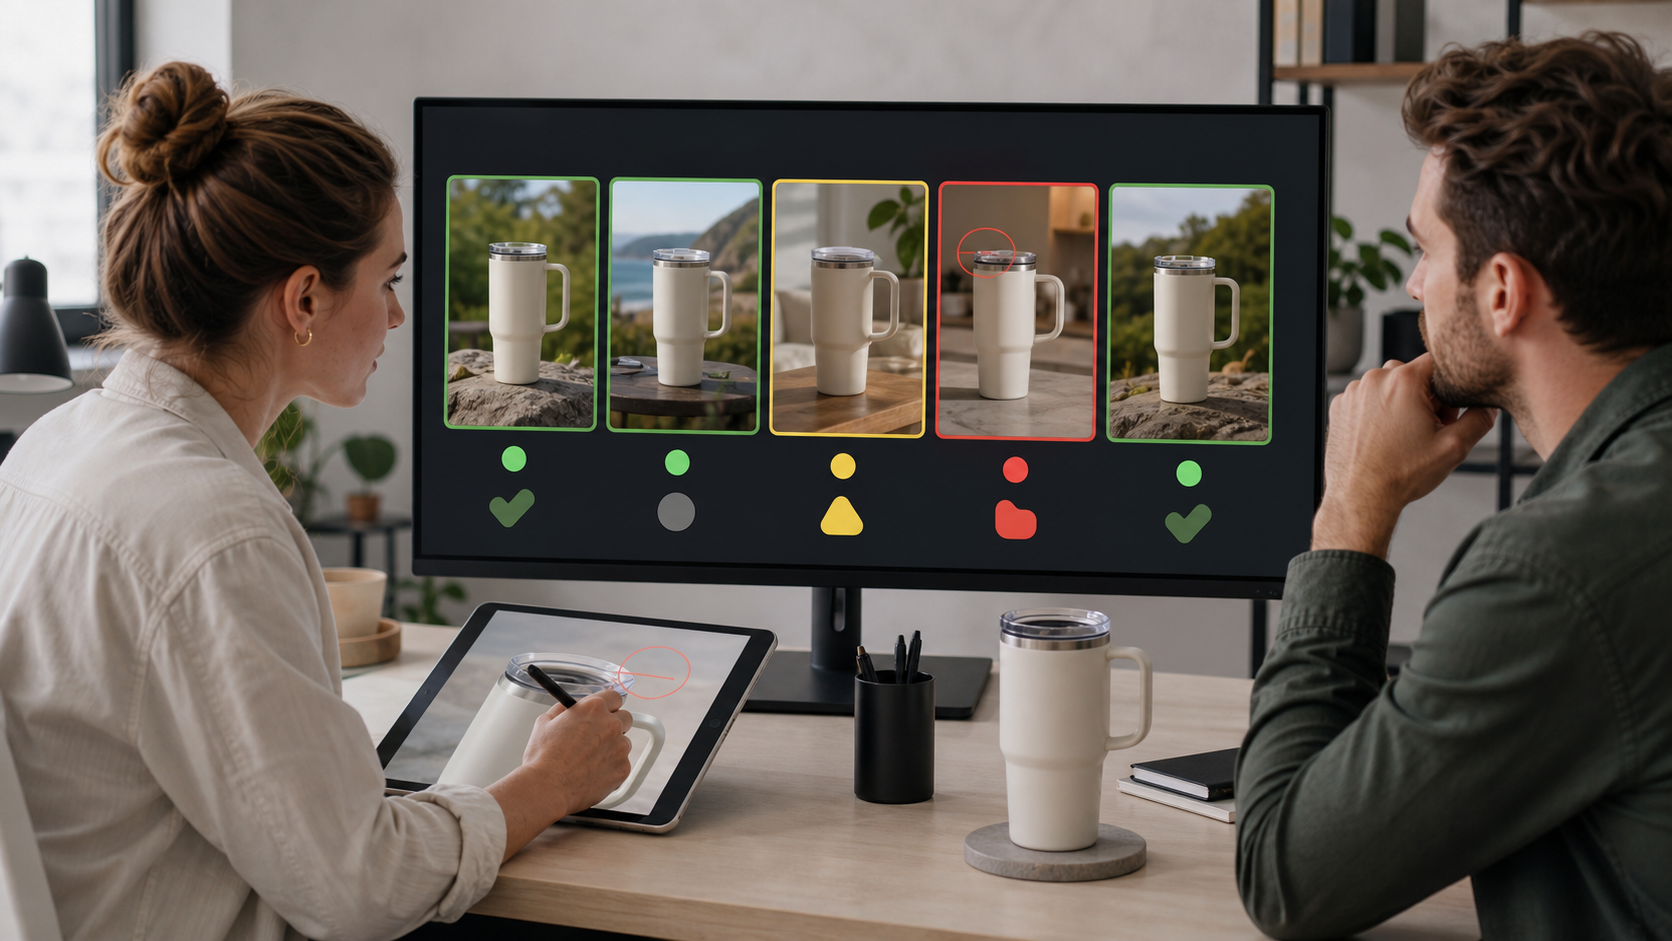
    Two creative team members compare generated product-video frames and inspect them for visual inconsistencies against a physical travel cup.

    Generating first and deciding what the ad means afterward produces a folder of clips, not a campaign. Write the creative brief before opening Asset Studio, even if the brief is only four lines.

    1. State the audience and problem. Name the person the ad is for and the single situation that makes the product relevant. Avoid a broad label such as “all shoppers.”
    2. Choose one promise. A short video rarely has room for a feature list. Select the one benefit the viewer should retain after the clip ends.
    3. Define the visible action. Describe what should move and why that movement helps communicate the promise. Motion should reveal, demonstrate, or focus attention; it should not exist only to make the image look active.
    4. Select up to three source images. Give each image a purpose, remove weak duplicates, and confirm that the product details agree across the set.
    5. Generate a restrained baseline. Start with the simplest version of the concept. A conservative baseline is easier to evaluate than an output containing simultaneous background, text, pacing, and visual-style changes.
    6. Create one deliberate variant. Change one meaningful element: the input image, the setting, the visual emphasis, or the template treatment. Do not change everything at once.
    7. Use Nano Banana for controlled edits. Swap a background or adjust the copy only after the core motion works. Treat each edit as a new creative that must pass review.
    8. Label the asset before launch. Put the concept, generation method, and variant in the name. A structure such as product, benefit, Veo, and variant number will be more useful later than a filename such as “final-video-3.”

    Inspect the output as an ad, not as a novelty

    Watch the generated clip several times with a different purpose on each pass. First judge the message. Then inspect the product. Finally, check every frame that contains copy, branding, or a transition.

    • Product identity: Does the same product remain recognizable from beginning to end?
    • Shape and scale: Do proportions stay stable as the camera or object moves?
    • Packaging and text: Are labels, logos, prices, and claims legible and accurate?
    • Physical behavior: Does the movement make sense for the material and setting?
    • Background integrity: Do shadows, reflections, edges, and contact points agree with the new environment?
    • Message hierarchy: Can a viewer understand the product, benefit, and next action without pausing?
    • Landing-page continuity: Will the person who clicks find the same product, offer, and promise on the destination page?

    If the product changes shape, the label mutates, or the setting creates a false impression, reject the output. A polished transition does not compensate for a misleading frame. When the defect affects the central subject, a new generation from a clearer image is usually a sounder decision than layering more edits onto the mistake.

    Separate creative testing from generation method

    AI-generated video creates two questions that are easy to collapse into one: did the creative idea work, and did the generation method help? You need to preserve the origin of each asset if you want to answer either question.

    Google Ads API v23.2 adds a VideoEnhancement resource that can distinguish Google-generated video from advertiser-provided video. If your team maintains a reporting pipeline, update the relevant client library and code before building analysis around that distinction. A dashboard cannot recover creative provenance later if the pipeline never captured it.

    Keep a corresponding field in the creative log used by marketers. Record the asset name, source images, generation method, concept, edited element, campaign, and launch status. The API classification tells you where a video came from; the creative log tells you what hypothesis it was meant to test.

    Run tests that lead to a decision

    Begin each test with a sentence that can be proved wrong. For example: “A product-in-use image will communicate the benefit more clearly than an isolated pack shot.” Then preserve everything you reasonably can except the element named in that sentence.

    • To test the generation method: Compare Google-generated and advertiser-provided videos with comparable messages, audiences, offers, and destinations.
    • To test an input image: Keep the template and message stable while changing the source visual.
    • To test a background: Keep the product, copy, and motion concept stable while changing only the setting.
    • To test a message: Keep the visual treatment stable while changing the benefit or call to action.
    • To test a template treatment: Use the same source images and promise, then vary the presentation rather than the underlying idea.

    Choose the campaign goal and evaluation metrics before launch. Do not declare a winner because one clip looks smoother or receives an early burst of delivery. Judge it against the action the campaign is intended to produce, and document the decision so the next generation builds on a finding rather than restarting the experiment.

    Google Ads AI video FAQ

    Can Veo replace a conventional video production?

    It can replace a narrow production task: turning up to three still images into a short, template-assisted video ad. It does not replace concept development, complex storytelling, accurate product demonstration, brand review, or footage that must document a real person, place, or event. Use it where the format matches the job.

    What should you test first?

    Start with a product that has clean photography, a single focal point, and an easily described motion concept. Generate one restrained baseline and one controlled variant. That pair will teach you more than a batch of unrelated outputs because you will know what changed.

    Do you need Google Ads API v23.2 to create Veo videos?

    No. Creation happens in Asset Studio. API v23.2 matters when you operate custom reporting and need programmatic visibility into whether a video was generated by Google or supplied by the advertiser. Teams that rely only on interface reporting can still adopt the same discipline by labeling assets and maintaining a creative log.

    Your next move should be small and auditable: choose one image-rich product, write one clear promise, generate a baseline plus one variant, and record the origin of both assets before they enter a campaign. That gives you a usable ad and a test you can learn from.

    References


  • Transform Your Webflow Experience with Profound Agents Integration

    Transform Your Webflow Experience with Profound Agents Integration

    I’m thrilled to share that Profound Agents now seamlessly integrate with Webflow. This new capability transforms your CMS into an active automation endpoint, streamlining processes and boosting efficiency.

    This integration is designed to elevate how you manage content, providing newfound ease and automation right at your fingertips. It marks a significant step forward in optimizing digital workflows, empowering me to focus more on creativity and less on manual tasks.


    Inspired by this post on Try Profound Blog.


    crushpress.ai community screenshot
  • Google Ads Developer AI Updates: A Practical Playbook

    Google Ads Developer AI Updates: A Practical Playbook

    You do not need another AI announcement in your backlog. You need to know whether Google’s direction changes what your advertising team should build, who should control it, and how much authority an AI agent should receive.

    The immediate answer is not to rebuild your Google Ads integration around agents. Treat the update as an architectural signal: prepare for AI systems to propose and invoke advertising actions, but keep permissions, validation, approvals, execution, and audit controls outside the model.

    The update is a learning channel, not an API release

    An engineer studies abstract signals from a studio beacon while a separate sealed production system remains unchanged on the workbench.

    Google has introduced Ads DevCast as a bi-weekly pilot hosted by Cory Liseno from its Advertising and Measurement Developer Relations team. Its technical scope includes Google Ads, Google Analytics, and Display & Video 360. Google is also inviting feedback while the pilot develops.

    That positioning matters. Ads Decoded, hosted by Ginny Marvin, addresses campaign strategy. Ads DevCast is intended for the people building, configuring, debugging, and governing the systems beneath that strategy. Subscribe the technical owner of your advertising stack, not only the person who manages campaigns.

    A new developer show does not, by itself, change an endpoint, schema, authentication flow, or deprecation date. Do not turn an episode into a production migration ticket merely because an idea sounds important. Use three separate lanes:

    • Discovery: Use Ads DevCast to notice technical themes, emerging capabilities, and the problems Google expects developers to encounter.
    • Verification: Confirm implementation details in the relevant official API documentation, release notes, schemas, and account controls before changing code.
    • Delivery: Create an engineering task only after you can name the affected platform, resource, operation, permission, test case, and rollback path.

    This distinction prevents two common errors. One is ignoring a directional signal until it becomes an urgent implementation problem. The other is treating a discussion of future architecture as though it were a released feature with stable production behavior.

    The agentic shift changes your control plane

    The first episode, titled “MCPs, Agents, and Ads. Oh My!”, presents an “agentic shift” in which AI agents become important users of advertising APIs. Treat that as Google’s direction of travel, not as evidence that every advertiser should give an agent unrestricted control of live campaigns.

    Model Context Protocol, or MCP, is relevant because it gives AI systems a common way to discover and invoke tools. A consistent tool interface can make an API easier for an agent to reach. It does not make the requested action correct, authorized, affordable, or reversible.

    The safest mental model is simple: the agent is a planner and operator working inside a control system. It is not the control system. A production workflow should separate intent from execution:

    1. Observe: Retrieve only the account and campaign data needed for the task.
    2. Propose: Produce a structured change showing the target resource, current value, proposed value, rationale, and expected scope.
    3. Validate: Check the proposal against the API schema, account state, internal policy, and allowed operations.
    4. Approve: Require the appropriate human or policy-based approval before any consequential write.
    5. Execute: Pass the approved action to deterministic code that calls the advertising API.
    6. Verify: Read the affected resource again, record the result, and surface any difference between the approved proposal and the final state.

    Put hard limits outside the prompt

    A prompt can tell an agent not to make risky changes. It should not be the only thing preventing them. The enforceable rules belong in the gateway between the agent and the ad platform.

    • Allowlist the accounts, resource types, fields, and operations the agent may access.
    • Use read-only access by default and grant write access per workflow rather than per agent.
    • Reject requests that omit the target account, current state, proposed state, or approval record.
    • Place budget, bid, scheduling, targeting, and deletion constraints in code or platform policy.
    • Use idempotency or equivalent duplicate protection where the operation supports it.
    • Log the request, tool call, actor, approval, API response, and resulting resource state.
    • Maintain a tested way to reverse mutable changes and a separate recovery procedure for actions that cannot be cleanly undone.

    This is a money-sensitive system. An agent with broad write access can alter live delivery before a person notices the mistake. For any action that can increase spend, narrow reach, pause revenue-producing activity, remove data, or change measurement, use a preview-and-approval flow until you have evidence that a more automated policy is safe for that exact operation.

    Turn each episode into an engineering decision

    A bi-weekly technical program can quickly become background noise unless someone owns the intake process. Give one person responsibility for converting each relevant item into a decision, including a deliberate decision to take no action.

    1. Capture the claim precisely. Write down the named product, capability, resource, or workflow. Avoid tickets such as “investigate AI for ads” because they have no testable boundary.
    2. Classify its status. Mark it as a concept, directional signal, pilot, documented capability, released change, or deprecation. Do not let enthusiasm silently upgrade its maturity.
    3. Map the affected surface. Identify whether it touches Google Ads, Google Analytics, Display & Video 360, or more than one system. Then name the relevant integration, credential, data flow, and owner.
    4. Verify implementation facts. Check the authoritative documentation for availability, supported operations, permissions, quotas, version requirements, and known limitations.
    5. Record the decision. Choose watch, prototype, adopt, migrate, or reject. Include the evidence needed to revisit that choice.

    Your decision record does not need to be elaborate. It should include the topic, status, affected system, documentation link, owner, next review trigger, test environment, approval requirement, and rollback method. That is enough to distinguish a useful technical signal from an unverified idea circulating in team chat.

    Use a prototype when the value is plausible but the operational risk is unclear. Start with a read-only workflow that answers one bounded question, then let the agent draft a change without executing it. Compare its proposal with the decision a qualified operator would make. Only after that should you test an approved write in a controlled account or environment.

    Because Ads DevCast is a pilot seeking community input, document where explanations leave an implementation gap. Useful feedback is specific: name the platform, operation, missing detail, and decision you could not safely make. That gives Google a clearer request than a general demand for more examples.

    Your ownership model must evolve with the integration

    An isometric AI advertising workflow routes action tokens through access controls, validation, human review, staging, and an audit vault while separate teams supervise their areas.

    Google is broadening the frame from a specialist Ads Developer Community toward a wider Ads Technical Community. That makes room for marketers to perform more technical work without waiting for a full development cycle. It does not erase the need for engineering ownership; it changes where the handoffs occur.

    Before connecting an agent to advertising tools, assign these responsibilities by name:

    • Business owner: Defines the campaign objective and decides which tradeoffs are acceptable.
    • Platform owner: Controls credentials, permissions, API configuration, and production access.
    • Workflow owner: Defines the agent’s tools, inputs, outputs, validation rules, and failure behavior.
    • Approver: Reviews consequential changes and has enough context to reject a technically valid but commercially poor action.
    • Incident owner: Can stop execution, assess affected resources, restore safe state, and preserve the audit trail.

    Do not collapse all five roles into “the AI team.” The business owner knows what should happen. The platform owner knows what can happen. The workflow owner controls how a request becomes an API call. The approver evaluates the actual change. The incident owner handles the moment when the system behaves differently from the plan.

    This division also makes low-code and agent-assisted work more practical. A marketer can describe or initiate a task without receiving unrestricted platform access. Engineering can provide constrained tools and reusable policies instead of implementing every request from scratch. The speed comes from a safer interface between roles, not from removing the roles.

    Key takeaways for your next working session

    • Use Ads DevCast as a technical discovery channel; verify every implementation detail in authoritative product documentation.
    • Treat Google’s agentic direction as a reason to prepare your architecture, not as permission to automate every campaign action.
    • Keep the agent focused on observation and structured proposals before granting narrowly scoped write capability.
    • Enforce permissions, spend constraints, approvals, logging, and recovery outside the model and its prompt.
    • Assign business, platform, workflow, approval, and incident ownership before connecting an agent to a live advertising account.
    • Convert each relevant update into a recorded decision: watch, prototype, adopt, migrate, or reject.

    Start with one existing Google Ads workflow that consumes too much operator time but has a clear input and output. Draw the six stages from observation through verification. Mark every place where a bad decision could affect spend, delivery, measurement, or data. Those marks define the controls your agent needs before it gets write access.

    Then build the smallest read-only version and require a structured proposal. That gives you a concrete way to evaluate Google’s agentic direction without betting a live account on an immature design.

    References