You changed a page, but Google still shows the old title, selects another canonical, omits the URL, or leaves its rankings unchanged. It is tempting to call every one of those outcomes a crawling delay. That label is too broad to tell you whether to wait or intervene.
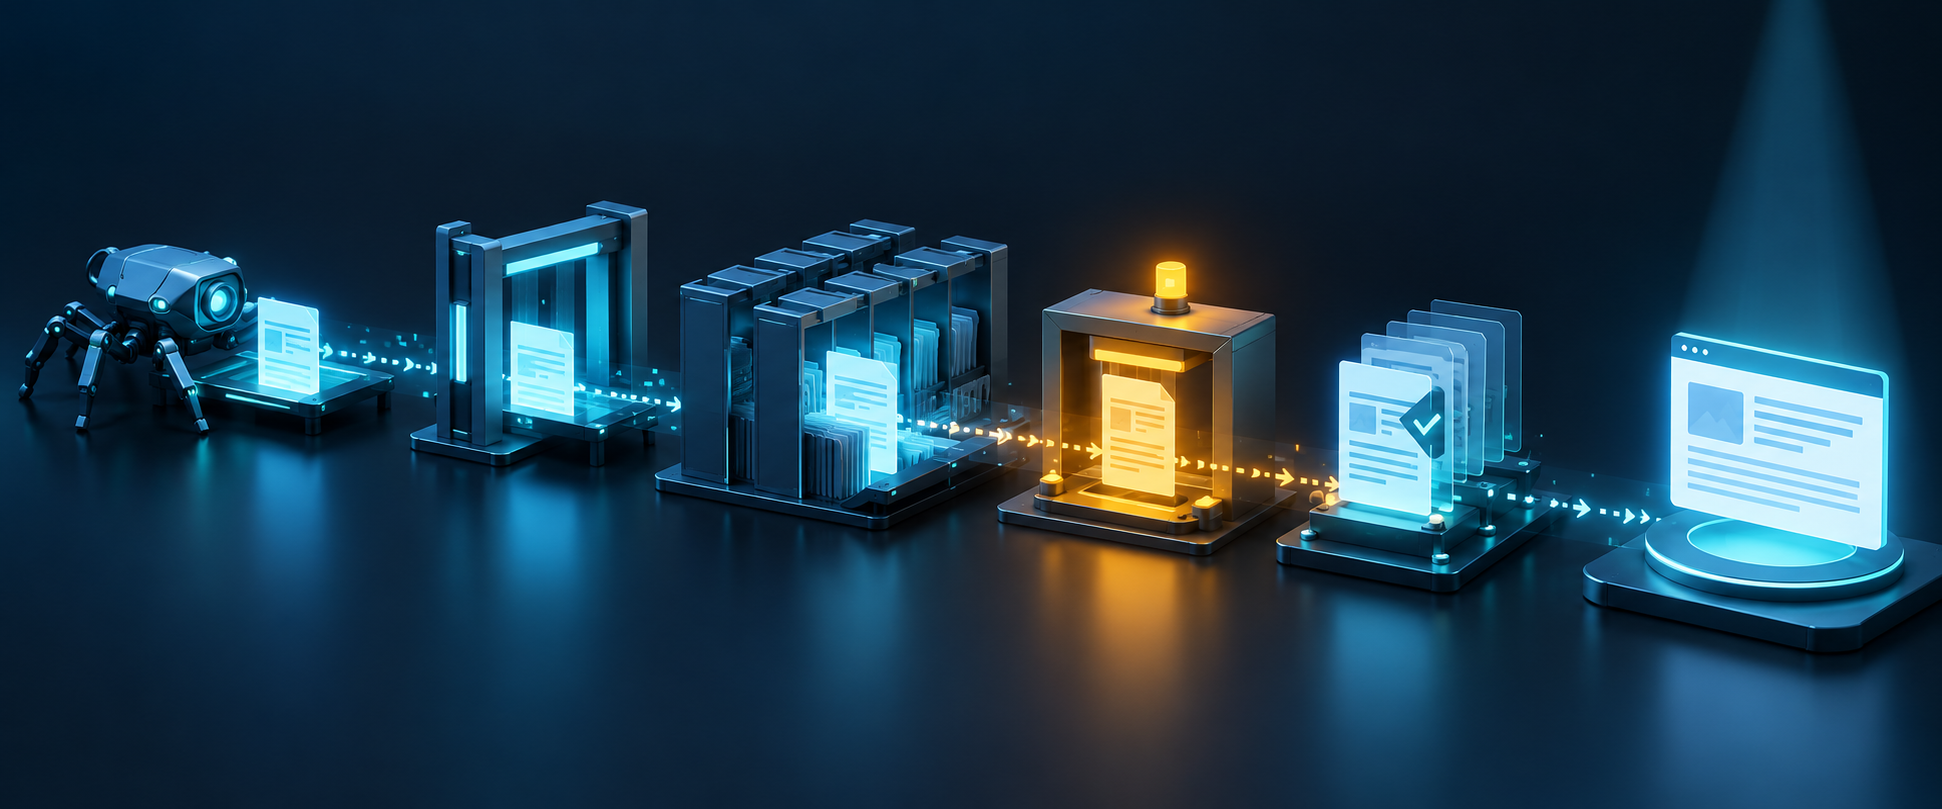
Treat search visibility as a sequence of handoffs. First identify the last handoff that completed. Then investigate the next one. This gives you a defensible timeline and keeps you from changing a page repeatedly while Google is still processing an earlier version.
A crawl is only the first handoff
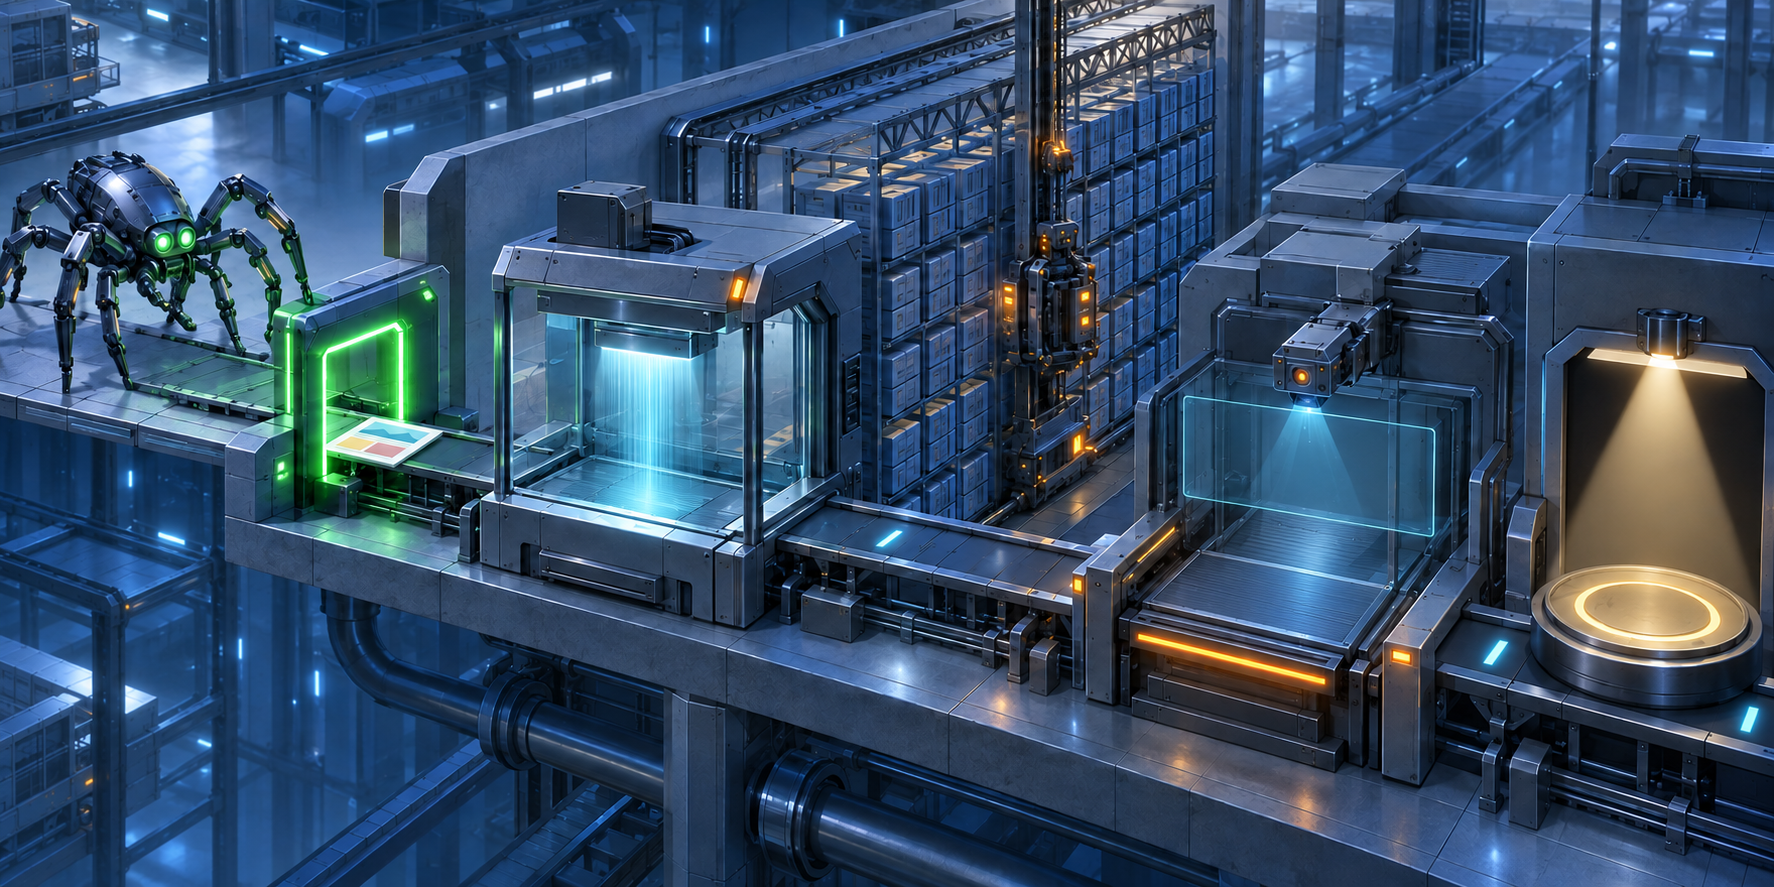
There is no universal timer that starts when you press Publish and ends when the page appears exactly as intended in search. Several distinct events have to occur:
- Discovery: Google learns that the URL exists or has changed.
- Crawling: Google requests the URL and receives a response.
- Rendering and processing: Google evaluates the returned document, including content that depends on rendering.
- Indexing and canonicalization: Google determines what the page represents, whether it belongs in the index, and which URL should represent substantially similar content.
- Serving: Google decides whether and how to show the indexed result for a particular query.
Passing one stage does not prove that the next stage has finished. A Googlebot request in your server logs proves a fetch occurred; it does not prove indexing. An indexed URL is eligible to appear, but it is not guaranteed to rank for the query you care about. A result appearing in search does not guarantee that Google will use your preferred title, snippet, canonical, or structured-data presentation.
Discovery, refreshes, sitemap processing, robots.txt controls, rendering, indexing, link annotations, removals, canonicalization, structured data, titles, snippets, core updates, and spam updates all have their own typical and slowest processing bands. Your deployment time therefore is not a reliable prediction of when every downstream search signal will change.
Set your expectation from the change you made
The right clock depends on what changed. Before diagnosing a delay, name the exact search outcome you expect.
- A new URL must be discovered, crawled, processed, considered for indexing, and then served. Finding it in a sitemap is only an early step.
- Updated body copy requires another crawl and another round of processing. The live page can be correct while Google’s stored understanding still reflects an earlier version.
- A title or description change is not complete merely because Google has fetched the page. Serving systems still decide what representation is useful for a query, so your supplied text may not be shown verbatim.
- A canonical change asks Google to reconsider a cluster of related URLs. The canonical element matters, but internal links, redirects, sitemap entries, and duplicate-page signals should point in the same direction.
- A robots, noindex, or removal change depends on Google being able to encounter and process the relevant control. Do not block a URL in robots.txt and assume Google can then fetch a page-level noindex directive from it.
- Structured-data changes require valid markup to be found and processed. Validity can establish eligibility for a search feature; it does not guarantee that the feature will be served.
- Internal-link changes can affect discovery and link annotations, but they do not create an immediate ranking promise.
- A sitewide ranking change may belong to a broader ranking or spam-system rollout rather than the crawl status of one page.
Use a typical range as a planning expectation and a slowest range as a prompt to investigate. Neither is a service-level guarantee. One spam-update benchmark put a typical change at one to two days, while the September 2026 spam update was expected to roll out over two weeks. Resubmitting one URL cannot shorten a system-level rollout. Rollout duration and URL-processing time answer different questions.
Diagnose the symptom before deciding to wait
Do not begin with the age of the change. Begin with the observable mismatch between the live page and Google’s current state.
| What you observe | Handoff to inspect | What to do next |
|---|---|---|
| No crawl or discovery signal for the URL | Discovery and access | Confirm the URL returns the intended response, is not accidentally blocked, appears in an appropriate sitemap, and is linked from a crawlable page that Google already knows. |
| Google fetched the URL, but important content is absent from the processed page | Rendering | Compare the initial HTML with the rendered output. Make essential content and links available reliably, and fix failed or blocked resources rather than waiting for another identical render. |
| The page is crawled, but another URL is selected as canonical | Canonicalization | Check for conflicting canonical elements, redirects, internal links, sitemap URLs, and near-duplicate pages. Align those signals before requesting another crawl. |
| The correct URL is indexed, but its title, snippet, or rich-result treatment is stale or different | Serving and presentation | Verify that the current HTML contains the intended information and that structured data is valid. Then allow time for reprocessing, while remembering that Google can generate a query-specific presentation. |
| The indexed page is current, but impressions or rankings have not improved | Ranking and query fit | Stop treating the issue as crawl latency. Examine whether the page satisfies the target intent, offers distinctive information, and has enough internal prominence and authority to compete. |
| Many pages shift during a named search update | System rollout | Separate rollout monitoring from page-level debugging. Avoid drawing a final conclusion from an incomplete rollout or making several unrelated sitewide changes at once. |
Google Search Console can help you locate the handoff. For an affected URL, compare the indexing status, last crawl information, Google-selected canonical, and inspected page with the live version. Server logs can confirm whether Googlebot requested the URL. A rendered-page check can reveal whether essential content was available during processing.
Interpret each signal narrowly. A successful live test shows that Google can access the page now; it does not establish what happened during an earlier fetch. A crawl in the logs establishes retrieval, not indexing. An indexing status establishes index state, not rankings. Keeping those distinctions intact prevents false diagnoses.
Build a release log that preserves the evidence
A useful crawl-to-serving timeline begins with your own deployment record. Without one, teams tend to compare today’s search result with an uncertain memory of what changed and when.
- Record the deployment. Save the timestamp, affected URL or template, old state, new state, and the specific result you expect Google to change.
- Classify the expected handoff. Decide whether success means discovery, a fresh crawl, corrected rendering, indexing, canonical selection, a new search presentation, or a ranking response.
- Verify production immediately. Check the response status, final URL after redirects, canonical element, robots directives, robots.txt access, rendered main content, internal links, and sitemap entry where relevant.
- Capture a baseline. Save the current Search Console state and relevant server-log evidence. If you later see a different crawl date or canonical, you will know which stage moved.
- Request reprocessing only when it helps. An indexing request can encourage another look at a limited set of important URLs, but it does not remove the later indexing, canonicalization, ranking, or serving decisions.
- Change one cause at a time. Rewriting content, changing canonicals, altering internal links, and resubmitting the URL together may produce movement, but you will not know which intervention mattered.
- Escalate by pattern. One delayed URL points toward page-level access, content, duplication, or canonical signals. A delayed template group points toward rendering, directives, linking, or sitemap generation. A sitewide movement may require update-level analysis.
Repeatedly requesting indexing without correcting a contradictory signal is not a diagnosis. Neither is changing the page every day. Both actions muddy the sequence you need to observe. Once production is technically sound, preserve the version long enough to see whether the next handoff completes.
Key takeaways
- Crawl-to-serving is a chain of separate processes, not one countdown from publication.
- A crawl proves retrieval. It does not, by itself, prove rendering, indexing, canonical selection, ranking, or the final search presentation.
- Set your expectation from the changed element: a new URL, canonical, title, structured-data block, internal link, or ranking signal can follow a different path.
- Use typical timing as a planning band and slowest timing as an investigation trigger, not as a guaranteed deadline.
- Diagnose the first incomplete handoff and correct its inputs before requesting another crawl.
For your next release, write down the first Google-visible signal that should change and where you will verify it. If that signal appears but the next one does not, move your investigation forward one stage. If nothing has reached the first stage, fix discovery or access before spending time on rankings.
References

Leave a Reply