Tag: Audit

  • Google Crawl-to-Serving Timelines: How to Diagnose Delays

    Google Crawl-to-Serving Timelines: How to Diagnose Delays

    You changed a page, but Google still shows the old title, selects another canonical, omits the URL, or leaves its rankings unchanged. It is tempting to call every one of those outcomes a crawling delay. That label is too broad to tell you whether to wait or intervene.

    Treat search visibility as a sequence of handoffs. First identify the last handoff that completed. Then investigate the next one. This gives you a defensible timeline and keeps you from changing a page repeatedly while Google is still processing an earlier version.

    A crawl is only the first handoff
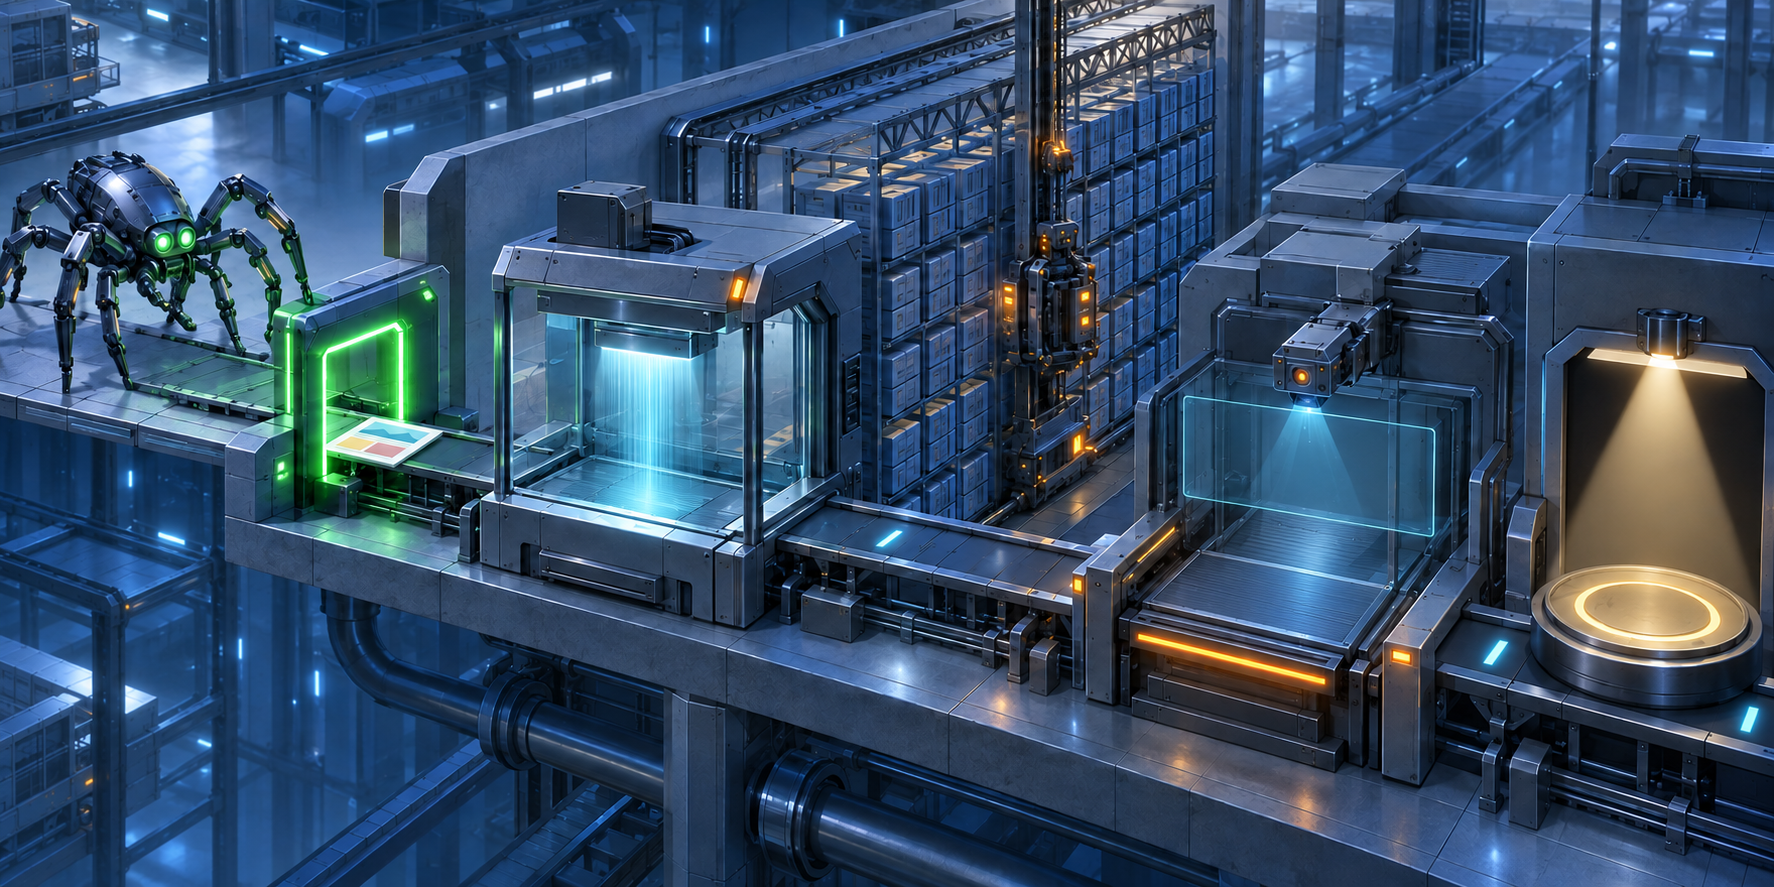
    An updated webpage moves from a retrieval machine through scanning, archive, comparison, and display stages in a digital facility.

    There is no universal timer that starts when you press Publish and ends when the page appears exactly as intended in search. Several distinct events have to occur:

    1. Discovery: Google learns that the URL exists or has changed.
    2. Crawling: Google requests the URL and receives a response.
    3. Rendering and processing: Google evaluates the returned document, including content that depends on rendering.
    4. Indexing and canonicalization: Google determines what the page represents, whether it belongs in the index, and which URL should represent substantially similar content.
    5. Serving: Google decides whether and how to show the indexed result for a particular query.

    Passing one stage does not prove that the next stage has finished. A Googlebot request in your server logs proves a fetch occurred; it does not prove indexing. An indexed URL is eligible to appear, but it is not guaranteed to rank for the query you care about. A result appearing in search does not guarantee that Google will use your preferred title, snippet, canonical, or structured-data presentation.

    Discovery, refreshes, sitemap processing, robots.txt controls, rendering, indexing, link annotations, removals, canonicalization, structured data, titles, snippets, core updates, and spam updates all have their own typical and slowest processing bands. Your deployment time therefore is not a reliable prediction of when every downstream search signal will change.

    Set your expectation from the change you made

    The right clock depends on what changed. Before diagnosing a delay, name the exact search outcome you expect.

    • A new URL must be discovered, crawled, processed, considered for indexing, and then served. Finding it in a sitemap is only an early step.
    • Updated body copy requires another crawl and another round of processing. The live page can be correct while Google’s stored understanding still reflects an earlier version.
    • A title or description change is not complete merely because Google has fetched the page. Serving systems still decide what representation is useful for a query, so your supplied text may not be shown verbatim.
    • A canonical change asks Google to reconsider a cluster of related URLs. The canonical element matters, but internal links, redirects, sitemap entries, and duplicate-page signals should point in the same direction.
    • A robots, noindex, or removal change depends on Google being able to encounter and process the relevant control. Do not block a URL in robots.txt and assume Google can then fetch a page-level noindex directive from it.
    • Structured-data changes require valid markup to be found and processed. Validity can establish eligibility for a search feature; it does not guarantee that the feature will be served.
    • Internal-link changes can affect discovery and link annotations, but they do not create an immediate ranking promise.
    • A sitewide ranking change may belong to a broader ranking or spam-system rollout rather than the crawl status of one page.

    Use a typical range as a planning expectation and a slowest range as a prompt to investigate. Neither is a service-level guarantee. One spam-update benchmark put a typical change at one to two days, while the September 2026 spam update was expected to roll out over two weeks. Resubmitting one URL cannot shorten a system-level rollout. Rollout duration and URL-processing time answer different questions.

    Diagnose the symptom before deciding to wait

    Do not begin with the age of the change. Begin with the observable mismatch between the live page and Google’s current state.

    What you observeHandoff to inspectWhat to do next
    No crawl or discovery signal for the URLDiscovery and accessConfirm the URL returns the intended response, is not accidentally blocked, appears in an appropriate sitemap, and is linked from a crawlable page that Google already knows.
    Google fetched the URL, but important content is absent from the processed pageRenderingCompare the initial HTML with the rendered output. Make essential content and links available reliably, and fix failed or blocked resources rather than waiting for another identical render.
    The page is crawled, but another URL is selected as canonicalCanonicalizationCheck for conflicting canonical elements, redirects, internal links, sitemap URLs, and near-duplicate pages. Align those signals before requesting another crawl.
    The correct URL is indexed, but its title, snippet, or rich-result treatment is stale or differentServing and presentationVerify that the current HTML contains the intended information and that structured data is valid. Then allow time for reprocessing, while remembering that Google can generate a query-specific presentation.
    The indexed page is current, but impressions or rankings have not improvedRanking and query fitStop treating the issue as crawl latency. Examine whether the page satisfies the target intent, offers distinctive information, and has enough internal prominence and authority to compete.
    Many pages shift during a named search updateSystem rolloutSeparate rollout monitoring from page-level debugging. Avoid drawing a final conclusion from an incomplete rollout or making several unrelated sitewide changes at once.

    Google Search Console can help you locate the handoff. For an affected URL, compare the indexing status, last crawl information, Google-selected canonical, and inspected page with the live version. Server logs can confirm whether Googlebot requested the URL. A rendered-page check can reveal whether essential content was available during processing.

    Interpret each signal narrowly. A successful live test shows that Google can access the page now; it does not establish what happened during an earlier fetch. A crawl in the logs establishes retrieval, not indexing. An indexing status establishes index state, not rankings. Keeping those distinctions intact prevents false diagnoses.

    Build a release log that preserves the evidence
    Three preserved webpage versions are arranged beside a server model, clock, camera, archive sleeves, and magnifying glass.

    A useful crawl-to-serving timeline begins with your own deployment record. Without one, teams tend to compare today’s search result with an uncertain memory of what changed and when.

    1. Record the deployment. Save the timestamp, affected URL or template, old state, new state, and the specific result you expect Google to change.
    2. Classify the expected handoff. Decide whether success means discovery, a fresh crawl, corrected rendering, indexing, canonical selection, a new search presentation, or a ranking response.
    3. Verify production immediately. Check the response status, final URL after redirects, canonical element, robots directives, robots.txt access, rendered main content, internal links, and sitemap entry where relevant.
    4. Capture a baseline. Save the current Search Console state and relevant server-log evidence. If you later see a different crawl date or canonical, you will know which stage moved.
    5. Request reprocessing only when it helps. An indexing request can encourage another look at a limited set of important URLs, but it does not remove the later indexing, canonicalization, ranking, or serving decisions.
    6. Change one cause at a time. Rewriting content, changing canonicals, altering internal links, and resubmitting the URL together may produce movement, but you will not know which intervention mattered.
    7. Escalate by pattern. One delayed URL points toward page-level access, content, duplication, or canonical signals. A delayed template group points toward rendering, directives, linking, or sitemap generation. A sitewide movement may require update-level analysis.

    Repeatedly requesting indexing without correcting a contradictory signal is not a diagnosis. Neither is changing the page every day. Both actions muddy the sequence you need to observe. Once production is technically sound, preserve the version long enough to see whether the next handoff completes.

    Key takeaways

    • Crawl-to-serving is a chain of separate processes, not one countdown from publication.
    • A crawl proves retrieval. It does not, by itself, prove rendering, indexing, canonical selection, ranking, or the final search presentation.
    • Set your expectation from the changed element: a new URL, canonical, title, structured-data block, internal link, or ranking signal can follow a different path.
    • Use typical timing as a planning band and slowest timing as an investigation trigger, not as a guaranteed deadline.
    • Diagnose the first incomplete handoff and correct its inputs before requesting another crawl.

    For your next release, write down the first Google-visible signal that should change and where you will verify it. If that signal appears but the next one does not, move your investigation forward one stage. If nothing has reached the first stage, fix discovery or access before spending time on rankings.

    References


  • Microsoft Automotive Ad Pricing Rules: A Dealer Checklist

    Microsoft Automotive Ad Pricing Rules: A Dealer Checklist

    A vehicle price can be correct in your inventory system and still become misleading by the time it reaches an ad. A conditional discount may lose its qualifier, a feed may retain yesterday’s amount, or the landing page may show a different offer.

    If you manage U.S. dealer campaigns, treat Microsoft Advertising’s updated automotive pricing policy as a reason to audit the entire path from inventory record to landing page. The central test is simple: does the price a shopper sees accurately represent the offer that shopper can obtain?

    Key takeaways for U.S. automotive advertisers

    • The revised pricing requirements apply to automotive dealers advertising in the United States through Microsoft Advertising.
    • Accuracy depends on more than the number in a feed. Review source data, feed transformations, discounts, ad rendering and landing pages together.
    • A discount that depends on eligibility, timing or another condition should not appear to be universally available.
    • Quarantine ambiguous or mismatched inventory records instead of allowing questionable prices to keep serving.
    • Keep evidence showing what the offer, feed, ad and landing page displayed when each pricing review was completed.

    Start with the requirement you can prove

    The revised requirements govern how vehicle prices are represented, including the treatment of prices, discounts and related pricing information across Microsoft Advertising formats. Microsoft has framed the change as a way to make compliance easier while keeping advertised prices faithful to the available offer.

    That principle is useful, but it isn’t a substitute for the current policy language. Before changing templates or feed logic, retrieve the active Microsoft Advertising policy and its change log from your account or policy library. Save the version your team reviewed. Then convert each requirement into a control that can be tested.

    Your requirements matrix should record:

    • Scope: the campaigns, formats, accounts and inventory covered by the requirement.
    • Price element: the feed field, discount, qualifier or rendered text that must be checked.
    • Expected behavior: what the feed, ad and destination must show for the record to pass.
    • Evidence: the feed export, ad preview, landing-page capture and approval record that demonstrate compliance.
    • Owner: the person or team responsible for correcting a failure.

    This prevents a familiar operational mistake: translating a policy change into a vague instruction such as “check the prices.” A requirement without a named field, pass condition and owner is unlikely to survive the next inventory refresh.

    Audit the price as a chain, not a field

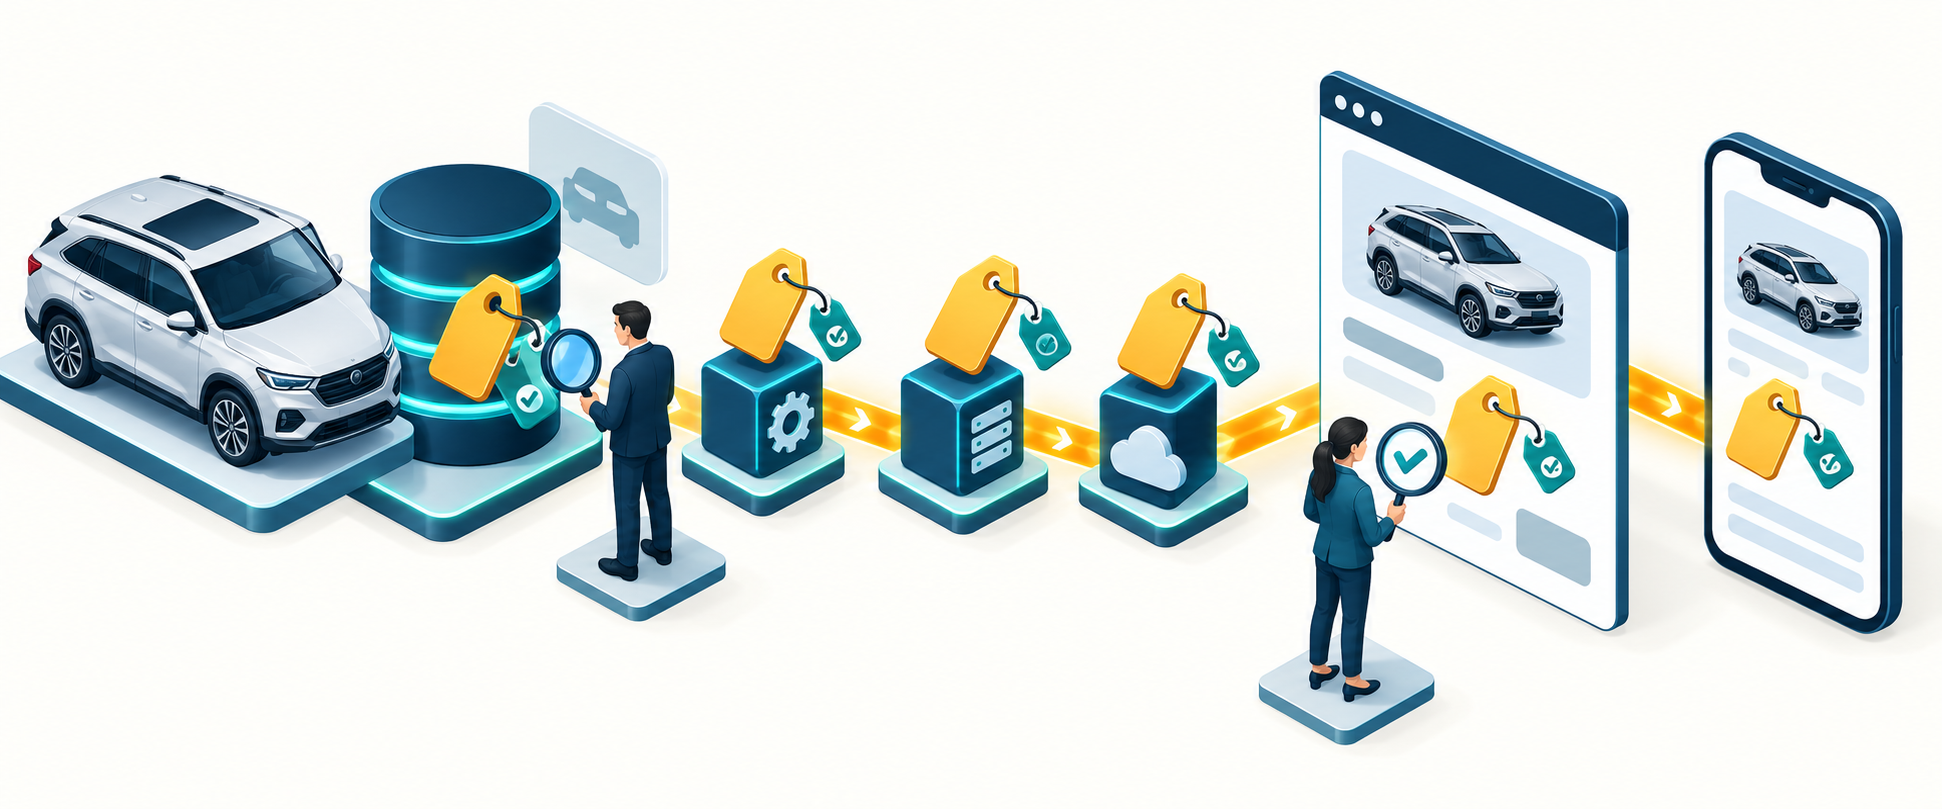
    An isometric audit chain links a vehicle inventory record, feed pipeline, online ad, and mobile landing page with connected price and discount tags.

    The shopper sees the output of several systems. Your audit should therefore follow the same route as the price.

    1. Confirm the underlying offer. For each sampled vehicle, record the stock identifier, selling price, included discounts, eligibility conditions, availability and relevant offer timing. This is the truth the rest of the chain must preserve.
    2. Inspect the feed transformation. Compare the inventory-system values with the exported values. Look for field mapping, rounding, fallback values, promotional overrides or other logic that can change the amount.
    3. Check the rendered ad. Use the actual ad preview or delivered-ad evidence where available. Do not rely only on the feed file; templates can omit qualifiers or place values in the wrong pricing field.
    4. Open the destination. Confirm that the click resolves to the same vehicle and that the visible price and conditions agree with the advertised offer. A correct feed does not repair a contradictory landing page.
    5. Test the handoff. A staff member who was not involved in creating the promotion should be able to identify who qualifies, which discounts are included and how the displayed amount is obtained.

    Keep the evidence together under the same stock identifier. If a campaign is questioned later, separate screenshots and exports are far less useful when nobody can tell whether they describe the same vehicle or the same version of the offer.

    Review discounts more aggressively than base prices

    Base prices are usually direct values. Discounts often contain business logic: a buyer must qualify, offers may or may not combine, inventory may be restricted, and a promotion may end while an old feed remains active. That makes discounts the natural place for a technically valid number to become an inaccurate promise.

    For every advertised discount, answer these questions before the record is eligible to serve:

    • Can the intended audience actually receive the discount on the advertised vehicle?
    • Does eligibility depend on a fact that the ad or destination fails to communicate clearly?
    • If several discounts produce the displayed price, can those discounts genuinely be combined?
    • Does the promotion apply to this specific inventory record rather than merely to a related model or trim?
    • What removes or replaces the promotional amount when the underlying offer changes?
    • Will the landing page explain the offer in a way that agrees with the ad rather than quietly narrowing it?

    Use a practical reproduction test: give the rendered ad and its destination to the person responsible for the offer, then ask that person to reconstruct the advertised amount. If the total depends on an undisclosed assumption, the price chain needs correction before the ad runs.

    Platform compliance is not a legal opinion. Automotive price disclosures can also create legal exposure outside Microsoft Advertising, so route uncertain wording, fee treatment and eligibility disclosures to qualified counsel or your compliance team before publication.

    Build controls that can handle a large vehicle feed

    Manual review is valuable for interpreting an offer, but it does not scale well across a changing inventory. Use automated checks to find records that deserve human attention.

    Block records with objective failures

    • A required price or stock identifier is missing or cannot be parsed.
    • The destination resolves to a different vehicle, a removed listing or an error page.
    • The feed amount and the landing-page amount do not match under the same stated conditions.
    • A discount is present without the data your process requires to validate eligibility and offer status.
    • A source update fails, but the campaign would otherwise continue serving the previous promotional value.

    Send these records to quarantine. Do not let a failed validation silently fall back to a stale or lower amount merely to preserve inventory coverage.

    Queue ambiguous records for human review

    • A new discount or pricing override appears.
    • The size of a discount changes unexpectedly.
    • Several incentives contribute to one advertised amount.
    • The ad copy implies broad availability while the underlying offer contains narrow eligibility conditions.
    • The visible landing-page explanation makes the price harder to understand than the ad itself.

    Prioritize the lowest advertised prices, the largest discounts, recently changed offers and records produced by fallback logic. This is risk-based review: it directs attention to the entries most likely to create a material gap between the advertised number and the obtainable offer.

    Keep each record in an explicit state such as eligible, quarantined or approved exception. An exception should contain its reason, approver and supporting evidence. Otherwise, a temporary workaround can become permanent feed behavior without anyone consciously accepting the risk.

    Handle a pricing violation as a data incident

    A dealership advertising team investigates an amber-highlighted pricing mismatch across inventory, ad, and landing-page systems.

    A pricing problem is rarely fixed by editing one headline. Policy violations can create compliance problems and potentially disrupt campaigns, so preserve the evidence and repair the system that produced the bad value.

    1. Contain the issue. Pause or exclude affected records without unnecessarily disabling inventory that has passed validation.
    2. Preserve the observed state. Save the source record, exported feed row, rendered ad, destination page and applicable policy version.
    3. Locate the first divergence. Determine whether the error began in merchandising data, discount logic, feed mapping, ad templates, the landing page or update timing.
    4. Correct the origin. A manual edit downstream may conceal the symptom while the next refresh recreates it.
    5. Revalidate the path. Confirm both the corrected record and comparable records that use the same rule or template.
    6. Document the prevention. Add a validation rule, ownership change or release check so the same failure cannot pass unnoticed.

    Do not assume every rejected vehicle has the same cause. One campaign may contain a stale-price problem, an eligibility problem and a destination mismatch at the same time. Classifying each failure before applying a bulk fix reduces the chance of introducing a second pricing error.

    Give one person authority over the final price path

    Pricing accuracy crosses several teams: merchandising defines the offer, feed operations map the data, paid media controls the ad, web teams publish the destination, and compliance interprets disclosure risk. Shared work still needs a final owner who can prevent a record from serving when those components disagree.

    Before your next feed publication, choose a discounted vehicle and trace it from the underlying offer through the rendered ad to the landing page. Record every transformation and assign an owner to every failure point. Once that path is reliable, apply the same control to the rest of the high-risk inventory before releasing broader campaign changes.

    References


  • Ecommerce Category Internal Linking: A Practical System

    Ecommerce Category Internal Linking: A Practical System

    Your ecommerce site has more category pages than your navigation can reasonably promote. Merchandising wants one collection featured, SEO sees demand for another, and yesterday’s bestseller still holds most of the site’s internal links. Adding links everywhere won’t resolve that conflict.

    You need a repeatable way to decide which categories deserve support, identify where the current architecture sends the wrong signal, and place links that are useful to shoppers. The goal isn’t an equal distribution. It is an intentional one.

    Make each category earn additional internal links

    Start with the category’s value, not its current link count. A URL does not become important merely because your platform created it, an audit flagged it, or a team wants to rank it. Before you promote a category, confirm that it represents a durable opportunity for both the business and the shopper.

    Evaluate each candidate against these criteria:

    • Business importance: The category supports a defined commercial priority, such as profitable growth, a strategic product line, or a sustained merchandising commitment.
    • Search opportunity: People look for the category as a distinct concept. Its intent is meaningfully different from the parent category and nearby alternatives.
    • Inventory strength: The page offers enough relevant products to satisfy the visit, and stock is likely to remain available. A prominent link to a thin or frequently empty collection sends shoppers into a dead end.
    • Durability: The category will matter beyond a brief promotion. A recurring seasonal category can qualify, but a disposable campaign URL usually should not receive permanent architectural prominence.
    • Landing-page usefulness: The page helps someone understand the selection and continue shopping. Links cannot compensate for an unclear category, irrelevant products, or an experience dominated by unavailable inventory.

    A practical approval record can be short. For every proposed target, write down the target URL, its business purpose, the demand it serves, the inventory owner, and whether it is permanent, recurring, or temporary. That forces the team to distinguish a real category opportunity from a request for more SEO attention.

    Be especially selective with filters. Color, size, brand, material, price, and other facets can produce a large population of URL combinations. Opening internal paths to all of them can slow the discovery of more useful content. Promote a filtered landing page only when it has distinct demand, dependable inventory, a stable purpose, and enough structural support to function as a genuine category.

    If a URL fails those tests, more internal links are not the remedy. Improve or consolidate the page, keep the filter available for shoppers without broadly promoting its URL, or direct attention to the stronger parent category.

    Audit the gap between business priority and site architecture

    Tabletop model contrasting prominently displayed product collections with uneven pathways through a digital storefront structure.

    Once you have a qualified set of categories, compare what the business considers important with what the site currently presents as important. This is the central diagnostic step.

    Google can infer a page’s relative importance from internal-link relationships, including how many internal links lead to the page and how many links a crawler must follow to reach it. Shoppers receive a similar message: categories exposed in navigation and related content look central, while deeply buried categories look peripheral.

    Run the audit in this order:

    1. Set the commercial priority first. Label each approved category as a current priority, a category to maintain, or a low-priority page. Do this before reviewing SEO metrics so existing visibility does not quietly become your definition of importance.
    2. Crawl from the shopper-facing site. Record the shortest click path from the homepage, the number of crawlable internal links pointing to each category, and the templates or pages supplying those links.
    3. Separate structural links from incidental links. A persistent navigation link, a parent-category path, an editorial recommendation, and an old campaign link do not play the same role. Label the source and placement instead of treating every link as interchangeable.
    4. Check relevance. Inspect whether the linking pages share a real product, audience, or shopping relationship with the target. A large count of unrelated links can conceal a weak architecture.
    5. Find mismatches. Prioritize categories with high commercial importance but weak site support. Also flag low-priority categories that still occupy prominent navigation or receive extensive legacy links.

    Use relative comparisons within your own catalog. A universal target for click depth or link count would ignore differences in store size, navigation design, and taxonomy. Compare equivalent category types, then look for outliers.

    Business priorityCurrent site supportWhat it meansRecommended action
    HighLowThe architecture understates a qualified opportunity.Find relevant, prominent pages that can supply links.
    HighHighThe site already reflects the priority.Maintain the paths; investigate other constraints before adding more links.
    LowHighLegacy architecture may be spending attention on an outdated priority.Review navigation and inherited modules before promoting new targets.
    LowLowThe architecture and current business priority are aligned.Leave it alone unless its role changes.

    This matrix prevents a common mistake: assuming that every important category needs more links. If a category is already easy to reach, prominently represented, and supported by relevant pages, its problem may be weak inventory, poor intent alignment, or an unhelpful landing page. Another batch of links would obscure that diagnosis.

    Place links where they help someone continue shopping

    Shopper viewing image-only product panels for trail shoes, hiking socks, outdoor clothing, and backpacks connected in a natural shopping sequence.

    After identifying an under-supported category, choose donor pages by relationship rather than raw authority. The best question is simple: would a shopper on this page reasonably want to explore that category next?

    Consider link locations in descending order of structural fit:

    1. Primary navigation: Reserve this scarce space for durable categories that matter broadly to the business and to shoppers. A short campaign or narrow subcategory rarely belongs here.
    2. Parent categories: A broader department or collection is often the clearest route to an important child category. Make the child visible in the page’s category list or other useful navigation, rather than relying on filters alone.
    3. Closely related categories: Add a related-category module when the destination is a plausible alternative or next step. The relationship should remain understandable without an SEO explanation.
    4. Buying guides and editorial content: Link when the content discusses the product type or helps the reader choose it. This connects informational intent with an appropriate shopping destination.
    5. Recurring seasonal hubs: Use them to support stable seasonal categories while the relationship is useful. Do not let expired promotional pages become the category’s only meaningful route.

    Use anchor text that identifies the destination in ordinary language. The category name is usually clearer than a vague phrase such as “shop now” or an awkward string of keyword variations. Surrounding copy should explain why the destination is relevant; the link should feel like part of the shopping decision, not an SEO insertion.

    Keep the implementation crawlable and consistent with the site’s existing components. Test the final rendered page rather than approving a design mockup alone. Confirm that the link resolves to the intended URL, appears for users and crawlers, works on mobile, and does not point through an unnecessary redirect.

    Avoid solving every mismatch with global navigation or a sitewide footer. Broad placements multiply links quickly, but they ignore context and consume space across the entire store. A focused set of strong paths from parent, related, and editorial pages usually tells a more coherent story about the category’s role.

    Roll out changes as an allocation test

    Internal-link changes often coincide with promotions, inventory shifts, content launches, paid campaigns, and seasonal demand. Without a record of what changed, an improvement or decline becomes difficult to interpret.

    Create a change log with the target category, donor page, placement type, anchor text, implementation date, and business reason. Capture a baseline before release for:

    • the target’s click path and internal-link sources;
    • organic impressions, clicks, and landing-page visibility;
    • shopper clicks on the new link or module;
    • category entrances, product engagement, and conversion outcomes;
    • inventory availability and any promotions affecting demand.

    When possible, phase the work by category group instead of changing the whole taxonomy at once. Keep a comparable set of qualified categories unchanged during the same period. It will not create a perfect experiment, but it gives you a better reference point than a simple before-and-after comparison.

    Look for a coherent chain of evidence. The new paths should be live and used; the target should become easier to discover; search visibility should move in a useful direction; and the traffic should produce meaningful shopping behavior. A ranking movement without inventory, engagement, or commercial value is not enough to justify permanent prominence.

    Review allocation when the business changes. A category that deserved navigation space during a sustained growth phase may later belong under its parent. Likewise, a category with emerging demand and dependable inventory may outgrow its old position. Internal architecture should reflect current priorities without swinging with every short promotion.

    FAQ: ecommerce category internal linking decisions

    Should every category receive a similar number of internal links?

    No. Equal counts would treat strategic categories, utility filters, temporary collections, and minor subcategories as if they had the same role. Allocate links according to business importance, search opportunity, inventory, durability, and relevance.

    Should a buried priority category go into the main navigation?

    Only when it is durable, broadly useful, and important enough to justify scarce navigation space. A narrower category may be better supported through its parent, related collections, and relevant buying content. The right correction is the clearest useful path, not automatically the most global placement.

    Should filtered pages receive internal links?

    Most filter combinations should remain shopping tools rather than promoted landing pages. Support a filtered URL only when it represents distinct and sustained demand, carries adequate inventory, has a stable purpose, and deserves a defined place in the taxonomy.

    Can internal links fix an underperforming category?

    They can correct weak discovery and an architecture that understates the category’s importance. They cannot create search demand, replenish inventory, clarify a confused taxonomy, or make a weak landing page useful. Diagnose those constraints before treating link volume as the answer.

    Start with one qualified category that the business values but the site currently hides. Document the mismatch, add the smallest set of relevant paths that corrects it, and measure the entire journey from discovery to commercial outcome. That gives you a defensible model for the next category instead of another sitewide link rule.

    References


  • How to Run an AI Citation Source Audit That Drives Action

    How to Run an AI Citation Source Audit That Drives Action

    You can rank well in traditional search and still be nearly absent from the pages AI assistants use to support answers about your market. When that happens, publishing more content without inspecting the citation trail is guesswork.

    An AI citation source audit shows which domains ChatGPT, Gemini, and Claude cite for your brand, which competitors those sources favor, and where a content or PR intervention has a realistic path to influence. The goal isn’t a longer spreadsheet. It is a defensible list of actions tied to actual prompts, answers, claims, and URLs.

    Define the decision your audit needs to support

    “Where does AI get its information about us?” is too broad to guide an audit. The useful version names the decision you need to make. You might need to decide which publications to pitch, which inaccurate claims to correct, which comparison pages to improve, or where a competitor has earned third-party validation that you lack.

    Write that decision at the top of your worksheet. It prevents the audit from drifting into a collection of interesting but unactionable mentions.

    Then separate three things that teams often collapse into one metric:

    • Brand mention: Your name appears in an answer, whether or not a link supports it.
    • Owned citation: The answer links to a page on your domain.
    • Third-party citation: The answer uses another domain to substantiate a claim about you, your competitors, or the category.

    Those outcomes require different responses. A mention without a citation may reveal awareness but provides no evidence about which external page shaped the answer. An owned citation creates a content-maintenance task. A third-party citation can become a media, partnership, reputation, or listing opportunity.

    Set the audit boundary before collecting anything. Record the market, audience, geography, language, products, competitors, and buying stages that are in scope. If the business has several unrelated product lines, audit them separately. Otherwise, a strong citation footprint for one line can conceal a serious gap in another.

    Your basic record should be the individual prompt-and-answer pair, not merely the cited domain. Keep these fields:

    • Exact prompt
    • Prompt theme and journey stage
    • AI platform and visible mode or model label
    • Date and relevant account, location, or language context
    • Brand mentioned or absent
    • Competitors mentioned
    • Exact claim associated with the citation
    • Cited page URL and root domain
    • Citation placement, such as inline or in a linked source list
    • Whether the page genuinely supports the claim
    • Accuracy or reputation issue
    • Recommended owner and next action

    This level of detail matters because the same domain can help in one answer and hurt in another. A simple domain tally cannot show that distinction.

    Build prompts around real discovery and buying decisions

    A brand-name prompt tests recognition. It does not represent the full discovery journey. If every test includes your brand, you can produce reassuring results while missing the prompts where an unfamiliar buyer first encounters the category.

    Build a prompt matrix that covers different kinds of intent:

    • Category discovery: Questions asking what kinds of solutions exist for a problem.
    • Problem diagnosis: Questions describing a symptom, obstacle, or desired outcome without naming a product category.
    • Comparison: Questions asking how approaches, products, or named competitors differ.
    • Recommendation: Questions seeking suitable options for a defined use case or audience.
    • Validation: Questions about trust, evidence, reputation, limitations, or suitability.
    • Implementation: Questions about setup, migration, integration, or ongoing use.
    • Branded evaluation: Questions that name your organization and ask what it does, who it serves, or how it compares.

    Use the language a buyer would use before they know your internal terminology. Product teams tend to write prompts with precise feature names. Buyers often describe the job, risk, or constraint instead. Include both forms and keep them as separate rows so you can see whether the citation landscape changes.

    Do not cram several intentions into one prompt. A question that asks for a recommendation, comparison, price assessment, implementation plan, and risk analysis creates an answer that is difficult to classify. Each prompt should expose one main decision.

    Keep the testing conditions visible

    AI answers can vary with the platform, available search mode, conversation context, and phrasing. That does not make auditing pointless. It means your evidence needs enough context to be interpreted later.

    Run each prompt in a fresh conversation unless conversation history is deliberately part of the scenario. Save the exact wording rather than a cleaned-up paraphrase. Record whether web access or a comparable source-discovery mode appeared to be active. If you rerun a prompt, preserve both observations instead of replacing the earlier result.

    Avoid teaching the assistant about your brand before asking the test question. Pasting your positioning statement and then asking which companies lead the category measures how the assistant uses supplied context, not whether your brand is discoverable independently.

    Capture the citation trail without losing the evidence

    A hand links an AI answer fragment to a source-page card and an organized evidence packet on a desktop.

    Collection is where a useful audit often turns into an unreliable one. Copying only the domain discards the relationship among the prompt, the answer, the claim, and the cited page. Preserve that relationship with a consistent workflow.

    1. Run the prompt exactly as written. Do not add a clarifying follow-up until the original answer has been saved.
    2. Capture the complete answer. Preserve the wording and citation placement, not just the sentence containing your brand.
    3. Extract every cited URL. Keep the full page URL and add the root domain in a separate field.
    4. Connect each URL to a claim. Record what the link appears to support: a recommendation, fact, comparison, warning, or general background statement.
    5. Open the page. Confirm that it exists, is the intended page, and contains evidence relevant to the associated claim.
    6. Label the result. Mark your brand as cited, mentioned without citation, omitted, or represented inaccurately. Record the same outcome for named competitors.
    7. Assign the next action. Choose a concrete route such as correct, update, pitch, contribute, earn inclusion, monitor, or take no action.

    Do not treat every displayed link as valid evidence. A URL can resolve while failing to support the sentence beside it. It can also point to an old page, a derivative summary, or a page about a similarly named entity. These are accuracy findings, not successful citations.

    Also distinguish citation placement. An inline link attached to a specific claim is different from a page included in a general source list. Both belong in the audit, but they should not be interpreted as equivalent support.

    Normalize URLs only after preserving the original. Remove obvious tracking parameters in your analysis field, consolidate equivalent URL variants, and keep separate pages separate. Collapsing everything to the domain level too early hides which asset type is actually being selected.

    Turn the URL inventory into an opportunity map

    A strategist examines a landscape of source tiles, citation paths, open gateways, and symbols for content, outreach, and reputation work.

    The first useful output is not a leaderboard. It is a map of how information travels from publishers, communities, reference pages, directories, vendors, and your own site into answers that affect the buyer’s decision.

    Classify every cited page by role:

    • Owned information: Your product, company, documentation, help, or editorial pages.
    • Independent editorial coverage: Reporting, analysis, reviews, or industry commentary.
    • Comparison and recommendation content: Roundups, alternatives pages, rankings, and buying resources.
    • Reference material: Definitions, standards, research, or other evidence-led resources.
    • Community discussion: Forums, question-and-answer threads, and other user-contributed discussions.
    • Directory or profile data: Listings and structured company or product records.
    • Commercially connected content: Partner, affiliate, reseller, marketplace, or vendor-controlled pages.

    The classification tells you which intervention is plausible. You can update an owned page directly. You may be able to correct a directory profile. You can pitch an editor with evidence, but you cannot rewrite independent coverage. You can participate transparently in a community, but manufacturing endorsements would create a reputation problem rather than solve one.

    Calculate a compact set of signals while retaining the underlying rows:

    SignalHow to read itDecision it supports
    Citation coveragePrompts in which your brand has supporting citations relative to the prompts testedShows where you are present, not whether the representation is favorable or accurate
    Accuracy statusCitations whose associated claims are accurate, incomplete, outdated, or wrongSeparates visibility work from correction work
    Competitive gapPrompts where competitors receive relevant support and your brand is absentIdentifies the query themes and third-party pages worth investigating
    Repeat domain presenceDomains appearing across several relevant prompt themes or platformsHighlights relationships and placements with broader potential value
    Domain concentrationThe extent to which citations depend on a narrow group of domainsReveals whether visibility is resilient or reliant on a small set of intermediaries
    Source-role mixThe balance among owned, editorial, community, reference, directory, and commercial pagesShows whether the next move belongs to content, PR, partnerships, reputation, or data maintenance

    Keep results separated by platform, prompt theme, and journey stage before calculating any overall view. A combined total can hide an important pattern, such as strong citations for implementation questions but no presence in category discovery or comparisons.

    Prioritize with judgment rather than a decorative score. Put each finding into an action tier:

    • Correct now: A cited page supports a materially wrong, outdated, or confusing claim about your organization.
    • Pursue next: A relevant independent domain appears repeatedly in prompts tied to an important buyer decision, and there is a legitimate route to contribute evidence or earn consideration.
    • Strengthen: Your owned page is cited but does not answer the associated question clearly, or a substantiated first-party resource is missing.
    • Monitor: A page appears in an isolated or low-relevance context with no sensible intervention.
    • Decline: The opportunity requires payment without clear disclosure, manufactured sentiment, or another tactic that would undermine trust.

    A high-frequency domain is not automatically your best target. Relevance, claim accuracy, editorial fit, and a credible access route matter more than raw appearances. A smaller specialist publication that is repeatedly cited for your buyer’s exact concern may deserve attention before a large general-interest domain.

    Convert the audit into content, PR, and reputation work

    Every priority finding needs an owner, an asset, an ask, and a verification step. Without those fields, “improve AI visibility” becomes an indefinite objective that no team can execute.

    Match the action to the cited page’s role:

    • Owned page: Correct the claim, answer the relevant question directly, show the supporting evidence, and keep important entity details consistent across the site.
    • Editorial coverage: Identify the coverage gap and offer verifiable information, an expert contribution, a useful dataset, or a legitimate update. Do not frame the outreach as a request to manipulate an AI answer.
    • Comparison page: Determine the inclusion criteria before contacting the publisher. Supply factual differentiation and evidence that helps the page serve its readers.
    • Reference resource: Create or expose the strongest substantiation you can stand behind. Unsupported marketing language is not a replacement for evidence.
    • Directory or profile: Correct missing, inconsistent, or outdated fields through the available listing process, then verify the public record.
    • Community discussion: Participate only where you can answer the question transparently and disclose your connection. Treat recurring complaints as product or support intelligence, not as threads to overwhelm with promotion.
    • Inaccurate third-party claim: Document the precise error and the evidence needed to correct it. Use the publisher’s correction route rather than demanding favorable wording.

    For each target, write a one-line action brief: the prompt gap, the cited page, the claim you need to support or correct, the evidence available, the outreach or publishing route, and the person responsible. That brief is specific enough to become a task without another strategy meeting.

    On your own site, make the supporting page easy to interpret. Use a stable URL, a descriptive title, a direct answer, clear entity names, visible authorship or ownership where relevant, an update date when freshness matters, and links to the evidence behind material claims. Accurate structured data can clarify what a page represents, but it cannot turn a weak or unsupported assertion into a credible citation.

    Do not publish a new page for every missed prompt. Group gaps that share the same underlying intent and determine whether an existing page should be improved first. A page that clearly resolves the buyer’s question is more useful than a stack of near-duplicate pages designed around minor wording variations.

    Recheck the relevant prompts after a meaningful change has had time to become publicly accessible. Preserve the earlier observation, record the new one, and compare the exact citation trail. A changed answer can be encouraging, but it does not prove that a single edit caused the change. Look for repeated movement across related prompts before treating it as a durable result.

    Key takeaways

    • An AI citation source audit measures which pages and domains support answers, not merely whether an assistant recognizes your brand.
    • Test discovery, comparison, recommendation, validation, implementation, and branded prompts instead of relying on brand-name questions alone.
    • Preserve the prompt, answer, claim, full URL, citation placement, and testing context. A domain-only list is not enough.
    • Verify that every cited page actually supports the associated claim before counting it as useful visibility.
    • Prioritize accurate, relevant domains that recur around important buyer decisions and have a legitimate route for contribution or correction.
    • Translate every finding into a content, PR, listing, partnership, or reputation task with a named owner and a recheck condition.

    Start with one decision-critical product area and build the prompt matrix before opening an AI assistant. Once the evidence is captured cleanly, you will know whether the next move is to repair your own information, earn third-party validation, correct a misleading claim, or leave a low-value citation alone.

    References


  • Google Search Visibility Data Changed: What to Trust Now

    Google Search Visibility Data Changed: What to Trust Now

    Your SEO dashboard can look worse even when your site has not lost meaningful Google visibility. If total ranking keywords or SERP features suddenly collapse while clicks and leads remain steady, do not declare a ranking loss until you determine whether the site changed or the measurement system did.

    Google has changed how third-party tools can collect search results, altered an important result-depth parameter, and added first-party reporting for multimodal searches. The practical challenge is no longer choosing one perfect metric. It is knowing which question each metric can still answer.

    Three breakpoints changed the meaning of your trend lines

    A rank tracker can lose the ability to observe a result without your page losing its position. That distinction became more important after three Google changes:

    Each change makes large-scale collection more difficult or expensive. Losing num=100 means a provider can no longer request the first 100 results in one operation. Resolving passthrough links adds work for each affected result. A provider may respond by collecting fewer positions, sampling more aggressively, refreshing less frequently, or charging more for equivalent coverage.

    The distortion is most likely to appear deep in the results because positions below the first page are expensive to collect and usually less valuable to customers. This turns a platform’s total keyword count into two measurements at once: your site’s search footprint and the platform’s ability to observe that footprint. Treating it as a pure performance metric is now a category error.

    Recognize the signature of a collection failure

    Luminous result tiles pass through a scanning tunnel, where a blocked aperture causes only part of the continuing stream to reach the collection trays.

    A genuine visibility loss and a collection failure can both produce a falling graph. The distribution of the decline tells you which explanation is more plausible.

    For Reddit, Semrush data from May to June 2026 showed more than 60 million fewer ranking keywords and more than 13 million fewer SERP features. Those represented month-over-month declines of 25% and 21%, respectively, while estimated traffic remained steady. The loss also became progressively larger at deeper positions:

    Position bandChange from May to June 2026What the pattern indicates
    Position 1+16%The most visible rankings remained observable
    Top 3+11%High-value coverage did not collapse
    Positions 4-10-8%Loss began within the remaining first-page results
    Positions 11-20-28%Missing coverage accelerated beyond page one
    Positions 21-50-34%Deep-result visibility deteriorated sharply
    Positions 51+-35%The deepest rankings were the least observable

    This is not a universal benchmark. It is a diagnostic pattern. A real sitewide ranking collapse of that scale would not normally erase progressively more deep positions while expanding Position 1 and Top 3 counts and leaving estimated traffic unchanged. A depth-weighted decline points more strongly to reduced collection coverage.

    It can also make the surviving data look deceptively healthy. If a tool stops observing positions 40 through 80 but retains positions 1 through 10, the reported keyword total falls while the average position may improve. That apparent improvement is survivor bias, not necessarily better SEO.

    Use this sequence whenever a visibility graph breaks:

    1. Start with business outcomes. Check whether organic leads, sales, sign-ups, or other meaningful actions declined during the same period. Stable outcomes do not prove that rankings were stable, but they reduce the likelihood of a commercially significant collapse.
    2. Check Google Search Console clicks and landing pages. If third-party keyword totals plunge while clicks and the pages receiving those clicks remain broadly stable, investigate collection coverage before changing content.
    3. Split rankings into Position 1, Top 3, positions 4-10, 11-20, 21-50, and 51+. A drop concentrated in the deepest bands is more consistent with an observation problem than an across-the-board ranking loss.
    4. Compare branded and non-branded priority queries separately from the provider’s entire discovered keyword universe. A controlled set of commercially important queries is more useful for tactical decisions than a volatile inventory of every term the tool happened to find.
    5. Look for provider-specific discontinuities. If one platform changes abruptly while first-party clicks, outcomes, and another independent ranking view do not, label the event as a probable measurement break.
    6. Allow for mixed diagnoses. A collection change and a real traffic decline can happen together. If clicks, conversions, important landing pages, and high-ranking priority queries all deteriorate, continue the SEO investigation even if deep-result coverage also changed.

    Rebuild reporting around questions, not one visibility score

    No single visibility number can now support every decision. Give each reporting layer a defined job and state its limitation beside it.

    Reporting layerUse it to answerMain limitation
    Business outcomesIs organic search contributing qualified leads, sales, or other valuable actions?Demand, attribution, and conversion behavior can change independently of rankings
    Google Search Console clicks and pagesDid Google Search send traffic, and which landing pages received it?Reporting definitions and automated search activity can affect historical comparability
    Priority rank setDid a controlled set of branded, commercial, and strategically important queries move?Results vary by location, device, and the provider’s collection method
    Total keywords and SERP featuresWhere might new topics, competitors, or result features be emerging?These inventory metrics are highly exposed to collection-depth changes
    Multimodal performanceAre visual search experiences discovering the site’s content?It is a distinct search surface and does not replace conventional ranking or generative AI query data

    Your report also needs a measurement change log. Record the date, affected tool, affected metric, likely mechanism, position bands involved, and whether the provider changed its collection method. Put the annotation on the chart itself. A note hidden in a separate methodology document will not stop someone from treating the break as a performance event.

    Keep the original series, but do not draw an unqualified continuous trend across an incompatible baseline. Compare periods collected under the same method where possible. If that is not possible, present pre-change and post-change periods as separate regimes and label the comparison as measurement-affected. Do not invent a correction factor unless you have enough overlapping data to defend it.

    September 2026 year-over-year reports require particular care. Search Console impressions fell after num=100 disappeared in September 2025 because automated requests had previously generated impressions for deep results. That creates a suppressed comparison baseline, so double-digit year-over-year impression growth can appear without an equivalent improvement in actual performance.

    Do not present that percentage alone. Put absolute clicks, business outcomes, priority-query movements, and landing-page performance beside it. If only impressions rebound against the lower baseline, describe the result as affected by measurement history rather than evidence of equivalent SEO growth.

    Measure multimodal discovery as a separate search surface

    An object on a pedestal is examined through three separate pathways represented by a visual sensor, an acoustic sensor, and a magnifying lens.

    While third-party result coverage is becoming less complete, Search Console is adding a first-party view of visual discovery. Its multimodal search filter covers Google Lens, Circle to Search on Android, image uploads to Google Search, and Chrome’s Search this image action. The data is rolling out globally and appears when a site receives traffic from those experiences.

    Multimodal visibility should not be folded silently into a general visibility score. A person searching with an image is expressing intent differently from someone typing a conventional query, and the optimization work is often different. Track the surface separately so you can see whether visual discovery is growing, which pages participate, and whether that exposure leads to useful behavior.

    • Record when multimodal data first becomes available for your property. Do not interpret the first visible reporting period as the date your site first appeared in visual search.
    • Review the landing pages associated with multimodal activity. Check that their images are useful to the page’s purpose, accessible to crawlers, supported by clear nearby text, and described with accurate text alternatives.
    • Keep structured data faithful to the visible page. Schema can clarify products, organizations, articles, and other entities, but it should not describe an image, offer, or claim that users cannot find on the page.
    • Connect multimodal reporting to page-level outcomes. More visual discovery is interesting; it becomes valuable when the discovered pages attract relevant engagement or conversions.
    • Do not manufacture query-level precision where Google does not supply it. The generative AI search performance report still lacks click and query data, so a generative visibility narrative should acknowledge that blind spot.

    The new filter is an additional lens, not compensation for missing third-party keyword coverage. It answers a new question: whether people are finding your content through visual and multimodal behavior. It does not tell you that a disappearing position-50 keyword remained stable, and it does not provide the prompt-level attribution many teams want from generative search.

    Key takeaways for your next SEO report

    • A falling third-party keyword count is not, by itself, evidence of lost Google traffic.
    • A decline concentrated below positions 10 or 20 is more suspicious as a collection problem than a uniform loss across top rankings.
    • Clicks, landing pages, and business outcomes should determine the severity of the response; discovered keyword totals should support exploration, not act as the verdict.
    • January 2025, September 2025, and August 2026 belong in your reporting change log because each altered how search visibility could be observed.
    • September 2026 year-over-year impression growth may be inflated by the lower post-num=100 baseline from September 2025.
    • Multimodal reporting deserves its own baseline, goals, and page-level analysis. Do not merge it into conventional web or generative AI visibility without a label.

    Before your next report goes out, annotate the three collection breakpoints, split ranking data by depth, and place first-party clicks and business outcomes ahead of total keyword counts. Then establish a separate baseline for multimodal discovery. That small reporting redesign can keep a measurement change from triggering the wrong content rewrite, budget decision, or performance diagnosis.

    References


  • How to Tell Whether an SEO Audit Is Worth the Money

    How to Tell Whether an SEO Audit Is Worth the Money

    You have an SEO audit proposal in front of you, but the deliverables sound suspiciously like a list of errors from a crawling tool. The price may buy expert investigation, or it may buy an export you could generate yourself.

    The difference is judgment. A valuable audit identifies which findings are real, explains why they matter to your business, accounts for intentional choices and technical constraints, and gives your team a safe order of operations. Use the framework below before signing a proposal or implementing recommendations from an audit you have already received.

    Start with the decision the audit must unlock

    An audit cannot be valuable in the abstract. It has to help you make a decision: what to repair, what to improve, what to leave alone, and where to invest next.

    Write the audit’s job as one sentence before discussing tools or deliverables. For example:

    • Find out why commercially important pages are not being crawled, indexed, or discovered.
    • Determine whether a site migration introduced technical problems that are suppressing organic visibility.
    • Identify which content gaps prevent the site from satisfying the audience’s most important questions.
    • Separate genuine technical defects from warnings that do not affect search performance.
    • Assess whether search and AI visibility lead visitors toward a meaningful conversion.

    That sentence becomes your first acceptance criterion. If a recommendation does not help answer the stated question, it should not outrank work that does.

    The auditor also needs context that a crawler cannot collect on its own. At minimum, provide your business goals, priority audiences, important products or services, conversion paths, recent site changes, platform constraints, known technical debt, and any SEO decisions your team made intentionally. Without that context, an automated warning can easily be mistaken for a defect. Implementing the resulting recommendation may waste development time or reduce visibility instead of improving it.

    AI search does not make this discovery work optional. Many large language model experiences use retrieval and existing search results to find information with which to construct or check an answer. Your pages still need to be accessible, indexable, relevant, credible enough to surface, and useful once someone arrives. That makes an effective SEO audit part technical review, part content evaluation, and part business analysis. Calling the same crawler export a GEO audit does not add value.

    A valuable audit adds judgment to crawler data

    A specialist inspects a layered website structure with a magnifying lens while automated devices flag both harmless details and one broken connection.

    Crawlers are useful. They can expose URLs, response behavior, directives, internal linking patterns, metadata, and other machine-readable signals at a scale that manual browsing cannot match. The mistake is treating those observations as conclusions.

    This distinction matters because professional audits can cost from $2,500 to more than $20,000, depending in part on the size of the site and the engagement. Screaming Frog and Sitebulb cost a fraction of that amount, and trial access may be available. Run one of them against your site before buying an audit. You do not need to become a technical SEO; you only need enough familiarity to recognize when the final deliverable reproduces automated output without adding analysis.

    Part of the workLow-value outputUseful audit work
    DiscoveryRepeats crawler warnings and severity labelsCombines automated findings with manual investigation
    ContextAssumes every unusual configuration is wrongChecks business intent, technical debt, templates, and platform constraints
    EvidenceNames an issue without showing its scopeProvides affected URLs, patterns, or examples when they are needed
    ExplanationUses generic wording that could describe any siteExplains what is happening on your site, why it matters, and what may have caused it
    RecommendationIssues a universal command such as fix all or remove allTailors the action to your goals and identifies exceptions, dependencies, and risks
    PriorityCopies a tool’s high, medium, or low labelOrders work by likely business impact, effort, confidence, and potential downside
    HandoffEnds with a list of tasksClarifies ownership, implementation needs, and how the result will be checked

    Ask the auditor to walk you through one finding using that table. A convincing answer should distinguish what the tool detected from what manual review established. It should connect the issue to your audit objective, explain the proposed change, identify what could be affected, and state how your team will know whether the change worked.

    Generic explanations are another warning sign. Crawler documentation often explains why a category of warning may matter. Paying an expert makes sense when the expert can determine whether it matters here. A useful explanation names the relevant part of your site and shows the path from observation to consequence. If the same paragraph could be pasted into an audit for an unrelated company, it is probably documentation rather than analysis.

    Test every recommendation before it enters the backlog

    A technical team tests a website component in a transparent staging chamber before moving it toward a balanced production structure.

    A long audit can feel substantial while still being difficult to use. Do not judge it by page count, warning count, or the number of charts. Judge each recommendation by whether your team can verify, understand, execute, and measure it.

    Is the finding valid?

    Start with the evidence. Which URLs, page types, templates, queries, or journeys are affected? Is the pattern consistent? Did manual review confirm the crawler’s interpretation? Could the behavior be intentional?

    A tool can tell you that two pages look similar or that a directive blocks crawling. It cannot reliably decide whether the pages serve different audiences or whether the directive protects low-value areas from unnecessary crawling. The audit should resolve that ambiguity, not hide it beneath a severity label.

    Is the finding material?

    Connect the issue to a meaningful outcome. Does it prevent discovery or indexing? Does it weaken the page’s relevance for an important audience? Does it make a valuable page harder to navigate? Does it obstruct the conversion path?

    Not every technically imperfect detail deserves engineering time. An audit should make that trade-off visible. The useful question is not whether a warning exists; it is whether resolving that warning is a better use of resources than the competing work in your backlog.

    Is the recommendation executable and safe?

    Your implementation team should be able to identify the target, desired behavior, dependencies, owner, and exceptions. The auditor should provide examples where that falls within their expertise. Where it does not, they should still explain what needs to change and why, then identify the type of specialist required.

    Be especially careful with recommendations that affect server configuration, templates, directives, canonicals, redirects, or large groups of URLs. A blanket change can alter access to far more pages than the audit intended. Do not send ambiguous instructions straight into production. Have a qualified developer define the implementation, use your normal review and testing process, and preserve a rollback path.

    Can you verify the result?

    Define completion before implementation. A technical change may be complete when the intended URLs return the expected behavior and the crawler confirms no unintended pattern. A content change may require checking discovery, relevant search visibility, qualified visits, and the next step in the conversion journey.

    Separate implementation validation from performance evaluation. The first asks whether the change was deployed correctly. The second asks whether it improved the outcome that justified the work. Without both, your team can close tickets without learning whether the audit created value.

    For a fast review, label every recommendation Keep, Clarify, or Reject. Keep it when the evidence, consequence, action, risk, and validation plan are clear. Mark it Clarify when one of those elements is missing. Reject it when manual review disproves the finding, the action conflicts with an intentional decision, or the likely value does not justify the risk and effort. This turns an intimidating report into a governed backlog.

    Protect the engagement in the scope and contract

    You should know what will be delivered before the crawl begins. A strong scope does not merely promise an SEO audit. It describes the investigative work, the form of the evidence, the method of prioritization, and the handoff.

    • Manual review: Require investigation beyond crawler, analytics, or LLM output.
    • Site-specific reasoning: Require each material finding to explain its relevance to your site, audience, and business objective.
    • Evidence: Specify that affected URLs, templates, examples, or patterns will be included where needed.
    • Prioritization: Ask for impact, confidence, effort, dependencies, and implementation risk rather than tool-generated severity alone.
    • Handoff: Define whether the fee includes a walkthrough, questions from developers, implementation examples, or post-change validation.
    • Exclusions: Record what the auditor will diagnose but cannot implement, and who is expected to own that work.
    • Early notification: Require the auditor to tell you if manual investigation finds nothing material beyond automated output.

    A refund or scope-change provision can make the final point enforceable. One practical starting point is: The deliverable must include material findings from manual review and site-specific reasoning beyond automated crawler or LLM output. If the auditor determines that no such findings exist, the parties will agree to a revised scope or an appropriate partial refund before final delivery. A deliverable consisting solely of automated output triggers a full refund.

    That language carries commercial and legal consequences, so have your procurement team or counsel adapt it to the engagement and local requirements. The purpose is not to prohibit crawlers or AI assistance. Those tools can support the work. The provision makes clear that your fee purchases human discovery, interpretation, and prioritization rather than undisclosed automation.

    If the investigation finds that a full audit is unnecessary, do not force production of a padded report. Agree on the useful alternative before the work continues. Depending on the professional’s actual skills and your original goal, the remaining effort might be redirected toward content, development planning, conversion analysis, analytics, or another defined need. Document the revised deliverable and price so goodwill does not replace accountability.

    You can also evaluate the auditor’s fit before signing. The relevant expertise depends on the question you need answered. A crawl and indexation problem calls for strong technical and development literacy. A visibility problem may require content and audience analysis. An engagement expected to connect traffic with revenue needs analytics and conversion competence. No individual has to implement every discipline, but the proposal should state where the auditor’s expertise ends and how gaps will be handled.

    Key takeaways

    • An audit fee should buy judgment, prioritization, and a safer decision path, not merely crawler data.
    • Define the business question first; recommendations that do not help answer it should not dominate the backlog.
    • Run a crawler yourself before hiring so you can distinguish automated output from expert investigation.
    • Require manual review that accounts for your audience, goals, intentional decisions, technical debt, and conversion path.
    • Accept a recommendation only when its evidence, consequence, action, risk, ownership, and validation method are clear.
    • Put site-specific deliverables, early notification, scope revision, and refund terms in the agreement before work begins.
    • Evaluate AI-search readiness through the same fundamentals: accessible and indexable pages, relevant content, sufficient visibility, and a useful destination for the visitor.

    Open the proposal or completed audit now and highlight where it promises manual discovery, site-specific reasoning, prioritized action, implementation safeguards, and validation. Ask for a revision wherever one of those elements is absent. If recommendations have already reached your backlog, place the ambiguous ones on hold until someone can supply the missing evidence or context.

    The right audit leaves you with fewer uncertainties, not simply more tasks. Buy it when you need informed decisions that your tools and internal context cannot produce separately.

    References


  • Search Console Indexing Data Gap: What to Check First

    Search Console Indexing Data Gap: What to Check First

    Your Page indexing chart runs normally, goes blank for several June dates, and then resumes. That pattern can look like mass deindexing at first glance. It is not. A missing observation is not a zero, and it does not show that Google removed your URLs.

    The June 2026 pattern was broadly observed across Search Console profiles. Google’s John Mueller said the Page indexing report was not updated during the affected period and the missing indexing data would not be backfilled. Your immediate job is therefore to confirm that your graph has the same fingerprint, verify the site’s present condition with independent evidence, and preserve the gap honestly in your reporting.

    Key takeaways

    • A blank interval in the Page indexing chart means data is unavailable. It does not mean that zero pages were indexed.
    • Matching June dates across unrelated Search Console properties strongly supports a platform reporting gap, especially when data resumes afterward.
    • The missing history cannot tell you what happened inside the gap. Current URL checks, server logs, technical controls, and search activity can tell you whether a problem exists now.
    • Do not change canonicals, robots directives, noindex rules, or sitemaps just to repair the chart. Those actions cannot recreate missing report data.
    • Record the affected dates as unavailable, not zero. Do not interpolate the gap and present the result as observed Search Console data.

    Confirm that you are looking at the June reporting gap

    Start with the shape of the graph. A decline and a data gap are different events. A decline gives you plotted values that move downward. A data gap removes observations from the time series altogether. Neither pattern proves its cause, but confusing one for the other sends the investigation in the wrong direction.

    1. Capture the visible boundaries. Record the first and last missing dates shown in each affected property. Use the dates in your own interface rather than copying a range from somebody else’s screenshot.
    2. Distinguish an empty interval from a zero value. If the chart has no point or line for a date, treat the value as unavailable. Do not enter zero indexed pages in a spreadsheet or dashboard.
    3. Compare properties. If you manage unrelated sites, check whether their Page indexing charts lose the same June dates. A synchronized hole across separate hosts is much more consistent with a reporting problem than with simultaneous technical failures on every site.
    4. Inspect the values on both sides. Data resuming near its earlier range supports the reporting-gap explanation. A substantially different level after the gap deserves attention, but it still does not reveal when or why the change occurred.
    5. Write down any contradictory evidence. Unexpected URL Inspection results, changed server responses, new robots rules, organic landing-page losses, or a recent deployment should be investigated on their own merits.

    This check identifies what the chart can and cannot prove. It cannot prove that every URL remained indexed during the missing period. It also cannot support a claim that URLs were dropped. The observations needed to answer that historical question are absent.

    Validate present indexing with independent evidence

    Three diagnostic signals converge on an intact website structure to represent independent indexing checks.

    Once you have identified the reporting gap, switch from trying to recover the graph to checking the site’s current condition. Use evidence that comes from the URLs, your infrastructure, and search outcomes. No single check replaces the missing history, but agreement across these layers gives you a defensible operational decision.

    Inspect representative URLs

    Choose a small but deliberate sample in URL Inspection. Include the homepage, a recently published URL, an important commercial or conversion page, a typical editorial page, and a template that has had indexing trouble before. Selecting only the homepage can hide a template-level failure.

    Review the current indexing information, crawl access, and canonical information shown for each sample. The goal is not to reconstruct June. It is to find out whether Google currently sees the pages in the state you intended. If several URLs from the same template show the same unexpected condition, stop treating the matter as a chart-only anomaly and investigate that template.

    Check the controls that can actually affect indexing

    • Confirm that important URLs return the intended HTTP response instead of an error, redirect loop, or soft failure.
    • Check page-level noindex directives and robots controls for unintended restrictions.
    • Verify that canonical destinations still point where you expect, particularly on templated and parameterized pages.
    • Review whether important URLs remain represented correctly in the relevant sitemap.
    • Check deployments, CMS changes, migrations, security rules, and template releases around the period for changes that could affect crawling or indexing.
    • If retained server logs are available, examine Googlebot requests and the responses returned by the server. Logs can show crawler access even when the Search Console chart cannot show historical totals.

    A configuration change is evidence only when it affects the URLs and behavior in question. A deployment happening near the gap is not automatically the cause. Connect the change to a response, directive, canonical, rendering problem, or other observable mechanism before you roll it back.

    Compare search and analytics outcomes

    Review Search Console Performance data, analytics landing-page activity, and available server logs over the same broad period. Stable organic activity does not prove that every URL stayed indexed, but it makes a sitewide indexing collapse less plausible. A decline in traffic does not prove deindexing either; rankings, demand, tracking, site availability, and page changes can produce similar symptoms.

    Use these signals as corroboration. When current URL states, technical controls, crawl evidence, and organic landing activity all look normal, the blank Page indexing interval is reasonably handled as a reporting limitation. When several independent signals move together, you have grounds for a technical investigation even though the June graph itself remains unusable.

    Protect your site and your historical reporting

    Missing telemetry creates pressure to do something visible. Resist changes that target the chart instead of a confirmed site fault. Repeatedly submitting the same sitemap, requesting indexing for every URL, or altering indexation controls will not recreate historical observations that Search Console did not retain.

    • Do not bulk-change canonicals. You could create a genuine consolidation problem while trying to solve a reporting problem.
    • Do not remove robots or noindex controls without checking their purpose. Some exclusions are intentional and protect search quality, private areas, or duplicate URL spaces.
    • Do not treat mass indexing requests as a repair. A request concerns a URL’s current handling; it cannot repopulate an aggregate historical chart.
    • Do not rewrite missing values as zero. Zero means an observed count of none. The June gap means no report observation is available.
    • Do not smooth the line without disclosure. An estimate may be useful for an internal model, but it must remain visibly labeled as estimated rather than reported Search Console data.

    In a data warehouse or spreadsheet, store the affected values as null or unavailable. In a chart, leave a break in the line. If your reporting system cannot accept null values, exclude the affected dates from calculations and add a visible annotation instead of coercing them to zero.

    For trend analysis, use complete periods before and after the gap. You can describe the difference between those periods, but you cannot assign the change to a particular missing date or calculate a reliable daily rate across the break. If data resumes at a different level, call it a post-gap difference until other evidence establishes the timing and cause.

    Ready-to-use status note: Search Console Page indexing data is unavailable for [affected June 2026 dates]. The Page indexing report was not updated during that interval, and Google does not backfill the missing values. Current URL, crawl-control, log, and traffic checks show [stable or changed conditions]. We are treating this as [a reporting-only limitation or an open technical investigation].

    Know when to open a real indexing investigation

    An overhead diagnostic pathway separates a harmless reporting gap from warning signs that merit an indexing investigation.

    The known reporting gap should lower the urgency of the blank chart, not become an excuse to ignore other evidence. Escalate when the anomaly extends beyond the shared June interval or when URL-level and operational signals indicate a separate problem.

    • Missing Page indexing observations continue beyond the affected June dates shown across your other properties.
    • Representative URLs now show an unexpected indexing condition or canonical destination.
    • Important templates return errors, carry unintended noindex directives, block crawling, or produce inconsistent canonical signals.
    • Server logs show a meaningful crawl-access or response change that aligns with a site release or infrastructure event.
    • Organic landing-page activity and Search Console Performance data decline outside the missing Page indexing interval.
    • The Page indexing series resumes at a materially different level and stays there rather than returning to its previous range.

    If one of those conditions appears, define the affected cohort before making changes. Segment URLs by template, response, canonical target, publication period, and intended indexability. Find the earliest independent sign of the problem, map it to deployments or configuration changes, and fix only the mechanism you can confirm. That sequence prevents a broad, risky response to what may be a narrow fault.

    For the June 2026 gap itself, the practical next move is simple: annotate the unavailable dates, inspect representative URLs, and preserve null values in every downstream report. If the independent checks remain stable, continue your planned SEO work. If they do not, begin the investigation from the earliest reliable signal rather than from the blank graph.

    References


  • How to Run a Claude-Assisted CRO Audit You Can Trust

    How to Run a Claude-Assisted CRO Audit You Can Trust

    If Claude has given you a polished CRO audit in minutes, the dangerous part isn’t obvious nonsense. It’s a plausible explanation built around the wrong conversion, a mismatched reporting period, blended audiences, or a tracking change that looks like user behavior.

    You can prevent that. Use Claude to organize evidence, expose inconsistencies, and draft testable findings. Keep measurement validation, causal judgment, and prioritization under human control. The result will be slower than asking for instant recommendations, but far more useful to the team deciding what to change.

    Key takeaways

    • Define the primary conversion and a downstream quality measure before Claude sees your analytics.
    • Give Claude a one-page audit brief covering scope, dates, measurement sources, recent changes, constraints, and known data problems.
    • Build a compact evidence pack from analytics, search, page, business, and change-history data instead of uploading files without context.
    • Require every finding to separate observation from explanation and include evidence, scope, confidence, alternatives, validation, and a next step.
    • Treat correlations, screenshots, and aggregate reports as inputs to a hypothesis, not proof that a page element caused a conversion change.

    Start with the business outcome, not the GA4 key event

    A CRO audit can be analytically tidy and commercially wrong. That happens when the metric Claude is asked to improve isn’t the outcome the business actually values.

    Marking an event as a GA4 key event makes it more prominent in reporting. It does not establish that the event fires correctly, represents a qualified outcome, or deserves to be the decision metric for your audit. Validate those points separately.

    For ecommerce, a completed purchase is often a sensible primary conversion, but purchase rate alone can hide a bad trade. Review it beside revenue per session, average order value, discount use, cancellations, refunds, and margin. A variation that produces more discounted orders may lift purchase rate while weakening the result the business keeps.

    For lead generation, a form submission is usually an early milestone. A shorter form may generate more submissions while sending sales a lower-quality pipeline. When matching data is available, connect the on-site action to the next meaningful stage: meeting booked, meeting attended, sales-accepted lead, opportunity created, or closed-won revenue.

    Write a conversion contract

    Before opening a new Claude conversation, write down the following:

    • Primary conversion: The exact on-site action you want to improve.
    • Quality measure: The downstream CRM, revenue, retention, or margin outcome that stops you from optimizing for low-value conversions.
    • Measurement source: The GA4 event, CRM field, transaction field, or reporting view used for each outcome.
    • Relationship between measures: How an on-site event is matched to its downstream result, including any gaps in that match.
    • Decision boundary: What must remain healthy even if the primary conversion increases.

    For a B2B SaaS audit, that contract might name the completed demo-request form as the primary conversion and the share of submissions becoming sales-accepted leads within 30 days as the quality measure. Claude can then distinguish a form-volume improvement from a business-quality improvement.

    If downstream matching is unavailable, say so. Do not quietly substitute form volume for qualified demand. Label form completion as a proxy, record the missing quality evidence, and limit the strength of any recommendation that depends on it.

    Build a one-page brief and a compact evidence pack

    A blank one-page brief is surrounded by anonymized interface cards, audience tokens, a calendar strip, funnel pieces, and a magnifying glass.

    Your brief is the operating contract for the audit. Keep it short enough to review before each analysis session, but precise enough that a different analyst would select the same metrics, periods, and page scope.

    Claude Projects can keep chat history, uploaded reference material, and project-level instructions in one workspace. If you use a Project, place the approved brief beside the audit files and tell Claude to treat it as authoritative whenever a file label, event name, or date is ambiguous.

    Put these fields in the brief

    • Primary conversion and quality measure: Use the definitions from your conversion contract.
    • Date range and comparison period: State both explicitly. Do not make Claude infer them from filenames.
    • Scope: List the pages, templates, devices, markets, audiences, and acquisition channels included. State what is excluded.
    • Recent changes: Record releases, tracking edits, campaign shifts, pricing changes, consent-banner updates, promotions, and inventory problems that overlap the analysis period.
    • Known limitations: Include duplicate events, incomplete cross-domain tracking, consent-related gaps, bot traffic, small samples, and missing CRM matches.
    • Business constraints: Note qualification rules, service locations, inventory, legal requirements, brand rules, and realistic implementation capacity.
    • Metric ownership: Identify who can verify analytics, CRM, commerce, and implementation questions when the evidence conflicts.

    A consent-banner release in the middle of the reporting period is not background trivia. A recorded drop after that release could reflect a measurement change, a real behavioral change, or both. Claude can identify the timing overlap, but someone must inspect the implementation before the audit calls it a UX problem.

    Assemble evidence by the question it can answer

    A larger upload is not automatically a stronger evidence pack. Include each file because it helps answer a defined question:

    • GA4 export: Where does recorded conversion performance differ by landing page, template, channel, device, market, or audience? Preserve raw counts and denominators alongside calculated rates.
    • Search Console export: Did the organic search demand or landing-page mix change while conversion performance moved? This helps separate an acquisition shift from a page-performance hypothesis.
    • CRM or commerce data: Do the conversions retain quality and economic value after the on-site event?
    • Page captures: What messages, offers, forms, navigation choices, proof elements, and calls to action were visible in the reviewed page state?
    • Change log: What releases, campaigns, promotions, inventory conditions, tracking edits, or consent changes coincide with the pattern?
    • Business notes: Which apparently simple changes would violate qualification, service, inventory, legal, brand, or implementation constraints?

    Give each export an inventory entry containing its date range, filters, time zone, metric definitions, row grain, and known exclusions. If two files cannot be joined reliably, say that before analysis. A model should not be invited to invent a relationship between rows that only happen to share a similar label.

    Common audit material can be supplied as CSV, PDF, DOCX, JSON, HTML, or image files. XLSX can also be usable where code execution and file creation are enabled. Choose the format that preserves the fields and context you need; a visually polished PDF is a poor substitute for row-level data when the task requires filtering or segmentation.

    You can also connect approved systems through Model Context Protocol, an open standard for connecting AI applications to external systems through defined tools. Curated exports create a stable snapshot that is easier to reproduce. A governed connection can reduce manual export work, but it must still enforce the intended scope, date filters, permissions, and metric definitions. Prefer the least access the audit needs, and exclude personal CRM fields that do not contribute to the analysis.

    Make Claude analyze in passes instead of writing the report immediately

    Three connected inspection stages sort abstract evidence, flag inconsistencies, and place validated findings on ranked platforms under human control.

    “Audit these pages and improve conversions” is an invitation to generic advice. It asks for recommendations before Claude has established whether the measurement is usable, which audience is affected, or whether the page evidence matches the analytics period.

    Use separate passes with a review checkpoint between them. Each pass should narrow uncertainty rather than add another layer of polished prose.

    Check measurement integrity first

    Ask Claude to produce a measurement-issues register before it produces CRO findings. The register should identify:

    • Which event and field represent each conversion and quality measure.
    • Whether every file uses the brief’s audit period and comparison period.
    • Whether rates retain their counts and denominators.
    • Whether event definitions, tracking implementations, consent behavior, or reporting views changed during either period.
    • Which results rely on small or incomplete samples.
    • Which checks require analytics, tag-management, CRM, or implementation access that Claude does not have.

    A clean spreadsheet cannot prove that an event fires once, fires at the intended moment, or survives a cross-domain journey. When that verification is missing, the correct output is an open measurement question, not a confident page recommendation.

    Separate segment performance from traffic mix

    Blended conversion rate can move because the composition of traffic changed. A page can receive more visitors from a lower-intent channel, query group, device category, or market even when the experience within each group is stable.

    Ask Claude to compare like with like across the dimensions named in the brief. For an organic landing page, check Search Console demand and landing-page patterns beside GA4 outcomes. If the acquisition mix changed, preserve that as an alternative explanation. Do not let an overall decline become “the page got worse” by default.

    Keep segments with weak volume visible but clearly limited. Removing them hides uncertainty; treating them as conclusive exaggerates it. The useful question is whether the pattern is strong enough to justify more validation, not whether Claude can write a convincing reason for it.

    Review page evidence without pretending it shows behavior

    A screenshot or HTML capture can support observations about the reviewed page state. It may show where a call to action appears, what the form asks for, how an offer is described, or whether proof is present in the captured content.

    It cannot establish that users noticed an element, understood it, hesitated because of it, encountered a validation error, or abandoned because of it. Those are behavioral explanations. They require additional evidence or a test.

    Be precise about the difference:

    • Observation: “The mobile capture places the primary call to action after the product explanation.”
    • Hypothesis: “Some mobile visitors may not reach the call to action.”
    • Unsupported causal claim: “The call-to-action position caused the lower mobile conversion rate.”

    The first statement can be checked against the capture. The second defines something to validate. The third overstates what page imagery and aggregate analytics can establish.

    Force every finding into an evidence record

    Place a standing instruction in the Project rather than repeating a loose request in every chat. A practical version is:

    Project instruction: Use the approved audit brief and supplied files as evidence. Do not assume a GA4 key event is qualified unless the brief defines it that way. Label observed facts, interpretations, and hypotheses separately. Do not infer causation from correlation, screenshots, or aggregate analytics. If evidence is missing or contradictory, state that directly.

    Then require the same fields for every proposed finding:

    • Finding name: A neutral description, not a verdict.
    • Observation: What the supplied evidence directly shows.
    • Evidence reference: The file, table, page, capture, field, and relevant filter supporting the observation.
    • Affected scope: The page, template, audience, channel, device, or market to which the finding applies.
    • Business relevance: Its relationship to the primary conversion and quality measure.
    • Confidence: High, medium, or low, with a reason.
    • Alternative explanations: Traffic mix, seasonality, campaign changes, tracking changes, consent effects, promotions, inventory, or other plausible confounders present in the evidence.
    • Validation needed: The analytics check, implementation inspection, additional segmentation, user evidence, or quality-data match required before action.
    • Next step: A measurement repair, deeper analysis, page investigation, or experiment.

    This format makes weak reasoning visible. If Claude cannot point to the evidence behind an observation, the finding is not ready for the roadmap.

    Rank findings by evidence and business impact, not confident wording

    Claude’s tone is not a prioritization signal. A fluent explanation can rest on a thin sample, an unverified event, or a screenshot with no behavioral evidence. Use an explicit confidence rubric and treat it as a routing tool rather than statistical certainty.

    • High confidence: The observation is supported by validated measurement and relevant page or business evidence, while the major alternatives in the brief have been checked. Move it into test or implementation design.
    • Medium confidence: The pattern appears in relevant evidence, but an important confounder, data gap, or implementation question remains. Resolve that issue before committing development time.
    • Low confidence: The idea comes mainly from a heuristic review, a screenshot, a weak sample, or blended analytics. Keep it in the investigation backlog rather than presenting it as an optimization decision.

    Confidence alone still isn’t enough. A strong observation may affect a narrow, low-value audience. A modest-looking issue may touch the main conversion path or damage lead quality. For each finding, ask:

    • Does it concern the primary conversion or only an intermediate interaction?
    • Could the proposed change weaken the downstream quality measure?
    • Which users, pages, devices, markets, and channels are actually affected?
    • Has the underlying measurement been verified?
    • What plausible explanation could reverse the interpretation?
    • Can the idea be tested or validated without creating unnecessary implementation or business risk?

    Write a test brief that can fail

    A useful experiment is designed to challenge a hypothesis, not decorate a recommendation. Convert the surviving finding into this structure:

    • Affected segment: Name the users and page state covered by the evidence.
    • Proposed change: State exactly what will differ from the current experience.
    • Evidence-backed mechanism: Explain why the change might help while preserving uncertainty.
    • Primary measure: Use the conversion contract’s on-site outcome.
    • Quality guardrail: Use the downstream CRM, revenue, retention, or margin measure.
    • Diagnostic measures: Include only the intermediate behaviors needed to interpret the result.
    • Validity checks: Confirm tracking, eligibility, allocation, page state, campaign overlap, and relevant release history before reading the outcome.
    • Decision rule: Agree in advance how the team will handle an improvement, a neutral result, conflicting primary and quality outcomes, or an invalid test.

    Do not ask Claude to invent expected lift, sample requirements, or a decision threshold from the audit files. Set those with the people responsible for experimentation and measurement, using the site’s traffic, baseline performance, business risk, and chosen method.

    Not every finding needs an A/B test. A broken event calls for measurement repair. A suspected form error calls for implementation inspection. A traffic-mix question calls for segmentation. A low-confidence usability explanation calls for behavioral validation. Choosing the correct next method is part of the audit; “test everything” is not a substitute for diagnosis.

    Associations found in spreadsheets, screenshots, and aggregate analytics do not prove causation. Claude has done its job when it makes the evidence easier to inspect and the remaining uncertainty harder to ignore.

    Before your next audit, write the conversion contract and the one-page brief before uploading anything. Then ask Claude for a measurement-issues register, not recommendations. That first output will tell you whether you are ready to optimize the experience or still need to repair the evidence.

    References