You can win visibility in an AI answer and still see nothing obvious in your analytics. The answer may remove the need for a click, or the prospect may remember your brand and return later through search or a direct visit. In either case, a last-click report can make useful work look unproductive.
The answer is not to invent AI-generated revenue or abandon attribution. You need a measurement system that separates exposure, observable behavior, and business outcomes. Then you can use the three together to decide what to improve, even when no single platform reveals the full journey.
The customer journey has moved outside your analytics
Attribution is an accounting rule, not a camera. It assigns credit among the interactions your systems can observe. It cannot assign reliable credit to an answer that influenced someone without producing a trackable visit.
The familiar search-to-click-to-conversion path is especially incomplete in AI search. Discovery can now follow a prompt-to-synthesis-to-direct-visit journey: a buyer asks a question, an AI assistant combines information from several places, and the buyer later searches for a company, types its address, asks a colleague about it, or converts on another device. Conventional analytics may record only the final interaction.
AI referral traffic still matters because it is directly observable. It proves that at least some people moved from an AI interface to your site. But it is a floor, not a complete measure of influence. It excludes people who received a sufficient answer without clicking and people who returned through an unconnected route.
This leaves you with three separate questions:
- Did your brand, product, or content appear in the answers that matter?
- Did audience behavior change after that exposure?
- Did a commercially meaningful outcome change?
No one metric can answer all three. A defensible measurement program keeps them separate and looks for agreement across them.
Key takeaways
- Treat AI referral sessions as observed traffic, not the total value of AI discovery.
- Measure brand mentions, recommendations, and citations separately. Being named is not the same as being recommended, and being cited is not the same as owning the answer.
- Triangulate an exposure metric, a behavioral signal, and a business outcome instead of forcing every interaction into a last-click model.
- Collect visibility data frequently enough to see short citation cycles. A monthly snapshot can miss both a gain and the subsequent loss.
- Report what is observed, what is supported by several signals, and what remains inferred. That distinction is more useful than a precise-looking AI ROI number built on missing data.
Build a three-layer AI measurement system
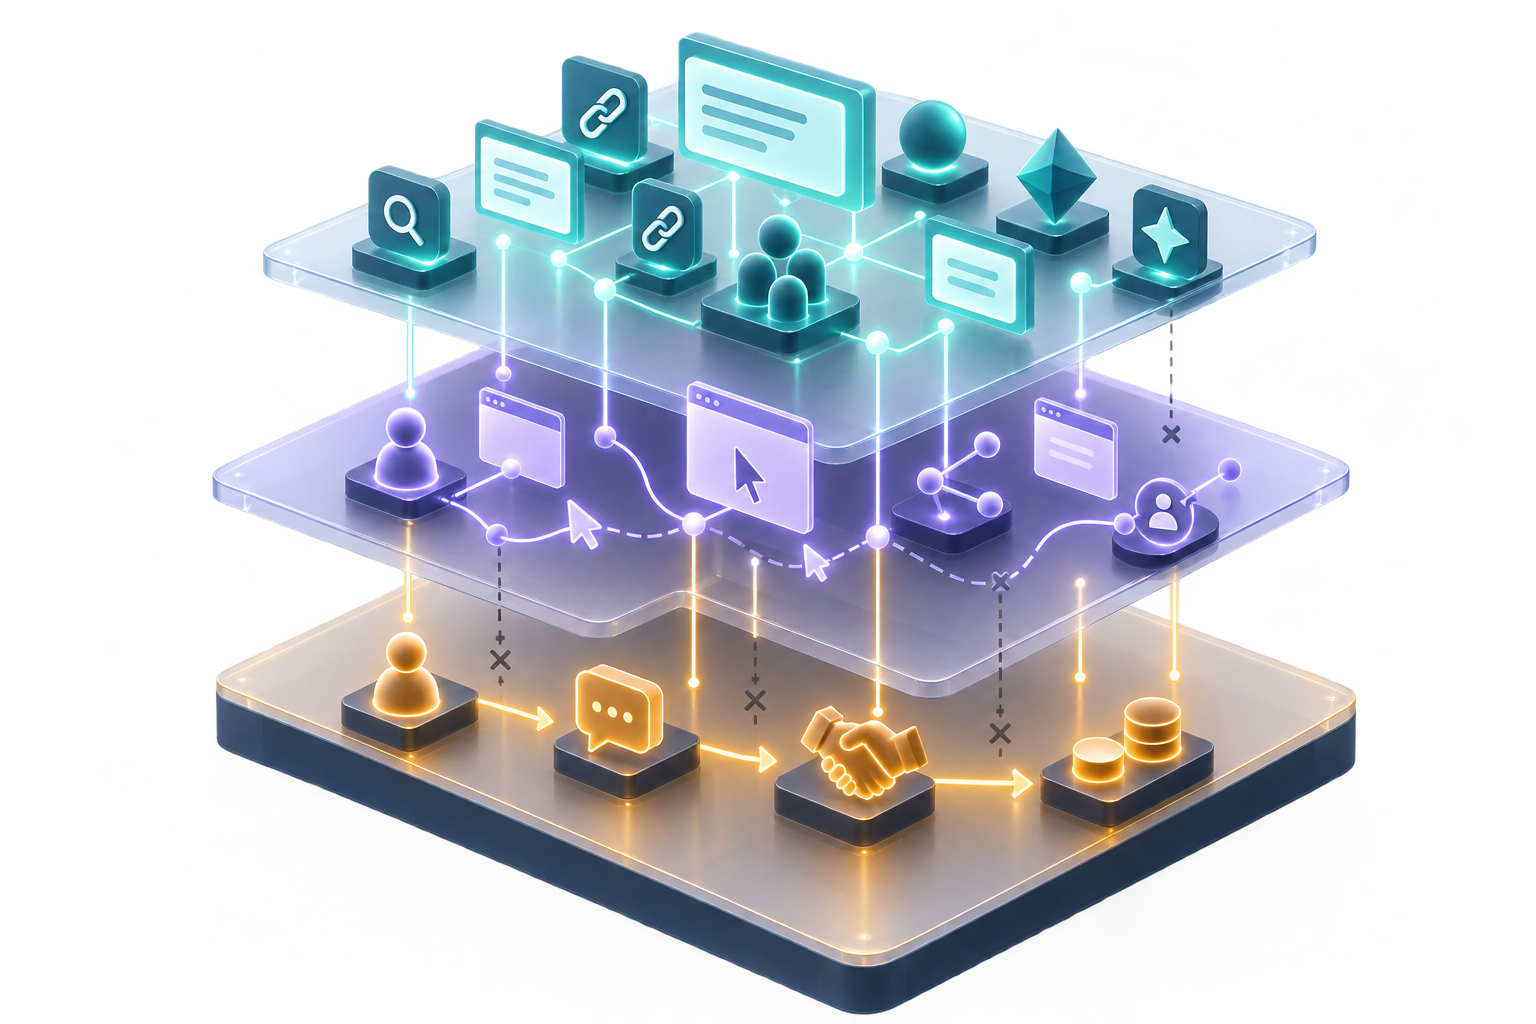
Your dashboard should preserve the boundary between visibility and value. Combining everything into one proprietary score may make the chart simpler, but it hides which part of the system actually changed.
| Measurement layer | Question | Useful signals | Main blind spot |
|---|---|---|---|
| Exposure | Were you present in relevant AI answers? | Visibility rate, recommendation rate, citation rate, citation share, AI share of voice | Exposure does not prove that a person noticed, trusted, or acted on the answer |
| Behavior | Did people do something consistent with that exposure? | AI referrals, engaged visits, branded search trends, direct-visit trends, self-reported discovery | Most signals have other possible causes, and many journeys remain disconnected |
| Outcome | Did the business result improve? | Qualified leads, activated accounts, pipeline, sales, subscriptions, retention | An outcome can change for reasons unrelated to AI visibility |
Define exposure with a stable prompt set
An AI visibility program starts with prompts, not keywords. Build the set around decisions your audience is trying to make: diagnosing a problem, understanding possible approaches, comparing options, shortlisting providers, evaluating risk, or planning implementation. A prompt that contains your brand name tests brand representation; it does not tell you whether you are discoverable before the buyer knows you.
For each observation, record enough context to reproduce or interpret it:
- The exact prompt and its intent cluster.
- The AI engine, observation date, and market or language when those factors are relevant.
- Whether the brand appeared at all.
- Whether it was recommended, described neutrally, or mentioned negatively.
- Whether an owned page was cited and which URL received the citation.
- Which competitors appeared in the same answer.
- Whether the response failed, refused the request, or was otherwise invalid.
Keep the denominator visible when you calculate a rate. A result such as “40% visibility” is uninterpretable unless the report also shows how many valid observations it covers, which engines were included, and whether the prompt mix changed.
Use explicit definitions:
- Visibility rate: valid observations in which the brand appears, divided by all valid observations in the tracked set.
- Recommendation rate: valid observations that actively recommend the brand, divided by all valid observations. A neutral mention should not count as a recommendation.
- Owned citation rate: valid observations containing at least one citation to your domain, divided by all valid observations.
- AI share of voice: your appearances divided by all tracked brand appearances in the same prompt set. Decide in advance whether one brand can count more than once per answer.
- Page citation share: citations received by a particular owned page divided by all citations observed in the defined comparison set.
Version these definitions. If you add engines, markets, or prompt clusters, report the new cohort separately until you can make a like-for-like comparison. Otherwise, a coverage change can masquerade as a visibility gain or loss.
Collect behavior without pretending every signal is causal
Capture AI referrers in your analytics, but inspect their landing pages and outcomes rather than reporting sessions alone. A small number of visits to a high-intent comparison or product page may be more informative than a larger number of low-intent visits. Record engaged visits, sign-ups, qualified conversions, and assisted conversions when your systems can observe them.
Referral traffic can tell you that something happened after a click, but not what happened before it or how much unclicked demand was created. Support it with a discovery question on lead, signup, or checkout forms. Ask, “How did you first hear about us?” Include an option for ChatGPT or another AI assistant and retain a free-text field. Do not replace the person’s answer with the last tracked channel.
Branded searches and direct visits can also support the picture, particularly when they move alongside AI visibility. They are not proof. A campaign, news event, recommendation, or offline conversation can produce the same pattern. Annotate those events so the team can see plausible alternative explanations.
Connect outcomes through the CRM
Choose the outcome that matches the motion. An ecommerce team may care about purchases and repeat customers. A subscription business may care about activation and retained accounts. A sales-led company may care about qualified pipeline and closed revenue. For an account-based program, useful measures include the percentage of the total addressable market reached, engaged, and activated each month.
Add structured CRM fields for self-reported discovery source, the named AI assistant when volunteered, first known landing page, acquisition date, and eventual outcome. Preserve the original discovery field when later touches occur. If a person first found the company through an AI answer and later converted after an email, both facts matter; overwriting the first with the last destroys evidence.
Do not award full revenue credit independently to the referral, the self-reported answer, and the final campaign. Those are different observations of one journey, not three sales. Use them to strengthen or weaken an explanation, not to inflate the result.
Measure often enough to see an 11-day citation half-life
AI citations are unusually perishable. Across 883,000 pages observed on seven AI search engines, the median page’s citation share was down 50% eleven days after reaching its peak. Citation lifecycles also differed by engine.
A monthly point-in-time report can therefore miss the event you wanted to measure. A page could gain substantial citation share, peak, and lose much of that share between two reporting dates. The final snapshot would show little movement even though the page briefly became an important answer source.
For a fixed set of commercially important prompts, weekly collection is a reasonable minimum starting cadence. Use more frequent automated checks for launches, reputation-sensitive queries, or prompt clusters tied closely to revenue. Report business outcomes on a cadence appropriate to the buying cycle, but do not let a long sales cycle force exposure measurement into the same slow schedule.
Make the time series usable:
- Keep a fixed benchmark cohort of prompts so one period can be compared with another.
- Add newly discovered prompts as a separate cohort instead of silently changing the benchmark.
- Show rolling trends as well as individual observations; one generated answer is a sample, not a permanent rank.
- Break results out by engine before calculating an overall total. An aggregate can hide a gain on one engine and a loss on another.
- Track citations at the URL level. A stable domain total can conceal one important page being replaced by another.
- Annotate substantive content changes, migrations, canonical changes, indexing incidents, product launches, campaigns, and major brand events.
- Store raw observations so a surprising chart can be checked against the answers that produced it.
The eleven-day figure is not an instruction to republish every page on an eleven-day schedule. It is a median measured after a page’s high point, not an expiration date. It does not mean every page follows the same curve, that the page disappears after eleven days, or that changing a date will restore visibility.
When citation share falls, diagnose before rewriting:
- Confirm that the prompt set, engine coverage, locale, collection method, and metric definition did not change.
- Check whether the loss is isolated to one engine, one intent cluster, or one page.
- Inspect the replacement citations. Determine whether another page answers the same question more directly or with more current information.
- Check the affected owned page for access, indexing, canonical, redirect, rendering, or accidental noindex problems.
- Review whether the answer itself has become incomplete or stale. Update the substance, evidence, and structure when the page no longer deserves to be the best source.
- Measure the result across repeated observations. Do not declare recovery from one favorable response.
A timestamp-only refresh may create activity without improving the answer. Change the page when you can identify a content or technical gap, and record that intervention so the next visibility movement can be evaluated.
Turn signal combinations into decisions, not invented certainty
Triangulation works because the three layers fail differently. Exposure tracking can see an answer without knowing whether anyone acted on it. Referral data sees a click but misses zero-click influence. CRM outcomes show value but often lose the discovery path. When differently biased signals move in the same direction, your confidence should rise.
Read the combinations before changing strategy
- Exposure and AI referrals rise together: you have direct evidence of greater visibility and more observable traffic. Check whether qualified actions rose before expanding the program.
- Exposure rises, referrals stay flat, and self-reported AI discovery or outcomes improve: the pattern is consistent with zero-click or disconnected journeys. It strengthens the case for influence, but it is not proof that AI caused every outcome.
- Exposure rises with no behavioral or business movement: inspect prompt relevance and how the brand is represented. You may be visible in low-value questions, appearing neutrally instead of being recommended, or reaching an audience that is not ready to act.
- Mentions remain stable while owned citations fall: separate brand presence from content ownership. Inspect which domains and pages are replacing your citations before treating the movement as a broad loss of awareness.
- One engine declines while others remain stable: investigate that engine’s prompt results and cited-page changes separately. An average across engines will obscure the problem.
- Visibility remains stable while conversions decline: do not automatically blame AI search. Review offer, landing-page, sales, pricing, seasonality, and other demand signals.
- Exposure, behavior, and outcomes decline together: prioritize the affected prompt clusters, but still check for technical, market, and measurement changes before assigning a cause.
Label the strength of each claim
A useful report distinguishes three evidence levels:
- Observed: an AI engine cited a URL, a referral session arrived, a form response named an AI assistant, or a CRM record reached a defined outcome.
- Supported: several independent signals moved together, and obvious competing explanations were checked.
- Inferred: AI visibility probably influenced demand, but the journey cannot be connected at the person or account level.
That language prevents a proxy from quietly becoming a fact. A Graphite estimate has put AI under-attribution as high as 10x, but a vendor estimate is a warning about missing observability, not a universal correction factor. Multiplying every observed AI conversion by ten would replace incomplete data with unsupported precision.
Make every reporting cycle end with an action
Your recurring report should include:
- Coverage and denominators: prompts, valid observations, engines, markets, and dates.
- Visibility, recommendation, citation, and share-of-voice trends by engine and intent cluster.
- Owned pages that gained or lost citations, plus the pages or domains replacing them.
- Observable AI referrals, landing pages, engagement, and conversions.
- Self-reported discovery and CRM-tagged outcomes, shown separately from tracked referrals.
- Relevant business outcomes and the period appropriate to the buying cycle.
- Known content, technical, campaign, and market events that could explain movement.
- The evidence level, competing explanations, and one named next decision.
The decision can be to maintain, diagnose, update, expand, test, or pause. Require more than a single generated response before making a material content or budget change. Where volume allows it, use controlled comparisons across similar markets, audiences, accounts, or time periods to test incrementality. Document the differences between groups; a comparison is weak if the supposedly comparable groups were exposed to different campaigns or demand conditions.
Start with one high-value prompt cluster. Freeze the metric definitions, capture a baseline by engine, add a discovery field to your forms and CRM, and schedule the first comparable visibility check within a week. Your first report does not need to claim exactly how much revenue AI produced. It needs to show where you are visible, what changed downstream, how strong the evidence is, and which action is justified next.
References
- Try Profound Blog — The half-life of an AI citation is 11 days
- Search Engine Land — The collapse of attribution

Leave a Reply