AI may already be drafting your client updates, interpreting search data, prioritizing content ideas, and recommending what to do next. The risk isn’t frequent use. It’s failing to notice when the assistant moves from handling work to deciding what matters.
You don’t need to pull AI out of the workflow. You need a visible boundary between assistance and authority. The framework below will help you set that boundary, supply the context a model cannot discover on its own, and keep a named person accountable for every consequential decision.
Define authority before you automate the workflow
Assistant adoption is no longer limited to occasional drafting. By August 2026, one weighted model estimated that Claude had 271.3 million monthly active users and 148.2 million weekly active users. Business strategy and operations represented 8.7% of sampled consumer conversations, excluding Claude Code sessions. Those estimates come from a third-party model, so they shouldn’t be treated as audited platform disclosures. They still illustrate the operational shift: people are bringing assistants into recurring work, not merely testing them.
That makes the number of AI users a weak governance metric. What matters is the authority those users give the system. A team that uses AI every day to organize material may carry less risk than a team that uses it once a month to approve a budget, publish an unsupported claim, or change a production website.
Classify each workflow by the decision right being delegated:
| Level | What the assistant does | What a person still owns |
|---|---|---|
| Prepare | Formats, summarizes, restructures, or drafts from supplied material | Checks accuracy, meaning, tone, and omissions |
| Analyze | Calculates changes, groups data, detects patterns, or surfaces anomalies | Validates definitions, measurement quality, segmentation, and business relevance |
| Recommend | Proposes or ranks options against stated criteria | Tests assumptions, adds missing context, compares alternatives, and selects the action |
| Decide | Selects an option within a clearly bounded policy | Sets the policy, exceptions, limits, escalation rules, and accountability |
| Act | Executes an approved or pre-authorized change | Controls permissions, monitors results, preserves a log, and can reverse the change |
Most teams can delegate preparation broadly. Analysis needs better controls because bad definitions can produce correct calculations with misleading meaning. Recommendations need explicit criteria. Decisions and actions require the strongest limits because they can create financial, technical, reputational, or client consequences.
For an SEO or GEO team, an assistant might cluster queries, extract recurring questions, compare page structures, or draft candidate JSON-LD. It should not silently choose the business’s priority audience, turn uncertain evidence into a factual claim, or publish structured data that misrepresents the visible page. A person must own those choices.
Write one authority sentence for every recurring AI workflow: AI may perform this task using these inputs, but this role approves this decision before this action occurs. Add the conditions that require escalation and the method for reversing an action. If you can’t complete that sentence clearly, the workflow isn’t ready for autonomous execution.
Give the assistant a decision brief, not just an export
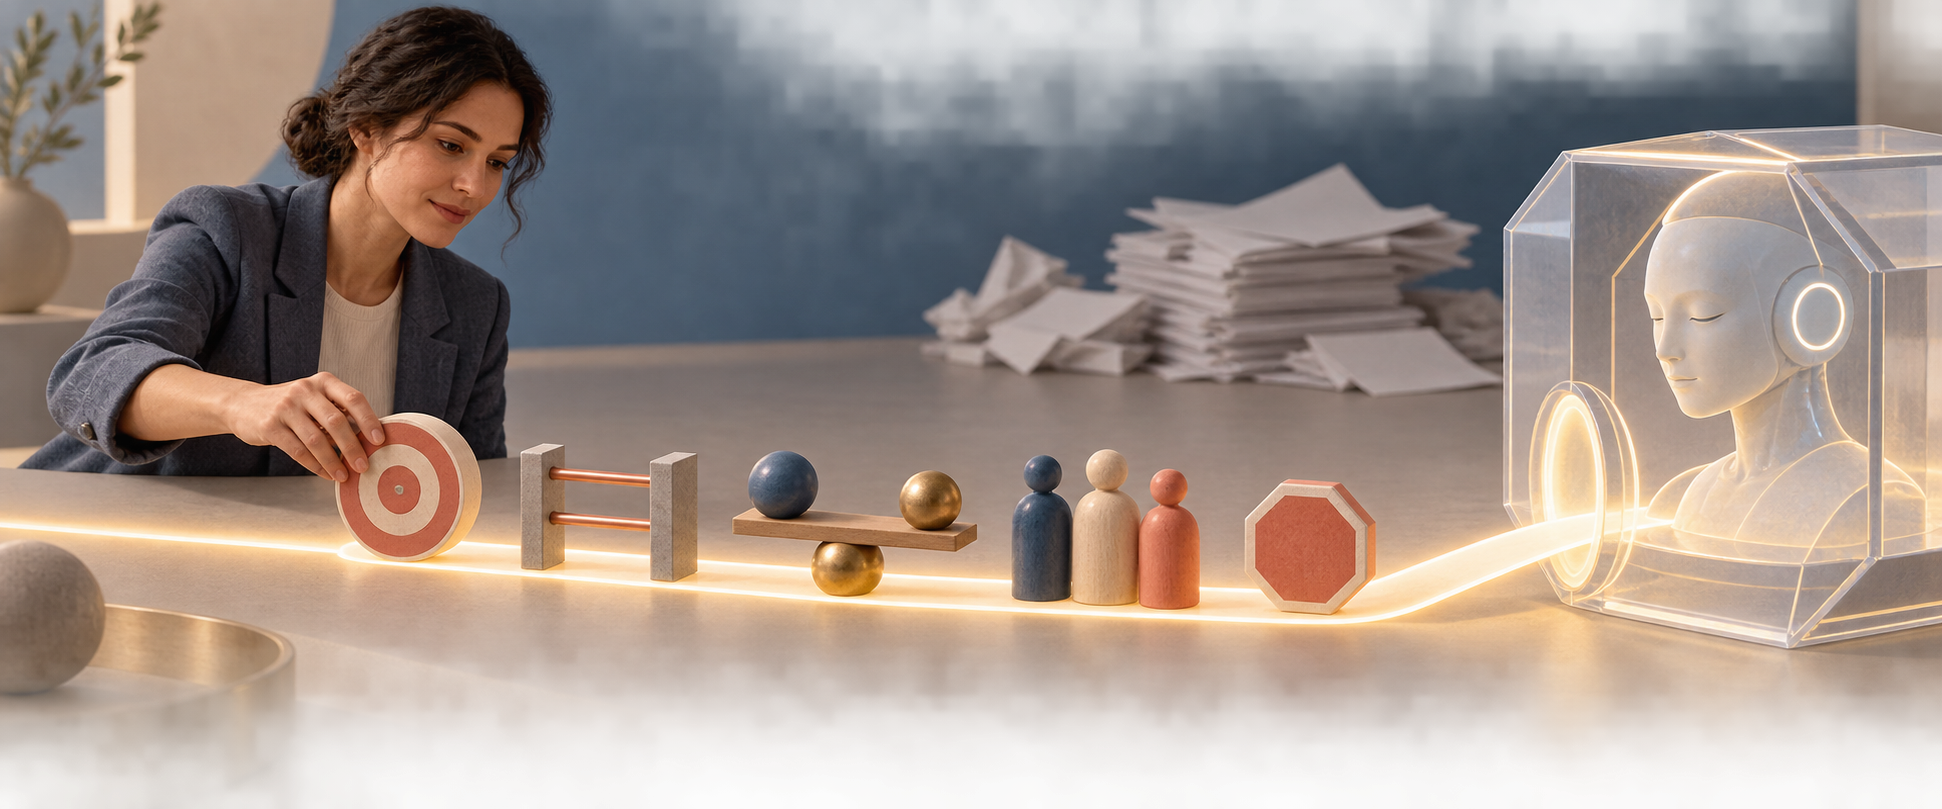
Uploading data does not upload the business that produced it. Search Console can show queries, pages, clicks, impressions, and positions. Analytics can show recorded sessions and conversions. Neither automatically explains that a promotion ended, a price changed, a key product went out of stock, a form broke, a consent configuration changed, margins moved, or the sales team altered its follow-up process.
This is why accurate data can still support the wrong recommendation. The system may describe its input correctly while missing the event that determines what the business should do.
Before asking an assistant to recommend an action, give it a compact decision brief containing:
- The decision: State the choice that must be made. Replace a broad request such as analyze performance with a decision such as determine whether to expand, repair, consolidate, or pause this content program.
- The business outcome: Name what success actually means: qualified leads, profitable sales, renewals, booked appointments, adoption, or another commercial result. Traffic is not a substitute unless traffic itself is the goal.
- The metric definitions: Explain what counts as a lead, conversion, branded query, priority page, new customer, or qualified opportunity. Include known measurement gaps.
- The relevant segments: Separate branded from non-branded demand, informational from commercial intent, priority services from peripheral topics, and new performance from recurring demand where those distinctions affect the choice.
- The business events: Record launches, stock constraints, pricing changes, promotions, sales-process changes, site releases, tracking changes, and market events that overlap the period.
- The constraints: Identify budget, capacity, compliance, brand, technical, contractual, and timing limits. A recommendation that ignores a real constraint is not actionable.
- The missing evidence: Say what the model cannot see and who can supply it. This might require input from sales, customer service, product, finance, engineering, or the client.
- The decision owner: Name the person who will evaluate the recommendation and accept responsibility for the final choice.
Consider rising impressions with flat clicks. A surface-level reading might celebrate wider visibility. Segmenting the change may reveal that broad informational queries produced the extra impressions while clicks to commercially important services declined. The top-line observation remains true, but its meaning changes. Before approving more content, inspect query intent, landing pages, priority topics, click behavior, and downstream outcomes separately.
Apply the same discipline when reported organic sessions fall. Verify whether tracking, consent, form behavior, or analytics configuration changed before treating the decline as lost demand. Otherwise, you may authorize a content overhaul to fix a measurement problem.
Require the assistant to divide its response into four parts: observations, inferences, recommendations, and unknowns. Observations should stay close to the supplied evidence. Inferences should expose their assumptions. Recommendations should identify the criteria used. Unknowns should state what could materially change the answer. This format won’t guarantee a good decision, but it makes weak reasoning easier to challenge.
For AI-search and structured-data work, include a factual source map in the brief. Connect each proposed answer, entity attribute, credential, product detail, price, review claim, and schema property to an approved page or business record. If the supporting fact is absent, the model may flag the gap; it may not fill it with a plausible invention.
Use AI to shorten communication, not distance people
A simple message can become a long, polished email when the sender asks an assistant to make it sound professional. The recipient then asks another assistant to summarize it and draft a reply. The machines expand, compress, and expand the message while both people search for the actual request.
That loop adds more than wasted words. Repeated transformation can weaken hesitation, exaggerate urgency, or convert a tentative suggestion into something that reads like a commitment. Tone and intent can degrade as a message is generated, summarized, and generated again.
Set communication rules around the human outcome:
- Start with the point. Put the answer, request, decision, or risk in the first sentence. Context belongs after it.
- Preserve uncertainty. If the sender is unsure, the message must remain unsure. Do not let polished language manufacture confidence.
- Keep commitments explicit. State who is doing what and when. Do not allow the assistant to infer agreement from a vague discussion.
- Delete decorative expansion. Professional writing is clear and proportionate. A one-sentence answer should remain one sentence when no further context is needed.
- Make the sender approve meaning. Reviewing grammar is not enough. The sender must confirm that the message reflects the intended position and requested action.
- Switch channels when needed. Use a direct conversation when the issue is sensitive, disputed, ambiguous, or likely to produce follow-up questions. Summarize the resulting decision afterward.
Client reporting needs particular care. A generated update can describe movement without explaining whether that movement matters. It also cannot notice an unexpected comment, ask why lead quality changed, or recognize that a neat recommendation conflicts with the client’s operations unless someone supplies that context.
A useful client update separates five things: what changed, what it may mean, what is still unknown, what the team will verify, and what decision or action is required. That structure prevents a polished narrative from disguising uncertainty. It also gives the client obvious places to add information that isn’t present in the reporting system.
The same rule applies to public content. AI can help reorganize an explanation, draft an FAQ, or format JSON-LD, but the brand must own the position and every factual assertion. Validate machine-generated structured data against the visible page and authoritative business records before publication. Never allow an assistant to invent reviews, prices, availability, credentials, authorship, or other claims simply because the markup expects a value.
Match review gates to consequences and measure decision quality
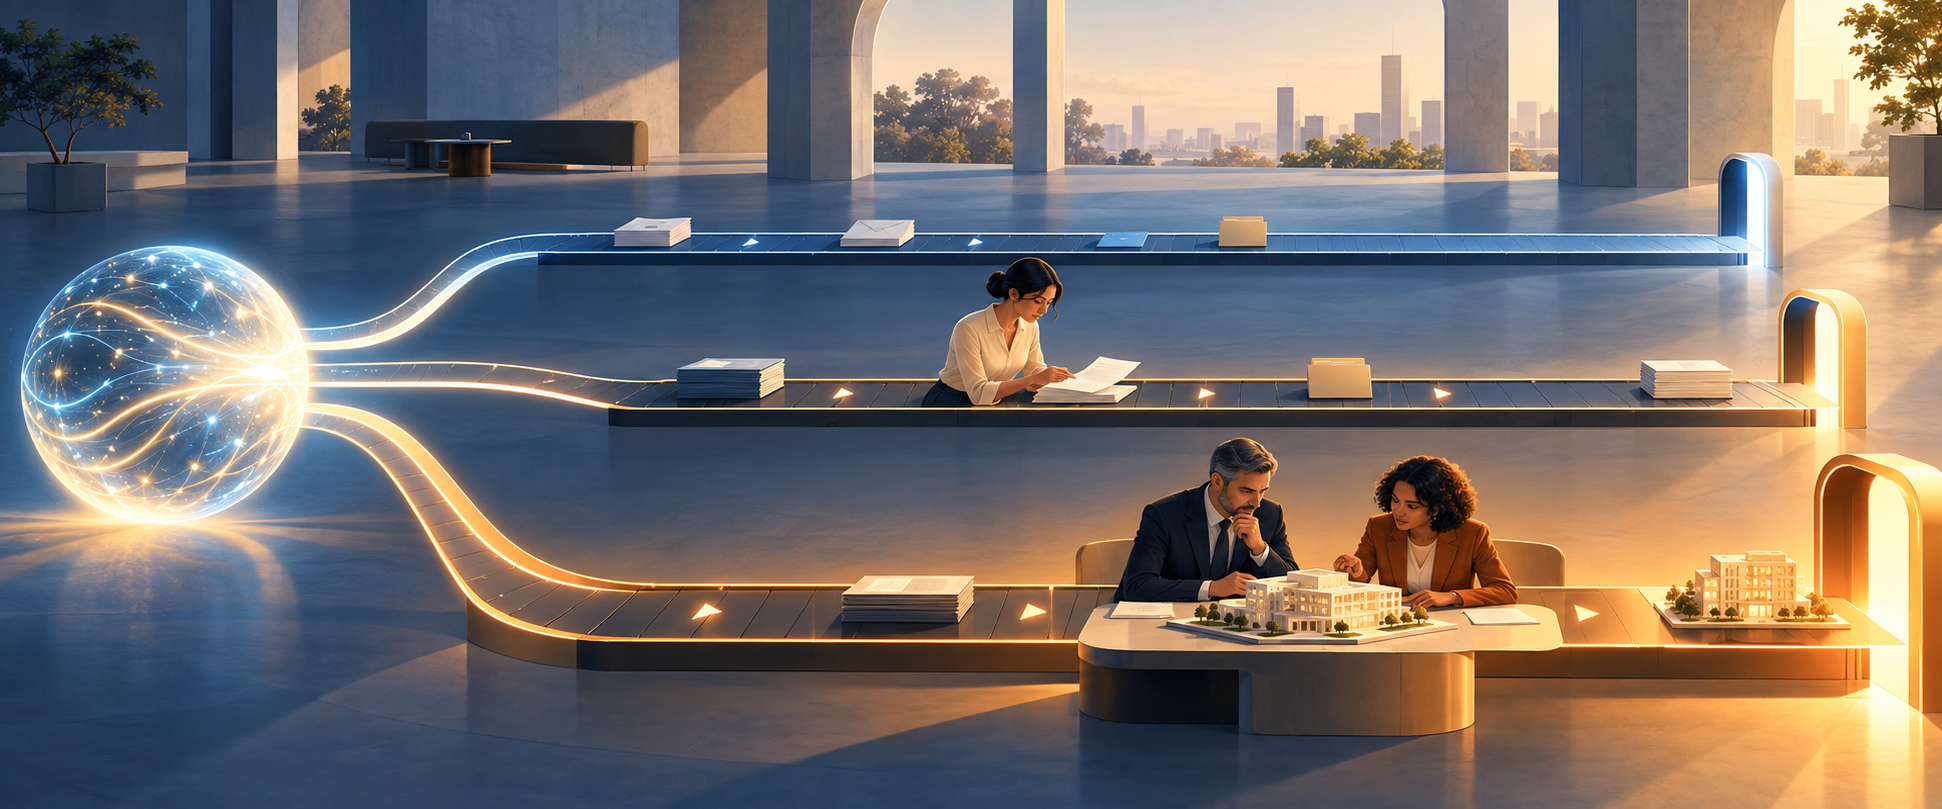
Human review is not one generic approval step. The gate should depend on consequence, reversibility, observability, and uncertainty.
- Low-consequence work: Allow automatic handling when errors are easy to see, easy to reverse, and limited in impact. Formatting internal notes is different from changing a live canonical tag.
- Moderate-consequence work: Queue the output for review when it influences priorities, client interpretation, or published content but has not yet committed resources or changed production systems.
- High-consequence work: Require named approval before spending money, making a client commitment, publishing a material claim, changing permissions, handling customer data, or applying a broad technical change. Preserve a tested rollback path where reversal is possible.
Every consequential recommendation should leave a short decision record. Capture the input set, known context, assumptions, recommendation, material alternative, approver, action taken, and result. This is not bureaucracy for its own sake. Without a record, you cannot tell whether a poor outcome came from missing data, weak reasoning, a bad instruction, an execution error, or a reasonable decision under uncertainty.
Measure the quality of delegation rather than celebrating output volume. Useful operating measures include:
- Context-correction rate: How often did the recommendation materially change after operational context was added?
- Unsupported-assumption rate: How often did the assistant rely on a claim, definition, relationship, or constraint that the input did not establish?
- Human override pattern: Which recommendations were changed, and why? Group overrides by missing context, risk, strategy, factual error, or stakeholder knowledge instead of treating every override as model failure.
- Reversal rate: How often did the team need to undo an AI-influenced action? Record the consequence as well as the count.
- Outcome fit: Did the action improve the business outcome named in the decision brief, or only an intermediate metric that was easier to measure?
- Communication rework: How often did recipients need clarification because the generated message hid the request, distorted uncertainty, or implied an unintended commitment?
A low human-override rate is not automatically a success. It may indicate strong recommendations, passive reviewers, or an organization that has stopped challenging the system. Review the reasons, outcomes, and consequences together.
Audit a fixed sample of routine decisions at a regular cadence, not only the failures that become visible. Escalate whenever important data is missing, evidence conflicts, the recommendation depends on unstated business conditions, the action cannot be reversed safely, or nobody is clearly willing to own the outcome.
Key takeaways
- Govern AI by the authority it receives, not by how often employees use it.
- Let assistants prepare and analyze broadly, but require explicit criteria and accountable ownership before recommendations become decisions.
- Supply commercial goals, metric definitions, operational events, constraints, missing evidence, and a decision owner with every consequential request.
- Separate observations, inferences, recommendations, and unknowns so confidence cannot conceal a weak evidence chain.
- Use AI to make human communication shorter and clearer. Do not let generated polish alter uncertainty, urgency, or commitment.
- Measure context corrections, unsupported assumptions, reversals, communication rework, and business outcomes rather than generated output.
Choose one recurring AI-assisted workflow this week. Write its authority sentence, create its decision brief, set the review gate, and record the next outcome. Expand delegation only after that workflow shows that people can see the assumptions, challenge the recommendation, reverse the action, and identify who owns the result.
References
- Search Engine Land – What you lose when AI starts handling your conversations and decisions
- First Page Sage – Claude Usage Statistics: October 2026

Leave a Reply