Your rankings can look healthy while your brand is missing from the answer a customer actually sees. Or an AI system can mention you, describe you incorrectly, and send no visit that your analytics can attribute. If you still judge organic performance only by positions and clicks, those failures stay hidden.
The practical response is not to abandon SEO for a new acronym. It is to extend your existing search system so that machines can retrieve your pages, understand your entities, quote your claims, represent your brand accurately, and give an interested person a clear route to act.
Run SEO and AI visibility as separate, connected scorecards
Traditional rankings tell you whether a URL can compete in a search results page. They do not tell you whether ChatGPT, Gemini, Google AI Mode, or another generated-answer experience mentions your brand, cites your site, or repeats the right facts. AI visibility therefore needs its own measurements.
This distinction matters because an answer interface can satisfy part of a search without passing the user to a website. In a March 2026 randomized field experiment involving 1,100 U.S. Chrome users, forcing nearly 95% of searches through Google AI Mode reduced the share that led to an external website by 18.8 percentage points. Participants also reported lower satisfaction, usefulness, control, personalization, and trust than people using Google normally.
Do not turn that number into a universal traffic forecast. The treatment lasted seven days, the sample skewed younger, highly educated, and politically left-leaning, and participants were pushed into AI Mode rather than choosing it. The sound conclusion is narrower: AI-mediated discovery can materially reduce referral opportunities, and fewer clicks do not necessarily mean the answer experience served the user better.
Build your reporting around three connected outcomes:
- Retrieval: Can search engines and answer systems find the right page for the question? Track crawlability, indexation, rankings, relevant internal links, and whether the page appears as a cited or consulted resource.
- Representation: Does the generated answer name the correct entity, describe it accurately, preserve important qualifications, and link to the appropriate URL? A positive-sounding mention is still a failure if it assigns the wrong feature, location, price, audience, or availability.
- Response: What happens after exposure? Track referral visits where they are available, branded demand, assisted conversions, leads, sales, bookings, subscriptions, or the business action appropriate to the page.
Keep these columns separate. A mention is not a citation. A citation is not a visit. A visit is not a conversion. Combining them into one visibility score hides the exact problem you need to fix.
Turn keyword research into a prompt-and-decision map
Keywords still reveal language, demand, and the pages competing for attention. Prompts reveal something different: the decision a person is trying to make, the conditions attached to it, and the comparison set an AI system may assemble before answering.
A query such as “project management software” names a category. A prompt such as “Which project management platform suits a distributed agency that needs client approvals but has no dedicated administrator?” also supplies an audience, operating constraint, required capability, and evaluation criterion. A generic category page may rank for the first expression and still be unusable for the second.
Create a prompt map for each product, service, location, person, or topic that matters commercially:
- Choose the entity. Start with one thing you need an answer engine to understand unambiguously: a product, service, organization, location, event, or expert.
- List the decisions surrounding it. Include discovery, comparison, validation, objection handling, and action. These are different information needs and may require different pages.
- Add real constraints. Capture the audience, use case, location, compatibility requirement, budget condition, risk, or desired outcome that changes the answer.
- Assign a canonical destination. Decide which page should answer each prompt family. If several URLs compete to make the same claim, consolidate the information or define a clear primary page.
- Record the proof required. Specifications, policies, examples, qualifications, prices, availability, authorship, and dates should sit close to the claims they support.
- Define the next action. A person who wants more than the generated answer should land on a page that continues the same task rather than restarting the journey.
| Decision moment | Prompt pattern | Job of the destination page | Useful visibility signal |
|---|---|---|---|
| Discover | What approaches solve this problem for this audience? | Explain the category, tradeoffs, and situations in which each approach fits. | Your entity appears in the correct category and context. |
| Compare | Which option fits these requirements or constraints? | Make differentiators, exclusions, and supporting evidence easy to verify. | The comparison includes you and states the right distinctions. |
| Validate | Does this option support a particular requirement? | Provide an explicit answer, scope, conditions, and authoritative details. | The answer uses the correct fact and cites its canonical page. |
| Act | Where can I buy, book, apply, contact, or begin? | Present current availability and a direct next step. | The answer sends the user to the correct action page. |
For every tracked prompt, save the exact wording, platform, language, market or location, intended destination, expected facts, observed competitors, and business stage. This prevents a common reporting error: treating two prompts as equivalent even though one asks for information and the other asks for a recommendation.
Your tooling should preserve this prompt-level detail. Rank Math AI, for example, tracks brand appearances in ChatGPT and Gemini separately from traditional rankings, with daily, weekly, or monthly monitoring in more than 30 languages. If you use a different platform or an internal process, require the same basic separation. The tool is instrumentation; your prompt set and evaluation criteria are the strategy.
Make important pages easy to quote and hard to misread
An answer engine should not have to assemble your central claim from an opening anecdote, a feature grid, a footnote, and a support page. Put the answer where a person can find it quickly, then place the evidence and limitations beside it.
Use this structure on pages mapped to consequential prompts:
- Direct answer: State the conclusion in plain language near the relevant heading. Answer the question before expanding it.
- Named entity: Identify exactly which product, service, organization, location, event, version, or plan the statement concerns. Pronouns and vague category labels create avoidable ambiguity.
- Qualifications: State who the answer applies to, where it applies, and which conditions or exclusions can change it.
- Supporting evidence: Put specifications, policies, examples, definitions, and source links close to the claims they substantiate.
- Freshness signal: Show a meaningful updated date when the information can change, and remove stale claims rather than leaving conflicting versions around the site.
- Next step: Link to the comparison, documentation, product, booking, contact, or transaction page that continues the reader’s task.
This is not permission to flatten every page into short answers. A concise answer earns comprehension; depth earns confidence. The page still needs the reasoning, evidence, alternatives, and boundaries a serious reader requires.
Use structured data to corroborate visible facts
JSON-LD should describe the same reality a visitor can see. It does not repair weak content, create an entity by itself, or make a stale offer current. Its useful role is to make entities, attributes, and relationships explicit without forcing a machine to infer them from presentation alone.
Select the type that matches the actual entity. A product page may support Product markup; a property page may call for Hotel; an event page may use Event; and an important visual may be represented with ImageObject. Then verify that names, URLs, images, locations, dates, attributes, prices, and offers agree with the visible page and any current feed, inventory, booking, or location data.
Audit these relationships as a system:
- The entity has one preferred name and a stable canonical URL.
- Alternate names do not accidentally create what looks like a second entity.
- The structured description does not make claims absent from the page.
- Offer, availability, date, location, and attribute data match operational systems.
- Images and videos point to the entity and variant they actually depict.
- Third-party profiles and distribution feeds do not contradict the first-party record.
More markup is not the goal. Fewer unresolved contradictions is the goal.
Use internal links to define the evidence path
Internal links help a crawler discover URLs, but their strategic value goes further. They show how an overview, a detailed claim, its supporting documentation, and the action page relate to one another.
Run a crawl and fix the basics first: broken destinations, redirect chains, and important pages with no contextual internal links. Then connect each canonical page in both directions. A category overview should point to the relevant detail page; the detail page should connect back to its parent and onward to proof or action. Use anchor text that names the relationship instead of repeating “learn more” throughout the site.
Do not add links to every possible page. A dense but indiscriminate link graph blurs hierarchy. Link when the destination answers the next reasonable question, verifies the current claim, distinguishes a related entity, or enables the next action.
Treat images and video as evidence, not decoration
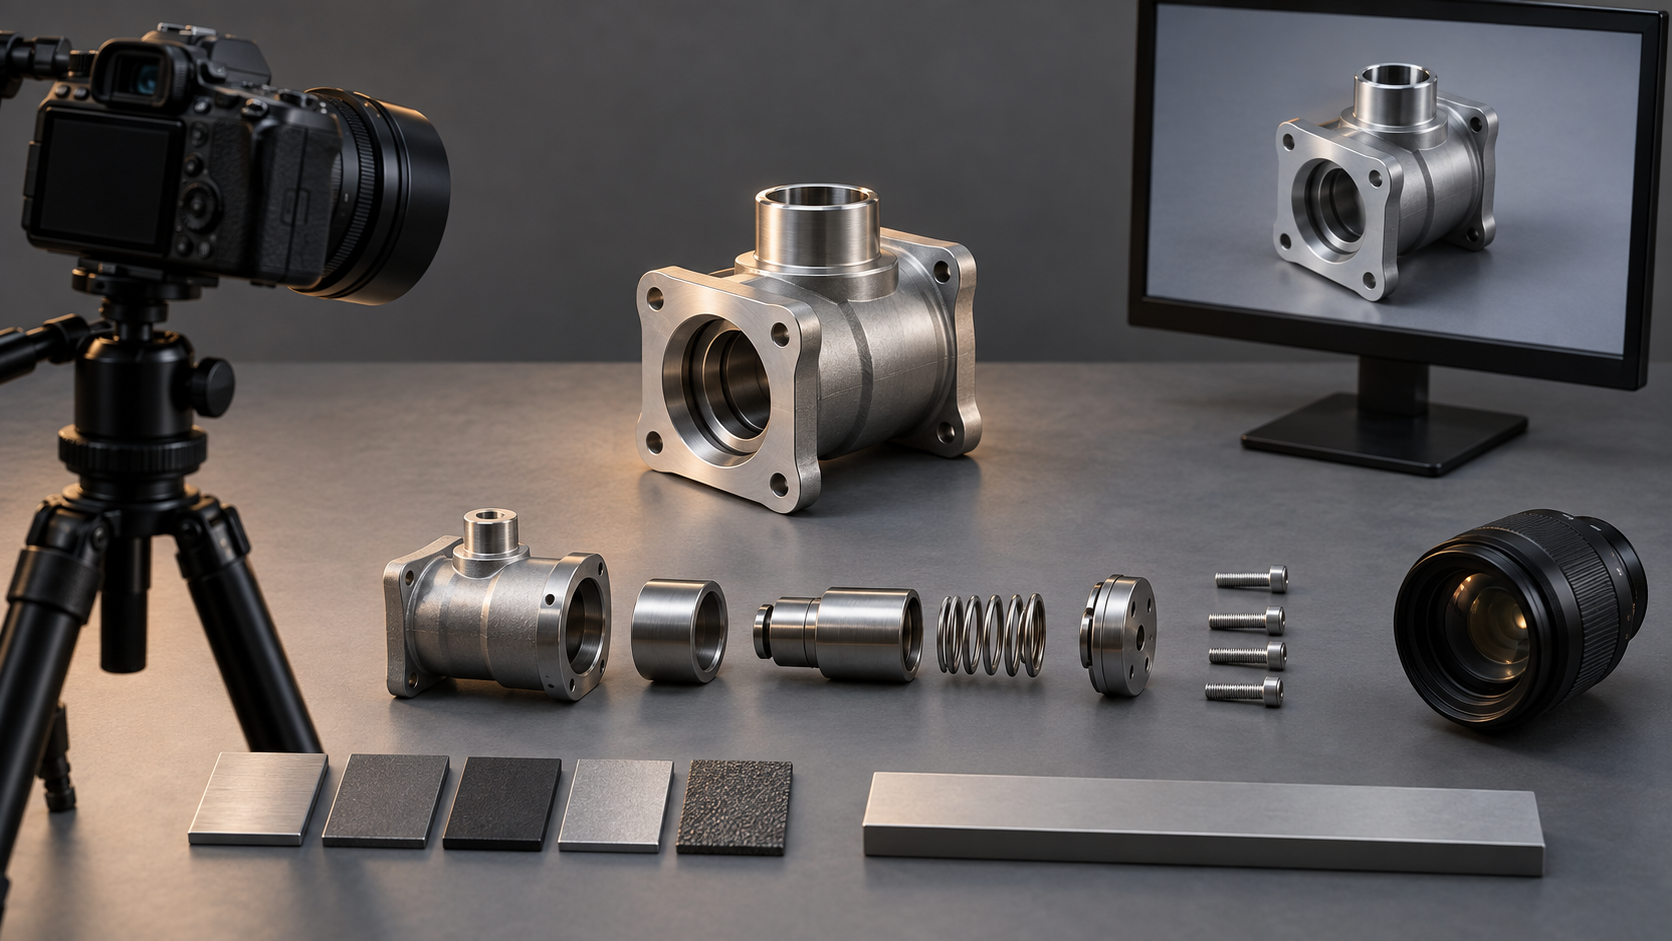
Visual optimization is no longer limited to image rankings or faster page loads. AI systems can interpret objects, attributes, surroundings, and relationships within a scene, then connect those observations to a product, place, business, or other entity. Google reports that Lens supports more than 25 billion visual searches per month, with one in five showing commercial intent.
The important unit is therefore not the image alone. It is the relationship among the asset, the entity it depicts, the page around it, the metadata describing it, and the operational data that keeps the claim current.
For every decision-relevant image or video:
- Show useful attributes clearly. Original imagery should reveal the color, material, configuration, room type, amenity, dish, location, feature, or experience that affects a customer’s decision.
- Identify the correct entity. A product image must connect to the right product and offer. A hotel image must connect to the correct property, room type, amenity, and location.
- Write literal metadata. Use a descriptive filename, accurate alt text, and a caption when the caption adds context. Do not stuff the target phrase into descriptions of things the asset does not show.
- Add explanatory surroundings. The heading, nearby copy, and page purpose should reinforce what the asset depicts and why it matters.
- Make video language accessible. Supply a transcript and useful metadata so the information is available without requiring a system to infer everything from frames and audio.
- Connect structured data. Associate the visual with the same entity, attributes, and canonical URL described on the page.
- Keep distribution consistent. Website pages, profiles, publishers, booking platforms, product feeds, and social channels should not attach contradictory names or attributes to the same visual.
Consider a hypothetical hotel image labeled as a rooftop pool on the property page while a booking feed assigns it to a different room category and a third-party profile calls the pool indoor. A person sees an appealing photograph; a machine sees competing entity relationships. Rewriting the alt text will not resolve that conflict. The property record, amenity data, page copy, structured data, and distribution feeds must agree.
An asset register makes this manageable at scale. For each important visual, record its URL, depicted entity, visible attributes, canonical page, relevant structured-data type, associated feed or listing, usage rights, and last verification date. That turns visual SEO from a tagging task into a maintainable information system.
Measure what the answer changed, then fix the weakest link
Generated answers are observations at a point in time, not permanent rankings. Save enough context to reproduce each check: exact prompt, platform, language, location when relevant, date, answer text, cited URLs, brand description, competitors included, and the intended destination page.
Use separate rates instead of one opaque score:
- Mention coverage: tracked prompts in which your entity appears, divided by prompts tested.
- First-party citation rate: answers citing your site, divided by answers in which your entity appears.
- Representation accuracy: audited brand claims that are correct and properly qualified, divided by brand claims checked.
- Destination accuracy: citations that lead to the canonical page for the task, divided by first-party citations observed.
- Response value: attributable visits, engaged sessions, assisted outcomes, and completed business actions associated with AI discovery.
Choose a monitoring cadence based on how quickly the underlying information and competitive answer set can change. A fast-moving offer or event warrants closer observation than an evergreen definition. Whatever cadence you choose, compare like with like; changing the prompt wording, language, geography, and platform at once makes the result impossible to diagnose.
When performance changes, work through the failure in order:
- Not retrieved: Check indexation, crawl access, canonicalization, internal links, page relevance, and whether the necessary information exists in accessible text.
- Retrieved but absent from the answer: Tighten the direct answer, make the entity explicit, add the missing qualification or proof, and remove competing pages that make the canonical source unclear.
- Mentioned inaccurately: Locate contradictions across visible copy, JSON-LD, feeds, profiles, media metadata, and older pages. Correct the underlying record before adding more content.
- Mentioned but not cited: Strengthen the first-party page as the clearest source for the claim. Put evidence and the canonical fact together rather than distributing them across weak fragments.
- Cited but not visited: Determine whether the answer already completed the task. If a click is still useful, make the linked page promise a clear next layer: a tool, full comparison, current inventory, detailed method, documentation, or transaction.
- Visited but not converted: Treat this as a landing-page and journey problem. Ensure the page fulfills the prompt’s intent and makes the appropriate next action obvious.
Do not judge an optimization by mention growth alone. A larger number of inaccurate mentions can damage understanding, while a smaller number of well-qualified citations on high-intent prompts may be more useful. Read representative answers, not just dashboard totals.
Key takeaways
- Keep classic rankings, AI mentions, citations, representation accuracy, visits, and conversions as distinct metrics.
- Map prompts to customer decisions, constraints, expected facts, canonical pages, and next actions.
- Place direct answers, qualifications, proof, and freshness signals together on the page that owns the claim.
- Use JSON-LD, internal links, feeds, profiles, and visual metadata to reinforce one consistent entity record.
- Diagnose the stage that failed before changing content: retrieval, inclusion, accuracy, citation, visit, or conversion.
Start with one commercially important entity and the prompt family closest to a real decision. Record a baseline in the answer systems your audience uses, audit the canonical page and its supporting signals, correct the largest contradiction, and run the same prompts again. That small loop will teach you more than a sitewide program built around an undefined AI visibility score.
References
- Search Engine Land – Rank Math AI unifies SEO tools, adds Gemini visibility tracking
- Search Engine Land – Visual content and SEO: How to use images and videos in 2027
- Search Engine Land – Google AI Mode cuts clicks and user satisfaction: Study

Leave a Reply