You have screenshots showing that AI systems mention your brand, a small line of AI referrals in GA4, and no defensible answer when someone asks whether either one affected pipeline. The problem isn’t necessarily weak performance. It’s that AI exposure, website behavior, and revenue happen in different systems, often without a trackable click connecting them.
You need a measurement chain, not one magic metric: what an AI says, which information appears to influence the answer, what the buyer does next, and which outcomes reach your CRM. Once those stages are separated, you can report what you observed without inflating what you proved.
Key takeaways
- AI visibility and AI attribution answer different questions. Measure them separately before connecting them.
- Referral traffic from AI assistants is an observable minimum, not a complete count of AI-influenced visits or buyers.
- Start with one customer segment and a fixed panel of about 20 prompts across awareness, consideration, and action.
- Organize attribution into three layers: directly recorded outcomes, influenced outcomes, and the future visibility moat you are building.
- Report changes as observed, attributed, associated, or still unknown. That vocabulary prevents correlation from turning into an unsupported revenue claim.
Why conventional attribution misses the AI search journey
Traditional search reporting assumes a recognizable sequence: a person searches, clicks a result, lands on a tagged page, and converts in the same measurable journey. AI search can break that sequence at every step.
A person may get a complete answer without leaving the interface. They may see your brand recommended, remember its name, and search for it later. They may copy your domain rather than use the citation link. Mobile and desktop applications can also remove referral information, while switching devices can sever the connection entirely. As a result, AI-generated visits recorded in analytics represent an observable floor, not the full population of people exposed to your brand.
This creates two measurement problems that must not be collapsed:
- Visibility: Does the AI include your brand, describe it correctly, and cite information that supports the answer?
- Attribution: Is there credible evidence that this exposure contributed to a visit, lead, opportunity, sale, or another business outcome?
A visibility score cannot prove revenue. A referral report cannot reveal all visibility. Treating either one as a complete measure produces false precision.
Direct traffic doesn’t solve the problem. In analytics, “direct” is a bucket for visits without usable referral information; it isn’t a synonym for people who typed your domain, and it certainly isn’t an AI channel. A rise in direct visits may be consistent with AI influence, but it needs supporting evidence before you describe it that way.
The practical fix is to preserve several kinds of evidence with different confidence levels. A ChatGPT referral that becomes a closed-won opportunity is strong but incomplete evidence. A simultaneous rise in AI mentions, branded searches, and direct demo requests is useful contextual evidence, but it doesn’t establish that AI caused every increase. Your framework should make that distinction visible.
Establish a repeatable AI visibility baseline first
You can’t attribute a change until you know what changed. Begin with a controlled visibility baseline for one customer segment, not a broad list of every question anybody might ask.
Build a fixed prompt panel around one buyer
Choose a segment with a distinct problem, evaluation process, and purchase decision. “Mid-market security teams replacing a legacy platform” is measurable. “Anyone interested in cybersecurity” isn’t.
Create approximately 20 prompts covering three stages of the journey:
- Awareness: Questions about the problem, available approaches, common mistakes, and signs that help may be needed.
- Consideration: Questions about leading providers, alternatives, pricing expectations, selection criteria, locations, and suitability for a specific type of customer.
- Action: Questions about your brand, its specialization, reviews, fit, and comparisons with named competitors.
Run every prompt in a fresh conversation. Use a private window or logged-out session where possible, because accumulated chat context and account personalization can change the answer. Test the same wording in AI Mode, Gemini, and ChatGPT, then add another platform only when your audience actually uses it. The goal is a stable panel, not the largest possible prompt inventory.
For every run, record the date, platform, exact prompt, whether your brand appeared, which competitors appeared, which pages or domains were cited, and whether the description of your brand was materially correct. This fresh-session testing method and three-stage prompt structure gives you a reproducible diagnostic rather than a collection of favorable screenshots.
Turn the prompt log into diagnostic metrics
Calculate metrics that reveal different failure modes:
- Mention rate: Prompts that mention your brand divided by eligible prompts tested. Break this out by journey stage; an overall average can hide strong awareness visibility and weak consideration visibility.
- Competitive inclusion rate: Consideration prompts in which your brand appears alongside the companies buyers are likely to evaluate.
- Owned citation rate: Eligible prompts whose answers cite one of your pages. If a platform doesn’t expose citations for a run, record “not available” rather than converting missing data into a zero.
- Perception accuracy: Brand mentions with a materially accurate description divided by all brand mentions. Keep an error log for incorrect claims about your offering, audience, pricing, location, or integrations.
- Citation-domain coverage: The domains repeatedly supporting answers in your category, marked by whether your brand is represented on them.
Keep the denominator beside every percentage. “Mention rate increased to 40%” means little unless the reader knows whether that represents eight mentions among 20 fixed prompts or an opaque score assembled from a changing prompt set.
A share-of-voice number is useful for detecting movement, but it functions as a temperature reading rather than a diagnosis. If visibility is weak, the remedy could be inaccurate brand information, absent third-party coverage, poor indexing, a mismatch between your offering and the prompt, or a competitor that has stronger evidence in the cited ecosystem. Publishing more pages before identifying the gap may simply create more content that AI systems continue to ignore.
Map where the answers are being shaped
Add an influence map beside the prompt panel. Put journey stages in the rows and four discovery behaviors in the columns: streaming, scrolling, searching, and shopping. In each cell, record two things: the channels or cited domains that influence the buyer at that moment, and whether your brand is present there.
This map tells you whether you have an on-site content problem or a broader representation problem. If the same review site, directory, video channel, discussion community, or competitor comparison keeps shaping answers and you are absent from it, another blog post on your own domain may not close the gap. If AI repeatedly misstates a product fact that your site never explains clearly, the correction belongs in your canonical product or service information first.
Connect visibility to outcomes with three attribution layers
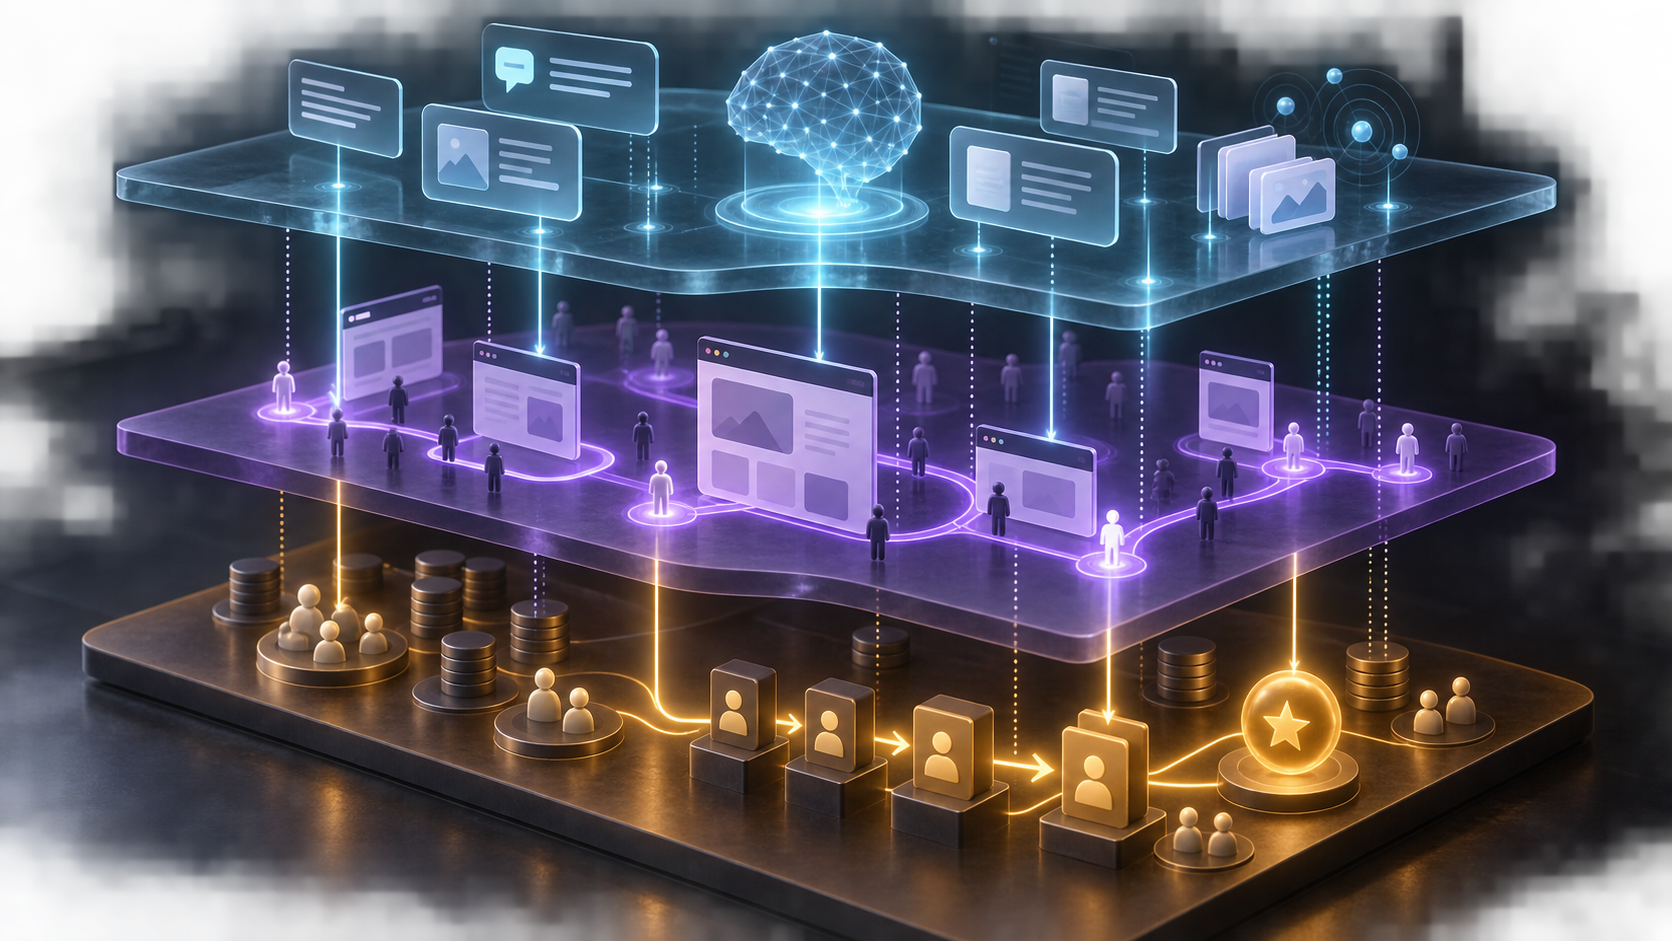
A three-layer model of direct attribution, influenced attribution, and future moat lets you preserve weak signals without pretending they all carry the same evidentiary weight.
| Layer | Evidence to track | What it can support | What it cannot prove alone |
|---|---|---|---|
| Direct attribution | Known AI referrals, self-reported discovery, CRM source details, opportunities, closed revenue | A recorded AI interaction was part of the measurable journey | The complete amount of AI-influenced demand |
| Influenced attribution | Branded search, direct-source visits and demos, sales-cycle length, conversion rate, competitive win rate | Business behavior changed in a way consistent with increased AI exposure | That AI caused every observed change |
| Future moat | Mention coverage, perception accuracy, citation presence, influence-map coverage, proprietary and task-completing assets | Your brand is becoming easier for search and AI systems to understand and recommend | Guaranteed traffic, pipeline, or future revenue |
Layer 1: Capture directly attributable outcomes
Start with the records you can defend individually. Create an AI search channel or source-detail field in your CRM for leads carrying a recognizable AI referrer. Preserve the original source data rather than overwriting it, because you may need to audit the classification later.
Add “AI assistant or AI search” to the “How did you hear about us?” field on high-intent forms. Follow it with optional free text asking which tool the buyer used and what they were researching. If changing the form would hurt completion, have sales representatives ask the same question during qualification and save the response in a structured field.
At minimum, retain these fields:
- Detected referral source and landing page.
- Self-reported discovery source and the buyer’s free-text explanation.
- Lead, opportunity, and close dates.
- Opportunity stage, value, and closed-won revenue.
- Product, segment, geography, and campaign context.
Revenue-linked records are your most defensible outcome evidence even when the count is small. Report them as recorded AI-attributed outcomes, while stating that lost referrals, no-click interactions, and cross-device journeys make the count incomplete.
Layer 2: Test for influenced demand
Next, examine behavior that could occur after an untracked AI interaction. The useful signals include branded organic search, direct-source visits and demo requests, lead-to-opportunity conversion, sales-cycle length, and win rate against competitors appearing in your prompt panel.
The mechanism matters. A buyer can ask an assistant for a shortlist, remember your name, and search Google several days later. They can also resolve pricing, integration, or fit objections before reaching your sales team. In those cases, the visible outcome may be a branded query or a better-prepared buyer rather than an AI referral. Branded search lift, direct demand, sales-cycle changes, and competitive win rates are therefore relevant influenced-attribution measures.
They are not automatically AI outcomes. Compare the same segment, product, geography, and time window. Annotate major brand campaigns, paid-media changes, launches, pricing changes, seasonality, public relations activity, and website migrations that could move the same metrics. Use the median sales-cycle duration as well as the average so a few unusually large or slow opportunities don’t dominate the result.
Your claim should match the evidence: “Branded demand and direct demo submissions rose during the same period as consideration-stage visibility” is defensible. “AI generated the entire increase” isn’t, unless individual records establish that connection.
Layer 3: Measure the future moat without monetizing it
The third layer is a strategic scorecard, not delayed revenue attribution. It tracks whether your brand is becoming easier to retrieve, understand, verify, and distinguish.
Monitor accurate category inclusion, coverage across high-value prompt clusters, representation in frequently cited domains, and correction of recurring perception errors. Track whether your site supplies assets that a generic answer cannot reproduce: proprietary data, useful tools, original workflows, product capabilities, and pages that help a visitor complete a task. Strong topical focus and a clear description of the business also make your entity easier to interpret.
Keep the SEO foundation visible here. Google’s generative answers depend on information in Google’s index, so crawlability, indexing, internal linking, and clear canonical pages remain prerequisites. Where Search Console provides a generative AI view, use it to identify which existing pages are being surfaced. Treat that information as visibility evidence, not as a complete cross-platform attribution report.
Build one dashboard that preserves confidence and context
Your dashboard should show a chain of evidence rather than compress everything into a proprietary score. Keep four panels on one page.
- Visibility panel: Mention rate, competitive inclusion, owned citation rate, perception accuracy, and results by journey stage.
- Influence panel: Frequently cited domains, competitor co-mentions, missing cells in the streaming-scrolling-searching-shopping map, and recurring factual errors.
- Behavior panel: Branded organic demand, direct-source visits, direct demo submissions, high-intent page visits, and conversion rates for the same segment.
- Business panel: AI-referred and self-reported leads, opportunities, pipeline value, closed revenue, sales-cycle duration, and competitive win rate.
Display the current value, baseline value, absolute change, denominator, reporting window, and data owner for every metric. Add an annotation lane for interventions and confounders. Without dates for page updates, technical changes, campaigns, and product announcements, a trend line cannot tell you what to investigate.
Do not add visibility, visits, and revenue into a single composite “AI performance” score. They use different units, denominators, and levels of confidence. A composite can improve even while the business outcome deteriorates, and nobody can diagnose the reason without unpacking it.
Use the pattern to choose the next action
- Low mentions and irrelevant citations: Check whether your offering actually fits the prompt, then investigate the domains and competitors shaping the answer before producing more content.
- Brand mentioned but described incorrectly: Strengthen the canonical pages that define the disputed facts, remove contradictory messaging, and address influential third-party profiles where possible.
- Accurate mentions but weak consideration visibility: Examine comparison, pricing, use-case, audience-fit, and selection-criteria gaps. Buyers need evidence that helps them choose, not another broad category definition.
- Visibility rises but behavior does not: Verify that the prompt panel represents commercially relevant demand. Visibility for informational questions outside your market may never become pipeline.
- Behavior rises without movement in your visibility panel: Your prompt set may be incomplete, another campaign may be responsible, or AI may be influencing questions you aren’t testing. Investigate before assigning credit.
- Direct AI revenue appears while reported traffic remains small: Preserve the revenue records and describe analytics traffic as incomplete. Do not scale the small tracked count into an invented total.
Run a 30-day operating cycle
- Days 1-3: Select one customer segment, define the buying problem, and inventory the analytics and CRM fields you already have.
- Days 4-7: Run the fixed prompt panel in fresh sessions, record citations and competitors, and score perception accuracy.
- Week 2: Build the influence map and identify one commercially relevant gap. Choose a gap that can be changed and measured, such as a missing comparison, unclear product fact, absent use-case page, or influential profile that misrepresents the brand.
- Week 3: Make one coherent intervention. Record the affected prompts, pages, channels, launch date, and expected leading signal.
- Week 4: Rerun the fixed panel under the same protocol. Review early visibility movement, but keep behavioral and revenue windows open long enough for your normal buying cycle.
One month is enough to install the measurement discipline and inspect leading signals. It may not be enough to judge pipeline or revenue, especially in a long B2B sales cycle. Match the evaluation window to the outcome: model visibility can move before branded demand, and branded demand can move before opportunities close.
Report the evidence without turning correlation into causation
A credible AI search report should separate four types of statements:
- Observed: The brand appeared, a page was cited, a competitor was included, or a tracked metric changed.
- Attributed: A preserved referral or self-reported response connects an AI interaction to a known lead, opportunity, or customer.
- Associated: Visibility and a business indicator moved in a consistent sequence for the same segment, but the individual journeys cannot be connected.
- Unknown: The journey may have involved AI, but available data cannot establish whether or how.
Use a consistent reporting sentence: “Among [N] fixed prompts for [segment], brand mentions changed from [A] to [B] after [intervention]. During [business window], [branded demand or pipeline metric] changed from [C] to [D]. [Known confounders] were also present, so we classify the relationship as [observed, attributed, or associated]. The next test is [action].”
This format answers the questions decision-makers actually have: What moved? How reliable is the connection? What else could explain it? What will you do next?
Start with one segment and 20 prompts rather than an enterprise-wide score. Within 30 days, you can have a repeatable visibility baseline, CRM fields that retain direct evidence, an influence map that exposes the real gaps, and one controlled improvement under measurement. That won’t make the dark funnel fully visible. It will give you a framework strong enough to guide the next investment without pretending uncertainty has disappeared.
References
- Search Engine Land — Measuring AEO: A 3-layer attribution framework
- Search Engine Land — How to become the answer in AI search: The ASC framework

Leave a Reply