Tag: Branded Search

  • Google Meridian Marketing Measurement: A Practical Guide

    Google Meridian Marketing Measurement: A Practical Guide

    Your paid-search dashboard says the campaigns are profitable. Brand demand was also rising, several other channels were active, and the customers who clicked may have intended to buy before they saw an ad. The dashboard can report the click. It cannot tell you how much of the outcome the advertising actually created.

    Google Meridian is built for that measurement gap. It uses aggregated marketing and business data to estimate incremental contribution without reconstructing individual customer journeys. Used carefully, it can give you a better basis for budget decisions. Used with weak data or overconfident assumptions, it can simply replace a misleading attribution number with a more sophisticated one.

    Choose Meridian for incrementality, not user-path attribution

    Google Meridian is an open-source, Python-based, fully Bayesian marketing mix modeling framework. It was introduced in 2024 and made available to marketers and data scientists in early 2025. Its purpose is not to produce a more detailed conversion path. It estimates how changes in marketing activity relate to changes in an outcome such as revenue, leads, or store visits.

    That distinction matters most in paid search. Under last-click attribution, a keyword can receive all the credit when someone clicks an ad and then buys. The method records what happened immediately before the conversion, but it cannot establish whether the ad generated the demand, captured demand created elsewhere, or intercepted a customer who was already looking for the brand. Meridian is designed to estimate the incremental revenue associated with search advertising rather than assigning credit to the final click.

    Use Meridian when your decision concerns channel-level or campaign-group investment over time. Suitable questions include:

    • How much of the observed revenue or lead volume was likely incremental to paid media?
    • Does branded search still look efficient after accounting for underlying search interest?
    • How should channel allocation change under a plausible budget scenario?
    • How does an experiment change the model’s estimate of a channel’s contribution?

    Do not use Meridian to answer which ad caused one person’s purchase, which exact sequence of touchpoints every customer followed, or what a single keyword will deliver tomorrow. Those are different measurement problems. Meridian works with aggregate patterns, so its useful resolution is constrained by the time, geographic, media, and outcome data you supply.

    This also explains why Meridian should complement rather than erase your operational reporting. Click and conversion data can still help with campaign pacing, landing-page diagnosis, and day-to-day execution. The mistake is treating those records as proof of incremental business impact.

    Treat search demand as a control, not proof of ad impact

    Search has an unusually difficult causality problem because demand often precedes the advertisement. A customer hears about your company, decides to visit, searches the brand name, and clicks the sponsored result. Spend, clicks, and sales all rise together, but the paid ad may not have caused the original intent.

    Meridian addresses part of this problem by allowing Google Query Volume to enter the model as a control variable. Query volume represents search interest, not paid-media performance. Including it can help the model separate underlying organic demand from paid-search effects.

    For your implementation, keep three data concepts separate:

    • Marketing input: paid-search spend, impressions, or the media variable selected for the model.
    • Demand control: query volume aligned to the same geographic and weekly structure.
    • Business outcome: the revenue, lead, or store-visit measure the model is supposed to explain.

    Do not substitute clicks for query volume and call the search-intent problem solved. Clicks are produced by the advertising system and sit inside the mechanism you are trying to measure. A demand control needs to represent the broader interest that may have existed without the paid click.

    Geographic variation provides another useful signal. Meridian’s hierarchical approach can model differences in spend and performance across regional or local markets. If one region’s media changes differently from another’s while you observe their outcomes, the model has more information with which to estimate incremental impact. If every region receives the same proportional budget change in the same week, geography adds far less identifying variation.

    Before modeling, plot spend, query volume, and the outcome by region. Look for markets that move in lockstep, regions with long missing periods, and abrupt jumps caused by reporting changes rather than customer behavior. You are not trying to find a pleasing correlation. You are checking whether the geographic panel contains real, explainable variation.

    Demand also changes without any media intervention. Meridian supports time-varying intercepts intended to account for seasonality, macroeconomic movement, and long-term organic growth in the baseline. That feature is important, but it is not permission to omit known business events. Record material pricing changes, distribution shifts, promotions, measurement changes, and other events that could move the outcome. The model cannot recognize an undocumented reporting break as a reporting break.

    Query volume and a flexible baseline reduce specific biases; they do not eliminate every confounder. Treat them as improvements to the causal design, not as automatic proof that every remaining paid-search effect is causal.

    Build a model-ready geo-by-week dataset
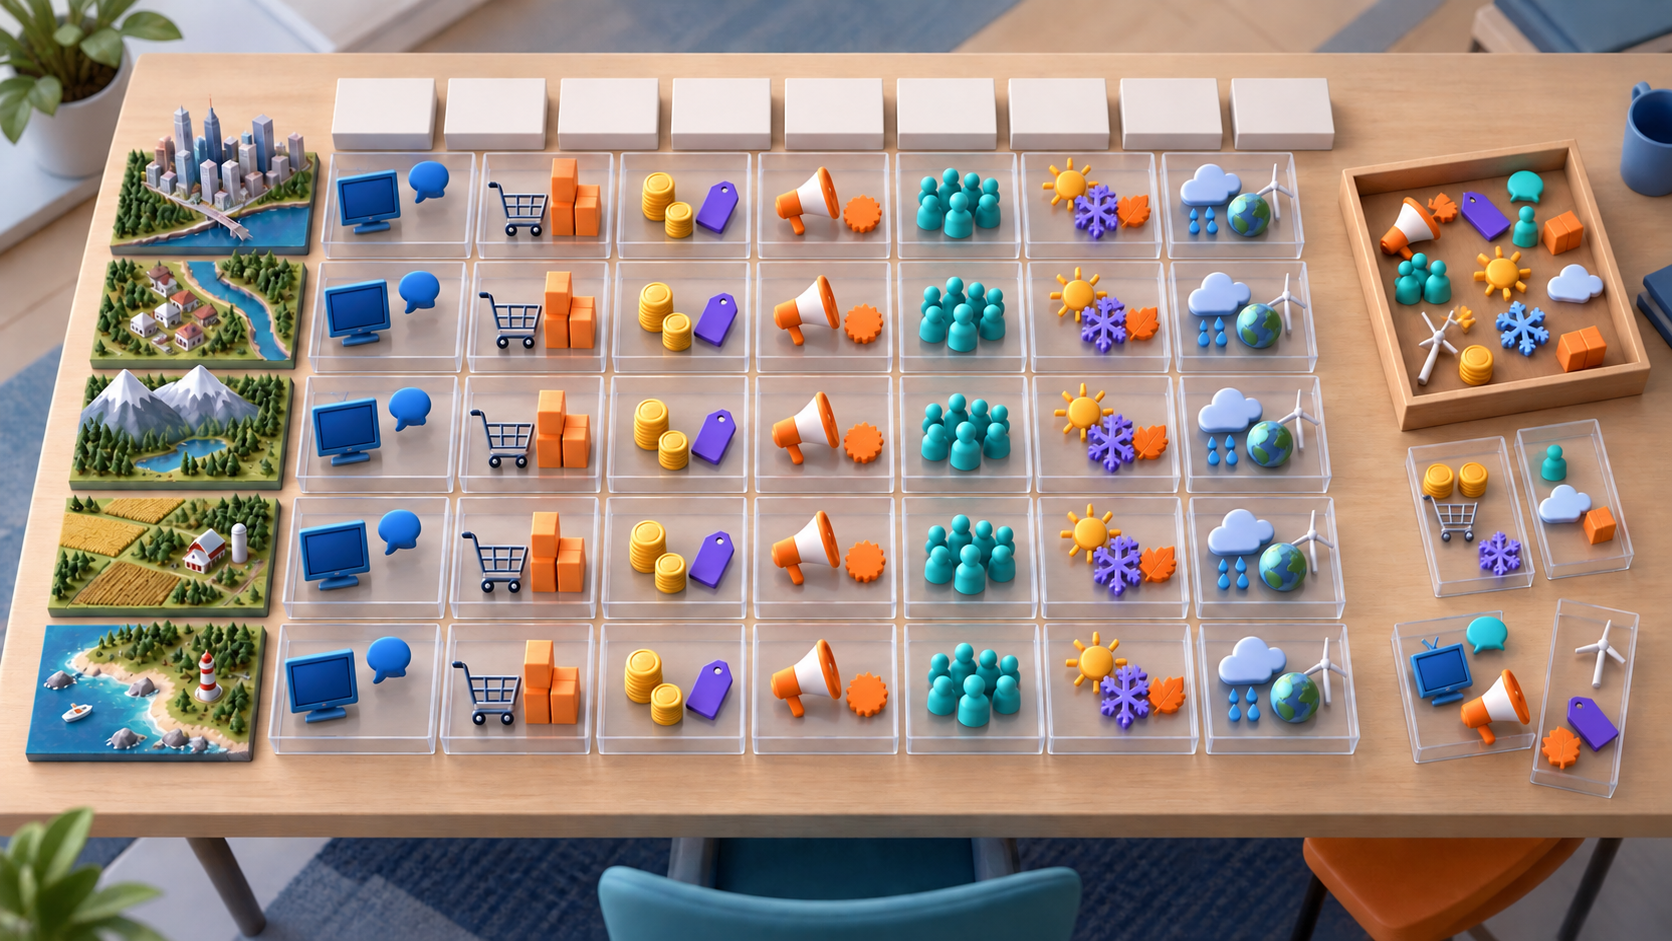
    Overhead illustration of geographic tiles and weekly blocks organized with media, sales, pricing, and seasonal data tokens.

    The practical readiness benchmark is historical weekly data, ideally broken out by geography and covering at least two years. That duration is an ideal, not a guarantee of quality and not a substitute for useful variation. Two years of inconsistent definitions can be less informative than a shorter, well-governed panel.

    Start with the decision, then choose one primary outcome. If the budget decision is about revenue, build a revenue model. If the organization manages acquisition against leads or store visits, define that measure precisely and keep the definition stable. Mixing several business outcomes into an ambiguous success metric makes the final recommendation hard to interpret.

    Data blockWhat to includeReadiness check
    Business outcomeWeekly revenue, leads, or store visits by geographyOne documented definition, stable units, and known reporting breaks
    Paid mediaSearch spend and impressions, plus relevant offline and other-channel metricsConsistent channel mapping and reconciliation with platform or finance totals
    Search demandGoogle Query Volume at a compatible geographic and time levelTreated as a demand control rather than a paid-media result
    Nonmarketing controlsKnown factors such as pricing changes and available competitor-sales signalsA credible reason each variable could affect the outcome independently of media
    Experimental evidenceRelevant incrementality or geo-lift resultsComparable channel, outcome, market, and time context, with uncertainty retained

    Audit the panel before anyone starts tuning a model:

    1. Write a data dictionary. Define every field, currency, geographic identifier, week boundary, and unit. Decide how refunds, cancellations, or revised records are handled before fitting.
    2. Reconcile totals. Aggregate the regional data and compare it with the totals used by finance and the media platforms. Explain material differences rather than silently accepting them.
    3. Distinguish zero from missing. Zero spend means the channel was inactive. A blank value may mean the feed failed. Treating both as zero can manufacture variation that never occurred.
    4. Map structural breaks. Mark changes to tracking, CRM stages, revenue recognition, pricing, territorial boundaries, and campaign naming. A clean-looking time series can still join incompatible definitions.
    5. Inspect geographic variation. Compare when and how sharply media changed across regions. Flag channels that moved almost identically everywhere, because the model may struggle to separate their effects.
    6. Preserve useful search detail. Keep enough campaign information to inspect branded search separately before deciding which paid-search activity should be grouped for modeling.

    Meridian can also use aggregated national data, but you give up some of the regional contrasts that make its geo-level approach valuable. If reliable geographic outcomes do not exist, be explicit about that limitation. Do not create false precision by assigning national sales to regions with an arbitrary allocation rule.

    A failed readiness audit is useful. It tells you to repair collection, preserve future geographic variation, or plan an incrementality experiment before asking the model for a budget answer. Forcing a run through a broken panel only postpones that work until the recommendations become harder to defend.

    Calibrate the Bayesian model before moving budget
    Balanced calibration mechanism with probability spheres, channel inputs, uncertainty rings, and budget tokens awaiting allocation.

    Meridian’s Bayesian design lets you combine historical aggregate data with prior knowledge. A prior expresses what the model knows about a parameter before it learns from the current dataset. If you have measured a channel through an incrementality test or geo-lift experiment, that result can inform the model’s priors.

    This is one of Meridian’s most useful features, but only when the evidence is genuinely comparable. A test of one campaign, market, or outcome should not be treated as universal truth for every form of search advertising. Document what was tested, where it ran, which outcome it measured, and how uncertain the estimate was. Carry that uncertainty into calibration rather than entering only the most convenient point estimate.

    Do not turn last-click return on ad spend into a strong prior merely because it is the number the team already has. That would import the original attribution bias into a model intended to move beyond it. If there is no credible experimental evidence, use appropriately cautious assumptions and let the observed aggregate data do more of the updating.

    A defensible implementation sequence looks like this:

    1. Write the measurement brief. Name the budget decision, primary KPI, planning horizon, channels in scope, and business constraints.
    2. Freeze an audited data version. Keep the model input reproducible so later changes can be traced to a data revision or a modeling decision.
    3. Specify the model. Decide the geographic structure, media variables, search-demand control, nonmarketing controls, and treatment of baseline movement.
    4. Calibrate with credible experiments. Record which prior each test informs and why that test is relevant.
    5. Examine uncertainty and sensitivity. Check whether the decision changes when reasonable priors, controls, or groupings change. A recommendation that reverses under a small specification change is not ready for a large budget shift.
    6. Run bounded scenarios. Use Meridian’s what-if planning capability for changes that remain plausible relative to the observed history. Treat extreme extrapolation cautiously.
    7. Stage the decision. Make a controlled change, define the outcome you will watch, and use a follow-up experiment where the financial consequence justifies it.

    The fitting work requires Python, commonly through a Jupyter Notebook, and usually needs an analyst or data scientist comfortable with model specification. Open source does make the code inspectable and modifiable. That helps your team review assumptions and adapt the framework, but it does not make every specification equally valid.

    When results arrive, resist reducing the posterior output to one definitive return number. Look at the range of credible outcomes, the contribution of the baseline, sensitivity to priors, and whether the result is consistent with experimental evidence. If a proposed reallocation could materially affect revenue, use the model to narrow the decision and then validate the change. Do not place a large financial bet on one run merely because its point estimate is precise.

    Google Meridian measurement FAQ

    Does Meridian replace Google Ads or analytics reporting?

    No. Advertising and analytics reports remain useful for delivery, pacing, conversion monitoring, and campaign diagnosis. Meridian addresses a different question: how much incremental business impact aggregate marketing activity appears to have produced. Keep operational reporting for execution and use the marketing mix model for strategic allocation.

    Do you need exactly two years of weekly data?

    Two years of weekly observations is an ideal data target, not proof that a model will work and not a stated universal cutoff. Coverage, consistency, geographic variation, and known business controls also matter. If you have less history, do not conceal the limitation. Assess whether a narrower model is defensible or whether data collection and experimentation should come first.

    Can a smaller company use Meridian?

    The code is openly available, so access is not restricted to companies with large television budgets. Practical suitability depends on whether you have enough stable historical data, meaningful media variation, a measurable outcome, and Python-capable analytical support. A smaller business with good data may be better positioned than a large organization with fragmented systems.

    Does open source make Meridian objective?

    No. Open source makes the underlying code available for inspection and modification, which reduces black-box risk and lets your team challenge the implementation. The answer still depends on the data, variables, priors, channel grouping, and assumptions you choose. Transparency makes scrutiny possible; it does not perform the scrutiny for you.

    Your next step should be a data inventory, not a software installation. Export weekly outcomes, paid-search spend, impressions, and available query volume by geography. Mark whether each field has two years of consistent coverage, identify definition changes, and inspect how much regional variation actually exists. If that panel survives the audit, write down the single budget decision the first model must support and assign a Python-capable analyst. If it does not, fix the collection gap or design an experiment before asking Meridian for an answer.

    References


  • Exact-Match Domains in 2027: What Is Actually Valuable?

    Exact-Match Domains in 2027: What Is Actually Valuable?

    A domain broker has the phrase your customers search, and the asking price assumes it comes with an SEO advantage. Your decision turns on a simpler question: are you buying ranking power, or are you buying a better name?

    In 2027, treat the ranking power as zero when you value the domain. An exact-match domain can still be an excellent business asset, but it has to earn its premium through clarity, recall, recognition, direct navigation, or strategic fit. The matching keywords alone are not the asset.

    The old exact-match ranking shortcut is gone

    Google gives a matching word in a domain or URL almost no standalone ranking weight, apart from how that word may appear in breadcrumbs. It also maintains an exact-match domain system intended to keep sites from receiving excessive credit merely because their domains mirror particular queries.

    The historical advantage was more complicated than a keyword sitting in a URL. A domain such as siamesekittens.com was likely to attract links whose anchor text, site name, and destination URL repeated the same phrase. Those reinforcing signals mattered more when keywords in domains carried more weight. The domain was part of a feedback loop, not a magic switch.

    That history creates a correlation trap. You can find strong businesses operating on exact-match domains, but you cannot assume the domain caused their visibility. The site may have better content, stronger links, greater market recognition, more direct demand, or a business people already know. Buying a similar-looking domain does not transfer those advantages.

    AI search does not restore the shortcut. A query-like domain is not proof that an organization is authoritative, distinct, or suitable for citation. Search and answer systems still need to determine which organization produced the information, what that organization is known for, and whether other signals support its claims. Matching the user’s wording may make the address understandable, but it does not answer those larger questions.

    Key takeaways

    • Do not buy an exact-match domain for an assumed Google ranking boost.
    • Value it as a naming, recognition, navigation, or positioning asset.
    • Distinguish a memorable descriptive brand from a generic search phrase.
    • Do not assume an exact match creates authority in AI search or answer engines.
    • Set the purchase price using benefits you can explain and, where possible, verify.

    A strong exact-match domain can still be a strong business asset

    Removing the presumed ranking bonus does not make every exact-match domain worthless. Some are unusually good names. Cars.com is short, easy to spell, easy to remember, and immediately tells a visitor what the business covers. The fact that cars is also a valuable keyword does not stop the domain from functioning as a brand.

    A descriptive name can be especially useful when you do not have a large advertising budget for teaching the market what an invented word means. If someone hears the domain once on a podcast, sees it briefly in an advertisement, or receives it as a recommendation, immediate comprehension reduces friction. That is a business benefit even if it adds no special ranking weight.

    Asset testEvidence that can justify a premiumWarning sign
    ClarityA new visitor understands the business without an explanation.The name could describe a company, directory, comparison page, or individual article.
    RecallPeople can remember and spell the domain after hearing it once.The name needs hyphens, qualifiers, unusual spelling, or repeated clarification.
    Direct navigationPeople already type or request the domain specifically.Traffic value exists only in a seller’s unsupported forecast.
    RecognitionThe name has documented awareness, references, links, or established market use.The asking price treats the keyword’s popularity as if it were brand recognition.
    Strategic fitThe name still suits the company if its products, geography, or audience expand.The phrase confines the business to one narrow service or location it expects to outgrow.

    Use those tests before discussing search volume. Search demand can explain why a category matters, but it does not automatically make one domain worth the seller’s price. The premium must connect to something the business can use: a clearer name, lower explanation cost, existing recognition, memorable advertising, direct visits, or control of scarce digital real estate.

    If the entire case is that the domain contains a lucrative keyword, walk away. If the domain would still be your preferred brand even with no search engine benefit, the conversation is worth continuing.

    Descriptive becomes a liability when it stops identifying you

    Descriptive and generic are not the same. A descriptive domain tells people what the business does. A generic domain merely restates a topic or query without clearly naming the organization behind it.

    Consider bestchicagoroofers.com. You can infer the subject immediately, but you cannot tell whether Best Chicago Roofers is a roofing company, a directory, a lead-generation operation, a ranked list, or a page about contractors in Chicago. The words provide topical clarity while leaving organizational identity unresolved.

    Google’s site-name guidance recommends a unique name that accurately represents the site’s identity. It uses a similarly generic label, Best Dentists in Iowa, to illustrate a name that is unlikely to be selected as the site’s name unless it is already a highly recognized brand. That does not mean generic domains cannot rank. Ranking a page and recognizing a distinct site name are different problems.

    The distinction also matters for AI discovery. A system trying to associate facts, mentions, reviews, credentials, and content with one organization needs a stable identifier. A string that reads like an ordinary query can make that association less clear, especially when the company uses a different name in its logo, structured data, profiles, and legal pages.

    Run a simple identity test before buying. Ask what a customer would call the company in conversation, what name a journalist or supplier would use when referring to it, and whether that name could point to only one organization in context. If every answer falls back to a phrase such as the Chicago roofers website, the domain describes a subject better than it identifies a brand.

    You do not need an invented five-letter name to solve this. A compact category word can become a distinctive brand when it is memorable and consistently associated with one organization. The problem is not descriptiveness itself. The problem is buying a long search phrase and mistaking its specificity for identity.

    Use a zero-SEO valuation before paying a premium

    A balance scale weighs a web-address token against symbols of strategy, commerce, recognition, and direct navigation while magnifying glasses sit aside.

    A premium domain is a capital allocation decision. Remove speculative ranking gains from the calculation, then work through the value that remains.

    1. Define the domain’s job. Decide whether you want it to be the company name, a memorable campaign address, a defensive registration, or an acquisition with existing recognition. A domain cannot be valued sensibly until its job is explicit.
    2. Model no ranking improvement. Assume your pages would occupy the same search positions on a neutral domain. If the purchase no longer makes economic sense, the price depends on an outdated SEO premise.
    3. Test comprehension and recall. Say the name aloud, ask whether its spelling is obvious, and check whether someone could remember it later without seeing it written. A phrase that is clear on a screen can still perform poorly in conversation.
    4. Test identity and expansion. Ask whether the domain sounds like one organization and whether it will still fit if the business adds services, enters another location, or changes its primary offer.
    5. Verify claims of existing value. If a seller prices in direct traffic, recognition, links, or recurring referrals, ask for evidence you can validate. Do not pay for a narrative as though it were measured demand.
    6. Compare the opportunity cost. Put the premium domain beside a less expensive, distinctive alternative. Then compare what the difference could fund in content, product, public relations, distribution, or customer acquisition.

    Your ceiling should come from justified naming value plus verified recognition or navigation value, minus transition costs and the value of the next-best use of the money. The keyword’s commercial importance may influence demand for the domain, but it does not obligate your business to pay the market’s asking price.

    If you already operate a recognized site, do not change domains solely to acquire matching keywords. A migration changes URLs and introduces opportunities for redirect, canonical, analytics, backlink, and indexing errors. Move only when the new name has enough durable business value to justify both the purchase and the technical transition.

    An expensive acquisition also deserves ordinary legal and transactional care. Screen the proposed name for trademark and naming conflicts, verify the seller’s control of the domain, and use qualified legal or domain-transaction help when the purchase is material. A memorable address is not valuable if its ownership or use creates a dispute.

    Build one recognizable entity around the name you choose

    A central geometric emblem connects to a storefront, package, mobile device, support desk, and parcel that share the same visual motif.

    Once you choose the domain, make the organization easy to identify. This is where branding, technical SEO, and AI optimization meet. The goal is not to repeat the domain’s keywords everywhere. It is to give people and machines one consistent answer to the question: who is responsible for this site?

    • Choose one canonical organization name. Use it consistently in the header, About page, contact information, author or publisher details, and relevant external profiles.
    • Separate the brand from the descriptor. Keep the organization name stable and use a tagline or page copy to explain the category, location, or service. Do not turn every target query into part of the company name.
    • Align visible and structured identity. Organization and WebSite structured data should match the name and identity users can see on the page. Schema can clarify an entity; it cannot manufacture recognition or authority.
    • Keep page targeting at the page level. Build useful pages for distinct questions and services instead of expecting one keyword-heavy domain to make the entire site relevant to every variation.
    • Watch the signals that reflect real brand value. Monitor branded searches, direct visits, referral language, earned mentions, and how the site name appears in search. These reveal whether the market recognizes the identity rather than merely encountering the URL.
    • Correct inconsistency early. If the domain, logo, structured data, profiles, and legal name all present different identities, decide which name customers should remember and align the rest around it.

    This work matters whether the domain is exact-match, descriptive, or invented. A category domain may reduce the time needed to explain what you do, but consistent identity, useful content, authority, and market recognition are what turn the address into a brand.

    Before you answer a seller, put the domain through the zero-SEO valuation. If the purchase still works because the name is clear, memorable, distinctive, and strategically useful, it may be exceptional digital real estate. If the numbers work only after adding an assumed ranking boost, keep the money and build the signals search engines and AI systems actually need.

    References


  • Search Marketing Attribution: Measure Incremental Revenue

    Search Marketing Attribution: Measure Incremental Revenue

    Your search dashboard can look healthy while the budget decision remains unresolved. Paid search claims conversions, organic search receives assisted credit, and AI-search referrals appear in GA4 when referral data survives. Then finance asks the question the dashboard cannot answer: how much revenue would disappear if you stopped?

    Choosing another attribution model will not settle that question. You need two connected systems: an evidence chain that follows search activity into realized revenue, and a causal test that estimates what search created rather than merely touched. Here is how to build both without pretending the data is cleaner than it is.

    Attribution assigns credit; incrementality tests causation

    Attribution asks which observed touchpoints should receive credit for a conversion. Incrementality asks whether the conversion happened because of the marketing activity. Those are different questions, and they support different decisions.

    Consider a customer who already intends to buy, searches for your brand, clicks a paid result, and completes the purchase. An attribution model may give the ad full or partial credit because the click is visible. An incrementality test asks how many comparable customers would have purchased without being eligible to see that campaign.

    This distinction matters most when a channel sits close to conversion. Branded Search can collect a large amount of credited revenue without necessarily creating an equally large amount of new demand. Performance Max can span several Google properties, making channel-by-channel paths harder to interpret. For eligible Search and Performance Max campaigns, user-based Conversion Lift creates an unexposed holdout and compares its behavior with that of users who can be exposed. The difference estimates incremental conversions.

    That does not make attribution useless. Attribution helps you reconcile customer journeys, diagnose tracking, allocate observed credit, and identify where conversions are being captured. It becomes misleading only when credited revenue is presented as revenue caused.

    Key takeaways

    • Use attribution to describe observed paths and allocate credit; use incrementality to make causal budget claims.
    • Connect search activity to realized revenue before debating which attribution model deserves the final click.
    • Keep unknown and unattributed revenue visible instead of forcing every conversion into a channel.
    • Run a controlled test when the causal answer could change a meaningful spending decision.
    • Report attributed and incremental results side by side. Never substitute one for the other.

    Build the revenue trail from the business outcome backward

    A continuous illuminated path connects search touchpoints, a conversion gateway, a customer record, a contract, a payment, and gold revenue tokens.

    A reliable measurement plan begins with the outcome your organization recognizes as revenue. It does not begin with the easiest event in GA4 or the conversion a media platform happens to optimize.

    1. Define the commercial outcome. For ecommerce, decide whether the recognized value is the completed order, collected payment, or revenue after refunds and cancellations. For lead generation, distinguish a submitted form, qualified lead, opportunity, and closed-won sale. Write down the event, its valuation method, and the point at which it becomes reportable revenue.
    2. Capture acquisition evidence. Store campaign parameters for links you control, along with the landing page, referrer when available, and timestamp. Add a self-reported discovery question when the buying journey can begin in an AI answer, an untagged result, or another environment that may not pass referral data. Keep the self-reported answer separate from the machine-captured source.
    3. Preserve the first and subsequent touches. Do not overwrite the original source every time a person returns. Retain the initial discovery evidence, the most recent measurable interaction, and relevant intermediate touches so that later analysis can distinguish demand creation from conversion capture.
    4. Carry a stable record into the revenue system. Use an approved internal transaction or lead identifier to connect analytics activity with the order platform or CRM. Avoid relying on names or email addresses as analytical keys when a privacy-safe internal identifier is available.
    5. Reconcile to realized value. Join the record to the value finance recognizes. Document how you treat duplicates, reopened opportunities, cancellations, refunds, repeat purchases, and records that never match.
    6. Measure coverage. Report the share of conversions with a known acquisition source, the share of revenue successfully matched to a transaction or CRM record, and the amount left unknown. A visible unknown bucket is more trustworthy than invented precision.

    AI search makes this discipline especially important. When an AI answer does not pass a referrer or tracked link, a later direct visit cannot reveal the earlier discovery by itself. Self-reported discovery can provide supporting evidence, but it should not silently replace behavioral data. Treat agreement between the two as corroboration and disagreement as a reason to inspect the journey.

    A workable AI-search revenue program puts GA4 setup, a five-level attribution ladder, and a board-ready scorecard in the same measurement system. Traffic collection without revenue reconciliation stops too early. A revenue total without source coverage hides too much.

    Use a five-level ladder to prevent signal inflation

    Search teams often mix visibility, visits, conversions, and revenue in one report even though each represents a different level of evidence. A five-level ladder keeps those claims separate.

    1. Visibility. Rankings, impressions, mentions, citations, or other forms of search presence show that your brand or content can be discovered. They do not establish that a person visited or bought.
    2. Visits. Sessions, referral data, campaign parameters, and landing-page activity show measurable traffic. They still do not prove that the visit produced a qualified outcome.
    3. Qualified outcomes. A business-defined action such as a qualified lead or valid purchase separates meaningful demand from raw activity. The definition must be stable enough to compare across channels.
    4. Attributed revenue. Transactions or closed-won revenue matched to observed search interactions show where measurable credit appears. The attribution model determines how that credit is distributed.
    5. Incremental value. A controlled comparison estimates the additional conversions or revenue caused by the marketing activity. This is the level needed for a causal return claim.

    Apply one rule throughout the report: a metric keeps the label of the highest level its evidence actually supports. Do not multiply AI-search visibility by an average conversion rate and present the result as measured revenue. That calculation may be useful as a forecast or scenario, but it remains modeled value and should be labeled accordingly.

    The same rule applies when you change attribution models. Moving from one credit-allocation method to another can redistribute attributed revenue among touchpoints. It cannot promote the result from attributed revenue to incremental value. A different model changes the accounting view, not the counterfactual.

    For each channel, ask what prevents the evidence from moving to the next level. Missing campaign parameters block clean visit classification. An analytics-to-CRM gap blocks revenue matching. A lack of controlled variation blocks causal inference. This turns the ladder into a measurement backlog rather than a decorative maturity score.

    Run an incrementality test when the answer can change spend

    Two matched miniature markets are separated into treatment and control groups, with a search-marketing beam and additional revenue tokens appearing only in the treatment group.

    Incrementality testing has a real cost. A holdout withholds campaign exposure from some users, and those users may generate fewer conversions. Use the method when the result can change a material decision: whether to retain, reduce, expand, or restructure a campaign.

    Self-serve Google Ads Conversion Lift has explicit eligibility gates for Search and Performance Max. An advertiser needs at least 1,000 observed conversions, excluding conversions that use supplementary data; participating campaigns need a minimum budget of $5,000; and the account needs at least one compatible conversion action. Availability can still vary by account, and alpha or beta campaign types may require assistance from a Google representative.

    Meeting those gates does not guarantee a decisive result. The selected action must occur frequently enough to be statistically useful. Purchases, leads, website activity, and other eligible actions can be evaluated, but the action you choose should correspond as closely as possible to the decision you need to make.

    1. Write the decision first. State which campaign and budget choice the result will inform. A test without a decision attached tends to become an interesting chart rather than an operating tool.
    2. Choose one primary outcome before launch. Define the eligible conversion action and how it maps to revenue. If the action is a lead rather than a sale, keep the test result in incremental leads until you have a defensible lead-to-revenue mapping.
    3. Set the campaign scope. Include the campaigns needed to answer the question and avoid mixing unrelated budget decisions into the same test.
    4. Accept the holdout tradeoff explicitly. A larger holdout can improve the comparison sample, but it also withholds ads from more users. Record who accepted that opportunity cost and why it is proportionate to the decision.
    5. Keep the plan stable. Avoid changing the primary outcome, campaign scope, or interpretation rule after seeing an early result. If operations force a material change, document it rather than presenting the test as untouched.
    6. Translate the output only as far as the evidence allows. Report incremental conversions directly. Convert them to incremental revenue only through an agreed value mapping, then connect that revenue to margin if the budget decision is based on profit.

    Keep two efficiency calculations distinct:

    • Attributed ROAS = attributed revenue divided by advertising spend.
    • Incremental ROAS = incremental revenue caused by the advertising divided by advertising spend.

    Attributed ROAS can be much higher than incremental ROAS when a campaign captures conversions that were likely to happen anyway. That does not automatically mean the campaign has no value. It means its budget case should be made with incremental economics rather than the full amount of credited revenue.

    If you are not eligible for the platform test, do not turn a before-and-after chart into causal proof. A carefully designed geographic or phased-rollout test may provide a comparison when you can maintain a credible control and consistent measurement. If you cannot create that comparison, report attributed performance and state plainly that the incremental effect has not been measured.

    A board-ready scorecard shows the decision, not just the dashboard

    Executives do not need every touchpoint row. They need to see what is observed, what is inferred, what is causal, how much of the revenue trail is covered, and what decision follows.

    Scorecard lineWhat to showQuestion it answersRequired label or caveat
    Attributed revenueRealized revenue allocated to measurable search interactionsWhere did observed credit appear?Name the attribution method and reporting scope
    Incremental outcomeAdditional conversions or revenue estimated by a valid control comparisonWhat did the campaign cause?Show the tested campaigns, primary outcome, and uncertainty provided by the test
    Measurement coverageSource-known conversions, revenue-matched records, and unknown revenueHow complete is the evidence chain?Do not redistribute the unknown bucket
    EconomicsSpend, attributed ROAS, incremental ROAS when available, and the finance-approved value basisIs the activity economically useful?Keep attributed and incremental returns separate
    DecisionScale, retain, reduce, retest, or repair measurementWhat changes because of this result?Name the owner and the condition that would reverse the decision

    Read the combinations, not just the largest number:

    • High attributed revenue and credible positive lift: the channel is receiving credit and creating additional outcomes. Evaluate whether incremental economics support more investment.
    • High attributed revenue and weak or uncertain lift: the channel may be capturing existing demand. Do not use the credited total as proof that the same revenue would vanish with the spend.
    • Low attributed revenue and poor measurement coverage: the result is inconclusive. Repair source capture and revenue matching before treating the channel as ineffective.
    • Attribution changes sharply when the model changes, while experimental lift remains stable: the disagreement is primarily about credit allocation, not whether the campaign caused additional outcomes.
    • No credible control comparison: keep the causal field marked as not measured. A blank causal result is more useful than a confident answer produced by the wrong method.

    In your next reporting cycle, add two lines to every search performance review: “What revenue can we trace?” and “What revenue did we cause?” If the second answer is unavailable, do not replace it with modeled certainty. Mark it as not yet measured, identify the live budget decision it affects, and plan the smallest credible control test around that decision. This prevents credited revenue from being mistaken for created demand.

    References


  • AI Overviews on Branded Searches: A Practical Audit Plan

    AI Overviews on Branded Searches: A Practical Audit Plan

    You can still rank first for your own name and lose control of the first impression. When a Google AI Overview appears on a branded query, it can frame your company, products, policies, or reputation before the searcher decides whether your result deserves a click.

    Your job is not to make every overview disappear or chase every citation. You need a repeatable way to find the queries that matter, distinguish a genuine brand risk from a harmless summary, repair weak information at its origin, and measure whether search behavior changes.

    Ranking first no longer tells you how Google frames your brand

    The scale of the change makes branded AI visibility worth treating as a standard search responsibility. In one tracked branded-keyword set, AI Overview presence rose from about 26% at the start of September to more than 80% late in the month, with a peak of 90.48% on September 27. A separate SerpApi check found AI Overviews for 93 of 100 enterprise brands.

    Those figures are a warning to monitor, not a universal incidence rate or a forecast for your site. The tracked terms were checked once per day across all markets and devices, and an overview counted as present whether or not it cited the brand. The enterprise-brand check was a separate snapshot. Google had not announced a corresponding change when the surge was observed.

    This distinction matters. An AI Overview can appear on your branded query without using your site as evidence. It can also cite you while compressing a qualification that matters to a buyer. Presence, citation, accuracy, framing, traffic, and business impact are separate things. Track them separately.

    Key takeaways

    • Treat branded AI Overviews as a search, content, and reputation surface rather than another ranking position.
    • Monitor high-intent and high-consequence brand modifiers, not only your exact company name.
    • Record what the overview says, which pages it cites, whether an owned page appears, and which claims need correction.
    • Repair canonical facts and contradictory content before trying to influence the wording of a generated answer.
    • Measure branded clicks and outcomes directly. Wider AI Overview presence does not, by itself, prove traffic loss.

    Build your monitoring set around real brand decisions

    Blank query cards are grouped around objects representing a company, product, policy, purchase decision, and reputation, with priority markers and a magnifying glass.

    A search for your bare brand name is only the starting point. The more revealing queries combine the brand with a decision, concern, or task. That is where an inaccurate synthesis can change what someone buys, believes, or does next.

    Build a stable query set from your search-query data, customer questions, support records, sales objections, and reputation monitoring. Group the terms by the decision behind them:

    • Identity: your brand name, what the company does, who it serves, and how it differs from similarly named entities.
    • Commercial: brand plus pricing, plans, products, availability, integrations, demo, or purchase terms.
    • Evaluation: brand plus reviews, alternatives, comparisons, complaints, reliability, or legitimacy.
    • Service and policy: brand plus login, contact, cancellation, refund, support, privacy, security, returns, or warranty.
    • Named entities: important products, locations, programs, and publicly associated people whose details affect how the brand is understood.

    Do not prioritize by search volume alone. A low-volume cancellation, security, or product-eligibility query can create more damage than a high-volume neutral query. Give each query an intent label and a consequence label. This lets you separate commercially important or reputationally sensitive questions from routine navigational searches.

    Check the list under repeatable conditions. Use the same market, device class, and signed-in state where possible. For every observation, preserve enough information to compare it later:

    • The exact query, not a shortened topic label.
    • The date, market, device class, and relevant session conditions.
    • Whether an AI Overview appeared.
    • The complete wording or a screenshot of the answer.
    • Every cited page and the order in which citations appeared.
    • Whether any cited page is controlled by your organization.
    • Each factual claim that is correct, outdated, incomplete, unsupported, or false.
    • The associated branded impressions, clicks, click-through rate, and business outcomes, kept outside the content-quality judgment.

    That last separation prevents a common analytical mistake. An overview can be factually poor without producing a measurable traffic decline, and it can be factually accurate while changing click behavior. You need both views to decide what deserves action.

    Grade the answer by consequence, not by whether you like it

    A generated description does not become a defect merely because it is less flattering than your marketing copy. Your audit needs labels that another person can verify. Start with factual accuracy, necessary context, citation support, and likely consequence.

    FindingWhy it mattersNext move
    Materially false claimIt could send a customer to the wrong action or create a false belief about the company, product, price, access, or policy.Document the correct fact, identify the likely conflicting evidence, and escalate it ahead of ordinary optimization work.
    Outdated factThe answer may once have been correct but no longer reflects a current offer, feature, location, policy, or relationship.Strengthen the current canonical page and clearly mark or update obsolete owned material.
    Qualification removedA broadly correct statement becomes misleading when a market, plan, eligibility rule, date, or other condition disappears.Put the condition next to the claim on the canonical page rather than burying it in a footnote or separate document.
    Claim unsupported by citationsThe answer goes beyond what its cited pages substantiate, making the synthesis difficult to verify.Capture the mismatch, then improve the clearest first-party evidence for the underlying question.
    Third-party-heavy citation setYour brand may be described mainly through reviews, directories, forums, or commentary even when an owned explanation should exist.Determine whether your page fails to answer the query directly before treating the third-party citations as the problem.
    Accurate but unfavorable descriptionThe answer may reflect a real customer, policy, product, or reputation problem rather than an information-retrieval failure.Address the underlying issue. Rewording your own page will not make a substantiated concern disappear.
    Accurate and adequately framedThe overview creates no material information problem even if it does not use your preferred language.Log it and monitor it. Do not manufacture work merely to replace neutral wording.

    Escalate first when a claim is both materially wrong and connected to an important decision. A false statement about whether a product is available, how an account is accessed, or what a policy permits deserves faster attention than an awkward but harmless company description.

    An owned citation is useful, but it is not a passing grade by itself. Read the generated claim against the cited passage. If your page states that a condition applies only to one plan or market, but the overview presents it as universal, the citation has not prevented a meaning error.

    Repair the evidence behind the answer

    A strategist reconnects several generic source documents so they feed through clear paths into a stable digital answer panel.

    You cannot directly edit an AI Overview. You can make the underlying information clearer, more consistent, and easier to verify. Work from the highest-consequence defect outward.

    1. Choose one canonical owned page for each important question cluster. A pricing query needs a current pricing page, not a vague feature page. A cancellation query needs a current policy or help page, not a promotional FAQ that avoids the actual process.
    2. Answer the question in visible copy. Use the exact company and product names. State the direct answer before the supporting detail. If the answer changes by market, plan, eligibility, or date, place that qualification beside the claim.
    3. Reconcile contradictions across owned material. Check product pages, support content, policy pages, legacy posts, downloadable documents, profiles, and location pages. Mark outdated material clearly and direct readers to the current record.
    4. Make structured data corroborate the page. Encode only facts supported by visible content and keep the values aligned with the canonical wording. Treat structured data as machine-readable confirmation, not a command that guarantees a particular overview or citation.
    5. Classify every influential third-party citation. Decide whether it is accurate, outdated, false, or opinion. For a verifiably false or stale statement, provide the publisher with concise evidence and the canonical correction. If the criticism is accurate, fix the underlying issue instead of pursuing removal simply because the page is unfavorable.
    6. Log the change and recheck the same query. Record what changed, where it changed, and which claim you expected it to clarify. A later overview change is useful evidence of movement, but it is not proof that one page edit caused the result.

    Avoid publishing a near-duplicate page for every branded modifier. That creates more places for facts to drift. One strong page can answer a coherent group of questions as long as its purpose, headings, and qualifications are explicit. The goal is query-to-answer alignment, not content volume.

    Also resist the urge to rewrite everything in promotional language. Generated answers need verifiable facts. Clear scope, current conditions, named products, and direct policy wording are more useful than unsupported claims of leadership or quality.

    Measure traffic impact without inventing a CTR story

    Wider AI Overview coverage does not prove that branded clicks have fallen. Neither the tracked branded-keyword series nor the separate enterprise-brand check measured clicks, leaving the actual branded CTR effect unknown. Treat traffic loss as a question to test in your own data, not a conclusion supplied by presence alone.

    Keep a stable query panel so the denominator does not change every time you run the audit. Track these measures by query cluster:

    • AI Overview presence: checked queries that triggered an overview divided by all checked queries.
    • Owned-citation coverage: triggered overviews containing at least one owned citation divided by all triggered overviews.
    • Material accuracy: high-consequence overviews without a material factual or qualification error divided by all high-consequence overviews reviewed.
    • Source mix: the balance of owned pages, publishers, review sites, directories, forums, and other cited page types.
    • Search response: impressions, clicks, and click-through rate for the same branded query clusters.
    • Business response: the relevant purchases, leads, account actions, support contacts, or other outcomes from branded landing sessions.

    Maintain both an unweighted query view and an impression-weighted view. The unweighted view stops a high-volume navigational term from hiding a serious low-volume error. The weighted view shows where changes could affect the largest share of observed search demand.

    Annotate other events that can change branded demand or result-page behavior, including campaigns, publicity, product changes, seasonality, and additional search features. If AI Overview presence rises while clicks and business outcomes remain stable, there is no evidence of an emergency. If CTR falls while conversions remain stable, investigate whether fewer low-intent visits explain the difference before declaring damage. If clicks and meaningful outcomes fall persistently within the same high-intent cluster, inspect the overview, citations, landing result, and other result-page changes together.

    A materially false answer remains a brand problem even when traffic looks normal. Conversely, an accurate overview is not automatically harmful because it answers part of the question without a click. CTR is a diagnostic measure; accurate representation and valuable business outcomes are the goals.

    Start with a small, consequential baseline: assemble your highest-intent and highest-risk branded modifiers, capture the current answers and citations, and correct the first material inconsistency you can verify. Once that record exists, the next AI Overview change becomes an observable search event rather than an anecdote.

    References


  • AI Search Visibility and Reputation Management Playbook

    AI Search Visibility and Reputation Management Playbook

    Your brand can appear often in AI answers and still be described badly. It can also have a clean first page in Google while an AI answer cites an unfavorable result buried much deeper. If you manage only rankings, sentiment, or citation counts, one of those gaps will eventually catch you.

    The practical answer is to run AI visibility and online reputation management as connected but distinct programs. One determines whether your brand enters the answer. The other determines which claims, sources, and impressions shape that answer.

    Key takeaways

    • A citation is evidence of retrieval, not approval. Measure brand visibility and brand sentiment separately.
    • Audit ordinary search results and AI answers together. A negative URL does not become harmless merely because it moves to page two.
    • Remove or correct damaging material at its origin when a legitimate path exists. Suppression is the fallback, not the first move.
    • Judge a suppression campaign by the accurate assets that earn visible positions, not by how many pages you publish.
    • Build a corroboration network: authoritative owned pages, credible independent coverage, complete business profiles, and useful video transcripts.
    • Track exact prompts, cited URLs, harmful claims, search positions, and citation persistence on a repeatable monthly schedule.

    Treat visibility and reputation as separate outcomes

    The first mistake is treating AI citation volume as a reputation score. It isn’t. A system may cite a brand because it is relevant, controversial, heavily documented, or central to the question. None of those conditions guarantees a favorable answer.

    A proprietary analysis of data tracked on Writesonic covered 9 million answers across nine AI platforms and more than 400 enterprise brands. Positive sentiment did not correspond to more citations across five of the largest platforms; the observed correlation was slightly negative. That is a directional finding from a vendor dataset, not proof that negative coverage causes visibility or that controversy is a sound growth strategy. It does show why citation counts cannot stand in for trust.

    Use two scorecards. Your visibility scorecard should answer whether the brand appears, which URLs are cited, and which prompts produce a recommendation, comparison, warning, or omission. Your reputation scorecard should record the accuracy, sentiment, prominence, and likely consequence of the claims being surfaced. A citation gain can then be recognized as a visibility win without being misreported as a reputation win.

    Build the audit around the questions people actually ask, not just your brand name. Include these intent groups:

    • Entity queries: the brand or executive name, ownership, location, leadership, history, and official website.
    • Commercial queries: pricing, alternatives, comparisons, reviews, and the best provider for a specific use case.
    • Trust queries: complaints, safety, legitimacy, lawsuits, regulatory issues, refunds, and recurring customer concerns.
    • Support queries: contact details, policies, account help, returns, cancellations, and other facts that should come from an official page.

    For each prompt, save the exact wording, platform, date, answer, brand description, cited URLs, and any unsupported claim. AI answers vary, so one screenshot is an observation rather than a trend. Repeat the same prompt set under comparable conditions and look for recurring sources and claims.

    Prioritize by consequence. An outdated address is easy to correct but usually less urgent than a false safety claim, a prominent complaint page, or an inaccurate comparison shown during a buying decision. Give each issue an owner and one of four actions: remove, correct, suppress, or strengthen. That turns an alarming collection of screenshots into an operating queue.

    Remove first, then suppress beyond the first page

    A robotic mechanism removes a dark tile while layers of brighter tiles extend behind it through a digital corridor.

    Removal is the cleanest outcome because a deleted URL cannot be retrieved again from the same location. Start by classifying every negative result by factual accuracy, publisher, source type, search position, AI citations, and whether you have a legitimate basis for deletion or correction.

    1. Preserve the evidence. Save the URL, page content, publication date, search position, and AI answer before requesting a change.
    2. Fix what you control. Correct outdated owned pages, inaccurate profiles, inconsistent executive biographies, and obsolete policy or product information.
    3. Request an appropriate remedy. Ask the publisher for a factual correction, update, or deletion when the facts justify it. A correction may be the realistic remedy when lawful reporting is accurate.
    4. Escalate carefully. Do not submit false copyright, privacy, or legal complaints. If removal depends on a disputed legal right, use qualified legal counsel rather than improvising a claim.
    5. Verify the result. Check the live URL, search result, cached description where applicable, and the AI experiences that previously cited it. A changed snippet is not the same as a removed page.

    If removal is unavailable, scope suppression from the starting position and number of negatives. Erase.com’s vendor-reported dataset covered 714 campaigns launched between August 2024 and May 2026. Campaigns whose highest negative began at position four or lower cleared the first page about 3.5 times as often as campaigns starting with a negative at number one. Campaigns with one negative cleared it about four times as often as campaigns with six to ten. These figures should inform workload and expectations, not become a guarantee for an individual case.

    Publishing volume alone did not separate success from failure in that dataset. Campaigns that cleared page one published a median of 28 assets, while those that did not clear it published 29. Placement was more revealing: successful campaigns had a median of six new assets in the top ten, compared with four in unsuccessful campaigns. Your working metric is therefore the number of accurate, relevant assets that earn visibility, not the number sent through an editorial calendar.

    Timelines also need a careful denominator. Among the campaigns in that dataset that eventually cleared page one, 40% did so by the end of month two, 63% by month three, and 85% by month four. That does not mean 85% of every campaign will succeed within four months. A top-ranked national news story, recent government page, durable Reddit thread, or established complaint profile is a different problem from one weak result near the bottom of page one.

    Most importantly, do not use page two as your universal finish line. An Ahrefs analysis of 4 million Google AI Overview citations found that only 37.9% of cited URLs ranked in the top ten for the associated search, while another 31.2% ranked between positions 11 and 100. AI systems can fan out into related searches and retrieve pages that the user never encounters in the first set of traditional results.

    That does not prove that every result on pages two through ten will enter an AI answer. It does invalidate the assumption that moving a negative from position ten to position eleven has solved the entire problem. Continue tracking the URL itself. If it remains an AI citation, pursue source-level correction or removal where justified, move it farther from prominent search positions, and give the system stronger, more relevant material for the exact question that triggers it.

    Build a source network AI systems can corroborate

    Multiple source objects connect through glowing paths to a central translucent AI core, with one dim fragment isolated at the edge.

    Owned content and third-party coverage do different jobs. Your site supplies canonical facts. Independent pages provide corroboration, context, and comparative credibility. You need both, especially when the prompt is close to a purchase.

    In the proprietary AI-answer dataset, 82% of citations on bottom-of-funnel commercial prompts went to third parties, while owned pages represented just 3%. Informational and navigational queries reached as much as 13% owned coverage. The implication is not that your site is unimportant. It is that a pricing, comparison, review, or best-for-use-case answer is likely to be assembled from voices beyond the seller.

    Owned citations were scarce but valuable. When an owned page appeared, it was associated with a fivefold increase in AI visibility and persisted three to nine times longer than third-party citations. As many as 58% of third-party citations in the same dataset did not reappear after their first observation. Those are associations within one vendor’s tracked population, but they support a sensible allocation: keep improving owned pages while deliberately earning independent coverage for commercial questions.

    Build the network in layers:

    • Canonical owned pages: Maintain a clear About page, leadership biographies, product or service descriptions, pricing scope, policies, locations, contact information, and direct explanations of disputed facts. Give important claims a stable URL instead of scattering them across temporary announcements.
    • Substantive explanations: Ordinary pages generated 64% of citations in the tracked AI answers. Improve the pages that already serve customers before commissioning a fleet of thin listicles. State who the offering is for, what it does, its limits, the evidence behind the claim, and how the page is maintained.
    • Independent validation: Pursue accurate interviews, contributed expertise, category coverage, reputable business profiles, and legitimate reviews where your buyers already research decisions. Do not manufacture testimonials, impersonate customers, or seed covert promotional comments.
    • Commercial-intent coverage: Give reviewers and journalists verifiable material for pricing, comparisons, alternatives, and use cases. A media campaign focused only on broad awareness can leave the most consequential buying prompts unanswered.
    • Video with retrievable language: YouTube produced the largest observed third-party citation lift in the tracked dataset at 2.8 times the baseline. Publish videos that answer a specific question, speak names and terms clearly, and include accurate captions or transcripts. A transcript gives retrieval systems a text representation of the explanation.
    • Consistent entity signals: Align the organization name, executive names, addresses, profiles, and descriptions across authoritative properties. Use applicable Person, Organization, or Product structured data to describe facts already visible on the page. Schema can clarify entities and relationships; it cannot turn an unsupported claim into independent evidence.

    Map every consequential claim to a source. For example, a pricing claim should lead to a maintained pricing page; a leadership claim should lead to a current biography; a safety or compliance claim should lead to specific, verifiable documentation. Then identify which claims require independent corroboration because a buyer would reasonably distrust a seller’s unsupported assertion.

    A second owned website is rarely a shortcut. In the suppression dataset, only about a third of second sites had reached page one when reviewed, and most remained on pages two through four. Strengthen the primary domain and its most relevant pages before dividing authority between satellite properties created mainly to occupy another result.

    Run a three-month control cycle, not a publishing sprint

    A three-month cycle is long enough to observe movement and short enough to correct weak tactics. It is not a promise that a difficult negative will disappear in that period. Use month four and beyond when the starting position, source authority, or number of negatives demands it.

    Month one: establish the baseline and repair controllable facts.

    • Capture the current first page and the cited URLs for your tracked AI prompts.
    • Separate factual errors from unfavorable but accurate opinions or reporting.
    • Submit justified correction or removal requests and log every response.
    • Repair owned pages, profiles, biographies, policies, and entity inconsistencies.
    • Select the existing pages that most directly answer the prompts producing harmful or incomplete answers.

    Month two: earn placements and close source gaps.

    • Upgrade the selected owned pages with complete answers, concrete evidence, limitations, dates, and clear ownership.
    • Pursue credible interviews, contributed expertise, category coverage, and business profiles relevant to the affected queries.
    • Publish a focused video when spoken explanation or demonstration adds information that a text page cannot convey as clearly.
    • Track which new assets enter the top ten. Do not respond to weak placement by increasing content volume indiscriminately.

    Month three: compare the same queries and make a decision.

    • If a negative fell in search but remains an AI citation, inspect the precise prompt and cited passage. Strengthen the pages that answer that question rather than celebrating the rank change.
    • If positive pages were published but none earned visibility, reassess their relevance, authority, distribution, and duplication before creating more.
    • If mentions increased while sentiment deteriorated, treat the result as a visibility gain and a reputation warning. Do not average the two into a reassuring score.
    • If an owned page becomes a recurring citation, maintain its URL, accuracy, internal links, and structured data. Avoid unnecessary migrations or rewrites that remove the passage being retrieved.
    • If a harmful claim is materially false, consequential, and resistant to ordinary correction, escalate to the appropriate communications, platform, or legal specialist based on the actual issue.

    Your monthly dashboard should contain the rank of the highest harmful result, the number of accurate assets in the top ten, the share of tracked prompts that mention the brand, the share that cite an owned page, the URLs cited by each platform, the recurrence of each citation, and the frequency of harmful or unsupported claims. Keep the underlying observations visible. A composite score can conceal the exact URL or statement that needs action.

    Start with the branded query that carries the greatest business risk. Save the search results and AI answers, list every cited URL, and label each item remove, correct, suppress, or strengthen. Assign the next action to a named owner, then rerun the same audit monthly. That first controlled loop is more valuable than another batch of generic reputation content.

    References


  • How to Segment Multi-Location SEO Data for Real Insight

    How to Segment Multi-Location SEO Data for Real Insight

    Your network’s organic traffic is up, yet several location managers say calls or bookings are down. Both can be true. A few high-volume markets can lift the total, while new locations can add traffic and conversions simply because they were absent from the earlier comparison period.

    You need reporting that separates portfolio expansion from SEO improvement, shows whether a problem is local or widespread, and points to the next action. That requires a stable location data model, like-for-like cohorts, and several connected views rather than one network-wide dashboard.

    Start with the decision, not the dashboard

    Segmentation becomes useful when each view answers a specific question. If you begin by collecting every available metric, you will usually end up with a crowded report that describes movement without explaining it.

    Write down the decisions the report must support before building filters or charts. For a multi-location SEO program, the practical questions usually include:

    • Are established locations growing, or is total growth coming from newly opened locations?
    • Is a decline limited to one location, shared across a metro, or visible throughout the network?
    • Is the change specific to Organic Search, or are all website channels moving in the same direction?
    • Are people finding the business through its name, or discovering it through services, products, cities, neighborhoods, and local-intent searches?
    • Is search visibility weakening, or are users still finding the location but taking fewer actions afterward?
    • Which locations deserve intervention, and which high performers contain a practice worth applying elsewhere?

    Each question needs a different denominator. A regional executive may need the total contribution from every location. An SEO manager diagnosing page quality needs location-page traffic and conversions. An analyst judging ongoing performance needs only locations that existed in both comparison periods.

    Keep three kinds of network measure visible: the portfolio total, the typical location, and the distribution across locations. The total shows business impact. A median or peer-group benchmark shows whether the typical branch is improving. The distribution reveals whether the result is broad or concentrated in a few outliers. None can safely replace the others.

    Build a location spine before joining SEO metrics

    An isometric central spine connects storefront and map-pin modules while colored data streams join the matching locations.

    Your reports need one durable record for every physical location. Think of this as the location spine: a controlled table that connects analytics, landing pages, search performance, local rankings, Google Business Profile data, reviews, and business events.

    Do not use a display name as the primary key. Names change, abbreviations vary, and two branches can share similar labels. Assign an immutable internal location key, then map every platform identifier and URL to it.

    FieldWhat it controlsWhy it matters
    Location keyThe permanent join key across systemsPrevents renames or URL changes from splitting one location into several records
    Operating statusOpen, temporarily unavailable, closed, relocated, or otherwise excludedKeeps inactive locations from being mistaken for SEO declines
    Lifecycle datesOpening, closing, relocation, and material expansion datesDetermines whether a location belongs in a like-for-like comparison
    Geographic hierarchyProvince or state, region, metro, city, and neighborhood where relevantSupports realistic market comparisons and isolates geographic patterns
    Location URL setCurrent page plus any mapped service or market pagesConnects page-level analytics and search visibility to the right branch
    Profile identifierThe associated Google Business Profile recordConnects Search and Maps visibility, actions, and review context
    Peer groupLocations with reasonably similar market conditions or operating modelsAvoids judging a small market against a major metro with different demand and competition
    Comparison cohortComparable, opening, closing, relocated, or exceptionSeparates organic improvement from changes in the location portfolio

    Decide how a relocation should be represented before the reporting period starts. If the business considers it the same branch but its page, profile, catchment area, or local competitors changed materially, preserve the permanent location key while flagging the affected periods as an exception. That retains operational history without pretending the local search environment remained constant.

    URL mapping needs the same discipline. A location may receive organic traffic through its main location page, a city page, or service pages associated with that market. Define which URLs belong to which reporting view. Do not silently attribute every site visit from a city to the nearest branch unless that allocation rule is explicit and defensible.

    If URL structure permits a simple landing-page filter, use it. If it requires regular expressions, test the expression against known included and excluded URLs before interpreting the results. Then compare the filtered inventory with the location spine. A broken filter can create a persuasive but false outlier, especially after a migration or naming change.

    Read every location through four evidence layers

    A storefront is surrounded by four translucent layers of discovery, engagement, conversion, and neighborhood-context symbols.

    No single metric explains local SEO performance. Treat analytics, search visibility, local rankings, and profile activity as connected evidence layers. When they disagree, the disagreement is diagnostic information rather than a reason to choose the most flattering metric.

    Evidence layerUseful measuresQuestion it answersCommon misreading
    Website analyticsOrganic traffic, engagement, conversion events, and corresponding all-channel measuresWhat did visitors do after reaching the site?Treating a tracking or sitewide conversion change as an organic-search problem
    Search visibilityClicks, impressions, click-through rate, average position, landing pages, and queriesHow often did the location appear, and what searches produced exposure or visits?Reading a network average without separating locations or query intent
    Local rank trackingCity-, service-, ZIP-code-, and near-me visibility, including grid or radius viewsWhere can a searcher actually see the location for priority local intent?Using one point ranking as though every searcher in the market sees the same result
    Google Business Profile and reviewsSearch and Maps views, website clicks, calls, directions, review volume, recency, and ratingWhat happened directly in local results, and what may affect user response?Assuming every profile action carries the same business value

    Website behavior: compare organic with the whole site

    Use GA4, Adobe, or the analytics platform already trusted by the business to review location-page traffic, engagement, and conversion events. Define a conversion in operational terms. Depending on the business, that may be an appointment request, booking, submitted form, phone call, or another recorded action.

    Always place the Organic Search view beside the equivalent all-channel view. If conversion activity falls across every channel, investigate tracking, page behavior, availability, or a broader business change before blaming rankings. If the decline appears only in organic traffic, continue into search visibility and query data.

    Do not average location conversion rates to create a network rate. Add the relevant conversion counts, add the corresponding traffic totals, and calculate the rate from those combined values. A simple average gives a small branch the same influence as a high-volume location and can distort the network result.

    Search visibility: split discovery from existing demand

    Use Google Search Console and Bing Webmaster Tools to examine clicks, impressions, click-through rate, average position, pages, and queries by location. Compare month over month for recent movement and year over year where the business needs a seasonal comparison.

    Classify queries with documented rules. At minimum, separate branded searches from non-branded discovery. The branded group should include the approved business and brand terms relevant to the network. The non-branded group can then be divided into service or product intent, explicit city or neighborhood terms, and near-me intent where the available query data supports that classification.

    This distinction changes the diagnosis. Rising branded clicks can reflect stronger existing awareness without proving that a location has become easier to discover for its services. Improving non-branded visibility is a clearer sign that the location is reaching people who have not already decided which business to find.

    Keep query taxonomy rules stable between periods. If you add brand terms or change classification logic, mark that change in the report. Otherwise, a reporting edit can look like a shift in customer behavior.

    Where a webmaster platform exposes AI-search performance, keep it as a clearly labeled view with its own available measures. Do not blend unlike visibility or traffic fields into a conventional web-search total. The label should tell the reader what the platform actually measured.

    Local rankings: measure the searcher’s geography

    Track priority local-intent searches at the city or ZIP-code level. In competitive markets, use grid or radius reporting to see how visibility changes as the searcher’s position changes. A branch may be prominent near its address and nearly absent elsewhere in the same metro; one rank captured from one point cannot represent that pattern.

    When visibility moves, inspect more than the recorded rank. Check whether the results page layout changed, whether a new search feature appeared, and whether new competitors entered the result set. A lower click-through rate with stable rankings may begin to make sense once you see that the page surrounding the listing has changed.

    Profile actions and reviews: interpret them by business model

    Google Business Profile activity covers visibility and actions that can occur before a user reaches the website. Review Search and Maps views alongside website clicks, calls, and direction requests. Calls may be more meaningful for a service business, while directions may better reflect intent for an in-person location. Choose the primary action based on how that business actually converts demand.

    Place review volume, recency, and average rating beside profile performance. These measures do not prove why a user acted, but they can explain why locations with similar visibility receive different engagement. Treat them as context to investigate, not as automatic causation.

    Separate portfolio growth from comparable-location growth

    A clean year-over-year report needs more than a date comparison. It needs a population definition. If the network opened, closed, relocated, or expanded locations, the locations contributing to the current period may not match those in the prior period.

    Publish separate views instead of forcing every branch into one percentage:

    • All-network view: every valid location in each period. Use this to show the total portfolio outcome.
    • Comparable-location view: only locations with a stable identity and valid data in both periods. Use this to judge underlying performance.
    • Opening cohort: locations that began operating after the earlier period. Use this to show incremental contribution without calling it like-for-like growth.
    • Closing cohort: locations that ceased operating or left the portfolio. Use this to explain lost contribution.
    • Exception cohort: relocations, material expansions, URL migrations, tracking interruptions, or other changes that make a direct comparison misleading.

    The all-network view answers, “How much organic activity did the business receive?” The comparable view answers, “Did the established footprint improve?” Those are both legitimate questions, but they are not interchangeable.

    Calculate comparable change from the same location keys in both periods. For an additive measure such as clicks or conversions, sum the current values for the matched cohort and compare them with the prior values for that exact cohort. For a rate such as click-through rate, combine the cohort’s numerators and denominators first, then calculate the rate. Do not average the individual location percentages.

    Also show each location’s contribution to the network change. A portfolio gain can be concentrated in a few branches even when most locations are flat or declining. Conversely, one closure or market-specific loss can pull down an otherwise healthy comparable cohort. Geographic and lifecycle segmentation exposes those drivers before they become a misleading network narrative.

    Apply cohort rules consistently across traffic, visibility, profile actions, and conversions. If the analytics table excludes openings but the profile table includes them, the dashboard will invite comparisons between different populations. Put the cohort definition and any exceptions directly in the report so a stakeholder can see what the result represents.

    Turn outliers into a prioritized SEO work queue

    A location is not an outlier merely because it trails the network average. Market demand, competition, maturity, and the number of nearby branches all affect the opportunity. Compare locations within relevant geographic and operating peer groups first: region, metro, city, or another grouping that reflects the business.

    This matters most when a network spans very different markets. A small city should not inherit the traffic target of a major metro. A dense metro with several branches may also have an internal differentiation problem: location pages can compete for the same broad city terms when neighborhood language would better distinguish their service areas.

    Use the pattern across evidence layers to choose the first investigation:

    Observed patternWhat to inspect nextPotential action
    Impressions and local rankings fall in one marketPriority queries, Map Pack visibility, new competitors, demand, page coverage, and profile accuracyCorrect listing data, strengthen the relevant location page, or build justified market-level coverage
    Impressions hold while clicks and click-through rate fallActual result pages, layout changes, new features, competing listings, and how the page or profile is presentedImprove the search-facing information that is within your control and monitor the changed result environment
    Organic traffic holds while conversions declineEngagement, conversion tracking, landing-page behavior, and all-channel conversion trendsRepair measurement or address the page-level conversion issue before treating it as a visibility problem
    Profile views hold while calls, clicks, or directions declineProfile completeness, business information, reviews, and whether the selected action still reflects customer behaviorUpdate the profile, address review weaknesses, or revise the primary action used for evaluation
    Several branches in one metro weaken while the wider region is stableShared competitors, overlapping pages, local rankings, neighborhood differentiation, and market conditionsUse a metro-level plan rather than repeating isolated page edits at every branch
    Every channel declines for the same locationTracking, operating status, availability, page function, and broader market or business changesResolve the cross-channel cause before assigning an organic SEO fix
    One peer location substantially outperforms comparable branchesQuery mix, page completeness, profile quality, review context, competition, and local involvementIdentify a transferable practice, then validate it in another appropriate peer market

    These patterns are starting points, not verdicts. Stable impressions with falling clicks, for example, can indicate a result-page change, weaker presentation, or a different query mix. Open the location, page, and query views before selecting the remedy.

    Every item in the work queue should contain the affected location or cohort, the observed evidence, the working explanation, the next check or change, an owner, and a review point. Keep observation and hypothesis in separate fields. “Non-branded impressions declined” is an observation. “A new competitor displaced the location” remains a hypothesis until the result and competitor data support it.

    Prioritize with three considerations: potential business impact, confidence in the diagnosis, and whether the team can act on it. A high-volume location with a clear profile error may deserve attention before a larger but poorly understood fluctuation. A strong outlier can be just as valuable as a weak one if it reveals a repeatable page, profile, or market practice.

    Key takeaways

    • Use a permanent location key to connect pages, analytics, search visibility, rankings, profiles, reviews, and lifecycle events.
    • Report the all-network portfolio and the comparable-location cohort separately; they answer different business questions.
    • Compare Organic Search with all-channel performance before assigning an organic cause to a conversion decline.
    • Split branded demand from non-branded discovery, and keep the classification rules consistent between periods.
    • Benchmark locations against relevant peers, then use cross-layer patterns to decide what to inspect and change.

    Start by creating the location spine and three saved views: all-network, comparable locations, and lifecycle exceptions. Then select one underperforming market and trace it from query visibility through page behavior and profile actions. Your reporting has done its job when that trail produces a specific, owned action rather than another network average.

    References


  • AI Search Visibility and Attribution: A Practical Framework

    AI Search Visibility and Attribution: A Practical Framework

    You have screenshots showing that AI systems mention your brand, a small line of AI referrals in GA4, and no defensible answer when someone asks whether either one affected pipeline. The problem isn’t necessarily weak performance. It’s that AI exposure, website behavior, and revenue happen in different systems, often without a trackable click connecting them.

    You need a measurement chain, not one magic metric: what an AI says, which information appears to influence the answer, what the buyer does next, and which outcomes reach your CRM. Once those stages are separated, you can report what you observed without inflating what you proved.

    Key takeaways

    • AI visibility and AI attribution answer different questions. Measure them separately before connecting them.
    • Referral traffic from AI assistants is an observable minimum, not a complete count of AI-influenced visits or buyers.
    • Start with one customer segment and a fixed panel of about 20 prompts across awareness, consideration, and action.
    • Organize attribution into three layers: directly recorded outcomes, influenced outcomes, and the future visibility moat you are building.
    • Report changes as observed, attributed, associated, or still unknown. That vocabulary prevents correlation from turning into an unsupported revenue claim.

    Why conventional attribution misses the AI search journey

    Traditional search reporting assumes a recognizable sequence: a person searches, clicks a result, lands on a tagged page, and converts in the same measurable journey. AI search can break that sequence at every step.

    A person may get a complete answer without leaving the interface. They may see your brand recommended, remember its name, and search for it later. They may copy your domain rather than use the citation link. Mobile and desktop applications can also remove referral information, while switching devices can sever the connection entirely. As a result, AI-generated visits recorded in analytics represent an observable floor, not the full population of people exposed to your brand.

    This creates two measurement problems that must not be collapsed:

    • Visibility: Does the AI include your brand, describe it correctly, and cite information that supports the answer?
    • Attribution: Is there credible evidence that this exposure contributed to a visit, lead, opportunity, sale, or another business outcome?

    A visibility score cannot prove revenue. A referral report cannot reveal all visibility. Treating either one as a complete measure produces false precision.

    Direct traffic doesn’t solve the problem. In analytics, “direct” is a bucket for visits without usable referral information; it isn’t a synonym for people who typed your domain, and it certainly isn’t an AI channel. A rise in direct visits may be consistent with AI influence, but it needs supporting evidence before you describe it that way.

    The practical fix is to preserve several kinds of evidence with different confidence levels. A ChatGPT referral that becomes a closed-won opportunity is strong but incomplete evidence. A simultaneous rise in AI mentions, branded searches, and direct demo requests is useful contextual evidence, but it doesn’t establish that AI caused every increase. Your framework should make that distinction visible.

    Establish a repeatable AI visibility baseline first

    An analyst reviews a symmetrical wall of abstract AI response cards generated from repeated query tokens and marked with recurring source indicators.

    You can’t attribute a change until you know what changed. Begin with a controlled visibility baseline for one customer segment, not a broad list of every question anybody might ask.

    Build a fixed prompt panel around one buyer

    Choose a segment with a distinct problem, evaluation process, and purchase decision. “Mid-market security teams replacing a legacy platform” is measurable. “Anyone interested in cybersecurity” isn’t.

    Create approximately 20 prompts covering three stages of the journey:

    • Awareness: Questions about the problem, available approaches, common mistakes, and signs that help may be needed.
    • Consideration: Questions about leading providers, alternatives, pricing expectations, selection criteria, locations, and suitability for a specific type of customer.
    • Action: Questions about your brand, its specialization, reviews, fit, and comparisons with named competitors.

    Run every prompt in a fresh conversation. Use a private window or logged-out session where possible, because accumulated chat context and account personalization can change the answer. Test the same wording in AI Mode, Gemini, and ChatGPT, then add another platform only when your audience actually uses it. The goal is a stable panel, not the largest possible prompt inventory.

    For every run, record the date, platform, exact prompt, whether your brand appeared, which competitors appeared, which pages or domains were cited, and whether the description of your brand was materially correct. This fresh-session testing method and three-stage prompt structure gives you a reproducible diagnostic rather than a collection of favorable screenshots.

    Turn the prompt log into diagnostic metrics

    Calculate metrics that reveal different failure modes:

    • Mention rate: Prompts that mention your brand divided by eligible prompts tested. Break this out by journey stage; an overall average can hide strong awareness visibility and weak consideration visibility.
    • Competitive inclusion rate: Consideration prompts in which your brand appears alongside the companies buyers are likely to evaluate.
    • Owned citation rate: Eligible prompts whose answers cite one of your pages. If a platform doesn’t expose citations for a run, record “not available” rather than converting missing data into a zero.
    • Perception accuracy: Brand mentions with a materially accurate description divided by all brand mentions. Keep an error log for incorrect claims about your offering, audience, pricing, location, or integrations.
    • Citation-domain coverage: The domains repeatedly supporting answers in your category, marked by whether your brand is represented on them.

    Keep the denominator beside every percentage. “Mention rate increased to 40%” means little unless the reader knows whether that represents eight mentions among 20 fixed prompts or an opaque score assembled from a changing prompt set.

    A share-of-voice number is useful for detecting movement, but it functions as a temperature reading rather than a diagnosis. If visibility is weak, the remedy could be inaccurate brand information, absent third-party coverage, poor indexing, a mismatch between your offering and the prompt, or a competitor that has stronger evidence in the cited ecosystem. Publishing more pages before identifying the gap may simply create more content that AI systems continue to ignore.

    Map where the answers are being shaped

    Add an influence map beside the prompt panel. Put journey stages in the rows and four discovery behaviors in the columns: streaming, scrolling, searching, and shopping. In each cell, record two things: the channels or cited domains that influence the buyer at that moment, and whether your brand is present there.

    This map tells you whether you have an on-site content problem or a broader representation problem. If the same review site, directory, video channel, discussion community, or competitor comparison keeps shaping answers and you are absent from it, another blog post on your own domain may not close the gap. If AI repeatedly misstates a product fact that your site never explains clearly, the correction belongs in your canonical product or service information first.

    Connect visibility to outcomes with three attribution layers

    Three transparent layers show abstract AI responses above website activity and customer pipeline stages, connected by solid, dotted, and faint glowing threads.

    A three-layer model of direct attribution, influenced attribution, and future moat lets you preserve weak signals without pretending they all carry the same evidentiary weight.

    LayerEvidence to trackWhat it can supportWhat it cannot prove alone
    Direct attributionKnown AI referrals, self-reported discovery, CRM source details, opportunities, closed revenueA recorded AI interaction was part of the measurable journeyThe complete amount of AI-influenced demand
    Influenced attributionBranded search, direct-source visits and demos, sales-cycle length, conversion rate, competitive win rateBusiness behavior changed in a way consistent with increased AI exposureThat AI caused every observed change
    Future moatMention coverage, perception accuracy, citation presence, influence-map coverage, proprietary and task-completing assetsYour brand is becoming easier for search and AI systems to understand and recommendGuaranteed traffic, pipeline, or future revenue

    Layer 1: Capture directly attributable outcomes

    Start with the records you can defend individually. Create an AI search channel or source-detail field in your CRM for leads carrying a recognizable AI referrer. Preserve the original source data rather than overwriting it, because you may need to audit the classification later.

    Add “AI assistant or AI search” to the “How did you hear about us?” field on high-intent forms. Follow it with optional free text asking which tool the buyer used and what they were researching. If changing the form would hurt completion, have sales representatives ask the same question during qualification and save the response in a structured field.

    At minimum, retain these fields:

    • Detected referral source and landing page.
    • Self-reported discovery source and the buyer’s free-text explanation.
    • Lead, opportunity, and close dates.
    • Opportunity stage, value, and closed-won revenue.
    • Product, segment, geography, and campaign context.

    Revenue-linked records are your most defensible outcome evidence even when the count is small. Report them as recorded AI-attributed outcomes, while stating that lost referrals, no-click interactions, and cross-device journeys make the count incomplete.

    Layer 2: Test for influenced demand

    Next, examine behavior that could occur after an untracked AI interaction. The useful signals include branded organic search, direct-source visits and demo requests, lead-to-opportunity conversion, sales-cycle length, and win rate against competitors appearing in your prompt panel.

    The mechanism matters. A buyer can ask an assistant for a shortlist, remember your name, and search Google several days later. They can also resolve pricing, integration, or fit objections before reaching your sales team. In those cases, the visible outcome may be a branded query or a better-prepared buyer rather than an AI referral. Branded search lift, direct demand, sales-cycle changes, and competitive win rates are therefore relevant influenced-attribution measures.

    They are not automatically AI outcomes. Compare the same segment, product, geography, and time window. Annotate major brand campaigns, paid-media changes, launches, pricing changes, seasonality, public relations activity, and website migrations that could move the same metrics. Use the median sales-cycle duration as well as the average so a few unusually large or slow opportunities don’t dominate the result.

    Your claim should match the evidence: “Branded demand and direct demo submissions rose during the same period as consideration-stage visibility” is defensible. “AI generated the entire increase” isn’t, unless individual records establish that connection.

    Layer 3: Measure the future moat without monetizing it

    The third layer is a strategic scorecard, not delayed revenue attribution. It tracks whether your brand is becoming easier to retrieve, understand, verify, and distinguish.

    Monitor accurate category inclusion, coverage across high-value prompt clusters, representation in frequently cited domains, and correction of recurring perception errors. Track whether your site supplies assets that a generic answer cannot reproduce: proprietary data, useful tools, original workflows, product capabilities, and pages that help a visitor complete a task. Strong topical focus and a clear description of the business also make your entity easier to interpret.

    Keep the SEO foundation visible here. Google’s generative answers depend on information in Google’s index, so crawlability, indexing, internal linking, and clear canonical pages remain prerequisites. Where Search Console provides a generative AI view, use it to identify which existing pages are being surfaced. Treat that information as visibility evidence, not as a complete cross-platform attribution report.

    Build one dashboard that preserves confidence and context

    Your dashboard should show a chain of evidence rather than compress everything into a proprietary score. Keep four panels on one page.

    • Visibility panel: Mention rate, competitive inclusion, owned citation rate, perception accuracy, and results by journey stage.
    • Influence panel: Frequently cited domains, competitor co-mentions, missing cells in the streaming-scrolling-searching-shopping map, and recurring factual errors.
    • Behavior panel: Branded organic demand, direct-source visits, direct demo submissions, high-intent page visits, and conversion rates for the same segment.
    • Business panel: AI-referred and self-reported leads, opportunities, pipeline value, closed revenue, sales-cycle duration, and competitive win rate.

    Display the current value, baseline value, absolute change, denominator, reporting window, and data owner for every metric. Add an annotation lane for interventions and confounders. Without dates for page updates, technical changes, campaigns, and product announcements, a trend line cannot tell you what to investigate.

    Do not add visibility, visits, and revenue into a single composite “AI performance” score. They use different units, denominators, and levels of confidence. A composite can improve even while the business outcome deteriorates, and nobody can diagnose the reason without unpacking it.

    Use the pattern to choose the next action

    • Low mentions and irrelevant citations: Check whether your offering actually fits the prompt, then investigate the domains and competitors shaping the answer before producing more content.
    • Brand mentioned but described incorrectly: Strengthen the canonical pages that define the disputed facts, remove contradictory messaging, and address influential third-party profiles where possible.
    • Accurate mentions but weak consideration visibility: Examine comparison, pricing, use-case, audience-fit, and selection-criteria gaps. Buyers need evidence that helps them choose, not another broad category definition.
    • Visibility rises but behavior does not: Verify that the prompt panel represents commercially relevant demand. Visibility for informational questions outside your market may never become pipeline.
    • Behavior rises without movement in your visibility panel: Your prompt set may be incomplete, another campaign may be responsible, or AI may be influencing questions you aren’t testing. Investigate before assigning credit.
    • Direct AI revenue appears while reported traffic remains small: Preserve the revenue records and describe analytics traffic as incomplete. Do not scale the small tracked count into an invented total.

    Run a 30-day operating cycle

    1. Days 1-3: Select one customer segment, define the buying problem, and inventory the analytics and CRM fields you already have.
    2. Days 4-7: Run the fixed prompt panel in fresh sessions, record citations and competitors, and score perception accuracy.
    3. Week 2: Build the influence map and identify one commercially relevant gap. Choose a gap that can be changed and measured, such as a missing comparison, unclear product fact, absent use-case page, or influential profile that misrepresents the brand.
    4. Week 3: Make one coherent intervention. Record the affected prompts, pages, channels, launch date, and expected leading signal.
    5. Week 4: Rerun the fixed panel under the same protocol. Review early visibility movement, but keep behavioral and revenue windows open long enough for your normal buying cycle.

    One month is enough to install the measurement discipline and inspect leading signals. It may not be enough to judge pipeline or revenue, especially in a long B2B sales cycle. Match the evaluation window to the outcome: model visibility can move before branded demand, and branded demand can move before opportunities close.

    Report the evidence without turning correlation into causation

    A credible AI search report should separate four types of statements:

    • Observed: The brand appeared, a page was cited, a competitor was included, or a tracked metric changed.
    • Attributed: A preserved referral or self-reported response connects an AI interaction to a known lead, opportunity, or customer.
    • Associated: Visibility and a business indicator moved in a consistent sequence for the same segment, but the individual journeys cannot be connected.
    • Unknown: The journey may have involved AI, but available data cannot establish whether or how.

    Use a consistent reporting sentence: “Among [N] fixed prompts for [segment], brand mentions changed from [A] to [B] after [intervention]. During [business window], [branded demand or pipeline metric] changed from [C] to [D]. [Known confounders] were also present, so we classify the relationship as [observed, attributed, or associated]. The next test is [action].”

    This format answers the questions decision-makers actually have: What moved? How reliable is the connection? What else could explain it? What will you do next?

    Start with one segment and 20 prompts rather than an enterprise-wide score. Within 30 days, you can have a repeatable visibility baseline, CRM fields that retain direct evidence, an influence map that exposes the real gaps, and one controlled improvement under measurement. That won’t make the dark funnel fully visible. It will give you a framework strong enough to guide the next investment without pretending uncertainty has disappeared.

    References


  • AI-Era Search Journeys: A Practical Demand Strategy

    AI-Era Search Journeys: A Practical Demand Strategy

    Your dashboard may show fewer informational clicks while branded queries, direct visits, and highly specific searches keep producing business. That does not automatically mean demand disappeared. It may mean people discovered you elsewhere, learned inside an AI answer, and reached search only when they wanted confirmation.

    You need a strategy that follows that whole journey. The practical shift is to organize marketing around connected questions, decide whether each demand theme should be captured or created, and measure the signals that appear before the final click.

    Map the question chain, not just the first keyword

    Hands arrange a branching network of symbolic question nodes on a dark workspace.

    A keyword usually records one moment in a longer decision. It may be the first question, but it may also be a refinement, a comparison, or the last confirmation before someone acts. Treating every query as an independent acquisition event hides that difference.

    Conversational interfaces make the hidden sequence easier for the user to continue. Context can carry from one request to the next, intent can move from research to purchase inside the same exchange, and the input can shift among text, speech, images, maps, product data, and other formats. The defining capability is that the person can continue the task without reconstructing the context.

    This makes the follow-up question strategically valuable. The opening prompt tells you the subject. The next prompt often reveals the constraint that will determine the choice: budget, compatibility, timing, location, risk, delivery, implementation effort, or proof.

    Start with a demand theme rather than a head term. A demand theme is a real decision your customer is trying to make, such as choosing project management software for a 20-person agency. Then map the questions that can move that decision forward.

    Journey turnWhat the person needsExample questionContent or data required
    ExploreUnderstand the available approachesHow should a small agency manage client projects?Clear explanation, decision criteria, terminology, and options
    ConstrainApply requirements to the optionsWhat works for contractors and external clients?Feature details, access controls, workflow examples, and limitations
    CompareResolve tradeoffs and reduce uncertaintyWhich option is easier to implement without an operations team?Fair comparison, setup requirements, evidence, and total effort
    VerifyConfirm the claim for a specific situationDoes it integrate with our billing system?Current integration records, documentation, screenshots, and version details
    ActComplete the next stepCan we start a trial or book a demo?Availability, pricing or quote path, qualification details, and a focused call to action

    You do not need to predict every wording. You do need to cover the recurring decisions. Build the chain from customer-support questions, internal site search, reviews, sales-call notes, community discussions, search-query data, and prompt testing. Label every question by the decision it advances, not merely by search volume.

    Also account for query fan-out. Google AI Overviews and AI Mode may run multiple related searches across subtopics and data sets before composing an answer. A page can therefore contribute useful evidence without repeating the visible prompt word for word. Complete coverage of a subproblem matters more than mechanical phrase matching.

    Choose whether to fight, influence, or generate demand

    Once you have question chains, stop giving every query the same paid-search and SEO treatment. Assign each demand theme to one of three jobs: fight for an action, influence the answer, or generate the demand that search can later capture.

    The assignment depends on the current result surface, the person’s likely next move, your existing visibility, and the economics of winning a click. It is not a permanent classification. The same theme can change as the search results, competitors, or your brand position change.

    Strategic jobUse it whenPrimary workUseful outcome
    FightThe query expresses a purchase, supplier, quote, availability, or branded buying decision and a click can still create direct commercial valueSearch ads, commercial SEO, a precise landing page, current offer data, and conversion-path improvementQualified leads, transactions, revenue, and acceptable incremental acquisition cost
    InfluenceAn AI answer or other answer-first surface performs much of the education and the person may not visit a websiteCitable explanations, comparison criteria, proof, third-party corroboration, structured data, and coordination between SEO and paid teamsAccurate brand mentions, citations, shortlist inclusion, and stronger branded confirmation demand
    Generate demandInformational discovery has become difficult to capture with a click or the right audience does not yet know the brandVideo, creator and community participation, public relations, original expertise, distribution, and audience-building campaignsQualified awareness, direct visits, branded searches, returning demand, and assisted pipeline

    Fight where the click can finish a commercial job

    Protect budget for queries that still connect directly to revenue: product or service terms with buying modifiers, supplier searches, quote requests, distributor searches, availability questions, and brand-plus-product combinations. On these searches, your ad and landing page should answer the purchasing question immediately.

    Do not infer commercial value from position alone. Estimate the incremental cost of moving higher, then compare it with incremental qualified leads or sales. If SEO or an AI answer already gives you strong visibility, a second paid appearance is not automatically worth the premium. The point is profitable coverage, not visual dominance.

    Influence when the answer is the destination

    An informational search can still shape a purchase even when it sends no visit. Your job is to supply material that deserves to become part of the answer: a precise explanation, a defensible comparison, current facts, explicit limitations, and evidence that another party can verify.

    SEO and paid search need a shared brief here. If organic content is already cited or the brand is already named accurately, use paid spend to cover a genuine gap instead of buying redundant exposure. If the brand is absent because the available evidence is weak, raising the bid will not repair that evidence.

    Generate demand when capture starts too late

    Recommendation feeds, videos, communities, creators, and AI systems can shape preference before a conventional query appears. The funnel can therefore look more like passive exposure, preference development, confirmation search, and purchase. When the observable search finally happens, it may be confirming a choice that is already taking shape.

    Do not ask a search campaign to recreate discovery if the result page already resolves the informational need. Fund the earlier work. Search can then capture the later commercial query. This is the central relationship: demand generation fills the pool; high-intent search captures people when they are ready to act.

    A last-click search report will usually undervalue that earlier work because the visible conversion may be credited to a branded query. Treat the branded query as an outcome to investigate, not proof that search created the preference by itself. The fight, influence, and generate-demand framework gives each channel a clearer job.

    Build an evidence system that survives follow-up questions

    A conventional content brief often ends with a primary keyword, secondary terms, word count, and conversion target. An AI-era brief should describe the decisions the content must support and the evidence needed at each turn.

    • Entry question: State the immediate problem in the language customers use, then answer it near the top without delaying the answer for an extended introduction.
    • Likely constraints: Cover the conditions that change the recommendation, such as company size, use case, compatibility, budget, location, implementation capacity, or delivery timing.
    • Decision criteria: Explain how to evaluate the options. Criteria are more reusable than a verdict because they help a person refine the question.
    • Verifiable facts: Publish specifications, policies, dates, authorship, methods, supported integrations, availability, and limitations wherever they affect the decision.
    • Comparative proof: Show why one option fits a condition better than another. Avoid declaring a universal winner when the tradeoff depends on context.
    • Next useful action: Link to the next decision in the chain, not merely to a generic contact page. A compatibility question should lead to documentation or a checker; a buying question should lead to pricing, availability, a quote, or a demo.
    • Maintenance owner: Assign responsibility for facts that can change. Stale prices, policies, inventory, and integration claims undermine the whole path.

    Do not force one page to answer every possible prompt. Create a connected path: an entry page for the broad problem, focused pages for major constraints, a comparison or selection page, proof and policy pages, and a transactional destination. Internal links should describe the question each destination resolves.

    Make the machine-readable layer match the visible evidence. Use the appropriate structured data for the entity and page type, keep names and identifiers consistent, and mark up only facts a visitor can verify on the page. JSON-LD can clarify relationships among an organization, author, service, product, article, offer, or FAQ when those entities are genuinely present. It cannot turn an unsupported assertion into trusted evidence.

    For commerce, treat feed quality as part of content quality. Product names, variants, identifiers, prices, availability, delivery information, and landing-page details should agree. A polished buying guide cannot compensate for contradictory operational data when a user asks a specific follow-up about stock or arrival.

    Finally, design for the format the question requires. A visual fit question may need labeled images or video. An installation question may need a sequence. A feature comparison may need a table. A location decision may need current local details. Text remains essential, but text alone is not always enough to finish the task.

    Create corroboration before the confirmation search

    Independent evidence sources converge through verification rings around a bright central claim while an observer examines the result.

    Your website is the canonical place to explain your offer, but it is not the only place where machines or people form a view of the brand. Reviews, videos, community discussions, independent coverage, and creator demonstrations can establish or contradict the claims you make on your own domain.

    This is why reputation management, public relations, content distribution, and search visibility now overlap. Earned media accounted for 84% of AI citations in a Muck Rack review of 25 million responses across ChatGPT, Claude, and Gemini. That finding covers a particular review rather than every market, but it is a useful warning: owned copy is only one input into brand representation.

    YouTube is particularly useful when the buyer needs to see a product, process, interface, result, or tradeoff. A strong video library should answer the questions that arise during evaluation, not exist only as ad creative. Clear titles, spoken specifics, accurate descriptions, chapters, and transcripts make the material easier for both people and retrieval systems to interpret.

    Third-party presence cannot be manufactured safely through fake reviews, disguised promotion, or scripted community praise. Those tactics create reputational risk and weak evidence. Give reviewers and creators accurate materials, access to knowledgeable people, demonstrations, current specifications, and permission to discuss limitations. Their independent conclusion must remain independent.

    Community participation should work the same way. Answer the actual question, disclose your relationship to the brand, correct material errors with evidence, and leave when you have nothing useful to add. The goal is not to occupy every conversation. It is to ensure that credible, consistent information exists where real evaluation happens.

    Run a consistency check across your website, product feeds, documentation, business profiles, social accounts, press materials, and major third-party listings. Look for mismatched names, categories, features, policies, prices, availability, and positioning. An AI system that encounters five versions of the same fact has to resolve a conflict you could have prevented.

    Measure movement through the journey, not clicks in isolation

    No single metric captures an AI-era search journey. Use a measurement chain that distinguishes discovery, influence, confirmation, and action. This prevents an informational page from being judged like a quote page and stops a branded search campaign from receiving all the credit for demand developed elsewhere.

    • Discovery: Track qualified video reach, repeat exposure, engaged viewing, relevant earned mentions, community visibility, direct traffic, and growth in people searching for the brand or product by name.
    • Influence: Maintain a stable panel of representative prompt chains. Record whether the brand is mentioned, cited, described accurately, included in an appropriate shortlist, and carried into relevant follow-ups.
    • Confirmation: Segment branded searches, brand-plus-product searches, return visits, comparison-page activity, documentation use, and visits to proof or policy pages.
    • Action: Measure qualified trials, calls, demos, quote requests, purchases, pipeline, revenue, and the incremental cost of capturing high-intent demand.

    Define AI visibility metrics internally before reporting them. For example, share of answer can mean the percentage of prompts in your fixed panel that produce a relevant brand mention or citation. Keep the prompt wording, market, device conditions, and evaluation rules as stable as practical. A prompt panel is a directional monitor, not a census of everything every user sees.

    Connect the stages with evidence rather than forcing false precision. Add self-reported discovery questions to lead forms or sales workflows, preserve first-touch and returning-visitor data where consent allows, annotate major video, PR, content, and paid launches, and compare branded demand and qualified pipeline before and after those changes. Self-reporting and attribution models are incomplete, but several imperfect signals pointing in the same direction are more useful than a last-click number pretending to tell the entire story.

    Review commercial capture more frequently than long-term demand creation. Fight campaigns expose costs and conversions quickly enough for active budget decisions. Influence and demand-generation work needs trend analysis across visibility, branded confirmation, and pipeline because the effect often appears later and in another channel.

    Put the strategy into motion over the next 30 days

    Do not begin with a site-wide rewrite or a list of hundreds of prompts. Choose one commercially important customer decision and build one complete path. A focused implementation will expose missing data, weak proof, handoff problems, and measurement gaps faster than a broad planning exercise.

    1. Week 1: Map the journey. Select the decision, collect the real questions surrounding it, arrange them into explore, constrain, compare, verify, and act stages, and identify the most consequential follow-ups.
    2. Week 2: Classify the demand. Inspect the actual result surfaces and assign each question to fight, influence, or generate demand. Record where you are already visible, where another brand supplies the answer, and where discovery happens before search.
    3. Week 3: Repair the evidence path. Update the direct answer, constraint pages, comparison criteria, factual proof, internal links, structured data, product or service data, and conversion destination. Publish the smallest set that lets a person complete the decision.
    4. Week 4: Extend and instrument. Turn the most visual or trust-sensitive question into video, support credible third-party coverage, establish the prompt panel and journey metrics, and move paid budget toward high-intent gaps rather than answered informational queries.

    Key takeaways

    • The first query names the topic; follow-up questions reveal the decision criteria.
    • Fight for clicks when they can complete a commercial action, influence answer-first journeys with verifiable evidence, and generate demand when discovery happens before search.
    • Build connected content, data, and proof around the full question chain rather than producing isolated keyword pages.
    • Strengthen credible third-party corroboration because AI systems and buyers evaluate more than your owned website.
    • Measure discovery, influence, confirmation, and action separately, then examine how movement in one stage affects the next.

    Pick the decision that matters most to your pipeline this week. Write down the opening question, the three follow-ups most likely to change the choice, the evidence each answer requires, and the next action you want to make easier. That single chain is a practical starting point for search, content, paid media, video, PR, data, and measurement to work as one demand system.

    References


  • How to Audit Search Visibility Before Reputation Risk Spreads

    How to Audit Search Visibility Before Reputation Risk Spreads

    Your branded results can look healthy while a serious risk is forming just outside the familiar blue links. A critical Reddit thread may be climbing, autocomplete may be repeating an uncomfortable association, or an AI answer may describe your product positively but recommend a competitor. By the time that pattern reaches revenue reports, the underlying problem is usually harder to isolate.

    You need an audit that treats search visibility as an early-warning system. That means examining every surface that can shape a branded decision, tracing unfavorable narratives back to their operational causes, and knowing how to respond if Google visibility falls without making recovery more difficult.

    Key takeaways

    • Audit branded search results, search features, and AI recommendations as one reputation surface. A clean organic page does not mean the wider footprint is safe.
    • Record ownership, sentiment, authority, prominence, commercial relevance, and movement for every result. Negative content becomes urgent when several of those factors align.
    • Treat repeated AI criticism as an operational lead. Marketing can clarify facts, but it cannot repair product quality, refund handling, release stability, or employee experience.
    • Separate a manual action from an algorithmic visibility loss before changing the site. Premature reconsideration requests and indiscriminate content deletion can complicate recovery.
    • If Google Search produces 50% or more of sales, visibility loss is a business concentration risk, not merely an SEO problem.

    Audit the decision journey, not just your brand name

    Start with the questions a buyer asks immediately before choosing, rejecting, or contacting you. A search for the company name matters, but it rarely exposes the full risk. Build the query inventory around distinct decisions:

    • Navigational intent: brand, website, login, locations, or contact details.
    • Product intent: brand plus a product, service, feature, model, or plan.
    • Trust intent: brand plus reviews, reputation, reliability, or customer experience.
    • Risk intent: brand plus complaints, problems, returns, refunds, cancellation, or support.
    • Comparative intent: brand versus a named competitor, brand alternatives, or the best option for a defined use case.

    For each query, capture more than the organic positions. Record the date, market, device, signed-in state, exact wording, and visible search features. Save screenshots and URLs so that later reviews compare evidence rather than memory. AI responses require the exact prompt and relevant conversation context because the recommendation can change as the system learns more about the buyer.

    SurfaceWhat to captureWhat should trigger attention
    Organic page onePosition, title, publisher, ownership, sentiment, and target pageA trusted negative result moving upward, or most positive coverage depending on a small cluster of assets
    AI answers and AI OverviewsExact prompt, whether the brand is mentioned or recommended, descriptive language, stated reasons, cited evidence, and competitorsThe brand is omitted, discouraged, weakly described, or consistently outperformed on a commercially important attribute
    Autocomplete and People Also AskSuggested phrases, recurring questions, and the concerns implied by their wordingA complaint or objection becoming part of the standard path to the brand
    Images, news, and Top StoriesDominant visual framing, publishers, headlines, recency, and which assets repeatedly appearUnfavorable framing occupies a highly visible feature even when organic links remain positive
    Discover and TrendsVisible brand themes, changes in interest, and associated topics when these observations are availableA new issue is gaining attention before it becomes prominent in conventional branded results

    Classify every observation as positive, neutral, or negative and as owned or third-party. Then assess four practical factors: prominence, authority, commercial relevance, and movement. A low-authority complaint buried beyond page one may deserve monitoring. A trusted third-party result about refunds that appears prominently for a product-intent query deserves immediate investigation.

    Do not calculate an average sentiment score and call the audit complete. Averages hide concentrated risk. The real question is whether one influential result, feature, or narrative can interrupt a high-value decision.

    Positive coverage also needs scrutiny. Depending on a few favorable ranking assets leaves the brand exposed when Google changes the result mix or a stronger third-party page appears. Repeated versions of an owned announcement are not independent protection. Durable coverage comes from varied, authoritative properties that readers already trust. Wikipedia, Reuters, and the Associated Press illustrate the level of independence involved, but they are not placement targets you can manufacture. Coverage must be warranted, accurate, and editorially earned.

    Trace AI narratives back to the business operation

    Glowing threads connect repeated online warning signals to a delayed package on a stalled warehouse conveyor.

    An AI system may retrieve information about your brand, or it may make a judgment about whether the brand fits a buyer. The second task is more consequential. A buyer asking what a product does is seeking facts. A buyer asking whether to purchase it is inviting the system to weigh suitability, drawbacks, alternatives, and personal constraints.

    Test both types of prompt. Use a stable prompt set that covers identity, fit, differentiation, concerns, and recommendation:

    • What is this brand or product known for?
    • Who is it a good or poor fit for?
    • Why would someone choose it instead of the main alternatives?
    • What recurring concerns should a buyer know about?
    • Would you recommend it for a buyer with a defined need or constraint?

    Record whether the brand appears, whether it is recommended, the adjectives used, the reasons given, the evidence types invoked, and which competitor receives stronger language. These are zero-click visibility measures. They show whether you are present and how you are represented even when no visit reaches your website.

    Do not treat one conversation as a universal ranking. AI recommendations can change with the buyer’s context and within the same conversation. Run the same prompt in a fresh conversation, then run it with a clearly defined buyer situation. Preserve both outputs. The difference tells you which needs or constraints alter the recommendation; it does not establish a single permanent answer.

    The difficult part begins when the answer identifies a credible weakness. Buyer-advice responses can draw on customer complaints, release notes, earnings calls, vendor case studies, and employee reviews. Those inputs sit across the organization, so the SEO team cannot own every remedy.

    • Product quality, inconsistent specifications, or materials belong with product and operations.
    • Returns, refunds, cancellations, and support delays belong with customer experience and the teams that operate those policies.
    • Release defects or instability belong with product and engineering.
    • Weak proof of outcomes belongs with customer success, communications, and the teams responsible for substantiating claims.
    • Recurring employee concerns belong with people leadership and senior management.

    Assign an operational owner to each recurring theme, not merely a communications owner. The sequence matters:

    1. Verify the claim against support records, product documentation, policies, and other relevant internal evidence.
    2. Determine whether it is accurate, outdated, misleading, isolated, or part of a recurring pattern.
    3. Fix the underlying process, product, policy, or service failure where the criticism is valid.
    4. Correct owned information so that current facts are clear, consistent, and crawlable.
    5. Build legitimate independent evidence through satisfied customers, credible case studies, and earned editorial coverage.
    6. Retest the affected queries and prompts while continuing to watch the original complaint.

    Schema can clarify entities and facts, but it cannot erase a consistent negative public record. Publishing more promotional pages while the operational cause remains unchanged usually adds claims without adding credibility. Your durable reputation improvement begins when the public evidence changes because the business changed.

    Diagnose a Google visibility loss before attempting recovery

    A specialist uses a magnifying lens to isolate a fault within a layered model of a website and its search connections.

    A sudden ranking decline creates pressure to act quickly, but speed without diagnosis is dangerous. First determine whether you are dealing with a manual spam action or an algorithmic loss associated with weak, inconsistent, or noncompliant signals.

    A manual action is targeted and is normally confirmed in Google Search Console. It may apply to a subdomain or directory, but a limited scope should not be treated as harmless. Leaving even a partial action unresolved can accompany broader and more persistent visibility damage.

    Without a manual-action notice, correlation with a known update is a hypothesis, not a diagnosis. For sites affected around Google’s August 2026 spam update, content quality appeared to be a primary concern. That does not establish that Google penalizes content simply because AI helped produce it. The relevant issue is the quality of what Google can crawl and index, including whether the publishing system supplies enough human oversight to prevent standards from deteriorating.

    Preserve the state of the site before making broad changes. Your investigation file should include affected directories and page types, query and landing-page movement, Search Console messages, server logs, recent deployments, template changes, and recent publishing batches. This evidence helps distinguish a sitewide system failure from an isolated section or rollout.

    Then work through the diagnosis in order:

    1. Crawl the affected site and compare technical signals across healthy and declining sections.
    2. Analyze server logs. They can reveal crawler activity and heavily visited sections that ordinary SEO reports do not expose.
    3. Review the content production system, including templates, review gates, duplication, editorial controls, and the separation of paid and editorial material.
    4. Test whether the apparent problem reflects a larger business-model conflict with Google’s policies rather than a page-level defect.
    5. Use an independent reviewer where possible. The team that designed and operates the system has an unavoidable incentive to defend its previous decisions.
    6. Remediate the production process as well as the published output so the same failure cannot immediately recur.

    If Search Console identifies a manual action, read its stated issue and scope carefully, but do not limit the audit to the flagged example. The site needs full compliance with Google’s spam policies before a reconsideration request is likely to succeed. Applying before remediation is complete can lead to rejection and make the next attempt more difficult and costly.

    Avoid deleting content wholesale in the hope of sending a dramatic signal. Bulk deletion is difficult to reverse and may destroy pages that could have been corrected, consolidated, or retained. Inventory the affected material, preserve copies, document the reason for each action, and make removal decisions from evidence rather than panic.

    Recovery can still take months. Google must recrawl and reassess the changed site, and a reconsideration request has no guaranteed turnaround time. Meanwhile, competitors can occupy the positions you lost. That is why the remediation plan should include business continuity, not only an SEO forecast.

    Build visibility that can survive a ranking or reputation shock

    Search resilience starts with governance. SEO can detect a narrative, ranking change, or crawl pattern, but the responsible business team must have the authority to resolve its cause. Maintain a shared risk register with the query or prompt involved, visible evidence, affected product, operational owner, severity, remediation status, and the condition that will trigger another review.

    Use event-driven checks as well as a regular monitoring cadence. Revisit branded results and AI prompts after a product launch, significant release, return-policy change, service incident, major employee issue, earnings communication, or material movement in a third-party result. These events can change the public evidence before a conventional ranking report shows the consequence.

    Your reporting should also reflect zero-click outcomes. Track whether the brand is mentioned, how it is described, which attributes it wins, why a competitor is preferred, and whether negative sentiment is becoming more prominent. A positive description is not automatically a win if competitors receive clearer and more persuasive reasons for selection.

    Reduce dependence on individual ranking assets by developing a varied body of credible third-party coverage. At the same time, reduce dependence on Google itself. If Google Search produces 50% or more of sales, treat that concentration as a material business risk. Bing visibility, stronger direct demand, and a recognizable brand can reduce exposure. Larger publishers may also evaluate distinct, genuinely independent brands rather than placing every commercial model under one search identity.

    Start with the product that contributes the most business value and the branded query most closely tied to its purchase decision. Capture the current organic page, search features, and AI narrative. Then assign every unresolved negative theme to the team capable of changing the underlying reality. The immediate goal is not perfect sentiment. It is eliminating unknown risks before rankings, recommendations, or revenue force the issue.

    References


  • How Google Maps Local Ranking Actually Works: An Audit Guide

    How Google Maps Local Ranking Actually Works: An Audit Guide

    If your Google Business Profile is accurate but local rankings still jump between queries, neighborhoods or devices, the problem may not be the field you last edited. Google Maps does not simply score a listing against nearby competitors. It assembles evidence about a place, interprets the search, retrieves candidates, applies geographic and quality systems, reranks the results and decides what the interface can display.

    That architecture changes how you should investigate poor visibility. Instead of chasing a supposed master list of ranking factors, you can identify the layer where the failure is probably happening and make a change that addresses it.

    Key takeaways

    • Your Google Business Profile is an interface to a larger geographic entity. Editing the profile adds evidence; it does not necessarily replace every competing value Google already holds.
    • The exposed Oyster Rank vocabulary contains 72 named signals, including 25 marked as deprecated. It does not reveal the live weights used to order results.
    • Maps ranking is a pipeline. Entity importance, query relevance, candidate retrieval, geography, quality, personalization, reranking and rendering can each affect what you see.
    • Local search does not operate within one fixed radius. The geographic footprint can change with the query, local density and search context.
    • A useful audit holds the query, origin and surface constant. Otherwise, a ranking change may reflect a different retrieval problem rather than the work you performed.

    Your listing is not the complete business entity

    Google represents geographic objects internally as Features in a system called Geostore. For an establishment, a Feature can contain identity, geometry, provider information, websites, chain relationships, concepts, ranking information and a Knowledge Graph machine ID. The listing displayed in Maps is assembled from that underlying representation.

    This is more than a technical distinction. A business owner may enter one phone number while another provider supplies an older one. The website may imply one business name while a directory, map feed or legacy record uses another. Google then has to determine whether those records describe one place, several places or a place that has changed.

    The exposed provenance system identifies 793 data providers and mechanisms for trust, priority and conflation. Conflation is the process of reconciling records that appear to describe the same object. Depending on the field and available evidence, a value may be selected, merged or combined with other values.

    That helps explain a familiar pattern: you correct an attribute, it appears briefly, and then it changes back. Your edit entered the evidence pool, but other evidence may still support the old value. Repeating the same edit without locating the conflict treats the visible symptom rather than the underlying identity problem.

    Build a small identity ledger before making more changes. Record the exact public name, primary URL, phone number, address or legitimate location description, map pin, primary business category and any old identities still visible online. Compare that ledger with your profile, homepage, contact page, location pages, structured data and important external citations. Look especially for moved locations, old telephone numbers, duplicate profiles and inconsistent business names.

    Use LocalBusiness or the most accurate applicable subtype in your JSON-LD to describe the same identity your pages present to people. Keep the name, URL, telephone, address and stable @id consistent across your own graph. Structured data makes your site less ambiguous, but it is supporting evidence, not a command that forces Maps to accept a value or improve a position.

    If a correct field keeps reverting, stop treating it as a ranking problem. Document the conflicting versions, correct the records you legitimately control and investigate whether Google is merging your business with an old location or duplicate entity. Until identity is stable, content and review work may be evaluated against an entity that Google does not understand the way you expect.

    Maps ranking is a pipeline, not a 72-factor checklist

    Transparent modular pipeline filters and reorders location markers as they travel from a neighborhood search to a compact map results interface.

    Oyster Rank appears to characterize the importance of a Feature inside Geostore. Its visible vocabulary includes Google reviews, web query volume, listing impressions, listing opens, direction requests, website clicks, chain membership, Wikipedia signals, popularity, prominence, landmark information and road usage.

    The existence of a signal name establishes that the system can represent that observation. It does not establish its current weight, whether it applies to every search or whether causing more of the observed event will improve rank. The recovered schema shows raw observations being extracted, normalized and mixed, but the coefficients needed to calculate their contribution were not exposed.

    Even a complete Oyster Rank score would not by itself predict the order of a local result set. Maps still has to understand the query, establish geographic context, find eligible candidates, assess semantic relevance, apply geographic and quality considerations, personalize where applicable, rerank the candidates and render the permitted result or label. A separate offline scorer with eight signals across 13 tiers was also identified on the device, distinct from Oyster Rank and server-side Places ranking.

    Architecture layerQuestion being resolvedLikely symptom when this layer fails
    Entity assemblyDo these records describe the same real place?Wrong or reverting fields, duplicates, merged identities or an incorrect map pin
    Query understandingWhat does the person mean, and what geographic context applies?Visibility differs sharply between apparently similar phrases
    Candidate generation and semantic matchingShould this business enter the eligible result set?The business is findable by name but absent for a relevant category or service query
    Geography, quality and rerankingWhich eligible candidates best fit this user and search?The business appears at some origins but falls behind in other competitive contexts
    RenderingWhat can the current map surface visibly show?A map label is absent even though the business can be found in search results

    These symptoms are diagnostic clues, not proofs. A business missing from one result can have more than one problem. The table is useful because it tells you what to inspect next. Wrong identity data points upstream toward entity reconciliation. Query-specific absence points toward intent, eligibility or semantic matching. Position changes across origins point toward geography and competitive reranking. Label-only disappearance may be a rendering issue rather than a loss of search eligibility.

    This is also why manufacturing clicks, direction requests or listing opens is not a defensible strategy. The vocabulary does not reveal the causal effect or weight of those events, and artificial activity contaminates your own measurements. Improve the listing and destination pages so qualified users can make decisions more easily; treat genuine interactions as outcomes to monitor, not buttons that mechanically raise rank.

    The geographic market changes with the query

    A fixed-radius model is appealing because it makes reporting easy: draw a circle around the searcher, collect the businesses inside it and rank them. Maps behaves more dynamically. Candidate geography can expand or contract according to what was searched and the environment in which that search occurs.

    At the same origin in Paris, a dense category query such as pharmacie produced a much smaller geographic footprint than a brand query such as Carrefour. Those measurements do not define a universal radius for either query. They demonstrate the more useful principle: the search area itself is query-dependent.

    This matters when you use a local rank grid. A grid is a sample of changing results, not a map of territory Google has permanently granted to the business. A position for the exact business name, a broad category and a specific service should not be averaged as if all three searches drew from the same candidate market.

    Separate your query families before interpreting coverage:

    • Branded queries test whether Google can identify and retrieve the intended entity.
    • Category queries test broader eligibility and relevance within a competitive local set.
    • Service or product queries test whether Google connects the entity with a more specific need.
    • Qualified queries, such as those containing a neighborhood or attribute, may create a different intent and geographic context again.

    For before-and-after comparisons, keep the wording and measurement origins unchanged. Compare branded performance with branded performance and service performance with the same service phrase. Report the share of sampled origins where the business appears, along with the positions at those origins, instead of reducing the entire market to one rank at one point.

    Content cannot move a physical business closer to a searcher. It can make the business’s relationship to a legitimate service, product or location clearer, which may help query interpretation and candidate matching. Write location and service pages to resolve real ambiguity: what the location offers, who it serves, where it operates and how the offering differs from similarly named services. Do not create unsupported location claims in an attempt to simulate proximity.

    Run a local ranking audit in architecture order

    A highlighted audit route circles a neighborhood map and passes through identity, query, candidate, geographic, quality, reranking, and interface inspection stations.

    The most efficient audit moves from upstream identity problems to downstream ranking and rendering problems. If you start by publishing more content while Google is conflating two entities, you add material without resolving the fault that controls everything below it.

    1. Define the exact failure. Record whether you are investigating an incorrect attribute, a duplicate, absence for a query, a low position among retrieved candidates or a missing map label. Those are different problems.
    2. Freeze a measurement baseline. Save the exact query text, origin coordinates, device or measurement method, result surface and date. Use the same configuration after making changes.
    3. Verify the canonical identity. Reconcile your profile, map pin, website, contact information, location pages, structured data and important external records. Give special attention to previous names, moved addresses, tracking phone numbers and duplicate profiles.
    4. Test retrieval by intent. At the same origin, check the exact brand, primary category and a small set of accurately described services. Branded retrieval with weak non-branded visibility points toward a different layer than total failure to find the entity.
    5. Inspect on-site semantic evidence. Make sure each relevant page identifies the offering, location and business relationship in visible copy as well as structured data. A schema property should agree with the page; it should not introduce claims the visitor cannot verify.
    6. Map geographic variation. Measure the same query across a stable set of origins. Keep branded, category, service and qualified queries in separate reports because each may generate a different candidate footprint.
    7. Improve real customer evidence. Ask eligible customers for honest reviews, keep decision-critical profile information accurate and make calls, directions and website actions easy for genuine users. Do not assign a ranking weight to any one interaction merely because its name exists in an internal vocabulary.
    8. Change one class of evidence at a time. Identity corrections, page revisions, structured-data changes and reputation work should be annotated separately. Retest the original query-origin matrix before deciding what to change next.

    Use the pattern of results to form your next hypothesis. If an attribute repeatedly reverts, investigate conflicting entity evidence. If the correct business appears for its exact name but not for a legitimate service at the same origin, inspect semantic relevance and candidate eligibility. If it appears close to the location but loses visibility where competitor density changes, investigate geography and relative prominence. If search retrieves it but the viewport does not display its label, separate rendering from rank before rewriting the listing.

    Do not call any one of those patterns conclusive. Personalization, changing competitors and different retrieval systems can produce similar symptoms. The purpose of controlled measurement is not to reverse-engineer a secret coefficient. It is to eliminate explanations until the next useful action becomes clear.

    Start with the identity ledger and a stable query-origin matrix. Correct one evidence class, repeat the same measurements and then decide whether the next move belongs in entity cleanup, content, reputation or conversion. That sequence gives you a defensible local strategy even when the live ranking weights remain unknown.

    References