If you are deciding whether to deploy an AI agent, do not start with the market leader. Start with the job you need completed, the systems the agent may touch, and the consequences when it stops halfway through.
The market is growing while its center of gravity weakens. Tracked AI agent usage rose from 142 million aggregate monthly active users in Q3 2025 to 293 million in Q3 2026, but the four largest platforms’ combined share fell from 58.6% to 49.3%. That is the environment you are buying into: rapid adoption, many credible specialists, and no safe assumption that one platform will own every workflow.
The market is expanding faster than any one leader
An AI agent is more than a chatbot with a new label. It accepts a goal, breaks that goal into subtasks, chooses actions as conditions change, and works across tools or systems until it reaches an end state. A single-turn assistant does not meet that definition. Neither does an orchestration framework such as LangGraph or Bedrock AgentCore, which helps developers build agents, nor a classification model that chooses a route without pursuing a goal of its own.
This distinction protects you from buying the wrong layer. A chat license may improve drafting without automating a process. A framework may give your engineering team control without supplying a ready-to-use worker. A fast decision model may make an agent cheaper and safer without replacing the agent itself.
The following snapshot covers selected leaders from a 40-platform market tracked between May 15 and September 10, 2026. The estimates combine company disclosures, app-store telemetry, procurement records, and account-level observations. They measure platform reach rather than unique people, so someone using several agents can appear in several platforms’ totals.
| Agent | Primary use | Estimated MAUs | Q3 2026 share | Quarter-over-quarter growth |
|---|---|---|---|---|
| ChatGPT Agent | Multi-step research, booking, and file work | 58.9M | 20.1% | +16% |
| Microsoft 365 Copilot | Document and Office workflow agents | 33.4M | 11.4% | +13% |
| GitHub Copilot Agent | Turning bug reports into code fixes | 26.7M | 9.1% | +11% |
| Gemini Agent Mode | Browser automation and form completion | 25.5M | 8.7% | +19% |
| Claude Code | Repository-wide refactoring and test generation | 19.3M | 6.6% | +24% |
| Cursor | Multi-file changes inside the editor | 13.5M | 4.6% | +8% |
| OpenAI Atlas | Site navigation and transactional tasks | 11.7M | 4.0% | +27% |
| Perplexity Comet | Agentic browsing, comparison, and checkout | 10.8M | 3.7% | +22% |
| Salesforce Agentforce | Support deflection and CRM pipeline hygiene | 9.1M | 3.1% | +15% |
| Grok Bot | Persistent work on a cloud computer | 7.9M | 2.7% | New |
| All other agents | Vertical, open-source, and smaller platforms | 45.1M | 15.4% | +14% |
Market-share loss does not necessarily mean user loss. ChatGPT Agent’s share declined from 24.9% in Q3 2025 to 20.1% in Q3 2026 while its estimated users increased from 35.4 million to 58.9 million. Microsoft 365 Copilot and GitHub Copilot Agent also added users while losing relative share. New entrants and expanding specialists diluted the incumbents because the total market grew faster than they did.
Use market share to assess reach, integration momentum, talent availability, and the likelihood that a product will remain supported. Do not use it as a proxy for successful task completion. The practical response to fragmentation is portability: retain task definitions, approval rules, logs, evaluation cases, and critical business data in systems you control wherever possible. Switching agents should not require rebuilding your operating knowledge from scratch.
Choose a workflow category before you choose a vendor
There is no single AI agent market in operational terms. Coding, browser automation, enterprise productivity, CRM work, personal assistance, and long-running general-purpose work have different tools, permissions, failure modes, and definitions of success.
Coding is currently the largest category, representing 24.8% of tracked agent usage. Even there, the products are not interchangeable. GitHub Copilot Agent is positioned around taking a bug report through to a finished fix. Claude Code emphasizes repository-wide changes and tests. Cursor centers work in the editor, Replit Agent spans prototype-to-deployment creation, and Amazon Q Developer focuses on cloud and coding operations.
The same specialization appears outside software development. Microsoft 365 Copilot sits inside Office workflows. Salesforce Agentforce works inside CRM processes. Gemini Agent Mode, OpenAI Atlas, and Perplexity Comet concentrate on browser actions, but their stated strengths range from form completion to transactional navigation and comparison-led checkout. A generic request for the “best agent” hides these material differences.
Write an outcome brief before requesting demonstrations
A useful evaluation begins with a workflow that has an observable finish. Document these elements before you shortlist products:
- Goal: State the result the agent must produce or the action it must complete.
- Starting state: Identify the request, file, ticket, record, or event that begins the run.
- Permitted systems: List the applications, data, credentials, and tools the agent may use.
- Definition of done: Describe the final artifact or system state precisely enough that a reviewer can mark it complete or incomplete.
- Approval gates: Specify where a person must approve publishing, payment, deletion, external communication, code deployment, or another consequential action.
- Stop conditions: Tell the agent what uncertainty, missing permission, policy conflict, or unexpected state requires escalation.
- Recovery requirement: Define what the agent must log, preserve, or reverse when it cannot finish.
For an SEO team, “help with a content audit” is too loose to evaluate. A testable workflow identifies the properties to crawl, the fields to collect, the rule for classifying each page, the destination for the findings, and whether the agent may change a live page. The clearer the end state, the easier it becomes to compare products without being distracted by fluent demonstrations.
Adopt at the workflow level rather than declaring an organization-wide agent strategy first. A company may reasonably use one agent for repository work, another for CRM operations, and another for browser research. Fragmentation becomes manageable when every deployment has a named job and a shared governance model.
Completion rate is the buying metric that corrects popularity
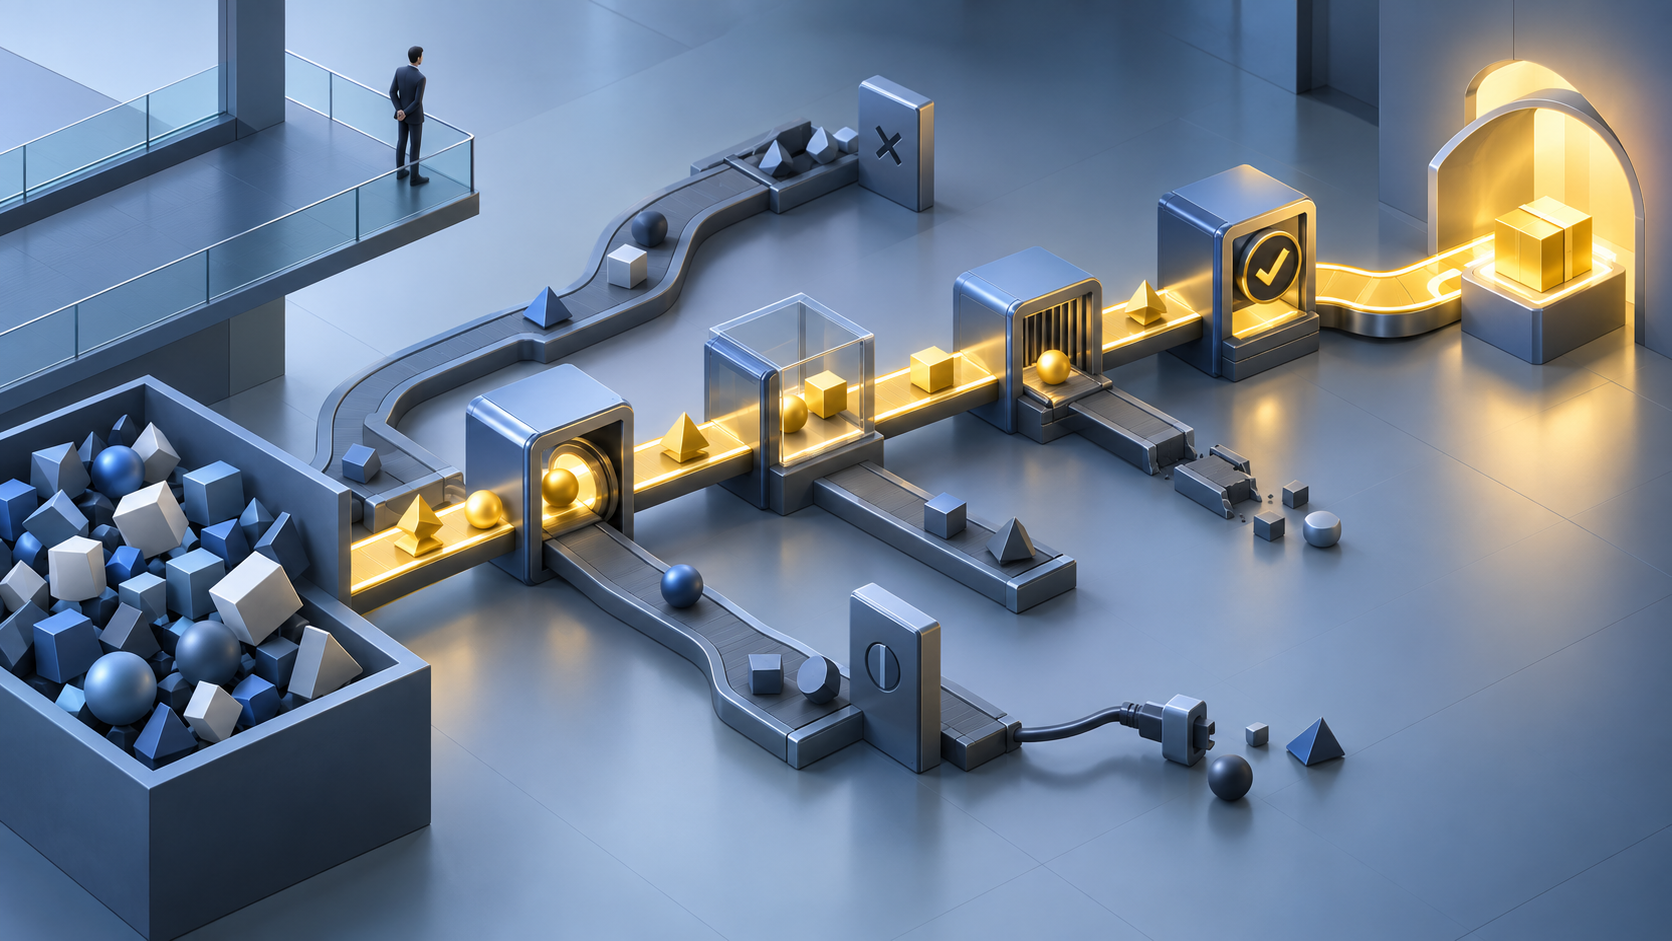
Monthly active users tell you that people invoked a platform. They do not tell you whether it finished the job. For an autonomous workflow, the more relevant question is simple: what percentage of eligible runs reaches the defined end state without a person correcting the agent?
One standardized comparison required each platform to attempt 48 multi-step tasks across five trials, producing 240 runs per platform. A run counted as complete only when it finished end to end without human correction. Claude Code led at 72.1% unassisted completion, followed by ChatGPT Agent at 65.3% and Grok Bot at 63.7%. Gemini Agent Mode reached 59.6%, GitHub Copilot Agent 57.2%, and Cursor 55.8%.
Those figures are useful for shortlisting, not for forecasting your deployment. The task mix may not resemble your workflow, and an agent’s performance changes with tool access, permissions, data quality, integration depth, and the exact definition of completion. Claude Code’s result is especially relevant to repository work; it does not establish that a coding agent is the best choice for CRM cleanup or browser checkout.
Speed also needs context. In that benchmark, OpenAI Atlas had a median completion time of 4 minutes 51 seconds and Perplexity Comet 4 minutes 39 seconds, while ChatGPT Agent took 8 minutes 52 seconds and Grok Bot 19 minutes 14 seconds. A fast incomplete run is not efficient. A slower run may still be preferable if it completes more often, requires fewer interventions, or handles a more complex job.
Measure the run, not the demo
Your pilot dashboard should separate these outcomes instead of compressing them into a vague satisfaction score:
- Unassisted completion rate: Eligible runs that reach the defined end state with no corrective intervention.
- Partial completion rate: Runs that create useful progress but fail to reach the required state.
- Intervention rate: Runs in which a person must clarify, repair, approve unexpectedly, or take over.
- Time to successful completion: Measure completed runs separately so quick failures do not make the agent appear faster.
- Cost per successful completion: Divide total run costs, including retries and supporting model calls, by completed outcomes rather than by invocations.
- Recovery quality: Check whether failed runs leave clear logs, preserve work, avoid duplicate actions, and return systems to a known state.
- Policy adherence: Record attempts to cross approval boundaries, use disallowed data, or invoke an unauthorized tool.
Keep every started run in the denominator. If your goal is autonomous completion, a person quietly fixing the result before it reaches the dashboard is a failed autonomous run, even when the final output looks good.
Separate the agent from the decision engines beneath it
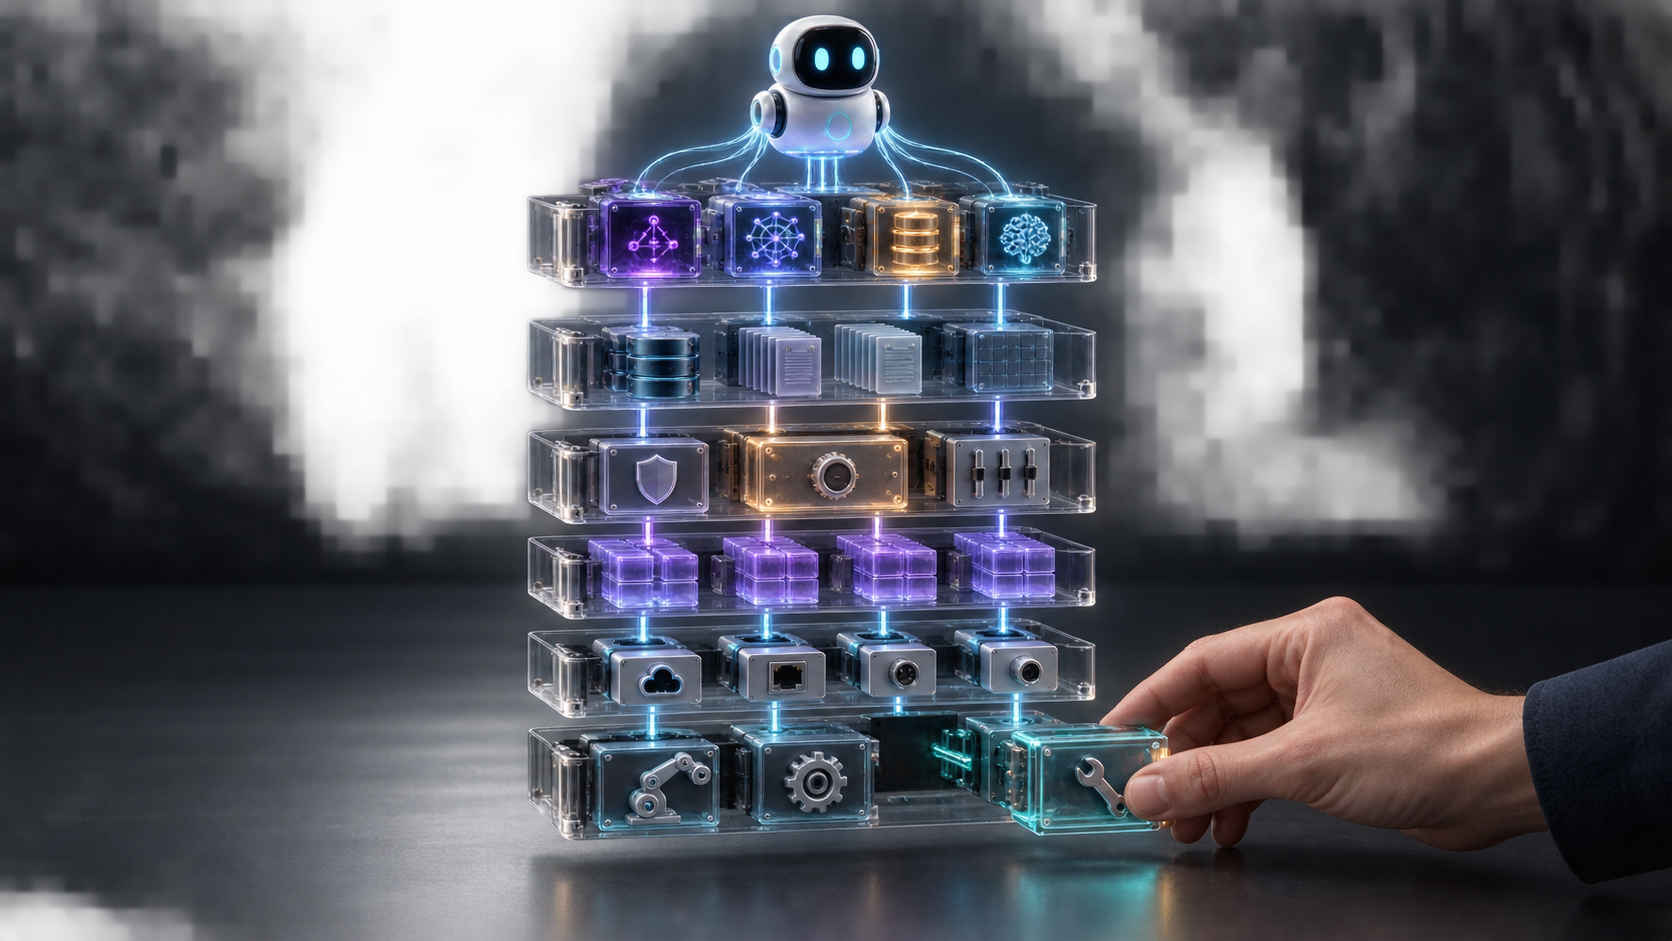
An agent does not need a large generative model for every step. Planning, writing, summarizing, classifying, routing, policy checking, and executing an API call are different computational jobs. Treating them as one undifferentiated prompt raises latency and cost while making failures harder to diagnose.
The term System One model is being used for a model that returns a typed, calibrated decision from a predefined answer set rather than free-form prose. It can choose a ticket category, route a request to a model, select a tool, or decide whether a proposed action meets a policy. It does not independently accept a goal and pursue it, so it belongs inside an agent architecture rather than in the agent column of a market-share table.
This layer matters because structured decisions are numerous but relatively inexpensive. Across 3.1 billion production API calls observed in 1,400 applications beginning June 1, 2026, structured decision tasks represented 63.7% of calls but only 15.5% of token spend. Long-form generation showed the opposite pattern: 9.1% of calls consumed 38.4% of token spend. A specialized decision model can therefore remove a large amount of traffic from a general-purpose model without displacing a comparable share of model spending.
The best candidates have an answer space you can enumerate before the call. Binary classification led a September 2026 survey of 421 AI engineering teams, with 60.5% already piloting or planning adoption within six months. Schema extraction ranked last at 28.7% because field values are often open-ended. That gap gives you a practical rule: use a decision model when you can list all legitimate outcomes; retain a generative model when the output itself must be created.
Type safety is necessary, but it is not factual accuracy
A model can return a perfectly valid category and still choose the wrong category. Constrained decoding on a small language model achieved a 0.0% type error rate in the same benchmark as Jev, so valid output syntax is not, by itself, a differentiator. You still need labeled evaluation cases that test whether the decision is correct.
The alternatives also remain competitive. A fine-tuned encoder classifier recorded 0.09-second median latency and a $0.018 cost per million input tokens, compared with Jev at 0.14 seconds and $0.042. The tradeoff is breadth: a new classification question can require another encoder to be trained, while a broader decision endpoint can answer different predefined questions. A small language model using constrained decoding was slower at 2.1 seconds, with input priced at $0.35 per million tokens and output at $1.40.
Early demand does not prove steady-state adoption. Jev was only seven days old when launch-week estimates put it at 31,416 developers making at least one API call, while 6.2% of new accounts reached production. Treat that as evidence of interest and low integration friction, not as evidence that the architecture has already become standard.
A clean production design assigns each layer a narrow responsibility:
- The agent owns the goal, task state, planning, and recovery path.
- Decision models handle enumerable classifications, routing, ranking, policy checks, and tool selection.
- Generative models create prose, summaries, code, and other open-ended outputs.
- Deterministic tools read or change external systems under explicit permissions.
- Human approval remains in front of irreversible, externally visible, or high-consequence actions.
Log the input, output, confidence or score, selected route, tool result, and final task outcome at the relevant layer. Otherwise, a failed workflow leaves you guessing whether the planner, classifier, generator, integration, or external system caused the problem.
Build an adoption plan that survives vendor churn
A durable rollout does not depend on predicting which logo will lead the next market table. It depends on preserving your workflow knowledge and measuring interchangeable components against the same definition of success.
- Select one bounded workflow. Favor a repeatable job with an observable end state and enough current friction to justify integration work.
- Map the action boundary. Separate read-only work, reversible internal changes, external communications, financial actions, deployments, and destructive operations. Require human approval where an error would be difficult to reverse.
- Shortlist by category fit. Compare agents designed for the systems and work involved instead of beginning with overall reach.
- Run identical evaluation cases. Include normal requests, missing information, ambiguous instructions, permission failures, tool errors, and requests that should trigger a refusal or escalation.
- Score completed outcomes. Track unassisted completion, interventions, time, cost, policy adherence, and recovery behavior using the same denominator for every candidate.
- Decompose expensive runs. Identify classification, routing, ranking, safety, and tool-selection calls that can move to a specialized decision model or deterministic rule.
- Retain a migration path. Keep prompts, outcome briefs, schemas, evaluation cases, logs, and business rules outside proprietary interfaces when the platform permits it.
If customers encounter your business through agents
Agent adoption changes acquisition as well as operations. ChatGPT Agent is used for multi-step research and booking; Gemini Agent Mode handles browser automation and forms; OpenAI Atlas performs site navigation and transactions; Perplexity Comet supports comparison and checkout. If any of those journeys matter to your business, visibility alone is an incomplete success metric. The agent must be able to identify the right page, understand the offer, verify important facts, and complete or correctly hand off the next step.
Apply the same outcome-based discipline to AI SEO, AEO, and GEO work:
- Put essential product, service, eligibility, policy, and contact information in visible page text rather than only in images or interactive widgets.
- Give each important entity, offer, and resource a stable canonical URL with a clear page purpose.
- Keep structured data consistent with the claims a visitor can see. Schema is a machine-readable consistency layer, not permission to publish contradictory or unsupported markup.
- Use specific labels for links, buttons, form fields, and required inputs so an agent does not have to infer what an interface element does.
- Publish dates, units, methodology, limitations, and originating evidence beside factual claims that an agent may need to evaluate or cite.
- Test complete journeys from discovery to the required outcome. Record where the agent selects the wrong page, loses context, cannot operate a control, encounters conflicting facts, or reaches an unexpected approval step.
This is where agent analytics should meet search analytics. A mention in an AI answer, an agent visit, a successful product comparison, and a completed transaction are separate events. Tracking only referral traffic hides the failures between discovery and completion.
Key takeaways
- AI agent usage is expanding rapidly, but market share is fragmenting rather than settling around one permanent winner.
- Choose an agent for a defined workflow category and observable end state, not for overall popularity.
- Use unassisted completion, intervention, recovery, time, and cost per successful outcome as the core buying metrics.
- Keep goal pursuit in the agent layer while routing enumerable decisions to specialized models or deterministic rules where appropriate.
- Make customer journeys explicit, structured, and testable if browser and general-purpose agents are part of your discovery or conversion path.
Your next move is deliberately small: choose one workflow whose finish you can describe in a sentence, preserve a human gate before consequential actions, and run the same cases through category-appropriate candidates. The market will keep changing. A clear outcome definition and a portable evaluation set let you benefit from that competition instead of being trapped by it.
References
- First Page Sage — Jev AI Adoption Statistics: September 2026
- First Page Sage — The Top AI Agents by Market Share — October 2026

Leave a Reply