Tag: Citations

  • How to Build Brand Trust Across AI Search Journeys

    How to Build Brand Trust Across AI Search Journeys

    You can rank well, appear in AI answers, and still lose the decision. A prospective customer asks an assistant for options, verifies the answer in Google, checks a community, watches a demonstration, and finally visits your website. If those stops present conflicting claims, more visibility creates more doubt.

    Your job is not to force every channel to repeat the same copy. It is to make every relevant surface support the same verifiable conclusion: who you help, what you do, where the offer fits, what its limits are, and why the customer should believe you. That requires a trust system spanning SEO, AEO, GEO, content, digital PR, community participation, reviews, and structured data.

    Key takeaways

    • Optimize the journey around unresolved uncertainty, not isolated channel ownership.
    • Match each confidence gap with the right evidence: reliable facts, peer experience, evidence of fit, or a clear path to action.
    • Maintain a claim ledger so your website, structured data, sales material, and third-party descriptions do not contradict one another.
    • Treat JSON-LD as a translation layer for supported facts, not a way to manufacture trust.
    • Prioritize independent, topically relevant corroboration over high-volume links or paid mentions with no editorial context.
    • Measure presence, answer accuracy, evidence coverage, proof-asset engagement, and customer-reported influence. Click attribution alone cannot show the whole journey.

    Map the confidence gap before choosing the channel

    AI search has expanded the journey rather than cleanly replacing traditional search. In one agency-led behavioral segmentation, 56% of people regularly used AI search while 57% still belonged to a Traditional Searcher segment. Those groups can overlap because the same person can use an AI assistant to understand a category, Google to verify a claim, Reddit to find candid experiences, YouTube to see a product in use, and a company website to decide whether the seller is credible.

    This makes a conventional funnel too blunt for trust planning. The customer is not thinking about moving from awareness to consideration. They are resolving one uncertainty after another until acting feels defensible. Your content plan should therefore begin with the question the customer still cannot answer, not the platform on which you hope to reach them.

    Confidence jobQuestion in the customer’s mindEvidence to prepareLikely discovery points
    Fact findingCan I rely on the basic claims?Clear specifications, definitions, methodology, original evidence, expert explanations, and current documentationAI answers, traditional search, your website, and cited reference pages
    CrowdsourcingWhat happened to people in a situation like mine?Authentic reviews, detailed case studies, customer commentary, and useful community discussionsReview platforms, Reddit and other communities, search results, and AI summaries
    Taste tuningDoes this approach fit my preferences, constraints, and working style?Demonstrations, examples, creator coverage, screenshots, use-case pages, and candid fit guidanceYouTube, creators, social platforms, comparison pages, and your website
    AutopilotCan I make the decision or complete the next step without unnecessary effort?Decision criteria, implementation steps, transparent requirements, comparison tools, and a clear conversion pathAI assistants, search, product workflows, sales material, and your website

    The same person may perform all four jobs during one purchase. An executive sponsor, a practitioner, and a procurement stakeholder may also have different gaps even when they are evaluating the same company. A single generic buyer-journey map will hide those differences.

    Run a confidence-gap exercise for one audience and one decision at a time:

    1. Write the decision in concrete terms, such as choosing a provider for a defined use case.
    2. Collect the questions that appear in search data, sales calls, support conversations, reviews, community threads, and comparison requests.
    3. Classify each question as fact finding, crowdsourcing, taste tuning, or autopilot. Some questions will serve more than one job.
    4. Write down what would constitute adequate proof. Do not settle for a content format such as a blog post; specify the evidence the customer needs.
    5. Identify where that customer would naturally seek the evidence and who must own its accuracy.
    6. Mark the gaps for which no credible asset exists. Those are your content priorities.

    This process often changes the brief. A broad educational article cannot repair a missing implementation explanation. Another landing page cannot replace independent customer evidence. A paid mention cannot settle a factual contradiction between your documentation and sales copy.

    Build a claim-and-proof system that survives summarization
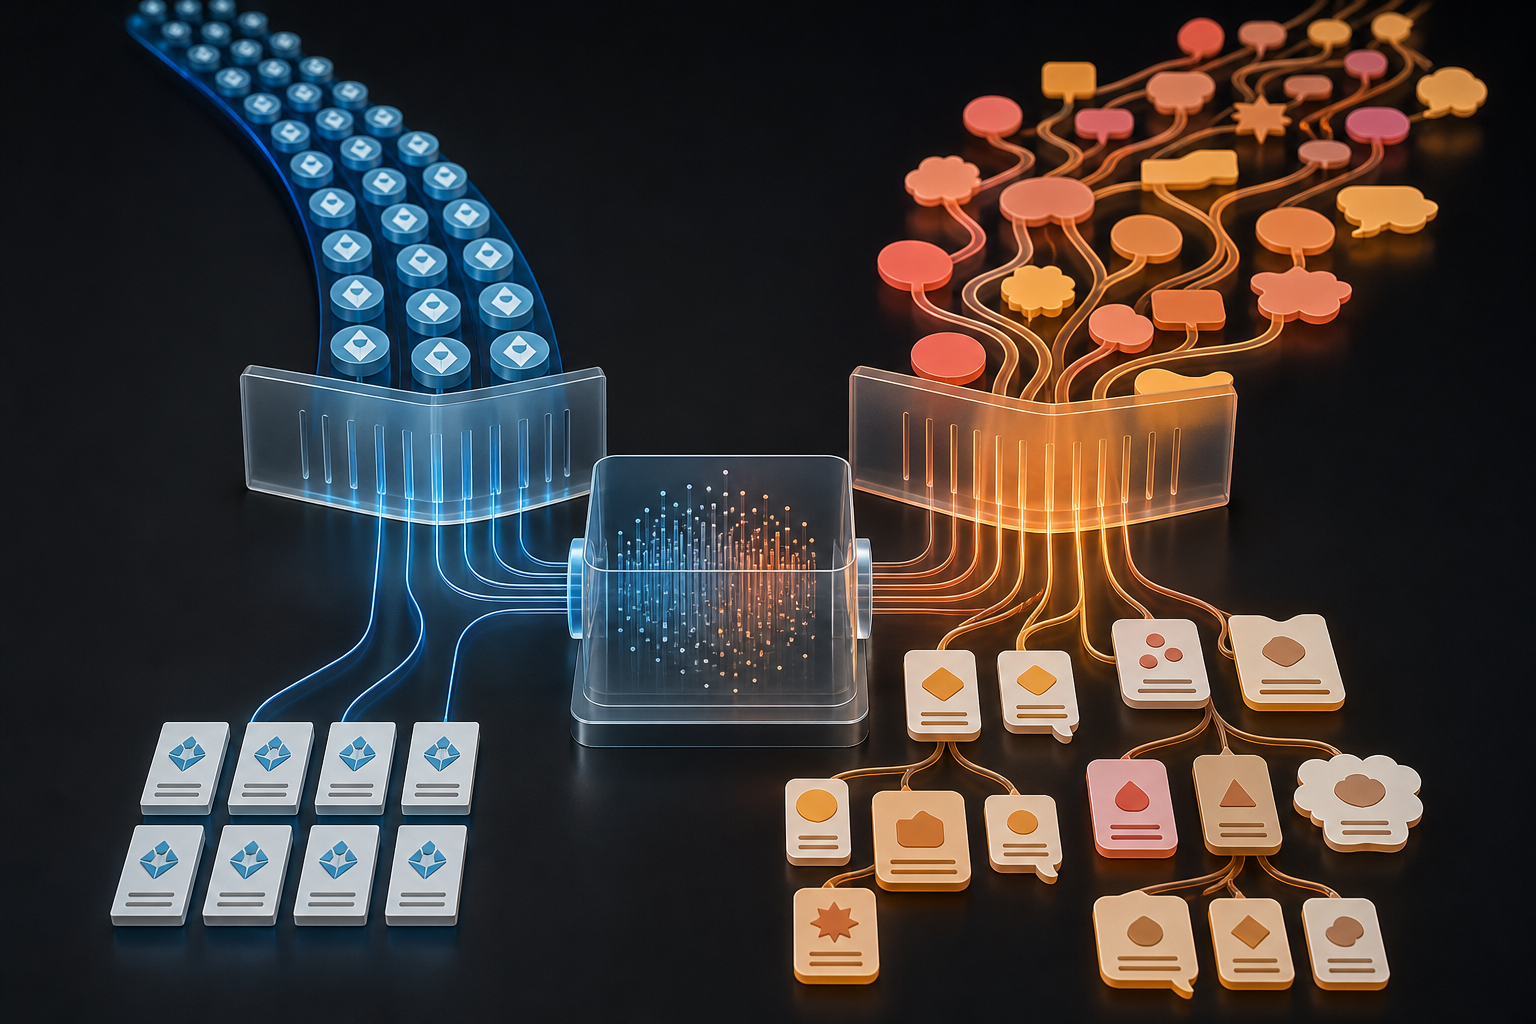
    Geometric claim tokens paired with evidence objects pass through a narrowing translucent funnel and emerge as compact modules with each claim still attached to its proof.

    AI-mediated discovery separates your claims from their original layout. A sentence may be summarized, compared with a competitor, quoted without its surrounding caveat, or combined with third-party commentary. Your important claims must remain accurate and understandable when they travel.

    Start with a claim ledger. This is a working record of what your organization wants customers and machines to understand. For each priority claim, record:

    • The exact proposition, including the audience, use case, product, tier, market, or other limits that define its scope.
    • The evidence supporting it, such as documentation, a demonstration, original data, a case study, a customer review, or an independently verifiable credential.
    • The canonical page where the complete claim and its qualifications live.
    • The current status: supported, partly supported, unsupported, outdated, or contradicted elsewhere.
    • The third-party pages that corroborate it and the context in which they mention the brand.
    • The person responsible for correcting or refreshing it when the product, policy, evidence, or market changes.

    Do not limit the ledger to promotional claims. Include basic entity facts: the brand name, products or services, audience, locations served, category, use cases, founders or experts, and the relationship between the company and its offerings. Confusion at this level can make every later trust signal harder to interpret.

    Then turn the ledger into a layered evidence system:

    • Canonical facts: Stable pages explain what the business and offer are, who they are for, and what conditions apply.
    • Decision evidence: Demonstrations, comparison criteria, methodology pages, case studies, original research, and expert explanations show why a claim deserves belief.
    • Experience evidence: Reviews, customer accounts, community recommendations, and creator coverage show what using the product or working with the company is like.
    • Risk evidence: Limitations, requirements, policies, implementation details, and honest fit guidance help customers rule the offer in or out.
    • Action evidence: Clear next steps show what happens after the customer chooses, reducing uncertainty at the handoff.

    Each evidence page should answer the central question near the claim, explain how the conclusion was reached, disclose important boundaries, and point to the next level of detail. Avoid burying the method or caveat in a disconnected document. If the qualification changes the meaning of the claim, keep the two together.

    Use structured data to clarify, not embellish

    JSON-LD can describe entities, attributes, authorship, products or services, and relationships in a machine-readable form. It cannot establish that a marketing claim is true, create an independent reputation, or guarantee inclusion in an AI answer.

    Keep the markup aligned with visible content. Organization identity, names, descriptions, authors, offers, reviews, and other marked-up details should agree with the page and with the canonical facts in your claim ledger. Do not place an accolade, rating, audience claim, or product attribute only in the markup. Structured data should be a faithful translation of the page, not a second and more flattering version of it.

    Consistency does not require copying one description word for word across the web. A creator needs a demonstration, a community participant needs a direct answer, and an AI-friendly reference page needs clear factual statements. The language can change while the underlying entity, scope, evidence, and conclusion remain stable.

    Earn corroboration instead of manufacturing consensus
    Four independent observers examine the same unbranded device from separate settings, with beams of light converging on one shared product feature while connected empty masks remain in the background.

    Backlinks still contribute to conventional SEO authority, but link volume does not prove that customers or AI systems should trust a brand. A placement can come from a high-authority domain and still be irrelevant, geographically mismatched, surrounded by unrelated commercial links, or disconnected from the page it supposedly endorses. That is why contextual relevance and credible corroboration are more useful tests than a domain metric alone.

    For AI visibility, use a practical working model: repeated, accurate descriptions on credible and topically relevant pages are more useful than isolated links inserted into unrelated content. A good external mention helps a person or system understand what the brand does, who it serves, the use case being discussed, and the basis for including it. The link may help discovery and navigation, but it cannot rescue meaningless context.

    Evaluate the mention as evidence

    Before pursuing or accepting a placement, inspect it with the same care you would apply to a claim on your own site:

    • Topical fit: The page discusses the problem, category, audience, or use case for which your brand is genuinely relevant.
    • Audience fit: The readers are people whose decisions the evidence could reasonably inform.
    • Editorial basis: The brand is included because of data, expertise, demonstrated capability, customer experience, or another explainable reason.
    • Claim specificity: The surrounding text says why the brand matters rather than dropping its name into a generic list.
    • Entity accuracy: The name, offer, market, use case, and relationship to the topic agree with your canonical facts.
    • Independence: Any sponsorship or commercial relationship is clear. A disclosed paid placement may provide reach, but it should not be counted as independent corroboration.
    • Context quality: The page is not overloaded with unrelated links, forced insertions, or claims that no reader could verify.

    Pitch the evidence, not the mention. Original findings can support an editorial explanation. A qualified expert can clarify a difficult decision. A working demonstration can help a reviewer assess fit. A customer with a relevant experience can support a case study or review, with appropriate permission and no script that predetermines the conclusion.

    One strong confidence asset can travel across several discovery points. An authentic review might appear in a traditional search result, inform an AI comparison, be quoted on a properly attributed website page, and be read directly on the review platform. The asset remains the evidence even when its discovery point changes. Plan distribution around that distinction.

    Reject tactics that imitate trust

    Buying a mention does not turn it into consensus. Be especially skeptical when a vendor promises AI visibility through reciprocal mention swaps, paid best-of lists presented as neutral rankings, irrelevant insertions on high-metric domains, or undisclosed promotional activity in communities. These tactics reproduce the weaknesses of commodity link building while changing the label from backlinks to GEO.

    The immediate problem is not merely that an artificial mention may fail to influence an answer engine. It gives your team a false picture of authority. A spreadsheet can show more placements while customers still lack a credible demonstration, an independent review, a current methodology page, or a clear explanation of fit. Third-party validation only helps when the third party and surrounding context are relevant enough to validate something.

    Do not set a quota for mentions until you can define what a qualifying mention is. Count the pages that accurately support a priority claim, not every page containing the brand name. This keeps outreach, PR, partnerships, community work, and link acquisition tied to customer confidence rather than output volume.

    Measure trust without pretending every influence is attributable

    Some confidence-building interactions are visible in analytics: visits, leads, sales, and conversions. Others happen before the customer reaches you. Someone may read a community thread, watch a review, ask an AI assistant for a comparison, and then conduct a branded search. Those interactions can influence the decision without appearing as attributable touchpoints.

    That does not make measurement futile. It means you need a scorecard that separates observable behavior from evidence coverage and directional signals.

    Track five views of the journey

    • AI and search presence: For representative queries, record whether the brand is absent, mentioned, included in a comparison, shortlisted, or recommended.
    • Answer fidelity: Check whether the surfaced description, audience, use cases, strengths, limitations, and other material claims are correct, ambiguous, outdated, or wrong.
    • Evidence coverage: Count which priority claims have a canonical page, adequate first-party support, credible external corroboration, and structured data that agrees with the visible facts.
    • Confidence-asset behavior: Monitor visits and meaningful engagement on case studies, demonstrations, methodology pages, reviews, comparisons, implementation guidance, and other proof assets. Examine whether customers who use those assets progress, without claiming the asset alone caused the outcome.
    • Commercial and customer signals: Track qualified leads, conversions, branded demand, direct visits, returning visitors, sales objections, and customers’ own descriptions of what influenced their choice.

    Replace the single-choice question How did you hear about us? with a multi-select question such as Which places helped you decide? Options can include an AI assistant, a search engine, a review site, a community, a video or creator, a colleague, and your website. Add an open response asking what almost stopped the customer from choosing you. The first question acknowledges a multi-platform journey; the second exposes the confidence gap your current assets did not fully close.

    Monitor prompts by confidence job

    A prompt library is more useful when it reflects how customers resolve uncertainty. Build unbranded and branded prompts for each job:

    • Fact finding: What should a defined audience verify before selecting this category for a particular use case?
    • Crowdsourcing: What experiences do similar buyers report with the available approaches?
    • Taste tuning: Which options fit a stated set of preferences, constraints, or working conditions?
    • Autopilot: Help the buyer evaluate a realistic shortlist and decide what to do next.

    For each check, save the exact prompt, search or assistant surface, date, result classification, claims made about the brand, cited pages, and any factual errors. Use the same core prompts again after material changes so you can inspect direction rather than reacting to one generated answer. Start unbranded to see whether the brand enters the category naturally, then use branded prompts to test whether its description and evidence remain accurate.

    Run the work in dependency order

    1. Select one valuable customer decision rather than auditing every possible journey at once.
    2. Map its fact-finding, crowdsourcing, taste-tuning, and autopilot gaps.
    3. Create the claim ledger and identify contradictions, unsupported claims, and missing canonical pages.
    4. Repair the first-party evidence before asking external sites or communities to repeat it.
    5. Package the strongest evidence for the publications, reviewers, creators, customers, partners, and communities that naturally serve the audience.
    6. Align visible content and JSON-LD with the supported claim set.
    7. Monitor representative prompts, proof-asset behavior, customer feedback, and commercial outcomes as separate but connected signals.
    8. Use the next cycle to fix the largest remaining confidence gap, not merely the channel with the easiest traffic report.

    Choose one high-value decision and audit its claims before publishing another awareness page. Mark each claim as supported, partial, unsupported, outdated, or contradicted, then fix the first contradiction a customer could encounter. In an AI-mediated journey, the fastest trust improvement often comes from making the evidence behind existing visibility easier to understand and verify.

    References


  • AI Visibility Signals: A Practical Framework for PPC

    AI Visibility Signals: A Practical Framework for PPC

    Your PPC account can look technically healthy while attracting buyers who expect the wrong service, product, price point or level of support. Search terms and conversion tracking show the resulting behavior, but they may not reveal where that expectation began.

    AI visibility signals add the missing pre-click context. They help you see how an AI system interprets a need, which information it retrieves and whether your brand helps shape the response. Used alongside PPC evidence, that context can tell you whether to adjust targeting, clarify a landing page, test new messaging or leave the campaign alone.

    Three signals fill the pre-click blind spot

    Conventional PPC analysis begins with observable activity: a search, an impression, a click, a visit or a conversion. AI can influence the buyer earlier by shaping what they know, which brands enter consideration and which words they later use. AI visibility data does not replace PPC reporting or prove that an AI response caused a conversion. It shows the informational environment surrounding the demand you are trying to capture.

    SignalWhat it revealsBest PPC useWhat it does not prove
    Grounding queriesThe retrieval searches an AI system uses to support a response, including the topics and sub-questions it associates with the original need.Diagnose intent, find useful language and identify possible keyword, search-theme, creative or landing-page tests.That every retrieved phrase should become a keyword.
    CitationsWhether your content was referenced while an AI-generated answer was assembled.Check whether the topics shaping consideration reinforce the promises in your campaigns.That the AI endorsed your brand, sent a visitor or produced a customer.
    Share of authorityHow much citation activity belongs to your domain relative to other cited domains in the same topic or query set.Locate topics where competitors help define the answer more often than you do and decide whether the gap is commercially important.Paid impression share, market share, brand sentiment or conversion probability.

    A single prompt can generate multiple grounding queries about comparisons, pricing, reviews, product details, availability or implementation. That makes grounding data richer than a keyword list, but also easier to misuse. It represents the system’s interpretation of intent, not a direct record of what a person typed.

    Citations need similar restraint. A citation means that a page contributed information to an AI experience. It does not tell you, on its own, whether the reference was prominent, favorable or persuasive. Review the associated topic and the cited page before deciding that a citation is commercially useful.

    Share of authority is comparative, so preserve the comparison. Use the same topic definition and query set when you evaluate changes. A number drawn from one prompt set should not be compared casually with a number drawn from another.

    Diagnose alignment across AI, ads, pages and customers

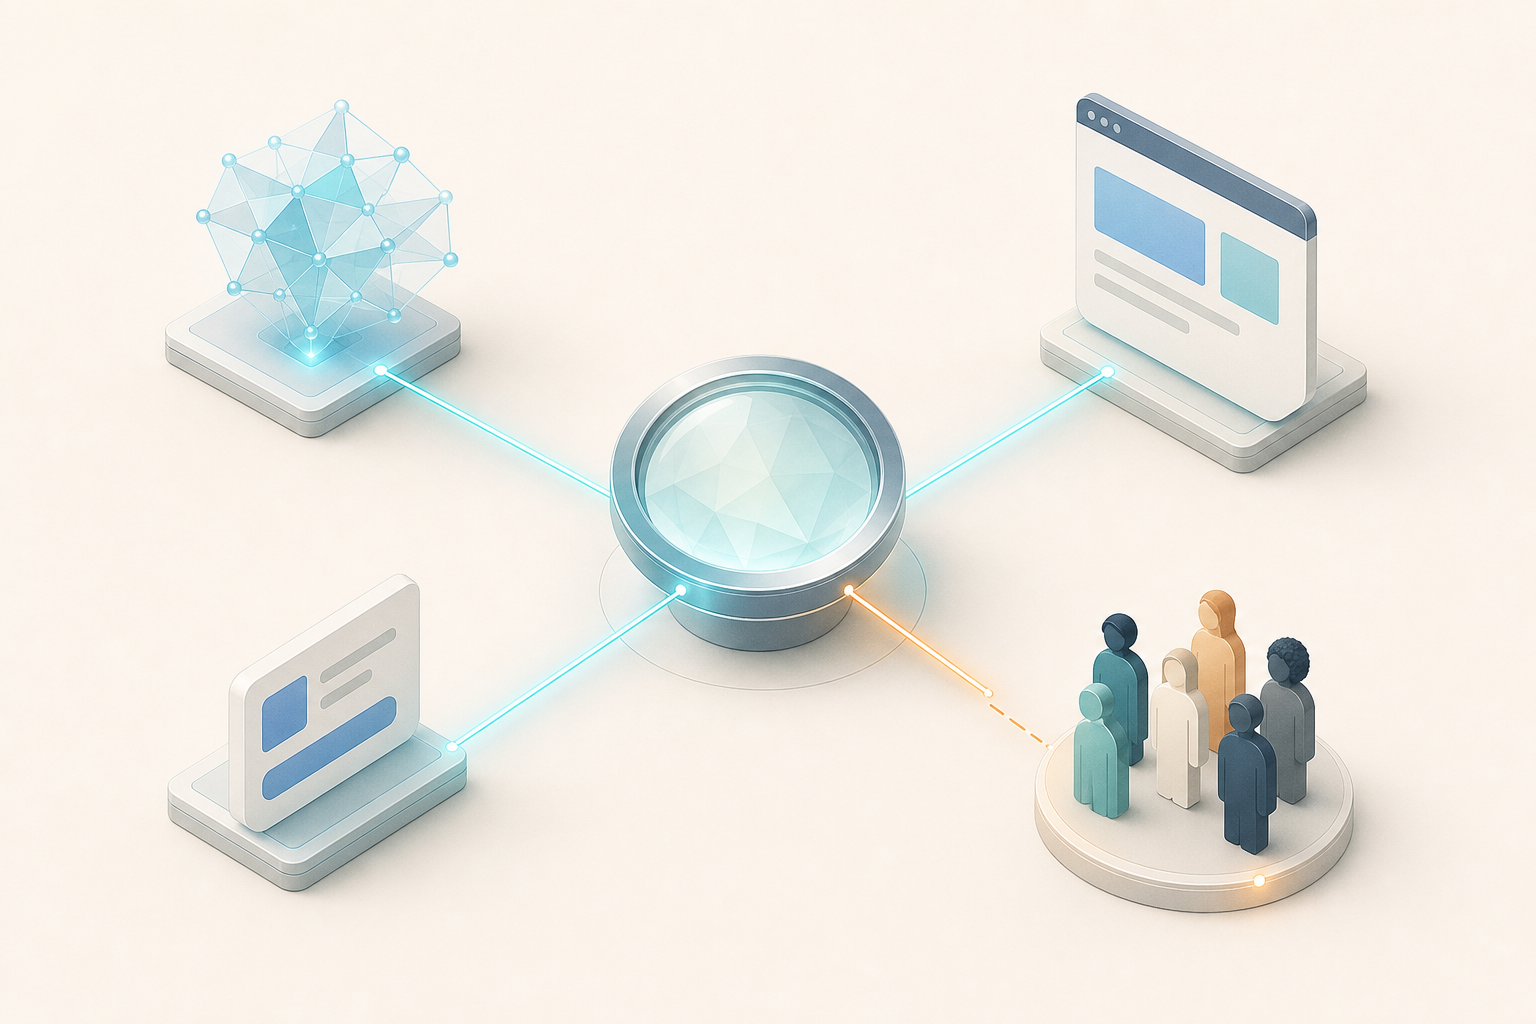
    An abstract AI node, ad tile, landing page and customer group connect through a central lens, with one amber path visibly out of alignment.

    The useful question is not whether your brand has AI visibility. It is whether AI interpretation, customer searches, advertising, landing-page claims and customer quality describe the same commercial offer.

    Trace one intent cluster through this sequence: AI interpretation, search behavior, ad promise, landing-page proof and business outcome. A break between two stages gives you a more specific diagnosis than a general visibility score.

    • AI and PPC intent align, and conversion quality is strong: you have a candidate for a controlled expansion test. Confirm that the landing page supports the intent before adding broader matching or automation.
    • AI interpretation and paid search terms drift in the same unwanted direction: the account may be reflecting a broader positioning problem. Clarify the offer and the audience before increasing bids or budget.
    • AI interpretation is wrong, but paid search terms and customers remain well aligned: treat this first as a content and brand-representation issue. Do not disturb a healthy campaign merely to react to an isolated AI signal.
    • AI interpretation is accurate, but paid search terms or customers are poor: investigate campaign matching, search themes, exclusions, ad promises and landing-page continuity. The evidence points more directly to the paid journey than to AI representation.
    • Competitors hold more citation activity for an important topic, but your PPC performance is healthy: inspect the content gap without assuming that paid budgets need to change. Share of authority is context for strategy, not a bidding instruction.

    Judge conversion quality using the downstream outcome your business actually values: customer fit, sales qualification, purchase value, retention potential or another established business measure. A form submission from the wrong customer can make campaign automation appear successful while teaching it to pursue more of the wrong demand.

    Topic alignment deserves particular attention. A cybersecurity platform seeking enterprise identity-protection buyers has a real problem if AI systems consistently associate it with small-business antivirus comparisons. The phrases are related at a broad category level, but they imply different customers, requirements and buying paths. That kind of mismatch can look like a targeting failure even when unclear positioning is the underlying issue.

    Build a repeatable AI-to-PPC analysis

    You do not need to pour every AI observation into the ad account. You need a repeatable method that separates evidence, interpretation and action.

    1. Write down the commercial truth first. State what you sell, who it is for, which problems it solves and which adjacent use cases you do not want to attract. This becomes the standard against which AI associations are judged.
    2. Choose a fixed set of commercially meaningful prompts. Cover the decisions that matter to your buyers, such as comparisons, pricing, reviews, product details, availability and implementation. Keep the set stable when you want to compare observations over time.
    3. Capture the AI evidence without interpreting it yet. Record the original prompt, grounding queries, cited domains and URLs, associated topics and share-of-authority result. Also record the AI surface, market and observation date so later comparisons retain their context.
    4. Cluster by underlying need. Group retrieval queries that express the same decision or problem even when their wording differs. Do not require an exact phrase match between a grounding query and a paid search term.
    5. Join each cluster to PPC evidence. Review related search terms, campaigns, ad promises, landing pages and conversion quality. Note whether AI and paid data point toward the same buyer and offer.
    6. Classify the association. Mark it as core, adjacent, misleading or unclear. Core means it matches a priority offer and customer. Adjacent means it is accurate but not a growth priority. Misleading means it describes something you do not sell or a customer you do not want. Unclear means the available evidence is insufficient.
    7. Write a testable diagnosis. Use a sentence such as: Because the AI evidence and PPC evidence both associate us with this lower-value need, we will clarify one page and one ad message, then judge whether customer quality improves.
    8. Prioritize corroborated patterns. Give more weight to an interpretation that appears across grounding queries, citations, search terms, landing-page language and customer quality. Log isolated observations, but do not let them trigger an account-wide change.

    A practical worksheet can use one row per intent cluster. Include the desired customer, grounding-query examples, cited topic, citation status, share-of-authority context, related paid search terms, current landing page, conversion-quality finding, alignment classification, working diagnosis, proposed action and success measure. Keeping those fields in one place stops a visibility observation from being mistaken for a campaign instruction.

    This process also prevents a common attribution error. AI visibility can help explain the context surrounding demand, but it cannot tell you that a specific citation caused a specific click or sale. Use conversion tracking for measured outcomes and AI visibility for interpretation.

    Turn the diagnosis into a controlled PPC test

    Two parallel marketing test lanes use the same audience inputs while one highlighted element differs between their ads and landing pages.

    When AI and PPC data expose a mismatch, resist the reflex to change bids. Audit the relevant landing page before assuming that budget, bidding or audience targeting is at fault. Check whether the page clearly identifies the problem being solved, supports its advertising claims with appropriate proof and describes the customer you actually want.

    Choose the smallest lever that can test the diagnosis

    • Test a keyword or search theme when the grounding-query cluster represents demand you genuinely want, related search terms show useful intent and an appropriate landing page already exists.
    • Test creative when AI and customers use accurate language that your ads fail to reflect, or when the ad needs to distinguish your offer from a nearby but lower-value category.
    • Update a landing page when the page blends several offers, fails to identify the intended customer or lacks proof for the promise made in the ad.
    • Update supporting content when useful comparison, product-detail or implementation questions appear repeatedly but your site does not answer them clearly.
    • Test AI-supported campaign matching when you find many relevant grounding queries, the offer is represented accurately and conversion quality can be measured. Performance Max, AI Max and other AI-supported campaign types can be candidates, but the grounding data remains an input rather than an instruction.
    • Make no campaign change when the observation is isolated, commercially unimportant or contradicted by stronger PPC and customer evidence. Preserve it for later comparison.

    Change as little as the diagnosis requires. If you rewrite the landing page, broaden matching, replace creative and alter the bidding strategy at the same time, you will not know which change affected customer quality. A bounded test should connect one documented interpretation problem to one primary lever and one business outcome.

    Protect the account from false inferences

    • Do not paste grounding queries into a keyword list without checking commercial fit, customer fit and landing-page support.
    • Do not call a citation a conversion, endorsement or attributable visit.
    • Do not treat share of authority as paid impression share or use it to allocate budget mechanically.
    • Do not broaden automation while the offer is described inconsistently across ads, pages and supporting content.
    • Do not judge success only by click-through rate or conversion count when the diagnosis concerns buyer quality.
    • Do not compare share-of-authority observations built from materially different topics, prompts or market contexts.

    AI-powered features such as final URL expansion, asset optimization and broader matching depend on interpretations of your pages and offers. If AI visibility reporting shows that the brand is being misunderstood, campaign automation may inherit some of the same confusion. Clear positioning is therefore a prerequisite for a sensible expansion test, not a cosmetic content task to postpone until later.

    Worked example: executive coaching versus sales training

    Suppose a B2B company sells executive coaching, but its grounding queries repeatedly cluster around tactical sales-training courses. Paid search terms also contain training-led intent, and the landing page uses coaching, training and advisory language interchangeably.

    The wrong response is to add every grounding query as a keyword or raise bids because the topic appears relevant. The better diagnosis is that AI interpretation, paid demand and page language all blur two offers that attract different buyers, expectations and conversion paths.

    1. Clarify the priority landing page around executive coaching, the intended buyer and the problems the engagement addresses.
    2. Qualify or remove tactical training language where it misrepresents the priority offer.
    3. Align ad creative with the same distinction.
    4. Use campaign controls to reduce clearly unwanted training intent where the PPC evidence supports that decision.
    5. Judge the test by customer fit and sales quality, not merely by the number of submitted forms.
    6. Consider broader AI-supported matching only after the offer is represented consistently.

    That sequence turns AI visibility into a falsifiable PPC hypothesis. It also preserves the possibility that the diagnosis is wrong: if customer quality does not improve after the message is clarified, return to the evidence instead of declaring the visibility signal predictive.

    Key takeaways

    • AI visibility adds pre-click context; it is not a replacement for PPC reporting or attribution.
    • Grounding queries reveal how an AI system decomposes intent, but they are not keywords.
    • Citations show participation in an AI-generated answer, not endorsement, traffic or conversion.
    • Share of authority compares citation activity within a defined topic or query set; it is not impression share.
    • The strongest diagnosis connects AI interpretation with search terms, landing-page language and conversion quality.
    • Fix a representation problem before asking broader matching or campaign automation to scale it.
    • Use one bounded change and a business-quality outcome to test each diagnosis.

    At your next PPC review, choose one commercially important intent cluster and add grounding queries, citations and share-of-authority context to the evidence you already use. If the same mismatch appears in AI interpretation, paid search behavior and customer quality, you have a specific problem worth testing. If it does not, keep observing rather than forcing the account to react.

    References


  • AI Visibility Platform or Specialist Agency: How to Choose

    AI Visibility Platform or Specialist Agency: How to Choose

    You know your brand is missing, misrepresented, or rarely recommended in AI answers. The difficult decision is what to buy next: software that shows you the problem, an agency that works on it, or both.

    Choose based on the work your team can own after the first audit. A visibility platform is primarily an instrument. A specialist agency is primarily an operating team. If you buy one while expecting the other, you can collect months of reports without changing what an AI system retrieves, believes, recommends, or lets a user do next.

    Key takeaways

    • Choose a platform when your main gap is measurement and your team can turn findings into content, technical, PR, and product changes.
    • Choose a specialist agency when the diagnosis is reasonably clear but you lack the expertise, coordination, or production capacity to act on it.
    • Use a hybrid when visibility is strategically important enough to require independent measurement and sustained execution.
    • Measure retrieval, recommendation, factual accuracy, citations, suitability, and action readiness separately. A single visibility score hides too much.
    • Evaluate agencies using client outcomes in your market, not the agency’s own AI presence or a newly adopted service label.

    Buy the kind of help your bottleneck requires

    The decision becomes easier when you replace the vague goal of “improving AI visibility” with a concrete bottleneck. Are you unable to observe relevant answers? Do you understand the answers but lack the people to change them? Or do several teams need a shared measurement system and an external execution partner?

    OptionWhat you are buyingBest fitCommon gap
    AI visibility platformRepeatable monitoring, prompt tracking, citations, competitor observations, and reportingYou have content, SEO, PR, analytics, and technical owners who can act on findingsThe platform identifies a weak result but does not make the organizational changes required to improve it
    Specialist agencyDiagnosis, strategy, production, coordination, and specialist judgmentYou need execution capacity or expertise across several disciplinesYou depend on the agency’s sampling, interpretation, and reporting unless you retain access to the underlying data
    Hybrid modelAn internal measurement layer plus external executionAI discovery affects meaningful demand and you need both continuity and delivery capacityOverlapping responsibilities can produce duplicate reports and unclear accountability

    A platform is the cleaner choice when your team already knows how to update comparison pages, strengthen entity information, earn credible coverage, correct unsupported claims, improve structured data, and coordinate changes with product or engineering. The tool should tell those owners where to look and whether the result is moving.

    An agency is the better choice when those tasks have no durable owner. That often happens when SEO manages rankings, PR manages external authority, product controls integrations, legal reviews claims, and nobody owns the complete AI answer. The agency’s value should be its ability to connect those functions and deliver approved changes, not merely produce another dashboard.

    The hybrid model works when you want measurement continuity even if you change agencies. Your company owns the prompt set, raw observations, definitions, and historical benchmark. The agency receives access, proposes interventions, executes an agreed scope, and reports against the same measurement system. This keeps the agency from becoming the only party that can interpret whether its work succeeded.

    Feature breadth deserves proof before you commit. A product can look complete in a demonstration and still thin out when your workflow requires deeper analysis. Test the exact workflow you need, including exports, answer snapshots, citations, segmentation, collaboration, and follow-through. A long feature list is not a substitute for completing one real investigation from prompt to corrective action.

    Map visibility across retrieval, evaluation, and action

    An isometric scene shows source materials passing through a retrieval gateway and an AI evaluation chamber before reaching a user action terminal.

    Brand mentions are only the first layer. Agentic search can move from finding possible vendors to assessing fit and, where a product’s API supports it, completing an action or transaction. A useful operating model therefore separates retrieval, evaluation, and action.

    1. Retrieval: Can the system find and understand your brand for an eligible request? Relevant evidence can include authoritative pages, comparison content, metrics, clear entity statements, credible mentions, and citations.
    2. Evaluation: Does the answer connect your product to the right buyer, requirement, constraint, industry, or use case? Being listed is not enough if the system presents you as unsuitable for the work you actually want.
    3. Action: Can the user or agent complete a sensible next step? Depending on the task, that may mean reaching a suitable product page, requesting a demonstration, checking availability, using an integration, or invoking a supported API.

    This model prevents a common purchasing mistake. If you only need retrieval monitoring, a platform may be sufficient. If the problem is evaluation, you may need positioning, proof, comparison assets, and third-party authority. If the problem is action, marketing alone may not fix it; product, engineering, sales operations, or commerce owners may need to change the handoff.

    Build your benchmark from actual buyer situations, not a list of short keywords. Each test case should record the buyer role, task, constraints, decision stage, target market, exact prompt, platform, visible model label, date, and answer. Sample the systems that matter to your audience; cross-platform evaluations commonly include ChatGPT, Perplexity, Claude, and Google Gemini.

    Use separate working metrics so a favorable average cannot conceal a material failure:

    • Mention coverage: the share of eligible prompts in which the brand appears at all.
    • Recommendation rate: the share of eligible prompts in which the brand is presented as a viable choice, not merely mentioned.
    • Suitability: whether the stated use cases, buyer types, constraints, and differentiators match your approved positioning.
    • Belief accuracy: the share of audited factual claims that are correct. Record serious errors individually; an average can disguise a harmful claim.
    • Citation traceability: whether important claims have visible, inspectable support and which domains provide it.
    • Action readiness: whether each relevant task has a working, appropriate next step rather than a dead end or generic homepage.

    Keep the prompt set and test conditions stable when comparing periods. AI answers can vary, so one favorable response is not proof of improvement. Preserve the raw answer alongside every score. Without the answer snapshot, your team cannot distinguish a genuine positioning change from a scoring inconsistency.

    Evaluate platforms and agencies with different evidence

    Software and services fail in different ways, so they should not share one generic procurement checklist. A platform needs trustworthy observation and usable data. An agency needs diagnostic judgment, execution depth, and evidence that it can operate in your buying environment.

    Questions to put to a visibility platform

    • What is captured? Ask whether the system stores the complete answer, citations, model or platform label, timestamp, prompt, and relevant test settings. A score without its underlying answer is difficult to audit.
    • Can we control the prompt set? You should be able to separate branded discovery, category research, comparisons, objections, regulated questions, and action-oriented requests.
    • How is volatility handled? Ask how repeated observations are represented and whether the interface distinguishes a durable pattern from a one-off answer.
    • Can we inspect the scoring rules? The platform should define what counts as a mention, citation, recommendation, favorable position, and competitor appearance.
    • Can we export raw and historical data? Confirm this before signing. Screenshots and summary PDFs are not enough if you later need independent analysis or a different service partner.
    • Does it lead to a corrective workflow? Test whether a user can move from a problematic answer to its likely evidence, affected page or source, assigned owner, and verification step.
    • Does access fit the operating team? Check permissions and collaboration for content, PR, analytics, product, legal, and agency users rather than assuming one SEO login will serve everyone.

    Ask the vendor to run your own prompts during the evaluation. Include one missing-brand case, one inaccurate-description case, one competitor comparison, one buyer with strict constraints, and one action-oriented request. Then export the evidence and assign a corrective task. That short exercise exposes more than a polished dashboard tour.

    Questions to put to a specialist agency

    • How do you establish the baseline? Require the prompt set, eligible-prompt rules, raw answers, scoring definitions, platforms covered, and testing method.
    • Which client outcomes can we inspect? Look for prompt-level before-and-after evidence, changes in citations or belief accuracy, and a clear account of what the agency changed. The agency’s own visibility is not a client result.
    • Who performs each part of the work? Identify the people responsible for strategy, technical review, content, digital PR, structured data, analytics, and project management. Confirm which work is subcontracted.
    • How does the plan address all three stages? Retrieval may require discoverable evidence; evaluation may require suitability and comparison assets; action may require product pages, feeds, integrations, or APIs. Ask what is in scope and what remains yours.
    • How will incorrect AI beliefs be handled? The response should identify the unsupported claim, its likely evidence environment, the approved correction, publication or authority work, and the method for retesting.
    • How is commercial relevance measured? Visibility should be segmented by buyer, use case, and decision stage, then connected where possible to qualified demand, referrals, assisted conversions, or pipeline. Raw mention volume can rise while business relevance falls.
    • What will we own at the end? Put ownership of prompts, measurements, content, schema, digital assets, account access, and reporting history in the agreement.

    Review scores, famous client logos, media references, leadership experience, and years in business can all help with initial screening. None proves that the team assigned to you can improve your visibility. Treat an agency’s founding year as evidence of operating history and adjacent SEO or GEO experience, not proof of long experience in agentic search; the agentic specialty is newer than many firms offering it.

    Raise the bar in regulated or technical markets

    Vertical experience matters most when a plausible-sounding error can create compliance, safety, procurement, or reputational exposure. Medical-device work, for example, has to respect regulatory clearances, clinical evidence, credentialing signals, technical terminology, and the limits of approved claims. Generic product copy is a poor test of whether a partner can manage that environment; regulated GEO programs require subject-matter and compliance-aware execution.

    Give a prospective agency a realistic claim-governance exercise. Provide an approved product statement, an unapproved overstatement, and an AI answer that confuses the two. Ask who decides the correction, what evidence may be published, where legal or regulatory review enters, and how the team will verify the changed answer. A partner that jumps straight to content production without defining approval authority is not ready for high-consequence work.

    Run a proof of workflow before committing to scale

    A small team tests a connected evidence, AI response, and user action workflow at a brightly lit pilot table while additional workstations remain inactive behind them.

    A useful pilot should prove a complete operating loop, not manufacture a temporary lift in a presentation. Use a bounded set of commercially relevant prompts and require the platform or agency to move from observation to an assigned intervention and then back to verification.

    1. Define the decision. Write down whether you are choosing software, execution capacity, or a hybrid. Name the internal teams expected to use the result.
    2. Select eligible prompts. Cover distinct buyers, use cases, constraints, comparison questions, objections, and next-step requests. Exclude prompts for which your brand would not reasonably be a fit.
    3. Freeze the baseline. Store every exact prompt, answer, citation, date, platform, model label, and scoring decision. Record factual errors separately from unfavorable opinions.
    4. Classify each failure. Mark it as retrieval, evaluation, or action. Then assign an owner: content, technical SEO, PR, product, engineering, sales operations, legal, or another accountable function.
    5. Choose a small intervention set. Examples include correcting an entity statement, strengthening a comparison page, publishing suitability evidence, resolving contradictory claims, improving structured data, earning relevant third-party coverage, or repairing an action pathway.
    6. Retest the same cases. Preserve new answer snapshots and compare them with the baseline. Do not substitute easier prompts after work begins.
    7. Review operational friction. Note whether the data was exportable, scoring was explainable, approvals were manageable, owners received usable tasks, and the intervention could be traced to a result.

    Set the commercial terms around that loop. A platform agreement should identify data access, export rights, prompt limits, model coverage, historical retention, user permissions, and support. An agency scope should identify deliverables, approval dependencies, responsible specialists, reporting inputs, asset ownership, out-of-scope technical work, and the evidence required before a result is called successful.

    For a hybrid engagement, make the division explicit. Your platform remains the shared measurement record. The agency owns named interventions and documents what changed. Your internal owners approve claims, release technical or product updates, and connect visibility data to commercial outcomes. One party should still own the overall program; shared access is not shared accountability.

    Start with the bottleneck you can name today. If you cannot reliably see the problem, prove the measurement workflow. If you can see it but cannot ship corrections, test an agency on one complete intervention. Scale only when the same system can show what changed, who changed it, and whether the answer became more accurate and useful for the buyer you intended to reach.

    References


  • How to Choose AI Search Optimization and Query Analytics Tools

    How to Choose AI Search Optimization and Query Analytics Tools

    You’re looking at an AI visibility dashboard that says your brand is being cited more often. The line is moving in the right direction, but it still doesn’t tell you whether new buyers discovered you, existing demand simply used your name, or any cited page contributed to a useful business outcome.

    That is the real tool-selection problem. You don’t need another score with an upward arrow. You need a system that preserves the chain from query to citation to page to outcome, then shows you what to change.

    Start with the decision your tool must support

    AI search optimization tools often combine monitoring, query analysis, content recommendations, competitive tracking, and attribution. Those functions may appear in one interface, but they answer different questions. Treating them as one category makes it easy to buy broad coverage without gaining a usable workflow.

    Write down the decisions you expect the tool to improve before you review its features:

    1. Where are we absent? Identify the topics, questions, platforms, markets, and answer types where your brand or pages are missing.
    2. Why are we absent? Determine whether the likely gap concerns content relevance, factual clarity, source eligibility, entity representation, authority, technical accessibility, or a weak match between the query and the page.
    3. What should we change? Turn the observation into a specific action on a specific URL, entity record, content brief, internal link, or structured-data implementation.
    4. Did the change matter? Compare the same query set and conditions after the change, then connect improved visibility to visits, leads, transactions, or another outcome that matters to your organization.

    The underlying measurement chain contains several distinct objects:

    • Audience intent: the problem or decision a person is trying to resolve.
    • User prompt: the words the person enters into an AI interface, when that information is actually available.
    • Grounding query: a lookup an AI system uses to find supporting information for its response. This is not necessarily the user’s verbatim prompt. Microsoft Clarity’s AI reporting, for example, surfaces grounding queries used to retrieve supporting information.
    • Citation: the page or domain selected as support.
    • Answer inclusion: whether the answer mentions, describes, compares, or recommends the brand.
    • Outcome: what happens after exposure, such as a visit, signup, qualified lead, assisted conversion, or transaction.

    A tool that observes only one layer cannot explain the whole chain. Citation tracking doesn’t automatically reveal the original prompt. A brand mention doesn’t prove that your page was cited. Referral traffic doesn’t show every answer that influenced a person without producing a click. Revenue attribution doesn’t become trustworthy merely because a dashboard attaches currency to an AI channel.

    Define each metric before accepting it. Record its numerator, denominator, platforms, markets, languages, query set, brand rules, reporting window, and treatment of missing observations. A citation rate calculated from a monitored query set describes that set; it is not a census of your visibility across every possible AI answer.

    Separate branded demand from non-branded discovery

    Two separate streams of abstract search signals represent existing brand demand and broader discovery before entering an analytics system.

    An aggregate visibility score can rise while your ability to reach unfamiliar buyers remains flat. That happens when branded questions and generic category questions are blended into one total.

    A branded query contains your company, product, domain, or another deliberate brand identifier. A non-branded query expresses a problem, category, use case, comparison criterion, or desired outcome without naming you. The first group usually tells you about retrieval around existing awareness. The second gives you a clearer view of discovery and consideration beyond that awareness.

    Microsoft Clarity can now label individual AI queries as branded, filter by branded or non-branded status, and break Share of Authority out by query type. The important lesson is broader than one product: any query analytics workflow should preserve this distinction rather than bury it inside a blended score.

    Observed patternWorking interpretationWhat to inspect next
    Branded visibility improves while non-branded visibility is flatExisting brand retrieval may be strengthening without broader category discoveryReview missing generic intents, competitor citations, and whether you have a suitable page for each important problem or category query
    Non-branded citations improve but brand inclusion does notYour pages may be useful as evidence without creating a strong connection to the brandInspect how clearly the cited page identifies the organization, product, expertise, and relationship between the evidence and the brand
    Citations improve but downstream outcomes remain flatThe new exposure may be informational, poorly matched to the intended audience, or disconnected from a useful next stepCheck the cited URLs, query intent, landing-page path, calls to action, and whether the outcome is measurable at all
    Branded visibility declines while non-branded visibility is stableGeneral topical relevance may be intact while brand-specific retrieval or representation has weakenedCheck name variants, product facts, changed URLs, outdated pages, inconsistent entity details, and competing pages that may have replaced the intended citation

    These are diagnostic hypotheses, not proof of causation. Use them to choose the next inspection, not to declare why an AI system behaved as it did.

    Your brand classification rules also need to be explicit. Build a controlled dictionary containing the company name, product names, domains, accepted abbreviations, former names that still matter, and common variants. Keep competitor-only queries out of your branded segment. Put queries that contain both your brand and a competitor into a separate brand-plus-competitor segment if comparisons matter to you.

    Preserve the raw query beside the assigned label. When the dictionary changes, record the change and reprocess historical data consistently where possible. Otherwise, a reporting shift caused by classification can look like a visibility shift caused by the market.

    Turn query analytics into an optimization queue

    Abstract query signals are sorted into groups and condensed into a short stack of prioritized optimization cards.

    A query report becomes useful when every important observation has an owner, a target page, a proposed change, and a validation method. Without those fields, the dashboard produces interesting meetings rather than better search assets.

    Use this operating loop:

    1. Capture the evidence. Keep the raw query, platform, observation time, market and language where available, branded status, cited URL, brand inclusion, answer evidence, and any connected outcome identifier. A screenshot can help with review, but retain exportable text or structured records as well.
    2. Cluster by intent. Group wording variants around the same underlying job, such as learning, evaluating, comparing, troubleshooting, or buying. Do not force ambiguous queries into a convenient category; an unknown bucket is more honest than false precision.
    3. Map each cluster to the page that should win. Record the preferred URL even when it is not currently cited. If several internal pages compete for the same intent, decide which one should be canonical for the task before producing more content.
    4. Write a testable diagnosis. Replace vague notes such as improve authority with statements such as the preferred page does not answer the comparison criterion present in the query, or the cited page contains an outdated product description.
    5. Make the smallest defensible change. Clarify the direct answer, add missing evidence, update obsolete facts, improve the heading and page structure, strengthen relevant internal links, or repair structured data that inaccurately expresses visible page content.
    6. Recheck under comparable conditions. Use the same defined query set, platforms, markets, and classification rules. Preserve before-and-after evidence and treat a single changed answer as an observation, not conclusive proof.
    7. Connect the result to an outcome. Determine whether the change affected only citation presence or also brand inclusion, qualified visits, assisted conversions, leads, transactions, or another declared objective.

    The diagnosis step prevents a common failure: applying the same content tactic to every visibility gap. Different observations call for different checks.

    • The relevant query appears, but your domain is not cited: inspect the pages that are cited, the kind of evidence they provide, and whether you have an eligible page that directly satisfies the intent.
    • Your domain is cited through the wrong page: inspect internal competition, redirects, canonical signals, page purpose, and whether the preferred page is actually the better answer.
    • Your page is cited, but the brand is not meaningfully included: examine whether the page supplies a fact without establishing a clear relationship between that fact, your entity, and the reader’s decision.
    • The brand appears, but a material fact is wrong: prioritize factual correction over visibility growth. Audit the current page, structured data, consistent entity details, and any outdated content that could support the error.
    • Visibility and traffic improve, but conversions do not: inspect intent fit and the path after arrival. The cited content may answer an early-stage question while the page asks for a late-stage commitment.

    Structured data belongs inside this workflow, but it isn’t a substitute for the page. JSON-LD should express accurate, visible, supported facts and relationships. Adding markup for information the reader cannot verify on the page creates a data-quality problem rather than an optimization advantage.

    Keep the queue prioritized by consequence as well as visibility. An inaccurate product claim deserves attention even if it appears in a small query cluster. A high-volume-looking theme may deserve less attention if it has no suitable audience, page, or business path. The tool should help you retain those distinctions instead of sorting every task by a single proprietary score.

    Choose the tool by the evidence it can preserve

    AI platform coverage, optimization actions, agentic commerce, and revenue attribution form a useful buying frame. They are not interchangeable, and a long feature list in one area does not compensate for missing evidence in another.

    Buying criterionEvidence to requestWarning sign
    Platform coverageA precise list of answer experiences, markets, languages, collection methods, refresh behavior, and historical availability, plus raw evidence behind each observationA platform logo is shown without explaining which surface, geography, or data-collection method it represents
    Query analyticsRaw query export, a clear distinction between user prompts and grounding queries, editable brand rules, intent grouping, page mapping, and traceable metric definitionsAll observations are collapsed into a visibility score whose denominator and monitored universe are unclear
    Optimization actionsA recommendation that identifies the query, diagnosis, target URL, proposed change, supporting evidence, owner, status, and validation signalGeneric instructions to add authority, improve quality, or write more content without showing the affected query and page
    Agentic commerceA concrete explanation of the agent action being observed or enabled, the product data required, the supported transaction path, and the event record available for verificationThe term agentic is used for ordinary content generation, chatbot interaction, or product monitoring without an observable commerce action
    Revenue attributionThe identifiers and rules that connect exposure, citation, visit, conversion, and revenue; documented attribution logic; accessible underlying records; and a path for unresolved or unattributed casesRevenue appears beside an AI channel without a reproducible connection between the visibility event and the business event
    Data portabilityExports for raw observations, labels, evidence, URLs, recommendations, status history, and outcome joins in a format your team can use elsewhereYour history, classifications, and evidence disappear when the subscription ends or cannot be independently audited

    Agentic commerce should carry substantial weight only when it matches your business model. If you sell structured products and expect agents to participate in discovery or transactions, ask exactly which part of that path the tool measures. If you publish advice, generate leads, or sell a service through a considered sales process, query coverage, citation evidence, content actionability, and attribution may deserve more weight.

    Do not evaluate attribution from the dashboard label. Ask the vendor to walk through one record from the observed AI event to the business outcome. You should be able to see what was directly measured, what was joined, what was modeled, which window and rules were applied, and where uncertainty remains. If that chain cannot be reproduced, treat the revenue figure as directional.

    Run a bounded pilot with your own query set before making a long-term commitment. Include branded, non-branded, comparison, factual, and action-oriented intents that matter to your audience. Define the preferred page and expected outcome for each cluster in advance. Then inspect whether the tool:

    • captures the platforms and markets you actually care about;
    • shows raw evidence behind its classifications and scores;
    • distinguishes prompts, grounding queries, citations, mentions, and outcomes;
    • lets you correct brand labels and query clusters without losing the original record;
    • turns a visibility gap into a page-level action your team can assign;
    • preserves before-and-after evidence after a change;
    • exports the data required for independent analysis; and
    • explains attribution without hiding the join logic.

    Treat missing raw evidence, unclear denominators, or unusable exports as gating failures when auditability matters. A polished interface can save reporting time, but it cannot repair an unverifiable measurement model.

    Key takeaways

    • Choose an AI search tool for the decisions it improves, not the number of charts it contains.
    • Keep audience intent, user prompts, grounding queries, citations, answer inclusion, visits, and outcomes as separate measurement layers.
    • Split branded retrieval from non-branded discovery before interpreting any aggregate visibility trend.
    • Require every optimization recommendation to name the affected query, target page, diagnosis, proposed change, and validation signal.
    • Judge platform coverage by precise surfaces, markets, collection methods, and raw evidence rather than platform logos.
    • Accept revenue attribution only when you can inspect the chain connecting an AI observation to the business event.

    Your next move can be small. Take one important non-branded query cluster, identify the page that should answer it, and trace the available evidence from grounding query to citation to brand inclusion to outcome. Make one defensible change and preserve the before-and-after record.

    If your current tool cannot support that chain, you now know the capability to look for. If it can, stop watching the aggregate score and start using the evidence to run an optimization queue.

    References


  • How to Turn AI Search Demand Into Measurable Brand Visibility

    How to Turn AI Search Demand Into Measurable Brand Visibility

    Your organic dashboard can look healthy while your brand is missing from the AI answers that shape a buyer’s shortlist. The reverse can happen too: a topic can look small in keyword tools even though people routinely describe the underlying problem to an AI assistant.

    The gap is easy to miss because AI discovery and conventional web analytics do not join cleanly. A buyer might encounter your brand in Gemini, research it later through Google, and eventually arrive through a branded query or direct visit. By then, the AI interaction is largely absent from Search Console and Google Analytics. To make better content decisions, you need a closed loop: identify demand, publish the right kind of asset, measure how AI systems represent your brand, and look for downstream business movement without claiming attribution you cannot prove.

    Separate demand, visibility, and business impact

    Three different questions are often collapsed into one AI visibility score. Keep them separate:

    • Demand: Are people searching for or asking about this topic?
    • Visibility: Does an AI answer include, recommend, describe, or cite your brand?
    • Impact: Does stronger visibility coincide with useful behavior such as branded research, qualified visits, leads, or sales?

    This separation prevents common misreadings. High prompt demand does not mean your brand is visible. A frequent brand mention does not mean the answer recommends you. A citation does not establish that the visitor converted because of AI. Each signal answers a narrower question.

    Use a measurement chain rather than a single blended number. Demand determines which topics deserve attention. Visibility shows whether your content and brand are entering the answer set. Business metrics tell you whether that exposure may be contributing to valuable outcomes. When one link is weak, you know where to investigate instead of treating every disappointing result as a content-quality problem.

    Build one demand map from keywords and prompts

    Blank search tiles, speech bubbles, and geometric intent tokens connect into a single illuminated map of clustered demand themes.

    Keyword research captures concise search behavior. Prompt research captures the longer, conditional questions people bring to ChatGPT, Gemini, Claude, Perplexity, and other assistants. Neither replaces the other. Putting keyword demand and prompt demand in the same working table exposes topics that either signal can miss on its own.

    Build the table in five steps

    1. Start with buyer decisions, not a keyword export. List the category questions, use cases, comparisons, objections, alternatives, pricing concerns, and suitability questions that appear from discovery through decision. Include branded and competitor-led questions, local variations where geography matters, and the follow-up questions a buyer would ask after an initial answer.
    2. Collect traditional search demand. Use Google Ads Keyword Planner and cross-check important topics in a third-party SEO platform such as Semrush or Ahrefs. Keep the keyword, reported volume, intent, market, and data date together.
    3. Collect prompt demand. A prompt-volume product can provide modeled demand and related conversational phrasing. If you do not have one, begin with a qualitative prompt library built from the questions your buyers actually ask, but label it qualitative rather than pretending it is volume data.
    4. Clean each signal on its own terms. Keyword Planner can merge close variants, so do not add near-duplicate rows as if they represent separate demand. Treat prompt-volume estimates as directional: they are useful for comparing broad magnitudes and trends, but their apparent precision should not drive the decision.
    5. Classify the demand shape. Define strong and weak relative to your own topic portfolio. Keyword volume and prompt volume are produced differently, so do not add them together or compare their raw values as if they shared a unit.
    Demand shapeWhat it indicatesBest initial assetPrimary success check
    Keyword-strong, prompt-weakPeople usually express the need as a concise search queryA focused, conventional SEO pageIntent match, rankings, organic engagement, and completeness
    Prompt-strong, keyword-weakPeople tend to describe a situation, constraint, or decision conversationallyAn answer-first explainer, decision resource, or use-case pageAI inclusion, recommendation context, citations, and messaging accuracy
    Strong on bothThe topic matters across search results and AI answersA flagship resource with supporting pagesSearch performance and AI visibility measured separately
    Weak on bothMeasured demand does not yet justify routine productionBacklog, unless customer evidence or strategic importance overrides the toolsDemand validation before a large content investment

    The final row matters. Demand tools are planning inputs, not permission slips. A new product category, a high-value account question, or a recurring sales objection can justify content before aggregated demand appears. Record the reason for the exception so that strategic work does not get confused with demand-led work later.

    Match the content format to the shape of demand

    Once a topic is classified, the content brief should change with it. Applying one universal AEO template to every query creates pages that are easy to scan but poorly matched to the actual decision.

    For keyword-led demand, win the search task first

    A keyword-strong topic still needs a recognizably strong SEO page. Match the title and page heading to the primary intent. Answer the core question early. Study the information the current results reward, then cover the related definitions and questions needed to complete the task. Use descriptive HTML headings, short definition blocks where they help, and clear conclusions near the beginning of each section.

    That structure also gives an AI system usable passages if the topic later develops stronger prompt demand. You do not need to distort a straightforward search page into a sprawling question bank. You need a complete answer with a clear information hierarchy.

    For prompt-led demand, answer the situation rather than the phrase

    A conversational prompt often contains several decision variables: who the buyer is, what they need to accomplish, which constraint matters, and what kind of recommendation they want. A page targeting only the short category phrase may never resolve that full situation.

    Build prompt-led content around the answer a qualified reader needs:

    • State the direct answer before the background.
    • Define the conditions under which the answer changes.
    • Name the buyer, use case, market, or product scope to which each claim applies.
    • Provide decision criteria that can distinguish suitable options.
    • Resolve likely follow-up questions instead of treating every wording variation as a separate page.
    • Keep product names, capabilities, positioning, and comparisons current so an extracted answer does not repeat stale information.
    • Support important claims on the page that you would want an AI response to cite.

    Do not create a thin page for every long prompt. Cluster prompts by the decision they are trying to make. If several phrasings require the same answer and evidence, they belong in one strong resource. Split them only when the audience, recommendation, or required evidence materially changes.

    For strong demand on both surfaces, build the flagship

    A topic with meaningful keyword and prompt demand deserves more than a long page assembled from loosely related questions. Give it a clear search target, an answer layer for common decisions, substantive evidence, and supporting pages for narrower use cases or comparisons. Keep one canonical resource at the center so your own pages do not compete to define the topic differently.

    A practical brief for any of these assets should include:

    • The topic’s demand classification and the data date.
    • The keyword cluster and search intent.
    • Representative first-turn prompts and follow-up prompts.
    • The audience, decision stage, use case, and relevant market.
    • The direct answer the page must earn the right to give.
    • The claims that require evidence or regular review.
    • The brand facts and differentiators that must remain accurate.
    • The pages you want cited, where those pages genuinely support the answer.
    • The measurement prompts that will be checked after publication or revision.

    The last item closes an operational gap. If the content team publishes without defining the prompts that would demonstrate improved visibility, the measurement team has to reconstruct the strategy afterward.

    Measure AI visibility as a pattern, not a ranking

    Several transparent lenses show different arrangements of source blocks around the same central brand object, with their light trails forming a combined pattern.

    There is no dependable single position called a Gemini ranking. Responses can change with follow-up questions, location, conversation history, personalization, and model updates. Opt-in personalization can also draw on signals from Google products such as Gmail, Photos, and Search. Two people can therefore receive meaningfully different competitive sets for similar questions. Your goal is to observe patterns across a controlled set of prompts, not celebrate or panic over one answer.

    Create a prompt panel you can repeat

    Organize prompts by platform, market, buyer stage, and intent. Your panel should cover category discovery, use cases, comparisons, branded evaluation, alternatives, decision objections, and location-dependent needs where relevant. Keep clean first-turn prompts separate from multi-turn conversation paths. A brand omitted from the opening response may appear only after the buyer adds a constraint or asks for a recommendation.

    For each test, preserve the exact wording and record the conditions that could affect the answer: platform, date, language, location, signed-in or signed-out state, visible model label, and whether prior conversation context was present. Consistency does not recreate every customer’s experience. It gives you a stable observation panel for directional comparisons.

    Record more than a yes-or-no mention

    A mention can be favorable, incidental, inaccurate, or actively disqualifying. Capture enough context to tell those outcomes apart:

    • Brand included: Was the brand named at all?
    • Recommendation status: Was it recommended for the stated need, merely listed, or mentioned as a poor fit?
    • Position: Where did it appear in a ranked list? If the response was narrative, record its role rather than inventing an ordinal position.
    • Competitors: Which alternatives appeared, and how were they framed?
    • Citations: Which URLs supported the response, and did an owned page receive a citation?
    • Message accuracy: Were the product, audience, capabilities, and positioning current?
    • Follow-up behavior: Did a later constraint add or remove the brand from consideration?

    From those fields, calculate metrics whose definitions remain stable. Inclusion rate is the share of eligible response runs that contain the brand. Recommendation rate counts only responses that actually recommend it for the tested need. Citation frequency tracks how often a page is used as supporting material. Competitive share of voice compares your appearances with the brands in the same prompt set. Keep accuracy as a separate quality measure; a high inclusion rate with outdated messaging is not a win.

    Use a cadence that can reveal change

    Weekly reviews suit highly competitive markets, while monthly reviews are sufficient for most organizations. Use the same cadence for your baseline and later comparisons. Add an annotation when you publish a flagship page, make a major positioning change, or update an important cited URL.

    Manual review remains valuable because it exposes tone, qualifiers, inaccuracies, and citation context. It is practical for dozens of important prompts. When the panel reaches hundreds or thousands, automation becomes useful for consistency and history. Platforms such as Profound, Scrunch AI, Otterly.AI, and Peec AI, along with AI visibility features in Semrush and Ahrefs, can automate repeated prompt checks.

    Evaluate a visibility tool by what you can inspect, not only by its headline score. Check whether it preserves raw answers and citations, separates platforms and markets, retains prompt versions, supports historical exports, and documents the test conditions. Its results will still represent standardized tests rather than every personalized user experience.

    Connect visibility to outcomes without inventing attribution

    The most useful reporting does not stop at answer inclusion. It also does not label every later branded visit as AI-generated. Because Gemini mentions do not appear as a native visibility report in Search Console or Google Analytics, use an evidence stack:

    1. Demand evidence: Which high-priority topic and prompt clusters are you addressing?
    2. Content evidence: What was published, revised, consolidated, or corrected, and when?
    3. Visibility evidence: Did inclusion, recommendation context, citations, competitive position, or accuracy change?
    4. Behavior evidence: Did branded search interest, direct traffic, identifiable AI referrals, engagement with cited pages, or return visits move in the same direction?
    5. Business evidence: Did qualified leads, assisted conversions, pipeline, or sales show a corresponding movement?

    The strength of the conclusion depends on how many links move together and whether another explanation is more plausible. A visibility increase followed by stronger branded research is evidence of contribution, not proof that AI caused every visit. Say that plainly in executive reporting.

    Use the combined data to diagnose the next action:

    • High demand, low inclusion: Check whether you have a page that fully resolves the prompt’s real decision. If you do, inspect the pages AI systems cite and identify the missing evidence, coverage, or brand clarity.
    • Frequent inclusion, weak recommendation: Review how clearly your pages describe fit, differentiators, limitations, and use cases. The brand may be known without being understood as the answer to that need.
    • Good inclusion, inaccurate messaging: Correct the owned pages carrying stale facts. Track the cited third-party pages as a separate reputation and outreach problem rather than assuming an onsite edit will change them.
    • Competitor citations without your brand: Examine what those cited pages substantiate. Build the missing evidence in your own voice; do not simply copy their format or claims.
    • Rising visibility, no useful behavior: Recheck the prompt set. You may be measuring broad awareness questions that do not lead to a meaningful buyer action, or the cited page may provide no sensible next step.
    • Business movement without visible AI referrals: Treat AI exposure as a possible contributor only when the visibility trend and timing support that interpretation.

    A compact operating dashboard should therefore show demand class, prompt coverage, inclusion, recommendation status, citations, accuracy, competitive context, and downstream indicators in adjacent columns. Resist turning them into an opaque composite. A single score hides whether the problem is demand selection, content coverage, brand representation, or conversion.

    AI demand and visibility FAQ

    Can branded prompts prove that people are discovering the brand?

    No. A branded prompt is useful for checking representation: whether the assistant describes your offer accurately, surfaces current information, and handles objections fairly. Discovery should be measured with non-branded category, use-case, comparison, and problem prompts where the brand has not already been supplied.

    Should a mention and a citation count as the same result?

    No. A mention tells you the brand entered the response. A citation identifies a page used to support the answer. Record both, then inspect the context. An uncited recommendation may still be commercially meaningful, while a citation may support a neutral definition that does not recommend the brand.

    Should you rerun a prompt until the brand appears?

    No. Decide the protocol before viewing the result, preserve every eligible run, and compare aggregate patterns. Stopping only when the brand appears creates a flattering but unusable inclusion rate. If you test conversational follow-ups, define that sequence in advance and report it separately from clean first-turn prompts.

    Before commissioning your next content batch, add prompt demand beside keyword demand and create a repeatable visibility panel for the topics you already consider important. The first decision is not how much more to publish. It is which demand you are missing, which answer you need to earn, and which observable change would show that the work mattered.

    References


  • How Brands Earn Visibility and Citations in AI Search

    How Brands Earn Visibility and Citations in AI Search

    Your brand can rank well in conventional search and still disappear from an AI-generated shortlist. When that happens, publishing another broadly optimized article may not solve the problem. The failure could occur before the system searches, while it retrieves evidence, or when it chooses which sources to cite.

    You need to identify that stage before deciding whether to invest in brand building, content, digital PR, technical optimization, or structured data. Treating every visibility problem as a citation problem wastes effort at the wrong end of the process.

    AI visibility passes through three separate gates

    Brand visibility and citation visibility overlap, but they are not interchangeable. A generated answer can mention a brand from prior model knowledge, discover it through live search, cite its own website, or support the recommendation with an independent source. Each outcome reflects a different path.

    • Consideration: Does the brand enter the model’s candidate set when it interprets the question?
    • Retrieval: Does live search find the brand, its content, or independent evidence about it?
    • Citation: Does the system select that evidence to support the answer it ultimately presents?

    The first gate matters more than many content teams assume. Across 3,960 responses to 66 U.S. buyer questions, models searched for brands they were already familiar with 3.2 times as often as unfamiliar brands. Familiar brands appeared in 55.7% of brand searches, compared with 17.4% for brands outside each model’s measured top 10.

    That advantage did not turn every retrieval query into a branded query. Only 31% of 13,281 fan-out searches named a company. When a query did name one, however, 63% involved one of the model’s five most familiar brands. Familiarity therefore appears to shape which companies receive direct investigation, while most of the wider research process still runs through unbranded questions.

    Use those figures as a directional signal, not a universal benchmark. The tests covered a defined set of U.S. buyer prompts and 1,416 brand-level observations. They found a relationship between measured familiarity and search behavior, but did not establish that familiarity caused each search. Some industry slices were based on as few as six prompts.

    This distinction gives you a practical diagnostic. If your brand is never mentioned, work on consideration and external recognition. If it appears but its evidence is not retrieved, improve discoverability and question coverage. If relevant pages are retrieved but competitors receive the citations, improve source fit, specificity, and corroboration.

    Win unbranded fan-out searches before chasing citations

    A glowing sphere branches into many paths leading to clusters of generic products and evidence tiles, with a blue marker appearing in several clusters.

    A buyer may ask for the best platform for a particular workflow, but an AI system can break that request into narrower searches about features, integrations, pricing structure, implementation, risks, alternatives, or suitability. Most of those searches will describe the need rather than name a vendor.

    This creates an opening for a less familiar brand. Live retrieval is not completely confined by model memory. In one documented example, Gemini searched for Lemon Squeezy while evaluating online payment providers even though the company was not present in its measured familiarity set. An unfamiliar brand can still enter through a relevant live search.

    Build your content map from those generic research needs, not from a list of product keywords alone:

    1. Choose a real buyer decision. Define the audience, use case, constraints, and consequence of choosing poorly. A prompt such as “Which platform is best?” is too broad to guide useful coverage.
    2. Break the decision into verifiable subquestions. Include fit, requirements, comparisons, limitations, implementation, and evidence. Keep each question narrow enough that a page can answer it directly.
    3. Inspect the sources that AI answers currently cite. Record the domain, page type, claim supported, and whether the brand behind the source is also recommended. This shows which evidence surfaces are actually entering the answer.
    4. Assign one source of truth to each important claim. Use an owned page for facts you control and seek independent corroboration where a self-published assertion would be weak.

    Do not force the brand name into every heading. A useful unbranded page should answer the generic question even if the reader has never heard of you. Introduce your product only where it genuinely satisfies the stated criteria, and make the connection explicit enough to verify.

    This approach serves both discovery and citation. It gives retrieval systems a relevant page for the unbranded query, while giving the answer generator a bounded claim it can use. A generic thought-leadership page may mention the topic repeatedly without doing either job.

    Segment citation patterns by model, market, and prompt

    There is no dependable universal list of domains that every AI system prefers. Citation behavior changes with the model and the category being researched. A large observational analysis covering 12 billion citations, 29 industries, and eight consumer LLMs found that source preferences differed across model-and-industry combinations.

    Brand familiarity also varied sharply by category. In the tested industries, models searched for familiar brands between 41% and 82% of the time, while unfamiliar brands appeared in 9% to 23% of searches. The small prompt counts in some categories make those ranges unsuitable as targets, but the variation is still a warning against managing AI visibility through one blended score.

    Separate your analysis at three levels:

    LevelWhat to recordDecision it supports
    ModelMentions, cited domains, cited URLs, and answer language for each tested systemWhere visibility is weak and whether one model is distorting the overall result
    Prompt classDiscovery, comparison, implementation, risk, and branded questionsWhich part of the buyer decision your evidence fails to cover
    Market or categoryRelevant publishers, directories, communities, review surfaces, and first-party sitesWhere credible evidence needs to exist outside your own domain
    ClaimThe exact statement supported by each citationWhether the source is helping your brand, merely discussing the category, or contradicting you

    The claim-level view is crucial. A domain may be cited frequently without ever supporting a recommendation for your brand. Conversely, an independent page may improve brand visibility even when your own site receives no link. Count the mention, the cited source, and the supported claim separately.

    Look for repeatable patterns inside each segment. If a model repeatedly cites product documentation for implementation questions, strengthen the relevant documentation. If independent comparisons dominate evaluation prompts, improve the accuracy and availability of third-party information. The point is not to copy a competitor’s backlink profile. It is to place verifiable evidence on the surfaces selected for the decision you want to influence.

    Publish evidence that can survive citation selection

    Verified evidence objects pass through a glowing selection aperture while vague and duplicate source fragments remain outside.

    Retrieval only earns your page an audition. Citation selection still depends on whether the page supplies a clear answer that fits the prompt. Repetition, word count, and schema volume cannot compensate for a claim that is vague, unsupported, or difficult to locate.

    Give every important page a citation-ready core

    A citation-ready passage is not a block written for bots. It is a self-contained answer that a buyer can understand and verify without reconstructing your argument from several pages.

    • Answer the question immediately. Put the direct answer near the relevant heading, then explain the reasoning and exceptions.
    • Name the entity precisely. Use consistent brand, product, and company names. Distinguish similarly named products and explain the relationship between a parent company, platform, and individual offering.
    • State the scope. Identify the audience, plan, product version, location, or use case to which the claim applies.
    • Expose the evidence. Put material facts in accessible page text. Do not make a video, image, downloadable file, or interactive widget the only place where the answer appears.
    • Separate facts from positioning. Replace unsupported superlatives with capabilities, constraints, methodology, and evidence a third party can check.
    • Maintain the claim. Show the relevant date or version when information can change, and update or retire pages that no longer describe the current product.

    These choices do not guarantee a citation. They reduce ambiguity and make it easier for both people and machines to determine what the page actually supports.

    Use JSON-LD to clarify, not manufacture, authority

    Structured data should describe the entity and content already visible on the page. Use the most accurate applicable types, such as Organization for the company, Product or SoftwareApplication for an offering when appropriate, Article for editorial content, and Person for a real author. Keep names, URLs, and relationships consistent with the page.

    Do not mark up claims that readers cannot see, and do not fill sameAs with loosely related profiles. JSON-LD can reduce entity ambiguity. It cannot make an unsupported claim credible, create brand familiarity by itself, or guarantee inclusion in an AI answer.

    Build corroboration beyond your own website

    Your website is the right source for documentation, specifications, policies, and other facts you control. It is not automatically the strongest source for comparative claims about quality, leadership, or market position.

    Compare the independent domains cited for your priority prompts with the places where your brand has an accurate presence. Correct stale descriptions. Supply partners, directories, reviewers, and publishers with verifiable information when there is a legitimate editorial reason to do so. Do not manufacture consensus through duplicate contributed content; repeated wording across low-value pages is not independent corroboration.

    This is where AI visibility connects with brand building and digital PR. Familiarity may help a brand enter consideration, while independent evidence gives retrieval systems something credible to find. Neither replaces the other.

    Measure the visibility funnel and fix its weakest gate

    Key takeaways

    • Measure consideration, retrieval, and citation separately; a failure at one stage calls for a different fix.
    • Test unbranded buyer questions because most observed fan-out searches did not name a company.
    • Segment results by model, prompt class, market, source, and claim instead of trusting one visibility score.
    • Make important answers direct, scoped, accessible, and verifiable before adding more markup.
    • Track third-party citations as brand visibility even when they do not produce a link to your domain.

    A useful measurement system preserves the path from prompt to claim. Without that path, a rising citation count can hide the fact that citations are supporting competitors, irrelevant topics, or outdated descriptions of your product.

    1. Freeze a representative prompt set. Cover the important buyer decisions with both unbranded and branded wording. Keep the wording stable so changes in output are not confused with changes in the test.
    2. Record the full answer. Capture the model, prompt, date, brand mentions, recommendation order, cited URLs, cited domains, and the claim attached to each citation.
    3. Capture retrieval only when it is observable. If a platform exposes fan-out searches, save them. If it does not, mark retrieval as unknown rather than inferring hidden queries from the final citations.
    4. Repeat prompts. Generated answers vary. A single appearance or omission is an observation, not a stable visibility pattern.
    5. Classify the bottleneck. Decide whether the next intervention belongs to entity recognition, unbranded content coverage, technical accessibility, independent corroboration, or citation-page quality.

    Use a simple decision rule when reviewing the results:

    • Never mentioned: strengthen entity clarity, relevant distribution, independent coverage, and category association.
    • Mentioned but absent from observable searches: determine whether the brand is being recalled without current evidence and whether generic fan-out queries expose a content gap.
    • Found but not cited: compare your page with the selected source at the claim level. Check directness, scope, evidence, accessibility, and freshness.
    • Cited through a third party: count the visibility, verify that the description is accurate, and decide whether an owned source should also exist for the underlying fact.
    • Cited with an incorrect claim: correct the source of truth and any external listings you can legitimately update. More mentions of the same error will deepen the problem.

    Start with one commercially important decision, establish its prompt and citation baseline, and identify the first gate where your brand consistently disappears. Fix that gate before expanding the program. The goal is not to accumulate citations in the abstract. It is to make your brand a credible, retrievable answer when a buyer asks the question that leads to a decision.

    References


  • How to Improve AI Search Visibility Without Hurting SEO

    How to Improve AI Search Visibility Without Hurting SEO

    Your pages rank, your product information is accurate, and your team publishes regularly. Yet when a buyer asks ChatGPT, Gemini, Claude, or Perplexity for a shortlist, your brand is missing or described in language you wouldn’t use.

    The fix isn’t to manufacture a page for every prompt. You need to make your strongest knowledge easy to retrieve, extract, verify, and reuse. That improves your eligibility for AI-generated answers while protecting the SEO authority you already have.

    Key takeaways

    • Measure presence, accuracy, evidence, and cited domains separately. A brand mention can still be wrong, unsupported, or irrelevant.
    • Fix crawl barriers and conflicting facts before creating more content. AI visibility cannot compensate for an inaccessible or internally inconsistent website.
    • Give each important question a direct, qualified answer that still makes sense when extracted from the surrounding page.
    • Build reusable content from an approved fact record, then adapt it for the format and context your audience needs.
    • Treat prompt gaps as hypotheses. Publish only when a distinct buyer need, useful evidence, and an appropriate destination justify a new URL.

    Start with an AI visibility baseline

    An analyst studies four unlabeled visual panels showing markers, evidence tokens, source documents, and connected pathways.

    AI visibility isn’t a single ranking. A system can mention your brand but misstate a feature. It can describe you accurately but omit you from the recommendation that matters. It can use your information without displaying your URL. You need a scorecard that preserves those differences.

    DimensionQuestion to answerWhat to record
    PresenceDoes the brand appear for the buyer’s prompt?Mention, omission, shortlist position, and context
    FramingIs the brand described as intended?Category, audience, use case, strengths, and limitations
    AccuracyAre the material claims current and correct?Stale features, conflicting descriptions, and unsupported statements
    EvidenceWhat appears to support the answer?Displayed URLs, named domains, quoted facts, or no visible citation

    Begin by writing the version of the answer you want a qualified buyer to receive. Define your category, intended audience, primary use cases, differentiators, limitations, and strongest proof points. This isn’t advertising copy. It is the reference against which you can identify omissions and factual drift.

    Next, build prompts from real buying decisions rather than keyword variants. Include category discovery, constrained recommendations, use-case questions, comparisons, and objections. A useful set might include prompts shaped like these:

    • Which products help [audience] complete [job]?
    • What should I look for when choosing a [category] for [use case]?
    • Which options meet [meaningful constraint]?
    • Compare [brand] and [competitor] for [specific use case].
    • Is [brand] suitable for [audience or condition]?

    Ask the same buyer questions across ChatGPT, Gemini, Claude, and Perplexity. Save the exact prompt, response, date, system or model shown in the interface, brand framing, factual errors, and displayed citations. If an answer shows no citations, record that instead of inferring where it came from.

    Treat one generated answer as an observation, not a universal rank. Preserve the wording of your prompts and repeat the same method on a consistent schedule and after meaningful changes. Otherwise, you won’t know whether the result changed or the test did.

    Your baseline should produce a gap with a destination:

    • If you appear with stale facts, correct the conflicting information on properties you control.
    • If a competitor appears because an external comparison page is repeatedly surfaced, investigate that domain and the evidence it uses.
    • If your relevant page is accessible but its answer is buried, restructure that page before commissioning another one.
    • If no existing page satisfies a distinct buyer need, consider a new page only after defining what unique information it will add.

    This turns a vague concern about AI into a repair queue. It also prevents the most expensive mistake in AI SEO: producing content before you know whether the gap is technical, editorial, reputational, or external.

    Make your best information retrievable

    Strong Google performance remains useful, but it is no longer the whole retrieval environment. Major AI systems can use search tools to find current pages; Gemini remains shaped by Google Search, while other systems use different search tools and crawlers. The practical question is whether the retrieval systems you care about can reach and understand the page that contains your best answer.

    Audit the URLs that represent your brand, products, categories, and priority use cases:

    1. Confirm that each important page is crawlable by the search engines and AI crawlers your policy allows. Inspect robots.txt and any page-level indexing directives rather than assuming all bots receive the same access.
    2. Put material claims in readable page text. Don’t leave a differentiator, price condition, product limitation, or proof point only inside an image or an interaction that a crawler may not extract.
    3. Use descriptive titles and plain headings. A heading such as “Data retention and deletion” gives readers and retrieval systems more context than “Your information.”
    4. Make product and category pages explicit about the audience, job, constraints, and current capabilities. Clever slogans are poor substitutes for factual descriptions.
    5. Link related pages where the relationship helps a reader continue the task. An implementation page should lead to prerequisites; a comparison should lead to the underlying feature or policy evidence.
    6. Remove or update statements that conflict across product pages, help documentation, company profiles, and other properties you control.

    Resolve contradictions before adding detail

    Conflicting facts create a selection problem. If one page uses an old category, another describes a discontinued feature, and a third targets a different audience, an AI system has several plausible versions of your brand. Adding another polished page doesn’t settle the conflict.

    Create a controlled fact record for statements that affect selection: official name, category, intended users, supported use cases, meaningful limitations, availability, and evidence. Give each fact an owner and a page that should be treated as its maintained destination. When a fact changes, update dependent pages and formats from that record.

    Use schema as clarification, not camouflage

    Structured data should describe what the visible page actually contains. Choose the schema type that matches the page and keep its names, dates, entities, and claims aligned with the human-readable content. For reported news, NewsArticle structured data is a relevant part of the publishing pattern.

    JSON-LD cannot rescue a blocked page, reconcile contradictory claims, or make generic copy authoritative. If markup and visible text disagree, you have created another inconsistency. Fix the content model first, then use schema to make that model explicit.

    Build answers that survive extraction and reuse

    A layered source document passes through a transparent chamber and becomes modular tiles that remain linked to evidence before fitting into several blank answer containers.

    An AI system rarely needs every paragraph on a page to answer a narrow question. It needs the relevant statement, its meaning, its qualifiers, and enough evidence to trust the selection. Your job is to make those parts clear without reducing the page to robotic fragments.

    Give each important question a complete answer unit

    For each priority question, create a passage that remains accurate when lifted out of context:

    • State the answer early, ideally in the opening sentence of the relevant section.
    • Name the subject instead of relying on vague pronouns such as “it” or “this solution.”
    • Carry the important qualifier with the claim. If a capability applies only to a particular plan, region, integration, audience, or workflow, say so in the same passage.
    • Place proof near the claim it supports. Don’t make a reader hunt through an unrelated resource to understand why the statement is credible.
    • Link to the maintained destination for deeper detail, prerequisites, or exceptions.

    This is answer-first writing, not answer-only writing. The direct response helps a busy reader decide whether to continue. The surrounding explanation helps them judge scope, trade-offs, and evidence.

    For long-form material, use an inverted-pyramid structure, an informative summary near the top, descriptive subheadings, highlighted lessons or quotes, and purposeful internal links. These elements make important information easier for people and AI systems to locate. A summary should reveal the useful facts, not tease them.

    Separate the knowledge from its page container

    A durable content operation doesn’t treat the finished page as the only copy of what the organization knows. Keep an inventory of reusable knowledge objects behind it:

    • The approved claim in plain language
    • The entity or product the claim describes
    • The conditions and exceptions that limit it
    • The evidence, quotation, data, or maintained URL that supports it
    • The owner responsible for changes
    • The pages and formats that currently reuse it

    This is the operational value of liquid content. Verified facts, quotations, data, and resources remain intact, but they are no longer locked inside one rigid presentation. The same approved knowledge can support a detailed page, an audio explanation, a video script, an infographic, a slide deck, a briefing, or a social asset.

    Choose the format from the audience’s situation

    Repurposing is useful when the format changes access or comprehension. An audio version can serve someone who cannot read at that moment; a text version can serve someone who cannot listen. A diagram can clarify a relationship that prose makes cumbersome. A short video can demonstrate a process, while a maintained page carries the full qualifications and links.

    AI tools can accelerate conversion into briefings, infographics, quizzes, podcasts, and presentations, but human review remains essential. A polished derivative can still omit a condition, distort a comparison, mismatch a label, or place the wrong value in a visual.

    Treat every transformation as a publication that requires editorial control:

    • Verify names, quotations, figures, labels, and links against the approved fact record.
    • Check that qualifications survived compression.
    • Keep important claims available as text, even when the primary experience is visual or audio.
    • Send corrections back to the shared fact record so the next format doesn’t repeat an error.
    • Retire or update derivatives when the underlying claim changes.

    Scale only what adds evidence or access

    A prompt audit can expose many missing queries. That doesn’t mean you need the same number of new pages. Several prompts may express one underlying need, and your strongest existing URL may already be the right destination.

    The relevant risk isn’t AI-assisted drafting by itself. It is publishing large amounts of thin, repetitive content that offers retrieval systems and readers no compelling reason to select one page over another. Overlapping URLs can also divide internal links, create maintenance conflicts, and blur which page represents the topic.

    Put every proposed page through a decision gate

    • Which buyer decision or task does this page resolve?
    • Can an existing page satisfy that need with a focused update?
    • What information, evidence, or utility will be genuinely new?
    • Which claim makes this page more useful than the material already available?
    • Does this subject belong on your domain, or is an independent industry, review, community, or reference destination more useful to the buyer?
    • Who will maintain the facts when the product, policy, or market changes?
    • How will the page connect to your existing topic structure without competing with a stronger URL?

    If you cannot answer those questions, keep the idea out of production. If the need is real but the information belongs on an established page, update that page. Create a new URL only when it has a distinct purpose and enough substance to remain useful on its own.

    Work on the external evidence AI systems already surface

    Your website is only one part of your AI visibility. When another brand wins a recommendation, record the domains and pages associated with that answer. A competitor may dominate a comparison because a relevant review destination is visible for the question, not because the competitor published more posts.

    Review recurring external destinations for relevance, editorial legitimacy, freshness, and fit with the buyer’s decision. Correct inaccurate profiles you are authorized to manage. Where you do not control publication, pursue inclusion by offering verifiable information or genuinely useful evidence. Don’t fabricate consensus, manipulate community pages, or copy the structure of a cited page without adding value.

    Measure whether the narrative improved

    Use the same prompt portfolio and score each observation against the baseline:

    • Presence: the share of tracked prompts in which your brand appears in a relevant context
    • Accurate framing: the share of appearances that use the intended category, audience, and use case
    • Factual integrity: the number and severity of stale, conflicting, or unsupported claims
    • Recommendation fit: whether you appear when your documented capabilities satisfy the stated constraints
    • Source coverage: which owned and external domains are repeatedly displayed or associated with the answer
    • Content reuse: which maintained pages or knowledge objects support several valuable prompts without spawning duplicate URLs

    Do not collapse these measures into a vanity score too early. An increase in mentions is not a win if the descriptions are inaccurate. A missing mention is not necessarily a failure if the prompt asks for a capability you do not provide. The goal is qualified visibility: being selected for the questions you can answer truthfully and supported by evidence that a buyer can inspect.

    You also cannot force an AI system to cite, phrase, or recommend your brand in a particular way. Optimization improves retrieval eligibility and reduces ambiguity; it does not create editorial control over generated answers.

    For your next working session, capture the baseline before changing a page. Then choose the clearest gap with an addressable cause: a crawl barrier, a contradiction, a buried answer, weak supporting evidence, or an absent external reference. Fix that gap, repeat the same test, and expand only when the result shows what the next investment should be.

    References


  • Agentic Web and AI Commerce: A Practical Visibility Playbook

    Agentic Web and AI Commerce: A Practical Visibility Playbook

    Your next customer may delegate much of the buying journey to an AI agent. The agent can identify options, compare claims, check availability and return policies, and sometimes move toward checkout before the customer opens one of your pages.

    That changes the visibility problem. You still need pages that persuade people, but you also need product facts that machines can find, interpret, verify, cite, and act on without guessing. The practical goal is not to attract every bot. It is to become a reliable candidate when a legitimate agent is helping someone make a decision.

    The customer journey now has a machine in the middle

    On June 3, 2026, Cloudflare CEO Matthew Prince said bots had reached 57.5% of HTTP traffic. That was the first reported point at which automated traffic exceeded human traffic. It does not mean 57.5% of your prospects are AI shoppers: HTTP traffic also includes search crawlers, monitoring systems, integrations, security tools, scrapers, and malicious automation. It does mean that treating every non-human request as irrelevant background noise is no longer workable.

    The interface is changing too. Chrome auto-browse launched on Android in late June 2026, putting browser-based task automation closer to ordinary users. In commerce, Google expanded AI Max to Shopping campaigns in April 2026, while Perplexity and Amazon were fighting in federal court over agentic checkout. Discovery, recommendation, advertising, and transaction execution are beginning to overlap.

    A conventional funnel assumes that a person searches, visits, evaluates, and converts. An agentic journey can compress or rearrange those steps:

    Journey stageWhat the agent needsWhat you must provideTypical failure
    DiscoveryA clear match between a request and an offeringExplicit category, use-case, audience, and availability informationThe page relies on slogans or images to explain what the product is
    EvaluationComparable facts and evidenceSpecifications, constraints, policies, and support for important claimsCritical facts are vague, buried, or inconsistent
    RecommendationA defensible reason to include the brandDistinctive, verifiable claims on stable URLsThe agent can find the brand but cannot justify recommending it
    ActionCurrent price, inventory, terms, and a safe handoffSynchronized offer data and controlled transaction stepsThe recommendation is correct, but the offer or checkout state is stale

    This gives you a useful diagnostic. If agents cannot find you, investigate discovery and crawlability. If they find you but omit you from recommendations, improve the clarity and support behind your claims. If they recommend you but orders fail, fix offer synchronization and the transaction handoff. Those are different problems and should not be placed in one generic AI visibility metric.

    Make your claims citable before you make them clever

    Traditional SEO often starts with the query and the page that should rank for it. Agentic search adds another question: what exact statement could an answer engine safely carry from your page into its response?

    A citation-ready claim is specific enough to quote or paraphrase, supported on the page, and qualified so that its limits are clear. A phrase such as best for modern teams gives an agent little usable information. A statement that identifies the type of team, the task, the relevant capability, and any compatibility limit gives it something it can evaluate.

    Build a claim inventory for each commercially important product or service. Record:

    • The claim: the precise fact you want an agent to understand or cite.
    • The evidence: the specification, policy, certification, methodology, documentation, or other support behind it.
    • The qualification: the region, plan, product version, customer type, configuration, or condition to which it applies.
    • The canonical URL: the stable page that should represent the fact.
    • The owner: the person or team responsible for correcting the claim when the product or policy changes.

    Then check whether the supporting page answers the obvious follow-up questions. A compatibility claim should identify compatible versions or models. A delivery claim should name the relevant location and conditions. A feature claim should distinguish what is included from what requires another plan, integration, or configuration. Removing ambiguity is usually more valuable than adding another paragraph of promotional copy.

    Give each important fact one authoritative home. Product pages, help documentation, comparison pages, merchant feeds, and policy pages can serve different purposes, but they should not disagree about the same fact. If a returns page says one thing and a product page says another, an agent has no reliable way to decide which version represents your current policy.

    Comparison content deserves particular care. Use consistent criteria, disclose material limits, and support claims about competitors. An unsupported comparison may create reputational or legal exposure, and machine-readable formatting only makes the unsupported statement easier to distribute. When you cannot verify a comparison, remove it or narrow it to facts you can substantiate.

    Turn each product page into an agent-readable record

    A generic product is surrounded by connected visual modules for dimensions, materials, inventory, shipping, returns, security, and supporting evidence.

    An attractive product page can still be difficult for an agent to use. Important information may be rendered only after interaction, represented only in images, mixed across variants, or contradicted by a feed. Treat the page as both a sales experience and a current product record.

    Start with the visible page. State the product name, brand, intended use, major specifications, variant, price and currency, availability, compatibility, shipping constraints, warranty, and return conditions wherever those facts apply. Do not force a crawler to infer a product’s purpose from a hero image or decode basic terms from a promotional slogan.

    Then use applicable structured data, including Product and Offer markup, to express the same facts in a machine-readable form. Include stable identifiers such as SKU or GTIN when they genuinely exist. Keep variant-specific values attached to the correct variant. A structured price for one configuration must not sit beside visible copy describing another.

    JSON-LD is a consistency layer, not an override switch. It cannot make an unsupported claim trustworthy, and it does not guarantee a citation, recommendation, ranking, or sale. Its value comes from making facts explicit while agreeing with the content a customer can see.

    Audit the product record in this order:

    1. Resolve identity. Confirm that the canonical URL, product name, brand, identifiers, and variant names refer to one unambiguous item.
    2. Resolve the offer. Compare the visible price, currency, availability, promotion terms, feed values, and structured data. Correct disagreements rather than choosing whichever representation is easiest to edit.
    3. Expose decision facts. Put specifications, compatibility, included items, exclusions, and material limitations in crawlable text.
    4. Connect supporting evidence. Link claims to the relevant policy, documentation, methodology, or certification page using descriptive anchor text.
    5. Check access. Verify that essential public information does not require a login, consent interaction, search form, or unsupported script execution.
    6. Assign freshness. Give volatile fields such as price, availability, promotions, and delivery terms a clear system of record and an update path.

    Do not solve agent access by removing every bot control. Separate public discovery from sensitive actions. Legitimate crawlers may need access to product and policy pages; they do not need unrestricted access to accounts, carts, checkout endpoints, or customer data. Use crawl rules, rate controls, authentication, and abuse monitoring according to the sensitivity of each surface.

    Design the transaction handoff for errors and consent

    A human hand confirms an AI-assisted checkout at a secure gate while inventory and payment errors branch into separate recovery paths.

    Being cited is not the same as being purchasable. An agent can recommend the correct product and still fail because inventory changed, a promotion expired, a variant was ambiguous, or checkout required information the agent did not have.

    If you expose cart or checkout actions to automated agents, design for mistakes before you optimize for speed. The safe path should include:

    • Stable identifiers: pass product, offer, and variant IDs rather than relying on a product name that may match several configurations.
    • Final validation: recheck price, inventory, quantity, delivery eligibility, and material terms immediately before an order is committed.
    • Explicit authorization: distinguish permission to research, permission to prepare a cart, and permission to place an order. One should not silently imply the next.
    • Complete cost disclosure: present the amount, currency, recurring terms where applicable, shipping charges, and other required costs before final approval.
    • Duplicate protection: make retries safe so that a timeout or repeated request does not create multiple orders.
    • Auditable records: retain the selected item, agreed terms, authorization event, and resulting order state so that an error can be investigated.
    • A human-readable exit: give the customer a receipt and a clear route to review, correct, cancel, return, or request support under the applicable policy.

    These controls matter because a conversational confirmation can be ambiguous. A customer may approve a shortlist without intending to authorize payment. Product design, transaction terms, and applicable law determine what constitutes valid consent, so involve legal and payment specialists before allowing an agent to make binding purchases on a customer’s behalf.

    You do not need agentic checkout to benefit from agentic discovery. A controlled handoff to a prefilled cart, product page, booking flow, or sales representative may be the right boundary. Choose that boundary deliberately based on purchase value, reversibility, product complexity, identity requirements, and the cost of an erroneous transaction.

    Measure whether agents can find, cite, and act

    Raw bot traffic is not an AI commerce KPI. It mixes useful discovery with ordinary crawling, integrations, monitoring, and abuse. A useful measurement plan starts with the decisions you want agents to support.

    Create a fixed set of prompts around real buying tasks. Cover problem discovery, category selection, product comparison, compatibility, policy questions, and purchase intent. For each test, record the prompt, engine or interface, date, locale, answer, brands mentioned, claims made, citations shown, and whether the cited page supports the answer. Keep the wording and conditions stable enough to compare results after a content or data change.

    Report the journey as separate layers:

    • Findability: can the system retrieve and correctly identify the brand, product, and relevant page?
    • Citation coverage: does the brand appear for the buyer questions it can legitimately answer, and are the right URLs cited?
    • Representation accuracy: are product capabilities, limitations, prices, availability, and policies described correctly?
    • Recommendation inclusion: does the product enter an appropriate shortlist, and is the stated reason supported?
    • Handoff quality: does the referral land on the correct product, variant, offer, or next step?
    • Commercial outcome: do agent-assisted journeys produce valid orders, qualified leads, cancellations, returns, duplicate attempts, or support issues?

    Do not reduce all of this to one visibility score. A mention with the wrong price is not a success. A citation to an obsolete policy can be worse than no citation. A completed order that the customer did not clearly authorize is a failure even if it appears in revenue reporting.

    Connect changes to specific interventions. When you clarify compatibility copy, watch compatibility prompts and the cited URL. When you synchronize offer data, watch price accuracy and checkout failures. This creates an evidence trail between the work and the result instead of treating every change in AI output as proof of a broad strategy.

    Key takeaways

    • Optimize for a sequence: discovery, verification, recommendation, and safe action.
    • Give important commercial claims a precise statement, supporting evidence, clear qualification, canonical URL, and accountable owner.
    • Keep visible content, structured data, merchant feeds, policies, and transaction systems consistent.
    • Treat bot access as a permissions problem: public facts can be discoverable while accounts and checkout remain controlled.
    • Measure whether agents represent you accurately, not merely whether they mention you or request your pages.

    Start with one commercially important product family. Trace a buyer’s question from discovery to order, note every fact an agent must retrieve, and correct the first ambiguity or contradiction that could stop the journey. That narrow audit will expose more useful work than a site-wide attempt to optimize for an undefined AI audience.

    References


  • AI Search Visibility in 2026: A Practical Operating System

    AI Search Visibility in 2026: A Practical Operating System

    You can keep your blue-link rankings and still lose the moment that matters. If an AI answer resolves the question before a click, the customer may never see your result, visit your site, or encounter the message you worked to rank.

    The 2026 response is not to discard SEO for a new acronym. It is to manage visibility at the answer level: where your brand appears, what role it is given, which claims are cited, and whether the answer moves a qualified buyer toward you. Here is how to turn that into a repeatable operating process.

    Key takeaways

    • Keep technical SEO and organic rank tracking, but add measurement for mentions, citations, recommendations, accuracy, and downstream action.
    • Monitor a fixed portfolio of decision-oriented prompts instead of checking a few flattering questions whenever someone asks for an AI visibility update.
    • Build pages around clear claims, evidence, scope, comparisons, and next steps. Generic prose gives an answer engine little reason to select or cite you.
    • Test across the AI experiences your customers use. A strong result in one engine does not establish visibility in the others.
    • Treat structured data as a machine-readable description of visible facts, not as a switch that guarantees inclusion in an AI answer.

    Reset your definition of search visibility

    AI search is no longer a side experiment that can be represented by one chatbot screenshot. Reported mid-2026 figures put ChatGPT at 900 million weekly active users, Gemini at 900 million monthly active users, and the share of consumers starting searches with AI at 37%. The weekly and monthly figures describe different windows, so they should not be compared as if they were the same metric. The consumer figure is also better treated as directional market evidence than as a forecast for your own audience.

    Google’s AI interfaces add another layer of scale. Reported 2026 reach put AI Mode at 1 billion users and AI Overviews at 2.5 billion. Do not convert those headline counts into a traffic projection. Their practical value is showing that synthesized answers have become an interface you need to manage, not merely a feature to watch.

    A ranking tells you that a page is eligible to be found in a conventional result set. AI visibility asks several additional questions: Was your brand selected for the answer? Was your site cited? Was the description accurate? Were you recommended, merely mentioned, or used as background evidence? Did the answer create a measurable business response?

    Visibility layerQuestion to answerEvidence to capture
    EligibilityCan the relevant page be accessed, rendered, indexed, and understood?Indexing state, canonical URL, rendered content, internal links, and structured data
    SelectionDoes the engine use your brand or page when constructing the answer?Brand mentions, linked citations, quoted claims, and the prompts that triggered them
    RepresentationDoes the answer describe your brand, product, and limitations correctly?Accurate claims, unsupported claims, omitted qualifiers, and conflicting facts
    ConsiderationAre you presented as a relevant option for the user’s decision?Recommendation position, comparison context, alternatives named, and reasons given
    ResponseDoes visibility produce a useful next action?Qualified visits, branded searches, assisted conversions, leads, and sales outcomes

    Your existing SEO dashboard covers part of the eligibility layer. Keep it. Then add the other layers instead of forcing mentions, citations, traffic, and conversions into the familiar language of keyword positions.

    Build a prompt portfolio around real decisions

    Blank symbol-marked cards are grouped around a faceted decision node and connected by colored threads on a studio table.

    A keyword list records phrases. A useful AI visibility program records decisions. The same broad subject can produce very different answers when the user adds a budget, audience, constraint, location, use case, or comparison. That context affects whether your brand is relevant at all.

    Choose prompts from the buyer’s work

    Begin with one product line or service area. Pull recurring questions from sales calls, support tickets, on-site search, paid-search terms, community discussions, and customer research. Convert them into the kinds of decisions a person delegates to an answer engine:

    • Learn: What is the problem, how does it work, and what terminology does the buyer need before evaluating options?
    • Compare: Which approaches or products fit a stated use case, and what trade-offs separate them?
    • Verify: Does a named option support a required feature, integration, market, policy, or technical constraint?
    • Choose: Which options should a buyer shortlist for a specific situation, and why?
    • Act: What should the buyer check, prepare, calculate, or ask before purchasing or implementing?

    Include branded and unbranded prompts, but report them separately. An unbranded prompt tests discovery and consideration. A branded prompt usually tests representation: whether the engine understands what you do, who you serve, how you differ, and where your limits are. Combining the two can make visibility look healthy even when new buyers never encounter you.

    Give every monitored prompt a durable record. Capture the exact wording, target audience, market, decision stage, intended fact, relevant page, engine, account state, location context when applicable, test date, answer, citations, competitors mentioned, and your brand’s role. If you change the wording, save it as a new prompt version. Otherwise, you cannot tell whether the answer changed or the question did.

    Test the environments that can change the answer

    ChatGPT-only monitoring is now an incomplete view of the market. Statcounter’s March 2026 data placed Gemini ahead of Perplexity as the second-largest source of AI chatbot referrals. That movement matters less as a league table than as a warning: engine mix changes, and visibility does not transfer automatically from one answer system to another.

    Track ChatGPT, Gemini, Perplexity, Google AI Mode or AI Overviews where available, and any other answer environment that produces meaningful discovery in your category. Use the same core prompts in each one. Then retain engine-specific prompts only when a platform supports a distinct customer behavior you actually need to measure.

    Account context also matters. Google’s Personal Intelligence reached all U.S. users in 2026, making a single signed-in result especially unsuitable as a universal view of what the market sees. When possible, compare a clean or minimally personalized session with a normal signed-in session. Log the difference instead of averaging it away.

    Do not call one favorable answer a win or one absence a loss. Answers can vary across runs, contexts, and product changes. Your fixed prompt portfolio is what turns those unstable observations into evidence: the same questions, checked under documented conditions, over time.

    Create pages an answer engine can use without guessing

    A page can be comprehensive and still be difficult to use in an answer. The problem is often not word count. It is that the key claim is buried, the subject is unnamed, the scope is unclear, or the evidence sits far from the sentence it supports.

    Build an answer asset, not a keyword container

    Give each important page a primary decision to resolve. Then make its answer inspectable:

    • State the answer early. Name the product, method, audience, or problem directly. Do not make a crawler or a reader infer the subject from pronouns and slogans.
    • Define the scope. Add the market, product version, eligibility rule, date, or use-case qualifier that determines when the claim is true.
    • Attach evidence to the claim. Place the methodology, primary documentation, calculation, policy, or clearly labeled first-party data near the statement it supports.
    • Expose the trade-off. Explain when another approach is more suitable. A bounded claim is easier to trust than a universal claim that collapses under scrutiny.
    • Resolve the next question. Link to the specification, comparison, implementation instructions, pricing context, or contact path that moves the reader forward.

    Write important facts as atomic statements. A reusable fact names its subject and predicate clearly: the product supports a named task; the service is available in a named market; the policy applies under stated conditions. Keep promotional adjectives out of these claim units. An engine cannot verify that something is transformative, seamless, or best-in-class unless you supply a defined comparison and defensible evidence.

    Comparison pages need particular discipline. Use consistent criteria, disclose where an option does not fit, show the date or version when capabilities can change, and link each consequential claim to its evidence. Do not create a matrix merely to insert your brand into every category. A comparison that hides constraints can produce the wrong kind of AI visibility: confident misrepresentation.

    Align structured data, technical access, and entity facts

    JSON-LD can make the page’s declared meaning easier to parse, but it must agree with the visible content. Use the most specific Schema.org type that truthfully describes the page and entity. Organization markup should carry stable identity fields. Article markup should match the visible headline, author, and dates. Product or Service markup should describe attributes actually presented to users. FAQPage markup should represent real, visible questions and answers rather than hidden keyword variations.

    Schema does not create authority, repair weak evidence, or guarantee a citation. Think of it as a consistency layer. If the copy says one thing and the JSON-LD says another, fix the underlying content model instead of adding more properties.

    Run a technical check on every page attached to a high-value prompt. Confirm that the intended URL returns normally, carries the right canonical, is not excluded by a noindex directive, exposes the important content in the rendered page, appears in the appropriate sitemap, and receives descriptive internal links. Review robots policies for search crawlers and AI agents separately. Changing those policies can affect security, infrastructure load, and content-licensing choices, so coordinate with the appropriate technical and legal owners before opening access broadly.

    Then reconcile the facts beyond the page. Your site, company profiles, product documentation, press materials, partner listings, and other maintained public records should agree on the brand name, category, offering, audience, availability, and current capabilities. Remove obsolete claims where you control them. When conflicts cannot be removed, publish a clear, dated statement on the canonical page so the current position is unambiguous.

    Use a scorecard that shows what to fix next

    A hand adjusts an unlabeled modular control console with lenses, evidence links, indicator lights, and decision-path components.

    AI visibility is not one percentage. A composite score can be useful for an executive trend line, but it should never replace the underlying measures. Presence, citation, accuracy, consideration, and business response fail for different reasons and require different owners.

    Keep the underlying measures separate

    • Presence rate: the share of eligible monitored prompts whose answers mention your brand. Report it by engine, intent, market, and branded versus unbranded prompt.
    • Owned citation rate: the share of checked answers that link to a page you control. Also record when your brand is mentioned but a third party receives the citation.
    • Representation accuracy: the share of captured brand claims that are supported, current, and correctly qualified. Flag harmful errors separately so they are not diluted by many harmless statements.
    • Consideration rate: the share of relevant choice or comparison prompts where your brand is recommended or shortlisted, not merely named in passing.
    • Qualified response: the visits, branded searches, assisted conversions, leads, or revenue events connected to AI discovery. Keep unattributed traffic separate rather than assuming that every direct visit came from an answer engine.

    Save the answer itself alongside the score. A mention classified as positive can still contain an outdated limitation. A citation can support a competitor rather than you. A recommendation can target the wrong audience. The captured language is what lets a content, product, PR, or legal owner understand the actual failure.

    Diagnose the failure before editing the page

    • If you are absent across engines, first check relevance, access, entity clarity, and whether you have a page that directly resolves the monitored decision.
    • If you are mentioned without an owned citation, improve the page that should substantiate the claim. Make its answer, evidence, scope, and identity clearer.
    • If the answer is wrong, locate conflicting public facts before adding new copy. More content will not resolve a contradiction if the obsolete version remains prominent.
    • If you are cited but not considered, inspect the role your page plays. Informational authority does not automatically establish product fit; a comparison or use-case gap may remain.
    • If visibility produces visits but no useful action, check prompt intent, landing-page continuity, and the next step. The engine may be sending curious researchers rather than qualified buyers.
    • If results swing between checks, expand the run history and segment by environment. Do not present volatility as a durable gain or loss.

    Turn monitoring into an operating cadence

    Run the fixed prompt portfolio on a regular schedule and preserve exact outputs. Review misses in a recurring working session. Group them by failure layer, assign an owner, change the smallest relevant asset, and rerun the affected prompts after the update is available. Revisit the portfolio when customer questions, products, markets, or engine interfaces materially change.

    Ownership should follow the failure. SEO owns crawlability, indexation, internal discovery, and page targeting. Content owns answer structure and claim clarity. Product and legal owners validate changing capabilities, restrictions, and policies. PR and reputation teams address contradictory or weak external representation. Analytics connects exposure to qualified response.

    This cross-functional model is already becoming part of mainstream marketing operations. More than 750 marketing leaders gathered for 13 sessions in April 2026 focused on strategy, team structure, and measurement in the AI era, with companies including OpenAI, LinkedIn, Figma, Webflow, Reddit, Expedia, Stripe, G2, and others represented. The useful signal is organizational: AI visibility touches too many systems to remain an occasional SEO report.

    Start with one commercially important product line, a stable prompt sheet, and one accountable owner for the evidence log. Repair the highest-intent inaccurate or absent answer first, then verify whether the change affected selection, representation, and response. That gives you a working AI visibility loop instead of another dashboard nobody knows how to act on.

    References


  • AI Search Visibility: A Strategy for Mentions and Demand

    AI Search Visibility: A Strategy for Mentions and Demand

    Your organic traffic can fall while your brand’s influence grows. The reverse can happen too. An AI answer may use your page as evidence without naming you, mention you without linking, or cite you before recommending a competitor. If your dashboard labels all three outcomes “AI visibility,” you won’t know what to fix.

    Your real job is to make your brand an easy, defensible choice and then measure whether it becomes one across repeated buying and research questions. That requires a different operating model from conventional rank tracking.

    Optimize for selection, not a familiar search position

    Classic SEO usually gives you a visible sequence: ranking, impression, click, session, conversion. AI search can compress that sequence into a generated answer. The user may finish the task without visiting a site, so a click-only report can miss the moment when your brand entered or left the consideration set.

    The scale and shape of the behavior have already changed. AI Mode reached 1 billion monthly active users, with queries around three times longer than classic searches. Longer prompts often contain the user’s situation, constraints, and desired outcome. They give an answer engine more room to compare options and make a recommendation rather than return a generic list of links.

    Whether your team calls the work AEO, GEO, or AI Visibility Optimization, separate these outcomes:

    • Citation: Your domain or page is linked as supporting evidence.
    • Mention: Your brand, product, or expert is named in the answer.
    • Shortlist inclusion: Your brand appears among the options a user is invited to consider.
    • Recommendation: The answer explicitly presents your brand as a suitable or preferred choice for the user’s conditions.
    • Accurate representation: The answer describes your offer, audience, strengths, limits, and availability correctly.

    A citation can help even when your brand isn’t named, because it supplies evidence to the answer. But a commercial brand usually gains more from being named accurately and recommended in the right context. A publisher may place more weight on citations and referred sessions. A software vendor, retailer, professional service, or local business should usually place more weight on shortlist inclusion, recommendation, and representation.

    Position still matters, but it isn’t the whole decision. Close to 75% of consumers in the reported behavior data chose the first option in an AI shortlist. A trusted brand appearing elsewhere on the list could nevertheless override that position. That gives you two distinct jobs: improve the likelihood of being selected by the system and build enough recognition that the user selects you even when you aren’t listed first.

    Define the business outcome before choosing an AI visibility metric. If you need discovery, track qualified mentions. If you need consideration, track shortlist inclusion and context. If you need authority or publisher traffic, track citations. If you need sales, connect recommendation exposure to branded demand, assisted conversions, qualified opportunities, and revenue without pretending every correlation is causal.

    Measure a prompt panel, not a single artificial rank

    Multiple blank query tiles feed signals into a transparent instrument that separates them into several distinct visibility outcomes, while one isolated pedestal sits apart.

    An AI answer isn’t a stable search result. Engine choice, model changes, reasoning settings, personalization, prompt wording, and stochastic variation can all change the output. Citation overlap is especially fragmented: 91% of citations appeared in only one of ChatGPT, Perplexity, or AI Overviews. A win in one surface doesn’t prove broad visibility, and one missing mention doesn’t prove that your optimization failed.

    Treat prompt monitoring more like recurring audience research than a daily position check. You are estimating how often and how favorably your brand appears within a defined set of decisions.

    Build the panel in this order:

    1. Start with a real decision. Use the questions that precede a purchase, sign-up, visit, specification, or vendor shortlist. A vague informational prompt may generate volume but reveal little about commercial visibility.
    2. Create prompt families. Cover category discovery, use cases, constraints, alternatives, comparisons, risk questions, and branded validation. Keep the intent stable while varying natural phrasing.
    3. Separate surfaces. Record ChatGPT, Perplexity, AI Overviews, AI Mode, or any other relevant experience independently. Don’t average unlike interfaces into one score.
    4. Preserve the conditions. Save the exact prompt, date, engine or mode, login state, relevant location, response, citations, and model details when they are visible. Without that record, a later difference is impossible to interpret.
    5. Repeat the sample. Compare distributions across the panel and over time. Don’t turn one favorable answer into a success claim or one unfavorable answer into a crisis.

    Your scorecard should answer different questions rather than collapse everything into a proprietary visibility number.

    SignalQuestion it answersPractical recording rule
    Mention rateAre we present?Share of eligible sampled answers that name the brand or product.
    Recommendation rateAre we endorsed?Share that explicitly recommends the brand for the stated need.
    First-choice shareDo we lead shortlists?Share of ordered shortlists in which the brand appears first.
    Citation rateIs our site used as evidence?Share of answers with citations that link to your domain.
    Context qualityWhy are we being named?Code each appearance as supportive, neutral, cautionary, or excluding, and retain the exact surrounding sentence.
    Representation accuracyCan a buyer rely on the answer?Check material facts such as audience, capabilities, limitations, location, availability, and pricing model when public.
    Competitor outcomeWho wins the same decision?Record the competing brands, their order, and the reason the answer gives for selecting them.

    Keep the raw responses. A rising mention rate can conceal deteriorating context, such as repeated descriptions of your product as an unsuitable option. Conversely, a lower citation rate may be less concerning if recommendation rate and qualified branded demand are rising. The underlying answer explains what the aggregate metric cannot.

    Give answer engines evidence they can use and reconcile

    You can’t force a model to cite or recommend you. You can reduce the work required to understand your entity, verify your claims, and match your offer to a specific need. That starts with information quality, not a new acronym.

    Make the owned-site answer explicit

    Pages built to satisfy a keyword can still be poor inputs for an answer engine. A long introduction, repeated category language, and an implied conclusion make the useful information expensive to extract. Content intended for AI discovery should lead with distinctive information, use direct language, remove filler, and remain fast and easy to access.

    Audit commercially important pages for the following:

    • A direct answer: State what the product, service, or page is for near the beginning. Don’t make the reader infer the category from marketing language.
    • Decision criteria: Explain who it is for, when it fits, when it doesn’t, what it requires, and how it differs from plausible alternatives.
    • Distinctive evidence: Publish facts only you can supply, such as original data, documented methodology, product specifications, implementation requirements, limitations, or clearly attributed expert knowledge.
    • Claim support: Put evidence close to the claim it supports. Avoid sending a machine or reader through several pages to determine whether a statement is substantiated.
    • Entity consistency: Use the same official names and material facts across product, company, author, location, support, and policy pages. Resolve outdated descriptions rather than letting contradictory versions coexist.
    • Accessible delivery: Keep essential text in crawlable HTML, return the correct status code, use coherent canonical URLs, provide internal links, and avoid placing the only useful answer behind an interaction a crawler may not complete.

    Structured data belongs in this system, but it has a limited role. Use relevant schema types such as Organization, Product, Service, Article, or FAQPage only when the visible page supports them. Keep names, identifiers, authorship, dates, offers, and relationships consistent with the page. Valid JSON-LD can reduce ambiguity; it cannot manufacture trust, replace missing evidence, or guarantee a mention.

    Build a corroboration footprint beyond your domain

    The low citation overlap between engines makes a one-domain strategy brittle. Different systems may assemble answers from different parts of the web, even when responding to similar prompts. Your brand therefore needs consistent, verifiable representation in the places relevant audiences and systems are likely to encounter it.

    Create a claim ledger for the facts that influence selection: what you offer, which audience you serve, where you operate, what differentiates the offer, what limitations apply, and which evidence supports each claim. Then check your site, public profiles, partner listings, documentation, interviews, reputable editorial coverage, and other legitimate references for contradictions. Correct records you control and pursue clarification where an important third-party description is materially wrong.

    Don’t try to create a large volume of shallow mentions. Repetition without independent substance can multiply inconsistent claims. Concentrate on accurate descriptions in contexts that help a buyer make the same decision represented by your prompt panel.

    Connect AI visibility to demand without inventing attribution

    Glowing visibility signals cross a layered bridge, merge with other paths, and reach people comparing unbranded products.

    Referral sessions are useful, but they aren’t a complete denominator for AI impact. A generated recommendation can lead to a later branded search, a direct visit, a marketplace search, or an offline conversation. The original answer may receive no conversion credit.

    Behavior also differs by surface. Users in AI Overviews tend to click, evaluate, and compare in a pattern closer to conventional search. In AI Mode product interactions, users accepted the recommendation as the best available option 88% of the time in the reported behavior data. That finding shouldn’t be treated as a universal rate for every audience or prompt, but it shows why an AI Overview click-through rate and an AI recommendation rate do not measure the same behavior.

    Report AI search through three connected layers:

    • Answer visibility: Mentions, recommendations, shortlist positions, citations, context, accuracy, and competitor outcomes from the prompt panel.
    • Audience response: AI referral sessions, branded search demand, direct visits, engaged visits to relevant landing pages, return visits, and on-site actions associated with the same topic.
    • Commercial outcomes: Qualified leads, assisted conversions, opportunities, sales, retention signals, or another business result appropriate to the decision.

    Use a shared topic or decision label across these layers. If you improve evidence for an enterprise-security question, compare it with the matching prompt family, related landing pages, branded query patterns, and qualified opportunities. A sitewide traffic total is too broad to show whether that work mattered.

    For a defensible evaluation, record the date and scope of each content, schema, technical, digital PR, or positioning change. Establish the prompt-panel baseline before the change. Compare the targeted prompt family with an untreated topic where possible, then inspect answer visibility and downstream behavior over the same period. Model updates and outside campaigns can still affect the result, so label the conclusion as directional unless you have a credible control.

    Present value as a range rather than a single overconfident ROI figure. The lower bound can include directly attributable conversions from identifiable AI referrals. A broader view can include assisted journeys and qualified branded demand that coincide with stronger recommendation visibility. Set those figures beside the cost of research, content, technical work, distribution, and monitoring. Keep observed value separate from inferred value so decision-makers can see where the uncertainty sits.

    This is why AI optimization behaves like a brand channel even when the team manages it like performance marketing. The system’s recommendation can shape demand before your analytics platform sees a session. Measurement must preserve that influence without claiming causation the data cannot support.

    Key takeaways for your next visibility cycle

    • Choose the outcome that fits your business: citation, mention, shortlist inclusion, recommendation, accurate representation, or a defined combination.
    • Track a stable family of commercial and informational prompts across each relevant AI surface. Evaluate distributions, not isolated answers.
    • Record context and competitor reasoning alongside presence. Being named for the wrong reason is not a visibility win.
    • Publish direct, distinctive, supported information and make it technically accessible. Remove contradictions across pages and public profiles.
    • Use structured data to clarify entities and relationships, not as a promise of citations or recommendations.
    • Connect answer-level changes to matched audience and commercial indicators. Distinguish directly observed value from inferred influence.

    Start with one commercially important decision your buyers already face. Build its prompt family, establish the baseline across the relevant surfaces, and identify the exact reason competitors are selected. Improve the content, evidence, entity data, or corroboration tied to that reason, then sample the same panel again before expanding the program. That gives you a strategy you can learn from, rather than a visibility score you can only watch.

    References