Tag: Citations

  • Microsoft Copilot Search Optimization: A Practical Guide

    Microsoft Copilot Search Optimization: A Practical Guide

    You can rank well in conventional search and still be absent when Microsoft Copilot assembles an answer. The missing piece is usually not another round of keyword insertion. It is whether the right page can be found, understood as a complete answer, supported by credible evidence, and selected as a useful citation.

    That gap deserves attention because Microsoft Copilot has been reported to send more AI referral traffic than any LLM except ChatGPT. The practical goal is not to manipulate a model. It is to make your best information easier for a search-grounded assistant to retrieve, interpret, verify, and cite.

    Key takeaways

    • Confirm that the intended page is publicly accessible, indexable, internally linked, and presented as the canonical version before changing its copy.
    • Optimize for the complete question behind a Copilot prompt, including the reader’s constraints, decision, and required evidence.
    • Write self-contained answer passages that remain clear when extracted from the surrounding page.
    • Use JSON-LD to describe visible entities and relationships accurately. Treat it as disambiguation, not a citation switch.
    • Build third-party corroboration around the claims and entities you want Copilot to associate with your brand.
    • Measure citation presence, citation accuracy, identifiable referral traffic, and business outcomes separately.

    First earn retrieval, then compete for the citation
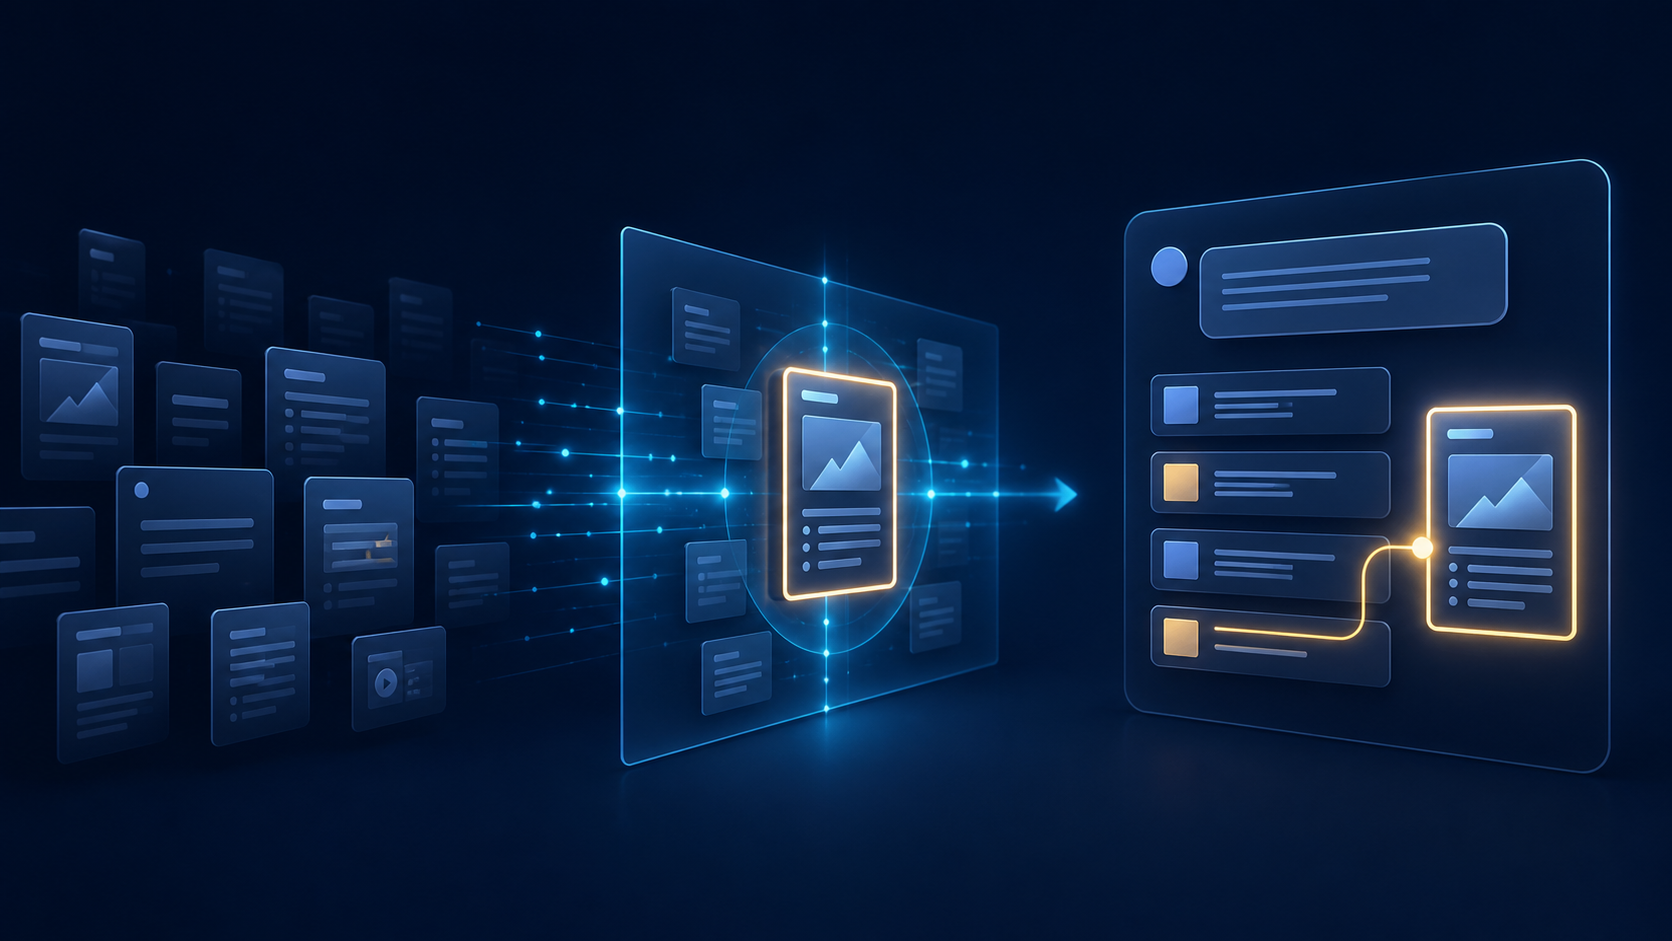
    Digital document library with one group retrieved and a single source selected and connected to an answer panel.

    Microsoft Copilot optimization is easier to manage when you separate four jobs: retrieval, interpretation, confidence, and citation. This is an audit framework, not a claim about a secret ranking formula.

    1. Retrieval: Can the search layer discover and access the intended URL?
    2. Interpretation: Can it identify the page’s subject, entities, answer, and scope?
    3. Confidence: Are important claims supported, qualified, current, and consistent with other credible information?
    4. Citation: Does the page contain a passage worth presenting to a user as evidence?

    This sequence matters. A polished answer cannot be cited if the page is blocked, orphaned, duplicated under competing URLs, or dependent on an interaction before its main content appears. Likewise, technical eligibility does not make a vague or unsupported page citation-worthy.

    Remove technical ambiguity

    Begin with the URL you actually want Copilot to cite. Audit that URL rather than assuming the most attractive page is also the version a search system sees.

    • Make the page available without a login, form submission, location gate, or other mandatory interaction.
    • Check robots directives and page-level indexing instructions for accidental exclusions.
    • Return a successful response and avoid redirect chains that leave several versions of the same content in circulation.
    • Use a self-referencing canonical when the page is the preferred version. Point genuine duplicates to that same canonical.
    • Place the substantive answer in rendered page content. Do not leave it exclusively inside an image, downloadable file, or script-dependent interface.
    • Link to the page from relevant navigation, category, hub, and supporting pages using descriptive anchor text.
    • Include the preferred URL in your sitemap and remove obsolete URLs after their redirects and canonicals are settled.
    • Check whether Microsoft’s search ecosystem recognizes the intended URL and inspect any reported crawl or indexing problems.

    Watch for content cannibalization. If a glossary entry, old blog post, product page, and support page all answer the same question differently, a retrieval system has to choose among conflicting candidates. Give each page a distinct job. Consolidate material when the distinction is artificial, and use internal links to make the authoritative answer obvious.

    Map prompts to decisions, not just keywords

    A conventional keyword often describes a topic. A Copilot prompt is more likely to describe a task with conditions attached. Someone may want a definition, a comparison, a troubleshooting path, an implementation plan, or a recommendation that fits a particular constraint. A page that merely repeats the topic can miss the actual decision.

    Build a prompt map for every commercially important subject. Record the question in the reader’s language, the decision behind it, the constraints that can change the answer, the evidence a responsible answer needs, and the page that should own the response. Then group prompts that can be satisfied by the same underlying page.

    • Definition prompts need a precise meaning, boundaries, and a concrete example.
    • Comparison prompts need consistent criteria, material differences, and guidance on which option fits which situation.
    • How-to prompts need prerequisites, ordered actions, decision points, and a way to verify completion.
    • Troubleshooting prompts need observable symptoms, likely causes, safe checks, and corrective actions.
    • Evaluation prompts need requirements, limitations, evidence, and a clear explanation of tradeoffs.

    Choose one dominant job for each page. A page can answer supporting questions, but it should not drift between an educational explanation, a product pitch, and an unrelated industry commentary. That mixture weakens the passage Copilot needs to extract and the next step a human visitor needs to take.

    Write passages that still work when lifted from the page

    AI citations are selected at the passage level even when authority and relevance are evaluated more broadly. Your page therefore needs useful blocks of text, not just an optimized title and a long narrative that reveals its answer near the end.

    Put the direct answer immediately after the heading that introduces the question. Follow it with the mechanism, qualification, evidence, and action. This does not mean every paragraph should sound like a dictionary entry. It means the reader should not have to assemble the central answer from several distant sections.

    Apply the standalone passage test

    Copy a candidate paragraph into a blank document and ask whether it still makes sense. A citation-ready passage should identify its subject, answer a recognizable question, preserve any important limitation, and avoid pronouns whose meaning depends on an earlier paragraph.

    Weak copy says that a solution is faster, better, or more accurate. Strong copy identifies what is being compared, which measure is relevant, where the claim applies, and what evidence supports it. If you cannot substantiate a superlative, remove it. Repetition does not turn a marketing claim into evidence.

    • Use headings that name the question, outcome, or distinction addressed below them.
    • Define an unfamiliar term when it first appears, then use the same term consistently.
    • Keep the actor, action, object, and qualification together when splitting them would change the meaning.
    • Use ordered lists for procedures and unordered lists for criteria. Use tables only when readers genuinely need to compare the same attributes across alternatives.
    • Label examples as examples. Do not let a hypothetical scenario look like a documented result.
    • Separate established facts from interpretation, recommendations, and predictions.
    • Link claims to the most direct evidence available rather than to a page that merely repeats the claim.
    • Show an update date when substantive information changes, but do not refresh a date without refreshing the content.

    Original information is especially useful when it is documented well enough to inspect. If you publish a benchmark, dataset, framework, or technical finding, explain the method, definitions, sample boundaries, and limitations on the same page or on a clearly linked methodology page. A result without a method may be quotable, but it is difficult to evaluate responsibly.

    Make the cited visit worth earning

    A complete answer and a useful landing page are not opposites. Give Copilot a concise factual passage, then give the visitor something the generated answer cannot conveniently contain: a decision framework, template, calculator, full comparison, implementation detail, primary evidence, or clearly defined next action.

    Match that next action to the prompt. A reader seeking a definition may need a deeper explainer. A reader comparing approaches may need specifications or selection criteria. A reader troubleshooting a problem may need a diagnostic sequence. Sending every visitor to the same generic sales request wastes the context that brought them to you.

    Make entity evidence consistent on and beyond your site
    A central unbranded business connected to matching website, location, profile, directory, and document cards.

    Clear prose tells Copilot what a page means. Structured data makes important entities and relationships explicit. Independent coverage can then provide corroboration outside your own domain. These layers should agree with one another.

    Use JSON-LD to clarify, not embellish

    Select the schema type that matches what the visitor can actually see: an organization, person, article, product, event, local business, or another relevant entity. Then connect the page to its author, publisher, subject, and canonical identity where those relationships are accurate.

    • Give important entities stable identifiers so repeated markup refers to the same organization, person, product, or service.
    • Keep names, URLs, authorship, publication details, and business information consistent between JSON-LD and visible content.
    • Use identity links only for profiles or records that genuinely represent the same entity.
    • Mark up questions and answers only when those questions and complete answers are visible to the reader.
    • Validate the generated markup after templates, plugins, or deployment systems have processed it.
    • Retest important templates after design or content-model changes, because technically valid markup can still describe the wrong entity.

    Do not use schema to introduce awards, ratings, authors, prices, availability, or other claims that the page does not support. Structured data is not a hidden copy field. Inconsistent markup creates another version of the truth for a machine to reconcile.

    Schema also cannot rescue a thin page. It can state that a page concerns a particular service, but it cannot supply the missing explanation, proof, or comparison. The visible content remains the answer a person must be able to use.

    Turn digital PR into corroboration

    Digital PR for Copilot visibility is not simply a link-count exercise. The useful outcome is a credible, accessible reference that connects your entity with a relevant claim, definition, specialty, or piece of evidence. The practical inference is straightforward: when important facts are expressed consistently across reputable locations, an answer system has less ambiguity to resolve.

    1. Choose the association. Write down the exact subject, claim, or expertise you want people and machines to connect with your organization.
    2. Create the canonical evidence. Publish the clearest version on your site, including definitions, methodology, limitations, authorship, and an update history where relevant.
    3. Pitch the evidence, not an adjective. A useful dataset, expert explanation, technical resource, or documented change gives publishers something concrete to evaluate.
    4. Preserve entity consistency. Use the same organization, product, expert, and methodology names in your own page, structured data, biographies, profiles, and outreach materials.
    5. Review the resulting coverage. Confirm that names, links, figures, and qualifications are correct. Request a correction when an error could propagate.

    A self-published announcement can establish what your organization claims, but it is not independent confirmation. Do not manufacture survey findings, inflate a sample, or pitch a conclusion the underlying material cannot support. Weak evidence distributed widely remains weak evidence.

    Look for gaps between your site and the public record. An expert page without a biography, a product renamed only on part of the site, or a company description that changes across profiles can fragment the entity. Fix the canonical page first, update the structured data, and then correct the most relevant external records.

    Measure visibility, accuracy, and value as separate outcomes

    Referral sessions alone cannot tell you whether Copilot understands your brand. A generated answer can mention or cite you without producing a click, and an identifiable visit can still land on the wrong page. Use prompt monitoring and analytics together.

    Start with a fixed prompt set drawn from your prompt map. Preserve the wording and relevant context so later checks are comparable. Then record the prompt, date, answer summary, whether your brand appeared, whether a URL was cited, which URL appeared, whether the description was accurate, which alternatives were cited, and what action the result implies.

    Do not collapse those observations into a single visibility score too early. A mention, a citation, an accurate recommendation, and a qualified visit are different events. Keeping them separate tells you what to fix.

    • The preferred page is not retrievable: investigate access, indexing instructions, rendering, canonicals, redirects, sitemaps, and internal links.
    • The page is retrievable but does not answer the prompt: repair the intent match and add the missing decision criteria or qualification.
    • Your brand is mentioned without a citation: strengthen the page’s direct answer, evidence, authorship, and external corroboration.
    • The wrong URL is cited: clarify page ownership, consolidate overlap, improve internal anchors, and align canonical signals.
    • The citation misstates your position: publish the correction prominently, remove ambiguous wording, align structured data, and correct relevant public records.
    • The citation is accurate but produces little useful activity: improve the landing experience and offer a next step that extends the answer instead of repeating it.

    In analytics, segment identifiable Copilot and Microsoft search referrals, then compare their landing pages, engagement, conversions, and assisted journeys with your other channels. Keep attribution limits visible in your reporting. Unattributed visits and no-click influence should not be relabeled as proven Copilot traffic.

    Run the first audit on one question that matters to your business. Assign it one canonical page, repair retrieval problems, rewrite the strongest answer passage, align its JSON-LD, and build credible corroboration around the underlying claim. Recheck the same prompt after each material change. That gives you a repeatable optimization loop instead of a collection of AI-search tactics with no diagnosis behind them.

    References


  • AI-Generated Images in Google Search: A Publisher Playbook

    AI-Generated Images in Google Search: A Publisher Playbook

    If you publish recipes, tutorials, or any page that depends on original visuals, the immediate question is practical: can Google generate an image that answers the query before your work earns a visit?

    Do not cancel an image shoot or replace your library with synthetic assets based on one search experiment. Google stopped the recipe-image test that triggered this concern. The useful response is to make your visuals stronger as evidence, connect them cleanly to your content, and measure whether a generated answer actually changes user behavior.

    What Google tested, and what it did not establish

    Google tested AI-generated illustrations inside AI Overviews for recipe results. The generated visual compressed the cooking process from preparation to the finished dish. Google subsequently said the small experiment was no longer running.

    The company also distinguished that experiment from Nano Banana, an image-generation feature announced in July that activates when a user explicitly asks to create an image. That distinction matters. An automatically generated visual inserted into a search answer is a different product behavior from an image a user deliberately requests.

    The narrow reading is the reliable one:

    • Google is willing to test generated visuals within the search-results experience.
    • The recipe experiment described here has ended.
    • The test does not establish a general rollout for generated images in AI Overviews.
    • It does not establish how Google ranks AI-generated images published on your own site.
    • It provides no measured traffic-loss figure that you can apply to your pages.

    That last point should guide your budget decisions. A generated answer could reduce the need to click, but a stopped experiment cannot tell you how large that effect would be. Treat displacement as a hypothesis to measure, not a loss percentage to assume.

    Separate the three image questions people keep mixing together

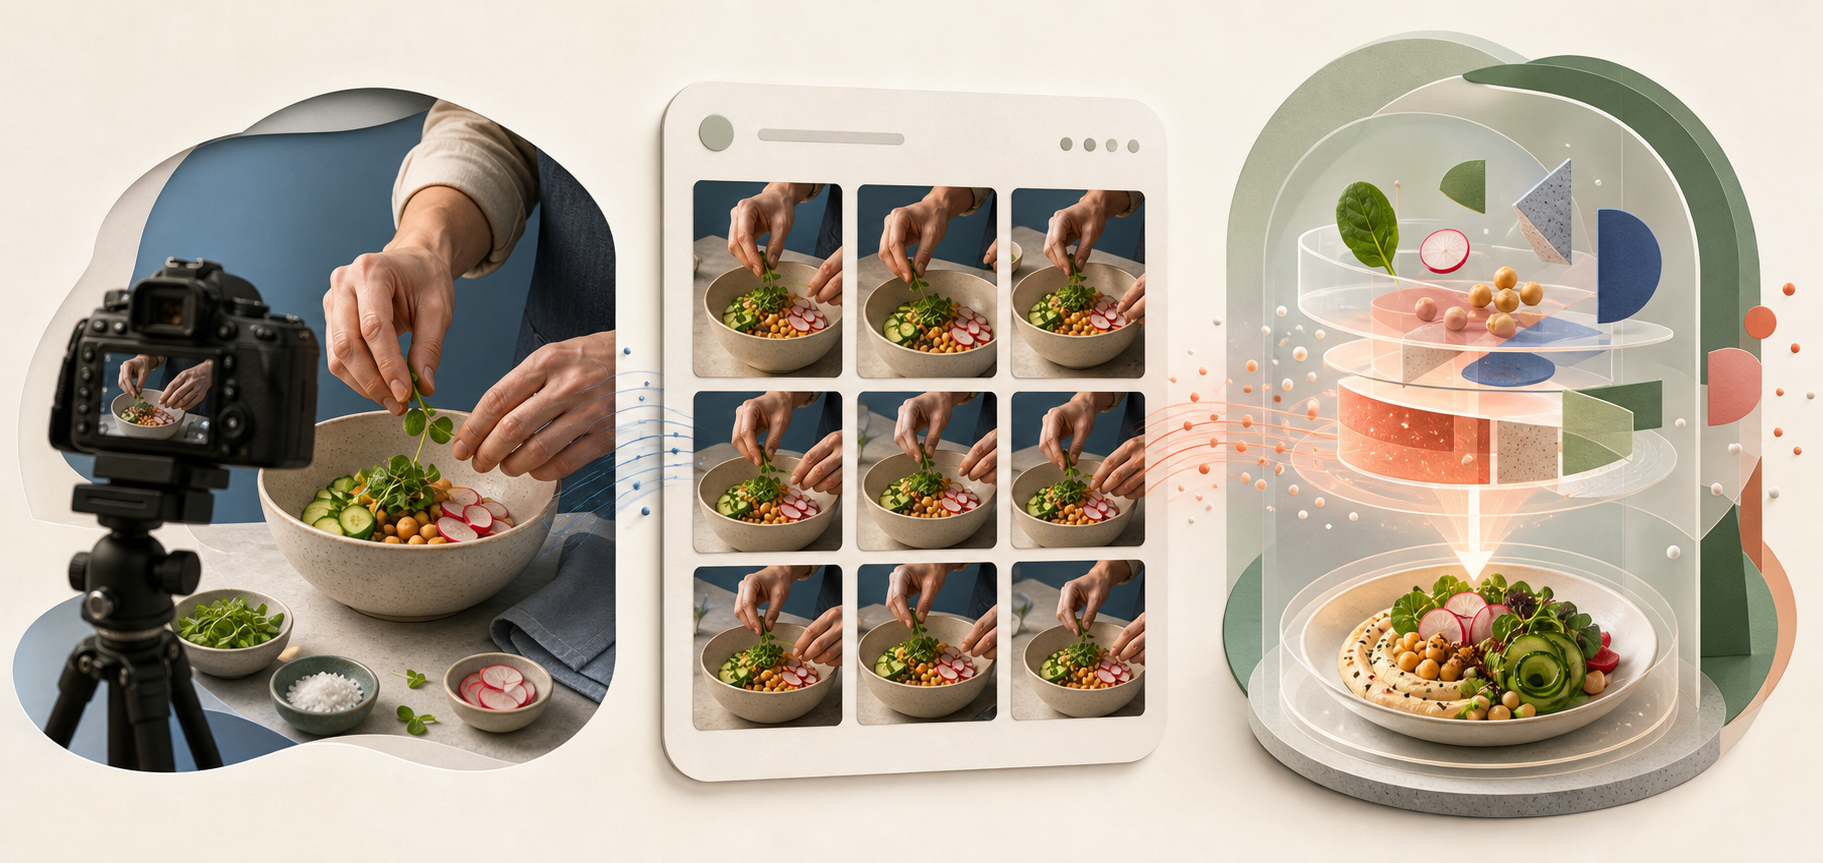
    A three-part illustration shows an original cooking photograph, image thumbnails organized for search, and visual fragments forming a newly generated dish image.

    “AI-generated images in Google Search” can describe three different situations. Confusing them leads to bad SEO decisions.

    QuestionWhat the recipe test tells youYour decision
    Will Google generate a visual inside the result?Google tested this in recipe AI Overviews and then stopped the experiment.Monitor the search surface for your important queries instead of assuming a permanent rollout.
    Will Google show or cite an image from my page?The stopped test does not answer that broader visibility question.Keep original images accessible, useful, and clearly associated with the visible page content.
    Can I publish an AI-generated image on my site?The event establishes no general ranking treatment for publisher-created AI images.Judge the asset by accuracy, transparency, reader value, and your content standards rather than an assumed SEO advantage.

    The most immediate concern is the first situation: Google owns the generated visual, while publisher citations may appear nearby. A recipe publisher affected by the experiment warned that users could mistake nearby citations for credit for the illustrations. That concern is plausible, but it should not be inflated into a claim that every AI Overview misattributes images.

    When you inspect a result, ask two separate questions: “Where did the factual instructions come from?” and “Who created this visual?” If the interface makes only the first answer clear, a citation does not necessarily give you visual attribution.

    Make original images carry evidence a summary cannot preserve

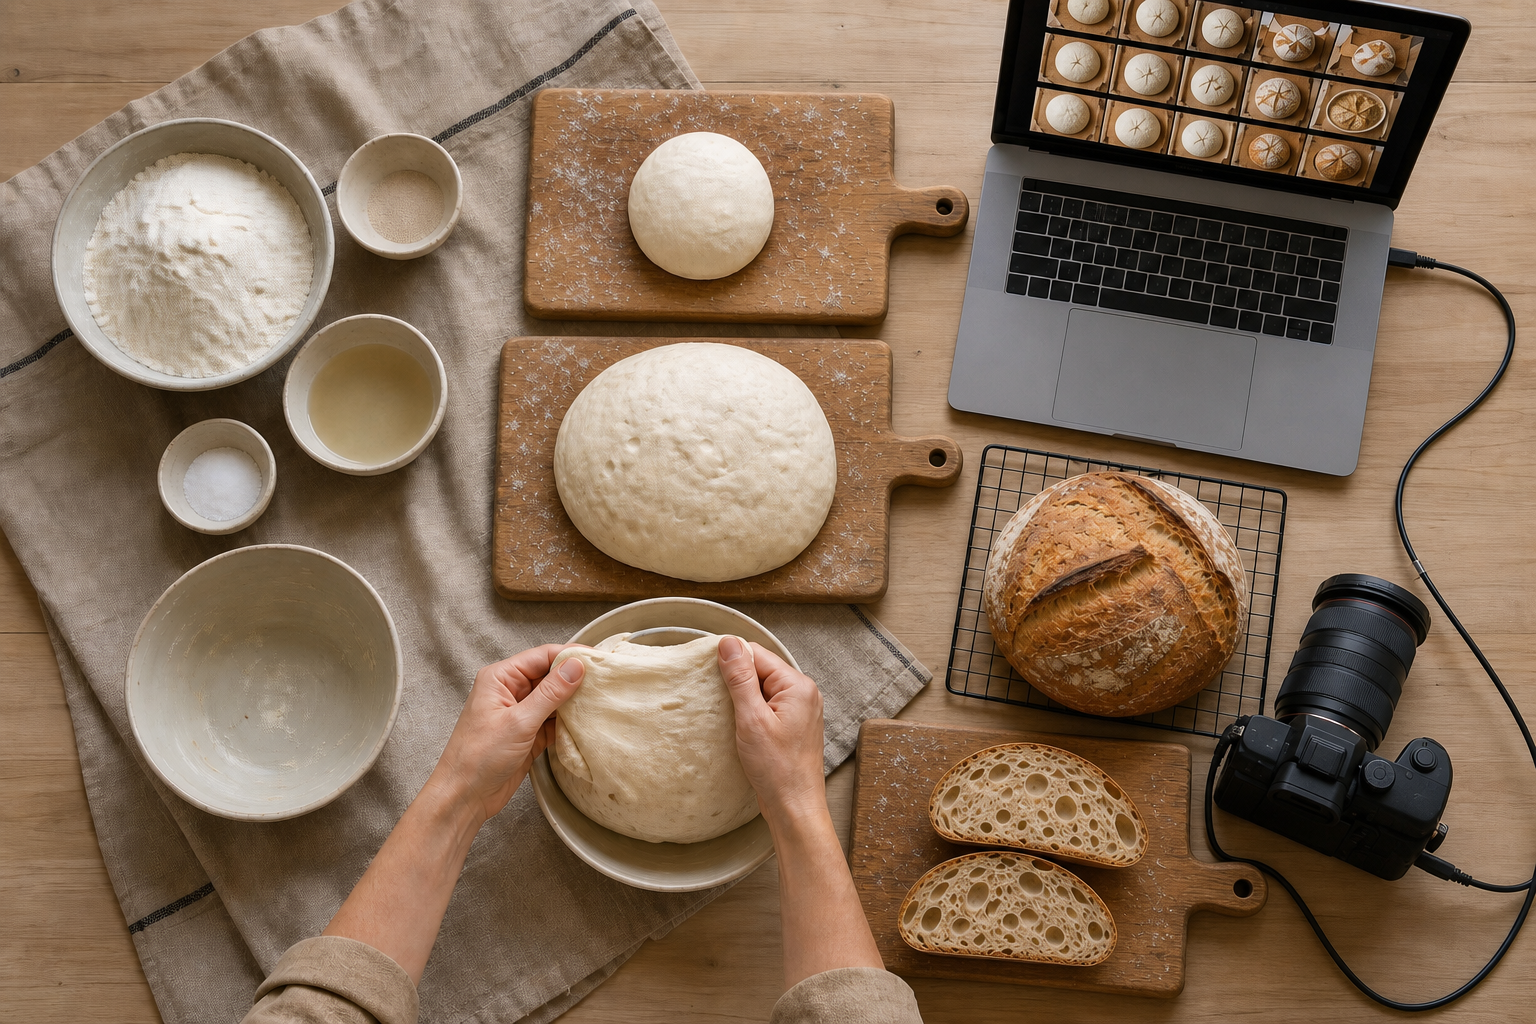
    An overhead workspace shows a creator photographing measured ingredients, dough stages, and the interior of a finished loaf as a consistent visual sequence.

    Your strongest response is not to publish more decorative images. It is to make each original visual communicate something a simplified reconstruction could omit, blur, or invent.

    • Give every image a defined job. Show a decision, condition, comparison, or outcome that the surrounding prose cannot communicate as quickly.
    • Capture consequential stages. For a recipe, that might be texture, color, consistency, assembly, or the difference between an intermediate stage and the finished result. For a repair tutorial, it might be component orientation or correct tool placement.
    • Keep the visual and written sequences aligned. If the text changes order during editing, update the image order and captions at the same time. A polished image attached to the wrong step is worse than no image.
    • Write captions that interpret the evidence. Name the stage and tell the reader what to notice. “Mixture after folding, with visible streaks remaining” is more useful than “Step three.”
    • Use accurate alt text. Describe the relevant content and purpose of the image. Do not turn alt text into a list of target keywords.
    • Keep credits in visible page context. If the photographer, illustrator, tester, or organization matters, identify that contributor where readers can see it rather than relying only on the file name.
    • Align structured data with the page. If you use Recipe or ImageObject markup, reference an image that represents the visible content. JSON-LD is a consistency layer; it is not proof of authorship or a guarantee that an image will appear in search.

    This changes the role of image production. A generic hero image decorates a page. A well-captioned process image documents a claim. When Google or another answer engine compresses the page, the second asset gives the system and the reader a clearer reason to preserve the connection to your work.

    If the image itself was generated

    An AI-generated image can be an illustration without being evidence that you performed a process, tested a product, or produced the depicted result. Keep that boundary explicit.

    • Check every depicted step against the instructions a reader will follow.
    • Look for invented ingredients, tools, components, labels, textures, and transitions.
    • Do not present a generated process scene as documentary photography.
    • Label the image’s role when the difference between illustration and documentation could affect trust.
    • Have a human editor verify the final asset in the context of the page, not only as a standalone image.
    • Replace the asset when an error could lead the reader to perform the process incorrectly; a disclaimer does not repair a misleading instruction.

    For image-led instructional content, consistency matters more than visual polish. If the prose says one thing and the image shows another, the page has an accuracy problem regardless of whether a camera, design tool, or generative model produced the asset.

    Measure exposure before changing your production budget

    A sitewide traffic change cannot tell you whether a generated image displaced a click. You need query-level evidence that the search feature appeared and page-level evidence that behavior changed.

    1. Define the exposed content group. Start with pages whose value can be compressed into a visual sequence: recipes, assembly instructions, repairs, demonstrations, comparisons, and other image-led tutorials.
    2. Record the actual result. For each important query, save the query wording, generated visual, visible citations, search language, location context, device context, and date observed. Search interfaces change, so the screenshot is part of your evidence.
    3. Annotate the first observation. Add it to the same change log you use for site releases, content updates, and search-feature changes. Without that marker, later traffic comparisons become guesswork.
    4. Compare the affected pages and queries. Use Google Search Console to review impressions, clicks, and click-through rate. Use analytics to examine entrances and the business actions that follow those visits. If your reporting does not identify the generated feature directly, pair performance data with the search-result captures.
    5. Use a relevant comparison group. Compare image-led pages where you observed the feature with similar pages where you did not. Do not use unrelated sitewide traffic as the only baseline.
    6. Inspect attribution and accuracy separately. A citation can be present while the generated visual remains confusing. Record whether the source of the instructions and the creator of the visual are each clear.
    7. Change strategy only when the pattern repeats. A generated visual appearing alongside a decline isolated to the same queries is more informative than a single screenshot or a broad organic fluctuation.

    If impressions remain stable but clicks decline only where the generated visual appears, the displacement hypothesis becomes more credible. If no such visual appears, or the decline affects unrelated pages, look for another explanation before changing your image workflow.

    Also separate visibility from value. A page can receive fewer visits without losing the same proportion of conversions, subscriptions, or qualified inquiries. Conversely, a visible citation can look positive while contributing little meaningful traffic. Track both search presence and the outcome you actually need.

    When you find an inaccurate or confusing generated visual, capture the evidence before the interface changes. Preserve the query, complete visual, citations, and relevant landing pages. Use any feedback or reporting control available in the result, then check whether ambiguity on your own page contributed to the problem. Correct your page when it is unclear, but do not rewrite accurate instructions merely to match a generated mistake.

    Key takeaways

    • Google stopped the small recipe experiment that automatically generated process illustrations inside AI Overviews.
    • The experiment was separate from image generation triggered by an explicit user request.
    • A Google-generated search visual, a publisher image shown in search, and an AI image published on your site are three different SEO questions.
    • The stopped test does not establish a general ranking penalty or benefit for AI-generated images on publisher sites.
    • Original visuals become more defensible when they document meaningful stages, match the instructions, include precise captions, and align with structured data.
    • Do not infer traffic loss from the feature’s existence. Record the result and compare affected queries and pages before changing your production strategy.

    Start with your highest-value image-led template. Audit the relationship among its instructions, visuals, captions, credits, alt text, and structured data, then establish a performance annotation you can use if generated visuals reappear. The next experiment may take a different form, but clear evidence and clean measurement will leave you in a position to respond without guessing.

    References

  • Brand Visibility in ChatGPT: A Search and Retrieval Playbook

    Brand Visibility in ChatGPT: A Search and Retrieval Playbook

    Your pages rank, your brand has authority, and buyers know your name. Yet when someone asks ChatGPT which companies belong on a shortlist, you are missing. That gap is real: search visibility can help ChatGPT find you without making your brand one of the names it chooses.

    The practical fix is to identify where visibility breaks. ChatGPT must associate your brand with the right category, retrieve usable evidence, and have enough corroboration to include you confidently. Each failure requires a different response.

    Find the layer where your visibility breaks

    A glowing signal travels through three transparent chambers, with an obstruction visibly blocking one stage of the pipeline.

    Brand visibility in ChatGPT is not a single ranking. It is a sequence of outcomes:

    1. Recall: ChatGPT recognizes your brand as relevant to the category or problem.
    2. Retrieval: your page, another page about you, or both enter the material available for the answer.
    3. Selection: ChatGPT uses that material to mention, describe, recommend, or cite your brand.

    A brand can pass one layer and fail the next. ChatGPT might know your name but not classify you as a provider in the requested category. It might retrieve your page but choose a competitor because that competitor is described more consistently across independent websites. It might mention you from prior model knowledge without citing your domain at all.

    Traditional SEO remains part of the foundation. In one broad brand dataset, more than nine in ten brands broadly followed the expected relationship between stronger search authority and stronger AI visibility. The important exceptions show why rankings alone are an incomplete diagnostic.

    An AI answer also creates a smaller consideration set than a search results page. A category may have hundreds of plausible providers, but ChatGPT often returns a short list of familiar names. If your brand is outside the five to ten names the model commonly recalls, more organic traffic will not automatically move you into that shortlist.

    Start your diagnosis with unbranded prompts. A branded question such as “What does Acme do?” only tests whether ChatGPT can navigate to or describe Acme. It does not test whether Acme appears when a buyer asks for the best platform for a job, industry, budget, audience, or constraint.

    Key takeaways

    • Keep the SEO foundation. Organic authority usually supports AI visibility, but it does not guarantee recall or recommendation.
    • Measure recall, retrieval, citation, and factual accuracy separately. Combining them into one score hides the problem you need to fix.
    • Make the brand-category relationship explicit on your own site and consistent across the web.
    • Build independent corroboration. Repeated third-party descriptions can matter more than another self-promotional page.
    • Test the ChatGPT product modes your audience uses. API output is not a reliable substitute for product-level retrieval.

    Make your brand-category association unmistakable

    ChatGPT cannot recommend your brand for a category it does not clearly associate with you. This is an entity-positioning problem before it is a keyword problem.

    Many brands make that association unnecessarily difficult. Their homepages lead with language such as “transforming possibilities” or “intelligent solutions” while the actual product category appears deep in a feature page. Human visitors may infer the meaning from design and context. A retrieval system assembling evidence from titles, snippets, cached text, and third-party descriptions has less room for inference.

    Write one internal positioning sentence before changing any page:

    [Brand] is a [specific category] for [specific audience] that helps with [specific job], especially when [relevant constraint or differentiator].

    This is not necessarily homepage copy. It is a control statement for checking whether your website, profiles, reviews, press coverage, comparison pages, and structured data tell the same basic story.

    1. Choose the category you need to own. Use the phrase a buyer would recognize, not an internal market label invented for differentiation.
    2. Define adjacent categories deliberately. If your product belongs in several markets, state the relationship instead of expecting ChatGPT to infer it from a feature list.
    3. Create a canonical page for each important use case. Explain who the product is for, the problem it solves, how it works, its meaningful constraints, and the evidence behind its claims.
    4. Connect supporting pages to that canonical explanation. Product documentation, customer stories, comparisons, integrations, pricing information, and help content should reinforce rather than contradict the core classification.
    5. Align identity signals. Use the same brand name, product names, company description, category language, and official URL across the properties you control.

    Structured data can support this clarity, but it should label facts already visible on the page. Organization, Product, Service, and Article markup can clarify entity relationships when they are accurate. They do not manufacture authority, repair vague positioning, or guarantee inclusion in a ChatGPT answer.

    Apply a simple editorial test: remove the logo and navigation, then read the first useful section of the page. Could an unfamiliar editor complete the sentence “[Brand] is a…” without guessing? If not, a retrieval system may face the same ambiguity.

    Comparison content can help when it reflects a genuine decision. Explain which buyer, use case, or constraint makes each option suitable. A page that declares your product the winner in every scenario supplies less credible evidence than one that states its boundaries. The goal is not to repeat a category phrase. It is to make your place in the category easy to verify.

    Build the corroboration your own website cannot provide

    Independent editorial, reference, comparison, conference, and review sources send beams toward a central blue brand object.

    Your website can establish what you claim. Independent coverage helps establish whether that claim is recognized elsewhere.

    The distinction explains some large visibility gaps. In one dataset, 471 brands, or about 5%, were underexposed in model answers despite strong traditional search footprints. Another 377 brands, or about 4%, appeared more often than their conventional SEO signals would predict. These figures are not universal benchmarks; they describe one analyzed prompt and brand set. Their diagnostic value lies in the pattern: frequent appearances in independent roundups, expert lists, and comparisons tracked with stronger AI visibility.

    That does not mean collecting as many mentions as possible. A syndicated announcement copied across dozens of sites is repetition, not necessarily independent corroboration. Useful coverage supplies context: what category the brand belongs to, who it serves, where it is strong, what evidence supports the description, and how it compares with realistic alternatives.

    Build a corroboration map around actual buyer decisions:

    • List the publications, specialist sites, professional communities, directories, reviewers, and comparison pages that already appear for your unbranded category prompts.
    • Record how each one describes your category. The language used by credible third parties may differ from the label your marketing team prefers.
    • Mark where competitors appear and you do not. That is a distribution gap, not an on-page optimization task.
    • Check whether existing coverage places you in the wrong category, uses an old product name, repeats a discontinued claim, or points to a retired URL.
    • Prioritize pages that help a reader make the same decision represented by the prompt. Relevance is more useful than an unrelated high-authority mention.

    Then give credible publishers something worth referencing. Original data, transparent methodology, technical documentation, clearly attributed expert analysis, useful tools, and verifiable customer outcomes create evidence. Generic claims such as “leading,” “innovative,” or “best-in-class” create copy that no careful editor needs.

    For each important external mention, look for six qualities:

    • Your current brand and product names are accurate.
    • The relevant category is stated plainly.
    • The intended audience or use case is clear.
    • Important claims have evidence or transparent attribution.
    • The page is publicly accessible at a stable URL.
    • The description agrees with current first-party facts without merely copying your sales language.

    Do not optimize only for positive wording. Accurate qualification is more useful. “Suitable for distributed enterprise teams that need X” gives ChatGPT a reason to select the brand for one prompt and omit it from another. That is better visibility than appearing indiscriminately and being described incorrectly.

    Make important pages easy to discover, read, and reuse

    ChatGPT search does not simply send one query to a conventional search engine and summarize the first page. In one observational capture involving 1,200 answers, 88,000 search results, and 26,900 distinct pages, web grounding showed three operational layers: a discovery index that surfaced candidates, cached full-page copies, and a smaller group of pages opened live.

    These layers are observed behavior, not a permanent OpenAI specification. The implementation can change. The model is still useful because it explains why “we rank in Google” and “ChatGPT can use this page” are different claims.

    Discovery comes first. A page needs a stable, indexable URL, a successful response, a descriptive title, internal links, and a place in the site’s normal crawl paths. A page that exists only behind search, an interactive selector, a login, or a client-side application shell is a weak candidate for dependable retrieval.

    Do not use Bing visibility as a definitive proxy for OpenAI discovery. The observed OpenAI index behaved differently: only 1.5% of its URLs appeared in Bing’s top 20 for the same fan-out queries, and its snippets and title handling also differed. Google rankings can matter in retrieval regimes that use scraped Google results, but they do not prove that a page entered OpenAI’s own index.

    Once discovered, the page must be understandable in isolation. Treat the retrieved document as if the navigation, design, and sales presentation were gone. The text itself should answer these questions:

    • What entity or product is this page about?
    • What question does it answer?
    • Which audience, market, version, region, or use case does the answer apply to?
    • What evidence supports its factual claims?
    • When was the information meaningfully updated?
    • Which page is canonical if similar versions exist?

    Put the direct answer near the top, then expand it under descriptive headings. Use tables only when readers are comparing stable dimensions. Keep qualifications beside the claim they limit. A sentence that says “available in Canada” on one page and “available globally” on another creates an avoidable conflict unless both statements explain their dates or product scopes.

    Cached reading introduces another practical issue: a fact can be corrected on your live page while an older copy or an outdated third-party description remains available elsewhere. When an answer repeats stale information, check more than the current page. Find obsolete URLs, duplicates, old documentation, directory profiles, and external comparisons. Update or redirect what you control, request corrections where appropriate, and make the current canonical page easy to reach through internal links.

    Different ChatGPT modes can retrieve from markedly different corpora. During one capture period, free Think drew 74.7% of results from OpenAI’s own retrieval hub, while paid Thinking drew 75.3% from scraped Google results. Treat those percentages as a snapshot, not a lasting optimization formula. Their value is the warning: two people can enter the same prompt, retrieve a similar volume of material, and still receive answers grounded in different parts of the web.

    Product and local discovery also require channel-specific work. In the observed system, shopping and local results used merchant feeds and business-listing pipelines rather than ordinary web search. If you sell products or operate physical locations, clean editorial pages are not a substitute for accurate merchant data, prices, inventory information, addresses, categories, and business listings.

    A retrieval-ready page therefore needs more than technical indexability. It needs explicit meaning, extractable evidence, consistent facts, and the correct distribution channel for the query.

    Measure the answer, then fix the right bottleneck

    A single screenshot is not an AI visibility program. ChatGPT answers vary with wording, product mode, retrieval corpus, system behavior, location, account context, and time. Your benchmark needs a controlled prompt set and enough detail to reproduce each observation.

    Build prompts from the decisions that matter to your audience:

    • Category discovery: requests for providers, products, or approaches in your market.
    • Problem discovery: prompts that describe the job without naming the solution category.
    • Constraint prompts: industry, audience, geography, integration, budget model, compliance need, or workflow limitation.
    • Comparison prompts: your brand against a named alternative or a request for options with explicit tradeoffs.
    • Branded verification: questions about what you do, who you serve, current features, availability, pricing model, or another fact you can validate.

    Keep category, problem, and branded prompts in separate groups. A strong score on branded verification can otherwise conceal complete absence from unbranded discovery.

    SignalWhat to recordWhat it diagnoses
    Brand mentionWhether the brand appears and in which prompt classCategory recall and consideration-set inclusion
    Position and framingWhere the brand appears, which use case is attached, and any qualificationBrand-category association and positioning accuracy
    CitationWhether a claim is cited, the linked URL, and whether the domain is yours or independentRetrieval and evidence selection
    Factual accuracyCorrect, outdated, unsupported, or contradictory claimsCanonical-content, cache, and corroboration problems
    Competitive recurrenceWhich alternatives repeatedly appear for the same prompt classThe actual AI consideration set
    Test contextExact prompt, ChatGPT mode, account tier, location context, and test dateWhether two observations are meaningfully comparable

    Use the actual ChatGPT experience your audience is likely to encounter. API tests can help probe what a model family appears to know, but they should be labeled as a different measurement. In captured comparisons, product-to-API brand overlap measured only 0.23 to 0.27 using Jaccard similarity. Even ChatGPT product regimes shared only about a third of the brands they mentioned. An API monitor can therefore be directionally interesting while failing to predict the product answer.

    Translate each result into a specific action:

    • If competitors recur in unbranded prompts and you never appear, inspect category association and third-party coverage before rewriting title tags.
    • If ChatGPT mentions you accurately but never retrieves your domain, improve the official pages that substantiate the relevant claims and make them easier to discover.
    • If your domain is cited but the answer describes you incorrectly, remove ambiguity and conflicting first-party facts from the cited page.
    • If outdated external pages drive an error, correct the corroboration layer rather than publishing another unsupported claim on your homepage.
    • If results vary by mode, retain the variation in your reporting. Do not average materially different retrieval regimes into a false sense of precision.
    • If shopping or local prompts fail while editorial prompts succeed, inspect merchant feeds or business listings instead of treating the problem as ordinary web SEO.

    Keep a changelog beside the benchmark. Record the pages changed, external descriptions corrected, new coverage earned, and structured data updated. Retest the same prompt set under the same documented conditions, then inspect whether recall, retrieval, citation, or accuracy moved. This keeps you from crediting one tactic for a change caused by a different product mode or retrieval update.

    Your next move should follow the clearest failure. If ChatGPT does not associate you with the category, fix positioning and corroboration. If it recalls you but cannot support the answer, fix retrieval and evidence. If it cites stale or incorrect material, reconcile the fact across every page that can still influence the answer. That is how AI visibility becomes an operating practice instead of a collection of screenshots.

    References


  • How to Measure and Improve Visibility Across AI Search

    How to Measure and Improve Visibility Across AI Search

    Your pages rank in conventional search, yet your brand disappears when a prospect asks an AI platform for options. Or the brand appears, but the answer cites the wrong page, omits the reason to choose you, or repeats an outdated claim.

    You do not fix that with a larger keyword list. You need a visibility system that separates retrieval, citation, accuracy, and business relevance. Once those layers are measured separately, you can see whether the real problem is access, content, authority, entity clarity, or the test itself.

    AI search visibility is a set of contexts, not one ranking

    A conventional rank tracker usually ties a query to a search engine, location, device, and result position. AI search adds more variables. The same underlying need can be handled by different products, modes, models, account tiers, languages, and prompt formulations.

    A Gemini 3.7 Flash rollout placed the model in Google Search’s AI Mode globally for English-language Google AI Pro and Ultra subscribers. At that stage, paid users could select it through the plus control inside AI Mode. Google said the change was intended to improve instruction following and intent understanding. That is a material testing distinction: a result produced in that mode cannot automatically represent every Google search experience.

    Record the environment beside every test result:

    • Platform and search surface, such as a conventional result page or an AI-specific mode.
    • Model or mode when the interface exposes it; otherwise record that the default was used.
    • Account or subscription context, including whether the test was signed in.
    • Language, market, and location relevant to the audience you actually serve.
    • Exact prompt and any follow-up prompts that changed the answer.
    • Test date, because platforms and underlying models change.

    Then separate four outcomes that are often collapsed into a vague visibility score:

    • Inclusion: Was your brand, product, expert, or content mentioned?
    • Citation: Did the response link to or otherwise identify one of your pages?
    • Representation: Were the claims about you correct, current, and properly qualified?
    • Destination: Did the cited page actually help the user take the next step?

    Do not call any of these a universal AI rank. A brand can be mentioned without being cited, cited below a competitor, accurately recommended in one mode, and absent in another. Preserve those distinctions in reporting or you will prescribe the wrong fix.

    Build a prompt map around decisions, not isolated keywords

    A person stands before branching paths that connect miniature scenes of discovery, comparison, evaluation, and selection.

    People often use AI search to describe a situation, add constraints, compare approaches, and ask follow-up questions. A keyword list strips away much of that intent. Build your test set around the decisions for which your brand should be a credible candidate.

    Start with prompt families that represent distinct jobs:

    • Problem discovery: The user describes an outcome or obstacle without naming a solution category.
    • Category education: The user asks what an approach is, how it works, or when it is appropriate.
    • Option discovery: The user asks for tools, providers, methods, or examples that meet stated constraints.
    • Evaluation: The user compares options by capability, audience, implementation requirements, or another relevant criterion.
    • Verification: The user checks a specific claim about a brand, product, person, policy, integration, or feature.
    • Action: The user asks how to implement, configure, buy, contact, or proceed.

    Attach context to each prompt family: the intended audience, the need behind the question, meaningful constraints, applicable market and language, the entity you expect an answer to discuss, and the page that best supports your eligibility. This turns a bag of prompts into an auditable coverage map.

    Keep branded and non-branded prompts separate. A test such as “What does Brand X offer?” measures whether the system can identify an entity it has already been given. A category question that never names Brand X tests discovery. Combining the two can make strong branded recognition conceal weak category visibility.

    For each important intent, retain a stable anchor prompt so results can be compared over time. Add natural variations to expose sensitivity to wording, audience, and constraints. Save the raw answer rather than recording only a pass or fail. Generated responses can vary, and the wording often reveals why a page was selected, misunderstood, or ignored.

    Relevance must remain part of the test. If your brand does not satisfy the user’s stated need, its absence is not a visibility failure. Define eligibility before running the prompt. Otherwise the measurement rewards forced mentions instead of useful recommendations.

    Make important claims retrievable, citable, and easy to verify

    An AI system cannot reliably cite a claim that exists only as an implication. If a reader must combine a slogan, an image, a pricing card, and a separate support page to understand what you offer, machine retrieval has the same avoidable burden.

    Write answer-bearing passages

    Give each important page a clear information job. A strong passage usually names the entity, answers a specific question directly, supplies the necessary qualification, and points to supporting evidence. The relevant facts should survive when the passage is read outside the visual context of the page.

    • Open a section with the answer it exists to provide, then explain the reasoning or process.
    • Use the same canonical names for the company, product, feature, and people across related pages.
    • Place limits, prerequisites, markets, and audience qualifications beside the claim they modify.
    • Distinguish current capabilities from planned, historical, optional, or third-party capabilities.
    • Link claims to the most direct supporting page instead of sending every citation to the homepage.
    • Show publication or modification information when recency affects whether the claim is usable.
    • Remove conflicting versions of material or make the authoritative version unambiguous.

    This is not an instruction to turn every page into a collection of short answers. Explanations, comparisons, examples, and limitations give an answer the context needed to be trustworthy. The goal is to eliminate ambiguity without stripping away substance.

    Check crawlability before rewriting everything

    A useful Perplexity visibility audit covers content quality, domain authority, community engagement, and AI crawlability. These are different layers. A polished answer will not help a system that cannot retrieve it, while open crawl access will not make a thin or unsupported claim worth citing.

    Before commissioning a broad content rewrite, inspect the affected URLs:

    • Confirm that robots rules and page-level indexing directives match the access policy you intend to enforce.
    • Check that the preferred URL returns successfully and does not depend on a login, consent failure, or unintended interstitial.
    • Make sure the canonical points to the version containing the information you want discovered.
    • Inspect the rendered page and underlying HTML. The primary facts should not exist only inside an image or an interaction that a retriever may never execute.
    • Use internal links and sitemaps to make important pages discoverable from the rest of the site.
    • Review server logs, when available, to determine whether the crawlers you intend to permit are reaching the relevant URLs.

    Do not weaken security or expose private material merely to gain visibility. Public product facts, protected customer data, and content licensed under access restrictions require different policies. Improve access only for material that is meant to be public.

    Use JSON-LD to clarify visible facts

    Structured data is a clarification layer, not a substitute for a useful page. Apply schema types that match the visible content, such as Organization, Person, Article, Product, Service, or BreadcrumbList where appropriate. Keep names, URLs, authorship, dates, and entity relationships consistent with what a reader can see.

    Do not add claims to JSON-LD that the page does not support. Do not mark up a generic sales statement as though it were independently verified evidence. Validate the syntax, but also validate the meaning: technically valid markup can still describe the wrong entity or contradict the page. No schema type guarantees inclusion or citation in an AI response.

    Build corroboration without manufacturing consensus

    Your site is the primary place to state what your organization does. It is not independent confirmation of every claim it makes. Accurate profiles, relevant industry coverage, genuine expert participation, and substantive community contributions can help other people and systems encounter the same entity in context.

    Prioritize mentions that clarify a real relationship: who the product serves, what problem it addresses, how an integration works, where an expert contributed, or why a claim is credible. Repeated promotional mentions with no additional evidence add noise. Fake reviews, undisclosed placements, and synthetic community activity also create reputational risk rather than dependable authority.

    Measure the response, diagnose the layer, then make the fix

    An analyst examines a transparent sequence of chambers in which a glowing signal passes through gates, documents, connections, and matching shapes.

    Run a repeatable visibility audit

    1. Freeze the baseline. Save the prompt set, eligibility rules, platform context, language, account state, and pages you expect to support each intent.
    2. Capture the full response. Record whether the brand appears, which claims are made, which pages are cited, which alternatives appear, and whether follow-up prompts materially change the answer.
    3. Label distinct outcomes. Mark discoverability as absent, mentioned, or cited; representation as accurate, partial, incorrect, or unclear; relevance as appropriate or forced; and the destination as direct, indirect, or missing.
    4. Look for patterns. Group failures by prompt family, page, platform, model or mode, and branded versus non-branded intent. A pattern is more diagnostic than an isolated answer.
    5. Change a single layer where practical. Fix access, rewrite the supporting passage, clarify the entity, improve internal linking, or pursue corroboration. Rerun the same baseline before expanding the test.
    6. Keep evidence. Store raw outputs and dates so a model change is not mistaken for the effect of an unrelated site edit.

    Use a failure pattern to choose the next check:

    What you observeLikely starting pointWhat to inspect next
    No relevant page from your domain appears across affected prompt familiesAccess, retrieval, authority, or a missing answer pageRobots rules, indexing directives, rendering, canonicals, internal discovery, server logs, and whether a page directly answers the need
    A relevant page is cited, but the brand or capability is omittedEntity or claim ambiguityThe answer-bearing passage, canonical naming, visible qualifications, internal links, and matching JSON-LD
    The brand appears with an incorrect or outdated claimConflicting information or weak version controlOld URLs, duplicated pages, modification information, entity consistency, and the page used as evidence
    The brand appears for branded prompts but not eligible category promptsDiscovery and authority gapNon-branded decision content, topical coverage, relevant corroboration, and how clearly pages connect the brand to the problem
    Results differ by mode, account tier, language, or marketContext-dependent visibilitySegmented reports and content coverage for the specific environment; do not average the difference away

    Prioritize accuracy before reach

    An AI mention is not automatically a win. If the summary is wrong or the cited page does not support it, more visibility amplifies the error. Correct material misrepresentation first. Then resolve access failures, strengthen the evidence behind eligible claims, and expand coverage into additional prompt families.

    Keep response visibility and website outcomes in separate views. Analytics can show visits and actions after a click, but it cannot reveal every unlinked mention or answer that satisfied the user without a visit. For AI visibility, report the share of eligible tests that mention the brand, the share that cite it, the accuracy of those representations, and the pages selected as evidence. For business performance, report what visitors do after reaching the site.

    Do not blend branded discovery, non-branded discovery, citation, and accuracy into one headline score. A rising total could conceal a damaging increase in incorrect answers. The segmented measures tell you what changed and which team can act on it.

    Key takeaways

    • Measure AI visibility by platform, surface, model or mode, language, market, and account context rather than treating it as a universal rank.
    • Organize tests around real user decisions and keep branded prompts separate from non-branded discovery.
    • Evaluate inclusion, citation, representation, and destination quality independently.
    • Fix crawlability before rewriting accessible pages, and fix inaccurate representation before pursuing more reach.
    • Write self-contained, qualified passages that a system can retrieve and cite without reconstructing the claim from several pages.
    • Use JSON-LD to clarify visible facts and entity relationships; do not treat schema as evidence or a citation guarantee.
    • Track raw responses over time while measuring referral traffic and onsite outcomes separately.

    Choose a customer decision that matters now. Map the prompts around it, test the AI contexts your audience can actually use, and identify the first broken layer. Repair that layer and rerun the same baseline. When a platform introduces another model or mode, you will have a controlled test to repeat instead of starting with another guess.

    References


  • Profound Citation Decay Tracking: A Practical Workflow

    Profound Citation Decay Tracking: A Practical Workflow

    Your AI visibility report can look healthy while an important page quietly loses citations week after week. If you only check the latest total, you may miss the decline until the URL has largely disappeared from the answers that matter to your business.

    Profound Citation Decay tracking gives you the history needed to spot that movement. The harder part is deciding whether the decline is meaningful, finding its likely cause, and choosing a response that does not make the page worse. This workflow takes you from the first downward signal to a controlled recovery test.

    Build a citation-lifetime view before diagnosing the decline

    Profound tracks week-over-week citation counts for every cited URL and shows the full lifetime of each citation. That history changes the question you can answer. A current count tells you where a URL stands now; its lifetime shows whether the current position is normal, deteriorating, recovering, or simply unstable.

    Treat citation decay as a trend in URL-level appearances, not as a conventional ranking drop. The count tells you how often the URL was cited within the monitored environment. By itself, it does not tell you why the URL was selected, whether the citation was favorable, how much traffic it generated, or whether the page still ranks in search.

    MeasurementQuestion it answersHow to use it
    Weekly citation countIs the URL appearing more or less often than in the previous reading?Keep this as the unmodified observation from Profound.
    Weekly directionIs the count rising, flat, or falling?Compare the current reading with the immediately preceding reading.
    Current decay runIs the decline isolated or continuing?Mark successive weekly decreases until the URL stabilizes or recovers.
    Distance from the previous highHow far has the URL moved from its strongest observed point?Compare the current count with the highest count in its recorded lifetime.
    Normalized citation rateCould a changing opportunity pool be distorting the raw count?Use citations divided by eligible monitored observations only when you have a valid, consistently measured denominator.

    Comparability matters more than a sophisticated formula. A weekly decline is difficult to interpret if you also changed the monitored questions, models, markets, languages, collection cadence, or URL-grouping rules. Record those scope changes beside the timeline. Otherwise, a measurement change can look like content decay.

    Keep raw URLs separate before you create domain or page groups. A canonical URL, a redirected address, and a parameterized variant may represent one underlying asset to you, but they are distinct strings in a URL-level history. Preserve those identities, then add an explicit grouping layer. This lets you see both the citation selected by the model and the broader performance of the content asset.

    Read the shape of decay before deciding what it means

    Three illuminated pathways show a gradual fade, a sudden drop, and an irregular decline with partial recovery.

    Not every downward movement deserves the same response. The shape of the history tells you what to investigate first.

    • An isolated weekly dip: One lower reading establishes movement, not a durable decline. Confirm that the tracking scope stayed comparable and inspect the next weekly reading before rewriting the page.
    • A persistent slide: Successive weekly decreases indicate that the URL is repeatedly losing citation appearances. Move the URL into active investigation and identify which monitored needs or answer contexts are affected.
    • A step-down followed by a lower plateau: A sharp break followed by stability calls for a dated check. Look first for a tracking-scope change, URL migration, redirect, publication change, technical issue, or broad shift in the answers being monitored.
    • Intermittent citation: Repeated disappearance and return means the URL is being selected inconsistently. Examine whether the page only partly satisfies the relevant user need, competes with another page on your site, or lacks a clear answer that can be extracted without extra interpretation.
    • A portfolio-wide fall: When many unrelated URLs decline together, start with common factors. Verify the monitoring setup, shared technical controls, site accessibility, and broad changes to the answer environment before launching page-by-page rewrites.
    • URL substitution: If one owned URL falls while another owned URL serving the same need rises, your domain may not have lost the citation opportunity. Confirm the replacement before classifying the movement as brand-level decay.

    This separation prevents a common analytical error: treating every falling URL as an editorial failure. Citation decay is evidence that selection changed. It is not evidence of a particular cause. Your job is to narrow the plausible causes with the least destructive checks first.

    Investigate in an order that prevents false fixes

    A magnifying lens, layered diagnostic tiles, and a precision tool form a left-to-right investigation and repair sequence around a citation network.

    Start with measurement and identity, then move toward technical and editorial explanations. If you reverse that order, you can spend hours improving a page whose apparent decline came from a changed prompt set or a replacement URL.

    1. Confirm a comparable measurement frame. Check whether the monitored questions, platforms, markets, languages, and collection rules remained consistent across the decline. Annotate any change instead of blending unlike periods into one trend.
    2. Reconcile the URL. Check redirects, canonical targets, trailing-slash variants, parameterized versions, protocol variants, and moved content. Determine whether Profound is tracking a real loss or a shift in the address being cited.
    3. Locate the affected user need. Review the monitored questions and generated answers in which the page was previously cited. Group them by the decision, problem, entity, or fact the user wanted. A page rarely needs to be improved for every possible query; it needs to become a better fit for the citation contexts it is losing.
    4. Check retrieval and page accessibility. Confirm that the URL returns usable content without an unintended redirect, access restriction, noindex instruction, canonical conflict, or rendering failure. Verify that the main answer is present in the rendered page rather than hidden behind an interaction that a retrieval system may not process reliably.
    5. Compare the currently cited alternatives. Look at what another URL provides in the affected answer context. Compare scope, directness, evidence, entity clarity, update status, and the amount of interpretation required to extract the answer. You are looking for a specific usefulness gap, not permission to imitate another page.
    6. Match the intervention to the evidence. Fix an access problem with a technical change, an identity problem with URL consolidation, a relevance problem with a clearer answer, and a scope problem with better measurement controls. Do not prescribe a content rewrite for every type of decay.

    Structured data deserves a check, but it is not a citation-recovery switch. Make sure your JSON-LD describes the visible page accurately, uses consistent entity names and URLs, and does not contain claims absent from the content. Then fix the actual access, identity, or answer-quality issue. Adding more markup cannot compensate for a page that does not satisfy the monitored need.

    Match the intervention to the observed pattern

    Observed patternWorking hypothesisBest first actionAvoid
    One URL falls while a related owned URL risesInternal URL substitution or overlapping intentConfirm that the replacement serves the same need, then clarify page roles or consolidate genuine duplication.Deleting the declining page before checking links, redirects, and unique value. Deletion can destroy useful content and inbound signals; preserve the page until the replacement path is verified.
    One URL falls while related pages remain stablePage-specific access, identity, or usefulness issueInspect the URL technically and compare it with the pages now being cited for the affected need.A sitewide rewrite that introduces unrelated variables.
    A related group of pages declinesShared topic gap, architecture problem, or changed monitoring demandAudit the group for overlapping intent, missing answers, weak internal relationships, and inconsistent entity descriptions.Patching an isolated paragraph without checking the shared pattern.
    Unrelated URLs decline togetherMeasurement, platform, or sitewide technical factorVerify tracking scope and common accessibility controls before editing content.Refreshing every publication date or rewriting the entire portfolio.
    The URL repeatedly falls and returnsUnstable selection or an ambiguous match to the user needCollect subsequent weekly readings under the same scope and make the relevant answer more explicit.Declaring recovery or failure from an isolated reading.

    When the evidence points to the page itself, edit for answer fit rather than generic freshness. Put the direct answer under the heading where a reader expects it. Define important entities and relationships explicitly. Remove contradictions and stale claims. Support factual claims with appropriate evidence. Use descriptive internal links to connect genuinely related pages. Align the title, primary heading, canonical identity, visible content, and structured data around the same subject.

    Consolidate pages only when they serve substantially the same need. If each page answers a distinct question, clarify that distinction instead. Combining unrelated intents can produce a longer page that is less precise and harder to cite. If consolidation is justified, preserve the stronger destination, update internal links, and use a verified redirect path rather than simply removing the weaker URL.

    Log every meaningful intervention beside the weekly history. Record the affected URL, the date, the diagnosis, the evidence behind it, the exact changes made, and the result you expect to see. Avoid stacking unrelated changes between readings. When accessibility, copy, internal links, and structured data all change at once, the eventual movement cannot tell you which diagnosis was right.

    Key takeaways

    • Use the URL’s full citation lifetime, not its latest count, to distinguish an isolated dip from persistent decay.
    • Keep the measurement frame comparable. Annotate changes to monitored questions, platforms, markets, languages, cadence, or URL grouping.
    • Check for URL substitution and portfolio-wide movement before concluding that one page has failed.
    • Investigate in sequence: measurement scope, URL identity, affected user need, technical accessibility, cited alternatives, then content and JSON-LD.
    • Choose the smallest intervention that fits the evidence, record it, and judge the result through subsequent weekly readings under the same conditions.

    Start with the declining URL tied to your most important user need. Write down the decay pattern, rule out a measurement or URL-identity problem, and form one testable explanation before changing the page. That turns citation decay from a worrying chart into a disciplined content and technical optimization loop.

    References


  • SEO for Multi-Query AI Search Journeys: A Practical Plan

    SEO for Multi-Query AI Search Journeys: A Practical Plan

    You can rank for the broad keyword and still lose the buyer. An AI answer names a shortlist, the searcher refines the question, a comparison follows, and the decisive click lands on a page you never mapped. If you measure only the opening query and its landing page, that continuing journey looks like lost traffic.

    SEO for multi-query AI search journeys means staying useful through each refinement. You need content that can help form the shortlist, support a comparison, answer objections, confirm suitability, and lead naturally to the next decision. Here is how to build that connected system without manufacturing a thin page for every keyword variation.

    Treat the search result as a loop, not a landing page

    Searchers have always revised their questions. The important change is the answer layer between those questions. It can resolve part of the search without a click, introduce several named options, and influence what the person asks next.

    In SparkToro’s 2026 analysis, 68% of Google searches ended without a click, while the share leading to another Google query rose by 7.2 percentage points. A zero-click result therefore isn’t automatically the end of a journey. It may be a handoff from a broad question to a narrower, better-informed one.

    AI visibility is especially important where people ask questions or compare choices. Across Seer Interactive’s 2026 dataset of 53 brands and 5.47 million queries, AI Overviews appeared for 95.4% of comparison queries and 85.9% of question-format queries. Those figures describe that dataset rather than every market, but they are strong enough to challenge a strategy built around earning the opening click alone.

    Map the search as a set of decision moments. A person can skip, repeat, or reverse these moments, so use them as planning labels rather than a rigid funnel.

    Journey momentTypical query shapeContent jobLikely next question
    DiscoveryWhat is X? How does X work?Define the category and establish its boundaries.Which options fit my situation?
    ShortlistBest X for YName meaningful selection criteria and qualified options.How do the leading options differ?
    ComparisonA vs. B for YCompare the choices against the same decision criteria.What are the limitations or implementation risks?
    ValidationA problems, limitations, reviews, integrationsResolve objections with specific evidence, trade-offs, and scope.Can I adopt, switch to, or use this option?
    ActionA pricing, setup, migration, demoRemove practical uncertainty and make the next action clear.What happens after I choose?

    Key takeaways

    • Optimize the sequence of likely questions, not just the keyword that begins the search.
    • Combine entity and attribute coverage with recurring query templates to find meaningful content gaps.
    • Create a separate URL only when a query represents a distinct decision that deserves an independent answer.
    • Make each page easy to interpret, cite, and continue from through direct answers, visible evidence, and purposeful internal links.
    • Measure AI citations, organic performance, and paid response by query family so one surface does not hide another’s contribution.

    Build a query graph from decisions, templates, and attributes

    Blank cards, decision nodes, and small attribute tokens form a branching network around a central object on a light surface.

    A conventional keyword list tells you which phrases exist. A query graph tells you how those phrases relate, which decision each one serves, and where a searcher is likely to go next. That difference turns an inventory of keywords into a content plan.

    Start with the entity class at the center of the decision. For a software category, the entities might include the category itself, named products, product pairings, integrations, and alternatives. Then list the attributes people need to evaluate: suitability, capabilities, price structure, setup, migration, integrations, support, and limitations. Finally, apply the query templates people repeatedly use, such as “best X for Y,” “X vs. Y,” “problems with X,” “how to use X,” and “alternatives to X.”

    The strongest coverage model combines entities and their shared attributes with the full range of useful query templates. Entity coverage gives you depth within the subject. Template coverage gives you breadth across the different ways people express a need. Their intersection is where the most valuable gaps usually appear.

    Build the graph in this order:

    1. Name the commercial or informational decision you want to support. “Project management software” is a topic; “choosing project management software for an agency” is a decision.
    2. List the entities that could appear in that decision, including the category, individual options, relevant pairings, integrations, and alternatives.
    3. List the attributes that materially change the choice. Exclude generic descriptors that would produce the same paragraph on every page.
    4. Apply query templates to meaningful entity-attribute combinations. Do not publish combinations merely because a keyword tool can generate them.
    5. Connect each query to the likely question before and after it. Those connections become internal-link paths and measurement groups.
    6. Assign an existing URL to every useful query family before proposing new pages. This exposes duplication before it reaches production.

    Suppose the opening query is “best payroll software for a distributed company.” The shortlist may lead to a product-versus-product comparison. That comparison may lead to questions about contractor support, accounting integrations, migration difficulty, or known limitations. Each refinement is narrower, but it belongs to the same decision. Your graph should preserve that relationship instead of sending every query to an isolated page.

    Label the edges between queries with the reason for the transition: compare, verify, troubleshoot, price, implement, or switch. That label is useful editorially. It tells the writer what uncertainty the next page must remove, and it prevents vague internal links such as “learn more” from doing all the navigational work.

    Give each decision one clear page owner

    A large query graph does not justify a large number of pages. The useful operating principle is Query Deserves a Page: give a query its own URL when it requires an independent answer, not merely because its wording differs.

    Create a dedicated page when the decision changes

    • The searcher needs a different outcome, such as comparing products rather than learning the category definition.
    • The answer requires distinct evidence, entities, assumptions, or selection criteria.
    • The query calls for a different content structure, such as a side-by-side comparison, an implementation procedure, or a troubleshooting path.
    • The appropriate next action differs from the action on the broader page.
    • The page can stand on its own without repeating most of another URL.

    Keep the answer on an existing page when only the wording changes

    • The modifier does not materially alter the answer.
    • The same evidence and recommendation would support both queries.
    • A focused section, table row, or clearly labeled subsection can answer the question completely.
    • A new URL would need a generic introduction and conclusion simply to surround a small amount of unique information.
    • The proposed page would compete with an established URL for the same intent.

    Maintain a page-ownership map with a primary query family, supporting queries, decision stage, required evidence, incoming handoff, and outgoing handoff for every URL. When several pages claim the same query family, choose one owner. Merge, narrow, or reposition the others. Adding more internal links between competing pages does not resolve unclear ownership.

    Be careful when consolidation changes URLs. Preserve established URLs when you can. If a move is necessary, map each old URL and important resource to its equivalent, implement redirects at the infrastructure level, and avoid combining the migration with unrelated changes to content, design, and URL structure. Incomplete resource redirects and simultaneous changes make search-engine adaptation and diagnosis harder, particularly when image or video URLs are replaced.

    Make every page easy to extract, trust, and continue from

    A page in a multi-query journey has three jobs. It must answer its assigned question, give the answer layer a clear passage it can evaluate, and prepare the searcher for the next decision. A long page can fail all three if its actual answer is buried beneath positioning language.

    In a Google AI Overview, a brand can buy an adjacent ad, but it cannot buy inclusion in the generated answer. The page must earn consideration as a cited resource. That makes answer quality, entity clarity, evidence, and technical accessibility part of the same SEO task.

    Match the format to the query’s job

    • Use a concise definition and explicit scope for “what is” queries.
    • Use consistent criteria, parallel descriptions, and visible trade-offs for comparison queries.
    • Use prerequisites, ordered actions, checkpoints, and failure conditions for implementation queries.
    • Use the limitation, its practical consequence, who it affects, and the available response for objection queries.
    • Use selection criteria and switching implications for alternative queries, rather than publishing an unqualified list of names.

    This structural match matters because the searcher should be able to recognize the answer format immediately. It also reduces the amount of interpretation required to connect the page with the query template. A comparison query should not force the reader to assemble a comparison from unrelated product descriptions.

    Build the answer before the promotion

    1. State the direct answer and its scope near the beginning of the page. Name the entity, audience, and situation instead of relying on pronouns or implied context.
    2. Define the decision criteria before naming a winner or recommendation. This lets the reader test whether your conclusion applies to them.
    3. Show the evidence behind each material claim. Separate facts, assumptions, and editorial judgments.
    4. Include meaningful limitations. A page that omits obvious trade-offs may generate impressions, but it is less useful at the validation stage where the searcher is actively looking for risk.
    5. End each major section with the logical next question, then link to the page that owns it. Use anchor text that names the decision rather than a generic invitation to continue.

    Keep answer passages self-contained enough to remain understandable when separated from the surrounding page. A heading, direct answer, qualifier, and supporting detail should form a coherent unit. Do not turn that advice into repetitive mini-answers; each section still needs a distinct purpose.

    JSON-LD should reinforce the visible page, not invent a cleaner version of it. Keep the named entity, page purpose, relationships, and factual claims consistent between the markup and the content a visitor can read. Structured data can clarify an already coherent page, but it cannot repair a page that mixes several intents without a clear centerpiece.

    Keep the technical centerpiece visible

    Your primary answer, comparison, product facts, or interactive tool should not disappear when client-side JavaScript fails or is delayed. Serve the essential content in accessible HTML where possible, reduce unnecessary DOM complexity, keep response times under control, and verify that structured data remains accurate after template changes. A documented QR-code project treated its generator as the page’s centerpiece and made it available without requiring JavaScript rendering.

    Run the same check across the journey, not only on the broad hub. Comparison, limitation, migration, and integration pages can be the decisive resources even when they attract fewer visits. If those pages are slow, inaccessible, orphaned, or missing from navigation, the content network breaks at the point where intent is strongest.

    Measure the journey as a connected demand system

    Glowing particles travel between linked page-like platforms in a looping digital landscape while translucent signals illuminate the full journey.

    Rank tracking by individual keyword cannot show whether visibility at one step assists performance at another. Group reporting by query family and decision stage. Keep the underlying query-level data, but add the journey context needed to interpret it.

    A practical scorecard should include:

    • Query family, template, entity, attribute, and decision stage.
    • The URL that owns the query and the pages that hand searchers into and out of it.
    • AI Overview presence, brand mention, citation status, and the exact URL cited when one is visible.
    • Organic impressions, clicks, click-through rate, landing page, and conversions for the query family.
    • Paid impressions, click-through rate, cost, and conversions for the same family where campaigns are active.
    • On-site movement from broad pages into comparison, validation, and action pages.
    • Observation context and date so AI-result checks can be repeated consistently.

    Do not treat an AI citation as an isolated vanity metric. Among the same 53 brands, citation inside an AI Overview was associated with 35% more organic clicks and 91% more paid clicks on the corresponding queries. That relationship did not establish that the citation caused the lift, and the paid sample was small. It is still a good reason to test citation status alongside organic and paid performance rather than placing it in a separate report.

    The operating loop is straightforward:

    1. Select a query family tied to a meaningful business decision.
    2. Record its current AI, organic, paid, and on-site visibility by journey stage.
    3. Identify whether the weakness is missing coverage, unclear page ownership, weak evidence, inaccessible content, or a broken handoff.
    4. Change the smallest part of the system that can resolve that weakness.
    5. Measure visibility, clicks, and downstream actions separately. A citation can rise without traffic rising, while paid or branded demand may change elsewhere in the loop.
    6. Use the result to update the query graph, then move to the next unresolved decision.

    Keep SEO and paid-search teams on the same query map. SEO owns much of the work required to become a credible citation, while paid search may capture demand after the answer layer has narrowed the shortlist. Shared reporting should therefore focus on the movement of demand, not a contest over which channel receives the final-click credit.

    Start with the revenue-relevant topic where your broad visibility is strongest but your comparison or validation coverage is weakest. Map the likely follow-up questions, assign each decision to a page, fix the most consequential gap, and connect the pages in both directions. Then review AI citations, organic clicks, and paid response as one query family. You will learn whether you merely answered the opening question or remained useful until the choice was made.

    References


  • AI Search Optimization Strategy: A Practical Framework

    AI Search Optimization Strategy: A Practical Framework

    You can rank well in Google and still disappear when someone asks an AI assistant which vendor, product, or approach fits their situation. Publishing more AI-written pages rarely closes that gap. Your business has to be easy to find, easy to understand, and easy to verify.

    A workable AI search optimization strategy connects traditional SEO, answer-ready content, and independent authority signals. It also gives you a repeatable way to diagnose why you are missing from an answer, so each change addresses an identifiable problem.

    Optimize for the whole recommendation path

    An isometric network guides several candidate solutions through evidence and validation gates toward one highlighted recommendation.

    AI visibility is often treated as a content-formatting exercise. Formatting matters, but it is only one part of the path from a user’s question to a recommendation. Your strategy has to perform three jobs:

    • Retrieval: Make the right pages and third-party mentions discoverable for the language your buyers use.
    • Extraction: State your category, specialization, evidence, and limitations clearly enough that a system can reuse them without guessing.
    • Corroboration: Support important claims with reviews, comparison pages, awards, accreditations, affiliations, directories, and customer evidence outside your own website.

    Traditional rankings contribute directly to retrieval. Pages holding the top three to five organic positions were almost always read first in live-search testing, while pages in positions six through twenty were more likely to be consulted when the leading results lacked the necessary detail. Unindexed pages were effectively unavailable unless a system received a direct route to them. These are test-derived observations rather than permanent platform rules, but they give you a sensible order of operations: fix discoverability before trying to optimize how an invisible page is quoted.

    External recommendation pages deserve equal attention. Estimated weights for authoritative list mentions reached 41% for ChatGPT, 49% for Google AI Overviews and Gemini, and 38% for Claude in one 2026 weighting model. Those percentages are not official algorithm disclosures, and they should not be treated as literal shares of a platform’s ranking formula. They are useful as directional evidence that prominent, relevant comparison pages can matter more than another unsupported claim on your own site.

    This gives you a simple diagnostic:

    • If your pages and credible mentions cannot be found for the query, you have a retrieval problem.
    • If your page is cited but the answer omits or misstates your differentiator, you have an extraction problem.
    • If competitors are recommended while your claims appear only on your own website, you probably have a corroboration problem.
    • If you are mentioned for the wrong customer or use case, you have a positioning problem that should be corrected before you pursue more exposure.

    Do not begin with a favorite tactic. Begin with the missing job. Schema cannot repair weak discovery, publisher outreach cannot clarify an ambiguous product page, and more copy cannot manufacture independent evidence.

    Win the pages AI systems already use for decisions

    Start with the questions a buyer asks immediately before making a shortlist. Use the exact category, comparison, specialization, and validation language that appears in the decision. A useful prompt inventory includes queries such as best category for a particular use case, one option versus another, category alternatives, brand reviews, and which providers hold a relevant accreditation.

    Run those prompts in the AI surfaces that matter to your audience. Record which businesses appear, which attributes are repeated, and which URLs are cited when citations are visible. Then search the same language traditionally. You are looking for the pages that repeatedly shape the answer: comparison lists, directories, review profiles, industry resources, and high-ranking explanatory pages.

    For this purpose, an authoritative page is not merely a domain with a high third-party score. It should address the same decision, compare the relevant category, use understandable criteria, and be visible for the query itself. A famous publication with a generic mention may contribute less useful context than a focused industry resource that explains exactly who each option suits.

    Earn inclusion with a verification package

    When a relevant list excludes your company, make the editor’s verification work easier. Send a concise package containing:

    • Your precise category and the customer or use case you serve best.
    • The specialization that distinguishes you from the companies already listed.
    • Links supporting any awards, accreditations, or affiliations you claim.
    • Published customer examples or usage data that support adoption and fit.
    • Your canonical company and product URLs, using the name you want represented consistently.
    • A factual correction if the page already contains outdated or inaccurate information about you.

    Do not ask an editor to declare you the best without evidence. Ask to be evaluated for the correct category, and supply the material needed to make that evaluation. This produces a more defensible mention and reduces the chance that your positioning is flattened into a generic company description.

    Publish a comparison resource only when it can stand on its own

    You can also create a comparison page that deserves to rank. A useful format places a summary table near the top and follows it with substantive analysis of every entry. Define the criteria, apply the same fields to each option, disclose relevant commercial relationships, and explain the situations in which different choices make sense.

    A self-published list should resolve a buyer’s decision, not disguise a promotional page as independent analysis. Include meaningful alternatives and limitations. If the only conclusion the methodology can produce is that your company wins every category, the resource will not help a careful reader evaluate anything.

    Treat directories as identity and trust infrastructure

    Prioritize directories and databases that real participants in your market recognize. Complete the relevant fields, choose the correct category, link to the canonical site, and keep the brand name and specialization consistent. Do not spread contradictory descriptions across dozens of low-value profiles. The goal is a coherent external record that confirms what the company is and where it belongs.

    Make every important claim extractable and corroborated

    Your page should let a reader locate the answer quickly and let a machine isolate the same passage. Clear headings, short paragraphs, bullets, comparison tables, concise answers, and query-aligned keywords all support that job. The point is not to make every page short. It is to remove the distance between a question and the evidence-backed answer.

    Use a decision-page anatomy

    For an important category or use-case page, include these elements in a logical sequence:

    • A direct category statement: Name what the product or service is without relying on a slogan.
    • A qualified fit statement: Identify who it is for, the problem it addresses, and any condition that changes the answer.
    • A comparison structure: Use a table only when several options share the same meaningful dimensions.
    • Evidence beside the claim: Place the customer example, accreditation, data, or external reference close to the sentence it supports.
    • Limitations: State where the offering is not the right fit. Qualification is more useful than universal superiority language.
    • Consistent terminology: Use the phrases buyers use for the category while preserving accurate technical language.

    Concise writing is not shallow writing. Put the direct answer first, then supply the method, evidence, exceptions, and detail needed to trust it. Do not make a system infer your specialization from a case study buried several screens below an abstract brand message.

    Apply structured data after the visible evidence layer is correct. JSON-LD can clarify entities and relationships, but it cannot turn an unsupported superlative into independent proof. The page should remain understandable if its markup is removed, and the markup should describe only information you can substantiate on the page or through a legitimate reference.

    Build an evidence matrix before rewriting copy

    List every important claim you want an AI answer to repeat. Then identify both the owned explanation and the external evidence that could corroborate it.

    Claim you want to earnWhat your page should explainUseful external corroboration
    Fit for a specialized customerThe qualifying use case, requirements, and limitationsA relevant comparison list or customer example
    Recognized professional standingThe credential, issuing body, scope, and statusAn accreditation, award, or affiliation record
    Meaningful customer adoptionWhat the usage measure represents and where it appliesThird-party usage data or a published customer account
    Positive customer experienceAn accurate description of support and product expectationsLegitimate reviews on a relevant review platform
    Established category identityA consistent company name, category, and specializationA trusted database or industry directory profile

    Platform weighting was not uniform in the available testing. Awards, accreditations, and affiliations received weights across ChatGPT, Google, and Claude; reviews received ChatGPT and Google weights but no Claude weight; customer examples and usage data appeared for ChatGPT and Claude; Google website authority was specific to Google; and social sentiment appeared as a smaller ChatGPT factor. Traditional databases and directories were especially prominent in the Claude model.

    Use those differences as a reason to diversify credible evidence, not to create a separate version of reality for each engine. A durable authority profile combines strong owned pages with accurate external records, real customer evidence, and editorial mentions relevant to the buying decision.

    Run AI visibility as a repeatable operating cycle

    Four connected workstations form a circular process around a glowing knowledge core, with outside source beacons supporting the loop.

    An AI answer is not a fixed organic rank. Measure a stable set of decisions and preserve enough context to tell whether an apparent change is meaningful.

    1. Define the eligible prompt set. Include only questions for which your business could truthfully be a relevant answer. Group them by discovery, comparison, validation, and use case.
    2. Capture a baseline. Record the exact prompt, model or surface, access mode when known, answer text, cited URLs, brands mentioned, fit description, and date.
    3. Classify each absence. Mark it as a retrieval, extraction, corroboration, or positioning gap. This turns an ambiguous visibility problem into a specific work queue.
    4. Make the smallest coherent intervention. Improve ranking and internal linking for retrieval, restructure the answer passage for extraction, pursue credible external evidence for corroboration, or correct inconsistent category language for positioning.
    5. Repeat the same prompts and inspect the path. Look beyond whether the brand appears. Check which pages were retrieved, which claims survived, and whether the recommendation describes the right customer fit.
    6. Feed the result back into the backlog. Route technical discovery problems to SEO, ambiguous answers to content, external proof gaps to public relations or reputation work, and inconsistent company records to the owner of directory data.

    Track measures that correspond to those jobs:

    • Eligible-prompt inclusion rate: the share of relevant prompts in which the brand receives a valid mention.
    • Citation coverage: the share that cites your site or an independent page validating the relevant claim.
    • Accurate-fit rate: the share of mentions that describe your specialization and limitations correctly.
    • External evidence coverage: the share of priority claims supported by a credible third party.
    • Retrieval coverage: the share of priority queries for which an owned page or qualified external mention is visible in traditional results.

    Do not collapse everything into one visibility score. A brand can appear frequently for the wrong reason, be cited without being recommended, or be recommended to customers it cannot serve. Keep inclusion, accuracy, citations, and commercial relevance separate.

    Timing also requires restraint. AI answers may rely on stored training patterns or live search results, so a newly published correction does not guarantee an immediate, uniform change across systems. Report what changed in the observable answer path; do not promise a universal refresh deadline.

    Key takeaways

    • AI search optimization has three core jobs: retrieval, extraction, and corroboration.
    • Traditional SEO remains a discovery layer because live-search systems often consult highly ranked pages first.
    • Relevant comparison lists can be powerful recommendation surfaces, but test-derived weights are not official platform formulas.
    • Write direct, qualified answers and place evidence beside the claims it supports.
    • Use JSON-LD to clarify accurate visible content, not to compensate for missing proof.
    • Measure a repeatable prompt set and classify each gap before choosing a tactic.

    Start with the buyer decision closest to your actual business value. Map the pages shaping that decision, repair the most important answer on your own site, and pursue the strongest missing external proof. That sequence gives you an AI search backlog tied to a reason for absence, rather than a collection of disconnected optimization tasks.

    References


  • How Community Signals Influence AI Software Buyer Research

    How Community Signals Influence AI Software Buyer Research

    When a software buyer asks an AI assistant which product fits their situation, your website is only one witness. The answer may also draw on a Wikipedia entry, a Reddit discussion, a LinkedIn post, a review platform and whatever those places imply about your category, reputation and fit.

    Your job is not to manufacture praise or flood communities with links. It is to make accurate product facts, useful expertise and authentic customer context available wherever buyers test their assumptions. That requires an always-on community strategy tied to buyer questions, not a campaign built around accumulating mentions.

    Your website is only one layer of the AI answer

    Owned content remains the foundation. In a US-only sample of SaaS-related ChatGPT citations from December 2025, vendor domains accounted for 66.7% to 71.8% of cited domains at every buyer-journey stage. You still need clear product pages, comparison content, documentation, pricing context and use-case explanations.

    The outside authority layer is substantial, though. User-generated content platforms held 17.1% of cited-domain share overall, compared with 4.0% for publishers. That made UGC the largest third-party class in this particular SaaS prompt set, ahead of both publishers and review platforms.

    Community is an umbrella term here, not a synonym for discussion forums. The UGC classification included Reddit, Wikipedia, Quora, YouTube and LinkedIn. Those platforms have different rules, content formats and levels of brand control. Treating them as one channel would produce a neat dashboard and a poor operating plan.

    The important pattern is persistence across the journey. UGC represented 17.8% of cited domains in discovery, 18.2% in exploration, 15.1% in evaluation and 17.2% in focused evaluation. Its range across those stages was only 3.1 percentage points.

    Buyer-journey stepUGC cited-domain shareWhat your community work needs to provide
    Discovery17.8%Language that helps buyers recognize the problem, its causes and the kind of solution they may need.
    Exploration18.2%Use cases, selection criteria, implementation realities and meaningful tradeoffs.
    Evaluation15.1%Evidence that helps a buyer decide which products belong on the shortlist.
    Focused evaluation17.2%Specific context for choosing between finalists, including fit, limitations and switching concerns.

    Review platforms follow a more purchase-intent-heavy pattern. Their share rose from 7.4% in discovery to 13.2% in evaluation, then fell to 8.4% in focused evaluation. Reviews are therefore well suited to shortlist formation, while community evidence needs attention before, during and after that point. You need both; they do different jobs.

    Brand-only monitoring will hide much of this influence. More than half of the prompts in the SaaS sample used commercial language, but only 1.5% named a vendor. Buyers often ask about the problem, category, workflow or alternatives before they ask about you. If your tracking begins with your brand name, it begins too late.

    Do not turn 17.1% into a universal AI-search benchmark. The measurement covered one engine, one country, one month and software vendor-seeking prompts. It measured share of unique cited domains rather than raw citation volume, with duplicate appearances reduced to one record per run, intent and domain. Use the pattern to set priorities, then establish a baseline for your own market.

    Map community work to buyer questions, not brand mentions

    A strategist and community members arrange visual evidence around a software buyer's needs, including compatibility, security, implementation and peer reassurance.

    A community plan should begin with the decision a buyer is trying to make. Starting with a platform usually leads to an output target such as posting more often. Starting with the decision gives you a coverage target: the questions for which buyers still lack a credible, specific answer.

    1. Build a decision inventory. Pull recurring questions from sales notes, support conversations, product onboarding, site search and relevant community discussions. Sort them into discovery, exploration, evaluation and focused evaluation. Preserve the buyer’s language instead of rewriting every question as a branded keyword.
    2. Separate factual gaps from experiential gaps. A factual gap might concern an integration, security requirement, deployment model or product limitation. An experiential gap concerns what implementation feels like, which tradeoff mattered or what kind of team is a poor fit. Your site should settle the first. Credible practitioners and customers are often better positioned to explain the second.
    3. Audit the current answer environment. Run a fixed set of non-branded, category and comparison prompts in the AI systems your buyers use. Save the exact prompt, answer, citations, date and market. Search the cited community domains separately so you can see the context the AI answer compressed or omitted.
    4. Create a canonical answer on your own site. Give each important question a stable, indexable destination containing the direct answer, relevant conditions, evidence and limitations. If a fact exists only in a community reply, you have no controlled reference to update when the product changes.
    5. Contribute expertise where the question already lives. Let a qualified employee answer in their own voice, disclose the affiliation when relevant and address the question before mentioning the product. A useful answer should remain useful even if its link is removed.
    6. Enable voluntary customer participation. Ask customers whether they are willing to describe the problem, decision criteria and outcome in their own words. Do not supply praise, require identical phrasing or disguise an incentive. A scripted chorus is neither trustworthy community evidence nor a durable reputation strategy.

    Good community contributions have a recognizable shape. They answer the question promptly, state who the advice fits, acknowledge a meaningful tradeoff, distinguish verifiable facts from opinion and disclose any relationship that could affect credibility.

    • Direct answer: Give the conclusion before the product link or background story.
    • Conditions: Explain what must be true for the recommendation to hold.
    • Non-fit: Say when another approach or product type would make more sense.
    • Evidence: Link to documentation, methodology or a canonical product fact only when it helps the reader verify the claim.
    • Disclosure: Make employment, sponsorship, incentives or customer status visible rather than leaving the audience to discover it.

    This approach changes the goal from mention generation to question coverage. A category expert can help a buyer understand a decision even when your product is not the answer. That restraint is part of what makes the contribution credible when your product genuinely is relevant.

    Keep the three authority layers connected. Your owned content should hold canonical facts. Independent reviews and coverage should validate claims that require outside proof. Community contributions should add lived context, objections and edge cases. If those layers contradict one another, increasing their volume will only amplify the inconsistency.

    Use each community platform for the role it can support

    Platform concentration can tempt you into a one-channel strategy. In the SaaS citation sample, Wikipedia, Reddit and LinkedIn accounted for 99% of UGC citations. The remaining UGC platforms shared the final 1%. That concentration describes what appeared in those ChatGPT answers; it does not guarantee the same mix for another engine, market, category or month.

    Wikipedia: maintain a factual backbone, not a sales surface

    Wikipedia alone contributed 10.1 to 14.0 percentage points of the roughly 17-point UGC share, depending on the journey stage. It was the largest single third-party domain in the measurement and exceeded the entire review-platform class at every stage except evaluation.

    That does not make Wikipedia a conventional acquisition channel. Treat it as a place where neutral, verifiable facts may be represented, not where positioning language belongs. If your organization is already covered, monitor the factual record for errors and use transparent, policy-compliant correction processes. If it is not covered, do not manufacture apparent notability or turn a company description into promotional copy.

    Your controllable work happens upstream: keep public facts consistent, make important claims verifiable and avoid changing basic descriptions from one channel to another. Wikipedia exposure may be difficult to influence directly, but factual inconsistency is firmly within your control.

    Reddit: answer decisions, objections and edge cases

    Use Reddit to understand how practitioners frame a problem when they are not following your navigation or campaign language. Look for recurring questions, rejected options, implementation complaints and conditions that change the recommendation. Feed those findings into product documentation and your buyer-question inventory.

    Participation should be selective. A product specialist can correct a material error or explain a technical tradeoff with a clear affiliation. They should not revive unrelated threads, coordinate praise, use undisclosed accounts or treat every category discussion as an opening for a link. Community members can distinguish help from distribution pressure.

    Reddit’s AI visibility also moves. Its visibility fell 11.7% and its AI mentions fell 10.9% in the 28 days ending June 8, 2026; three weeks later, the direction moved the other way. A snapshot can therefore mislead you about both the platform’s importance and the success of recent activity.

    LinkedIn: make practitioner expertise attributable

    LinkedIn is useful when a buyer benefits from knowing who holds an opinion and what professional context shaped it. Product leaders, engineers, operators and customer-facing specialists can explain how they evaluate a decision, what they would check first and where a popular rule breaks down.

    Avoid turning employee advocacy into synchronized copy. Give specialists a question, the underlying facts and the disclosure requirements, then let them write from their own expertise. Distinct reasoning is more useful than several accounts publishing the same approved claim.

    YouTube, Quora and smaller communities: follow the buyer

    A small share in one citation sample is not proof that a platform has no value. A technical category may rely on long-form demonstrations. A niche buyer group may gather in a specialist forum that barely registers in aggregate data. Before allocating effort, check whether your actual buyers use the platform to investigate the decisions in your inventory.

    Build portable assets rather than dependence on one domain: a maintained question taxonomy, qualified subject-matter experts, verifiable claims, demonstrations and clear explanations of tradeoffs. Those assets can move when buyer behavior or AI citation patterns move.

    Measure answers, citations and business effects separately

    An analyst observes separate layers representing an AI answer, supporting community sources and a buyer progressing toward a software decision.

    Raw mentions do not tell you whether an AI answer includes your brand, represents it accurately or helps the right buyer make a decision. Track those outcomes separately. Otherwise, a burst of community activity can look successful while the answer remains wrong or the resulting interest remains irrelevant.

    1. Fix the prompt set. Include non-branded problem prompts, category exploration, shortlist questions, focused comparisons and recurring objections. Do not overweight branded prompts simply because they are easier to monitor.
    2. Record the environment. Store the engine, date, market, exact prompt and any relevant account state. Keep results from different engines separate rather than blending them into one visibility score.
    3. Capture the answer and its citations. Log whether your brand appears, what role it is assigned, which claims are made, whether caveats are preserved and which root domains support the response.
    4. Classify the evidence. Tag each cited domain as owned, community, review, publisher or another useful class. Tag the prompt by journey stage. This lets you see whether a visibility gap belongs to a question, a stage or a source type.
    5. Connect visibility to qualified behavior. Review community referrals, assisted conversions, sales-call mentions and the buyer questions entering your pipeline. Treat these as separate signals; do not claim that a citation caused revenue merely because both changed at the same time.

    Your scorecard should make several distinctions explicit:

    • Answer inclusion rate: the share of eligible monitored prompts in which your brand appears.
    • Citation coverage: the share of monitored prompts supported by relevant third-party domains, with community domains visible as their own class.
    • Narrative accuracy: whether each material claim is correct, outdated, misleading or unverifiable.
    • Buyer-question coverage: the share of priority questions with both a maintained owned answer and credible outside context.
    • Source concentration: how much of your observed third-party visibility depends on one platform or domain.
    • Qualified-demand signals: whether the people arriving from or mentioning community research fit the use cases you can serve.
    Observed patternWhat to inspectNext action
    Competitors appear in non-branded category prompts, but you do notMissing category explanations, unclear use-case fit or absent community expertiseStrengthen the canonical answer, then contribute to existing discussions where your expertise is genuinely relevant.
    Your brand appears, but important claims are wrongStale owned pages, conflicting descriptions or repeated third-party errorsCorrect the canonical facts first, then address prominent community inaccuracies transparently.
    Answers are accurate, but citations depend on one community domainPlatform concentration and weak evidence portabilityAdapt useful expertise to other buyer-relevant formats without duplicating the same promotional message.
    Community mentions increase, but qualified demand does notPrompt relevance, audience fit and brand positioningRefine the buyer-question set before producing more community activity.
    Review platforms appear during evaluation, but earlier-stage community coverage is weakDiscovery and exploration questionsDevelop category education and practitioner explanations that help buyers before a shortlist exists.

    Cross-engine consistency is especially important. With 91% of citations appearing in only one engine in the available consensus context, a ChatGPT result should not be treated as a universal AI-search result. Measure each engine your buyers use and look for repeated patterns rather than declaring success from one captured answer.

    Use a fixed review cadence and preserve historical captures. When visibility changes, check whether the cited domains changed, the answer changed, or both. If you also changed several pages and launched a large community push, you may know that the system moved without knowing why. Where practical, change one class of activity at a time and label causal claims as hypotheses until repeated observations support them.

    Key takeaways

    • Owned content remains the base, but community platforms formed the largest third-party citation class in the SaaS ChatGPT sample.
    • Community evidence appeared across discovery, exploration, evaluation and finalist comparison, so it needs an always-on operating model rather than a bottom-of-funnel campaign.
    • Build coverage around non-branded buyer questions. Most commercial prompts in the sample did not name a vendor.
    • Give each platform a distinct role: factual stewardship for Wikipedia, decision context for Reddit, attributable practitioner expertise for LinkedIn and audience-led investment elsewhere.
    • Measure answer inclusion, citation coverage, narrative accuracy, question coverage, source concentration and qualified demand as separate signals.
    • Do not buy, script or disguise community sentiment. Transparent expertise and voluntary customer language are the durable assets.

    Start with one decision your next buyer is struggling to make. Build the prompt set, document the current answers and identify one missing canonical fact and one missing piece of practitioner context. Close those gaps, contribute where the question already exists, and rerun the same prompts. That is a community-signal program you can improve without pretending you control the community.

    References


  • How AI Search Changes Publisher Traffic and SEO Strategy

    How AI Search Changes Publisher Traffic and SEO Strategy

    Your search visibility can look intact while the business result weakens. A page may still rank, yet an AI answer can resolve the reader’s question before a visit occurs. If you publish news, analysis, or expert guidance, your work can influence the answer without producing the session that funds it.

    That does not make SEO obsolete. It means you must stop treating rankings, clicks, citations, and commercial value as interchangeable outcomes. The practical response is to diagnose where traffic is being lost, measure AI visibility separately, and give every important page two jobs: supply a clean answer and offer something the answer surface cannot replace.

    A ranking no longer guarantees a visit

    Traditional search encouraged a simple mental model: a query produced a results page, the user chose a listing, and the publisher received a visit. AI search inserts an answer layer between the query and the organic result. Google AI Overviews can appear above traditional listings, while answer engines such as ChatGPT and Perplexity can synthesize material from several publishers into a response.

    This creates three distinct outcomes. Your page can be cited and clicked, cited without a click, or excluded from the answer entirely. Only the first produces both visibility and an attributable visit. The second may contribute to recognition or authority, but it does not create an ad impression, subscription opportunity, lead, or ecommerce session by itself.

    The economic tension is already visible. Nearly 300 French newspapers filed a complaint with France’s competition authority, alleging that Google launched AI-generated summaries without their approval, reduced visits to original reporting, and breached commitments connected to a 2022 compensation agreement. Those are publisher allegations, not a universal estimate of traffic loss, but they identify the central problem clearly: being used in an answer is not the same as being paid, visited, or even visibly credited.

    Key takeaways

    • Do not diagnose an aggregate organic decline as an AI problem until you inspect affected queries and landing pages.
    • Keep SEO metrics, AI citations, AI referrals, and business outcomes in separate reporting layers.
    • Make priority pages easy for machines to interpret without making them unnecessary for people to visit.
    • Build concentrated authority around a defined subject instead of spreading limited publishing capacity across unrelated topics.
    • Treat crawler access, content licensing, and compensation as governance decisions, not routine SEO settings.

    Before changing your editorial strategy, classify the pattern you are actually seeing. The following checks will not prove causation, but they will tell you where to investigate next.

    Observed patternWhat it may indicateWhat to check next
    Rankings and impressions are broadly stable, but clicks or click-through rate fallThe results interface or the appeal of your listing may have changedReview the live result for affected queries, including AI answers and other search features; also check whether your title and description still match the intent
    Rankings, impressions, and clicks all declineA conventional discoverability, demand, or competitive problem may be responsibleInvestigate crawling, indexing, query demand, ranking changes, content quality, and competing coverage before blaming AI
    Organic clicks decline while referrals from AI interfaces appearSome discovery may be shifting between channelsCompare landing pages, conversion outcomes, and the questions that produced each type of visit
    AI citations or brand mentions rise without referral trafficYour influence may be increasing without a corresponding audience transferDecide whether that exposure supports a measurable business objective; do not record it as traffic

    The first row deserves particular care. Stable rankings plus falling clicks are consistent with a results-page interception problem, but they do not prove that an AI answer caused it. Search features, changing intent, weak snippets, seasonality, and shifts in demand can produce similar symptoms. Inspect the query and its current result before rewriting the page.

    Measure traffic and AI influence as separate outcomes

    Two glass chambers separately show glowing footprints entering a publisher portal and source cards feeding light into an answer orb.

    A publisher dashboard built only around sessions will miss influence that occurs inside an answer engine. A dashboard built only around citations will hide whether that influence has any business value. Your measurement system therefore needs two ledgers that can be examined together without being collapsed into a vague visibility score.

    The traffic ledger

    • Impressions and ranking visibility: whether your pages remain eligible and visible for the queries that matter.
    • Organic clicks and click-through rate: whether search visibility still transfers an audience to your site.
    • Landing-page sessions: which content actually receives the visit.
    • Meaningful outcomes: subscriptions, registrations, leads, purchases, ad-supported page consumption, or another result tied to your publishing model.

    Google Search Console, ranking data, and organic traffic remain relevant even when AI answers are present. They reveal whether traditional search visibility is shrinking, holding, or converting differently. Do not remove these metrics merely because a new discovery channel has appeared.

    The influence ledger

    • Prompt citation presence: whether your domain or a specific URL is referenced for important audience questions.
    • Brand mentions: whether the answer names you even when it does not provide a clickable citation.
    • Cited-page distribution: which pages answer engines select, rather than which pages you hoped they would select.
    • AI referral traffic: visits that arrive from identifiable AI interfaces.
    • Recurrence over time: whether visibility persists across audits instead of appearing in an isolated response.

    A combined SEO and GEO program should track prompt citations, AI referrals, and brand-mention frequency alongside conventional organic metrics. The distinction matters because a citation without a visit is an influence event, while a referral is a traffic event. Neither should be credited with revenue until your analytics connects it to a meaningful outcome.

    Run prompt audits as controlled observations, not as demonstrations prepared for a meeting. Start with a stable set of questions that represents the information, comparison, and decision tasks your audience brings to search. For every check, retain the exact prompt, platform, date, resulting answer, cited domains, linked pages, brand mentions, and notable competitors. Keep the wording and evaluation rules consistent when you compare periods.

    Do not call an isolated answer a ranking. Generated responses can vary, and a single favorable result does not establish durable visibility. Look for repeated selection across your prompt set and across successive audits. If you change the prompts, platform context, or scoring rules, mark the break in your reporting so a methodology change is not mistaken for growth.

    Your final dashboard should answer four different questions: Were you discoverable? Were you selected or cited? Did the person visit? Did the visit or exposure create value? When those questions occupy separate fields, a traffic decline cannot be disguised by a rising citation count, and genuine AI visibility will not disappear inside an organic sessions chart.

    Make priority pages citation-ready and visit-worthy

    A layered article pavilion offers a glowing fragment to a hovering search orb while a visitor enters an open passage containing richer research and visual material.

    Trying to force every answer behind a click is a poor response to AI search. If a page is vague, evasive, or structurally confusing, it becomes harder for both readers and machines to use. The better design offers an extractable answer while reserving meaningful depth for the page itself.

    Create an extractable answer layer

    • State the page’s central answer early in a short, self-contained paragraph.
    • Name the relevant organization, person, product, place, method, or concept explicitly instead of relying on pronouns and implied context.
    • Define specialized terms before using them to carry the argument.
    • State the scope and conditions of the answer, especially when it applies only to a particular market, platform, date, or audience.
    • Use descriptive headings that correspond to real follow-up questions.
    • Keep authorship, publication context, evidence, and update information easy to locate.
    • Add accurate structured data that matches what a reader can see on the page. JSON-LD can clarify entities and relationships, but it is not a switch that guarantees an AI citation.

    Clear entity definitions and direct answers make content easier to retrieve and summarize. They also reduce a common editorial failure: publishing a sophisticated page that never states its conclusion plainly enough for a reader to confirm that it answers the query.

    Build a reason to visit beyond the summary

    The extractable layer should not contain the page’s entire value. Give the reader something that cannot be reproduced faithfully in a short synthesis: original reporting, primary documents, full data tables, a transparent methodology, detailed examples, local context, a useful tool, a decision framework, or careful treatment of exceptions.

    This is not permission to tease an answer and withhold it. The page should resolve the stated question. Its deeper layer should help the reader verify the conclusion, apply it to a particular situation, or make the next decision. A thin page with a clear answer may be easy to summarize but unnecessary to visit. A deep page with no clear answer may be valuable but difficult to retrieve. You need both layers.

    Build topical depth around the page

    AI visibility is better approached as a body of coherent expertise than as an optimization added to an isolated URL. A team with limited capacity should define a narrow area it can cover consistently, map the questions surrounding that area, and assign a clear purpose to each page. Specificity, depth, and consistency can be more useful than publishing indiscriminately at high volume.

    • Choose the boundary: identify the subject, audience, and decisions the cluster will serve.
    • Map distinct intents: separate definitions, current developments, comparisons, procedures, objections, and decision questions rather than forcing them into duplicate pages.
    • Assign canonical coverage: give each important intent a primary page and update that page instead of repeatedly starting over.
    • Connect the cluster: use contextual internal links that explain how supporting pages relate to the central subject.
    • Remove contradictions: reconcile outdated definitions, numbers, names, and recommendations across the cluster.
    • Show expertise: identify where first-hand reporting, specialist analysis, or original evidence materially improves the answer.

    This architecture helps machines associate your publication with a defined subject, but it also improves the human journey. A reader who arrives for a concise answer can move into evidence, context, and adjacent questions without returning to search.

    Protect content rights without making blind SEO tradeoffs

    AI search turns content access into a governance issue as well as a traffic issue. Editorial, audience, product, commercial, technical, and legal teams may value the same crawler or answer surface differently. The SEO team wants discoverability. The commercial team wants visits or licensing value. The newsroom wants attribution. Legal counsel may need to interpret agreements and jurisdiction-specific rights.

    The French newspaper dispute shows why those decisions cannot be reduced to a crawler setting. APIG alleges that AI Overviews were introduced without publisher approval and violated commitments under a compensation arrangement. Google maintains that AI Overviews help people ask more complex questions, discover content, and manage how publisher material appears. The complaint has not, by itself, settled those competing claims.

    The surrounding enforcement history raises the stakes: France’s competition authority fined Google €250 million in 2024 for failing to comply with parts of the 2022 agreement. That does not establish what another publisher is entitled to in another jurisdiction. It does mean access, compensation, and competitive effects should be reviewed as real business risks rather than left to an informal SEO decision.

    • Inventory exposure: document which content classes are open to search engines, answer engines, partners, feeds, archives, and licensed distributors.
    • Map economic value: identify which sections depend on advertising, subscriptions, lead generation, ecommerce, syndication, licensing, or reputation.
    • Preserve evidence: retain traffic histories, referral records, prompt-audit captures, cited URLs, contracts, and relevant platform communications.
    • Review current controls: confirm what each platform’s present controls actually govern. Crawling for search discovery, answer generation, snippets, and model-related uses should not be assumed to be the same function.
    • Model the tradeoff: estimate what happens if a content class loses search visibility, loses AI visibility, gains licensing value, or receives citations without visits.
    • Assign decision authority: require technical, editorial, commercial, and legal approval for broad access-policy changes.

    Do not interpret a compensation agreement or content-use right from SEO guidance alone. Use qualified legal counsel for the relevant contract and jurisdiction. A broad blocking, gating, or de-indexing change can also reduce discovery, so validate the exact technical effect and begin with a limited, reversible test when that is compatible with your legal position.

    What to change in your next publishing cycle

    You do not need a sitewide redesign to begin. Apply the new operating model to the topic cluster that already matters most to your audience and business.

    1. Select the priority cluster. Choose an area where you can demonstrate real expertise, where audience questions recur, and where visits or influence have a defined value.
    2. Capture the baseline. Record rankings, impressions, clicks, click-through rate, landing-page outcomes, AI referrals, prompt citations, and brand mentions before changing content.
    3. Inspect the answer surfaces. Run your fixed prompt set and review the live search experience for important queries. Note whether an answer resolves the task, which pages it cites, and what reason remains to visit.
    4. Retrofit priority pages. Add a clear answer, explicit entities, well-scoped claims, visible evidence, accurate structured data, and a deeper layer that helps the reader verify or apply the answer.
    5. Strengthen surrounding coverage. fill genuine question gaps, consolidate overlapping pages, repair internal links, and reconcile inconsistent information across the cluster.
    6. Set decision rules before reviewing results. Define how you will respond when citations rise without visits, visits rise without citations, both improve, or neither changes.

    Those decision rules keep the program honest. If citations rise but no traffic or measurable business outcome follows, record the result as influence and decide whether influence is worth funding. If rankings remain stable while clicks fall on queries now resolved by an answer surface, strengthen the page’s visit-worthy layer or shift effort toward questions that require deeper engagement. If neither traditional visibility nor AI selection improves, more tracking will not solve the problem; revisit the content’s authority, clarity, and fit with audience intent.

    Start by capturing the baseline for your highest-value cluster before its next update. Then make the answer easier to extract and the full page harder to replace. That combination gives you a defensible SEO strategy even when discovery, citation, and traffic no longer arrive together.

    References


  • AI Watermarking in SEO and GEO: What Publishers Should Do

    AI Watermarking in SEO and GEO: What Publishers Should Do

    If your publishing workflow includes Gemini, Claude, or ChatGPT, the practical question is whether a machine-readable marker could affect Google rankings or citations in AI-generated answers. You need an answer that protects visibility without forcing your team into an unnecessary ban on useful tools.

    The defensible response is to treat watermarking as a measurable risk variable, not as proof of an AI-content penalty. Early B2B evidence shows a meaningful performance gap, but it does not separate the watermark from differences in authorship, judgment, and content quality. Audit what your tools actually mark, strengthen the editorial process, and test your own publishing workflow before changing it at scale.

    The performance gap is a warning, not proof of a penalty

    A controlled August 2026 comparison tracked 1,682 pages across 139 websites in four B2B industries. The unwatermarked group reached an average Google position of 6, while AI-created, watermarked content averaged position 11. The corresponding AI citation rates were 12% and 7%.

    Visibility measureUnwatermarked contentWatermarked, AI-created contentWhat was counted
    Average Google position611Position for the target keyword within three days of publication
    AI citation rate12%7%Share of pages cited for at least one target query in Google AI Overview, ChatGPT, or Claude

    Those are commercially relevant gaps. Five positions can separate prominent first-page visibility from a much weaker result, while a five-percentage-point citation difference matters when only a small portion of eligible pages earns a citation at all. The direction was also consistent across B2B SaaS, manufacturing, financial services, and healthcare.

    But the comparison cannot establish that a watermark caused either gap. Four limitations should control how you use these numbers:

    • Production method and watermark status moved together. The 1,060 watermarked pages were created with AI tools; the 622 unwatermarked pages were produced without AI. There was no otherwise identical set of pages in which only the watermark changed.
    • Content quality was not controlled through a common objective measure beyond the publisher’s professional standards. Human-created pages may have received more original judgment, better reasoning, or more careful treatment even when the AI output was reviewed.
    • Google positions were measured within three days of publication. That makes the result useful for examining early visibility, but it does not establish a durable ranking effect after indexing settles and longer-term signals accumulate.
    • The sample covered four B2B industries. It does not establish the same effect for ecommerce product pages, local service pages, news, consumer publishing, or other formats.

    This is enough evidence to add provenance to your SEO and GEO monitoring. It is not enough to tell clients that Google has confirmed an AI-watermark penalty, to rewrite an entire content library, or to attribute every weak page to its generation tool.

    A watermark is not one universal signal

    Several scanning devices examine one translucent digital document and reveal different abstract particle, color, mesh, and block layers.

    Watermarking is an umbrella term for several machine-readable mechanisms. Treating them as interchangeable will produce a bad audit because the relevant signal depends on the platform and the type of output.

    A statistical text watermark, an image-pixel signal, and signed provenance metadata are not the same artifact. A generic AI-detector score is different again: it is an inference about how text looks, not proof that a cryptographic credential or an official platform watermark is present. Copying text into a CMS, uploading an image through a media library, or seeing a low detector score does not tell you which machine-readable signal survived publication.

    Build your inventory at the output level rather than assigning one AI-generated flag to a whole URL:

    1. Record the exact generator and modality: Gemini text, Claude text, ChatGPT image, or another defined output. Note which parts of the page were human-created, AI-assisted, or directly generated.
    2. Retain the original generated file or output with its provenance information. Once an asset has passed through several editors and export tools, reconstructing its origin becomes much harder.
    3. Fetch the public version of each image after the CMS and CDN have processed it. Inspect that served asset with a verifier that supports the relevant credential rather than assuming the uploaded and delivered files are identical.
    4. For text, record the generating platform and workflow. Do not substitute the verdict of a general-purpose AI detector for platform-specific watermark evidence.
    5. Keep a private provenance log connected to the URL, author or reviewer, publication date, material revisions, and disclosure decision. This gives SEO, editorial, legal, and compliance teams one consistent record.

    This audit tells you what you are actually testing. Without it, a performance report may combine text patterns, image credentials, different levels of human involvement, and ordinary editorial quality under one label.

    Strengthen the page instead of laundering its provenance

    Removing metadata to make synthetic material appear human-created is a poor SEO strategy. It attacks a suspected signal before the causal mechanism has been established, does nothing to improve weak reasoning, and may remove useful provenance. A text-level statistical pattern may also be unrelated to the metadata attached to an image, so changing one does not neutralize the other.

    Google, Anthropic, and OpenAI have described their adoption of watermarking as a response to disclosure requirements such as Article 50 of the EU Artificial Intelligence Act and to concerns about undisclosed synthetic media. If those obligations may apply to your organization, market, or content type, obtain qualified legal guidance before removing credentials or changing disclosures. The safe operational choice is to preserve provenance while legal applicability is being assessed.

    For pages expected to rank, convert, or earn AI citations, apply a review that improves the factors obscured by the watermark comparison:

    • Assign an accountable human editor who can verify every material claim, resolve contradictions, and approve publication. A name added after the fact is not a review process.
    • Answer the target question near the relevant heading before expanding into qualifications. AI answer systems need a passage they can extract, while readers need a direct answer before supporting detail.
    • Maintain a claim ledger for statistics, product behavior, dates, named standards, and legal assertions. Each consequential claim should map to a real reference that supports that exact statement.
    • Add original examples, experience, internal data, or expert judgment only when they genuinely exist and can be defended. Never fabricate first-hand evidence to make generated copy look distinctive.
    • Remove generic transitions, repeated conclusions, unsupported superlatives, and sections that merely rephrase the query. These are quality failures regardless of whether a machine can identify their origin.
    • Check that visible authorship, publisher information, publication dates, revision dates, and primary images agree with the page’s JSON-LD. Structured data should describe what a reader can verify, not create a false provenance story.

    Schema cannot wash away an embedded signal. Use properties such as author, publisher, datePublished, dateModified, and image only when the corresponding facts are visible and accurate. Do not create a fictional human author, mislabel generated material, or change a modification date without a material revision.

    These controls do not guarantee rankings or citations. They address the largest unresolved variable in the available evidence: watermarked pages and human-created pages may have differed in thoughtfulness and judgment as well as provenance. A disciplined edit gives you better content and a cleaner test.

    Test your publishing workflow without fooling yourself

    Two matching digital manuscript workflows run in parallel through review modules, with one lane passing through an additional glowing sensor.

    If AI-assisted publishing is material to your operation, run a prospective workflow test on representative, low-risk content. The goal is to find out whether your normal AI workflow is associated with different visibility on your site. Unless a platform provides an official watermark control, the test will not isolate the watermark as the sole cause.

    1. Choose comparable queries within the same site, topic area, search intent, page type, and publishing period. Comparing an established product page on a strong domain with a new informational page on a weaker domain will tell you very little.
    2. Assign the workflow before drafting. Use a fully human-created cohort and a cohort produced through your normal AI-assisted process. Do not move difficult topics into one group after seeing the briefs.
    3. Give both cohorts the same editorial requirements: comparable briefs, claim verification, subject-matter review, internal-link treatment, template, and publication approval. Keep the standard high enough that you would be comfortable publishing either group.
    4. Log generator, modality, human contribution, reviewer, asset credentials, publication time, indexing state, internal links, later backlinks, and material revisions. These annotations help explain a gap that is not actually caused by provenance.
    5. Measure each target keyword at the same early checkpoint used in the 2026 comparison – within three days – and continue at consistent later checkpoints. Record the actual position and indexing status rather than reducing every result to page one or page two.
    6. Measure GEO separately. Enter the same target queries into Google AI Overview, ChatGPT, and Claude, then record the date, locale, account state, cited URL, and whether your page was cited at least once. AI answers can vary, so keep the measurement setup consistent across cohorts and checkpoints.
    7. Define the decision rule before reviewing the outcome. Decide which metric matters, what operational change a repeatable gap would justify, and which confounders require a retest. This prevents one surprising URL from becoming company policy.

    Interpret the result in layers. If no repeatable gap appears, retain the workflow and continue monitoring instead of treating external averages as your own. If a gap disappears after stricter editing, quality is a more plausible explanation than watermark status. If it persists across matched content and checkpoints, route the most commercially important pages through a more human-led process, preserve the provenance record, and test again. Even then, describe what you found as a workflow association rather than a confirmed algorithmic penalty.

    Do not blend SEO and GEO into one success score. Ranking position shows where a page appears in conventional results. Citation rate shows whether an answer surface selected the page as supporting material. A workflow can perform differently on those outcomes, and each failure points to a different investigation.

    Key takeaways

    • Early B2B evidence found unwatermarked content averaging Google position 6 versus position 11 for watermarked, AI-created content.
    • The same comparison found AI citation rates of 12% for unwatermarked pages and 7% for watermarked pages.
    • Those differences show correlation, not causation, because watermark status, AI involvement, and possible quality differences were not independently controlled.
    • Text watermarks, image-pixel signals, C2PA credentials, and generic AI-detector scores are different things. Audit the exact platform, modality, and delivered asset.
    • Do not strip provenance as a speculative SEO fix. Preserve credentials, check disclosure obligations, and improve the page’s evidence, accountability, directness, and structured-data accuracy.
    • Use matched cohorts and separate SEO ranking from GEO citation measurements. Your test should evaluate your real workflow, not claim to prove a universal watermark penalty.

    Start with your next planned content cluster. Add a provenance field to the brief, require a named reviewer, verify the live assets, and record early rankings and AI citations separately. That gives you evidence you can act on without hiding how the content was made or letting one preliminary correlation dictate your entire strategy.

    References