Tag: Citations

  • How to Choose a Generative Engine Optimization Agency

    How to Choose a Generative Engine Optimization Agency

    If you are choosing a generative engine optimization agency, finding candidates is the easy part. The difficult part is deciding whether a firm can improve your visibility in AI-generated answers or has simply put a GEO label on its existing SEO package.

    You need a proposal that connects questions your buyers ask to sources an answer engine can retrieve, understand, trust, and cite. You also need measurement you can audit. The framework below will help you test both before you sign a long engagement.

    Key takeaways for choosing a GEO agency

    • Hire for an operating system, not a label. The agency should connect audience research, content, technical access, entity clarity, external authority, and measurement.
    • Require a reproducible baseline built from a defined set of questions, answer environments, markets, and evaluation rules.
    • Ask to see the evidence chain from observed problem to recommendation, implemented change, later answer, and business interpretation.
    • Treat schema markup as a supporting layer. JSON-LD can clarify what a page describes, but it cannot manufacture authority or guarantee a citation.
    • Reject guaranteed mentions, citations, rankings, or recommendations. An agency can influence the inputs to an answer system, but it cannot control the answer selected for every user.
    • Start with a bounded, commercially meaningful scope. Expand only when the agency can show its work and your team can verify the resulting evidence.

    What a real GEO agency should actually own

    Generative engine optimization is the work of improving how accurately and often a company, product, service, or expert is represented in AI-generated answers. It overlaps with SEO, but the unit of performance changes. A conventional search program often concentrates on pages and rankings. GEO must also examine whether an answer system retrieves the right information, understands the entity behind it, includes the brand in the relevant context, and cites an appropriate source when citations are shown.

    The specialist label alone proves little. In 2026, buyers can already compare seven firms presented as GEO agencies. That makes the label a useful way to build a shortlist, but not evidence that a particular agency has a distinct method.

    A credible scope should connect the following workstreams:

    • Audience-question mapping: The agency identifies the questions that matter before, during, and after a buying decision. It groups them by intent instead of treating every prompt containing your category name as equally valuable.
    • Baseline visibility: It records where your brand appears, where competitors appear, which sources are cited, and whether the resulting description of your business is accurate.
    • Content and evidence planning: It finds missing definitions, explanations, comparisons, proof points, policies, product details, and expert material. Each recommendation should answer a documented information need rather than merely add more words to the site.
    • Technical accessibility: It checks whether the intended pages are discoverable, indexable, internally connected, and available to the retrieval systems included in the engagement. A page cannot support an answer if the relevant system cannot reach or interpret it.
    • Entity and structured-data work: It aligns names, descriptions, relationships, authorship, organization details, and supported schema markup with the visible content. Markup should describe evidence that actually exists on the page.
    • External corroboration: It considers reputable third-party mentions, reviews, profiles, expert contributions, public relations, and other off-site signals. Publishing a claim on your own domain does not automatically make that claim persuasive.
    • Measurement and iteration: It repeats a documented evaluation process, connects changes to observations, and tells your team what to keep, revise, investigate, or stop.

    These workstreams cross organizational boundaries. Content teams control explanations. Developers control templates and access. Communications teams influence external mentions. Subject-matter experts validate claims. A serious agency identifies those dependencies in the proposal and assigns an owner to each action. A vague promise to “optimize your site for LLMs” is not an implementation plan.

    Use the rebranded-SEO test

    Ask the agency to show a recommendation it would make specifically because of AI-answer behavior, then ask how it would measure the effect. The response should go beyond adding keywords, publishing generic articles, or installing schema across the site.

    A defensible answer might involve a missing question class, an inaccurate entity relationship, a source routinely used in relevant answers, an unsupported claim, weak external corroboration, or a page that is available to search engines but unsuitable for direct answer extraction. The agency should be able to show the observation that led to the recommendation and the evidence it would inspect afterward.

    This does not make traditional SEO irrelevant. Useful pages still need clear information architecture, accessible content, descriptive headings, internal links, and credible evidence. The warning sign is an agency that either treats GEO as identical to SEO or presents it as a complete replacement for SEO. The work overlaps, but the questions being measured are not identical.

    Demand an AI-visibility measurement system you can audit
    An analyst inspects transparent measurement layers that trace abstract AI answer signals back to questions and source documents.

    AI-generated answers can vary with the wording of a question, the interface used, available retrieval features, market, language, and evaluation date. A collection of favorable screenshots is therefore not a baseline. It is a collection of examples.

    Before accepting an agency’s visibility score, ask for the measurement protocol behind it. The protocol should define:

    • Answer environments: Which models, search experiences, assistants, modes, or features are included? Which are explicitly outside scope?
    • Question set: What exact questions are monitored? How were they selected, and which audience, buying stage, product line, or market does each represent?
    • Core and exploratory questions: Which questions stay stable so you can compare observations over time, and which may change as new customer language or opportunities emerge?
    • Evaluation context: What language, location, account state, date, and other relevant settings are recorded with each observation?
    • Classification rules: What counts as a mention, recommendation, citation, accurate description, competitive inclusion, or absence?
    • Evidence archive: Does the agency preserve the exact question, raw answer, cited URLs, evaluation context, and timestamp rather than only a derived score?
    • Change log: Can you see which pages, claims, markup, links, or external activities changed between measurement periods?

    The denominator matters as much as the result. “We increased citations” is not interpretable unless you know how many eligible responses were evaluated, whether the monitored questions stayed comparable, and whether branded questions were mixed with non-branded discovery questions. A brand should naturally appear more often when its name is already in the prompt. That does not prove improved discovery.

    Ask the agency to separate several kinds of outcomes:

    • Brand inclusion: The brand appears in responses to relevant, eligible questions.
    • Owned-source citation: An eligible answer cites a page controlled by your organization.
    • Representation accuracy: The answer correctly describes what you offer, who it is for, and any important limitations.
    • Competitive consideration: The brand appears in a relevant comparison or recommendation context, not merely in a list created by a branded question.
    • Source quality: Citations point to the most appropriate current page rather than an outdated, weak, or unrelated URL.
    • Downstream behavior: Referral visits, engaged sessions, qualified inquiries, assisted conversions, or other agreed business signals move in a useful direction.

    Do not collapse all of these into a single proprietary visibility number. A composite score may be convenient for reporting, but you should still receive the underlying records and definitions. Otherwise, you cannot tell whether a change came from broader discovery, more branded prompting, a modified scoring formula, or a genuine improvement in how the brand is represented.

    Business attribution also needs restraint. An AI answer may influence a buyer without producing a trackable click, while a referral visit may occur without causing a sale. Ask the agency to report visibility indicators and commercial outcomes separately, then explain the plausible connection without presenting correlation as proof of causation.

    Score every agency proposal against the same evidence
    A client team evaluates three anonymous agency proposals using matching evidence frames and sets of visual criteria.

    Marketing language makes proposals difficult to compare. A common scorecard forces each agency to reveal its method, implementation assumptions, and reporting limits. Use the same criteria for every finalist and request supporting examples wherever a claim remains abstract.

    AreaWhat an acceptable proposal containsWarning sign
    ScopeNamed answer environments, markets, languages, products, audiences, and question groupsPromises visibility “across AI” without defining where or for whom
    BaselineA reproducible method, recorded context, raw observations, and clear classification rulesA visibility score or screenshots with no query set, denominator, or methodology
    StrategyPrioritized hypotheses linking visibility gaps to specific content, technical, entity, or authority workA generic publishing calendar produced before the visibility gaps are examined
    ContentQuestion-level briefs, evidence requirements, expert review, update rules, and a defined approval processHigh-volume AI-generated pages treated as the main deliverable
    Technical workChecks for access, indexability, rendering, internal discovery, canonical signals, structured data, and implementation ownershipSchema installation presented as a complete GEO strategy
    External authorityA plan for relevant third-party corroboration with editorial standards and approval controlsGuaranteed placements, undisclosed paid mentions, or citation schemes
    ReportingRaw evidence, change logs, limitations, business context, and next actionsA dashboard that shows movement but cannot explain what changed
    Commercial termsDeliverables, responsibilities, tool costs, data ownership, exit rights, and change-control termsA long commitment before the method, baseline, and implementation dependencies are visible

    Ask questions that force the method into the open

    A polished presentation can hide an undeveloped process. These questions require the agency to move from claims to inspectable work:

    • Which specific answer experiences are included, and why do they matter to our buyers?
    • How will you build the monitored question set, and how will you prevent branded prompts from inflating the result?
    • What raw data will we receive behind every score?
    • Can you walk us through a sanitized example from observed answer to diagnosis, recommendation, implementation, and later evaluation?
    • How do you distinguish an owned-page problem from a lack of third-party corroboration?
    • Which recommendations will require developers, subject-matter experts, legal reviewers, communications teams, or product owners?
    • How do you verify factual claims before publishing or marking them up?
    • What work will you refuse to do because it is unreliable, misleading, or likely to create reputational risk?
    • How will you report an answer that mentions us often but describes us inaccurately?
    • Which tools, question sets, observations, content briefs, and reports can we export when the engagement ends?
    • What evidence would make you advise us not to expand the program?

    The final question is especially revealing. A consultancy should have a stopping rule. If every possible result leads to a larger retainer, the measurement system is serving the sale rather than the decision.

    Treat guarantees as a control problem, not a bonus

    No agency controls how an independent answer system generates every response. Guarantees of permanent citations, universal coverage, or fixed recommendation positions should therefore reduce your confidence, not increase it.

    Ask for controllable commitments instead: audits completed, questions mapped, pages improved, factual evidence reviewed, markup validated, outreach approved, observations recorded, and reports delivered. Then evaluate whether those actions improve the agreed indicators. This keeps the contract enforceable without pretending the agency controls a third-party model.

    Structure the first engagement so you can inspect the work

    A bounded first engagement is not merely a cheaper version of a retainer. It is a way to test whether the agency’s diagnosis, execution, and measurement connect. Choose a commercially meaningful topic area with enough existing evidence to examine, then define what the agency must deliver before expansion is considered.

    Your kickoff document should contain:

    • A clear business objective and the audience decisions connected to it
    • The products, services, markets, and languages in scope
    • The approved question set and baseline protocol
    • A record of current brand mentions, citations, inaccuracies, and important absences
    • A prioritized backlog with an owner, dependency, rationale, and acceptance condition for each action
    • Rules for factual review, brand approval, technical deployment, and external communications
    • A change log connecting completed work to the pages or assets affected
    • Conditions for expanding, revising, pausing, or ending the work

    Do not define acceptance as a guaranteed position in an AI response. Define it through deliverables the agency controls and observations your team can verify. For example, an important question gap can lead to an evidence-backed page, expert approval, correct technical implementation, inclusion in the monitoring set, and a documented follow-up evaluation. Visibility movement can then inform the decision to continue, but it is not fabricated into a contractual certainty.

    Protect the assets and access your team will need later

    The contract should say who owns the question taxonomy, raw response records, scoring definitions, dashboards, content briefs, written content, schema specifications, technical documentation, outreach records, and reporting history. It should also state which formats you can export without the agency’s proprietary platform.

    Clarify third-party software fees, data-retention limits, credential handling, approval requirements for automated publishing, and the process for removing access at the end of the engagement. If the agency will contact publishers, customers, partners, or experts in your name, require an approval workflow. Poor outreach can create a reputational cost long after the campaign ends.

    Include a handoff requirement as well. Your team should leave with the current measurement protocol, unresolved issues, deployed changes, pending outreach, known limitations, and the next recommended decisions. A dashboard login that disappears on termination is not a usable knowledge transfer.

    Send every shortlisted agency the same brief and score each response against the table above. Then ask the finalists to walk a sample question through their complete evidence chain. Choose the firm that makes its assumptions, data, dependencies, and limits easiest to inspect. If that chain is unclear before the contract, a more elaborate report will not make it clearer afterward.
    References

  • A Decision Guide to Eight Insurance GEO Agencies in 2026

    A Decision Guide to Eight Insurance GEO Agencies in 2026

    Insurance companies evaluating generative engine optimization agencies face a specialized buying decision: a partner may understand AI search without understanding insurance, or know insurance marketing while offering little evidence of a mature GEO practice.

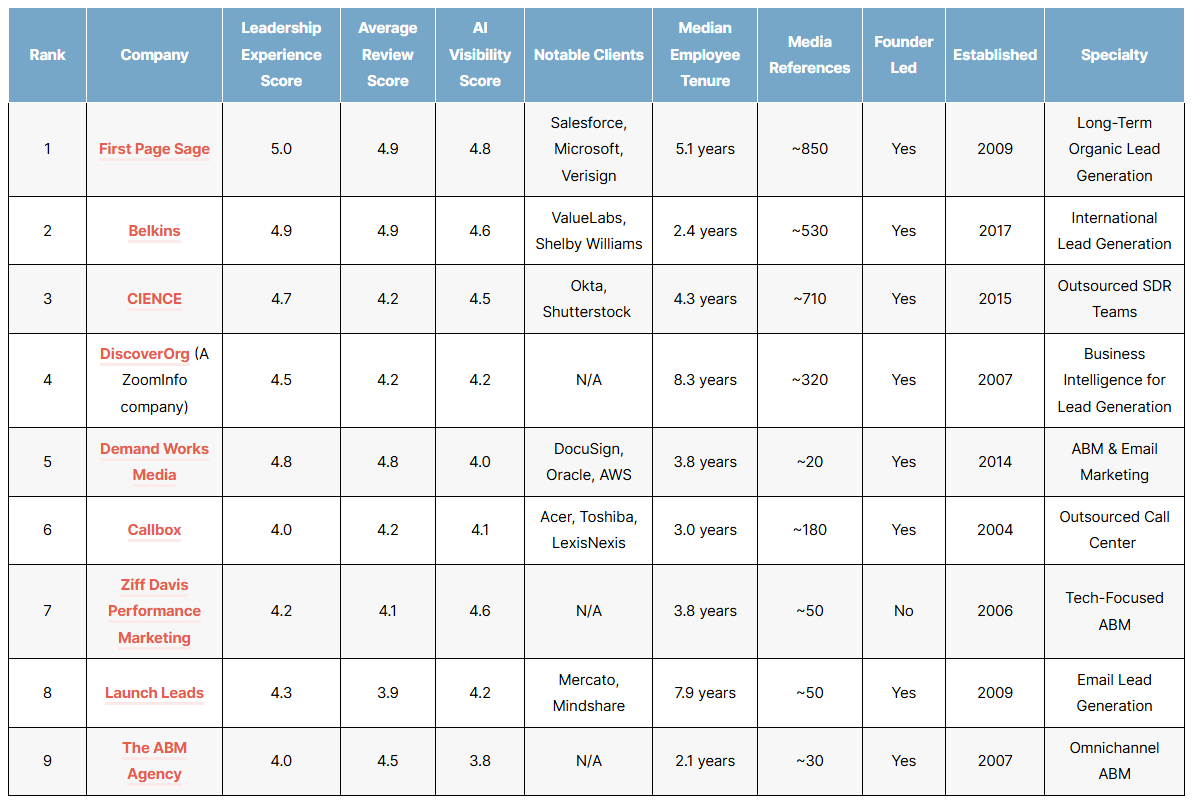
    A comparison published by First Page Sage Blog highlights eight agencies with different combinations of AI visibility, sector knowledge, content capabilities, and channel coverage. Because First Page Sage evaluated the market and ranked itself first, buyers should treat the results as a vendor-produced shortlist rather than an independent industry benchmark.

    How the reported comparison was constructed

    First Page Sage Blog says its team assessed 38 agencies and selected eight. AI visibility carried 25% of the evaluation, while the depth of each GEO offering and aggregated client reviews each represented 20%. Leadership experience accounted for 15%, with media references and notable insurance clients contributing 10% apiece.

    This framework rewards more than conventional search performance. It considers whether an agency can help a brand appear in answers from platforms such as ChatGPT, Perplexity, Claude, and Google Gemini, while also examining evidence such as GEO research, case studies, reviews, leadership credentials, media citations, and client portfolios. The source does not describe independent auditing of the scores, so the numbers are most useful as comparison points to investigate further.

    The eight-agency scorecard at a glance

    The following table preserves the source’s ranking and its four scored dimensions. A higher position reflects the complete weighted framework, not AI visibility alone.

    RankAgencyAI visibilityGEOReviewsLeadership
    1First Page Sage4.95.04.94.9
    2Genevate4.64.84.84.3
    3Focus Digital4.34.54.84.2
    4Amsive4.34.44.74.4
    5BrightFire4.24.24.84.4
    6EWR Digital4.44.44.64.2
    7Neilson Marketing4.14.04.74.3
    8Digital Logic4.24.34.64.3

    Match the agency model to the insurance buyer

    For a GEO-led content program, the source places First Page Sage at the front of the field. It describes an in-house insurance content operation covering regulatory reports, interviews, compliance topics, and commercial landing pages. The publisher also reports that its insurance clients average $1.7 million in new net revenue annually, alongside a 1.7% landing-page conversion rate and 63% average engagement rate. Those are vendor-reported campaign claims and should be validated against comparable client references, attribution rules, and contract scope.

    Genevate and Focus Digital represent two alternatives for organizations prioritizing GEO expertise over deep insurance specialization. The source characterizes Genevate as combining AI-focused optimization with public relations and reputation work, while Focus Digital emphasizes thought-leadership content for smaller and mid-market companies. It also cautions that both portfolios contain less insurance experience than those of sector-focused competitors. EWR Digital occupies related territory, combining B2B SEO, digital PR, and AI search visibility, but with a portfolio reportedly weighted toward other professional-services sectors.

    Amsive is positioned for larger insurers that need data, paid media, email, direct mail, organic search, and programmatic execution under one relationship. First Page Sage Blog identifies USAA and Allstate as notable clients, but says GEO is one component of a broader performance-marketing operation rather than the agency’s defining specialty.

    BrightFire, Neilson Marketing, and Digital Logic are more closely aligned with traditional insurance marketing needs. The source describes BrightFire and Neilson as insurance-focused specialists, with Neilson bringing more than 30 years of sector experience. Digital Logic is presented as a practical option for independent agencies and regional brokerages. In each case, however, the report finds less public evidence of a developed GEO methodology than it attributes to the higher-ranked GEO specialists.

    Key takeaways

    • No single score captures both AI-search capability and insurance fluency.
    • First Page Sage leads its own published ranking, making independent validation especially important.
    • Genevate, Focus Digital, and EWR Digital emphasize GEO or AI visibility but reportedly have less insurance depth.
    • Amsive suits complex multichannel programs, while BrightFire, Neilson Marketing, and Digital Logic lean toward established insurance marketing services.

    What to verify before selecting a partner

    A useful procurement process should test the claims behind the scorecard. Buyers can ask each finalist to show insurance-specific work, explain how AI visibility is measured, distinguish citations from referral traffic, and identify which activities are handled in-house. Case studies should clarify baselines, time periods, attribution methods, and whether reported outcomes came from GEO, traditional SEO, paid media, or several channels working together.

    Fit also depends on operating needs. A carrier coordinating multiple channels may value Amsive’s breadth, while an independent agency may prefer a managed insurance-marketing provider. An insurtech seeking stronger brand representation in AI answers may place more weight on GEO and digital PR. The most defensible choice will be the agency that can connect its proposed work to the buyer’s audience, compliance review process, distribution model, and measurable business objective.

    As AI discovery develops, documented methodology and transparent measurement should matter more than labels alone. A short paid pilot with agreed reporting standards can reveal whether an agency’s claimed specialization translates into useful visibility and qualified demand.


    Inspired by this post on First Page Sage Blog.


    crushpress.ai community screenshot
  • A Practical Framework for Auditing Local AI Visibility

    A Practical Framework for Auditing Local AI Visibility

    A strong Google Maps presence does not reveal whether an AI assistant will recommend a local business, describe it accurately, or favor a competitor. A local generative engine optimization (GEO) audit measures those outcomes directly.

    The goal is to establish a controlled baseline before changing content, citations, reviews, or technical settings. That baseline turns an uncertain visibility problem into a set of errors and opportunities that can be tracked.

    Why local AI visibility needs its own benchmark

    Traditional local rankings and AI recommendations are related, but they are not interchangeable. Search Engine Land cites SOCi’s 2026 Local Visibility Index, which analyzed nearly 350,000 business locations. ChatGPT reportedly recommended 1.2% of those locations, compared with a 35.9% appearance rate in Google’s local three-pack. The reported recommendation rates were 11% for Gemini and 7.4% for Perplexity.

    The source also reports that business information was about 68% accurate on ChatGPT and Perplexity, while Gemini reached 100% accuracy in that analysis and relied entirely on Google Maps data. These findings illustrate why map rankings alone cannot serve as an AI visibility scorecard: different systems can select different businesses, consult different sources, and reproduce business facts with different levels of accuracy.

    Key takeaways

    • Test discovery, comparison, trust, and logistics questions across the AI platforms customers may use.
    • Record whether the business appears, where it appears, how it is framed, whether its details are correct, and which sources support the answer.
    • Separate visibility failures from factual errors and weak competitive positioning.
    • Resolve crawl access and business-data inconsistencies before investing heavily in new local content.
    • Repeat the same test set over time so changes can be compared against a stable baseline.

    Build a test that produces comparable evidence

    Begin with a spreadsheet and a fixed set of prompts. The prompt set should represent four kinds of customer questions: discovery queries such as the best service in a city, comparisons between the brand and a competitor, trust questions about reviews or reliability, and logistics questions covering hours, address, parking, or phone number.

    Run the same questions in the relevant interfaces, which may include ChatGPT, Perplexity, Gemini, and Google AI Overviews. For every response, log the prompt, platform, date, test location, and session state. Search Engine Land recommends comparing logged-in and clean logged-out sessions to help identify personalization noise. The city or ZIP code must also remain explicit because local context can change the answer.

    Each result should capture five observations: whether the brand was mentioned, its order in the answer, the positive, neutral, or negative framing, the accuracy of operational facts, and the cited sources. Competitors should be recorded in the same rows, including their position and supporting sources. This makes the audit useful for both brand diagnosis and competitive analysis.

    Translate results into three types of failure

    An aggregate visibility percentage shows how often the business appears, while an accuracy percentage shows how often its details are correct. Those summary figures are useful, but the underlying problem determines the appropriate response.

    Futuristic web browser and analytics dashboard overlap amid neon data streams, illustrating the convergence of SEO, PPC and AI-driven search marketing.
    Organic visibility, paid media and artificial intelligence merge into one connected search ecosystem, where vivid data streams link a creative website with a powerful analytics dashboard.
    • Invisible: The business is absent from relevant answers. Possible causes identified by the source include crawler restrictions, insufficient citable material, or limited third-party mentions.
    • Inaccurate: The business appears with an obsolete address, incorrect hours, or outdated services. On-site errors and inconsistent name, address, and phone data across directories should be investigated.
    • Misframed: The business is mentioned but placed below competitors or presented as a weaker choice. A limited review profile or weaker authority signals may be contributing factors.

    This classification prevents a common planning mistake. Publishing another city page will not correct blocked access, and adding schema will not by itself overcome weak third-party validation. The audit should connect each observed symptom to the most plausible layer of the problem.

    Prioritize access, trust, and then relevance

    Remediation should follow the dependency chain. First, confirm that relevant crawlers can reach the site by reviewing robots.txt and applicable security or Cloudflare controls. Search Engine Land notes Cloudflare’s announcement that AI crawlers would be blocked by default on sites using its network, making the site’s actual configuration worth checking rather than assuming access.

    Next, align the business name, address, and phone number across the website and external profiles. Validate appropriate structured data, including LocalBusiness, Organization, FAQ, and Service markup where the page content supports it. Then strengthen trust through accurate profiles, reviews, responses to customer questions, and a consistent description of the business across directories, social accounts, and coverage.

    Content becomes the priority after those foundations are sound. Useful local pages should contain genuine city-specific information, concrete service examples, and practical details rather than repeating a template with a different place name.

    Turn the baseline into an operating metric

    Search Engine Land suggests a quarterly audit for most local businesses. Reuse the same core prompts and controls, then compare mention rate, position, factual error rate, citation count, and competitor share of voice with the previous run. Changes in cited sources or answer wording may indicate model drift and should be documented rather than treated as isolated anomalies.

    Clicks are not the only relevant outcome because an AI answer may influence a decision without producing a website visit. Branded search activity, calls, and direction requests can provide additional business context. The next audit should then test whether the chosen fixes improved the specific weakness originally observed.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • AI Agent Website Accessibility: A Practical Framework

    AI Agent Website Accessibility: A Practical Framework

    AI agent website accessibility is the ability of an automated assistant to discover a page, retrieve its contents, identify the relevant facts, and cite the business as the source. A site can work well for a human visitor yet fail this sequence when important information is hidden, dynamically rendered, ambiguous, or difficult to fetch.

    The practical goal is not to redesign every page for bots. It is to ensure that decision-critical facts survive the agent’s path from search to answer, especially when a prospective buyer asks about pricing, features, integrations, security, or compliance.

    Agent accessibility is a chain, not a page feature

    An agent typically starts with a task rather than a preferred website. It searches for relevant pages, fetches their contents, extracts an answer, and identifies sources it can cite. Failure at any stage can remove the vendor from the resulting answer even if the information appears somewhere on its site.

    This makes agent accessibility broader than visual presentation. A polished pricing grid offers little machine value if its values appear only after client-side code runs. A detailed PDF may contain the answer but make individual plan terms difficult to isolate. A contact-sales page may be accessible and accurate, but it cannot support a numeric answer that the company has chosen not to publish.

    This operational definition should not be confused with, or used as a replacement for, accessibility for people with disabilities. Human accessibility and agent accessibility address different users and failure modes, even though clear structure and understandable content can benefit both.

    Pricing exposes weaknesses that other product facts do not

    A geometric AI assistant faces layered website panels where pricing symbols are visible on one panel but obscured behind a modal and fragmented elements on others.

    A CrushPress.AI analysis conducted with Siteline founder David Kaufman examined three buyer tasks across 100 B2B products. The agent had to find each official vendor site without being given a starting URL, and each task was run five times to account for variable model behavior.

    Buyer taskFirst-party answer rateFirst-party citation share
    Pricing and features79%84%
    Integrations93%99%
    Security and compliance92%99%

    According to the analysis, pricing and feature research generated 77% of all third-party citations in the study. The contrast matters because pricing is both commercially sensitive and central to comparison. Integrations and security information can often be stated as straightforward facts; pricing may depend on plans, billing periods, usage, optional services, negotiated terms, or eligibility rules.

    Non-disclosure was only part of the problem. When a vendor did not publish a real price, 45% of pricing runs cited at least one third-party source. When a numeric public price was present, third-party sources still appeared in 18% of runs. Publishing information therefore improves the opportunity for first-party attribution, but does not guarantee that an agent can extract or trust it.

    Three failure gates determine whether the vendor remains the source

    Disclosure: is there a direct answer?

    The first gate is whether the company states the requested fact. If a price is unavailable, the page can still give an authoritative first-party answer by clearly saying that pricing is customized or requires sales contact. Vague packaging language creates a larger information gap, which third parties may fill without the vendor controlling the context.

    Extraction: can the fact be separated from the interface?

    The second gate is machine-readability. The source identified JavaScript interfaces, calculators, toggles, screenshots, PDFs, and ambiguous tables as potential obstacles. Its Zendesk example described a pricing grid that loaded for people but left the agent without usable plan data, leading to a 53-second process involving six tool calls before the agent turned to third-party blogs.

    The underlying editorial requirement is precision. A price needs an associated plan, unit, billing period, qualification rule, and any material condition. If those relationships are conveyed mainly through layout or interactive state, an agent may retrieve the values without understanding what they mean.

    Reachability: can the page be fetched consistently?

    The third gate is access. Fetch failures, blocking, rate limits, or unreachable pages appeared in 7% of all runs reported by CrushPress.AI, but their effect was disproportionate. Within pricing runs, an access error was associated with third-party fallback in 77% of cases, compared with 17% when no access error occurred.

    The study also compared high- and low-friction runs at the 90th and 10th percentiles. It reported a 4.4-fold cost difference, a 4.7-fold token difference, and a twofold time difference. Those costs are borne by the agent operator rather than the website, but they indicate how quickly retrieval friction can make an alternative source more attractive.

    A practical audit should follow the agent’s full journey

    A luminous AI agent travels through search, web document, fact extraction, and source-link stations along a pathway with three gateways and one blocked side route.

    Start with buyer questions, not page templates

    An audit can begin with the questions a buyer would delegate: What does the product cost? What is included? Which systems does it integrate with? Which security or compliance claims does the vendor make? Testing should begin from external discovery rather than a supplied page URL, mirroring the study’s method and revealing whether the intended first-party page can be found at all.

    Separate essential facts from interactive presentation

    Core plan and product facts should appear as clear page text that a fetcher can retrieve, even when the human experience also uses toggles or calculators. Labels should make relationships explicit: which plan a value belongs to, what the billing basis is, and which conditions change the amount. Complex pricing can remain complex, but its methodology should be explained in a form that can be quoted and cited without reconstructing the interface.

    Evaluate the answer and the citation separately

    A successful audit asks two different questions: did the agent produce an accurate answer, and did it support that answer with the vendor’s page? An answer sourced from a directory or editorial site may appear satisfactory while still showing that the vendor has lost control of attribution. In the reported pricing fallbacks, editorial pages accounted for 52.2% of fallback citations, directories for 45.7%, and ecosystem pages for 2.1%.

    Repeated testing is important because one successful retrieval does not establish reliable access. Results should be checked across multiple attempts, with special attention to blocked fetches, empty dynamic components, inconsistent plan labels, and facts that change when an interface control is activated.

    Key takeaways

    • Agent accessibility depends on discovery, retrieval, extraction, interpretation, and citation; a failure at any gate can push the answer to another source.
    • Pricing is a demanding test because disclosure choices and technical presentation can both prevent first-party attribution.
    • Publishing a number is insufficient when its plan, billing basis, conditions, or surrounding methodology remain ambiguous.
    • Access errors were uncommon in the reported study but sharply increased third-party fallback when they occurred.
    • Audits should test realistic buyer questions from search, repeat the attempts, and score answer accuracy separately from first-party citation.

    As agents assume more research and comparison work, the most resilient sites will treat machine access as part of publishing quality. The priority is a first-party record that remains understandable and citable after the interface itself is removed.

    References

  • Google AI Mode Visibility Is Splitting Into Three Channels

    Google AI Mode Visibility Is Splitting Into Three Channels

    Commercial visibility in Google AI Mode is developing along several paths at once. Advertisers can buy placements, publishers and brands can earn citations, and businesses can appear through Google-hosted profiles or product panels.

    Two separate reports show why these surfaces should not be treated as one ranking system. Paid coverage is expanding across commercially valuable queries, while Google is also becoming a more prominent source inside its own AI-generated answers. The practical payoff is a clearer way to assign budgets, ownership and measurement.

    Key takeaways

    • CrushPress.AI’s summary of an SE Ranking study reported text ads on 29.45% of the commercial AI Mode queries examined.
    • Ad incidence rose with keyword cost, but the study did not find the same relationship with search volume or keyword difficulty.
    • Paid placement provided little overlap with cited or traditionally ranked URLs, indicating that advertising, citations and organic search require separate strategies.
    • A second CrushPress.AI report said google.com became AI Mode’s second-most-cited domain in Profound’s tracking, driven mainly by Google Business Profiles and Product Knowledge Panels.
    • Commercial visibility therefore depends on both website performance and the quality of information presented on Google-controlled surfaces.

    Commercial visibility now has three distinct layers

    The reports describe complementary changes rather than competing explanations. The SE Ranking analysis covered paid text placements, whereas Profound tracked the domains AI Mode cited. Together, the findings suggest that appearing near an AI-generated response can happen through three substantially different mechanisms: an ad auction, selection as a cited source, or a Google-hosted information surface.

    The distinction matters because each layer answers a different business need. Advertising can provide purchased exposure on a relevant query. A citation can establish a website as supporting material for the generated answer. A Google Business Profile or Product Knowledge Panel can present decision-making information without requiring the user to reach the company’s website first.

    Profound’s tracking, as summarized by CrushPress.AI, found that citations to google.com increased 8.4-fold in roughly two months, making it the second-most-cited domain in the data. The report attributed almost all of that increase to Google Business Profiles and Product Knowledge Panels. Its analysis ran from April 15 through June 30 and covered more than 32 million google.com/searchviewer instances.

    The reported shift was especially relevant to local searches in hospitality and travel, home services, restaurants and dining, real estate, and healthcare. For product-oriented queries, panels appeared more often around comparisons, compatibility and specifications. These are situations in which structured facts can influence consideration before a conventional website visit.

    Paid reach follows commercial value, not general popularity

    CrushPress.AI’s account of the SE Ranking study reported ads across 14,733 queries, or 29.45% of the commercial searches analyzed. The study examined 50,032 U.S. keywords across 20 niches, using results collected on June 30. It focused on queries eligible for text ads and excluded product carousels.

    Cost per click was the clearest reported indicator of whether an ad appeared. Ad incidence was 24.33% among keywords with CPCs below $2, 32.45% in the $2-to-$10 group and 53.56% for keywords at $10 or more. Search volume and keyword difficulty did not show the same relationship in the study. This pattern supports a cautious interpretation: AI Mode ad deployment appears more closely aligned with the economic value of a query than with its popularity or organic competitiveness alone.

    When an ad block appeared, it usually included more than one advertiser. The study found two ads in 71.1% of ad-triggering responses and one ad in the remaining 28.9%. Category results varied sharply, from a reported 72.38% ad rate for pets to 2.64% for healthcare. Those differences warn against using the overall 29.45% rate as a forecast for every market.

    The study also noted that AI Mode results can vary between sessions. Its percentages should therefore be read as observations from the stated collection date and methodology, not permanent delivery guarantees. The source further cautioned that the pattern could change as Google introduces more AI-specific advertising formats.

    Buying an ad does not secure the other layers

    Three separate glass corridors contain bid tokens, connected source pages, and a digital storefront with products.

    The most consequential finding for planning was the limited overlap between advertisers and unpaid visibility. According to the SE Ranking analysis summarized by CrushPress.AI, only 11.53% of advertiser domains appeared among cited sources for the keywords on which they advertised. At the individual URL level, overlap fell to 1.95%.

    Traditional organic results showed a similar separation. Just 2.32% of advertised URLs also ranked organically for the corresponding queries, while domain-level overlap reached 15.35%. In other words, approximately 85% of advertisers did not appear in organic results for the same keywords, according to the source.

    Visibility comparisonReported overlapPlanning implication
    Advertiser domain and cited domain11.53%Paid reach is not a substitute for earning citations.
    Advertised URL and cited URL1.95%The landing page is rarely the exact source selected for the answer.
    Advertiser domain and organic domain15.35%Advertising and domain-level organic visibility remain largely separate.
    Advertised URL and organic URL2.32%Buying exposure does not ensure that the same page ranks.

    The researchers reportedly compared advertisers with similar non-advertising domains while accounting for domain strength, backlinks, referring domains and organic visibility. Even so, the findings are observational. They do not establish that advertising causes or prevents citation and ranking outcomes. They do show that purchasing an AI Mode placement should not be assumed to improve either one.

    A practical operating model for AI Mode visibility

    An operations table is divided into zones for paid media, source citations, and product profiles, each with separate measurement tools.

    Organizations can respond by assigning each visibility layer a distinct job. Paid-search teams can evaluate AI Mode ads according to query economics, placement availability and conversion performance. SEO and content teams can monitor whether the brand’s pages are cited or ranked, then improve the relevance and usefulness of the pages intended to earn that exposure.

    Local and commerce teams need a third workstream for Google-hosted information. Business hours, locations, photos and reviews can become part of the AI Mode experience through Google Business Profiles. Product specifications and compatibility information may surface through Product Knowledge Panels. Because those details can be encountered before the website, maintaining them is part of commercial presentation rather than a secondary listing task.

    Reporting should preserve the same separation. A combined visibility score can conceal whether progress came from spending more, earning stronger source selection, improving organic rankings or maintaining a more complete Google-hosted profile. Channel-specific reporting makes it possible to connect each outcome to the team and investment responsible for it.

    The next useful evidence will be longitudinal: whether ad incidence continues to rise, whether new formats change advertiser competition, and whether Google’s share of citations remains concentrated in its own local and product surfaces. Until those patterns are clearer, the sound approach is to manage AI Mode as a portfolio of paid, earned and platform-hosted visibility rather than as a single search position.

    References

  • How AI Search Is Becoming the New Digital Storefront

    How AI Search Is Becoming the New Digital Storefront

    AI search is creating a commercial interface between brands and buyers before many people reach a company’s website. That interface can introduce the brand, assemble a consideration set, compare alternatives and move a buyer closer to a decision.

    Two complementary ideas clarify what marketers need to manage. HiGoodie describes AI-generated brand representation as an unofficial homepage, while Profound’s shopping research frames the product shortlist as a new digital shelf. Together, they suggest that the emerging AI storefront has both a narrative layer and a selection layer.

    One storefront, two distinct commercial layers

    The homepage metaphor concerns interpretation. An AI answer may summarize what a company does, associate it with a category, explain its benefits and cite sources that influence the resulting description. HiGoodie’s account argues that brands already have this kind of model-generated presence, even though they did not design or publish it themselves.

    The shelf metaphor concerns consideration. When an answer recommends several products, the named options become the immediately visible assortment. A brand can therefore be described accurately yet still be commercially absent if it does not appear when the model constructs a shortlist.

    These layers depend on related but different signals. Citations and distributed information help shape the brand story; recommendation visibility determines whether the brand enters the comparison. Treating AI search only as a referral channel misses both functions. The answer itself is part of the customer experience, not merely a link leading to it.

    The shortlist evidence points to influence, not proven causation

    Profound reported a behavioral study conducted with Kevin Indig and Clickstream Solutions in which 56 participants completed 221 shopping tasks. According to the published account, brands that appeared more often in ChatGPT answers were also more likely to be selected by participants.

    The same source reported that 57.1% of sessions ended with participants ready to decide, while another 36.5% reached active comparison. Within the boundaries of that study, AI-assisted shopping generally advanced the decision rather than leaving the participant at an early discovery stage.

    That is meaningful evidence of an association between answer visibility and choice, but it should not be converted into a causal claim. A brand might appear frequently because it is already prominent, well documented or suitable for the task. The study nevertheless highlights a practical risk: exclusion from the generated set can remove a product from consideration before conventional website analytics register a visit.

    Storefront influence varies sharply by category

    A shopper stands at the center of pathways leading to differently illuminated displays for electronics, personal care, furniture, and everyday goods.

    The reported relationship was not uniform. Profound’s category ranking showed a +0.97 correlation for grocery and a -0.98 correlation for coaching between ChatGPT visibility and participant choice. These figures came from the source’s study and should be read as category-specific findings, not universal benchmarks.

    The contrast matters because an AI shortlist does not play the same role in every purchase. In some categories, recognizable products and comparable attributes may make the generated set especially useful. In others, personal fit, trust or evaluation outside the answer may dominate. The evidence therefore supports category testing rather than a single visibility target applied across an entire portfolio.

    A useful assessment asks where the answer sits in the decision process. It may function as an initial orientation, a comparison aid or a near-final recommendation. The closer it sits to selection, the more consequential shortlist inclusion becomes. Where it mainly supplies context, accurate representation and credible citations may deserve greater attention than raw mention frequency.

    Managing the AI storefront requires broader measurement

    Analysts examine an abstract interface connecting AI discovery, product selection, a website, a retail shelf, and a purchase point.

    The first management task is to separate representation from recommendation. Teams can examine recurring customer questions and record how AI systems describe the brand, which claims they emphasize, what sources they cite, which competitors appear and whether the brand reaches the shortlist. This produces a more useful view than a single visibility score because it reveals the role assigned to the brand in each answer.

    Distribution is part of that work. HiGoodie argues that AI search rewards broad visibility, complicates selective partnerships and weakens the value of exclusivity. The strategic implication is not indiscriminate publishing. It is that a polished corporate site alone may be insufficient when models also rely on information encountered through other cited sources. Consistency across credible, relevant coverage becomes part of storefront management.

    Measurement also has to extend beyond ordinary referral reports. Profound characterizes the decision moment inside ChatGPT as difficult for traditional analytics to observe. A website can measure visitors who arrive, but it cannot directly show how often an answer excluded the brand or persuaded someone to choose a competitor without clicking. Prompt-based visibility monitoring, citation reviews and controlled customer research can help examine that missing part of the journey, while on-site data remains useful for the traffic that does arrive.

    Any resulting program should distinguish four questions: Is the brand represented accurately? Is it supported by appropriate citations? Does it enter relevant comparison sets? Does its presence align with customer choice in the category being studied? Keeping those questions separate reduces the temptation to treat every mention as equivalent commercial value.

    Key takeaways

    • The AI storefront has a narrative layer that explains the brand and a selection layer that determines whether it enters consideration.
    • Profound’s study found a strong relationship between ChatGPT visibility and participant choice, but the reported association does not by itself prove causation.
    • The sharply different grocery and coaching results show why AI-search performance should be evaluated by category and decision context.
    • Brands need to review answer quality, citations and shortlist inclusion alongside conventional traffic and conversion measures.

    As AI answers take on more of the work once performed by search results, homepages and comparison pages, the central challenge will be to connect accurate representation with meaningful inclusion at the moments when buyers narrow their options.

    References

  • Brand Visibility in AI Search Depends on Source Trust

    Brand Visibility in AI Search Depends on Source Trust

    Brand visibility in AI search is not simply a matter of ranking highly or publishing more content. It depends on whether an AI system can find credible sources that mention the brand, support relevant claims and provide enough context to construct an answer.

    The source material points to a practical shift: brands must manage a portfolio of evidence rather than optimize for one universal result. Audience relevance, model-specific citation preferences, factual accuracy, freshness and platform-hosted business data can all influence which version of a brand appears.

    Source trust has become a distribution layer

    Traditional search encouraged brands to think primarily about pages and positions. Generative systems add another layer because they assemble answers from selected sources. A brand can therefore be visible indirectly through a publisher, community, reference site, video platform, business profile or product panel even when its own website is not the principal destination.

    This helps reconcile several of the reports. research described by Search Engine Land argues that repeated associations across credible, niche-relevant channels can strengthen a brand’s entity authority. Separately, Profound’s comparison of Google AI products found that their visibility differences reflected which brands and supporting sources they selected, rather than a large difference in the number of brands mentioned per answer.

    Together, those findings suggest that AI visibility has at least two dimensions. The first is inclusion: whether the brand enters the system’s available evidence. The second is interpretation: whether the selected evidence supports an accurate and favorable description. A mention can help with the first while hurting the second if the underlying information is obsolete, ambiguous or false.

    Trust should therefore be treated as contextual rather than as a single score. A source can be influential because it is authoritative, closely aligned with an audience, frequently used by a particular AI product or embedded in a platform’s own information environment. None of the reports establishes a universal hierarchy that applies to every query and model.

    Audience relevance can outweigh headline reach

    A focused beam illuminates a small attentive audience while a broader faint beam spreads across a large distant crowd.

    The clearest challenge to reach-first media planning comes from the publisher-affinity study. According to the Search Engine Land account, the niche publishers examined achieved 1.7 times the audience affinity of major media outlets despite receiving 130 times less traffic. The reported analysis covered audiences in eight industries and used SparkToro affinity data alongside conventional metrics such as organic traffic, domain rating and referring domains.

    The implication is not that large publications have lost their value. The same report presents mainstream and specialist coverage as complementary: major outlets can deliver scale and broad validation, while focused publishers can establish stronger topical and audience associations. A sensible source portfolio uses each for the job it performs rather than treating traffic as a complete proxy for influence.

    This changes media selection. A placement should be assessed not only by how many people might encounter it, but also by who relies on the outlet, how precisely the outlet covers the subject and whether its coverage adds substantive evidence. A smaller trade publication may provide detailed category context that a general-interest mention cannot. Conversely, a major outlet may provide wider recognition that a specialist source cannot match.

    The same reasoning extends beyond publishers. The affinity research considered websites, YouTube channels, podcasts, social accounts and community-led platforms. That broader view is consistent with the model comparison, which reported citations from editorial, reference, social and user-generated sources. Brand authority in AI search is consequently better understood as a network of corroborating contexts than as the product of one prominent link.

    Visibility changes when the model changes

    Three translucent lenses use different source objects to cast varying levels of light on the same unbranded object.

    A source strategy cannot assume that Google’s generative products return interchangeable representations. Profound reported tracking 15,155 brand configurations daily in May 2026 and found a median eight-point gap between each brand’s best- and worst-performing Google model. Gemini, AI Overviews and AI Mode reportedly mentioned a similar number of brands per response, averaging between 4.4 and 5.0, but differed in the brands selected and the sources cited.

    In that dataset, Gemini leaned more heavily on editorial and reference sources, including Reddit, YouTube and Wikipedia. AI Overviews and AI Mode relied more on social and user-generated platforms and produced roughly twice Gemini’s citation depth per run. These are reported observations from one analysis, not proof of a permanent sourcing rule. They nevertheless show why a visibility score from one interface cannot stand in for the entire AI-search environment.

    AI Mode introduces an additional platform consideration. Profound reported that Google.com had become AI Mode’s second-most-cited domain, with Google Business Profiles and Product Knowledge Panels appearing inside answers. The report highlights particular consequences for local-intent searches and physical products: the decision journey may proceed through Google-hosted information before a user reaches the brand’s site.

    For measurement, the useful unit is therefore a query-model-source combination. Teams need to compare how different systems answer the same meaningful questions, which claims each one makes and which citations or hosted data support those claims. For operations, this means that publisher outreach, community presence, video or reference visibility, product feeds, business-profile accuracy and review management can contribute through different routes.

    Accuracy and freshness determine whether visibility helps

    More visibility is not automatically beneficial. Profound’s FactCheck announcement describes a system for breaking AI answers into brand claims and tracing them to owned pages and third-party citations. Its example concerned an incorrect claim that Relay ERP was deployed on premises when the cited verified information described the product as cloud-native. The case illustrates the operational distinction between being mentioned and being represented correctly.

    Freshness creates a related problem. A Search Engine Land account of AI reputation management describes an old story about a customer-service incident at a Midwestern grocery chain resurfacing in Google AI Overviews after the issue had been resolved. The article argues that conventional suppression is insufficient because an AI system may still retrieve and cite an older source after it has faded from prominent search positions.

    These reports reveal three separate failure modes. A source may contain a false claim, a once-accurate source may no longer reflect the current situation, or an accurate source may lack the context needed for a balanced answer. Publishing more pages does not directly resolve any of them. The corrective evidence must itself be clear, credible, current and accessible to the systems producing the answer.

    Audit questionRisk it exposesPractical response
    Which claims recur across AI products?A repeated error may be becoming entrenched.Trace the claim to its cited or likely supporting sources and correct the evidence at the source where possible.
    Which sources appear for priority queries?The brand may depend on a narrow or poorly aligned evidence base.Develop credible coverage across relevant specialist, mainstream, community and platform-hosted sources.
    Does each source reflect the current business?Old reporting or stale profile data may distort the answer.Request appropriate updates and publish dated, verifiable context about what changed.
    Do results differ by model?A strong result in one product may conceal weak or inaccurate representation elsewhere.Repeat the same query set across multiple interfaces and record claims, citations and answer changes separately.

    This approach joins reputation management with AI visibility measurement. The objective is not to erase every unfavorable source or manufacture unanimity. It is to ensure that systems have access to a sufficiently broad body of reliable evidence, while genuine inaccuracies and obsolete information are addressed transparently.

    Key takeaways

    • AI visibility depends on the sources selected to support an answer, not only on the brand’s own rankings or content.
    • Niche publishers can add audience and topical relevance even when their traffic is modest; mainstream outlets still provide complementary scale and validation.
    • Gemini, AI Overviews and AI Mode should be measured separately because reported sourcing patterns and brand selections differ.
    • Google-hosted profiles and product information can influence AI Mode visibility before a user visits a brand-controlled website.
    • Claim accuracy and source freshness must be monitored alongside mention volume because an incorrect or outdated citation can turn visibility into reputation risk.

    As AI products continue to develop distinct source preferences, durable visibility will come from maintaining evidence that travels well across systems: accurate first-party data, relevant independent coverage and timely context when the business changes. The strategic advantage will belong to brands that can see not only whether they appear, but also why a model trusts the version of the story it tells.

    References

  • AI Search Visibility for Travel Brands: A Practical Framework

    AI Search Visibility for Travel Brands: A Practical Framework

    Travel discovery is becoming less about securing a place in a list of links and more about being included in a synthesized answer. For travel brands, that shifts the visibility question from “Where does the page rank?” to “When, why, and how does the brand appear in an AI-assisted decision?”

    The supplied CrushPress.AI source argues that conversational answer engines can compress research, comparison, recommendation, and booking assistance into one continuing interaction. The practical challenge is therefore to make a brand understandable, credible, and useful throughout that interaction without abandoning the search foundations that still support discovery.

    Travel discovery is shifting from page selection to answer formation

    Traditional travel search commonly asks the user to assemble an answer: enter a destination-focused query, examine several results, compare details, and construct an itinerary. The source contrasts that process with conversational planning in tools such as ChatGPT, where a traveler can refine a question while the system synthesizes recommendations and comparisons.

    This distinction matters because the unit of competition changes. A conventional results page gives brands visible positions that users can inspect directly. An AI-generated response may instead select, combine, summarize, or omit information before the traveler encounters it. A travel company can therefore have discoverable webpages yet remain absent from the answer that shapes consideration.

    The opposite outcome also deserves attention. A brand mentioned favorably in an answer may influence a trip before the traveler visits its website. AI visibility can consequently create value earlier than a click, although a mention alone does not demonstrate that the traveler eventually booked.

    Visibility now has four dimensions

    An unbranded hotel is surrounded by four visual layers representing discovery, understanding, trust, and inclusion in a travel route.

    The source identifies mentions, citations, and trust as increasingly important components of visibility. Those ideas can be translated into four dimensions that travel marketers can examine separately.

    Inclusion asks whether the brand appears at all for relevant planning questions. Attribution asks whether the answer names or links to the brand as a source. Representation examines whether the description is accurate, current, and aligned with what the company actually offers. Influence considers whether the brand is merely listed or is positioned as a plausible choice for the traveler’s stated needs.

    These dimensions prevent a misleading all-or-nothing view of AI visibility. A citation can support discovery without producing a recommendation. A recommendation can mention a brand while misstating an important condition. A correct mention can still be unhelpful if it appears for an irrelevant audience. Effective monitoring must therefore evaluate the quality and context of an appearance, not just count brand names.

    Content must support decisions, not merely destination keywords

    A traveler reviews a visual itinerary connecting lodging, transportation, dining, accessibility, weather, and family activities.

    Conversational travel planning tends to accumulate context through follow-up questions. A broad destination request may develop into a comparison shaped by budget, timing, location, group needs, amenities, or preferred experience. The source’s account of continuing conversations implies that visibility cannot be treated as a single-query contest.

    Travel brands can respond by organizing content around the decisions travelers need to make. Clear descriptions of the offer, intended guest, location, limitations, policies, and differentiators give an answer engine less room to infer essential facts. Comparison-oriented pages should explain meaningful trade-offs rather than rely on unsupported superlatives. Destination content should connect local guidance to the brand’s legitimate expertise instead of functioning as generic traffic capture.

    Consistency is equally important. Names, locations, service descriptions, and other core details should agree across the brand’s own pages and relevant public profiles. Where details can change, visible context and update information help users and systems distinguish durable facts from time-sensitive material. These practices do not guarantee inclusion in an AI response, but they make the brand easier to interpret and represent accurately.

    The source also emphasizes trust. That makes AI search visibility broader than an on-site publishing exercise: a brand’s public footprint, third-party coverage, and clearly attributable expertise may all affect how confidently it can be discussed. The appropriate goal is not indiscriminate mention volume, but a coherent body of information that supports the claims the brand wants associated with it.

    Key takeaways

    • AI-assisted travel planning can combine discovery, comparison, recommendation, and booking help within one conversation.
    • Travel brands should assess inclusion, attribution, representation, and influence rather than treating every AI mention as equivalent.
    • Useful content answers decision questions and states important details, limitations, and trade-offs clearly.
    • Traditional search performance remains relevant, but rankings and clicks do not fully describe visibility inside generated answers.
    • Measurement should connect answer-level visibility with qualified visits and booking outcomes without assuming that one caused the other.

    Measurement should separate exposure from business impact

    A practical measurement program begins with a stable set of representative planning prompts. These should cover the destinations, traveler needs, comparison situations, and decision stages that matter to the business. Repeating the prompts over time can reveal whether the brand appears, which competitors accompany it, what sources receive attribution, and whether material details are represented correctly.

    Results should be reviewed at the response level because conversational outputs can vary and because wording changes the context of a recommendation. Monitoring only a single broad prompt risks turning one answer into a market conclusion. The more useful question is whether recognizable patterns emerge across relevant scenarios.

    Answer visibility should then be considered alongside conventional indicators such as branded interest, referred visits, engagement, and booking activity where those signals are available. The source argues that brands appearing in AI search may be better placed to shape itineraries and decisions, but it does not establish that every appearance produces a booking. Reporting should preserve that distinction between observed exposure, subsequent behavior, and proven commercial contribution.

    As conversational planning develops, travel brands will need a combined discipline: technically discoverable information, decision-ready content, credible public evidence, and careful outcome measurement. The durable advantage will come from making the brand consistently useful at the moments when an itinerary is being formed.

    References

  • Why ChatGPT Search Citations Change Across Hidden Pipelines

    Why ChatGPT Search Citations Change Across Hidden Pipelines

    A ChatGPT citation is the visible end of a much larger selection process. Before a source can appear beside an answer, the system may decide whether to search, choose a retrieval pipeline, rewrite or expand the query, fetch candidate pages and select which evidence deserves a citation.

    That layered process explains why repeated prompts can produce different source lists without any underlying page changing. It also changes how publishers should interpret AI visibility: one observed answer is a sample of a variable system, not a definitive ranking.

    A citation is the output of several hidden decisions

    The source cards visible to users do not disclose the full route that produced them. According to the CrushPress.AI report, research by Chris Green and Suganthan Mohanadasan identified internal source-selection labels including Labrador, Bright, Oxylabs and SERP. These labels appeared behind the answer rather than in its public citations.

    This creates several distinct opportunities for a page to be excluded. ChatGPT may classify the prompt as not requiring web search. If it does search, the selected retrieval source may not surface the page. The system may then fetch the page but decline to cite it, or it may use the page for a narrow factual claim while relying on another source for the broader answer.

    The practical distinction is important. A missing citation does not, by itself, show that a page lacks authority or relevance. It may reflect an earlier routing, retrieval or parsing decision that is invisible in the final response.

    Repeated prompts expose pipeline-level variability

    Three identical inputs move through different branching retrieval paths and produce different sets of source cards.

    Green examined 1,000 prompts, running each as many as 10 times, and recorded 9,946 completed searches, as reported by CrushPress.AI. Labrador was the primary search source in 88.1% of those runs, followed by Bright at 9.9%, Oxylabs at 1.7% and SERP at 0.3%.

    Most prompts remained on one primary source, but 11.6% switched sources across repeated runs. For prompts that switched, reported URL overlap declined from 0.273 to 0.149, while domain overlap declined from 0.265 to 0.155. Green characterized those changes as approximately 45% less URL overlap and 42% less domain overlap.

    Those overlap figures measure consistency between result sets; they should not be read as a page’s probability of earning a citation. Their significance is structural: a change in retrieval route can materially change the pool of domains and URLs available to support an answer.

    Mohanadasan observed a different distribution while examining two days of raw network traffic from one logged-in Pro account. His sample contained about 1,240 source records from a few dozen searches. Although he found the same four result-source values, Bright had a larger role in his sample, particularly for commercial, shopping, finance, weather and local queries. SERP appeared mainly with news-oriented results, while Labrador included established publishers and reference sites; Bright and Oxylabs were associated with their namesake data providers.

    The differing distributions are not necessarily contradictory. The studies used different prompts, observation methods, sample sizes and account contexts. Together, as presented in the source article, they suggest that no single observed pipeline mix should be assumed to represent every query class or user session.

    Search can be skipped, rewritten or expanded

    Pipeline selection matters only after the system decides to search. Mohanadasan reported that ChatGPT first classified some requests through a turn-use-case field. Some apparently current prompts were categorized as text tasks and did not trigger a web search. When that happens, no current page can be fetched or cited, regardless of how well it is optimized.

    Queries that received more extensive reasoning could travel in the opposite direction. The reported traces showed branching searches that included site-specific probes, pricing checks and searches for competitors the user had not named. Consequently, a publisher may be competing for retrieval against results generated from several machine-created subqueries, not merely the exact wording entered by the user.

    This makes prompt-level visibility difficult to reduce to conventional rank tracking. The same surface question can lead to no search, a relatively direct search or a multi-step investigation. Each path creates a different candidate set before citation selection begins.

    Fetched, cited and mentioned are different outcomes

    Blank webpage cards are progressively narrowed from a large candidate pool to a few cards linked to a final answer.

    Mohanadasan separated source participation into three useful states: fetched, cited and mentioned. A fetched page enters the system’s working context. A cited page is displayed as support for a claim. A mentioned brand may appear in the prose without its own site serving as visible evidence.

    OutcomeWhat it indicatesWhat it does not establish
    FetchedThe page was retrieved for possible use.That users saw it or that it supported a final claim.
    CitedThe page was presented as evidence for part of the answer.That it was the only source consulted or the preferred source in every run.
    MentionedThe brand or entity appeared in the response.That its own website was retrieved or cited.

    The source article illustrates the distinction with a small commercial-query sample. Reddit and YouTube were both fetched frequently, but Reddit received citations while YouTube did not. Mohanadasan attributed the difference to accessible text: Reddit threads exposed usable copy, whereas YouTube search results often supplied metadata rather than full transcripts. Because the sample was limited, this should be treated as an observed pattern rather than a universal rule about either platform.

    Source roles also varied by claim type. Vendor pages supported first-party facts such as prices and specifications, while third-party pages were more likely to support comparative recommendations. In some cases, ChatGPT appeared to seek an official pricing page but use a third-party source when the official information was hidden behind JavaScript or otherwise difficult to parse.

    The broader implication is that citation eligibility depends on both relevance and usability. A page can contain the right information yet lose the visible citation if the information is inaccessible, ambiguous or less suitable for the particular claim than another source.

    A better framework for measuring ChatGPT visibility

    Because routing and search behavior can change between runs, citation monitoring should emphasize distributions rather than isolated answers. Repeated tests can show how often a domain appears, whether the cited URL changes, which claim types attract first-party or third-party support, and how volatile the results are. The studies reported here do not establish a universal number of repetitions, so testing depth should be documented instead of presented as a fixed standard.

    Measurement should also keep brand inclusion separate from source attribution. Citation share, mention share and fetched-page data answer different questions. Combining them into one visibility score can conceal whether a brand is absent from the answer, present without evidence from its own site, or retrieved but not shown to the user.

    Key takeaways

    • A citation is produced by a chain of classification, routing, retrieval and evidence-selection decisions.
    • Repeated prompts are necessary to reveal variability; a single response cannot represent a stable source position.
    • Search eligibility should be evaluated separately from citation performance because some prompts may not trigger web retrieval.
    • Fetched pages, visible citations and uncited brand mentions should be tracked as distinct outcomes.
    • Plain HTML, clearly labeled facts, accessible prices and specifications, and substantial text improve the chance that retrieved information can support a claim.
    • First-party pages and independent coverage serve different evidentiary roles, so visibility work should account for both.

    As AI search measurement matures, the most durable approach will be to record uncertainty rather than hide it. Publishers that make evidence easy to retrieve and interpret, while measuring performance across repeated runs and source types, will be better equipped to understand citation changes as the underlying pipelines evolve.

    References

  • When Original Research Becomes an AI Citation Benchmark

    When Original Research Becomes an AI Citation Benchmark

    Original research can give AI systems something unusually valuable: a defensible answer that does not exist on every competing page. Yet the available citation analysis suggests that publishing proprietary numbers is not enough. The strongest results appear when those numbers form a benchmark that resolves a specific comparison.

    That distinction changes the content strategy. The goal is not merely to demonstrate that a company has data. It is to turn first-party evidence into a transparent, retrievable answer to a question buyers are already asking.

    The citation advantage is substantial but concentrated

    An analysis reported by Search Engine Land examined Gauge’s set of 301 live pages cited by AI systems across 316 unique prompts and seven verticals. Those pages collectively received 1,075 citations. Only eight pages, or 2.7% of the cited set, qualified as primary research under the analysis’s definition: they presented original data and explained its methodology.

    Despite their scarcity, those eight pages accounted for 90 citations, or 8.4% of the total. They averaged 11.3 citations per page, compared with 3.4 for the other pages. On that measure, primary-research pages were approximately 3.3 times as citation-dense as pages without primary research.

    The result supports a useful but limited conclusion. Within this cited-URL set, original research was associated with disproportionately high citation volume. It does not establish that any page containing proprietary data will earn citations, nor does it measure the success rate of all published research. The dataset begins with pages that had already been cited, so it reveals patterns within successful sources rather than the probability that a new study will succeed.

    Concentration inside the research subset makes that qualification especially important. According to the same report, 75 of the 90 primary-research citations came from a cloud data warehouse benchmark cluster. A Fivetran warehouse benchmark received 44 citations by itself, while two Fivetran benchmark pages together accounted for 58 of the 90. Once that cluster was removed, original research had a much smaller presence in the citation set.

    A benchmark gives proprietary data a clear job

    Translucent data fragments pass through a circular framework and emerge as an orderly set of comparable geometric forms.

    The reported pattern is better understood as a benchmark advantage than a general research advantage. A benchmark measures named alternatives against a defined yardstick and publishes comparable results. It can therefore answer questions such as which product is faster, less expensive or more efficient under stated conditions.

    This format aligns the evidence with the shape of a commercial query. When a prompt asks an AI system to compare options, a benchmark supplies entities, criteria and results in one source. A collection of interesting statistics may demonstrate expertise, but it is less useful if the numbers do not resolve a recognizable decision.

    The warehouse examples illustrate that alignment. Search Engine Land reported that the primary-research citations clustered around prompts involving measurable characteristics such as speed, cost, latency, yield and performance. Fivetran, Estuary and ClickHouse had numerical evidence applicable to those comparisons. In the crypto and Solana area, Marinade and Helius received citations for firsthand data relevant to staking and MEV questions.

    The pattern was not uniform across subjects. After the source’s data cleaning, no cited primary-research pages were found in its B2B SaaS and CRM, education and TEFL, or product analytics topics. Those areas instead surfaced formats such as explainers, product pages, case studies and listicles. This does not show that benchmarking is impossible in those markets. It indicates that the observed citation advantage appeared where the prompt, metric and competing entities could be connected cleanly.

    Retrievability turns a study into citation infrastructure

    An illuminated path connects an abstract AI network to a highlighted block within an orderly digital research archive.

    The Fivetran example helps separate data creation from citation readiness. Its reported performance was not attributed to one isolated statistic. The page combined a direct comparison, visible methodology, supporting material and a structure that made individual answers easy to locate.

    A bounded question and recognizable entities

    The benchmark named BigQuery, Redshift, Snowflake and Databricks and evaluated them on speed and cost. This creates a close match between a buyer’s comparison and the content’s entities and measurements. The research is not simply about cloud infrastructure in general; it is organized around identifiable choices.

    A method readers can inspect

    Search Engine Land reported that Fivetran used actual customer usage rather than relying only on synthetic assumptions. The page explained the queried data, the queries used, and the configuration and tuning of each warehouse. It also linked to underlying data and supporting references. Those elements allow a reader to examine where the results came from and where comparisons might cease to be equivalent.

    Limits, corrections and a stable home

    The benchmark included dated correction notes from December 2022, qualitative limitations and a caveat about a performance floor. These disclosures narrow the claim instead of presenting the result as universal. The source also noted that the URL remained at one canonical address: a page published in 2022 was still receiving citations in the analyzed 2026 data.

    Together, these features make the page function less like a campaign asset and more like durable reference material. Clear result headings help isolate relevant passages; methodology makes the figures interpretable; raw material supports verification; and corrections preserve trust without discarding the accumulated authority of the original URL.

    Research planning should begin with the decision

    A benchmark-oriented program starts by identifying a recurring question that can be answered with evidence the publisher is genuinely positioned to collect. The relevant opportunity is not necessarily the largest available dataset. It is the gap where buyers compare named alternatives but lack a credible, well-scoped source with reproducible measurements.

    The metric must also represent the decision fairly. A speed comparison needs declared workloads and configurations; a cost comparison needs a consistent basis; and any ranking needs boundaries that prevent a conditional result from appearing universal. Methodological disclosure is therefore part of the product, not supporting material to add after publication.

    Editorial structure matters for the same reason. A useful benchmark states the question, identifies the compared entities, defines the yardsticks, presents the result and explains why it may differ from other findings. Descriptive headings should connect each passage to a likely reader question. Supporting data, source notes, limitations and dated corrections should remain attached to the canonical page.

    This approach also establishes a higher bar for deciding what deserves publication. Proprietary numbers that cannot support a meaningful comparison may still be useful for internal analysis, thought leadership or market education. They should not automatically be treated as citation assets. The observed advantage belongs to research whose evidence, question and presentation reinforce one another.

    Key takeaways

    • In the reported Gauge set, primary-research pages were rare but averaged about 3.3 times as many citations per page as other cited pages.
    • Most primary-research citations were concentrated in cloud data warehouse benchmarks, so the result should not be generalized to every proprietary-data article.
    • The strongest format compares named options using explicit, commercially relevant measurements.
    • Methodology, underlying data, limitations, correction notes and a stable canonical URL help turn a result into a durable reference.
    • A research brief should begin with the buyer’s decision and work backward to the data, metric and test conditions needed to answer it responsibly.

    As more publishers produce original data, scarcity alone will become a weaker differentiator. The more durable opportunity is to build benchmarks that remain understandable, inspectable and useful whenever an AI system or a person needs to make the comparison again.

    References