Tag: Citations

  • Brand Visibility in Google AI: From Citation to Recommendation

    Brand Visibility in Google AI: From Citation to Recommendation

    Brand visibility in Google AI results is no longer a simple matter of ranking or being cited. A company can make its content available, have that content used as evidence, and still watch Google recommend a competitor.

    The two source reports expose different sides of that problem: one examines controls over participation in Google’s AI experiences, while the other shows why participation alone does not secure an endorsement. Together, they suggest a more useful framework for managing AI visibility.

    AI visibility now passes through three separate gates

    Google AI visibility can be understood as three related but distinct outcomes: eligibility, citation and recommendation. Treating them as interchangeable can produce misleading reports and poor strategic decisions.

    • Eligibility: Whether a publisher permits its content to appear in an AI-powered search experience.
    • Citation: Whether Google uses a page as supporting material in an AI-generated response.
    • Recommendation: Whether the response presents the brand itself as an option a user should consider.

    The article about Google’s reported AI opt-out controls concentrates on the first gate. It says site owners are being given a way to exclude content from experiences such as AI Overviews and AI Mode, alongside early-stage AI reporting in Google Search Console. The article about self-promotional software listicles concentrates on the second and third gates, reporting that Google may cite a company’s page without recommending that company.

    This distinction changes the central business question. Being available does not guarantee selection, but becoming unavailable removes even the opportunity to supply evidence, earn a mention or influence the comparison.

    Why a citation can create visibility for a competitor
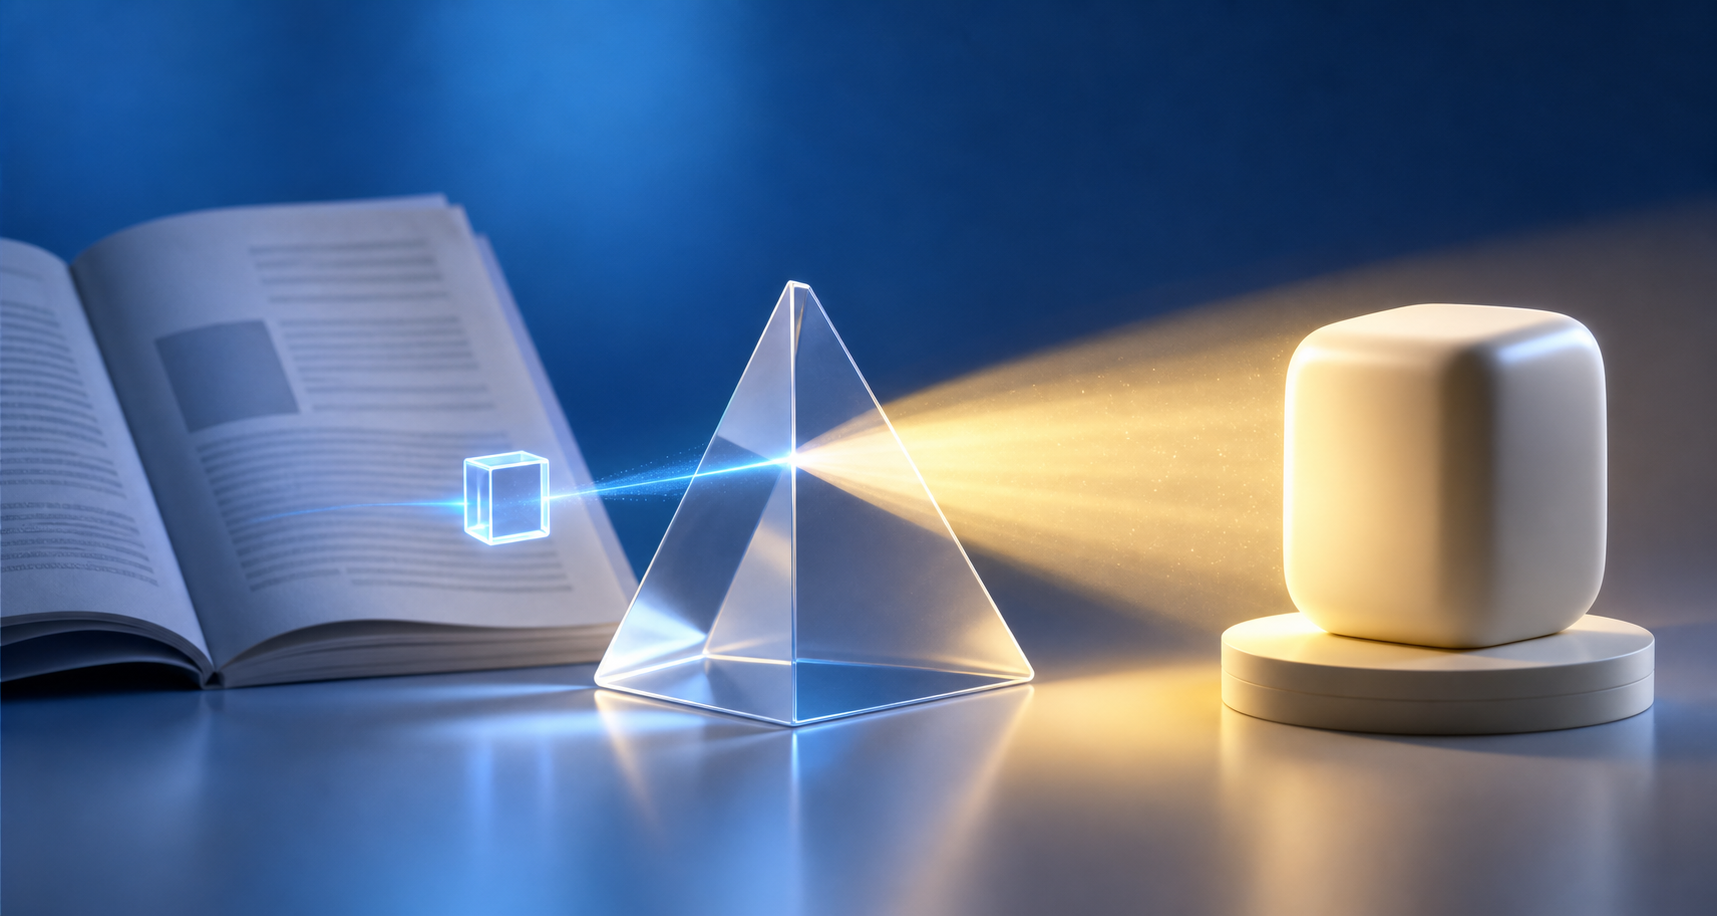
    An open document feeds evidence into a translucent AI prism that directs a spotlight toward a different product-shaped object.

    The clearest warning comes from the analysis attributed to Lily Ray in the source about "best" software listicles. According to that report, Ray examined 100 B2B software queries across three collection dates: April 15, May 15 and June 8. Eighty of those queries produced an AI Overview.

    The source reports that self-serving listicles appeared among the citations 323 times, but that the publishing brands were not recommended in 224 of those instances. It also reports that such listicles were cited in 69% of the B2B software queries studied. Those figures come from a limited query set and should not be generalized to every market, but they illustrate an important failure mode: content visibility and commercial visibility can move in different directions.

    In one example described by the source, an Oasis LMS page was cited for a query about the best learning management system for selling courses, while Kajabi and other competitors appeared among the recommended options. The owned page may therefore have helped Google construct an answer without persuading the system to favor its publisher.

    The same report says third-party sources including Reddit, Forbes and YouTube were becoming more prominent in citations for these queries. That observation supports a broader interpretation: a brand’s claim about itself is only one input, while external discussion may help determine whether the brand is treated as a credible recommendation. The sources do not establish a precise causal formula, so this should be treated as a strategic hypothesis rather than a confirmed ranking rule.

    Opting out changes brand eligibility, not user demand

    The opt-out source argues that withdrawing content does not stop people from using AI Overviews or AI Mode. Instead, it changes which brands and sources remain eligible to appear. Under that interpretation, an absent publisher leaves Google to assemble its response from participating competitors and third parties.

    That does not make participation an automatic choice for every organization. Publishers may have legitimate concerns about content rights, representation, traffic substitution or the commercial value exchanged when their work supports an AI answer. The key is to evaluate those concerns against the actual effect of the control. An opt-out is a content-distribution decision, not a mechanism for reversing user adoption of AI search.

    The listicle findings make the trade-off more complicated. Remaining eligible can create an opportunity to be cited, but citation may still transfer attention to another brand. The strategic task is therefore not merely to stay present. It is to improve the probability that Google’s answer connects the evidence supplied by a company with a favorable, accurate representation of that company.

    A measurement model for meaningful AI visibility
    Three translucent rings surround a central object as document tiles, evidence nodes, and spotlights form pathways toward it.

    The opt-out article calls for reporting that extends beyond conventional SEO traffic and includes brand mentions, citation frequency and representation across AI platforms. The listicle analysis demonstrates why those dimensions must be separated rather than collapsed into a single visibility score.

    A practical monitoring program can classify each important query using the following fields:

    • AI result presence: Whether the query triggers an AI-generated result.
    • Source inclusion: Whether the company’s domain is cited or otherwise used.
    • Brand inclusion: Whether the company is named in the generated answer.
    • Recommendation status: Whether the brand is presented as a preferred or relevant option.
    • Competitor benefit: Which rival brands are recommended when the company’s content is cited.
    • Representation quality: Whether the description of the brand, product and limitations is accurate.

    This structure makes several otherwise hidden outcomes visible. A page can win a citation while the brand loses the recommendation. A brand can be mentioned without receiving a link. A competitor can gain the commercial benefit from evidence published by someone else.

    Content reviews should follow the same separation. Self-authored comparison pages need a transparent method, supportable claims and meaningful treatment of alternatives; simply declaring the publisher’s product the best may not influence the recommendation as intended. Because the reported study also observed more third-party citations, teams should assess how the brand is described outside its own domain instead of treating owned content as the whole AI visibility strategy.

    Key takeaways

    • Eligibility, citation and recommendation are separate stages of Google AI visibility.
    • According to the reported B2B software analysis, Google often cited self-promotional listicles without recommending their publishers.
    • Opting out may remove a brand’s content from consideration, but it does not remove the user’s underlying AI search activity.
    • Reporting should identify who supplies the evidence, who receives the mention and who ultimately earns the recommendation.

    As Google’s controls and reporting mature, the strongest strategy will be based on observable outcomes rather than a binary debate over participation. Brands that distinguish being used as a source from being selected as an answer will be better equipped to protect and improve their visibility.
    References

  • How to Build Content Authority Across AI Search Engines

    How to Build Content Authority Across AI Search Engines

    Content authority in AI search is not a single score that a brand earns once and carries everywhere. The source reports point to a more conditional system: visibility depends on the AI engine, the topic and prompt, the sources retrieved, and whether a useful passage can be extracted from the page.

    That changes the optimization task. Instead of producing one broad guide and accumulating undirected mentions, publishers need to decide where they want to appear, understand what that system retrieves for the topic, and create evidence-rich passages that can survive the final selection process.

    Authority now operates at three distinct layers

    A cutaway illustration shows a source network, modular content blocks, and selection lenses arranged in three layers.

    Taken together, the sources suggest that AI visibility has three layers: engine selection, topical trust, and passage extractability. A weakness at any layer can prevent a brand from being cited even when its conventional search performance is strong.

    The engine layer determines which index, retrieval process, and content formats are likely to enter consideration. Uncover 7 Unmissable AI Search Trends Transforming Marketing reports that ChatGPT and Claude shared only 8% of citations in the analysis it covered. It also reports substantial format differences: community sites accounted for about 16% of ChatGPT citations, while Claude cited listicles 36% of the time and opinion content 13.2% of the time, compared with approximately 20% and 7.2%, respectively, for ChatGPT.

    The topic layer determines whose evidence the system treats as relevant and credible. Boosting AI Visibility: Mastering Topic-Driven Authority argues that citation sources cluster by subject rather than following one universal hierarchy. Its examples indicate that competitor domains had a larger role in invoicing queries than in starting-a-business queries. A publication that matters for one part of a market may therefore contribute little authority to an adjacent part.

    The passage layer determines whether the system can isolate a clear answer from the selected document. Mastering AI Search: Building Machine-Friendly Content reports a 66% extraction rate for pages under 5,000 characters and 12% for pages over 20,000 characters. Those figures should be treated as findings reported by that article, not as a universal length rule. Their strategic significance is that authority without retrievable statements may never become a citation.

    Choose the engine and prompt class before optimizing

    An AI-search plan should begin with the audience and the engine it uses, not with a generic content calendar. The trends report says 64% of sites cited by Claude appeared in Google’s top 50 for corresponding queries, compared with 37% of sites cited by ChatGPT. It further reports that 79.2% of Claude citations aligned directly with the top 10 Brave Search results in the analysis it references. Within that reported environment, Brave rankings offer a more observable diagnostic for Claude than conventional Google rankings alone.

    Audience context may also affect prioritization. Citing Ramp’s AI Index, the trends article reports Anthropic usage at 34.4% of businesses and OpenAI at 32.3%. It also says approximately 85% of Anthropic’s revenue came from enterprise and API usage. These figures do not establish that every B2B organization should optimize for Claude first, but they support testing Claude as a distinct business channel rather than treating its consumer web traffic as a complete measure of relevance.

    Even a priority engine is not equally optimizable for every prompt. According to the same report, ChatGPT initiated web searches for nearly 95% of prompts in the cited analysis, while Claude did so about one-third of the time. Claude was reportedly more likely to search for current-event, ranking, location, and comparison prompts, with reported search rates of 81%, 67%, 55%, and 51%, respectively. Definitions and procedures were described as much less likely to trigger retrieval.

    This distinction prevents a common measurement error. A page cannot win a fresh web citation when an engine answers from internal model knowledge without searching. Prompt testing should therefore record whether retrieval occurred before a team interprets a missing citation as a content or authority failure.

    Query expansion adds another engine-specific variable. The trends report characterizes ChatGPT fan-out queries as changeable, while reporting that Claude produced the same fan-out strings 65% of the time and attached the current year to 94% of them, compared with 17% for ChatGPT. Stable expansions may support tightly targeted pages; volatile expansions call for broader coverage across owned, earned, community, and other relevant sources.

    Design passages around problems, claims, and constraints

    A modular claim block is supported by source, context, and constraint pieces while a scanning beam isolates it from surrounding blocks.

    Machine-friendly content is not simply shorter content. The more useful objective is modularity: each section should resolve a recognizable subproblem without requiring an AI system to reconstruct the answer from a long narrative.

    The machine-friendly content report recommends replacing broad category positioning with problem-specific positioning. Its illustrative shift is from identifying a company merely as an insurance provider to explaining that it addresses underwriting for first-time drivers under 25 who have been declined by standard insurers. The example also shows why constraints matter. Stating who a solution is not for, where it applies, or what condition changes the answer can make a claim more precise and credible.

    Headings should name the outcome or question addressed by the section. Paragraphs should open with a direct answer or citable claim, then add conditions, evidence, and explanation. The same source reports that explicit headings increased retrieval likelihood by 17.54% and says Gemini may use approximately 380 words for query grounding. These reported limits reinforce the value of self-contained sections, although they do not justify stripping away evidence or necessary nuance.

    The synthesis is a two-level editorial model. At page level, the article should offer a coherent argument for a human reader. At passage level, it should state entities, relationships, qualifications, and evidence clearly enough to be extracted independently. Narrative still has a role, but it should extend a usable answer rather than delay it.

    Build off-site authority inside the relevant source network

    On-site clarity makes a document usable; it does not make the publisher trusted by every system or for every topic. The topic-driven authority report recommends mapping the domains, publications, experts, and platforms that repeatedly appear in answers for the exact subject a brand wants to own. This is more focused than pursuing links or publicity from generally prominent sites without checking their topical role.

    That mapping should also distinguish content formats. The topic-authority report describes YouTube as an exception that can surface across larger language models and recommends working with recognized subject-matter experts and relevant LinkedIn voices. The engine trends report, meanwhile, finds that community content was more prominent in ChatGPT citations and that listicles and opinion pieces were more prominent in Claude citations. Together, these observations suggest that the right distribution mix depends on both the topic’s trusted entities and the target engine’s retrieval preferences.

    Concentration may matter more than raw mention volume. The authority report argues that recognition can move in jumps when a brand earns coverage from a highly trusted topical source, and it recommends ranking potential collaborators by authority tier. This remains a strategic recommendation from the source rather than proof that every high-profile placement will produce citations. Teams should validate it by comparing citation frequency before and after individual placements.

    Measurement should follow the same conditional structure. For each priority prompt, a useful record includes the engine, whether it searched the web, the apparent query expansions, cited domains, cited passage types, the brand’s inclusion, and the presence of paid placements. The trends report says ChatGPT ads can appear around competitor mentions, so organic citation monitoring and paid competitive monitoring should be kept separate. Otherwise, a purchased appearance can be mistaken for earned authority, or a strong organic mention can obscure a competitor’s paid defense.

    Key takeaways

    • Define authority by engine and topic; citation strength in one model or subject does not automatically transfer to another.
    • Confirm that the target prompt triggers web retrieval before investing in pages intended to earn fresh citations.
    • Build problem-specific, self-contained sections with direct claims, explicit conditions, and enough evidence to stand alone.
    • Concentrate outreach on the publications, experts, communities, and formats that already shape answers for the target topic.
    • Measure retrieval, organic citations, and paid placements separately so each visibility mechanism can be diagnosed accurately.

    As retrieval systems, source preferences, and advertising models change, durable advantage will come from maintaining this engine-topic-passage map as a living operating system rather than treating AI optimization as a one-time rewrite.

    References

  • From Search Intent to Citation Share: Measuring AI Visibility

    From Search Intent to Citation Share: Measuring AI Visibility

    AI search visibility is becoming easier to observe, but measurement alone does not explain what content should change. Bing’s emerging reporting describes where a site appears across intents, topics and citations; the next-question intent framework examines whether its pages contain enough detail to support the comparisons and decisions behind those appearances.

    Used together, these perspectives create a practical loop: identify the contexts in which a site is being cited, inspect whether the underlying content supports the user’s full decision path, and then monitor how citation visibility changes.

    Two layers of intent explain different parts of visibility

    The Bing reporting source says the preview of its enhanced AI performance report classifies grounding queries by intent, including Informational, Commercial and Navigational categories. This is a reporting layer: it helps publishers understand the broad purpose associated with the queries for which their content surfaces.

    Next-question intent is an editorial layer. The separate analysis defines it as the information a person will need after the opening query to compare options, establish trust or make a decision. A page can therefore match an initial commercial query while still failing to answer the more specific questions that determine which option is suitable.

    The distinction matters because the two concepts should not be treated as competing taxonomies. Reported intent describes an observed visibility context. Next-question intent helps diagnose whether a page has enough substance to remain useful as that context becomes more specific.

    Key takeaways

    • Bing’s reported intent and topic views organize AI visibility by user purpose and thematic context rather than isolated queries alone.
    • Citation Share and Compare provide directional evidence about visibility, but they are not rankings, quality scores or proof of business impact.
    • Next-question intent connects reporting to content decisions by identifying the follow-up information users need to trust, compare and choose.
    • The strongest workflow reads intent, topic and citation signals together, then validates the relevant pages for specificity, evidence and decision support.

    How Bing’s reporting dimensions fit together

    An isometric website tile connects to groups of intent gateways, topic spheres, and citation markers.

    According to the Bing reporting article, the new enhancements are being introduced globally as a preview. The source says Bing had launched its underlying AI performance report in February and that a similar Google Search Console feature arrived in June. Those dates and the characterization of Google’s release come from the source and are not independently verified here.

    Reporting dimensionWhat the source says it showsUseful question for publishers
    IntentsGrounding queries classified into broad purposes such as Informational, Commercial and NavigationalIn what kinds of user situations is the site appearing?
    TopicsRelated queries grouped into thematic clustersWhich broader subjects are producing visibility?
    Citation ShareThe site’s percentage of citation visibility relative to other sourcesIs the site’s presence expanding or contracting within the measured set?
    ComparePrevious data overlaid on current reportingHow has citation activity changed between the displayed periods?

    These dimensions become more informative when read as a sequence. An intent indicates the general task, a topic identifies the subject area, Citation Share supplies a relative visibility signal, and Compare adds a time dimension. No individual metric provides the whole explanation.

    The source illustrates topic clustering with queries about solar panels and solar energy efficiency being grouped under a broader Solar Energy theme. It also cautions that labels may remain broad for niche domains during the preview. Topic names should therefore be treated as navigational aids for analysis, not as exact descriptions of every underlying query.

    Next-question intent turns observations into content diagnosis

    A report might reveal visibility in commercial, comparison-oriented experiences, but it cannot by itself determine whether a page answers the questions that shape a purchase. The next-question analysis uses a search for the best customer relationship management software for a small business to make this problem concrete. The opening request does not settle which product fits a two-person team, integrates with QuickBooks, works without a formal sales department or suits a local service company.

    Those follow-ups expose the difference between category relevance and decision utility. A page can accurately describe several products yet give an AI system little usable material for distinguishing who each product serves, when it is appropriate, how it differs from alternatives or what supports its claims.

    The analysis applies the same test to broad brand language. Claims such as customized strategies, family safety or suitability for small businesses remain underspecified unless the page explains how the offer is customized, which family members are covered, or which kinds of small businesses are meant. This is not a call to make pages longer by default. It is a call to replace ambiguity with relevant conditions, distinctions and evidence.

    For an informational intent, the next question may concern method, limitations or applicability. For a commercial intent, it may concern trade-offs, compatibility or fit. For a navigational intent, it may concern the exact destination or action available there. These examples are an analytical extension of the source framework rather than categories reported by Bing.

    A reporting-to-content workflow for AI visibility

    A circular sequence links citation observation, branching questions, expanded content blocks, and ongoing monitoring.

    Start with the intersection of intent and topic rather than a sitewide citation total. A change within a particular context is more actionable than an aggregate movement because it narrows the pages and user needs that deserve investigation. Citation Share can then indicate whether the site’s relative presence in that measured environment is moving, while Compare provides the period-over-period view described by the Bing source.

    Next, inspect the pages associated with that context as decision resources. The relevant test is whether they explain what the offering or subject is, whom it applies to, when it is useful, how alternatives differ and what evidence supports consequential claims. The next-question source argues that this substantive layer gives AI systems material they can synthesize, compare and use in recommendations.

    Content changes should address identifiable gaps rather than chase a metric mechanically. If a page appears around a comparison topic but lacks selection criteria, the useful revision is to clarify fit and trade-offs. If a niche topic label is broad, analysis should begin with the underlying pages and their actual subject matter instead of assuming that the dashboard label precisely captures demand.

    Finally, monitor the same intent-topic context over time. The Bing source notes that citation activity can be affected by AI model updates, changes in user demand and other factors. A rise or fall after an edit is therefore a signal for further investigation, not automatic evidence that the edit caused the movement.

    What current visibility reporting cannot establish

    Citation visibility is not equivalent to a conventional ranking. The Bing article explicitly describes Citation Share as directional and says it does not provide a ranking or quality score. A citation also does not, on its own, show whether the user clicked, converted, trusted the source or ultimately selected the brand.

    The source further says click and click-through rate data were still awaited. Without those measures, the reported tools are best suited to visibility diagnosis and trend monitoring. They should not be presented as a complete attribution system or as proof of commercial performance.

    Next-question intent has a boundary as well: it is a framework for improving content utility, not a guaranteed formula for earning citations. Its value is in making pages more explicit and decision-ready while reporting supplies evidence about where visibility exists and how it changes.

    As AI reporting develops, the durable advantage will come from connecting clearer measurements to better editorial questions. Publishers that preserve the distinction between an observed citation, an inferred cause and a verified outcome will be better positioned to improve content without overstating what the dashboards prove.

    References

  • AI Search Visibility: From Retrieval to Recommendation and Action

    AI Search Visibility: From Retrieval to Recommendation and Action

    AI search visibility is no longer adequately described by rankings or clicks alone. A brand may be discovered as a source, cited in an answer, recommended for a particular need or selected by an agent that completes a task – and each outcome requires a different kind of optimization.

    Read together, the source articles suggest a practical model for this environment: make the brand retrievable, unambiguous, independently credible, suitable for a defined audience and technically ready for action. This model connects traditional SEO, generative engine optimization and the emerging discipline of agentic search optimization without treating them as interchangeable.

    AI visibility is a chain, not a single ranking

    Traditional search usually exposes a list of pages and leaves most of the evaluation to the user. AI systems can compress several parts of that journey into one response. They may retrieve information from multiple sources, decide which evidence deserves a citation, compare possible providers and recommend an option that appears to fit the user’s circumstances.

    The CrushPress.AI article on retrieval versus citation makes an important distinction: being available to an AI system does not guarantee that the content will be cited. Its argument is that citation-worthy content must combine familiar technical SEO foundations with a useful experience, clear audience relevance and credible signals beyond the brand’s own website.

    The travel-focused source extends this distinction from citations to recommendations. It describes AI-assisted travel planning as a conversational process in which people ask for options matching constraints such as location, budget, atmosphere or family needs. The desired output is often a recommendation rather than a directory of links. The source framed around trust and brand visibility, meanwhile, reinforces the broader issue connecting these stages: an AI system needs sufficient confidence in the brand and its claims.

    The agentic-search article adds another stage. It distinguishes generative engine optimization, where a person still acts on an AI recommendation, from agentic search optimization, where software may evaluate options and execute the task. Its reported framework divides that process into retrieval, evaluation and action.

    Visibility stageQuestion the system must answerPrimary optimization needUseful measurement
    RetrievalCan the brand or content be found?Crawlable content, clear structure and relevant external mentionsPresence across a controlled set of prompts
    CitationIs this source useful and credible enough to support the answer?Specific evidence, clear explanations and corroborationCitation frequency and accuracy
    RecommendationIs the offering a strong fit for this user’s needs?Explicit positioning, suitability criteria and reliable attributesRecommendation share and represented attributes
    ActionCan the requested task be completed?Machine-readable information and a usable transaction pathCompletion, abandonment and assisted conversion

    This chain explains why a visibility strategy focused only on ranking can underperform. Retrieval is necessary, but it does not by itself produce a citation, recommendation or transaction.

    Resolve the brand, verify its claims and communicate fit

    A sharply defined faceted object is illuminated by connections from several independent evidence sources while similar objects remain blurred in the background.

    AI systems synthesize information from an ecosystem rather than treating a company’s website as the sole authority. Both the retrieval-versus-citation article and the travel-brand report emphasize the importance of consistent positioning across owned pages and third-party platforms. Read alongside the trust-focused source, their shared implication is that brand visibility depends partly on reducing uncertainty.

    A practical entity audit should answer several questions:

    • Is the brand’s primary category stated consistently?
    • Are its target customers and strongest use cases explicit?
    • Do the website and major external profiles agree on important facts?
    • Can important product, service or location attributes be found in structured, accessible content?
    • Do reviews, editorial mentions or other independent sources substantiate the positioning?
    • Are outdated descriptions or conflicting details weakening confidence?

    The travel article illustrates this with properties that serve different needs. A family-oriented hotel should consistently surface family suites, activities and relevant guest feedback, while a business hotel should make workspaces, connectivity, meeting facilities and location context clear. The wider lesson is not limited to travel: a brand should identify the situations in which it is a particularly good option and ensure those attributes recur accurately across the sources an AI system may consult.

    Structured data can help machines interpret categories, locations, amenities and other defined attributes. Server-side rendering, understandable page structure and sound technical SEO also remain relevant, according to the retrieval-versus-citation source. These measures improve accessibility and interpretation, but none should be presented as a guarantee of citation. Technical clarity supplies evidence; it does not manufacture authority.

    Independent corroboration therefore matters. The sources recommend relevant editorial coverage, digital public relations, reviews, guides and accurate platform listings. The objective is not to accumulate undifferentiated mentions. It is to have credible sources associate the brand with the same meaningful qualities that appear on its own site.

    Fit information deserves equal attention. The agentic-search article recommends suitability pages that state who an offering serves and who it does not. Boundaries can make a claim more credible and give an evaluating system information it can use. Useful pages might organize the decision around audience, use case, requirements, limitations, alternatives and proof rather than repeating broad promotional language.

    The evidence reported for agent behavior comes from one source and should be treated accordingly. The CrushPress.AI summary of a First Page Sage study says the researchers issued 2,417 agentic commands between March 4 and June 10, 2026. It reports that agents selected a platform’s top-ranked recommendation in 44.6% of commands but chose an option ranked fourth or lower in 38.2%. It also reports that pre-existing brand beliefs influenced 81.6% of evaluations. These findings have not been independently verified in the supplied material, but they support a useful strategic hypothesis: inclusion in the candidate set and perceived suitability are separate competitive problems.

    Prepare the conversion path for agent-led action

    A robotic hand moves a glowing token through connected digital gates toward an open package and a green completion light.

    Optimization changes again when software is expected to do more than make a recommendation. An agent may need to check requirements, compare prices, confirm availability, submit information or complete a purchase. Content that is persuasive to a person can still fail if the underlying process cannot be interpreted or operated reliably.

    The agentic-search source reports a large difference in its study between machine-actionable and non-actionable conversion pages. According to the article, agents completed 78.3% of attempts when the page was machine-actionable, compared with 9.6% when it was not; the source says agents often substituted a transactable competitor. Because this result comes from the study as described by a single publication, it should be treated as directional evidence rather than a universal benchmark.

    Organizations preparing for this stage can examine the complete task path:

    <!– wp:list {
  • AI Search Visibility: How Prompts and Rankings Shape Citations

    AI Search Visibility: How Prompts and Rankings Shape Citations

    AI search visibility is not one universal ranking contest. A page’s chance of appearing in an answer depends on what the user asks, whether the AI searches the live web, which search index it consults and how easily the page can support the requested response.

    The two source reports illuminate different parts of that process. One maps prompt patterns across healthcare, B2B and ecommerce; the other examines when Claude reportedly searches and how Brave Search rankings affect its citations. Together, they suggest a practical strategy built around prompt demand, retrieval eligibility and answer-ready evidence.

    A prompt can change whether an AI searches at all

    Two abstract prompts enter an AI core, with one leading directly to an answer and the other triggering a search across web pages.

    AI answers can draw on information already represented in a model or retrieve material from the web. That distinction matters because a page cannot earn a live citation in an answer when no web search takes place.

    The Claude visibility report attributed to Jonathan Clark said Claude used web search in 36.6% of the observed cases, compared with about 90% for ChatGPT. It also reported that Claude was more likely to search when prompts signaled recommendations, rankings, location, recency or direct comparison. Definition and process formulations such as how something works, what something is or which steps to follow were reportedly less likely to trigger a search.

    Prompt signalReported Claude web-search rateLikely information need
    Best81%Recommendation or shortlist
    Ranking-focused67%Ordered evaluation
    Location55%Geographically relevant information
    Comparison51%Trade-offs between alternatives

    These figures come from the reported analysis and should not be treated as universal platform benchmarks. Their strategic value lies in the pattern: prompts that require fresh, comparative or context-dependent evidence appear more likely to create a retrieval opportunity than prompts that can be answered from general model knowledge.

    Search rankings matter, but visibility does not transfer cleanly

    The Claude report said the system frequently relied on Brave Search for web retrieval and incorporated Brave’s top 10 results without rearranging them. If that behavior holds for a target prompt set, Brave ranking becomes a measurable eligibility layer: content must first enter the retrieved result set before it can be considered for citation.

    At the same time, the sources caution against treating conventional rankings as a complete proxy for AI visibility. The prompt-pattern report cited research as finding that more than 80% of links in AI-driven searches came from domains outside the traditional top search results. By contrast, the Claude analysis reported a 64% overlap between Claude’s results and Google rankings, while Claude and ChatGPT citations matched in only 8% of cases for the same queries.

    Those measurements describe different systems and apparently different analyses, so they should not be combined into a single benchmark. The useful synthesis is that ranking influence is engine-specific. Google performance may have some relationship with Claude visibility, Brave may directly affect Claude’s retrieved candidates, and neither reliably predicts which sources ChatGPT will cite.

    The Claude report also said query fan-outs returned the same results across users 65% of the time and frequently included years. Clark suggested that a current year in a title might help with some ranking- and recency-driven searches. That is a testable hypothesis, not a reason to add dates indiscriminately: a dated title should correspond to genuinely maintained content.

    Industry prompts determine what evidence a page must provide

    Retrieval is only the first gate. Once a page is available to an AI system, its usefulness depends on whether it contains the facts, relationships and qualifications needed for the user’s prompt. The prompt-pattern report described markedly different expectations by vertical.

    VerticalReported prompt patternContent implication
    HealthcareSymptoms combined with personal context, medication considerations and safety thresholdsOrganize information around symptom combinations, risk factors, cautions and clear guidance on when professional help may be needed.
    B2BVendor comparisons shaped by company requirements, implementation effort and return on investmentPublish transparent comparison criteria, technical details, timelines and substantiated commercial evidence in extractable formats.
    EcommerceQuality and review signals combined with budgets, use cases and exclusionsConnect crawlable reviews, product attributes, constraints and specifications to practical buyer outcomes.

    This changes the unit of optimization. An isolated keyword may identify a subject, but a prompt often expresses a decision that must be made. A healthcare reader may need to distinguish monitoring from urgent action; a B2B buyer may need to defend a purchase; an ecommerce shopper may need to eliminate products that fail a specific constraint. Content designed only to define the topic can be relevant in a broad sense yet still lack the evidence required for the answer.

    The same principle explains the value of headings, concise answer passages, comparison tables, structured product information and crawlable supporting detail. The prompt-pattern report said optimization for direct citations and structured information could improve visibility by as much as 40%, citing research from Princeton and the Allen Institute for AI. Because that figure is relayed through the source rather than independently established here, it is best treated as directional support for extractability rather than a guaranteed uplift.

    Measure the path from prompt to citation

    A query travels through search, ranked pages, and an evidence checkpoint before selected source cards connect to an AI-generated answer.

    Prompt coverage

    Research should begin with realistic prompt classes rather than a renamed keyword list. Search logs, customer questions, sales conversations and support interactions can reveal the attributes people combine, the comparisons they request and the follow-up questions that shape a decision. Each important class should include enough context to represent the actual task.

    Retrieval eligibility

    Testing should record whether an AI searches the web for each prompt, which query variations it generates and which domains appear in the underlying search results. For Claude prompts involving recency, rankings or comparisons, the source report indicates that Brave deserves specific attention. Traditional Google tracking remains useful, but it should not stand in for direct observation of the answer engine being evaluated.

    Answer inclusion

    A retrieved page still has to be selected, represented accurately and cited. Measurement should therefore distinguish ranking in the source engine from appearing in the AI answer. Repeated tests can track whether the brand is mentioned, whether its page is cited, which passage appears to support the response and whether competitors provide evidence the page lacks.

    Key takeaways

    • Prompt structure affects both the likelihood of live retrieval and the evidence an answer requires.
    • Search rankings can create citation eligibility, but the relevant index and degree of overlap vary by AI system.
    • Healthcare, B2B and ecommerce content need different forms of context, proof and decision support.
    • Readable structure helps only when the underlying information is specific, transparent and responsive to the prompt.
    • Visibility reporting should separate prompt coverage, retrieval rankings and actual answer citations.

    As AI search interfaces evolve, durable visibility will come from testing the whole route between a real audience question and a supported answer. Teams that maintain useful evidence, observe each engine directly and update prompt sets as customer needs change will be better positioned than those relying on a single ranking proxy.

    References

  • AI-Driven SEO Strategy: Build Monitoring That Leads to Action

    You can lose search visibility without seeing one dramatic ranking drop. A robots change can block discovery, a stale claim can weaken trust, and a page can keep receiving traffic while disappearing from AI citations. If your dashboard reports only clicks and conversions, it may reveal the damage too late.

    A useful monitoring system works as a control loop: detect a meaningful change, identify the affected layer, assign an owner, repair the cause, and verify recovery. That gives you something more valuable than another dashboard: a repeatable way to protect and improve visibility.

    Key takeaways

    • Monitor access, meaning, selection, and business outcomes separately so you can locate failures quickly.
    • Use alerts for changes that require a decision, not every movement in a metric.
    • Track AI citations alongside rankings because retrieval and selection are different stages.
    • Keep page copy, entity details, internal links, and structured data consistent.
    • Pair monitoring with original information, brand building, distribution, and public relations.

    Monitor the full path from discovery to conversion

    Start by separating the signals in your dashboard. Search performance can fail at several points, and each point needs a different response.

    Monitoring layerWhat to watchWhat the signal tells you
    AccessStatus codes, robots directives, noindex tags, canonicals, sitemaps, rendered content, and important resource filesWhether crawlers and AI systems can reach the intended version of a page
    MeaningCore claims, headings, organization and author details, internal links, JSON-LD, and consistency across related pagesWhether machines can interpret the page and connect it to the right entities
    SelectionRankings, AI-answer inclusion, citations, brand mentions, competitor inclusion, and visibility by query intentWhether an eligible page is being chosen for an answer or search result
    OutcomeLanding-page visits, identifiable AI referrals, conversions, assisted actions, and engagement with priority pagesWhether visibility is producing useful business activity

    This separation matters because AI-facing search introduces a selection problem. A system may discover and understand your page without choosing it for a generated response. Broader candidate pools place more weight on verification, semantic relationships, trust signals, and distinct information. A crawl report cannot tell you whether you are winning that stage.

    Build your monitored inventory around business importance. Include revenue pages, high-value informational pages, core entity pages, important query groups, and the prompts or questions that lead customers toward a decision. Record the expected URL, canonical, indexability, main claim, schema type, conversion action, and responsible owner for each asset. That expected state becomes your baseline.

    Create alerts that point to a decision

    An alert is useful only when someone knows what it means and what to do next. Continuous monitoring can protect visibility from technical failures, but 24/7 detection and real-time notification still need sensible routing and response rules.

    Favor state changes over routine noise. A priority page becoming non-indexable deserves an alert. So does an unexpected canonical change, a missing schema block, a mismatch between visible copy and JSON-LD, or the disappearance of rendered content. Normal day-to-day movement in one query usually belongs in a trend report unless it repeats across a meaningful group.

    Give every alert a severity, owner, and response note. Reserve the highest severity for failures that affect access or conversion across important assets, such as a sitewide robots change or unavailable purchase path. Use a lower severity for isolated visibility changes that require investigation but do not establish a systemic failure.

    Your alert should answer these questions without requiring a separate investigation just to understand it:

    • What changed?
    • Which URLs, entities, queries, or prompts are affected?
    • What was the last known good state?
    • Was there a deployment, content update, migration, or schema change nearby?
    • Who owns the next action?
    • How will recovery be verified?

    Keep ranking, citation, and conversion alerts connected rather than blended. If citations decline while access and rankings remain stable, investigate content distinctiveness, entity clarity, and corroborating signals. If rankings and citations decline together after a template release, start with technical and rendering checks. If visibility improves but conversions do not, inspect intent alignment and the landing-page journey.

    Use one response workflow for every visibility incident

    A shared workflow prevents teams from making unrelated edits until a metric happens to recover. Use the same sequence whether the first signal comes from crawling, rankings, AI citations, or analytics.

    1. Confirm the symptom. Check the affected URL, query, prompt, device, and market. Determine whether the change is isolated or appears across a coherent group.
    2. Classify the failure. Decide whether the problem concerns access, interpretation, selection, or outcomes. Do not rewrite content to solve a blocked crawler.
    3. Compare with the baseline. Review the last known good crawl, rendered page, structured data output, citation record, and relevant deployment or editorial notes.
    4. Repair the smallest plausible cause. Restore the intended directive, correct the conflicting fact, repair the markup, strengthen an unclear answer, or realign the page with its query intent.
    5. Validate both human and machine views. Check the visible page and its rendered output. Confirm that structured data describes the same facts a reader can see.
    6. Annotate and watch recovery. Record the change, affected assets, owner, and validation result. Keep monitoring the original symptom and downstream business outcome.

    Do not treat recovery as proof that every edit helped. When several changes are bundled together, you lose the ability to identify the effective fix. Small, documented interventions produce a more useful operating history.

    Improve the information that AI systems can select

    Monitoring protects existing visibility, but it cannot create information worth selecting. Pages need precise claims, clear entity relationships, and details that add something beyond the same summary already available elsewhere.

    Review important pages at the claim level. Each answer should state one clear idea, explain its scope, and avoid mixing several loosely related claims in a long paragraph. Remove outdated facts and reconcile contradictions between product pages, help content, author profiles, organization details, and structured data. JSON-LD should reinforce the page’s meaning, not introduce unsupported facts that readers cannot verify.

    Strengthen internal relationships as well. Link an organization to its people, products, policies, evidence, and relevant expertise using descriptive language. This creates a coherent path for readers while helping machines interpret how the entities relate.

    Then look beyond on-page optimization. Keyword research and page improvements remain foundational, but sustainable growth also depends on original research, proprietary information, brand visibility, distribution, and public relations. Track those activities as visibility inputs. Monitor whether new findings earn mentions, whether expert contributions create relevant connections, and whether distribution reaches the communities where your audience already looks for answers.

    Start with one group of commercially important pages. Define their expected technical state, record their core claims and entity relationships, add citation and outcome tracking, and assign each alert to a named owner. Once that loop works, extend it to the next group. A smaller system that produces action is more valuable than a large dashboard nobody trusts.

    References

  • AI-Ready SEO Strategy: A Practical Visibility Framework

    AI-Ready SEO Strategy: A Practical Visibility Framework

    If your pages rank in search but rarely appear in AI-generated answers, adding a few schema fields won’t solve the whole problem. AI visibility depends on whether a system can find your answer, understand what it means, judge it worth referencing, and connect it to a credible brand.

    You need an operating system for those four jobs. The framework below connects query selection, brand context, citation-worthy content, structured data, and measurement so you can improve AI readiness without abandoning the SEO work that already drives traffic and revenue.

    Choose the answers your business needs to own

    “Get mentioned by AI” is too vague to guide a content team. Start with the questions that matter during a real buying journey. A software company might need to appear when someone compares approaches, checks compatibility, evaluates risk, or looks for implementation help. A local business may care more about suitability, location, availability, and service details.

    Create a query-to-page map before you create new pages. For every priority question, record:

    • The exact decision the searcher is trying to make.
    • The audience and level of knowledge behind the question.
    • The page that should provide the best answer.
    • The facts, examples, or evidence that would make that answer credible.
    • The next action you want a qualified visitor to take.
    • Whether the answer is already complete, partly covered, or missing.

    This exercise exposes a common failure: several pages loosely target the same subject, but none gives a self-contained answer. Consolidate overlapping pages when they serve the same intent. Keep separate pages when the reader, decision, or required evidence is materially different.

    Write the direct answer early on the chosen page. Then support it with definitions, constraints, evidence, alternatives, and next steps. A reader should be able to extract a useful answer without interpreting marketing language, while someone making a serious decision should have enough depth to keep reading.

    Give your team and its AI tools durable brand context

    Geometric AI devices connect to one organized central library of product objects, documents, profiles, and evidence folders.

    AI-assisted SEO drifts when each task begins with a fresh prompt. The tool doesn’t know which audience matters most, which claims require caution, why an old keyword was rejected, or what your CMS can actually support. Team handoffs create the same problem when important decisions live in someone’s memory.

    A compact, shared account knowledge base can preserve that context. Separate stable brand rules from changing operational knowledge so people and AI systems can retrieve the right information without treating every old note as permanent policy.

    Record the stable rules

    Your stable layer should cover five things in plain language:

    • Company profile: what you sell, where you operate, and what makes the business meaningfully different.
    • Audience: who you help, what they already understand, and what makes them hesitate.
    • Style: voice, terminology, claim standards, and examples of acceptable writing.
    • Keyword and topic map: priority subjects, intended pages, and known overlaps.
    • Never-do rules: prohibited claims, unwanted angles, legal constraints, and tactics the brand has rejected.

    Record decisions and outcomes separately

    Your changing layer should capture what was decided, why it was decided, what happened afterward, and what evidence supports the entry. Include campaign outcomes, recurring editorial feedback, technical limitations, experiments, and unresolved questions. Add dates and owners so an old constraint isn’t mistaken for a current one.

    You can create a useful first version in a focused 90-minute working session with the people who know the account best. Keep the format simple. Plain-text files in a shared, controlled location are enough to begin. Assign an owner to approve stable-rule changes, while making it easy for the wider team to add new observations to the changing layer.

    Require every AI-assisted brief, draft, optimization, and analysis to load the relevant context first. Small teams can load the whole knowledge base. Larger teams can route only the files needed for a task. In either case, a person remains responsible for checking factual accuracy, current policy, and strategic fit.

    Publish assets that other people would choose to cite

    Clear answers make a page extractable. They don’t automatically make it authoritative. Search engines and AI systems still need reasons to distinguish your page from dozens of competent alternatives.

    Build link intent into the brief. Before drafting, ask who would reference the finished work and what they would gain by doing so. Links and references continue to support authority and discovery, but outreach works best when the page supplies something genuinely useful to the recipient’s audience.

    A citation-worthy asset usually contains at least one element that isn’t easy to replace:

    • A clear method that lets someone repeat a process.
    • A comparison built around explicit, defensible criteria.
    • First-party observations or data with enough methodology to evaluate them.
    • A practical framework that simplifies a difficult decision.
    • A maintained reference page that resolves a recurring question.
    • A timely interpretation that adds useful context rather than repeating news.

    Specificity is the test. “Improve your content” gives nobody a reason to cite you. A documented audit process, decision tree, calculation method, or constraint-based recommendation can become a working reference.

    Plan distribution only after the asset passes that test. Identify journalists, practitioners, publishers, partners, and community leaders who already cover the problem. Explain which part of the asset helps their audience. Don’t lead with a link request, a quota, or a swap. Lead with the useful finding, framework, or resource.

    Track more than the number of backlinks. Review which pages earned references, the relevance of the referring sites, referral visits, qualified conversions, and whether the asset prompted branded searches or further coverage. Those signals tell you what your market considers worth repeating.

    Make page meaning explicit with structured data

    An unlabeled web page separates into connected semantic objects that are recognized through a glowing AI lens.

    Once a page deserves to be found, reduce the effort required to interpret it. Structured data gives machines explicit labels for entities, attributes, and relationships that might otherwise be buried in layout and prose. That matters as search systems move from displaying links toward answering questions and completing tasks.

    Google and Bing can use structured data in search experiences, while AI systems can use explicit fields to evaluate relevance and actionability. Clean markup also makes a page less costly to interpret than relying entirely on unstructured HTML. This is why schema is becoming part of the infrastructure for agentic discovery.

    Treat schema as a site-wide knowledge graph, not a collection of isolated rich-result tricks. Use this implementation sequence:

    1. Inventory the entities. Identify the organizations, people, products, services, places, events, and resources that your pages describe.
    2. Establish canonical pages. Decide which URL is the primary description of each important entity or concept.
    3. Select appropriate schema types and properties. Mark up what the page actually contains, not what you wish it contained.
    4. Implement JSON-LD consistently. Use templates for repeatable page types while preserving page-specific facts.
    5. Connect relationships. Link an author to their profile, an offering to its provider, and related entities to their canonical identifiers.
    6. Validate against visible content. Every material claim in the markup should agree with what a visitor can read on the page.
    7. Monitor templates after changes. A CMS or design release can quietly remove fields, duplicate entities, or leave stale values across many URLs.

    Completeness matters more than decorative volume. Populate relevant properties with accurate values, but don’t add unsupported ratings, prices, authors, FAQs, or availability. Schema clarifies evidence; it doesn’t create evidence and can’t guarantee that an AI system will cite the page.

    Also check that the human-readable page provides the details an agent would need to act. If a service page never states eligibility, location, limitations, or the next step, structured data cannot repair the missing information. Improve the page first, then encode its meaning.

    Measure AI readiness as a learning system

    A single AI visibility score won’t tell you what to fix. Review performance by question, page, and business outcome. Run a repeatable set of representative prompts, record whether your brand appears, note which page or competitor is cited, and compare the response with your intended positioning. Because generated answers can vary, look for recurring patterns rather than treating one response as a verdict.

    Pair those observations with conventional evidence: crawl and indexation status, organic queries, referring domains, referral traffic, assisted conversions, and leads or sales. Diagnose the weakest link in the chain:

    • Not discovered: improve crawlability, internal linking, and distribution.
    • Discovered but misunderstood: clarify the answer, entities, terminology, and schema.
    • Understood but not selected: strengthen evidence, differentiation, references, and brand authority.
    • Selected but not converting: align the cited answer with a useful landing experience and next action.

    Record each meaningful change and its result in the changing layer of your knowledge base. That prevents the team from repeating failed ideas and gives future AI-assisted work the context needed to build on what you learned.

    Key takeaways

    • Map commercially useful questions to one clear, complete answer page.
    • Give people and AI tools a maintained record of brand rules, decisions, constraints, and outcomes.
    • Create resources with a specific reason for credible people to link to or cite them.
    • Use accurate JSON-LD to express entities and relationships already supported by visible content.
    • Measure discovery, interpretation, selection, and conversion separately so you know what to improve.

    Start with one high-value question this cycle. Improve its answer, document the relevant brand context, add defensible schema, and put the finished resource in front of people who genuinely need it. That small end-to-end test will teach you more than rolling out disconnected AI SEO tactics across the whole site.

    References

  • How to Make Your Content Visible in Agentic AI Search

    How to Make Your Content Visible in Agentic AI Search

    Your pages rank, your facts are accurate, and your technical SEO is sound. Yet ChatGPT Search or Google AI Mode still cites a competitor. The missing piece may be how well your content survives the steps between a user’s question and an AI-generated answer.

    AI search is no longer a simple contest to appear in one set of retrieved results. You need content that can support several related searches, answer at passage level, connect entities, and remain credible when a system checks its own work.

    AI search now investigates before it answers

    Classic retrieval-augmented generation, or RAG, followed a mostly linear path: interpret a query, retrieve relevant passages, and generate an answer. Visibility depended heavily on making the initial retrieval set.

    Agentic RAG adds a decision-making loop. A system can break the original request into smaller questions, choose different tools, retrieve more evidence, evaluate what it found, and repeat the process. Some workflows can involve up to twenty sub-retrievals before the answer is finalized.

    Four capabilities shape that process:

    • Planning: turning the user’s request into a sequence of sub-questions and deciding how to investigate them.
    • Tool use: selecting web search, APIs, code execution, databases, or other available methods for each step.
    • Iteration: retrieving additional material when the first pass leaves gaps or creates new questions.
    • Reflection: checking whether the collected evidence is sufficient, consistent, and diverse enough to support an answer.

    This changes the visibility problem. Your page might not answer the user’s original wording directly, but it can still become useful during a sub-query. The reverse is also true: ranking for the broad query won’t guarantee inclusion if your page can’t support the narrower checks that follow.

    Map the questions hidden inside the main query

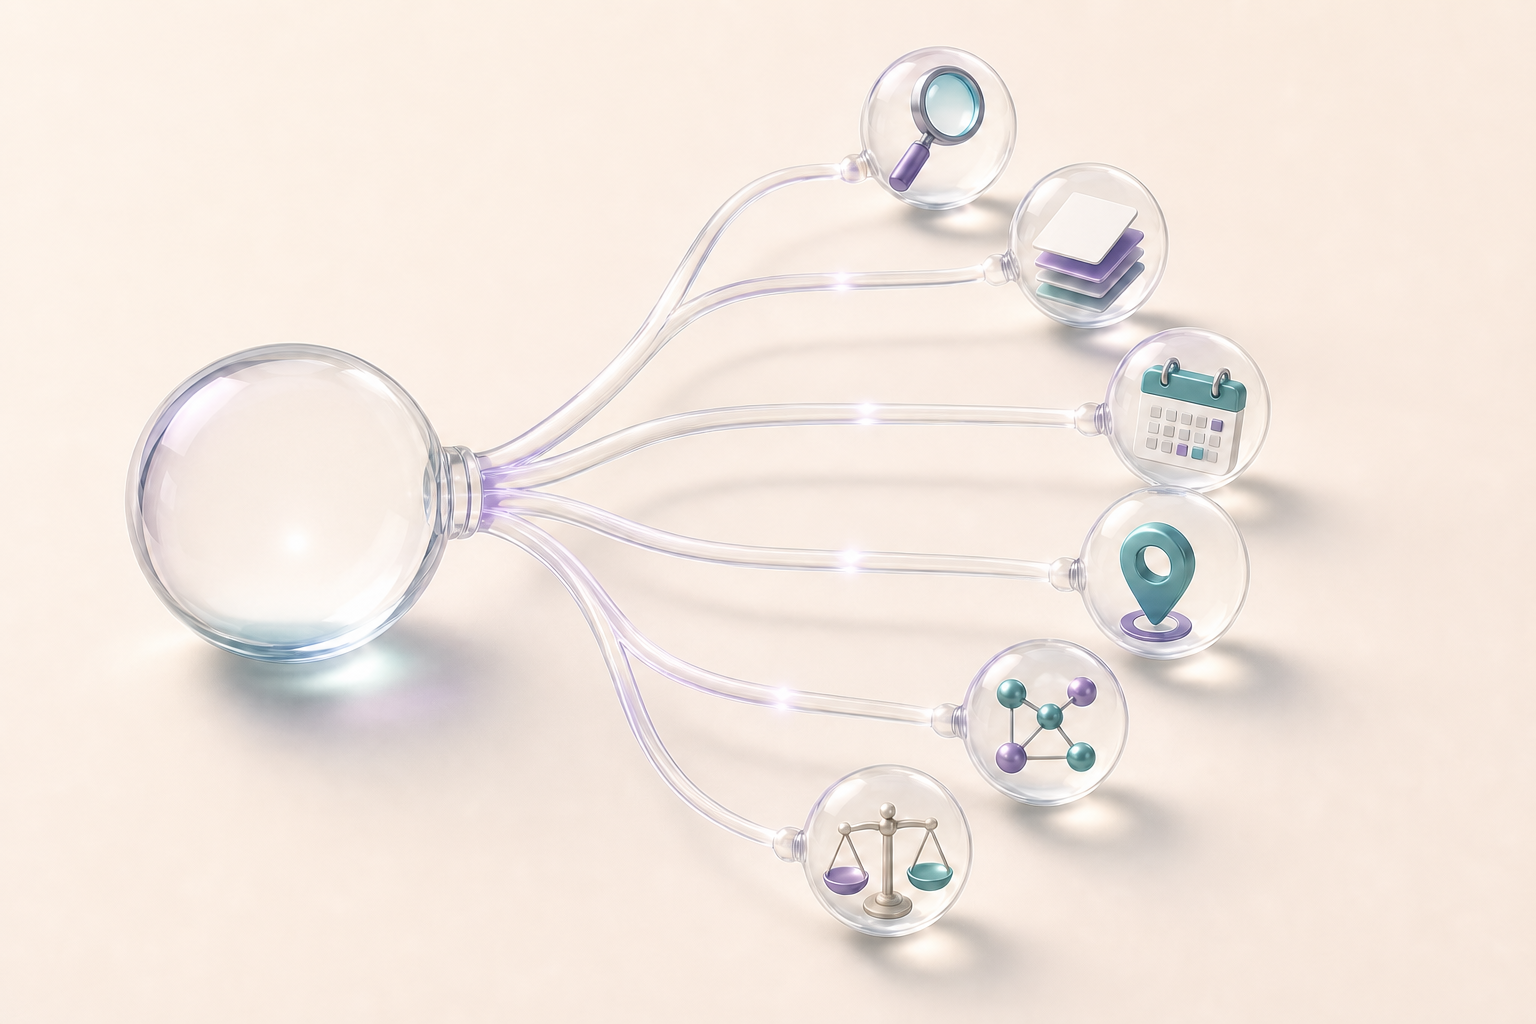
    A glass orb branches into connected smaller orbs containing symbols for research, documents, time, location, relationships, and comparison.

    Start with a real decision your audience needs to make. Then model the investigation an AI system may perform around it. A person asking how to choose an AI visibility platform may also need definitions, evaluation criteria, integration requirements, pricing logic, limitations, and measurement methods.

    Build a sub-query map before revising the page:

    1. Write the primary question in the reader’s own language.
    2. List the facts required to answer it without making assumptions.
    3. Add the likely comparison, verification, and follow-up questions.
    4. Mark which questions your page answers completely, partially, or not at all.
    5. Expand only where the added material serves the same reader and decision.

    Don’t turn one page into an encyclopedia. If a sub-question has a different intent, give it a dedicated page and link the two with descriptive anchor text. The goal is a connected body of coverage, not a single bloated URL.

    Pay particular attention to bridge entities: the products, standards, organizations, methods, and concepts that connect one part of the investigation to another. Name them precisely and explain the relationship. A sentence such as “Platform A exports citation records to BigQuery for longitudinal analysis” carries more usable connections than three separate paragraphs that mention the platform, export feature, and database without relating them.

    Engineer passages that can stand on their own

    Retrieval often operates on passages rather than entire pages. Each important section therefore needs enough context to remain useful when separated from the surrounding copy.

    Audit a passage with five questions:

    • Does the heading name the exact question or decision?
    • Does the opening sentence answer it directly?
    • Are important entities named instead of replaced with “it,” “they,” or “this tool”?
    • Are conditions, limitations, and exceptions close to the claim they qualify?
    • Could someone understand the passage without reading the introduction?

    A strong passage usually starts with the answer, then supplies the reasoning, evidence, and boundary conditions. That structure helps both hurried readers and retrieval systems. It also prevents a qualified claim from being extracted without the sentence that explains when it applies.

    Use lists for steps, tables for genuine comparisons, and descriptive headings for navigation. Add relevant structured data when it accurately represents visible page content, but don’t treat schema markup as a substitute for clear writing. Machines still need an accessible, coherent answer in the page itself.

    Make facts easy to verify and retrieve

    A hovering scanner examines one illuminated modular information block connected to organized evidence objects in the background.

    An agent may return to a page, compare it with other evidence, or use a tool to inspect supporting data. Reduce friction at each of those points.

    • Expose important information in HTML. Don’t hide the only useful answer inside an image, video, or interaction that requires several clicks.
    • Use stable names and units. Keep product names, feature labels, dates, and measurements consistent across copy, tables, metadata, feeds, and documentation.
    • Show how claims are supported. Link factual assertions to the most direct available evidence and keep qualifications beside the claim.
    • Offer structured access where it serves users. Accurate feeds, APIs, downloadable data, and well-formed markup can make changing information easier for tools to inspect.
    • Remove conflicting leftovers. Old pricing, renamed features, duplicate definitions, and stale comparison pages create ambiguity during verification.

    Freshness is not a decorative “updated” date. Review the claims that can change, correct the visible copy, update any structured representation, and record a meaningful revision date. If a page remains accurate, don’t rewrite it merely to make it look new.

    Measure coverage across the retrieval journey

    A single prompt check can’t tell you whether your strategy works. Agentic systems can take different routes through the same topic, and only the final answer is visible. You need a repeatable prompt set that represents the routes most likely to matter.

    Create a small measurement sheet with one row per prompt. Include the main question, comparison prompts, verification questions, follow-ups, and adjacent sub-queries from your map. For every check, record:

    • whether your brand or page appeared;
    • whether it received a citation or an unlinked mention;
    • which URL and passage were used;
    • what claim the answer attributed to you;
    • which competing pages appeared;
    • whether the answer was accurate, incomplete, or misleading.

    Run the same set after material content changes. Look for patterns rather than celebrating one citation. If you appear for definitions but disappear from comparison prompts, your weakness is probably decision support. If you appear for a broad prompt but not its verification questions, strengthen the evidence and qualifications around the relevant claims.

    Conventional analytics still matters, but referral traffic alone is incomplete. AI visibility can influence a decision without producing a click. Combine citation tracking with branded search, qualified conversions, sales conversations, and the accuracy of how your brand is represented.

    Key takeaways

    • Optimize for the sub-questions an AI system may investigate, not only the user’s opening query.
    • Give each important passage a clear heading, direct answer, named entities, and nearby qualifications.
    • Connect related concepts explicitly so your content can support multi-step retrieval.
    • Keep visible copy, structured data, feeds, and documentation consistent and current.
    • Measure citations and representation across a stable set of task-shaped prompts.

    Choose one commercially important topic this week. Map its hidden questions, repair the weakest passages, and establish a baseline prompt set before you publish changes. That gives you a practical starting point for improving visibility even when the retrieval path itself remains hidden.

    References

  • How Brand and Content Signals Earn Visibility in AI Search

    How Brand and Content Signals Earn Visibility in AI Search

    You can publish technically sound pages and still remain invisible in AI answers. The missing ingredient is often not another keyword variation. It is a clear brand identity, useful evidence, and enough credible connections for an AI system to understand when your brand belongs in the answer.

    Your job is to make that connection easy to retrieve and safe to repeat. That requires coordinated work across your website, structured data, customer-led content, and mentions on relevant third-party domains.

    Key takeaways

    • Define one consistent relationship between your brand, its category, its audience, and the problems it solves.
    • Turn real customer questions into complete answers, not thin FAQ fragments created to capture keywords.
    • Support important claims with original evidence, concrete examples, expert input, or clearly explained methods.
    • Build relevant third-party mentions that confirm what your own website says about the brand.
    • Measure brand demand, topical visibility, entity consistency, external mentions, and AI output instead of counting citations alone.

    Make your brand an entity AI systems can understand

    A central faceted object connects consistently to symbols representing a website, organization, products, audience, location, and people, while tangled duplicate shapes fade in the background.

    AI visibility starts with a basic question: what should your brand be known for? If your homepage describes a software platform, your social profiles call it a consultancy, and partner pages place it in a third category, the resulting identity is difficult to interpret.

    A strong brand signal has three qualities: salience, coherence, and relational density. Salience means the brand is associated with a topic even when a user does not search for its name. Coherence means descriptions and facts agree across locations. Relational density comes from credible connections to products, people, organizations, and subjects. These qualities can affect whether a brand is retrieved and confidently represented.

    Write a canonical identity statement before changing individual pages. Use this structure: [Brand] is a [category] for [audience] that helps with [problem] through [distinct method]. It is an internal reference, not necessarily homepage copy. Every public description should express the same essential relationships without repeating identical prose.

    Audit the homepage, About page, product or service pages, author biographies, social profiles, directory listings, partner biographies, and press boilerplate. Record the brand name, category, audience, core offer, location where relevant, and named experts shown in each place. Resolve contradictions before adding more content.

    Your structured data should confirm visible facts rather than introduce a second version of the business. Use the most specific applicable schema types and keep identity properties such as the organization name, URL, logo, and linked profiles aligned with the page. Connect articles to their real authors and products or services to the organization that provides them. Schema can clarify an entity, but it cannot create authority that the wider web does not support.

    Publish answers built from customer language

    Broad keyword lists rarely reveal the uncertainty behind a search. Customer questions do. More than 80% of AI Overview queries are informational, and most of those queries have search volumes below 1,000. That makes long-tail questions useful inputs even when conventional keyword tools show little demand.

    Begin with Google Search Console. Find queries that start with terms such as who, what, where, when, why, how, which, is, does, can, or should. Compare average position with click-through rate. A page receiving impressions for a relevant question but answering it only indirectly is a clear improvement opportunity.

    Then broaden the collection with People Also Ask results, support conversations, sales calls, on-site search terms, community discussions on Reddit, and available AI prompt data. Keep the wording customers use. It often exposes distinctions, objections, and comparison criteria that internal marketing language hides.

    1. Group questions by the decision or task behind them, not merely by shared words.
    2. Assign each group to the page best positioned to give a complete answer.
    3. Open with a direct response that makes sense without the surrounding page.
    4. Add the conditions, evidence, examples, limitations, and next action a reader needs.
    5. Link to supporting pages only when they resolve a related question or substantiate a claim.
    6. Review unanswered questions from search and customer conversations as an ongoing editorial input.

    A useful answer block is specific enough to stand alone but substantial enough to deserve retrieval. For example, do not answer “Does this platform support enterprise teams?” with “Yes.” Explain which team needs it supports, what the relevant workflow looks like, what constraints apply, and where the reader can verify the details.

    Do not manufacture dozens of near-duplicate FAQ entries. Generic copy creates little reason for a retrieval system to select your page over an established alternative. Original data, documented processes, expert explanations, worked examples, and candid limitations make an answer harder to replace.

    Earn corroboration beyond your own domain

    Light beams from separate publication, microphone, forum, review, research, and partner symbols converge around a central sphere beneath a retrieval lens.

    Your website can declare what the brand is. Independent domains help confirm it. One reported estimate places about 85% of brand mentions in AI systems on external domains. The practical lesson is not to chase mentions everywhere. It is to become present in the places that already carry meaning for your category.

    Build a relationship map around your priority topic. Include the publications, professional communities, subject experts, partners, integrations, comparison pages, directories, and customer organizations that a buyer would reasonably consult. For each relationship, identify why the connection is real and what useful asset could support it.

    A strong external mention might come from expert commentary, a partner integration page, a customer example, a useful community answer, an industry glossary, or a benchmark others can reference. The surrounding context matters. A relevant paragraph that accurately connects your brand to its field is more useful than an isolated name dropped into an unrelated page.

    Check how third parties describe you. Correct outdated names, categories, URLs, executive details, and product descriptions where you have a legitimate route to do so. Repeated inconsistencies weaken the same coherence you worked to establish on your own site.

    This is also why brand building remains valuable when search behavior fragments across engines, answer interfaces, and communities. A memorable name and trusted relationships can influence a decision even when the user never clicks your page. In that environment, brand memory travels farther than an individual ranking.

    Measure the signals that lead to AI visibility

    A citation is an observable result, not a diagnosis. It does not reveal whether your brand was retrieved because of its own content, an external mention, established familiarity, or a combination of signals. Citation counts alone can therefore send your team toward superficial tactics.

    SignalWhat to inspectWhat to do next
    Entity coherenceConflicting names, categories, descriptions, people, or URLsCorrect the highest-authority pages and profiles first
    Brand demandBranded queries and searches combining the brand with a topicStrengthen distribution around topics already gaining recognition
    Topical salienceNonbranded impressions for priority questions and categoriesImprove the canonical page and its supporting content
    Content coverageImportant customer questions with incomplete or scattered answersConsolidate each cluster into the most useful destination
    External corroborationRelevant mentions, their context, and factual consistencyDevelop credible relationships and correct material errors
    AI outputWhether the brand appears, how it is described, and which URLs are citedTrace gaps back to content, identity, or external evidence

    Maintain a stable set of representative prompts for your main audience problems. When you check them, record the exact prompt, platform, date, brand inclusion, description, cited URLs, and visible competitors. Use the record to notice patterns, not to claim universal performance from a single response. AI outputs can vary, so repeated observations are more useful than isolated wins.

    Start with the topic most important to your business. Align the brand identity, map the real questions around it, strengthen the canonical answer, and pursue corroboration from a credible external entity. That creates a repeatable operating system for visibility rather than a collection of disconnected AI search tactics.

    References

  • How to Build Source Authority for Visibility in AI Search

    How to Build Source Authority for Visibility in AI Search

    Your pages rank well, yet ChatGPT, Google AI Overviews, and other answer engines rarely mention your brand. That gap usually isn’t solved by publishing another broad guide. You need to give AI systems a clear reason to use your page as evidence.

    The practical goal is to become the best available source for a specific claim, decision, or task. That means creating information worth citing, making it easy to verify, and measuring visibility as a trend rather than chasing a single generated answer.

    Key takeaways

    • Source authority comes from useful evidence, identifiable expertise, and claims that readers and machines can verify.
    • Original data, focused analysis, and named tools give AI systems more reason to cite you than interchangeable educational copy.
    • Put a direct answer near the top, then support it with methodology, examples, limitations, and a sensible next step.
    • Keep visible content, structured data, product feeds, internal links, and campaign assets consistent.
    • Measure recurring query pathways quarterly. Organic rankings and AI visibility overlap, but they are not the same performance system.

    Give AI systems something they cannot produce alone

    An expert documents a hands-on experiment while an abstract AI form observes the resulting evidence.

    An AI assistant can already explain a common concept by combining information it has encountered elsewhere. Rewriting that explanation at greater length rarely makes your domain essential. Your advantage begins where generic synthesis ends.

    Create material that depends on your access, experience, or product. Useful options include proprietary measurements, a transparent test, a customer-data pattern, a calculator, a benchmark, a decision framework, or an expert interpretation of a changing market. The asset does not need to be large. It needs to contain a defensible contribution that another answer can attribute to you.

    This distinction showed up sharply in a dataset covering 10 websites and 150,000 indexed pages. Trends and analysis content appeared in the citation pool 78% of the time, while educational how-to content accounted for 12%. Pages with unique data held a substantial advantage. Because these figures come from one dataset, treat them as a prioritization signal rather than a universal benchmark. The useful lesson is that distinct information gives a model a reason to retrieve your page.

    Before approving a new page, ask a hard editorial question: what will exist after publication that did not exist before? If the answer is only another explanation of established knowledge, narrow the topic until you can add a result, example, comparison, tool, or judgment that belongs to your organization.

    Build pages that are easy to quote and verify

    A useful page can still be difficult for an answer engine to use. The main claim may be buried beneath scene-setting, mixed with unsupported marketing language, or separated from the evidence that qualifies it. Reduce that extraction work.

    Start with an answer capsule: a short paragraph that states the answer, names the important condition, and tells the reader what to do next. Follow it with the supporting detail. This is not a detached summary written for bots. It is the fastest route into the page for a person who arrived with a precise question, and prominent, concise answers have also been associated with stronger LLM visibility.

    Then make the claim auditable. Identify what was measured, where the information came from, what the result applies to, and where uncertainty remains. If you publish an original dataset, describe the sample and method. If you make a recommendation, connect it to the observation behind it. If a claim comes from elsewhere, link to the primary material instead of a page that merely repeats it.

    Match each page to one clear search need. A research page should make its finding unmistakable. A tool page should name the tool, explain its input and output, and let the visitor use it without hunting. A service page should answer the commercial questions that determine fit. In the same 10-site dataset, service and product pages generated 29.4 LLM sessions per 1,000 organic sessions, compared with 23.4 for articles and 14.0 for FAQ or support pages. Tools also produced the strongest average LLM engagement at 146 seconds, reinforcing the value of pages that help visitors complete a task rather than merely read about it.

    Make authority consistent across every machine-readable input

    A central source connects to coordinated webpage, profile, data, research, and reference panels.

    Authority weakens when your page title promises one thing, the copy says another, and the structured data introduces facts a visitor cannot see. Treat each technical input as a consistent description of the same real-world page.

    Use schema that accurately matches the visible content. Keep names, URLs, product details, authorship information, and other important identifiers consistent wherever they appear. Do not use markup to imply a fact the page does not support. Structured data can clarify meaning, but it cannot manufacture credibility.

    Internal links should also communicate purpose. Link to the original research behind a claim, the relevant tool that applies it, and the service or product that solves the next problem. This creates a coherent evidence path instead of a collection of isolated pages.

    Apply the same discipline to paid visibility

    If you advertise in AI-assisted search, the landing page is only one of the inputs. Shopping relies heavily on product-feed quality, while Performance Max and AI Max can use page content, feeds, audience information, search intent, and creative assets to determine relevance. Clear product titles, complete descriptions, strong images, varied assets, and aligned landing-page copy therefore affect more than conversion after the click. They help the system understand which queries your offer can appropriately answer.

    Review the resulting search terms, selected landing pages, exclusions, and assets regularly. Automation expands reach, but your evidence, audience signals, and negative keywords still define the boundaries within which it operates.

    Build audience preference as well as algorithmic relevance

    Source authority is not confined to on-page optimization. It also grows when people recognize your name, choose your work, and refer others back to it. Google has made that relationship more visible by labeling user-selected preferred sources in AI experiences. More than 345,000 unique sources had been selected, and selected sources received twice the click-through rate.

    Do not treat preferred-source selection as a shortcut or assume it is a general ranking factor. Treat it as evidence that recognition matters after visibility is earned. Give readers a reason to remember where an insight came from: use a stable name for recurring research, make useful tools easy to revisit, update important pages visibly, and maintain a clear point of view within your field.

    The expansion of highly cited labels creates another incentive to publish the material others reference, not merely commentary derived from it. If your team has the primary numbers, the original reporting, or the working tool, place that asset on a durable URL and make it the canonical destination for future mentions.

    Measure query pathways instead of chasing one AI answer

    An AI response is not a fixed search ranking. Recommendations can change with the user’s wording, context, prior interaction, model, and interface. You usually cannot inspect the full chain that led to a mention. That makes a single prompt check a weak performance metric.

    Build a funnel query pathway instead. Define recurring query groups around the problems your buyers bring to AI systems: early discovery, evaluation, comparison, and action. Recheck the same groups quarterly with a stable method. Record whether your brand appears, which URL is cited, what role it plays in the answer, which competitors appear, and whether referrals lead to meaningful actions.

    Look for movement across the pathway rather than demanding precise rank tracking. Maintaining the same macro measurement method over eight quarters can reveal recommendation trends that isolated screenshots cannot.

    Keep organic and AI reporting separate. The top 10 organic pages in the 10-site dataset attracted more than half of organic sessions but only 29% of LLM sessions, and nearly half of the top 100 organic pages received no LLM traffic. Strong SEO remains valuable for discovery and technical accessibility, but it does not prove that an AI system will choose the same pages as answer material.

    Referral analytics also show only part of the picture. LLM crawlers can request pages before client-side analytics loads, so GA4 does not record those bot visits. Use referral sessions to understand human behavior, server-level evidence to inspect crawler access where available, and recurring prompt checks to observe recommendations. No one stream is a complete visibility score.

    For your next publishing cycle, choose a commercially important question for which your organization has evidence others do not. Publish the direct answer, expose the method, connect it to a useful tool or decision, and add the query to your quarterly measurement set. That is a manageable first step toward becoming a source AI systems can use and people can trust.

    References