Tag: Campaign Performance

  • How to Run a Google Ads Target ROAS and CPA Health Check

    How to Run a Google Ads Target ROAS and CPA Health Check

    Your campaigns can meet their platform target while the business loses cash. They can also miss an ambitious target while profitable demand goes uncaptured. In both cases, the dashboard is measuring performance against a number that may never have been reconciled with margin, payback, or growth strategy.

    A proper health check turns target ROAS or CPA back into a business rule. You calculate the economic boundary, decide how much profit to reinvest, check whether the account can realistically deliver the result, and then determine whether the next block of advertising spend still earns enough.

    Start with the business decision behind the bid target

    Target ROAS and target CPA look like optimization settings because you enter them in an advertising platform. Their real function is to tell the bidding system what economic outcome you are willing to accept. That makes the target a business decision, not merely an account setting.

    The direction of the constraint matters. A higher target ROAS is stricter because it demands more conversion value from each advertising dollar. A lower target CPA is stricter because it allows less spend per conversion. Tightening either target can protect unit economics, but it can also reduce volume by making fewer auctions acceptable.

    Consider two otherwise similar advertisers. One requires 800% ROAS while the other accepts 400%. The first requires twice as much revenue per advertising dollar. The second can pursue demand that would be rejected under the 800% requirement. Neither strategy is automatically correct: one may prioritize retained margin, while the other may intentionally exchange some margin for market share. The health check establishes whether that choice was made deliberately and whether the business can fund it.

    Health-check questionEvidence you needDecision it supports
    Where is break-even?Effective margin, profit per customer, lead-to-sale rate, and payback windowThe ROAS floor or CPA ceiling below which acquisition loses money
    How much profit should acquisition consume?The share of profit the business is willing to reinvestThe operating target entered into the account
    Can the account deliver that target?Actual performance, spend, conversion volume, mix, and measurement qualityWhether the target is plausible under current conditions
    Should you spend more?Incremental value or conversions produced by incremental spendWhether the next block of spend meets the business threshold

    Keep those questions separate. Break-even is not your recommended operating target. Average account performance is not the return on additional spend. And a target that is economically sound is not necessarily attainable without changes to conversion rate, offer, traffic quality, or campaign structure.

    Calculate the economic boundary with honest inputs
    An isometric workbench divides revenue from one product into production, shipping, returns, fees, profit, and advertising reserves.

    The first calculation identifies where paid acquisition stops contributing profit under your chosen cost and payback assumptions. For ecommerce, that boundary is usually expressed as a minimum ROAS. For lead generation, it is usually a maximum CPA.

    Break-even ROAS for ecommerce

    Use this formula, with effective margin expressed as a decimal:

    Break-even ROAS = 1 / effective margin

    At a 40% effective margin, break-even ROAS is 2.5, normally displayed as 250%. Every $1 of advertising spend must therefore produce $2.50 of revenue merely to replace the profit consumed by that spend. This is a boundary, not a recommendation: at exactly break-even, the acquisition uses all the profit included in the calculation.

    The dangerous input is margin. Do not copy the headline gross-margin percentage from a management deck without checking what it excludes. Effective margin should reflect the costs required to fulfill the order, including subsidized shipping, payment fees, fulfillment, and returns where applicable. A retailer that begins with a 40% gross margin and faces a 25% return rate may end up with an effective margin in the low 30% range after the relevant deductions. At 30%, the break-even ROAS rises from 250% to about 333%.

    That difference explains why a campaign can look profitable in Google Ads while finance sees weak cash generation. The platform may be reporting gross conversion value, while the business earns profit on net, fulfilled, non-returned orders. Before changing the target, reconcile those definitions. If product groups have materially different effective margins, calculate their boundaries separately rather than letting a blended average hide which sales create profit.

    Break-even CPA for lead generation

    When the advertising conversion is a lead rather than a sale, use:

    Break-even CPA = profit per customer within the payback window x lead-to-sale conversion rate

    If a customer produces $1,000 in profit within the selected payback period and one in five advertising leads becomes a customer, the break-even lead CPA is $200. Paying more than $200 per lead loses money under those assumptions. Paying less leaves some profit after acquisition.

    The payback window must be selected before you calculate the CPA. Full lifetime profit creates a more generous ceiling, but it may take years to materialize. A business that needs its cash back within six or 12 months should use only the profit expected inside that window. Using lifetime value while managing against a shorter cash requirement produces a mathematically correct answer to the wrong business question. The formula is only as reliable as its profit window and conversion-rate inputs.

    Match the lead-to-sale rate to the conversion counted by the campaign. If Google Ads optimizes toward submitted forms, do not insert the close rate for sales-qualified opportunities unless every counted form is also a qualified opportunity. Reconcile the stages first, or calculate separate economics for each lead type.

    Turn break-even into an operating ROAS or CPA target

    Break-even tells you where profit disappears. Your operating target determines how much profit the business intends to keep. The missing input is the acquisition share: the percentage of available profit you are willing to spend to acquire the customer.

    For ecommerce:

    Operating target ROAS = 1 / (effective margin x acquisition share)

    For lead generation:

    Operating target CPA = profit per customer within the payback window x lead-to-sale conversion rate x acquisition share

    Express acquisition share as a decimal in both formulas. At a 100% acquisition share, the operating target equals break-even because all available profit is reinvested. A smaller share raises the required ROAS or lowers the allowable CPA, leaving more profit after acquisition. Spending beyond 100% means accepting a loss within the defined payback window, which requires an explicit, funded strategic decision rather than an unnoticed bidding change.

    This is where finance, marketing, and leadership must agree. The correct share depends on the job paid acquisition is expected to do. A business protecting cash may retain more profit. A business deliberately pursuing market share may reinvest more. The platform cannot resolve that trade-off because it does not own the profit-and-loss decision.

    1. Get the effective margin or payback-period profit approved by the person who owns the P&L.
    2. Confirm that the revenue, lead, and customer definitions match what the advertising account measures.
    3. Choose the acquisition share based on the current cash, profit, and growth objective.
    4. Calculate the operating target and document every assumption beside it.
    5. Record who approved the target and what event will trigger a recalculation.

    Recalculate when pricing, product mix, fulfillment costs, return rates, close rates, or the payback requirement changes. Even without an obvious trigger, the owner of the number and the advertising team should review the assumptions at least once a year. An inherited target without assumptions, an owner, and a review date is not a strategy.

    Pressure-test the target against account reality

    An economically defensible target can still be unrealistic for the account in its current state. Smart Bidding cannot manufacture conversion rate, demand, measurement quality, or order value. If the target demands performance far beyond what the account can currently produce, tightening it can suppress spend and conversions without fixing the underlying economics.

    Start the outside-in check with measurement. Confirm which actions are counted as primary conversions, whether revenue values reflect cancellations and returns, whether lead quality is available downstream, and whether conversion delay makes recent performance incomplete. A target calculation built on net economics cannot be evaluated against a platform report built on inflated gross outcomes.

    Next, create a representative baseline. Put the operating target, actual ROAS or CPA, break-even boundary, spend, conversion volume, and business-quality outcome in the same view. Segment where economics differ materially, but do not fragment the data merely to find a favorable result. You need enough evidence to distinguish a persistent constraint from ordinary variation.

    What you observeWhat it may meanWhat to check before changing the target
    The platform target is met, but cash contribution is weakThe account and finance are using different value, margin, return, or payback definitionsReconcile conversion value with fulfilled orders or downstream customer profit
    ROAS repeatedly misses the target, or CPA exceeds it, while spend and conversions contractThe target may be too restrictive for current account conditionsCheck tracking, conversion rate, traffic quality, campaign coverage, and whether the economic assumptions are still valid
    Actual performance comfortably beats the target while available budget goes unusedA stricter-than-needed target, limited demand, or another delivery constraint may be suppressing growthConfirm profitable demand exists, then test a controlled relaxation rather than changing the whole account
    Spend and conversions grow, but the business return deterioratesThe additional orders, products, or leads may have weaker economics than the existing averageCalculate marginal ROAS or CPA and inspect product or lead quality mix

    These patterns identify where to investigate; they do not prove a cause. Conversion rate, Quality Score, offer strength, competition, and demand can all change what the auction permits. The target is the main bidding lever you control, but it is not the only driver of the outcome. A landing-page problem does not become a bidding problem simply because the target is the easiest field to edit.

    When a target appears unrealistic, do not immediately loosen it across the account. First decide whether the business economics are wrong, the measurement is wrong, or the account needs operational improvement. If the economics are valid and the measurement is clean, a limited test can show how much volume becomes available at a less restrictive target and whether that volume remains profitable.

    Test whether the next advertising dollar still earns enough
    Equal stacks of advertising tokens produce progressively smaller returns across a row of vessels as a hand considers the next investment.

    Average ROAS and CPA describe all the spend already in the account. They do not tell you whether additional spend is attractive. Strong existing traffic can keep an average healthy even when the newest block of spend performs below the business threshold. That is why the final health check focuses on the marginal return.

    The last advertising dollar is not meant literally. In practice, you test a measurable increment of spend under comparable conditions. Use a controlled experiment or a carefully matched baseline and test period, and avoid changing prices, promotions, conversion definitions, landing pages, and bid targets at the same time. Otherwise, you will not know what produced the difference.

    For a ROAS campaign, calculate:

    Incremental spend = test spend – baseline spend

    Incremental conversion value = test conversion value – baseline conversion value

    Marginal ROAS = incremental conversion value / incremental spend

    For a CPA campaign, calculate:

    Incremental conversions = test conversions – baseline conversions

    Marginal CPA = incremental spend / incremental conversions

    If extra spend produces no additional conversions, marginal CPA is not meaningfully calculable as a favorable result. Treat that as a failed expansion test, then check whether conversion delay, tracking, or external demand distorted the observation before drawing a final conclusion.

    1. Select a campaign or segment with clean measurement and economics you can isolate.
    2. Record baseline spend, conversion value, conversion count, and downstream business quality.
    3. Define the target or budget change, the maximum financial exposure, and the rule for stopping the test.
    4. Change one material lever and allow the normal conversion delay and lead-quality feedback to arrive.
    5. Calculate incremental results rather than comparing only the two average ROAS or CPA figures.
    6. Apply the same margin, payback, and value definitions used to calculate the operating target.
    Marginal resultEconomic meaningPractical decision
    Marginal ROAS meets or exceeds the operating target, or marginal CPA meets or beats the operating targetThe additional spend satisfies the chosen profit-retention policyConsider another controlled expansion while monitoring mix and downstream quality
    The marginal result is profitable but misses the operating targetThe added spend remains above break-even but retains less profit than the agreed policy requiresScale only if leadership deliberately accepts the margin-for-growth trade-off
    Marginal ROAS falls below break-even, or marginal CPA exceeds break-evenThe added spend destroys contribution under the approved assumptionsRevert or stop the expansion unless the business has explicitly authorized and funded a loss-making strategy

    Run this check before declaring that a profitable average justifies more budget. The useful question is not whether the account has made money so far. It is whether the incremental advertising dollar still clears the required economic threshold.

    Key takeaways

    • Break-even ROAS is 1 divided by effective margin. Use margin after the costs required to fulfill the order, not an unadjusted headline percentage.
    • Break-even CPA is payback-period profit per customer multiplied by the lead-to-sale conversion rate. The lead definition and payback window must match the business reality.
    • Your operating target should preserve the agreed share of profit. For ROAS, divide 1 by effective margin multiplied by acquisition share. For CPA, multiply break-even CPA by acquisition share.
    • A higher target ROAS and a lower target CPA are more restrictive. Either can protect profit or suppress viable volume, depending on whether the target is economically justified.
    • Average performance cannot answer whether you should spend more. Use marginal ROAS or CPA to evaluate the additional spend separately.

    Before the next bid-strategy change, put the margin, payback, close-rate, acquisition-share, measurement, and marginal-return assumptions in one worksheet. Get the definitions approved by the P&L owner, then test any expansion in a limited scope with a clear loss boundary. That turns the target from an inherited number into a decision you can defend and revise.
    References

  • How to Measure and Test Google Ads Without False Winners

    How to Measure and Test Google Ads Without False Winners

    Your Google Ads experiment produced a lift, but you still can’t answer the question that matters: should you change the account? That usually happens when the platform reports movement without proving what caused it, whether it will persist, or whether the measured conversion was valuable in the first place.

    You need a measurement system that can survive automated bidding, responsive creative, uneven audience delivery, and pressure to declare a winner. The framework below helps you define the decision before launch, protect the test from weak tracking, interpret conditional results, and report what the evidence actually supports.

    Key takeaways for reliable Google Ads experiments

    • Define the business decision before the metric. A test should tell you whether to adopt, reject, extend, or refine a specific change. It should not merely produce a dashboard comparison.
    • Separate primary outcomes from diagnostic actions. Purchases, qualified leads, calls, chats, and video engagement do not carry the same business value and should not be flattened into one conversion total.
    • Test strategic inputs while holding the operating environment as stable as practical. Creative propositions, landing pages, offers, and first-party signals are useful inputs to test. Simultaneous budget, bidding, tracking, and promotion changes make the result difficult to interpret.
    • Expect performance to vary by context. A creative asset can be valuable for one audience or situation without becoming the account-wide winner. Evaluate the role it plays before removing it.
    • Report counts, percentages, quality, and value together. No single metric explains performance. A transparent report shows what happened, what composed the result, what remains uncertain, and what decision follows.

    Define conversion truth before you design the test

    Glowing signal particles pass through transparent filters that remove duplicates and low-quality events before verified tokens reach a value balance.

    A conversion is whatever the account configuration counts as a conversion. It is not automatically a customer, revenue event, or profitable outcome. A form submission, marketing-qualified lead, and closed sale represent different stages of the business, even when all three appear under a conversion heading.

    Start with a measurement contract. This is a short written agreement between the people running the campaign and the people using its results. Complete it before anyone builds an experiment:

    1. Name the decision. State exactly what you will change if the evidence is favorable. Examples include replacing a landing page, introducing a new value proposition, expanding an audience signal, or changing the allocation between campaign types.
    2. Select one primary business outcome. Use the deepest dependable event available at sufficient volume, such as a purchase, qualified lead, or imported sale. If the final sale arrives later, record the delay rather than quietly substituting a faster but weaker action.
    3. Classify secondary actions. Calls, chats, form starts, page engagement, and video views can help diagnose behavior. Mark them as secondary unless the business has explicitly established their value.
    4. Define the population. Record the campaigns, locations, devices, customer types, products, and dates included. Decide how you will handle existing customers, branded demand, and other traffic that could answer a different question.
    5. Set guardrails. Identify outcomes that must not deteriorate even if the primary metric improves. Lead quality, total acquisition volume, cost, order value, and downstream revenue are common guardrails when they are available.
    6. Write the decision rules. Specify what would justify adoption, extension, iteration, or rejection. Do not invent the rule after seeing which interpretation makes the test look best.

    Audit the composition of the conversion column

    Open the conversion-action breakdown rather than trusting the headline total. For every action, record its name, trigger, inclusion status, assigned value, source, and relationship to revenue. If a video-engagement event and a purchase are both included, the aggregate conversion count cannot serve as an unqualified business result.

    This audit also protects automated bidding. When weak actions sit beside valuable ones without an appropriate distinction, the bidding system can pursue the easier event while the report celebrates a rising total. The number may be technically accurate and strategically misleading at the same time.

    Automation can build tags, but it cannot validate meaning

    If Google Tag Manager displays the Google Ads Purchase Conversions Guided Setup card, the beta can create the required tags, triggers, and variables automatically. Availability is not universal, and generated configuration should still go through the same quality checks as a manual implementation.

    Complete a real test transaction before launching the experiment. Confirm that the expected action fires once, reaches the intended Google Ads conversion action, and carries the correct value and currency when those fields are part of your setup. Check any order identifier or deduplication mechanism your implementation uses. Then compare the platform record with the commerce or lead system that represents business truth.

    Do not launch new tracking and a strategic campaign test at the same time. If the numbers move, you will not know whether user behavior changed or measurement changed. Stabilize and verify the instrumentation first; start the experiment afterward.

    Design the experiment for an automated auction

    A randomized split feeds two protected experiment lanes with matching bidding machines while uneven audience signals flow through an automated auction environment.

    Modern Google Ads delivery is already adaptive. Bidding changes auction participation, responsive formats assemble different assets, and audience signals influence where the system searches for demand. Your experiment therefore sits inside another optimization system. A clean plan isolates the strategic input you control without pretending that every impression is otherwise identical.

    Write a hypothesis with a mechanism

    Use this structure: For a defined audience and context, changing a specific input should improve the primary business outcome because of a stated mechanism, without breaching named guardrails.

    The mechanism matters. Improving a headline because it makes the offer clearer is a hypothesis. Improving performance because the new headline is better is circular. A mechanism tells you what to inspect when the aggregate result is mixed and what to carry into the next creative iteration.

    Choose one strategic variable at the experiment-arm level whenever practical. If you test a new offer, new landing page, new audience signal, and new bidding target together, you may learn whether the package performed differently, but you will not know which input deserved the credit. A package test can still be valid when the decision is whether to adopt the entire package; label it that way from the start.

    Screen creative before spending money on it

    Letting the platform rotate every submitted idea is not a substitute for creative judgment. Use the MOCA framework as a preflight check:

    • Magnetic: Does the message attract the intended buyer while helping an unsuitable visitor decide not to click? Good qualification can reduce wasted traffic even when it does not maximize click-through rate.
    • Obvious: Can someone identify the offer, category, and payoff without decoding the ad? Every text, image, and video asset should reinforce the same central idea.
    • Congruent: Does the promise fit the user’s likely intent, and does the landing page fulfill that promise? Message match is necessary, but the offer must also make sense for the stage of demand.
    • Actionable: Is the next step clear, specific, and appropriate to the commitment being requested?

    Reject assets that fail this screen before the test. The purpose is not to predetermine the winning execution. It is to ensure the experiment compares ideas that are coherent enough to deserve budget.

    Build useful variety, not cosmetic variation

    Responsive creative needs assets with distinct jobs. One message might qualify a price-conscious buyer, another might emphasize speed, and another might address risk or governance. That variety gives the system options for different users. Rewriting the same claim with minor punctuation or capitalization changes produces little strategic information.

    This is the practical meaning of testing for asset liquidity rather than one universal champion. A headline with weaker aggregate reporting may still be the strongest match for a smaller, valuable audience. Before pausing it, ask whether it supplies a proposition that no remaining asset covers.

    Set stopping rules that do not reward volatility

    There is no defensible universal test duration. Conversion volume, sales delay, demand patterns, budget, and delivery behavior differ too much. A single week is especially weak evidence when automated bidding is still finding where to allocate spend and a short-lived auction opportunity can dominate the result.

    Before launch, schedule review points and define what must be true before a decision is allowed:

    • Tracking has remained stable and reconciliation checks have passed.
    • The test has covered the demand patterns relevant to the business rather than one unusual day or promotion.
    • The primary outcome has accumulated enough evidence for the size and consequence of the decision. If it has not, report the result as inconclusive instead of promoting a secondary metric.
    • Recent conversions have had enough time to mature through the normal reporting or sales delay.
    • No material budget, bid, targeting, site, inventory, pricing, or promotional change has compromised the comparison.
    • The result persists beyond an isolated performance spike.

    Maintain a change log while the experiment runs. Record the date, affected arm, change, reason, and likely direction of impact. This gives you a defensible explanation when a stakeholder asks why the test was extended or why a period was treated cautiously.

    Interpret and report results without manufacturing certainty

    Read the result in three passes: validity, business outcome, and context. Reversing that order encourages a common mistake: finding an attractive number first and looking for a story that supports it.

    Pass one: decide whether the comparison is trustworthy

    Check tracking health, conversion delay, exposure, budget constraints, and the change log. Look for promotions, outages, inventory shifts, or other conditions that affected only part of the test. If validity is compromised, do not rescue the result with a longer explanation. Mark the experiment inconclusive and state what must change before it can answer the question.

    Pass two: evaluate the business outcome before diagnostics

    Lead with the primary outcome named in the measurement contract. Show its raw count, rate, cost, and value where available. Then show downstream quality and the guardrails. CTR, CPC, impression volume, and engagement can help explain movement, but they do not replace the outcome the business funded.

    A universal CTR benchmark does not establish account health in an environment where algorithms can find audiences that are easier to click. A higher CPC is not automatically deterioration either; more expensive traffic can produce a lower acquisition cost when it carries stronger intent. Judge diagnostic metrics by their relationship to the agreed business result.

    Pass three: inspect context without rewriting the hypothesis

    Break the result down by audience, device, timing, query or theme, and creative proposition when the available reporting supports it. Treat those intersections as explanations and future hypotheses, not automatic proof that a small subgroup should become the new account strategy.

    A sudden device or weekday gain may mean the bidding system found a temporary pocket of efficient inventory, not that user preferences permanently changed. Competitor absence, auction prices, and budget allocation can all affect where delivery lands. Performance volatility should not be mistaken for a durable testing conclusion.

    Unexpected audience segments are useful for discovery. If a segment over-indexes, translate the observation into a customer hypothesis, develop creative that speaks to the implied need, and test it deliberately. Do not immediately narrow targeting around a segment that the system may have reached under a specific, temporary set of auction conditions.

    Use decision language that matches the evidence

    • Adopt: The primary outcome supports the change, tracking is valid, and guardrails remain acceptable.
    • Reject: The change harms the business outcome or violates a guardrail without a credible compensating benefit.
    • Iterate: The aggregate result is insufficient, but a clear mechanism or contextual signal justifies a narrower follow-up test.
    • Extend: The setup remains valid, but conversion maturity or evidence volume is not yet adequate for the planned decision.
    • Inconclusive: The experiment cannot answer the original question because of weak evidence, contamination, or measurement failure.

    Inconclusive is an honest result, not a failed presentation. It prevents a weak test from turning into an expensive account-wide change.

    Give stakeholders the whole denominator

    Show raw numbers and percentages together. Counts explain scale; percentages explain composition; rates explain efficiency; value and downstream quality explain business consequence. Choosing only the representation that looks favorable changes the story, even when every displayed number is technically correct.

    A useful test report can fit into seven blocks:

    1. Decision: Adopt, reject, iterate, extend, or mark inconclusive.
    2. Question: The original hypothesis and business action under consideration.
    3. Validity: Tracking status, material account changes, conversion maturity, and known limitations.
    4. Primary result: Raw outcomes, rate, cost, and value for each arm.
    5. Composition and quality: Conversion types, their shares, and downstream qualification or sales data.
    6. Context: Audience, device, timing, and creative patterns that may explain the aggregate result.
    7. Next action: The owner, exact change, and next measurement point.

    Keep observations separate from interpretations. Then label interpretations by confidence. That small discipline makes it much harder for a temporary spike, flattering denominator, or secondary conversion to masquerade as a business win.

    Match the measurement method and budget to the decision

    Not every question belongs in the same experiment. Choose the method based on the decision and the outcome you can credibly observe.

    Decision questionUseful approachDo not call this success
    Did a change improve purchase or lead economics?Use the deepest reliable conversion outcome, reconcile it with business records, and evaluate cost, value, and quality.More interactions or a larger blended conversion total when sales quality did not improve.
    Which creative direction deserves more investment?Pre-screen assets with MOCA, test distinct propositions, and inspect conditional audience and placement patterns.A global asset label or click-through rate viewed without business outcomes and context.
    Did broad delivery reveal a new audience opportunity?Treat the segment as discovery, write a customer-need hypothesis, and run a focused follow-up with relevant creative.A temporary over-index as permanent proof that the segment should be isolated or scaled.
    Did an upper-funnel campaign change brand perception?Use a Brand Lift option when the campaign has sufficient scale and the detectable difference would change a real budget decision.Clicks or attributed conversions as a complete measure of awareness or consideration.

    Pay for greater Brand Lift sensitivity only when it matters

    Google Ads offers Standard and Enhanced Brand Lift options. Google’s reported product specifications position Standard Brand Lift to measure lifts of 2% or more, while Enhanced Brand Lift can detect lifts as low as 1.2%. The enhanced option requires approximately three times the budget, and Google estimates that it raises the likelihood of detecting a positive lift by 60%.

    Those figures describe vendor-reported study sensitivity and budget requirements, not a guarantee that your campaign will create lift. The practical question is whether distinguishing a modest effect from no detectable effect would change your decision. If a result between 1.2% and 2% would not affect investment, the additional sensitivity may not justify roughly tripling the required budget. If that distinction would determine a substantial upper-funnel allocation, the enhanced option can be relevant when the campaign has enough scale.

    For your next experiment, write the measurement contract and the empty seven-block report before building the campaign. Validate one complete conversion path, record the stopping rules, and reject creative that fails the preflight screen. Once the test begins, your job is to protect that decision structure from mid-test improvisation. The result may be adopt, iterate, or inconclusive; any of those is useful when it is tied to a clear next action.

    References

  • How Expanded PMax Reporting Changes Performance Analysis

    How Expanded PMax Reporting Changes Performance Analysis

    Google’s product-level reporting now captures a wider share of the activity associated with Performance Max and several other campaign types. That added visibility can help advertisers understand product results across more of Google’s inventory, but it also creates an abrupt break in reporting continuity.

    The practical challenge is interpretation: a chart may rise because more activity is being counted, not because ads suddenly became more effective. Advertisers therefore need to distinguish a measurement expansion from a true performance change.

    What changed in product-level reporting

    Search Engine Land reports that, as of June 15, Google expanded Performance Max product reporting beyond Search network activity. Previously, reported metrics such as cost and conversions covered products served through Search networks and Standard Shopping campaigns.

    The expanded scope includes product performance data from the following eligible campaign inventory:

    • All Performance Max networks
    • Video campaigns
    • App campaigns
    • Demand Gen campaigns where product data is available through Google Merchant Center

    This is primarily a reporting change. It gives advertisers a broader view of where product interactions occur, but the source does not indicate that the campaigns themselves were altered by the update.

    Why performance charts may show a sudden jump

    When a report begins counting activity from additional networks, its totals can increase even when underlying campaign behavior remains stable. Search Engine Land says advertisers may see higher impressions, clicks and other metrics as a one-time consequence of the wider reporting scope.

    That distinction matters because a larger reported total is not automatically evidence of improved targeting, stronger creative or better bidding. Performance should be judged only after determining whether the apparent change came from campaign results, measurement coverage or a combination of both.

    Futuristic web browser and analytics dashboard overlap amid neon data streams, illustrating the convergence of SEO, PPC and AI-driven search marketing.
    Organic visibility, paid media and artificial intelligence merge into one connected search ecosystem, where vivid data streams link a creative website with a powerful analytics dashboard.

    Key takeaways for advertisers

    • Product reports now include more eligible Google Ads inventory than they did before the June 15 change.
    • Sudden increases in reported activity may reflect newly included networks rather than genuine growth.
    • Results from before and after the reporting expansion are not directly comparable without qualification.
    • Network-level filtering and clear report annotations can reduce the risk of misreading the change.

    How to handle historical comparisons

    The reporting boundary creates a discontinuity in time-series analysis. A month-over-month comparison that crosses June 15 may combine two different measurement scopes, so the percentage change alone cannot explain what happened.

    Advertisers can make those reports more useful by marking the date of the methodology change and explaining it in client or stakeholder summaries. Where possible, periods measured under the same scope should be compared with one another. If a report must cross the boundary, any observed lift should be presented as potentially influenced by expanded coverage.

    This caveat also applies to internal benchmarks, forecasts and automated dashboards that rely on historical trends. The underlying data may still be valuable, but the change in scope needs to remain visible to anyone using it for decisions.

    A practical review workflow for affected accounts

    A disciplined review can prevent a measurement change from being mistaken for a campaign win or loss:

    1. Identify reports and dashboards that use Performance Max product-level data.
    2. Check whether the analysis period spans the June 15 reporting change.
    3. Use the Network (with search partners) filter to examine where the newly reported activity originated.
    4. Review impressions, clicks, cost and conversions in context instead of treating any single increase as proof of improvement.
    5. Add a concise methodology note to recurring reports and explain the change to stakeholders.

    Google Ads specialist Bia Camargo highlighted the notice, according to the source, and cautioned that clients should be prepared for apparent gains caused by expanded measurement. That communication step is important because broader reporting is useful only when decision-makers understand what changed.

    As future reporting periods accumulate under the new scope, comparisons should become easier. Until then, advertisers should treat June 15 as a measurement boundary and require network-level evidence before crediting a spike to campaign optimization.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Performance Max Placement Controls Enter an Early Alpha

    Performance Max Placement Controls Enter an Early Alpha

    A limited Performance Max alpha could give selected advertisers a consequential new choice: whether a campaign includes Search Partners and the Google Display Network. The reported setting does not dismantle campaign automation, but it may let advertisers define two important boundaries around the inventory that automation can use.

    The distinction matters for both expectations and testing. This is a reported network-level control, not evidence of comprehensive placement management, and its value will depend on whether advertisers can measure the effects of each configuration reliably.

    Key takeaways

    • CrushPress.AI reported that a Partners (Alpha) setting is appearing in some Performance Max campaigns.
    • The reported interface provides separate inclusion choices for Search Partners and the Google Display Network.
    • Because the setting is labelled Alpha and has limited availability, it should be treated as an experiment rather than an established campaign feature.
    • The most useful evaluation is a controlled comparison based on business outcomes such as cost per acquisition or return on ad spend.
    • The reported controls apply to networks; they should not be interpreted as proof of granular control over individual websites, apps, searches or placements.

    The alpha changes the boundary of automation

    According to CrushPress.AI’s report, advertisers with access can use checkboxes to include or exclude Search Partners and the Google Display Network. The publication said both networks had previously been included automatically in Performance Max without a corresponding exclusion option.

    That makes the test notable without making Performance Max a manually managed campaign type. Google would still automate decisions within the inventory available to the campaign; the advertiser would gain a higher-level choice about whether two sources of inventory are available at all. In practical terms, the control changes the perimeter in which the system operates rather than replacing automated delivery.

    The terminology also deserves care. Although network selection affects where ads may appear, the reported setting is broader than a conventional placement exclusion. It does not, based on the available report, establish controls for selecting particular sites, apps, pages or search contexts.

    Why network choice could improve campaign diagnosis

    An analyst compares two separated streams of generic advertising inventory connected to one automated campaign engine.

    When several inventory sources contribute to one automated campaign, an aggregate result can show whether the campaign succeeded without fully explaining which environments helped or hurt. An option to remove Search Partners or the Google Display Network creates a clearer diagnostic question: does the campaign produce stronger business results when either network is unavailable?

    That question should be framed around the campaign’s actual objective. CrushPress.AI identified return on ad spend and cost per acquisition as relevant measures for evaluating the setting. Advertisers may also need to examine whether changes in those outcomes accompany changes in conversion volume, reach or delivery stability. A lower cost per acquisition is less useful if the configuration can no longer produce the required volume, while additional reach is not automatically valuable if it fails to support the campaign goal.

    The setting may also help separate an inventory concern from a broader campaign problem. If excluding a network does not materially improve the chosen outcome, attention may be better directed toward inputs such as creative, offers, audience signals, conversion measurement or landing-page experience. If performance changes consistently, the result supplies a more focused basis for deciding which inventory belongs in the campaign.

    A useful test requires more than toggling a checkbox

    Two matched campaign pathways use different switch settings in a controlled side-by-side testing setup.

    A credible comparison begins with a decision rule established before the configuration changes. The advertiser should specify the primary business metric, the acceptable trade-off between efficiency and volume, and the conditions that would justify retaining or reversing the exclusion. This reduces the risk of choosing whichever metric looks most favorable afterward.

    The comparison should also avoid unnecessary simultaneous changes. Major adjustments to budgets, conversion definitions, creative assets or landing pages can make it difficult to attribute a result to network selection. Normal volatility and automated learning further argue against drawing a conclusion from a brief movement in performance.

    Interpretation should account for interaction effects. Excluding inventory can change the opportunities available to the campaign, which may alter how automation distributes delivery elsewhere. The meaningful comparison is therefore the campaign’s total outcome under each configuration, not an assumption that removed activity would have transferred unchanged to another network.

    What remains unresolved while access is limited

    The available evidence is preliminary. CrushPress.AI described the control as an Alpha available to a limited group and reported that Google had not announced whether or when it would become more broadly available. The report attributed the discovery to PPC Growth Strategist Saquib Syed, who shared the setting on LinkedIn.

    The report does not establish how eligibility is determined, whether the interface will remain unchanged, or whether Google will add related reporting and controls. Those omissions are especially important because a network toggle is most actionable when advertisers can clearly evaluate the inventory affected by it.

    The next meaningful signal will be broader availability accompanied by documented behavior and sufficient reporting to support sound comparisons. Until then, advertisers with access can treat the alpha as a structured learning opportunity, while those without it should avoid planning around a control that has not been confirmed as a general release.

    References

  • How Paid Social Shapes Search ROAS and Budget Decisions

    How Paid Social Shapes Search ROAS and Budget Decisions

    Search can appear to be the most efficient paid channel while benefiting from demand that paid social created earlier. That makes channel-level return on ad spend useful for optimization but potentially misleading for budget allocation.

    The practical question is not whether social deserves credit for every later search conversion. It is whether reducing social changes the volume, readiness, or acquisition cost of people arriving through search. Answering that question requires treating search and social as connected parts of the customer journey.

    Key takeaways

    • Paid social can influence search without generating a measurable click, particularly when exposure leads to a later branded query.
    • Search ROAS may reflect both search execution and the strength of upstream demand generation.
    • Brand-query impressions, non-brand conversion rates, and search auction metrics can provide early evidence of a cross-channel effect.
    • A social budget cut may not damage search immediately because previously exposed audiences can continue searching for several weeks.
    • Budget decisions should combine channel reports with lagged analysis and controlled tests wherever practical.

    The mechanism extends beyond attribution credit

    ROAS compares attributed revenue with advertising spend. It does not, by itself, reveal which activity originated the demand. Search is often positioned near the end of a journey because a query expresses an existing need or interest. Paid social can operate earlier, introducing a brand or product before the person is ready to act.

    The supplied source article describes three ways this relationship may appear. First, its author reports frequently seeing weekly Meta or TikTok spend move with branded-query impressions in Google Ads. The proposed explanation is that some people notice a social ad, do not click, and later search for the advertiser by name.

    Second, the article reports stronger conversion rates on generic search queries when audiences may already know the brand. The query, auction, and landing page can remain unchanged while prior exposure alters the searcher’s willingness to convert. In that situation, search captures the transaction, but its conversion rate partly reflects work performed upstream.

    Third, the article proposes an auction effect: greater familiarity may improve click-through rates on brand-adjacent searches, which can affect expected click-through rate and potentially influence cost per click. This is a more indirect hypothesis than the branded-search relationship, so it should be tested rather than assumed.

    Together, these mechanisms separate two questions that channel dashboards often merge: which ad received conversion credit, and which advertising changed the probability that the conversion would happen. The second question is the more important one for incremental budget decisions.

    Why channel reports can overstate search’s independence

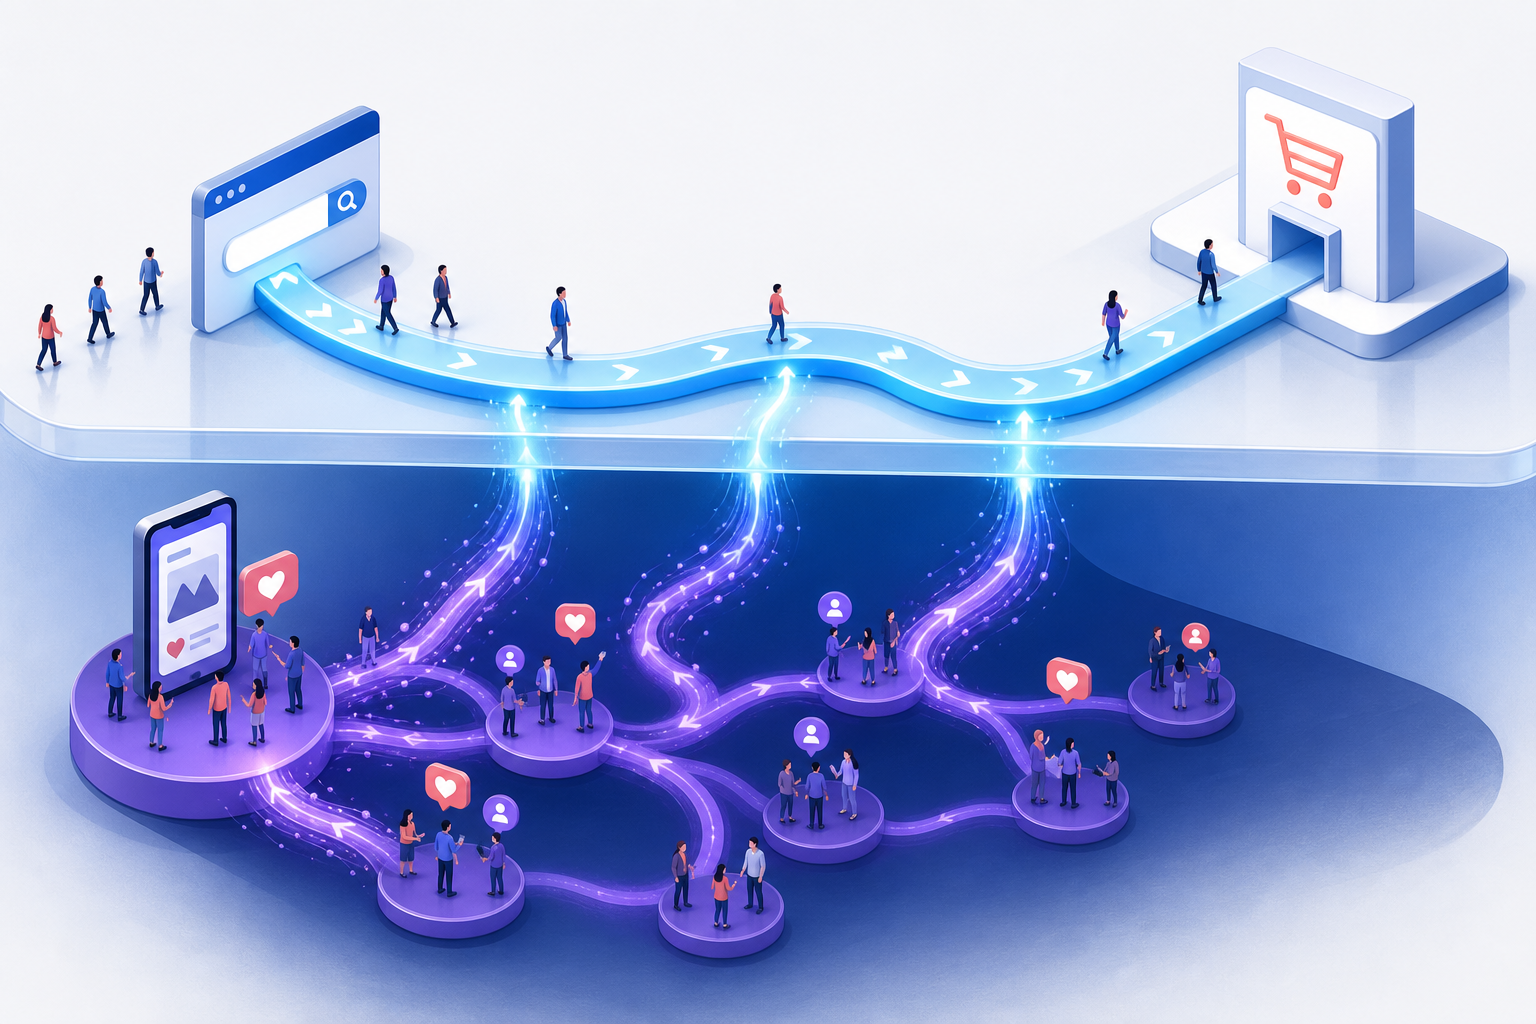
    Cutaway illustration showing an apparent search path to purchase supported by a hidden stream of people arriving from social discovery.

    Last-click reporting naturally favors the touchpoint nearest the transaction. Even data-driven attribution remains constrained by the interactions a measurement system can observe. A social impression followed by no click may leave little or no usable path data when the same person searches later.

    Social platforms may report view-through conversions, but the source notes that teams often distrust figures calculated by the platform selling the ads. Discarding view-through credit entirely avoids accepting an inflated platform claim, yet it creates the opposite risk: treating an unobserved influence as no influence at all.

    This produces an uneven comparison. Search is judged largely on its ability to capture expressed intent, while social is judged on whether its exposure generated an observable conversion path. A search campaign showing a higher reported ROAS can therefore be the better conversion-capture channel without necessarily being the best destination for the next unit of budget.

    The source is best read as a practitioner account rather than controlled proof. Its author identifies as a paid search specialist and bases the argument on patterns observed across accounts. Those observations offer a credible hypothesis and useful diagnostic signals, but correlation between social spend and search results can also be affected by promotions, seasonality, total media investment, or changing demand. Attribution reports should not settle the question, but neither should a simple correlation chart.

    Delayed search decay can hide a poor reallocation

    Illustration of a flywheel continuing to turn after its input is reduced while the downstream flow of customers gradually thins.

    The timing of the effect complicates budget evaluation. According to the source, search performance can remain stable for four to eight weeks after social spending is reduced because people reached by earlier campaigns may continue to search. The apparent success of moving money into search can therefore precede a decline in the audience that social had been preparing.

    The article recounts cases in which teams cut social spending by 40% and later saw search cost per acquisition rise by 25%, despite no meaningful changes inside the search account. These figures are reported examples, not a universal forecast. Their value is in illustrating why the date of a budget change should remain visible when later search deterioration is investigated.

    A useful diagnosis connects several signals over time. Weekly social spend can be compared with branded-query impressions using multiple lag periods. Non-brand conversion rate can show whether generic searchers are becoming less likely to buy. Click-through rate and cost per click on relevant terms can indicate whether auction behavior is also changing. Promotions, pricing changes, search impression share, competitive pressure, and seasonality should be examined alongside those trends so that an upstream-media explanation does not become the default answer to every decline.

    The sequence matters more than any isolated metric. A social reduction followed by softer branded demand and weaker non-brand conversion provides a more coherent signal than a simultaneous movement in two weekly charts. Even then, the pattern supports a hypothesis; it does not prove causation.

    Measure the halo before changing the channel mix

    The strongest evaluation asks what happens to total acquisition when upstream exposure changes. Where scale and operations permit, a holdout or geographic test can compare markets or audiences with different levels of paid social support while search activity remains as consistent as possible. The evaluation window must be long enough to capture the lag suggested by normal buying behavior rather than only immediate social conversions.

    When a controlled test is not feasible, teams can still improve the decision. They can mark budget changes, examine lagged relationships, separate branded and non-branded search, and compare channel results with blended revenue or acquisition outcomes. The aim is not to assign a perfect fractional credit to every impression. It is to estimate whether social spending causes enough additional business, including downstream search performance, to justify its marginal cost.

    The underlying principle is channel-agnostic. The source argues that YouTube and Demand Gen can generate upstream exposure within Google’s ecosystem, while Microsoft Audience Ads can play a similar role across Microsoft properties. Keeping discovery and search activity on one platform does not eliminate the measurement problem: an earlier visual exposure can still assist a later search conversion without receiving proportionate credit.

    Budget governance should therefore distinguish reported channel ROAS from incremental portfolio value. Search teams can optimize queries, ads, bids, and landing pages while also monitoring the demand inputs that make those optimizations productive. Social teams, in turn, should be accountable for more than platform-reported conversions by tracking credible downstream indicators and participating in incrementality tests.

    The next budget cycle should treat search efficiency as a shared outcome, then test how much of it persists when upstream exposure changes. That approach protects strong search performance without assuming that search created all the demand it converted.

    References

  • Google Search Partners Performance: A Practical Audit

    Google Search Partners Performance: A Practical Audit

    Google Search Partners can extend a campaign beyond the main Google search results page, but additional reach is useful only when it produces meaningful business outcomes. Lower click costs and higher traffic volume can look efficient while concealing weak conversion quality.

    The practical question is therefore not whether the network can generate clicks, but whether its traffic creates enough incremental value to justify the spend. The supplied CrushPress.AI article recommends answering that question with network-level reporting, placement review and conversion-quality checks.

    Key takeaways

    • Search Partners should be assessed separately from Google Search because blended campaign totals can hide major differences in traffic quality.
    • Cheap clicks are not sufficient evidence of efficiency; advertisers need to examine valuable conversions and the quality of the actions used for optimization.
    • New Search and Shopping campaigns can begin without Search Partners, establish a reliable Google Search baseline and then test the additional reach deliberately.
    • Performance Max requires a different response because Search Partners cannot simply be disabled; monitoring and optimization controls become more important.

    Why lower CPCs can give the wrong performance signal

    Search Partners are third-party properties that use Google-powered search results. According to the source article, eligible environments can include YouTube, directories, other search experiences and parked domains. Although the activity remains search-related, the context and audience quality may differ from traffic generated on Google’s primary search results page.

    The article reports a recurring pattern of substantial impressions and clicks at lower cost per click, followed by limited meaningful conversion value. That distinction matters because CPC measures the price of acquiring a visit, not the commercial value of the visit. A less expensive click is beneficial only if its downstream results remain economically useful.

    Search Partners should also not be treated as another name for the Google Display Network. The source distinguishes search-based partner activity from ads shown while people browse websites or apps using AdSense. Some properties may participate in both systems, but the user context and placement logic are different.

    Traffic sourceUnderlying contextPrimary audit question
    Google SearchSearches on Google’s main results pageDoes this provide a dependable performance baseline?
    Search PartnersSearch-based activity on participating third-party propertiesDoes the added reach produce valuable incremental conversions?
    Google Display NetworkAds encountered while browsing participating sites and appsDoes the audience and placement context support the campaign objective?

    A useful audit separates volume, outcomes and quality

    An analyst sorts anonymous traffic tokens into three trays while examining unbranded partner-site tiles with a magnifying glass.

    For Search and Shopping campaigns, the source recommends opening the campaign view and using the Network (with search partners) segment. This creates separate rows for Google Search and Search Partners, preventing stronger results from one network from masking weaker results on the other.

    The comparison should move through three layers. First, impressions, clicks and CPC show how much traffic each network supplies and what that traffic costs. Second, conversion volume, conversion rate, cost per conversion and conversion value indicate whether the visits produce measurable outcomes. Third, the advertiser must determine whether those outcomes represent genuine business progress rather than merely easy-to-complete actions.

    That final layer is especially important. The source cautions that Search Partner traffic can appear productive when optimization relies on shallow signals such as page views or low-friction form submissions. A campaign can meet its reported conversion target while generating outcomes that sales teams cannot use or that contribute little economic value.

    The Content Suitability report under Insights and reports provides another diagnostic view. The article says it can reveal websites or YouTube channels where Search Partner ads appeared. Placement context does not replace outcome data, but it can explain suspicious performance and expose properties that appear irrelevant or low quality.

    Performance Max changes the available controls

    The opt-out decision applies differently across campaign types. The source states that Search Partners are required within Performance Max, so advertisers cannot manage the network with the same checkbox available to conventional Search or Shopping campaigns.

    Instead, the article directs advertisers to the Channel Performance report. Heavy Search Partner activity should prompt a review of conversion tracking, bid-strategy settings and the conversion actions guiding optimization. This reframes the task from excluding the network to ensuring that the automated system is learning from business-relevant signals.

    The source also reports that conversion-focused Smart Bidding may reduce Search Partner spend as it learns that the placements are not producing desired conversions. That observation should not be treated as a guarantee. Automated bidding can only respond to the objectives and measurement signals supplied to it; weak conversion definitions can reward weak traffic.

    A baseline-first test makes the decision clearer

    Two parallel traffic channels run from a shared starting platform into separate outcome reservoirs connected by a balance mechanism.

    The source’s starting recommendation is to leave Search Partners disabled when launching new Search or Shopping campaigns. Concentrating the initial budget on Google Search can establish a cleaner baseline for traffic quality, conversion behavior and unit economics before another source of variability is introduced.

    Once the core campaign is performing reliably, Search Partners can be evaluated as an incremental-volume test. The decision should be based on the additional network’s own results rather than on blended totals or CPC alone. If it supplies conversions that retain their value after qualification, the extra reach may be worthwhile. If it mainly adds inexpensive visits, questionable placements or low-value actions, disabling it protects budget for the stronger source.

    This approach avoids turning a campaign setting into a universal rule. Search Partners remains a testable inventory source, but it should have to demonstrate business value independently. As Google Ads automation takes on more delivery decisions, accurate conversion definitions and network-level scrutiny will become even more important.

    References

  • Google Demand Gen Gets Gemini Creative and Reporting Boost

    Google Demand Gen Gets Gemini Creative and Reporting Boost

    I’m seeing Google roll out a new set of Demand Gen updates designed to help advertisers improve creative performance, reach more potential customers across YouTube, and measure campaign results with more clarity.

    For me, the bigger story is that Demand Gen is becoming less about manually adapting assets and more about using AI-assisted tools to make creative work harder across Google’s most visual surfaces.

    Demand Gen campaigns are built to drive discovery and conversions across Google’s visual placements. With these latest updates, I see Google trying to reduce creative friction while giving advertisers better visibility into what is actually moving performance.

    Google says the enhancements arrive as YouTube continues to show value for customer acquisition. The company cited research from Measured showing that 72% of incremental conversions on YouTube come from new customers.

    What’s new. I’m watching Demand Gen add expanded video resizing capabilities, giving advertisers the ability to automatically transform creative into more aspect ratios, including vertical-to-square, vertical-to-landscape, and square-to-landscape formats.

    That matters because it should make it easier to adapt existing creative for different YouTube placements without having to produce every version manually from scratch.

    Why I care. Expanded video resizing can help existing assets fit more YouTube inventory, Gemini can provide AI-powered recommendations before launch, and new web-to-app measurement can give marketers a clearer view of how Demand Gen campaigns influence app installs and return on ad spend.

    Gemini joins the creative workflow. Google is also bringing Gemini-powered recommendations directly into the Demand Gen campaign creation process, which makes AI guidance part of the asset selection workflow instead of a separate optimization step.

    When advertisers choose image and video assets, Gemini will offer automated suggestions for optimizing creative for YouTube. I see this as a way for marketers to improve asset choices before campaigns go live, rather than waiting for performance data after launch.

    Better app measurement. Demand Gen now includes Web to App Acquisition Measurement, allowing advertisers to measure when web campaigns lead users to install an app.

    The new reporting gives me a more complete way to evaluate campaign performance because it attributes app installs generated through Demand Gen campaigns. That should help advertisers better understand the full impact of their media spend.

    The bottom line. I see Google’s latest Demand Gen updates as a practical combination of AI-powered creative guidance, more flexible video optimization, and broader measurement tools that can help advertisers improve performance while gaining clearer insight into customer acquisition.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Why Better PPC Bidding Still Depends on Conversion Quality

    Why Better PPC Bidding Still Depends on Conversion Quality

    PPC bidding can determine which auctions an advertiser enters and how aggressively a campaign pursues demand. It cannot, by itself, determine whether a click becomes a qualified lead, a signed client, or profitable revenue.

    Taken together, the two source reports point to a more useful way to evaluate bidding: connect auction-time optimization with search intent, landing-page relevance, operational follow-up, and closed-loop measurement. That makes it possible to distinguish genuine growth from a larger volume of inexpensive but low-value conversions.

    Key takeaways

    • Automated bidding can explore additional demand, but its value depends on whether the campaign optimizes toward conversions that reflect business outcomes.
    • CPA and ROAS targets are operating controls, not complete measures of performance; qualified leads, signed cases, and revenue provide essential context.
    • Temporary bidding and budget changes can help capture peak demand when they are paired with sufficient fulfillment or intake capacity.
    • Search-term reviews, intent-specific landing pages, CRM outcomes, and offline conversion data give bidding systems more meaningful signals.
    • Budget allocation should follow marginal business value rather than lead volume alone.

    Why efficient bidding can still produce weak business results

    A platform can lower the reported cost per conversion while the underlying economics deteriorate. This happens when the conversion being optimized is too far removed from the outcome the advertiser actually values. A form submission, for example, may be easy to generate but may say little about qualification, purchase intent, or eventual revenue.

    The law-firm PPC source illustrates the problem through the difference between leads and signed retainers. It argues that cost per lead alone leaves out the intake process, response speed, qualification, and the rate at which qualified prospects become clients. Its recommended reporting chain extends from ad spend and leads through qualified leads, signed cases, CPL, and CPA, segmented by channel and practice area.

    That distinction also changes how an advertiser should interpret automated bidding. Google’s Smart Bidding Exploration update, as described in the other source, lets advertisers specify a ROAS tolerance so campaigns can pursue conversion opportunities beyond queries they might otherwise reach. The source reports that campaigns using the capability saw about an 18% increase in unique converting search-query categories and a 19% increase in conversions. Those are platform-reported expansion indicators; they do not establish that every additional conversion carried the same downstream value.

    The practical question is therefore not simply whether bidding found more conversions. It is whether the incremental conversions remained qualified and profitable after the full customer journey was considered.

    Conversion quality is built before and after the auction

    An auction gateway connects search-intent pathways on one side with a landing experience, human follow-up, and a business handshake on the other.

    Better outcome data begins with the query. The law-firm source recommends reverse-engineering keyword strategy from call transcripts and CRM records rather than beginning with broad, generic terms. It also advocates segmenting keywords and campaigns by intent, funnel stage, budget, and conversion objective, with weekly search-term reviews used to identify valuable language and exclude irrelevant demand.

    This creates an important complement to bidding automation. The algorithm decides among available opportunities, while campaign structure defines which opportunities are grouped together and which outcome signals they share. If high-intent and exploratory traffic are mixed under one target, an aggregate CPA can conceal substantial differences in lead quality.

    Landing pages provide the next quality filter. The law-firm report calls for alignment between the searcher’s intent and the page headline, supporting proof, fast mobile performance, and immediate contact options. It reports that replacing a generic page with intent-specific pages, recent reviews and results, and fewer form fields doubled one client’s conversion rate without additional ad spend. Because this is a single account example reported by the source, it should be treated as illustrative rather than a universal expectation.

    Post-contact operations complete the chain. The same source recommends a response time below 60 seconds, an answer rate above 90%, and a signed rate of 25% to 40% among qualified leads for the law-firm context. These are the source’s operational targets, not general benchmarks for every industry. Their broader significance is that slow or inconsistent follow-up can erase gains produced by bidding and landing-page optimization.

    Use automated expansion and peak bidding with guardrails

    Google’s reported updates introduce two distinct bidding use cases. Smart Bidding Exploration is intended to uncover incremental demand while allowing a degree of ROAS flexibility. Promotion Mode, described as a beta in the source, is designed for temporary changes to ROAS targets and daily budgets around seasonal events, product launches, and flash sales. The source also says Exploration was extended to Performance Max campaigns without product feeds and was being tested for Shopping ads in Performance Max and Standard Shopping campaigns.

    Exploration should be judged as a controlled expansion test. Advertisers need to compare the new query categories with established traffic on qualified-conversion rate, acquisition cost at the final outcome, and revenue contribution. Search-term analysis remains relevant even when automation broadens reach because it can reveal whether incremental volume represents new high-intent demand or merely looser matching.

    Promotion-oriented bidding requires a different guardrail: operational readiness. Raising a daily budget and relaxing a ROAS target may generate more opportunities during a short demand window, but the extra volume only has value if inventory, sales, intake, and customer service can process it. Temporary settings should also have a defined end point so an exceptional trading period does not quietly become the campaign’s permanent efficiency standard.

    For campaigns constrained by budget, the Smart Bidding source also reports a change intended to produce more consistent performance against CPA and ROAS targets. Consistency can make planning easier, but a target should not be treated as proof of profitability. Budget decisions still need to account for the quality and economic value of the outcomes being purchased.

    Build a measurement loop that bidding can learn from

    A circular system links an ad auction, webpage, customer conversation, agreement, and revenue, with outcome signals flowing back to the auction.

    A reliable PPC system connects UTMs, call tracking, website analytics, CRM stages, and final outcomes. The law-firm source specifically points to Google Analytics and CRMs such as Lawmatics or Clio as parts of that chain. Its emphasis is not the choice of software, but the ability to trace a click through qualification and retention rather than ending reporting at the ad platform.

    That closed loop supports better decisions at three levels. Search terms and landing pages can be evaluated by the quality they produce. Campaign targets can be based on downstream value instead of superficial conversion volume. Budgets can then move toward the channels, practice areas, or intent groups that contribute the strongest business outcomes.

    The law-firm source also recommends Marketing Efficiency Ratio as an ecosystem-level measure rather than evaluating every channel in isolation. Used alongside channel-level CPL, CPA, qualified-lead rates, and signed outcomes, it can help distinguish the contribution of the overall marketing mix from the performance reported inside a single platform.

    The next stage of PPC optimization is therefore less about choosing between automation and manual control than about improving the feedback connecting them. Advertisers that define valuable conversions, preserve intent distinctions, and return verified outcomes to the campaign will be better positioned to use bidding expansion without losing sight of profitability.

    References