Tag: Campaign Performance

  • Chrome Ad Metrics: How to Audit an Ad-Heavy Website

    Chrome Ad Metrics: How to Audit an Ad-Heavy Website

    If increasing ad revenue has made your pages feel crowded or slow, you no longer have to settle the argument with screenshots and opinions. Chrome can now expose four separate dimensions of ad load through real-user data: how many ads people see, how much space those ads occupy, how many bytes they consume, and how much processing time they require.

    The useful move is not to chase the lowest possible number. It is to find the page patterns where advertising consumes more attention or resources than the commercial return justifies, then reduce the specific cost without weakening the rest of the business.

    The four metrics reveal different kinds of ad load

    Chrome has added four experimental advertising metrics to the Chrome User Experience Report, commonly called CrUX. Treat them as four diagnostic signals, not as interchangeable measures of whether a page has too much advertising.

    MetricWhat Chrome measuresWhat it helps you notice
    Ad CountThe average number of ads visible in the viewportHow many detected ads compete for the user’s visible attention at the same time
    Ad DensityThe average percentage of the viewport occupied by adsHow much of the visible screen advertising takes over, regardless of the number of placements
    Ad Weight – NetworkThe bytes consumed by advertisingThe data cost of the detected ad experience
    Ad Weight – CPUThe processing time consumed by ads, measured in millisecondsThe execution cost imposed by ad-related resources and scripts

    The distinction matters because a single large placement can create high density without a high count. A collection of small placements can raise count while occupying less space. A visually restrained layout can still transfer substantial data or consume considerable processing time.

    Read the metrics in combination:

    • Count and density rise together: Start with the layout. Too many placements may be visible concurrently, and they collectively occupy more of the screen.
    • Density rises while count stays near your cleaner-page baseline: Investigate placement size and persistence before removing every slot. One dominant unit may be the main difference.
    • Network weight rises while count and density remain stable: The visible layout is not telling the whole story. Inspect the advertising payload and repeated resource requests.
    • CPU weight rises by itself: Concentrate on execution. Reducing visible ad space will not necessarily address script-related processing cost.
    • The four signals stay near your baseline but commercial results remain weak: Do not assume ad load is the cause. Creative relevance, audience fit, placement quality, or another factor may deserve attention first.

    This gives you a better decision model than a blanket instruction to run fewer ads. You can identify whether the problem is competition for space, data transfer, processing, or a combination of them.

    Understand what Chrome is actually observing
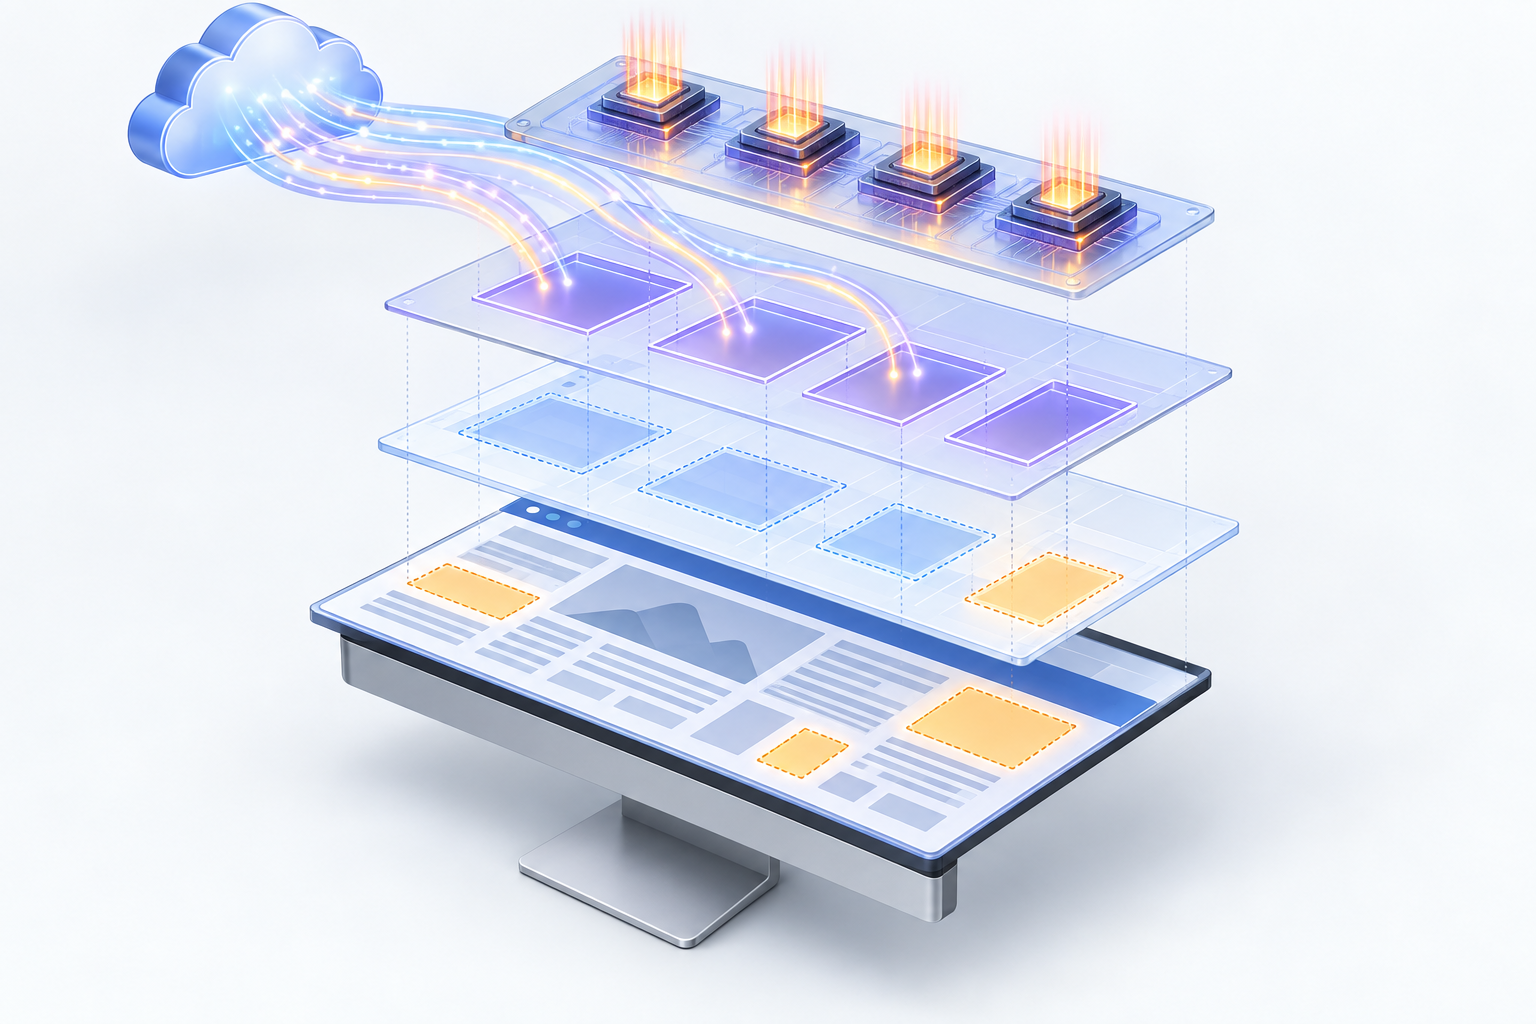
    Four floating webpage layers depict visible ad placements, their occupied area, incoming data, and processor activity above a computer monitor.

    Your ad server, content management system, and Chrome do not necessarily count the same thing. Your systems know which slots, campaigns, or line items you configured. Chrome detects advertising from the browser side.

    Chrome uses network-level filtering and script-execution analysis to identify ads. It can classify a URL as advertising when that URL matches its ad filter list. It can also recognize resources or frames created by scripts that have already been identified as ad-related.

    Ad Count should therefore be read as a count of ads Chrome detected in the visible viewport, not as a count of the placements declared in your page template. When an internal slot report and the Chrome metric differ, first check whether the two systems are measuring the same object. Do not label either figure incorrect merely because it does not match the other.

    Timing changes the interpretation too. Chrome samples the visible viewport once per second for Ad Count and Ad Density. Network and CPU usage accumulate through the user’s session. CrUX then reports the results at the 75th percentile.

    • A screenshot is not a session. A page may begin with a restrained layout and become denser as advertising appears or remains visible during use. Inspect the experience over time.
    • An initial transfer is not total network weight. Resources loaded later in a session still contribute to the accumulated advertising cost.
    • A quick lab run is not field data. CrUX reflects real Chrome usage, so device capability, network conditions, page behavior, and actual user journeys can produce a different result from a controlled check.
    • The 75th percentile is not the arithmetic mean. It marks a value at or below which three-quarters of measured experiences fall. The remaining quarter is heavier, so do not describe the number as the experience of an average user.

    That measurement model should shape your quality assurance. Reproduce an ordinary journey rather than loading the page, taking one screenshot, and declaring the layout acceptable. Let advertising appear, scroll through the content, and continue long enough to expose resources that arrive after the first view.

    Build an audit around contrasts, not invented thresholds
    Three similar webpage layouts with different ad patterns are compared on a light table using a magnifying lens and abstract resource signals.

    Chrome has not established a recommended pass or fail threshold for any of the four metrics. They are experimental, and they are not Core Web Vitals. A universal scorecard that labels a page good or bad would therefore create precision that the current program does not provide.

    You can still run a disciplined audit. Use your own comparable page patterns to establish context:

    1. Define comparable groups. Separate page patterns that have materially different jobs or layouts. An article template, a gallery, and a short reference page should not automatically share one baseline.
    2. Record all four ad metrics together. Do not report density without network and CPU weight, or combine the four into an unsupported composite score. Keeping the raw dimensions visible prevents one improvement from hiding a regression elsewhere.
    3. Keep Core Web Vitals in a separate column. The advertising metrics can sit beside established performance reporting, but they should not be relabeled as Core Web Vitals or folded into a made-up Google score.
    4. Find useful contrasts. Compare cleaner and more heavily monetized experiences within a relevant group. Look for the metric that changes most clearly rather than assuming every ad-heavy page has the same defect.
    5. Reproduce the suspected behavior. Review the page across a realistic session, paying attention to what is visible and what continues loading or executing. The goal is to connect a field signal to an observable mechanism.
    6. Change one cost dimension first. Reduce concurrent visible placements for count, occupied screen area for density, advertising payload for network weight, or unnecessary execution for CPU weight. A focused change makes the result easier to interpret.
    7. Judge the tradeoff with business outcomes. Put the ad metrics beside the revenue and campaign measures your team already trusts. Keep changes that improve the experience at an acceptable commercial cost; investigate further when a lower ad metric merely moves the problem elsewhere.
    8. Create internal guardrails only after you have a baseline. Express them as limits for comparable page patterns and document why they exist. Do not present them as official Chrome thresholds.

    A practical internal rule might require a redesigned template not to materially worsen density or CPU weight against the template it replaces while maintaining an acceptable monetization result. Your team still has to define what materially and acceptable mean, but the rule identifies the comparison, the protected outcomes, and the owner of the decision.

    When possible, test changes in isolation. Removing a placement while simultaneously changing the ad vendor, page layout, and loading behavior may improve the numbers, but it will not tell you which intervention mattered. That leaves you unable to repeat the result elsewhere.

    Avoid five costly interpretation errors

    The new metrics are useful precisely because they separate layout pressure from resource pressure. That value disappears when a team compresses them into a simplistic verdict.

    • Do not optimize only for fewer ads. A lower count can coexist with high density, network weight, or CPU weight. Verify which cost actually fell.
    • Do not treat density as a performance metric. Density describes visible space. Network and CPU weight describe resource consumption. One cannot stand in for the others.
    • Do not claim an SEO ranking effect. Nothing in the current rollout establishes these experimental measurements as ranking signals. Track them beside SEO and performance data when useful, but keep the labels honest.
    • Do not promise a media-value or bidding uplift. Better transparency could affect how buyers assess inventory, but Google has not said whether Display & Video 360 is testing these signals for bidding, valuation, or reporting.
    • Do not wait for an official cutoff before measuring. The absence of a universal threshold prevents a pass or fail verdict; it does not prevent you from detecting regressions, comparing relevant experiences, or correcting an obvious outlier.

    Publishers with cleaner experiences may eventually use the metrics to distinguish their inventory. Advertisers and agencies may use them to identify placements where clutter or resource consumption threatens attention and campaign performance. Independent advertising platforms are expected to receive the CrUX data at the same time as Google’s advertising businesses, which makes it sensible to preserve the raw metrics now rather than build a process around a proprietary composite score.

    For buyers, the right first use is comparison and investigation, not automatic exclusion. A high reading identifies a question to ask about the experience. Without an established threshold or evidence connecting that reading to your own campaign outcome, it is not yet a sufficient reason to reject inventory by itself.

    Key takeaways

    • Ad Count measures how many detected ads are visible; Ad Density measures how much of the viewport they occupy.
    • Ad Weight – Network measures advertising bytes, while Ad Weight – CPU measures advertising processing time in milliseconds.
    • Chrome samples the viewport once per second, accumulates network and CPU use through the session, and reports CrUX results at the 75th percentile.
    • The four measurements are experimental, are not Core Web Vitals, and do not have official recommended thresholds.
    • Use the metrics as separate diagnostic signals, compare relevant page patterns, and evaluate every change against both user-experience and commercial outcomes.

    Choose one commercially important page pattern this week and capture all four dimensions before changing it. That baseline will give your ad, performance, analytics, and editorial teams something concrete to improve – and it will keep future decisions grounded if buyers begin using the same signals to value inventory.

    References


  • Facebook Ad Costs in 2026: What Better Clicks Really Mean

    Facebook Ad Costs in 2026: What Better Clicks Really Mean

    If your Facebook dashboard is showing cheaper clicks, the tempting response is to open the budget. The 2026 numbers support cautious optimism: traffic campaigns are attracting more clicks at a lower price, and lead campaigns are also paying less per click. But the metric that determines whether many advertisers can afford to scale—cost per lead—has barely changed.

    That gap is where your decision lives. A cheaper click is useful only when its value survives the rest of the funnel. Before you increase spend, find out whether Facebook has lowered your acquisition cost or merely made the first step less expensive.

    What actually changed in the 2026 Facebook benchmarks

    In 2026, nearly 1,800 Facebook ad campaigns across multiple industries were measured using click-through rate, cost per click, conversion rate and cost per lead. Traffic and lead campaigns both became more efficient at generating clicks, but the improvement was much smaller at the completed-lead stage.

    Campaign objectiveAverage CTRAverage CPCAverage CVRAverage CPL
    Traffic1.93%, up 12.87% year over year$0.60, down 14.29%Not includedNot included
    Leads2.70%, up 4.25% year over year$1.80, down 6.25%8.54%$27.39, down 0.98%

    CTR measures how often an impression becomes a click. CPC measures the amount spent for each click. CVR tracks how often a click becomes a conversion, while CPL divides campaign spend by the number of leads generated.

    For traffic campaigns, the direction is unambiguously favorable at the click stage: CTR increased by 12.87% while CPC fell by 14.29%. Advertisers received stronger engagement and cheaper visits at the same time.

    Lead campaigns tell a more restrained story. Their CPC fell by 6.25%, but CPL declined by only 0.98%. In aggregate, most of the click-cost improvement did not appear as an equivalent reduction in lead cost. That does not prove where the difference was absorbed. It tells you where to investigate: between the click and the completed lead.

    Better bidding and campaign optimization may be contributing to the stronger performance, but these aggregate outcomes do not establish a single cause. Your own campaign history remains the evidence that should determine your next budget move.

    Key takeaways for your next Facebook budget decision

    • Cheaper Facebook traffic is a real top-of-funnel gain, but it is not automatically a lower customer-acquisition cost.
    • Judge traffic and lead campaigns against their intended jobs. A traffic CPC and a lead CPL answer different business questions.
    • If CTR rises and CPC falls while CPL stays flat, examine the audience-to-offer match, landing experience and lead process before buying more clicks.
    • Use the $27.39 overall CPL as context, not as a universal target. Industry averages range from $12.30 to $61.56 among the reported verticals.
    • Do not move money from search to Facebook based on CPC alone. The channels often reach people at different stages of intent.

    Follow cheaper clicks through the whole lead funnel

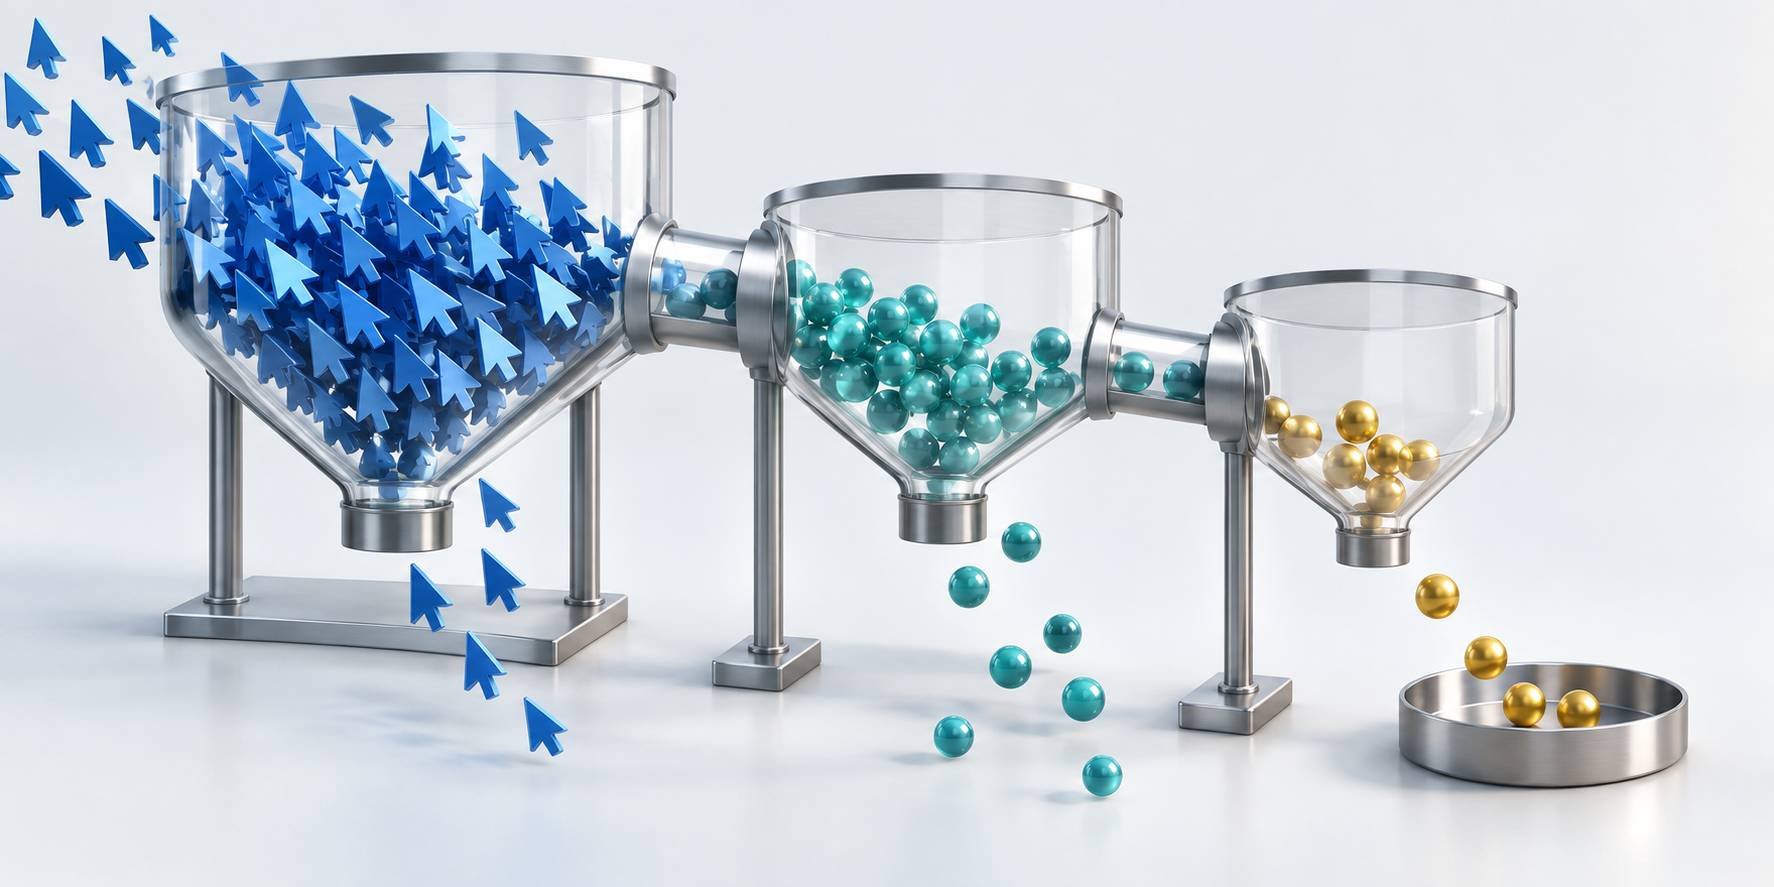
    A transparent three-stage funnel carries many blue cursor symbols through visitor and lead stages, with some markers dropping out along the way.

    One metric cannot tell you whether a campaign is improving. CPC is an input cost. CPL is an acquisition outcome. Lead quality and eventual revenue sit farther downstream. If you stop at the cheapest visible metric, you can scale a campaign that looks efficient while its business value deteriorates.

    Use the same reporting period, spend base and lead definition for each stage of your account-level calculation:

    • CTR = clicks divided by impressions.
    • CPC = spend divided by clicks.
    • Click-to-lead CVR = leads divided by clicks.
    • CPL = spend divided by leads.
    • Qualified-lead rate = leads that meet your qualification criteria divided by total leads.
    • Customer conversion rate = acquired customers divided by the relevant lead group.

    The last two measures are specific to your business, which makes them more valuable than a broad platform average. A low CPL can be a false economy if the form is attracting people who cannot buy, are outside your service area or do not match the offer. Conversely, a CPC increase can be acceptable when the resulting visitors convert into qualified leads at a higher rate.

    Pattern in your accountWhat it can meanWhat to inspect next
    CTR up, CPC down, CVR stable or up, CPL downThe media-efficiency gain is reaching lead acquisitionLead quality and performance as spend increases
    CTR up, CPC down, CVR down, CPL flat or upAttention is cheaper, but more clicks are failing to become leadsAudience intent, message continuity, landing page, form and offer
    CPC up, CPL downMore expensive clicks may be converting efficientlyDo not cut the campaign on CPC alone; verify lead quality
    CPL down, qualified-lead rate downThe apparent acquisition gain may come from lower-value leadsQualification rules, geographic fit, duplicate or invalid leads and sales outcomes
    Traffic CPC down, but valuable site actions unchangedThe campaign is buying visits without improving useful behaviorPost-click intent, page relevance and the action chosen as the next success signal

    Read the sequence from left to right. If CTR improves, the ad is earning more clicks per impression. If CPC also falls, those clicks are becoming less expensive. If CVR then falls, however, the added traffic may not match the promise, destination or conversion request. That is a handoff problem, not a reason to celebrate the click metric.

    For a lead campaign, compare the language and expectation across the ad, landing page or instant form, and follow-up. The person who clicks should encounter the same offer, audience fit and next step throughout. If the ad attracts broad curiosity but the form asks for a serious commitment, Facebook can deliver an attractive CTR without delivering an attractive CPL.

    Industry averages can reverse the headline

    The overall decline in Facebook CPC hides substantial differences between industries. For traffic campaigns, only two reported verticals paid more per click year over year: Shopping, Collectibles and Gifts rose 73.53%, while Sports and Recreation rose 43.90%. At the other end, Real Estate fell 39.56%, Restaurants and Food fell 37.50%, and Industrial and Commercial fell 37.21%.

    Lead-campaign CPC also fell in most verticals. Automotive – For Sale dropped 44.17%, Dentists and Dental Services dropped 41.72%, and Health and Fitness dropped 30.30%. Education and Instruction, up 4.24%, and Sports and Recreation, up 0.93%, were the only reported industries with higher lead-campaign CPC.

    Those click-cost movements still do not reveal what a lead should cost in your market. Average CPL varied sharply:

    IndustryAverage CPLPosition among reported industries
    Career and Employment$12.30Lowest
    Real Estate$13.74Lower end
    Arts and Entertainment$14.59Lower end
    Home and Home Improvement$42.95Higher end
    Beauty and Personal Care$50.91Higher end
    Dentists and Dental Services$61.56Highest

    Dentistry exposes the danger of treating click cost as the result. The vertical recorded a 41.72% reduction in lead-campaign CPC while still carrying the highest reported CPL at $61.56. Access to attention became much cheaper, yet a completed lead remained expensive relative to the other listed industries.

    Use benchmarks in the right order. Start with your own comparable historical period, because it reflects your offer, geography, audience and lead definition. Next, compare campaigns and segments inside the account. Only then use the industry figure to judge whether your experience is directionally unusual. The overall $27.39 average should not become a target imposed on a dentist, recruiter or real estate advertiser as though their economics were interchangeable.

    Turn the trend into a controlled budget decision

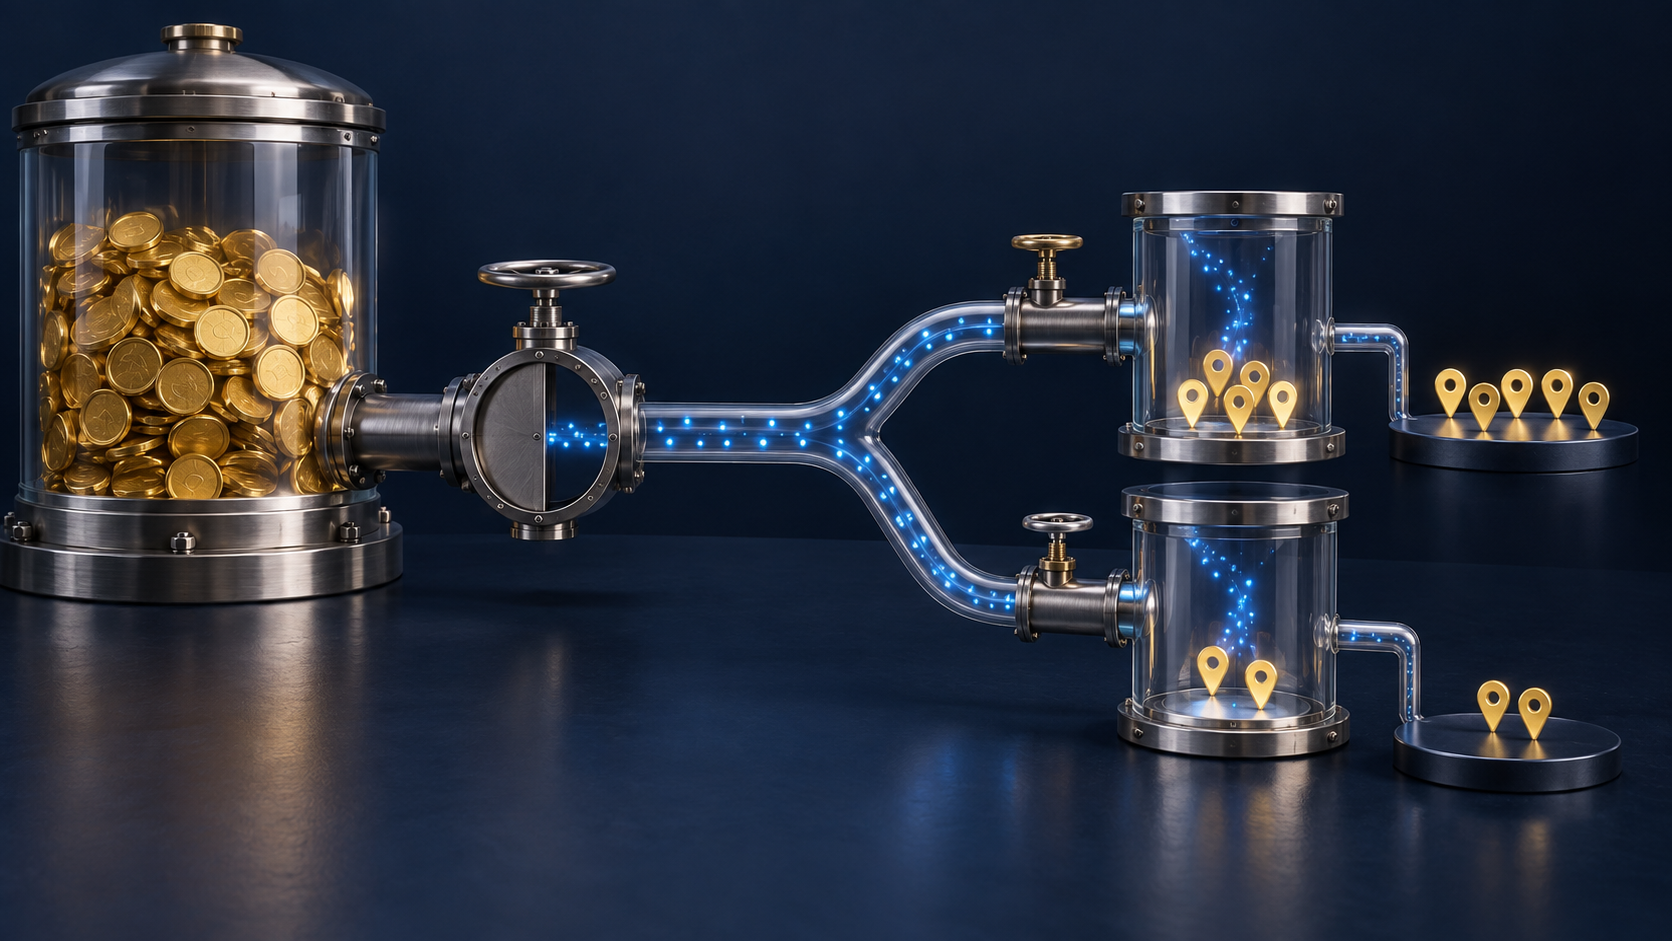
    A branching pipeline sends blue traffic particles through two small test chambers while most gold budget tokens remain behind a partially closed gate.

    The 2026 trend gives you a reason to test for additional efficiency, not a reason to approve an unrestricted increase. A broad budget shift can turn an attractive average into expensive marginal volume. Make the decision with a sequence you can audit.

    1. Name the outcome before reading the dashboard. For a traffic campaign, define the valuable behavior expected after the visit. For a lead campaign, define both the counted lead and the criteria for a qualified one.
    2. Build a comparable baseline. Keep the reporting period, conversion event and lead definition consistent. If any of those changed, label the break rather than presenting the before-and-after figures as a clean trend.
    3. Separate campaigns by objective. Do not blend a $0.60 traffic CPC with a $1.80 lead CPC and call the result an account benchmark. The systems are optimizing toward different actions.
    4. Locate the first metric that failed to improve. Read CTR, CPC, CVR and CPL in order, then continue into qualified-lead rate and customer outcomes. The first break identifies the part of the funnel that needs attention.
    5. Test a limited, reversible budget increase in the segments where lower CPL and acceptable lead quality appear together. Keep unrelated variables stable enough to distinguish a budget effect from a simultaneous creative, audience or offer change.
    6. Judge marginal performance, not only the old average. If the extra spend raises CPL or reduces qualification quality beyond what your unit economics support, stop expanding that segment even if its blended CPC still looks inexpensive.
    7. Compare channels by their role in the buyer journey. Within the benchmark context, Google Ads CPC is more than twice Meta’s average CPC, but Google Search typically captures stronger purchase intent. Paying less for a Facebook click does not make it a direct substitute for a high-intent search click.

    If your primary goal is traffic, the lower 2026 CPC gives you room to test whether additional visits produce meaningful on-site behavior. If your goal is leads, the nearly flat CPL calls for more discipline: isolate where cheaper clicks stop translating into cheaper acquisition before you scale.

    Start with the campaigns where CTR improved and CPC declined but CPL or lead quality did not. Put those campaigns at the top of your diagnostic queue. Repair the audience-to-conversion handoff first, then increase spend only where the efficiency survives into qualified outcomes. Facebook may be offering cheaper access to attention in 2026; your account still has to prove that the savings reach the business.

    References


  • How to Build a Google Analytics Dashboard for Decisions

    How to Build a Google Analytics Dashboard for Decisions

    You open Google Analytics to answer one question and end up moving through several reports, copying figures into a document, and trying to remember whether everyone used the same comparison period. The data may be available, but the route to a decision is unnecessarily long.

    Google Analytics Dashboards can shorten that route by putting selected KPIs and visualizations on a customizable, grid-based canvas. The useful part isn’t the canvas itself. It is the discipline of deciding which questions deserve permanent space, which chart can answer each question, and what someone should do after seeing the result.

    Decide what the dashboard must make obvious

    A dashboard should reduce decision time. It shouldn’t reproduce every report your team might occasionally need. Before you add a card, write a short dashboard brief that answers:

    • Who will use it? An SEO lead investigating landing pages needs different detail from an executive checking overall acquisition and conversion performance.
    • What recurring decision will it support? Examples include deciding where to investigate a traffic decline, which content group needs attention, or where users leave a conversion journey.
    • How often will someone review it? The review rhythm determines whether short-term movement or longer trends deserve more space.
    • What is the primary outcome? Name the result the dashboard is supposed to monitor before choosing supporting metrics.
    • Who owns the response? A metric without an owner becomes decoration. Decide who investigates, who explains, and who acts.

    Turn each proposed card into a complete question. “Organic traffic” is only a label. “Is traffic from organic discovery moving in the expected direction, and which landing content explains the change?” is a question. It tells you that you need a headline value, a trend, and enough detail to locate the affected content.

    Give every KPI an explicit scope as well. The team should know which property, audience, outcome, time period, and comparison the number represents. Two people can read the same number differently when one assumes all traffic and the other assumes a particular channel. The dashboard won’t fix an unsettled definition; it will simply make the ambiguity more visible.

    This distinction matters for SEO, AEO, and GEO reporting. Google Analytics can show activity captured in the property, including measurable visits and subsequent behavior. It cannot turn external rank tracking, AI citation visibility, crawl findings, CRM revenue, or platform delivery data into Analytics measurements merely by arranging cards on a page. Keep those claims in their appropriate systems, then use the dashboard for the questions its data can actually answer.

    Build from outcomes to diagnosis

    A large outcome tile branches into several smaller diagnostic dashboard modules in a layered hierarchy.

    The builder lets you drag dimensions and metrics onto the canvas, then position, resize, and align the resulting visualizations. That makes experimentation easy, but it also makes it easy to fill the page before establishing a hierarchy.

    Build in the order a reader will think:

    1. Start with the outcome. Place the KPI that best represents the dashboard’s primary business result where the eye lands first.
    2. Add its context. Show the input or volume metric needed to interpret that result. An outcome without scale can make a small fluctuation look more important than it is.
    3. Show direction. Add a time-series view so the reader can distinguish a sustained movement from an isolated value.
    4. Expose the main comparison. Break performance down by the category most likely to explain a change, such as an acquisition grouping or content grouping that your measurement plan defines consistently.
    5. Provide a diagnostic route. Use a detailed table for the pages, campaigns, or other entities someone will inspect next.
    6. Add the journey where it matters. If the decision concerns an ordered conversion process, use a funnel to reveal the step where progress changes.
    7. Remove repetition. If two cards lead to the same observation and action, keep the clearer one.

    This sequence creates a practical reading path: outcome, context, trend, explanation, detail, action. It also leaves room beneath the documented cap of 15 cards for standard properties. Premium properties can contain up to 30, but a larger allowance isn’t a reason to use every available position.

    Review the completed canvas at the size your intended audience will normally use. Visual priority comes from position and size as well as chart type. If the primary outcome is smaller than a supporting breakdown, the layout is telling the reader that the breakdown matters more.

    Match each business question to the right visualization

    Six dashboard cards display abstract line, bar, ring, funnel, dot, and gauge visualization forms.

    Six visualization types are available: scorecards, tables, line charts, bar charts, donut charts, and funnel charts. Choose among them by the question being asked, not by the visual variety they add to the page.

    VisualizationQuestion it should answerBest useCommon mistake
    ScorecardWhat is the current headline value?A primary KPI or an essential context metricDisplaying several isolated values without showing why any change matters
    Line chartWhen did the movement begin, and did it persist?Performance over timeUsing a trend line when the real question is a comparison between categories
    Bar chartWhich categories are larger, smaller, ahead, or behind?Direct category comparisonsAdding so many categories that meaningful differences become hard to see
    Donut chartHow is a whole divided among a limited set of parts?A simple composition or share breakdownUsing similar-sized or numerous slices that are difficult to compare
    TableWhich exact item requires investigation?Detailed rows that support diagnosisTurning the dashboard into an exhaustive data export
    Funnel chartAt which ordered step does progression change?Conversion steps and drop-offsTreating unrelated actions as if they formed a single sequential journey

    Use date context deliberately. Scorecards can display percentage change when a date comparison is applied, while line charts support daily, weekly, and monthly views. Pick the line-chart interval that matches the decision rhythm. A view that is too granular can distract the reader with ordinary variation; one that is too broad can conceal when a meaningful shift began.

    A percentage movement also needs its underlying value. A large percentage attached to a small base may deserve less attention than a modest movement in the metric most closely tied to the business outcome. Keep the scorecard for quick detection, then place a trend or detailed breakdown nearby so the reader can test whether the movement is broad, persistent, and actionable.

    Publish with property-wide governance in mind

    Creating a useful layout is only half the job. A user needs an Editor or Administrator role to create and publish a dashboard. Once published, the dashboard can be viewed by anyone who has access to the property, and it can be placed directly in the Reports navigation without routing it through the Analytics library.

    That convenience changes the governance standard. Published dashboards are shared across the property rather than privately with selected individuals, so don’t treat the published area as a personal scratchpad. Settle experimental metric definitions and layouts before exposing them to every property user.

    • Name the audience and purpose clearly. A title such as “Content performance” is weaker than one that identifies the intended decision or review context.
    • Assign an owner outside the dashboard. Someone should be responsible for definitions, layout changes, and questions from viewers.
    • Record the KPI definitions. Preserve the scope, outcome meaning, and expected response in team documentation so the dashboard doesn’t become its own undocumented vocabulary.
    • Check the published view with ordinary access. Confirm that the navigation placement and reading order work for viewers, not only for the person who built it.
    • Review cards when strategy changes. Remove KPIs that no longer inform a live decision instead of leaving them in place for historical familiarity.

    Plan around the launch limitations before promising the dashboard as a complete reporting system. API support, segments, and card-level comparisons were not supported at launch. That means you shouldn’t design a workflow that depends on programmatic dashboard management, segment-based dashboard cards, or a different comparison basis for each card unless those capabilities are verified in your property.

    The absence of card-level comparisons is especially important. Agree on a coherent comparison before presenting the page, and explain any analysis that requires a different baseline somewhere else. Otherwise, adjacent cards can appear comparable while answering different questions.

    Key takeaways

    • Start with a recurring decision and its owner, then choose the metrics needed to make that decision.
    • Arrange cards as a reading path from outcome to context, trend, explanation, and diagnostic detail.
    • Use scorecards for headline values, line charts for timing, bar charts for comparison, donut charts for simple composition, tables for diagnosis, and funnels for ordered journeys.
    • Keep metric definitions and scope explicit; a clean layout cannot repair an ambiguous KPI.
    • Design within the 15-card standard or 30-card premium limit, but treat those figures as ceilings rather than targets.
    • Publish only after accounting for property-wide visibility, role requirements, and the feature limitations that applied at launch.

    Your first dashboard should feel focused rather than comprehensive. Open the builder with your decision brief beside you, place the primary outcome first, and add a card only when it helps the reader detect a change, explain it, or choose the next action. If a card does none of those jobs, leave the space empty.

    References


  • Google AI Tools for Search Marketers: A Practical Workflow

    Google AI Tools for Search Marketers: A Practical Workflow

    Google now puts AI on both sides of a search marketer’s desk. On the organic side, AI-generated search experiences decide how information is assembled and cited. On the paid side, AI interprets campaign data and proposes explanations for performance changes.

    Your job is not to collect every new feature. It is to separate two workflows: earning visibility in AI-generated answers and using AI to investigate paid-search performance. That distinction tells you what to measure, what to prompt, and which conclusions still need human verification.

    Match each Google AI tool to the question it can answer

    Start by deciding whether you are examining the market or examining your account. AI Mode, AI Overviews, and Gemini can help you observe how Google interprets a topic. Google Ads AI Dashboards, homepage insights, and Ask Advisor work with advertising performance.

    Google AI surfaceUseful marketing questionOutput to captureConclusion to avoid
    AI ModeHow is this query answered, and which pages support the answer?Answer structure, cited URLs, entities, claims, and missing subtopicsA citation is a permanent ranking position
    AI OverviewsWhat synthesized answer appears alongside conventional search results?Answer framing, cited domains, and the relationship between the generated answer and the surrounding resultsOne result represents every user, query variation, or future search
    GeminiHow might an AI assistant interpret the topic or decompose the user’s request?Terminology, follow-up questions, ambiguities, and information needsA Gemini response is a direct proxy for Google Search rankings
    Google Ads AI DashboardsWhat changed in campaign performance, where did it change, and what may have contributed?A scoped visualization, account segments, and an explanation to verifyAn AI-generated explanation proves causation
    Ask Advisor and homepage insightsWhich account questions or anomalies deserve investigation?Questions, hypotheses, and paths into the underlying account dataA recommendation should be applied without checking its scope and commercial risk

    This separation matters because AI Mode is an external discovery environment, while an Ads dashboard is an internal analysis environment. AI Mode can show how Google retrieves, orders, and cites information. It cannot tell you why an advertising campaign’s cost changed. An Ads dashboard can analyze account data, but it cannot establish whether your organic content is eligible to support an AI-generated answer.

    Do not combine all of these observations into a single “AI visibility” score. Keep at least two records: an organic answer-and-citation log and a paid-performance investigation log. Otherwise, a change in advertising efficiency can be mistaken for a change in search demand, or a volatile AI citation can be mistaken for durable organic growth.

    Use AI Mode as a citation audit, not a rank tracker

    A magnifying glass inspects links between an abstract AI answer panel and several source documents, with one unsupported connection highlighted.

    A conventional rank check asks where a URL appears for a query. An AI citation audit asks a different set of questions: What answer did Google construct? Which claims needed support? Which sources were selected? What did the cited pages make especially clear?

    That makes AI Mode useful for diagnosing content, but weak as a one-observation scoreboard. Generated answers can change with wording, context, and the shape of the request. Record what you see, but do not turn a single appearance or absence into a general claim about visibility.

    1. Build the query set from real decisions. Include the problem a person is solving, the comparison they need to make, the constraint that changes the answer, and the follow-up question likely to come next. A broad head term rarely reveals the whole information journey.
    2. Run a controlled observation. Keep the wording of each query in your log. Check the conventional results page, note whether an AI Overview appears, and inspect AI Mode separately. Do not silently change the prompt and then compare the outputs as though the query stayed constant.
    3. Record the answer anatomy. Capture the main answer, the subquestions it addresses, named entities, cited URLs, and the specific claim each citation appears to support. A domain count alone tells you almost nothing about why a page was useful.
    4. Inspect the cited pages. Look for the passage that answers the question, the definitions surrounding it, supporting evidence, descriptive headings, and any comparison structure. The useful unit is often a clearly supported claim inside a page, not the page as an indivisible object.
    5. Compare your page with the information need. Mark missing answers, buried definitions, unexplained terminology, unsupported assertions, and comparisons that use inconsistent dimensions. Those are concrete editing targets.
    6. Recheck after a meaningful revision. Keep the original query and observation beside the new one. Treat a changed answer as an observation to investigate, not proof that one edit caused it.

    The resulting worksheet should have one row per query and columns for intent, answer framing, cited pages, supported claims, gaps, planned edits, and the next observation. This gives your team evidence it can discuss. A screenshot folder without query wording or claim-level notes does not.

    Make a page easier to retrieve without writing for a robot

    Retrievability starts with clarity. Put the direct answer near the question it resolves. Name the entity before switching to pronouns. Define specialist terms. Keep qualifications attached to the claim they limit. If you compare options, use the same criteria for each option so the relationship is visible rather than implied.

    • Give each important question a descriptive heading and an immediate answer.
    • Use the full name of a product, organization, method, or standard when ambiguity is possible.
    • Support factual claims on the page instead of expecting a search system to infer evidence from a distant internal link.
    • Place limitations beside recommendations. Moving them to a generic disclaimer weakens the answer and can mislead the reader.
    • Use structured data only when it accurately describes visible content. Schema can clarify meaning; it cannot rescue an unsupported or missing answer.
    • Link related pages according to the reader’s next question, not merely because they share a keyword.

    This is not a replacement for technical SEO. A page still needs to be accessible, indexable, canonicalized correctly, and connected to the rest of the site. AEO and GEO work build on that foundation by making answers, entities, relationships, and evidence easier to identify.

    Prompt Google Ads AI Dashboards like an analyst

    Google Ads AI Dashboards are appearing in some advertiser accounts, so you may not have access yet. Where the feature is available, a natural-language request can generate a visual report instead of requiring you to select every metric, dimension, and chart manually.

    The dashboard can also attach a real-time AI summary of what changed and what may be driving it. That saves report-construction time. It does not remove the need to frame the question or verify the explanation.

    A useful dashboard prompt contains six parts: the decision, account scope, metric, comparison, segmentation, and requested output. If one is missing, Gemini has to infer it, and the chart may be technically correct while answering the wrong business question.

    • Decision: State what you are trying to understand, such as whether an efficiency change is concentrated or account-wide.
    • Scope: Name the campaigns, campaign type, product group, geography, device, or other relevant boundary.
    • Metric: Specify the outcome and its related inputs. Asking only about conversions can hide a simultaneous change in spend or traffic.
    • Comparison: Name the periods or segments being compared and make sure they are commercially comparable.
    • Segmentation: Ask for the dimension that could expose the change instead of accepting an account-wide average.
    • Output: Request the visualization, largest contributors, and a clear separation between observed data and possible explanations.

    A reusable prompt pattern is:

    Compare [metric set] for [campaign scope] between [period or segment A] and [period or segment B]. Break the result down by [dimension]. Visualize absolute and relative changes, identify the largest contributors to the account-level movement, and separate observations from possible causes.

    Reusable Google Ads analysis prompt

    You can adapt that pattern to practical questions:

    • Compare cost, conversions, and cost per conversion across campaigns for two comparable periods. Show which campaigns contributed most to the account-level change.
    • Break out cost, conversions, and conversion value by device for brand and non-brand campaign groups. Flag cases where volume and efficiency moved in different directions.
    • Chart daily spend and conversions for a selected campaign group. Identify the dates and campaigns responsible for the largest deviations, without assigning a cause.
    • Compare performance by geography for the selected campaigns. Separate changes caused by traffic volume from changes in conversion efficiency.

    These prompts do more than request a prettier report. They force you to define the denominator, the comparison, and the decision. If the generated chart cannot accommodate a requested metric or dimension, revise the scope rather than accepting a substitute without noting it.

    Verify the AI explanation before changing content or spend

    An analyst cross-checks an AI-generated performance explanation against a calendar, change history, source document, and calculator before approving an action.

    The most convincing AI mistake is a plausible explanation attached to accurate numbers. A dashboard may correctly show that cost per conversion rose while offering a cause that the chart cannot prove. The phrase “may be driving” marks a hypothesis, not a causal finding.

    Run every material insight through the same verification loop:

    1. Confirm the scope. Check the date range, campaign selection, filters, excluded segments, and comparison period. A summary can be accurate for its slice and still misrepresent the account.
    2. Confirm the metric definition. Make sure the chart is using the conversion, value, cost, or efficiency measure your decision actually depends on. Similar labels are not interchangeable.
    3. Locate the contributors. Move from the account total to campaigns and then to the dimension behind the movement. An average can conceal opposite changes in separate segments.
    4. Separate observation from cause. “Mobile efficiency declined” is an observation. “The landing page caused the decline” requires evidence beyond two events occurring near each other.
    5. Check the underlying rows. Review the data behind the visualization before presenting the summary or applying a recommendation. The chart is an interface to the account, not an independent record.
    6. Choose a reversible next step. Investigate, annotate, or run a controlled change before making a broad account adjustment.

    Paid-search decisions can spend real money. Do not increase budgets, change bids, pause broad campaign groups, or alter conversion settings solely because an AI summary sounds certain. Use the same approval process you would apply to a human analyst’s recommendation, and preserve a record of the original settings and the reason for the change.

    Apply the same discipline to organic content. Do not rewrite an accurate, useful page merely because it was absent from one AI Mode response. First determine whether the page answers the same intent, whether another page on your site is the better candidate, and whether the proposed edit improves the reader’s answer. Citation visibility is an outcome to observe, not permission to weaken the page.

    Key takeaways and your next working session

    • Use AI Mode and AI Overviews to inspect answer construction and citations; do not treat them as conventional rank trackers.
    • Use Gemini for exploratory interpretation, not as proof of how Google Search will rank a page.
    • Use Ads AI Dashboards to reduce report-building work, but define the scope, metric, comparison, and segment in the prompt.
    • Treat every generated explanation as a hypothesis until the underlying account data supports it.
    • Keep organic citation observations separate from paid-performance investigations.
    • Improve content by clarifying answers, entities, evidence, and relationships while preserving technical SEO and reader value.

    For your next working session, choose one valuable query cluster and one unresolved Google Ads performance question. Build a citation log for the first and a tightly scoped dashboard prompt for the second. If every conclusion can be traced back to a cited page or a defined slice of account data, the AI is helping you investigate. If it cannot, keep it in the hypothesis column.

    References


  • How to Measure Google Ads Offline Sales for Real Profit

    How to Measure Google Ads Offline Sales for Real Profit

    Your ads generated store visits, your point-of-sale system recorded purchases, and Google Ads reports a healthy return. The awkward question is whether those events represent the same customers – and whether the resulting sales left any money after returns, tax, product cost, transaction fees, fulfillment, and media spend.

    The answer requires more than uploading store revenue. You need an auditable chain from ad interaction to finalized offline sale to contribution. Build and validate that chain before asking automated bidding to act on it. A faulty value feed does not merely misreport performance; it teaches the campaign to pursue the wrong outcome.

    Keep attribution, incrementality, and profit separate

    An offline conversion can support three different claims. Mixing them is the fastest way to turn a respectable dashboard into a bad budget decision.

    • Attribution: Google Ads matched or credited a store sale to an eligible advertising journey. This is useful for campaign reporting, but credit is not proof that the ad caused the purchase.
    • Incrementality: The purchase would not have happened without the advertising. Establishing this requires a credible comparison, such as a controlled geographic or store-level test, rather than another attribution setting.
    • Profitability: The sale produced enough contribution to cover its share of advertising cost. You cannot answer this from gross revenue alone.
    QuestionWorking metricDecision it can support
    What did Google Ads credit?Attributed offline conversions, conversion value, and reported ROASCampaign diagnosis inside the platform
    What did the sale earn?Contribution before advertising and contribution returnValue rules, break-even analysis, and bidding guardrails
    What did advertising cause?Incremental contribution minus advertising costBudget allocation and growth decisions

    ROAS is reported conversion value divided by ad spend. An 11x ROAS says that spend was about 9% of the reported conversion value. It does not tell you whether that value includes tax, whether returns were removed, whether the customers were incremental, or whether the retained revenue covered the remaining variable costs.

    Before anyone sets a target ROAS, get marketing and finance to approve written definitions for reported revenue, net revenue, contribution before media, and profit after media. If those definitions are missing, the target is just a ratio attached to an unknown value.

    Build an offline sales data loop you can reconcile

    An isometric data loop connects a smartphone, matching tokens, store checkout, purchase record, returns box, and finalized database through validation paths.

    Google Ads cannot infer what happened at the register. It needs a consistent store-sales feed, and you need evidence that every handoff preserved the intended transactions and values.

    Where Store Sales is available in Data Manager, Google Ads can use a direct CRM or Google Sheets connection for offline sales data. That reduces technical friction, but a simpler connector does not resolve unclear business rules, duplicated transactions, premature revenue, or the wrong value calculation.

    1. Choose the transaction of record. Define whether a conversion becomes valid when an order is placed, paid, collected, or closed. State how cancellations, exchanges, refunds, partial returns, and duplicate records will be handled.
    2. Preserve transaction lineage. Keep the internal transaction identifier, store, transaction time, currency, original amount, current status, and permitted matching data consistent across the point-of-sale system, CRM, export, and Google Ads workflow. Have the appropriate privacy or legal owner approve which customer fields can leave the system of record.
    3. Keep raw and adjusted values separate. Retain the booked sale amount for reconciliation and a profit-adjusted value for decision-making. Do not overwrite the original financial record with a marketing calculation.
    4. Automate the connection carefully. Use the CRM or Google Sheets route in Data Manager when it is available and appropriate for your account. Confirm the expected schema and eligibility inside Google Ads rather than assuming that every exported row can be used.
    5. Reconcile before optimizing. Compare the file or connector output with the accepted import, then compare attributed results with Google Ads reporting. These are different tests: one checks data movement, while the other checks platform matching and attribution.
    6. Assign an owner and cadence. Document who reviews failures, when values are refreshed, how late returns are handled, and who can change the value formula. An unattended feed becomes a silent bidding instruction.

    Your recurring control report should show finalized POS or CRM transaction count and value, rows prepared for transfer, rows accepted or rejected, Google Ads conversion count and value, and an explanation for material differences. Do not compare attributed Google Ads sales directly with total store revenue and call the gap a tracking error. First reconcile the exported population with the imported population; only then investigate matching and attribution.

    Keep the campaign on observation while you validate at least one complete import and financial-finalization cycle. Avoid making a large budget change, switching the primary conversion, and changing the bid strategy at the same time. If results move, you need to know whether the cause was customer demand, a bidding decision, or the measurement pipeline.

    Turn store revenue into a defensible profit signal

    A pile of revenue coins passes through deduction gates for returns, tax, product materials, transaction processing, shipping, and media spend, leaving a smaller illuminated stack.

    The value used for bidding should resemble contribution, not the number printed at the top of the receipt. A practical starting formula is:

    Contribution before advertising = net sales excluding sales tax – returns and refunds – cost of goods sold – variable fulfillment, transaction, and order-handling costs.

    Use the costs that change when you make the sale. The correct stack will differ across retailers, restaurants, and local service businesses. A store purchase might avoid outbound shipping but incur payment fees, product preparation, delivery, sales commission, or another transaction-level cost. Finance should decide which costs belong in the calculation.

    Do not subtract Google Ads spend from the conversion value you upload if you will evaluate that value against ad cost inside the platform. Otherwise, you risk charging the same media cost twice. Keep the two calculations explicit:

    • Contribution return: contribution before advertising divided by ad spend.
    • Profit after media: contribution before advertising minus ad spend.
    • Revenue ROAS break-even: one divided by the contribution margin expressed as a decimal. This works only when the margin definition and revenue basis are consistent.

    A composite apparel account shows how gross revenue can conceal a loss. The reported order looked exceptional at 11x ROAS, yet the cost stack ended below zero:

    StageValue remaining from a £100 order
    Reported conversion value£100.00
    After a 28% return rate£72.00
    After VAT was removed£60.00 net revenue
    After COGS at 63% of net revenue£22.20
    After fulfillment, shipping subsidy, return postage, and handling£11.20
    After payment and platform fees£8.70
    After the ad cost implied by 11x ROAS-£0.39

    Do not copy those rates into your account. Use the sequence as a checklist for costs that may be absent from Google Ads. Your point-of-sale and finance data must supply your own return behavior, tax treatment, product margin, payment costs, and variable operating expenses.

    Timing matters as well. The value available on purchase day may be provisional because refunds, returns, or fulfillment costs arrive later. Maintain an early bidding view and a closed-period finance view, then compare them on a recurring basis. If provisional margin consistently overstates finalized contribution for a product group, location, promotion, or campaign, adjust the bidding value rule instead of accepting the bias.

    Let profit, incrementality, and volume decide the budget

    Once the data loop works, the next mistake is treating the highest efficiency ratio as the automatic winner. Budget decisions need the marginal economics of the next sale, not just the average economics of the sales already captured.

    Separate demand capture from demand creation

    A blended account result can hide very different jobs. In one 11x blended account, brand campaigns ran at roughly 18x while nonbrand activity sat around 3x. People searching a brand name may already be close to buying, so brand advertising can receive credit for demand it did not create.

    Report brand and nonbrand performance separately, even if the final finance view combines them. For offline campaigns, also examine location coverage, store type, promotion, and local demand conditions where your data supports those dimensions. A high blended ratio should not be used to justify more prospecting spend unless the prospecting segment itself has acceptable contribution and credible incremental value.

    When the budget is material, use a controlled comparison where feasible. Comparable stores or geographic areas can help you estimate what would have happened without the campaign. Keep major influences such as operating hours, promotions, and inventory availability as comparable as possible, and evaluate finalized POS contribution rather than platform-attributed revenue alone. If you cannot run a credible comparison, label the incremental result as uncertain instead of converting attribution into a causal claim.

    Use local optimization only after the value signal is trustworthy

    Local Customer Optimization is a campaign-level control for Performance Max store-goal campaigns. Where available, it can prioritize nearby, in-market consumers across Google Maps, Waze, and local Search.

    That can improve how the campaign pursues local demand, but proximity and intent are not proof of profit. Before enabling the control, confirm that your locations are represented accurately, the offline conversion reflects the outcome you actually value, the imported amount uses an approved economic definition, and the stores can serve additional demand. Review its effect against a stable baseline; changing local targeting, values, budgets, and creative simultaneously will make the result difficult to interpret.

    Do not maximize efficiency at the expense of total contribution

    A very tight efficiency target directs automated bidding toward the cheapest and most certain conversions. That can improve a ratio while reducing total sales. For a retailer holding seasonal stock, the unsold units can later require deeper markdowns and keep cash tied up.

    Consider an illustrative seasonal SKU with eight weeks remaining: 1,000 units at an £18 unit cost and a £45 recommended retail price. A tight efficiency target sells 350 units and leaves 650 to be cleared at 70% off after the season. Relaxing the target to 4x sells 850 units and leaves 150 to clear. The second path produces a worse ROAS but more total contribution and releases more working capital.

    This is not permission to lower a target whenever sales slow. Model the expected contribution, clearance loss, cash effect, and inventory exposure first. Use a capped test and obtain finance approval when the decision materially changes margin or working-capital risk.

    • Scale: the next block of spend is expected to produce positive contribution after media, the data feed is reliable, incremental evidence is credible enough for the decision, and the business has inventory or service capacity.
    • Hold and test: average performance is profitable, but marginal performance or incrementality remains unclear.
    • Reduce or repair: finalized contribution is negative, the import contains material errors, or the campaign is being credited for sales that are unlikely to be incremental.
    • Relax an efficiency target deliberately: a lower ratio is expected to increase total contribution, prevent a more expensive inventory outcome, or release necessary cash. Record the commercial reason and the stopping condition before the test begins.

    Key takeaways

    • An attributed offline sale is evidence of platform credit, not automatic proof of incrementality or profit.
    • Reconcile the POS or CRM export with the Google Ads import before using store-sales data for automated bidding.
    • Value conversions with contribution before ad spend, while preserving gross revenue separately for financial reconciliation.
    • Separate brand from nonbrand activity so existing demand does not disguise weak acquisition economics.
    • Judge budget changes by marginal and total contribution, not by whichever campaign has the highest average ROAS.
    • Use local-intent controls after the store-sales feed, economic definition, and operational capacity have been validated.

    Start with one recently closed accounting period and one manageable campaign or store cohort. Reconcile its transactions, calculate finalized contribution, separate brand from nonbrand demand, and compare the campaign ranking under ROAS with the ranking under contribution after media. If the order changes, fix the value signal before you scale. Once the rankings are stable and defensible, expand the feed and test local optimization with clear financial guardrails.

    References


  • Google AI Search Ads: How to Read the Performance Shift

    Google AI Search Ads: How to Read the Performance Shift

    If your Shopping click-through rate is climbing while clicks barely move, do not label the campaign healthier yet. That combination can appear when the impression pool contracts faster than click volume. The rate improves, but the business receives little or no additional traffic.

    At the same time, Google is testing a new route into AI Mode for tightly controlled Search campaigns. You therefore have two changes to manage: AI-generated experiences may be reshaping the inventory available to Shopping ads, while some exact and phrase match campaigns may gain access to a new search surface. The practical response is to separate reach, efficiency, intent and business outcomes before changing bids or budgets.

    Google is routing intent into different search experiences

    Google’s AI search shift is not simply another placement added to the same auction. The results experience can vary by query. A person may receive an AI Overview, conventional search results with ads, a Shopping-led result or an AI Mode response. Your campaign cannot earn an impression when Google chooses an experience that does not offer that particular ad opportunity.

    A notable pattern has appeared across thousands of Shopping and Performance Max campaigns spanning hundreds of advertiser accounts: impressions often declined more clearly than clicks, leaving clicks relatively flat or slightly lower and pushing CTR upward.

    One possible mechanism is selective routing. Google may be more likely to show an AI Overview for a query with relatively low predicted ad-click propensity, while preserving Shopping placements for searches more likely to generate a commercial click. Anecdotal observations have also found Shopping ads and AI Overviews uncommon on the same results page.

    That explanation is a hypothesis, not a demonstrated cause. The timing could be coincidental, AI Overviews could be contributing through a different mechanism, or another change could be reducing impressions. Treat the account pattern as observed and the AI Overview explanation as unconfirmed.

    Search contextWhat is supportedHow you should interpret it
    Shopping inventory alongside the growth of AI OverviewsSome large campaign datasets show impressions falling more than clicks while CTR rises. The causal role of AI Overviews remains unproven.Report the loss of reach alongside the higher rate. Do not call CTR growth an optimization win by itself.
    AI Mode with explicit, direct intentExact and phrase match keywords can trigger traditional text ads in a small experiment.Existing controlled campaigns may gain reach without an immediate switch to a more automated campaign type.
    AI Mode with complex or conversational intentAI Max and Performance Max remain Google’s products for broader conversational searches and newer formats such as Highlighted Answers.Test automated expansion separately from your controlled keyword campaigns so that you can measure what the additional reach contributes.

    The important distinction is between selection and persuasion. A higher CTR can mean that your ad persuaded a larger share of the same audience. It can also mean that Google removed lower-propensity impressions before your creative entered the picture. Those are different performance stories and demand different decisions.

    The Shopping CTR trap: a stronger rate can hide weaker reach

    A narrowing funnel reduces a field of impression particles while only a few click tokens emerge beside an unlabeled rising gauge.

    CTR is clicks divided by impressions. If impressions decline faster than clicks, CTR rises automatically. Your ad does not need to generate a single additional visit for the rate to look better.

    The size of the observed movement makes this more than a theoretical concern. One ecommerce dataset showed Shopping CTR up 17% year over year, close to a roughly 20% increase in another benchmark. Looking below the rate revealed that clicks were often flat or slightly down while impressions had fallen more substantially.

    Read CTR as one link in a metric chain

    Put these measures beside one another in every Shopping and Performance Max review:

    • Impressions show how much exposure the campaign received. A decline may indicate a smaller available opportunity, a change in eligibility, a different query mix or another delivery constraint.
    • Clicks show the traffic actually delivered. Flat clicks paired with rising CTR usually mean the rate has improved more than the outcome.
    • CTR describes click efficiency within the inventory Google served. It does not measure the size or quality of the inventory that disappeared.
    • Cost shows what you paid to participate. A selective inventory pool can change both traffic volume and auction economics.
    • Conversions, conversion value and profit show whether the campaign created a business result. Use the measure that reflects your actual commercial objective rather than treating a platform rate as the objective.

    A reach-compression pattern looks like this: impressions decline more sharply than clicks, CTR rises and total traffic remains flat or falls. That pattern should trigger an inventory and query-mix investigation, not a bid increase prompted by the CTR improvement.

    A genuine performance improvement is broader. Click volume, qualified conversions or conversion value should move in the desired direction without unacceptable cost or margin deterioration. CTR can support that conclusion, but it cannot establish it alone.

    Use comparable reporting periods and keep promotions, budget changes, product availability and campaign restructuring visible in the same view. Otherwise, an AI-search hypothesis can become a convenient explanation for a change caused inside your own account.

    Exact and phrase match are entering AI Mode with boundaries

    You do not necessarily need to move every Search campaign into AI Max or Performance Max to become eligible for AI Mode. Google has started a small experiment allowing exact and phrase match keywords to serve text ads in AI Mode.

    The restriction matters. Those keywords can participate only when Google’s systems identify explicit and direct user intent. Eligibility is therefore not guaranteed merely because a keyword uses exact or phrase match. Google still decides whether the person’s request maps directly enough to the advertiser’s keyword.

    The experiment also does not put traditional Search campaigns on equal footing with every automated option. AI Max and Performance Max are still positioned for more complex, conversational searches and provide access to newer AI Mode formats, including Highlighted Answers. Traditional campaigns are being tested specifically with text ads attached to clearer intent.

    No broad or permanent rollout has been confirmed. Do not rebuild a functioning account or move material budget solely to chase access to an experiment whose coverage Google has not disclosed. A premature migration can expand spend, change the query mix and destroy the clean baseline you need to judge incrementality.

    Keep controlled intent and automated exploration separate

    1. Preserve a control lane. Keep exact and phrase match campaigns for queries with an obvious commercial request. Think in practical intent classes such as a named product, a specific service, a price request or a purchase-ready action.
    2. Create an exploration lane. Test AI Max or Performance Max separately when you want coverage for longer, less predictable or conversational searches. Give the test its own measurement view and a bounded budget.
    3. Map the landing experience to the intent. A direct query should reach a page that answers the direct request without forcing the visitor through an unrelated explainer. A comparison or discovery query needs enough context to support a decision.
    4. Judge incremental outcomes. Measure whether the exploration lane adds useful clicks, conversions and value to the account. A higher CTR within either lane does not prove that it generated incremental demand.

    This structure lets you benefit if controlled Search inventory expands into AI Mode without surrendering the ability to test Google’s more automated route. It also prevents performance from different intent classes from being blended into one reassuring average.

    Audit the query path before changing bids or budgets

    An analyst traces an illuminated query path through abstract search, AI response, ad placement, and conversion stages while two control knobs remain untouched.

    Your next account review should identify what changed, what you can only infer and what remains unknown. Use this sequence:

    1. Capture a stable baseline. Export impressions, clicks, CTR, cost, conversions and conversion value for comparable periods before changing campaign types, match strategies or budgets.
    2. Separate campaign cohorts. Review standard Shopping, Performance Max and traditional Search independently. Within Search, separate exact and phrase match from broader automated reach. Blended account totals can hide which inventory pool contracted or expanded.
    3. Group search intent. Distinguish explicit commercial requests from exploratory or conversational needs. Google’s AI Mode test uses that distinction as an eligibility boundary, so your analysis should use it too.
    4. Diagnose the denominator. When CTR rises, check whether clicks increased or impressions merely fell faster. If the latter is true, describe the result as more selective delivery until evidence supports a stronger explanation.
    5. Label causal confidence. Mark each conclusion as observed, inferred or confirmed. Impressions down and CTR up is observed. AI Overviews caused the decline is inferred. Do not allow those statements to merge in a dashboard annotation.
    6. Change one lane at a time. Retain the original controlled campaigns while testing automated expansion. Separate budgets and document the change date so that any gain or loss remains attributable.
    7. Report the business consequence. End with traffic, conversions, value and cost. A useful report sentence is: Shopping CTR increased while impressions declined more sharply than clicks; the pattern is consistent with a more selective inventory mix, but it does not establish AI Overviews as the cause.

    Paid search and AI-search optimization should also share the intent map. If repeated results-page checks show that a query cohort receives an AI answer without a Shopping placement, the PPC team cannot bid its way into inventory that was not offered. That cohort becomes a content and AI-visibility question as well as an advertising question. Build pages that answer the exploratory need clearly, define the relevant product or entity precisely and give the user an obvious path into a commercial page.

    Keep that cross-channel conclusion proportionate to the evidence. A handful of manual searches is directional, not proof of universal delivery. Search experiences can vary, so record repeated observations and continue to distinguish your own results-page evidence from a proposed explanation of Google’s system.

    Key takeaways for your next reporting cycle

    • A rising Shopping CTR may be a denominator effect caused by impressions falling faster than clicks.
    • Cross-account data supports the impression-and-click pattern, but the claim that AI Overviews caused it remains a hypothesis.
    • Exact and phrase match Search campaigns can enter AI Mode in a small experiment when Google detects explicit, direct intent.
    • AI Max and Performance Max remain the routes positioned for more complex conversational searches and newer AI-native formats.
    • Keep controlled intent and automated exploration in separate campaign and measurement lanes.
    • Report impressions, clicks, cost and business outcomes with CTR so that shrinking reach cannot masquerade as improved performance.

    For your next report, add one line beneath every CTR change: what happened to impressions, clicks and conversion value at the same time. Then classify the explanation as observed, inferred or confirmed. That small discipline will keep your decisions sound while Google’s AI search inventory continues to change.

    References


  • Google AdSense Begin-to-Render: A Publisher Action Plan

    Google AdSense Begin-to-Render: A Publisher Action Plan

    If AdSense revenue helps you judge whether your content strategy is working, February 2027 could produce a misleading signal. Your reported display impressions may fall even when traffic and reader behavior have not materially changed.

    The right response is to establish a clean baseline, mark the measurement break, and compare impressions with traffic, clicks, and earnings before changing your site. That lets you separate a new counting rule from a real monetization or SEO problem.

    Key takeaways

    • Beginning February 17, 2027, an AdSense display impression will be counted after the ad has successfully loaded and started to render, not when it merely starts downloading.
    • Downloads that never reach rendering will disappear from the impression total. An early page exit is one example of how that gap can occur.
    • A lower impression count does not, by itself, prove that traffic, ad demand, viewability, engagement, or revenue declined.
    • Click-through rate and other per-impression ratios may change mechanically because their denominator has changed.
    • Preserve pre-change data now, separate display inventory from inventory already using Begin-to-Render, and evaluate post-change results by page type, device, and placement where your reporting supports those dimensions.

    What Begin-to-Render changes in AdSense

    Three generic browser panels show an empty ad space, the first visible pixels appearing with an indicator light, and the completed ad rendering.

    On February 17, 2027, Google will change the counting trigger for AdSense display impressions. Under the current method, the impression is recorded when an ad starts downloading to the user’s device. Under Begin-to-Render, or BTR, the ad must successfully load and start rendering on that device.

    Measurement pointCurrent display methodBegin-to-Render method
    Counting triggerThe ad starts downloadingThe ad successfully loads and starts rendering
    User leaves after download starts but before renderingThe impression can be countedThe impression is not counted
    Inventory affected by the transitionAdSense display adsDisplay joins the unified BTR approach
    Other inventoryNative, app, and video inventory already uses or complies with Begin-to-Render counting

    The important difference is the interval between download and render. If an ad crosses both points, it qualifies under either method. If it begins downloading but never reaches rendering, it can contribute to the old total but not the new one.

    Begin-to-Render should not be treated as another name for viewability, attention, or engagement. It confirms that rendering began after a successful load. It does not tell you how much of the ad the person saw, how long it remained available, or whether the person interacted with it. Avoid relabeling the new count as a viewable impression in internal reports unless the metric you are using separately establishes viewability.

    The transition also is not a directive to move every placement higher on the page. It is a measurement change. First identify where download-to-render failures actually occur; otherwise, a layout overhaul may damage the reading experience without addressing the cause.

    Why the dashboard can look better and worse at once

    Google has warned that publishers may see a change in total impressions because downloads that never render will no longer count. No universal percentage change has been specified. Your result will depend on how often your display ads currently enter that unfinished state.

    That creates a break in the time series. A chart that places pre-February 17 impressions beside post-February 17 impressions without an annotation makes the two periods look directly comparable when they are not. Treat the date as a measurement boundary in dashboards, forecasts, stakeholder reports, and automated alerts.

    Derived rates require even more care. Click-through rate divides clicks by impressions. If clicks remain unchanged while the newly defined impression total falls, the reported rate rises automatically. That increase does not prove that people became more interested in the ads. Part of it may be denominator removal.

    The same arithmetic applies to any earnings-per-impression calculation. If earnings remain stable while counted impressions decline, earnings per thousand impressions can rise without any improvement in total revenue. If earnings and impressions fall together, the rate may remain similar even though the site earns less. A rate by itself cannot tell you which situation occurred.

    This is why neither conclusion is safe on impression data alone. Fewer impressions do not automatically mean your SEO traffic weakened, and a higher per-impression rate does not automatically mean monetization improved. Keep the numerator and denominator visible: traffic, display impressions, clicks, and earnings should be reviewed as separate values before you interpret their ratios.

    Build a baseline that survives the February change

    The useful work happens before the switch. You need enough context to answer one practical question afterward: did the business change, or did only the definition change?

    1. Map the inventory in scope. Identify the reports and dashboards that contain AdSense display impressions. Keep native, app, and video inventory distinct where possible because those formats already use or comply with BTR counting.
    2. Save a stable pre-change baseline. Export the reports you routinely use before February 17, including their exact date range and filters. Preserve raw impressions, clicks, and earnings rather than saving only calculated rates.
    3. Add independent traffic context. Retain pageviews, landing-page visits, sessions, or the equivalent traffic measures your analytics setup uses. Align site scope and reporting dates so that an AdSense property is not accidentally compared with traffic from a different set of pages.
    4. Record operational changes. Note ad-placement edits, template releases, consent-flow changes, performance work, major campaigns, and content migrations near the transition. Any of these can complicate the comparison even though they are separate from the counting rule.
    5. Choose meaningful cohorts in advance. Where your existing reports support them, prepare comparisons by device, page template, content section, and ad placement. A site-wide total can hide a problem concentrated in one implementation.
    6. Annotate February 17, 2027 everywhere. Put the date in reporting calendars, dashboard notes, forecast assumptions, and recurring stakeholder reports. Future analysts should not have to rediscover why the series changed.

    Four paired calculations are especially helpful: display impressions per pageview, clicks per display impression, earnings per display impression, and earnings per pageview. Use the same definitions and scope on both sides of the change.

    The per-impression measures show what happened inside the newly counted population. The per-pageview measures show whether the economic result changed for the traffic you actually received. If earnings per impression rises while earnings per pageview stays flat, you may be looking mainly at a denominator effect. If earnings per pageview declines as well, there is a business outcome to investigate rather than merely relabel.

    Do not force a comparison between periods with visibly different traffic composition. A major campaign, seasonal event, ranking change, or shift in device mix can move ad behavior independently of BTR. Use comparable traffic cohorts and keep those differences explicit.

    Turn the post-change gap into a defensible decision

    An analyst compares four abstract measurement streams across a divider, with only the impression tiles dropping while traffic, clicks, and earnings remain steady.

    Read the pattern before changing the site

    Start with the shape of the change, not a theory about its cause. The following patterns point to different next steps:

    • Traffic is stable, display impressions fall at the transition, and clicks and earnings are broadly stable: a counting-definition effect is plausible. Document the break before treating it as an optimization problem.
    • Traffic and display impressions decline together: investigate acquisition and audience changes as well as ad measurement. BTR alone cannot establish why fewer people reached the site.
    • Display impressions fall mainly on one template, device group, or placement: inspect that implementation. A concentrated gap deserves more attention than a uniform site-wide adjustment.
    • Click-through rate rises while clicks are flat: treat the increase as denominator-sensitive. Do not claim stronger engagement without additional evidence.
    • Earnings per pageview declines: the economic result changed for the traffic received. Review earnings, traffic mix, placement behavior, and render failures together rather than assuming the counting rule explains the entire loss.

    For an SEO-led publisher, compare organic landing traffic with display impressions separately. Stable organic visits alongside a lower ad-impression total are not evidence of a ranking loss. Falling organic visits and falling impressions, by contrast, require an SEO investigation that is independent of the AdSense definition change.

    Inspect the download-to-render interval

    Once you find a cohort with an unusual gap, test representative pages on the affected device type. Observe whether the ad begins loading, whether the creative starts rendering, and whether navigation or another page event occurs first. Browser developer tools, the visible page state, and the diagnostics already available in your ad implementation can help you distinguish an initiated request from an actual render.

    Treat possible causes as hypotheses. A user may leave before rendering, which is the explicit example behind the change. A slow page, late ad initialization, template-specific integration, consent sequence, or navigation behavior may also deserve inspection when the evidence points there. Do not declare one of these the cause merely because it sounds plausible.

    Change one relevant variable at a time and review the same cohort again. If several layout, performance, consent, and placement changes launch together, you will not know which one affected rendering or revenue.

    Optimize the outcome, not the retired counter

    The old metric gave credit at an earlier technical milestone. Trying to recover every disappearing impression can push you toward the wrong goal. A download that repeatedly begins but never produces a rendered ad is not a number you should preserve merely for continuity.

    Prioritize genuine implementation failures, avoidable delays, and placements that fail to render despite meaningful reader activity. Avoid disruptive layout changes whose only justification is restoring the old impression total. The decision should improve rendered ad delivery, earnings per visit, or the reader experience under the new definition.

    Put February 17, 2027 on your reporting calendar now and preserve the unaggregated values behind your ratios. When the switch arrives, make the first review a measurement audit. Redesign a placement only after the traffic, cohort, and earnings evidence shows that you have a delivery problem rather than a cleaner count.

    References


  • Google Ads API v25.1: A Practical Measurement Playbook

    Google Ads API v25.1: A Practical Measurement Playbook

    If you pull Google Ads data into a warehouse, dashboard, or client-facing platform, adding fields is the easy part. The harder job is deciding which business question each field can answer without turning unlike signals into one misleading performance score.

    Google Ads API v25.1 gives you several useful separations: original versus adjusted conversion value, attributed results versus incremental lift, internal performance versus category benchmarks, and total converters versus loyalty segments. Used carefully, those distinctions can make your reporting more explainable. Used carelessly, they can produce a wider dashboard that is no more trustworthy than the old one.

    Key takeaways

    • Store original_conversion_value beside the corresponding adjusted value. The difference shows how conversion value rules and customer lifecycle goals are changing the values used downstream.
    • Treat Conversion Lift and Brand Lift as distinct measurement layers. Their API resources are read-only, and access is currently limited to allowlisted Google Ads accounts.
    • Use Product & Service Category benchmarks as context for investigation, not as automatic bidding instructions.
    • Keep brand sentiment separate from campaign outcomes. It can guide review and creator analysis, but it does not establish incremental impact.
    • Model loyalty tier, loyalty membership conditions, and conversion value as separate fields so you can explain who converted and why a value adjustment applied.
    • Although v25.1 is a drop-in upgrade for v25, you still need updated client libraries, code changes for the new capabilities, and semantic regression tests before using the data in decisions.

    Build your measurement model around six different questions

    Six separate measurement workstations examine different signals from one central data source using distinct instruments.

    The most important design choice is not which new metrics to retrieve. It is which question each capability answers. A clean measurement model keeps the following layers separate:

    Business questionv25.1 capabilityAppropriate use
    What was the conversion worth before Google applied value adjustments?original_conversion_valueAudit the effect of value rules and lifecycle goal adjustments.
    Did advertising create incremental conversions or awareness?Conversion Lift and Brand Lift resourcesInspect eligible lift studies, configurations, dimensions, and results.
    How does performance compare with a relevant market category?BenchmarksService with Product & Service CategoriesAdd competitive context to internal performance analysis.
    What sentiment is associated with a creator or brand?ContentCreatorInsightsService sentiment dataSupport creator intelligence, brand review, and reporting workflows.
    Which loyalty groups converted, and did membership affect value?Loyalty tier segmentation and loyalty membership dimensionsAnalyze converters by tier and explain membership-based value rules.
    How might parental-status targeting affect planned reach?ReachPlanService targetingUse parental status in forecasting and plannable product discovery.

    Do not collapse these capabilities into a composite campaign health score. A strong benchmark, positive sentiment, and positive lift are different observations with different scopes. Combining them can hide the exact information a decision-maker needs.

    Make original conversion value an audit layer

    The new original_conversion_value metric exposes the value of a biddable conversion before conversion value rules or customer lifecycle goal adjustments. That distinction matters whenever the value used for reporting and optimization is not identical to the underlying conversion value.

    For each compatible reporting grain, preserve at least three concepts in your own model:

    • Original value: the pre-adjustment value returned by original_conversion_value.
    • Adjusted value: the corresponding value after the applicable rules or lifecycle adjustments.
    • Adjustment delta: adjusted value minus original value, calculated in your reporting layer.

    Report the absolute delta before reaching for a percentage. A percentage becomes undefined when the original value is zero and can look extreme when the denominator is small. If you do show a percentage, define how zero and missing values are handled instead of letting a dashboard silently convert them into zeros.

    The delta is not evidence that Google changed a value incorrectly. It tells you that an adjustment occurred. Your next question is whether that adjustment matches the value rule or lifecycle policy your team intended. Where your system already stores rule metadata, expose it beside the delta so an analyst can move from detection to explanation.

    Do not replace an established revenue or return-on-ad-spend metric with original_conversion_value in one step. That can change budget conclusions simply because the definition changed. Run original and adjusted value in parallel, reconcile known value-rule cases, and label both clearly before either number reaches automated budget logic.

    Keep lift, benchmarks, and sentiment in their own lanes

    Lift data needs its study context

    Google Ads API v25.1 adds read-only resources for Conversion Lift and Brand Lift studies. You can inspect configurations, flight dates, associated campaigns, and conversion goals. The API also adds 24 Conversion Lift metrics, winner score metrics for statistical analysis, and Brand Lift dimensions covering age range, campaign, device, gender, and video.

    Read-only is an important boundary. Build your integration to retrieve and explain study data, not to promise study creation or modification through these resources. Put configuration and result data in the same analytical view: a result without its flight dates, campaign scope, and conversion goal is easy to apply to the wrong period or objective.

    Access is another boundary. Brand Lift and Conversion Lift API capabilities are currently limited to allowlisted accounts, and advertisers are directed to contact their Google representative for access. Check eligibility before committing a delivery date. In a multi-account platform, treat eligibility as an account-level capability rather than assuming that one successful request means every account is supported.

    Your internal presentation should distinguish at least four states: supported with data, supported with no returned data, unavailable because eligibility has not been established, and failed because the request encountered an error. Those are product states you define in your application, not API status labels. Keeping them separate prevents an access limitation from being reported as a zero lift result.

    Winner score metrics should retain Google’s metric names and definitions in your semantic layer. Do not relabel a winner score as probability, certainty, or incremental return unless the applicable definition supports that interpretation. The safe workflow is to display the score with its study scope, then let the measurement owner determine how it informs a campaign decision.

    Category benchmarks provide context, not a target

    BenchmarksService can now compare performance within specific Product & Service Categories and return aggregate cost and views alongside share-based measurements such as share of voice. The narrower category dimension can make a comparison more relevant than a broad benchmark group, but relevance still depends on whether the selected category represents the business being evaluated.

    Before placing a benchmark beside an account metric, document the category, measurement window, metric definition, and any other comparability controls available in your query. If those elements differ, show the benchmark as external context rather than a direct performance gap.

    A share metric and an aggregate volume metric also answer different questions. Share of voice describes relative presence, while aggregate cost and views add scale context. Show both when available. A low share in a large category may deserve a different response from the same share in a small category.

    Do not let a benchmark variance trigger bid or budget changes automatically. The comparison may identify an issue worth investigating, but it does not tell you whether the right response is more spending, different creative, narrower targeting, or no change at all. Route the variance into an analyst review that also considers the account’s own goals and economics.

    Brand sentiment is an intelligence signal

    ContentCreatorInsightsService now supports brand sentiment distributions and summaries for creators and brands. That gives advertising platforms another signal for creator research and brand reporting, but sentiment should not be presented as conversion performance or causal campaign impact.

    Use the distribution when you need to understand the mix behind a summary. A single summary can conceal whether sentiment is consistently moderate or sharply divided. The practical use is triage: identify creators or brands that warrant closer review, then examine the relevant campaign and brand context before acting.

    Connect loyalty reporting to value-rule governance

    Concentric groups of customer tokens pass through adjustable rule gates into a transparent value-measurement chamber.

    Google Ads API v25.1 allows reporting metrics to be segmented by the loyalty program tier of users who converted. It also makes loyalty membership a primary dimension for conversion value rules, allowing you to identify when a loyalty membership condition was satisfied.

    Those capabilities describe two related but different facts:

    • Loyalty tier segmentation tells you which tier is associated with a converting user.
    • Loyalty membership as a value-rule dimension tells you whether a membership condition was met when a conversion value rule was evaluated.

    Do not infer the second from the first. A converter’s tier is an audience attribute; a satisfied rule condition is part of value-processing logic. Store them separately even if your first dashboard shows them together.

    The most useful loyalty analysis combines tier segmentation with the original-versus-adjusted value audit. Start with these questions:

    • How many conversions and how much original conversion value came from each returned tier?
    • How much adjusted conversion value was reported for those same segments?
    • When a loyalty membership condition was satisfied, did the resulting delta match the intended value policy?
    • Are any apparent differences driven by a small number of conversions rather than a stable segment pattern?

    Always report conversion volume beside value when reviewing tiers. A high average value from a small segment can dominate a ranking without providing a dependable basis for budget changes. You do not need an invented universal threshold; you need enough context for the owner of the loyalty program to judge the segment responsibly.

    Parental-status targeting in ReachPlanService belongs in a different part of your model. It expands reach forecasting and plannable product discovery; it is not an observed conversion result. Keep forecast inputs and planned reach outside outcome tables so users cannot mistake a planning scenario for delivered performance.

    Roll out v25.1 without changing metric meaning by accident

    Google describes v25.1 as a drop-in upgrade for v25, but access to the new capabilities still requires the latest client libraries and corresponding code updates. Drop-in compatibility reduces migration friction; it does not replace testing of your transformations, labels, and downstream decisions.

    1. Inventory the current integration. Record the v25 services, fields, generated client types, transformation jobs, dashboards, and automated decisions that could be affected.
    2. Update the client library in an isolated change. Confirm that the existing extraction and build processes still work before requesting new resources or metrics.
    3. Regression-test existing outputs. Run representative unchanged queries through the old and upgraded paths. Compare row grain, identifiers, null handling, totals, and field mappings.
    4. Add one capability group at a time. Original conversion value, lift studies, benchmarks, sentiment, loyalty, and reach planning should enter separate staging models. This makes a semantic error easier to locate.
    5. Model access explicitly. Check allowlist eligibility for lift features and make unavailable capabilities visible to the user. Do not coerce an unavailable response into zero.
    6. Validate with known business logic. For accounts using conversion value rules or lifecycle goals, select known cases and verify that the original-to-adjusted relationship matches the configured intent.
    7. Release reporting before automation. Let analysts inspect the new fields and definitions in read-only dashboards before any benchmark, sentiment, loyalty, or value delta changes bids, budgets, or alerts.

    Give every new metric a short data contract. It should name the business question, API service or resource, reporting grain, raw and derived fields, eligibility requirement, refresh process, null policy, and downstream decision. That document is what stops an accurate field from becoming a misleading KPI six months later.

    If you need one place to start, add original_conversion_value as a parallel audit field and trace its path through your warehouse and reports. Then add category benchmarks and loyalty segmentation as separate analytical views. Treat lift integration as its own workstream because account eligibility and study context must be resolved first. Your next API pull should not merely contain more columns; it should make the path from underlying value to business decision easier to explain.

    References


  • Paid Media Conversion Measurement: What to Change Now

    Paid Media Conversion Measurement: What to Change Now

    Your paid media dashboard can keep filling up while the measurement underneath it becomes less dependable. The practical fix is not another master metric. You need to strengthen how outcome events reach Microsoft Advertising and change how your team interprets branded-search activity in Google Ads.

    Those are separate jobs. One improves event collection when browser signals are limited. The other exposes a consideration signal that sits between an ad impression and a conventional conversion. If you combine them indiscriminately, you can end up with a larger conversion total and a weaker understanding of performance.

    Separate event collection from campaign interpretation

    The most important distinction is between how an event is captured and what the event means. Microsoft Advertising’s Conversions API, or CAPI, changes the collection path. Google’s Branded Searches changes what behavior you can observe after an ad exposure.

    Measurement componentWhat it recordsHow to use itWhat not to infer
    Microsoft UETActivity captured in the browserMaintain browser-side visibility and use it with CAPIDo not assume browser collection alone covers every online or offline outcome
    Microsoft CAPIOnline or offline events sent from your systems through a server-to-server connectionImprove signal coverage and connect outcomes that do not exist solely in the browserDo not assume a second collection path automatically fixes event definitions or duplicate handling
    Google Branded SearchesA search for your brand on Google or YouTube after someone sees an eligible adAssess whether YouTube or Demand Gen activity is followed by greater brand-seeking behaviorDo not treat the signal as a sale, a bidding target, or proof of incremental lift

    This distinction should survive all the way into your dashboard. A server-recorded purchase or qualified offline outcome and a subsequent branded search may both carry a conversion label inside an ad platform, but they answer different questions. Combining them in one unlabeled total makes that total difficult to use for budgeting.

    Create separate reporting groups for business outcomes, consideration actions, and measurement diagnostics. That gives each signal a job before anyone uses it to defend a campaign.

    Add Microsoft CAPI without dismantling UET

    An isometric website and server send conversion-event packets through separate browser and server routes to one measurement destination.

    Microsoft CAPI is currently a beta capability, so your first implementation question is whether the account has access. The second is whether someone can own a server-side integration after launch. This is not a one-time tag installation; it needs an event definition, a connection to the systems where those events originate, and ongoing monitoring.

    Keep UET in place. Microsoft recommends that advertisers combine CAPI with Universal Event Tracking: UET continues to observe browser activity, while CAPI sends data directly from your systems. Treat the two paths as complementary coverage, not competing implementations.

    1. Confirm account eligibility and name a technical owner. If the beta is not available, finish the event design now so access does not become the start of the project.
    2. Build an event register before writing integration code. For every event, record the business definition, originating system, online or offline status, browser collection path, server collection path, reporting purpose, and accountable owner.
    3. Identify overlap between UET and CAPI. When the same real-world action can arrive through both paths, confirm Microsoft’s current deduplication requirements and define the identifier that ties the records together. Do not assume duplicate prevention happens automatically.
    4. Test online and offline flows separately. Use known test cases and verify that the originating system, integration logs, and advertising report describe the same action.
    5. Reconcile events at three stages: created in your system, sent by the integration, and acknowledged or reported downstream. A discrepancy then points to a specific handoff instead of becoming a general tracking mystery.
    6. Document failure handling. Your owner should know where rejected or unsent events appear, how they are retried, and how a prolonged interruption becomes visible.

    The event register matters because server-side transport cannot rescue an ambiguous conversion. If sales and marketing use different definitions of a completed outcome, CAPI can transmit that disagreement more reliably without making the resulting metric more useful.

    Server-side collection is also a transport choice, not permission to send every available customer field. Moving data out of the browser does not remove your privacy, consent, security, or data-governance obligations. Limit the payload to the approved measurement purpose and have the appropriate internal owner review it before production use.

    Reset how you report Google’s Branded Searches

    An abstract ad panel leads to a magnifying glass over products, while only one branch continues to a separate checkout package.

    Branded Searches measures a meaningful middle step: someone sees an ad and later searches for the advertiser’s brand on Google or YouTube. That can reveal demand that a click-only report misses, particularly when the ad creates memory rather than an immediate site visit.

    It is still a consideration action, not an end-of-funnel outcome. Google formally places it under the Consideration goal, and its current rules create several reporting traps that you should resolve before presenting the number.

    • The default conversion window is seven days. You can set it from one to 30 days.
    • YouTube and Demand Gen are currently listed as eligible campaign types.
    • Performance Max is not included in the current eligibility list, even though it appeared when the conversion type was originally announced.
    • Brand mapping must be configured. A missing or incomplete setup can prevent the measurement from working.
    • Branded Searches is treated as a primary conversion action, but it cannot be selected as a bidding optimization goal.
    • The metric appears in Results and All Conversions rather than the standard Conversions column.
    • You can inspect it at campaign, ad group, and asset levels, as well as through Report Editor.

    These eligibility, attribution, and reporting rules mean that a missing number is not automatically a demand problem. Check campaign type, brand mapping, conversion window, and report column before diagnosing the creative or audience.

    Choose the window for comparability, not a bigger count

    The seven-day setting is an attribution boundary. It determines how long a subsequent branded search can qualify after the relevant ad exposure; it is not a waiting period before the data becomes useful.

    Start with the seven-day default unless your measurement plan supports a different choice. If you change it, record the effective date and avoid comparing the new count directly with a period measured under the old window. Extending the eligible period can change the volume even when the campaign itself has not changed.

    Use the signal to investigate influence, not claim causation

    A search that follows an impression establishes sequence inside Google’s measurement framework. By itself, it does not prove that the search would never have happened without the ad. That distinction separates attribution from incrementality.

    Describe the metric internally as observed branded-search behavior after ad exposure. Do not rename it brand lift, incremental search, or acquired demand. If your decision requires a causal claim, an attributed sequence is not a substitute for a controlled lift design.

    The primary-conversion label deserves similar care. In this case, primary does not mean the action can steer bidding, and it does not place the metric in the usual Conversions column. Build a dedicated report from Results or All Conversions, then keep the signal separate from the outcome conversions used to judge commercial return.

    For Performance Max, treat support as unconfirmed unless the current interface or Google guidance available to your account explicitly establishes otherwise. Its absence from the current campaign list is a reason to verify, not a reason to copy the YouTube or Demand Gen setup and assume equivalent coverage.

    Put every measurement change behind a written contract

    A measurement contract is a short operating record for each signal. It prevents platform terminology from becoming your business definition and makes reporting changes auditable. Create one before you alter dashboards, goals, or stakeholder reports.

    • Signal name and plain-language definition
    • The real-world action represented
    • Originating system and collection path
    • Eligible platforms and campaign types
    • Attribution or conversion window
    • Required setup dependencies
    • The platform columns and reports where it appears
    • Whether bidding can use it
    • Whether the signal represents an outcome, consideration action, or diagnostic
    • The owner responsible for implementation and validation

    For Microsoft, the contract should distinguish UET, CAPI, and any event that can arrive through both. It should also show whether each event is online or offline and how overlap is controlled.

    For Google Branded Searches, record YouTube and Demand Gen as the currently listed campaign types, the selected one-to-30-day window, the brand-mapping dependency, the Results and All Conversions reporting locations, and the prohibition on bidding optimization. Mark Performance Max as requiring verification rather than silently treating it as eligible.

    Then use a fixed decision hierarchy. Business outcomes answer whether the investment produced value. Consideration signals help explain movement toward those outcomes. Collection diagnostics tell you whether the measurement path worked. A diagnostic should not determine budget, and a consideration action should not be presented as revenue.

    Before approving a period-over-period comparison, verify that the following conditions remained stable:

    • The eligible campaign set did not change.
    • The conversion window did not change.
    • Brand mapping remained active.
    • The same reporting column or report was used.
    • UET and CAPI coverage remained stable, or any change was annotated.
    • Duplicate handling was verified after integration changes.
    • The business definition of each outcome remained the same.

    If one of those conditions changed, annotate the break and report the affected periods separately. A clean-looking trend line is less useful than an honest discontinuity.

    Key takeaways for your next measurement review

    • Microsoft CAPI is a beta server-side measurement path, not a replacement for UET.
    • Design duplicate handling before sending the same action through browser and server paths.
    • Use CAPI to support online and offline event coverage, but keep one documented business definition for every conversion.
    • Google Branded Searches currently applies to YouTube and Demand Gen; do not assume Performance Max eligibility.
    • The Branded Searches default window is seven days and can be adjusted from one to 30 days.
    • Report Branded Searches as a consideration signal from Results or All Conversions, not as a bidding goal or proof of incremental lift.

    Your next measurement meeting should end with two named owners and two concrete outputs: a technical plan for UET plus CAPI coverage, and a reporting contract for Branded Searches. Once those are explicit, you can add signal without weakening the decisions built on it.

    References