Tag: Campaign Performance

  • Paid Search Incrementality Testing: A Practical Framework

    Paid Search Incrementality Testing: A Practical Framework

    You may know exactly how much revenue Google Ads claims and still not know how much revenue the ads created. That gap matters most when branded campaigns, strong organic rankings, and direct traffic all reach the same customer.

    A paid search incrementality test replaces that ambiguity with a controlled absence. You pause a defined slice of advertising, measure what actually disappears and what moves elsewhere, then compare the incremental loss with the spend you avoided. The goal isn’t to prove that paid search works or doesn’t. It is to identify where it acquires demand, where it supports another channel, and where it charges you for demand you already own.

    Attribution records a route; incrementality measures an effect

    Platform attribution answers, “Which tracked interaction received credit?” Incrementality answers, “What would have happened without this interaction?” Only the second question tells you whether removing or reducing spend would materially change the business outcome.

    Suppose a customer searches your company name, clicks an ad above your top organic result, and buys. The advertising platform can correctly record the ad click while still overstating the ad’s causal value. The unresolved question is whether that same customer would have clicked the organic listing and bought anyway.

    You can’t settle that question with last-click, first-click, data-driven, or multi-touch attribution alone. Changing the credit rule redistributes recorded value among observed touches. It doesn’t create the missing counterfactual.

    The prior evidence is genuinely mixed. Google’s pause experiments across more than 400 advertisers estimated that 89% of ad clicks were incremental on average, while eBay’s branded-search experiment found that almost all missing paid clicks and sales moved to organic. Google’s result is platform-supplied evidence, and neither finding is a universal rule. The difference is the point: brand strength, organic visibility, query type, competition, and account structure can produce very different answers.

    For a useful diagnosis, classify paid search at the query or campaign level:

    ClassificationWhat it meansWhat you should test or decide
    IncrementalPaid search reaches customers or produces outcomes that your other channels would not have captured.Keep it when incremental contribution exceeds its cost; test expansion separately.
    DependentOrganic or another channel performs worse when paid support disappears.Measure the combined channel effect and avoid treating paid and organic as isolated budgets.
    CannibalizedThe ad captures a click or conversion that a strong unpaid result was already positioned to win.Reduce or pause the affected slice while monitoring total revenue, query clicks, and competitive pressure.

    These aren’t permanent labels. A branded query can be largely cannibalized while you rank first, then become more incremental if organic visibility falls or a competitor changes the search results. Your test should therefore support a budget rule with conditions, not a timeless verdict about the channel.

    Key takeaways

    • Test a material but reversible slice of spend instead of switching off the entire account by default.
    • Judge the test on total business outcomes, not on the revenue that disappears from the advertising platform’s report.
    • Separate branded search, non-brand search, Shopping, and Performance Max because their substitution patterns can differ.
    • Join paid search-term data with organic query data before the pause so you know where paid and organic already overlap.
    • Allow for delayed substitution. A short test can make paid search look more incremental than it is if customers and reporting take time to move.
    • Make the final decision with incremental contribution or profit, not attributed ROAS.

    Design the pause around one budget decision
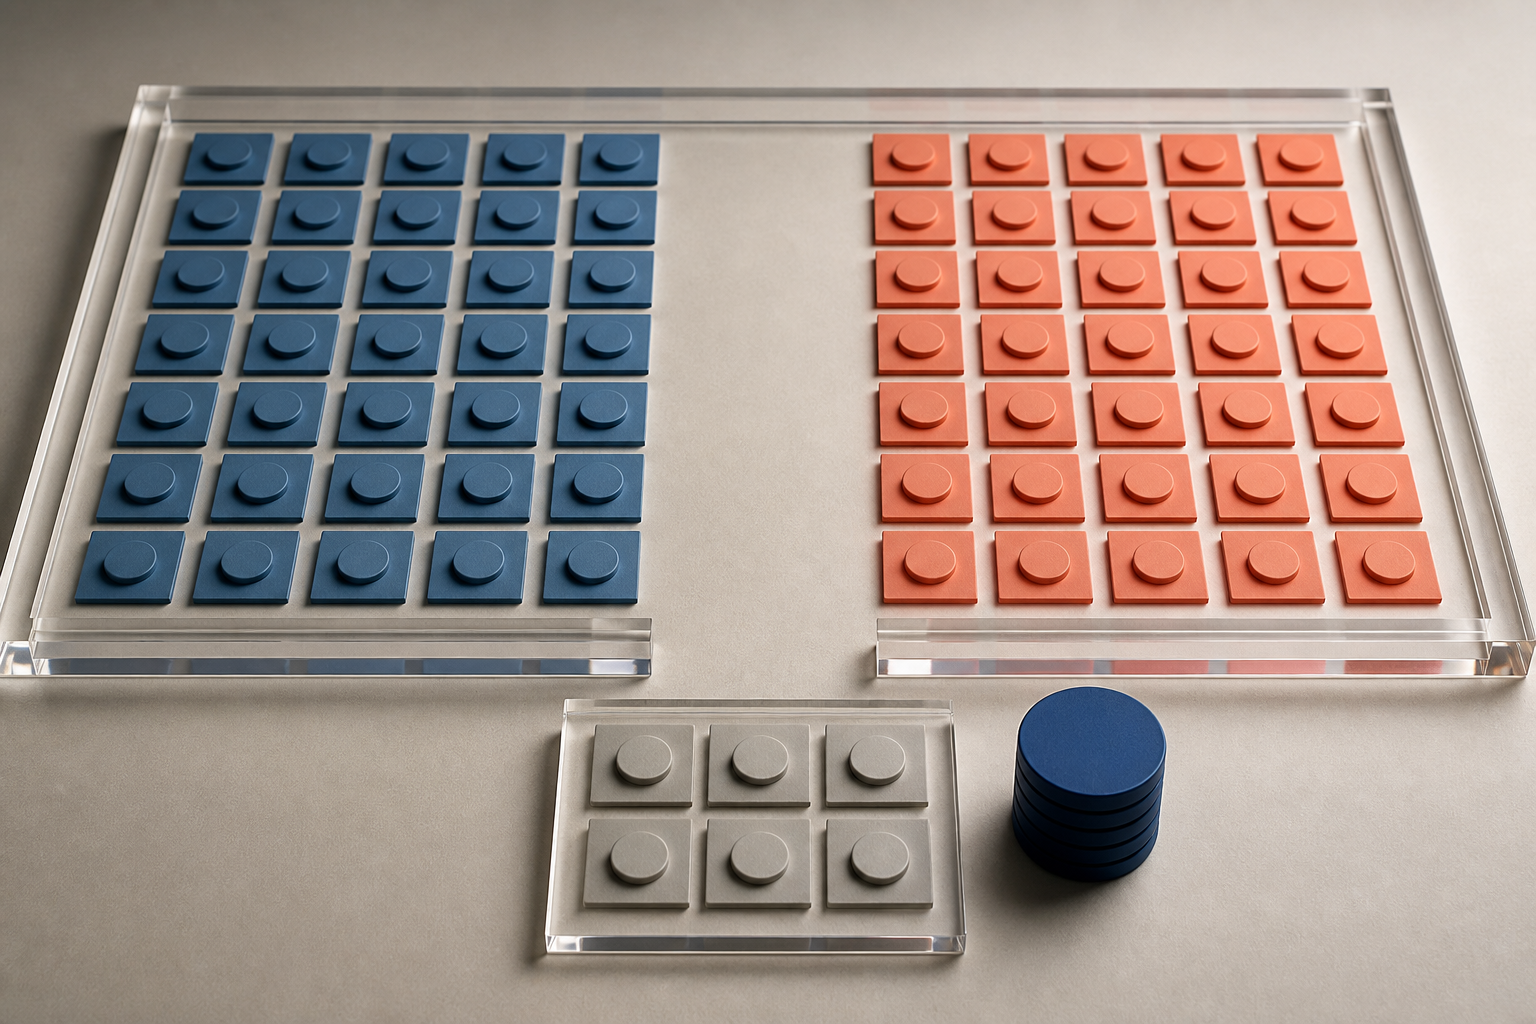
    Matched groups of campaign tiles arranged for a controlled experiment, with one bounded set removed beside a stack of budget tokens.

    A broad question such as “Does paid search work?” cannot produce a clean action. Define the decision first: whether to keep branded ads in a particular market, reduce spend on terms where you already rank strongly, or retain a non-brand campaign that appears to introduce new customers.

    Then write the test plan before changing the campaigns:

    1. State the counterfactual. Write what you expect customers to do when the selected ads disappear. For example, they may move to organic listings, arrive directly, choose a competitor, or not visit at all. This forces you to measure the channels where substitution should appear.
    2. Choose one testable slice. Isolate branded search from non-brand search, Shopping, and Performance Max. A result from brand terms should not be used to cut prospecting campaigns whose job and audience are different.
    3. Select the test unit. A campaign, coherent query group, or market can be paused while a comparable unit remains active. A credible control helps distinguish the pause from seasonality, promotions, or a general change in demand. If no good control exists, be explicit that a pre-versus-post result carries more uncertainty.
    4. Lock the primary outcome. Use total revenue, qualified leads, purchases, or another business result that exists outside the ad platform. Record paid-attributed revenue, organic revenue, direct revenue, organic clicks, and total query clicks as diagnostic measures rather than competing versions of success.
    5. Define the economic rule. Decide in advance how you will compare the incremental outcome with avoided media cost. Where margin data is available, use contribution rather than revenue; otherwise a high-revenue, low-margin campaign can appear more valuable than it is.
    6. Record known disruptions. Promotions, price changes, inventory constraints, site outages, tracking changes, SEO releases, and brand publicity can alter the same metrics as the pause. Log them during the test and exclude or qualify affected periods instead of explaining them away after seeing the result.
    7. Set exposure and rollback conditions. Specify the largest acceptable business loss before launch. If the downside could be material, stage the pause or use a narrower market. Don’t invent the rollback threshold after an uncomfortable result appears.
    8. Declare the observation window. Include enough time for buying cycles, channel switching, and revenue reporting to settle. One documented pause recovered 30% of paid-attributed revenue through organic and direct within six weeks, but that figure rose to 65% by week 13. That is evidence that substitution can lag, not a universal thirteen-week minimum.

    Build the overlap baseline before you pause

    Export Google Ads search terms with their spend and outcomes, then export matching Google Search Console queries and organic clicks for the same dates. Normalize obvious differences such as capitalization and whitespace, but preserve query intent. A brand name, a brand-plus-product query, and a generic category query shouldn’t be collapsed into one row merely because all three contain the company name.

    For each matched query, record paid clicks, paid spend, paid outcomes, organic clicks, and whether a meaningful organic result is present. This gives you a map of expensive overlap. It does not prove cannibalization on its own: customers can still respond differently when both listings appear. The pause provides the causal evidence; the query join tells you where to look and how to interpret the movement.

    Protect the business without protecting the assumption

    A total-account blackout can create unnecessary financial exposure. Choose the largest coherent slice whose potential loss the business can tolerate, while retaining enough volume to produce a useful signal. If a small unit cannot distinguish normal variation from a real effect, acknowledge that limitation or have an analyst assess the design before increasing exposure.

    Monitor competitor activity on branded results during the pause, but don’t treat a competitor impression as proof that your ad is incremental. The relevant outcome is whether the changed results cause a measurable loss in total clicks, conversions, revenue, or contribution. Brand protection can be a legitimate job for paid search; it should be named and valued as protection rather than reported as customer acquisition.

    Measure substitution outside the advertising dashboard
    Customer tokens reroute from a paused paid channel into several other acquisition paths, while some demand disappears before reaching the shared sales destination.

    The moment you pause ads, paid clicks and paid-attributed revenue will fall. That is an implementation check, not the test result. The result is the difference between the total outcome you observed and the total outcome you would reasonably have expected with the ads still running.

    Use a comparable control market or campaign when you have one. Measure how the control changed over the same period, then apply that movement to the test unit’s baseline. This is more defensible than assuming the week before the pause would otherwise have repeated exactly. Without a control, compare against a predeclared baseline and carry the added uncertainty into the decision.

    Calculate the readout in this order:

    1. Estimate the paid-on counterfactual. Determine the total revenue, purchases, or qualified leads you would have expected in the test unit if ads had remained active.
    2. Measure the total incremental loss. Subtract the observed total outcome during the pause from the paid-on counterfactual. This is the business effect attributable to removing the ads, subject to the design’s uncertainty.
    3. Measure channel substitution. Compare organic, direct, and any other plausible substitute channels with their counterfactual levels. Use these movements to explain where demand went, not to override the total-outcome calculation.
    4. Calculate recapture. Divide verified substitute-channel lift by the paid-attributed revenue that disappeared. State clearly which channels were counted and how their counterfactuals were estimated.
    5. Compare incremental value with avoided cost. For a revenue-based view, divide the incremental revenue preserved by the ad spend required to preserve it. For the economic decision, apply the relevant contribution margin and subtract media cost.

    Direct traffic deserves special care. A rise in direct revenue may represent people who saw no ad and typed the address, customers returning through bookmarks, or a change in how analytics classified the visit. The first two can be genuine substitution; the third is measurement reclassification. Look for timing, market specificity, and corresponding stability in total business outcomes before counting the entire increase as recaptured demand.

    The same caution applies to organic traffic. More organic clicks after a pause are persuasive when they occur on the affected queries, in the affected market, during the declared window, and alongside the expected loss of paid clicks. A sitewide organic increase caused by an unrelated SEO release shouldn’t be credited to paid-search substitution.

    What a delayed recapture looks like in practice

    One company paused branded search in the United States, United Kingdom, Australia, and Canada, then paused most non-brand paid search by the end of the month. Its prior spend across branded search, non-brand search, Shopping, and Performance Max averaged $113,000 per month. In one branded campaign, organic already held 71% of overlapping clicks while ads were active, and only $3,945 of $36,129 in spend appeared to purchase clicks that organic could not capture. The remaining $32,184, or 89.1%, functioned as brand defense in that analysis.

    Time after the pauseMonthly organic revenue changeMonthly direct revenue changePaid-attributed revenue recaptured
    Weeks 1-6+$17,800+$14,50030%
    Weeks 7-12+$28,100+$14,10039%
    Week 13 onward+$15,800+$54,00065%

    The important pattern is the delay, not a benchmark you should copy. A six-week read would have made the ads appear much more incremental than the later observation did. The shift toward direct revenue also shows why a paid-versus-organic traffic comparison is too narrow: substitution can cross both channel and attribution boundaries.

    Don’t treat the remaining 35% as automatically incremental. Some of it may be a real paid-search effect, but the strength of that conclusion depends on the counterfactual, controls, tracking, and outside events. Report the observed total loss, the estimated substitute lift, the avoided spend, and the uncertainty separately. A single blended percentage hides the assumptions leadership needs to judge.

    Turn the result into campaign-level budget rules

    An incrementality test should end with a rule someone can execute in the account. “Paid search is incremental” and “brand ads are wasteful” are both too broad.

    • High incremental contribution: retain the tested campaign when the contribution it protects exceeds media cost. Treat expansion as a new hypothesis; the next dollar may not perform like the current dollar.
    • Low incrementality with strong organic substitution: keep the slice paused or reduce it, then monitor organic visibility, total query clicks, revenue, and competitor pressure. Define the conditions that would trigger a retest or restart.
    • Dependent organic performance: manage paid and organic as a combined search system. Investigate which queries lost total clicks or outcomes rather than assuming that an organic ranking alone guarantees replacement.
    • Primarily defensive value: label the budget as brand protection. Decide whether the measured conversion or revenue loss justifies that protection instead of letting attributed ROAS disguise it as acquisition.
    • Uncertain result: don’t force a binary decision. Restore only what is required by the predeclared guardrail, improve the control or measurement, and run a better-bounded test.

    Keep a permanent test record containing the hypothesis, test and control units, campaign changes, baseline dates, primary outcome, rollback rule, exclusions, calculation method, and final decision. Revisit the rule when organic visibility changes, competitors become more aggressive, margins shift, tracking changes, or the campaign begins serving a materially different mix of queries.

    Your next step is to choose one material but reversible slice of paid search. Write its counterfactual, export the paid-organic overlap, lock the business guardrail, and schedule the readout far enough beyond the pause to observe substitution. If the spend returns, it should return with a clear job description: acquisition, channel support, or brand defense. If it doesn’t, you can redirect the budget toward demand you weren’t already positioned to capture.

    References


  • Google Analytics Attribution Windows: How to Choose the Right Fit

    Google Analytics Attribution Windows: How to Choose the Right Fit

    Your campaigns may not be underperforming. Your attribution window may simply be cutting off conversions before your customers finish deciding.

    Google Analytics now gives you much finer control over that cutoff. The useful question isn’t whether you should choose a longer window. It’s which window reflects the conversion you’re measuring, the interaction you’re crediting, and the decision you need the report to support.

    What an attribution window actually changes

    An attribution window, also called a lookback window, defines how long an advertising interaction remains eligible to receive credit for a later conversion. If the conversion occurs after the selected window closes, that interaction no longer qualifies for credit under that setting.

    The window changes attribution eligibility. It doesn’t create or remove the customer’s action, accelerate the buying process, or prove that an ad caused the conversion. That distinction matters whenever a settings change makes campaign results appear better or worse.

    Don’t confuse the window with the attribution model. The window determines which interactions are recent enough to qualify. The model determines how credit is handled among eligible interactions. A model can only work with the interactions admitted by the window.

    A longer window keeps delayed conversions eligible for longer. That can increase the number of conversions associated with advertising interactions, especially when buyers take time to research, compare, seek approval, or return later. A shorter window applies a stricter recency standard, but it can exclude advertising interactions that genuinely began the decision process.

    Neither direction is automatically more accurate. A long window can sweep distant interactions into the report even when their practical influence is uncertain. A short window can make longer consideration journeys disappear from campaign reporting. Your job is to choose the cutoff that makes the report useful for a defined decision.

    Choose the window from the conversion backward

    A conversion platform at the end of a winding customer path, with translucent arcs extending backward across several generic decision moments.

    Start with the event being counted, not the platform’s maximum setting. A form submission, account registration, purchase, and completed contract represent different points in a customer journey. Their normal delays from ad interaction can be very different.

    Define the event before estimating its delay

    If Google Analytics records a lead form as the conversion, select a window for the time between the advertising interaction and that form submission. Don’t silently base it on the later time required to close the sale. Conversely, if the recorded conversion is an imported final outcome, the relevant delay extends to that final outcome.

    Write a one-sentence definition for every conversion you optimize toward: what happened, when it is recorded, and what business decision it informs. This prevents teams from debating window length while referring to different endpoints.

    Use observed decision lag, not a convenient preset

    Look for the elapsed time between relevant ad interactions and the conversion event. Use the evidence available in your analytics paths, ecommerce records, lead timestamps, or customer system. You are looking for the ordinary shape of the delay: whether conversions cluster soon after interaction, continue arriving gradually, or commonly require a longer decision period.

    Then choose the shortest window that still represents the normal journey you intend to measure. This is a decision rule, not a universal benchmark. It keeps the setting tied to customer behavior while limiting credit from interactions so old that their relevance becomes difficult to defend.

    When evidence is thin, don’t hide the uncertainty behind the maximum available value. Pick a defensible starting point, document why you chose it, and treat the setting as a measurement assumption to validate.

    Decide separately for clicks and engaged views

    Click-through and engaged-view conversions begin from different types of advertising interaction, so they shouldn’t inherit the same window without examination. Ask what each interaction represents in your campaign and how long it can reasonably remain relevant to the measured action.

    • For click-through conversions, examine the delay from an ad click to the defined conversion event.
    • For engaged-view conversions, examine the delay from the qualifying view engagement to the same event.
    • If the two paths show different timing, use different windows. Symmetry is not a measurement goal.
    • If stakeholders disagree, make the assumption explicit rather than blending the two interaction types into one unexplained rule.

    Configure the custom windows without defaulting to the maximum

    Google Analytics now accepts any whole-number lookback value within the supported range. That removes the need to force your buying cycle into a small menu of presets.

    Conversion typeCustom rangePrevious limitation
    Engaged-view conversion1 to 30 daysFixed 3-day window
    Click-through conversion1 to 90 daysPreset choices of 1, 7, 14, 30, 60, or 90 days

    In Google Analytics, go to Advertising > Conversion management > Settings. The controls are also available through the conversion management interface in linked Google Ads. Because both surfaces can be involved in campaign measurement, review the active values where your team actually manages conversions rather than assuming everyone is looking at the same configuration.

    1. Inventory the conversions used in reporting, bidding, or budget decisions.
    2. Define the exact customer action represented by each conversion.
    3. Review the observed delay for click-through and engaged-view interactions separately.
    4. Select a whole-day value within the applicable range.
    5. Record the previous value, the new value, the change date, the evidence used, and the owner of the decision.
    6. Check dashboards, recurring reports, and campaign reviews that may be affected by the new eligibility cutoff.

    Resist setting click-through to 90 days and engaged-view to 30 days merely because those values capture the most possible credit. Maximum inclusion isn’t the same as accurate attribution. The right value is the one you can explain in terms of the conversion event and the customer’s normal decision time.

    Evaluate the change without mistaking attribution for growth

    A fixed group of glowing conversion spheres surrounded by adjustable colored pathways that redistribute credit without changing the total number of outcomes.

    A window change can move reported campaign performance even when customer demand and campaign execution haven’t changed. Treat the configuration change as a break in measurement continuity.

    Annotate the effective date in your reporting workflow. When comparing periods, disclose whether both periods used the same window. If they did not, a difference in attributed conversions may reflect the eligibility rule rather than a change in campaign quality.

    Recent conversion cohorts also need time to mature. The longer the selected window, the longer an interaction can remain eligible for a delayed conversion. A click tracked under a 90-day window can continue receiving eligible conversion credit for far longer than one tracked under a short window. Don’t judge the newest cohort as complete while that opportunity remains open.

    Use a controlled review process:

    • Keep a record of the configuration change so analysts can distinguish it from campaign edits.
    • Compare the observed conversion-delay pattern with the window you selected. Conversions accumulating near the cutoff deserve scrutiny because the setting may be truncating a meaningful part of the journey.
    • Inspect click-through and engaged-view results independently before combining them in a campaign conclusion.
    • Ask whether any apparent gain comes from more customer actions or simply from allowing older interactions to qualify.
    • Revisit the choice when the conversion definition, buying process, campaign format, or reporting objective changes.

    The strongest internal test is explainability. A stakeholder should be able to ask, “Why does this interaction still deserve credit?” and receive an answer grounded in the conversion event and observed journey, not in a desire to preserve reported return.

    Key takeaways

    • An attribution window controls how long an ad interaction remains eligible for conversion credit; it does not prove causation.
    • Choose the window for the conversion event actually recorded, not for a later business outcome that Analytics isn’t measuring as that conversion.
    • Google Analytics supports custom click-through windows from 1 to 90 days and custom engaged-view windows from 1 to 30 days.
    • Clicks and engaged views represent different interaction paths, so evaluate their timing separately.
    • Document every window change because it can alter reported attribution without any underlying change in customer behavior.
    • Use the shortest defensible window that captures the normal decision journey, then validate it against observed conversion delay.

    Before your next campaign review, list the conversion actions that influence spend and write down the active window beside each one. Any value your team can’t connect to a defined event and an observed decision lag is the first setting to revisit.

    References


  • Campaign Manager 360 Real-Time Reporting API Guide

    Campaign Manager 360 Real-Time Reporting API Guide

    You need Campaign Manager 360 performance data inside a dashboard while someone is still looking at the screen. The traditional create-run-poll-download workflow can do the reporting, but it makes an interactive product carry the machinery of a batch job.

    The reportData.query endpoint gives you a shorter path: describe the data you need in the request and receive structured JSON synchronously. That can simplify dashboards and ad-hoc analysis considerably. It does not mean every reporting workload should move, nor does the word “real-time” guarantee that every underlying metric is updated instantly.

    The reporting flow is now a direct request-response path

    The traditional Campaign Manager 360 reporting flow is built around generated reports. Your application creates a Report resource, runs it, polls until processing finishes, and downloads the resulting file. That sequence remains useful when the file is part of the deliverable, but it introduces several states that an interactive application must manage.

    1. Create or identify the report configuration.
    2. Start the report run.
    3. Poll for completion.
    4. Download and parse the generated CSV or Excel file.
    5. Transform the result into the shape required by your interface or analysis.

    With reportData.query, developers can instead specify dimensions, metrics, and filters in the request body and receive structured JSON in the response. You do not have to create a Report resource before asking for the data.

    1. Define the dimensions that determine the result’s grain.
    2. Select the metrics needed by the dashboard or analysis.
    3. Apply filters that keep the request focused.
    4. Submit the synchronous query.
    5. Map the returned JSON into your application’s data model.

    The practical gain is not simply fewer API calls. Your application no longer has to model a report job, persist its status, poll it, retrieve an artifact, and parse that artifact before it can show a result. For a user-driven dashboard, removing that orchestration can make both the code and the experience easier to reason about.

    Keep the distinction precise, though: reportData.query simplifies the retrieval path. It does not make the Reports service obsolete, remove the need for a reporting data model, or turn an unfocused query into a fast one.

    Choose the endpoint by workload, not by which API is newer

    Two data-reporting routes show a short interactive query path beside a larger multistage batch-processing path.

    The clearest implementation decision is based on how the result will be consumed. Use reportData.query when a person or application needs a structured answer immediately. Keep the Reports service when the workload is large, scheduled, or expected to produce a downloadable file.

    Decision factorreportData.queryReports service
    Interaction modelSynchronous request and responseCreate, run, poll, and download
    Response formatStructured JSON in the API responseGenerated CSV or Excel file
    Best fitInteractive dashboards, real-time reporting experiences, and ad-hoc analysisLarge datasets, scheduled reporting, and file-based workflows
    ConfigurationDimensions, metrics, and filters are supplied directly with the queryA Report resource defines the report before retrieval
    Execution considerationA query can run for up to 60 secondsCompletion is handled as an asynchronous report job

    Four questions usually settle the choice:

    • Is a person waiting for the answer? A dashboard refresh, filtered table, or investigative view is a strong candidate for reportData.query.
    • Is the output itself a CSV or Excel deliverable? Keep the Reports service rather than retrieving JSON only to recreate the same file workflow.
    • Is this a large or scheduled extraction? The existing Reports service remains the preferred route.
    • Does the same system have both interactive and batch needs? Use both paths. A hybrid architecture is a deliberate workload split, not an incomplete migration.

    This prevents a common architectural mistake: replacing a sound batch process merely because a more convenient interactive endpoint exists. The new endpoint solves a different access pattern. It should take over the requests that benefit from synchronous JSON while the Reports service continues handling work that benefits from generated files and asynchronous execution.

    Design interactive queries that remain useful under pressure

    A direct endpoint removes report-job ceremony, but your dashboard still needs a disciplined query layer. The following design choices determine whether reportData.query feels responsive and trustworthy in production.

    Start with the user’s question, not every available field

    Define one question for each dashboard component. A campaign summary, a filtered placement table, and a diagnostic drill-down do not need to share one universal request. Give each component the smallest dimension grain, metric set, and filter scope that answers its question.

    Write down a compact query contract before implementation:

    • The decision or question the result supports.
    • The dimensions that determine what one result row represents.
    • The metrics the interface will actually display or calculate with.
    • The filters controlled by the application and the filters controlled by the user.
    • The behavior the user sees while the request is running.
    • The fallback shown when the request cannot return a usable result.

    This contract helps you notice accidental scope growth. If a new chart needs a different grain, give it a separate query rather than quietly expanding an existing request and making every dashboard refresh carry the extra work.

    Treat 60 seconds as a ceiling, not a target

    The endpoint allows queries to run for up to 60 seconds. That accommodates meaningful interactive analysis, but a dashboard can still feel broken long before the request reaches its limit.

    Design the interface for a genuinely synchronous operation. Show a clear loading state, keep unrelated controls usable, and decide what happens if the request takes longer than the user’s workflow can tolerate. Where appropriate, retain the last successful result and label it as such rather than replacing useful data with an indefinite spinner.

    Do not hide a consistently slow query behind a longer loading message. Narrow its dimensions, metrics, or filters. If the workload is inherently large rather than accidentally broad, route it to the Reports service.

    Do not equate synchronous retrieval with instant measurement

    “Real-time” describes the reporting access pattern here: your application submits a query and receives data directly instead of waiting for a generated report file. That alone does not establish how quickly every underlying campaign event becomes available as a reportable metric.

    If freshness affects an operational decision, verify it for the dimensions and metrics you use. Give the dashboard an “as of” indicator based on information your implementation can substantiate, and avoid labels such as “live” or “instant” unless you have validated what those words mean for that view. This keeps a faster retrieval method from creating a stronger freshness promise than the data supports.

    Put a stable adapter between CM360 and the interface

    Structured JSON is easier to consume than a downloaded file, but your UI should not become a direct reflection of a vendor response. Map the response into an internal model with names and types that make sense to your application.

    • Keep the API request definition in one reporting layer rather than duplicating it across dashboard components.
    • Validate that the returned structure contains what the component needs before rendering it.
    • Centralize metric labels and formatting so the same measure is not presented differently across views.
    • Record the query definition alongside operational logs so a bad result can be traced to its dimensions, metrics, and filters.
    • Version your internal contract when a dashboard changes its grain or meaning.

    This adapter also preserves your options. The UI can consume one internal shape even if some views use reportData.query and other data arrives through the Reports service.

    Separate no data, zero, slow, and failed

    These states can look similar in an empty chart, but they mean different things:

    • No matching data: the selected dimensions and filters produced no rows.
    • Measured zero: the query returned a legitimate result whose displayed metric is zero.
    • Still running: the application has not received the synchronous response yet.
    • Failed request: the application cannot present the requested result.
    • Last successful result: a previous result remains visible while its replacement is unavailable.

    Model and label these states explicitly. Otherwise, an API problem can be mistaken for campaign performance, or an empty filter result can be presented as a technical failure.

    Also control how often the interface sends requests. Trigger queries on deliberate actions, avoid submitting a new request for every unfinished input change, and reuse identical results for an appropriate period when your freshness requirements permit it. The right reuse period is a product decision; the existence of a synchronous endpoint does not require every screen interaction to generate a new API call.

    A low-risk rollout keeps the batch path intact

    Parallel reporting pipelines pass through a controlled traffic junction and comparison stage, with a return route to the established batch system.

    You do not need to redesign the entire reporting stack to benefit from reportData.query. Start with one view where report creation, polling, or file parsing is clearly getting in the way of an interactive experience.

    1. Inventory the current flow. Identify where the application creates the Report resource, starts the run, polls, downloads the file, parses it, and transforms it for display.
    2. Classify the use case. Confirm that a person or interactive application needs the result directly. Leave scheduled, large, and file-based jobs in the Reports service.
    3. Write the query contract. Specify the exact dimensions, metrics, filters, expected result grain, loading behavior, and failure behavior for the selected view.
    4. Build the response adapter. Convert the returned JSON into the internal shape already expected by the interface, or introduce a stable model that both reporting paths can use.
    5. Verify meaning, not just transport. Compare the new view with the existing reporting output for the same requested scope. Investigate differences before assuming that receiving JSON means the migration is complete.
    6. Exercise the slow and empty paths. Confirm that the interface remains understandable if a query runs for a substantial part of the allowed window, returns no matching data, or fails.
    7. Switch only the interactive read path. Keep existing scheduled reports and downloadable exports running until there is an independent reason to change them.

    Measure the rollout by what it removes from the interactive path: report-resource management, polling, file retrieval, and parsing. Do not judge it by how much legacy reporting code you can delete. If that code still supports a valid batch workload, retaining it is the correct design.

    Campaign Manager 360 reporting API FAQ

    Is reportData.query a streaming API?

    No. Its documented interaction is a synchronous query that returns structured JSON. Your application requests a defined result; it is not described as subscribing to a continuous stream of campaign events.

    Does “real-time reporting” mean every metric is instantly current?

    Not on the evidence available for this endpoint. The direct synchronous response removes the generated-report workflow, but that does not by itself define the freshness of every underlying metric. Validate freshness for your use case before making a user-facing promise.

    Should an existing Reports service integration be migrated completely?

    No. Keep the Reports service for large datasets, scheduled jobs, and workflows that require CSV or Excel downloads. Move only the interactive and ad-hoc requests that benefit from direct JSON.

    What is the best first use case?

    Choose one narrowly scoped dashboard view whose user currently waits for a report job or whose implementation exists mainly to download and parse a file. Define its dimensions, metrics, and filters; build the JSON adapter; then compare its output with the established reporting path before expanding the rollout.

    Your next step is small and concrete: identify one interactive report, write down the exact question it answers, and determine whether a synchronous query can answer it within the endpoint’s 60-second window. If it can, migrate that read path. If it is fundamentally a large export or scheduled artifact, leave it where it belongs.

    References


  • YouTube and Discover Ad Updates: A Practical Action Plan

    YouTube and Discover Ad Updates: A Practical Action Plan

    If you manage YouTube or Discover campaigns, the dangerous mistake is to treat every Google update as a campaign change. In this case, one update changes how requirements are written; another changes what Merchant Center counts and where it places traffic. Only the second should alter your reporting workflow.

    That distinction matters because a dashboard can move even when audience demand and campaign delivery have not. Separate policy status from measurement changes before you edit creative, adjust budgets, or explain a sudden performance swing.

    Key takeaways

    • Google characterizes the YouTube and Discover Feed requirements update as an editorial rewrite with no new requirements or enforcement changes.
    • Merchant Center reporting changes scheduled to begin rolling out on August 24 affect traffic classification, organic YouTube measurement, and the campaign data included in product-level reports.
    • You may see a one-time decline in reported organic traffic, while product impressions and clicks may increase because reporting coverage is expanding.
    • Historical data back to July 1 will be revised for the YouTube affiliate classification, so a live report may no longer reproduce an export created under the previous logic.
    • Annotate the reporting transition, update dashboard definitions, and validate real delivery and business outcomes before changing spend.

    The policy page changed, but the approval standard did not

    Google revised the language and formatting of its YouTube and Discover Feed ad requirements to make them easier to interpret. It says the revision does not add requirements or change enforcement. There is no policy-driven campaign rebuild to perform solely because the page now reads differently.

    That does not make the page irrelevant. Clearer wording can help you catch an existing compliance problem during routine creative review. The important distinction is that better documentation may improve your understanding of an old rule; it does not, by itself, create a new rule.

    1. Check the actual approval, limitation, and delivery status of your ads. Account-level evidence matters more than the fact that a requirements page was reformatted.
    2. If status and delivery are unchanged, do not rewrite or resubmit approved creative solely in response to the editorial update.
    3. Use the clarified requirements during your normal prelaunch review. Compare each asset and its destination with the applicable requirement, just as you would have before the rewrite.
    4. If an ad becomes limited or disapproved, investigate the policy reason attached to that ad. Do not assume the documentation update caused the decision.
    5. Record any interpretation your team changes after reading the clearer wording. That creates a usable internal rule for future briefs without falsely labeling it as a new Google requirement.

    This approach prevents two expensive reactions: unnecessary creative work and budget changes made in response to a policy event that did not occur.

    Merchant Center numbers may move without performance moving

    A steady flow of shoppers and parcels continues below data tokens being redistributed between reporting containers.

    The Merchant Center update is different because it changes reporting definitions and coverage. Treat it as a measurement transition, not a documentation cleanup.

    YouTube affiliate traffic gets its own category

    Traffic generated by YouTube creators participating in Google’s affiliate program is moving out of Organic and into a separate YouTube affiliate category. The platform will also revise historical data back to July 1 to apply the new classification.

    A decline in Organic can therefore be a transfer between reporting buckets rather than a loss of traffic. Look for the newly separated YouTube affiliate category before concluding that free listings or creator-driven discovery weakened.

    Do not expect a simple equation in which old Organic always equals new Organic plus YouTube affiliate. Google is also revising how organic YouTube clicks and impressions are measured so that Merchant Center aligns more closely with YouTube’s definitions. That second change can reduce reported organic activity independently of the affiliate reclassification.

    Product-level reporting gains broader paid coverage

    Merchant Center product performance reporting is expanding to include data from all Google Ads channels and formats, including Performance Max, Video, App, and Demand Gen campaigns. Broader coverage can produce a one-time increase in reported impressions and clicks even if your campaigns did not suddenly scale.

    The practical question is not simply whether a metric rose. Ask whether more campaign formats are now contributing to that metric. A coverage increase and a performance increase can appear identical in a top-line chart, but they require completely different decisions.

    Google also plans to add a Network reporting dimension so merchants can eventually segment results by Google network in a way that resembles Google Ads. Treat that as planned functionality until it is actually available in your account; do not build a current reporting commitment around a future dimension.

    Build a reporting bridge across the August 24 rollout

    An analyst stands on a bridge of linked data checkpoints connecting two differently organized analytics systems.

    A reporting bridge documents what changed, when it changed, and which comparisons remain valid. It protects you from turning a measurement artifact into a real campaign intervention.

    1. Add an August 24 annotation to every Merchant Center dashboard that uses organic YouTube traffic or product-level Google Ads data. Label it as the start of the rollout, not necessarily the exact switch time for every account.
    2. Preserve existing exports where available. Include the queried date range, export date, filters, dimensions, and metric definitions. Because data back to July 1 is being revised, the export date is part of the evidence.
    3. Create separate definitions for Organic, YouTube affiliate, and paid product traffic. If an executive dashboard combines them, retain the components underneath the combined figure so that a transfer between categories remains visible.
    4. Review formulas, filters, automated alerts, and scheduled reports. An alert based on an Organic decline or an impression increase may fire because the underlying classification or coverage changed.
    5. Do not splice old-logic and new-logic values into an unlabeled trend line. Use separate series, a visible transition marker, or a restated baseline so readers know that the comparison crosses a definition change.
    6. Validate any apparent gain or loss against campaign delivery and your business outcomes before changing bids, budgets, or creative. A reporting discontinuity alone is not evidence that the campaign improved or deteriorated.

    If you do not have a pre-change export, do not manufacture a precise bridge from incomplete data. Mark history from July 1 as restated, document the current definitions, and establish a new baseline. An honest break in the series is more useful than a smooth chart built from incompatible numbers.

    Read the reporting pattern before changing spend

    What you seeLikely explanation to test firstWhat to do before acting
    Organic traffic falls as YouTube affiliate traffic appearsCreator affiliate traffic moved into its own categoryCompare the two categories together, then isolate any remaining difference
    Organic YouTube clicks or impressions fall beyond the affiliate transferOrganic YouTube measurement was revised to align more closely with YouTube definitionsCompare periods calculated under the same definition and annotate the break
    Product impressions or clicks rise after the rolloutPerformance Max, Video, App, or Demand Gen data may now be includedCheck campaign-format coverage before describing the movement as growth
    The requirements page looks different while ad status stays the sameThe policy documentation received an editorial rewriteContinue normal compliance review without rebuilding the campaign
    An ad becomes limited or disapprovedThe editorial rewrite alone does not establish a new enforcement causeInspect the specific policy status and affected asset before making changes
    You need a network-level Merchant Center breakdownThe announced Network dimension may not be available yetUse currently available channel reporting and wait for the dimension to appear in the account

    Before your next performance review, update the data dictionary, add the rollout annotation, and give stakeholders a short note explaining which series were reclassified or expanded. Then keep campaign settings stable unless delivery or business results provide a separate reason to act. That is how you prevent Google’s reporting cleanup from becoming an avoidable optimization mistake.

    References


  • Google’s Mobile Search Ad Test: A Practical Response Plan

    Google’s Mobile Search Ad Test: A Practical Response Plan

    If you manage paid search, Google’s mobile ad presentation test creates an awkward question: should you change campaigns now, or wait until the format becomes more than an isolated experiment? The right answer is to prepare the brand elements the layout exposes, preserve your measurement baseline, and avoid auction-level changes that the available evidence cannot justify.

    The test changes what a mobile searcher may notice first. That could matter for recognition and trust, but it does not yet establish a new campaign rule. Your immediate job is to separate the visible interface change from the performance effects you can actually demonstrate.

    The test adds an identity layer before the ad copy

    In the observed mobile layout, Google places a list of advertisers, including their favicons and domain names, at the top of a sponsored-results block. The individual ads appear below that list. A searcher therefore encounters the participating companies before reaching the first complete ad.

    That is more than a cosmetic rearrangement. The standard ad-reading sequence starts with a specific advertiser’s message. This test inserts a preliminary identity check: which companies are present, which ones look familiar, and which domains appear credible enough to consider.

    Three practical implications follow, although none has been proven as a performance outcome:

    • Recognition may arrive before relevance. A familiar favicon or domain could attract attention before the searcher compares headlines and descriptions.
    • Unfamiliar advertisers may face a sharper trust test. If your domain does not clearly map to your brand, the user may have little reason to remember you when the full ad appears.
    • Ad copy remains important, but it may no longer make the first impression. The advertiser list can frame the choice set before any individual value proposition is read.

    Do not turn those possibilities into conclusions. The test does not show that recognized brands will necessarily gain clicks, that unfamiliar brands will lose them, or that inclusion in the list conveys an endorsement. It only gives you a credible set of hypotheses to examine.

    Treat this as a presentation test, not a new campaign rule

    Google has not publicly explained the experiment, and it remains unclear whether the layout will move beyond limited testing. That uncertainty should govern your response. A screenshot is evidence that a format exists; it is not evidence that your account is consistently exposed to it or that the format changed your results.

    Use this response sequence if someone on your team encounters the layout:

    1. Capture the entire mobile results block. A cropped advertiser row is not enough to understand its position relative to the Sponsored results label, individual ads, and nearby organic results.
    2. Record the observation context. Save the query, date and time, market, device type, browser, and whether the search was performed while signed in. These details will not reveal Google’s test assignment, but they make repeated observations comparable.
    3. Check whether the layout appears again under controlled conditions. Look for a pattern across relevant queries and devices. Do not treat one person’s result as universal.
    4. Annotate the observation in your reporting. Keep it separate from campaign launches, budget changes, promotional periods, landing-page releases, and other events that could affect performance.
    5. Delay structural campaign changes. Bids, budgets, match types, targeting, and creative rotation all introduce new variables. Changing them in response to an unconfirmed interface test makes later diagnosis harder.

    The distinction is simple: prepare for the format where preparation is low-risk, but require performance evidence before altering how you buy traffic.

    Audit the two brand assets users may see first

    A specialist compares a circular identity mark and a rectangular brand image in small mobile interface previews.

    The observed advertiser list emphasizes two compact identity cues: the favicon and the domain. You can review both without rebuilding a campaign or assuming the experiment will become permanent.

    • Inspect the favicon at a genuinely small size. A detailed logo can become an indistinct shape when reduced. Look for strong contrast, a recognizable silhouette, and freedom from tiny text that disappears on a phone.
    • Check the domain as a brand signal. Read the domain without the surrounding ad. It should be easy to associate with the company a user expects to find. Document confusing abbreviations, legacy names, unexpected subdomains, or other mismatches before deciding whether any change is warranted.
    • Compare identity across the journey. The favicon, domain, ad language, and landing-page branding should feel like parts of the same company. A mismatch can be especially costly when a compact advertiser list prompts users to evaluate identity before the offer.
    • Review ad differentiation after the identity check. Once the user reaches the full ads, your message still needs to explain why your option fits the query. Brand recognition cannot substitute for a relevant proposition.
    • Make landing-page verification immediate. An unfamiliar advertiser should not force visitors to hunt for the company name, product relationship, or reason to trust that they reached the intended destination.

    Keep this audit within its proper scope. Nothing disclosed about the experiment establishes that JSON-LD, organic structured data, or an SEO schema change controls the advertiser list. Do not modify markup merely because the interface displays a favicon and domain. That would connect two systems without supporting evidence.

    Measure the effect without confusing visibility with causality

    Two identical smartphones display generic ad layouts with and without an identity layer, separated for controlled comparison.

    The central measurement problem is exposure. Unless Google identifies test participation in reporting, you may know that the layout was observed without knowing which impressions used it. Any account-level analysis is therefore directional, not a clean experiment.

    Build the analysis around the part of the journey the layout can plausibly influence:

    1. Preserve a baseline. Retain mobile performance from a comparable period before the first confirmed observation. Use a window long enough to reflect your normal buying cycle rather than selecting dates because they produce a convenient result.
    2. Separate mobile from desktop. The observed format is a mobile Search test. A blended device report can hide a mobile movement or incorrectly attribute an account-wide change to the layout.
    3. Split branded and non-branded intent. Brand recognition is one of the clearest hypotheses created by the advertiser-first presentation. If branded and non-branded queries move differently, that difference deserves investigation.
    4. Start with click-through rate, then follow the click. Presentation acts before the visit, so CTR is the nearest directional signal. Conversion rate, cost per acquisition, return on ad spend, and lead quality tell you whether any additional clicks were commercially useful.
    5. Use stable comparisons where possible. Compare query groups, markets, or campaigns with similar conditions rather than placing all traffic in one before-and-after total. A comparison is useful only if it was not changed by a different promotion, bid strategy adjustment, budget constraint, or creative release.
    6. Keep a confounder log. Record every material account and site change during the observation period. Without that log, a mobile CTR shift can easily be credited to the interface when a new ad, offer, competitor, or landing page changed at the same time.

    Interpret patterns conservatively. A mobile CTR increase while desktop remains stable would be consistent with a mobile presentation effect, but it would not prove one. A larger branded than non-branded shift would fit the recognition hypothesis, but other brand activity could produce the same pattern. If clicks rise while conversion quality weakens, the format may be attracting attention without improving intent. If nothing meaningful changes, the correct action may be no action at all.

    Only consider campaign changes after you can state the decision rule in advance. For example: if a repeatable mobile-only movement persists while comparable traffic remains stable, review creative or budget allocation in the affected segment. Defining the rule first prevents ordinary volatility from becoming a story after the fact.

    Key takeaways for paid search teams

    • Google’s test places advertiser favicons and domains before the individual mobile Search ads, potentially changing the first cue a user evaluates.
    • The format remains a limited experiment with no confirmed broad rollout, so one sighting should not trigger changes to bids, budgets, targeting, or campaign structure.
    • Audit favicon legibility, domain recognition, ad-to-landing-page consistency, and message differentiation now because those checks are useful even if the test ends.
    • Measure mobile separately, preserve branded and non-branded segments, and treat CTR as an early signal rather than the final business result.
    • Do not assume structured data or schema markup controls the paid advertiser list; no such connection has been established.
    • Without impression-level test identification, performance analysis can support a hypothesis but cannot cleanly prove causation.

    Your next move should be small and reversible: document any sightings, complete the favicon-and-domain audit, and protect a clean performance baseline. If the presentation expands, you will be ready to measure it. If it disappears, you will not have disrupted a working account in pursuit of a temporary interface.

    References


  • Google Campaign Data Import Validation: A Practical Workflow

    Google Campaign Data Import Validation: A Practical Workflow

    You have a cross-channel dashboard ready for review, but some campaign numbers arrived through an import rather than Google’s native collection. The dangerous failure may not look like an error. A campaign can appear in the report while its cost, clicks, or impressions are absent, leaving a dashboard that looks complete enough to trust.

    Google’s Campaign Data Import Validation Report gives you a quality-control checkpoint. It reviews non-Google campaign data and previously imported data, then highlights campaigns that may be missing cost, clicks, or impressions. The practical move is to treat this validation as a release gate for reporting, not merely as a troubleshooting screen.

    Read each result as a completeness warning

    The validation report is designed to help answer a narrow but important question: are essential reporting fields missing from imported campaign data? It does not remove the need to determine why a field is absent or whether a populated value is correct.

    Keep three data states separate:

    • Present and correct: the imported value agrees with the originating platform for the same campaign and reporting window.
    • Present but incorrect: the field contains a value, but a mapping, transformation, unit, scope, or duplication problem changed its meaning.
    • Missing: the import contains no usable observation for a field that should have been supplied.

    The validation report is especially useful for finding the third state. Do not automatically convert it into the first by replacing a missing field with zero. Zero means the platform recorded none of the activity being measured. Missing means you do not yet have a usable value. Treating those states as interchangeable can understate totals and make derived performance metrics look valid when they are not.

    Missing fieldWhat becomes unreliableFirst question to ask
    CostSpend totals and cost-based efficiency metricsDid the source export contain spend in the expected unit and column?
    ClicksClick totals, cost per click, and click-through calculationsWas the source click field mapped to the imported click field?
    ImpressionsExposure totals, click-through rate, and impression-based cost metricsWas the impression field included for the same campaign and date range?

    Run validation before the dashboard is released

    A report that is checked after executives or clients have acted on it is an incident review, not a control. Put validation between the import and the reporting handoff.

    1. Define the expected scope. Record the non-Google platforms, accounts, campaigns, and reporting window that the import is supposed to cover. Without an expected set, an omitted campaign can remain invisible because there is nothing to compare against.
    2. Complete the import. Keep the import run, date range, and source files identifiable so that a flagged result can be traced back to the data that produced it.
    3. Review the validation report. Identify campaigns with missing cost, clicks, or impressions. Include previously imported data in the review when it remains part of the reporting period.
    4. Create an exception record. For every unresolved campaign, capture the platform, campaign, missing field, reporting window, owner, cause, and planned reporting treatment.
    5. Repair the earliest broken layer. Correct the source extract, field mapping, transformation, or import scope instead of typing a replacement value into the final dashboard.
    6. Import the corrected data and validate again. A change is not complete merely because the pipeline ran without an operational error. Confirm that the original warning has been resolved.
    7. Reconcile against the originating platform. Compare campaign coverage and totals for the same reporting window before approving the dashboard.

    Your pass condition should be explicit. Every expected campaign should either contain the applicable metrics or have a documented exception explaining why a metric is unavailable and how the campaign will be handled. If a platform genuinely does not provide a particular field, record that limitation rather than manufacturing a value.

    Trace a missing metric to the layer that failed

    A cutaway data pipeline shows one amber signal disappearing at a broken connection before the remaining signals reach a dashboard.

    A validation flag identifies the symptom. Diagnose it in pipeline order so you do not waste time fixing a later layer that never received the data.

    1. Check the source extract. Find the affected campaign and reporting window in the exported data. If the metric is absent there, the importer could not have populated it. Correct the export selection or document the source limitation.
    2. Check field mapping. Confirm that the source column for cost, clicks, or impressions maps to the intended destination field. Pay attention to renamed columns and platform-specific labels.
    3. Check transformations. Look for parsing rules, data-type conversions, filters, and blank-value handling that could remove a valid value before loading it.
    4. Check scope. Compare the account, campaign, and date filters used in the extract with those used in the import. A valid metric from the wrong period does not repair the affected reporting window.
    5. Check the load result. Verify that the corrected campaign row reached the imported dataset and that a repeated import did not create an unintended duplicate.

    If several metrics are absent for the same campaign, check row coverage and scope before debugging each field independently. If only one metric is absent while the others are populated, inspect that field’s source column, mapping, and transformation path first. These are diagnostic priorities, not assumptions about the cause.

    Fix the problem where it first appears. A manual patch in a dashboard may repair one visible number while leaving the import pipeline broken for the next refresh.

    A clean validation result still needs reconciliation

    Two sets of campaign data tokens are compared on an analyst desk, with one mismatched pair highlighted beside a complete dashboard.

    Completeness and accuracy are different controls. A populated cost field can still contain the wrong currency, the wrong reporting period, a duplicate value, or data from the wrong campaign. Presence validation cannot establish that the number carries the intended meaning.

    After resolving missing-field warnings, run these checks:

    • Campaign coverage: compare the imported campaign roster with the expected roster from each non-Google platform. Use a stable campaign identifier where one is available; names alone may be ambiguous.
    • Reporting window: confirm that both systems use the same start date, end date, and time-zone treatment.
    • Units and currency: verify that cost values have not been mixed across currencies or transformed into an unexpected unit.
    • Metric definitions: make sure the source field represents the same type of click or impression that your cross-channel report labels. Similar names do not guarantee identical platform definitions.
    • Aggregate totals: compare imported totals with totals from the originating platform for the same scope. Define how documented processing differences or rounding will be handled instead of accepting any unexplained mismatch.
    • Reimport behavior: determine whether a correction replaces, updates, or appends to previous data. Then check for duplication after the corrected load.

    This second control catches an important failure mode: the wrong value in the right field. A fully populated import can pass a completeness check while still producing a misleading channel comparison.

    Key takeaways

    • Use the Campaign Data Import Validation Report to identify non-Google and previously imported campaigns that may be missing cost, clicks, or impressions.
    • Treat a missing metric as unknown until you investigate it. Do not silently convert it to zero.
    • Validate after the import but before the data reaches a decision-making dashboard or recurring report.
    • Repair problems in the source extract, mapping, transformation, scope, or load rather than patching the presentation layer.
    • Reconcile campaign coverage and totals after clearing validation warnings because complete data can still be incorrect.

    For your next reporting cycle, make the handoff require three items: validation status, a list of unresolved exceptions, and confirmation that source totals were reconciled. That turns imported-data quality from an assumption into a control someone must complete.

    References


  • How to Use AI Agents for Google Ads and Analytics Reporting

    How to Use AI Agents for Google Ads and Analytics Reporting

    Your reporting problem probably isn’t a lack of charts. It is the delay between a meaningful change, someone noticing it, and the team deciding what to do. AI agents inside Google Ads and Google Analytics can shorten that interval, but only if you treat their answers as the start of analysis rather than the final verdict.

    The practical goal is a tighter reporting loop: detect the change, ask a precise question, verify the answer in the underlying data, and make a documented decision. That is where these tools can save time without quietly lowering the standard of evidence behind your campaign choices.

    Put the agent in the right role

    Google is moving its reporting assistant beyond passive data retrieval. Ask Advisor can surface performance changes, investigate natural-language questions, recommend next steps, and generate visual reports with explanatory summaries. The advertiser still controls campaign decisions.

    That makes the agent most useful as an analyst interface, not an autonomous media buyer. It can reduce the work required to find a signal and form an initial explanation. It cannot remove the need to establish whether that explanation is complete, whether the comparison is appropriate, or whether the proposed action is commercially sensible.

    • Observation: What changed in the data, for which metric, segment, and period?
    • Interpretation: What might explain the change, and which competing explanations remain possible?
    • Decision: What action, if any, is justified after you verify the observation and interpretation?

    Keep those three layers separate in every report. If Ask Advisor connects competitor pressure with a loss of impression share, for example, that is an interpretation to investigate. Confirm the affected campaigns, date range, comparison period, and magnitude before changing bids or budgets. A plausible explanation is not yet an approved action.

    Ask questions that lead to a decision

    A broad prompt such as “What happened?” invites a broad narrative. You may receive an interesting summary without learning what deserves attention. A stronger question gives the agent a metric, scope, comparison, diagnostic angle, and decision to support.

    Use this structure when you write a prompt: Find the change in [metric] for [scope] over [period], compare it with [baseline], break it down by [segments], test [possible explanation], and show what I should verify before [decision].

    Start in Google Analytics when the question is about user or sales behavior

    Google Analytics homepage AI Overviews are designed to summarize important changes since your previous login. They can call attention to developments such as traffic shifts or seasonal sales spikes, offer possible next steps, and pass a selected insight into Ask Advisor for deeper investigation. In this setting, “AI Overview” means an Analytics account summary, not an AI Overview in Google Search.

    A since-last-login summary is useful for triage, but it is not automatically a sound reporting period. Reframe anything important against the comparison your business actually uses before drawing a conclusion.

    • Which traffic change contributed most to the sales movement highlighted on the homepage? Break the result down by channel and device, and identify any seasonal pattern I should test.
    • Which segment explains the largest part of this change? Show whether the account-wide direction still holds inside that segment.
    • What changed first: traffic volume, user behavior, or the reported business outcome? List the views I should open to verify the sequence.

    Start in Google Ads when the question is about campaign delivery

    The redesigned Google Ads homepage uses personalized AI insight cards, while Ask Advisor accepts natural-language questions about issues such as competitor effects on impression share and trends that could influence campaign performance. Use those cards as an investigation queue, not as a replacement for your normal controls.

    • Which campaigns lost impression share during the relevant period, and does the visible pattern support competitor pressure or another explanation?
    • Which performance change is concentrated in one campaign, device, location, or audience rather than spread across the account?
    • What trend could affect campaign performance next, which current metrics support that possibility, and what evidence would contradict it?
    • Create a visual report for the affected campaigns, include the comparison period, and summarize the largest movement without recommending a budget change.

    If an answer does not identify its metric, scope, comparison, and relevant segment, ask again. The purpose of the follow-up is not to make the wording more polished. It is to make the claim testable.

    Use a three-pass reporting workflow

    Three connected workstations depict an AI detecting a change, an analyst verifying evidence, and a reviewed action being documented.

    The cleanest way to integrate an AI agent is to separate detection, investigation, and approval. This prevents a generated explanation from moving directly into a campaign change simply because it arrived in a confident tone.

    1. Pass one – detect: Review the Analytics overview or Ads insight cards. Select only changes that could affect an active business decision. Do not turn every card into a task.
    2. Pass two – frame: Rewrite the selected insight as a question that could be proven wrong. Replace “Performance fell” with a question about the exact metric, campaign or segment, period, and comparison.
    3. Pass two – investigate: Ask Advisor to break the change into relevant components and explore more than one explanation. Request the views or segments needed to check its reasoning.
    4. Pass two – verify: Open the underlying report. Confirm the date range, filters, comparison period, metric definition, conversion setup, and attribution context where relevant. Check that the movement still exists when you inspect the affected segment directly.
    5. Pass three – decide: Record whether you will act, monitor, or reject the hypothesis. Name the evidence that determined the decision so the same question does not restart at the next reporting meeting.
    6. Pass three – distribute: Google Analytics users can opt in to receive AI-generated summaries through email or mobile notifications. Treat a notification as an invitation to review, not as approval to make a campaign change.

    Use a simple stop rule: if the explanation changes materially when you correct the date range, isolate a segment, or apply the intended comparison, the analysis is not ready for action. Continue investigating or leave the campaign unchanged.

    Budget, bid, targeting, and measurement changes can affect real spend and future reporting. Do not approve them from an AI-generated narrative alone. Verify the relevant platform data and apply your existing account approval process first.

    Build dashboards that preserve context

    Analyst examines a transparent dashboard where one performance signal is linked to time, audience, campaign-change, and comparison context.

    Google Ads Dashboards can be generated from text prompts, with AI producing visual reports and real-time summaries of the trends represented by the charts. Google Analytics support was identified as a later addition, so availability may differ between the two products. If the Analytics option is not present in your account, use Ask Advisor for investigation and keep your established reporting workflow in place.

    A useful dashboard should preserve the path from outcome to diagnosis. Build it in layers so a reader can see what changed before encountering an explanation:

    • Outcome layer: Show the business and campaign metrics tied to the decision the dashboard supports.
    • Change layer: Show the active period beside the intended baseline, using clearly stated date ranges.
    • Diagnostic layer: Break the result down by the dimensions most likely to reveal concentration, such as campaign, channel, device, or location.
    • Interpretation layer: Label confirmed observations separately from AI-generated possible explanations.
    • Decision layer: Keep a note alongside the dashboard stating the owner, chosen action, verification performed, and next review point. Do not imply that this note is created automatically unless your account supports it.

    A practical dashboard prompt might read: Create a visual report for the campaigns connected to this decision. Show the current period and comparison period, break the main outcome down by campaign and device, identify the largest change, and separate observed facts from possible causes in the summary.

    Review every generated dashboard against five questions: Are the dates explicit? Is the scope visible? Are metric definitions understood? Does the summary distinguish correlation from explanation? Can the reader tell which decision the report is meant to support?

    Real-time summaries improve speed, not certainty. If a chart and its narrative appear to disagree, trust neither automatically. Check the chart configuration and underlying report before circulating the conclusion.

    Key takeaways for safer AI-assisted reporting

    • Use Ask Advisor to detect changes, form hypotheses, and accelerate report creation; keep campaign approval with a person.
    • Give every prompt a metric, scope, period, baseline, segmentation request, and decision context.
    • Treat homepage summaries and notifications as triage signals rather than completed analysis.
    • Verify important claims in the underlying Ads or Analytics report before changing spend, targeting, bids, or measurement.
    • Design dashboards to separate observed facts, possible causes, and approved actions.
    • Begin with one recurring reporting decision and a repeatable verification checklist before expanding the workflow.

    At your next reporting session, choose one question your team answers repeatedly. Turn it into a structured Ask Advisor prompt, write down the checks required before action, and use that same sequence for several reporting cycles. Expand only when the agent consistently helps you reach a verified decision faster.

    References


  • Marketing Attribution Blind Spots: What Your Reports Miss

    Marketing Attribution Blind Spots: What Your Reports Miss

    Your campaign report says one channel drove the conversion. That may only mean the channel left the cleanest trail.

    Before you cut, scale, or defend a marketing investment, you need to distinguish three very different situations: the campaign failed, the customer journey was only partly observable, or the measurement plumbing broke. Treat those as the same problem and a precise-looking dashboard can steer your budget in the wrong direction.

    Your dashboard records evidence, not the entire journey

    Attribution works with observable events. An impression, tagged visit, form submission, CRM record, and purchase can be connected only when the necessary data survives each handoff. Anything that happens outside that chain may influence the buyer without receiving credit.

    That creates four common blind spots:

    • Unobserved exposure: Someone encounters your brand or advice without visiting your site.
    • Lost campaign context: The person visits, but an identifier disappears before analytics records it.
    • Disconnected outcomes: Marketing captures a lead, while the eventual opportunity or revenue remains in a separate system.
    • Misread evidence: A visible touchpoint receives credit even though the report cannot establish that it caused the conversion.

    AI discovery makes the first blind spot especially important. A person can read an AI-generated answer, see your company cited or recommended, and get what they need without clicking. They may return later through branded search, direct navigation, or another channel. Page views will show the later visit, if there is one, but they cannot represent the original zero-click exposure. That is why AI citations, share of voice, and revenue need distinct measurement layers.

    Lost campaign context creates a different problem. Google Analytics includes a diagnostic for URLs missing aggregate identifiers such as GBRAID and gad_. Those parameters matter to attribution in a privacy-focused measurement environment, and their absence can reduce campaign attribution accuracy. A campaign can therefore appear weaker because its evidence was dropped, not because its audience stopped responding.

    The practical distinction is simple: invisible influence calls for broader measurement, while missing identifiers call for a technical repair. Neither should be interpreted as campaign underperformance until you know which one you are dealing with.

    Measure visibility, visits, and business outcomes separately

    Three connected spaces show a beacon reaching a crowd, visitors entering a corridor, and customers completing purchases and consultations.

    A useful attribution view has three layers. Each answers a different question, and none can substitute for the others.

    LayerQuestion it answersEvidence to collectWhat it cannot prove
    AI visibilityDoes your brand appear in relevant generated answers?Mentions, citations, recommendations, answer position, tracked-query share of voiceThat a person visited, bought, or was persuaded
    TrafficDid an observable visit reach your site?Referral sessions, tagged links, landing pages, assisted paths, campaign identifiersThat every exposure produced a click or that the visit caused the outcome
    Business outcomesDid demand become something valuable?Leads, qualified opportunities, purchases, revenue, renewals, and CRM source evidenceWhich earlier touch deserves causal credit when the path is incomplete

    Define AI visibility against a fixed question set

    Do not report a vague claim such as “our AI visibility improved.” Build a query set from the questions customers ask while identifying a problem, comparing options, and making a decision. Keep that set stable long enough to make one reporting period comparable with the next.

    For every checked answer, record whether your brand was absent, mentioned, cited as a source, or explicitly recommended. Those states are not equivalent. A citation shows that your material surfaced in the answer; a recommendation is a stronger form of representation, but it still does not prove commercial impact.

    State the denominator whenever you report AI share of voice. For example, define it as the number of eligible answers containing your brand divided by the total eligible answers checked in the fixed query set. Without the query set, platforms, conditions, and denominator, a share-of-voice percentage has no stable meaning.

    Preserve traffic evidence without treating it as the whole result

    Create a dedicated segment for identifiable AI referrals. Record the landing page, referrer when available, engagement, and downstream conversion. Use tagged links wherever you control the destination link, but do not relabel unexplained direct traffic as AI traffic. “Unknown” is a more defensible classification than a confident guess.

    Compare AI referral traffic with the visibility layer instead of expecting the numbers to match. Rising citations with flat referrals can indicate more zero-click exposure, but it does not establish that the exposure caused later demand. It is a signal to investigate, not a revenue claim.

    Connect marketing evidence to outcomes the business values

    Carry a durable lead or customer key from the conversion point into your CRM where your setup permits it. Preserve the original source, the latest known source, landing page, campaign data, and relevant sales outcome as separate fields. Overwriting the first touch with the latest touch destroys evidence you may need later.

    Add a short self-reported discovery question to high-value conversion points. Offer recognizable options, including AI assistants, and leave room for free text. Self-reporting is imperfect, but it can reveal discovery paths that click-based analytics cannot see. Keep it beside behavioral attribution rather than using it to replace behavioral data.

    Report the three layers side by side. Do not collapse citations, sessions, leads, and revenue into one synthetic score. A single score hides the exact break you need to find: limited visibility, weak click-through, lost campaign data, poor lead quality, or a missing CRM connection.

    Repair campaign plumbing before judging performance

    A technician repairs loose and blocked connections in transparent pipes carrying glowing signals toward a central customer-record hub.

    A campaign-quality discussion should stop when the tracking path is visibly damaged. Creative, targeting, and bidding changes cannot repair a parameter stripped by a redirect or a revenue field that never returns to the reporting system.

    Use this sequence when Google Analytics flags missing aggregate URL parameters or when campaign data unexpectedly becomes incomplete:

    1. Record the affected scope. Note the campaign, platform, landing page, identifier involved, and example URLs identified by the diagnostic. Do not begin with an account-wide conclusion when the fault may affect only one route.
    2. Follow a controlled path. Start with a platform-generated test URL and record the browser URL at the initial landing page and after every redirect.
    3. Locate the first loss. Check link templates, shorteners, server redirects, cross-domain handoffs, consent flows, and landing-page scripts. The first point where the parameter disappears is more useful than the final unattributed session.
    4. Use generated identifiers as intended. Do not invent or reconstruct privacy-related identifier values. Preserve the parameters supplied by the advertising platform and follow its remediation guidance.
    5. Verify collection after the repair. Repeat the same controlled route and confirm that the identifier survives the handoffs and reaches the intended analytics setup.
    6. Annotate the affected period. Record when the issue began, when it was discovered, what scope was affected, and when the fix was verified. Historical reports may remain incomplete even after new traffic is measured correctly.

    The diagnostic identifies a data-quality symptom; it does not automatically identify the root cause or restore missing history. It also does not prove that every unattributed conversion belongs to the affected campaign. Use it to narrow the investigation, then validate the actual path.

    Track a simple completeness rate after the fix: eligible records containing the expected campaign evidence divided by all eligible records. The useful comparison is the rate over time and across equivalent paths. There is no universal threshold that can tell you whether your particular implementation is healthy.

    Run a blind-spot audit around decisions, not dashboards

    A generic analytics audit can produce a long list of tidy fields without protecting an important decision. Start with the decision that could move money: whether to scale a campaign, pause a channel, invest in AI visibility, or change the content program.

    Then audit the evidence in this order:

    1. Write the decision in one sentence. Name the investment being evaluated, the outcome that matters, and the reporting period. This prevents convenient metrics from replacing the business question.
    2. Draw the observable path. Map exposure, click, landing page, conversion, lead record, opportunity, purchase, and revenue. Mark which system owns each event.
    3. Mark every join. Identify the field that connects one stage to the next. If no shared key exists, label the gap instead of assuming the systems reconcile.
    4. Reconcile adjacent counts. Compare platform interactions with analytics visits, visits with form completions, form completions with CRM leads, and closed outcomes with reported revenue. You are looking for a structural break, not perfect equality between systems that measure different events.
    5. Test one known path. Use a controlled journey to confirm that the expected campaign context survives each relevant handoff. A dashboard total cannot show you where an individual field disappeared.
    6. Classify the evidence. Separate directly observed, successfully joined, inferred, and unknown data. Display the classification beside the metric used for the decision.
    7. Assign the gap. Give each material blind spot an owner, a next check, and a verification condition. “Improve attribution” is not an action; “confirm that GBRAID survives the landing-page redirect” is.

    Keep a blind-spot register with seven fields: decision at risk, missing evidence, affected systems, suspected break, owner, next verification, and confidence level. This turns uncertainty into a manageable queue instead of burying it in a dashboard footnote.

    Evidence labels also make budget conversations more honest:

    • Directly observed: The event was recorded in the system where it occurred.
    • Joined: Records were connected using a defined key across systems.
    • Inferred: The relationship is plausible and supported by directional evidence, but the individual path is not observed.
    • Unknown: The necessary evidence is missing or contradictory.

    Attribution and causality must remain separate. Attribution assigns credit under a chosen rule. It does not, by itself, establish what would have happened without the marketing activity. If a large investment requires a causal answer, use a controlled experiment where one is feasible and keep its result separate from the attribution model.

    Use a few firm decision rules. Do not declare a campaign decline while its expected identifiers are missing. Do not call growing AI citations revenue merely because branded demand also rose. Do not call unattributed traffic organic, direct, or AI-derived without evidence. When visibility, identifiable visits, self-reported discovery, and connected outcomes move in the same direction, confidence improves, but the pattern is still not automatic proof of causation.

    Key takeaways

    • An attribution report describes the observable trail, not every influence on the customer.
    • Measure AI visibility, identifiable traffic, and business outcomes as separate layers with separate denominators.
    • Treat missing GBRAID, gad_, or other expected campaign evidence as a data-quality issue before evaluating campaign quality.
    • Preserve original and later source fields instead of overwriting one with the other.
    • Label evidence as observed, joined, inferred, or unknown so decision-makers can see how much confidence a metric deserves.
    • Use attribution to allocate recorded credit; use controlled testing when you need a causal answer.

    Before your next budget review, choose the highest-consequence campaign and trace one complete path from exposure to revenue. At the same time, choose one AI discovery use case and build its three-layer view. Fix any broken handoff first. Then make the investment decision with the blind spots visible rather than pretending they are not there.

    References

  • Google Ads Video Campaign Groups: Planning and Measurement

    Google Ads Video Campaign Groups: Planning and Measurement

    If you run several YouTube awareness campaigns against much of the same audience, each campaign can look acceptable on its own while the account-level picture remains unclear. You still need to know how many people the campaigns reach together, how often those people see your ads, and whether separate campaigns are competing for the same exposure.

    Google Ads video campaign groups give you that broader control layer. You can coordinate multiple YouTube reach and frequency campaigns around one shared reach or frequency objective without giving up their individual budgets, creative assets, or campaign settings. The opportunity is useful, but only if the campaigns belong together strategically.

    One group objective sits above campaign-level controls

    A video campaign group is not merely a folder for tidying an account. It adds cross-campaign optimization and unified reporting for eligible YouTube reach and frequency campaigns. The feature is available globally in Google Ads, but its scope matters: it is designed around reach and frequency management rather than every type of video campaign.

    Decision or controlWhere it remainsHow to use it
    Shared reach or frequency objectiveCampaign groupDefine the exposure outcome the included campaigns should pursue together.
    BudgetIndividual campaignAllocate spending according to each campaign’s role and review the combined amount before launch.
    Creative assetsIndividual campaignKeep distinct messages or executions while coordinating their overall audience exposure.
    Other campaign settingsIndividual campaignPreserve the controls that make each campaign operationally distinct.
    Unique reach and average weekly impressionsCampaign group reportingJudge the combined audience outcome instead of adding campaign reports together.

    The budget distinction deserves special attention. A shared objective does not turn separate campaign budgets into one shared budget. Check every included campaign and calculate the total amount you intend to have active. Otherwise, a clean group-level strategy can sit above an allocation that does not reflect it.

    Key takeaways

    • Use a group when several YouTube reach and frequency campaigns should pursue one audience-exposure outcome.
    • Keep using campaign-level budgets, creatives, and settings to define each campaign’s role.
    • Read unique reach at the group level; adding campaign-level reach can count the same person more than once.
    • Treat unified reporting as a decision tool, not as permission to combine strategically unrelated campaigns.

    Group campaigns by the decision you need to make

    Hands sort video campaign tiles into separate groups represented by reach, frequency, and audience-overlap symbols.

    The best grouping rule is not a naming convention, product line, or account structure. It is whether you would make a shared reach or frequency decision across the campaigns.

    Write the intended decision before building the group: “Across these campaigns, we want to manage for [reach or frequency] among [the intended audience] during [the relevant campaign period].” If that sentence describes every candidate campaign without becoming vague, the group is probably coherent. If you need several different objectives, audiences, or time horizons to finish it, you are likely forcing unlike campaigns together.

    A campaign is a sensible candidate when:

    • It is an eligible YouTube reach or frequency campaign.
    • Its audience exposure should be coordinated with the other campaigns.
    • It supports the same high-level reach or frequency outcome.
    • Its separate budget, creative, or settings serve a clear purpose within that shared outcome.
    • You would take action based on the group’s combined reach and frequency results.

    Keep campaigns in different groups when they pursue conflicting exposure goals, operate over periods that make one combined view misleading, or serve audiences whose results you would never manage together. A campaign focused on expanding the number of people reached and another intentionally concentrating repeated exposure may both be legitimate, but placing them under one ambiguous objective makes the group harder to interpret.

    Separate campaigns can still preserve different creative strategies inside a group. That is one of the feature’s practical strengths. You do not have to flatten meaningful creative or budget differences merely to coordinate delivery across the larger campaign set.

    Build the measurement plan before evaluating the group

    Unified reporting is valuable because campaign reports cannot reveal combined audience reach simply by being added together. If one person sees ads from three campaigns, each campaign can include that person in its own reach result. Summing those figures would treat repeated people as additional people. Group-level unique reach is the relevant view when the business question concerns the whole campaign set.

    The group view includes unique reach, average weekly impressions, and reach-and-frequency performance across the group. Give each metric a job:

    • Unique reach tells you whether the campaigns collectively reached more distinct people. Use the group figure rather than a sum of campaign figures.
    • Average weekly impressions helps you see how much repeated weekly exposure accompanies that reach.
    • Group reach and frequency performance shows whether the combined system is moving toward the shared objective.
    • Campaign-level results help you diagnose which budget, creative set, or campaign setting may be contributing to the group outcome.

    This creates a useful reporting sequence: assess the group first, then investigate campaigns. Starting with individual campaigns can pull you into local optimizations that look beneficial in isolation but do not improve combined reach or exposure.

    1. State whether reach or frequency is the primary group objective.
    2. Record which campaigns are included and why each one belongs.
    3. Confirm every campaign budget and the combined planned allocation.
    4. Review the group-level audience metrics before drawing conclusions from individual campaigns.
    5. Use campaign-level controls to investigate a group-level problem.
    6. Document changes so you can distinguish a strategic adjustment from ordinary variation in delivery.

    Do not expect one metric to answer every question. Growing unique reach can be desirable when expansion is the objective, while more repeated exposure can be intentional when frequency is the objective. The metric only becomes useful after you state which outcome the group is meant to produce.

    Interpret frequency as an account-specific decision

    There is no universal weekly frequency that automatically produces the best result for every advertiser. Google has cited a Meridian marketing mix modeling analysis in which 2.7 impressions per week was the modeled optimum and produced a 19% increase in ROI. Those figures show that frequency can have measurable economic consequences, but they do not establish 2.7 as a default setting for every brand, audience, creative strategy, or campaign period.

    Use 2.7 as a hypothesis worth examining, not a number to copy uncritically. Your practical question is whether additional weekly exposure is still contributing to the campaign’s purpose or merely increasing repetition among people you have already reached.

    Several reporting patterns can guide that investigation:

    • If unique reach is expanding while average weekly impressions remain consistent with your plan, the group may be balancing audience growth and repetition as intended.
    • If average weekly impressions rise while unique reach changes little, investigate whether particular campaign budgets or settings are concentrating delivery among the same people. This is a signal to inspect, not proof of waste.
    • If group performance looks acceptable but one campaign appears weak in isolation, check whether that campaign plays a useful role in the combined result before cutting it.
    • If the group average looks healthy, still inspect campaign-level reporting. An average can conceal one campaign receiving substantially different exposure from another.

    Video campaign groups can help reduce unnecessary overlap and overexposure, but grouping alone does not guarantee either result. The advantage is that you can now see and optimize the shared outcome more directly while retaining the controls needed to correct it.

    Use a controlled first rollout instead of grouping everything

    A small group of active video campaign modules is measured inside a controlled test area while additional modules remain inactive outside it.

    Start with one campaign family whose overlap is easy to explain. A smaller, coherent group makes it easier to learn what the group-level reporting changes in your decisions. Adding every eligible campaign at once can produce a combined result that is technically complete but strategically meaningless.

    1. Inventory eligible campaigns. Identify the YouTube reach and frequency campaigns that may be addressing the same exposure opportunity.
    2. Choose one shared objective. Decide whether the group should prioritize reach or frequency. Do not leave both as equally important if they would lead to different actions.
    3. Define inclusion criteria. Include a campaign only when its exposure should be coordinated with the others.
    4. Verify campaign-level controls. Check budgets, creative assets, and other settings because they remain separate after grouping.
    5. Calculate the active budget. Review the combined allocation before launch or expansion; the group objective does not replace individual budget responsibility.
    6. Assign each campaign a role. Be able to explain why its creative, budget, or settings need to remain distinct.
    7. Review from group to campaign. Start with unique reach, average weekly impressions, and overall reach-and-frequency performance, then use campaign reporting for diagnosis.
    8. Expand only when the group answers a real decision. Add more campaigns when their inclusion improves coordination, not merely because the interface allows it.

    Your first useful group does not need to contain every YouTube awareness campaign. Choose the campaigns most likely to reach the same people, define the shared objective, and use the unified report to decide whether your spending is buying broader reach or additional repetition. If the group cannot support a clear action, tighten its membership before changing its campaigns.

    References