Tag: Campaign Performance

  • Paid Media Diagnostics: From Clean Data to Catalog Health

    Paid Media Diagnostics: From Clean Data to Catalog Health

    A weak paid media result can originate in several places: the reporting may be misleading, an advertised item may be unable to serve, or eligible inventory may simply be underperforming. Treating every symptom as an optimization problem risks changing bids, budgets, or creative before the underlying fault is known.

    Recent reporting on Google Analytics source controls and Microsoft Ads catalog diagnostics points to a more disciplined approach. Measurement integrity should be checked first, delivery eligibility second, and performance efficiency only after both foundations are credible.

    A diagnostic sequence for separating symptoms from causes

    The two source reports address different parts of the paid media system. The Google Analytics changes concern how traffic is classified and which domains contribute events to reporting. Microsoft Ads Product Explorer concerns whether catalog items are eligible, sufficiently described, and producing results. Together, they support a layered diagnostic model rather than a single dashboard verdict.

    Diagnostic questionLayer under reviewRelevant evidenceDecision it informs
    Can the reported traffic be trusted?Measurement integritySource classification and hostname provenanceWhether channel comparisons are reliable enough to guide budget decisions
    Could the advertised products serve?Delivery eligibilityCatalog status, required metadata, and identified feed issuesWhether reach is constrained before bidding or creative can have an effect
    How did eligible inventory perform?Performance efficiencyProduct-level results and consistently classified conversion trafficWhich items or channels warrant optimization, expansion, or closer investigation

    This sequence matters because similar symptoms can have unrelated causes. A channel can appear fragmented when one platform is recorded under several source names. A product can show no meaningful activity because it is not eligible to serve. Only after those possibilities are addressed does an efficiency diagnosis become well grounded.

    Clean attribution before comparing channel performance
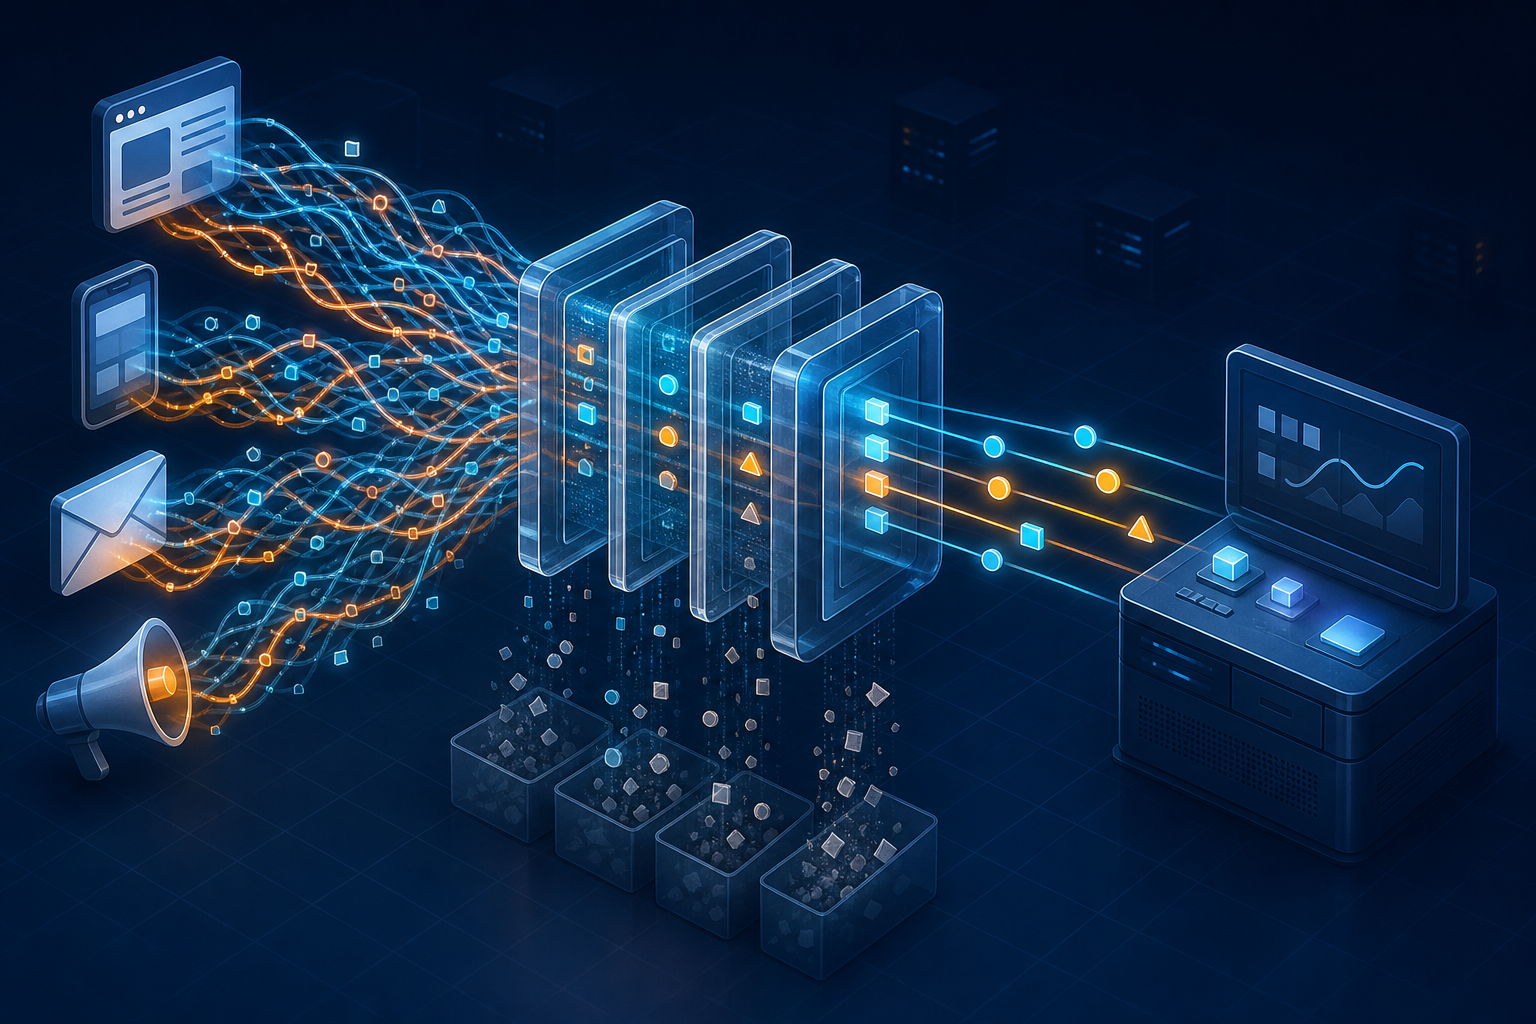
    Tangled digital signals pass through a transparent filter and emerge as clean, distinct data streams.

    The Google Analytics source reported that a new Source Group reporting dimension consolidates variations of the same traffic source. Its example groups labels such as “facebook” and “fb” into one recognizable value. It also reported improvements to the Source Platform field intended to make classifications more consistent across advertising channels.

    For paid media diagnostics, that standardization reduces a common analytical distortion: one platform appearing as several small sources while another appears as a single consolidated source. The report said the structure extends beyond Google properties to platforms including TikTok, Pinterest, and Amazon, while also accounting for AI-originated traffic such as ChatGPT and Perplexity. It further said source-group information is available retroactively for historical analysis.

    Source consolidation does not resolve every attribution limitation. It makes labels more coherent, but a consistently named source is not automatically proof that the source caused a conversion. Analysts still need to distinguish reporting consistency from causal measurement and apply the same attribution interpretation when comparing channels.

    The reported hostname filters address a separate trust issue. According to the Google Analytics source, administrators can exclude events from unapproved domains before those events enter reporting. This can help prevent traffic associated with unexpected hosts from influencing campaign analysis. The practical control is to document which domains are legitimate before filtering; otherwise, an overly narrow approval set could remove activity that should have remained visible.

    Check catalog eligibility before optimizing retail campaigns
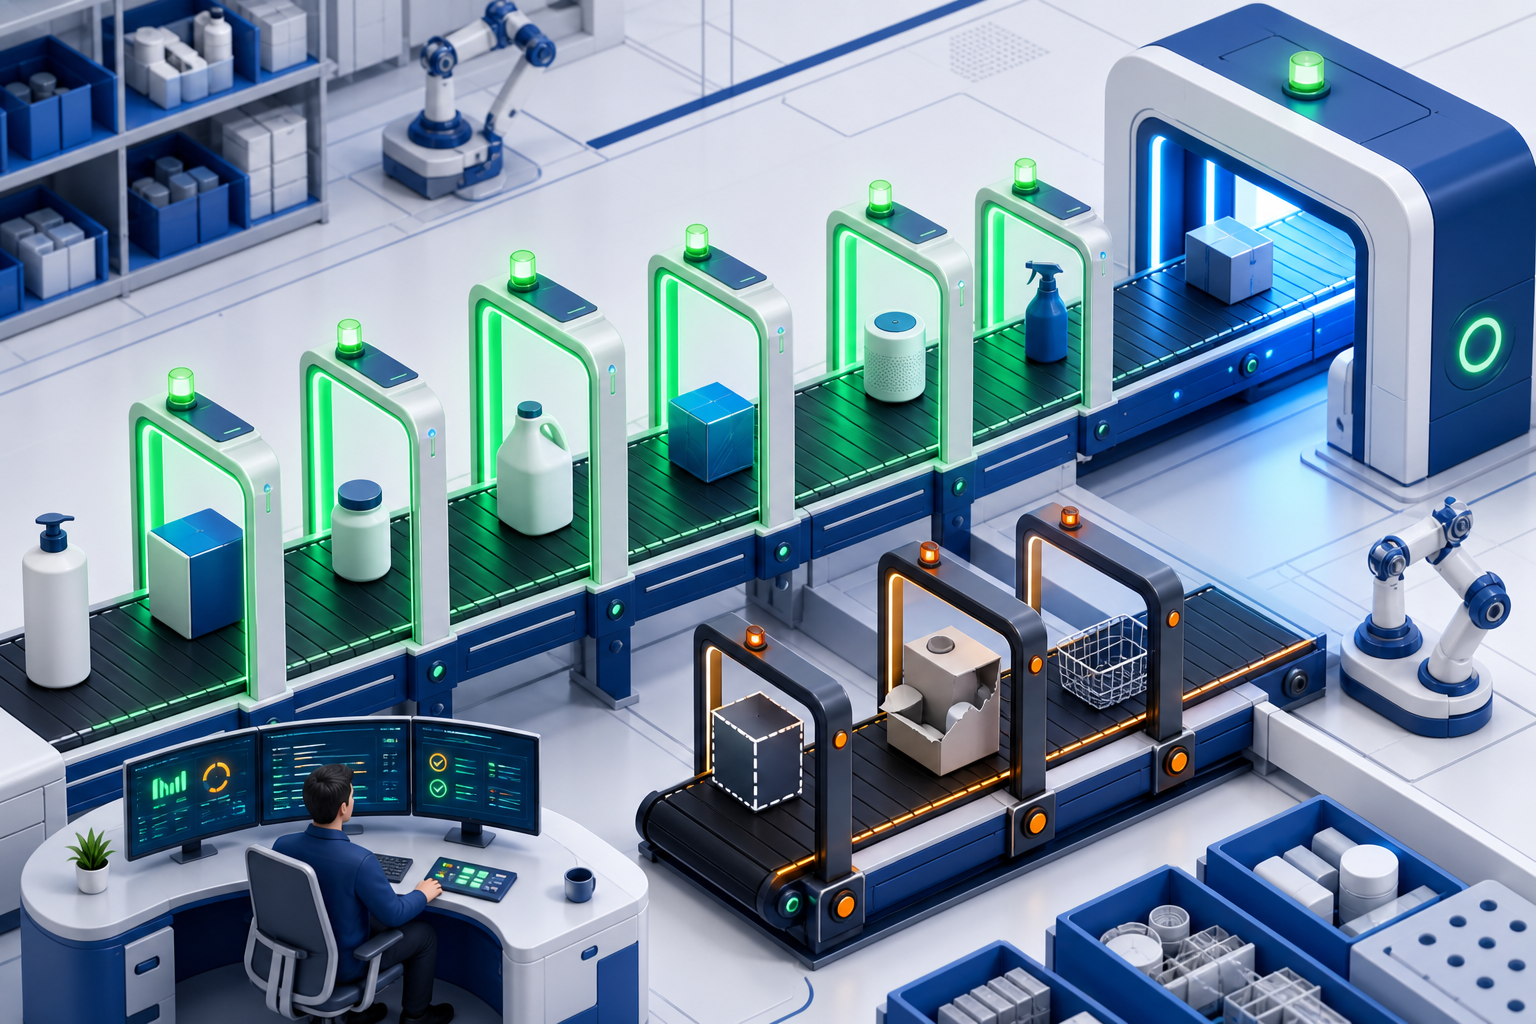
    Generic retail products move through eligibility checkpoints while a few incomplete or unavailable items are diverted for inspection.

    Microsoft Ads Product Explorer moves the investigation from attribution to inventory readiness. The Microsoft-focused source described a searchable catalog interface with filters for SKU, title, GTIN, and product ID. It reportedly surfaces eligibility problems, metadata gaps, and other conditions that may stop products from serving, while providing recommended actions and exportable filtered product lists.

    This changes how low delivery should be interpreted. If a product is ineligible or lacks necessary feed information, adjusting campaign-level settings does not address the immediate constraint. Catalog remediation comes first. Once an item is active and capable of serving, its advertising results can be evaluated as a performance issue rather than confused with a feed-health issue.

    The source also reported product-level performance visibility covering the previous 30 days. That window can connect operational diagnostics with observed activity: advertisers can distinguish products blocked by catalog problems from active items receiving exposure or producing results. The report stated that Product Explorer was live in advertiser accounts, although the source did not independently test its coverage or recommendations.

    Turn cleaner evidence into better optimization decisions

    The strongest synthesis is not a new all-in-one metric. It is a division of diagnostic responsibilities. Analytics source controls help establish whether cross-channel reports are internally coherent. Catalog tools help establish whether retail inventory can participate in the auction. Performance analysis then assesses what happened among the traffic and products that survived those checks.

    That separation also clarifies ownership. Measurement anomalies belong with analytics governance; product eligibility and metadata gaps belong with feed operations; efficiency questions belong with campaign management. Teams can still investigate collaboratively, but each finding should be routed to the layer capable of correcting it.

    A defensible performance review should therefore record both the result and the conditions under which it was observed. Channel comparisons should note whether source grouping and hostname controls were reviewed. Retail conclusions should note whether the relevant products were eligible and whether catalog issues were present. This creates an audit trail that makes later changes in reported performance easier to interpret.

    Key takeaways

    • Validate source classification and domain provenance before moving budget based on cross-channel reports.
    • Treat source standardization as a reporting improvement, not as proof of causal attribution.
    • For retail advertising, resolve eligibility and metadata problems before diagnosing low delivery as a bidding or creative failure.
    • Evaluate product and campaign efficiency only after measurement integrity and serving readiness have been checked.

    As advertising platforms automate more campaign execution, diagnostic discipline becomes more important, not less. The next useful advance will be a repeatable review process that connects trustworthy measurement, servable inventory, and performance decisions without collapsing them into the same signal.
    References

  • Google Ads Updates Link Trust Rules With Creative Testing

    Google Ads Updates Link Trust Rules With Creative Testing

    Two Google advertising updates point to a broader operating model for advertisers: eligibility must be maintained through clearer requirements, while campaign improvements should be validated through controlled experiments. The changes affect different products, but together they show how governance and optimization are becoming more structured.

    For Local Services Ads, the reported emphasis is on clearer terminology and alignment with Google’s revised badge framework. For Performance Max, the emphasis is on testing creative decisions before applying them more broadly. Advertisers therefore need both reliable compliance processes and a repeatable approach to experimentation.

    Two updates address different kinds of advertising risk

    A metallic link symbol and verification shield passing through a security checkpoint toward generic local storefront icons.

    CrushPress.AI’s Local Services Ads coverage reported that Google plans to rename its “Local Services platform policies” as “Local Services Ads requirements” on July 6. The report characterized the change as a clarification and modernization of guidance rather than a major enforcement crackdown. It also connected the revised language to Google’s recent restructuring of its badge system and verification standards.

    That update concerns participation risk: whether a business understands and satisfies the conditions associated with advertising and badge eligibility. Clearer requirements may reduce ambiguity, but a new label does not eliminate the need to keep credentials, verification information and operating standards current.

    The separate Performance Max report focused on decision risk. Because creative changes can affect results, advertisers need evidence before committing budget across campaigns. The newly reported experiment capabilities are intended to provide a more controlled way to assess assets instead of treating every creative revision as an immediate full rollout.

    Performance Max testing adds more useful creative comparisons

    Two different generic ad creatives moving through matching glass test modules before reaching a network of blank device displays.

    According to CrushPress.AI’s coverage, Performance Max advertisers can test entirely new asset groups, evaluate the effect of adding individual assets, and compare seasonal material with evergreen creative. The report also said that assets produced through Google’s Asset Studio can be included, allowing generated creative and other asset approaches to be assessed within the same experimentation framework.

    The practical value is not simply the ability to declare one asset a winner. The report described an additional success metric that can help advertisers evaluate more than one objective, such as conversion volume alongside efficiency. This matters because a creative change can improve one measure while weakening another; a broader evaluation can expose that trade-off before the change is expanded.

    The coverage also reported that experiments, including conversion lift studies, are being centralized on one Experiments page. Support for manager accounts and the Google Ads API was described as beginning to roll out soon, while further experiment and measurement capabilities were said to be forthcoming. Those rollout statements should be treated as reported product direction rather than proof that every account already has access.

    Key takeaways

    • Local Services Ads guidance is reportedly being reframed as explicit requirements and aligned with Google’s revised badge and verification framework.
    • The Local Services Ads change was presented as a clarity initiative, but businesses still need dependable processes for maintaining eligibility information.
    • Performance Max experiments reportedly support tests of asset groups, individual additions, seasonal versus evergreen creative, and assets created with Asset Studio.
    • An additional success metric can help teams judge creative against multiple campaign objectives rather than a single headline result.
    • Centralized experiment management may simplify oversight, although manager-account and API support were reported as rolling out rather than universally available.

    Advertisers need separate controls for eligibility and performance

    The two updates should not be collapsed into a single workflow. Local Services Ads requirements concern whether an advertiser can participate and qualify under the relevant framework. Performance Max experiments concern whether a proposed creative change produces a desirable outcome. Passing a verification check says nothing about asset effectiveness, while a successful creative test says nothing about compliance or badge eligibility.

    A practical response is to assign each issue to the appropriate review process. Local advertisers and their agencies can track requirement changes, verification materials and badge-related dependencies as governance work. Performance teams can document the hypothesis behind each asset experiment, the primary and secondary measures used to judge it, and the scope of any subsequent rollout.

    This separation also makes accountability clearer. Eligibility reviews should answer whether the business remains qualified and whether its information is current. Experiment reviews should answer what changed, what comparison was made, which measures moved and whether the evidence supports broader deployment. Both disciplines reduce avoidable risk, but they do so in different ways.

    Questions remain about access, enforcement and interpretation

    The source material does not establish how the renamed Local Services Ads requirements will affect individual advertisers, whether enforcement practices will change, or exactly how compliance will determine badge status in every case. The reported alignment suggests that eligibility and trust signals should be reviewed together, but it does not justify assuming a new penalty or automatic badge outcome.

    Likewise, the Performance Max report does not provide universal availability dates, account-level eligibility details or a guarantee that every experiment will produce a conclusive result. Advertisers should confirm which capabilities appear in their own accounts and avoid treating an announced rollout as completed access.

    As Google develops both frameworks, the durable advantage will come from operational readiness: maintaining evidence for eligibility decisions and using experiments to support creative decisions. Teams that establish those routines can adapt to additional requirements and measurement features without rebuilding their processes around every product update.

    References

  • Shopify Outage Response: Protect Sales, Ads and SEO

    Shopify Outage Response: Protect Sales, Ads and SEO

    Your Shopify admin will not load, customers are reporting checkout errors, and paid campaigns are still sending people to the store. The worst response is to change everything at once.

    You need to identify which part of the buying journey is broken, stop avoidable losses, preserve reliable data, and keep a temporary platform failure from becoming a lasting search problem.

    Key takeaways

    • Test the store as a customer. An inaccessible admin does not automatically mean the storefront or checkout is unavailable.
    • Pause conversion campaigns when customers cannot complete payment, and record when you changed each campaign.
    • Do not noindex products, redirect product URLs, or mark inventory as out of stock solely because Shopify checkout is unavailable.
    • Resume promotion only after you have tested the complete journey from product page to order confirmation.

    Triage the customer journey before changing campaigns

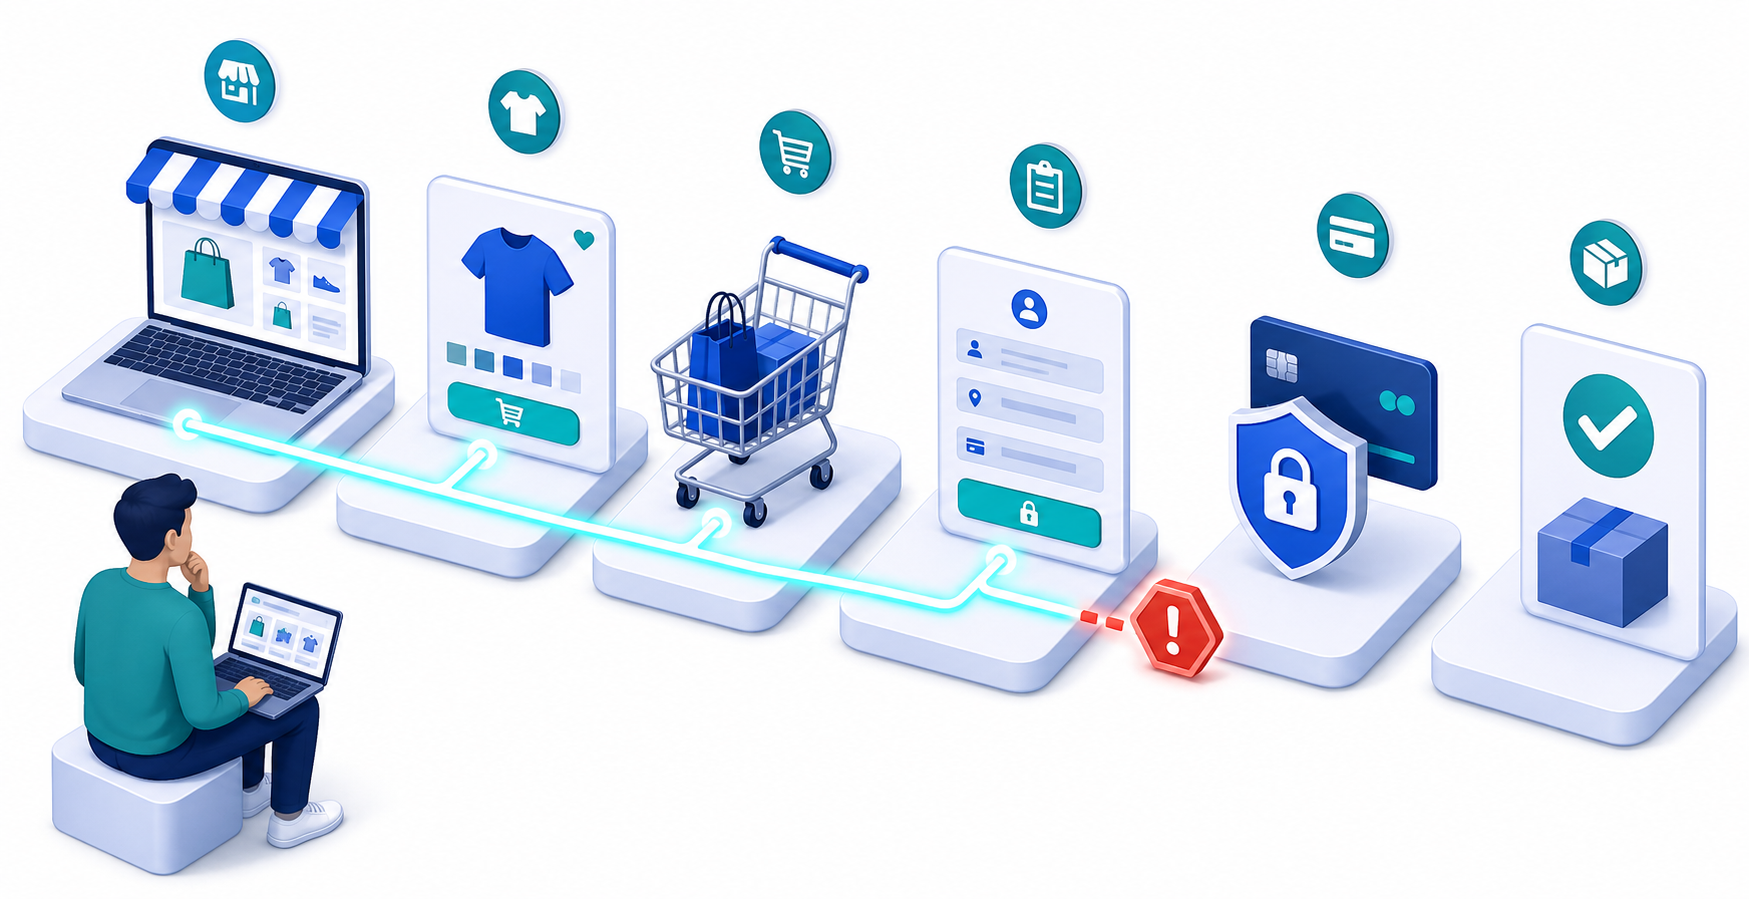
    An isometric customer purchase journey shows working storefront and cart stages followed by an interrupted payment connection.

    Start outside Shopify Admin. Open a private browser window and follow the same path a new customer would take: load a product page, add the product to the cart, begin checkout, and attempt to reach the final payment stage. If you operate physical locations, check Retail POS separately.

    This separation matters because one service can fail while another remains usable. During the reported Tuesday disruption, Shopify acknowledged problems involving Admin and Retail POS at 9:27 a.m. EDT, while merchants and customers also encountered trouble with storefronts, checkout, and support access. Shopify was still investigating at 9:45 a.m. and reported an identified cause and improving service at 10:37 a.m. That improvement did not, by itself, prove that every merchant’s customer journey had recovered.

    What you observeWhat it means for your response
    Admin is unavailable, but a customer can browse and complete checkoutKeep monitoring sales. Do not pause every campaign merely because store management is difficult.
    Storefront loads, but checkout failsPause campaigns intended to produce immediate purchases and hold scheduled promotional sends.
    Storefront does not loadStop traffic whose landing pages are unavailable and publish a clear service notice on a channel you can still control.
    Retail POS fails while online checkout worksSeparate the retail response from the ecommerce response. Do not treat all revenue channels as unavailable.
    Support is inaccessibleMaintain an internal incident log and use the platform’s available public updates without waiting for a support reply.

    Assign one person to maintain the incident record. Capture what failed, how it was tested, when the failure was first confirmed, which promotions were active, and which actions the team took. This prevents several people from making conflicting campaign, site, or customer-service changes.

    Control paid traffic without destroying useful evidence

    If checkout cannot accept orders, each additional conversion-focused click can add cost without creating a sale. Pause the affected campaigns rather than deleting them. A pause preserves campaign settings and makes it easier to compare performance before, during, and after the interruption.

    Make decisions by destination and objective. A campaign leading to a failed product or checkout path should stop. A campaign serving a functioning market, store, or non-transactional resource may not need the same treatment. The test result should decide, not the frustration of being locked out of Admin.

    Record the time of every pause, budget adjustment, promotional cancellation, and restart. Add the incident window to your analytics annotations or reporting notes. Keep Shopify’s acknowledgement and recovery updates in the record, but use your own customer-path tests to define the period when your store was actually unable to convert.

    Do not evaluate that window as an ordinary campaign-performance decline. Separate traffic sent during the failure from normal traffic, then reconcile ad-platform conversions with completed Shopify orders after access returns. Otherwise, automated bidding changes and human budget decisions may both react to a platform problem as though it were weak demand or poor creative.

    Protect SEO, product schema and AI-facing answers

    A temporary checkout failure is not an inventory change. Do not switch Product or Offer structured data to OutOfStock unless the item is genuinely unavailable. Machine-readable availability can remain visible after the checkout problem ends, leaving search engines, shopping systems, and AI assistants with an inaccurate description of the product.

    Likewise, do not noindex product pages, remove canonical tags, delete URLs, or redirect the catalog to the homepage as an emergency measure. Those changes can outlive the incident and create crawling, indexing, and reporting problems that are harder to reverse than the outage itself.

    If you can publish outside the affected storefront, maintain one plain-language status message. State which customer action is failing, which channels still work, and when you last verified the condition. Use the same wording in social updates, support replies, and internal scripts. Consistent public language gives customers a clearer answer and reduces the chance that search or AI systems encounter contradictory explanations.

    Avoid promising a recovery time you do not control. A platform update saying that services are improving is a reason to retest, not a reason to declare your own store operational.

    Restart only after a complete purchase succeeds

    A merchant verifies a successful test payment as a package enters fulfillment and customer traffic begins to reopen.

    Recovery should be verified from the customer’s side. Restored Admin access is useful, but it does not establish that product pages, carts, checkout, payment, confirmation, and order recording are all working together.

    1. Repeat the full purchase path in a clean browser session.
    2. Confirm that the completed order appears where your team expects to manage it.
    3. Check Retail POS separately if physical stores were affected.
    4. Review the incident window for incomplete, delayed, or unexpectedly repeated customer activity before sending more promotion.
    5. Resume campaigns in a controlled order, starting with the paths you have directly verified.
    6. Update the public service message only after your own checks pass, and preserve the incident notes for reporting.

    Once operations are stable, save a short outage runbook containing the incident owner, customer-path tests, campaign controls, analytics annotation process, and status-message template. The next Shopify disruption should trigger a familiar sequence, not a fresh argument about what to do.

    References

  • How to Scale a High-ROAS Campaign Without Wasting Budget

    How to Scale a High-ROAS Campaign Without Wasting Budget

    Your campaign is profitable, lead quality looks good, and someone wants to double the budget. The tempting assumption is that twice the spend will produce twice the revenue.

    That only works when the campaign has profitable demand left to capture. Before you raise the budget, verify the business value behind the reported ROAS, confirm that budget is the real constraint, and decide how much efficiency you are prepared to trade for additional volume.

    High average ROAS does not prove the next dollar will perform

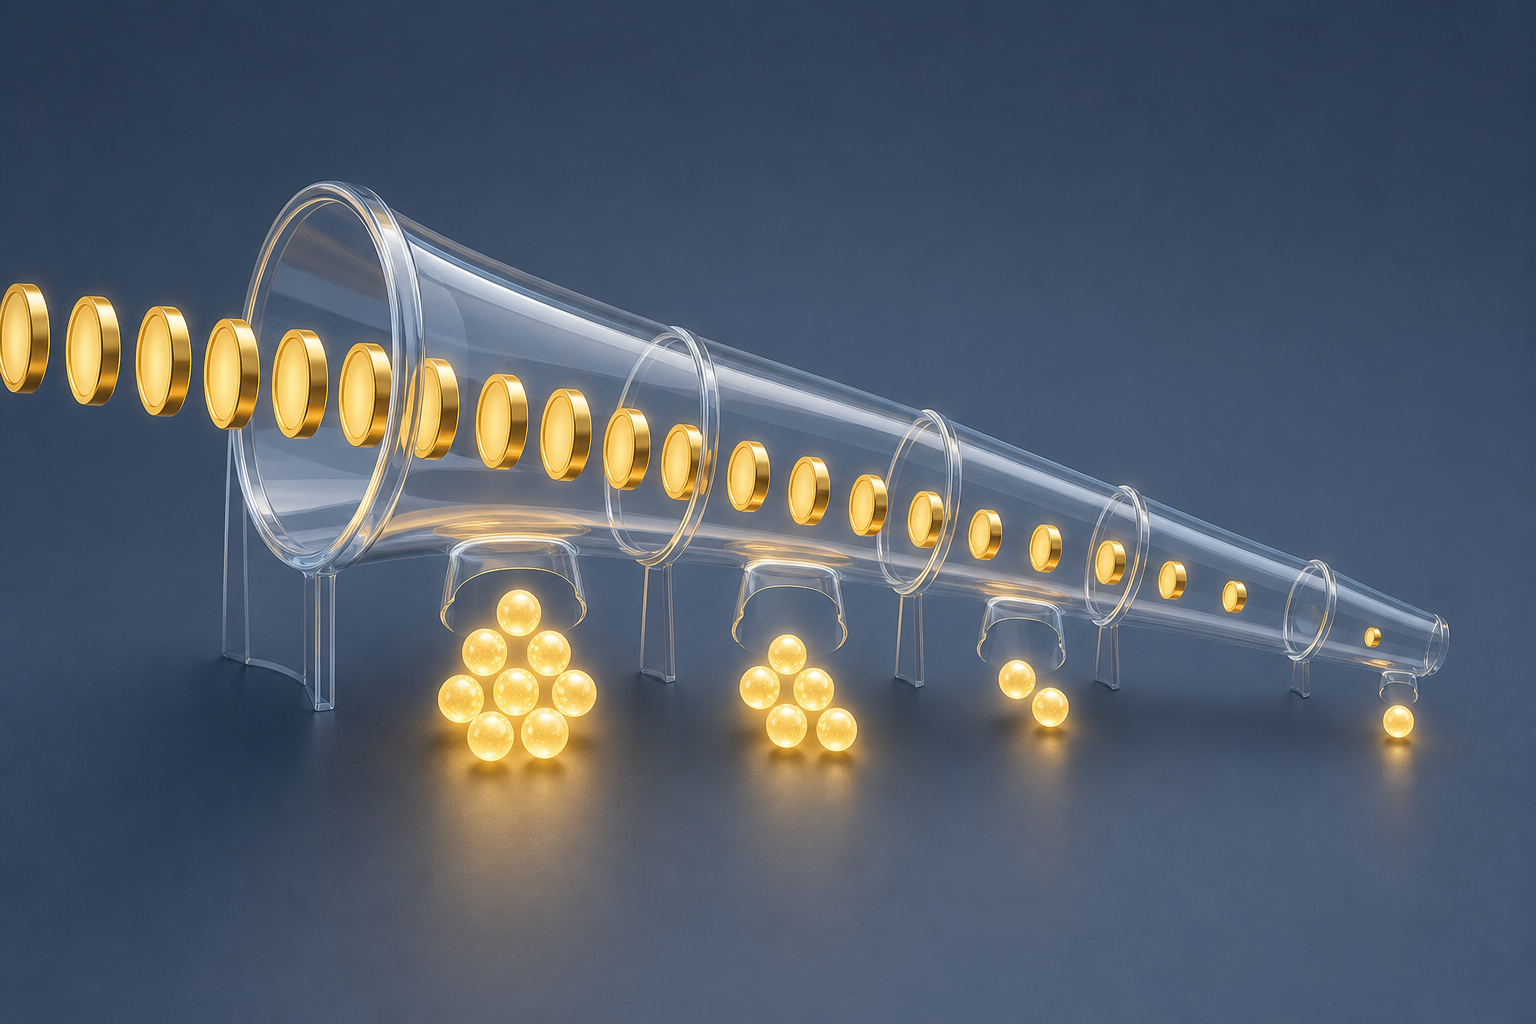
    A curved transparent funnel converts successive gold tokens into progressively fewer glowing spheres.

    The ROAS in your dashboard describes the spend you have already made. It does not tell you what the next dollar will return. A tightly constrained campaign may be collecting the easiest conversions: high-intent searches, familiar audiences, strong locations, or the most responsive hours. More budget can push delivery into less efficient opportunities.

    That is why budget scaling should be judged on marginal performance. Calculate incremental ROAS as additional revenue divided by additional spend. If spend rises but qualified revenue barely moves, the campaign has not scaled successfully, even if its blended ROAS still looks respectable.

    You also need an economic floor. Your target should reflect gross margin, fulfillment costs, returns, sales costs, and any other expense that changes when you acquire another customer. A campaign can exceed a platform ROAS target and still produce weak profit.

    Key takeaways

    • Scale only when the campaign is constrained by budget and still has qualified demand available.
    • Validate conversion tracking, lead quality, order value, and profitability before trusting a high ROAS.
    • Increase budget in controlled steps and avoid changing bids, targeting, creative, and budget at the same time.
    • Judge the test by incremental qualified revenue and profit, not spend growth alone.

    Validate the business result before funding it

    A scaling decision is only as reliable as the conversion signal behind it. Run this audit before approving more spend:

    1. Check conversion tracking. Confirm that each important action fires once, carries the correct value, and represents a result the business actually wants. Remove duplicate, test, or low-value actions from the primary optimization signal.
    2. Trace leads to outcomes. Compare campaigns using qualified opportunities, closed sales, or another downstream milestone. A form submission is not equivalent to revenue when lead quality varies.
    3. Reconcile order value. Check whether the value sent to the ad platform reflects cancellations, refunds, discounts, and unusually large purchases that can distort the average.
    4. Compare revenue with profit. Establish the lowest acceptable return before scaling. This gives you a stopping rule if marginal efficiency declines.
    5. Confirm operational capacity. Make sure sales, inventory, fulfillment, and customer support can absorb more volume. Paying for demand that the business cannot serve is not productive growth.

    If any of these checks fails, fix the measurement or business constraint first. Increasing the budget would amplify the uncertainty rather than resolve it.

    Prove that budget is the constraint

    A strong campaign can have limited scale for reasons that money cannot fix. Search demand may be finite. Targeting may be narrow. Inventory may be unavailable. The sales team may reject additional leads. Budget should rise only when the evidence points to a spend constraint.

    What you observeLikely interpretationWhat to do next
    The campaign regularly reaches its budget while qualified conversions remain profitableBudget may be limiting useful demandRun a controlled budget increase
    The campaign does not consistently spend its current budgetBudget is probably not the immediate constraintInvestigate demand, bids, eligibility, targeting, and creative
    Platform ROAS is high but downstream lead quality is weakThe optimization signal does not match business valueRepair tracking and feed stronger outcomes back into optimization
    Spend rises but qualified revenue stays nearly flatMarginal demand is weak or already exhaustedStop increasing budget and diagnose the expansion
    More orders create stock or service problemsThe constraint sits outside advertisingResolve operational capacity before buying more demand

    Do not treat a platform recommendation to spend more as sufficient evidence. It can identify delivery capacity, but your business data must determine whether that capacity is worth buying.

    Scale in stages with a written stopping rule

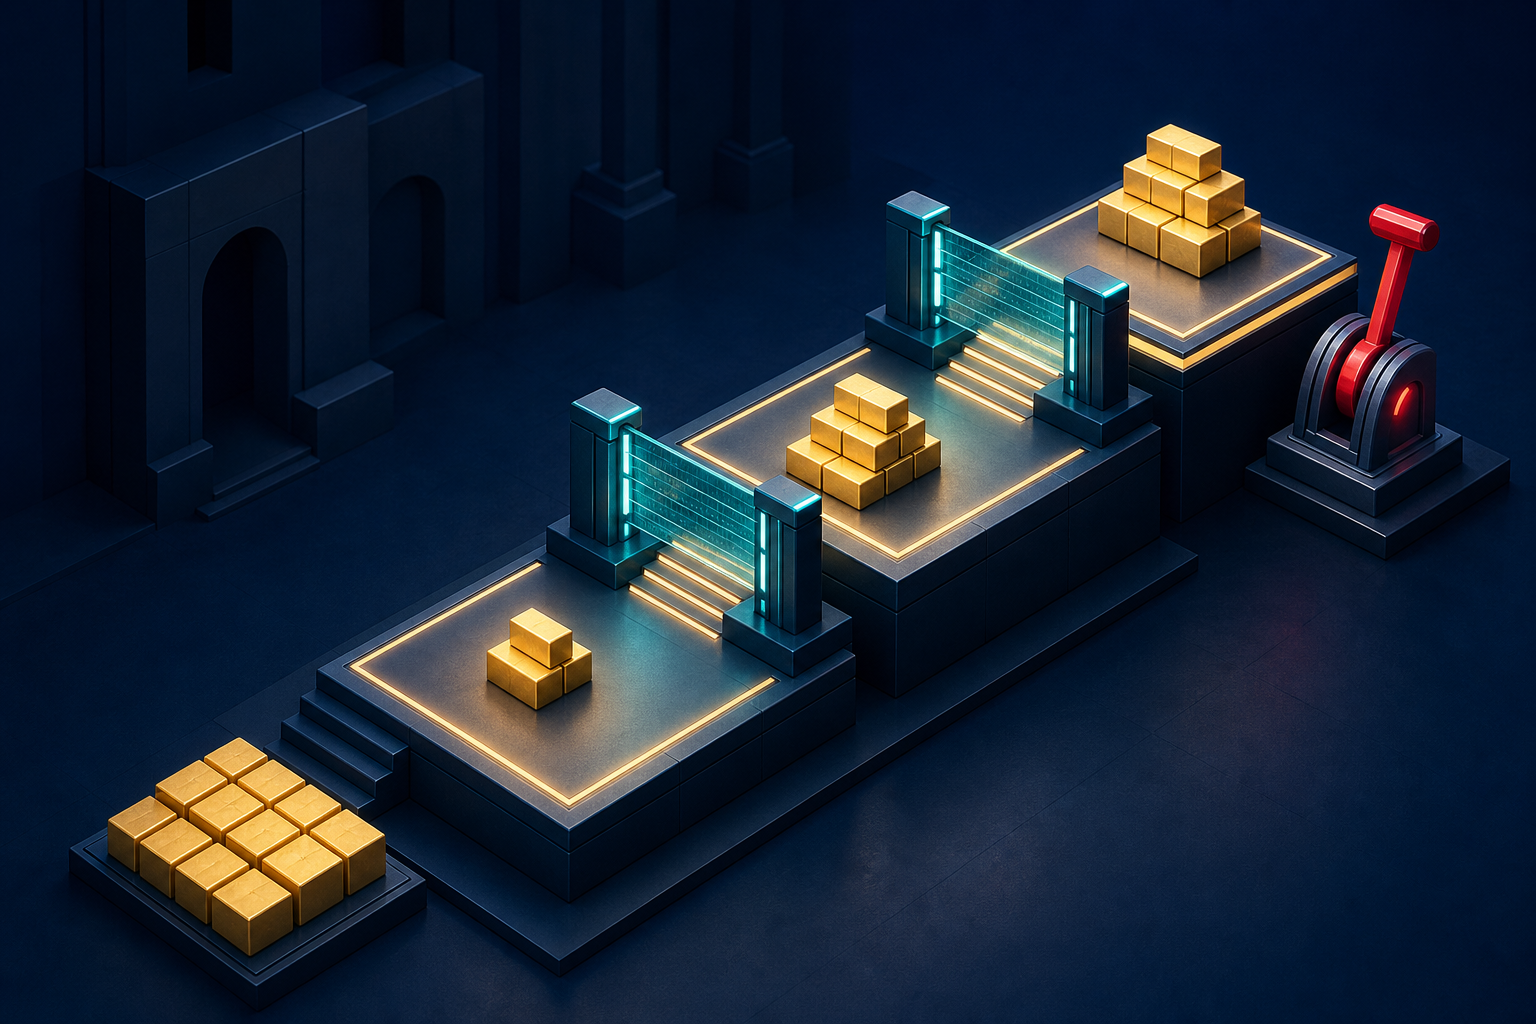
    Gold budget blocks move up three platforms with checkpoint gates, while a stop lever and reserve blocks sit nearby.

    Large budget changes can disturb a stable campaign and make the result harder to interpret. In Microsoft Advertising, changes beyond 15% may introduce volatility or a renewed learning period. Other platforms have their own behavior, so check the system you use and favor measured adjustments.

    1. Save the baseline. Record spend, qualified conversions, qualified revenue, profit, cost per acquisition, ROAS, and conversion volume before the change.
    2. Name the hypothesis. Write down why more budget should capture additional profitable demand. For example, the campaign is repeatedly constrained while downstream conversion quality remains stable.
    3. Set the guardrails. Define the minimum acceptable marginal ROAS or maximum acceptable acquisition cost. Include lead-quality or profit requirements where platform revenue is incomplete.
    4. Change the budget only. Keep bidding strategy, targeting, ads, landing pages, and conversion definitions stable. Otherwise, you will not know what caused the result.
    5. Allow the campaign to settle. Avoid reacting to an isolated day. Wait until you have enough conversion volume to compare the new period with the baseline while accounting for normal business conditions.
    6. Choose the next action. Increase again only if incremental volume meets the guardrails. Hold when the result is promising but uncertain. Reduce the budget when additional spend fails the profitability test.

    Document each change with its date, amount, rationale, and result. This creates a usable scaling history and prevents a sequence of undocumented increases from turning into a permanent efficiency loss.

    Read the result as a business decision

    A lower blended ROAS after scaling is not automatically a failure. Additional volume can justify some efficiency loss if the new customers or leads remain profitable. The decision depends on what happened at the margin.

    • Spend and qualified profit both rise: the campaign has demonstrated headroom. Consider another controlled increase.
    • Spend rises, revenue rises, but profit does not: you have crossed the economic limit. Return to the last profitable level or improve margins and conversion quality before testing again.
    • Spend rises but qualified volume barely changes: more budget is not solving the active constraint. Examine demand, auction eligibility, targeting, the offer, and the landing experience.
    • Platform conversions rise while sales outcomes weaken: the campaign is optimizing toward the wrong signal. Pause scaling and reconnect optimization to verified business outcomes.

    Your next budget increase should be earned by evidence. Establish the profit floor, verify headroom, make one controlled change, and fund the next step only when the additional spend produces business value.

    References

  • Paid Campaign Measurement and Creative Testing That Works

    Paid Campaign Measurement and Creative Testing That Works

    Your ad dashboard says performance is improving, but pipeline and revenue are standing still. That usually means the campaign is being rewarded for activity that looks valuable inside the platform, or your creative tests aren’t different enough to reveal what buyers actually respond to.

    You can fix both problems with one operating system: define the business outcome first, measure the additional value your spend creates, and test creative concepts before polishing minor variations.

    Start with the business decision, not the platform metric

    A useful measurement plan begins with a decision. Are you deciding whether to increase a campaign’s budget, pause an audience, promote a creative concept, or change the conversion signal used for bidding? The answer determines which metric deserves authority.

    Separate your metrics into three layers:

    LayerWhat it tells youExamples
    Business outcomesWhether paid media created commercially useful resultsQualified opportunities, pipeline, closed revenue
    Optimization signalsWhat the ad platform can use to improve deliveryQualified leads, sales-accepted leads, purchases
    Diagnostic metricsWhy delivery or response may have changedClicks, click-through rate, landing-page conversion rate, cost per lead

    Business outcomes judge success. Optimization signals help the system find more promising users. Diagnostic metrics help you investigate. Trouble starts when a diagnostic metric becomes the goal simply because it updates quickly.

    Audit every primary conversion before trusting the total. If one person is counted as a lead, a qualified lead, and a sales-qualified lead, the dashboard may show three conversions even though the business acquired one prospect. Assigning a value to every stage can compound the distortion and produce an inflated platform-reported return.

    Choose one primary outcome for each bidding objective. Keep earlier and later funnel events available for observation, but don’t automatically include all of them in the same optimization total. When the final monetary value arrives too late, use relative values that reflect the observed quality difference between stages, then validate those values against actual pipeline and revenue.

    Measure the next dollar, not just the average dollar

    Two parallel channels compare a gray baseline flow with a second flow that produces additional gold customer tokens after extra spend is added.

    Average CPA answers a historical question: how much did all recorded conversions cost on average? It doesn’t answer the budget question: what did the additional conversions cost when spending increased?

    For that, track marginal CPA. Compare two observed spending levels and divide the additional spend by the additional conversions. Run the same comparison with qualified opportunities or revenue when those outcomes are available. If spend rises while qualified output barely moves, the average can still look acceptable even though the latest budget increase was inefficient.

    Maintain a baseline for each campaign, audience, or market before changing spend. Then record what moved after the change:

    • Additional spend
    • Additional unique conversions
    • Additional qualified leads or opportunities
    • Additional pipeline or revenue
    • Marginal cost per additional business outcome

    This comparison is more useful than celebrating a higher conversion count in isolation. It exposes diminishing returns and shows where another unit of budget is likely to do useful work.

    Be precise about what the evidence proves. Mapping CRM outcomes to campaigns shows which paid interactions are associated with pipeline. A controlled holdout or other credible baseline is needed to make a stronger causal claim about incrementality. Don’t label every attributed conversion incremental.

    Test creative concepts before testing cosmetic variations

    A creative workshop table displays three distinctly different campaign concept sets, with a smaller group of nearly identical color variations pushed aside.

    Five ads with the same promise, image, and audience aren’t five meaningful tests because the text color changed. Platforms can recognize near-duplicate assets, and flooding an account with them can fragment the budget and slow learning.

    A concept changes why someone should care. It might lead with a different problem, motivation, objection, emotional trigger, proof mechanism, or format. An execution changes how that concept is expressed: the opening line, pacing, visual treatment, or call to action.

    Phase 1: Find a concept worth scaling

    Build each macro test around a written hypothesis. Complete these fields before production:

    • Audience tension: What problem, desire, or objection are you addressing?
    • Angle: What distinct reason are you giving the audience to act?
    • Expected behavior: What should improve if the hypothesis is right?
    • Business safeguard: Which downstream quality metric must not deteriorate?
    • Learning: What decision will you make if the concept wins or loses?

    Mine customer reviews, sales conversations, support questions, and social comments for recurring language and concerns. The production doesn’t have to be elaborate. A simple asset with a specific, resonant message can teach you more than a polished asset built around a weak premise.

    Phase 2: Improve the winning execution

    Once a concept demonstrates value, test its components. Change hooks, pacing, calls to action, or presentation while preserving the core angle. This is where additional variations become useful: they help you refine a validated idea rather than asking a limited budget to evaluate many nearly identical guesses.

    Connect creative learning to pipeline quality

    A creative winner should survive more than a click-through-rate comparison. The ad that attracts the most leads may attract the wrong leads, while a lower-volume concept may generate more qualified pipeline.

    Preserve the creative, campaign, and audience identifiers when a prospect enters your CRM. Without that connection, downstream results collapse into a channel total and you lose the information needed to improve the message.

    1. Give every concept a stable identifier that remains consistent across its executions.
    2. Pass campaign and creative identifiers into the lead or customer record.
    3. Deduplicate people before counting funnel stages.
    4. Return qualified and revenue outcomes to your reporting system.
    5. Compare concepts on both response and downstream quality.
    6. Increase budget only when the additional business outcome remains economically sensible.

    This prevents two common mistakes: scaling ads that generate cheap but weak leads, and killing ads that produce fewer conversions but more valuable opportunities. CRM-to-campaign mapping is what lets you see the difference.

    Review creative and measurement together. Ask whether the concept was genuinely distinct, whether it received enough concentrated delivery to generate a useful signal, whether its downstream quality held up, and whether the next budget increase created enough additional value.

    Key takeaways

    • Use business outcomes to judge performance, optimization signals to guide delivery, and diagnostic metrics to explain changes.
    • Deduplicate funnel events so one prospect doesn’t become several conversions.
    • Compare marginal cost and incremental outcomes before increasing a campaign’s budget.
    • Test distinct creative concepts first, then refine the winning concept with execution-level variations.
    • Carry campaign and creative identifiers into the CRM so lead volume can be evaluated against pipeline quality.

    For your next review, pick one campaign and one creative concept. Reconcile its primary conversion with the CRM, calculate what the latest spend increase produced, and write the next creative hypothesis before requesting another batch of assets. That small discipline will make both your reporting and your testing more trustworthy.

    References

  • How to Read Paid Search Signals in Conversational AI Ads

    How to Read Paid Search Signals in Conversational AI Ads

    Your PPC dashboard can look healthy while campaign economics are already changing. A rival may be bidding harder, presenting a stronger offer, or taking more search-result space. At the same time, conversational AI may be qualifying prospects inside the ad experience before your landing page sees them.

    That changes what you need to watch. Clicks and form fills still matter, but they no longer explain the full journey. You need to separate auction pressure, conversational quality, and real business value before changing bids or budgets.

    Key takeaways

    • Treat CPC, impression share, and visibility changes as alerts. Diagnose the cause before reacting.
    • Track competitor bidding, branded-query entrants, offers, messaging, ad frequency, and search-result coverage alongside your campaign metrics.
    • Judge conversational ads by the quality of the business outcomes they create, not merely by clicks or interaction volume.
    • Send accepted-lead, opportunity, sale, and revenue data back into the advertising system whenever your setup supports it.
    • Define where automation can explore and where a person must approve claims, offers, targeting changes, or budget shifts.

    Read the signal stack from auction pressure to revenue

    Start with the auction

    Rising CPC, declining impression share, weaker visibility, and new advertisers on branded searches can reveal changing competition before the damage reaches revenue. These movements may appear days or weeks before a visible performance decline.

    None of those metrics explains itself. A CPC increase can reflect more aggressive bidding, but it does not tell you whether the additional pressure affects valuable searches. A visibility decline may matter on a core commercial query and be harmless on exploratory traffic. Segment the change by campaign, query theme, brand versus non-brand demand, device, and geography before choosing a response.

    Inspect the conversation

    A conversational ad can let a prospective customer ask about services or pricing without following the familiar click, landing page, and form path. That interaction creates a new diagnostic layer. The questions people ask can reveal uncertainty about fit, cost, availability, proof, or the next step.

    Use whatever interaction reporting the platform makes available, but do not mistake activity for success. A busy conversation that produces unsuitable inquiries is not better than a quiet one that produces qualified opportunities. Connect question themes and handoffs to downstream outcomes wherever privacy, consent, and platform controls allow.

    Follow the outcome into your business

    A form submission is an advertising event. An accepted lead, booked appointment, opportunity, sale, or renewal is a business result. If the bidding system sees only the first event, it may learn to find more inexpensive forms even when your sales team rejects them.

    This is why CRM integration and offline conversion tracking become more important as automation expands. AI can optimize only against the information it receives. Pass back the deepest reliable outcome your sales cycle supports, and distinguish valuable outcomes from weak ones instead of assigning every conversion the same meaning.

    Account for the model interpreting those signals

    Lead intent scores, journey-aware bidding, predictive attribution, and AI Max move decision-making beyond visible keyword-to-conversion paths. AI Max can explore demand beyond familiar targeting patterns, while predictive measurement can connect exposure with later behavior. Those capabilities may uncover growth, but they also make weak data and unclear goals more consequential.

    Keep a written record of the outcome being optimized, the data supplied to the system, and the decisions delegated to automation. When performance moves, you will know whether to investigate the market, the conversation, the business data, or the model interpreting it.

    Use a signal map instead of reacting to isolated metrics

    An isometric map connects auction competition, branching AI conversations, and customer value while isolated signal fragments sit at the edges.

    A useful monitoring view pairs every warning sign with a plausible explanation, a verification step, and a limited response. This prevents a single red metric from triggering an account-wide change.

    SignalWhat it may meanWhat to check firstPractical response
    CPC rises while impression share or visibility fallsCompetitors may be bidding more aggressively on important demandQuery value, competitor coverage, budget constraints, and brand versus non-brand movementDefend commercially important demand rather than raising bids across the account
    A new advertiser appears on branded searchesA competitor may be trying to intercept high-intent prospectsBrand query coverage, ad distinction, impression share, and landing experienceProtect valuable brand demand and make your official offer unmistakable
    CTR or conversion rate falls after rival messaging changesYour proposition may look less relevant or less attractiveOffer, call to action, proof, pricing context, and search-result assetsTest a clearer value proposition based on customer needs rather than copying the rival
    A competitor occupies more extensions, shopping placements, or other formatsYour visibility may be compressed even if rank appears stableAsset eligibility, format coverage, feed quality, and query intentAdd formats that genuinely fit your inventory and the searcher’s task
    Conversion volume holds while accepted leads or revenue declineAutomation may be finding cheap actions instead of valuable customersCRM stages, offline imports, outcome definitions, and value mappingRepair the business signal before expanding targeting or budget
    Conversation activity rises without stronger qualified outcomesThe interaction may expose friction, attract poor-fit demand, or use incomplete business contextAvailable question themes, answer accuracy, qualification logic, and handoffsImprove the approved answer set and route uncertain cases to the right next step

    Interpret related signals together. Rising CPC with stable qualified revenue may be acceptable if the economics remain within your target. Growing form volume with declining accepted-lead quality is a stronger warning, even if the advertising dashboard labels the campaign successful.

    Prepare your offer for questions, not only clicks

    A customer follows a path of question bubbles while modular offer elements rearrange before a landing-page doorway.

    A click-focused ad makes a promise and sends the user elsewhere for detail. A conversational ad may need to explain fit before the visit. Give the system a consistent, approved business context covering audience fit, service availability, pricing context, exclusions, evidence, and the next step.

    Start with the questions that determine whether someone should continue. Can you serve this location? Is the service appropriate for this type of need? What affects price? What is not included? What should the person do if the standard path does not apply? Clear answers can prevent poor-fit inquiries without forcing the AI to improvise.

    Consistency matters across the ad conversation, landing page, sales script, and CRM. If the ad implies instant availability while the landing page describes a waiting period, you have created friction before the lead reaches a person. If pricing language changes between surfaces, you may attract interest that cannot survive qualification.

    Finance, healthcare, and other trust-critical businesses need tighter controls. Use approved language for sensitive claims, define what the system must not infer, and provide a human escalation path when a question falls outside the approved context. The goal is useful qualification, not unrestricted improvisation.

    AI-assisted creative production can reduce the effort required to make and test assets, but easier production does not create differentiation by itself. As more advertisers gain similar tools, brand strategy, audience understanding, and a defensible offer carry more of the load.

    Respond without teaching automation the wrong lesson

    Validate the cause. Pair the alert with evidence from another layer. If CPC rises, look for competitor expansion and check whether qualified acquisition cost or revenue changed. If lead quality falls, inspect the conversion signal and conversation path before blaming the auction.

    Contain the exposure. Protect branded searches and the non-brand demand that reliably creates value. Avoid using an account-wide budget increase to solve pressure limited to a narrow query group. Expand ad formats only where they help you answer the searcher’s task or recover useful visibility.

    Correct the weakest input. Auction pressure may call for tighter bidding or stronger coverage. A relevance problem may call for a clearer offer. Poor conversational qualification may call for better answers and handoffs. Weak business optimization requires better CRM and offline conversion data before more automation is added.

    Test with a clean decision rule. Change a single major variable at a time when practical, state the business outcome you expect to improve, and record competitor conditions during the test. Otherwise, a market change can look like a successful creative test, or an improved offer can be hidden by a sudden auction surge.

    Keep human control over strategy. Automation can explore targeting, predict intent, and assemble creative. You still need to decide which customers matter, which outcomes deserve value, which claims are acceptable, and when efficiency has become dependence on an opaque forecast. Lead-generation campaigns without reliable offline data face particular risk when AI-driven exploration expands beyond familiar campaign paths.

    On your next campaign review, add competitor movement, conversational friction, and accepted business outcomes beside the usual PPC metrics. Require every bid, budget, creative, or automation change to name the layer it addresses and the downstream result it should improve. That is how you keep conversational advertising from turning a signal problem into a spending problem.

    References

  • How to Evaluate AI-Powered Advertising Platforms

    How to Evaluate AI-Powered Advertising Platforms

    You’re probably not deciding whether AI belongs in advertising. You’re deciding how much of your budget, product catalogue and campaign analysis you can safely hand to it.

    The useful question is not, “How advanced is this platform?” It is, “Which decision will this platform improve, what data will it use, and what can it change without approval?” Answer those three points before you compare features.

    Key takeaways for your platform decision

    • Separate AI that explains performance from AI that creates or delivers ads. The second category carries more financial and brand risk.
    • Treat your product feed, conversion events and campaign rules as operating inputs, not setup details. Automation scales their errors as readily as their strengths.
    • Use prompt-driven dashboards to shorten investigation time, but verify filters, totals and metric definitions before changing spend.
    • Test one bounded workflow at a time. Define its inventory, budget, approval rights, primary outcome and stop condition before launch.
    • Judge the platform on business outcomes and control, not on how quickly it produces an ad, chart or answer.

    Separate decision support from automated execution

    “AI-powered advertising” describes several different jobs. Combining them into one category makes platform evaluations fuzzy and permissions unnecessarily broad.

    AI roleWhat you provideWhat it producesMain risk to check
    Reporting and interpretationAccount data, a question and reporting filtersA chart, table, breakdown or explanationA plausible answer built on the wrong scope, filter or metric
    Ad assemblyProduct data, images, attributes and eligibility rulesAds assembled from approved inputsIncorrect or unsuitable catalogue data appearing at scale
    Delivery and optimizationA budget, objective, conversion signal and constraintsBids, placements or allocation decisionsSpend being optimized toward a weak or misconfigured signal

    Google Ads’ Gemini-powered dashboards sit primarily in the first row. Advertisers can use prompts to customize views, while the dashboard presents performance through charts, graphs and tables that update with the query. That can reduce the work required to reach a useful breakdown, but it does not give the dashboard permission to define your business objective.

    ChatGPT’s product-feed advertising moves further into execution. Retailers can connect catalogue data so the system can assemble sponsored product ads from names, images and other attributes. Retailers can also set rules governing which products may be featured. Here, data quality and eligibility rules directly affect what a prospective buyer can see.

    Before granting access, write down four permission levels: read, recommend, create and spend. A reporting assistant may need only read access. A product-ad system needs approved data plus creation rules. A bidding system needs a tightly defined budget and a trustworthy conversion signal. Do not grant all four levels merely because one integration supports them.

    This distinction also clarifies ownership. Your analyst can own reporting questions. Merchandising should own product eligibility. Marketing and finance should agree on spend limits. Whoever owns the business outcome should approve the conversion definition. “The AI team owns it” is not an operating model.

    Audit the data contract before evaluating the AI

    Two analysts inspect customer, product and campaign data moving through a transparent pipeline with permission, quality and verification controls.

    An automated platform can only act on the facts and signals it receives. If a product is misidentified, an image is stale or a conversion fires at the wrong moment, faster automation creates a faster version of the wrong campaign.

    For a feed-based commerce channel, inspect the feed as a contract between your catalogue and the advertising system. Review it in the same form the platform will receive it, not only as it appears in your storefront.

    1. Confirm item identity. Each product and variant should be distinguishable. If two records appear identical to a machine but represent different options, ad assembly can select the wrong one.
    2. Check customer-facing facts. Review names, images and every connected attribute for accuracy. Compare the resulting destination page with the feed record so the promise in the ad matches the page.
    3. Define eligibility explicitly. Create rules for products that may be advertised and exclusions for products that should not be. Do not rely on someone remembering to remove an unsuitable item manually.
    4. Assign update ownership. Name the system or person responsible for correcting catalogue facts. A feed without a clear owner becomes stale infrastructure.
    5. Design failure handling. Decide whether questionable or incomplete records are excluded, held for review or corrected upstream. Silent substitution is a poor default when brand or pricing information is involved.
    6. Keep an audit trail. Record which feed version, rules and approvals were active when an ad ran. Without that record, you cannot separate a platform problem from an input problem.

    This matters beyond paid placement. ChatGPT’s model allows product information to support both answers and advertising, connecting organic product discovery with a paid campaign workflow. The operational lesson is larger than one channel: machine-readable product facts are becoming shared discovery infrastructure.

    Your product feed and on-page structured data should therefore agree, but do not treat them as interchangeable. A channel feed supplies data to a specific system. JSON-LD describes information on a page in a machine-readable form. Keep names, product identity, images and other shared facts consistent across both, while using the integration method the advertising platform actually documents. Do not assume that publishing schema automatically enrols a product in an ad programme.

    For non-commerce campaigns, the equivalent data contract is your measurement setup. Identify the event that represents the business result, the events that are merely steps toward it and the system responsible for recording each one. If the platform sees a click but not the qualified action that follows, it may become efficient at producing visits without becoming effective at producing customers.

    Use conversational dashboards as an investigation layer

    Prompt-driven reporting changes how you reach a view, not what makes that view trustworthy. A natural-language interface can remove report-building friction, but the underlying questions still need a metric, dimension, scope and comparison.

    The Gemini-powered Google Ads dashboard is designed to show metrics including impressions, clicks, video views and costs across devices, audiences and campaign types. Those combinations are useful because they let you move from “performance changed” to “where did it change?”

    Use prompts that describe a reporting operation. The following are question shapes to adapt, not guaranteed platform commands:

    • Show impressions, clicks and cost by device for the selected campaign type.
    • Break down video views and cost by audience, using the same campaign scope.
    • Compare clicks and cost across campaign types, then isolate the segment responsible for the largest difference.
    • Keep the same metrics and change only the device breakdown so the two views remain comparable.

    The discipline is in changing one analytical dimension at a time. If you alter the metric, campaign scope and audience definition in the same prompt, you may get an attractive chart without knowing which change produced the result.

    Build a short verification routine around every consequential finding:

    1. Read back the date range, campaign scope, filters and dimensions shown in the resulting view.
    2. Check the displayed total against the corresponding native account report before moving budget.
    3. Confirm that compared views use the same definitions and aggregation.
    4. Save the prompt or question alongside the resulting filters. Natural-language wording is part of the analysis and should be reproducible.
    5. Translate the observation into a testable hypothesis. “Mobile cost increased” is an observation; it is not yet an instruction to reduce mobile spend.

    Prompted reporting is most valuable when it shortens the path from a broad symptom to a precise segment. It is less useful when it becomes a substitute for measurement definitions or causal testing.

    Access and exact behaviour also need verification. The dashboard rollout was introduced with further details still expected at Google Marketing Live. Check what is available in your own account before retiring a custom report or external analytics workflow on the assumption that every required capability has arrived.

    Run a bounded pilot before expanding authority

    A campaign manager monitors a small AI advertising pilot enclosed by a transparent boundary, with human controls separating it from a larger campaign network.

    A good pilot answers a decision, not merely whether the software works. “The platform generated ads” proves that the integration ran. It does not prove that the ads reached appropriate buyers, produced incremental value or justified broader automation.

    1. Name one workflow. Test prompt-driven account diagnosis, feed-based ad assembly or automated delivery separately. Combining them makes failures hard to locate.
    2. Write the decision statement. Specify what you will expand, change or stop if the test succeeds or fails.
    3. Capture the existing process. Record its inputs, human effort, approval path and outcome metrics. Otherwise, “faster” and “better” have no comparison point.
    4. Limit exposure. Use a defined campaign or approved product subset, a controlled budget and explicit permissions. Automated advertising can spend real money or expose incorrect catalogue information, so set pause conditions before activation rather than during an incident.
    5. Lock the measurement contract. Choose one primary business outcome and document the conversion event, reporting source and attribution configuration used to evaluate it. Keep clicks, impressions, views and cost as diagnostic metrics rather than automatically treating them as success.
    6. Log human intervention. Record feed corrections, prompt revisions, exclusions, bid changes and manual pauses. A result that depends on constant rescue is not evidence of autonomous performance.
    7. Decide explicitly. Scale, revise, hold or stop. Do not let a pilot become permanent simply because nobody scheduled the decision.

    Match the test to capabilities that exist, not capabilities on a roadmap. ChatGPT’s advertising direction includes cost-per-click bidding and conversion tracking, while cost-per-action models were reported as still in development. A future buying model should not be included in the business case for a current pilot.

    Ask vendors and internal owners the same practical questions before you approve expansion:

    • Which source fields and conversion signals drive the system’s decisions?
    • Can you exclude products, audiences or campaign types without rebuilding the workflow?
    • Which actions require human approval, and which occur automatically?
    • Can you export the underlying data and reproduce a reported result outside the conversational interface?
    • How are sponsored placements distinguished from organic recommendations? In ChatGPT’s current product-ad format, the units appear beneath responses and remain labelled as sponsored.
    • What happens when feed data, conversion tracking or an integration becomes incomplete?
    • Can you pause execution without losing the configuration and evidence needed for review?

    Your next move should be narrow. If you manage a catalogue, audit one approved feed segment and its page-level structured data. If you manage campaigns, choose one recurring reporting question and test whether a prompted dashboard answers it accurately and reproducibly. Write the outcome, permissions and stop condition first. Broader authority should follow evidence, not the ease of the interface.

    References

  • Google Ads Tag Manager Integration: A Safe Workflow

    Google Ads Tag Manager Integration: A Safe Workflow

    You open Google Ads to investigate a conversion problem, but the change itself lives in Tag Manager. That usually means switching tools, reconstructing the implementation, and finding out who is allowed to publish.

    Embedded Tag Manager controls can shorten that path. They don’t make tagging risk-free, however. If you can manage tags from Google Ads, you still need a controlled way to inspect, test, approve, publish, and verify every change.

    What the integration changes – and what it does not

    Inside Google Ads Data Manager, an observed Manage action for a connected Tag Manager source opens embedded controls. That puts campaign configuration, data connections, and at least some tag-management actions closer together.

    The immediate benefit is less navigation. A marketer investigating campaign measurement may be able to reach the relevant Tag Manager controls without leaving Google Ads. That can be especially useful for a small team that doesn’t have a developer available for every routine inspection.

    Don’t read the shared interface as a merger of the underlying responsibilities. Your website or app still produces the action and its data. Tag Manager still decides whether a tag should fire and what it should send. Google Ads still receives and uses the resulting signal. Moving the controls closer together doesn’t remove any of those layers.

    The functional scope also appears unsettled. It isn’t yet clear whether the complete Tag Manager experience will be embedded or whether Google Ads will expose only selected management actions. Availability may vary while the interface is surfacing. Treat the embedded view as a convenient entry point, not as proof that every preview, permission, versioning, or troubleshooting function is present.

    That distinction gives you a simple rule: use the embedded controls when they show enough context to make the change safely. Move to the full Tag Manager interface when you can’t see the trigger logic, variables, testing state, version history, permissions, or rollback path you need.

    Run each tag change as a controlled measurement release

    A geometric tracking module passes through inspection, testing, peer review, a guarded release gate, and final verification.

    The dangerous part of tag management isn’t opening the right interface. It is publishing a plausible-looking change without proving what will happen. A conversion tag that fires twice can inflate results. A trigger that stops matching can interrupt measurement. Either problem can distort campaign decisions and obscure whether performance actually changed.

    Use the same release sequence whether you start in Google Ads or Tag Manager:

    1. Define the business action. Write one sentence describing what should count. Name the user action, the point at which it qualifies, and any value or category the implementation must carry. “Track leads” is too vague; distinguish a successful submission from a form view, button click, validation error, or duplicate confirmation-page load.
    2. Map the existing path before editing it. Identify what the site emits, which trigger listens for it, which tag sends it, and which Google Ads destination expects it. Check for another site-installed tag or container that may already send the same action.
    3. Confirm that the available controls are sufficient. The embedded surface is appropriate only if it exposes the objects and context required for your task. If you can’t inspect dependencies or run your normal preview process there, continue in the full Tag Manager interface.
    4. Make one scoped change. Avoid combining a trigger repair, naming cleanup, consent adjustment, and destination change in one release. A narrow change is easier to test and much easier to reverse.
    5. Test qualifying and non-qualifying behavior. Prove that the intended action fires once. Then test a page view without the action, a failed or abandoned action, repeated interaction, and any relevant consent states. Confirm the destination identifiers and variable values, not merely that some tag fired.
    6. Publish with a useful record. Record what changed, why it changed, who approved it, what was tested, and which version can be restored. A label such as “tag fix” won’t help during a later incident.
    7. Verify the receiving side. After publishing, repeat the action in a controlled test and check both the tag behavior and the Google Ads side. Allow for normal processing delay before concluding that a working tag is broken, but don’t use that delay as a reason to skip implementation-level evidence.

    Keep screenshots or a short test log for material conversion changes. The useful evidence is specific: the scenario tested, the event or input observed, the trigger result, the tag result, the destination used, and the version published. This makes a future discrepancy diagnosable instead of debatable.

    Consent behavior deserves its own test case. Opening Tag Manager from Google Ads doesn’t change what a visitor permitted, what your configuration allows, or what your organization is responsible for. If the correct behavior is unclear, pause the release and involve the person responsible for privacy requirements and consent implementation.

    Keep ownership clear when the interfaces converge

    The integration reduces tool switching, but it may also blur who owns a measurement change. Access to a Manage control is not the same as authority to publish. Decide that boundary before someone is troubleshooting a live campaign.

    A workable division of responsibility looks like this:

    • The campaign owner defines what the conversion means, confirms the correct Google Ads destination, and checks whether reporting matches the intended business action.
    • The Tag Manager owner maintains tags, triggers, variables, naming, preview evidence, versions, and publishing discipline.
    • The site or app owner controls the event and data produced by the user experience. This person fixes missing, unstable, or incorrectly populated data at its origin.
    • The privacy owner defines the applicable consent requirements; the implementation owner translates those requirements into testable behavior.

    One person may fill several of these roles on a small team. The roles still need to be named. Otherwise, the person who can reach the control becomes the person assumed to understand every downstream consequence.

    Set three permissions explicitly: who may inspect, who may edit, and who may publish. Inspection can be broad. Publishing should stay with people who can evaluate the implementation, its consent behavior, and its effect on campaign measurement.

    Your handoff record can be brief, but it should connect the systems. Include the business event, affected container or version, changed tag and trigger, Google Ads destination, test evidence, publisher, and rollback point. That record prevents Google Ads and Tag Manager from becoming two separate stories about the same conversion.

    Diagnose the failing layer before changing anything

    A technician inspects an isolated break in one layer of a stacked digital conversion-tracking system.

    When a conversion disappears or looks inflated, start at the user’s action and move downstream. Don’t begin by republishing tags or changing campaign settings. Each speculative change introduces another variable and can erase the evidence you need.

    LayerQuestion to answerWhat a failure usually requires
    Site or appDid the qualifying action produce the expected event and values?Repair the event, data, or user-flow behavior at its origin.
    Tag Manager triggerDid the intended trigger match, and did non-qualifying actions stay excluded?Correct trigger conditions or the variables they evaluate.
    Tag executionDid the correct tag fire once with the intended identifiers and values?Correct tag configuration, duplicates, runtime problems, or consent-dependent behavior.
    Google Ads connectionWas the signal sent to the intended Ads destination?Check the destination configuration and the connection between the systems.
    ReportingIs the received signal being interpreted as the business expects?Separate an implementation problem from a reporting or attribution interpretation.

    This order matters. If the site never emitted the event, changing a Tag Manager trigger won’t create reliable source data. If the trigger and tag worked but the destination was wrong, rewriting the site adds risk without addressing the failure.

    Duplicate conversions require the same discipline. Reproduce the action once, then look for multiple matching events, repeated trigger matches, multiple tags targeting the same destination, and parallel installations outside the container. Don’t delete the first duplicate-looking tag you find until you know which implementation is authoritative and what else depends on it.

    For a missing conversion, capture evidence at each boundary: the action occurred, the event existed, the trigger matched, the tag executed, and the intended destination received the signal. Stop at the first failed boundary. That is where the next investigation belongs.

    After a website release, repeat the same path before blaming Google Ads. Changes to forms, confirmation states, URLs, element selectors, or data structures can invalidate trigger assumptions even when the container itself hasn’t changed. The tag configuration may be unchanged and still no longer match the site.

    Key takeaways

    • Embedded Tag Manager controls shorten the route from a Google Ads measurement problem to the relevant management surface.
    • The shared interface doesn’t collapse the site, tag, destination, consent, and reporting layers into one system.
    • Use the full Tag Manager interface whenever the embedded view lacks the context, testing, permissions, versioning, or rollback controls needed for a safe release.
    • Define inspection, editing, and publishing permissions separately; visible controls should not silently redefine ownership.
    • Troubleshoot from the user action downstream, stopping at the first boundary where the expected evidence disappears.

    If the Manage option is available in your account, start with inspection rather than a live edit. Choose one important conversion, map its complete path, document its current owner, and run the qualifying and non-qualifying tests. That gives you a safe baseline for deciding which future tasks belong in Google Ads and which still need the full Tag Manager workflow.

    References

  • How to Test Emerging Ad Platforms With Better Measurement

    How to Test Emerging Ad Platforms With Better Measurement

    You have access to a promising new ad placement, the first click-through rates look excellent, and someone wants to know whether to increase the budget. That is exactly when measurement discipline tends to slip. A strong dashboard number feels like an answer even when it only describes the first step in the journey.

    Your real task is to determine whether the platform creates valuable outcomes that would not otherwise happen, whether those outcomes remain economical as the test expands, and whether the available inventory can absorb more spend. This framework helps you answer those questions without expecting one attribution model to do every job.

    Separate channel discovery from budget proof

    An emerging platform can be interesting before it is investable. That distinction matters because discovery metrics and budget metrics answer different questions.

    Click-through rate tells you whether people respond to a placement. It does not tell you whether the resulting customers are profitable, whether the ad caused those customers to act, or whether similar performance will survive broader distribution. This is especially important for conversational advertising, where early engagement has been strong but inventory and testing remain limited.

    Run the test as a sequence of decisions. Each decision requires different evidence:

    DecisionEvidence to inspectWhat it does not prove
    Does the placement attract attention?Impressions, clicks, click-through rate, and engagement by query or audience segmentThat the attention creates business value
    Does the traffic produce the right outcome?Purchases, qualified leads, subscriptions, revenue, lead quality, and downstream completionThat the advertising caused the outcome
    Is the outcome incremental?Holdout testing, geo experimentation, or another credible counterfactualThat the same return will persist at a larger spend level
    Can the platform scale efficiently?Available inventory, spend delivery, reach, frequency, conversion quality, and cost as exposure expandsThat it improves the entire media portfolio
    Should the portfolio budget change?Experiment-calibrated media mix modeling alongside commercial constraintsThat every individual conversion can be assigned to one touchpoint

    This separation protects you from two common mistakes. The first is rejecting a potentially useful channel because it has not yet accumulated enough evidence for a permanent budget allocation. The second is scaling it because a high early click-through rate has been mistaken for incremental profit.

    Label the stage of the evidence in every internal update. Use plain terms such as discovery signal, conversion signal, incremental evidence, and scale evidence. If the team only has a discovery signal, say so. That small piece of language prevents a preliminary result from hardening into a forecast.

    Write the measurement contract before the first impression

    Hands arrange matching campaign materials into separate test and control areas on a measurement planning table.

    A measurement plan should be a decision contract, not a list of every metric the platform can export. Write it before launch so the team cannot redefine success after seeing the results.

    1. Name one primary business outcome. Choose the event closest to value that the test can credibly observe: a completed purchase, a qualified opportunity, a subscription, or another commercially meaningful result. Keep clicks and engagement as diagnostics unless attention itself is the campaign objective.
    2. State the causal question. Write what you are trying to learn in counterfactual terms: how many desired outcomes occurred because the ads ran, beyond what would have happened without them? This wording exposes the limit of ordinary attribution before anyone treats credited conversions as incremental conversions.
    3. Define the test unit. Decide whether results will be examined by query theme, audience, geography, product, offer, creative, or another controlled unit. The unit must match the mechanism you expect to drive performance.
    4. Set the comparison rules. Document the conversion definition, attribution window, revenue basis, treatment of returns or cancellations, and handling of duplicate records. Use the same definitions for the emerging platform and the benchmark channel.
    5. Choose guardrails. Track conversion quality, acquisition cost, spend delivery, reach concentration, and any operational consequence such as low-quality leads. A channel that creates more form submissions but overwhelms sales with poor prospects is not passing the business test.
    6. Predeclare the verdicts. Specify what evidence would justify scaling, continuing the test, pausing for an instrumentation repair, or stopping. Your thresholds should come from the economics of your own business rather than a generic platform benchmark.

    The contract also needs a data lineage section. For every result, record where the event originates, how it is passed, which identifier joins it to campaign data, and which system is authoritative when two systems disagree. If a purchase appears in the ad platform but not in the commerce system, the team should already know which record governs the decision.

    Do not postpone this work until reporting begins. Missing identifiers and inconsistent event definitions cannot always be repaired after exposure has occurred. If the primary outcome is not reliably captured, pause the test and fix the measurement path before buying more traffic. Otherwise, additional spend produces a larger dataset without producing a better answer.

    Read early AI ad performance without fooling yourself

    Conversational ads may appear beside a response at the moment a user is expressing a need. That context can make the placement feel more relevant than an interruptive format. It also creates several reasons for early results to look unusually strong.

    Intent mix is the first reason. Prompts about Mother’s Day have been observed to trigger ads about three times more often than the overall average. A test concentrated in gift-seeking conversations is not representative of every prompt, product category, or stage of the buyer journey. Report results by intent class instead of averaging all conversations into one channel-wide figure.

    Format novelty is the second reason. People may inspect a new placement because they have not seen it before. You cannot prove that novelty caused the clicks from an initial campaign, but you can watch for the pattern. Repeat the test across cohorts or campaign waves, keep the offer and conversion definition stable, and check whether engagement and downstream quality hold as the format becomes more familiar.

    Inventory selection is the third reason. Limited supply can concentrate delivery in the prompts, advertisers, or use cases most likely to perform. Expansion may introduce weaker contexts, more competition, and different pricing. Track how much of the planned budget is actually delivered, where impressions cluster, whether new query categories enter the mix, and how acquisition cost changes as spend rises. A channel that cannot spend the approved amount is not yet a scalable acquisition engine, even if its small pool of impressions performs well.

    The comparison channel matters too. Early conversational-ad click-through rates have exceeded display and podcast benchmarks, but that comparison describes engagement, not equivalent economics. Search, paid social, display, podcast advertising, and conversational placements differ in intent, buying method, inventory, and the role they play in a journey. Compare them on the same final outcome and accounting basis before moving budget.

    At the review meeting, force the result into one of four decisions:

    • Scale: the primary business outcome meets the predeclared requirement, the evidence supports incrementality, data quality is intact, and the platform has enough inventory to test a higher spend level.
    • Continue testing: engagement and conversion quality are promising, but incrementality, pricing stability, or inventory depth remains uncertain. Name the next uncertainty and design the next test specifically around it.
    • Pause and repair: event loss, inconsistent definitions, broken joins, or missing downstream outcomes make the result unreliable. Fix the data path before resuming.
    • Stop: the test has enough reliable evidence to show that the business outcome does not meet your requirement, or repeated expansion causes economics or conversion quality to deteriorate beyond the accepted limit.

    “Promising” is not a fifth verdict. It is a description that must be followed by a specific next decision.

    Build an evidence ladder instead of trusting one model

    An abstract ladder of measurement methods rises from raw signals to a verified outcome, with several evidence paths converging near the top.

    No single measurement method can tell you whether an ad was served correctly, influenced an individual journey, created incremental demand, and deserves a larger share of the portfolio. Use a ladder in which each layer answers a narrower question and checks the layers below it.

    Layer 1: instrumentation and platform diagnostics

    Start with clean event collection. Connect ad delivery, site or app behavior, commerce results, and CRM outcomes. Preserve campaign identifiers where possible, deduplicate events, and reconcile totals against the system that records the actual transaction or qualified lead.

    The direction of Google’s tooling shows how central this plumbing has become. Data Manager is being expanded with a map-based view of connections involving systems such as BigQuery, HubSpot, and Shopify, while Google tag changes are intended to extend existing setups without requiring additional code. The useful principle is broader than any vendor: make the flow of data visible enough that a marketer can locate a missing connection before it distorts a campaign decision.

    Platform reports remain useful at this layer. They help you diagnose delivery, creative response, query mix, and conversion paths. Treat attributed conversions as claims that need reconciliation, not as automatic proof of causality.

    Layer 2: controlled experiments

    An experiment estimates the counterfactual that ordinary attribution cannot observe. A holdout keeps an eligible group from receiving the treatment. A geo experiment varies advertising across comparable regions and evaluates the difference in business outcomes. Neither method is a decorative validation step. It is the evidence used to decide how much of the platform-reported performance is genuinely incremental.

    Google’s Meridian GeoX reflects this shift toward causal validation. It is built on an open-source framework and connects geo experimentation with the broader Meridian media mix modeling system. For your team, the practical lesson is to plan experimentation and portfolio modeling together. Experimental results can challenge an attribution narrative and provide a firmer basis for calibrating broader budget models.

    Choose an experimental design only when the platform and your market provide a defensible control. If exposure leaks heavily between groups, the regions behave differently for unrelated reasons, or the outcome volume is too sparse to distinguish change from noise, do not dress the result up as causal proof. Document the limitation and continue at the lower rung of the evidence ladder.

    Layer 3: media mix modeling

    Media mix modeling examines aggregated changes in spend and outcomes across channels and time. It is suited to portfolio questions: how channels work together, how budget shifts may affect total results, and where marginal investment may be more productive. It does not need to identify a single ad as the exclusive cause of a single purchase.

    An emerging channel may initially be too small or too stable in spend for a portfolio model to isolate reliably. That is not a reason to invent precision. Use controlled testing to establish an initial incremental read, create meaningful and documented variation when expanding the channel, and add it to the model when the underlying data can support the distinction.

    Google is also working to reduce the operational burden of this layer through Meridian Studio, a Google Cloud-powered environment for building, customizing, and scaling media mix models. Easier tooling does not remove the need for sound inputs, transparent assumptions, or experimental checks. A faster model built on inconsistent revenue, incomplete spend, or unexplained tracking changes is still an unreliable model.

    Keep a measurement change log alongside the model. Record tag updates, consent changes, platform launches, campaign restructures, pricing changes, promotions, and breaks in source data. When performance moves, this log helps you distinguish a market effect from a measurement artifact.

    Key takeaways for your next platform test

    • High click-through rate is a discovery signal. It is not evidence of incremental revenue, efficient scaling, or portfolio impact.
    • Define the business outcome, counterfactual, comparison rules, guardrails, and decision thresholds before the campaign begins.
    • Segment conversational-ad results by intent and query class. A concentration of high-intent prompts can make the channel average look more transferable than it is.
    • Evaluate scale separately from efficiency. Limited inventory can produce good economics while preventing meaningful budget deployment.
    • Use platform reporting for diagnostics, experiments for causal lift, and media mix modeling for portfolio allocation.
    • Pause when instrumentation is broken. More spend cannot repair missing identifiers, inconsistent events, or an unreliable outcome definition.

    Before accepting the next emerging-platform test, write the measurement contract on one page and identify the weakest rung in your evidence ladder. Fund the test that resolves that uncertainty. Increase the budget only when the business outcome, incremental effect, data quality, and available inventory all support the same decision.

    References

  • AI-Era Advertising: How to Prove and Scale Real Growth

    AI-Era Advertising: How to Prove and Scale Real Growth

    Your dashboard says advertising is working. ROAS is up, automated campaigns are claiming conversions, and conversational AI is opening new inventory. But the decision in front of you is harder: which spending actually created revenue that would not have happened otherwise?

    You can answer that question without waiting for perfect attribution. Separate platform-reported performance from incremental lift, measure the return on the next dollar rather than the average dollar, and treat new AI placements as controlled learning investments. That gives you a practical basis for scaling, holding, or cutting spend.

    A high ROAS can still describe demand capture

    Platform ROAS answers a narrow question: how much revenue did the platform attribute to ads relative to their cost? It does not tell you how many of those purchases required the ads.

    That distinction becomes important when automated systems can concentrate spending around branded searches, repeat visitors, existing customers, and people already close to buying. The platform may be accurately recording its involvement while claiming revenue that would have arrived through direct, organic, or another channel. The number is useful for optimizing activity inside the platform, but it is not causal proof of growth.

    Before you increase a campaign budget, ask three separate questions:

    • Did the platform influence conversions? Platform attribution, CPA, and ROAS can help answer this.
    • Did advertising cause additional conversions? A controlled incrementality test is needed to estimate this.
    • Will the next block of spending remain profitable? Marginal return and contribution economics answer this better than average ROAS.

    Use the right calculation for each decision

    • Attributed ROAS equals platform-attributed revenue divided by ad spend. Use it to compare campaigns under the same attribution rules and improve execution within a platform.
    • Incremental revenue is the difference between the outcome for an exposed group and the estimated outcome for a comparable unexposed group, after accounting for relevant baseline differences.
    • Incremental ROAS equals incremental revenue divided by the advertising cost required to produce that lift. Use it to decide whether the campaign adds enough business value to keep funding.
    • Marginal ROAS equals the change in incremental revenue divided by the change in spend. Use it to decide whether an additional budget block is worth buying.

    The average and marginal numbers can point in opposite directions. A campaign that produces $50,000 from its first $10,000 has a 500% average ROAS. If another $5,000 produces only $5,000 more revenue, the combined average still looks respectable at roughly 366%, but the marginal ROAS on the added spend is only 100%.

    Do not call that final dollar break-even merely because one dollar of spend returned one dollar of revenue. Product costs, fulfillment, payment fees, returns, sales commissions, and other variable costs can make a 100% revenue ROAS unprofitable. Convert incremental revenue into incremental contribution before approving more budget. If margins differ by product or customer segment, calculate contribution at that level instead of applying one blended percentage to everything.

    Build a measurement ladder instead of one master metric

    Two analysts inspect a five-level staircase containing signal lights, matched customer groups, test vessels, and a prism illuminating a new group.

    No single metric can optimize campaigns, prove causality, and allocate the next dollar. A measurement ladder gives each metric a specific job and prevents a familiar dashboard number from being stretched beyond what it can establish.

    DecisionPrimary evidenceWhat that evidence cannot prove alone
    Which bid, audience, or creative should run?Platform conversions, CPA, and attributed ROASWhether the advertising caused the conversion
    Should the campaign keep receiving money?Incremental lift, incremental ROAS, and contributionWhether a larger budget will perform at the same rate
    Where should the next budget block go?Marginal incremental revenue or contributionHow performance will change after a major market or product shift
    Is the brand gaining visibility in AI answers?Paid exposure and unpaid AI mentions measured separatelyThat either form of visibility caused profitable demand

    Run an incrementality test that matches the business question

    You do not need a perfect measurement laboratory. You do need a credible counterfactual: an estimate of what would have happened without the advertising.

    1. Choose one business outcome before launch. Use completed revenue, gross contribution, qualified pipeline, new customers, or another outcome tied to the decision. Do not replace it mid-test with whichever platform metric looks strongest.
    2. Choose a control design. Comparable geographic markets, randomized audience holdouts, platform lift tests, audience exclusions, and controlled spend reductions can all create evidence beyond ordinary attribution. Geo splits and audience holdouts are especially useful when user-level journeys cannot be observed cleanly.
    3. Protect the contrast. Record which campaigns, markets, audiences, promotions, and prices differ between treatment and control. A large promotion in only one group can look like advertising lift even when the ad had little effect.
    4. Record the exposure rules. Preserve campaign settings, eligibility, placement types, creative versions, market coverage, and any platform product changes. This matters more in AI inventory, where formats and reporting can change while the channel is still maturing.
    5. Let the test cover the decision cycle. A test that ends before delayed purchases or qualified leads can mature will favor channels with short feedback loops. Set the observation window from the actual buying process, not from a convenient reporting date.
    6. Report uncertainty with the result. A positive point estimate from a small or volatile control group is not automatically a scalable win. If the result is too noisy to distinguish lift from normal variation, enlarge the test unit, repeat it, or classify the conclusion as unresolved.

    Maintain a test ledger with the hypothesis, primary outcome, treatment and control definitions, launch and end conditions, known confounders, result range, and budget decision. That record stops teams from remembering only successful tests and makes later retesting much faster.

    Treat conversational AI ads as a learning budget

    A researcher directs a measured stream of budget tokens into three transparent chambers testing abstract conversational ad experiences with anonymous audiences.

    Conversational advertising should not inherit the assumptions of search, social, or display. OpenAI began rolling out ads to Free and Go users in Australia, New Zealand, and Canada while keeping Pro, Business, Enterprise, and Education plans ad-free. Results from that inventory therefore should not be generalized to every ChatGPT user, market, or subscription tier.

    The early buying environment also carries unusually high measurement risk. Initial advertiser accounts described impression-led campaigns, limited reporting, high CPMs, and starting commitments in the six-figure range. Those accounts are preliminary, not a dependable benchmark for what every advertiser will pay or achieve. They are still enough reason to demand a sharper test plan before committing a material budget.

    Write the pilot brief before negotiating inventory

    • State the user moment. Name the conversational situation you expect to influence, such as category comparison, product research, retailer selection, or troubleshooting. A generic awareness objective is too broad to diagnose.
    • Define an exposure. Establish whether the platform reports a served impression, visible placement, interaction, click, conversation, or another unit. Do not compare CPMs until you know what the impression represents.
    • Name one primary outcome. Choose incremental qualified visits, incremental orders, incremental contribution, or qualified pipeline. Treat impressions and clicks as diagnostic signals rather than proof of growth.
    • Set the economic boundary in advance. Calculate the maximum acceptable acquisition cost or minimum contribution return from your own unit economics. If the required commitment would displace a proven campaign or consume the budget needed for a valid control, wait.
    • Specify the control. Use an unexposed geography, audience, eligible period, or other comparable unit where the placement will not run. If the seller cannot support or tolerate a credible comparison, classify the investment as exploratory rather than performance-proven.
    • Preserve evidence. Export the available delivery, market, tier, placement, creative, billing, and outcome data. Note reporting-definition changes so a product update is not mistaken for a performance change.
    • Set a stop rule. Decide what level of economic loss, reporting failure, brand-safety concern, or control contamination ends the test. The novelty of the format is not a reason to ignore an invalid experiment.

    Keep paid presence separate from earned AI visibility

    A sponsored brand appearing near a recommendation is not the same as a model selecting, citing, or mentioning that brand without payment. Early placements may influence the journey indirectly by making a sponsored retailer more prominent among recommendations, even when the underlying answer is presented as independent from the ad.

    Measure three lanes separately:

    • Paid AI delivery: eligible exposure, served placements, interactions, clicks, cost, and available conversion signals.
    • Earned AI visibility: unaided brand mentions, citations, recommendation presence, and factual accuracy across a fixed set of representative prompts.
    • Business effect: incremental visits, qualified leads, new customers, revenue, and contribution against a control or credible baseline.

    This separation protects your AEO and GEO work from a false success signal. Paid exposure can increase while unpaid recommendation visibility falls, or an AI system can mention the brand more often without creating profitable demand. Neither outcome should be credited to the other without a test.

    Move budget according to marginal contribution

    The AI shift does not make established channels irrelevant. IAB/PwC figures put U.S. search advertising revenue at $114.2 billion in 2025 within a $294.6 billion digital advertising market. Digital video reached $78 billion after 25.4% growth, while social reached $117.7 billion after 32.6% growth. The ten largest companies controlled 84.1% of the market.

    Those market totals describe where money went, not where your next dollar belongs. A rapidly growing channel can be unprofitable for your offer, while a slower-growing channel can still produce strong incremental contribution. Concentration also means the same large platforms often control inventory, optimization, and attribution. Use their reporting to manage campaigns, but require independent business outcomes or controlled lift before treating claimed conversions as proof.

    Use a repeatable capital-allocation cycle

    1. Rank current channels by marginal contribution. Use the most recent credible spend change or controlled test, not lifetime average ROAS.
    2. Choose the next observable budget block. It should be large enough to create a measurable change but small enough that a weak result does not materially damage the plan.
    3. Estimate the expected range. Record a low, central, and high outcome using evidence from your tests and unit economics. Do not convert an uncertain pilot into a single precise forecast.
    4. Move one block from the weakest expected marginal use to the strongest. Keep major promotions, pricing changes, and other confounders visible so they do not receive advertising credit.
    5. Remeasure after the change. Marginal returns usually change with spend. A channel that deserved the previous increase does not automatically deserve the next one.

    It also helps to classify spending by purpose. Core campaigns have repeatable causal and economic evidence. Experimental campaigns buy information about new inventory, audiences, or creative. Verification spending retests old assumptions after platform, product, or market changes. A brand-defense campaign may remain strategically valuable despite low measured incrementality, but label it as protection rather than presenting it as growth. That makes the trade-off explicit.

    Key takeaways

    • Platform ROAS measures attributed performance; it does not establish how much revenue advertising caused.
    • Incrementality tells you whether a campaign created an outcome that would not otherwise have occurred.
    • Marginal contribution, not blended ROAS, should determine whether the next budget increase is economically sound.
    • Conversational AI ads need a defined exposure unit, control, business outcome, economic limit, and stop rule before a substantial commitment.
    • Paid AI placements, earned AI visibility, and business impact belong in separate measurement lanes.
    • Market growth identifies where advertisers are moving, but your own causal evidence and unit economics should determine where you move.

    For your next budget review, replace the single ROAS column with six fields: attributed return, incremental lift, incremental contribution, marginal return, confidence level, and next test. Mark an untested channel as unproven rather than successful or failed. Then fund the next measurable budget block where the expected marginal contribution is strongest. AI formats will keep changing; that decision discipline will remain useful even when the placements do not.

    References