Tag: Campaign Performance

  • How to Audit Google Ads Data and Cut Spend Waste Safely

    How to Audit Google Ads Data and Cut Spend Waste Safely

    Your Google Ads account can report a better return while the underlying business gets less efficient. That happens when conversions are duplicated, low-value actions are treated as primary goals, delayed sales are missing, or automated bidding receives values that do not match real revenue.

    So do not begin an efficiency audit by lowering bids. Use this order: validate the conversion signal, classify waste, protect proven demand, choose automation that fits the available data, and then check whether product data is steering Shopping spend correctly.

    Treat conversion tracking as a bidding input, not a reporting detail
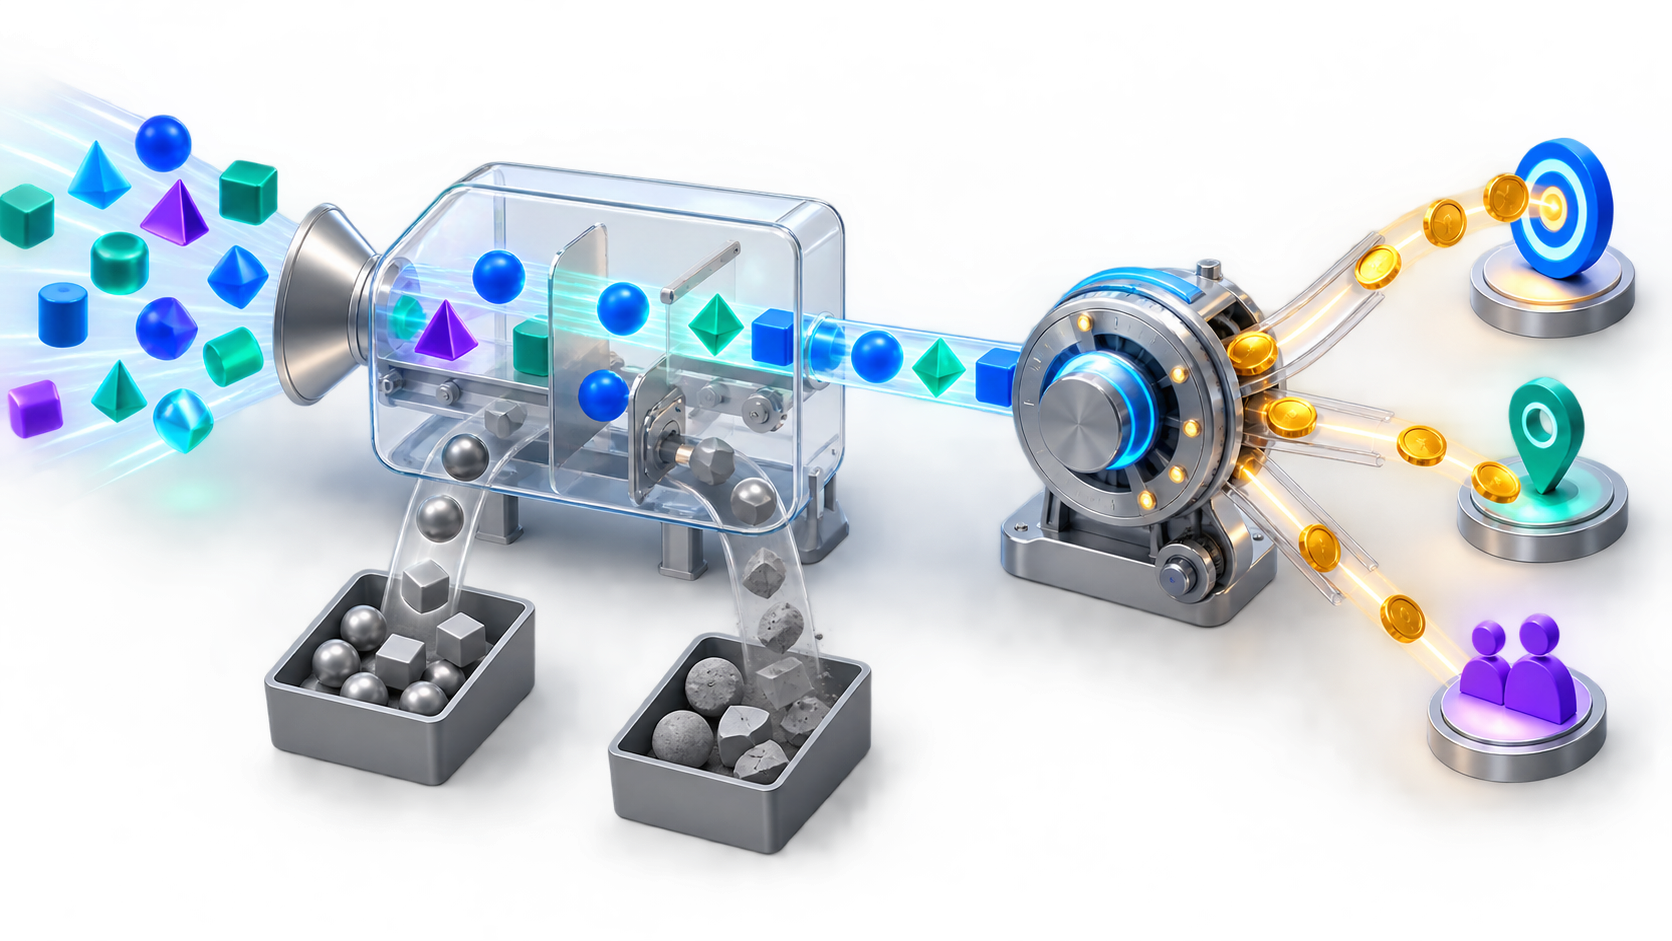
    A signal-validation machine removes duplicate and low-value conversion events before verified signals reach an automated bidding mechanism.

    Automated bidding does not know which outcomes matter to your business. It knows which conversion actions and values you send. If a page view, unqualified lead, duplicate purchase, or inflated order value is marked as a primary outcome, the system can optimize successfully toward the wrong result.

    Start by writing a plain-language definition for every primary conversion. A purchase conversion should represent a completed order, not a checkout visit. A qualified-lead conversion should represent the stage named in its label, not every form submission. If revenue arrives after the initial lead, keep the early event for diagnosis but base your main performance decision on the deepest reliably measured outcome available.

    • Confirm the event: Identify exactly what user or business action causes the conversion to fire.
    • Confirm the count: Check whether one business outcome can create multiple ad conversions. Repeat purchases may be valid; repeated firing for one order is not.
    • Confirm the value: Reconcile conversion values and currency with the system that records actual orders, revenue, or accepted leads.
    • Confirm the role: Separate primary actions used for bidding from secondary observations used for diagnosis.
    • Confirm the delay: Compare results only after the normal lag between an ad interaction and the recorded business outcome has had time to mature.

    Google’s consolidated enhanced-conversions system makes matching easier, but it does not replace this validation. Under the June 2026 consolidation, user-provided data can arrive through website tags, Data Manager, and API connections at the same time. You no longer have to choose a single implementation method for enhanced conversions for web or leads.

    That broader intake can recover conversions that would otherwise be harder to match. It cannot correct an event that fires twice, turn an unqualified lead into revenue, or repair an incorrect order value. Think of enhanced conversions as a matching layer around a conversion definition that must already be sound.

    A practical validation sequence

    1. Choose one high-spend campaign and list the primary conversion actions affecting its bidding.
    2. Trigger each action through a controlled test and verify that the expected event arrives once with the correct label and value.
    3. Reconcile a complete period of platform conversions against the corresponding records in your order, CRM, or lead-management system.
    4. Investigate missing outcomes, duplicate outcomes, unexplained value differences, and changes in the normal reporting delay.
    5. Resolve the discrepancy before changing a bid target or using the platform’s reported return to move budget.

    Existing enhanced-conversions users generally do not need to enable the consolidated feature again if the required customer-data terms have already been accepted. New setups can enable it under Goals, then Settings, under Customer data use; it can also be controlled for individual conversion actions.

    User-provided data still creates privacy and compliance obligations, even when it is hashed or transmitted through an approved integration. Do not enable another input merely because the switch is available. Confirm the applicable customer-data and data-processing terms, your consent or other lawful basis, your privacy disclosures, and the fields your implementation is permitted to send. Involve your privacy or legal owner if that authority is unclear.

    Separate obvious waste from performance that needs more evidence

    A zero-conversion row is not automatically waste. It may be new, low volume, affected by reporting delay, or part of a longer path to purchase. Cutting every row at zero conversions selects against campaigns before they have had a fair opportunity to produce an outcome.

    A better audit divides questionable spend into three classes:

    • Structural waste: The traffic cannot produce the intended outcome. Examples include an irrelevant search term, an unavailable product, or a destination that does not support the advertised action. Act as soon as you verify the mismatch; waiting for more conversions will not make the traffic relevant.
    • Performance waste: The traffic could convert, but it has accumulated enough impressions, clicks, spend, and mature outcomes to miss the account’s CPA or ROAS requirement. This class needs sufficient data before you pause or constrain it.
    • Measurement uncertainty: Spend looks weak because conversions, values, or delays cannot be trusted. Repair measurement before making a budget decision unless the traffic is also structurally irrelevant.

    A useful working hypothesis is that 20% to 30% of spend may underperform in an audited account. That is an audit prompt, not a universal benchmark and certainly not a quota to cut. If your analysis identifies only 8% of defensible waste, removing 20% would damage productive activity. If it identifies more, preserving the budget because it fits the plan would be equally hard to justify.

    Build your review at the lowest level where you can take a meaningful action. Search-term data can reveal irrelevant queries hidden by campaign averages. Product-level data can reveal items consuming spend while generating no conversions or falling well below the required return. Campaign totals alone can allow a few strong components to conceal a long tail of loss.

    1. Choose an evaluation period that includes the normal conversion lag and enough activity to judge the unit fairly.
    2. Review search terms, products, and other actionable segments using impressions, clicks, spend, conversions, conversion value, CPA, and ROAS.
    3. Mark definite mismatches separately from low-performing but plausible traffic.
    4. For each performance outlier, inspect the query, product availability, feed information, landing-page path, conversion signal, and offer before assigning the cause to bidding.
    5. Apply the narrowest corrective action: add an exclusion for irrelevant demand, repair the destination or feed, constrain a proven outlier, or pause a segment whose economics no longer work.
    6. Record what changed, the reason, the decision period, and the metric that will determine whether the intervention worked.

    Use CPA and ROAS for different questions. CPA is cost divided by conversions and works only when the counted outcomes are sufficiently comparable. ROAS is conversion value divided by cost and works only when the values are complete and economically meaningful. A strong reported ROAS can still be unattractive if revenue values omit cancellations, returns, fulfillment costs, or other business constraints, so reconcile the platform result with the financial view used to run the business.

    Reallocate budget instead of cutting every campaign evenly

    An across-the-board reduction feels neutral, but it removes money from proven demand and waste at the same rate. That can preserve the account’s weakest activity while forcing high-intent campaigns to stop serving earlier.

    Protect lower-funnel activity that has trustworthy measurement, sufficient volume, and a return that meets the business requirement. Move money away from confirmed structural waste first, then from mature performance outliers. Keep uncertain activity in a clearly bounded diagnosis or testing budget so it cannot consume funds without an explicit decision date.

    • Protected budget: Proven, high-intent activity meeting its business target with reliable tracking.
    • Repair budget: Valuable demand whose feed, landing page, creative, or measurement problem has a credible fix.
    • Test budget: New queries, products, audiences, or creative variations with a stated hypothesis and success criterion.
    • Exit budget: Irrelevant demand and mature segments that remain outside acceptable economics after measurement problems are ruled out.

    Do not let platform ROAS become the only judge. Compare it with actual revenue or qualified outcomes from the business system and with the combined effect of your channels. That blended view matters because lower-funnel campaigns can capture demand created elsewhere, while upper-funnel activity may look weak when judged only by the final recorded click. The answer is not to protect every awareness campaign; it is to give each stage a measurement question appropriate to its job.

    Ask two separate questions during every reallocation. First, should this activity exist at all? Second, how much budget has it earned? Combining those questions creates bad choices: a useful campaign may receive too much money simply because it belongs in the plan, while an irrelevant segment may survive because its budget is small.

    Match bidding and creative decisions to the signal you actually have

    A bid strategy cannot compensate for a weak objective. Select it only after you know which conversion signal is reliable and what the business is trying to control.

    • Maximize Clicks: Use it when acquiring traffic is genuinely the immediate goal or when a dependable conversion signal is not yet available. Do not evaluate it as though it were instructed to maximize sales.
    • Target CPA: Use it when the primary conversions are reasonably comparable in value and the account can supply trustworthy conversion data. A lead target is useful only if the counted leads correspond to the quality level the business can afford.
    • Target ROAS: Use it when conversion values vary and those values accurately represent the outcomes you want the system to favor. Bad values turn a revenue-aware strategy into an amplifier of accounting errors.

    Automation needs boundaries as well as data. Keep exclusions current, prevent invalid products and irrelevant queries from competing for budget, and avoid changing targets merely to make the interface report a preferred status. If a target conflicts with the economics of the business, the target is wrong even when the campaign reaches it.

    Creative is another control surface, not decoration. Automated campaigns need meaningful variations to learn which message, format, and offer fit different opportunities. Maintain a queue of distinct assets rather than superficial rewrites of the same claim. Review each variation after adequate exposure, retire clearly weak assets, and preserve the message differences so the next test answers a new question.

    Human review remains necessary because the platform can optimize the target it receives without knowing whether that target reflects margin, lead quality, inventory constraints, or business priorities. Use automation to process the signal; keep responsibility for defining and auditing the signal with your team.

    For Shopping campaigns, product data is spend control
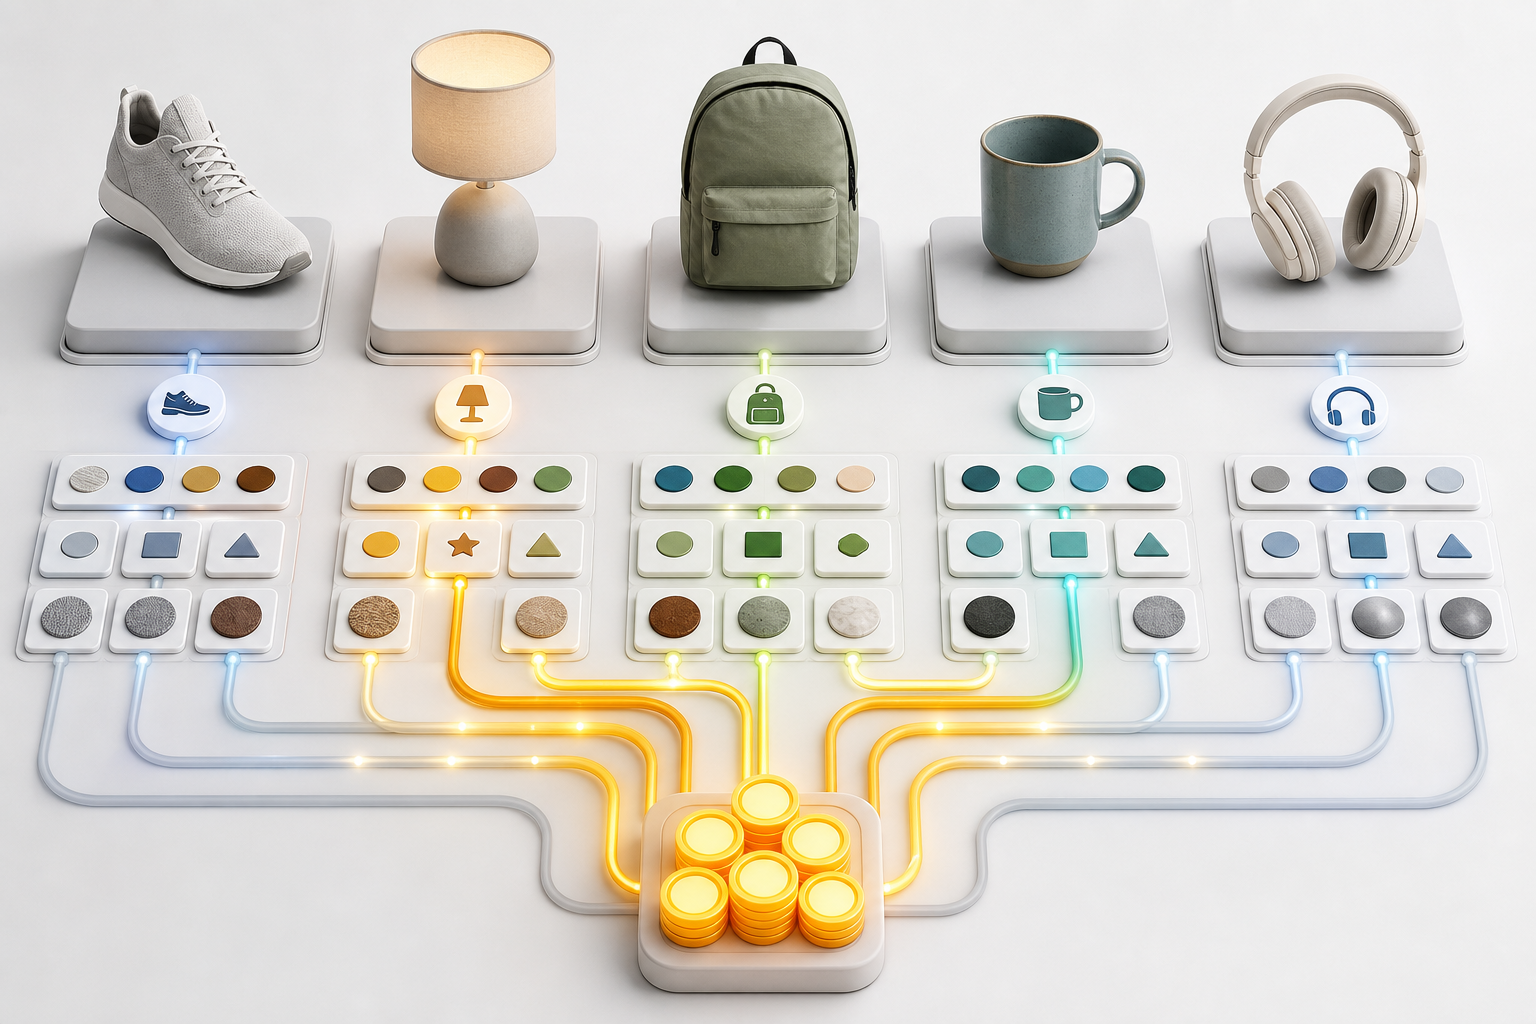
    Generic products with organized visual attributes receive more advertising tokens than incomplete or mismatched product listings.

    Shopping efficiency begins before the auction. Titles, product identifiers, availability, inventory, promotions, and other feed attributes determine what can serve and how the system understands the offer. A bid adjustment is the wrong fix when the product data itself is incomplete, stale, or mapped incorrectly.

    Google set April 22, 2026 as the start of Merchant API support in Google Ads Scripts and August 18, 2026 as the retirement date for the Content API for Shopping. The Merchant API transition is therefore both a continuity requirement and an opportunity to improve how product-data problems are detected.

    The Merchant API uses modular sub-APIs and expands control over supplemental product data, local and regional inventory, promotions, product and store reviews, and notifications. Google Product Studio also introduces generative-AI capabilities. Treat those enhancements as optional improvements after the functional migration is correct; generated content does not compensate for missing inventory or a broken product mapping.

    1. Inventory every dependency: Find scripts, scheduled jobs, feed tools, supplemental inputs, inventory updates, promotions, reviews, and alerts that still rely on the Content API.
    2. Map each function: Identify the relevant Merchant API module and the credentials, permissions, fields, and error handling needed by that function.
    3. Enable the Advanced API: Update Google Ads Scripts that require Merchant API access and remove assumptions tied only to the legacy response structure.
    4. Validate in parallel: While both paths are available, compare product identifiers, item counts, availability, inventory, promotions, and reported errors rather than assuming a successful request means equivalent data.
    5. Test failure handling: Confirm that authentication errors, rejected products, delayed inventory updates, and other exceptions produce an alert that someone owns.
    6. Cut over deliberately: Retire the legacy dependency only after the new path has completed its scheduled runs and the resulting catalog state matches the expected business state.

    The Notifications API can make product issues visible sooner, but an alert has value only when it identifies the affected item, the severity, and the person or workflow responsible for the response. Route urgent availability or rejection problems differently from informational feed changes.

    Key takeaways

    • Reconcile primary conversion counts and values with the business system before changing bids or budgets.
    • Use enhanced conversions to improve matching, not to repair duplicate events, weak conversion definitions, or incorrect values.
    • Remove structural waste immediately, but require mature data before classifying plausible traffic as a performance failure.
    • Protect proven lower-funnel demand, isolate tests, and move budget from confirmed waste instead of cutting every campaign equally.
    • Choose Target CPA, Target ROAS, or Maximize Clicks according to the quality of the available signal and the outcome each strategy is actually designed to pursue.
    • For Shopping campaigns, complete and validate the Merchant API migration because feed integrity directly affects where spend can go.

    Open one high-spend campaign and reconcile its primary conversion count and value over a fully matured period. If the numbers match your business records, audit its search terms or products for structural and performance waste. If they do not match, fix the signal first. Every later optimization depends on that distinction.

    References


  • Google AI Ads and Sales Lift: A Practical Testing Playbook

    Google AI Ads and Sales Lift: A Practical Testing Playbook

    You have probably seen the headline number: a retailer used Google AI advertising and revenue rose by 80%. The useful question is not whether AI ads can work. It is whether they can produce profitable, incremental sales for your business without weakening measurement or surrendering control of your brand.

    You can answer that question, but not by switching on every automated feature and comparing this month’s revenue with last month’s. Treat AI Max, Performance Max, reusable text rules, and recommendation reporting as separate tools inside a controlled commercial test. That gives you a result you can defend when someone asks what actually caused the lift.

    An 80% lift is a case result, not your forecast

    Google has highlighted Aritzia as having achieved an 80% increase in revenue with AI Max. That is evidence of possibility, not a transferable benchmark. It does not tell you what Aritzia would have earned without AI Max, how much media spend changed, which customers were new, or what happened to margin.

    Revenue lift can come from several places. An advertiser may reach previously missed queries, improve the match between a shopper and a product, spend more, capture demand that another campaign would have converted, or count conversions differently. Only the first two clearly demonstrate better advertising. Additional spend can still be worthwhile, but it is a different claim and should be judged against your allowable acquisition cost.

    Write your expected mechanism before starting. A useful hypothesis is specific: AI Max will find additional non-brand demand for selected products and increase contribution profit without pushing customer acquisition cost above our limit. A weak hypothesis is that AI will increase sales. The stronger version identifies the demand, the product scope, the business outcome, and the constraint.

    Set a budget boundary and stop conditions at the same time. Automation can spend into newly discovered demand quickly. Without a pre-agreed limit, higher expenditure can resemble growth even when each additional order is less valuable. Your own margins, return rates, sales cycle, and cash constraints should determine that limit; a vendor case result should not.

    AI changes matching, but your inputs set its ceiling

    Traditional search advertising starts with keywords chosen by the advertiser. Google’s newer systems place more weight on inferred intent. They assess the retailer’s website and creative assets, interpret a search, and dynamically match products and messages to that context. Performance Max and AI Max are designed to operate within this more intent-driven model.

    The opportunity is clearest in conversational search. Google says queries in AI Mode tend to be two to three times longer, giving the matching system more context. Google also says 15% of daily searches are novel. A rigid keyword list cannot anticipate every new formulation, while an intent model can potentially connect unfamiliar wording with an appropriate offer.

    That does not remove the need for optimization. It moves optimization upstream. The system cannot reliably distinguish two similar products if your pages use vague names, bury the differences, or contradict the creative. It cannot protect a nuanced brand position that has never been translated into operational rules.

    • Clarify the product: Make the product type, variant, intended buyer, availability, price, and material differences easy to identify on the landing page and in the product data you provide.
    • Align the promise: Check that advertising claims, promotions, shipping terms, and calls to action agree with the destination page. Automation can scale a mismatch as easily as it scales a good message.
    • Supply useful creative range: Give the system assets that express different legitimate benefits, use cases, and objections. Cosmetic variations of the same vague claim do not create meaningful choice.
    • Define the sale correctly: Confirm that the primary conversion represents a commercially useful outcome. If low-value actions sit beside completed purchases without a clear hierarchy, more reported conversions may not mean more revenue.
    • Separate brand rules from campaign ideas: Tone, prohibited language, required qualifications, product naming, and legal restrictions should remain stable. Offers and audience-specific messages can change by campaign.

    Google Ads is testing a beta capability that lets advertisers clone approved AI text guidelines from an existing campaign. If it is available in your account, use it to turn recurring brand decisions into reusable instructions. A practical rule set should cover voice, required product terminology, claims the system must not make, promotion wording, and acceptable calls to action.

    Cloning saves setup time; it does not eliminate review. Read the copied rules in the context of the destination campaign. A restriction written for one market, product category, or promotion can be incomplete or actively wrong elsewhere. Assign an owner and version the rules internally so your team knows which guidance was approved and why.

    Build a test that can explain where sales came from

    Two matched groups of product boxes travel through separate treatment and control lanes toward individual checkout stations.

    The main measurement mistake is changing automation, budget, creative, offers, landing pages, and conversion tracking at once. A good result then produces enthusiasm but little knowledge. A bad result creates the same problem because you cannot identify which change failed.

    1. Choose one commercial hypothesis. Name the customer demand you expect AI matching to capture, the products included, the primary business metric, and the maximum cost you will tolerate.
    2. Set a clear boundary. Limit the first test to a defined campaign, product group, market, or customer cohort. Avoid exposing the entire account before you know how the system behaves with your inputs.
    3. Preserve a comparison. Keep a control when account structure and volume permit it. Otherwise, save the pre-change campaign data and identify a comparable product or market that will not receive the change.
    4. Reduce simultaneous changes. Hold pricing, promotions, landing pages, inventory policy, and conversion definitions steady where practical. Record anything that cannot be held steady, including stockouts and major merchandising events.
    5. Allow for conversion lag. Do not declare a winner while one group has had more time to accumulate purchases, cancellations, or returns. Read both groups over equivalent conversion windows.
    6. Review three layers of evidence. Check delivery, customer response, and business value separately. More reach may explain more orders, but only revenue quality and cost reveal whether the expansion was worthwhile.

    At the delivery layer, inspect spend, impressions, click volume, and the kinds of demand being reached. At the response layer, inspect purchases, conversion rate, and average order value. At the business layer, inspect net revenue, contribution margin, new-customer share where you can measure it, cancellations, and returns. A campaign can look strong in the advertising interface while failing the business layer.

    Split branded and non-branded demand in the analysis wherever your reporting allows. AI can appear efficient when it captures customers already searching for your company or products. That traffic may still deserve coverage, but it should not be presented as newly created demand. The same principle applies to returning customers: retained revenue and acquired revenue answer different questions.

    Google Ads has also added a Results tab intended to show the impact of recommendations. Use it to investigate what changed after a recommendation was applied, not as automatic proof that the recommendation caused incremental profit. Platform reporting can identify a useful correlation and shorten diagnosis, but it does not control for promotions, seasonality, inventory, competitor behavior, or sales that another campaign might have captured.

    Key takeaways

    • An 80% revenue increase from one retailer establishes potential, not an expected return for your account.
    • AI Max and Performance Max can interpret demand beyond a fixed keyword list, which matters as searches become longer and more conversational.
    • Clear product information, aligned landing pages, useful creative, and correctly defined conversions are inputs to the system, not cleanup tasks for later.
    • Reusable AI text rules can speed campaign setup, but every cloned rule set still needs market- and product-specific review.
    • Measure incremental business value rather than reported conversions alone. Separate brand demand, returning customers, media spend, returns, and margin.
    • Use recommendation results as diagnostic evidence. Validate causation with a control or the strongest comparable baseline available.

    Scale only after the result survives business checks

    A stream of purchase tokens passes through margin, inventory, and quality checkpoints before reaching a larger retail network.

    A successful test should answer more than whether sales rose. You should know which products gained, what type of demand expanded, how much spend changed, whether acquisition remained within your limit, and whether the revenue retained its value after discounts, cancellations, and returns.

    Before expanding the campaign, require the result to pass five checks:

    • Incrementality: The gain remains credible after separating branded demand and other traffic the campaign may have absorbed.
    • Economics: Acquisition cost and contribution margin stay within the limits set before the test.
    • Quality: Search intent, generated messaging, landing pages, and purchased products align with the hypothesis.
    • Durability: The outcome is not explained by a short promotion, inventory event, reporting delay, or one unusually strong segment.
    • Control: Brand and compliance reviews find no unacceptable claims, tone, targeting pattern, or customer experience.

    Scale in stages if those checks pass. Expand one boundary at a time, such as the eligible product set or budget, and keep the same business metrics visible. If revenue rises but margin, new-customer acquisition, or message quality deteriorates, pause the expansion and correct the input or objective before spending more.

    Google is also experimenting with personalized direct offers and supporting a broader move toward purchases inside AI interactions through the Universal Commerce Protocol developed with Shopify. Those developments point toward a shorter path from conversational discovery to checkout, but experiments and infrastructure plans are not guaranteed sales. Your immediate advantage comes from making your business legible to intent-matching systems and building measurement that can distinguish a real commercial gain from a persuasive dashboard.

    Start with one bounded campaign. Write the hypothesis, unit-economics limit, brand rules, comparison method, and stop conditions before enabling the change. That single page of decisions will do more for your eventual sales result than adopting every AI feature at once.

    References

  • Unveiling Google’s PMax Timeline: Boost Your Ad Strategy

    Unveiling Google’s PMax Timeline: Boost Your Ad Strategy

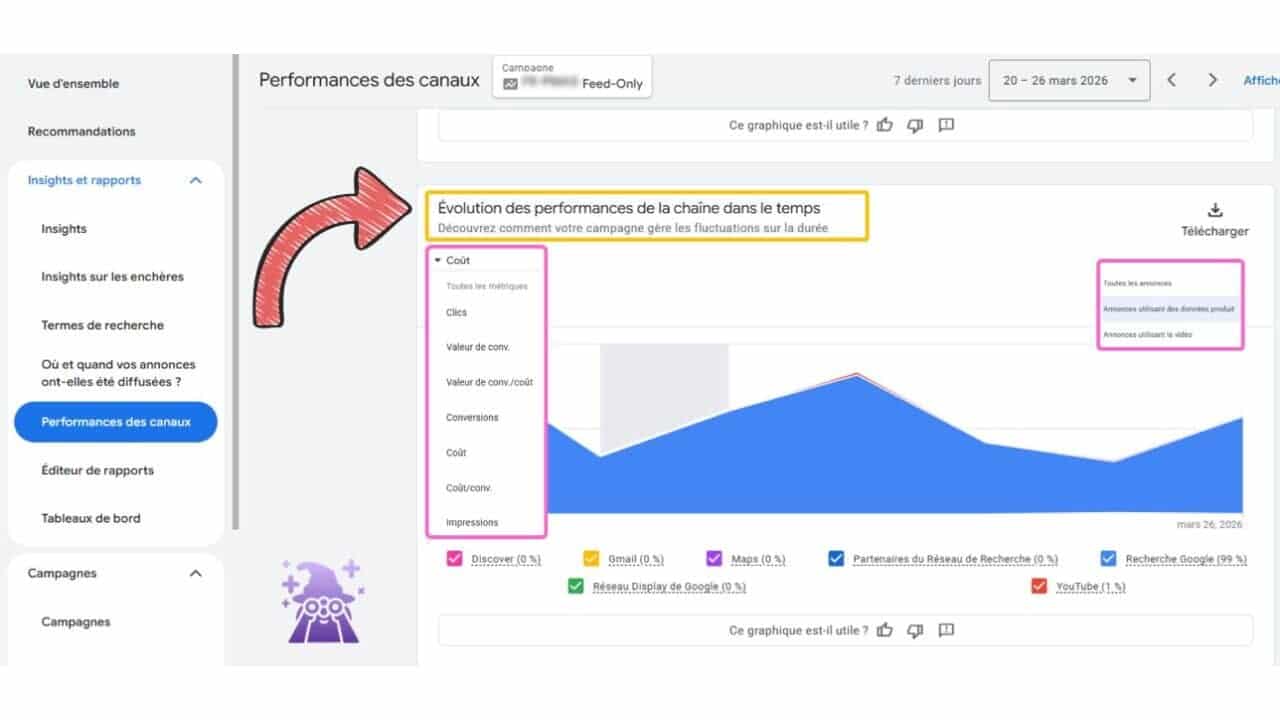
    Recently, I discovered that Google has launched an exciting new feature for Performance Max campaigns. As an advertiser, I’m always on the lookout for tools that provide clearer insights, and this new channel performance timeline view does just that. It offers a comprehensive breakdown of how different channels like Search, YouTube, and Display contribute to my campaign results over time.

    What’s New

    The latest update introduces a timeline graph that showcases channel-level contributions over a selected period, complete with investment and performance filters. This means I can quickly identify which channels are excelling and which ones might need a bit more attention.

    The chart features helpful visual cues—like a yellow box highlighting channel performance evolution over time, and a pink box indicating different ad types, such as All Ads, Ads Using Product Lists, and Ads Using Video.

    Why I Care

    Managing Performance Max campaigns across multiple channels often left me guessing about where my budget was working best. This new view provides valuable insights into channel-level trends, allowing me to adjust strategies or budgets more efficiently. If I notice YouTube underperforming while Search is thriving, I can now make informed decisions without relying purely on guesswork or exported data.

    ```json
{
  "alt": "Dashboard showing performance metrics and graph over time.",
  "caption": "Explore how your channel's performance evolves over time with detailed metrics and graph visualizations.",
  "description": "The image shows a dashboard interface with a focus on channel performance metrics over time. The left menu includes options like 'Insights' and 'Performances des canaux.' A red arrow points to a highlighted section explaining performance evolution. A blue graph depicts data trends with metrics like cost, clicks, and conversions selected. Options to download data and filter ads are visible, enhancing user interaction and analysis capabilities. Keywords: dashboard, performance metrics, graph, data analysis."
}
```

    The Big Picture

    This new view empowers me to evaluate PMAX performance more effectively, without relying solely on Google’s automated decisions. Now, I can see consistent underperformance or excellence across channels, which guides my budget and asset strategies moving forward.

    The Bottom Line

    Though it’s not full transparency, this update is a significant move in the right direction. I now have a more structured way to detect trend anomalies in PMax campaigns early and make necessary adjustments to optimize performance.

    First Spotted

    This feature was first noticed by Axel Falck, Head of Search at Le Mage du SEA, who shared his insights on LinkedIn.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How to Make LinkedIn Recruitment Campaigns More Efficient

    How to Make LinkedIn Recruitment Campaigns More Efficient

    Your LinkedIn recruitment campaign can generate plenty of clicks and applications while still failing at the one outcome that matters: producing qualified hires at a sustainable cost. When interview volume stays flat as campaign activity rises, you are probably paying for attention rather than candidate fit.

    The remedy is not simply a narrower audience or a lower bid. You need a campaign system that identifies intent, filters candidates before expensive actions, separates different stages of demand, and connects media spend to interviews and hires.

    Define efficiency before you buy another click

    Recruitment efficiency is not a high click-through rate, a cheap click, or even a low cost per application. Those metrics describe parts of the journey. They do not tell you whether the campaign is helping the company hire suitable people.

    Start with a complete conversion chain. Every active campaign should be traceable through these stages:

    1. Ad click or lead interaction.
    2. Pre-qualification page visit.
    3. Application start.
    4. Completed application.
    5. Qualified application.
    6. Interview.
    7. Hire.

    Define a qualified application with the hiring team before launch. It might require a particular certification, a minimum level of relevant experience, permission to work in the required location, or another genuine condition of the role. If recruiters apply different definitions after applications arrive, campaign comparisons will be unreliable.

    Calculate cost per hire using one consistent scope: the spend assigned to a campaign divided by the hires attributed to it. If you include creative, agency, or platform costs, include them consistently across every campaign you compare. Apply the same attribution rule as well. A neat dashboard cannot rescue inconsistent definitions.

    Your working report should show spend, clicks, completed applications, qualified applications, interviews, and hires for each campaign. Add conversion rates and costs between stages. That makes the source of waste visible:

    • High click-through rate but few applications: the ad may be creating curiosity that the role cannot satisfy, or the application handoff may be too demanding.
    • Many applications but few interviews: your audience, creative, or landing page is not doing enough pre-qualification.
    • Qualified applicants and interviews but few hires: inspect the offer, recruiter follow-up, interview process, and hiring decision before changing the ads.
    • Hires from one segment but weak volume: increase that segment carefully instead of loosening the requirements across the whole account.

    The first two patterns are especially important because click and application volume can conceal poor alignment. Optimizing to the earliest available event encourages the campaign to find more of that event, not necessarily more people the hiring team wants to meet.

    For early testing, manual cost-per-click bidding can give you tighter control over how quickly the budget is exposed. Consider automated bidding after conversion tracking is working and the campaign has produced a stable enough mix of qualified applicants to judge. The purpose is not to defend manual bidding forever. It is to avoid paying an automated system to amplify an unproven audience or message.

    Build audiences from fit and intent, then keep them separate

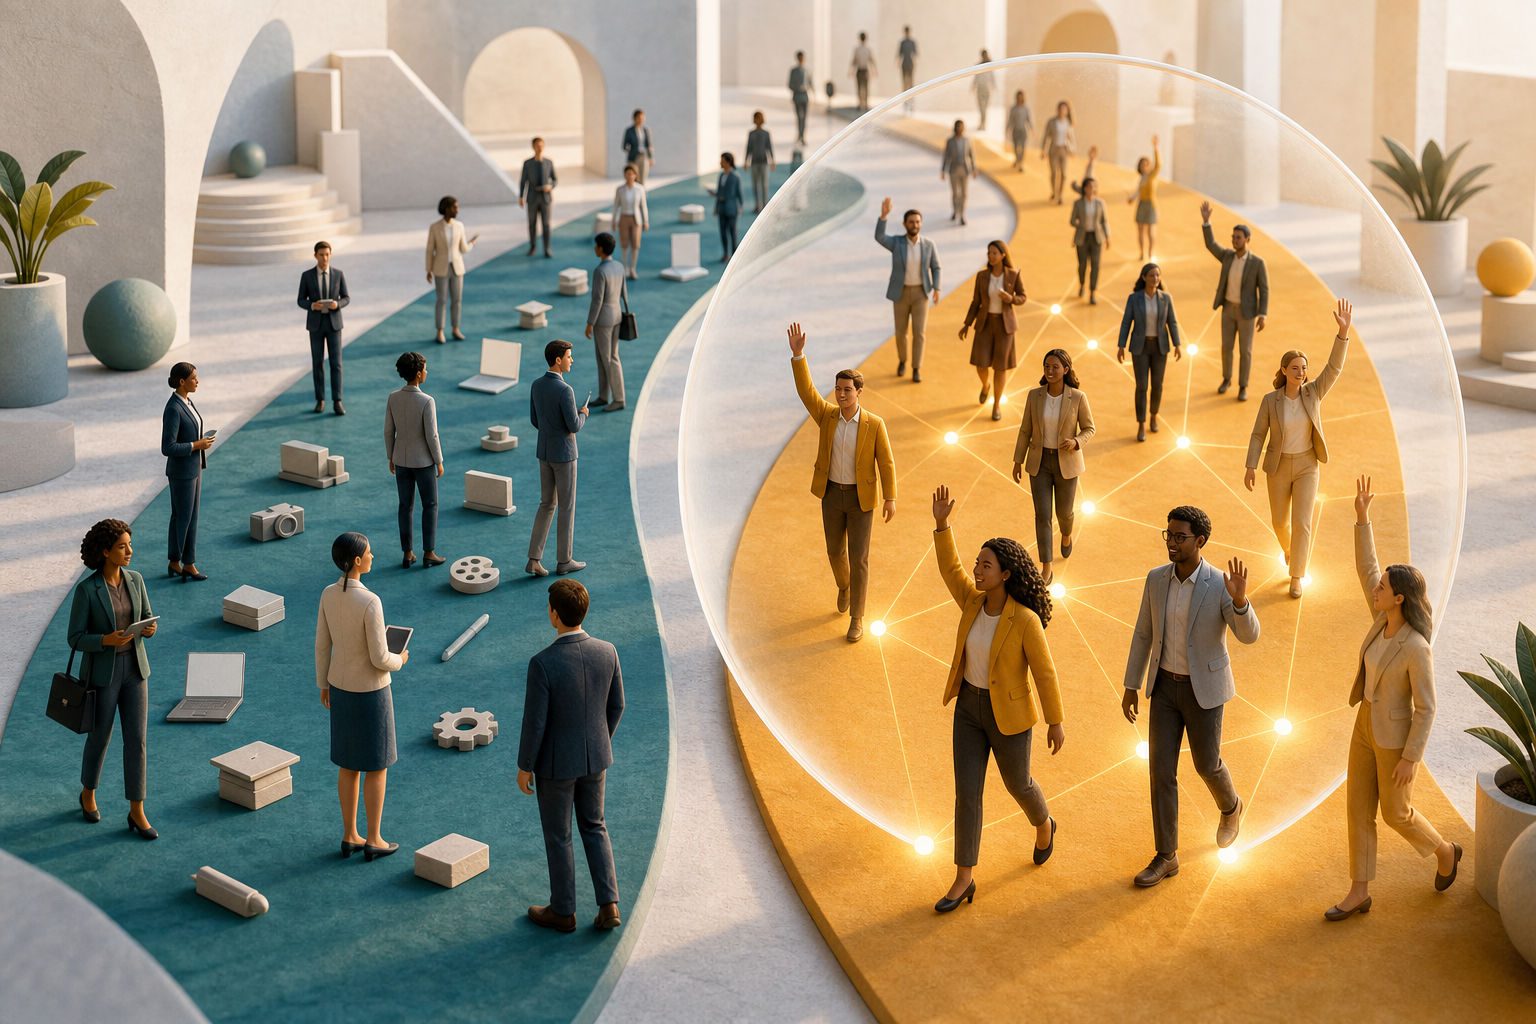
    Diverse professionals move along separate teal and amber pathways while a translucent lens highlights people where fit and intent overlap.

    Job title, industry, and seniority tell you who a person is professionally. They do not tell you why that person might consider changing jobs. A more useful audience plan combines three layers:

    • Core fit: relevant titles, skills, certifications, and experience.
    • Behavioral intent: open-to-work status, recent job-seeking activity, relevant group membership, or engagement with industry content, where those signals are available in your campaign setup.
    • Career-friction hypotheses: roles associated with burnout, employers affected by layoffs, or environments where advancement may be limited.

    Use career friction to form a messaging hypothesis, not to pretend you know how an individual feels. An employee at a competitor is not automatically dissatisfied. A person in a demanding profession is not automatically burned out. Your ad can describe a credible alternative without making a personal claim about the viewer.

    Give each intent level its own campaign job

    Active candidates and cold passive candidates should not share the same budget, message, and success expectation. Separate them so that a high-intent audience cannot hide waste in a broad awareness campaign.

    Intent segmentUseful audience signalsMessageCampaign job
    High intentOpen-to-work users, recent job seekers, and retargeting audiencesRole specifics and a direct application invitationGenerate qualified applications now
    Warm passiveRelevant skills, competitor employers, and niche professional groupsA concrete career, schedule, compensation, or lifestyle improvementTurn openness into consideration
    Cold passiveBroader qualified audiences and lookalike audiencesEmployer reputation, culture, mission, and realistic day-in-the-life contentBuild a future talent pool

    This high-, warm-, and cold-intent structure also changes how you interpret performance. A cold employer-brand campaign should not be expected to match the immediate application rate of retargeting. Its job is to create an audience that a later campaign can convert more economically.

    Control overlap when you build these segments. Start with the most specific high-intent pool, then exclude it from warm campaigns where your setup allows. Exclude both from the cold campaign. Without those exclusions, the same promising candidate can appear in several campaigns, making cost and conversion comparisons harder to trust.

    Skill-based segmentation is often more actionable than one large professional audience. If a role accepts candidates from several disciplines, place each major skill group in a separate campaign and adapt the value proposition. You will see which background produces qualified applicants, rather than averaging unlike candidates into one result.

    Make the ad qualify candidates before they click

    A recruitment ad has two jobs: attract the right person and discourage the wrong person from spending your budget. If the ad hides hard requirements to maximize clicks, the application process has to reject those people later, after you have paid for their attention and consumed recruiter time.

    A practical recruitment ad contains four elements:

    1. A recognizable identity or friction: name the professional situation the role improves.
    2. A hard fit statement: specify the required role, skill, certification, or experience.
    3. A verified reason to move: state the real compensation, flexibility, schedule, growth path, mission, or working conditions.
    4. A clear boundary: say when the position is not entry-level or requires a specific background.

    Use this fill-in structure when drafting creative:

    [Professional identity]: If [specific, credible friction] is making you consider a change, [company] is hiring for [role]. You will need [must-have requirements]. The position offers [approved and verifiable benefits]. This role is not suitable for [clear exclusion]. [Direct next step].

    The exclusion is not an apologetic footnote. It is part of the offer. Phrases such as “requires enterprise account management experience” or “not an entry-level position” can reduce irrelevant responses and protect recruiter capacity. The same principle applies to licensed or specialist roles: put the non-negotiable credential in the ad, not halfway through the application.

    Only promote benefits the employer has confirmed. “Flexible schedule” is not useful filtering language if flexibility depends on the manager. A compensation claim should match the actual structure and conditions. An exaggerated promise may raise clicks, but the mismatch will surface in application abandonment, interviews, or offer rejection.

    Test the message against qualified outcomes

    Run creative tests that change one decision-relevant element at a time. You can compare an identity-led opening with a friction-led opening, test schedule against career growth as the primary value proposition, or move the hard qualification earlier in the copy. Keep the audience, role, and destination consistent while you test.

    Do not declare a winner because one variation earns more clicks. Compare completed applications, qualified-application rate, interview rate, and eventual hires. The more selective ad may have a lower click-through rate and still be the more efficient recruitment asset.

    For specialized or senior positions, a narrowly targeted Message Ad can carry more context than a short feed ad. Keep the outreach specific and easy to decline:

    Hi [First Name], your background in [relevant skill or field] stood out. We are hiring a [role] for people with [must-have experience]. The position offers [two verified benefits], and it is intended for [seniority or specialist profile], not entry-level candidates. Would you be open to a brief conversation? If not, thank you for considering it.

    Broad message campaigns can become expensive quickly. Reserve this format for audiences whose eligibility and likely value proposition are already well defined.

    Use a two-stage application path and retarget real interest

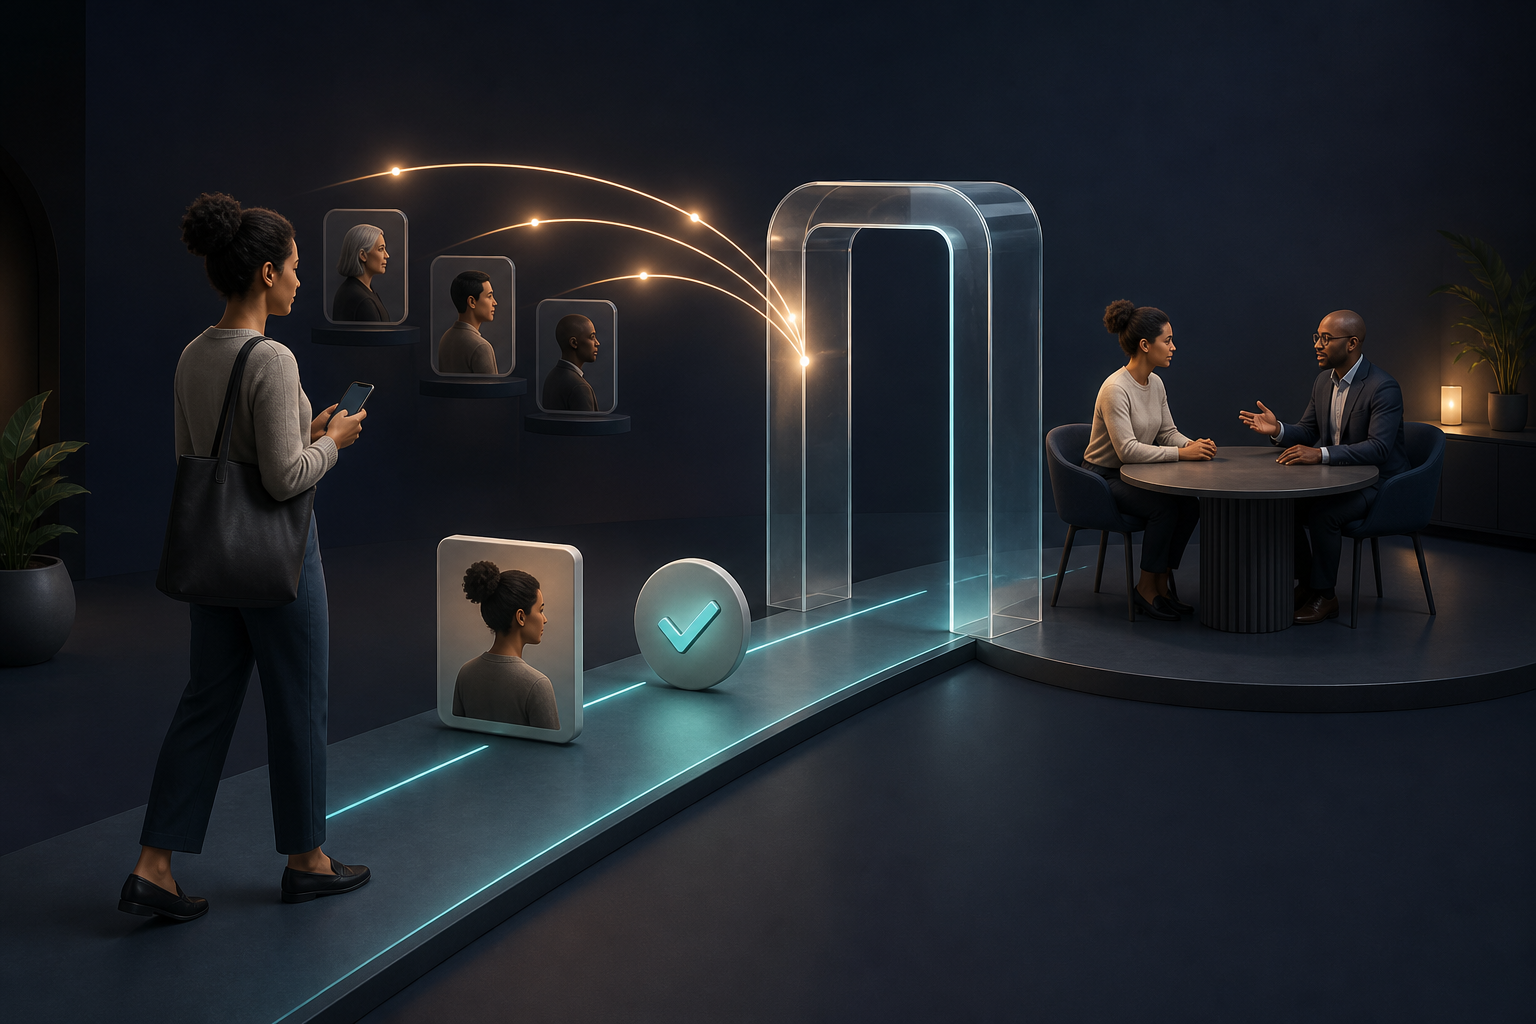
    A job seeker begins on a smartphone, passes through a qualification gateway, and reaches an interview table while glowing connections loop back to other interested candidates.

    Sending every click directly to a long applicant-tracking form forces candidates to do too much before they understand the role. It also prevents you from distinguishing between a poor offer and a difficult application experience.

    Use a two-stage path instead:

    1. Pre-qualification page: explain the work, expectations, location or schedule, compensation details, must-have criteria, and who should not apply.
    2. Short application: ask only for the information needed to evaluate the next step, or use LinkedIn Easy Apply when it suits the hiring workflow.

    The first stage should increase clarity, not create an obstacle course. A reported 30-50% reduction in cost per hire has been associated with this two-step structure, but treat that range as a directional campaign claim rather than a forecast. Your result will depend on the role, offer, audience, tracking, and existing application process.

    Instrument both stages separately. Track the proportion of ad visitors who reach the page, start the application, complete it, qualify, interview, and get hired. If many suitable-looking visitors leave before starting, inspect the offer and page. If many begin but do not finish, inspect the form. If completions are high but interview selection is low, strengthen the qualification language.

    Retarget people according to what they already did

    Not every qualified person applies during the first visit. Build retargeting audiences from career-page visitors, ad viewers, and people who watched at least 50% of a recruitment video. Their next message should move the decision forward rather than repeat the original ad.

    • Career-page visitor: restate the role’s main benefit and the most important qualification.
    • Substantial video viewer: show an employee outcome, realistic role detail, or day-in-the-life proof that answers a likely concern.
    • Application visitor who did not complete: return to the role and a shorter next step, if your tracking and campaign rules support that audience.
    • Interested candidate near a genuine deadline: communicate the real closing date. Do not manufacture urgency.

    Exclude people who have already applied unless the follow-up has a deliberate recruiting purpose. Otherwise, you keep paying to ask for an action they have completed and distort the apparent efficiency of the retargeting campaign.

    Once the core funnel is working, expand carefully. Competitor-employee targeting can emphasize a verified advantage without attacking another employer. Skill-specific campaigns can reveal which backgrounds convert. Targeted messages can reach a small pool of senior specialists. Each tactic should remain separate enough that you can identify its qualified applications, interviews, and hires.

    Key takeaways for your next recruitment campaign

    • Measure cost per qualified application, interview, and hire alongside clicks and completed applications.
    • Define qualification with recruiters before launch so campaign comparisons use the same standard.
    • Combine core professional fit with available intent signals instead of targeting job titles alone.
    • Separate high-intent, warm passive, and cold passive candidates because they need different messages and success criteria.
    • Put must-have requirements and meaningful exclusions in the ad to prevent avoidable clicks.
    • Use a clear pre-qualification page followed by a short application, then track the handoff between them.
    • Retarget demonstrated interest with a next-step message and exclude candidates who have already applied.
    • Move budget according to qualified applications, interviews, and hires, not the campaign with the busiest top-line metrics.

    Before increasing your next LinkedIn budget, rebuild one role from end to end. Separate active and passive audiences, add one hard qualifier to the creative, route candidates through a concise role page, and add qualified applications, interviews, and hires to the campaign report. That smaller redesign will show you where the waste actually begins.

    References


  • How to Prove AI Marketing ROI Before Scaling Your Spend

    How to Prove AI Marketing ROI Before Scaling Your Spend

    Your AI dashboard can look busy while the P&L remains unchanged. Faster drafts, more creative variants, rising AI visibility, and a lower apparent cost per task do not prove that AI created economic value.

    If you need to defend an AI marketing budget, you need a credible answer to three questions: what changed compared with what would otherwise have happened, how that change became profit or cash savings, and what the change cost in full. The framework below gives you a practical way to answer them before a promising pilot becomes an expensive permanent line item.

    Key takeaways

    • Classify every AI investment as an operational-efficiency bet, a marketing-performance bet, or a distribution-channel bet. Each requires different evidence.
    • Calculate ROI from verified economic benefit, not output volume, model usage, impressions, mentions, or hours theoretically saved.
    • Include implementation, data preparation, quality assurance, training, governance, measurement, and rework in the cost base.
    • Compare results with a credible counterfactual. A before-and-after improvement alone does not show that AI caused the change.
    • Keep released capacity separate from cash savings. Time saved has economic value only when you remove a cost or redeploy the capacity productively.
    • When a platform cannot provide adequate performance data, fund it as a capped learning experiment rather than presenting it as a proven acquisition channel.

    Define the AI bet before you calculate its return

    AI marketing is not one investment category. The label often hides three economically different bets. Combining them in one dashboard produces an attractive blended number that nobody can audit.

    Operational-efficiency bets

    An operational bet uses AI to reduce the resources needed for research, briefing, production, analysis, reporting, or quality control. Its first useful measures are cost per approved deliverable, cycle time, rework, throughput, and error rates.

    The word approved matters. Producing twice as many drafts is not a productivity gain if editors reject more of them or senior staff spend the saved time correcting unsupported claims. Measure the complete path from request to usable output, including human review.

    Marketing-performance bets

    A performance bet uses AI to improve an existing marketing activity: audience selection, creative development, content optimization, lead qualification, conversion, or budget allocation. The economic question is not whether the AI produced more activity. It is whether the intervention created incremental qualified demand or contribution profit.

    Pair the business outcome with a guardrail. If AI-generated landing pages increase initial conversions but attract poorly matched leads, conversion rate alone will overstate the return. Depending on your funnel, the guardrail may be qualification rate, sales acceptance, cancellation, return rate, retention, factual accuracy, or brand compliance.

    Distribution-channel bets

    A channel bet pays for access to an audience or invests in visibility inside an AI-mediated discovery environment. ChatGPT advertising and programs intended to improve a brand’s presence in AI answers belong here, even though one is paid distribution and the other may involve content, technical, and authority work.

    Channel economics depend heavily on observability. An early ChatGPT advertising program combined manual buying through calls, email, and spreadsheets with limited performance reporting. That does not prove the inventory has no value. It means an advertiser cannot responsibly claim performance ROI that the available evidence does not establish.

    Write a one-sentence investment claim before approving any of these bets: Because we will use AI to change a named process for a defined audience, a named business outcome should improve through a stated mechanism. If the team cannot complete that sentence without using words such as engagement, innovation, scale, or efficiency as substitutes for an outcome, the proposal is not ready for an ROI calculation.

    Then record seven fields on an investment card:

    1. The decision the measurement must support: scale, continue, redesign, or stop.
    2. The exact AI intervention and the workflow or channel it changes.
    3. The mechanism that should connect the intervention to value.
    4. The eligible audience, campaign, account, content group, or business unit.
    5. The baseline and the best available counterfactual.
    6. One primary business outcome and the relevant quality guardrails.
    7. The maximum cost, evidence standard, decision owner, and decision point.

    This card prevents metric drift. A team should not begin with qualified pipeline as its goal, fail to influence pipeline, and later declare success because the model generated a large number of assets.

    Build a cost and value ledger that survives scrutiny

    Unmarked compute, labor, storage, revenue, and savings objects are arranged in parallel cost and value lanes.

    The clean formula is simple:

    AI marketing ROI = (verified economic benefit – fully loaded AI cost) / fully loaded AI cost x 100.

    The difficult work sits inside the two inputs. Verified economic benefit should normally consist of incremental contribution profit and realized cash savings. Fully loaded cost should include every material resource required to produce, govern, measure, and maintain the result.

    Count more than the software invoice

    Your cost ledger may need the following entries:

    • Subscriptions, model usage, API charges, media, and platform fees.
    • Integration, workflow design, prompt development, and automation maintenance.
    • Data preparation, permissions, tagging, analytics configuration, and CRM work.
    • Employee and contractor time spent operating or supervising the workflow.
    • Editorial review, factual verification, brand review, security review, and legal or compliance review where applicable.
    • Training, documentation, adoption support, and process redesign.
    • Experiment design, holdout management, reporting, and analysis.
    • Rework caused by incorrect, inconsistent, duplicated, or unsuitable output.
    • Replacement costs for tools or services that the new system does not fully eliminate.

    Use an internal labor-cost basis consistently. A billable agency rate, an employee’s loaded cost, and the opportunity value of an hour are different numbers. Switching among them to make a project look attractive turns the model into advocacy rather than measurement.

    Separate profit, savings, and capacity

    Incremental revenue is not incremental profit. Convert additional revenue into contribution profit by applying the relevant contribution margin and subtracting variable fulfillment costs that arise with the new business. Keep the measurement period consistent across the revenue, cost, and margin inputs.

    Cash savings require an expense to disappear. A cancelled vendor contract, eliminated overtime, reduced external production spend, or a role that no longer needs to be added can create a realizable saving. A team finishing a task earlier while payroll remains unchanged creates capacity, not an immediate cash saving.

    Capacity can still be valuable, but you need to show where it went. If marketers use released time to run additional experiments, improve sales enablement, or serve more accounts, measure the resulting throughput and economic outcome. If the time simply becomes slack, record the operational improvement without booking it as profit.

    Avoid double counting. Suppose AI reduces editing time and the team uses that time to launch an additional campaign. If the campaign produces verified incremental contribution profit while payroll stays constant, credit that contribution profit. Do not also claim the same editing hours as a payroll saving.

    Calculate the breakeven outcome before launch

    A breakeven calculation gives the team a concrete hurdle before optimism enters the reporting:

    Required incremental outcomes = fully loaded AI cost / contribution profit per incremental outcome.

    An outcome might be a completed purchase, a retained customer, a qualified opportunity, or another event with defensible economic value. Match the event to the investment. A campaign intended to create qualified pipeline should not use raw leads as its breakeven unit merely because leads are easier to count.

    If contribution varies widely, calculate more than one scenario using your own documented assumptions. Label those results as forecasts until observed outcomes replace them. The purpose is not to predict the future precisely. It is to expose what the investment must accomplish to pay for itself.

    Use an evidence standard the channel can support

    Two matching transparent chambers compare conventional and AI-assisted marketing routes under controlled conditions.

    Attribution and incrementality answer different questions. Attribution assigns credit to a touchpoint under a chosen rule. Incrementality estimates what happened because of the marketing intervention and would not otherwise have occurred. ROI needs the second answer, even if attribution data helps you investigate the first.

    Choose the strongest feasible design before the campaign begins. The following ladder runs roughly from stronger causal evidence to weaker directional evidence:

    1. A randomized holdout in which eligible units are assigned to treatment and control.
    2. A matched comparison using similar regions, accounts, audiences, or content groups, with known differences documented.
    3. A staggered rollout that compares early and later groups across the same period.
    4. An instrumented journey using permitted campaign parameters, dedicated destinations, CRM fields, offer paths, or customer-reported discovery.
    5. An adjusted before-and-after comparison that explicitly accounts for other material changes.
    6. Platform-reported attribution, AI visibility, impressions, mentions, citations, or production volume without a counterfactual.

    Report what the design supports. A controlled test may justify a causal estimate. An instrumented path can show that a tracked interaction preceded a conversion, but it does not automatically show that the interaction caused the conversion. A visibility increase is evidence of increased presence, not evidence of revenue.

    Before-and-after reporting is especially easy to misread. Pricing, promotions, seasonality, sales follow-up, product availability, competitor activity, media mix, and site changes can all move during the same period. Document those factors and use a concurrent comparison when feasible.

    Measure AEO and GEO as a connected outcome chain

    For AI search, answer engine optimization, and generative engine optimization, visibility belongs near the beginning of the outcome chain. Define a stable prompt set around your actual audience and buying questions. Record the model, date, conditions, brand mentions, citations, cited pages, and competitor presence. Sample consistently instead of treating one favorable response as a benchmark.

    Next, connect visibility to behavior where observable: qualified referral sessions, engaged visits, branded demand, assisted leads, direct inquiries, sales conversations, and customer-reported discovery. Then connect those behaviors to qualified pipeline, purchases, retention, or contribution profit.

    Do not assign revenue to an AI mention merely because a conversion occurred later. When the click trail is incomplete, present the visibility result, the observed business movement, and the uncertainty between them as separate facts. That is more useful than forcing an exact return from incomplete data.

    Treat low-observability advertising as a learning purchase

    When an advertising platform cannot provide the performance data needed for an incrementality analysis, cap the spend at an amount the business can afford to treat as experimentation. Write down the learning objective, the permitted instrumentation, the audience or placement being explored, and the evidence that would justify another round.

    Where the format permits, use a dedicated landing path, campaign parameters, a distinct offer, CRM source fields, and a customer-reported discovery question. None of these creates a perfect counterfactual, but they can produce more decision-useful evidence than aggregate traffic and anecdotal sales feedback.

    Do not promise a performance return above the platform’s evidence ceiling. Early ChatGPT advertisers faced too little performance data to prove that ads translated into business results. In that situation, the honest deliverable is a documented learning result, not a fabricated return on ad spend.

    Protect the economics after the pilot

    An AI pilot can improve production economics and still weaken the surrounding business model. This is particularly visible in agencies: automation reduces delivery effort, while clients expect the efficiency to lower their fees. SparkToro’s worldwide survey of agency owners put concern about AI as a potential threat at 53% in 2025, up from 44% in 2024.

    Reporting only tokens consumed, assets produced, or hours removed reinforces the idea that the service is a commodity. The durable value sits in diagnosing the commercial problem, choosing the right intervention, creating defensible evidence, interpreting exceptions, and taking responsibility for the decision that follows.

    Choose a pricing model that matches measurability

    AI does not make every engagement suitable for performance pricing. Use the model that matches the amount of control and measurement available:

    • Use a fixed fee when the deliverable, quality standard, scope, and acceptance criteria are clear.
    • Use a retainer when the client is buying continuing strategy, experimentation, governance, and decision support rather than a predetermined volume of output.
    • Use time-based pricing for ambiguous discovery work where the necessary scope cannot yet be defined responsibly.
    • Use a performance component only when both parties agree on the eligible outcome, system of record, baseline, attribution or incrementality rule, measurement window, exclusions, data access, and payment limits.

    Performance fees create disputes and potentially uncapped financial exposure when those terms are vague. Put the definitions, adjustment rules, caps, termination conditions, and audit rights in the contract, and have qualified counsel review material compensation changes.

    Track contribution margin by account or service line: revenue minus direct labor, AI usage, contractors, and appropriately allocated delivery support. If efficiency improves, decide explicitly whether the gain will fund a lower price, higher quality, greater throughput, or a healthier margin. Assuming one workflow change will deliver all four at once usually hides an unpriced tradeoff.

    The commercial pressure is not hypothetical. Some agency sales cycles have lengthened from 7-8 weeks to more than 12 weeks as buyers question what AI should do to price and value. Answer that question directly in proposals: disclose where automation supports delivery, define the human accountability that remains, and tie the fee to scope and economic responsibility rather than an inflated count of manual hours.

    Include quality control and talent development in the model

    Removing routine work can also remove the training ground that produces future strategists. Sixty-six percent of agency owners expressed concern about shrinking career opportunities for junior staff. Treating that as someone else’s future problem understates the long-term cost of automation.

    Redesign junior work instead of deleting development. Have less-experienced marketers verify AI output against source material, document recurring failure modes, prepare experiment readouts, observe senior decision reviews, and own bounded tests under supervision. Include the supervision and training time in the investment ledger. A margin that depends on unrecorded senior rework is not a real margin.

    Put every investment through a scale, continue, or stop gate

    A pilot does not need perfect attribution, but it does need a precommitted decision process. At the decision point:

    • Scale when verified economic benefit exceeds the fully loaded cost, quality guardrails remain inside approved limits, and the evidence is strong enough for the amount of money at risk.
    • Continue as an experiment when the signal is promising, the uncertainty is material, and the next test has a realistic way to resolve that uncertainty.
    • Redesign when the mechanism appears plausible but adoption, data quality, workflow fit, or measurement prevented a fair test.
    • Stop when the benefit remains below the economic hurdle, guardrails fail, or the evidence gap cannot be closed at a proportionate cost.

    Start with the largest AI-related line in your current marketing budget. Label it as an efficiency, performance, or channel bet. Rebuild its fully loaded cost, write down the counterfactual, and identify the strongest evidence you can obtain. If you cannot do those three things yet, move the spend into a capped experiment. Scale it only when the economic benefit and the quality of evidence can withstand the same scrutiny as any other marketing investment.

    References

  • Google Ads Modernization: Better Automation, Better Measurement

    Google Ads Modernization: Better Automation, Better Measurement

    If Google Ads feels less like a collection of ads you build and more like a system you supply with signals, your instinct is right. Manual controls still matter, but the consequential decisions increasingly happen upstream: what Google may use, which conversion it should optimize, how long a click remains eligible for credit, and whether your inventory data can be trusted.

    That changes how you should modernize an account. Adding automation before fixing measurement gives the bidding system a faster way to pursue the wrong outcome. The practical order is measurement first, structured inputs second, automation third, and independent business validation throughout.

    Modernization moves control upstream

    In the policy change dated March 17, Google phased out multiple legacy ad-format policies, including older frameworks concerning form ads and image quality. Many of the formats had evolved into newer campaign types, so maintaining separate rule sets created unnecessary complexity.

    This policy cleanup does not mean creative quality, landing-page suitability, or compliance stopped mattering. It means an old checklist organized around retired formats is no longer a reliable account-control system. You need to map each campaign, asset, feed, and destination to the current policies governing the format that actually serves.

    The same shift appears in campaign execution. Google can select inventory, assemble richer ad experiences, and optimize bids from the signals you provide. You may make fewer decisions about the exact ad shown in an individual auction, but you have more responsibility for the boundaries within which those decisions occur.

    For every active campaign, document the inputs that define those boundaries:

    • The business outcome the campaign is supposed to produce.
    • The primary conversion action Smart Bidding uses as its success signal.
    • The click attribution window attached to that conversion.
    • The feeds, assets, prices, images, and landing pages available to automation.
    • The business system you will use to verify sales, revenue, profit, or qualified leads.
    • The current policy framework governing the campaign and its assets.

    If any item is unknown, you have found a more important modernization task than changing a bid strategy. Automation cannot repair an ambiguous objective. It can only optimize the signal it receives.

    Choose an attribution window from buying behavior

    Anonymous shoppers follow different-length paths from discovery and comparison to a completed purchase beneath a translucent time arc.

    An attribution window is an eligibility rule. It determines how long after an ad click a later conversion may receive credit. It does not prove that the click caused the sale, and it should not be treated as a substitute for understanding the customer journey.

    The default setting can be badly matched to the buying cycle. One DTC retailer had a 2.2-day average path to conversion, with a substantial share of purchases happening within a day, while Google Ads was using a 30-day click window. That gap left plenty of time for Google to claim orders after other marketing interactions had occurred, especially when Meta was receiving most of the advertising budget.

    The answer is not to copy a 7-day window into every account. A considered purchase with a longer sales cycle can legitimately need more time. Shortening its window too aggressively would exclude conversions that belong in campaign evaluation and could deprive Smart Bidding of useful signals.

    Start with the conversion-path data in your own account. Look for the delay between an eligible click and the conversion you actually value. Then ask whether the current window reflects that observed behavior or merely preserves a default.

    Because the primary conversion action influences bidding and spend, changing it in place can create an avoidable financial risk. It can also start a bidding recalibration before you have established whether the new measurement definition is suitable. A parallel secondary action gives you a safer comparison.

    The DTC implementation used this sequence:

    1. Duplicate the primary purchase conversion.
    2. Give the duplicate a 7-day click window and keep it as a secondary conversion action.
    3. Observe the original and duplicate actions side by side for two weeks.
    4. Move the shorter-window action into primary optimization only after checking its behavior. The account made that transition on January 12, 2026.

    That sequence separates measurement design from bidding intervention. During the comparison, inspect how much credited conversion value falls outside the proposed window, whether the excluded conversions fit the known purchase cycle, and whether the shorter definition improves agreement with the commerce or CRM record.

    Prepare stakeholders for two possible effects. Reported conversions may initially fall because fewer delayed orders qualify, and Smart Bidding may need to recalibrate when the primary signal changes. Neither effect automatically means the decision was wrong. The question is whether the new setting represents real buying behavior more faithfully and produces a cleaner optimization signal.

    Treat inventory feeds as campaign controls

    Products move from warehouse shelves through data validation gates into an automated campaign system while hands adjust the feed controls.

    Google Ads supports vehicle feeds from Merchant Center inside Search campaigns. The resulting listings can add make, model, price, and images to the text-ad experience. They appear as clickable assets beside or below the main ad and can send a user to a specific vehicle page or a broader landing page, depending on the interaction.

    This is more than a creative enhancement. The feed becomes part of ad selection, message construction, and destination selection. Google decides which vehicles to show from the query context and inferred intent, so the advertiser controls the quality of the candidate inventory rather than manually choosing the vehicle for every auction.

    That makes feed governance campaign governance. Before enabling the integration, check the parts of the experience automation will expose:

    • Confirm that the Merchant Center feed represents the inventory you are prepared to advertise.
    • Check that make, model, price, and image data agree with the corresponding vehicle page.
    • Open the destination as a prospective buyer would and verify that the advertised vehicle or relevant inventory path is easy to find.
    • Decide who owns corrections when inventory, pricing, imagery, or destination content changes.
    • Keep the existing Search campaign structure unless a separate campaign serves a real business purpose; the feed integration does not require duplicate campaign setup.

    Do not judge the feature only by whether the ads look richer. Segment reporting by Click type to distinguish interactions with vehicle listings from standard ad interactions. Compare the downstream conversions and conversion value available in the account, then validate lead or sale quality in the business system of record.

    A vehicle-listing click can indicate stronger inventory interest, but a higher click-through rate alone does not establish better economics. If the listing attracts people to unavailable inventory, a mismatched price, or an unhelpful destination, the richer format has amplified a data problem. If it attracts buyers who progress to qualified leads or profitable sales, the feed is doing useful work.

    Separate attribution improvement from business improvement

    Platform ROAS is useful for optimization, but it is not a complete account of incremental return. Google and Meta can each credit the same order under their own attribution rules. A shorter Google click window can reduce some delayed overlap, but changing the window does not itself create revenue or prove causality.

    Use three measurement layers, each answering a different question:

    • Platform attribution: Which conversions does Google Ads credit under the configured rules, and what signal is bidding using?
    • Business records: Did total sales, revenue, profit, qualified leads, or closed business improve in the system where those outcomes are recorded?
    • Incremental analysis: How much additional business did each channel likely generate beyond what would have happened without that investment?

    The DTC account produced an instructive, account-specific result after moving from the 30-day to the 7-day click window. The comparison covered the 30 days after the switch against the preceding period:

    Measurement layerMeasureReported change
    Google AdsSpendDown 6.3%
    Google AdsConversionsUp 42.9%
    Google AdsConversion valueUp 52.1%
    Google AdsROASUp 62.3%
    ShopifyTotal salesUp 20%
    ShopifyNet profitUp 30%
    Marketing mix modelingGoogle incremental ROASUp 10% to 1.82
    Marketing mix modelingMeta incremental ROASDown 25% to 0.59

    Those figures do not prove that shortening the window caused the gains. Campaign refinements were happening at the same time, so the effects cannot be cleanly isolated. The result should be read as evidence that performance remained stable while measurement became more aligned with the retailer’s short purchase cycle, not as a promise that a 7-day window will lift every account.

    It is also important not to compare Google Ads ROAS directly with incremental ROAS as though they were the same metric. Platform ROAS reflects conversions credited under platform rules. Incremental ROAS estimates additional return attributable to the channel. The ending value of 1.82 is an account result, not a universal target or threshold.

    The strongest interpretation comes from triangulation. Google Ads showed more conversion value on less spend, Shopify recorded higher sales and profit, and the marketing mix model reassigned the relative contribution of Google and Meta. Agreement across those layers supports a decision more convincingly than an isolated platform metric, while the concurrent campaign work still limits any causal claim.

    A shorter, better-aligned window can also make optimization feedback more current. Delayed attribution is reduced, diagnostics become easier to interpret, and Smart Bidding receives fresher signals after recalibration. That operational benefit matters even when the reported headline improvement is modest.

    Run your next account review in the right order

    A modern account review should begin with signal quality, not with a tour of campaign settings. Use this sequence to keep measurement changes, feed changes, and bidding changes distinguishable:

    1. Name the business outcome. Write down the sale, profit, qualified lead, or other result the campaign is expected to influence, plus the system that records it.
    2. Inspect conversion timing. Use conversion paths to understand how quickly the valued outcome normally follows an eligible ad interaction.
    3. Audit the primary conversion. Confirm that Smart Bidding is optimizing the intended action and that its attribution window fits the observed buying cycle.
    4. Test measurement in parallel. When a material window change is warranted, create a secondary version first so you can compare definitions without immediately changing bidding.
    5. Audit automation inputs. Review feeds, prices, images, assets, and destinations as parts of the campaign, not as background data maintained by someone else.
    6. Segment the new experience. For vehicle feeds, use Click type to isolate listing interactions and compare their downstream value with standard ad interactions.
    7. Validate outside Google Ads. Check platform movement against commerce or CRM outcomes and, when available, an incremental measurement method such as marketing mix modeling.
    8. Update the policy checklist. Remove dependencies on retired format-specific frameworks and map active formats to the current rules that govern them.

    Key takeaways

    • Google Ads modernization shifts control toward conversion definitions, attribution settings, structured data, assets, and policy boundaries.
    • Your attribution window should follow observed buying behavior rather than a default or a result from another account.
    • A secondary conversion action lets you evaluate a shorter window before exposing primary bidding and budget decisions to it.
    • Vehicle feeds turn Merchant Center inventory into Search ad inputs, while Click type reporting helps separate listing interactions from standard ad interactions.
    • Platform ROAS, business results, and incremental return answer different questions; a defensible decision uses all available layers.
    • Changing attribution can improve clarity and feedback speed, but it cannot by itself prove or create business growth.

    At your next review, resist the urge to begin with bids. Pull the conversion-path data, identify the primary action and its window, name the independent business record, and inspect every feed Google can use. Once those inputs are trustworthy, automation has a clear job and you have a credible way to judge whether it performed.

    References

  • Google Video Ad Changes: What Advertisers Should Do Next

    Google Video Ad Changes: What Advertisers Should Do Next

    Your video plan now has two moving parts. Google Ads is giving you a clearer view of video inside Performance Max, while YouTube is testing an ad experience that may keep a brand visible after a viewer skips. One affects what you can measure. The other may affect what people continue to see.

    You don’t need to rebuild every campaign in response. You do need to separate observation from causation, audit whether your creative still works when the full video is not watched, and make budget decisions with more discipline than a single reporting split can provide.

    Two video changes require two different decisions

    Google Ads has added an “Ads using video” segment to Performance Max reporting. It lets you separate results according to whether video was used in the ad mix. That makes video easier to investigate without changing how the campaign itself is managed.

    YouTube is also testing a sticky branded banner that can remain after a viewer skips an ad. Instead of disappearing with the skipped video, the advertiser’s card stays visible in the player until the viewer dismisses it.

    These developments should not be folded into one vague “video is becoming more important” conclusion. The Performance Max segment is a reporting change. It helps you diagnose where video is associated with results. The YouTube experiment is a format change. If it expands, it could alter the creative value of a skipped impression.

    That distinction determines your next move: use the first change to improve analysis, and use the second to pressure-test creative. Neither one, by itself, justifies an immediate budget increase.

    Use the Performance Max segment as a diagnostic, not a verdict

    An analyst examines a video performance tile with a magnifying lens while it remains connected to audience, budget, and conversion evidence.

    The new segment answers a useful descriptive question: how do results differ when video is part of the ad mix? It does not answer the causal question: how much incremental performance did video create?

    That difference matters because campaigns or reporting rows can vary for reasons unrelated to format. Budget, products, offers, audience signals, seasonality, conversion setup and campaign maturity can all influence the result. Performance Max also automates delivery, so the advertiser is not holding every placement and exposure condition constant.

    Use this reporting workflow before you change creative or move spend:

    1. Write down the decision you are trying to make. “Should we expand video assets in this campaign?” is useful. “Is video good?” is too broad to test.
    2. Choose the business outcome before looking at the split. Use the campaign’s actual objective, such as qualified conversions, conversion value, cost per acquisition or return on ad spend.
    3. Apply the “Ads using video” segment and compare video-associated results with the relevant non-video results.
    4. Check whether the compared rows share the same campaign objective, conversion configuration, date range, market, offer and product mix. Treat a mismatch as a confounding factor, not a minor footnote.
    5. Read volume and efficiency together. More conversions at an unacceptable acquisition cost are not automatically an improvement. Better efficiency on negligible volume may not support expansion.
    6. Record the observation, your explanation for it and the smallest action that could test that explanation. Add a review date so the result does not become an unsupported permanent rule.

    What common result patterns should trigger

    • If video-associated results show stronger volume and acceptable efficiency, verify that the comparison is reasonably like-for-like. Then expand video in a limited, clearly identified set rather than across the account at once.
    • If volume rises but efficiency weakens, decide whether the marginal acquisition cost still fits your economics. Do not call the result a win solely because the conversion count is higher.
    • If efficiency improves but volume falls, inspect whether delivery is too limited to support a reliable operational decision.
    • If there is little difference, check whether the creative carries a distinct message and whether video was used enough to make the comparison meaningful. A flat result does not prove that format never matters.
    • If video-associated results are worse, inspect the offer, landing-page continuity and comparison conditions before blaming the video asset. The segment identifies a pattern; it does not isolate the cause.

    The safest budget rule is simple: do not move material spend on the strength of an observational split alone. Use the segment to find a promising hypothesis, then make a bounded change whose downside your account can absorb. This is especially important when a reporting difference could actually reflect a different product, audience or period.

    Design for a skip that may no longer end exposure

    A hand dismisses a video on a smartphone while a smaller tile with the same unbranded product silhouette remains visible at the screen edge.

    A skippable ad has traditionally created a clean mental boundary: the viewer skips, the video disappears and attention returns to the chosen content. A persistent branded card changes that boundary. The viewer may reject the video while still receiving a lighter, static brand exposure.

    This remains a test, so do not treat it as a universal YouTube format or redesign your entire asset library around it. Instead, use it as a reason to check whether your advertising can survive partial attention.

    Audit each active video in three passes:

    1. Watch only the opening portion. Can a viewer identify the brand, product category or problem being addressed without waiting for the full narrative?
    2. Pause on the clearest branded frame. Does the identity remain understandable as a compact visual, or does it depend on motion, narration or a later reveal?
    3. Review the destination and call to action. If a viewer engages after only partial exposure, will the landing page immediately confirm the same brand, offer and next step?

    Do not respond by squeezing every selling point into one frame. A residual banner has less room and less attention than a complete video. Prioritize recognition: a clear brand, one useful proposition and an intelligible action. Dense copy turns extended visibility into visual noise.

    You should also keep exposure and response separate in your analysis. A skip may no longer mean that every trace of the advertiser vanished, but it still does not demonstrate interest, recall or purchase intent. Do not relabel a skip as an engagement merely because a branded element may persist afterward.

    Until Google establishes how any wider release appears in standard reporting, keep completed views, skips, clicks, site visits and conversions distinct. For brand activity, persistent exposure may be a useful directional signal. For performance activity, downstream behavior still carries the decision.

    Turn the changes into a controlled account workflow

    The practical opportunity is not simply “make more video.” It is to connect creative decisions to a cleaner evidence trail. You want to know what changed, where it changed and which outcome would justify keeping it.

    1. Inventory Performance Max campaigns with and without meaningful video creative.
    2. Capture a baseline for the business metrics that govern each campaign before changing assets or budget.
    3. Use the video reporting segment to locate the campaigns with the clearest difference worth investigating.
    4. Check for alternative explanations, including different offers, products, markets, conversion actions or seasonal conditions.
    5. Select one bounded campaign or product group for the next creative change.
    6. Give the pilot an evaluation window consistent with your normal conversion cycle and decision process. Do not stop it early because of an isolated daily movement.
    7. Evaluate the business result alongside the delivery context, document the conclusion and decide whether to expand, revise or stop.

    If the sticky-banner experience appears in your inventory, document it separately from the Performance Max analysis. A YouTube interface test and a Performance Max reporting segment are not two stages of one controlled experiment. Combining them would make it harder to tell whether a result came from creative, delivery, format or measurement.

    Key takeaways

    • The “Ads using video” segment makes video easier to investigate inside Performance Max; it does not prove that video caused the reported difference.
    • Compare business outcomes under similar campaign conditions before changing budgets.
    • YouTube’s post-skip banner is a test, not a format you should assume every viewer will encounter.
    • Creative should communicate a recognizable brand and proposition even when the complete video is not watched.
    • Keep skips, persistent exposure, clicks and conversions conceptually separate until the platform provides enough reporting clarity to connect them responsibly.

    Start with one account audit: apply the video segment, identify one result that is worth explaining and write down the confounding factors before you touch the budget. Then review the corresponding video as if the viewer will see only a fragment. That gives you one defensible measurement decision and one concrete creative improvement, without pretending the platforms have given you more certainty than they have.

    References

  • A Marketer’s Playbook for Ads in AI-Assisted Discovery

    A Marketer’s Playbook for Ads in AI-Assisted Discovery

    Your next paid discovery brief may arrive before the format has a stable name. The ad might represent an entire store instead of a single product, while an AI assistant might capture useful engagement before the buyer ever visits your site. A campaign structure built around a keyword, a product, and a click will not give you enough control.

    You do not need to predict which interface will win. You need a preparation model that works across store-level placements, conversational environments, and whatever hybrid appears between them. That means strengthening the advertised object, the evidence around it, the routes a buyer can take, and the measurement required before you commit budget.

    The advertised object is getting larger

    Traditional shopping campaigns make the individual product the center of gravity. Google is testing Sponsored Shops, a Shopping block that groups several products from one retailer with the store name, ratings, and broader brand presence. The impression can therefore introduce an assortment and a merchant, not merely an item.

    Conversational discovery creates a different expansion. OpenAI has begun testing an Ads Manager dashboard with selected partners as it develops advertising around ChatGPT. The exact inventory, interaction model, and optimization system remain early. You should treat them as provisional rather than assume conversational ads will inherit the rules of paid search.

    The practical lesson is that the thing you advertise can sit at several levels. It might be a product, a coherent assortment, a store, or a solution to the need expressed in a conversation. Each level requires different proof and a different continuation after the impression.

    Add the following fields to your campaign planning before a new platform makes them mandatory:

    • User need: the problem, task, or buying situation that triggered discovery.
    • Advertised object: the product, collection, store, or solution path the unit represents.
    • Evidence: the ratings, product details, range, brand facts, and on-page claims that support the promise.
    • Possible interactions: product selection, brand selection, continued conversation, or a direct visit.
    • Continuation: the exact page or in-platform step that follows each interaction.
    • Business event: the observable action that would make the placement valuable.

    This prevents a common category error: treating a larger discovery unit as if it were merely a wider text ad. More visible products do not automatically create a coherent reason to choose the store. A conversational placement does not automatically produce a qualified visit. The advertised object must make sense as a whole.

    Build a discovery asset stack before you buy media

    A modular stack of storefront, product, evidence, inventory, and data elements connects to three abstract discovery interfaces.

    A store-level placement exposes the quality of the catalog as a portfolio. Sponsored Shops could favor merchants with stronger product feeds, useful assortment depth, and credible seller ratings, because several products and the retailer identity appear within the same unit. A weak item is no longer isolated; it can make the entire selection feel less relevant.

    Do not answer that pressure by putting more products into every group. Build an asset stack in which every layer has a defined job:

    1. Catalog facts establish what each product is, what it costs, whether it is available, and how it differs from nearby options.
    2. Assortment logic explains why a set of products belongs together for a particular need. Shared inventory is not enough; the group needs a shopper-facing reason to exist.
    3. Brand evidence gives the buyer a reason to trust the store behind the assortment. Ratings and consistent brand identity matter more when the merchant is part of the advertised object.
    4. Destination continuity carries the same promise from the ad into the next page. The buyer should not have to reconstruct the category, filter, or use case after clicking.
    5. Machine-readable agreement keeps feeds, visible page content, and structured data aligned. JSON-LD should repeat defensible facts shown to the user, not introduce a cleaner but contradictory version of the offer.

    Audit this stack by discovery theme rather than by campaign name. Write the buyer’s need in plain language, select the products that genuinely address it, and inspect every item in that set. Mark missing details, inconsistent naming, stale availability, weak images, unexplained variations, and claims that do not match the destination. Then decide whether the set deserves to be presented as a store-level recommendation.

    Keep product-level optimization intact while you do this. A broad assortment should not bury the strongest item or force unrelated products into the same story. You are adding a portfolio layer above the product layer, not replacing product relevance with brand reach.

    Give every interaction a deliberate next step

    A multi-element discovery unit creates more than one possible click. With Sponsored Shops, the split between clicks on the brand and clicks on individual products is an open measurement and usability question. If you only plan the final conversion page, you will miss the intent expressed by the element the buyer selected.

    Design a continuation for each route that the format exposes:

    • Store or brand interaction: use a focused storefront that confirms the range, positioning, and evidence shown in the unit. Avoid a generic homepage unless it already performs that job.
    • Collection interaction: preserve the discovery theme, relevant filters, and visible product set. Do not make the buyer rebuild the selection from a broad category page.
    • Product interaction: land on the exact item with its important facts, proof, availability, and next action easy to find.
    • In-assistant interaction: identify what the platform can report when the user continues the conversation without visiting your site. Treat unreported engagement as unknown, not as a click or a conversion.

    Put this destination map in the campaign brief before creative production. For every clickable element, record the likely intent, destination, page promise, and success event. If the platform allows distinct tracking parameters for different elements, use them. If it does not, record that limitation before deciding how much you are willing to spend.

    The first visible part of each destination should close the loop opened by the ad. A store-level promise about range should reveal that range. A product promise should show the exact product. A solution-oriented message should answer the need before introducing unrelated navigation. That continuity is more useful than repeating the ad headline word for word.

    Keep paid visibility separate from organic AI visibility in your reporting. Buying placement does not make an unclear page easier for an answer engine to understand elsewhere. Your AEO and GEO work still needs clear naming, consistent facts, direct answers, accessible evidence, and structured data that agrees with the visible page. Paid discovery adds distribution and control; it does not repair weak information architecture.

    Make measurement and budget pass the same gate

    A glowing interaction moves through a branching journey toward a product shelf, consultation doorway, or parcel while paired measurement and budget tokens pass through one gate.

    Use a measurement ladder, not a click counter

    Early ChatGPT advertisers have reportedly received weekly CSV reports containing impressions and clicks, while initial click-through rates have trailed Google Search. Delivery and click data can confirm that an ad ran. They cannot, on their own, tell you whether conversational discovery created valuable demand.

    Measure emerging discovery formats as a ladder:

    • Delivery: impressions, placement, advertised object, unit variant, and any available context about where the ad appeared.
    • Interaction: clicks by element, product selections, brand selections, or reported continuation inside the interface.
    • Progression: meaningful visits to product or collection pages, deeper product exploration, cart activity, lead starts, or another relevant journey event.
    • Outcome: completed purchases, qualified leads, revenue, or the business result attached to the campaign.
    • Incremental value: evidence that the new channel added outcomes rather than taking credit for demand another channel had already created.

    Mark unavailable fields as unavailable. Do not enter zero, because zero means the platform measured the event and found none. Missing element-level interaction data is itself a decision signal: it limits what you can learn about creative, assortment, and destination performance.

    Your tracking taxonomy should identify the platform, placement, advertised object, unit variant, and destination wherever the platform exposes those controls. Keep those dimensions separate. Otherwise, a store click and a product click can collapse into the same campaign total even though they represent different user decisions.

    Write the test decision before launch. State the hypothesis, the variable being changed, the primary business outcome, the supporting engagement signals, the acceptable downside, and the condition that will stop or expand the test. A low click-through rate is not automatically failure for an upper-funnel discovery unit, but it cannot be excused by vague claims about awareness. The downstream evidence must carry the argument.

    Set a budget gate that reflects platform maturity

    Some early ChatGPT advertisers have reportedly been asked for a minimum commitment of $200,000. That creates material financial exposure while reporting and optimization capabilities are still developing. Early access is not valuable merely because access is scarce.

    Before accepting a pilot, require clear answers to these questions:

    • Where can the ad appear, and how is sponsorship disclosed to the user?
    • Which audiences, contexts, placements, products, and destinations can you include or exclude?
    • Which delivery, interaction, conversion, and cost fields can you export, and at what reporting cadence?
    • Can you distinguish a brand interaction from a product interaction?
    • How will conversion measurement work when part of the journey remains inside the assistant?
    • Which campaign changes can you make during the pilot, and what are the stop conditions?

    Ring-fence money you can genuinely treat as experimental. Do not pull budget from a proven acquisition channel simply to claim first-mover status. If the minimum commitment is too large to absorb as a learning cost, or the reporting cannot connect delivery to business outcomes, observing the format is the disciplined choice.

    Move from observation to a pilot when destinations are traceable, controls are understandable, disclosures are clear, and the downside fits the approved test budget. Move from pilot to scale only when the outcome is repeatable and the reporting explains why it happened. Impressions and novelty are not scale criteria.

    Key takeaways for your next planning cycle

    • Plan around the advertised object, which may be a product, assortment, store, or solution path.
    • Treat catalog quality, assortment logic, brand evidence, landing pages, and structured data as one discovery asset stack.
    • Map separate continuations for brand, collection, product, and in-assistant interactions.
    • Measure delivery, interaction, journey progression, business outcomes, and incremental value as distinct layers.
    • Do not fund a large early pilot without exportable reporting, usable controls, explicit stop conditions, and a tolerable downside.

    Your next move is to choose a commercially important discovery theme and complete the advertised-object and destination map for it. Audit the supporting catalog, page evidence, and machine-readable facts before a platform representative puts a media proposal in front of you.

    When access becomes available, ask the platform to map every promised metric and control to that plan. If the gaps prevent a business decision, keep observing. If the path is traceable and the risk is bounded, run a focused pilot with written stop conditions. Emerging discovery inventory should earn its budget on evidence, just like any established channel.

    References

  • Master Google Ads Audits: Navigate the Changes in 2026

    Master Google Ads Audits: Navigate the Changes in 2026

    I recently tuned into an episode of Google’s Ads Decoded podcast where Brandon Ervin, Director of Product Management for Google Search Ads, shared insights on campaign consolidation, AI Max, and the future of advertiser control as we approach 2026. It was enlightening to hear a product team so in tune with advertiser concerns.

    However, I felt the podcast left some gaps. There’s a significant disconnect between Google’s narrative and what advertisers truly experience on the ground. While Ervin’s team is making strides, the fast-evolving platform presents new challenges, shifting performance measurement onto economic standards. This change fundamentally alters how we should approach search ad audits.

    As I reflect on recent improvements, it’s clear that enhancements like brand exclusions in Performance Max and Demand Gen, exclusion of site visitors in PMax campaigns, and improved search term visibility are crucial. These are responses to issues caused by bundling and aggressive automation. It’s worth noting that these controls arrived after advertisers were already knee-deep in implementation.

    In an era where Google’s product team pushes for advancement, it’s vital for us to audit whether these new tools genuinely expand control or simply restore baseline transparency lost with earlier automation efforts.

    In building the foundation for a 2026 search audit, we need to start with the basics, ensuring full ad extensions, strategic automated bidding, and maintaining negative keyword lists, among others. These are undeniable essentials that set the stage for deeper audits.

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    Focusing on the intricacies of signal architecture, I realize that while traditional controls like exact match and manual bids gave us direct oversight, the new controls shift focus to data quality, density, and selectivity. These influence the algorithm, which ultimately makes the decisions.

    An effective audit in this context addresses three core aspects: the quality of the data imported, the density of high-quality data available for modeling, and the selectivity of the data shared with Google. These elements are pivotal in shaping campaign success.

    Being mindful of incrementality is another key consideration. Google optimizes towards reported conversions, often encompassing brand search and retargeting signals that may not truly reflect incremental gains.

    It’s critical to analyze marginal returns as Google’s system operates on a blended cost-per-action model. Without understanding the incremental cost at each spend tier, advertisers risk overspending without realizing diminishing returns.

    ```json
{
  "alt": "Sales funnel process from meaningful engagement to a closed-won deal, highlighting stages and predictions.",
  "caption": "Navigating the sales funnel: From initial engagement to securing the deal, each stage plays a critical role in success.",
  "description": "This image illustrates a sales funnel process, moving from meaningful engagement with high-quality non-conversion activity to a closed-won deal with revenue booked. It highlights stages such as Lead, Strong Lead, MQL, SQL, OPP, culminating in WON. The funnel emphasizes prediction and density levels, with notes like 'We are here' at Strong Lead and 'These are our money makers' at MQL. It provides clarity on how leads progress to sales."
}
```

    Furthermore, as Ervin acknowledged, AI-driven campaigns sometimes misalign with intended targets. Query mapping has deteriorated over time, and AI Max exacerbates irrelevant matches, underlining the need to rigorously classify queries by intent to maintain high-value engagements.

    Lastly, the economics of network performance in bundled campaigns like Performance Max and Demand Gen need thorough examination as they obscure valuable insight into actual network-driven outcomes.

    By focusing on value redistribution through audits, we can ensure that the surplus value generated by high-intent searches isn’t misallocated into Google’s weaker inventory, thereby optimizing ad spend efficiency and accountability.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Meta’s European Digital-Tax Surcharge: A Budgeting Guide

    Meta’s European Digital-Tax Surcharge: A Budgeting Guide

    Your Meta campaign can hit its media-spend target and still exceed the amount finance expected to pay. From July 1, ads aimed at several European markets carry an additional charge of 2%, 3% or 5%, before any VAT.

    If you advertise across borders, your company’s address won’t protect the budget. The rate follows the location targeted by the ad, so you need to revise forecasts, performance metrics and client billing at the market level.

    The surcharge follows the audience, not your billing address

    Glowing ad signals travel from an office and unmarked invoice to audience locations across a map of Europe, where separate coin stacks appear.

    Under Meta’s announced digital-services-tax policy, the advertiser pays a location-specific surcharge beginning July 1. France, Italy and Spain carry a 3% rate; Austria and Turkey carry 5%; and the UK carries 2%.

    The practical rule is simple: look at where the campaign targets people, not where the ad account, agency or company is based. A US business targeting France is exposed to France’s 3% rate. A UK business targeting Austria is exposed to Austria’s 5% rate.

    Target locationSurchargeCost of $100 in media, before VAT
    France3%$103
    Italy3%$103
    Spain3%$103
    Austria5%$105
    Turkey5%$105
    UK2%$102

    The table shows why a media budget and a payable budget can no longer be treated as the same number. Meta’s own example is a $100 ad targeting Italy: the advertiser pays $103, excluding VAT. VAT remains separate, so $103 should not automatically be treated as the final invoice total.

    For campaigns covering several countries, don’t apply one country’s rate to the whole plan. Allocate spend by target market, multiply each amount by the applicable rate, and add the results. If delivery shifts toward a 5% market, the total charge rises even when aggregate media spend stays unchanged.

    For locations outside the listed schedule, don’t invent a planning rate. Check the billing notice for that market before approving the budget. The absence of a country from this table is not evidence about every other tax or platform fee that might apply.

    Choose which budget number must stay fixed

    You can’t preserve the same media delivery, the same total cash outlay and the same return ratio simultaneously when a new cost is added. Decide which constraint matters before changing campaign budgets.

    1. Keep media spend fixed. Use this when reach, traffic or conversion volume matters more than the existing cash ceiling. A $100 Italy media plan remains $100 in media, but its pre-VAT cost becomes $103.
    2. Keep total cash outlay fixed. Reduce allowable media spend so the media plus surcharge fits the approved total. For a $100 pre-VAT cap in a 3% market, allowable media spend is approximately $97.09, because $97.09 multiplied by 1.03 is about $100.
    3. Keep an economic return threshold fixed. Continue funding markets only while revenue or contribution margin supports the all-in cost. This may produce different budget decisions in two countries even when their in-platform conversion performance looks identical.

    Use two formulas in your planning sheet:

    • Expected pre-VAT cost = media spend x (1 + surcharge rate).
    • Allowable media spend = fixed pre-VAT cash cap / (1 + surcharge rate).

    Do not respond by cutting every European campaign 5%. That would overcorrect UK campaigns, which carry a 2% rate, and the 3% markets. It would also confuse a finance constraint with a performance decision. Apply the actual target-location rate first; then decide whether the resulting economics still meet your threshold.

    The same distinction matters in annual and quarterly plans. If your existing budget authorization covers media only, add a separate surcharge line. If it is an all-in cash ceiling, calculate how much media remains available after the charge. Write that assumption into the plan so the campaign manager and finance team don’t each interpret the same number differently.

    Measure all-in CPA and ROAS, not just platform performance

    A billing surcharge can create a reporting split. The advertising view may focus on media spend and auction performance, while the ledger records the higher amount actually paid. Unless your reporting layer imports the surcharge, both views can be internally correct and still lead to different decisions.

    Keep the media metrics for campaign diagnosis. They tell you whether targeting, creative, bids or conversion volume changed. Add all-in metrics for budget and profitability decisions:

    • Media CPA = media spend / conversions.
    • All-in CPA = media spend plus the surcharge / conversions.
    • Media ROAS = attributed revenue / media spend.
    • All-in ROAS = attributed revenue / media spend plus the surcharge.
    • All-in CPM = media spend plus the surcharge, divided by impressions, multiplied by 1,000.

    Suppose an Italy campaign produces the same impressions, conversions and revenue after July 1 as it did before. Its media performance has not deteriorated. Its economic performance has: every $100 of media now creates $103 of pre-VAT cost. If you compare the old media-only ROAS with the new all-in ROAS without labeling the methodology, the apparent decline can be mistaken for an auction or creative problem.

    Preserve both columns rather than rewriting history. Label one set as media metrics and the other as all-in metrics, then mark July 1 as a change in cost methodology. This gives operators a stable campaign diagnostic while giving finance and leadership the number that reflects actual cost.

    VAT needs its own treatment. Whether VAT belongs in a profitability model can depend on the business, jurisdiction and recoverability. Have the finance or tax owner decide that treatment; don’t make a universal VAT assumption inside the advertising dashboard.

    Build a market-level control sheet before approving spend

    A blank market-planning board organizes colored budget tokens beside a calculator, coins and an unlabeled map of Europe.

    A single blended percentage is acceptable for a rough scenario, but it is weak operational control. The country mix can change, and the difference between 2% and 5% is large enough to distort forecasts when spend is concentrated in the higher-rate markets.

    Your control sheet should contain one row per target market and these fields:

    • Target country and reporting currency.
    • Planned media spend.
    • Applicable surcharge rate.
    • Expected surcharge amount.
    • Expected total before VAT.
    • Approved cash ceiling and whether it includes the surcharge.
    • Conversions and attributed revenue.
    • Media CPA and ROAS.
    • All-in CPA and ROAS.
    • Invoice variance and the person responsible for resolving it.

    Then work through the change in this order:

    1. Inventory active and scheduled campaigns. Identify every campaign that targets France, Italy, Spain, Austria, Turkey or the UK, including campaigns run from accounts based elsewhere.
    2. Map spend to the correct rate. Avoid applying a company-wide rate when campaigns deliver into countries with different percentages.
    3. Declare the fixed constraint. Record whether the approved number is media spend, pre-VAT cash outlay or a return target.
    4. Update forecasts and purchase approvals. Add the charge as a visible line instead of hiding it in a miscellaneous variance allowance.
    5. Update performance reporting. Add all-in CPA, ROAS and CPM while keeping media-only metrics available for diagnosis.
    6. Reconcile the first affected invoice. Compare the charged amounts with spend delivered into each covered location. Investigate differences instead of silently absorbing them into campaign variance.

    You don’t necessarily need to split every multi-country campaign. Separate markets when country-level budget control, margin differences, client ownership or invoice reconciliation justify the added structure. Keep them consolidated when a unified campaign is operationally preferable, but calculate the expected surcharge as a spend-weighted amount rather than using the highest or lowest rate.

    Agencies also need a contract check. Don’t add a generic 5% client fee to all European activity: the listed rates differ, and the charge follows the target location. Confirm whether taxes and platform surcharges are included in the existing fee arrangement or passed through separately. If the contract is unclear, get legal or finance review before changing a client’s invoice.

    Key takeaways for your July 1 plan

    • Meta’s surcharge is determined by the ad’s target location, not the advertiser’s home country.
    • The listed rates are 3% for France, Italy and Spain; 5% for Austria and Turkey; and 2% for the UK.
    • A $100 Italy ad becomes $103 before VAT, so media spend and total payable cost are different numbers.
    • If the cash ceiling cannot rise, divide that ceiling by 1 plus the applicable rate to find the allowable media spend.
    • Use media-only metrics to diagnose campaigns and all-in CPA, ROAS and CPM to judge economic performance.
    • Forecast and reconcile by market, especially when one campaign covers countries with different rates.

    Before the next Europe-focused budget is approved, add the country, rate and all-in cost fields to the planning sheet and make one person responsible for the first invoice reconciliation. The surcharge itself isn’t optional for covered delivery; the decision you control is whether it becomes a planned cost or an unexplained miss.

    References