Your analytics can tell you that an AI assistant sent almost no visits and still miss the commercial event that mattered. If the assistant named three vendors, supplied the comparison criteria, ruled one out and reassured the buyer about another, the brand decision moved before any trackable session began.
The practical question is not whether AI referrals can replace organic search. They cannot. It is whether your brand enters an AI-mediated decision, how it is represented there and what the assistant encourages the buyer to do next. That calls for a brand-influence strategy with stricter measurement than a referral dashboard can provide.
Referral traffic and decision influence are different variables
AI assistants are weak traffic sources by conventional performance standards. Across 12 months of GA4 data from 100 sites, ChatGPT referrals amounted to 0.62% of the traffic delivered by Google organic. A separate benchmark found that organic search produced 39 times as much traffic and roughly 30 times as many conversions.
Those figures support a narrow conclusion: you should not forecast AI assistants as if they were another high-volume search acquisition channel. They do not support the broader claim that assistants have no influence. A conversation can alter a shortlist or resolve an objection without producing a referral at all.
The opposite overclaim is just as risky. Across 632 tests involving 12 sites, AI visibility did not produce a reliable subsequent lift in branded search or direct traffic. A brand effect may exist in particular journeys, but aggregate analytics have not established it consistently. You should therefore measure exposure and representation without presenting either as proven revenue attribution.
The scale still deserves attention. The reported audiences included 1.2 billion weekly ChatGPT users, more than a billion monthly AI Mode users and 2.5 billion people reached by AI Overviews. Those are audience figures, not evidence of commercial impact, but they explain why ignoring the interface solely because referrals are scarce would be a category error.
The behavior inside the interface matters more than the label attached to it. In observed AI Mode tasks involving choices such as credit-card loyalty programs and shoes under $75, people asked follow-up questions and developed an opinion inside the conversation. They did not behave as if each prompt were a conventional query followed by a list of pages to visit.
For AI Mode and AI Overviews, an initial request may also be expanded into several synthetic searches before passages are retrieved and assembled into an answer. That means your brand can be evaluated against questions the user never typed. A buyer who asks for suitable accounting software may receive an answer shaped by inferred questions about company size, integrations, implementation difficulty and price. Optimizing only for the literal starting phrase misses most of that decision surface.
The assistant can influence five moments in a brand decision
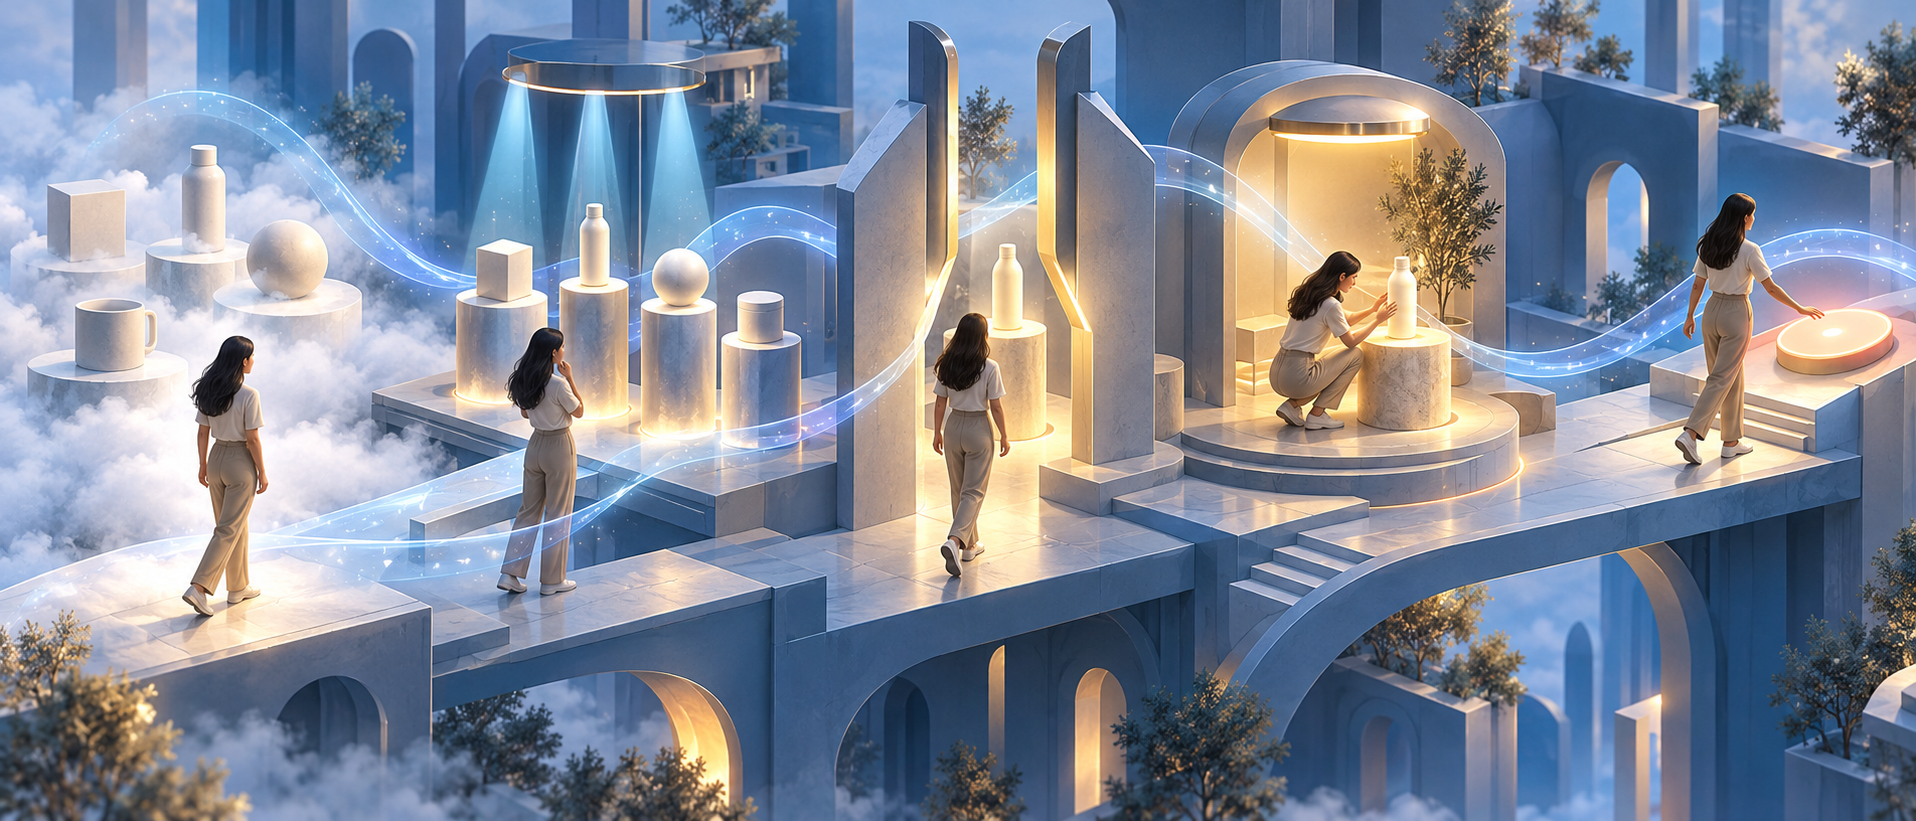
You need a more precise definition of influence than being mentioned. A passing citation and a recommendation are not equivalent. Audit the moments at which an answer can redirect the buyer:
- Candidate formation. The assistant decides which brands are worth mentioning. If you are absent here, the buyer may never reach your site or search for your name.
- Criteria formation. The answer tells the buyer what to value: price, compatibility, support, safety, ease of use, specialist expertise or another factor. A brand can appear prominently and still lose if the criteria favor a different kind of offer.
- Positioning. The assistant assigns your brand a role, such as the enterprise option, the low-cost option, the technical option or the beginner-friendly option. That shorthand can be commercially useful, misleading or badly outdated.
- Risk interpretation. Follow-up questions often concern limitations, trust and suitability. An inaccurate answer about a restriction or missing feature can eliminate you before a visit occurs.
- Next action. The assistant may recommend visiting the site, comparing alternatives, consulting a professional or taking no further action. This handoff determines whether influence becomes observable traffic.
This framework prevents a common reporting mistake. A raw mention count treats every appearance as positive and equal. In practice, being named as unsuitable is different from being conditionally recommended, and both are different from being presented as the default choice.
There is also no single AI viewpoint. A blinded panel of 16 licensed professionals scored 3,640 answers generated from the same 520 advice questions, and the leading platform changed by subject area. Claude led four of the eight areas, while ChatGPT and Google Gemini led two each. That evaluation concerned personal advice rather than commercial recommendations, so it does not prove that brand prompts behave identically. It does demonstrate why a result from one model should not be reported as universal AI visibility.
Context changes the answer too. A generic request for the best option may produce a popularity-driven list. Add a budget, location, technical constraint or regulated use case, and the shortlist can change. Your audit should therefore cover the situations in which people choose you, not merely your brand name and category keyword.
Build an influence scorecard instead of a referral dashboard
You cannot inspect private conversations, and you should not pretend that a prompt-monitoring tool reveals them. What you can measure is how representative decision prompts are answered under documented test conditions.
Start with prompts collected from real decision friction: sales questions, support tickets, on-site search, comparison-page queries and the objections that repeatedly delay a purchase. Cover category discovery, selection criteria, direct comparisons, drawbacks, suitability and next steps. Useful prompt forms include:
- Category discovery: Which options suit this use case and constraint?
- Criteria: What should a buyer check before choosing this type of product?
- Comparison: How do these named alternatives differ for this specific situation?
- Objection: What are the limitations or risks of choosing this brand?
- Suitability: Is this brand appropriate for a buyer with these requirements?
- Handoff: What should the buyer verify or do before deciding?
Keep a fixed baseline set so that changes are interpretable. Record the assistant, model when disclosed, date, prompt wording, supplied context and whether web retrieval was active. Run the same prompts across the assistants your audience plausibly uses. If you change the prompt and the model at the same time, you will not know what caused the answer to move.
| Dimension | Question to score | What to do with the result |
|---|---|---|
| Candidate inclusion | Does the brand appear for a relevant unbranded decision? | Investigate whether your category, audience and use case are stated clearly enough to retrieve. |
| Factual fidelity | Are products, capabilities, limitations and policies described accurately? | Correct conflicting or outdated first-party information before pursuing broader visibility. |
| Positioning | What role does the answer assign to the brand, and is that role commercially accurate? | Strengthen the evidence for the position you can legitimately own. |
| Recommendation strength | Is the brand merely mentioned, conditionally suitable, directly recommended or ruled out? | Read the stated rationale; rank alone does not explain the decision. |
| Evidence | Which claims are supported by citations or identifiable evidence? | Fill evidence gaps and correct pages that cannot substantiate the answer. |
| Consistency | Does the representation survive changes in model and relevant buyer context? | Separate persistent problems from one-off answer volatility. |
| Handoff | What action does the assistant recommend next? | Make the relevant verification, contact or purchase path easy to complete. |
Track categorical states rather than manufacturing a precision score. Absent, inaccurate, accurate but weakly framed, conditionally recommended and directly recommended are more informative than a composite number with no validated link to revenue. Preserve the answer text or a dated capture so that anyone reviewing the result can see the evidence behind your classification.
Attribution should remain layered. AI-answer monitoring tells you what an assistant may expose people to. Branded search, direct visits and assisted conversions show downstream demand but do not identify its cause. Customer surveys, lead-form questions and sales notes can provide corroboration if they ask whether an assistant affected discovery, comparison or validation. None of these signals proves causality alone.
This distinction protects you from two bad decisions: cutting the work because referral sessions are low, or claiming revenue because visibility and branded demand rose during the same period. Report what you observed, what changed after an intervention and which business signals moved alongside it. Label the rest as a hypothesis.
Make the brand easier to recommend without writing for robots
The goal is not to produce stiff copy addressed to an imagined machine. It is to make your offer, evidence and boundaries clear enough that a retrieval system can represent them without guessing.
- Establish a canonical description. State what the brand is, who it serves, where it operates and what each product does on accessible first-party pages. Resolve contradictions between product pages, documentation, location pages, profiles and old announcements.
- Publish decision-ready information. Explain suitability, prerequisites, limitations, integrations, policies and meaningful differences between options. A page that only declares leadership gives an assistant little material with which to justify a recommendation.
- Put evidence beside the claim. Connect performance statements to the method, scope and applicable version. Separate measured facts from customer opinions and editorial positioning.
- Answer the disqualifying questions. Say who the offer is not for and what it cannot do. Clear limits improve qualification and reduce the chance that an assistant fills a silence with an unreliable inference.
- Strengthen legitimate corroboration. Independent coverage, reviews and authoritative citations can help a system evaluate claims that would otherwise be self-asserted. Do not manufacture consensus or disguise promotional material as independent evidence.
- Keep important facts synchronized. When a price, feature, name, market or policy changes, update the pages and structured data that describe it. An answer engine cannot reliably resolve contradictions you leave published.
Structured data belongs in this work, but it is a consistency layer rather than a persuasion engine. Mark up visible, accurate information with the appropriate schema. Do not place unsupported claims in JSON-LD, and do not expect a schema tweak or an llms.txt file to compensate for unclear positioning, thin evidence or inaccessible content. Tactical shortcuts of that kind have been criticized as a distraction from the surfaces and fundamentals that already produce demand.
That is why AI optimization should usually share a roadmap with SEO, content operations, reputation management and digital PR. A clear product page can improve conversion, retrieval and sales enablement at once. An accurate comparison page can address a buyer objection whether it is read directly, quoted by an assistant or summarized in a search feature. Work that only inflates a visibility metric is harder to defend.
High-stakes categories require an additional standard. In the professional evaluation of personal advice, the rate of answers judged unsafe or factually wrong ranged from 2.1% to 8.5% across platforms. When professional help was warranted, referral rates ranged from 76.9% to 94.4%; crisis-help rates ranged from 83.3% to 98.3%. These are results from one defined evaluation, not permanent platform characteristics, but the spread is large enough to reject the assumption that every assistant will handle risk consistently.
If your content concerns health, finance, law or personal safety, publish scope, eligibility, material limitations and escalation guidance plainly. Have qualified professionals review consequential claims. Do not optimize toward an unconditional recommendation when the responsible answer depends on individual circumstances, and do not try to suppress advice to consult an appropriate professional.
Assistants can also respond differently to a user’s prior belief. In 80 prompts where professional judges considered the user clearly in the wrong, the rate at which a platform sided with the user ranged from 18.8% to 41.2%. Commercial behavior cannot be inferred directly from that test, but it is a useful warning: an answer is produced through model behavior and user framing, not by a neutral brand database.
Set the budget according to decision exposure, not click volume
AI influence work deserves more attention when buyers need explanation, comparison or reassurance before acting; when an answer can satisfy much of the research process without a visit; when an inaccurate description can materially damage trust; or when the product sits in a regulated or otherwise consequential category.
It deserves less incremental spend when your basic search presence is weak, your product facts conflict across the web, important pages are inaccessible, or nobody owns content maintenance. In those conditions, a specialized AI campaign adds another dashboard without fixing the information the systems depend on.
Keep conventional search investment tied to the traffic and conversions it demonstrably produces. Add AI-answer monitoring as a separate brand and decision-quality function. Its operating metrics should be coverage of priority decisions, factual accuracy, defensible positioning, quality of supporting evidence, consistency across relevant contexts and the rate at which known answer failures are corrected.
Key takeaways
- Low referral traffic does not prove low decision influence, but current analytics also do not prove a reliable brand lift from AI visibility.
- Measure inclusion, framing, factual accuracy, recommendation strength, evidence and next action rather than counting mentions alone.
- Test real decision prompts across relevant assistants and buyer contexts; do not treat one answer as a universal result.
- Improve canonical facts, decision-ready content, corroboration and structured-data consistency before spending on tactical AI-visibility tricks.
- In high-stakes categories, optimize for accurate qualification and safe escalation, not unconditional recommendation.
Start with the decision that matters most to your business. Capture how the relevant assistants handle it, identify the most consequential mismatch and fix the underlying information. Then rerun the same prompts under the same conditions. That gives you a defensible AI influence program: not a promise of invisible revenue, but a disciplined way to improve what buyers encounter before the click.
References
- Search Engine Land – AI search is a branding channel, not a distraction
- First Page Sage – Which AI Is Best for Advice in 2026?

Leave a Reply