If you are considering Profound’s Agents, the first decision is not which campaign to automate. It is which marketing decision is stable enough to delegate without losing context, brand judgment, or accountability.
Profound now lets you define an Agent’s job conversationally, assign tools, start runs on a schedule or trigger, inspect the rationale shown for each run, and retain control over what is sent or published. That can reduce setup friction, but it does not remove the need for precise instructions, constrained permissions, and a review process. Your results will depend less on how impressive the first run looks than on how well you design the operating boundary around every run.
What changes when a prompt becomes a running workflow
A chat prompt is temporary. You initiate it, watch the response, and decide what happens next. An Agent can begin work later, including when no marketer is actively supervising the interaction. That shift changes the core design problem. You are no longer asking only, “Can the model complete this task?” You are also asking, “Under exactly what conditions should it act, what may it access, and what must a person approve?”
Four components determine whether that workflow remains useful after the novelty wears off:
- The job: a bounded outcome the Agent can recognize as complete.
- The tools: the minimum data and actions required to do that job, not every available integration.
- The start condition: either a predictable schedule or a meaningful event that justifies a run.
- The release condition: a rule defining what the Agent may complete independently and what must wait for approval.
If any of those components is vague, the Agent has to fill the gap with an assumption. A single uncertain assumption in a draft is usually easy to catch. The same assumption repeated across scheduled runs becomes an operating defect.
Choose a schedule or trigger from the work pattern
Use a schedule when the work is naturally reviewed in batches and a modest delay will not change the decision. Recurring content audits, consolidated visibility reviews, and routine opportunity queues fit that shape when the required tools can provide the underlying data.
Use a trigger when a supported event creates a time-sensitive decision and the event contains enough context to begin safely. A trigger should represent a meaningful change, not merely activity. If marketers still have to investigate what happened before the Agent can do useful work, trigger the investigation or draft stage rather than the final action.
| Work pattern | Start condition | Safest initial output |
|---|---|---|
| Recurring review of accumulated data | Schedule | Prioritized recommendations for a person to review |
| Response to a supported, meaningful event | Trigger | Evidence summary and proposed response |
| External communication or publication | Either, depending on the workflow | Draft held behind an explicit approval gate |
Do not choose a trigger merely because it sounds more autonomous. Choose it when reduced latency improves the marketing decision. Otherwise, batching related work on a schedule usually gives reviewers more context and fewer interruptions.
Build the Agent around an operational contract
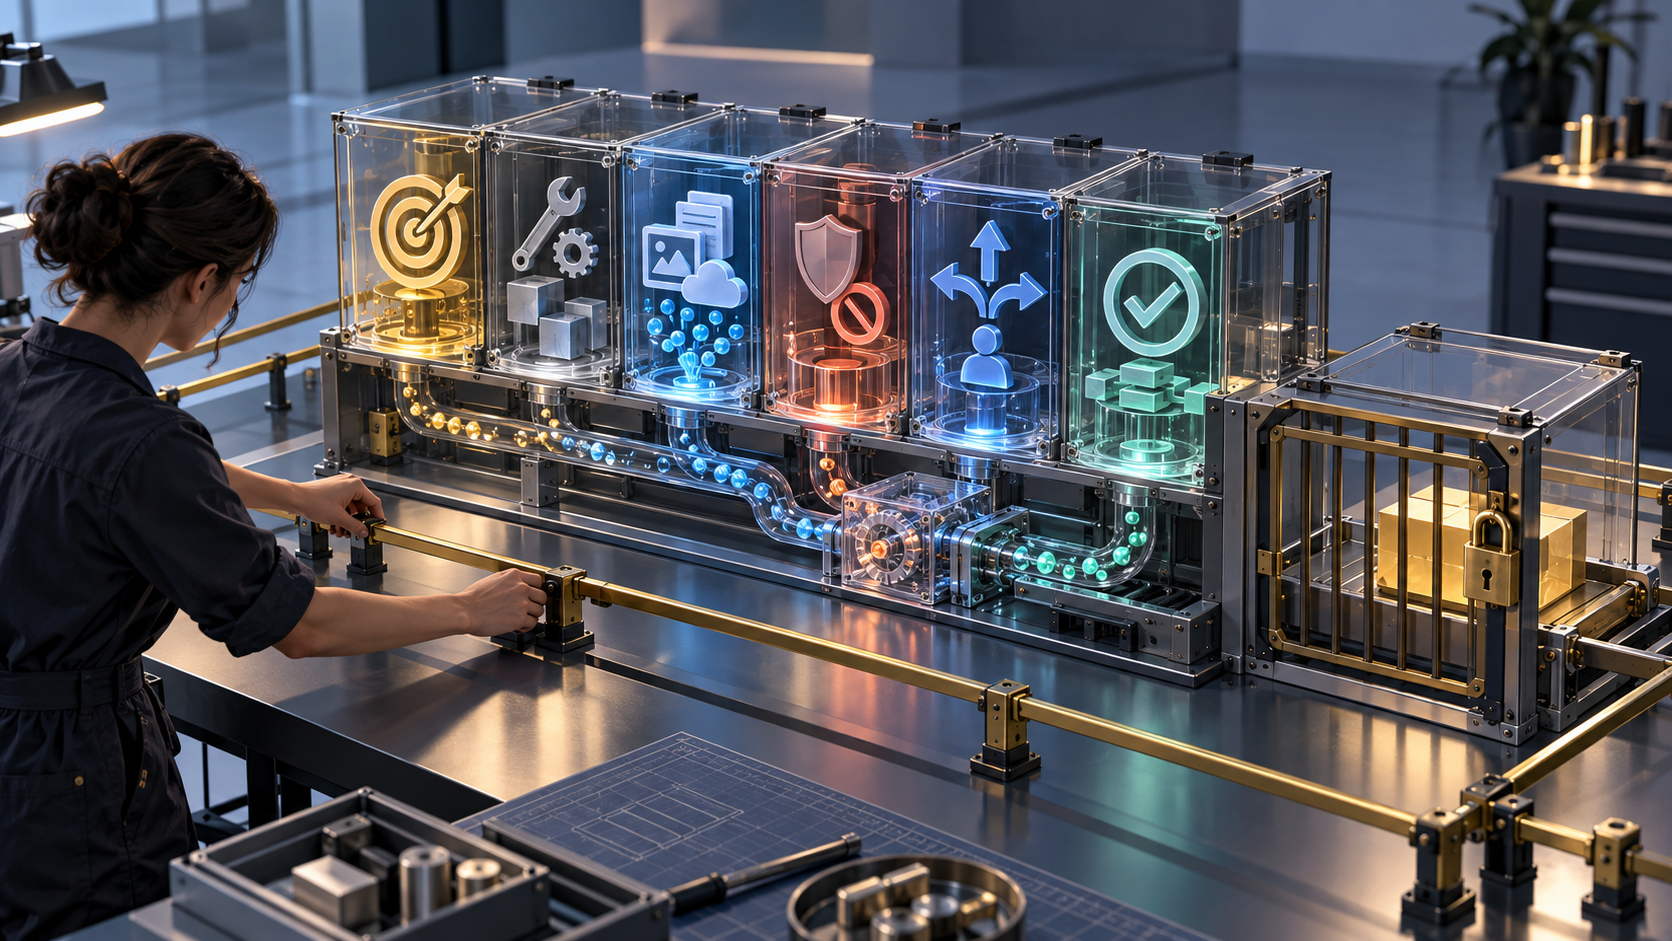
A conversational builder makes configuration easier, but natural language still needs the precision of a good operating procedure. Before you give the AI Marketer instructions, write a short contract for the job. If your team cannot agree on the contract, the task is not ready for autonomous execution.
- Name one outcome. Use a result such as “prepare an evidence-backed content update queue” rather than a department-sized ambition such as “improve our GEO strategy.”
- Define the scope. Specify the sites, markets, campaigns, content types, or approved records that belong in the run. State what is excluded.
- Identify authoritative inputs. Tell the Agent which available tools and datasets it may rely on. Explain what it should do when required data is absent, stale, or contradictory.
- Write the decision rules. Define how items are included, excluded, prioritized, and escalated. A priority label without a stated reason is not a usable decision rule.
- Specify the output. Require consistent fields so a reviewer can evaluate runs quickly. For an optimization queue, useful fields might include the affected URL, observed issue, supporting evidence, recommended action, and uncertainty.
- Add stop conditions. Tell the Agent not to guess when evidence is missing, not to move outside the named scope, and not to execute a higher-risk action merely because a lower-risk step succeeded.
- Assign an approval owner. Name the role responsible for accepting, correcting, or rejecting the output. “The marketing team” is not an owner.
- Define done. Make completion observable. A run is complete when it produces the required review package or a clear explanation of why it could not, not when it has simply attempted the task.
A practical first brief for an AI search workflow
A sensible initial use case is a read-only recommendation workflow. For example, ask the Agent to prepare a recurring queue of existing pages that may need an accuracy, coverage, or structured-data review. Adapt the following fields to the tools and data your Profound workspace actually provides:
- Outcome: produce a prioritized review queue, not completed edits.
- Scope: include only the approved domain, content collection, and market.
- Evidence rule: attach the observation supporting every recommendation and label uncertainty instead of inventing a cause.
- Output rule: return the page, issue, evidence, proposed next step, and reason for its priority.
- Stop rule: do not recommend a change when the required evidence is unavailable or internally inconsistent.
- Permission rule: do not modify structured data, edit a page, send a message, or publish anything.
This brief separates detection from intervention. That matters in SEO, AEO, and GEO work because identifying an apparent gap and deciding how to change a live page are different judgments. A recommendation may be technically plausible while still conflicting with editorial intent, product positioning, legal review, or the meaning of the page.
Avoid making sitewide schema changes, automatic factual updates, or external outreach your first Agent workflow. Those actions can spread one bad assumption across many pages or put an unreviewed statement in front of customers and partners. Begin with observation and drafting; expand permissions only after repeated runs show that the contract produces reviewable work.
Use approval and run reasoning as a control system
Human control is not a single approve button at the end. It is a permission ladder. Each step should open only after the previous step has become predictable:
- Observe: read approved inputs and identify possible issues.
- Recommend: explain the evidence and propose an action.
- Draft: prepare the exact change, message, or asset without releasing it.
- Execute a reversible internal action: update a queue, classification, or other recoverable state when your connected tools allow it.
- Send or publish: release externally only under an explicit policy and approval path.
The rationale displayed for a run gives you a useful review surface. It can reveal whether the Agent used the intended evidence, interpreted the goal correctly, and respected the boundaries. It is not proof that the conclusion is correct. A fluent explanation can still rest on missing data, an invalid inference, or an instruction that was ambiguous from the beginning.
Review each run in the same order:
- Goal: Did the Agent solve the assigned problem, or substitute an easier one?
- Evidence: Can the reviewer trace the recommendation to approved inputs?
- Rules: Were the inclusion, prioritization, and stop conditions applied consistently?
- Action: Is the proposed step proportionate to the evidence?
- Boundary: Did the Agent stay within its permitted scope and release level?
- Exception: Did it surface ambiguity for a person, or quietly resolve it on its own?
When a run fails, correct the contract before correcting only the output. If the Agent repeatedly treats weak evidence as conclusive, add an evidence requirement and a stop condition. If it keeps returning irrelevant pages, tighten the scope. If reviewers disagree about what should be approved, define the policy before increasing automation.
Keep a lightweight decision record outside the final deliverable. Capture the inputs or data version used, the Agent’s output, the review decision, the correction made, and any downstream result. This lets you distinguish a model error from bad input, unclear instructions, or a changed business rule. It also prevents the same correction from being rediscovered on later runs.
Judge the pilot by decision quality, not output volume
An Agent that produces more recommendations is not necessarily creating more value. It may simply be transferring a larger filtering burden to your team. The first pilot should therefore run in shadow mode: let the workflow produce its output, but do not let that output change a live page, contact an external party, or publish content.
Compare the Agent’s runs with the process your team already trusts. Record metrics that expose review effort and failure patterns:
- Valid-run rate: usable runs divided by all initiated runs. A run that lacks required evidence is not valid merely because it completed.
- Acceptance rate: recommendations accepted without a substantive change divided by recommendations reviewed.
- Correction rate: runs that require material factual, strategic, or policy corrections divided by completed runs.
- Escalation quality: whether the Agent sends genuinely ambiguous cases to a person while completing routine cases within scope.
- Review burden: the marketer time required to verify, correct, and approve the output.
- Downstream quality: the business or search outcome attached to approved actions, measured separately from the quantity of Agent output.
Set acceptable thresholds before the pilot produces results. Otherwise, a polished demonstration can tempt the team to redefine success around whatever the Agent happens to do well. The right threshold depends on the consequence of an error: a research queue can tolerate more false positives than a customer-facing message or a published factual change.
Expand the workflow only when the evidence supports a specific next permission. If recommendations are consistently relevant but drafting still needs work, permit drafting rather than publication. If output quality is strong but the evidence trail is incomplete, improve traceability before adding actions. Autonomy should increase one boundary at a time.
Key takeaways
- Start with one bounded, recurring marketing outcome rather than a broad strategic mandate.
- Treat tools as permissions and expose only what the job requires.
- Use a schedule for batchable work and a trigger only when a meaningful event makes speed valuable.
- Require evidence, consistent output fields, explicit stop conditions, and a named approval owner.
- Read the displayed run rationale as diagnostic context, not as proof of accuracy.
- Pilot in read-only or draft mode and measure corrections, escalations, review burden, and downstream quality before increasing autonomy.
Your next step is to write the operational contract for one read-only workflow your team already performs. Decide whether it belongs on a schedule or behind a supported trigger, define the evidence and output fields, and identify the person who will reject weak runs. Then configure the Agent and let several reviewed runs tell you which permission, if any, it has earned next.
References

Leave a Reply