Tag: AI Transparency

  • Human Accountability in AI-Assisted Marketing Decisions

    Human Accountability in AI-Assisted Marketing Decisions

    An AI assistant has given your team a confident plan: publish more pages, change the message, and redirect resources toward the tactics it predicts will work. The output is polished enough to put into a deck. The hard question is whether anyone can explain why it fits your customers, constraints, and sales process – and who will answer for the result.

    Human accountability does not mean doing every marketing task manually. It means a qualified person owns the decision, verifies the supporting evidence, controls what gets released, and follows the outcome. That operating discipline lets you use AI for speed without quietly allowing it to become the decision-maker.

    Draw the line between AI assistance and decision authority

    AI can propose options, organize information, expose questions, transform approved material, and accelerate production. A person should retain authority over positioning, priorities, investment, customer promises, and the criteria used to judge success. Those decisions depend on context a generic model response may not contain. A recommendation can sound sensible while omitting something as basic as how customers buy.

    Use consequences, not content format, to decide how much oversight is required. A short tagline can be consequential if it changes the promise your brand makes. A long set of ad variations can be relatively contained if every option stays within an approved offer, audience, and call to action.

    • Execution support: AI formats approved information, groups data, creates variants, or produces a first-pass outline. The task owner checks accuracy and adherence to the brief.
    • Recommendation support: AI diagnoses a problem, ranks opportunities, or proposes a campaign change. A subject-matter owner inspects the evidence, assumptions, business fit, and test design before acting.
    • Consequential decisions: The work changes positioning, budget, material claims, customer experience, or a large part of the website. An experienced marketer explicitly approves, modifies, or rejects the recommendation.

    Accountability includes more than final approval. The human owner must define the problem, set the constraints, decide what evidence counts, and remain responsible after launch. If the only explanation for a choice is that AI recommended it, no accountable marketing decision has actually been made.

    Assign AI work only to people who can evaluate it

    Before assigning a task to AI, ask whether the designated reviewer could evaluate the result without the tool. They do not need to produce it at the same speed. They do need enough knowledge to detect a missing assumption, an unsupported claim, an unsuitable tactic, or a recommendation that conflicts with how the business operates. Access to a tool is not a substitute for understanding the work it performs.

    Consider a recommendation to increase website traffic. A competent reviewer will ask who currently visits, which visitors are relevant, what they do after arriving, and whether the offer is clear. More traffic will not repair a weak explanation, attract the right buyer automatically, or make an unclear next step easier to find.

    The same test applies when AI proposes a large SEO or GEO content program. The reviewer must be able to distinguish a genuine information gap from a request to produce more pages. If nobody can explain which audience needs each page, what decision it helps them make, and why existing content cannot do the job, the team is not ready to approve the plan.

    Give every AI assignment a review brief before prompting. At minimum, record:

    • The business problem the work is meant to solve.
    • The intended audience and the relevant stage of its buying journey.
    • The approved facts, offer, positioning, and operational constraints.
    • The outcome that would count as an improvement.
    • The claims, promises, or changes that are outside the assignment.
    • The person qualified to review and release the work.

    If you cannot name a qualified reviewer, narrow the assignment, obtain the missing expertise, or keep the work out of production. A more elaborate prompt does not repair a missing accountability structure.

    Put every AI recommendation through a human review gate
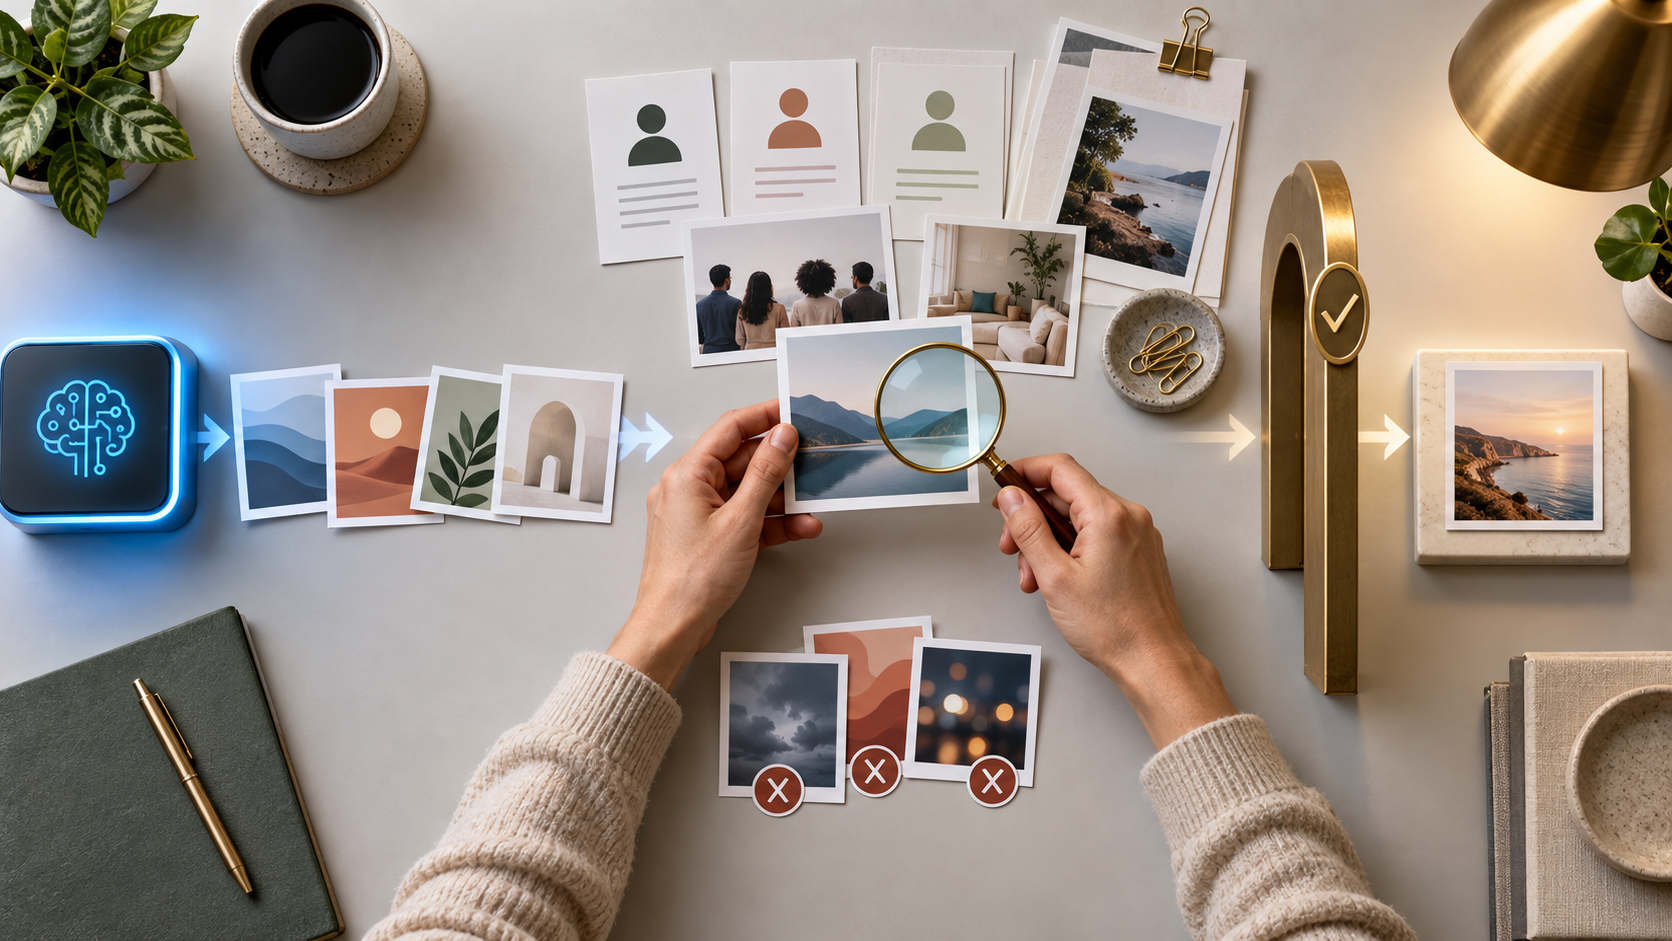
    Hands verify AI-assisted campaign materials against research before one item passes through a physical review gate.

    A consistent gate prevents fluent output from slipping directly into campaigns, content, or site changes. Use the following sequence for recommendations that affect performance, spend, public claims, or customer-facing experiences.

    1. Name the owner before reviewing the answer. Identify the person who can approve, modify, or reject the recommendation. The AI system is a contributor, not the owner.
    2. Restate the business problem. Write it without mentioning AI or the proposed tactic. There is an important difference between users not understanding a service and a perceived need to publish more content. The first is a problem; the second is only one possible response.
    3. Expose the missing context. Check the target customer, sales cycle, available budget, team capacity, current performance, brand position, and delivery constraints. A valid tactic can still be wrong for the organization expected to carry it out.
    4. Inspect the evidence. Ask AI to identify the basis for its recommendation and disclose important assumptions. Open the cited material and determine whether it supports the specific advice. A citation must be read and checked for relevance; the presence of a link is not proof.
    5. Check operational truth. Reject copy that promises something the business cannot deliver. Confirm product facts, audience fit, availability, approval requirements, and any regulated or contractual language with the appropriate human owner.
    6. Convert the recommendation into a bounded test. State the expected effect, the measurement, the review point, and the smallest reversible scope that can produce useful evidence. Do not make a site-wide change when a limited set of pages can test the same premise.
    7. Record the decision and follow-up. Note whether the recommendation was approved, modified, or rejected; why that choice was made; what changed; and who will review the result. This keeps later analysis from turning into guesswork.

    Timing must reflect the actual buying process. If a service typically takes six months to purchase, judging a campaign after several weeks only by closed sales would ignore how that business wins customers. Early evaluation should examine the relevant conversations and buying activity while preserving a defined point at which the investment will be reconsidered. Patience is not permission to spend indefinitely.

    A compact decision record

    The record can live beside the campaign brief, content ticket, or website change log. A short, specific entry in each field is more useful than a long narrative nobody will revisit.

    FieldWhat to record
    OwnerThe person accountable for approval and follow-up.
    Business problemThe customer or performance problem, stated independently of the proposed tactic.
    AI contributionWhat the system generated, analyzed, summarized, or recommended.
    Context and assumptionsThe audience, sales process, resources, constraints, and uncertain premises that affect the decision.
    Evidence checkedThe material a human opened and reviewed, plus any gaps that remain.
    DecisionApproved, modified, or rejected, with a concise reason.
    Test and measureThe change being tested, expected effect, metric, and bounded scope.
    Review pointWhen the result will be assessed and who will assess it.

    Match the control to the marketing assignment
    Three marketing assignments receive progressively stronger human oversight as their potential risk increases.

    Not every task needs the same process. The useful question is what the model can contribute safely and what judgment must remain with a person who understands the subject and the consequences.

    AssignmentUseful AI roleRequired human release check
    Ad and tagline variationsGenerate alternatives within an approved offer, audience, and action.Reject inaccurate claims, off-brand language, and promises the business cannot deliver.
    Expert or thought-leadership contentDevelop questions, organize an outline, expose gaps, or improve readability.A subject-matter reviewer owns the reasoning, factual accuracy, citations, usefulness, and voice.
    SEO or GEO content planningGroup themes, propose hypotheses, and identify possible information gaps.Confirm a real audience need, a distinct purpose for each page, and a connection to the business problem.
    JSON-LD and schema generationDraft markup from approved page information and a defined entity model.Confirm that every entity, relationship, and claim matches the visible content and the real business, then validate the markup before deployment.
    Positioning, priorities, and budgetOrganize evidence, surface assumptions, and compare scenarios.An experienced marketer makes and signs off on the decision after considering customer knowledge, resources, sales process, and consequences.

    Generation and approval should be separate acts even when the same person performs them. First ask the model for possibilities. Then review those possibilities against the brief and evidence. You do not owe an AI-generated option a place in the final work merely because it is fluent.

    Substantive content needs more than a readability pass. An editor can improve a sentence without knowing whether its conclusion is true, distinctive, or useful. Someone familiar with the subject must evaluate the substance and stand behind what is published.

    Search recommendations deserve the same discipline because a weak premise can create work across an entire site. When AI proposes more pages, require an intended reader, a missing question, a reason the existing site cannot answer it, and a useful next step. Investigate whether relevant visitors already lack a clear service explanation or path to contact before committing the team to a larger publishing schedule.

    For structured data, technical validity is only one part of approval. Perfectly formatted markup can still describe the wrong entity or repeat an unsupported claim. The accountable reviewer must check semantic truth as well as syntax. That is the difference between automating production and automating judgment.

    Key takeaways

    • Let AI generate, organize, and challenge ideas, but give a named person authority over consequential marketing decisions.
    • Do not assign AI work unless someone with relevant knowledge can evaluate its substance, not merely its tone or formatting.
    • Treat model confidence as presentation, not evidence. Check cited material, assumptions, and business fit yourself.
    • Test consequential recommendations within the smallest useful, reversible scope before applying them across campaigns or websites.
    • Keep a decision record that states the problem, owner, evidence, choice, change, measurement, and review point.
    • Judge performance against the real sales cycle and customer journey, not the speed with which AI produced its recommendation.

    For your next AI-assisted task, start before the prompt. Name the owner, write the business problem, define the release check, and decide how the result will be tested. Then let AI work inside those boundaries. If your team cannot fill in those fields, pause the assignment: the missing input is not another prompt but accountable human judgment.

    References


  • How to Build Brand Trust for Better AI Search Visibility

    How to Build Brand Trust for Better AI Search Visibility

    Your brand can be technically discoverable and still fail the answer that matters: which option should the buyer trust? An AI search system may find your pages, mention your company, and even cite you without being willing to recommend you.

    That changes the work in front of you. Publishing more content will not repair invented expertise, inconsistent company facts, a chatbot that makes promises your support team cannot keep, or public conversations dominated by unresolved complaints. Better AI search visibility starts by making the evidence around your brand accurate, consistent, and useful enough to support a recommendation.

    Separate being found from being trusted

    Visibility is not a single outcome. A brand can be retrieved as relevant, cited as a factual source, included as an option, recommended as the preferred option, or mentioned with a warning. Treating all five outcomes as a ranking position hides the reason you are winning or losing.

    When you diagnose an AI answer, examine three layers of evidence:

    • Identity evidence: Is it clear who the company is, who created the content, and who is responsible for the claims?
    • Claim evidence: Are product capabilities, policies, qualifications, and comparisons specific enough to verify?
    • Experience evidence: Do customer-facing systems and independent discussions support or contradict what the company says about itself?

    Your website controls much of the first two layers. The third often develops elsewhere. A customer can encounter a bad answer in your chatbot, describe it in a community, and create a public record that later competes with your product page. That does not mean every complaint changes an AI answer. It means you cannot evaluate visibility by auditing owned pages alone.

    LastPass illustrates the persistence problem. Reddit discussions about past security incidents continued to rank for the brand name and were pulled into ChatGPT answers. The practical lesson is not to suppress criticism. It is to watch for recurring trust failures, resolve the underlying issue, and make accurate corrective information easy to find.

    Make every owned claim verifiable

    Two researchers inspect luminous connections between a geometric block, an unmarked document, a product sample, a medallion, and a clock.

    Trust begins with an unglamorous question: is the page honest about who made it? Google now explicitly treats AI-generated headshots, invented names, and false credentials used to simulate human expertise as deceptive authorship information. Its guidance says deception makes a page untrustworthy to users and automated quality systems and signals low quality.

    You do not need a celebrity expert on every byline. You need an accurate chain of responsibility. Audit your content templates with these checks:

    • Use a person’s name only when that real person created, substantially shaped, or took editorial responsibility for the work.
    • Keep biographies factual. List roles, experience, and credentials you can substantiate rather than qualifications chosen to make a page look authoritative.
    • Do not label someone a reviewer unless a meaningful review occurred. Record what the review covered internally so the label has an operational meaning.
    • If the organization is genuinely responsible for the content, say so. A truthful organizational byline is stronger than a fictional personal profile.
    • Explain how information was produced or checked when that process helps the reader judge reliability. Do not use a vague process statement to disguise absent human oversight.
    • Make publication and update dates reflect real editorial events. A new date on unchanged material is not evidence of freshness.

    Use schema as a consistency check, not a credibility generator

    Structured data can clarify the identity and relationships already visible on a page. It cannot turn a fabricated expert into a trustworthy author. Your Article, Person, and Organization markup should agree with the byline, biography, About page, editorial policy, and company details a visitor can see.

    For each important template, compare the visible page with its JSON-LD field by field. Check the author type, name, URL, publisher, publication date, modification date, and any identity links. Remove a field when you cannot support it. Do not add credentials or sameAs references merely because a schema tool offers an empty box for them.

    This catches a common trust leak: every individual statement looks plausible, but the collection does not describe one coherent entity. A shortened brand name in one place, an obsolete company description in another, and an unrelated author profile in the markup can leave both people and automated systems with avoidable ambiguity.

    Treat your chatbot as a reputation surface

    A customer faces a translucent digital kiosk as light paths connect it to a service team, with one clear path and one warning-marked path.

    A commerce or support chatbot is not only a conversion tool. It is also where customers test whether your brand’s promises survive contact with a real question. A poor bot experience can therefore affect AI search visibility as well as the immediate sale.

    The mechanism is straightforward. The bot gives an inaccurate or evasive answer. The customer cannot reach a person or verify the claim on your site. They take the question to a forum, review platform, or social conversation. The resulting public explanation may be clearer and more durable than anything you published yourself.

    Audit the bot around complete customer tasks, not isolated response quality:

    1. Select real tasks. Use recurring questions from bot logs, sales conversations, support tickets, and on-site search. Include questions that affect eligibility, pricing, returns, compatibility, security, delivery, and cancellation when those apply to your business.
    2. Run each task to its endpoint. Record the first answer, follow-up questions, linked page, escalation option, and final resolution. A friendly opening does not compensate for a dead end later in the exchange.
    3. Compare the answer with the source of truth. Check the bot against current product pages, policy pages, documentation, and the answer a trained employee would give. Flag unsupported promises and contradictions before rewriting the tone.
    4. Test the recovery path. Deliberately ask an ambiguous question, challenge an answer, and request a human. The bot should acknowledge uncertainty and provide a usable next step instead of inventing certainty.
    5. Turn recurring failures into content work. If customers repeatedly need an external discussion to understand a policy, improve the policy page and the bot’s retrieval source. Do not treat the symptom as a prompt-writing problem alone.

    Keep a simple failure log with the customer task, incorrect answer, correct answer, responsible owner, affected page, and resolution status. This connects conversion operations with reputation and AI visibility. It also prevents separate teams from fixing the bot, help center, and structured data in incompatible ways.

    Earn third-party evidence without manufacturing it

    Communities can give buyers and AI search systems context that an About page cannot. They can also expose promotional behavior quickly. The useful goal is not to plant brand mentions. It is to contribute answers that remain valuable even if the reader never clicks your profile.

    Start only after your own site is worth citing. One documented B2B SaaS workflow begins with a set of 200 to 500 SEO keywords and maps them to roughly 150 relevant subreddits. Those figures describe that operating model, not a quota every company should copy. The transferable method is to connect existing buyer questions with communities where those questions already receive substantive answers.

    Use the following participation rules to protect trust:

    • Work with real accounts. An employee can participate as a knowledgeable person, but the account should not exist solely to promote the employer. Build a genuinely useful history and disclose the relationship whenever it is relevant to the recommendation.
    • Stay with live conversations. The same practitioner team limits engagement to threads less than 20 days old because returning to old conversations can look unnatural and increase moderation risk. Treat that as a conservative operating rule from one program, not a universal Reddit ranking factor.
    • Answer the question completely. Give the useful explanation before mentioning a product. If the comment only works when the reader follows your link, it is probably promotion rather than an answer.
    • Match the community’s language. Use direct descriptions, real constraints, and relevant experience. Corporate copy and polished slogans make a comment less credible, not more.
    • Earn the right to start a thread. Original posts work better after the account has participated constructively. An AMA or a detailed solution to a recurring pain point has a clearer community purpose than a disguised announcement.
    • Do not coordinate fake praise. Sockpuppets, invented customers, and concealed affiliations create the same underlying problem as fake author profiles: apparent evidence with no truthful person behind it.

    For an active reputation program, search your brand name on Reddit every day and log the threads that introduce a new factual claim, recurring complaint, or comparison. Respond only when you can add a correction, resolution, or genuinely useful context. A defensive reply can amplify the very evidence you want to displace.

    Community work is a secondary layer. If your product facts, policies, authorship, and customer experience remain weak, more participation simply gives the weaknesses more places to surface.

    Run a trust-first AI visibility audit

    Build a fixed prompt set around the decisions your buyers actually make. Include category discovery, use-case fit, comparisons and alternatives, risk or support concerns, and direct questions about your brand. Reuse the same prompts so you can distinguish a meaningful change from a different question.

    For each run, record the platform or model, date, exact prompt, whether the brand appeared, how it was characterized, whether it was recommended, any warning language, and the cited URLs. The citation list is often more diagnostic than the mention itself because it shows which evidence shaped the answer.

    Observed patternLikely evidence gapFirst action
    Your brand is absent from an unbranded category answerThe available material may not answer that category or use case precisely enoughPublish a focused, factual answer on your own site and make its ownership clear
    Your brand is mentioned but not recommendedRelevance exists, but trust, fit, or comparative evidence is weakInspect cited alternatives, verify your claims, and identify missing proof or unresolved objections
    Your brand appears with a warningNegative experience evidence is outweighing owned claimsTrace the warning to its cited or likely origin, fix the underlying issue, and publish an accurate resolution
    The answer contains outdated or conflicting factsYour entity details, policies, or product information are inconsistentAlign visible pages, feeds, profiles, and JSON-LD around one current source of truth
    The answer cites you but describes you inaccuratelyYour page may be extractable without being sufficiently explicitRewrite ambiguous passages so the qualification, scope, and responsible entity appear together

    Prioritize by trust risk, not implementation convenience. Remove deception and factual errors first. Repair broken customer journeys next. Resolve contradictions across owned properties after that. Then strengthen missing evidence and improve schema. A markup change is quick, but it is the wrong first move when the underlying claim is false or the customer experience disproves it.

    Assign each issue to an owner who can change the root cause. Content teams can clarify a page, but they cannot repair a returns process. SEO teams can expose inconsistent entities, but they cannot validate a security claim. The audit becomes useful when it routes each trust gap to the team with authority to close it.

    Key takeaways

    • AI search visibility includes retrieval, citation, recommendation, and warning outcomes; a mention alone does not prove trust.
    • Real authorship, supportable credentials, and JSON-LD that matches the visible page give your owned claims a coherent identity.
    • Chatbot failures can become public reputation evidence, so audit complete customer tasks and escalation paths rather than tone alone.
    • Community visibility should be earned through real accounts and complete answers after your own site is worth citing.
    • Measure the language and citations around your brand, then fix deception, broken experiences, and contradictions before optimizing presentation.

    Start with a small, fixed set of buyer prompts and follow each answer back to the evidence supporting it. Fix the highest-risk contradiction you find, rerun the same prompts, and keep the record. That turns AI visibility from a mention count into a practical trust-improvement loop.

    References


  • Political Campaign AI Spending: Where the 2026 Money Goes

    Political Campaign AI Spending: Where the 2026 Money Goes

    If you are building, buying, or measuring AI for a 2026 political campaign, the biggest budgeting mistake is treating AI as a single technology line. The headline total combines tools, AI-assisted work, automated outreach, and the media used to distribute AI-influenced advertising. A campaign can therefore spend little on software while creating a large AI-related footprint.

    You need to separate cost, operational use, and public exposure before deciding whether your campaign is underinvesting, overspending, or simply counting differently. That distinction turns an eye-catching market estimate into a budget you can actually manage.

    The $899 million headline is not a software market size

    Political campaigns, party committees, and outside groups are projected to spend $899 million on AI during the 2026 cycle. That would be 2.8 times the 2024 total and about 22 times the 2022 total. It is also equivalent to roughly 8.5% of the projected $10.6 billion in overall political advertising for the cycle.

    But $899 million does not mean campaigns are buying $899 million of AI software. The estimate includes three materially different forms of spending:

    • Direct payments for AI vendors, platforms, and general-purpose subscriptions.
    • The portion of production, targeting, fundraising, and outreach costs attributed to AI.
    • Media dollars placed behind advertisements generated or enhanced with AI.

    Those categories answer different questions. Direct vendor spending helps you assess the technology market. AI-attributable workflow spending tells you how deeply campaigns are using the technology. Media placement measures how much paid distribution sits behind AI-influenced assets. Combining them is useful for estimating AI’s overall campaign footprint, but it cannot tell you what AI products earned or how much a campaign saved.

    The total is also a projection, not a final audited tally. Its methodology covers more than 41,000 federal and state disbursement records, platform advertising libraries, and 57 consultant and vendor interviews, with activity tracked through September 24 and modeled through Election Day on November 3. Treat it as a structured market estimate. Do not use it as proof that every campaign classifies AI spending the same way.

    Before comparing your own budget with the market, decide which question you are asking. If you want to know what your technology stack costs, exclude media. If you want to understand operational adoption, include the AI-assisted share of labor and services. If you are assessing voter exposure, include distribution but keep it separate from production. One blended figure cannot answer all three questions.

    Distribution and outreach absorb more money than AI tools

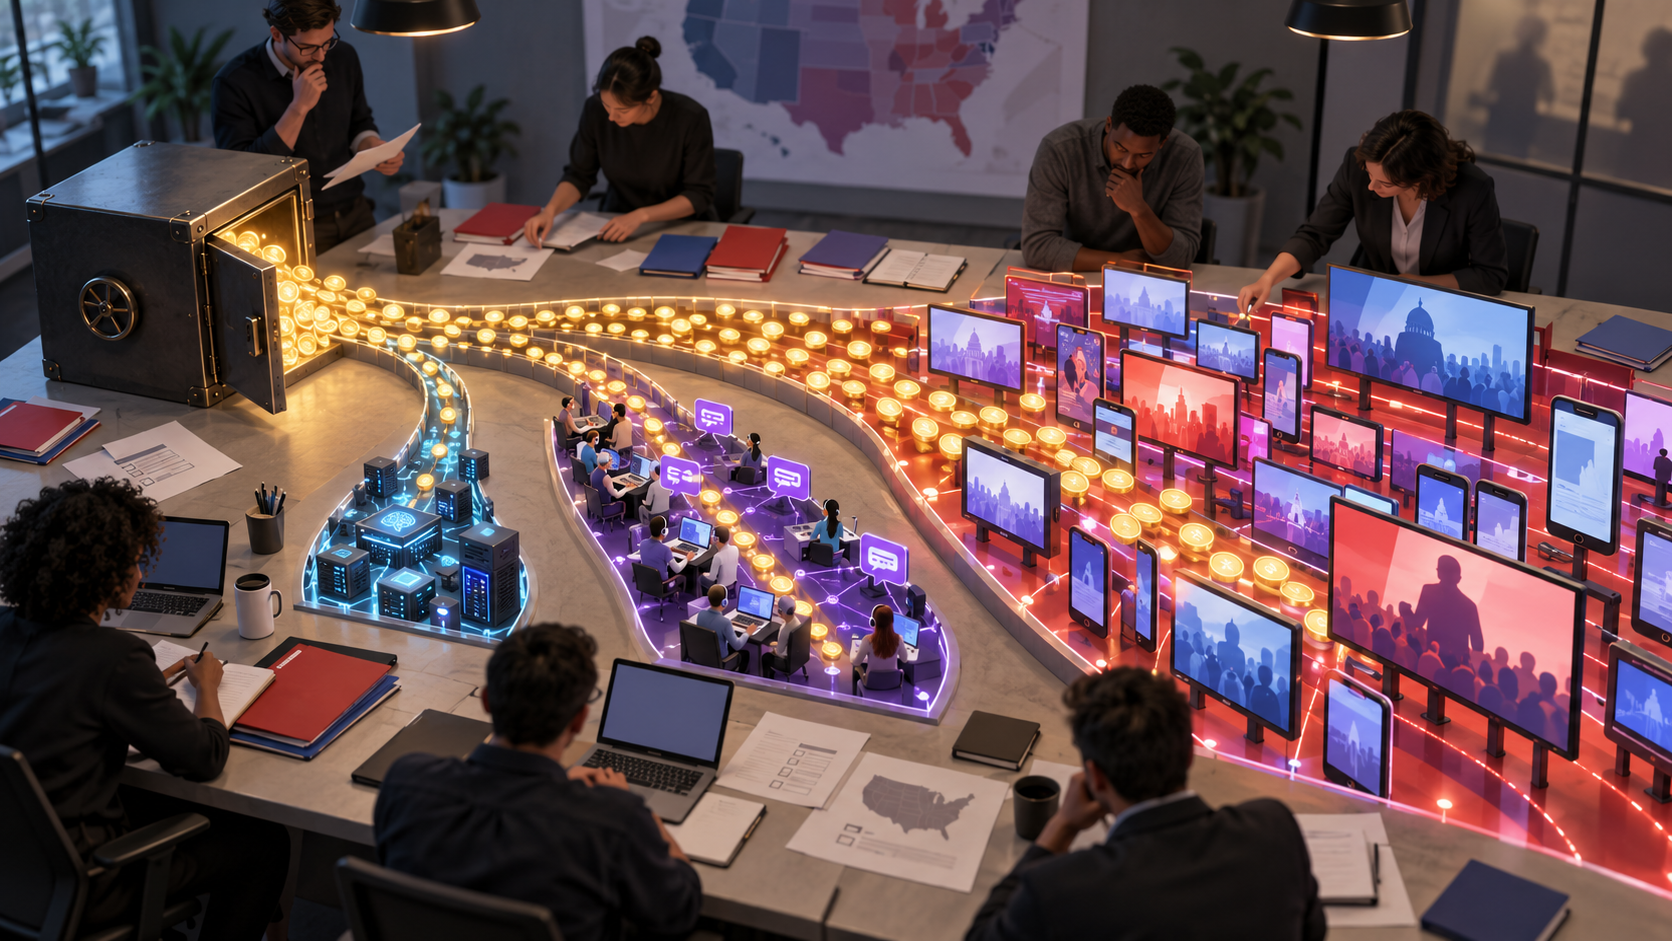
    A small AI workstation connects through branching light trails to many phones, screens, mail pieces, and canvassing devices.

    The projected category mix shows where AI is entering campaign operations. Media placement behind AI-generated or AI-enhanced advertising is the largest category. General-purpose subscriptions are the smallest. That gap matters: the visible scale of political AI is being driven more by amplification and workflow adoption than by the price of access to a model.

    Spending categoryProjected 2026 spendingShare of totalGrowth versus 2024Question your budget should answer
    Media placement behind AI-generated or AI-enhanced ads$237 million26.4%3.3xCan you connect each placement to a specific asset, audience, and outcome?
    AI voter outreach$173 million19.2%3.0xWhen does an automated interaction move to a trained person?
    AI fundraising optimization$147 million16.4%2.4xAre you measuring net fundraising performance rather than message volume?
    AI audience modeling and targeting$131 million14.6%1.8xDoes the model improve decisions against a defined non-AI baseline?
    AI creative production$98 million10.9%4.7xWho verifies facts, voices, likenesses, and required disclosures before release?
    AI-assisted media buying fees$65 million7.2%2.8xCan you separate the service or algorithmic fee from the underlying media spend?
    General-purpose AI tools and subscriptions$48 million5.3%4.0xWho controls accounts, data access, retention, and offboarding?

    Creative production is growing fastest at 4.7 times its 2024 level, but it still accounts for only 10.9% of projected 2026 AI spending. Audience modeling is growing slowest at 1.8 times because it already had a meaningful base before the recent expansion of generative tools. Fast growth, large spending, and operational maturity are therefore three different signals.

    Do not judge an AI program by the number of assets it produces. A campaign can generate hundreds of variants without improving persuasion, fundraising, or contact quality. Measure the result associated with each workflow: approved production time for creative, net revenue for fundraising, successful contacts and escalations for outreach, incremental performance for targeting, and cost per desired action for media. Keep output volume as a diagnostic metric, not the primary success metric.

    Adoption also cuts across party lines. Republican candidates, parties, and aligned outside groups account for a projected $415 million, compared with $374 million on the Democratic side. Outside groups allocate a larger portion of their budgets to AI than candidates and parties, with Republican-aligned groups reaching 10.2%. Party affiliation is a poor proxy for AI maturity; spender type and workflow are more useful.

    Race size, geography, and timing change the right strategy

    Absolute spending concentrates in federal contests. House races account for a projected $305 million and Senate races for $286 million, together representing 65.7% of campaign AI spending. Yet smaller races use AI more intensively relative to their available media.

    Local and judicial races have AI-generated or AI-enhanced elements in 16.2% of ads, and AI represents 13.8% of their media budgets. State legislative races follow at 14.7% of ads and 12.4% of media budgets. House races are lower on both measures, at 9.2% and 8.9%, despite carrying the largest dollar total. Ballot measures sit at the other end, with AI elements in 6.3% of ads and 5.2% of media budgets.

    This is a denominator problem that can distort competitive analysis. A small campaign may look more AI-intensive because automation replaces work it could not otherwise afford. A large federal campaign can spend far more dollars while AI remains a smaller percentage of a much larger operation. Compare campaigns on both absolute spending and share of budget. Using only one will misclassify the smaller operation or obscure the larger one’s reach.

    Geography produces another concentration effect. The ten highest-spending states account for $460.1 million, or 51.2% of the projected total. Maine reaches $25.09 per registered voter, almost three times the next-highest figure in that group, as a competitive Senate race concentrates spending across a relatively small electorate. A national average will not tell you what competitive pressure looks like in an individual state.

    Disclosure practices vary just as sharply. Among the ten highest-spending states, the recorded share of AI ads carrying a disclosure ranges from 29% in Georgia to 78% in California. Across states with AI disclosure laws, 64% of AI ads carried a disclosure, versus 27% in states without one. That relationship indicates that legal requirements affect behavior, but it is not a substitute for a state-by-state compliance review.

    Build a jurisdiction field into the asset record before production begins. Record where the asset will run, what was generated or materially altered, which disclosure decision was made, who approved it, and which final version entered distribution. When the applicable rule is unclear, hold the asset and ask qualified election counsel. Retrofitting a disclosure after placement creates avoidable legal, financial, and reputational exposure.

    Timing is equally important. At the aligned one-month point, cumulative 2026 AI spending reaches $612 million, with a projected $899 million by Election Day. Spending within each cycle has roughly doubled every three months as Election Day approaches. The final month is projected to contain 32% of 2026 spending, below the 37% final-month share in 2024 because outreach and fundraising automation moved earlier to reach early voters.

    Do not postpone governance until the spending ramp. The final weeks are when review time contracts, asset volume rises, and media decisions become harder to reverse. Approve vendors, data permissions, escalation paths, disclosure rules, and evidence requirements before the high-volume period. The late-cycle budget should scale a controlled workflow, not finance the first real test of one.

    Build an AI budget that can survive scrutiny

    Transparent budget containers, coins, a magnifying glass, a locked data box, and a balance scale are arranged on an orderly campaign planning desk.

    A defensible AI budget starts with a ledger, not a list of tools. The cost of an AI program can include software, implementation, data work, human review, compliance, vendor services, and media. If you record only subscription invoices, you will understate the program. If you label every placement behind an AI-assisted asset as technology spend, you will lose sight of what the technology itself costs.

    1. Choose the unit of analysis. State whether you are tracking direct vendor cost, AI-enabled workflow cost, or media exposure. Maintain all three if leadership needs a complete view, but never merge them without labels.
    2. Classify spending at the invoice or line-item level. Assign every item to creative production, outreach, fundraising, targeting, media-buying services, general tools, or media placement. Prevent one invoice from disappearing into a broad digital-services account.
    3. Attach each cost to an accountable workflow. Record the race, jurisdiction, vendor, campaign owner, data used, synthetic or altered elements, human reviewer, approval status, and distribution channel.
    4. Set the baseline before the pilot. Compare the AI-enabled workflow with the existing process on the outcome that matters. Time saved is meaningful for production; it is not evidence of better persuasion. Message volume is meaningful for operations; it is not evidence of better fundraising.
    5. Create a release gate. Require factual verification, permission checks for voice and likeness, disclosure review, accessibility review where relevant, security review, and named human approval before an asset or automated interaction goes live.
    6. Scale only the validated component. If a creative workflow saves time but targeting does not improve performance, scale production rather than buying a larger bundled program. A vendor relationship does not have to expand as one indivisible unit.

    Your ledger should let a reviewer move in both directions: from an invoice to the assets and outcomes it funded, and from a public asset back to its production record, approval, disclosure decision, and media spend. That traceability is more useful than a generic AI policy because it shows how the policy operated in a specific case.

    If you publish or optimize political content

    More campaign investment means more creative variants, automated contacts, and paid distribution. It does not create independent corroboration. Treat campaign-generated material as a claim that requires verification, even when the asset looks polished or appears repeatedly across channels.

    • Put the publication or revision date, jurisdiction, race, candidate or issue, and sponsor context where a reader can see them.
    • Separate campaign assertions from independently verified facts, and link to the strongest available primary evidence for factual claims.
    • Keep the original approved asset and a correction history so changes do not erase provenance.
    • Use structured data only for information visible on the page. Markup can clarify entities and dates, but it cannot turn an unsupported claim into reliable evidence.
    • Do not present repeated synthetic content as multiple independent confirmations. Distribution volume and source diversity are not the same thing.

    These practices help human readers, search systems, and AI answer engines distinguish what happened, who is making a claim, when it applies, and which evidence supports it. They do not guarantee visibility or favorable treatment, but they reduce ambiguity at the point where political information is most likely to be compressed into a short answer.

    Key takeaways

    • The projected $899 million total measures a broad AI-related campaign footprint, not just software purchases or vendor revenue.
    • Media placement is the largest category at $237 million, while general-purpose tools and subscriptions account for $48 million.
    • Creative production is growing fastest, but output volume alone does not establish campaign impact.
    • Federal races lead in total dollars, while local, judicial, and state legislative races use AI more intensively relative to their media.
    • Disclosure practices differ substantially by state, so every asset needs a jurisdiction-specific review and an auditable approval record.
    • Budgeting should separate direct technology cost, AI-enabled workflow cost, and paid exposure, then connect each to a defined outcome.

    Start by exporting every AI-related expense and reclassifying it into technology, workflow, or distribution. Then choose one high-exposure workflow, give it a measurable baseline and a named approval owner, and resolve its disclosure path before shifting more money into it. That is how you turn a market trend into a campaign decision you can explain, test, and defend.

    References


  • Web Data Access Mandates: A Playbook for Site Owners

    Web Data Access Mandates: A Playbook for Site Owners

    You want search engines and AI systems to discover your work, but you also need to know who is copying it, why they want it, and whether your access rules mean anything. At the other end of the market, opening a dominant platform’s data may improve competition while moving sensitive search histories beyond the systems that originally protected them.

    The useful question is not whether web data should be open or closed. It is whether each access decision has a verified actor, a defined purpose, a proportionate data scope, an enforceable control, and an accountable owner. That is the operating model site owners, SEO teams, AI platforms, and data recipients need as transparency mandates develop.

    Key takeaways

    • Crawler transparency and platform data sharing are different obligations. The first identifies who is requesting access; the second governs data that is transferred to another party.
    • A User-Agent is a claim, not proof of identity. Give special access only after the crawler has been verified through evidence controlled by its operator.
    • Use robots.txt to communicate preferences to cooperative crawlers, but enforce important restrictions through edge controls, authentication, scoped credentials, or restricted endpoints.
    • Separate discoverability from permission. Allowing a crawler does not guarantee citations or AI visibility, while blocking one can reduce its ability to retrieve current content.
    • Anonymization is not a label applied to an export. Sensitive search data needs minimization, re-identification testing, access controls, retention limits, audit logs, and incident procedures.

    Two transparency mandates solve different problems

    One policy track concerns traffic arriving at your site. The proposed federal Stealth Bot Prohibition Act would require automated crawlers to identify themselves and disclose their purpose. It targets tactics such as posing as a human visitor, routing requests through residential proxies, or using scraping services to get around website controls. A similar New York measure applies to news publishers, while the federal proposal would extend more broadly across websites and digital platforms.

    The other policy track concerns data leaving a large platform. The European Commission has required Google to share with competitors in the European Union the same search data it uses to improve its own search services, subject to anonymization. The reported deadline for search-data sharing is January 2027. Google has appealed the decision, arguing that the required anonymization is insufficient and that moving query data outside its infrastructure creates additional security exposure.

    Those positions are not opposites. A crawler can disclose its identity without receiving unrestricted access. A platform can be required to provide access without publishing raw data to the world. Transparency identifies the actor and the rules; it does not eliminate access controls.

    Operational questionCrawler transparencyPlatform data sharing
    Who must act?The automated requesterThe platform holding the required dataset
    What must become clear?Identity, purpose, and compliance with the site’s policyDataset scope, recipient, purpose, safeguards, and permitted use
    Does data have to leave the holder?Not necessarily; disclosure can precede an allow-or-block decisionYes, to the extent required by the applicable mandate
    Main control failureA false identity defeats crawler-specific rulesWeak minimization, anonymization, or recipient security exposes sensitive data
    First question to answerCan you prove which operator sent this request?Can you prove why each transferred field is necessary and protected?

    Keep these workstreams separate in your compliance register. The owner of bot verification may sit in infrastructure or security, while the owner of a mandated data transfer may span legal, privacy, security, and product teams. Combining them into a generic transparency project makes it easy to miss the control that actually matters.

    The legal stakes also differ from an ordinary integration project. Under the Digital Markets Act’s general penalty regime, non-compliance can expose a company to fines of up to 10% of annual global revenue, up to 20% for repeated infringements, and periodic payments of up to 5% of average daily sales. These are statutory maximums, not a prediction about any particular dispute. If your organization may be in scope, have qualified EU competition and privacy counsel confirm the current deadlines, the effect of any appeal, and the technical form of compliance.

    Make crawler identity verifiable, not merely declared

    A crawler presents a digital key at a network checkpoint while unverified crawler devices remain outside the gate.

    A crawler can place a recognizable name in its User-Agent header. That makes the name useful for classification, but it does not make the claim true. A hidden crawler can imitate browser traffic, borrow another bot’s label, or use residential addresses that do not resemble data-center infrastructure. This is why an identity mandate matters: rules addressed to a named bot are ineffective when the requester can lie about being that bot.

    Build your crawler register around five records:

    1. Declared operator and product. Record the organization claiming responsibility, the crawler name, an official contact path, and the date you checked the information.
    2. Declared purpose. Distinguish functions such as search indexing, live answer retrieval, model training, monitoring, and commercial content reuse. A label such as AI bot is too vague to support a meaningful decision.
    3. Verification method. Prefer evidence controlled by the operator, such as an official verification endpoint, safely validated published network ranges, or authenticated or signed requests when the operator supports them. Do not grant allow-list privileges from a User-Agent alone.
    4. Policy outcome. Map the verified identity and purpose to a specific action for each content class: allow, rate-limit, block, challenge, or route to an authenticated licensing channel.
    5. Observed evidence. Log the time, host and path, request method, response status, claimed User-Agent, relevant network information, verification result, policy matched, action taken, and response volume. Set retention around operational and legal need rather than keeping the data indefinitely.

    Be careful with URL logging. Query strings and path segments can contain account identifiers, search terms, or other personal information. Redact unnecessary values, restrict access to raw logs, and involve your privacy team before expanding retention merely because a bot dispute is possible.

    robots.txt still has a useful role. It gives cooperative crawlers a machine-readable statement of your preferences, and crawler-specific groups can express different choices for identified agents. It is not authentication and cannot stop a requester that ignores the file or hides behind another identity. Put consequential enforcement at the CDN, web application firewall, application, API gateway, or authenticated delivery layer.

    The same distinction applies to SEO infrastructure. A sitemap helps systems discover URLs. Structured data and JSON-LD help them interpret eligible page content after retrieval. Neither verifies the requester or grants unrestricted reuse rights. Keep discovery configuration, crawler authorization, and content licensing as three separate controls.

    If content access is licensed, use credentials or a dedicated delivery route. Define the permitted purpose, content scope, request volume, attribution terms, retention, onward use, reporting, suspension conditions, and termination process. A crawler-identification mandate can make negotiation and enforcement more practical, but it does not by itself create a right to payment, attribution, or a licensing agreement.

    Build an access policy without giving up AI visibility

    Automated traffic is too large to manage as an occasional exception. Cloudflare Radar estimates bots account for 64% of internet traffic. On the publisher sites it monitors, TollBit reported more than 22 billion AI-bot scrapes during the first half of 2026. Its observed ratio of AI-bot visits to human visits moved from roughly one per 200 in the first quarter of 2025 to one per 31 in the fourth quarter. Those vendor-specific figures do not tell you the composition of your traffic. They tell you why your own server and edge logs should, rather than assumptions.

    Use this sequence to turn that telemetry into an enforceable policy:

    1. Inventory content surfaces. Separate public HTML pages, media files, feeds, APIs, downloadable archives, licensed material, account areas, and private content. Anything genuinely private should sit behind access control rather than a crawler instruction.
    2. Write a decision matrix. For each content class, decide what happens when the requester is a verified desired crawler, a verified crawler with an unapproved purpose, a claimed but unverified bot, an authenticated licensee, or unknown automation. Give unverified claims no special allow-list privilege.
    3. Enforce in layers. Publish crawler preferences, apply rate and resource controls at the edge, require credentials for restricted delivery, and keep application-level authorization in place. Roll out aggressive rules carefully so false positives do not lock out people or the search services you depend on.
    4. Measure the consequence. Before changing a rule, record verified crawler requests, pages served, bandwidth or compute cost, response errors, identifiable referrals, and the AI citations or mentions you monitor for priority queries. Compare equivalent periods after the change and alter one major policy variable at a time where practical.
    5. Prepare an incident path. Define who preserves logs, verifies the claimant, changes the edge rule, contacts the operator, assesses privacy exposure, and involves counsel. Record why the final allow, throttle, or block decision was made.

    Do not collapse this into a single allow AI or block AI switch. A public documentation page intended to win citations has a different job from a licensed report, a subscriber archive, or an account dashboard. Apply access decisions at the smallest content class your stack can reliably enforce.

    Be equally precise about visibility. Allowing retrieval creates an opportunity for a system to process current content; it does not guarantee ranking, citation, attribution, model training, or referral traffic. Blocking a specific crawler may reduce visibility in the service that relies on it, but it does not prove that all copies disappear or that other systems will stop finding the page. Decide from observed outcomes and your content rights, not from the crawler’s brand name.

    If you cannot verify a requester, fall back to a documented rule based on content sensitivity, infrastructure cost, request behavior, and your visibility objective. That is more defensible than guessing which company is behind an address and quietly granting it privileged access.

    Treat shared search data as a security product

    An analyst monitors a secure vault as search data is minimized, encrypted, and transferred through a controlled access port.

    The European dispute exposes a hard design problem. Search data can help competing search and AI services improve, which supports the Commission’s competition objective. Query histories can also reveal unusually sensitive interests, and transferring them creates another environment that can be attacked or misconfigured. Google’s security argument is a litigant’s position, not a final finding that the mandate is unsafe. The responsible response is to make the privacy and security claims testable.

    Anonymization must be evaluated against re-identification risk, not treated as the removal of obvious account fields. Rare queries, repeated sequences, timestamps, locations, and combinations of attributes may distinguish a person even when a direct identifier is absent. The appropriate transformation depends on the dataset, the recipient’s other information, the allowed use, and the governing mandate. Privacy and security specialists should test that risk before release and after a material change in fields or granularity.

    If you hold the data

    • Create a field-level inventory that names the business purpose, sensitivity, granularity, update frequency, and recipient for every element proposed for transfer.
    • Start with the least detailed representation that can satisfy the authorized purpose, then have counsel confirm whether the mandate requires additional parity with the data used internally.
    • Document the anonymization threat model, including rare records, sequence linkage, external-data linkage, and the conditions under which a recipient could regain access to more detailed information.
    • Deliver data through a segregated, authenticated environment with least-privilege access, encryption, audit logging, and a defined process for credential revocation. Avoid unmanaged bulk copies.
    • Set enforceable rules for retention, deletion, onward sharing, subcontractors, security incidents, and purpose changes. Verify compliance rather than relying only on contractual promises.
    • Publish a plain-language transparency record describing what is shared, with whom, for what purpose, and under which safeguards, while withholding details that would weaken security.

    If you receive the data

    • Accept only fields tied to a documented product or research need. Receiving extra sensitive data creates risk without guaranteeing a better service.
    • Separate raw access from derived outputs. Keep the smallest possible group able to reach detailed records and use aggregated outputs for broader product work where feasible.
    • Test whether the data produces the intended improvement. Access to a dominant platform’s dataset does not automatically change user habits or produce a competitive product.
    • Maintain lineage from the received field through each transformation and output so you can investigate misuse, honor deletion requirements, and explain how the data influenced a result.
    • Prepare a containment and notification procedure before ingestion. It should identify who can stop processing, revoke access, preserve evidence, assess affected data, and contact the provider.

    Your first deliverable should be one accountable register. Put inbound crawler identities and purposes on one side, outbound or received datasets and purposes on the other, and assign a named operational owner to every decision. Then test two scenarios: an unverified crawler requesting high-value content, and a sensitive export appearing outside its approved environment. Any missing owner, log, revocation path, or policy rule is your next fix.

    That register will remain useful even if a bill changes or an appeal succeeds. It gives you something legislation alone cannot: a repeatable way to prove who accessed data, why access was allowed, what left your systems, and how you limited the resulting risk.

    References


  • Google Ads Controls and Measurement: An Audit Framework

    Google Ads Controls and Measurement: An Audit Framework

    You can hit your cost target and still have a control problem. A campaign average will not show whether a claim is valid in every target country, whether AI matched the right query to the right message, or whether advertising on the destination made the page harder to use.

    To manage Google advertising properly, you need one evidence trail spanning pre-launch permission, automated decisions, and post-click experience. The framework below turns those separate concerns into an audit process you can use before expanding a campaign or increasing its budget.

    Separate controls from observations

    A control determines what should happen. Measurement tells you what did happen. Confusing the two creates familiar mistakes: treating ad approval as proof of legal compliance, treating an AI instruction as a guaranteed constraint, or treating a satisfactory conversion rate as proof that every customer journey was appropriate.

    Build your operating model around four layers. Each layer answers a different question and needs its own evidence.

    LayerQuestion to answerEvidence to retainSuggested owner
    Market permissionWhat may this business claim, promote, and target in this location?Applicable Google policy, law, regulation, local code, review decision, and approval dateCompliance or market approver
    Automation instructionsWhat business, audience, and message context did AI Max receive?Versioned brief, campaign scope, approved claims, and destination mapPaid search owner
    Delivered journeyWhich search term, creative assets, and landing page came together?Observable query-to-creative-to-page combinations and their outcomesChannel analyst
    On-page ad experienceHow much advertising did real users encounter on the site?CrUX ad count, density, CPU weight, and network weightSite experience or monetization owner

    One person can own several layers in a small team. The important part is that no layer disappears into an aggregate dashboard. Cost, conversion volume, and return can tell you whether a campaign is commercially productive. They cannot answer whether a local claim was permitted or explain why a particular search led to a particular page.

    Gate each country before you copy the campaign

    Campaign modules pass through separate country checkpoints where documents, consent, and policy controls are reviewed.

    Geographic expansion is not merely a targeting change. The business may be based in one country while its ads create obligations in every country they reach. Copying a successful campaign into another market can therefore change which claims, disclosures, products, and promotional language require review.

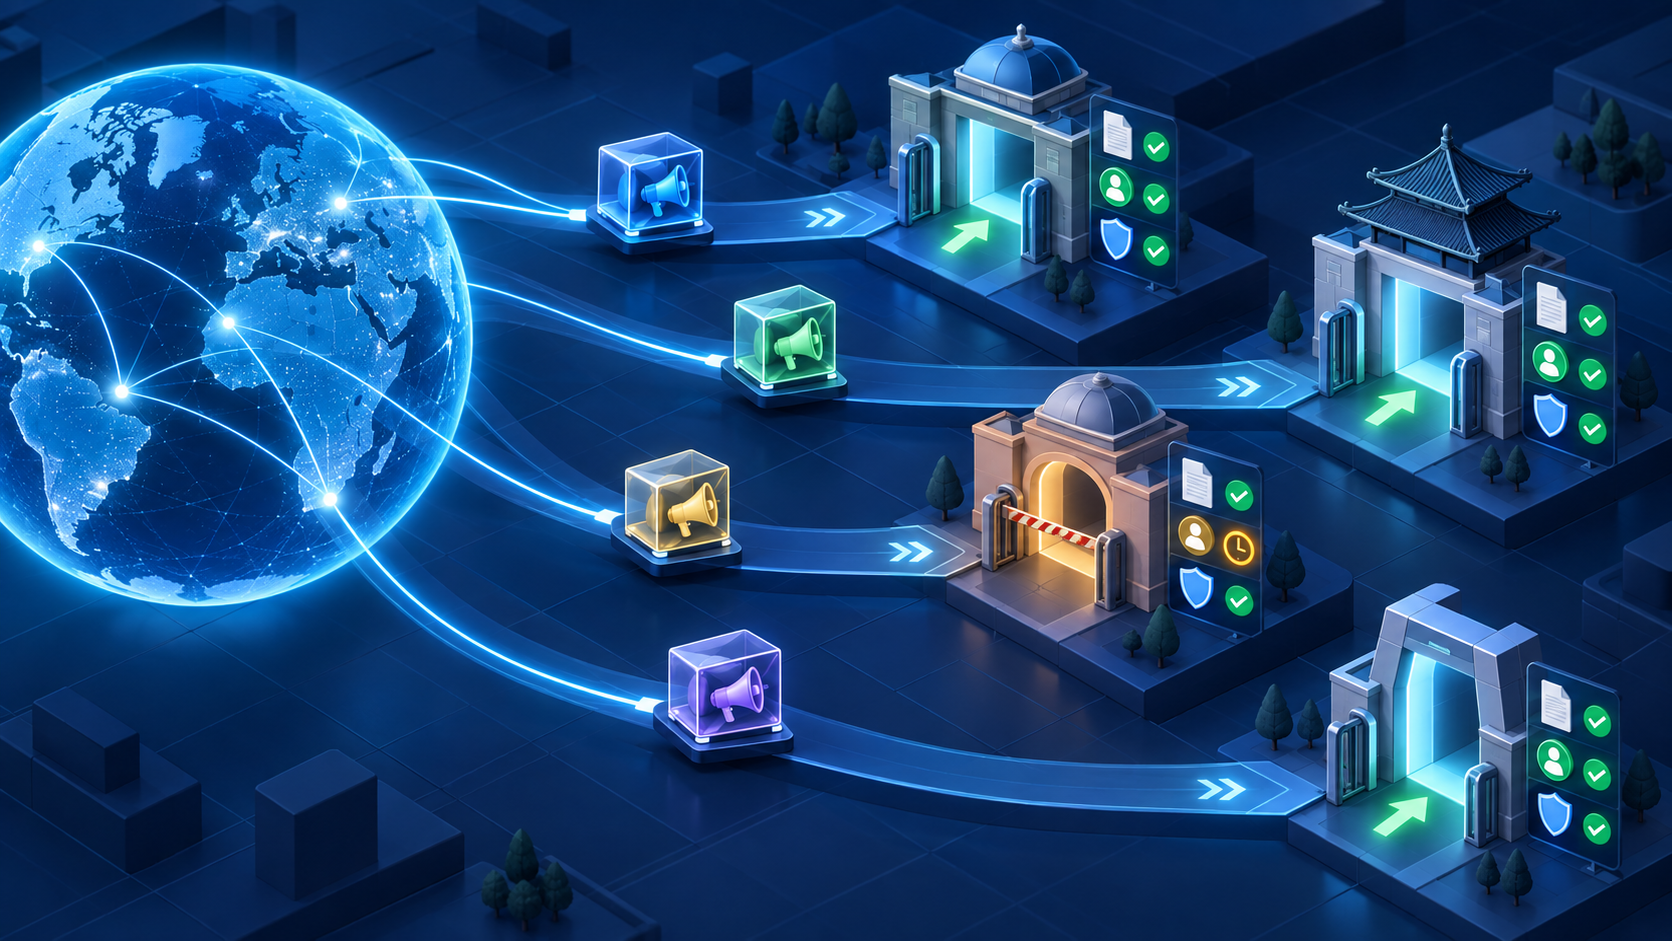
    On September 22, 2026, Google expanded its reference list of advertising and marketing codes for Argentina, Australia, Chile, Colombia, Paraguay, and South Africa. That change matters if you advertise in those markets, but it does not turn Google’s list into a complete statement of local law.

    You remain responsible for the full rule stack: Google Ads policies, applicable laws and regulations, and relevant industry or advertising self-regulatory codes. Google’s local-code references do not replace its existing policies and are not an exhaustive explanation of local requirements.

    Use a launch gate for every country-and-offer combination:

    1. Create a target matrix. Record the country, campaign, offer, audience, domain, landing-page version, and planned launch state. Do not hide several countries inside one approval row.
    2. Inventory the claims. Include headlines, descriptions, asset text, prices, eligibility statements, comparisons, guarantees, testimonials, disclosures, and the claims repeated on the landing page.
    3. Check every applicable layer. Log the Google Ads policy reviewed, the local legal or regulatory question, and any relevant self-regulatory code. A blank field should mean not reviewed, not silently assumed irrelevant.
    4. Attach the decision. Record who approved the claim, what evidence supported the decision, which market it covers, and what conditions or required qualifiers apply.
    5. Define review triggers. Reopen the row when you add a country, change the offer or audience, introduce a new claim, replace a destination, or materially revise the creative.

    Do not treat an accepted ad as legal clearance. Platform eligibility and legal compliance answer different questions. This distinction is especially important in regulated industries, where a small change in wording or audience can change the risk. If the decision depends on interpreting local law, have qualified counsel for that market make it before you launch; a policy reference cannot substitute for jurisdiction-specific legal advice.

    Audit AI Max at the query-creative-page level

    AI-driven search advertising changes the unit you need to inspect. It is no longer enough to review a keyword list, approve a fixed ad, and assume one destination. The useful unit is the complete journey: the search term that expressed intent, the assets the person saw, and the landing page that received the click.

    AI Brief gives AI Max written context about your business, intended audience, and key messaging. Its closed beta has expanded to Dutch, French, German, Italian, Japanese, Portuguese, and Spanish. If the feature is available in your account, the additional languages can help you express market context more directly, but a translated brief does not remove the need for local claim review.

    Build a working brief with five components:

    • Business truth: a precise description of what you sell, who provides it, and what the offer does not include.
    • Audience boundary: the customer need and level of intent the campaign is meant to serve.
    • Message priority: the benefit or differentiator that should lead, supported by approved language.
    • Claim restrictions: statements that are prohibited, conditional, or require a qualifier in each market.
    • Destination map: the approved page for each offer, language, audience, and country.

    Put the business, audience, and messaging context into AI Brief where supported. Keep claim restrictions and destination approvals in your external control register as well. AI Brief supplies context for optimization; it is not evidence that every generated or selected combination passed your legal review.

    Version the brief instead of continually overwriting it. Retain a version identifier, effective date, campaign scope, approving owner, supported languages, and the landing-page map that was current at the time. When performance changes, that record lets you distinguish an automation change from a change in the instructions you supplied.

    Google is also developing a unified reporting view connecting the triggering search term, the creative assets shown, and the landing page reached. No specific launch date has been announced; additional availability details are expected later in 2026. Treat that as planned visibility, not a feature you can assume is already present in every account.

    When the connected view is available, review each journey in this order:

    1. Search term: Does the term express an intent the campaign should serve, and is that intent appropriate for the targeted market?
    2. Creative: Do the shown assets answer that intent without adding an unsupported promise or dropping a required qualifier?
    3. Landing page: Does the destination fulfill the same promise, use the correct market version, and make the next step clear?
    4. Outcome: Did the combination produce the business result you intended, rather than merely generating a click?
    5. Intervention: Should you revise the brief, query control, asset, destination, or market approval before the combination appears again?

    Until unified reporting arrives in your account, reconstruct a sample from the separate data the account exposes. Start with high-spend terms, regulated offers, new markets, and combinations producing weak or surprising outcomes. Record unavailable fields as measurement gaps. Do not infer which asset a user saw merely because that asset currently exists in the library.

    This journey-level review protects you from a misleading average. Strong aggregate performance can coexist with irrelevant queries, mismatched promises, incorrect destinations, or a small number of high-risk combinations. The aggregate tells you where to look; the connected journey tells you what to change.

    Use CrUX to measure the ad load users actually experience

    Two phones show a stable page beside a page whose late-loading ad blocks shift content near a user's hand.

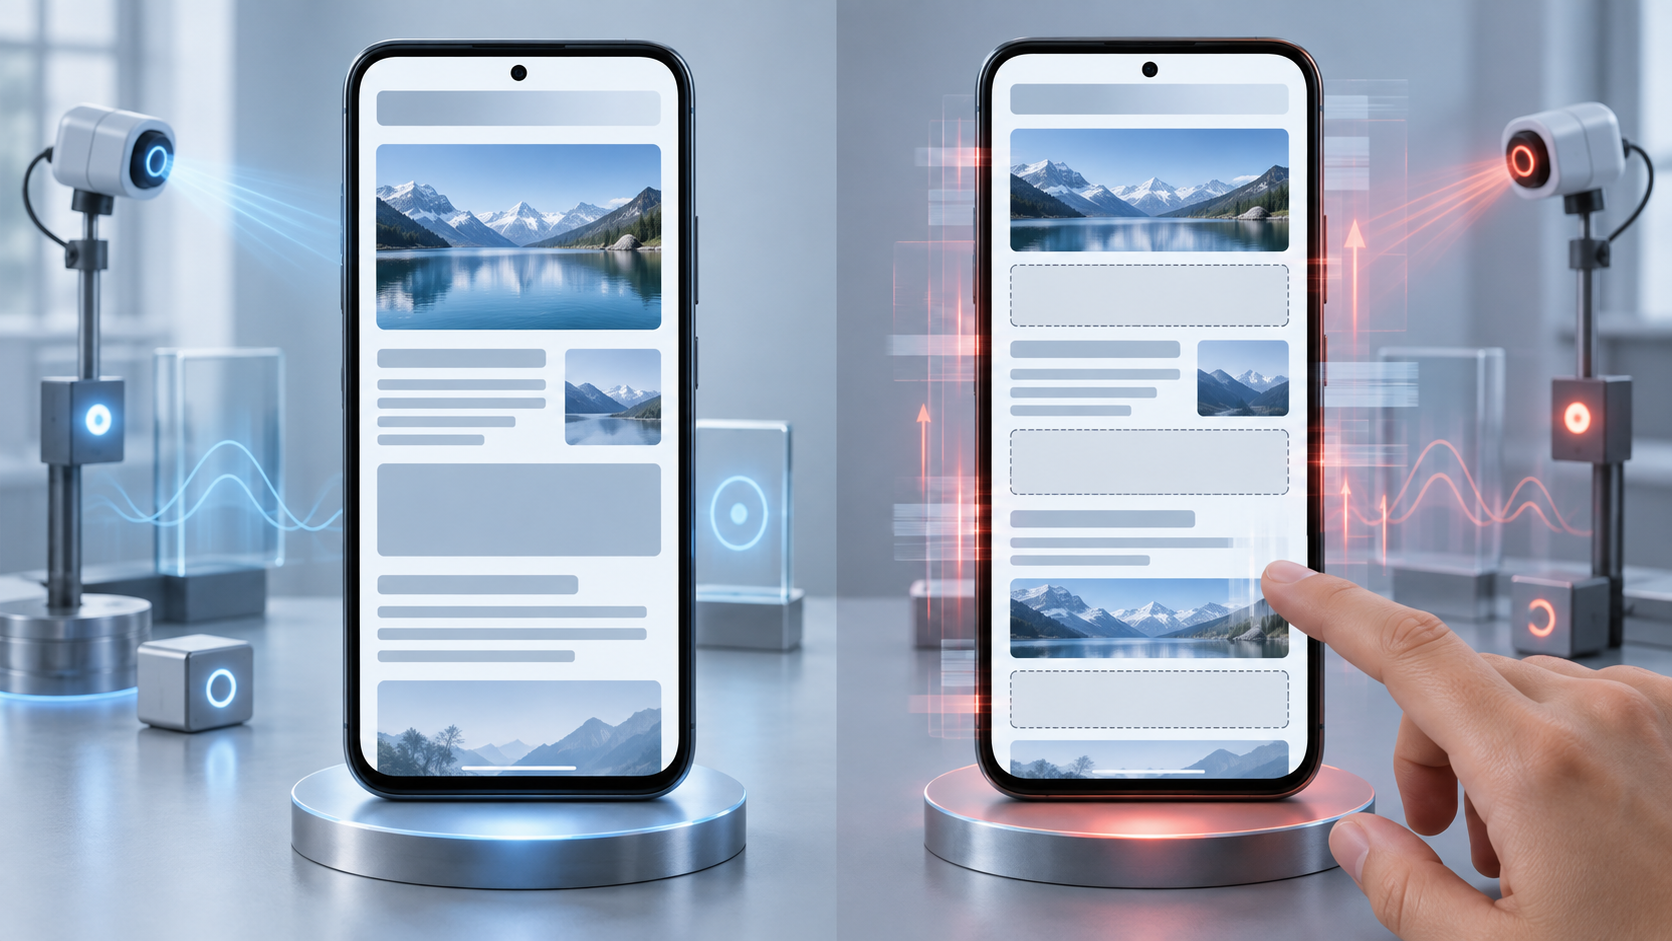
    The click is not the end of advertising measurement. If your landing pages or content pages carry advertising, the site’s own ad stack can consume processing power, transfer data, and occupy the viewport after the visitor arrives.

    Chrome’s public User Experience Report now includes four experimental advertising metrics based on real Chrome user experiences. They measure a different layer from Google Ads reporting:

    CrUX metricWhat it measuresUnit or formOperational question
    Ad Weight – CPUProcessing resources consumed by adsMillisecondsDid the advertising stack create a larger computational burden?
    Ad CountAverage number of ads visible in the viewportAverage countDid the layout expose users to more ads at once?
    Ad DensityAverage share of the viewport occupied by adsPercentageDid commercial inventory crowd out the page’s primary task?
    Ad Weight – NetworkData consumed by advertisingBytesDid ad delivery become heavier for real users?

    Use these metrics as diagnostics, not as a made-up pass-or-fail score. Google added them to its page-experience resources to help site owners evaluate ad experiences, while also cautioning that not every available experience metric is a direct search ranking factor. A movement in an experimental metric does not, by itself, prove why rankings, conversions, or engagement changed.

    A practical review looks like this:

    1. Identify paid-traffic destinations that also display on-site ads. If a page has no advertising, mark this layer not applicable instead of forcing the metrics into its scorecard.
    2. Capture the four metrics at the CrUX scope available to you and establish an internal baseline. Compare like with like inside your own site rather than inventing an unsupported universal threshold.
    3. Annotate ad-stack releases, placement changes, template revisions, and monetization experiments so a later movement has a plausible change record.
    4. Read the metrics together. Rising count or density points you toward quantity and placement; rising CPU or network weight points you toward the technical burden of delivery.
    5. Pair the diagnosis with the business outcome you already trust. The aim is to improve the user experience without pretending that one metric explains every performance change.

    Keep the scope distinction clear. CrUX ad metrics describe advertising experienced on your site. They do not reveal how Google Ads selected a search term, assembled creative, or chose a destination. That is why the journey audit and the on-page experience review belong beside each other rather than being collapsed into one score.

    Key takeaways

    • Separate market permission, automation instructions, delivered journeys, and on-page ad experience. Each layer needs different evidence.
    • Open a new compliance row for every country-and-offer combination. Google’s local-code list is helpful, but it is neither exhaustive nor a replacement for Google Ads policies and applicable law.
    • Treat AI Brief as versioned steering context, not as legal approval or proof that every automated output complied with your restrictions.
    • Evaluate AI Max through the complete search-term, creative, landing-page, and outcome chain. Campaign averages can conceal strategically poor combinations.
    • Use the four experimental CrUX ad metrics to diagnose advertising on your own pages, not to manufacture a ranking score or judge the Google Ads auction.

    Before your next market expansion or material budget increase, create one control-register row for the country and offer in question. Fill in the approved claims, brief version, destination map, observable journey evidence, and CrUX measurements where they apply. If a field has no owner or evidence, resolve that gap before you ask automation to scale it.

    References


  • AI Marketing Agent Safety: A Practical Oversight Framework

    AI Marketing Agent Safety: A Practical Oversight Framework

    Your marketing agent can draft a campaign, diagnose performance, or prepare a site update. The risk changes the moment it can spend money, suppress traffic, publish claims, email customers, or overwrite a working configuration.

    You don’t need a binary verdict on whether the model is trustworthy. You need an operating system around it: complete enough context, narrowly scoped permissions, enforceable policies, approval before consequential actions, and a record that lets you reconstruct what happened.

    Replace abstract trust with three control questions

    The safer question is not whether you trust an AI model in the abstract. Ask what the agent can see, what it is structurally allowed to do, and who must approve its work before production. Those questions turn trust into controls you can inspect and test.

    1. What can it see? List every account, dataset, field, date range, customer-data class, and external tool available to the agent. Record important gaps as carefully as available data.
    2. What can it do? Separate reading, analysis, drafting, recommendation, and execution. A prompt describing what the agent should do is not a permission boundary.
    3. Who signs off? Name the role that must approve each protected action. Reviewing a change log afterward is auditing, not approval.

    Use those answers to assign every workflow an operating mode. Do not give an entire agent one blanket risk label; the same agent may be safe to query campaign data and unsafe to change a budget.

    Operating modeWhat the agent may doMinimum control
    ObserveRead approved data and explain findingsNo production write credential; disclose data scope and gaps
    ProposePrepare copy, settings, or recommended changesPolicy validation; no direct route from proposal to production
    Limited executionCreate drafts, apply labels, or act inside a designated sandboxNamed resources, hard action limits, result verification, and a tested recovery path
    Protected executionChange spend, bids, targeting, negative keywords, live content, customer communications, access, or destructive settingsExplicit approval for the exact change before execution

    Reversible does not necessarily mean low risk. You can unpause a campaign, but you cannot recover traffic and opportunities lost while it was paused. You can restore a previous page version, but not necessarily retract a claim already seen by customers or answer engines. Classify risk by consequence and exposure, not merely by whether the interface has an Undo button.

    Scope each permission across several dimensions:

    • Environment: sandbox, draft workspace, or production.
    • Identity: the brands, business units, clients, and accounts included.
    • Resource: campaigns, pages, audiences, feeds, schemas, or customer records.
    • Action: read, create, edit, publish, pause, archive, or delete.
    • Magnitude: the amount of spend, number of entities, or audience size the action can affect under your existing internal limits.
    • Time: when permission begins, when it expires, and whether approval can be reused.

    The resulting permission register should be readable by marketing, security, and the workflow owner. If nobody can state an agent’s maximum possible action without opening its prompt, the boundary is not yet clear enough.

    Ground the agent before you evaluate its reasoning

    A fluent answer can still be built on an incomplete account view. The model may not know that a missing dataset contains the decisive explanation, so its tone will not reliably reveal the gap. Treat grounding as a safety control that reduces confidently wrong diagnoses, not as an optional convenience.

    Write a grounding contract

    A grounding contract defines the context a workflow requires before the agent may answer or act. It should record:

    • The systems, accounts, entities, fields, and historical periods the agent can access.
    • Excluded or inaccessible systems that could materially change the conclusion.
    • Data freshness, timezone, attribution settings, and the time of the last successful refresh.
    • The identifiers used to join advertising, analytics, CRM, commerce, and content data.
    • Which connectors are read-only and which can write.
    • What the workflow must do when a query fails, a join is ambiguous, or required context is stale.

    For a Google Ads agent, a strong PPC grounding baseline extends well beyond a packaged performance summary:

    • Full Google Ads query access through GAQL for the resources, fields, segments, and metrics needed by the question.
    • GA4 data alongside ad data when the diagnosis depends on what happened after the click.
    • Complete change history across interface edits, scripts, agents, and other connected tools.
    • Negative keywords assembled across account-level negatives, shared lists, campaigns, and ad groups, including a deterministic check of whether a query is already blocked.
    • Auction Insights and an inspectable view of the keywords shared with a competitor when making competitive claims.
    • Relevant vertical benchmarks whose cohort and calculation are visible, rather than an unexplained generic average.

    The same principle applies outside paid search. A content agent diagnosing lost visibility needs the relevant page versions, publication history, analytics context, and technical state. A schema agent needs the live markup and the page content it describes. A lead-nurture agent needs the current consent and suppression state available to the workflow. The exact systems differ; the requirement to expose material gaps does not.

    Make missing context part of every answer

    Require an input manifest with each recommendation. It should list the datasets queried, account and entity IDs, date ranges, filters, refresh times, failed queries, and inaccessible dependencies. When required context is absent, the agent should return an incomplete-data state instead of filling the gap with a causal story.

    This also improves review. The approver can challenge the evidence itself instead of judging polished prose with no way to see what sits underneath it.

    Enforce policy outside the model

    An abstract AI core is surrounded by separate layers of permissions, rule gates, rate controls, and a locked execution chamber that block risky actions.

    A system prompt can explain policy, but it should not be the component that enforces policy. Instructions can be misunderstood, displaced by conflicting context, or applied inconsistently. A control implemented in credentials, an action gateway, or workflow code can refuse an operation regardless of the text the model produces.

    A practical enforcement path has four parts:

    1. Separate agent identity. Give the agent its own credentials so its activity is distinguishable from a person’s work.
    2. Least-privilege access. Where the platform supports granular scopes, issue only the read and write capabilities required for the approved workflow.
    3. Action gateway. Route every proposed write through one controlled service rather than allowing the model to call production tools directly.
    4. Workflow states. Move work through proposed, validated, approved, executed, and verified states. Do not let the model skip a state.

    The policy layer should inspect the actual operation, not merely the agent’s description of it. Evaluate the destination account, object IDs, current values, proposed values, batch size, credential, policy version, and approval record before the write is sent.

    Start with rules you can test

    • Deny production writes by default and allow only named actions on named resources.
    • Treat drafting and publishing as different permissions.
    • Protect changes to budgets, bidding, targeting, conversion definitions, negative keywords, customer-facing messages, user access, and billing behind the appropriate internal approver.
    • Set an internal maximum for entities affected in one execution. A request above that limit must be split or separately approved.
    • Block execution when required data is unavailable, stale under your policy, or inconsistent across systems.
    • Prefer drafts and archives to deletion. If deletion is required, identify what cannot be restored before approval.
    • Fail closed when the policy service or approval store is unavailable. An outage in the safety layer must not silently become permission to proceed.
    • Log blocked attempts and policy exceptions as well as successful actions.

    Use your organization’s existing budget authority and publishing ownership to set thresholds. A generic dollar limit copied from another company cannot express your margins, account size, customer commitments, or tolerance for interruption.

    Test the boundary, not just the happy path

    Before granting production access, deliberately submit requests that should fail:

    • A valid action aimed at the wrong client or brand.
    • A batch larger than the configured action limit.
    • A protected change with no approval.
    • A request based on missing or stale required data.
    • A connected document containing instructions that conflict with the workflow policy.
    • A proposal altered after approval.
    • An execution in which the platform accepts some changes and rejects others.

    For every test, verify the operation was blocked or contained, the event was recorded, and the right owner was notified. If success depends on the model deciding to behave, the test has exposed a prompt preference rather than a hard control.

    Make human approval an exact, usable decision

    A campaign operator reviews a website publication package, audience envelope, spending token, and rollback component before choosing between separate approval and rejection controls.

    Human approval is valuable only when it happens before the consequential action and gives the reviewer enough evidence to make a decision. Grounding makes proposals more useful to review, while policy filtering removes obvious non-starters before they reach the queue. That combination keeps human attention focused on judgment rather than basic cleanup.

    Build a proposal packet, not a chat transcript

    Every approval request should contain:

    • The exact account, campaign, page, audience, feed, schema, or record affected.
    • A before-and-after representation of every proposed value.
    • The business reason for the change and the evidence used, with its date range and refresh time.
    • The expected effect, known uncertainty, and any plausible downside.
    • The policies evaluated, including passes, blocks, warnings, and requested exceptions.
    • The total number of entities and the maximum spend, reach, or publication surface exposed under the proposal.
    • The recovery procedure, including anything that cannot be reversed.
    • The person or role responsible for approval and the time at which that approval expires.

    Show this information in the marketing system reviewers already understand when possible. A technically complete payload is not enough if the person accountable for the campaign cannot see the practical effect.

    Bind approval to the exact proposal version, destination IDs, and values. If the agent edits the proposal, the underlying account state changes, or the approval expires, require validation and approval again. Never treat approval of an idea as standing permission for whatever implementation the agent later chooses.

    Verify the write and prepare for partial failure

    1. Recheck the destination, current state, data freshness, policy version, and approval immediately before execution.
    2. Apply only the approved delta. Do not let execution broaden into related cleanup that was absent from the proposal.
    3. Read the affected resources back from the platform and compare them with the approved values.
    4. Record the request, approval, actor, platform response, successful entities, failed entities, and verification result.
    5. If only part of a batch succeeds, stop the remaining work and send the exact partial state to the owner. Do not improvise a rollback whose consequences have not been reviewed.

    A rollback plan should be tested against the real platform before you rely on it. Some operations can be restored from a known previous value; others create exposure that restoration cannot undo. Keep a kill switch that can revoke the agent’s write path independently of the model and document who is authorized to use it.

    Monitor adoption, safety, and outcomes separately

    A central view is useful because unregistered agents become invisible operational dependencies. At minimum, maintain an agent registry with the owner, purpose, connected systems, permissions, policy set, approver, current status, and kill-switch owner for each workflow.

    Management dashboards can help expose usage patterns. For example, one vendor describes a command center that shows how teams use marketing agents, the hours their work returns, and adoption relative to peers. Those are adoption and capacity signals. They do not, by themselves, prove that the work was safe, accurate, or commercially valuable.

    Organize oversight metrics into three lenses:

    • Adoption and capacity: active agents, active users, workflow frequency, proposals created, actions executed, and estimated hours returned. Document how any time-return estimate is calculated.
    • Safety and control: missing-context responses, policy blocks, exception requests, rejected proposals, stale approvals, out-of-scope attempts, partial executions, failed verification, rollbacks, incidents, and near misses.
    • Business outcomes: the marketing measures the workflow was intended to influence, alongside cost, error, complaint, and rework signals. Do not attribute an outcome to the agent merely because the two appeared in the same reporting period.

    Configure immediate alerts for attempted protected actions, unavailable policy enforcement, writes to an unregistered destination, changes to agent credentials, partial execution, and failed post-write verification. A weekly dashboard cannot contain an agent that is actively writing to the wrong account.

    During rollout, inspect every attempted production write and every policy block. Once the controls have behaved correctly under real workload, choose a recurring review cadence based on action frequency and consequence, while keeping event-driven alerts for protected operations.

    Read metrics in context. Zero policy blocks can mean that workflows are well designed, that nobody is using them, or that enforcement is not recording failures. High approval rates can indicate good proposals or automatic rubber-stamping. Pair each number with sample-level review and an accountable owner.

    Key takeaways

    • Trust is the result of inspectable controls, not a personality judgment about the model.
    • Give agents enough context to reason well, and force them to expose material gaps.
    • Enforce permissions and policies outside prompts.
    • Require approval before actions that can affect money, traffic, customers, access, or live content.
    • Bind approval to an exact, time-limited proposal and verify the resulting platform state.
    • Measure adoption, safety, and business outcomes as separate questions.

    Start with the highest-consequence agent workflow you already use. Write its grounding contract, remove every unnecessary permission, and force its next production change through proposal, policy validation, exact approval, execution, and verification. Expand only one permission or action class at a time after that path works as designed.

    References


  • Microsoft Synthetic Ad Disclosure Rules: A Practical Workflow

    Microsoft Synthetic Ad Disclosure Rules: A Practical Workflow

    Your designer used generative fill, your editor replaced a voice segment, or your campaign team built an image from an AI prompt. Now you need to decide whether the ad can run on Microsoft Advertising, whether it needs a disclosure, and what evidence you should keep.

    Make that decision before the final export. A disclosure added at the upload screen cannot recover missing permission, removed provenance data, or a misleading depiction. The workable approach is to review AI involvement, accuracy, authorization, disclosure, and provenance as separate controls.

    Start with AI involvement, not whether the ad looks artificial

    Microsoft Advertising places AI-generated, AI-manipulated, and other synthetic content within its policy scope. When AI helped create or materially alter an ad, the audience may need to be told.

    That does not mean every use of AI automatically receives the same label. It means every use should receive a disclosure determination. If your media buyer first learns about the AI work after receiving the finished asset, the review has started too late.

    Add these questions to the creative brief:

    • Did AI generate any copy, image, video, audio, voice, person, product, setting, or event shown in the ad?
    • Did AI materially change recorded or photographed material, even if the original was real?
    • Could the finished creative make a viewer believe that a real person said, did, endorsed, or experienced something?
    • Does it reproduce or simulate an identifiable person’s likeness or voice?
    • Which countries or regions will receive the campaign?
    • Does the working file contain watermarks, metadata, or other provenance information that must survive production?

    For an internal materiality test, ask whether the AI work could change what a reasonable viewer believes about a person, product, place, claim, or event. A background cleanup is not operationally equivalent to fabricating a product demonstration or making a person appear to deliver a statement. This is a practical escalation test, not a universal legal definition. When the answer is unclear and the campaign carries rights or regulatory exposure, have counsel qualified in the relevant market review it.

    Treat compliance as four separate approval gates

    The common mistake is to treat an “AI-generated” label as a complete compliance solution. It is only one control. Your ad should pass four gates independently.

    1. Accuracy and eligibility

    Review the people, products, places, claims, and events depicted in the creative. Microsoft expects advertisers to check that those elements are accurate before submission. A disclosure explains how content was made; it does not make a false claim, prohibited deepfake, or deceptive demonstration acceptable.

    Run the review against the finished ad, not just the prompt. Generative systems can introduce details that nobody explicitly requested, so prompt approval is not creative approval. Compare the final asset with the real product, approved claim language, authorized spokesperson material, and the event or location it purports to show.

    2. Authorization

    Confirm that you have any permission required to use a person’s likeness or voice. Advertisers remain responsible for applicable laws in every market where a campaign appears, including requirements involving consent, permissions, disclosures, likenesses, and voices.

    Do not infer authorization from access to a photograph, recording, stock asset, or previous campaign file. Document what was authorized, for which media and markets, and whether synthetic alteration or voice replication falls within that authorization. If the permission does not clearly cover the planned use, pause the ad rather than relying on a label to fill the gap.

    3. Consumer disclosure

    Determine whether a visible or audible disclosure is required for that asset, format, and market. When notice is required, it must be clear and positioned close to the content it explains. Permission from the depicted person does not eliminate a separate disclosure obligation.

    4. Machine-readable provenance

    Preserve watermarks, metadata, and other available signals identifying how synthetic content was created. These signals support provenance, but they are not necessarily visible to a consumer. Passing the provenance gate therefore does not mean you have passed the disclosure gate.

    Approve the ad only when all four gates pass. That structure prevents a reviewer from answering one narrow question – “Does it have a label?” – while missing the reason the ad should not run at all.

    Put the disclosure where the consumer encounters the synthetic content

    A person views a tablet ad with an abstract disclosure symbol placed directly beside the synthetic image.

    An AI note in a production ticket, file name, landing-page footer, or internal media plan is not a consumer-facing disclosure. When disclosure is required, Microsoft recommends embedding it directly in image and video assets. Microsoft Advertising’s disclaimer feature can also be used with formats that support it.

    Use this placement process:

    1. Add the approved disclosure to the asset master, not only to one exported placement.
    2. Keep it close to the synthetic element or claim it qualifies. Do not make the viewer search another screen for the explanation.
    3. Match the disclosure mode to the experience. Image and video disclosures need to be visible; audio-led creative may also require an audible notice.
    4. Export every required size and format, then inspect the actual output. Cropping, compression, scaling, captions, and interface overlays can make a disclosure unreadable or separate it from the relevant content.
    5. Where the Microsoft Advertising disclaimer feature is supported, decide whether it should supplement or deliver the required notice for that format. Do not assume feature availability removes the need to inspect the consumer-facing result.
    6. Record the approved wording, placement, disclosure mode, markets, formats, and approver so later adaptations do not silently change the decision.

    Do not invent a single global font size, duration, or phrase and treat it as universally sufficient. The governing requirement is that the disclosure be clear, close to the relevant content, and compliant wherever the campaign runs. If a local rule or approval imposes more specific wording or presentation, carry that requirement into the asset specification.

    Localization deserves a new review. Translated wording can become longer, a resized layout can push the label out of view, and a newly added market can change the applicable requirement. Treat each of those changes as a controlled version, not a harmless derivative.

    Protect provenance and permission records throughout production

    A creative team preserves connected provenance markers while storing permission and approval records in a secure archive.

    Images, audio, and video created with Microsoft AI tools can contain machine-readable provenance data, metadata, and imperceptible watermarks indicating AI involvement. Because those signals may not be apparent to the audience, you may still need a separate visible or audible disclosure.

    Your production workflow should preserve both the technical evidence and the human approval record:

    • Keep the original AI output before retouching, resizing, or re-encoding.
    • Retain the working file and submitted export so reviewers can trace what changed.
    • Do not deliberately remove a watermark, metadata field, or provenance signal merely to make the file look cleaner.
    • Check whether your export process retained the provenance information present in the source asset.
    • Store documented likeness and voice authorization with the creative record, including any limits relevant to synthetic alteration.
    • Keep the market-by-market disclosure decision with the exact asset version it covers.
    • Save evidence of how the consumer-facing disclosure appears in the final format.

    This record is useful only if versioning is disciplined. A later editor should be able to tell whether a new crop, translated label, revised voice track, or altered product scene reopened one of the four approval gates. “Approved” should never float free of a specific file and campaign scope.

    Interfering with machine-readable provenance information is not a harmless optimization. Along with prohibited deepfakes, impersonation, unauthorized use of a likeness or voice, and omitted required disclosures, it can contribute to an ad being rejected, restricted, or removed.

    Use a repeatable approval workflow before every submission

    Build the review into campaign operations instead of asking the media buyer to reconstruct the creative history at launch. The following workflow is specific enough to assign owners and flexible enough to use across image, video, audio, and copy-led ads.

    1. Inventory AI involvement. Record which portions of the ad were generated or materially altered and retain the original outputs.
    2. Map distribution. List the markets, languages, Microsoft Advertising formats, and derivative sizes planned for the campaign.
    3. Challenge accuracy. Verify every depicted person, product, place, claim, and event against approved factual material.
    4. Clear rights. Confirm that any likeness or voice use has the authorization required for the specific synthetic use, media, and market.
    5. Screen for stop conditions. Do not submit deceptive creative, prohibited deepfakes, impersonation, or unresolved unauthorized use merely because a disclosure can be added.
    6. Make the disclosure decision. Determine the required wording, visible or audible treatment, proximity, and market coverage. Escalate unresolved legal questions to qualified counsel.
    7. Build the notice into production. Embed it in image or video assets when required and configure the platform disclaimer feature where supported and appropriate.
    8. Run final-output quality assurance. Confirm that the disclosure remains clear and close to the relevant content and that provenance information has not been stripped.
    9. Approve a specific version. Store the decision, evidence, permissions, asset identifier, formats, markets, and approver together. Reopen review after any material creative or distribution change.

    If an ad fails because its underlying depiction is deceptive or unauthorized, rebuild or withdraw it. Relabeling is not remediation. Microsoft is allowing AI-assisted advertising, but an AI disclosure does not make deceptive creative acceptable.

    Key takeaways

    • Route every AI-generated or materially altered ad through review, even when the synthetic work is difficult to notice.
    • Assess accuracy, authorization, disclosure, and provenance separately; success in one area does not cure failure in another.
    • When disclosure is required, make it clear, close to the relevant content, and part of the asset where appropriate.
    • Preserve metadata, watermarks, and other provenance signals, but do not mistake them for consumer-facing notice.
    • Do not use a label to justify a deepfake, impersonation, deceptive claim, or unauthorized likeness or voice.
    • Repeat the determination for each market, format, language, and materially changed creative version.

    Your next move is concrete: add five required fields to the creative intake form – AI involvement, likeness or voice use, target markets, disclosure decision, and provenance status. Assign an owner to each field before the asset enters paid-media production. That small change moves compliance from a last-minute label request to a reviewable part of how the ad is made.

    References


  • How to Audit AI Marketing Recommendations Across Audiences

    How to Audit AI Marketing Recommendations Across Audiences

    You give an AI marketing tool a clear goal, and it returns a confident audience, channel, or brand recommendation. The answer looks ready to use. But before you build a campaign around it, you need to know two things: what evidence produced the recommendation, and whether the recommendation changes when the audience changes.

    If neither is visible, you do not have decision support yet. You have a plausible output whose scope, assumptions, and failure modes are hidden. The practical fix is to audit recommendation evidence and audience variation as one workflow, then require human approval wherever a change could affect reach, spend, eligibility, or brand strategy.

    One AI answer is not a complete market view

    A single answer-engine response can be useful without being representative. The engine may interpret the question through details about the user, the wording of the prompt, prior conversational context, or other signals available to the system. Change that context and the shortlist, ranking, citations, or explanation may also change.

    A vendor analysis of 71,147 answer-engine responses found differences in brand mentions, citations, and search behavior associated with income, age, gender, and occupation. That finding does not establish that every answer engine personalizes every request, nor does it explain the cause of every observed difference. It does show why a persona-neutral prompt should not be treated as a universal picture of AI visibility.

    Some variation is appropriate. A buyer prioritizing affordability and a buyer prioritizing enterprise governance may reasonably receive different recommendations. The issue is not whether answers ever change. It is whether the change follows a relevant criterion, rests on supportable evidence, and remains consistent with the underlying facts.

    Separate the stable layer from the audience-sensitive layer:

    • Stable facts include product identity, documented capabilities, known requirements, and the meaning of cited evidence. A persona change should not silently reverse them.
    • Audience-sensitive judgments include which criterion receives more weight, which use case is emphasized, which options appear first, and which tradeoff is considered acceptable.
    • Presentation choices include tone, examples, terminology, and depth. These may change while the substantive recommendation remains the same.

    This distinction helps you spot three common measurement failures:

    • False universality: one prompt produces one answer, and the result is reported as what the platform recommends to everyone.
    • Hidden exclusion: a brand appears for one persona but disappears for another, with no visible criterion explaining the difference.
    • Averaged-away variation: a dashboard combines responses across audiences and makes unstable visibility look consistent.

    Treat an AI visibility observation as a combination of platform, prompt, audience context, and observation time. If any part changes, you may be measuring a different answer environment.

    A transparent recommendation shows decision evidence

    Hands inspect the visible source, assumption, recommendation, and approval components inside a transparent decision-making assembly.

    Transparency does not mean exposing every internal model operation or demanding a private reasoning transcript. Neither gives a marketer a reliable basis for approval. You need the evidence, uncertainty, and tradeoffs that could materially change the decision.

    This matters because marketing data is rarely as tidy as the campaign brief. A marketer searching for a completed-purchase signal may encounter several similarly named events, such as purchase, checkout success, and checkout completion. The labels alone do not reveal which event represents a confirmed order, which fires earlier in the funnel, or which remains reliable after implementation changes.

    Volume does not settle the question. A frequently firing purchase event could occur before payment confirmation, while a lower-volume checkout-success event could align more closely with the business definition of a completed order. Selecting the biggest signal without checking its meaning can create a large but conceptually wrong audience.

    Require each consequential recommendation to carry an evidence card. It can appear in a conversational response, side panel, review screen, or exported log, but it should answer the following questions:

    Evidence fieldWhat the system should exposeWhat you can decide
    Business objectiveThe outcome the recommendation is intended to support, in business languageWhether the proposed action answers the request you actually made
    Selected signal or criterionThe event, attribute, source, or decision criterion carrying the recommendationWhether the system used the right representation of the goal
    Meaning and funnel stageWhat the signal appears to represent and where it occurs in the customer journeyWhether purchase, checkout, intent, and engagement are being confused
    Provenance and observed behaviorWhere the signal comes from, how it behaves, how often it fires, and when it was last observedWhether the evidence is current and dependable enough for this decision
    Audience boundariesWho is included, who is excluded, and the resulting potential reachWhether the audience matches campaign eligibility and strategy
    Alternatives consideredThe plausible competing signals or approaches that could change the outcomeWhether an apparently obvious recommendation ignored a better-defined option
    TradeoffsHow changing a threshold or criterion affects reach, expected performance, precision, or riskWhich compromise fits the business rather than merely optimizing a model score
    Uncertainty and missing contextAmbiguous definitions, unavailable metadata, sparse observations, or assumptions supplied by the systemWhether to accept, refine, investigate, or reject the recommendation
    Decision stateWhether the output is exploratory, proposed, saved, connected, or activatedWhether any real-world action has occurred and what still requires approval

    Do not accept vague evidence labels such as recent, strong, or large when the interface can expose the underlying context. Recent relative to what observation? Strong against which alternative? Large compared with which eligible population? The system does not need to manufacture precision, but it should distinguish known values from inferred meanings and unavailable information.

    The approval flow matters as much as the evidence. For recommendations that can change spending or customer eligibility, keep proposal, saving, connection, and activation as distinct states. An exploratory conversation should not silently become an active audience. Explicit confirmation creates a point where a marketer can apply business judgment, document an override, or request better evidence.

    Conversation and direct controls also serve different jobs. A conversational agent is well suited to exploring unfamiliar data and explaining why signals differ. A visual interface is better for making precise threshold adjustments after the reach-versus-performance tradeoff is understood. A trustworthy workflow lets you move between them without losing the evidence or approval state.

    Run a controlled audience-variation audit

    Four controlled test lanes hold the same campaign brief while different audience groups lead to visibly varied recommendation objects.

    An audience audit should isolate whether persona context changes the recommendation, not merely collect a folder of unrelated prompts. Keep the decision question and test conditions stable, change one relevant audience dimension at a time, and record substantive differences separately from stylistic ones.

    Build the test grid

    1. Define the decision. Write the exact question the answer must resolve, such as which solution fits a use case or which audience should receive a campaign. State the criteria that should matter before looking at the output.
    2. Create a neutral baseline. Ask the decision question without demographic or occupational context that is not necessary to answer it. This becomes the comparison point, not the presumed correct answer.
    3. Select relevant audience dimensions. Test occupation, age, income, gender, or another persona attribute only where it could plausibly affect needs, constraints, terminology, access, or evaluation criteria.
    4. Change one dimension at a time. Keep the platform, wording, product category, requested format, and other context constant. Composite personas may reflect real buyers, but they make it harder to identify which attribute drove a change.
    5. Capture the complete response. Record the prompt, audience variation, platform and model label exposed by the interface, observation time, recommended brands or actions, ordering, rationale, citations, caveats, and omitted options.
    6. Compare decisions before wording. A different example or tone is less important than a changed shortlist, reversed ranking, new exclusion, altered factual claim, or different call to action.
    7. Inspect the support. Check whether each changed recommendation is tied to an explicit audience need and whether its cited material actually supports the criterion being applied.
    8. Assign a disposition. Mark the variation as presentation-only, relevant and supported, unexplained and substantive, or factually contradictory. Each label should lead to a different next action.

    Interpret changes by materiality

    Presentation-only variation changes the vocabulary, explanation depth, or examples without altering the decision. You may still care about tone and accessibility, but it is not evidence that brand visibility changed.

    Relevant, supported variation changes the recommendation because the persona introduces a genuine decision criterion. An occupational context may change workflow requirements. An affordability constraint may alter which options qualify. The output should make that connection visible rather than relying on an unexplained proxy.

    Unexplained substantive variation changes inclusion, exclusion, order, or recommended action without identifying a relevant criterion or supporting evidence. Do not immediately label it bias or personalization; the system may be responding to ordinary output variation, hidden context, or a retrieval difference. Rerun the unchanged baseline alongside the persona variant, preserve the outputs, and investigate before drawing a causal conclusion.

    Factual contradiction occurs when stable product facts or evidence claims change solely with the persona. That is a blocking issue. Do not use the output for activation or publish the claim until you can resolve which statement is supported.

    Pay special attention to citations. A persona may receive different cited pages even when the recommendation stays similar. Record whether a citation is present, whether it supports the nearby claim, and whether it represents the same kind of evidence across variants. Citation count alone cannot tell you whether the recommendation is sound.

    Age, gender, and income can be useful diagnostic variables because audience-linked variation has been observed, but they can also be sensitive attributes. Using them to determine real customer eligibility can create privacy, fairness, or legal exposure depending on the context and jurisdiction. Use them in testing only when necessary, minimize personal data, and route any activation rule based on sensitive traits through your legal and privacy review process.

    Turn the audit into content, measurement, and controls

    An audit is only valuable if it changes how you publish, measure, or approve marketing decisions. The goal is not to force every audience to receive identical recommendations. It is to make legitimate differences explainable and unsupported differences visible.

    Make audience criteria explicit in your content

    If an answer engine changes its recommendation because of a criterion your content barely addresses, close that evidence gap on the relevant page. Add clear passages that identify:

    • who the product, service, or method is designed for;
    • which use cases it supports and which it does not;
    • what prerequisites, limitations, or eligibility conditions apply;
    • which tradeoffs a buyer must make;
    • how important terms and outcomes are defined; and
    • which verifiable facts support each suitability claim.

    Write around decision contexts, not demographic labels. A page explaining the needs of a regulated procurement workflow is more useful than a thin page targeting an occupational persona by name. A clear affordability limitation is more informative than assuming what someone can spend from a demographic category.

    Structured data can reinforce supported facts about the page, organization, product, service, author, or other entities where the relevant schema applies. It cannot make an unsupported claim trustworthy, encode every possible persona preference, or guarantee that an answer engine will recommend a brand. Use schema to clarify machine-readable facts, then make the audience-specific reasoning legible in the visible content.

    Measure visibility at the audience level

    Do not reduce answer-engine performance to a platform-wide mention rate if your buyers approach the category with materially different contexts. Track AI visibility by audience as well as by platform, while retaining the neutral baseline so you can see where variation begins.

    For each monitored decision question, record:

    • the exact prompt and persona context;
    • the engine, interface, and model information exposed at the time;
    • whether your brand was mentioned;
    • where it appeared in an ordered recommendation, if the answer provided an order;
    • the use case or criterion attached to the mention;
    • the pages or sources cited;
    • the caveats attached to the recommendation; and
    • whether the result was stable, relevantly different, unexplained, or contradictory.

    Keep the prompt set and audience definitions fixed when comparing observations over time. If you rewrite the question, change the persona, and switch platforms at once, you cannot tell whether a visibility movement came from your content, the engine, or the test design.

    Define approval boundaries before activation

    Set review rules before an agent proposes an audience or campaign. Require human approval when:

    • the selected data signal has an ambiguous business meaning;
    • the origin, observed behavior, or recency of the evidence is unavailable;
    • a threshold creates a material reach-versus-performance tradeoff;
    • a sensitive audience attribute changes inclusion or exclusion;
    • persona variants produce contradictory facts or unexplained recommendations;
    • the action can change budget, customer eligibility, messaging, or external activation; or
    • the system cannot show which assumption would most affect the recommendation.

    Preserve the human decision in a log. Record the proposal, evidence shown, audience context, chosen action, override, approver, and activation state. This is not paperwork for its own sake. It lets you distinguish a model recommendation from the business decision that followed it and prevents later reporting from treating the two as interchangeable.

    Key takeaways

    • A single AI response represents one platform, prompt, audience context, and observation time. It is not a universal market answer.
    • Useful transparency exposes the selected signals, their meaning and recency, audience boundaries, alternatives, uncertainty, and tradeoffs. A private reasoning transcript is not required.
    • Test audience variation by holding the decision question constant and changing one relevant persona dimension at a time.
    • Separate presentation changes from substantive recommendation changes, and block activation when stable facts become contradictory.
    • Measure brand mentions, ordering, use cases, citations, and caveats by audience rather than averaging every response into one platform score.
    • Keep exploration, saving, connection, and activation distinct so a marketer can refine or override the recommendation before it affects customers or spend.

    Start with the next recommendation your team is already preparing to use. Attach an evidence card, run the neutral prompt beside one relevant audience variant, and classify every substantive difference. If the system cannot explain a changed recommendation with current evidence and a relevant criterion, do not report it as universal and do not activate it. Fix the evidence, the content, or the decision rule first.

    References


  • Anthropic AI Watermarking and SEO: A Practical Guide

    Anthropic AI Watermarking and SEO: A Practical Guide

    If Claude touches your production copy, your immediate question is probably simple: can a search engine detect the watermark and demote the page? No direct ranking penalty has been established for Anthropic’s watermark. It is a provenance mechanism, not an SEO quality score.

    That does not make it irrelevant. The larger exposure sits in governance. A client, employer, platform, or regulator may interpret detection as proof that Claude wrote an entire page, even when the signal only reflects rewriting, translation, or tone adjustment. You need to separate ranking risk, content risk, reputation risk, and compliance risk before anyone makes a consequential decision from one detector result.

    What Claude’s watermark actually tells you

    Anthropic’s approach is not the familiar trick of planting zero-width spaces, unusual punctuation, or hidden characters in finished text. It uses statistical, or generative, watermarking.

    A language model does not always select the single most probable next token. It samples from several plausible choices so the output remains varied and natural. Statistical watermarking guides some of those choices with a secret key. Across a sufficiently suitable passage, the resulting sequence can carry a detectable statistical signature.

    The visible text still behaves like ordinary text. There is no watermark overlay, metadata label, HTML attribute, or string of invisible characters for an editor to find and delete. In this context, “machine-readable” means that a compatible detection process can analyze patterns in the generated language. It does not mean that the watermark appears in your page source, JSON-LD, sitemap, or content-management fields.

    Anthropic says its method does not identify an individual user and has no practical effect on output quality. Those are vendor claims about the mechanism, not proof that every watermarked passage is accurate, original, useful, or publication-ready.

    A positive result is evidence of processing, not complete authorship

    Suppose a subject-matter expert writes a page and asks Claude to simplify the sentences, translate it, or adjust the tone. The resulting copy can carry a watermark even though the facts, argument, and original draft came from a person. The signal indicates that Claude processed the language. It cannot explain how much intellectual work Claude performed.

    That distinction matters whenever an organization has an AI policy. “Was Claude used?” is a different question from “Who developed and verified the substance?” A detector may help with the first question. It cannot answer the second without revision history, editorial records, and human review.

    A negative result is not a certificate of human authorship

    The inverse is equally important. Human editing, paraphrasing, or processing through another model can weaken a statistical pattern. Text produced by an unwatermarked system may have no Anthropic signature at all. A negative result therefore cannot prove that a person wrote the copy from scratch.

    This asymmetry makes detector-based enforcement fragile. Careful, legitimate users can be flagged after light assistance, while low-value publishers have a strong incentive to alter the signal. Do not promise clients, employees, or writers that a detector can authenticate human authorship. It cannot provide a complete chain of custody for a document.

    The regulatory purpose is not an SEO purpose

    Anthropic introduced the measure in response to Article 50(2) of the EU AI Act, Regulation 2024/1689. The provision addresses providers of systems that generate synthetic text, images, audio, or video. It calls for machine-readable marking that is effective, interoperable, robust, and reliable to the extent technically feasible.

    That context is crucial. The watermark is intended as a transparency and compliance mechanism at the model-provider layer. It was not introduced as a search ranking system, a spam classifier, or a measure of editorial value.

    Do not assume that provider-level watermarking settles your own disclosure obligations. Contracts, client policies, employment rules, and laws affecting a publisher can impose separate requirements. If a publishing decision creates meaningful legal or regulatory exposure, have qualified counsel interpret the rules for your market and use case rather than treating detector output as legal advice.

    Separate SEO risk from quality and governance risk

    A central document connects to separate branches represented by a search magnifier, a quality prism, and a governance shield with a reviewer.

    The word “watermark” encourages people to collapse four questions into one. Keeping them separate prevents unnecessary rewrites and missed compliance problems.

    QuestionWhat the watermark can establishWhat you should use instead
    Will search engines demote this page?No direct ranking penalty or search-engine integration is established by the watermark itself.Evaluate search performance, technical accessibility, intent satisfaction, accuracy, and the page’s distinctive value.
    Did a person write every sentence?A positive result may show Claude processing, but it cannot allocate authorship between a person and the model.Use drafts, version history, prompts, editor notes, and accountable sign-off.
    Is the content high quality?Nothing. The signature does not grade accuracy, originality, usefulness, expertise, or style.Apply factual, editorial, brand, and search-quality review.
    Was AI use permitted?Detection may be relevant evidence, but it does not interpret a contract, policy, or law.Check the exact rule, the role Claude performed, and the required disclosure or approval.

    The direct ranking concern is currently unsupported

    A statistical signature is not inherently a judgment about whether a page deserves to rank. It does not tell a search system whether the answer is correct, whether the page resolves the query, whether the examples are original, or whether the claims are supported. Your page can be detector-positive and excellent. It can also be detector-negative and useless.

    That means rewriting good copy solely to weaken a possible watermark is not an SEO strategy. It changes words without necessarily improving the answer. It may also introduce factual errors, flatten a subject-matter expert’s meaning, or make the prose less precise.

    The familiar SEO risk remains more important: publishing interchangeable copy that gives a searcher or answer engine no reason to select your page over another. Claude can help produce that kind of copy quickly, but the weakness is generic content, not the existence of a statistical signature.

    The indirect reputation risk is real

    Detection can become a shorthand for misconduct even when the underlying use was ordinary editing. A client may read “watermarked” as “fully generated.” A manager may treat it as evidence that no expert reviewed the work. A publisher may apply a blanket rule without distinguishing ideation, translation, rewriting, drafting, and final approval.

    You reduce that risk with a documented workflow, not with synonym swapping. Decide in advance which uses are permitted, what must be disclosed, who owns the claims, and what evidence must be retained. If the rules are only discussed after a detector flags a page, the organization has already lost the clearest opportunity to make a fair decision.

    AEO and GEO still depend on extractable, supportable answers

    Anthropic’s watermark does not create citations, entity clarity, structured data, or supporting evidence. It does not repair ambiguous wording or reconcile conflicting facts. Those remain separate editorial and technical tasks.

    For search and generative answer visibility, audit the published page for what a retrieval system can actually use. Put the direct answer near the relevant heading. Name entities consistently. Attach evidence to consequential claims. State limitations and conditions next to the advice they qualify. Make comparisons use the same dimensions. Ensure structured data agrees with the visible copy rather than introducing facts that readers cannot see.

    These improvements are worth making whether Claude generated zero words or every initial sentence. They help the page communicate clearly without pretending that a watermark is either a quality guarantee or a disqualifier.

    Build a publishing workflow that survives watermarking

    A human editor reviews a document as it moves through fact-checking, policy review, recordkeeping, and publication workstations.

    You do not need a detector-led content operation. You need a workflow that can explain how each page was produced, prove who verified it, and measure whether it serves its intended audience.

    1. Classify Claude’s role before work begins. Use a small, stable vocabulary: ideation, outline, first draft, transformation, translation, fact organization, or final copy edit. Record the role in the assignment. “AI-assisted” alone is too vague to distinguish a generated draft from punctuation cleanup.
    2. Assign review depth according to consequence. Routine educational content still needs an accountable editor. Product claims, pricing, contractual language, public policy, and regulated subjects need verification by the person who owns those facts. Medical, legal, or financial claims warrant review by an appropriately qualified professional; a fluent model output is not a substitute.
    3. Give the model an approved fact pack. Supply the confirmed names, dates, definitions, internal claims, permitted evidence, and boundaries before drafting. Mark uncertain material as uncertain. If a claim cannot be traced to an approved record, remove it or send it back for verification.
    4. Edit for contribution, not for watermark removal. Confirm the answer matches the query. Replace generic observations with supported details. Add the organization’s genuine expertise, examples, constraints, and decision criteria. Remove invented transitions that imply causation. Check that every number, quotation, date, and named claim has a traceable basis.
    5. Keep an honest provenance record. Retain the original brief, relevant prompts, model output, human revisions, evidence links, reviewer, and approval date where policy permits. Do not describe materially processed text as entirely human-written. If public disclosure is required by law, contract, or editorial policy, use wording that accurately describes the model’s role.
    6. Run technical SEO checks on the final URL. Verify indexability, canonicalization, rendered headings, title and description, internal links, media alternatives, and mobile presentation. Validate that structured data describes visible content accurately. These checks answer whether a crawler can understand the page; watermark detection does not.
    7. Measure publishing outcomes separately from provenance. Annotate when the workflow changed, then monitor impressions, qualified organic clicks, query mix, conversions, and any AI citation tracking you use. Compare affected pages with a sensible baseline. One ranking movement cannot establish that a watermark caused it.

    What to do when a detector flags a page

    A flag should trigger review, not an automatic conviction. Use the following sequence:

    1. Preserve the evidence. Keep the flagged version, result, date, detector name, settings, and any confidence information. Do not immediately overwrite the page or revision history.
    2. Identify the question being investigated. Are you checking compliance with an internal ban, a disclosure requirement, a client contract, or content quality? The same result has different relevance to each question.
    3. Confirm what the detector claims to detect. A generic “AI detector” is not automatically an Anthropic watermark detector. Ask whether the method is compatible with Claude’s statistical signal and whether the result is probabilistic.
    4. Review production records. Compare the brief, human draft, Claude output, version history, editor changes, and final approval. This is how you distinguish model drafting from model-assisted editing.
    5. Assess quality independently. Recheck factual accuracy, originality, reader value, citations, search intent, and technical implementation. A positive result does not make a correct claim wrong, and a negative result does not validate a weak page.
    6. Resolve any policy breach directly. If Claude use violated an agreement, send the matter to the responsible owner and correct the process. Paraphrasing the text until a detector stops reacting does not undo the violation.

    Do not paste confidential, personal, client-owned, or embargoed material into an unapproved detection service. Preserve the text internally and use a detector that has passed your organization’s privacy and security review.

    Do not turn evasion into an optimization objective

    Once detection exists, people will experiment with paraphrasing, repeated editing, and multi-model processing to weaken the signal. That may change detectability, but it adds no inherent reader value. It can also obscure accountability and make the final text harder to verify.

    If a passage needs revision, revise it because it is inaccurate, generic, unclear, unsupported, badly structured, or inconsistent with the brand’s genuine position. “Detector-negative” is not a meaningful editorial standard.

    Key takeaways

    • Anthropic’s watermark is a statistical pattern in generated language, not a hidden character, page tag, or visible label.
    • A positive result can indicate Claude processing, but it cannot prove that Claude originated the ideas, facts, or complete draft.
    • A negative result cannot prove human authorship because editing, paraphrasing, other models, and unwatermarked systems can leave no detectable Anthropic signature.
    • No direct SEO ranking penalty has been established for the watermark itself. Content quality and technical search readiness still require separate evaluation.
    • The practical risk is governance: people may mistake a provenance clue for a quality score or a complete authorship record.
    • The durable response is documented AI use, accountable human review, traceable evidence, accurate disclosure, technical QA, and outcome monitoring.

    Add three fields to your next content brief: Claude’s permitted role, the accountable human reviewer, and the location of the supporting evidence. That small change gives you something a watermark never can: a defensible explanation of how the page earned publication.

    References


  • How to Build Trustworthy AI Agents for Marketing Operations

    How to Build Trustworthy AI Agents for Marketing Operations

    You have an agent that can inspect ad accounts overnight, draft a content brief before stand-up, or flag a broken funnel. The uncomfortable question arrives just after the demo: what, exactly, are you willing to let it do without asking?

    If your answer is “we’ll review it,” you don’t yet have a control system. You have an intention. A trustworthy marketing agent needs a bounded job, owned data, explicit permissions, evidence attached to its conclusions, a release gate, and a way to stop or reverse its actions. Here is how to put that operating model in place.

    A trustworthy agent is a controlled workflow, not a clever model

    A model generates an answer. An agent combines a model with data, instructions, tools, scheduled triggers, and permission to take or prepare actions. That surrounding system determines whether a plausible mistake becomes a harmless draft, a misleading alert, or a customer-facing incident.

    Trustworthiness therefore isn’t the promise that an agent will never be wrong. It is your ability to see what the agent observed, understand why it reached a conclusion, constrain what it can do, route uncertain cases to the right person, and recover when something fails. In production, reliability is decided by governance, realistic testing, and named review paths at least as much as by model capability.

    The most useful mental model is a new employee with unusual speed. You wouldn’t give a new marketing analyst unrestricted CRM access, authority to change pricing, and permission to email customers on the first morning. You would define the role, grant only the access it needs, review early work, and expand responsibility after the work proves dependable. An AI agent needs the same management discipline, encoded in the workflow rather than left in a manager’s head.

    Before deployment, make sure every agent has clear answers to these questions:

    • What specific decision or task does the agent own?
    • Which systems, records, fields, and time periods may it inspect?
    • Which facts and business rules must it know before making a judgment?
    • What evidence must accompany each conclusion or recommendation?
    • When must it abstain, escalate, or ask for missing information?
    • Who reviews consequential work, and what counts as approval?
    • Which actions can it take, and how can those actions be stopped or reversed?
    • Which version of the model, instructions, tools, and data definitions produced the result?

    If any answer is “it depends,” write down what it depends on. That conditional logic is part of the product. It cannot remain tribal knowledge if the agent is expected to make repeatable decisions.

    Begin with one bounded decision, not a general marketing assistant

    “Monitor our marketing” sounds like a useful assignment, but it contains dozens of hidden jobs. Does monitoring mean detecting a tracking outage, explaining a CPA change, checking whether campaigns are serving, judging lead quality, finding off-brand copy, or recommending budget shifts? Each job needs different data, context, freshness rules, and escalation paths.

    Start with a task whose input and acceptable output can be described precisely. Read-only analysis is usually the safest entry point because the agent can create value without changing the underlying system. Examples include investigating an ad-delivery alert, identifying content briefs with missing source material, finding inconsistent campaign naming, or preparing a proposed JSON-LD correction for validation and human review.

    Write a short job card for the workflow:

    • Trigger: State what starts the run, such as a scheduled account check or an anomaly from an existing monitoring rule.
    • Question: Express the decision in one sentence. For example: “Has campaign delivery stopped during comparable business hours?”
    • Inputs: Name the approved systems, fields, reporting windows, business rules, and account notes.
    • Output: Define the required finding, supporting evidence, uncertainty, and proposed next step.
    • Prohibited behavior: State what the agent must not infer, retrieve, publish, send, or change.
    • Escalation: List the conditions that require abstention or human judgment.
    • Reviewer: Assign a role or person responsible for accepting consequential recommendations.
    • Success and failure: Describe both a useful result and an unsafe result. A fluent explanation without adequate evidence belongs in the failure column.

    Pay special attention to time. Marketing data often arrives on different schedules, so “recent” does not necessarily mean “complete.” A production ad-management agent once interpreted conversions that had not arrived yet as a severe performance decline. Making its analysis dependable required safe comparison windows, conversion-maturity rules, uncertainty ranges, and refusal when the lag could not be modeled reliably.

    Apply that lesson beyond paid media. A CRM agent should not label a campaign unproductive before the normal sales cycle has elapsed. A content agent should not declare a page unsuccessful before the chosen reporting period is complete. An SEO agent should not turn a partial crawl or delayed analytics import into a confident diagnosis. Freshness and maturity are different properties, and the agent needs rules for both.

    Refusal is not a defect when the evidence is immature, contradictory, or missing. A trustworthy response may be: “I cannot distinguish a real decline from reporting delay with the approved data.” That is more useful than an elaborate guess because it tells the operator what information is needed next.

    Give the agent a data contract and a business context pack

    Connecting an agent to more systems does not automatically make it better informed. It can instead create several conflicting versions of revenue, conversion, customer status, or campaign ownership. The agent will still produce coherent prose even when the underlying records disagree.

    A data contract tells the agent what it may use and how each input should be interpreted. Create one before refining the prompt. For every permitted input, record:

    • The system and field that hold the data.
    • The business owner responsible for its meaning and quality.
    • Whether it is the authoritative value or a convenience copy.
    • How frequently it updates and when it becomes mature enough for judgment.
    • The unit, attribution rule, time zone, status definition, and other interpretation rules.
    • Known gaps, exclusions, and failure signals.
    • What the agent must do when the input is absent, stale, or inconsistent.
    • Whether the field contains personal, confidential, regulated, or otherwise restricted information.

    Then create a separate context pack for facts that do not live cleanly in reporting tables. Include the products the business actually sells, excluded services, target locations, budget constraints, active promotions, sales-cycle expectations, conversion-lag patterns, campaign goals, approved claims, brand restrictions, and known tracking limitations. Without this context, an agent can correctly calculate the numbers and still reach the wrong business conclusion. A paid-media agent, for example, cannot identify an irrelevant pet-insurance keyword for a business-insurance advertiser unless it knows what the business sells and can access the operational context used by human analysts.

    Keep the context pack owned and maintainable. Each rule should have an owner, a status, and a replacement path when the business changes. Otherwise an old promotion, discontinued service, or superseded approval rule can remain active inside the agent long after people have moved on.

    Use least-privilege access. If the task requires campaign totals, do not expose raw customer records. If the agent only prepares a content update, give it draft access rather than publishing rights. If it reads a CRM status, restrict it to the approved fields rather than the full contact object. Governed implementations can limit access to approved data, mask immature conversion information, and require evidence for recommendations.

    Trace where the data goes as well as what the agent can retrieve. Before customer, prospect, health, or financial information reaches a third-party AI service, determine where it is processed, what the provider may retain or reuse, and which internal policy governs that transfer. Marketing data deserves the same boundary-setting applied to other sensitive operational systems; convenient access is not the same as necessary access.

    If the team cannot identify the owner or meaning of an important field, stop at read-only experimentation. A better prompt cannot resolve a disputed definition of revenue, repair missing conversion data, or decide which system is authoritative.

    Set autonomy by consequence and reversibility

    An AI device faces three increasingly restricted action zones, from reversible draft tasks to guarded campaign controls and a locked high-consequence mechanism.

    Teams often treat autonomy as a switch: either the agent acts or a person does. A safer design separates observation, recommendation, preparation, and execution. The agent can then earn broader permissions without receiving blanket authority.

    Operating levelMarketing exampleDefault permissionRelease condition
    ObserveCheck reporting data and surface a possible anomalyRead approved fields; create an internal recordFreshness checks pass and evidence is attached
    RecommendExplain a performance change or propose a content correctionNo external changeAssumptions, uncertainty, affected assets, and reviewer are explicit
    PrepareBuild a draft ad, email, brief, metadata edit, or schema patchWrite only to a draft or sandboxValidation passes and a named person approves publication
    ActPause a campaign, move budget, publish content, change pricing, or send a messageOff by defaultThe action is narrowly pre-approved, policy-compliant, observable, and safely reversible; otherwise human approval remains mandatory

    Two variables should control the level: consequence and reversibility. A duplicate internal alert is annoying but recoverable. An incorrect customer email, pricing change, destructive CRM update, or large budget movement can create brand, financial, privacy, or legal exposure. Work carrying that weight needs a human checkpoint; letting an unreviewed agent send customer communications or make consequential commercial decisions is not an acceptable starting posture.

    For high-impact recommendations, add an independent check before the decision reaches the approver. That check should evaluate the evidence and policy conditions, not merely ask another model whether the prose sounds convincing. It can verify that the reporting window is mature, the cited records exist, the requested action is permitted, and contradictory data has been surfaced. Higher-stakes analysis benefits from a separate review path before a person is asked to act.

    Require an evidence packet for every recommendation. It should contain:

    • The conclusion in plain language.
    • The period, comparison, account, page, campaign, or record under review.
    • The approved inputs actually used.
    • Missing, stale, masked, or contradictory inputs.
    • Assumptions and relevant business rules.
    • The agent’s uncertainty or reason for abstaining.
    • The proposed action and assets it would affect.
    • The required approval and available rollback path.

    Do not allow the agent to hide uncertainty inside polished prose. Evidence must be inspectable by the person making the decision. If a recommendation cannot be traced back to permitted inputs, it should fail the release gate regardless of how reasonable it sounds.

    Release, monitor, and stop the agent like production software

    Human operators monitor an AI agent moving from testing through a gated deployment lane, with health sensors, an evidence trail, an emergency stop, and a rollback track.

    Test safe behavior, not just good answers

    A handful of impressive demo prompts proves very little. Build an evaluation set from the situations the agent will face after release: routine work, different ways users phrase the same request, incomplete data, delayed conversions, stale account notes, conflicting systems, out-of-scope requests, and cases where the correct response is escalation.

    For each case, define the expected behavior rather than one perfect paragraph. Should the agent answer, flag uncertainty, request information, refuse, or escalate? Which evidence must appear? Which tools may it call? Which actions must remain blocked? This makes the evaluation durable even when wording varies.

    Add simple pass-or-fail checks around important invariants:

    • A read-only agent cannot invoke a write operation.
    • A draft-only content agent cannot publish.
    • Restricted fields never appear in retrieved context or output.
    • A performance judgment cannot use a reporting window marked immature.
    • A recommendation cannot pass without evidence identifiers and required assumptions.
    • A missing authoritative input triggers the prescribed abstention or escalation.
    • An action outside the job card is rejected even when a user asks persuasively.

    Run the agent in shadow mode before granting action rights. Let it inspect real work and produce results without changing external systems. Compare its findings with the decisions made through the existing process, examine both disagreements and omissions, and update the job card, data contract, context pack, and evaluation set. Only then consider expanding its operating level.

    Version every component that can change behavior

    The prompt is not the whole agent. Store the system instructions, policy rules, model identifier, provider settings, tool definitions, data-field mappings, business definitions, context-pack version, evaluation results, approval decision, and release date as one traceable configuration.

    This matters because behavior can drift even when your team changes nothing visible. A provider can update the model underneath a workflow, while a data field, tool response, or business rule can change independently. Unversioned models and prompts make it difficult to explain why customer-facing behavior changed or recreate how the system acted earlier. Marketing teams need release discipline and behavior monitoring around model and prompt changes, just as they do around application changes.

    Rerun the relevant evaluations whenever any behavioral component changes. If the provider does not expose a fixed model version, record the identifier it does provide and use recurring evaluation results to detect observed changes. Do not assume unchanged prompts guarantee unchanged behavior.

    Monitor usefulness, silence, and operator burden

    Accuracy on answered cases is not enough. Monitor unsupported conclusions, inappropriate certainty, policy violations, reviewer overrides, action reversals, duplicate alerts, unnecessary escalations, and cases where a reviewer had to retrieve evidence the agent should have supplied.

    Review non-alerts as well as alerts. An agent can look quiet because nothing is wrong, because its thresholds are sensible, or because it missed the problem. Sample runs where it concluded that no action was needed and verify that the underlying data supports that silence.

    Noise is an operational failure. If people repeatedly dismiss duplicate, untimely, or low-value alerts, they will stop treating the agent as a useful colleague. A working ad-management agent had to remove duplicate notifications and messages that could wait because convincing the team to pay attention depended on reducing noise as well as improving analysis.

    Give operators a visible stop path. When the agent behaves unexpectedly, they should be able to pause scheduled runs, revoke write credentials, preserve the decision trace, identify the changed component, rerun evaluations, and restore a known configuration. Re-enable a smaller scope before returning full permissions.

    Rollback has limits. You can restore a campaign setting or draft, but you cannot make a sent email unread or erase a public impression of an incorrect claim. Keep human approval in front of actions whose consequences cannot be meaningfully reversed.

    Key takeaways

    • Trust is a property of the whole workflow: data, context, permissions, evidence, review, monitoring, and recovery.
    • Start with a bounded, read-only decision whose correct inputs and safe output can be described precisely.
    • Treat data freshness, data maturity, and business meaning as separate requirements.
    • Grant the minimum fields and tools needed for the job; broad access is not a substitute for context.
    • Increase autonomy according to consequence and reversibility, not model fluency.
    • Make abstention, escalation, and evidence-bearing recommendations part of the success criteria.
    • Version every component that can change behavior, then retest and monitor real-world use.

    Pick the smallest marketing decision that currently consumes repeated human attention. Write its job card and data contract before connecting an agent. If you cannot define the evidence, permissions, reviewer, and stop path, the workflow is not ready for autonomy. If you can, you have a foundation that can earn broader responsibility instead of merely requesting trust.

    References