Tag: AI Strategy

  • Enterprise AI Automation: A Practical Path to Production

    Enterprise AI Automation: A Practical Path to Production

    Your AI pilot probably does not need a smarter demo. It needs an accountable owner, a credible baseline, reliable data, permission boundaries, an escalation path, and a clear reason to exist after the demonstration ends.

    That is where many enterprise programs stall. In adoption data compiled through May 14, 2026, enterprises led at 25% adoption, but adoption covered everything from an initial trial to full-scale implementation. Among enterprise adopters, 62% remained in experimentation and only 13% had reached full deployment. If you are responsible for moving AI automation into production, the job is not to collect more use cases. It is to turn a carefully chosen workflow into a controlled, measurable operating process.

    Key takeaways

    • Fund a defined workflow with a business owner, not a broad AI capability looking for a problem.
    • Record the current cost, delay, error rate, conversion rate, or customer outcome before changing the process.
    • Favor workflows with stable triggers, accessible data, verifiable completion, bounded exceptions, and reversible actions.
    • Treat the model as one component. Production also requires permissions, deterministic rules, evaluations, monitoring, audit logs, human escalation, and rollback.
    • Set stage-gate criteria and stop conditions before the pilot begins. A project that cannot prove value should end without becoming permanent experimental infrastructure.

    Choose the first workflow by value and controllability
    Two operations leaders examine one illuminated, guardrailed process lane within a larger floor of branching workflows.

    Start below the level of a department. Customer service transformation is too broad. Qualifying an after-hours inquiry, answering approved questions, and offering an available appointment is a workflow. Supply chain optimization is too broad. Detecting a delayed shipment, checking an approved set of alternatives, and preparing a resolution for review is a workflow.

    This distinction matters because ordinary automation and agentic AI solve different parts of the process. A conventional automation follows predefined rules. Generative AI produces an output such as a summary or draft. An agentic system can plan, decide, and execute a multi-step task from beginning to end. More autonomy creates more ways to complete useful work, but it also expands the number of decisions, integrations, and failure modes you must control.

    A strong initial candidate has the following properties:

    • A visible operational leak: Work is being delayed, repeated, missed, or handled at an unnecessarily high cost.
    • A stable trigger: The workflow starts from a recognizable event such as an inbound request, completed meeting, status change, or new record.
    • Accessible inputs: The required data can be retrieved with appropriate permissions and has meanings the operating team agrees on.
    • A verifiable finish: You can tell whether the appointment was booked, case was resolved, package was sent, record was updated, or decision reached the right person.
    • Bounded exceptions: Unusual cases can be recognized and routed to a person instead of forcing the system to improvise.
    • Manageable consequences: A wrong draft can be reviewed or discarded. An unauthorized payment, deletion, price change, or legal commitment is much harder to reverse.
    • Enough recurring demand: The workflow occurs often enough for reduced handling time, faster response, or higher completion to matter.

    Score candidate workflows as high, medium, or low on each property. Do not average away a fatal weakness. Low data access, an undefined finish, or an unbounded consequence should block the candidate until the underlying process is redesigned.

    Structured processes tend to move first. Customer service and supply chain coordination show stronger agentic AI adoption, while finance faces more regulatory scrutiny. The practical lesson is not that every enterprise should begin in customer service. It is that repeatable inputs, explicit policies, and observable outcomes make automation easier to validate.

    A useful workflow can also be unglamorous. One documented PR automation locates a completed Zoom recording, creates a transcript, and prepares an email containing both for the journalist. It saves about 30 minutes per interview while shortening the handoff. The value comes from removing a specific delay, not from inventing a new communications platform.

    Apply the same discipline to the build-versus-buy decision. Existing software should handle commodity functions such as scheduling, transcription, telephony, CRM records, and routine orchestration when it meets your requirements. Custom development is easier to justify when the workflow depends on a proprietary process, distinctive formula, or exclusive data that is central to the business. Otherwise, concentrate engineering effort on integration, policy, evaluation, and observability rather than recreating a mature product category.

    Make the pilot prove a business case it cannot game

    Before selecting a model or vendor, write a testable operating hypothesis:

    By automating these defined steps for these eligible cases, we expect this business metric to move from its recorded baseline to an approved target, without worsening these guardrails, as measured in this system over this evaluation window.

    If the team cannot fill in each part, it is not ready to approve the pilot. A goal such as improve productivity leaves too much room to declare success after the fact. Reduce median handling time for eligible requests while maintaining resolution quality and escalation compliance can be measured.

    The measurement plan should separate five kinds of evidence:

    • Business outcome: Completed bookings, qualified opportunities, resolved cases, accepted deliverables, cycle time, recovered demand, or another result the operating owner already values.
    • Guardrail: Error severity, complaint rate, rework, policy violations, inappropriate messages, missed escalations, or another consequence that must not deteriorate.
    • Coverage: The share of incoming work that is actually eligible and processed. A system can perform well on a narrow subset without materially changing the operation.
    • Technical diagnostic: Extraction quality, classification quality, tool-call success, retrieval failures, latency, retries, and exception frequency. These explain performance but do not replace a business result.
    • Economics: Software, model usage, integration, monitoring, review labor, incident handling, and ongoing process ownership.

    Measure the baseline before the team sees pilot results. Otherwise, definitions tend to drift toward whatever the system can demonstrate. Specify which cases qualify, which are excluded, where each metric comes from, and who resolves disputed labels. When feasible, compare pilot cases with equivalent manually handled cases rather than assuming every change came from the automation.

    Do not count outputs as outcomes. Drafts generated, conversations handled, or tasks attempted are activity measures. They matter only when the workflow reaches a valid completion or produces verified capacity that the business can use. Time saved is not automatically a cash saving, either. State whether the capacity will absorb growth, reduce a queue, improve service, avoid new hiring, or be reassigned to higher-value work.

    Revenue automations need an additional capacity check. AI can help build targeted prospect lists, accelerate qualification, recover missed calls, and respond outside staffed hours, but increased demand can damage the customer experience when the business cannot fulfill it reliably. Map the next handoff before accelerating the top of the funnel. A faster response is not valuable if it creates an unstaffed queue downstream.

    Finally, define the stop rule while expectations are still neutral. Stop, narrow, or redesign the pilot if it cannot move the primary outcome, breaches an approved guardrail, depends on unsustainable review labor, or lacks a credible path to production economics. Unclear success criteria and weak data are recurring reasons AI projects fail to progress, while cost pressure is particularly important for smaller organizations. An enterprise budget may delay that reckoning, but it does not remove it.

    Build the operating system around the model
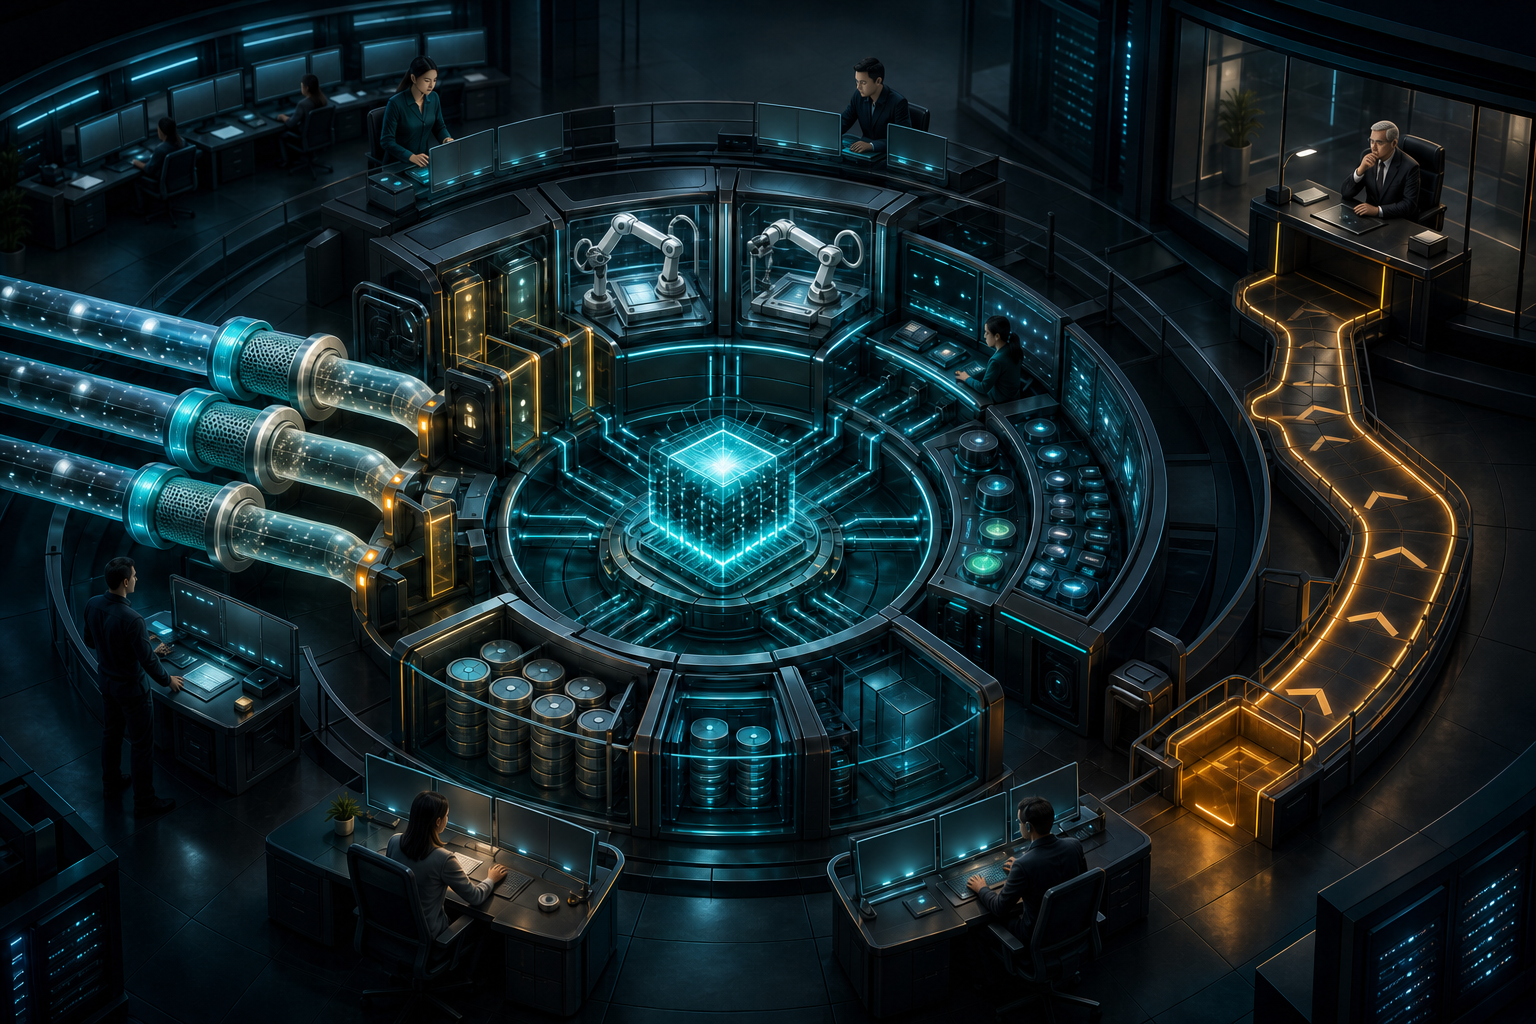
    A central AI computing unit is surrounded by data filters, permission gates, test chambers, monitoring equipment, audit storage, and human review stations.

    Separate deterministic rules from model judgment

    Map the workflow from trigger to completion before deciding what the model should do. For every step, record the input, rule or judgment, system of record, permitted action, expected output, exception path, and owner.

    Use ordinary code or workflow rules where the answer is deterministic. Required fields, account permissions, arithmetic, approved status transitions, duplicate checks, and routing tables should not become probabilistic merely because a language model is available. Use AI where interpretation is genuinely required, such as extracting intent from a message, summarizing an interaction, comparing unstructured evidence, or preparing a response under policy constraints.

    This separation makes failures easier to locate. It also reduces the chance that a persuasive output will bypass a rule the business intended to enforce.

    Increase authority only after the evidence supports it

    Autonomy should be an explicit permission level, not an accidental property of an integration. A practical authority ladder is:

    1. Read and recommend: The system analyzes data but cannot change a record or communicate externally.
    2. Prepare a draft: It creates a message, decision, or action package for a person to review.
    3. Execute after approval: A named reviewer authorizes the action with the relevant evidence visible.
    4. Execute within narrow limits: The system acts only for approved case types, values, destinations, and tools; exceptions are escalated.
    5. Execute the bounded workflow: The system completes eligible work autonomously while monitoring, audit, and shutdown controls remain active.

    Start at the lowest level that can test the business hypothesis. Advance only when the prior level meets predeclared quality and guardrail requirements. Full deployment does not require maximum autonomy. A stable draft-and-approval system can be the right production design when the action carries legal, financial, employment, security, reputational, or regulatory consequences.

    Use least-privilege credentials and separate test access from production access. Restrict the agent to the systems, records, fields, and actions required for the approved workflow. Payments, deletions, contractual commitments, price changes, sensitive employee decisions, and regulated communications should not become autonomous merely to remove a review step. If the business later approves that authority, it needs risk-specific testing, monitoring, and recovery controls.

    Make every handoff observable and recoverable

    A production trace should let an operator reconstruct what happened without relying on the model to explain itself. Capture the case identifier, input snapshot, relevant data version, workflow and prompt version, model and tool calls, retrieved evidence, proposed action, approval or override, external write, error, retry, elapsed time, unit cost, and final business outcome.

    Design retries so they do not duplicate a booking, order, message, refund, or record. Provide a clear shutdown control, queue failed work for recovery, and document how the operating team restores the last valid state. Alerts should identify an actionable condition and its owner; a dashboard that merely shows activity will not shorten an incident.

    Data readiness should be scoped to the workflow. You do not need to repair every enterprise dataset before beginning, but you do need a reliable contract for the fields this automation uses: canonical definitions, stable identifiers, permitted sources, freshness expectations, missing-value behavior, conflict resolution, and write-back ownership. Poor-quality and inconsistent data are common barriers to successful agent deployment. Giving an agent access to more systems does not solve disagreement between those systems.

    Build an evaluation set from representative normal cases, boundary cases, known exceptions, and costly failure modes. For each case, define an acceptable result, required escalation, and prohibited action. Run it before live access, compare the system with the existing process in shadow mode, and retain it as a regression suite whenever the prompt, model, tools, policy, or data mapping changes. Production monitoring then checks whether real traffic is drifting beyond what the evaluation set covered.

    Use stage gates to escape permanent pilot mode

    The large gap between experimentation and full deployment is a governance problem as much as a technical one. Teams can keep improving a demonstration indefinitely when nobody has defined the evidence required for the next decision. Gartner has projected that around 40% of agentic AI projects could be canceled by 2027. Cancellation is not necessarily the wrong outcome; discovering weak value or uncontrolled risk early is cheaper than scaling it.

    GateEvidence requiredDecision
    Workflow approvalNamed owner, process map, baseline, eligible cases, business hypothesis, risks, and stop ruleApprove a bounded test, redesign the workflow, or reject the use case
    Offline validationData contract, representative evaluation set, expected results, prohibited actions, permission design, and cost modelMove to shadow operation only if declared quality and safety requirements are met
    Shadow operationComparison with the existing process, exception analysis, reviewer feedback, diagnostic logs, and revised operating proceduresEnter limited production, narrow the scope, or return to offline work
    Limited productionVerified business outcome, guardrail performance, coverage, review burden, incident response, rollback, and actual unit costScale, maintain the bounded scope, redesign, or stop
    Operational scaleAccountable service owner, support model, change control, recurring evaluation, capacity plan, security review, and portfolio fundingExpand only while value and controls remain intact

    Set the thresholds for these gates according to the consequence of failure, and approve them before results arrive. A drafting assistant and a payment agent should not share the same tolerance. The important discipline is that the team cannot redefine success after seeing the output.

    At portfolio level, centralize the controls that should be consistent and decentralize ownership of the business outcome. A central AI function can provide identity, approved integrations, logging, evaluation tooling, security patterns, vendor review, and incident standards. The operating team should still own the process, metric, exceptions, staffing impact, and customer consequence. If ownership remains with an innovation lab after launch, the automation has not truly entered the business.

    Maintain a register of active automations showing the workflow owner, systems touched, data classification, permitted actions, risk level, deployment stage, model and vendor dependencies, current economics, and next gate. Use it to find duplicate experiments, unsupported integrations, and pilots that consume resources without approaching a decision.

    Before the next platform purchase, choose a specific queue or handoff that is already causing measurable loss. Name its owner, baseline, eligible cases, prohibited actions, escalation path, and stop rule. If those items cannot be written clearly, more AI will not make the process ready. If they can, you have the beginning of an automation that can earn its way into production.
    References

  • How to Choose an Industry-Specific GEO Agency in 2026

    How to Choose an Industry-Specific GEO Agency in 2026

    You have a shortlist of GEO agencies, and every one claims to understand your industry. The hard part is deciding whether that specialization will change the work or merely decorate the proposal.

    Even bounded 2026 evaluations considered 68 environmental agencies, 42 hospitality agencies, and 38 entertainment agencies. Those counts are not a census of the market, but they make the procurement problem clear: an industry label is a weak filter. You need evidence that the agency understands your customers’ questions, your entities, your acceptable claims, and the business outcome behind AI visibility.

    Key takeaways

    • Industry specialization should change the agency’s query map, evidence requirements, entity strategy, content plan, and measurement model.
    • Ask for reproducible AI visibility evidence: the prompts, engines, outputs, cited URLs, recording conditions, and examples where the brand was absent.
    • Build your own evaluation scorecard. Environmental, hospitality, and entertainment evaluations assign different importance to specialization, leadership, reviews, client history, and media authority.
    • Treat structured data as supporting infrastructure. JSON-LD can clarify entities and relationships, but it cannot compensate for weak claims, missing evidence, or undifferentiated content.
    • Use a fixed-scope pilot with written acceptance criteria before committing to a broad retainer.

    Specialization begins with the industry’s decision process

    A specialist should be able to explain how people evaluate your category before discussing content volume. That explanation should identify the questions that lead to a shortlist, the facts needed to answer them, the entities involved, and the sources an AI system may encounter while forming an answer.

    The required knowledge changes materially by sector. The environmental category covers renewable energy firms, waste management facilities, and conservation nonprofits. Hospitality includes hotels, resorts, vacation rentals, hospitality groups, and travel brands. Entertainment spans venues, streaming platforms, production companies, festivals, and music labels. An agency that uses one generic playbook across those business models is selling a production method, not industry expertise.

    IndustryWhat the agency must modelProof to request
    EnvironmentalTechnical offerings, commercial buyers, public-interest questions, project evidence, and the distinctions among companies and nonprofitsA question map separated by organization type, audience, and decision stage, with the evidence required for each answer
    HospitalityProperties, brands, destinations, amenities, traveler intent, and the path from discovery to bookingA prompt map by traveler need and property type, plus an audit of property and brand entities across owned pages
    EntertainmentTitles, talent, venues, events, releases, distribution channels, reputation, and time-sensitive informationA content and authority plan tied to the actual titles, people, venues, events, or services the business needs audiences to discover

    Prepare a fit brief before speaking with an agency. State the commercial decisions you want to influence, the audiences making them, the entities that must be understood, the geographic or market boundaries, the claims you can substantiate, and the action that counts as business value. A specialist should refine that brief. If the proposal could be sent unchanged to a company in an adjacent sector, the claimed specialization has not affected the strategy.

    Score evidence, not the word “specialist”

    A strategy director examines case-study materials, entity tokens, source documents, a claim shield, and a customer decision path beside an empty presentation box.

    There is no universal agency-ranking formula. Environmental evaluations gave AI visibility a 25% weight and leadership experience 20%. Hospitality evaluations weighted AI visibility at 25%, industry specialization at 20%, notable clients at 15%, and GEO expertise at 15%. Entertainment evaluations placed 25% on leadership experience, 25% on reviews, 20% on founder involvement, 10% each on notable clients and media references, and 5% each on longevity and specialty.

    That variation matters. It means you should not borrow a published rank as your buying decision. Use it to find candidates, then score each candidate against your own constraint. Mark every area as Pass, Partial, or Fail and attach the evidence behind the mark.

    • Industry model: Can the team describe your buyers, entities, terminology, evidence standards, and decision journey without relying on your explanation? Ask it to map one commercially important question from initial prompt to final action.
    • AI visibility evidence: Request the prompt set, engine, captured response, cited URLs, brand treatment, recording date, and testing conditions. A favorable screenshot without the prompt and method is not an auditable result.
    • Sector work: A client logo proves a commercial relationship, not the quality or relevance of the work. Ask for a redacted artifact such as a query map, entity audit, citation analysis, content brief, or performance report from a comparable engagement.
    • Strategy-mechanism fit: Determine whether your bottleneck calls for content, technical cleanup, entity clarification, digital PR, reputation work, measurement, or a coordinated mix. The agency should diagnose the bottleneck before prescribing deliverables.
    • Measurement: Ask how the team distinguishes appearance in an AI response from a useful business outcome. The answer should cover visibility and citations as well as the downstream event that matters to you, such as an inquiry, booking, ticket sale, application, or qualified visit.
    • Delivery ownership: Find out who performs the analysis, who approves recommendations, and who joins reporting calls. Leadership credentials matter only if that expertise reaches your account.
    • Operating fit: Reviews, communication, onboarding, access requirements, and reporting quality affect whether the strategy can be implemented. Ask what the agency needs from your subject-matter experts, developers, communications team, and analytics owner before signing.

    Founder involvement can be useful, but it is not a substitute for a documented process. Likewise, a large number of media references may indicate authority, but it does not prove that the assigned team can diagnose your site or measure your priority outcomes. Score the evidence that will affect delivery, not the prestige of the label attached to it.

    Demand a GEO operating system, not a content package

    GEO does not produce a permanent position that an agency can own. AI answers can change with the engine, prompt wording, context, and available information. Your program therefore needs a repeatable process for observing answers, improving the underlying evidence, and checking what changed.

    The monitored engine set should reflect where your audience asks questions. Sector evaluations already examine visibility across ChatGPT, Perplexity, and Google Gemini, while hospitality work also includes Claude. Including every platform is not automatically better. The agency should explain why each platform belongs in your measurement plan and keep the testing method consistent enough to interpret the observations.

    1. Map decisions to questions. Begin with questions that precede a real choice: identifying options, checking suitability, comparing alternatives, resolving objections, and deciding what to do next.
    2. Establish the baseline. Record the prompt, engine, response, cited pages, brand inclusion or omission, competitors mentioned, and the language used to represent each entity.
    3. Audit the evidence layer. For each important answer, identify the factual claims you can support, where those facts live, whether the pages are accessible, and which claims lack a credible owned or independent source.
    4. Repair the entity and content layer. Improve the pages that define the organization, offerings, people, places, products, events, or other relevant entities. Resolve contradictions before expanding content.
    5. Build authority where the gap requires it. Some problems call for stronger third-party coverage or clearer brand representation, not another page targeting a variation of the same query.
    6. Measure visibility and consequence separately. Track whether the brand appears and receives citations, then connect that observation to qualified traffic and the commercial event named in your fit brief.

    One documented entertainment approach connects AI citations with ticket sales and customer acquisition costs. That is a useful model for procurement even when your outcome differs: visibility belongs in the report, but it should not be mistaken for the final result.

    Structured data belongs inside this operating system, not above it. Ask the agency which entity or relationship each schema property clarifies, which visible page statement supports it, and how it will be validated after deployment. Reject a schema-only plan that leaves thin content, contradictory facts, poor internal linking, or weak external authority untouched. Markup can make existing meaning easier to interpret; it cannot manufacture evidence.

    You should also expect different agency models. Entertainment specialists in 2026 ranged across GEO content strategy, multi-channel marketing, budget-conscious execution, analytics-led tracking, and PR-integrated GEO. None of those models is inherently right for every business. Choose the one that matches the bottleneck identified in your baseline.

    Use a fixed-scope pilot before a broad retainer

    A client and agency team observes a compact test chamber that moves source blocks through connected research, review, monitoring, and measurement modules before wider lanes are activated.

    A pilot should test the agency’s reasoning and operating discipline, not ask it to promise a ranking. Give every finalist the same fit brief and require written answers to the same procurement questions.

    1. Which customer decisions and prompt patterns would you prioritize for our business, and why do they matter commercially?
    2. How will you establish an observable baseline across the engines that matter to our audience?
    3. Which parts of the plan depend on owned content, technical changes, structured data, independent authority, digital PR, or reputation work?
    4. What facts and access do you need from our subject-matter experts, analytics owner, communications team, and developers?
    5. Who will perform each part of the work, and where will senior sector or GEO expertise enter the process?
    6. How will reporting separate captured AI outputs from interpretation, recommendations, and downstream business results?
    7. Which work products, prompt records, datasets, briefs, and account access will we retain if the engagement ends?

    Write the acceptance test into the pilot scope. The baseline should be reproducible from the recorded method. The priority questions should correspond to real customer decisions. Recommendations should identify the evidence behind each proposed claim. Every implementation item should have an owner. Reporting should distinguish visibility observations from business impact. The pilot can pass those tests even before meaningful visibility changes appear; its immediate purpose is to prove that the agency has built a credible system for producing and evaluating change.

    Several warning signs should stop the process before a long contract creates avoidable cost:

    • A guarantee that your brand will hold a particular position in an AI answer
    • A visibility claim supported only by selected screenshots
    • A generic sector case study with no inspectable artifact or method
    • A proposal measured mainly by content volume
    • A schema-only prescription offered before an entity, content, and evidence audit
    • No named delivery owner or no explanation of when senior experts participate
    • A broad retainer proposed before the agency has defined your query universe and baseline

    Your next move is simple: send the same written fit brief to every finalist and compare the mechanisms they propose. Choose the agency that can show why your industry’s questions, evidence, entities, and outcomes require a distinct plan. If nobody can do that, narrow the pilot rather than expanding the commitment.

    References

  • Professional vs. Consumer AI Adoption: What Marketers Should Do

    Professional vs. Consumer AI Adoption: What Marketers Should Do

    If AI seems unavoidable in your professional feed, it is easy to assume your customers have already moved their discovery and buying journeys into ChatGPT, Claude, or Gemini. That assumption can send budget toward the loudest channel rather than the audience you actually serve.

    The useful question is not whether AI is popular. It is which audience uses which assistant for which job, and whether that behavior affects discovery, evaluation, or purchase. Once you separate those questions, you can make a defensible AI search plan instead of reacting to general enthusiasm.

    Professional and consumer adoption are moving on different curves

    Broad reach and segment-level growth can move in opposite directions. At its measured high point, OpenAI or ChatGPT reached 37% of U.S. desktop users in September 2025, then slipped to 34% by March. That is a reach signal within a specific geography and device class. It does not mean 34% used the tool daily, preferred it over every alternative, or relied on it during a purchase.

    The professional pattern looks different. Claude usage among B2B professionals was 373% higher than the U.S. average, while Claude and Gemini continued to gain users as ChatGPT’s desktop growth slowed. The 373% figure describes relative overrepresentation. It is not a market-share percentage, and it does not prove that most professionals use Claude.

    Retail-shopping audiences provide the counterweight. People in that audience were 15% less likely to use ChatGPT than a typical U.S. consumer, and Claude did not rank among their top four AI tools. An AI-heavy professional network can therefore give you a distorted baseline for consumer behavior.

    This is not a clean split between people who use AI and people who do not. The same person can be a heavy assistant user at work and follow a conventional search, marketplace, or retailer journey when shopping. Adoption depends on context, task, and perceived value, not just demographics.

    Key takeaways

    • Do not apply one AI adoption rate to professional and consumer audiences.
    • Separate assistant reach, frequency of use, task relevance, brand visibility, and commercial impact. They are different measurements.
    • If you market to B2B professionals, include Claude alongside ChatGPT and Gemini in your visibility testing.
    • If you market to retail shoppers, keep search, category, product, marketplace, and on-site discovery paths strong while you test AI as an additional layer.
    • Increase investment only when audience use and a relevant business outcome appear in the same segment.

    Map adoption by audience and task before assigning budget

    A marketing team arranges audience, device, search, shopping, document, and AI symbols on an unlabeled strategy table connected by illuminated routes.

    A market-wide AI number cannot tell you where to publish, what to optimize, or which assistant deserves attention. Build an audience-by-task map instead. It should distinguish what has been observed from what still needs to be tested.

    AudienceObserved signalWhat it does not establishPlanning response
    Broad U.S. desktop usersOpenAI or ChatGPT moved from 37% reach in September 2025 to 34% by MarchFrequency, task, loyalty, mobile behavior, or purchase influenceMaintain a baseline presence, but do not forecast automatic growth from general awareness
    B2B professionalsClaude usage was 373% higher than the U.S. averageWhich roles, industries, or work tasks produced the differenceAdd Claude to role-specific discovery and evaluation tests
    Retail-shopping consumersChatGPT usage was 15% lower than among typical U.S. consumers; Claude was outside the top four AI toolsWhether AI influences an earlier research step or a later purchase decisionPreserve conventional shopping journeys and test assistants selectively

    Build the map before choosing a platform

    1. Define audiences by commercial context. Separate professional users, procurement participants, existing customers, retail shoppers, and other materially different groups. Do not merge them merely because they can buy the same product.
    2. Name the task. Record whether the person is trying to understand a problem, compare options, verify a claim, troubleshoot, create work, find a seller, or complete a purchase. A tool can be strong for one job and irrelevant to the next.
    3. Collect audience-level evidence. Combine AI referral analytics with customer interviews, sales and support language, on-site search terms, and a direct attribution question. Ask which tool was used and what the person was trying to accomplish; a yes-or-no question about AI is too broad.
    4. Label your confidence. Mark each audience-task-tool combination as observed, indicated, or unknown. A visible market trend can justify a test, but it should not be relabeled as proof about your customers.
    5. Assign an action. Scale combinations supported by audience and outcome evidence, test combinations with a plausible signal, and monitor combinations supported only by general market attention.

    The most common planning error is to start with a platform and look for reasons to fund it. Start with the audience and task instead. The platform should be the last column you fill in, not the first.

    Adjust SEO, AEO, and GEO priorities to match the pattern

    Adoption signals should change your priorities, not your technical standards. Pages still need to be crawlable, indexable, internally linked, consistent about named entities, and clear enough for a person to verify. Structured data must describe visible content accurately; it cannot compensate for a vague, unsupported, or inaccessible page.

    For professional audiences, optimize around decisions

    Where your audience resembles the measured B2B cohort, Claude belongs in the test set. That does not justify abandoning ChatGPT or Gemini. It means a ChatGPT-only visibility report can miss an assistant that is unusually prominent among professional users.

    • Give each important page a decision job. A page might explain compatibility, implementation requirements, operating constraints, use cases, or the difference between two approaches. Do not make one page answer every stage of the buying process.
    • Lead with a direct answer. Follow it with evidence, definitions, exceptions, and practical constraints. This gives human readers a fast answer while leaving enough context for an assistant to represent it accurately.
    • Keep entities unambiguous. Use consistent organization, product, feature, and category names in visible copy, titles, internal links, and applicable schema. If two names refer to the same thing, explain the relationship.
    • Test real professional questions. Run the questions your target roles ask through ChatGPT, Claude, and Gemini. Record whether your brand appears, whether the description is accurate, whether a citation is present, and which URL is surfaced.
    • Fix the underlying page before chasing mentions. If an assistant gives an incomplete answer, check whether your page actually states the missing fact clearly and supports it. Assistant-specific duplicate pages create more content to reconcile and can leave conflicting claims online.

    For consumer audiences, treat AI as an added path

    Lower ChatGPT incidence among retail shoppers and Claude’s absence from that audience’s top four do not make AI irrelevant. They do make an assistant-only discovery plan hard to defend. Keep the complete shopping journey usable without requiring an AI intermediary.

    • Protect category, product, marketplace, local, review, and on-site search paths that already help shoppers find and evaluate an offer.
    • Answer natural-language buying questions on the relevant category or product page instead of hiding useful details in promotional copy or disconnected FAQ pages.
    • Use applicable Product, Offer, or other structured data only when the corresponding information is visible, current, and internally consistent.
    • Test the assistants your audience actually mentions or sends traffic from. Do not give every platform equal budget merely because each one is growing somewhere.
    • Treat AI visibility as a supporting indicator until you can connect it to product discovery, qualified visits, assisted conversions, or purchases for that consumer segment.

    The useful distinction is not B2B equals AI and B2C equals conventional search. It is that professional adoption currently provides a stronger reason to test multiple assistants aggressively, while consumer planning needs more segment-specific proof before AI becomes the primary route.

    Measure adoption separately from visibility and revenue

    An analyst examines three separate transparent instruments containing usage tokens, discovery symbols, and purchase symbols connected by narrow pipes and valves.

    A single AI traffic chart cannot tell you whether customers are adopting assistants, whether assistants know your brand, or whether visibility changes business results. Track those questions in separate layers.

    • Audience use: Ask which assistants people use, for what tasks, and at which point in the journey. Preserve an open-text option so your questionnaire does not force respondents into your platform assumptions.
    • Referral behavior: Break AI-referred sessions down by assistant, landing page, audience, and outcome. Treat this as a floor rather than a complete adoption count: copied answers and manually entered URLs will not preserve an AI referrer.
    • Answer visibility: Maintain a fixed set of audience-specific questions. For each check, record the assistant, date, answer, brand inclusion, factual accuracy, cited URLs, and competitors mentioned. Prompt tracking samples outputs; it does not measure how many customers saw them.
    • Commercial outcomes: Connect identifiable AI visits and self-reported AI use to qualified leads, sign-ups, assisted conversions, purchases, or the outcome your organization already values. Do not label correlation as causation when several channels touched the journey.
    • Technical access: Use server logs and crawl diagnostics to confirm whether relevant bots can reach important pages. Bot activity shows technical access or crawler interest, not human demand.

    Use a simple decision rule. Scale when a defined audience uses an assistant for a relevant task, your visibility has a fixable gap, and improvement is associated with a qualified outcome. Run a contained test when audience and task are supported but commercial impact remains uncertain. Keep monitoring lightweight when the only evidence is broad market enthusiasm.

    For your next planning cycle, choose one high-value professional segment and one important consumer segment. Build separate audience-task maps, test the assistants indicated for each, and move the next content investment only where audience, task, and outcome align.

    References

  • How to Measure Realistic AI Productivity Gains at Work

    How to Measure Realistic AI Productivity Gains at Work

    An AI demo can collapse a visible task into a few prompts and still tell you almost nothing about productivity. The business question is whether the full workflow produces more accepted work, at the same or better quality, without quietly transferring effort to reviewers, managers, or downstream teams.

    If you need to set an AI target, evaluate a pilot, or defend an investment, measure the gain from the workflow boundary to the accepted result. That turns a promising time-saving claim into a decision you can trust.

    Key takeaways

    • A realistic AI productivity gain is net of preparation, prompting, review, correction, coordination, and failed outputs.
    • Measure labor per accepted output, not just generation time or the number of drafts produced.
    • Every percentage needs a named denominator, workflow boundary, baseline, and quality standard.
    • Released time becomes useful capacity only when the team can redirect it, remove a bottleneck, improve quality, or shorten delivery time.
    • Keep task efficiency, workflow efficiency, throughput, cost, and business value as separate claims.

    The usable gain is smaller than the visible time saving

    AI usually changes where work happens. Drafting may become quicker while context preparation, fact-checking, editing, escalation, and approval take more effort. A 25% efficiency gain can still matter, but its meaning depends on what became more efficient and whether the saved capacity survives the rest of the workflow.

    Separate the layers before you attach a productivity label:

    • Model speed: how quickly the system returns an output. This affects waiting time, but it is not a measure of human productivity by itself.
    • Task time: the active labor required for a bounded activity such as drafting metadata, classifying queries, or generating a first version of JSON-LD.
    • Workflow labor: all human effort from the request entering the process to the output passing its normal acceptance gate.
    • Accepted throughput: the amount of usable work completed within a defined period, after quality control and rework.
    • Business capacity: the additional work, faster delivery, lower operating burden, or higher quality the organization can actually use.

    Report the lowest layer you have genuinely measured. If your test covers only first-draft production, call the result a change in drafting time. Do not call it a change in content-team productivity. If you timed schema generation but excluded validation, page matching, deployment, and post-deployment checks, you measured generation rather than implementation.

    Use explicit calculations so hidden labor cannot disappear inside a headline:

    • Gross task saving equals baseline operator time minus AI-assisted operator time.
    • Net workflow saving equals gross task saving minus new preparation, review, correction, escalation, and coordination time.
    • Acceptance rate equals outputs passing the normal quality gate without material correction divided by outputs submitted for review.
    • Labor per accepted output equals total human labor across the workflow divided by the number of outputs that passed.
    • Cost per accepted output includes human labor, tooling, implementation, and rework rather than the AI subscription alone.

    The denominator matters as much as the result. Labor time per accepted brief, cost per validated schema deployment, and published pages per editor-hour are defined measures. AI productivity is not. It might refer to time, volume, cost, quality, or revenue, and those measures do not move in equal proportions.

    Measure the workflow, not the impressive task

    Isometric illustration of one work item moving through preparation, AI assistance, review, revision, and final handoff.

    Start by drawing a boundary around a unit of work that has a recognizable finish. A generated asset is not finished merely because the model stopped responding. It is finished when the person or system that normally receives it would accept it.

    Define the workflow in this order:

    • Name the unit. Examples include an approved content brief, a published landing page, a validated schema deployment, or a completed technical recommendation.
    • Mark the start. Use an observable event such as a complete request entering the queue, not the moment an operator opens the AI tool.
    • Mark the finish. Tie completion to the existing acceptance or publication gate.
    • List every role that touches the unit, including reviewers and specialists who handle exceptions.
    • Separate active labor from elapsed time. Waiting for an approval is different from the labor required to perform that approval.
    • Define rejection, material rework, and minor correction before the pilot begins.

    For a content workflow, the boundary may include intake, research, briefing, drafting, factual review, search optimization, brand review, CMS entry, quality assurance, and publication. For structured data, it may include identifying the entity, selecting appropriate properties, grounding claims in page content, generating JSON-LD, validating syntax, checking vocabulary use, confirming consistency with the visible page, deploying, and monitoring.

    This map exposes displaced effort. If AI reduces drafting labor but creates an editing queue, the drafting task improved while the workflow bottleneck moved. If the approval stage already limits throughput, sending it more drafts can increase work in progress without increasing published output.

    Choose a pilot workflow with repeatable units, a stable quality gate, and enough ordinary volume to show variation. A one-off strategy project may be valuable, but it is a poor first benchmark because the work changes from case to case. Repeated briefs, metadata updates, query classification, internal-link candidates, schema drafts, and standardized audit checks are easier to compare without pretending every unit is identical.

    Run a quality-adjusted before-and-after test

    Overhead view of two matched work lanes being evaluated with input folders, completed outputs, review materials, and timers.

    A credible baseline comes from normal work completed before the AI-assisted process begins. Use a representative mix rather than selecting unusually easy or painful cases. Record complexity in advance so a change in task mix cannot masquerade as a productivity gain.

    Build the test around the following controls:

    • Use the same workflow boundary, output definition, and acceptance gate in the baseline and assisted conditions.
    • Keep task categories and complexity bands visible. Compare like with like before combining results.
    • Record active labor for preparation, prompting, reviewing, correcting, coordinating, and escalating.
    • Track elapsed lead time separately so a faster task is not confused with a faster delivery process.
    • Log whether each output passed on first submission, required minor edits, required material rework, or was rejected.
    • Record the tool, model, configuration, prompt or template version, and human role involved. A material process change creates a new test condition.
    • Separate rollout costs from ongoing operating costs. Training and workflow design matter to the investment decision even when they do not recur for every unit.

    Do not let faster production lower the acceptance standard. Define quality in terms the workflow already understands. For SEO and AI-optimized content, that may include factual accuracy, completeness, intent fit, source traceability, brand compliance, internal consistency, and technical correctness. For JSON-LD, a syntax pass is necessary but not sufficient; the markup must also describe the visible content accurately and use the intended vocabulary appropriately.

    Make rework categories operational. A minor correction is something the reviewer can fix without reconsidering the approach. Material rework changes the argument, evidence, structure, entity model, implementation choice, or substantial portions of the output. Write those definitions before reviewers see pilot results. Otherwise, enthusiasm for the tool can turn serious revisions into minor edits after the fact.

    Your measurement sheet should include the workflow, accepted unit, task category, complexity band, owner, baseline active labor, assisted active labor, preparation time, review time, correction time, escalation time, elapsed lead time, first-pass status, final acceptance status, error class, tooling cost, and workflow version. Keep the raw observations. A single average hides whether the result is reliable across routine and difficult work.

    Use the median to describe a typical case and show the spread or range to expose variability. Segment results when complex work behaves differently from routine work. An overall improvement can conceal a serious decline in the cases where accuracy matters most.

    Convert released time into capacity the organization can use

    Net time saved is an operational input, not automatically a business result. The next question is what happened to that time. If it remains scattered across tiny fragments, sits behind another bottleneck, or appears in a role with no additional demand, it may not create more output.

    Decide which outcome you are targeting before the rollout:

    • More accepted output with the existing team.
    • Shorter lead time for the same output volume.
    • Higher quality, deeper analysis, or broader coverage without extending delivery time.
    • Lower overtime, fewer backlogs, or more resilience during demand spikes.
    • Capacity redirected to work that had been deferred or neglected.
    • Lower cost per accepted output after tooling and operating costs are included.

    These outcomes are all legitimate, but they are not interchangeable. Reduced labor per unit does not prove payroll savings. Claim a cash saving only when paid hours, contractor spend, hiring requirements, or another real cost changes. Otherwise, describe the result as released capacity and identify where that capacity went.

    Apply a bottleneck test before forecasting additional throughput:

    • Was the improved stage actually limiting the workflow?
    • Can the next stage absorb more volume without adding a queue?
    • Is there enough demand for additional accepted output?
    • Does the saved time arrive in usable blocks that can be scheduled elsewhere?
    • Does the team have authority and a plan to reassign that capacity?
    • Will higher volume create new review, publishing, governance, or maintenance work?

    If the answer to those questions is no, do not discard the gain. Classify it correctly. It may reduce interruptions, create a buffer, shorten a stage, or make quality work possible. Those benefits can matter even when total output stays flat. What matters is reporting the observed outcome rather than converting every saved minute into hypothetical production.

    A defensible result can fit into a single reporting sentence: In the named workflow and task category, the AI-assisted process changed median active labor per accepted unit from the baseline to the measured assisted level after preparation, review, and rework; first-pass acceptance changed from the baseline rate to the assisted rate; the team redirected the resulting capacity to the stated use; and tooling plus rollout costs were recorded separately.

    Start with a single bounded workflow. Pull a representative batch of completed work, define its accepted unit, map every human touch, and capture the baseline before introducing AI. Then run the assisted process through the same gate. A modest gain that survives review and becomes usable capacity is worth more than a dramatic demo that disappears in production.

    References

  • Building an AI-Ready SEO and GEO Program That Performs

    Building an AI-Ready SEO and GEO Program That Performs

    Your team may already have an SEO roadmap, a schema backlog, a content calendar, and a dashboard that checks whether your brand appears in generated answers. That can still leave you without a program. The work sits in separate queues, each team reports a different success metric, and nobody has a clear rule for deciding what to improve next.

    An AI-ready SEO and GEO program connects those pieces. It starts with the questions your audience asks, maps them to accessible and trustworthy pages, makes the meaning of those pages explicit, measures visibility across search and answer engines, and ties the result to a business decision. Here is how to build that operating system without turning GEO into a disconnected collection of tools and speculative tactics.

    Build the business case before you build the tool stack

    Do not begin with a GEO platform, a schema type, or a list of prompts. Begin with the decision the program is supposed to improve. Otherwise, you can produce impressive-looking citation charts without knowing whether the cited answers concern commercially relevant questions, reach the right audience, or contribute to a useful action.

    Your first document should be a short program charter. It needs to answer six practical questions:

    • Who are you trying to reach? Name the audience, market, language, and buying situation. A broad label such as business users is not enough to guide content or measurement.
    • Which questions matter? Define the topic areas and decisions for which you want to be discoverable. Include informational questions, comparison questions, validation questions, and action-oriented questions where they are relevant.
    • What should visibility accomplish? Choose the business outcome: qualified reach, revenue, conversion, market entry, customer education, or lower operating cost.
    • Which signals will show progress? Separate leading indicators such as technical eligibility, answer inclusion, and citations from outcomes such as qualified visits and conversions.
    • What is outside the program? State the markets, products, page types, and answer engines that you are not evaluating. A boundary keeps a pilot from becoming an unmanageable sitewide audit.
    • Who can approve and ship changes? Name the program owner and the people responsible for content, subject-matter review, development, analytics, and final approval.

    This framing matters because technical work rarely wins priority on terminology alone. Internal linking, index management, performance, hreflang, and schema markup become easier to fund when they are connected to revenue, conversion, reach, or cost reduction. If the company wants to grow in a particular region, for example, the case for correcting hreflang is not that hreflang is an SEO best practice. The case is that sending search engines to the wrong regional version works against the market-expansion goal.

    Use the same discipline with performance claims. The claim that a one-second delay can reduce conversions by up to 7% can illustrate why speed deserves attention, but it is not a forecast for your site. Your own page performance, traffic mix, and conversion data must determine the actual opportunity. A benchmark can open the conversation; it cannot replace measurement.

    Give every proposed initiative a simple value chain:

    • Change: What will be altered?
    • Mechanism: How should that alteration improve discovery, comprehension, selection, or user experience?
    • Leading signal: What should move first if the mechanism is working?
    • Business signal: Which meaningful outcome could move afterward?
    • Decision: What will you expand, revise, or stop when you see the result?

    That last field prevents reporting from becoming ceremonial. A metric belongs in the program only if a change in that metric could cause you to make a different decision.

    Design one workflow from audience question to measurable page

    Four specialists work along one illuminated path that turns an audience question into researched content, structured page elements, and a webpage displayed on several devices.

    SEO and GEO should not operate as rival channels. SEO helps your pages become accessible, indexable, relevant, and competitive in conventional search. GEO aims to make the same body of knowledge easier for generative systems to interpret, select, and cite when constructing answers. The practical unit of work is therefore not a GEO tactic. It is a question, the page that should answer it, the evidence on that page, and the systems that need to retrieve it.

    Build the workflow in the following order:

    1. Create a question inventory. Record the actual decision or uncertainty behind each question, not just a keyword. Add the intended audience, market, language, journey stage, and the kind of answer required.
    2. Group questions by intent and required evidence. Questions that use similar words may need different pages if one asks for a definition and another asks for a purchase comparison. Questions with different wording may belong together when the same page can answer them completely.
    3. Assign a destination page. Give every important question cluster an existing page to improve or a justified content gap to fill. If several pages compete to do the same job, decide which one should be canonical before producing more copy.
    4. Make the answer usable. Put a direct response close to the question it resolves, then supply the explanation, evidence, limitations, and next step the reader needs. Do not force a person or a retrieval system to assemble the central answer from scattered hints.
    5. Verify technical access. Check status codes, indexability, canonical signals, rendering, internal links, sitemap inclusion, and regional or language targeting where applicable. Content cannot perform reliably if the intended URL is inaccessible, duplicated, or poorly connected to the rest of the site.
    6. Describe the page accurately with structured data. Use JSON-LD and schema types that match the visible page and the real entities involved. Then validate the markup and monitor the deployed output rather than assuming the CMS generated it correctly.
    7. Measure and feed the result back into the backlog. Track which questions produce visibility, which URLs are cited, what qualified engagement follows, and where the answer remains absent or inaccurate.

    A content brief produced by this workflow should be much more precise than write an authoritative article about a topic. It should specify the audience question, the promised answer, the destination URL, the entities that need unambiguous names, the evidence required, the important qualifications, the internal links, the appropriate structured data, and the business action available after the answer.

    Use page-level acceptance criteria before publication:

    • The page answers its primary question in language the intended audience can understand.
    • Headings expose the page’s logic rather than merely repeating variations of a keyword.
    • Important claims have suitable evidence, context, and qualifications.
    • Names for the organization, product, service, people, and other entities remain consistent.
    • Internal links connect the page to relevant supporting and conversion content.
    • The canonical URL is accessible and returns the intended content.
    • JSON-LD describes what is visibly present and does not introduce unsupported claims.
    • The page offers a sensible next step without obstructing the answer.

    Structured data is useful here because it provides a machine-readable description of the page. It is not a substitute for clear content, technical access, or credible evidence, and it does not guarantee inclusion in a generated answer. If the visible page is vague, duplicated, or contradictory, adding more markup only gives you a more elaborate description of a weak asset.

    Choose a GEO platform after this workflow is defined. The practical value of these tools is their ability to help you observe AI visibility and citations in systems such as ChatGPT and Gemini. Your use case should determine which platform fits, not the length of its feature list.

    Evaluate a platform against the decisions in your charter:

    • Does it monitor the answer engines your audience actually uses?
    • Can you segment by topic, brand, product, market, language, or other necessary dimensions?
    • Does it show the cited URL, not merely whether the brand appeared?
    • Can you preserve a stable question set and compare results over time?
    • Does it retain enough response context for a person to judge whether a mention is accurate and relevant?
    • Can you export the data or connect it to your reporting workflow?
    • Can your team reproduce how a reported metric was calculated?
    • Do its access controls, data handling, and retention practices fit your organization’s requirements?

    No monitoring platform can tell you by itself why an answer changed. Models, retrieval behavior, citations, and interfaces can change outside your site. Treat the tool as an observation layer. Keep page changes, prompt definitions, engine settings, and measurement dates alongside the results so your team can interpret movement without inventing certainty.

    Make every AI-assisted audit pass the CaML test

    An AI-generated audit can be detailed, polished, and wrong. The most common failure occurs before the recommendations: the system never received the full page, reliable query information, a comparison set, or a definition of success. It fills the missing context with assumptions and presents those assumptions in the same confident tone as verified findings.

    Use the CaML framework: Context, Methodology, and Human in the Loop. If any element is missing, the output is a draft for investigation, not an audit you should send to a writer or developer.

    Context: give the system the evidence it needs

    Start by retrieving the actual page content. A search snippet is not an adequate substitute: it may omit most of the answer, qualifications, internal links, structured data, or even the wording the audit intends to change. Supply the canonical URL, rendered content where relevant, page purpose, intended audience, target questions, business goal, and any constraints the recommendation must respect.

    Where the task depends on demand or competition, provide appropriate keyword data and the relevant top-ranking URLs rather than asking the model to guess. If you use a structured content outline, include it. The AI should know what evidence it has, what it does not have, and which fields came from tools rather than model inference.

    Mark an audit as incomplete when the system cannot access the page or a required dataset. That is a useful finding. A fabricated recommendation is not.

    Methodology: define how a finding becomes a recommendation

    A repeatable audit needs a declared method. State the checks, comparison set, evidence standard, prioritization fields, and output format before the model evaluates anything. Otherwise, two runs can produce different backlogs without revealing why.

    A page-level SEO and GEO method might ask:

    • Can search and retrieval systems access the canonical content?
    • Does the page resolve the intended question clearly and early enough?
    • Are the central claims supported, qualified, and internally consistent?
    • Are important entities named consistently on the page and across related pages?
    • Does the internal-link structure help a visitor and a crawler find necessary supporting material?
    • Does the structured data match the visible content and page type?
    • Does the page differ meaningfully from competing answers, or does it merely restate common material?
    • Is there an appropriate next action for the intended visitor?

    Prioritize each finding by expected business impact, confidence in the evidence, implementation effort, and dependencies. Do not collapse those fields into an unexplained score. A high-impact idea supported by weak evidence needs validation; a well-proven defect blocked by a template migration needs coordination; a trivial wording preference may not deserve a ticket at all.

    Human in the loop: make the recommendation fit reality

    A knowledgeable reviewer should verify factual accuracy, search intent, brand language, technical feasibility, and business priority. The reviewer also needs to catch conflicts that a page-level agent may not see, such as a recommendation that duplicates another URL, breaks a shared template, contradicts product policy, or creates more maintenance than value.

    Turn approved findings into small implementation tickets. Each ticket should contain:

    • Finding: the specific defect or opportunity.
    • Evidence: the page element, query data, comparison, or technical observation supporting it.
    • Consequence: the audience or business problem created by the current state.
    • Action: the smallest clear change that addresses the problem.
    • Owner and dependency: the person who can ship it and anything that must happen first.
    • Validation: how you will confirm that the change deployed correctly.
    • Outcome check: which leading and business signals you will revisit afterward.

    This format is intentionally shorter than a long narrative audit. Writers and developers need decisions they can act on. Keep the full evidence available for review, but do not bury the required change inside pages of generic commentary.

    Measure visibility as a funnel, not a citation trophy

    Glowing signals from search and conversational interfaces pass through a transparent funnel toward completed actions, while a small trophy sits apart in the background.

    A citation is useful evidence that a system selected a URL while producing an answer. It is not, by itself, proof of qualified reach, favorable representation, traffic, conversion, or revenue. Your scorecard needs to show the path from implementation to visibility and from visibility to business effect.

    Measurement layerWhat to recordDecision it supports
    DeliveryPages changed, technical fixes deployed, structured data validated, and content approvedWhether the planned work actually reached production
    EligibilityCanonical accessibility, indexability, rendering, internal-link coverage, and other relevant technical statesWhether a technical barrier needs to be removed before judging content performance
    AI visibilityAnswer presence, brand mention, citation presence, cited URL, question, engine, market, language, and observation dateWhich topics and pages are being selected, omitted, or represented inaccurately
    Search and site engagementRelevant landing-page visits, referral information where available, engagement, and conversion-path behaviorWhether discoverability is producing useful site activity
    Business outcomeQualified conversions, revenue where observable, market reach, or documented cost reductionWhether to expand, revise, or stop the initiative
    Answer qualityAccuracy, citation relevance, outdated claims, missing qualifications, and brand representationWhich content or entity problems require correction even when raw visibility is high

    Create a baseline before changing the pages. Preserve the monitored questions, wording, engine, market, language, date, response, cited URLs, and relevant settings. Separate branded questions from non-branded questions because they represent different discovery conditions. Group results by topic and destination page so you can diagnose an asset instead of reacting to an isolated answer.

    Define every calculated metric. If you report citation rate, specify the denominator: the fixed set of monitored question runs for which a citation was checked. If you report share of visibility, state which brands, questions, engines, markets, and dates were included. A percentage without its measurement universe is not a decision-ready metric.

    Treat referral traffic as partial evidence. A generated answer can influence a person without producing a click, and a click may not preserve all the attribution detail you want. Do not respond by claiming every mention as an assisted conversion. Report what you can observe, label what you infer, and keep the two separate.

    Use patterns across the funnel to decide what to do:

    • Implementation rose, but eligibility did not: check deployment, rendering, canonical behavior, templates, and validation before rewriting content.
    • Eligibility is sound, but visibility remains absent: revisit question-to-page fit, answer clarity, evidence, entity consistency, and whether another URL is competing for the same role.
    • Mentions appear, but citations do not: inspect whether the brand is being discussed through third-party material, whether your destination page is sufficiently clear and supportable, and whether the monitored answer normally provides links.
    • Citations rise, but qualified engagement does not: check the intent of the monitored questions, the relevance of the cited page, and the next action available to the visitor. You may be winning visibility that has little business value.
    • Traffic or conversions improve without a matching visibility change: look for conventional search gains, campaigns, seasonality, site changes, or measurement gaps before crediting GEO.
    • Visibility rises while answer quality declines: prioritize factual correction and clearer qualifications. More exposure to an inaccurate answer is not a successful outcome.

    Annotate content releases, migrations, template changes, internal-link updates, and schema deployments. Where feasible, compare changed pages with a suitable unchanged group. Even then, describe causality carefully because external systems can change at the same time. The aim is to prove impact over time, not to assign every favorable movement to the most recent SEO ticket.

    Close each reporting cycle with decisions, not just charts: what will be expanded, what needs another test, what is blocked, what should be stopped, and which assumption was disproved. That creates institutional knowledge and makes the next request for engineering or editorial support much easier to evaluate.

    Key takeaways

    • Start with an audience question and a business decision, then select pages, tactics, and tools that serve them.
    • Run SEO, content, JSON-LD, and GEO measurement as one workflow around a canonical destination page.
    • Do not accept an AI audit unless it has sufficient context, a declared methodology, and a qualified human reviewer.
    • Measure delivery, technical eligibility, AI visibility, engagement, answer quality, and business outcomes as separate layers.
    • Keep a stable, documented question set so changes in visibility can be interpreted instead of merely observed.
    • Turn every report into an explicit choice to expand, revise, validate, defer, or stop work.

    Start with a commercially important topic rather than the entire site. Write the charter, map its questions to destination pages, establish the baseline, run a CaML-based audit, and ship the smallest defensible set of changes. Once the measurement loop produces decisions your content, development, and business teams trust, you have a program worth scaling.

    References

  • AI-Driven SEO Strategy: Build Visibility Beyond Your Site

    AI-Driven SEO Strategy: Build Visibility Beyond Your Site

    If your rankings look respectable but your brand rarely appears in AI-generated answers, publishing more keyword-targeted pages may not solve the problem. You may already have enough content. What you lack is a connected body of facts, answers, and independent evidence that an AI system can find and reconcile.

    An effective AI-driven SEO strategy connects five things: the questions your audience asks, the answers you want associated with your brand, the evidence supporting those answers, the places that evidence appears, and the business outcomes you measure. Here is how to build that system without abandoning the SEO work that still matters.

    Key takeaways

    • AI-driven SEO is not simply using AI to produce more content. It is designing your search presence for discovery, interpretation, and corroboration across multiple surfaces.
    • Your website remains the canonical home for your facts and expertise, but it cannot be the only place where your brand is represented.
    • Plan around audience questions and the proof needed to answer them, not isolated keywords or publishing quotas.
    • Keep important claims consistent across pages, structured data, official profiles, directories, contributed content, and earned mentions.
    • Measure whether AI answers include, describe, and support your brand accurately, then connect that visibility to qualified visits, leads, and revenue.

    Treat your website as the center, not the entire strategy

    Traditional SEO concentrates much of its effort on the website: improve crawlability, target relevant queries, earn links, and move pages up the results. Those jobs still matter. If your pages cannot be discovered, understood, or trusted, they are unlikely to become useful inputs for any search experience.

    The strategic boundary has expanded, however. AI search can form its understanding of a brand from multiple inputs, including articles, brand mentions, social activity, third-party profiles, directories, press material, and other published content. Your site is a critical input within that environment, not a substitute for it.

    This changes the unit you optimize. A page is still an SEO asset, but the larger unit is an evidence network: several discoverable representations that agree about who you are, what you do, who you serve, and why a particular claim should be believed.

    Audit three separate visibility layers

    • Discovery: Can a search system find a relevant page, profile, mention, or listing when it investigates the subject?
    • Understanding: Do those surfaces use clear language for your brand, category, offering, audience, people, and locations?
    • Corroboration: Does the available evidence support your important claims, or does everything lead back to an unsupported statement on your own site?

    Run the audit for a small set of commercially important questions. For each one, search your site, review your official profiles, inspect prominent third-party pages, and examine representative AI answers. Record whether the brand is absent, present but vaguely described, accurately represented, or supported with useful evidence. Those are different failures and require different fixes.

    An absent brand may need stronger topical coverage or distribution. A misdescribed brand needs clearer entity facts and correction of conflicting profiles. A correctly named brand that is never recommended may have an evidence problem rather than a content-volume problem.

    Build the plan from questions, claims, and proof

    Abstract audience questions, claim modules, source folders, document stacks, and verification tokens converge into one organized structure on a table.

    A keyword list tells you which phrases people type. It does not tell you what an AI answer must resolve before it can mention your brand responsibly. Add a prompt-to-proof map beside your keyword research so that each priority question has a defensible answer and a clear evidence requirement.

    Create a prompt-to-proof map

    Use one row for each question family and include these fields:

    • Audience situation: Who is asking, and what decision are they trying to make?
    • Question family: Group alternate phrasings that seek the same underlying answer.
    • Desired brand association: State the accurate role your brand should occupy, without promotional superlatives.
    • Answer requirements: List the facts, distinctions, caveats, and comparison criteria a useful response must cover.
    • Proof required: Identify the documentation, demonstrated expertise, verifiable credentials, product information, or independent recognition needed to support the answer.
    • Canonical asset: Choose the page that should contain the most complete and current explanation.
    • Corroborating surfaces: Record the profiles, directories, partner pages, publications, communities, or social channels where related evidence legitimately belongs.
    • Current failure: Label the gap as missing answer, weak proof, inconsistent facts, limited distribution, or poor technical access.
    • Next action and owner: Give the row a concrete change and a person responsible for maintaining it.

    Suppose a buyer asks which platform is appropriate for an international ecommerce team. A page that repeats the phrase “international ecommerce platform” is not a complete answer. The buyer may need to understand market support, language handling, operational constraints, integrations, and the situations in which the product is not a fit. Your map should expose which of those decision criteria you can answer and prove.

    This also prevents indiscriminate content generation. If several prompts require the same underlying evidence, strengthen one definitive resource and distribute its verified claims appropriately. If you have no proof for a desired claim, do not turn it into a larger publishing campaign. Change the claim, obtain the evidence, or deprioritize the question.

    Prioritize gaps, not content formats

    Choose work by business relevance, answer weakness, and available proof. A commercially important question with a weak existing answer and strong internal evidence is usually a better target than a high-volume topic where your brand has nothing distinctive or verifiable to contribute.

    The required fix may be a service page, comparison framework, technical explainer, expert biography, directory correction, original documentation, or stronger distribution. Starting with the gap keeps the team from prescribing a blog post before it understands the problem.

    Make important facts consistent and machine-readable

    AI visibility becomes fragile when every channel describes the same company differently. A rebrand appears on the homepage but not the executive profiles. A service is available in one market, while an old directory implies global availability. Structured data names one organization, while the visible page uses another variation without explaining the relationship.

    Consistency does not mean publishing identical sentences everywhere. It means maintaining agreement on the facts that determine identity, relevance, and qualification.

    Maintain a canonical fact and claim register

    • Official brand name, accepted name variations, and the relationship between parent brands, divisions, and products.
    • Plain-language descriptions of the categories and problems the organization addresses.
    • Current offerings, intended audiences, locations served, and material limitations.
    • Named people, roles, credentials, and areas of expertise that can be verified.
    • Important performance, leadership, or differentiation claims, each paired with its evidence and necessary qualifier.
    • The canonical URL for each fact or claim, plus the profiles and external pages where it also appears.
    • An owner and a review trigger, such as a product change, market launch, rebrand, leadership change, or expired credential.

    Use the register during content briefs, profile updates, public relations work, partnership reviews, and schema implementation. It gives every channel the same factual foundation while allowing each one to use language appropriate to its audience.

    Use JSON-LD as a translation layer, not as evidence

    Structured data should represent the facts a visitor can verify on the page and clarify the relationships among the entities discussed there. It should not introduce unsupported awards, ratings, credentials, prices, or organizational relationships. Markup can make a fact easier for a machine to interpret; it cannot make the fact credible by itself.

    For each priority page, compare the visible copy, metadata, internal links, and JSON-LD. Names, descriptions, identifiers, authorship, dates, availability, and entity relationships should not contradict one another. Validate the markup, but also perform a human fact check. Technically valid schema can still describe the wrong thing.

    Make the main answer easy to extract without stripping away the reasoning that makes it trustworthy. Use a descriptive heading, answer the central question directly, define important terms, state qualifications near the claim they limit, and place evidence beside the statement it supports. Then link to deeper documentation where a reader or retrieval system may need more context.

    Repeat the audit for every language-market pair

    For international SEO and AI visibility, do not assume a strong global page settles the question everywhere. Search language, market terminology, local offerings, recognized experts, relevant directories, and available proof can differ. Create a market-level version of the prompt-to-proof map, while keeping the underlying brand identity reconciled with the global register.

    Do not translate unsupported claims into additional languages. Confirm that the offering, evidence, and qualification apply in the target market first. If they do not, adapt the answer rather than forcing global copy into a local search context.

    Publish and distribute proof as one coordinated system

    Matching evidence travels from one source package to several digital platforms and is gathered by a translucent AI retrieval lens.

    A broader footprint does not mean opening every channel or syndicating the same paragraph across the web. Choose surfaces because they help a particular audience discover, understand, or verify something important about the brand.

    SurfacePrimary jobWhat to publish or correct
    Canonical website pageProvide the complete answerDefinitions, decision criteria, qualifications, evidence, ownership, and update context
    Official profilesConfirm identityCurrent name, category, description, location, people, offering, and canonical link
    Relevant directoriesSupport category or market discoveryAccurate classification, service details, credentials, location data, and current links
    Partner or association pagesVerify a real relationshipThe nature of the relationship, applicable expertise, and supporting resources
    Earned coverage and contributed expertiseAdd independent contextNewsworthy developments, attributable expertise, original explanations, and defensible claims
    Social and community channelsExpose timely expertise and audience languageUseful explanations, answers to recurring questions, and links to definitive resources when needed

    A fragmented channel strategy produces weaker signals when messaging and expertise do not align. Solve that operationally. Give SEO, content, social, public relations, partnerships, and brand teams access to the same question map and claim register. Plan campaigns around the evidence you need to establish, not separate channel quotas.

    A practical distribution sequence looks like this:

    1. Publish or update the canonical explanation on a page you control.
    2. Bring official profiles and structured data into factual agreement with that page.
    3. Update legitimate directories and partner records where the same facts are relevant.
    4. Develop earned or contributed material only when there is independent value: genuine news, attributable expertise, useful analysis, or a verifiable relationship.
    5. Use social and community content to answer narrower questions and lead interested readers to the deeper resource.
    6. Record every material claim and placement so later changes can be propagated without recreating the audit.

    Press releases and directory listings are not automatic authority. A release needs actual news, and a listing needs relevance and accurate information. Publishing either solely to create another mention can add noise without supplying meaningful corroboration.

    When you find a conflict, correct the canonical page, structured data, and official profiles first. Then update controlled listings and request corrections from third parties. Keep a record of pages you cannot change so the team understands why an outdated description may continue to surface.

    Measure whether AI can find, understand, and support you

    Rankings, organic sessions, and conversions remain necessary, but they do not reveal how a generative answer represents your brand. AI mention counts alone have the opposite weakness: they can show exposure without showing accuracy, influence, or business value. Use both diagnostic and outcome measures.

    Build a repeatable visibility record

    Keep a stable set of priority questions organized by journey stage, audience, language, and market. When you review an AI search surface, record:

    • The exact question and the context needed to interpret it.
    • The platform, search mode, language, market, and review date.
    • Whether your brand appears and what role it occupies in the response.
    • Whether the description is accurate, incomplete, outdated, or wrong.
    • Which pages or external references support the answer, when references are shown.
    • Which competitors appear and what claims or evidence distinguish them.
    • The specific gap exposed: missing content, weak evidence, entity confusion, poor distribution, or inaccessible information.
    • The action taken and the canonical asset expected to change.

    Do not treat a single generated response as a trend. Repeat the same controlled review over time and look for persistent patterns across the question family. Separate a one-off omission from a recurring inability to associate the brand with the subject.

    Connect visibility to business outcomes

    Pair the visibility record with qualified organic and referral visits, assisted conversions, leads, sales, and branded demand where your analytics can support those connections. The purpose is not to claim that every mention caused a conversion. It is to see whether stronger representation around high-value questions accompanies useful audience behavior.

    Review failures before celebrating totals. Being mentioned for an irrelevant use case, described with an outdated feature, or attached to an unsupported claim can create more work than being absent. Accuracy, relevance, and evidence quality belong beside visibility on the dashboard.

    Start with one question cluster tied to a real buying or evaluation decision. Build its prompt-to-proof map, repair the canonical facts, strengthen the best page, align the surrounding profiles, and establish a repeatable baseline. Once that workflow holds together, extend it to the next cluster. That is how AI-driven SEO becomes an operating system rather than another publishing campaign.

    References

  • Human Factors That Make Agentic AI Deployments Work

    Human Factors That Make Agentic AI Deployments Work

    Your agent can draft pages, change metadata, select audiences, trigger campaigns, and coordinate customer journeys. The hard question isn’t whether it can perform those actions. It’s whether it should be allowed to perform each one without stopping for a person.

    If you’re deciding how much autonomy to grant, treat the deployment as an operating-model decision rather than a software installation. Define who owns the outcome, which actions require approval, how people will detect a bad decision, and how they can stop or reverse it. Those human controls determine whether the agent produces useful leverage or merely executes mistakes faster.

    Start with a decision, not an AI agent

    Agentic AI projects often begin with a capability demonstration: the system can plan a campaign, create content, update a workflow, or act across several tools. A convincing demonstration doesn’t establish that the workflow is worth automating or safe to delegate.

    The warning is concrete. Gartner expects more than 40% of agentic AI projects to be canceled by the end of 2027. The projection, based on more than 3,400 organizations investing in the technology, points to unclear value, weak governance, and hype-led experimentation rather than a simple lack of technical capability. Treat that percentage as a forecast, not a settled outcome, but don’t miss the operational problem behind it.

    Before you select a product or build an agent, write a decision brief for one workflow. It should answer these questions:

    • What outcome changes? Name the business result, not the AI activity. “Reduce the time required to prepare a technically reviewed content brief” is an outcome. “Use an agent for briefs” is not.
    • What does the workflow look like now? Record its inputs, decisions, handoffs, failure points, review work, and final action. Otherwise, you won’t know whether the agent improved the process or merely moved effort into supervision and repair.
    • Which judgment is scarce? Separate repetitive coordination from decisions that depend on audience knowledge, brand context, ethics, or commercial priorities. Automating the former may create capacity. Hiding the latter inside a prompt creates unmanaged risk.
    • What evidence would justify continuation? Choose outcome, quality, intervention, and recovery measures before launch. A pilot without an exit rule tends to survive because it exists, not because it works.
    • Who can stop it? Assign a named operational owner with authority to pause actions, narrow scope, and require remediation.

    This brief also protects you from “agent washing.” A conventional chatbot or fixed automation shouldn’t be purchased as an autonomous agent simply because the label changed. Ask the vendor or internal team to demonstrate the operating loop: what the system observes, which choices it makes, what it can change, how it checks the result, when it stops, and when it escalates. If every meaningful path was predetermined, you may still have useful automation, but you don’t have the adaptive autonomy the name implies.

    For an SEO or GEO workflow, make the distinction visible. An agent that recommends schema corrections is materially different from one that edits production markup. An agent that identifies possible internal links is different from one that publishes them. An agent that proposes a redirect is different from one that changes routing. Evaluate the authority being granted, not just the sophistication of the output.

    Design human control before you grant autonomy

    Two operators oversee a modular automated workflow equipped with an approval gate, a pause lever, and a track that can reverse direction.

    “Human in the loop” is too vague to serve as a control. A person can technically appear in a workflow while lacking the context, time, authority, or evidence needed to catch a problem. Effective oversight specifies the decision rights on both sides of the human-agent boundary.

    Classify every action the agent may take using four practical questions:

    • Can it be reversed? Saving a draft is easy to undo. Sending a customer message, changing access, publishing an unsupported claim, or allowing a damaging URL change to propagate may not be.
    • How wide is the impact? A suggestion affecting one draft has a smaller blast radius than a template change affecting thousands of pages or an audience rule applied across campaigns.
    • How much context does the decision require? Stable rules are easier to delegate than choices involving brand nuance, conflicting evidence, unusual customer circumstances, or several acceptable outcomes.
    • Will failure be visible quickly? A malformed output may be obvious. A plausible but strategically wrong recommendation can remain unnoticed while it influences content, spend, or customer treatment.

    Use the answers to assign authority. Reversible, narrow, observable actions with clear rules are reasonable candidates for bounded autonomy. Irreversible, broad, ambiguous, or slow-to-detect actions should require approval or remain human-owned. Don’t use one autonomy setting for the entire workflow.

    ControlQuestion it must answerEvidence to retain
    Named ownerWho is accountable for the business outcome and failure response?Owner, backup, authority, and escalation route
    Scope boundaryWhich systems, records, audiences, and actions may the agent touch?Allowlist, denied actions, and permission configuration
    Approval gateWhich conditions force a person to decide?Trigger, reviewer, required context, and decision record
    Stop controlHow can a person halt new actions without waiting for the agent?Pause procedure, access owner, and confirmation that execution stopped
    Recovery pathHow will the team contain and reverse a bad action?Rollback method, affected-system inventory, and notification route
    Audit trailCan reviewers reconstruct what the agent knew, chose, and changed?Inputs, retrieved context, proposed action, approval, execution result, and exceptions

    The audit trail needs to capture more than generated text. Store the context used for the decision, the action requested, the tools called, the result returned, any human intervention, and the final system state. A polished explanation generated after the event isn’t a substitute for an execution record.

    Approval interfaces deserve the same care. Don’t ask a reviewer to click “approve” after showing only the agent’s preferred answer. Show the original input, relevant constraints, proposed change, affected assets, uncertainty or missing information, and available alternatives. Make rejection and escalation as easy as approval. Otherwise, the interface quietly trains people to accept.

    For content and search operations, require explicit review before actions such as publishing factual claims, changing canonical directives, modifying crawl controls, issuing broad redirects, altering product or business data, sending outreach, or communicating with customers. Your exact gates should reflect your systems and risk, but the rule is stable: the person must intervene before the consequential action, not after the impact appears in analytics.

    Increase autonomy only after the workflow becomes observable

    Analysts monitor tasks moving through a transparent automated system while an unusual task is diverted into a separate human review bay.

    A pilot should test the complete operating system around the agent. Testing only whether the model can produce a good answer leaves permissions, handoffs, monitoring, escalation, and recovery unexamined.

    Move through these modes in order:

    1. Shadow mode: Let the agent observe real inputs and record what it would do, but prevent external actions. Compare its proposed decisions with actual outcomes and inspect where its context is incomplete.
    2. Advisory mode: Let it recommend actions to a responsible operator. Record approvals, edits, rejections, escalation reasons, and the time required to review. Heavy correction is evidence that the workflow or context is not ready for autonomy.
    3. Bounded action mode: Allow a defined set of reversible actions within an allowlisted scope. Keep consequential actions behind approval gates and enforce a direct stop mechanism.
    4. Expanded autonomy: Broaden authority only when the existing scope produces acceptable outcomes, exceptions are understood, logs support investigation, and the team can demonstrate recovery.

    Promotion between modes should be an evidence decision. Don’t advance because the pilot deadline arrived or because a successful demonstration created executive enthusiasm. Review routine cases, edge cases, ambiguous requests, missing-data situations, conflicting instructions, permission failures, and attempts to push the agent beyond its assigned scope.

    Measure the deployment across four layers:

    • Outcome: Did the workflow improve the business result named in the decision brief?
    • Quality: Were outputs accurate, complete, on-brand, appropriately sourced, and suitable for the intended audience?
    • Control: How often did people edit, reject, stop, or escalate an action, and why?
    • Recovery: Could the team identify affected assets, contain the problem, restore the correct state, and learn from the failure?

    Don’t optimize the intervention rate toward zero. A falling rate can mean the system improved, but it can also mean reviewers stopped looking carefully. Read intervention data alongside sampled quality checks, downstream outcomes, and exception reports. The useful question is whether human attention is landing on the decisions where it changes the outcome.

    FOMO creates pressure to skip this progression and move directly from demo to production. That pressure is especially dangerous when an agent can act at campaign or site scale. Speed comes from making the safe path repeatable: clear permissions, reusable evaluation cases, reliable logs, tested rollback, and known escalation owners.
    Protect human judgment and customer trust as operating assets

    An agent’s output can look coherent even when its recommendation is unsuitable. That makes reviewer competence part of the control environment. If the person approving an action can’t recognize a strategic, factual, or ethical error, the approval step is ceremonial.

    One projection expects half of organizations to reassess their competencies as reliance on AI threatens critical thinking. You don’t need to reject automation to respond. You need to keep the relevant judgment active.

    • Require a reason for consequential approvals. The reviewer should identify why the action fits the goal and constraints, not merely confirm that the output reads well.
    • Keep people capable of performing the underlying task. Rotate qualified operators through manual cases and exception handling so the team retains a working model of what good looks like.
    • Separate creation from high-impact approval. The person who configured or champions the agent shouldn’t be the only person judging its production readiness.
    • Review disagreements, not just errors. Repeated edits and rejected recommendations reveal missing context, unclear policy, or a task that requires more human judgment than expected.
    • Run post-incident reviews around the system. Examine instructions, data, permissions, interface design, workload, escalation, and incentives. Telling reviewers to “be more careful” leaves the mechanism intact.

    Customer trust needs its own controls. A related forecast warns that poorly applied agentic AI could damage customer relationships by 2026. The risk isn’t limited to obviously nonsensical responses. An agent can send a polished message to the wrong person, apply a reasonable rule at the wrong moment, or take an authorized action that conflicts with the customer’s circumstances.

    Map each customer-facing action to an identity, authority, and escalation rule. The customer should be able to tell what happened, correct wrong information, reach a person when the automated path is unsuitable, and receive a clear resolution when an action causes harm. Internally, the team should be able to identify which agent acted, under whose authority, using what information.

    Brand alignment can’t live only in a long prompt. Translate it into reviewable policies: prohibited claims, evidence requirements, tone boundaries, audience exclusions, escalation topics, and actions the agent may never take. Give each policy an owner and a process for change. That turns “use good judgment” into controls a team can inspect.

    Key takeaways

    • Begin with one defined business decision and its current workflow, not a general mandate to deploy an agent.
    • Evaluate actual autonomy by inspecting what the system observes, decides, changes, verifies, and escalates.
    • Grant authority action by action. Reversibility, impact, ambiguity, and observability should determine where people intervene.
    • Test in shadow, advisory, bounded-action, and expanded-autonomy modes, with evidence required before each increase in authority.
    • Retain execution logs, explicit stop controls, and tested recovery paths before the agent touches consequential systems.
    • Treat reviewer competence and customer escalation as core infrastructure, not training tasks to add after launch.

    Before your next agent demo, produce a one-page deployment contract for the workflow: outcome, owner, allowed actions, prohibited actions, approval triggers, stop mechanism, recovery path, and evidence required for more autonomy. If the team can’t agree on that page, the agent isn’t ready for broader access. Resolving those human decisions first is the shortest route to a deployment you can trust.

    References

  • AI-Era Advertising: How to Prove and Scale Real Growth

    AI-Era Advertising: How to Prove and Scale Real Growth

    Your dashboard says advertising is working. ROAS is up, automated campaigns are claiming conversions, and conversational AI is opening new inventory. But the decision in front of you is harder: which spending actually created revenue that would not have happened otherwise?

    You can answer that question without waiting for perfect attribution. Separate platform-reported performance from incremental lift, measure the return on the next dollar rather than the average dollar, and treat new AI placements as controlled learning investments. That gives you a practical basis for scaling, holding, or cutting spend.

    A high ROAS can still describe demand capture

    Platform ROAS answers a narrow question: how much revenue did the platform attribute to ads relative to their cost? It does not tell you how many of those purchases required the ads.

    That distinction becomes important when automated systems can concentrate spending around branded searches, repeat visitors, existing customers, and people already close to buying. The platform may be accurately recording its involvement while claiming revenue that would have arrived through direct, organic, or another channel. The number is useful for optimizing activity inside the platform, but it is not causal proof of growth.

    Before you increase a campaign budget, ask three separate questions:

    • Did the platform influence conversions? Platform attribution, CPA, and ROAS can help answer this.
    • Did advertising cause additional conversions? A controlled incrementality test is needed to estimate this.
    • Will the next block of spending remain profitable? Marginal return and contribution economics answer this better than average ROAS.

    Use the right calculation for each decision

    • Attributed ROAS equals platform-attributed revenue divided by ad spend. Use it to compare campaigns under the same attribution rules and improve execution within a platform.
    • Incremental revenue is the difference between the outcome for an exposed group and the estimated outcome for a comparable unexposed group, after accounting for relevant baseline differences.
    • Incremental ROAS equals incremental revenue divided by the advertising cost required to produce that lift. Use it to decide whether the campaign adds enough business value to keep funding.
    • Marginal ROAS equals the change in incremental revenue divided by the change in spend. Use it to decide whether an additional budget block is worth buying.

    The average and marginal numbers can point in opposite directions. A campaign that produces $50,000 from its first $10,000 has a 500% average ROAS. If another $5,000 produces only $5,000 more revenue, the combined average still looks respectable at roughly 366%, but the marginal ROAS on the added spend is only 100%.

    Do not call that final dollar break-even merely because one dollar of spend returned one dollar of revenue. Product costs, fulfillment, payment fees, returns, sales commissions, and other variable costs can make a 100% revenue ROAS unprofitable. Convert incremental revenue into incremental contribution before approving more budget. If margins differ by product or customer segment, calculate contribution at that level instead of applying one blended percentage to everything.

    Build a measurement ladder instead of one master metric

    Two analysts inspect a five-level staircase containing signal lights, matched customer groups, test vessels, and a prism illuminating a new group.

    No single metric can optimize campaigns, prove causality, and allocate the next dollar. A measurement ladder gives each metric a specific job and prevents a familiar dashboard number from being stretched beyond what it can establish.

    DecisionPrimary evidenceWhat that evidence cannot prove alone
    Which bid, audience, or creative should run?Platform conversions, CPA, and attributed ROASWhether the advertising caused the conversion
    Should the campaign keep receiving money?Incremental lift, incremental ROAS, and contributionWhether a larger budget will perform at the same rate
    Where should the next budget block go?Marginal incremental revenue or contributionHow performance will change after a major market or product shift
    Is the brand gaining visibility in AI answers?Paid exposure and unpaid AI mentions measured separatelyThat either form of visibility caused profitable demand

    Run an incrementality test that matches the business question

    You do not need a perfect measurement laboratory. You do need a credible counterfactual: an estimate of what would have happened without the advertising.

    1. Choose one business outcome before launch. Use completed revenue, gross contribution, qualified pipeline, new customers, or another outcome tied to the decision. Do not replace it mid-test with whichever platform metric looks strongest.
    2. Choose a control design. Comparable geographic markets, randomized audience holdouts, platform lift tests, audience exclusions, and controlled spend reductions can all create evidence beyond ordinary attribution. Geo splits and audience holdouts are especially useful when user-level journeys cannot be observed cleanly.
    3. Protect the contrast. Record which campaigns, markets, audiences, promotions, and prices differ between treatment and control. A large promotion in only one group can look like advertising lift even when the ad had little effect.
    4. Record the exposure rules. Preserve campaign settings, eligibility, placement types, creative versions, market coverage, and any platform product changes. This matters more in AI inventory, where formats and reporting can change while the channel is still maturing.
    5. Let the test cover the decision cycle. A test that ends before delayed purchases or qualified leads can mature will favor channels with short feedback loops. Set the observation window from the actual buying process, not from a convenient reporting date.
    6. Report uncertainty with the result. A positive point estimate from a small or volatile control group is not automatically a scalable win. If the result is too noisy to distinguish lift from normal variation, enlarge the test unit, repeat it, or classify the conclusion as unresolved.

    Maintain a test ledger with the hypothesis, primary outcome, treatment and control definitions, launch and end conditions, known confounders, result range, and budget decision. That record stops teams from remembering only successful tests and makes later retesting much faster.

    Treat conversational AI ads as a learning budget

    A researcher directs a measured stream of budget tokens into three transparent chambers testing abstract conversational ad experiences with anonymous audiences.

    Conversational advertising should not inherit the assumptions of search, social, or display. OpenAI began rolling out ads to Free and Go users in Australia, New Zealand, and Canada while keeping Pro, Business, Enterprise, and Education plans ad-free. Results from that inventory therefore should not be generalized to every ChatGPT user, market, or subscription tier.

    The early buying environment also carries unusually high measurement risk. Initial advertiser accounts described impression-led campaigns, limited reporting, high CPMs, and starting commitments in the six-figure range. Those accounts are preliminary, not a dependable benchmark for what every advertiser will pay or achieve. They are still enough reason to demand a sharper test plan before committing a material budget.

    Write the pilot brief before negotiating inventory

    • State the user moment. Name the conversational situation you expect to influence, such as category comparison, product research, retailer selection, or troubleshooting. A generic awareness objective is too broad to diagnose.
    • Define an exposure. Establish whether the platform reports a served impression, visible placement, interaction, click, conversation, or another unit. Do not compare CPMs until you know what the impression represents.
    • Name one primary outcome. Choose incremental qualified visits, incremental orders, incremental contribution, or qualified pipeline. Treat impressions and clicks as diagnostic signals rather than proof of growth.
    • Set the economic boundary in advance. Calculate the maximum acceptable acquisition cost or minimum contribution return from your own unit economics. If the required commitment would displace a proven campaign or consume the budget needed for a valid control, wait.
    • Specify the control. Use an unexposed geography, audience, eligible period, or other comparable unit where the placement will not run. If the seller cannot support or tolerate a credible comparison, classify the investment as exploratory rather than performance-proven.
    • Preserve evidence. Export the available delivery, market, tier, placement, creative, billing, and outcome data. Note reporting-definition changes so a product update is not mistaken for a performance change.
    • Set a stop rule. Decide what level of economic loss, reporting failure, brand-safety concern, or control contamination ends the test. The novelty of the format is not a reason to ignore an invalid experiment.

    Keep paid presence separate from earned AI visibility

    A sponsored brand appearing near a recommendation is not the same as a model selecting, citing, or mentioning that brand without payment. Early placements may influence the journey indirectly by making a sponsored retailer more prominent among recommendations, even when the underlying answer is presented as independent from the ad.

    Measure three lanes separately:

    • Paid AI delivery: eligible exposure, served placements, interactions, clicks, cost, and available conversion signals.
    • Earned AI visibility: unaided brand mentions, citations, recommendation presence, and factual accuracy across a fixed set of representative prompts.
    • Business effect: incremental visits, qualified leads, new customers, revenue, and contribution against a control or credible baseline.

    This separation protects your AEO and GEO work from a false success signal. Paid exposure can increase while unpaid recommendation visibility falls, or an AI system can mention the brand more often without creating profitable demand. Neither outcome should be credited to the other without a test.

    Move budget according to marginal contribution

    The AI shift does not make established channels irrelevant. IAB/PwC figures put U.S. search advertising revenue at $114.2 billion in 2025 within a $294.6 billion digital advertising market. Digital video reached $78 billion after 25.4% growth, while social reached $117.7 billion after 32.6% growth. The ten largest companies controlled 84.1% of the market.

    Those market totals describe where money went, not where your next dollar belongs. A rapidly growing channel can be unprofitable for your offer, while a slower-growing channel can still produce strong incremental contribution. Concentration also means the same large platforms often control inventory, optimization, and attribution. Use their reporting to manage campaigns, but require independent business outcomes or controlled lift before treating claimed conversions as proof.

    Use a repeatable capital-allocation cycle

    1. Rank current channels by marginal contribution. Use the most recent credible spend change or controlled test, not lifetime average ROAS.
    2. Choose the next observable budget block. It should be large enough to create a measurable change but small enough that a weak result does not materially damage the plan.
    3. Estimate the expected range. Record a low, central, and high outcome using evidence from your tests and unit economics. Do not convert an uncertain pilot into a single precise forecast.
    4. Move one block from the weakest expected marginal use to the strongest. Keep major promotions, pricing changes, and other confounders visible so they do not receive advertising credit.
    5. Remeasure after the change. Marginal returns usually change with spend. A channel that deserved the previous increase does not automatically deserve the next one.

    It also helps to classify spending by purpose. Core campaigns have repeatable causal and economic evidence. Experimental campaigns buy information about new inventory, audiences, or creative. Verification spending retests old assumptions after platform, product, or market changes. A brand-defense campaign may remain strategically valuable despite low measured incrementality, but label it as protection rather than presenting it as growth. That makes the trade-off explicit.

    Key takeaways

    • Platform ROAS measures attributed performance; it does not establish how much revenue advertising caused.
    • Incrementality tells you whether a campaign created an outcome that would not otherwise have occurred.
    • Marginal contribution, not blended ROAS, should determine whether the next budget increase is economically sound.
    • Conversational AI ads need a defined exposure unit, control, business outcome, economic limit, and stop rule before a substantial commitment.
    • Paid AI placements, earned AI visibility, and business impact belong in separate measurement lanes.
    • Market growth identifies where advertisers are moving, but your own causal evidence and unit economics should determine where you move.

    For your next budget review, replace the single ROAS column with six fields: attributed return, incremental lift, incremental contribution, marginal return, confidence level, and next test. Mark an untested channel as unproven rather than successful or failed. Then fund the next measurable budget block where the expected marginal contribution is strongest. AI formats will keep changing; that decision discipline will remain useful even when the placements do not.

    References


  • AI Search Adoption Is Unequal: How Brands Should Respond

    AI Search Adoption Is Unequal: How Brands Should Respond

    If your search strategy begins with the assumption that everyone is moving from Google to ChatGPT at roughly the same pace, stop before you move the budget. The shift is real, but the average adoption figure hides the people, circumstances, and confidence levels driving it.

    You need a strategy that serves confident AI-search users without making conventional search worse for everyone else. That means maintaining two discovery paths, designing AI features as optional assistance, and measuring who benefits rather than treating every AI interaction as progress.

    The average adoption number hides different search realities

    In UK monitoring that began in early 2025, 27% of users said they regularly used ChatGPT. That topline becomes much less useful once household income enters the picture: higher-income households were substantially more likely to use generative AI tools.

    Treat that result as a segmentation signal, not a universal market adoption rate. It tells you that AI use can cluster around particular audiences. It does not tell you that every high-income person uses AI, that lower-income users lack interest, or that the same distribution applies in every country and category.

    Income matters partly because it sits alongside several mechanisms that affect whether someone makes AI part of a normal search journey:

    • Access: Can the person readily use the relevant tool in the context where the question arises?
    • Exposure: Do their workplace, peers, or professional routines encourage them to use AI? People in digital and corporate environments may encounter more prompts to incorporate it into daily work.
    • Capability: Can they frame a useful request, add context, refine a weak response, and inspect the supporting material?
    • Confidence: Do they trust themselves to use the interface and know when an answer needs checking?

    These factors reinforce one another. Frequent exposure builds skill. Skill can improve results. Better results can increase confidence and make the tool feel like the natural place to begin the next task. Someone without that loop may try the same interface once, receive an unhelpful answer, and return to a familiar search box.

    Trust also needs context. Perplexity users have reported high trust while the platform remains comparatively niche. Strong confidence inside a self-selecting user group is not proof of broad public confidence. It may simply describe the people who chose that tool and stayed.

    This is where an average can misdirect strategy. A revenue-weighted customer view may make AI search appear nearly universal if affluent decision-makers are overrepresented among early adopters. A traffic-weighted view may make it look marginal if the larger audience still relies on conventional results. Neither view is sufficient by itself.

    Before reallocating search investment, audit four questions for each important audience:

    1. Where does this audience normally encounter the problem: at work, at home, during a purchase, or while learning?
    2. Which interface do they use to begin, and which interface do they use to verify?
    3. What capability does the journey assume, such as prompting, comparing options, or checking citations?
    4. What happens when confidence fails: do they reformulate, open a conventional result, ask another person, or abandon the task?

    Do not use household income as a shortcut for individual behavior. Use it, when legitimately available and appropriately governed, as one possible research variable. Behavioral evidence such as entry path, repeated feature use, verification actions, and successful task completion is more useful for designing an experience.

    Build one evidence base for two discovery paths

    A shared foundation of connected content and evidence supports both an abstract conventional search interface and an abstract conversational AI interface.

    You do not need an AI site and a non-AI site. You need one dependable body of content that can support two ways of exploring it.

    Journey stageConventional search behaviorAI-search behaviorWhat your content must provide
    Frame the problemEnters a short query and scans resultsDescribes a situation and refines it through follow-up promptsA direct statement of the problem, audience, scope, and relevant terminology
    Compare optionsOpens several pages and compares claims manuallyRequests a synthesis, shortlist, or side-by-side explanationConsistent attributes, explicit differences, limitations, and decision criteria
    VerifyChecks the page, publisher, evidence, and supporting materialInspects citations or leaves the answer to check the underlying pageVisible evidence, clear authorship, dates where relevant, and traceable claims
    ActNavigates to a product, form, store, or next-step pageActs on a shortlist and may enter the site late in the journeyAccurate facts and an obvious next action that does not depend on AI

    The shared content layer matters because optimization for AI discovery cannot rescue weak information. A machine-readable page that never gives a clear answer is still unclear. A polished conversational response built from unsupported claims is still unsupported.

    For every high-value page, make the evidence layer usable in both paths:

    • Lead with the decision-relevant answer. State who the page is for, what question it resolves, and where the answer changes by circumstance.
    • Name entities consistently. Use the same product, organization, service, location, and category names throughout the visible content and metadata.
    • Expose comparison attributes. If a buyer must compare eligibility, compatibility, availability, process, or limitations, place those facts in plainly labelled sections rather than implying them through promotional copy.
    • Separate fact from judgement. Make it obvious which statements describe a documented feature and which represent your recommendation or interpretation.
    • Show evidence near the claim. A reader should not have to hunt through a generic resources page to discover what supports an important assertion.
    • Keep structured data aligned with visible content. JSON-LD should clarify the entities and relationships already present on the page, not introduce claims that visitors cannot verify.
    • Preserve a complete human-readable route. Do not require an AI assistant to reveal essential instructions, terms, limitations, or next steps.

    This approach lets conventional SEO, answer engine optimization, and generative engine optimization share the expensive part of the work: producing content precise enough to retrieve, interpret, compare, and verify. The delivery layer can vary without creating competing versions of the truth.

    Prioritization should reflect audience value without turning early adopters into a stand-in for the market. Fast adopters often include decision-makers and higher-income consumers, so AI visibility may deserve early investment even when total usage remains limited. The correct conclusion is to add coverage for an influential segment, not to remove coverage from everyone else.

    Add AI interfaces as assistance, not as a gate

    People choose between a conventional search panel and an optional conversational assistant while using a range of devices and accessibility methods.

    An on-page AI button can shorten a difficult task. It can also add ambiguity, expose visitors to weak generated output, or hide information behind an interface they do not want to use. The debate around AI buttons spans usability benefits, SEO risk, and fears of AI poisoning, so the useful question is not whether a button looks innovative. It is whether it helps a defined user complete a defined job safely.

    Start with the verb. Labels such as Summarize this policy, Compare these plans, or Ask about eligibility tell the visitor what the feature will do. A vague AI button asks the visitor to understand the technology before understanding the benefit, which creates exactly the kind of confidence barrier you are trying to reduce.

    Use six release gates before putting an AI interface into a search or content journey:

    1. Defined task: Write down the user job in one sentence. If the feature is meant to summarize, compare, explain, or route, choose one primary job and design for it.
    2. Optional path: Confirm that a visitor can reach the same essential information and next action without opening the AI experience.
    3. Clear boundary: Tell users what information the assistant uses and what it cannot determine. Do not invite sensitive or consequential input merely because a free-text box makes that possible.
    4. Grounded output: Make the response traceable to the approved page content or other clearly identified material. AI poisoning, in this context, is the risk that manipulated content or instructions distort what the system produces; limiting and validating the material available to the feature reduces the opportunity for that distortion.
    5. Recovery route: Provide a visible way to open the relevant page section, inspect supporting details, start over, or continue through the standard journey when the response is unhelpful.
    6. Success measure: Define success as task completion or a meaningful next step, not the number of times the button is clicked.

    Progressive enhancement is the right operating principle. Publish the essential content in stable, accessible HTML. Keep navigation, forms, and core actions usable without generated assistance. Then add the AI layer where summarization, comparison, or conversational clarification removes genuine work.

    This also protects the conventional search journey. If important information exists only inside a generated interaction, users cannot reliably scan it before opting in, and the standard page no longer carries the complete answer. The feature has stopped being assistance and become a gate.

    Test the full experience, not just whether the button opens. Check keyboard operation, focus order, labels, loading and error states, generated links, narrow screens, and the non-AI fallback. Review sample outputs for unsupported claims, missing qualifications, inconsistent names, and recommendations that exceed the page’s evidence.

    Measure adoption without averaging away inequality

    A single AI engagement rate cannot tell you whether the feature broadens access or merely serves the people who were already confident enough to try it. Build reporting around exposure, use, usefulness, recovery, and outcome.

    • Eligible exposures: How many visits actually encountered the feature on a relevant page?
    • Activation rate: Of those eligible visits, how many initiated the feature?
    • Task completion: How many users reached the intended next step after using it?
    • Fallback rate: How often did users leave the AI flow for the standard page, search, navigation, or support route?
    • Correction signals: How often did users regenerate, reformulate, dispute, or abandon the response?
    • Downstream outcome: Did the interaction support the real goal, such as finding the right page, understanding a requirement, completing a form, or making an informed selection?

    Break these measures down by relevant, ethically collected context. Useful views may include entry channel, task, first-time versus returning visit, exposure to the AI feature, prior feature use, and voluntarily reported confidence. If your organization has a legitimate basis for audience or income research, keep that analysis aggregated and governed rather than turning a population-level pattern into an assumption about an individual.

    Read the combinations, not just the totals:

    • Low activation and high completion can mean the feature is useful once discovered, but its label, placement, or trust cues are weak.
    • High activation and high fallback can mean curiosity is strong while output quality, task fit, or confidence is poor.
    • Strong outcomes concentrated among experienced users can mean the interface rewards existing AI literacy rather than reducing the skill barrier.
    • Rising AI engagement alongside falling conventional completion can mean the new interface is disrupting the baseline journey instead of improving it.
    • High commercial value from a small AI-search cohort can justify targeted investment, but it does not justify treating that cohort’s behavior as universal.

    Keep external AI discovery separate from on-site AI usage. Mentions, citations, referrals, assisted visits, and landing-page behavior describe visibility outside your site. Button activations, response quality, fallback, and completion describe the experience you control. Combining them into one AI score makes it harder to identify whether the problem is discoverability, content quality, interface design, or audience readiness.

    Your investment decision should follow the constraint. If the right audience cannot find you in AI-generated results, improve retrievability, entity clarity, and evidence. If people arrive but cannot verify the answer, strengthen the page. If an AI feature attracts clicks but blocks completion, fix or remove the feature. If conventional search still carries most successful journeys for an important audience, maintain it.

    Key takeaways

    • Do not use an average AI-adoption rate as your audience model; segment by behavior, context, exposure, capability, and confidence.
    • Treat income-linked adoption as a planning signal, not as a rule about any individual user.
    • Build one verifiable content base that supports both conventional search and conversational discovery.
    • Keep AI buttons optional, label them by the job they perform, and preserve the complete non-AI route.
    • Measure task completion, fallback, correction, and downstream outcomes by cohort; a click on an AI feature is not success.
    • Invest early where AI-search users are commercially important, but do not weaken the search paths used by the rest of your audience.

    Your next move is not to choose between SEO and AI search. Take one high-value customer journey, draw its conventional and conversational paths, inspect the shared evidence beneath both, and define the cohort-level measures before adding another AI feature. If you cannot see who gains, who struggles, and how either group recovers, the experience is not ready to scale.

    References


  • How to Choose an AI Search Optimization Agency in 2026

    How to Choose an AI Search Optimization Agency in 2026

    If you are comparing AI search optimization agencies, the hard part is not finding firms that promise more visibility. It is identifying which one can turn your content, technical foundation, brand knowledge, and authority into a coherent program without selling you a renamed SEO retainer.

    Your decision should leave you with a defined problem, an evidence standard, and a clear ownership model. Choosing well means testing an agency’s experience, previous work, AI expertise, and fit with your brand. Because discovery now extends into LLM and AI-driven search experiences, conventional ranking reports cannot carry the whole business case.

    Define the job before you ask agencies to solve it

    AI search optimization is not a single deliverable. It is a set of connected activities intended to make your brand and content easier for AI systems to retrieve, understand, represent accurately, cite, and recommend when the context warrants it.

    That distinction matters during procurement. If your brief says only that you want to improve AI visibility, every agency can interpret the assignment in a way that matches what it already sells. One may propose content production, another may lead with JSON-LD, and another may offer a monitoring dashboard. Those services can be useful, but none is a strategy by itself.

    Start by defining the change you want across four layers:

    • Representation: AI-generated answers describe your company, products, people, and claims accurately.
    • Discovery: your brand or content appears for relevant questions where you have a legitimate reason to be included.
    • Evidence: the answer can connect its claims to useful, authoritative pages rather than merely mentioning your name.
    • Action: the visibility supports a sensible next step, such as visiting a product page, reading supporting evidence, comparing options, or contacting your team.

    This framing prevents a common measurement mistake. A brand mention, a linked citation, an accurate recommendation, a referred visit, and a qualified conversion are not interchangeable outcomes. Record them separately. Otherwise, a dashboard can show improvement while the answers remain inaccurate or commercially irrelevant.

    Your agency brief should give every contender the same operating context:

    • Your priority products, services, audiences, markets, and buyer situations.
    • The questions people ask while identifying a problem, comparing approaches, checking trust, and making a decision.
    • The pages, databases, documentation, and internal experts that act as your sources of truth.
    • Claims that require legal, compliance, technical, or subject-matter approval.
    • Your current content, development, analytics, public relations, and editorial resources.
    • The systems the agency may advise on and the systems it will actually be allowed to change.
    • The business outcomes you ultimately care about, along with the earlier signals you can observe before those outcomes occur.

    Include a baseline rather than asking the agency to invent one after work begins. For each important question, save the exact wording, the AI service used, the date, the resulting answer, any linked citations, and whether the brand representation was accurate. Keep the relevant landing-page and conversion data alongside those observations when available.

    A useful objective might be: improve accurate inclusion and citation for priority decision questions, direct qualified visitors toward authoritative pages, and establish a repeatable process for finding and fixing representation gaps. It is specific enough to guide a proposal without pretending that you control an external answer engine.

    Inspect whether the strategy works as a connected system

    Five connected modules feed a central translucent AI core, while one isolated module remains outside the working system.

    A credible agency should be able to explain how audience demand, content, entity signals, technical access, outside authority, and measurement reinforce one another. It does not need to perform every activity itself. It does need to identify the dependencies and tell you who owns each one.

    Question and intent discovery

    Keyword research is useful input, but it does not fully describe the questions people put to an assistant. Ask how the agency will build a working set of questions from customer language, sales objections, support issues, product comparisons, documentation gaps, and conventional search demand.

    The result should be organized by user task, not presented as a shapeless list of prompts. Someone defining a problem needs a different answer from someone comparing vendors or checking whether a solution fits a regulated workflow. That difference affects the required evidence, page format, and appropriate call to action.

    Watch for invented precision. A prompt list becomes useful when the agency can explain why each question matters, which audience it belongs to, what a good answer must contain, and which page should support it. A large list with no decision context is inventory, not strategy.

    Content and entity clarity

    The agency should examine whether your pages answer the target questions clearly and whether the supporting claims are specific, consistent, and attributable. It should also distinguish between a missing page and a weak page. Publishing something new when an existing authoritative page needs a clearer answer can create duplication and split maintenance effort.

    For each priority page, the plan should identify its subject, intended audience, direct answer, supporting evidence, related entities, internal links, maintenance owner, and next action. This turns vague advice such as improve content quality into an editable specification.

    Entity consistency matters as well. Product names, company relationships, leadership details, service areas, and other defining facts should not conflict across core pages and structured data. Ask how the agency will find discrepancies and decide which internal record is authoritative before it recommends markup or rewrites.

    Technical access and structured data

    The technical review should cover whether important information is available on stable, indexable URLs; whether internal links make relationships understandable; whether canonicalization or access rules create conflicts; and whether templates hide, fragment, or duplicate key answers.

    JSON-LD belongs in this workstream, but it should describe facts that users can verify on the page. Structured data can clarify the type of entity or content being presented and expose defined relationships in a machine-readable form. It cannot manufacture expertise, prove an unsupported claim, or rescue content that never answers the question.

    Ask for a structured data inventory rather than a promise to add schema. The inventory should connect each proposed type and property to a visible fact, a source-of-truth field, an eligible page template, a validation method, and an owner responsible for keeping the information current.

    Authority, distribution, and measurement

    An on-site plan is incomplete if it ignores how the brand is represented elsewhere. Relevant mentions, expert contributions, documentation, original evidence, partnerships, public relations, and other legitimate forms of distribution can help establish context beyond your own domain. The agency should explain which activities are justified by the audience and where another team must participate.

    Measurement completes the system. The agency should connect each recommendation to an observable change: a clearer answer on the page, corrected entity information, valid structured data, stronger citation coverage, more accurate AI representation, useful referred traffic, or a downstream business action. If the plan jumps from publishing content directly to revenue without showing the intermediate signals, you will struggle to diagnose either success or failure.

    Test agency claims with evidence, not vocabulary

    Most contenders can discuss AEO, GEO, AI SEO, entities, retrieval, citations, and structured data. Terminology tells you that the team follows the market. It does not tell you whether the team can diagnose your situation, prioritize work, implement recommendations, or separate its contribution from unrelated changes.

    Use the same evidence request for every finalist:

    Evaluation areaAsk to seeEvidence that matters
    Relevant experienceA comparable, sanitized case narrativeThe starting condition, diagnosis, intervention, implementation owner, observed change, and limits of the result
    AI search expertiseA live explanation of one priority question and pageClear reasoning across intent, answer quality, entities, technical access, authority, and measurement
    MeasurementA sample baseline and recurring reportRaw prompts, captured answers, citations, accuracy judgments, dates, page metrics, and change history behind any summary score
    ImplementationA sample content brief, technical ticket, or schema specificationNamed owners, dependencies, acceptance criteria, quality checks, and a route from recommendation to release
    Brand fitAn explanation of how the plan changes for your audience and constraintsChoices tied to your products, source material, risk, market, workflow, and business goals
    Commercial clarityA scope showing included and excluded workSeparate visibility into strategy, tools, production, development, outreach, reporting, and optional work

    Do not accept a case study that starts with a result. Ask what was happening before the work, what changed, what else changed at the same time, and what evidence would weaken the agency’s interpretation. A team that can discuss confounding factors and uncertainty is giving you more useful information than one presenting a smooth success story with no audit trail.

    A working session is especially revealing. Give each finalist the same page, target audience, and small group of priority questions. Ask the team to talk through what it would inspect first, which assumptions it would verify, what it would avoid changing prematurely, and how it would turn the diagnosis into tasks. You are assessing the reasoning process, not asking for unpaid strategic work.

    Ask who will actually do the work after the sales process. You need to know which roles will handle strategy, content, technical analysis, JSON-LD, analytics, and project management; whether those people are assigned to your account; and where subcontractors or software-generated work enter the process. Senior expertise in a pitch has little value if delivery depends on an unnamed team using an undefined workflow.

    Several claims deserve immediate scrutiny:

    • Guaranteed placement in generated answers. An agency cannot control the output of an external AI service, so it should promise defined work and transparent measurement rather than a specific placement.
    • A proprietary visibility score with no underlying observations. A score can summarize data, but you still need access to the prompts, outputs, citations, classification rules, and sampling conditions behind it.
    • Schema as the complete solution. Markup is one technical layer and should be connected to accurate visible content, source-of-truth data, and ongoing maintenance.
    • Content volume as the primary strategy. More pages can add duplication, inconsistent claims, and editorial debt when question coverage and page purpose have not been mapped first.
    • A monitoring dashboard presented as optimization. Monitoring can expose a problem; it does not research, edit, implement, validate, distribute, or govern the fix.
    • AI search results credited entirely to ordinary organic growth. Ask the agency to separate conventional search improvement, branded demand, public relations activity, product changes, and AI-specific observations wherever the available evidence allows.
    • Recommendations with no implementation owner. A technically correct audit still fails if nobody can convert it into approved changes in your CMS, codebase, data layer, or editorial process.

    Build your scorecard before proposals arrive. Evaluate strategic fit, evidence quality, technical breadth, content judgment, measurement rigor, implementation clarity, governance, team continuity, and commercial transparency. Decide which criteria matter most for your current constraint. A company with strong in-house developers may need strategic and editorial depth, while a lean team may need a partner that can carry more implementation.

    Put measurement, ownership, and change control in the scope

    A conference table displays an evidence portfolio, a balance, verified tokens, and a locked asset box with a key.

    AI-generated answers can vary with prompt wording, service, context, and time. That makes a single screenshot weak evidence. It does not make measurement pointless. It means the method must preserve enough context for you to distinguish an observation from a trend and a trend from a business outcome.

    For each monitored question, the measurement record should retain:

    • A stable identifier, exact wording, audience, intent, and market or language context when relevant.
    • The AI service, capture date, and other available execution context.
    • The complete answer or a faithful stored capture, not only a yes-or-no brand mention.
    • Whether the brand appears, what role it is assigned, and whether the description is accurate.
    • Every visible citation and whether it points to your site, another source, or no accessible supporting page.
    • The owned page intended to answer the question and its publication or revision history.
    • Referred visits, meaningful on-site actions, and business outcomes when those can be observed responsibly.

    Keep three layers separate in reporting. Visibility observations describe what appeared. Quality judgments describe whether the answer and citation were useful and accurate. Business outcomes describe what people did. Combining all three into one number hides the very information you need for prioritization.

    Require a change log beside the baseline. It should connect recommendations to approved work, affected URLs or templates, release dates, validation results, and subsequent observations. Without that record, the agency can report movement but cannot show which intervention may have contributed to it.

    The scope should also resolve ownership before work starts:

    • Who approves the question set and can add or retire monitored questions.
    • Who controls analytics, monitoring, CMS, schema, repository, and reporting access.
    • Who supplies subject-matter evidence and approves sensitive claims.
    • Who writes, edits, develops, validates, publishes, and maintains each type of change.
    • Who owns the resulting briefs, dashboards, configurations, structured data specifications, and historical captures.
    • How open recommendations and data are handed over if the engagement ends.

    Retain administrative control of your own site, analytics, and core business data. Give the agency the access required for its role, but avoid making your ability to operate dependent on an account only the vendor controls. The same principle applies to prompt histories and reporting data: you should be able to inspect and export the evidence used to evaluate performance.

    If uncertainty remains, use a bounded pilot to test the working relationship. Give it a defined audience, question set, group of pages, deliverables, implementation route, evidence method, and decision point. The purpose is to learn whether the agency can diagnose, communicate, ship, and measure within your environment. A short pilot should not be treated as proof that every market-level outcome will move.

    Compare the cost of the full operating model, not only the agency fee. A proposal may exclude monitoring software, content production, development, design, public relations, or subject-matter review. Make those dependencies visible so a cheaper retainer does not become the more expensive program after implementation begins.

    Key takeaways before you sign

    • Define AI visibility as a set of observable outcomes: accurate representation, relevant inclusion, useful citations, qualified action, and business impact.
    • Give every agency the same priority audiences, questions, pages, constraints, baseline, and implementation boundaries.
    • Look for a connected strategy spanning intent, content, entities, technical access, structured data, authority, distribution, and measurement.
    • Ask for raw evidence behind case narratives and visibility scores, including prompts, answers, citations, dates, changes, and limitations.
    • Reject guaranteed placements, schema-only plans, volume-first content programs, and dashboards presented as complete optimization.
    • Put owners, access, deliverables, acceptance criteria, change history, data control, handover, and excluded costs into the scope.

    Your next move is straightforward: choose one important audience, one decision journey, a manageable set of questions, and the pages that should support the answers. Capture the baseline, send the same brief to each finalist, and require each team to show how it would move from diagnosis to an implemented, measurable change.

    Select the agency whose reasoning remains clear when the evidence is incomplete. The right partner will make assumptions visible, define what it can and cannot control, and leave your organization with a stronger operating system for AI discovery rather than a collection of unexplained tactics.

    References