Tag: AI Strategy

  • AI Agent Adoption in 2026: A Practical Market Guide

    AI Agent Adoption in 2026: A Practical Market Guide

    If you are deciding whether to deploy an AI agent, do not start with the market leader. Start with the job you need completed, the systems the agent may touch, and the consequences when it stops halfway through.

    The market is growing while its center of gravity weakens. Tracked AI agent usage rose from 142 million aggregate monthly active users in Q3 2025 to 293 million in Q3 2026, but the four largest platforms’ combined share fell from 58.6% to 49.3%. That is the environment you are buying into: rapid adoption, many credible specialists, and no safe assumption that one platform will own every workflow.

    The market is expanding faster than any one leader

    An AI agent is more than a chatbot with a new label. It accepts a goal, breaks that goal into subtasks, chooses actions as conditions change, and works across tools or systems until it reaches an end state. A single-turn assistant does not meet that definition. Neither does an orchestration framework such as LangGraph or Bedrock AgentCore, which helps developers build agents, nor a classification model that chooses a route without pursuing a goal of its own.

    This distinction protects you from buying the wrong layer. A chat license may improve drafting without automating a process. A framework may give your engineering team control without supplying a ready-to-use worker. A fast decision model may make an agent cheaper and safer without replacing the agent itself.

    The following snapshot covers selected leaders from a 40-platform market tracked between May 15 and September 10, 2026. The estimates combine company disclosures, app-store telemetry, procurement records, and account-level observations. They measure platform reach rather than unique people, so someone using several agents can appear in several platforms’ totals.

    AgentPrimary useEstimated MAUsQ3 2026 shareQuarter-over-quarter growth
    ChatGPT AgentMulti-step research, booking, and file work58.9M20.1%+16%
    Microsoft 365 CopilotDocument and Office workflow agents33.4M11.4%+13%
    GitHub Copilot AgentTurning bug reports into code fixes26.7M9.1%+11%
    Gemini Agent ModeBrowser automation and form completion25.5M8.7%+19%
    Claude CodeRepository-wide refactoring and test generation19.3M6.6%+24%
    CursorMulti-file changes inside the editor13.5M4.6%+8%
    OpenAI AtlasSite navigation and transactional tasks11.7M4.0%+27%
    Perplexity CometAgentic browsing, comparison, and checkout10.8M3.7%+22%
    Salesforce AgentforceSupport deflection and CRM pipeline hygiene9.1M3.1%+15%
    Grok BotPersistent work on a cloud computer7.9M2.7%New
    All other agentsVertical, open-source, and smaller platforms45.1M15.4%+14%

    Market-share loss does not necessarily mean user loss. ChatGPT Agent’s share declined from 24.9% in Q3 2025 to 20.1% in Q3 2026 while its estimated users increased from 35.4 million to 58.9 million. Microsoft 365 Copilot and GitHub Copilot Agent also added users while losing relative share. New entrants and expanding specialists diluted the incumbents because the total market grew faster than they did.

    Use market share to assess reach, integration momentum, talent availability, and the likelihood that a product will remain supported. Do not use it as a proxy for successful task completion. The practical response to fragmentation is portability: retain task definitions, approval rules, logs, evaluation cases, and critical business data in systems you control wherever possible. Switching agents should not require rebuilding your operating knowledge from scratch.

    Choose a workflow category before you choose a vendor

    There is no single AI agent market in operational terms. Coding, browser automation, enterprise productivity, CRM work, personal assistance, and long-running general-purpose work have different tools, permissions, failure modes, and definitions of success.

    Coding is currently the largest category, representing 24.8% of tracked agent usage. Even there, the products are not interchangeable. GitHub Copilot Agent is positioned around taking a bug report through to a finished fix. Claude Code emphasizes repository-wide changes and tests. Cursor centers work in the editor, Replit Agent spans prototype-to-deployment creation, and Amazon Q Developer focuses on cloud and coding operations.

    The same specialization appears outside software development. Microsoft 365 Copilot sits inside Office workflows. Salesforce Agentforce works inside CRM processes. Gemini Agent Mode, OpenAI Atlas, and Perplexity Comet concentrate on browser actions, but their stated strengths range from form completion to transactional navigation and comparison-led checkout. A generic request for the “best agent” hides these material differences.

    Write an outcome brief before requesting demonstrations

    A useful evaluation begins with a workflow that has an observable finish. Document these elements before you shortlist products:

    • Goal: State the result the agent must produce or the action it must complete.
    • Starting state: Identify the request, file, ticket, record, or event that begins the run.
    • Permitted systems: List the applications, data, credentials, and tools the agent may use.
    • Definition of done: Describe the final artifact or system state precisely enough that a reviewer can mark it complete or incomplete.
    • Approval gates: Specify where a person must approve publishing, payment, deletion, external communication, code deployment, or another consequential action.
    • Stop conditions: Tell the agent what uncertainty, missing permission, policy conflict, or unexpected state requires escalation.
    • Recovery requirement: Define what the agent must log, preserve, or reverse when it cannot finish.

    For an SEO team, “help with a content audit” is too loose to evaluate. A testable workflow identifies the properties to crawl, the fields to collect, the rule for classifying each page, the destination for the findings, and whether the agent may change a live page. The clearer the end state, the easier it becomes to compare products without being distracted by fluent demonstrations.

    Adopt at the workflow level rather than declaring an organization-wide agent strategy first. A company may reasonably use one agent for repository work, another for CRM operations, and another for browser research. Fragmentation becomes manageable when every deployment has a named job and a shared governance model.

    Completion rate is the buying metric that corrects popularity
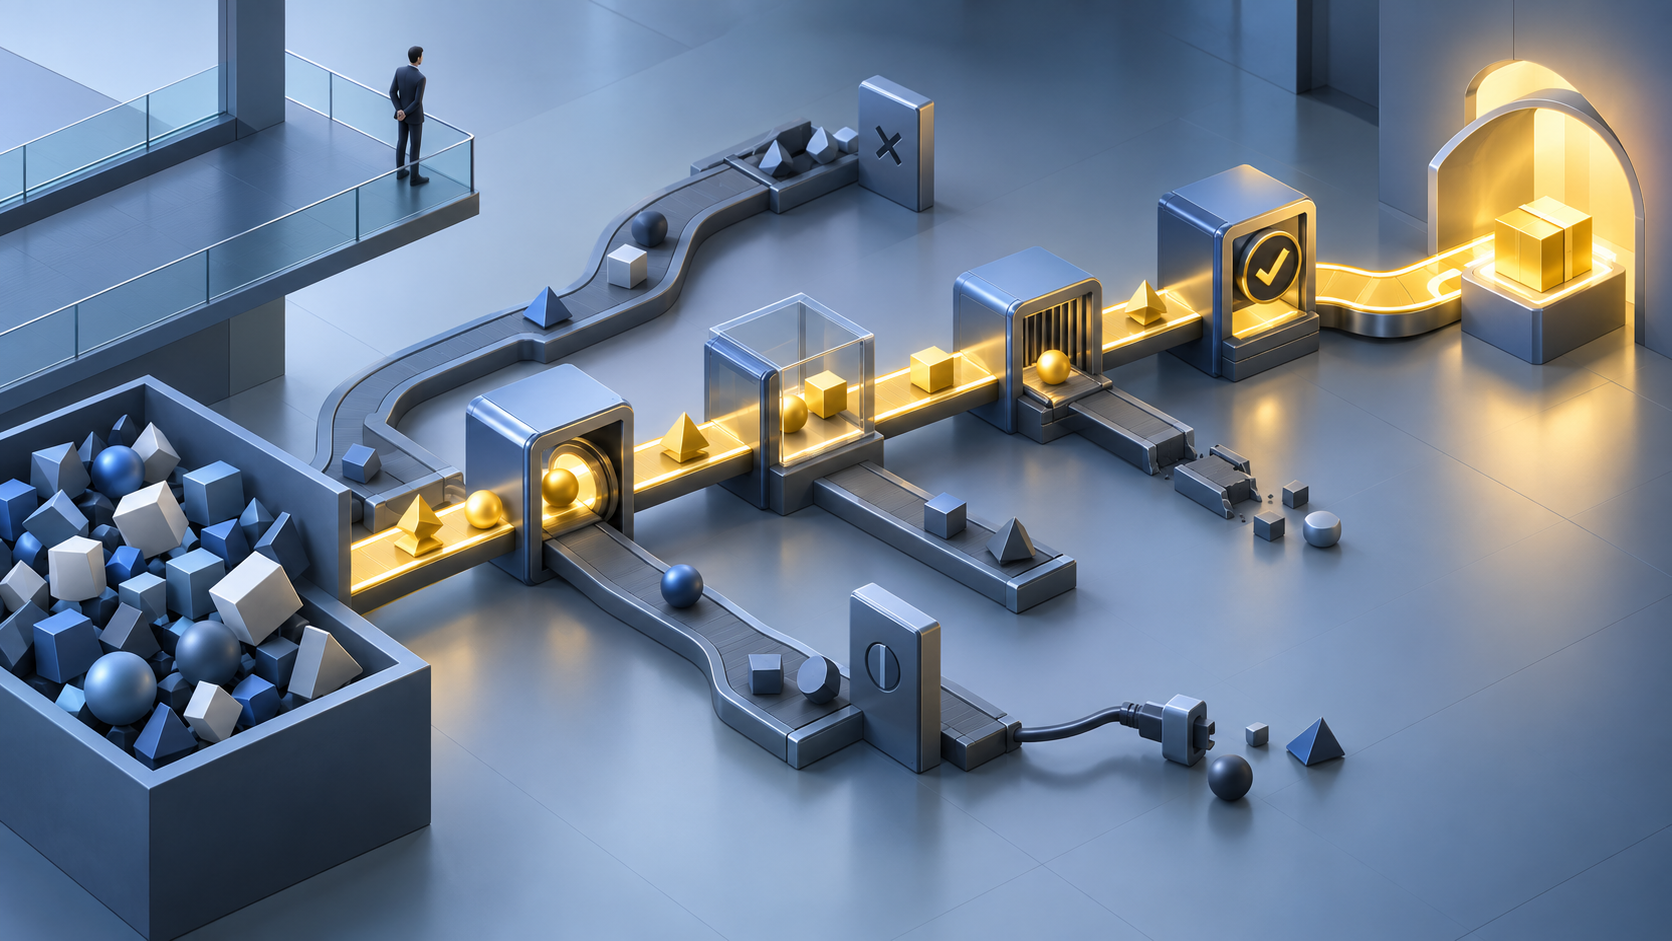
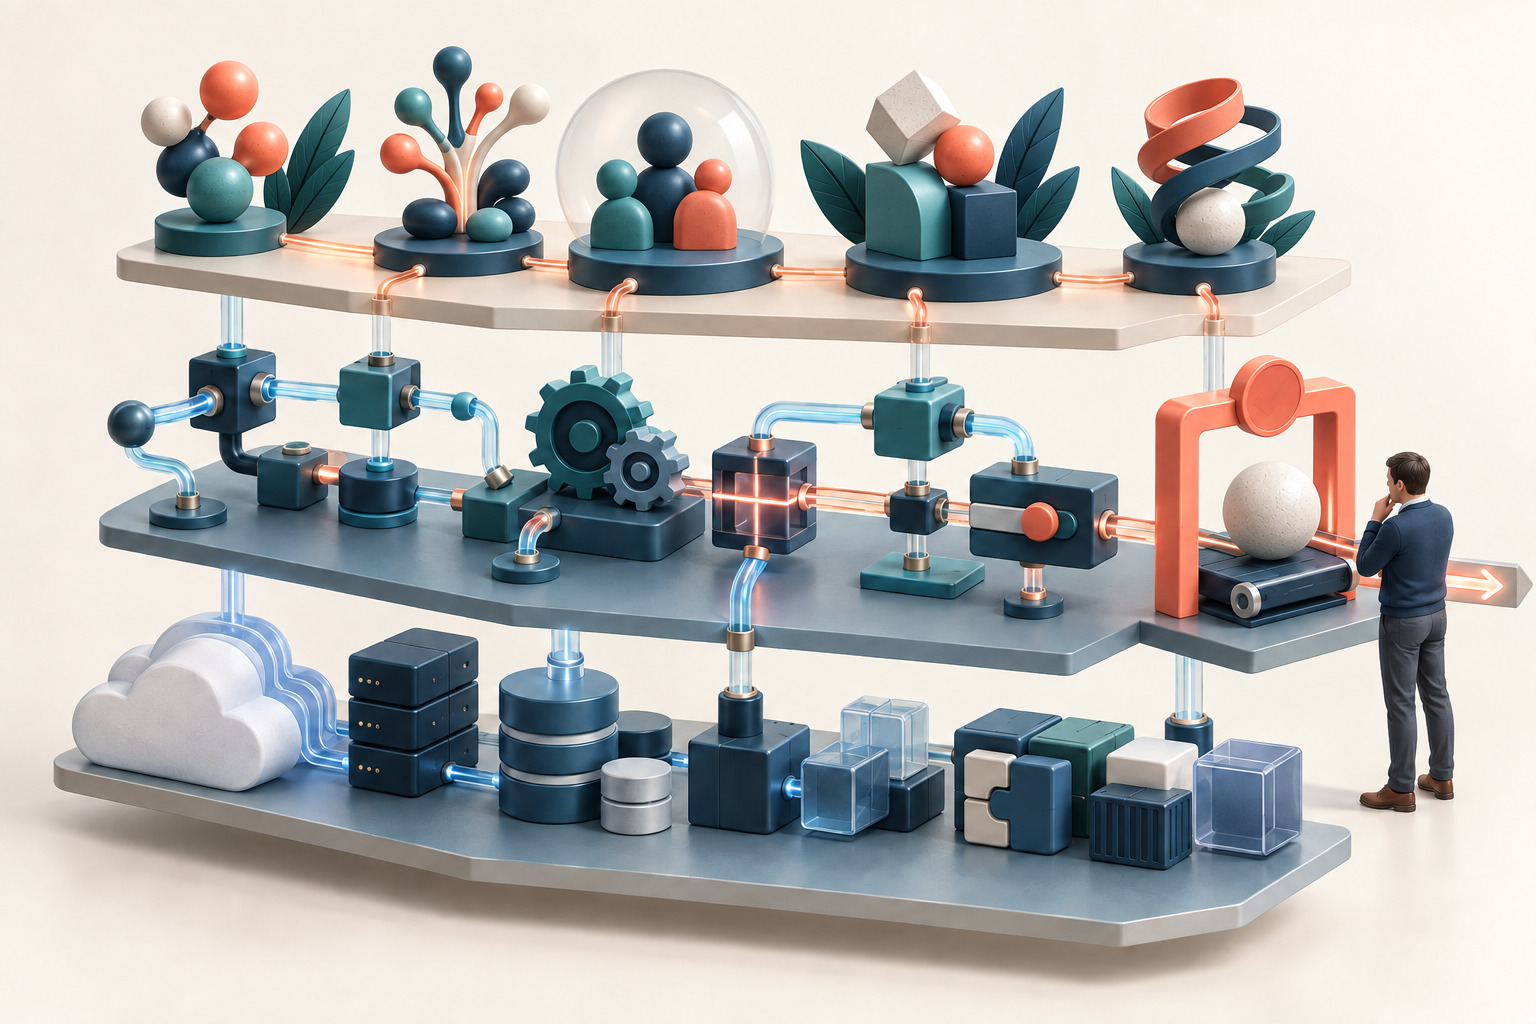
    An automated workflow passes through connected stations to a completed package while several alternate routes stop at incomplete handoffs.

    Monthly active users tell you that people invoked a platform. They do not tell you whether it finished the job. For an autonomous workflow, the more relevant question is simple: what percentage of eligible runs reaches the defined end state without a person correcting the agent?

    One standardized comparison required each platform to attempt 48 multi-step tasks across five trials, producing 240 runs per platform. A run counted as complete only when it finished end to end without human correction. Claude Code led at 72.1% unassisted completion, followed by ChatGPT Agent at 65.3% and Grok Bot at 63.7%. Gemini Agent Mode reached 59.6%, GitHub Copilot Agent 57.2%, and Cursor 55.8%.

    Those figures are useful for shortlisting, not for forecasting your deployment. The task mix may not resemble your workflow, and an agent’s performance changes with tool access, permissions, data quality, integration depth, and the exact definition of completion. Claude Code’s result is especially relevant to repository work; it does not establish that a coding agent is the best choice for CRM cleanup or browser checkout.

    Speed also needs context. In that benchmark, OpenAI Atlas had a median completion time of 4 minutes 51 seconds and Perplexity Comet 4 minutes 39 seconds, while ChatGPT Agent took 8 minutes 52 seconds and Grok Bot 19 minutes 14 seconds. A fast incomplete run is not efficient. A slower run may still be preferable if it completes more often, requires fewer interventions, or handles a more complex job.

    Measure the run, not the demo

    Your pilot dashboard should separate these outcomes instead of compressing them into a vague satisfaction score:

    • Unassisted completion rate: Eligible runs that reach the defined end state with no corrective intervention.
    • Partial completion rate: Runs that create useful progress but fail to reach the required state.
    • Intervention rate: Runs in which a person must clarify, repair, approve unexpectedly, or take over.
    • Time to successful completion: Measure completed runs separately so quick failures do not make the agent appear faster.
    • Cost per successful completion: Divide total run costs, including retries and supporting model calls, by completed outcomes rather than by invocations.
    • Recovery quality: Check whether failed runs leave clear logs, preserve work, avoid duplicate actions, and return systems to a known state.
    • Policy adherence: Record attempts to cross approval boundaries, use disallowed data, or invoke an unauthorized tool.

    Keep every started run in the denominator. If your goal is autonomous completion, a person quietly fixing the result before it reaches the dashboard is a failed autonomous run, even when the final output looks good.

    Separate the agent from the decision engines beneath it
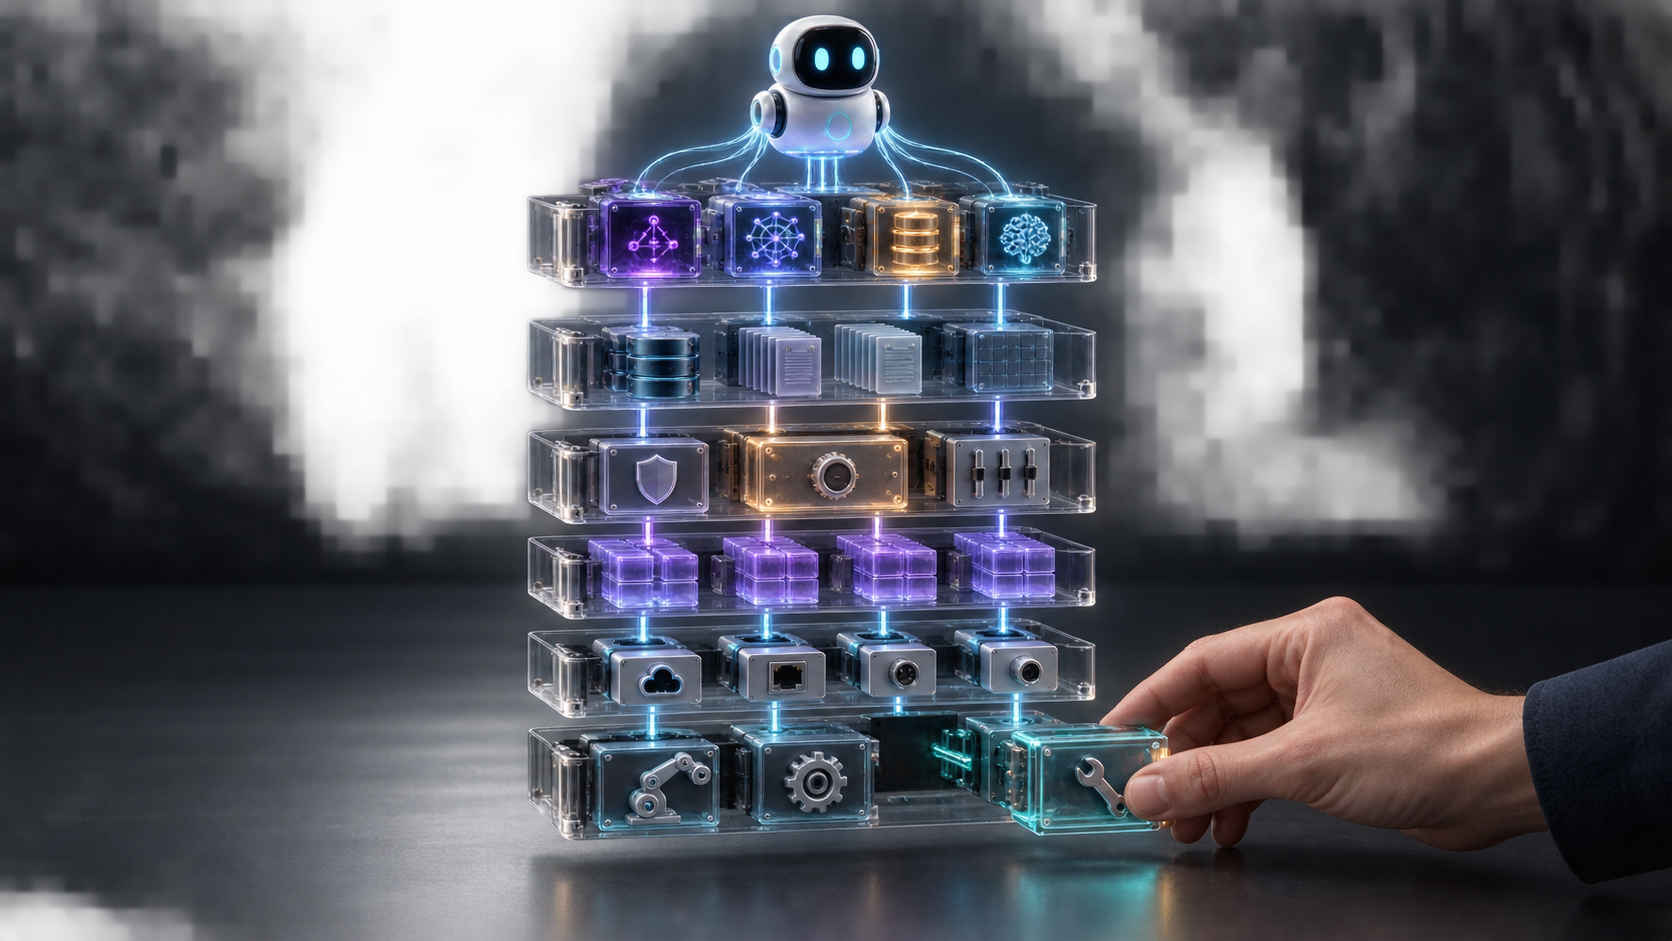
    An exploded modular AI system shows an agent above separate reasoning, memory, control, data, and tool components as a hand replaces one module.

    An agent does not need a large generative model for every step. Planning, writing, summarizing, classifying, routing, policy checking, and executing an API call are different computational jobs. Treating them as one undifferentiated prompt raises latency and cost while making failures harder to diagnose.

    The term System One model is being used for a model that returns a typed, calibrated decision from a predefined answer set rather than free-form prose. It can choose a ticket category, route a request to a model, select a tool, or decide whether a proposed action meets a policy. It does not independently accept a goal and pursue it, so it belongs inside an agent architecture rather than in the agent column of a market-share table.

    This layer matters because structured decisions are numerous but relatively inexpensive. Across 3.1 billion production API calls observed in 1,400 applications beginning June 1, 2026, structured decision tasks represented 63.7% of calls but only 15.5% of token spend. Long-form generation showed the opposite pattern: 9.1% of calls consumed 38.4% of token spend. A specialized decision model can therefore remove a large amount of traffic from a general-purpose model without displacing a comparable share of model spending.

    The best candidates have an answer space you can enumerate before the call. Binary classification led a September 2026 survey of 421 AI engineering teams, with 60.5% already piloting or planning adoption within six months. Schema extraction ranked last at 28.7% because field values are often open-ended. That gap gives you a practical rule: use a decision model when you can list all legitimate outcomes; retain a generative model when the output itself must be created.

    Type safety is necessary, but it is not factual accuracy

    A model can return a perfectly valid category and still choose the wrong category. Constrained decoding on a small language model achieved a 0.0% type error rate in the same benchmark as Jev, so valid output syntax is not, by itself, a differentiator. You still need labeled evaluation cases that test whether the decision is correct.

    The alternatives also remain competitive. A fine-tuned encoder classifier recorded 0.09-second median latency and a $0.018 cost per million input tokens, compared with Jev at 0.14 seconds and $0.042. The tradeoff is breadth: a new classification question can require another encoder to be trained, while a broader decision endpoint can answer different predefined questions. A small language model using constrained decoding was slower at 2.1 seconds, with input priced at $0.35 per million tokens and output at $1.40.

    Early demand does not prove steady-state adoption. Jev was only seven days old when launch-week estimates put it at 31,416 developers making at least one API call, while 6.2% of new accounts reached production. Treat that as evidence of interest and low integration friction, not as evidence that the architecture has already become standard.

    A clean production design assigns each layer a narrow responsibility:

    • The agent owns the goal, task state, planning, and recovery path.
    • Decision models handle enumerable classifications, routing, ranking, policy checks, and tool selection.
    • Generative models create prose, summaries, code, and other open-ended outputs.
    • Deterministic tools read or change external systems under explicit permissions.
    • Human approval remains in front of irreversible, externally visible, or high-consequence actions.

    Log the input, output, confidence or score, selected route, tool result, and final task outcome at the relevant layer. Otherwise, a failed workflow leaves you guessing whether the planner, classifier, generator, integration, or external system caused the problem.

    Build an adoption plan that survives vendor churn

    A durable rollout does not depend on predicting which logo will lead the next market table. It depends on preserving your workflow knowledge and measuring interchangeable components against the same definition of success.

    1. Select one bounded workflow. Favor a repeatable job with an observable end state and enough current friction to justify integration work.
    2. Map the action boundary. Separate read-only work, reversible internal changes, external communications, financial actions, deployments, and destructive operations. Require human approval where an error would be difficult to reverse.
    3. Shortlist by category fit. Compare agents designed for the systems and work involved instead of beginning with overall reach.
    4. Run identical evaluation cases. Include normal requests, missing information, ambiguous instructions, permission failures, tool errors, and requests that should trigger a refusal or escalation.
    5. Score completed outcomes. Track unassisted completion, interventions, time, cost, policy adherence, and recovery behavior using the same denominator for every candidate.
    6. Decompose expensive runs. Identify classification, routing, ranking, safety, and tool-selection calls that can move to a specialized decision model or deterministic rule.
    7. Retain a migration path. Keep prompts, outcome briefs, schemas, evaluation cases, logs, and business rules outside proprietary interfaces when the platform permits it.

    If customers encounter your business through agents

    Agent adoption changes acquisition as well as operations. ChatGPT Agent is used for multi-step research and booking; Gemini Agent Mode handles browser automation and forms; OpenAI Atlas performs site navigation and transactions; Perplexity Comet supports comparison and checkout. If any of those journeys matter to your business, visibility alone is an incomplete success metric. The agent must be able to identify the right page, understand the offer, verify important facts, and complete or correctly hand off the next step.

    Apply the same outcome-based discipline to AI SEO, AEO, and GEO work:

    • Put essential product, service, eligibility, policy, and contact information in visible page text rather than only in images or interactive widgets.
    • Give each important entity, offer, and resource a stable canonical URL with a clear page purpose.
    • Keep structured data consistent with the claims a visitor can see. Schema is a machine-readable consistency layer, not permission to publish contradictory or unsupported markup.
    • Use specific labels for links, buttons, form fields, and required inputs so an agent does not have to infer what an interface element does.
    • Publish dates, units, methodology, limitations, and originating evidence beside factual claims that an agent may need to evaluate or cite.
    • Test complete journeys from discovery to the required outcome. Record where the agent selects the wrong page, loses context, cannot operate a control, encounters conflicting facts, or reaches an unexpected approval step.

    This is where agent analytics should meet search analytics. A mention in an AI answer, an agent visit, a successful product comparison, and a completed transaction are separate events. Tracking only referral traffic hides the failures between discovery and completion.

    Key takeaways

    • AI agent usage is expanding rapidly, but market share is fragmenting rather than settling around one permanent winner.
    • Choose an agent for a defined workflow category and observable end state, not for overall popularity.
    • Use unassisted completion, intervention, recovery, time, and cost per successful outcome as the core buying metrics.
    • Keep goal pursuit in the agent layer while routing enumerable decisions to specialized models or deterministic rules where appropriate.
    • Make customer journeys explicit, structured, and testable if browser and general-purpose agents are part of your discovery or conversion path.

    Your next move is deliberately small: choose one workflow whose finish you can describe in a sentence, preserve a human gate before consequential actions, and run the same cases through category-appropriate candidates. The market will keep changing. A clear outcome definition and a portable evaluation set let you benefit from that competition instead of being trapped by it.

    References


  • Build, Buy, or Outsource Marketing AI: A Decision Framework

    Build, Buy, or Outsource Marketing AI: A Decision Framework

    Your team has found a marketing workflow worth improving with AI. A vendor can sell you a platform, a specialist can configure a solution, and someone internally is probably confident they can build a prototype. The dangerous question is which option looks cheapest at the start.

    The useful question is where repeatable software should end, where your workflow needs specialist implementation, and where qualified human judgment must remain. A focused 30-minute sorting exercise can answer that before an interesting prototype becomes an unsupported internal product.

    Key takeaways

    • Buy software when the capability is common across companies and the vendor can absorb maintenance, updates, and support.
    • Outsource implementation knowledge when your workflow is custom but the expertise needed to build it is temporary.
    • Build internally when the logic is genuinely differentiating, your team will improve it regularly, and you can support it after launch.
    • Do not deploy an AI workflow unless a named person can verify its output using evidence and subject knowledge.
    • Make the decision for each workflow step, not for an entire department, role, or AI initiative.
    • Compare lifecycle cost, including review and maintenance, and validate the choice with a controlled pilot before allowing autonomous action.

    Treat the workflow as layers, not one build-or-buy choice

    An exploded three-layer workflow combines standard software modules, configurable connections, and a human approval checkpoint.

    A marketing automation is rarely one indivisible system. A visibility report, for example, may collect data, normalize names, identify changes, interpret those changes, route exceptions, obtain approval, and distribute a finished report. Those steps do not have to come from the same place.

    Break the workflow into boxes before comparing solutions. For every box, record its input, transformation, output, owner, reviewer, and downstream decision. You can then route each layer according to what makes it difficult.

    Workflow layerMarketing examplesSensible defaultYour continuing responsibility
    Common software capabilityRank tracking, citation monitoring, brand-mention tracking, crawl diagnostics, and content scoringBuyConfiguration, data access, quality checks, and vendor oversight
    Company-specific implementationApproval routing, data mapping, reporting cadence, subject-matter-expert intake, and approved CTA insertionOutsource the initial design or implementation, then own itRequirements, acceptance tests, documentation, and an internal process owner
    Differentiating logicYour prioritization rules, proprietary data relationships, brand judgment, and decision criteriaBuild or retain internallyRoadmap, maintenance, testing, and knowledge continuity
    Human controlAccuracy review, exception handling, interpretation, and final approvalKeep qualified ownership inside the teamEvidence standards, escalation rules, and accountability for the resulting decision

    This is a deliberate hybrid, not a compromise. You might buy the monitoring engine, hire a specialist to connect it to your reporting process, build a narrow layer containing your prioritization rules, and keep final interpretation with an analyst. Recreating the monitoring platform would add little advantage; handing your judgment to an opaque system would surrender too much.

    An MIT review of enterprise generative AI projects reported zero return among 95% of the organizations it examined, while external partnerships represented a higher share of successful deployments than internal development. That should not be converted into a universal failure probability: the initiative volumes were uneven, and there was too little hybrid build-buy evidence to quantify that route. The practical warning is narrower. A working prototype is not a successful deployment, especially when the system does not fit the way people already work.

    Do not automate work that nobody can verify

    Two people inspect assets at a checkpoint in an automated production line before approved items continue.

    Before discussing price or architecture, ask one gating question: can a named person on your team perform the task manually or reliably check the result? If the answer is no, pause the automation. You would be installing a system whose failures your team cannot recognize.

    Fluent output makes this risk easy to underestimate. A model can turn a spike in a group of Google Search Console queries into a confident claim that AI visibility is rising, even though the data does not establish that conclusion. The error can look polished enough to enter a leadership meeting unless someone understands both the data and the inference being made.

    Only 13% of marketers fully trust AI output without a human reading it. That is not merely an adoption problem. It is a staffing and workflow requirement: the review still needs time from someone qualified to judge the work.

    The State of CRM Data Report 2026 found that nearly 78% of C-suite respondents and 92% of SVP or VP respondents had acted on an AI recommendation they later suspected was wrong because of poor underlying data. The corresponding figure among individual contributors was 41%. These are self-reported suspicions, not measured model error rates, but they expose an important control problem: the person with authority to act may be farther from the evidence needed to challenge the recommendation.

    Create a verification contract before you automate. It should answer:

    • What decision can this output influence? A draft that stays in an editor is different from a report that changes budget or reaches an executive.
    • What evidence should support the answer? Require links, source records, query data, calculation inputs, or another trace that the reviewer can inspect.
    • Who is qualified to review it? Assign a person or role, not an unspecified human in the loop.
    • What counts as an unacceptable error? Define concrete failure classes such as fabricated facts, incorrect data mapping, unsupported attribution, missing exceptions, or off-brand recommendations.
    • What happens when confidence is low or evidence is missing? Route the case to a person rather than letting the system improvise.
    • Which outputs always require approval? Keep review on every output that can publish content, contact a customer, alter spending, or materially influence a leadership decision.

    If no one can fill in that contract, your next investment is expertise, not automation. Narrow the task, train an owner, or obtain specialist help before deploying the tool.

    Buy common capability, outsource the learning curve, build your edge

    Buy when the underlying problem is common

    Buying is usually the sound route when thousands of other teams need substantially the same capability. Tracking, monitoring, crawling, diagnostics, and scoring all require unglamorous infrastructure work: connectors change, interfaces break, usage grows, and edge cases accumulate. A mature vendor spreads that work across its customers and provides someone to fix the product when it fails.

    Do not evaluate only the demo. Ask the vendor to show how the product handles your real inputs and exceptions. Confirm:

    • whether it supports the data systems you actually use;
    • how it logs inputs, changes, failures, and human approvals;
    • whether reviewers can inspect the evidence behind an output;
    • how data, configurations, and results can be exported;
    • which maintenance and support work is included;
    • how usage, seats, or additional integrations affect cost;
    • what happens to your workflow when the vendor changes a model or feature; and
    • what access controls apply before customer, employee, or proprietary data enters the system.

    The product does not need to mirror your process perfectly out of the box. It does need to cover the commodity layer without forcing your team to become its unpaid engineering and support department.

    Outsource when the workflow is yours but the learning is temporary

    Your approval chain, internal taxonomy, reporting schedule, subject-matter-expert process, and pre-approved copy may be unique. The implementation problems hiding underneath them often are not. Someone who has configured similar workflows already knows where handoffs fail, which exceptions need human input, and which apparently simple steps become brittle when automated.

    Use a practical test: will your team apply the knowledge gained from building this every week? If not, paying employees to discover each failure mode for the first time is an expensive way to acquire one-use expertise. Buy the learning curve through a validated template, a focused consultation, a short implementation engagement, or a specialist resource library.

    Outsourcing should leave you with an operable system, not a permanent mystery. Put these deliverables into the engagement:

    • a map of the workflow, inputs, outputs, owners, and exceptions;
    • documented configuration and administrator access;
    • acceptance tests covering normal, messy, and missing inputs;
    • a failure log describing known limits and escalation paths;
    • training for the internal owner and reviewers;
    • a handover plan, maintenance estimate, and change process; and
    • clear ownership and export rights for data, prompts, rules, documentation, and other deliverables.

    Keep an internal owner involved throughout. A handoff at the end cannot recover reasoning and decisions that were never documented.

    Build when the capability creates durable advantage

    Building internally makes sense when the system encodes something meaningfully different about how you market, not merely because your workflow has custom field names. Your team should be able to answer yes to all of these questions:

    • Does the logic create a real advantage rather than duplicate a standard product feature?
    • Will your team use and improve the resulting technical or operational knowledge regularly?
    • Are your requirements unlikely to be met through configuration, integration, or a narrow extension of existing software?
    • Can you assign an enduring product owner and the people needed to test, monitor, document, and repair it?
    • Will ownership survive if the original builder changes roles or leaves?
    • Can a qualified person verify the system’s output and stop it when it behaves incorrectly?

    An internal prototype may appear inexpensive because its future obligations are invisible. Once colleagues depend on it, the team owns permissions, changing integrations, model behavior, tests, documentation, support, incident response, and every request for a small improvement. If those duties do not have owners, the organization has created software without creating a software function.

    Build the narrowest layer that contains your advantage. Purchasing a stable platform and adding your own orchestration or decision rules is often more defensible than rebuilding data collection, authentication, dashboards, and administrative features around it.

    Use a hybrid route deliberately

    A strong marketing AI workflow may use all three routes. A vendor collects visibility data. A specialist maps the data to your taxonomy and approval path. Your team encodes its prioritization rules and approved CTA library. An analyst reviews anomalies and interpretation before the report reaches leadership.

    Write the boundary between those layers down. Specify who owns the data, configuration, custom logic, review, maintenance, and recovery process. Hybrid systems become fragile when every participant assumes somebody else owns the seam.

    Make the decision in 30 minutes, then test one handoff

    You do not need a long procurement exercise to choose an initial route. You do need a disciplined comparison that counts work beyond the visible fee.

    Use this 30-minute decision agenda

    1. Minutes 0-5: define the outcome. Name the marketing result, the user, and the decision the workflow should improve. Reject objectives such as use AI or automate content; they do not define value.
    2. Minutes 5-10: map the steps. Draw each input, transformation, review, exception, and output. Do not route the workflow until you can see its parts.
    3. Minutes 10-15: classify the layers. Mark each step as common capability, company-specific implementation, differentiating logic, or human control.
    4. Minutes 15-20: apply the verification gate. Name the reviewer, required evidence, unacceptable errors, and escalation path.
    5. Minutes 20-25: compare lifecycle cost. Add internal labor, implementation, review, maintenance, support, and displaced marketing work to the visible price.
    6. Minutes 25-30: choose a route and pilot boundary. Decide what to buy, outsource, build, or leave manual. Assign an owner and state what evidence would justify expansion.

    Compare total cost on the same basis

    A subscription price cannot be compared directly with a development estimate. Use the same operating horizon and the same labor assumptions for every option.

    • Buy: subscription or usage charges, implementation, integrations, internal administration, review, training, migration, and eventual exit work.
    • Outsource: specialist fees, required software, internal subject-matter-expert time, review, training, handover, and ongoing maintenance.
    • Build: discovery, meetings, design, development, testing, infrastructure, documentation, monitoring, support, review, repairs, and the marketing work displaced by those hours.

    Calculate internal labor using the time of every contributor, not just the person writing prompts or code. Include the people clarifying requirements, attending meetings, preparing data, testing outputs, correcting errors, approving work, and responding when the workflow breaks.

    Then name the opportunity cost in operational terms. Which campaign, analysis, customer interview, content update, or technical fix will wait while the team builds and maintains this? If no displaced work appears in the comparison, the internal option has been priced as though staff time were unlimited.

    Keep consequence separate from speculative arithmetic. If a bad output could publish an unsupported claim, misclassify performance, expose sensitive data, or redirect budget, record that failure and the control that prevents it. Do not invent a precise dollar value merely to make the spreadsheet look complete.

    Pilot a bounded step before replacing a job

    Test one handoff whose output can be compared with the existing process. A narrow pilot reveals whether the proposed route reduces work or merely moves it into checking, correction, and maintenance.

    1. Capture the baseline. Record the current input, output, turnaround, human effort, recurring errors, and approval path.
    2. Prepare test cases. Include normal inputs, incomplete data, unusual cases, and situations that should be escalated rather than answered.
    3. Define acceptance before testing. State the required evidence, allowed error classes, review time, and conditions that would stop the pilot.
    4. Run in shadow mode. Compare results without letting the system publish, send, spend, or change a production record on its own.
    5. Log every intervention. Separate factual corrections, data-mapping problems, brand edits, integration failures, and exceptions. That log shows whether the problem is the model, the implementation, the input, or the process itself.
    6. Calculate net value. Subtract review, repair, administration, and maintenance effort from gross time saved. Include improvements in consistency or turnaround only when the pilot demonstrates them.
    7. Decide explicitly. Expand, revise, change the sourcing route, keep the step manual, or stop. Name the production owner and rollback method before expansion.

    Stop or narrow the automation when failures are hard to detect, review consumes most of the apparent saving, changing inputs repeatedly break the workflow, or nobody accepts maintenance ownership. That is useful pilot evidence, not a reason to keep investing until the original idea appears justified.

    Take the next proposed marketing automation and draw its steps on one page. Mark each box buy, outsource, build, or human control. Do not approve procurement or development until every box has a verification owner and the resulting system has a lifecycle owner. The goal is not to own more AI software. It is to improve a marketing outcome with the smallest reliable system that your team can understand and sustain.

    References


  • Profound’s $180M Funding: What Marketing Teams Should Test

    Profound’s $180M Funding: What Marketing Teams Should Test

    If you are deciding whether Profound’s funding makes its platform a safer strategic bet, separate two questions immediately: Does the company have more capacity to pursue its vision, and can the product remove work from your marketing operation? The first is supported by the raise. The second still requires proof inside a workflow that matters to you.

    That distinction will keep a large funding number from becoming a substitute for product, governance, and commercial due diligence. It also gives you a practical way to evaluate AI Marketer without either dismissing the platform or buying the story before testing the system.

    What Profound has actually committed to

    Profound has raised $180 million to build an AI platform for marketing. Its stated premise is that AI is generating additional work for marketers, not simply automating existing tasks. AI Marketer is positioned as the response: a system that brings company context and agents together so marketing teams can get that work done.

    Those points establish capital, direction, and a product thesis. They do not establish the return a customer will receive. A funding total cannot tell you whether the platform fits your data, integrates with your operating stack, produces reliable outputs, shortens approval cycles, or reduces the total cost of a workflow.

    The stated goal also indicates a broad platform ambition rather than a single-purpose feature. That can be valuable when your work crosses research, analysis, content, brand governance, and execution. It can also increase implementation scope. The more jobs a platform is expected to coordinate, the more important permissions, source quality, handoffs, and ownership become.

    Use the announcement as a reason to ask better questions, not as the answer to them. Do not add unconfirmed details about valuation, investors, product allocation, delivery dates, or business performance to your internal brief. If one of those details affects your decision, request it directly and distinguish a written commitment from a forward-looking plan.

    Why more AI can create more marketing work

    A marketing team sorts and reviews a growing flow of campaign materials produced by several automated machines.

    AI reduces the cost of producing an output, but output generation is only one part of marketing. Every new model, answer surface, automated campaign, and content variant can create additional monitoring, interpretation, validation, approval, and measurement work. Faster production can therefore move the constraint downstream rather than remove it.

    You can see that effect by mapping the full chain around an AI-assisted task:

    • Inputs: Someone must select the relevant brand rules, product facts, audience assumptions, performance data, and prior decisions.
    • Generation: A model or agent produces an analysis, recommendation, brief, campaign asset, or other deliverable.
    • Verification: A person checks factual accuracy, source quality, brand fit, compliance, and whether the output answers the original question.
    • Execution: The approved output must reach the correct channel, owner, or system without losing its context.
    • Learning: Results must return to the process so that the next action reflects what changed.

    A platform can make generation faster while leaving every other stage intact. It can even increase review work if it produces more material than your team can verify. That is why prompts completed, agents deployed, and assets generated are weak measures of operating value on their own.

    Before watching a demonstration, draw one real workflow from request to approved outcome. Mark every system, human handoff, approval, wait state, and rework loop. Record the elapsed time, active working time, and recurring errors using evidence you already have. You now have a baseline against which automation can be judged.

    If your remit includes AI search visibility or generative engine optimization, a suitable workflow might begin with a visibility finding and end with an approved content or entity-data change. The test should include the analysis, supporting evidence, assignment, revision, publication approval, and follow-up measurement. Automating only the first step does not automate the workflow.

    What company context and agents must prove

    The combination of company context and agents is the central idea behind AI Marketer’s positioning. Those terms can sound complete while hiding the hardest implementation questions. Treat them as two systems to test separately.

    Test context as a governed source of truth

    Company context should do more than place files near a model. It should help the system select current, authorized information and show you what influenced an output. Ask for a live demonstration that answers these questions:

    • Which repositories, pages, records, and instructions can the system use for this task?
    • How does it decide which source is authoritative when two sources conflict?
    • How quickly does a changed product fact, policy, or brand rule become available?
    • Can access be limited by team, role, market, client, or workspace?
    • Can a reviewer trace an output back to the facts and instructions that shaped it?
    • What happens when the required evidence is missing, stale, or ambiguous?

    Do not test this with a polished sample library. Bring a controlled set of realistic material that includes one outdated item, one conflict, and one fact the system should not expose to every user. Designate the correct source in advance. A useful context layer should handle the conflict predictably, respect access boundaries, and make its reasoning inspectable enough for a reviewer to catch a mistake.

    Test agents as bounded operators

    An agent is valuable when it can advance work without gaining more authority than the task requires. Evaluate its operating boundaries, not only the quality of its final output:

    • What triggers the agent, and who can change that trigger?
    • Which data can it read, and which systems can it alter?
    • Which steps require human approval before the agent proceeds?
    • Can you stop a run immediately and prevent it from retrying?
    • Does the audit history preserve inputs, actions, outputs, approvals, and failures?
    • How does the agent behave when a dependency is unavailable or the evidence is inconclusive?
    • Can its work be exported, reassigned, or completed manually?

    Run the same task after changing a canonical input, revoking a permission, and withholding a required fact. You are looking for controlled behavior: the output should update when the approved context changes, access should disappear when permission is removed, and the agent should stop or escalate when it cannot support an answer.

    Do not grant autonomous publishing or campaign-changing permissions merely to make a pilot look complete. An opaque error can create public misinformation, brand damage, or avoidable spend. Start with read access, draft outputs, explicit approval gates, and a visible audit trail. Expand authority only after the failure behavior is understood.

    Turn the funding story into a procurement test

    A cross-functional team evaluates an AI agent in a transparent test chamber using visual checkpoints for quality, security, time savings, and commercial value.

    New capital can support product development, infrastructure, implementation, hiring, or market expansion, but the amount alone does not tell you which customer outcomes will improve. Ask Profound to connect its funded platform direction to the operating requirements in your evaluation.

    Use a short, evidence-based process:

    1. Separate product from roadmap. Mark every required capability as available, configurable, dependent on services, planned, or unsupported. Ask for written confirmation of anything that affects the purchase.
    2. Select one costly workflow. Choose a process with a clear owner, recurring inputs, an observable outcome, and enough friction to justify change. Do not begin with a broad goal such as improving marketing productivity.
    3. Run your material through the system. Use representative company context, normal approval requirements, and the systems the production workflow would need. A vendor-curated example cannot expose your integration or governance problems.
    4. Measure total work. Compare active effort, waiting, handoffs, corrections, and review demand with the baseline. Count work displaced to administrators, analysts, agencies, or implementation teams.
    5. Test failure and exit paths. Introduce stale context, a conflicting instruction, a denied permission, and an unavailable dependency. Then verify how you export outputs, retrieve records, remove data, and continue the workflow if the platform is unavailable.

    A pass-or-fail scorecard keeps the evaluation focused when a demonstration is visually impressive:

    DimensionEvidence to requestReason to pause
    Workflow valueA proof run showing less total effort, delay, or reworkThe claimed value depends mainly on future features
    Context integritySource traceability, conflict handling, freshness controls, and scoped accessThe system cannot explain which facts governed an output
    Agent controlLeast-privilege permissions, approvals, stop controls, and audit historyAgents require broad access or take opaque actions
    Operational fitWorking integrations, clear ownership, administration, and support pathsManual bridges recreate the work you intended to remove
    Commercial durabilityWritten terms for current capabilities, service levels, support, and pricingThe funding total is used in place of contractual commitments
    Exit safetyDocumented export, deletion, access removal, and offboarding proceduresYour data or workflow history cannot leave cleanly

    Funding matters most where it changes the risk of relying on the platform. Ask which capabilities exist now, which dependencies require professional services or third-party systems, what support is included, and how roadmap changes are communicated. For every answer, identify the proof: a live control, a technical document, a contractual term, or merely an intention.

    Data handling deserves the same precision. Confirm what information the system stores, where it is processed, who can access it, how long it is retained, whether it is used to improve models, and how deletion is verified. If your marketing context contains customer, partner, employee, or confidential product information, involve the people responsible for security, privacy, and legal review before production access is granted.

    Key takeaways

    • Profound’s $180 million raise supports its ability to pursue an AI platform for marketing, but it does not prove customer outcomes.
    • AI can create work after generation, especially in verification, approval, execution, governance, and measurement. Evaluate the whole workflow.
    • Company context must demonstrate source authority, freshness, traceability, conflict handling, and permission boundaries.
    • Agents must demonstrate limited authority, approval controls, predictable failure behavior, auditability, and a safe manual path.
    • Your decision should depend on production-like evidence and written commitments, not funding momentum or a curated demonstration.

    For your next step, take one workflow into the evaluation meeting and bring its real inputs, permissions, exceptions, and approval rules. Ask Profound to show what AI Marketer does at each stage, what remains human work, and which capabilities are available now.

    A platform is worth adopting when it reduces the total burden of producing a trustworthy marketing outcome while preserving control. The funding gives Profound room to pursue that standard. Your proof run should determine whether the product meets it for you.

    References


  • Commercial AI Token Costs: Budgeting Beyond List Price

    Commercial AI Token Costs: Budgeting Beyond List Price

    Your spreadsheet says one model is cheaper. Your invoice says otherwise. The gap appears because the spreadsheet priced the prompt and final answer, while production also paid for reasoning, repeated instructions, failed tool calls, retries, discarded drafts, and cache behavior.

    If you are choosing a commercial AI model or defending an AI budget, compare cost per accepted outcome, not cost per million tokens. That change turns a rate card into a forecast you can actually use.

    A token price is only one layer of your production cost

    Published input and output prices tell you the rate applied to certain tokens. They do not tell you how many tokens the model will consume before your application gets an acceptable result. A useful cost model therefore has three layers:

    • Unit rates: the applicable prices for input, output, reasoning, cache reads, cache writes, and any long-context tier.
    • Consumption: the number of tokens used by the prompt, retrieved context, system instructions, tool definitions, intermediate reasoning, and response.
    • Completion efficiency: how many attempts, revisions, and tool calls you pay for before the result passes your acceptance checks.

    The third layer causes many budget misses. A cheap attempt is not a cheap task if the attempt is rejected and repeated. Nor is a successful API response necessarily a completed business task. A coding agent that returns malformed code, a content model that produces an unusable draft, or a schema generator that fails validation has consumed tokens without delivering the outcome you intended to buy.

    In measured 2026 production usage, the categories commonly omitted from simple estimates represented 52.5% of billed tokens and added 70.4% above a list-price-only estimate. These percentages are not universal overhead rates. They are a practical checklist of what your own logging needs to capture.

    Cost commonly missedShare of billed tokensAdded cost versus list-price estimateWhat to inspect
    Invisible reasoning tokens22.4%38.6%Whether reasoning usage is returned separately from visible output
    Re-sent system prompts and tool schemas11.9%9.4%How much fixed context is transmitted on every model call
    Retried and discarded generations7.8%8.1%Every failed, rejected, or superseded attempt
    Long-context pricing above 200K tokens3.1%6.2%Requests crossing a provider’s long-context pricing boundary
    Failed tool calls and malformed structured output4.6%5.3%Calls that return successfully but fail downstream validation
    Unrecovered cache-write premium2.7%2.8%Cache entries written without enough subsequent reuse

    Do not solve this by applying one generic markup to every vendor quote. Instrument each category instead. A reasoning-heavy model, a tool-using agent, and a short classification call can have radically different overhead even when their visible prompts look similar.

    Falling rate-card prices do not remove this problem. Within a constant-capability mid-tier series from Q1 2023 through Q3 2026, the list-price index fell 91.4%, but real cost per completed task fell only 62.9%. Token consumption per completed task rose 4.3 times. The completed-task cost reached its low point in Q4 2024 and then increased 80% by Q3 2026 even as published rates generally continued downward. More capable reasoning behavior can consume part of the saving advertised on the price sheet.

    Compare models by accepted task, not by token rate

    Three abstract AI processing stations turn identical inputs into rejected fragments and one finished object that fits a quality-check fixture.

    A model comparison becomes useful only after the denominator represents something your business accepts. From May 4 through August 21, 2026, a standardized set of 14 production tasks was run across 11 commercial models. The resulting cost included billed reasoning, prompt repetition, cache activity, retries, and discarded output. The September 2026 prices and measured completed-task costs show why rate-card ranking and production ranking can diverge.

    ModelInput per 1M tokensOutput per 1M tokensMeasured cost per completed task
    GPT-5.4 nano$0.20$1.25$0.0219
    Gemini 3.1 Flash-Lite$0.25$1.50$0.0288
    Claude Haiku 4.5$1.00$5.00$0.0474
    GPT-5.6 Luna$1.00$6.00$0.0607
    GPT-5.4 mini$0.75$4.50$0.0627
    Claude Sonnet 5$2.00$10.00$0.0848
    Gemini 3.6 Flash$1.50$7.50$0.1040
    GPT-5.6 Terra$2.50$15.00$0.1662
    Gemini 3.1 Pro$2.00$12.00$0.1683
    Claude Opus 5$5.00$25.00$0.2131
    GPT-5.6 Sol$5.00$30.00$0.3447

    Several reversals matter when you shortlist a model. GPT-5.4 mini had lower published input and output prices than Claude Haiku 4.5, yet its measured task cost was $0.0627 versus $0.0474. Claude Sonnet 5 had higher published rates than Gemini 3.6 Flash but completed the task set for $0.0848 instead of $0.1040. At the frontier end, GPT-5.6 Sol and Claude Opus 5 shared the same $5.00 input price, but Sol cost 62% more per completed task, with the difference driven almost entirely by output volume.

    These results do not make one model universally cheaper. Your prompts, tools, input-to-output ratio, quality threshold, and retry policy may reverse the ranking again. Use published comparisons to choose candidates, then reproduce the comparison on your own workflow.

    1. Define completion before testing. For JSON-LD, completion might require parsable output that passes your validation checks. For a content brief, it might require every mandatory field and entity. An HTTP success code is not an acceptance criterion.
    2. Freeze a representative task set. Give every candidate the same source material, system instructions, tools, output requirements, and acceptance tests.
    3. Record every billable attempt. Keep rejected generations, malformed output, repair prompts, tool-call failures, and fallback calls in the numerator.
    4. Separate visible output from total usage. Store every usage field the provider exposes, including reasoning and cache categories where available.
    5. Compare only models that meet the quality gate. A low-cost result that cannot be used is a failed attempt, not a bargain.
    6. Divide total model spend by accepted completions. That figure is your effective task cost and the basis for a credible monthly forecast.

    Content costs multiply after the first draft

    Content teams often estimate AI spend from the tokens in one draft. That calculation stops before the expensive part: revisions, replacement drafts, citation repair, structural fixes, and output that never reaches publication.

    For 1,000 words of finished, publishable copy, the measured token cost included revision rounds and discarded generations. The difference between first-draft and finished cost was substantial across every tested model.

    ModelFirst-draft costAverage revision roundsDiscarded draftsFinished cost per 1,000 wordsFinished versus first draft
    GPT-5.6 Sol$0.0861.614%$0.2072.4x
    Claude Opus 5$0.0791.29%$0.1642.1x
    GPT-5.6 Terra$0.0431.817%$0.1142.7x
    Gemini 3.1 Pro$0.0361.919%$0.1012.8x
    Gemini 3.6 Flash$0.0242.426%$0.0843.5x
    Claude Sonnet 5$0.0321.513%$0.0742.3x
    GPT-5.6 Luna$0.0172.324%$0.0583.4x
    GPT-5.4 mini$0.0132.931%$0.0544.2x
    Claude Haiku 4.5$0.0162.122%$0.0513.2x
    Gemini 3.1 Flash-Lite$0.00414.145%$0.0245.9x
    GPT-5.4 nano$0.00344.448%$0.0216.2x

    The cheapest and most expensive first drafts were separated by roughly 25 to 1. After revisions and discards, finished costs were separated by about 10 to 1. Draft rejection narrowed the apparent advantage of the cheapest models.

    Discard rate was also more useful than list price for anticipating finished cost. Claude Sonnet 5 started at $0.032 per 1,000 words, above Gemini 3.6 Flash at $0.024. Sonnet finished lower, at $0.074 versus $0.084, because its discarded-draft rate was 13% rather than 26%.

    Build that distinction into your content operations. Give every generated asset a final status such as accepted, revised, or discarded, and associate all attempts with the same job identifier. Then calculate finished token cost from all spend attached to accepted copy, divided by accepted word count and multiplied by 1,000. Counting only the last successful generation erases the waste you are trying to manage.

    Keep the quality gate explicit. For an SEO or GEO workflow, your requirements may cover factual accuracy, source support, search intent, entity coverage, structure, brand constraints, and valid structured output. The exact rubric is yours, but it must be stable across models. Otherwise, a permissive review process can make a weak model look artificially inexpensive.

    The figures above cover model-token spend. They do not represent a fully loaded content cost. Your internal budget should add editorial review, fact-checking, workflow infrastructure, monitoring, and any human repair work rather than treating a low token figure as the total cost of publication.

    Budget by workload, then route each job to the right tier

    Different task objects move through a central routing hub toward small, medium, and large processing machines, with one path passing through a cache chamber.

    A single company-wide average hides the workflows most likely to break your budget. Agentic coding, customer support, retrieval-based research, document processing, sales personalization, and content production have different volumes, context sizes, output patterns, and failure modes.

    For a modeled 50-person company, the same mix of 157,400 monthly tasks cost $6,610 at the economy tier, $19,150 at the mid tier, and $48,670 at the frontier tier. That is a 7.4-times spread before changing the workload itself.

    WorkloadMonthly tasksFrontier tierMid tierEconomy tier
    Coding agent, 20-developer team14,800$18,350$7,140$2,510
    Customer support automation62,000$9,610$3,720$1,240
    Internal RAG research tool21,500$7,290$2,940$1,020
    Document and contract processing9,700$6,410$2,580$890
    Sales outreach personalization46,000$4,830$1,910$640
    Content marketing, 8-person team3,400$2,180$860$310
    All workloads157,400$48,670$19,150$6,610

    Volume alone does not reveal the expensive workflow. The coding agent ranked fourth by task count but was the largest monthly cost. At the frontier tier, it cost $1.24 per completed task, compared with $0.16 for customer support. Agentic workflows repeatedly call models, tools, and validation steps, so a task can contain much more billable activity than one support interaction.

    Build your forecast from accepted workload volume

    Your budget sheet should have one row per distinct workflow, not one row per provider. Separate content briefs from finished drafts, retrieval answers from document ingestion, and schema generation from schema repair. They may use the same API while having different cost behavior.

    • Workload identity: team, application, task type, model, and model version.
    • Demand: expected completed tasks, not merely API requests.
    • Usage: input, output, reasoning, cache-read, and cache-write tokens where exposed.
    • Workflow overhead: attempts, tool calls, validation failures, fallback calls, and discarded results.
    • Outcome: accepted, repaired, rejected, or abandoned.
    • Unit economics: total billed spend divided by accepted completions.

    Forecast monthly model spend by multiplying expected accepted-task volume by your measured cost per accepted task. Keep the rate-card calculation beside it as a reconciliation check, not as the primary forecast. A widening gap between the two tells you to investigate prompt growth, longer retrieved context, increased reasoning, lower cache reuse, tool failures, or a rising retry rate.

    Recalculate after changes to the model version, system prompt, tool schema, context strategy, output format, or acceptance threshold. Each can alter consumption or completion efficiency even when the published token rate stays fixed.

    Use routing instead of choosing one model for everything

    Model tier should be a workload decision. Economy models are strongest candidates when the task is constrained, output can be checked automatically, and failure is cheap to retry. Mid-tier models suit broader production work where reliability and cost both matter. Frontier models deserve the jobs whose ambiguity or quality requirement produces a measurable improvement worth their higher completed-task cost.

    That does not require moving every workflow downmarket. In the modeled company, moving only the two highest-volume workloads – customer support and sales personalization – to economy models while leaving the other four at the frontier tier reduced total monthly spend by 26%. Selective routing captured savings without imposing one capability tier on every task.

    Put a quality gate after the lower-cost route and send only failed or uncertain cases to a stronger model. Count both calls when escalation occurs. Otherwise, the first model appears cheaper in your dashboard while the fallback cost disappears into another service or team.

    Key takeaways

    • Published cost per million tokens is a unit rate. Your actionable metric is total billed spend per accepted task.
    • Log reasoning, repeated system context, cache activity, retries, discarded output, tool failures, and long-context pricing instead of hiding them in a generic contingency.
    • For content, calculate cost per 1,000 accepted words from every draft and revision associated with the finished asset.
    • Benchmark candidates on the same tasks and acceptance criteria. Compare costs only among models that clear the required quality threshold.
    • Route by workload. High-volume, tightly validated tasks may justify an economy model, while ambiguous or high-impact work may justify a more capable tier.
    • Refresh the forecast whenever the model, prompt, tools, context, output contract, or quality gate changes.

    Start with one workflow that already generates meaningful volume. Attach every billable attempt to an accepted or rejected outcome, calculate its effective cost, and use that result to challenge the rate-card estimate. Once the accounting works for one workflow, extend the same measurement to the rest of your AI stack and route each task on evidence rather than model reputation.

    References


  • AI Search Visibility Governance: A Practical Operating Model

    AI Search Visibility Governance: A Practical Operating Model

    Your team can monitor ChatGPT, Gemini, and Perplexity, publish technically sound pages, and still have no reliable answer when leadership asks, “Are we becoming more visible, and what should we change next?” A visibility score alone cannot tell you whether an answer changed because of your work, inconsistent business data, reputation signals, a platform update, or ordinary variation between responses.

    You need an operating model, not another dashboard. That means defining the questions that matter, separating visibility from business impact, protecting the data used in AI workflows, and assigning a person to every decision. Here is how to build that system without turning governance into a stack of policies nobody follows.

    Stop treating AI visibility as a single score

    Answer engine optimization is becoming a formal technology category. Forrester’s Q3 2026 AEO technologies landscape included Profound, reflecting the emergence of dedicated products for this work. A platform can help you observe answers, citations, competitors, and changes. It cannot decide what visibility means for your organization or which result deserves action.

    Start with the decision your measurement must support. A software company may need to know why its product disappears from high-intent comparison answers. A healthcare publisher may care more about inaccurate summaries of its guidance. A multi-location business may need to find locations that are absent from local recommendations even though their listings rank in traditional search.

    Replace the broad question “Are we visible?” with a set of observable outcomes:

    • Mention: Does the answer name your organization, product, expert, or location?
    • Recommendation: Does it present you as a suitable choice for the user’s stated need?
    • Citation: Does it link to or identify one of your pages as evidence?
    • Representation: Are the description, attributes, availability, location, price context, and limitations accurate?
    • Position: Which alternatives appear, and what reasons does the answer give for preferring them?
    • Action: Can a user move from the answer to a measurable visit, lead, purchase, booking, or other useful next step?

    These outcomes are related, but they are not interchangeable. A citation can support a competitor recommendation. A mention can repeat an outdated fact. A favorable answer can produce no referral traffic because the interface does not expose a prominent link. Report them separately.

    Next, create a prompt registry. Each test case should record the user’s need, audience, market, language, exact prompt, engine and interface, test date, expected factual anchors, acceptable outcome, observed answer, cited domains, and reviewer. Keep the wording stable for trend measurement. Place experimental prompts in a separate group so a new phrasing does not masquerade as a performance improvement.

    Do not collapse one answer into a universal claim about a platform. AI responses can change with phrasing, context, location, interface, and time. Retain the response or a permitted capture of it, not just the score derived from it. When a result changes, you need to inspect what changed in the answer, not merely watch a line move on a chart.

    Build a scorecard that separates inputs, answers, and outcomes

    Three connected transparent chambers contain source materials, AI answer bubbles, and user outcome symbols as separate stages of measurement.

    A useful scorecard follows the path from facts you control to answers you influence and outcomes you want. This prevents a common governance failure: treating an observed recommendation as proof that a particular optimization caused it.

    LayerQuestionExamples to monitor
    FoundationCan systems identify the business and retrieve consistent facts?Names, locations, hours, products, policies, page accessibility, structured data consistency, and canonical source pages
    EvidenceWhat public evidence supports the claims you want an answer to make?Relevant content, citations, independent mentions, review sentiment, review responses, expert attribution, and localized information
    Answer outputHow does each AI surface represent the entity?Mentions, recommendations, citations, factual errors, omitted attributes, competitor inclusion, and answer framing
    Business outcomeDid the exposure contribute to something valuable?Qualified visits, assisted conversions, leads, bookings, branded demand, support contacts, and corrected misinformation

    The distinction matters because traditional search strength does not guarantee an AI recommendation. In a vendor-supplied comparison of eight expanding and eight contracting restaurant brands, SOCi measured recommendations in ChatGPT for about 20% of tested queries for the expanding group and roughly 3% for the contracting group. Its broader local visibility data found that only about 1% to 11% of brand locations were recommended across ChatGPT, Gemini, and Perplexity, compared with 35.9% appearing in Google’s traditional local 3-Pack.

    Use those figures as a directional warning, not a universal benchmark. The sample concerned restaurant chains, and the comparison cannot prove that digital visibility caused expansion or contraction. It does show why a local program should inspect search rankings, business data, reputation, localized content, and AI recommendations as connected signals while keeping the business outcome in a separate layer.

    The same comparison gives you a more immediate operational lever. Expanding brands responded to 72.4% of Google reviews, compared with 43.6% for contracting brands. A review-response process can change faster than a rating accumulated over years. That does not make response rate an AI ranking factor. It makes it a manageable indicator of whether local reputation is being treated as an operating discipline.

    For every percentage on your dashboard, retain the numerator, denominator, query set, market, platform, and collection period. A 40% recommendation rate based on two recommendations from five prompts should not be presented beside a rate based on hundreds of observations as though the two carry equal confidence. If your monitoring product hides the underlying observations, export or preserve enough evidence to audit the conclusion.

    Diagnose failures by layer before assigning work:

    • If your name, address, hours, or product facts conflict across properties, correct the source records, visible pages, listings, and structured data before commissioning more editorial content.
    • If the facts are consistent but the answer lacks evidence, strengthen the page that should substantiate the claim and make its authorship, scope, limitations, and supporting material clear.
    • If competitors are recommended for an attribute you genuinely provide, check whether that attribute is stated explicitly on a crawlable, authoritative page rather than implied in marketing language.
    • If you are recommended but not cited, inspect which domains the answer relies on and whether your own page answers the question directly enough to function as evidence.
    • If visibility rises without a useful business outcome, examine the intent of the tracked prompts, the route from the answer to your site, and the landing experience before declaring success.
    • If an answer is wrong, treat factual correction as a content and entity-management task, not merely a reputation problem.

    Put risk controls inside the daily SEO workflow

    Governance works when the safe path is also the normal path. A policy stored in a shared drive will not stop someone from pasting a client export into an unapproved tool under deadline. Put the checks into the brief, ticket, template, approval flow, and publishing system the team already uses.

    Use five controls in every AI-assisted task: accuracy, accountability, security, fairness, and sustainability. They become practical when each one creates a visible checkpoint.

    1. Classify the task and data. Mark the input as public, internal, or restricted before selecting a tool. Customer records, employee data, unpublished financial information, credentials, and identifiable analytics require stricter handling than a public product page.
    2. Select an approved tool for the job. Record which tools and models may receive each data class. Use the least powerful model that can perform the task reliably; a meta-description rewrite does not need the same resources as complex code or data analysis.
    3. Define what the model may do. Drafting, extraction, clustering, summarization, and formatting are different from deciding what to publish, which claim is true, or which strategic recommendation to accept. Keep consequential decisions with a named person.
    4. Require inspectable output. Ask for claims, uncertainties, and supporting references in a structure a reviewer can check. Fluent prose is not evidence.
    5. Verify against authoritative material. Confirm statistics, quotations, dates, product details, legal claims, and platform metrics at their origin. AI can invent a credible-looking source or even a Search Console metric that does not exist.
    6. Apply risk-based approval. A human can review a low-risk rewrite quickly. Public claims about health, finance, law, safety, security, or a client’s performance need the appropriate subject-matter and organizational review.
    7. Log, publish, and monitor. Preserve the use case, tool, reviewer, evidence, approval, publication target, and monitoring owner. The brand remains accountable for every public claim regardless of how much text a model generated.

    Security needs an unambiguous boundary. Do not enter personally identifiable information, customer data, employee data, or confidential business material into an unapproved AI product. For any trial, confirm in writing that the provider will not train on your data, set an end date, require deletion, and avoid tools that obtain broad browser access to whatever the user is viewing. These are minimum controls for testing an unapproved tool, not substitutes for your security, privacy, procurement, or legal requirements.

    Maintain a tool register so nobody has to guess. Include the tool owner, approved uses, prohibited inputs, permitted data class, training terms, retention and deletion terms, browser or account permissions, access method, review date, and trial expiry. A trial that has no owner or end date is an unmanaged production dependency waiting to happen.

    Accuracy review should focus on claims, not writing style. Mark every externally verifiable statement in an AI-assisted draft, trace it to a real origin, and remove details that cannot be supported. Check that the evidence actually proves the sentence beside it. A real URL attached to an unrelated claim is still a factual failure.

    Fairness review belongs in keyword research and content briefs as well as final copy. Look for unsupported assumptions about who the user is, which examples are treated as normal, and whether the recommended language excludes or stereotypes part of the intended audience. Do not delegate inclusive framing to the model and assume it has been handled.

    Sustainability is both a resource decision and a capability decision. Use a heavy reasoning model where complexity warrants it, not as the default for every rewrite or summary. Repeatedly routing trivial work through an expensive system raises cost and can make a team dependent on automation that adds no meaningful value. If a person can complete the task safely and accurately in less time than it takes to prompt, inspect, and correct the model, the model is the extra step.

    Give every decision an owner and every failure a route

    Professionals oversee sealed data containers moving through review and monitoring checkpoints, with a warning route leading to an incident-response station.

    A governed visibility program needs more than an SEO lead. It touches entity data, editorial claims, analytics, security, procurement, reputation, and sometimes local operations. Name the roles even when one person fills several of them.

    • Program owner: defines the query portfolio, priorities, success criteria, budget, and review cadence.
    • Measurement owner: maintains the prompt registry, collection method, denominators, evidence captures, and dashboard definitions.
    • Entity or data steward: resolves conflicting business facts across websites, listings, feeds, structured data, and internal systems.
    • Content owner: determines which page should answer the need and keeps its claims current, explicit, and supportable.
    • Subject-matter reviewer: validates consequential claims within the relevant discipline instead of merely approving tone.
    • Security or privacy owner: approves tools, data classes, permissions, retention terms, and escalation requirements.
    • Publisher: confirms that required approvals and evidence exist before public release.
    • Incident lead: coordinates containment, correction, notification, root-cause analysis, and control updates.

    For each recurring use case, create a one-page control record. It should state the business purpose, owner, approved tool, permitted inputs, prohibited inputs, model action, required human checkpoint, evidence standard, publication destination, monitoring method, and escalation route. This is short enough to use and specific enough to audit.

    Then rehearse the failures you are most likely to face. A model may fabricate a statistic in a page that becomes publicly indexable. An employee may disclose restricted data to an unapproved service. An automated workflow may update hundreds of pages with an inaccurate claim. An answer engine may repeat outdated location information from a page your team forgot to retire.

    Your incident procedure should tell the first person who notices a problem what to do:

    1. Stop the affected publication, automation, integration, or trial without destroying the evidence needed to investigate it.
    2. Preserve the prompt, input classification, output, model or tool, user, timestamp, approval trail, and affected URLs.
    3. Notify the incident lead and the relevant data, content, security, privacy, or legal owner based on the type of exposure.
    4. Contain the problem by restricting access, correcting or withdrawing false material, and identifying other assets produced by the same workflow.
    5. Assess who or what was affected, including customers, employees, clients, search users, downstream feeds, and pages that may have reused the claim.
    6. Correct public facts at the authoritative source and propagate the correction through pages, listings, feeds, and structured data where applicable.
    7. Document the root cause and update the control that failed, whether it was tool approval, data classification, verification, permissions, or human review.

    Do not punish people for reporting a near miss. Hidden mistakes are harder to contain than visible ones. Give the team a living place to share approved workflows, useful prompts, unexpected outputs, failures, and questions. A dedicated internal channel can turn an isolated experiment into something that receives security and quality review before wider use. It also exposes impractical rules before people begin working around them.

    Finally, make change records part of visibility analysis. When a tracked answer shifts, you should be able to see whether the team changed a source page, corrected structured data, improved local listings, earned new public evidence, altered the prompt set, or changed monitoring tools. Without that record, correlation will repeatedly be mistaken for causation.

    Key takeaways for your operating plan

    • Define visibility as separate outcomes: mention, recommendation, citation, representation, competitive position, and user action.
    • Keep a stable prompt registry with the exact context, engine, market, evidence, result, and reviewer for every tracked test.
    • Separate foundation data, public evidence, answer outputs, and business outcomes so you do not credit the wrong intervention.
    • Put accuracy, accountability, security, fairness, and sustainability checks inside the production workflow rather than a policy nobody opens.
    • Prohibit restricted data in unapproved tools, document provider terms, and give every trial an owner, deletion requirement, and expiry date.
    • Assign named owners for measurement, entity data, content, approval, security, and incidents, even if a small team combines several roles.
    • Treat an AI visibility change as a signal to investigate, not proof that an optimization worked or that visibility caused a business result.

    Start with one commercially important query family. Register the prompts, capture a baseline across the relevant AI surfaces, classify each failure by scorecard layer, and choose one correction with a named owner. Repeat the same test conditions after the change and log what happened. Once that loop produces decisions your team can explain and defend, expand it to the next query family.

    That is the point of governance: not to slow AI search work down, but to make every action traceable, every claim reviewable, and every result useful enough to guide the next decision.

    References


  • Business Context for AI Marketing: A Practical Operating System

    Business Context for AI Marketing: A Practical Operating System

    Your AI can sound polished and still make the wrong marketing decision. It may address the wrong buyer, lead with a secondary benefit, treat an internal ambition as an approved claim, or pursue search demand that has little connection to your offer.

    If better prompting has not fixed that pattern, the missing input is probably business context. You need an approved, current layer of knowledge that tells AI what your business means, which facts it may use, and where its judgment must stop. Build that layer before you scale content generation or marketing automation.

    Why prompt polishing cannot supply missing business truth

    A prompt describes a task. It might specify the format, channel, topic, length, or desired action. It cannot reliably stand in for everything your organization knows about its customers, products, priorities, proof, and restrictions.

    When that knowledge is absent, the model has to complete the task using broad patterns. The result can be grammatically strong and strategically interchangeable. The problem is not necessarily weak writing. It is that the model has no basis for choosing your priority audience over a plausible adjacent audience, an approved product benefit over a popular category claim, or a defensible answer over a more confident one.

    A dedicated context layer is designed to hold, structure, and apply business knowledge so an AI marketer can tailor recommendations and outputs. That is a useful design principle, but reduced manual intervention should be treated as an outcome to validate in your own workflows, not as an automatic result of buying a tool.

    Separate four things that are often mixed into one oversized prompt:

    • Instructions: what the AI should do in this task.
    • Business context: what it needs to know to make choices consistent with your organization.
    • Evidence: what supports the claims it may publish.
    • Guardrails: what it must not infer, disclose, promise, or change.

    This separation makes defects diagnosable. If the format is wrong, fix the instruction. If the audience is wrong, fix the context. If a claim is unsupported, fix the evidence policy. If confidential information appears, fix access and publication controls.

    Key takeaways

    • Business context should change marketing decisions, not merely make prose sound more branded.
    • Store approved facts, priorities, boundaries, and evidence separately from task instructions.
    • Give each context item an owner, scope, status, and rule for resolving conflicts.
    • Retrieve only the context relevant to the current audience, market, offer, and channel.
    • Test context with real marketing tasks and evaluate factual fit, strategic fit, and claim discipline.

    Build context around the decisions AI must make

    Organized groups of customer, product, proof, priority, and constraint objects connect to a central processing device on a strategy table.

    Do not begin by uploading every document your company has produced. A document archive can contain useful knowledge, but it can also contain expired offers, unsupported claims, conflicting terminology, abandoned strategies, and information that should never reach a public workflow.

    Begin with a recurring marketing decision. For example: which angle should lead a landing page, which audience should receive a campaign, which questions deserve answer pages, or whether a query belongs in your organic search plan. Record the business knowledge required to make that decision correctly.

    Business layerContext to recordDecision it should change
    Strategic directionCurrent objective, priority market, priority offering, planning horizon, and explicit non-goalsWhat the AI recommends and what it deprioritizes
    AudienceTarget roles, situations, knowledge level, pains, desired outcomes, objections, and excluded segmentsWho the work addresses and which problem leads
    OfferApproved name, included capabilities, exclusions, prerequisites, availability, and customer responsibilityWhat the AI may promise or compare
    PositioningCategory, differentiation, alternatives, message hierarchy, and claims that require qualificationHow the offer is framed
    EvidenceApproved proof, claim-to-evidence relationships, citation locations, and unsupported assertionsWhich statements can be published confidently
    Brand languagePreferred terminology, prohibited wording, tone rules, definitions, and representative examplesHow the decision is expressed
    Search and discoveryCanonical entity names, topics, audience intent, query groups, answer boundaries, and relevant pagesWhat the organization should be discoverable for
    Operating constraintsGeographic scope, channel restrictions, required reviews, access limits, and escalation ownersWhat can be generated, published, or routed automatically

    For each layer, keep only information that changes a choice or constrains an output. A corporate history may be valuable background, but it does not belong in every content task. An approved definition of your product category may affect almost every page. Context earns its place through decision value, not document length.

    Separate durable knowledge from current work

    Context becomes unreliable when stable business facts and temporary campaign choices occupy the same undifferentiated file. Divide it by scope:

    • Durable business context covers identity, approved terminology, product boundaries, standing evidence rules, and persistent audience definitions.
    • Initiative context covers a launch, campaign, market, offer, or strategic priority that applies only within a named scope.
    • Task context covers the query, page, channel, format, deadline, and action required for the current output.

    Consider a hypothetical software company that generally serves finance teams but is running a campaign for controllers. Durable context defines the product and its approved capabilities. Initiative context makes controllers the priority audience for that campaign. Task context asks for an answer page addressing a controller’s specific question. The campaign should not silently redefine the company’s entire market, and the task should not rewrite product truth.

    Resolve contradictions before generation

    AI should not have to arbitrate between a sales deck, an old web page, and a current product record. If those materials disagree, more retrieval can make the result less reliable.

    Assign a canonical owner for each context type. Mark every item as approved, draft, disputed, or retired. Record which rule wins when scopes overlap. If the business has not resolved a conflict, label it as unresolved and prevent the system from converting either position into a public claim.

    A useful context layer does not pretend the organization is more certain than it is. It gives the AI a safe way to say that information is unavailable, request review, or leave a claim out.

    Make every context item usable and governable

    Long prose is easy to collect but hard to govern. One paragraph can mix an approved fact, a preference, a prediction, and an exception. When one part changes, nobody knows whether the whole paragraph remains valid.

    Store important knowledge as small records that can be approved, retrieved, superseded, or retired independently. Each record should contain:

    • Identifier: a stable name that workflows and reviewers can reference.
    • Statement: one clear fact, rule, priority, definition, or boundary.
    • Type: audience, offer, evidence, positioning, terminology, restriction, or another controlled class.
    • Scope: the brands, products, markets, audiences, channels, and initiatives to which it applies.
    • Status: approved, draft, disputed, or retired.
    • Authority: the internal system or person responsible for confirming it.
    • Evidence: the supporting material, where substantiation is required.
    • Effective condition: when the record applies and which event should trigger review.
    • Precedence: what should happen if another applicable record conflicts with it.
    • Publication permission: whether it is public, internal, restricted, or prohibited from generated output.

    This structure is useful even if you begin in a spreadsheet or content management system. The technology matters less than whether your team can tell what is true, where it applies, who approved it, and what happens when it changes.

    Translate adjectives into decision rules

    Context such as “sound professional” or “focus on quality” gives the model almost no business-specific direction. Replace abstract preferences with observable rules.

    • Replace “sound authoritative” with rules such as: lead with the decision, define specialist terms on first use, distinguish approved facts from recommendations, and omit claims that lack named support.
    • Replace “target enterprise buyers” with the roles involved, the problem each role owns, the objections that matter, the expected knowledge level, and the situations outside the campaign.
    • Replace “highlight our flexibility” with the exact configurable elements, fixed constraints, prerequisites, and wording that must not imply unlimited customization.
    • Replace “optimize for AI search” with the questions the page should answer, the entity names it must use consistently, the evidence available for each material claim, and the pages that establish supporting detail.

    The test is simple: could a reviewer look at the output and determine whether the rule was followed? If not, the context is still a mood rather than an operating instruction.

    Set an explicit order of authority

    Context records will eventually overlap. Establish an order before they do. A practical starting point is to let mandatory legal, security, privacy, and compliance restrictions override approved product facts; let approved facts override campaign language; and let campaign instructions override stylistic preferences. Your actual order should reflect your governance, but it must be visible to the workflow.

    Do not let recency win automatically. A newer brainstorm is not more authoritative than an approved product record merely because its timestamp is later. Status, ownership, and scope are stronger signals than freshness alone.

    Limit what each workflow can see

    Business context may contain unreleased plans, contractual restrictions, customer information, pricing logic, or competitive intelligence. Do not assume every model, integration, user, or publishing workflow should receive every field.

    Create separate public, internal, and restricted views. A public content workflow should receive only facts approved for publication. An internal planning workflow may receive confidential priorities but should be blocked from publishing them. Customer-level or personally identifiable information should not enter an AI workflow unless the organization has explicitly approved the tool, purpose, access controls, and handling process.

    Apply context to SEO, AEO, GEO, and campaign workflows

    A central repository is not enough. Context creates value only when the right records reach the right task. Passing the entire repository into every prompt can introduce irrelevant instructions and hidden conflicts. Retrieve the smallest approved bundle that can support the decision.

    Use this execution flow for a recurring marketing task:

    1. Name the decision, audience, market, offer, channel, and intended action.
    2. Retrieve context whose scope matches those fields.
    3. Resolve precedence and remove draft, retired, restricted, or irrelevant records.
    4. Ask the AI to produce the strategic decision or brief before it produces the finished asset.
    5. Check proposed claims against the approved evidence records.
    6. Generate the asset using only the approved decision, facts, and boundaries.
    7. Route missing evidence, conflicting context, and policy exceptions to the named owner.

    Generating the decision first matters. If you ask for the finished page immediately, a polished draft can hide an incorrect audience or message choice. A short brief exposes those errors while they are still cheap to correct.

    For SEO briefs

    Give the system more than a keyword. Supply the target audience, market, search intent, relevant offering, approved entity names, business objective, available evidence, existing page relationships, and topics that fall outside the offer.

    Require the brief to explain why the query belongs in your strategy. It should connect the query to a real audience problem, an answer your organization can support, and a useful next step. If the connection is weak, the correct output may be to deprioritize the query rather than manufacture relevance.

    For AEO and answer content

    Record the answer boundary as well as the answer. The system needs to know which conditions change the response, which terms require definition, which claims need evidence, and when a general answer would overstate what your business can support.

    Ask for a direct response that can stand on its own, followed by qualifications and supporting detail. Then verify that the visible page actually contains the facts used in summaries, metadata, and structured representations. A concise answer is useful only if compression has not removed a material condition.

    For GEO and AI discovery

    Use context to keep entity identity, product names, audience definitions, category language, and material claims consistent across related pages. Create a claim ledger for each important page with the claim, its supporting evidence, its visible location, its approval status, and any structured-data property that represents it.

    This discipline can make your published information clearer and more internally consistent. It cannot guarantee that a frontier model, answer engine, or AI search feature will retrieve, cite, summarize, or rank the page. Treat visibility as an external outcome to measure, not a promise encoded in the context layer.

    Schema markup should consume approved public facts; it should not become a back door for unverified or confidential context. The visible page, structured data, and canonical business record should agree. Schema is a publication format, not a truth engine.

    For campaigns and content operations

    Keep the strategic decision stable while adapting execution to the channel. The audience, offer boundaries, evidence policy, and intended action can remain consistent, while format, length, sequencing, and creative treatment change for email, paid media, social, landing pages, or sales enablement.

    Route human review to consequential points: new claims, unsupported comparisons, policy exceptions, sensitive audience targeting, and conflicts between records. When approved context already covers a routine choice, reviewers should not have to reconstruct the same business logic for every asset.

    Test the context system, not just the prose

    An analyst observes two parallel AI marketing test pipelines, one producing scattered results and the other producing consistent outputs through organized context modules.

    Do not judge the system by whether one draft sounds impressive. A fluent output can still be wrong, and a stylistic preference can distract reviewers from a serious context failure.

    Build a test set from real, recurring work: a search brief, an answer page, a campaign angle, a product comparison decision, a content refresh, or another task your team already reviews. Include ordinary cases, boundary cases, missing-information cases, and cases in which the correct response is to escalate or refuse a claim.

    For each task, compare a context-enabled run with a baseline using the same task and model settings. Evaluate the decision and evidence use before evaluating style. Your review should answer:

    • Did it select the intended audience, market, offer, and objective?
    • Did it use the approved terminology and canonical entity names?
    • Did it distinguish a verified fact from a recommendation, hypothesis, or unknown?
    • Did every material claim stay within the available evidence?
    • Did it obey exclusions, publication permissions, and review requirements?
    • Did it explain why the recommendation fits the current business priority?
    • Did it avoid dragging irrelevant context into the output?
    • Did the same approved facts remain consistent across channels and formats?

    Record failures against the context system rather than patching each draft in isolation.

    Observed failureLikely context defectCorrective action
    The output is polished but aimed at the wrong buyerAudience scope is vague, overlapping, or not retrievedAdd inclusion and exclusion rules, then test retrieval against the task scope
    The output contains a plausible but unsupported benefitClaims are not linked to evidence or unsupported claims are not prohibitedCreate a claim-to-evidence record and require escalation when support is absent
    The recommendation follows an outdated priorityInitiative status or precedence is unclearRetire the old record and specify which current initiative overrides durable defaults
    The answer is correct but interchangeable with competitorsPositioning is expressed as adjectives rather than decision rulesRecord the actual category, differentiators, alternatives, and message hierarchy
    Different workflows describe the same offer differentlyCanonical names and offer boundaries are duplicated across systemsReference one approved record and distribute channel-specific views from it
    The AI exposes internal plans in public copyPublication permissions or access scopes are missingSeparate public and restricted views, then block restricted fields from publishing workflows
    The system asks for manual review on every taskApproval status, boundaries, or exception rules are incompleteApprove routine cases explicitly and reserve escalation for named exceptions

    Define what ready means

    Your context layer is ready for a workflow when the AI can make the intended decision, identify the applicable evidence, respect the stated boundaries, and surface uncertainty without a reviewer rebuilding the brief from scratch. It is not ready merely because the repository is large or the generated copy sounds on-brand.

    Start with one recurring decision before attempting an organization-wide knowledge project. Capture only the context needed for that decision, assign authority and publication status, compare it with the baseline, and repair the defects you observe. Expand to another workflow only when the first context bundle consistently changes decisions in the intended way.

    The goal is not maximum context. It is the minimum approved context required for AI to do useful marketing work without inventing the business around your prompt.

    References


  • Embedded AI Search Adoption: A Practical Content Strategy

    Embedded AI Search Adoption: A Practical Content Strategy

    If your AI search dashboard starts with chatbot referrals, you may be measuring the easiest activity to see rather than the behavior that matters most. Embedded AI can answer, compare, and recommend inside a product the user has already opened, so no separate chatbot session – or visit to your website – is required.

    The shift is large enough to change your priorities. AI search grew 70% year over year in 2026, while embedded AI in Meta, Amazon, and Google products outpaced standalone chatbots. Your practical question is now broader than whether a chatbot can cite a page: can each relevant platform identify, interpret, and use your information correctly when a person needs it?

    Key takeaways

    • Treat embedded AI as a discovery and decision layer, not merely another referral channel.
    • Organize your strategy around customer decisions before choosing platforms, prompts, or schema types.
    • Give every important fact one authoritative home, then keep its wording and qualifications consistent across relevant surfaces.
    • Use JSON-LD to reinforce meaning already visible on the page. Valid markup cannot guarantee AI inclusion.
    • Measure presence, accuracy, attribution, destination, and business outcomes separately. A single traffic figure hides most of the useful diagnosis.

    Embedded AI changes the unit of optimization

    A standalone chatbot is a destination. A person opens it, enters a prompt, and receives a response. Embedded AI is a capability inside a journey that has already begun: searching, shopping, browsing, evaluating, or deciding what to do next.

    That distinction changes what successful optimization looks like. A traditional search report tends to emphasize rankings, impressions, clicks, sessions, and conversions. Those metrics still matter, but an embedded answer can influence a decision without producing a referral that your analytics can identify.

    Evaluate each important topic as a sequence of outcomes:

    1. Eligibility: Is your information available in a form the relevant system can access and interpret?
    2. Understanding: Can the system identify the subject, the claim, the relationship between entities, and any conditions attached to the answer?
    3. Representation: Does the generated response describe your brand, product, service, or expertise accurately?
    4. Usefulness: Does the response help the user complete the decision rather than merely repeat a slogan?
    5. Next action: When a visit is appropriate, does the response lead to the correct page, listing, profile, or product record?

    This model prevents two common misreadings. No click does not prove that your content had no influence, and a click does not prove that the preceding answer was accurate. Track exposure, representation, and traffic as related but distinct events.

    Do not abandon conventional SEO to pursue this shift. Clear page architecture, crawlable content, stable canonical URLs, accurate titles, descriptive headings, internal links, and authoritative evidence still make your information easier to find and understand. AI optimization extends that foundation; it does not excuse a weak one.

    You should also resist the idea of a universal AI ranking position. Embedded systems operate in different products and contexts. An appearance in one response is evidence about that response, not proof of broad visibility across every AI surface.

    Plan around decisions, then adapt to each environment

    A central decision point and supporting evidence branch into adapted answer, comparison, and recommendation modules across several generic devices.

    Starting with a list of AI products usually creates scattered work: a page for one chatbot, a few experimental prompts, and schema added wherever it fits. Start instead with the decisions your audience is trying to make. The same decision may surface in several environments, while the evidence needed to resolve it should remain consistent.

    Embedded environmentLikely user taskInformation to make explicit
    Google productsUnderstand a subject, compare options, find an entity, or choose a next stepDirect answers, definitions, comparison criteria, entity relationships, evidence, and any location or service boundaries
    Amazon productsCompare products and reduce uncertainty before a purchaseCanonical product identity, variants, specifications, compatibility, intended use, and material limitations
    Meta productsDiscover, ask about, or evaluate a brand or offer in a social contextConsistent names, concise factual claims, supporting context, recognizable assets, and a clear next action

    This is a planning map, not a claim about hidden ranking factors. Use it to identify which facts a person needs in each context. Then validate visibility through observation rather than assuming that every platform retrieves, weighs, or presents information in the same way.

    Build an intent-to-fact matrix

    For each high-value decision, create a working record with the following fields:

    • User decision: What is the person actually choosing, checking, or trying to understand?
    • Direct answer: What is the shortest accurate response your evidence supports?
    • Required qualifications: Which audience, market, product, plan, version, location, or use case does the answer cover?
    • Supporting facts: What evidence, specifications, examples, definitions, policies, or primary records make the answer credible?
    • Canonical home: Which owned URL or structured record is authoritative for this information?
    • Relevant environments: Where is the decision likely to arise, and how does the surrounding task change the presentation?
    • Known conflicts: Which pages, profiles, listings, feeds, or product records currently contradict the canonical answer?

    One page does not have to target every platform. The important discipline is that each critical fact has one authoritative home and does not acquire a different meaning as it moves through your content system.

    Prioritize the matrix with a simple editorial rule: work first on decisions that combine high business value, a meaningful information gap, and strong relevance to an embedded environment. This is more useful than spreading effort evenly across every prompt that happens to mention your category.

    Make important claims easy to extract and hard to misread

    Many pages contain the right information but make a machine – and often a hurried reader – assemble it from several sections. The product name appears in one heading, the answer sits in an image, the limitation is buried near the footer, and a conflicting statement survives on an older page. That is an interpretation problem before it is an AI problem.

    Audit every answer-bearing section for the elements below:

    • Name the subject: Use the complete entity, product, service, or concept name in the heading or opening sentence instead of relying on vague pronouns.
    • Lead with the answer: Put the direct response before history, positioning, or promotional context.
    • Keep qualifications attached: If a claim applies only to a particular market, plan, version, audience, or condition, state that boundary in the same sentence or immediately after it.
    • Define comparisons: Say what is being compared and on which criteria. Words such as better, faster, simpler, and cheaper are incomplete without a basis.
    • Separate facts from persuasion: Distinguish a verifiable capability from a marketing interpretation of that capability.
    • Support consequential claims: Link to the strongest evidence you actually have, preferably the primary record behind the claim.
    • Resolve contradictions: Update, redirect, remove, or clearly qualify stale pages instead of hoping a system chooses the newest wording.
    • Keep key information in text: Images and video can add context, but the decisive answer and its limitations should also appear as accessible page content.

    Write answer blocks that remain accurate when extracted

    An effective answer block has a descriptive heading, a direct opening sentence, the condition that limits the answer, and enough supporting detail to make the response useful. Follow it with criteria, steps, or a comparison only when those elements help the user complete the decision.

    Read the opening sentence by itself during your audit. If it becomes misleading after removal from the surrounding page, the block is not self-contained enough. For example, a capability that is available only for a particular plan remains false when the plan limitation is several paragraphs away. Move the limitation next to the capability.

    This does not mean writing robotic fragments or repeating the same keyword. It means preserving the relationship between the subject, the claim, and its boundary. You can still explain nuance in natural prose after the direct answer is secure.

    Use JSON-LD as a consistency layer

    Structured data is most useful when it confirms the meaning of visible content. Select a schema type that fits the page, identify the main entity precisely, and connect related organizations, people, products, offers, places, or creative works only when those relationships are real and supported on the page.

    • Keep names, URLs, identifiers, prices, availability, authorship, and other marked-up properties aligned with the visible page whenever those properties apply.
    • Use one canonical identifier for the same entity across templates and records.
    • Do not add unsupported claims to JSON-LD because they are easier to publish there than in visible copy.
    • Validate syntax and inspect the rendered page, not just the content-management field where the markup was entered.
    • Recheck structured data whenever a template, product feed, page type, or canonical URL changes.

    Valid markup is not a guarantee that an AI system will retrieve, cite, or recommend the page. Schema reduces ambiguity; it does not create authority, repair contradictory content, or replace evidence.

    Measure adoption without pretending every influence is a click

    A shopper progresses from an embedded AI recommendation through comparison and product inspection to purchase, with connected signals showing indirect influence beyond a website click.

    Your analytics may identify some AI referrals. They cannot record an embedded interaction that ends inside another platform. A useful measurement system therefore combines direct observations with business data and labels the difference between them.

    Build the scorecard around separate diagnostic questions:

    • Presence: Does your brand, product, page, or expertise appear for the tracked decision?
    • Accuracy: Are the core facts correct, complete, and properly qualified?
    • Attribution: Is the information associated with the right entity, and is a citation or link present when the response provides one?
    • Destination: Does any available link lead to the authoritative page rather than an obsolete or irrelevant URL?
    • Competitive context: Which alternatives appear, and what information do they make clearer than you do?
    • Business effect: Do qualified visits, branded demand, assisted conversions, or other relevant outcomes change alongside visibility? Treat this as an association unless you can establish causation.

    Keep visibility metrics and business metrics in separate columns. Combining them into a single AI score makes diagnosis difficult: an accurate answer with no link requires a different response from an inaccurate answer that sends substantial traffic.

    Use a repeatable observation protocol

    1. Create a fixed set of queries from the decisions in your intent-to-fact matrix. Include discovery, comparison, qualification, and next-step language where those stages are relevant.
    2. Run each query in the environments where that decision naturally occurs. Do not treat a standalone chatbot check as a substitute for an embedded surface.
    3. Record the exact query, response, environment, date, visible citation or link, and any account, location, language, or device context that could affect interpretation.
    4. Classify the result as present and correct, present but incorrect or incomplete, or absent.
    5. Trace errors back to a specific cause you can inspect: missing content, ambiguous wording, contradictory records, weak evidence, incorrect entity relationships, inaccessible information, or the wrong destination.
    6. Make a focused correction, document it, and repeat the same observation process at a consistent cadence.

    Repeated observations matter because generated responses can vary. Preserve the history instead of replacing an unfavorable result with a favorable screenshot. Your goal is not to prove that you appeared once; it is to understand whether your information is represented reliably enough to support the user’s decision.

    Turn embedded search optimization into an operating routine

    Embedded AI search crosses responsibilities that many organizations keep separate. Editorial teams own explanations, SEO teams own discovery and technical quality, product or commerce teams own specifications and feeds, brand teams own naming, and analytics teams own measurement. If those groups publish conflicting facts, no schema plugin or prompt test can create a reliable answer layer.

    Use this sequence to turn the strategy into routine work:

    1. Select the highest-value decisions. Begin where an absent or incorrect answer would materially affect discovery, qualification, or purchase intent.
    2. Assign a canonical owner. Make one team or role responsible for approving the definitive fact and its qualifications.
    3. Audit every expression of that fact. Check relevant pages, profiles, listings, product records, feeds, and structured data for disagreement.
    4. Repair the authoritative asset. Add a self-contained answer block, supporting evidence, clear entity naming, and matching JSON-LD where appropriate.
    5. Propagate the correction. Update the other owned surfaces that legitimately repeat the fact without creating competing canonical versions.
    6. Observe relevant embedded environments. Score presence and accuracy using the same decision-led queries.
    7. Feed errors back into content operations. Treat incorrect AI representation as a data-quality or content-quality issue with an owner, not as an isolated screenshot for the SEO team.

    Do not optimize for mentions at the expense of truth. If an embedded response exposes a genuine ambiguity in your offer, policy, product data, or explanation, fix the ambiguity at its origin. The durable advantage is not wording engineered for one generated answer; it is a body of content that reaches the same accurate conclusion wherever a system encounters it.

    Start with the decision where a missing or wrong answer costs you the most. Give its facts a canonical home, attach every necessary qualification, align the structured data, and test it in the environments your audience already uses. Once that loop works, expand by decision value rather than by platform novelty.

    References


  • Human-Led AI Workflows for SEO: A Practical System

    Human-Led AI Workflows for SEO: A Practical System

    You don’t need to choose between banning AI from SEO and letting an agent run your site. The useful middle is a workflow in which AI accelerates analysis and production while a person remains accountable for the decisions that can affect rankings, crawlability, brand trust, and measurement.

    Your goal is not to put a human approval step at the end of an automated content factory. It is to place human judgment at the few points where a plausible answer can become an expensive mistake: choosing the page, defining its unique contribution, validating its evidence, approving the technical change, and interpreting the result.

    Human-led means retaining decision authority, not doing everything manually

    AI is genuinely useful for clustering keywords by intent, identifying content gaps, analysing pages, and producing first-pass outlines. Those tasks compress a large amount of reading and organisation. They do not require the model to decide what your site should publish or change.

    The boundary should be based on authority. Let AI transform information, expose patterns, draft options, and run checks. Keep a person responsible for choosing the objective, accepting the evidence, resolving conflicts, approving live changes, and deciding whether an experiment worked.

    That distinction matters because fluency is not reliability. A model can produce a tidy keyword map, persuasive rationale, polished page, and confident recommendation even when the underlying choice is wrong. It may not know that a proposed URL conflicts with an existing page, that a claim lacks support, or that a template renders essential content only after client-side JavaScript runs.

    Google’s stated position is that using AI to produce content is not inherently against its guidelines when the result is helpful and made for people. The operational risk is therefore not the presence of AI. It is publishing low-value or technically unsound work because nobody tested whether the output deserved to exist.

    Key takeaways

    • Use AI to analyse evidence and generate options; do not let it define success or approve its own work.
    • Separate opportunity selection, research, briefing, drafting, technical validation, publication, and measurement into distinct gates.
    • Require a unique contribution before drafting. A new keyword target is not, by itself, a reason to create a new URL.
    • Route every live change through a reviewable diff, a validation checklist, and a rollback plan.
    • Measure one declared hypothesis against the pages and metric the change could actually affect.

    Turn the workflow into gates with visible pass conditions

    A human reviewer inspects five abstract SEO workflow stages separated by approval gates on a studio table.

    A single prompt that asks for research, strategy, a draft, optimisation, and publication collapses several different decisions into one answer. By the time you see the finished page, the model has already assumed the search intent, selected the format, decided whether to create or update a URL, filled evidence gaps, and judged its own quality.

    Break that chain apart. Each stage should produce an artifact that the next reviewer can inspect. A pass condition should be observable rather than subjective: not good quality, but target intent is named, competing URLs were checked, every factual claim has support, and the proposed contribution is absent from the comparison set.

    StageAI contributionHuman decisionRequired artifact
    1. OpportunitySummarise query, page, conversion, and competitive data; surface patterns and anomalies.Choose the business and user problem worth solving.A work order with the target audience, objective, metric, scope, and exclusions.
    2. Intent and URL mappingCluster queries, describe likely intents, and identify potentially competing pages.Decide whether to create, consolidate, refresh, redirect, or stop.A query-to-URL map that names the current owner and proposed owner of each intent.
    3. EvidenceOrganise supplied data, first-hand notes, examples, and references; flag unsupported claims.Confirm provenance and decide what may be published.An evidence pack in which every input has an owner or traceable origin.
    4. Information gainCompare the planned coverage with ranking pages and identify repetition or gaps.Determine whether the page adds a useful fact, method, example, tool, dataset, or point of view.A one-sentence unique-contribution statement plus the evidence needed to deliver it.
    5. Brief and draftBuild an outline, draft sections, suggest internal links, and mark open questions.Correct the framing, verify claims, remove filler, and protect the brand’s position.A draft with unresolved questions clearly marked rather than silently completed.
    6. Technical preflightRun repeatable checks on metadata, links, structured data, indexation directives, and rendered content.Inspect the actual change and resolve conflicts or failures.A pass-or-fail report tied to the exact URL, build, or commit being reviewed.
    7. ReleasePrepare a diff, change log, test instructions, and rollback steps.Approve the specific version that will go live.A recorded sign-off and a recoverable previous state.
    8. MeasurementCollect the declared metric and summarise what changed.Judge causality, retain or reverse the change, and select the next test.An append-only experiment record, including inconclusive results.

    The information-gain gate belongs before the draft. If the only proposed difference is a longer word count, a new title, or rearranged coverage, stop. Ask for first-hand evidence, proprietary data, a concrete workflow, a useful tool, or a sharper answer to a neglected part of the intent. A gated system prevents average ideas from becoming finished pages merely because drafting is cheap.

    A useful gate prompt is narrow: Review this opportunity as an SEO decision, not as a writing task. Using the target query, existing URL map, ranking-page notes, and evidence pack, return the dominant intent, the URL that should own it, any cannibalisation risk, the unique contribution, missing evidence, and one verdict: pass, revise, or stop. Do not fill evidence gaps with assumptions.

    The verdict remains advice. The human reviewer should be able to explain why the page should exist without repeating the model’s wording. If you cannot state the intended reader, unmet need, unique contribution, and correct URL in plain language, the opportunity has not cleared the gate.

    Keep AI away from unreviewed changes to the live site

    A human operator reviews abstract page and code modules in a staging area before allowing them into a protected live website environment.

    The most important permission boundary sits between proposing a change and applying it. Read access to analytics, crawls, keyword sets, page inventories, and content repositories can create enormous leverage. Unrestricted write access to a CMS, routing configuration, templates, redirects, canonical tags, robots directives, structured data, or measurement code creates a different risk class.

    A live-site failure shows why. An AI system asked to recommend keywords and build the necessary pages produced two new URLs that largely copied the homepage while changing the title tag and H1. After six months, the two dedicated pages had zero impressions and zero clicks in Google Search Console, while the homepage continued to receive the relevant queries. This is one site’s result, not a universal performance benchmark. The reusable lesson is the failure mode: the system satisfied the surface instruction to create targeted pages without giving either page a distinct purpose.

    The same cloning pattern appeared on a separate project, where a batch of keyword-targeted pages copied the homepage and changed little beyond their titles. That is what a human URL-mapping gate should catch before a draft exists. Microsoft has also confirmed that Bing’s models can group near-duplicate URLs and select an unintended representative, so duplication can obscure which page should appear in conventional search and AI-generated answers.

    Use a change packet whenever AI proposes work that could reach production. The packet should contain:

    • Exact scope: every URL, template, file, rule, and structured-data type affected.
    • Before-and-after diff: the actual text or configuration change, not a prose summary.
    • Purpose: the user problem, target intent, and expected mechanism of improvement.
    • Evidence: the data and approved claims used to justify the change.
    • Conflict check: existing URLs, keywords, canonicals, redirects, and templates that could overlap.
    • Validation plan: what will be checked in staging and again after release.
    • Rollback: how to restore the previous state without reconstructing it from memory.
    • Measurement: the page-specific metric and the condition that would count as a valid result.

    Then perform the preflight against the built page, not the intended page. Confirm that the title, H1, main content, internal links, canonical URL, indexation directives, and structured data are present in the delivered output. Check that structured data describes visible content and approved claims. Inspect server-returned HTML as well as the browser-rendered page when essential content depends on JavaScript.

    That last check matters beyond Google. One practitioner’s measurement found ClaudeBot downloaded a JavaScript bundle in 24% of its requests but did not execute it. Treat that as one observed implementation behaviour, not a guaranteed rate for every site or bot. The practical response is still sound: do not assume a page is machine-readable because it looks complete in your browser.

    For routine work, let the system create a CMS draft, branch, pull request, or staging build. Require a named person to approve URL creation or deletion, redirects, canonical changes, indexation controls, template-wide edits, bulk internal links, measurement code, and publication. AI can produce the checklist and flag deviations; it should not be the sole reviewer of its own output.

    Measure a declared hypothesis instead of rewarding activity

    Human control is also necessary after publication. An automated report can find a favourable movement and attach it to the latest task, even when the changed pages could not have caused that movement. That creates a learning system that rewards coincidence.

    Define the experiment before the change. Use one sentence: If we make this change to these pages, we expect this metric to move because this user or crawler problem will be reduced. Name the affected URLs, the baseline, the primary metric, any guardrail metric, the review window, and the evidence that would make the outcome valid. Choose the review window based on the site’s crawl patterns, traffic, and decision cycle rather than inventing a universal deadline.

    Keep each run narrow enough to interpret. A bounded agent can read the roadmap, state file, and prior log, then recommend one justified action. It can also recommend no change when the evidence is weak. If you permit execution, constrain it to a reviewable draft or branch unless the action has already been proven safe, is reversible, and falls inside an explicitly approved class.

    The experiment log should record:

    • the hypothesis and why the action should affect the selected metric;
    • the exact pages and elements changed;
    • the baseline and date range used;
    • the model, instructions, evidence pack, and workflow version involved;
    • the human reviewer and approval decision;
    • the release date and any confounding changes;
    • the observed result, including negative and inconclusive outcomes;
    • the decision to retain, revise, reverse, or run a follow-up test.

    Use a strict causal rule: a metric movement does not count if the shipped change did not touch the pages or mechanism that metric represents. In one autonomous run, average position improved from 48 to 39, but the result was logged as inconclusive because the change affected pages outside the measured target set. That is the behaviour you want from an AI-assisted testing system. Its job is to preserve the truth of the experiment, not to manufacture wins.

    Do not hide rejected recommendations or failed tests. They reveal which inputs are missing, which instructions are ambiguous, and which permission boundaries need tightening. An append-only log turns human review from an approval ritual into operational memory.

    Install a minimum viable workflow before expanding automation

    You do not need to redesign the whole SEO operation at once. Start with one recurring unit of work, such as content briefs, refresh recommendations, internal-link opportunities, or schema proposals. Pick a task that happens often enough to expose patterns but can still be reviewed carefully.

    1. Write the work order. Name the user problem, business objective, primary metric, allowed inputs, prohibited actions, and person accountable for approval.
    2. Disable direct publication. Route output to a draft, ticket, branch, or staging environment. Preserve the original state.
    3. Create three reusable templates. Use an evidence pack for inputs, an acceptance checklist for review, and an experiment log for outcomes.
    4. Pilot a small batch. Ten items can be enough to expose recurring rejection reasons without turning the pilot into a production commitment. This is a practical batch size, not a performance threshold.
    5. Classify every intervention. Record whether the reviewer corrected intent, URL choice, evidence, factual accuracy, duplication, brand framing, technical implementation, or measurement.
    6. Improve the system at the earliest failed gate. If reviewers repeatedly catch duplicate intent at final QA, move the URL-map check ahead of drafting. Do not solve an upstream decision problem with more downstream editing.
    7. Expand one permission at a time. Grant a new capability only when its inputs, output, reviewer, validation, and rollback path are explicit.

    Before any item goes live, ask the reviewer five questions: Why should this page or change exist? What evidence supports it? What exactly will change? What could it conflict with or break? How will we know whether it worked? A missing answer is a stop signal, not an invitation for the model to improvise.

    The next time your team asks to automate more SEO, automate the collection, comparison, drafting, checking, and documentation first. Keep the decision rights visible. Once the workflow can show its evidence, its diff, its reviewer, and its result, you can increase speed without surrendering control of what your site becomes.

    References


  • AI Search Terminology: What Marketers Should Call the Work

    AI Search Terminology: What Marketers Should Call the Work

    You need a name for the work. It might be a budget line, a strategy deck, a job description, a service page, or the agenda for a meeting between SEO, content, PR, and analytics. Should you call it SEO, AI SEO, AEO, GEO, LLM optimization, or AI search optimization?

    Use SEO as the organizational umbrella and AI search optimization as the plain-language qualifier. Reserve AEO, GEO, and similar terms for a defined workstream. That gives familiar language to the person approving the work without hiding what has changed.

    The practical naming default: SEO plus AI search visibility

    Marketers have not abandoned SEO as quickly as specialist vocabulary might imply. Among 343 U.S. marketing decision-makers surveyed, 81% still called their internal AI search visibility strategy SEO. When searching online for help, 46% said they would use “AI search optimization” and 24% would use “SEO.” Together, those two understandable phrases accounted for 70% of the reported demand.

    Formal terminology is even less settled inside teams. Only 27% had adopted a term beyond SEO, while 42% had decided against doing so and 31% remained undecided. Treat those percentages as a directional view of one U.S. sample, not a universal naming law. They are self-reported choices from 343 decision-makers, not a census of every market or industry.

    Slow vocabulary adoption does not mean the work is being ignored. Respondents allocated an average of 24% of their search or content budgets to AI search visibility. Up to 82% reported committing at least some budget, and 43% allocated more than 20%. The label is lagging behind the investment.

    This creates a useful naming hierarchy:

    • SEO is the established program or department under which the work can sit.
    • AI search visibility names the business outcome: whether and how the brand appears in AI-mediated discovery.
    • AI search optimization names the work intended to improve that outcome.
    • AEO, GEO, LLM optimization, and agentic search optimization name narrower approaches or environments, but only after you define their scope.

    A practical strategy title is therefore “SEO and AI Search Visibility.” A defensible budget line is “SEO, including AI search optimization.” Both acknowledge the new surface without asking every stakeholder to learn an unsettled taxonomy before approving the work.

    A working glossary that distinguishes outcomes from methods

    A glowing destination and audience symbols are connected by a bridge to an arrangement of tools, content blocks, and linked source nodes.

    The category now spans AI search, answer engine optimization, and agentic-web terminology. These labels are useful, but they are not interchangeable and they are not universally standardized. Adopt working definitions inside your organization so the same acronym does not describe three different plans.

    TermUseful working definitionUse it whenCommon failure
    SEOThe established program for improving organic discovery, site accessibility, relevance, authority, and search performance.You need an umbrella understood by executives, practitioners, procurement teams, and job candidates.Treating AI-generated discovery as merely another ranking report, with no attention to answers, citations, or brand representation.
    AI search visibilityThe observable outcome of whether, where, and how a brand, product, person, or idea appears in AI-mediated search and answers.You are discussing goals, reporting, competitive presence, or reputation rather than a specific technique.Reducing visibility to a single score without examining accuracy, prominence, cited evidence, or business relevance.
    AI search optimizationThe broad set of activities intended to improve discovery, accurate representation, citations, and useful visibility across AI-generated search experiences.You need a buyer-friendly name for a cross-functional program that extends existing SEO.Using the phrase as a vague replacement for SEO without specifying platforms, prompts, owners, or measurements.
    AEOAnswer engine optimization: making relevant information clear, retrievable, well-supported, and suitable for systems that resolve questions with direct answers.The work focuses on question coverage, answer clarity, content structure, entity facts, and supporting evidence.Presenting AEO as a schema-only project. Structured data can clarify machine-readable facts, but it does not create authority or make weak content worthy of use.
    GEOGenerative engine optimization: improving the chance that a brand or its information is accurately represented, supported, and cited in generated responses.The scope includes generated answer behavior, third-party authority, citations, brand mentions, and source influence.Using GEO as an unexplained synonym for all SEO work or implying that optimization can guarantee a model recommendation.
    LLM optimizationA label centered on visibility or representation in products powered by large language models.The analysis genuinely concerns LLM-powered outputs, model-specific behavior, or the information environments those products use.Implying that a marketer can directly optimize an underlying model in the same way a page can be edited.
    Agentic search optimizationWork intended to help AI agents discover, evaluate, and use information while researching or completing tasks.Agent behavior and task completion are explicitly in scope, not merely the display of an answer.Using an early, specialized label as a general buyer-facing umbrella without defining what the agent is expected to do.

    The boundaries will overlap. An authoritative comparison page can support SEO, answer retrieval, generative citations, and agent research at the same time. That overlap is a reason to define the terms, not a reason to build separate teams around every acronym.

    For each term you adopt, write one sentence that answers three questions: Which discovery surface is in scope? What outcome are you trying to change? What work will the team perform? If the definition cannot answer all three, the term is branding rather than an operating instruction.

    Choose the term by the decision it needs to unlock

    The best label depends less on who has the newest vocabulary and more on what the recipient must decide. An executive deciding whether to fund the program needs a different level of detail from an analyst designing a prompt-monitoring workflow.

    1. For a strategy title, use “SEO and AI Search Visibility.” It connects the established function to the new outcome. Follow it with a scope statement naming the relevant answer surfaces, content, authority, technical foundations, and measurement.
    2. For a budget line, use “SEO, including AI search optimization.” State which existing budget funds it and which additional work the allocation covers. This prevents a terminology change from quietly becoming duplicate spending.
    3. For a vendor brief, ask for “AI search visibility across named buyer journeys and platforms.” Require the response to explain prompt selection, source analysis, content and authority work, measurement, and ownership. Do not award points merely for using GEO or AEO.
    4. For a dashboard, report “Organic Search” and “AI Search Visibility” as related views. Keep familiar SEO measures where they remain useful, then add AI-specific observations such as brand presence, answer accuracy, cited URLs, third-party source inclusion, referral quality, and assisted outcomes.
    5. For a specialist workstream, use the narrow acronym and define it. “AEO for support questions” or “GEO for category-comparison prompts” gives the term an object, a surface, and a purpose.
    6. For a job description, lead with the established function. A title such as “SEO Manager, AI Search” is easier to interpret than an acronym-only role. Put the changed responsibilities in the job scope: prompt research, answer-surface monitoring, entity consistency, structured content, external authority, and cross-channel measurement.

    Seniority changes the vocabulary but does not eliminate confusion. C-suite respondents used GEO at 28% and AEO at 17%, compared with 9% and 3% among individual contributors. Yet 56% of C-suite respondents also reported looking up an unfamiliar term. An executive using GEO may be signaling interest in the category, not agreement on a detailed operating model.

    Meet that interest with a definition, not another acronym. The most useful copy-ready version is:

    AI search optimization is the part of our SEO program that improves how our brand is discovered, represented, and cited in AI-generated search and answers. It combines technical accessibility, useful content, credible external signals, and measurement across the platforms our buyers use.

    That statement connects the emerging category to work a team can assign. It also avoids promising control over an AI system’s output.

    Clear language matters in vendor selection. Excessive buzzwords without explanations were the leading red flag for 36% of respondents. When GEO or AEO appeared in a pitch, 42% said their reaction depended on the context provided, 30% considered the language innovative, 22% said it had no effect, and 7% considered the vendor less trustworthy. The acronym can open a conversation, but it cannot carry the business case.

    Any internal proposal or vendor pitch should explain four things before introducing a specialized term:

    • Outcome: What should become more visible, accurate, authoritative, or useful?
    • Surface: Which search experiences, AI products, and buyer questions are included?
    • Method: What will change on owned pages, technical systems, structured data, external publications, community sources, or measurement workflows?
    • Evidence: What baseline, observations, and business measures will show whether the work helped?

    Turn terminology into an operating model

    Four teams at connected workstations contribute content, search, relationship, and measurement elements to a shared central hub.

    A new term earns its place only when it makes execution clearer. If GEO appears in a deck but nobody can identify the prompts, sources, owners, or measures attached to it, the team has renamed the problem rather than organized the work.

    Do not begin by creating a separate strategy for every platform. Reported priorities were fragmented: 34% prioritized ChatGPT, 16% Gemini, 6% Claude, 5% Copilot or Bing AI, and 1% Perplexity, while 14% had not selected a target platform. Those figures describe stated priorities in the U.S. sample, not platform usage or market share. They show why your own buyer behavior must determine scope.

    Build a scope from prompts and evidence sources

    1. Start with buyer decisions. Build a prompt set around the questions that precede discovery, comparison, validation, purchase, implementation, and troubleshooting. Include branded and unbranded questions. A list of head keywords alone will miss the context carried through a conversational query.
    2. Select surfaces based on those buyers. Test the relevant prompts across ChatGPT, Gemini, Google AI Overviews, Claude, Copilot or Bing AI, Perplexity, and any category-specific experience that matters to your market. You do not need to prioritize every surface equally.
    3. Record the answer, not just presence or absence. Capture whether the brand appears, how it is characterized, which alternatives appear, what factual errors matter, which URLs or publishers are cited, and whether the response satisfies the intended question.
    4. Map the information environment. Generated answers may draw influence from your own site, competitor content, list articles, trade publications, analyst pages, community discussions, Reddit threads, and YouTube transcripts. Mark each recurring source as owned, earnable, partner-controlled, community-controlled, or outside your realistic influence.
    5. Assign work by lever. SEO can own crawlability, internal architecture, canonical signals, and search demand. Content can own question coverage, clarity, evidence, and maintenance. PR and brand teams can build credible third-party mentions. Subject-matter experts can validate factual claims. Analytics can connect answer visibility to referral and downstream behavior.
    6. Name the workstream last. Once the team can see the surface, outcome, and activities, decide whether it is best described as SEO, AI search optimization, AEO, GEO, reputation work, digital PR, content operations, or a combination.

    This sequence prevents a label from dictating tactics. A query audit might reveal that a technical indexing problem is limiting discoverability, that weak comparison content is leaving an answer gap, or that authoritative third-party pages consistently omit the brand. Those are different problems even when all three reduce AI visibility.

    Measure the representation, the evidence, and the outcome

    No single metric can represent the entire program. An AI visibility score may help summarize repeated observations, but it can hide whether the brand is being recommended accurately, criticized, cited only for irrelevant questions, or mentioned without a path to the business.

    Use a compact scorecard with four layers:

    • Presence: How often does the brand appear for the defined prompt set, and which competitors appear beside it?
    • Representation: Are important facts, positioning, limitations, and differentiators described accurately?
    • Evidence: Which owned and third-party pages support the response? Are the citations relevant, credible, current enough for the question, and realistically influenceable?
    • Business effect: Do AI referrals, branded searches, qualified visits, assisted conversions, sales conversations, or other appropriate outcomes change alongside visibility?

    Keep the prompt set, platform set, capture method, and scoring rules documented. Otherwise, an apparent gain may come from changing the questions or evaluation method rather than changing market visibility. Generated responses can vary, so repeated observations and saved evidence are more useful than treating one answer as a permanent ranking.

    The naming debate should not consume the strategy. In the same decision-maker group, 28% named the pace of change as their leading challenge, ahead of measuring AI-result performance or visibility at 17%, choosing platforms at 15%, and the lack of standards or best practices at 13%. A durable operating model should therefore preserve familiar ownership while allowing the tested platforms, prompts, sources, and measures to change.

    Key takeaways

    • Keep SEO as the default organizational umbrella unless a different label solves a specific ownership or budgeting problem.
    • Use AI search optimization when you need a clear external or cross-functional name for the work.
    • Use AI search visibility for the outcome you measure, not as a substitute for defining the work.
    • Use AEO, GEO, LLM optimization, or agentic search optimization only with a one-sentence definition of the surface, outcome, and activities.
    • Do not mistake slow acronym adoption for weak investment. Teams can fund new work while keeping the familiar SEO label.
    • Evaluate a strategy by its prompts, evidence sources, owners, and measurements. Terminology is useful only when it makes those elements easier to understand.

    Open your current strategy document and inspect the first mention of the program. If it contains only an acronym, replace it with “SEO and AI Search Visibility” and add one sentence defining the surfaces, outcomes, and work included. If a term cannot be mapped to an owner, an activity, and a measure, remove it until it can.

    References


  • How to Coordinate Teams for Reliable LLM Visibility

    How to Coordinate Teams for Reliable LLM Visibility

    You have been asked to improve how your brand appears in LLM answers. The request may have landed with SEO, but SEO cannot correct a product claim, approve brand language, earn independent coverage, or reconcile conflicting facts across every public surface.

    You do not need to wait for a reorganization. You need a shared definition of visibility, a reliable path for resolving contradictions, and a way for each team to act without losing sight of the same brand reality. This operating model will help you build that coordination.

    Diagnose the coordination problem before choosing tactics

    LLM visibility resembles a search problem, so the first response is often an SEO audit, a prompt-tracking dashboard, or a content plan. Those tools can reveal symptoms. They cannot settle which claims are true, which language is approved, who owns an outdated third-party description, or what another team is willing to change.

    The underlying mismatch is organizational: teams are usually managed by channel, while LLM visibility may depend on the strength and consistency of the brand’s broader digital footprint. Your website, documentation, profiles, media coverage, partner pages, community discussions, and public responses can all contribute to the environment in which the brand is understood. No channel owner controls that environment alone.

    Make a coordination diagnosis your first deliverable. Speak with the people who control the relevant facts and surfaces, then capture:

    • The outcome each team thinks it owns. Ask what success means to SEO, content, brand, product, PR, analytics, legal, support, and any other involved function.
    • The facts and public surfaces each team controls. Separate ownership of information from ownership of publication. Product may own the fact while content owns the page that expresses it.
    • The evidence each team trusts. Record the canonical product record, approved messaging, customer evidence, policy documentation, and other materials used to validate a claim.
    • The decisions that require another team. Note where work pauses for approval, clarification, technical implementation, external outreach, or risk review.
    • The contradictions already visible. Look for inconsistent names, categories, capabilities, relationships, limitations, and descriptions across public properties.

    Separate conversations are useful before a joint working session. People tend to describe their constraints more precisely before the discussion becomes a negotiation over priorities. You are not collecting complaints. You are locating the handoffs where accurate information becomes delayed, diluted, or inconsistent.

    Turn the diagnosis into a tension map

    A tension map names competing needs without treating either side as the problem. Typical examples include:

    • SEO needs a clear answer, while legal needs qualifications that prevent an overbroad claim.
    • Brand wants one stable category description, while product is still refining its market position.
    • PR needs a timely narrative, while subject-matter owners need more time to validate the supporting evidence.
    • Analytics wants a stable measurement set, while channel teams need room to test different questions and formats.
    • Content needs an approved fact, while no function has accepted responsibility for maintaining it.

    Do not force every tension into an immediate action plan. Mark the missing owner, disputed fact, approval dependency, and unresolved tradeoff. The first objective is a shared account of how the organization actually works. A polished roadmap built on conflicting assumptions will only distribute the conflict into more tasks.

    Create a visibility contract that every team can use

    Six colleagues assemble colored interlocking components into one translucent shared structure in a bright workspace.

    Teams cannot coordinate around a phrase that means something different to each of them. SEO may interpret LLM visibility as mentions for a monitored prompt set. PR may see it as authority and third-party recognition. Brand may care about how the company is described. Product may care most about factual accuracy. All are relevant, but none is a complete operating definition.

    Use a working definition such as this: LLM visibility is the accuracy, consistency, relevance, and discoverability of the organization’s representation in model-mediated answers that matter to its audiences.

    This definition prevents three common mistakes. Visibility is not reduced to a mention count. It is not treated as a website-only outcome. It is not framed as a result that one team can guarantee. The organization instead coordinates the public facts, evidence, and explanations it can responsibly improve.

    Put the agreement into a short shared brief

    The brief should be compact enough to use during real decisions. Include:

    • Priority audience situations. Describe what the person is trying to learn, compare, verify, or decide. A business situation is more durable than a disconnected list of prompt variations.
    • Entity truth. Record official names, products, relationships, categories, locations, audiences, and other facts that must remain consistent.
    • Desired representation. State what a useful, accurate answer should help the audience understand. Do not turn this into promotional copy.
    • Claim rules. Identify which claims are approved, what evidence supports them, what qualifications must travel with them, and who can approve a change.
    • Relevant surfaces. List the owned and external places where the information appears or should appear. Assign responsibility for each surface without pretending that external publishers are controllable.
    • Decision rights. Name who validates facts, approves language, chooses technical implementation, authorizes outreach, evaluates risk, and settles cross-team disputes.
    • Measurement boundaries. Specify what the team can observe, what it can influence, and what it cannot confidently attribute.

    If the group cannot agree on the brief, that disagreement is the work. Buying another tool or publishing more pages will not resolve it.

    Maintain a claim registry, not just a keyword list

    Keywords and prompts reveal demand. Claims are the units that teams must validate and keep consistent. Create a registry for the facts and propositions most likely to shape how the brand is understood. For each claim, record:

    • The canonical fact or approved wording.
    • The evidence that supports it.
    • The business owner responsible for its accuracy.
    • Required limitations, conditions, or risk language.
    • The pages, profiles, documents, and other surfaces where it appears.
    • Its current approval state and the point at which it should be reviewed again.

    Suppose a product name or capability changes. The registry lets product update the canonical fact, legal review the permitted wording, content revise the explanation, SEO update relevant pages and structured data, PR adjust future outreach, and profile owners correct managed listings. Without that record, each channel learns about the change at a different time and preserves a different version of the brand.

    Treat JSON-LD as an expression of supported, visible information, not as a place to manufacture certainty. If the page, structured data, product documentation, and public messaging disagree, adding more schema does not solve the governance failure. Confirm the fact first; then align its machine-readable and human-readable forms.

    Build a decision workflow around visibility issues

    A conflicting two-color signal moves through staffed decision stations and emerges as synchronized light paths leading to several public channels.

    Once teams share a definition and a claim registry, coordination can become concrete. Organize the work around visibility issues rather than channel campaigns. That allows you to change cross-functional working habits without waiting for reporting lines to change.

    1. Capture the audience situation. Save the exact question or decision context, the observed answer, the interface or model used, and any citations or referenced properties.
    2. Classify the gap. Decide whether the issue is absence, factual error, ambiguity, stale information, weak evidence, inconsistent terminology, or an answer that is technically correct but unhelpful.
    3. Confirm the canonical truth. Route the underlying fact to its business owner before anyone rewrites content or markup.
    4. Select interventions by surface. Determine whether the response belongs on an existing page, in documentation, in structured data, on a managed profile, in public communications, through external outreach, or across several of these places.
    5. Sequence dependent work. An approved fact may need to precede copy, schema, outreach, and profile corrections. Record those dependencies so teams do not publish incompatible versions.
    6. Validate and retain the result. Check whether the intended properties changed, record what remains unresolved, and preserve the decision for the next person who encounters the issue.

    An absence is not automatically a content gap. The brand may be described under an inconsistent name, its category may be ambiguous, the supporting claim may lack evidence, or external descriptions may conflict. Classification prevents the team from prescribing another page for every symptom.

    Use an issue brief that can travel between teams

    A useful issue brief contains the audience situation, the observed representation, the specific gap, the canonical correction, supporting evidence, affected surfaces, required approvers, accountable owner, intended success signal, and review point.

    This is different from sending legal a request to approve AI copy or asking PR to get more mentions. The brief gives every function the same problem statement and shows why its decision affects the complete representation. It also exposes unresolved truth before implementation work begins.

    Make the cross-team meeting a decision forum

    Status meetings reward reporting. Visibility coordination needs decisions. Circulate prepared issue briefs and use the shared session to answer questions such as:

    • What changed in the business that public information has not yet reflected?
    • Which brand facts or descriptions currently conflict?
    • Which claims are awaiting evidence, approval, or qualification?
    • Which managed surfaces need correction, and which external surfaces warrant outreach?
    • What did recent observations change about the team’s working hypothesis?
    • Which dispute needs escalation because no participating function owns the final decision?

    Keep responsibilities explicit:

    • SEO identifies discoverability and representation gaps, maps relevant owned pages, and recommends technical changes.
    • Content turns validated facts into clear explanations that answer real audience needs.
    • Product or subject-matter owners confirm capabilities, limitations, terminology, and relationships.
    • Brand protects coherent positioning and naming across surfaces.
    • PR and communications connect defensible claims with relevant external conversations and publications.
    • Legal or compliance defines the boundaries within which a claim may be used.
    • Analytics maintains observation methods, definitions, and reporting caveats.
    • An accountable sponsor settles tradeoffs that functional owners cannot resolve between themselves.

    Responsibility does not mean that a function executes every related task. Product can own the truth of a capability without editing the website. SEO can own discovery of a visibility issue without owning the claim. The distinction prevents work from being assigned to the most interested team instead of the team with authority to decide.

    Translate every request into the receiving team’s stakes. Brand needs to know which inconsistency is confusing the market. Legal needs the exact claim, evidence, context, and proposed qualification. Product needs to see where an outdated fact is still public. PR needs a defensible idea, not a demand for links. Internal communication becomes useful when it lets people protect their own responsibilities while contributing to the shared outcome.

    Measure representation and workflow without false certainty

    Measurement can damage coordination when a single visibility score is presented as ground truth. It encourages teams to optimize the number while disagreements about accuracy, evidence, and audience value remain hidden.

    Use a scorecard with several distinct views:

    • Information health. Track whether priority claims have owners and evidence, whether important pages and profiles agree, whether structured data reflects visible facts, and whether stale public descriptions have been identified.
    • Representation quality. Evaluate whether observed answers identify the correct entity, describe it accurately, use consistent terminology, include material qualifications, and help with the intended audience decision.
    • Workflow health. Monitor unresolved contradictions, facts awaiting validation, decisions awaiting approval, recurring rework, and issues with no accountable owner.
    • Business signals. Where data is available, examine qualified referral activity, branded demand, assisted conversion evidence, and recurring questions reported by sales or support. Keep these separate from claims of direct LLM attribution.

    Preserve the context behind every captured answer: the exact prompt, model or product, interface, date, relevant location or personalization state when known, full response, visible citations, and the reason your evaluator marked it accurate or problematic. Treat that answer as an observation, not a universal ranking position.

    Maintain a stable set of audience situations for directional monitoring, while allowing new questions to enter when the market or product changes. Stability helps you compare observations. Flexibility prevents the measurement set from becoming a museum of old priorities.

    If you use a composite AI visibility score, require a transparent methodology. The team should know what is being counted, how quality is judged, what can vary between observations, and which decisions the score is fit to support. A score that cannot answer those questions belongs in exploration, not executive certainty.

    Treat resistance as operational information

    Cross-team work changes who must approve, explain, maintain, and answer for public information. Resistance may therefore point to a real cost: additional review work, a threatened channel KPI, unclear credit, loss of autonomy, unsupported claims, or responsibility without decision authority.

    When someone pushes back, ask what risk the proposed change transfers to that function. Then document the constraint, the agreed compromise, and the owner of the remaining risk. Separate reversible experiments from lasting policy changes so a small test does not quietly become an unlimited commitment.

    Keep a decision log next to the claim registry. Record what was decided, why, who approved it, which surfaces are affected, and what would cause the decision to be revisited. This prevents every new visibility issue from reopening the same internal argument.

    Key takeaways

    • LLM visibility is a shared brand-representation problem, even when SEO is asked to lead it.
    • Diagnose conflicting assumptions, facts, incentives, and decision rights before building a tactical roadmap.
    • Coordinate around validated claims and audience situations rather than treating prompts, keywords, or channels as the whole problem.
    • Use issue briefs, a claim registry, and a decision log to make cross-team handoffs explicit and reusable.
    • Measure information health, representation quality, workflow health, and business signals separately instead of hiding them inside one score.

    Start with a concrete contradiction your teams already recognize. Confirm the canonical truth, identify every affected surface, assign the decisions to the people who have authority, and record the result. That gives you a complete coordination loop you can improve without waiting for a new org chart or perfect visibility data.

    References