Tag: AI Strategy

  • AI Visibility Platform or Specialist Agency: How to Choose

    AI Visibility Platform or Specialist Agency: How to Choose

    You know your brand is missing, misrepresented, or rarely recommended in AI answers. The difficult decision is what to buy next: software that shows you the problem, an agency that works on it, or both.

    Choose based on the work your team can own after the first audit. A visibility platform is primarily an instrument. A specialist agency is primarily an operating team. If you buy one while expecting the other, you can collect months of reports without changing what an AI system retrieves, believes, recommends, or lets a user do next.

    Key takeaways

    • Choose a platform when your main gap is measurement and your team can turn findings into content, technical, PR, and product changes.
    • Choose a specialist agency when the diagnosis is reasonably clear but you lack the expertise, coordination, or production capacity to act on it.
    • Use a hybrid when visibility is strategically important enough to require independent measurement and sustained execution.
    • Measure retrieval, recommendation, factual accuracy, citations, suitability, and action readiness separately. A single visibility score hides too much.
    • Evaluate agencies using client outcomes in your market, not the agency’s own AI presence or a newly adopted service label.

    Buy the kind of help your bottleneck requires

    The decision becomes easier when you replace the vague goal of “improving AI visibility” with a concrete bottleneck. Are you unable to observe relevant answers? Do you understand the answers but lack the people to change them? Or do several teams need a shared measurement system and an external execution partner?

    OptionWhat you are buyingBest fitCommon gap
    AI visibility platformRepeatable monitoring, prompt tracking, citations, competitor observations, and reportingYou have content, SEO, PR, analytics, and technical owners who can act on findingsThe platform identifies a weak result but does not make the organizational changes required to improve it
    Specialist agencyDiagnosis, strategy, production, coordination, and specialist judgmentYou need execution capacity or expertise across several disciplinesYou depend on the agency’s sampling, interpretation, and reporting unless you retain access to the underlying data
    Hybrid modelAn internal measurement layer plus external executionAI discovery affects meaningful demand and you need both continuity and delivery capacityOverlapping responsibilities can produce duplicate reports and unclear accountability

    A platform is the cleaner choice when your team already knows how to update comparison pages, strengthen entity information, earn credible coverage, correct unsupported claims, improve structured data, and coordinate changes with product or engineering. The tool should tell those owners where to look and whether the result is moving.

    An agency is the better choice when those tasks have no durable owner. That often happens when SEO manages rankings, PR manages external authority, product controls integrations, legal reviews claims, and nobody owns the complete AI answer. The agency’s value should be its ability to connect those functions and deliver approved changes, not merely produce another dashboard.

    The hybrid model works when you want measurement continuity even if you change agencies. Your company owns the prompt set, raw observations, definitions, and historical benchmark. The agency receives access, proposes interventions, executes an agreed scope, and reports against the same measurement system. This keeps the agency from becoming the only party that can interpret whether its work succeeded.

    Feature breadth deserves proof before you commit. A product can look complete in a demonstration and still thin out when your workflow requires deeper analysis. Test the exact workflow you need, including exports, answer snapshots, citations, segmentation, collaboration, and follow-through. A long feature list is not a substitute for completing one real investigation from prompt to corrective action.

    Map visibility across retrieval, evaluation, and action
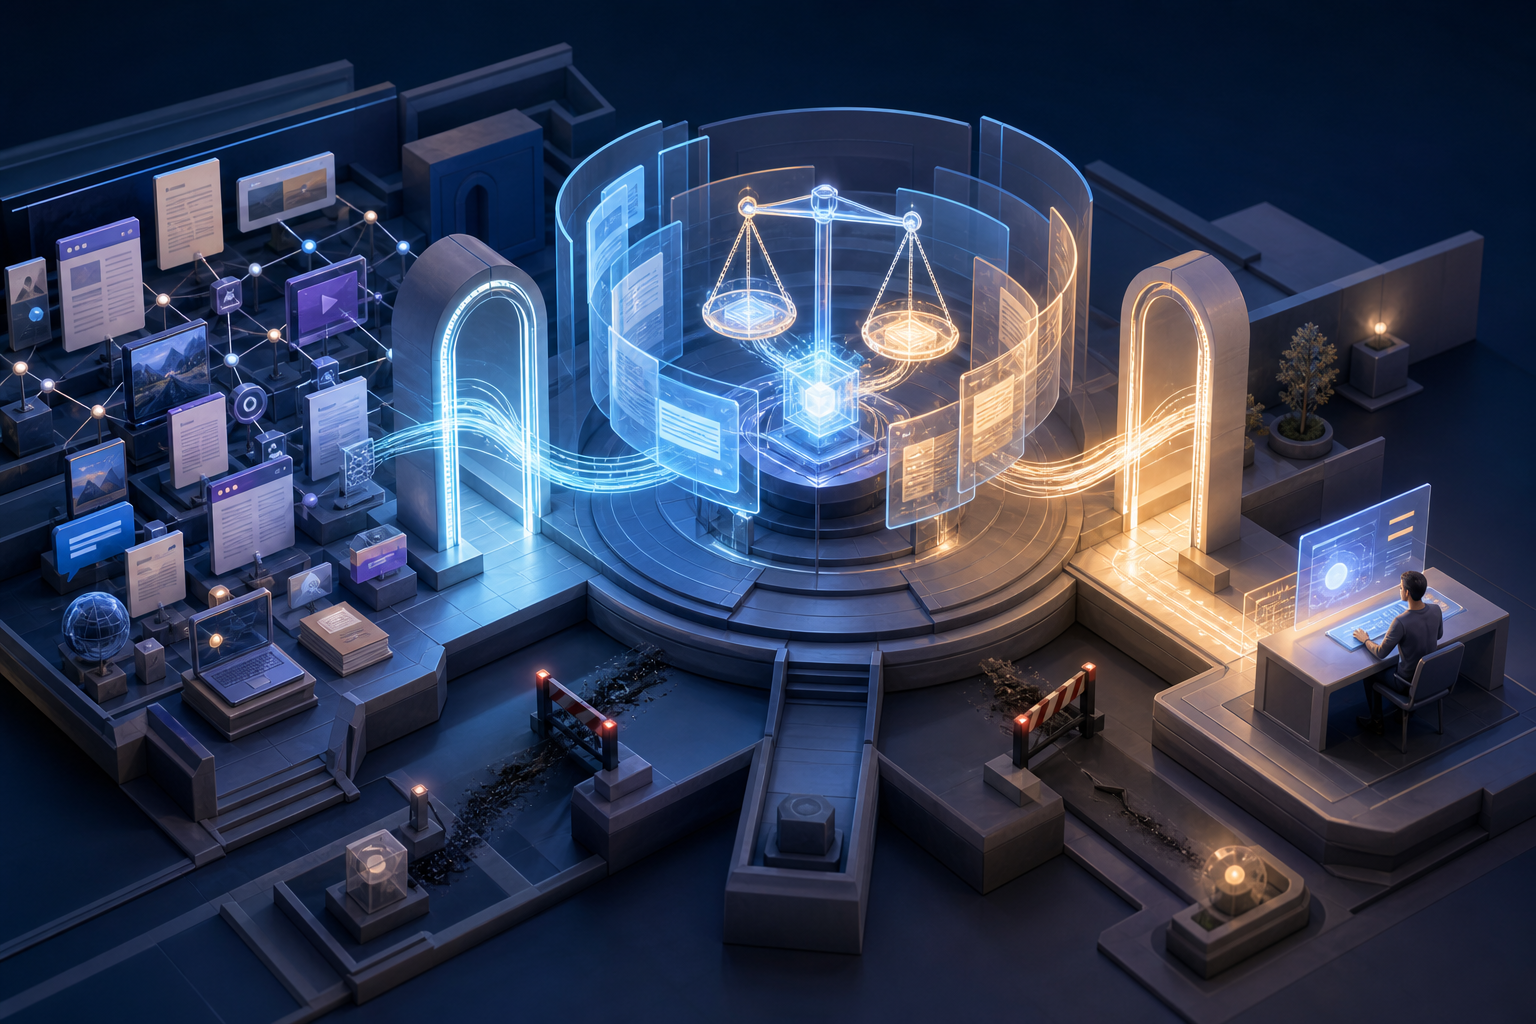
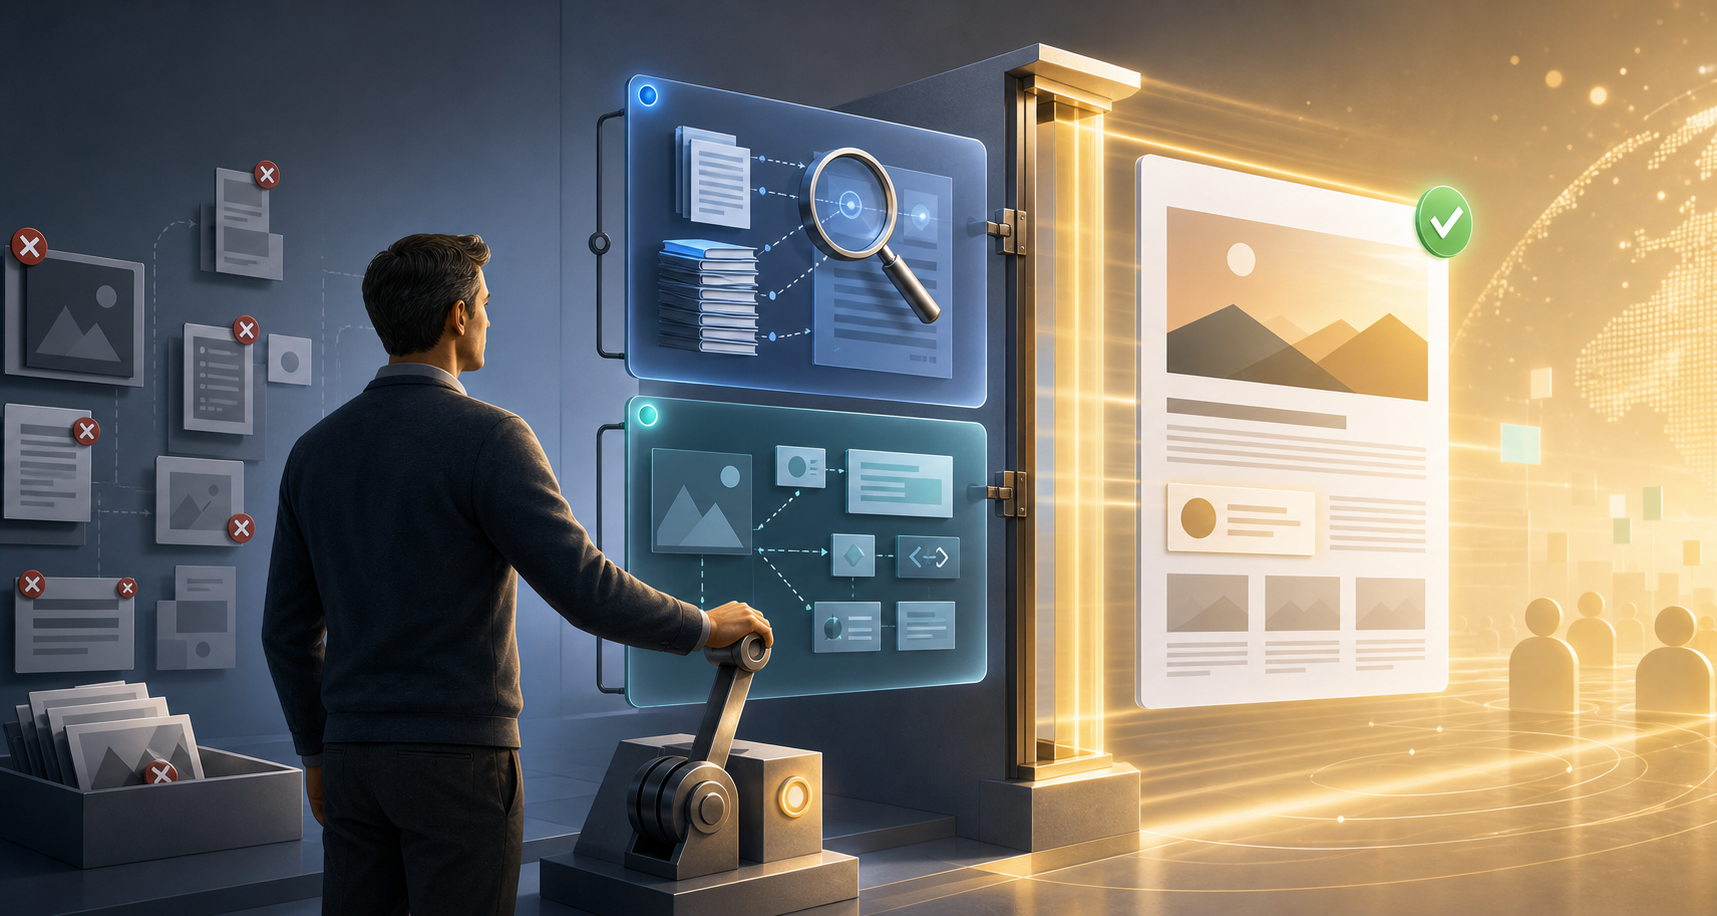
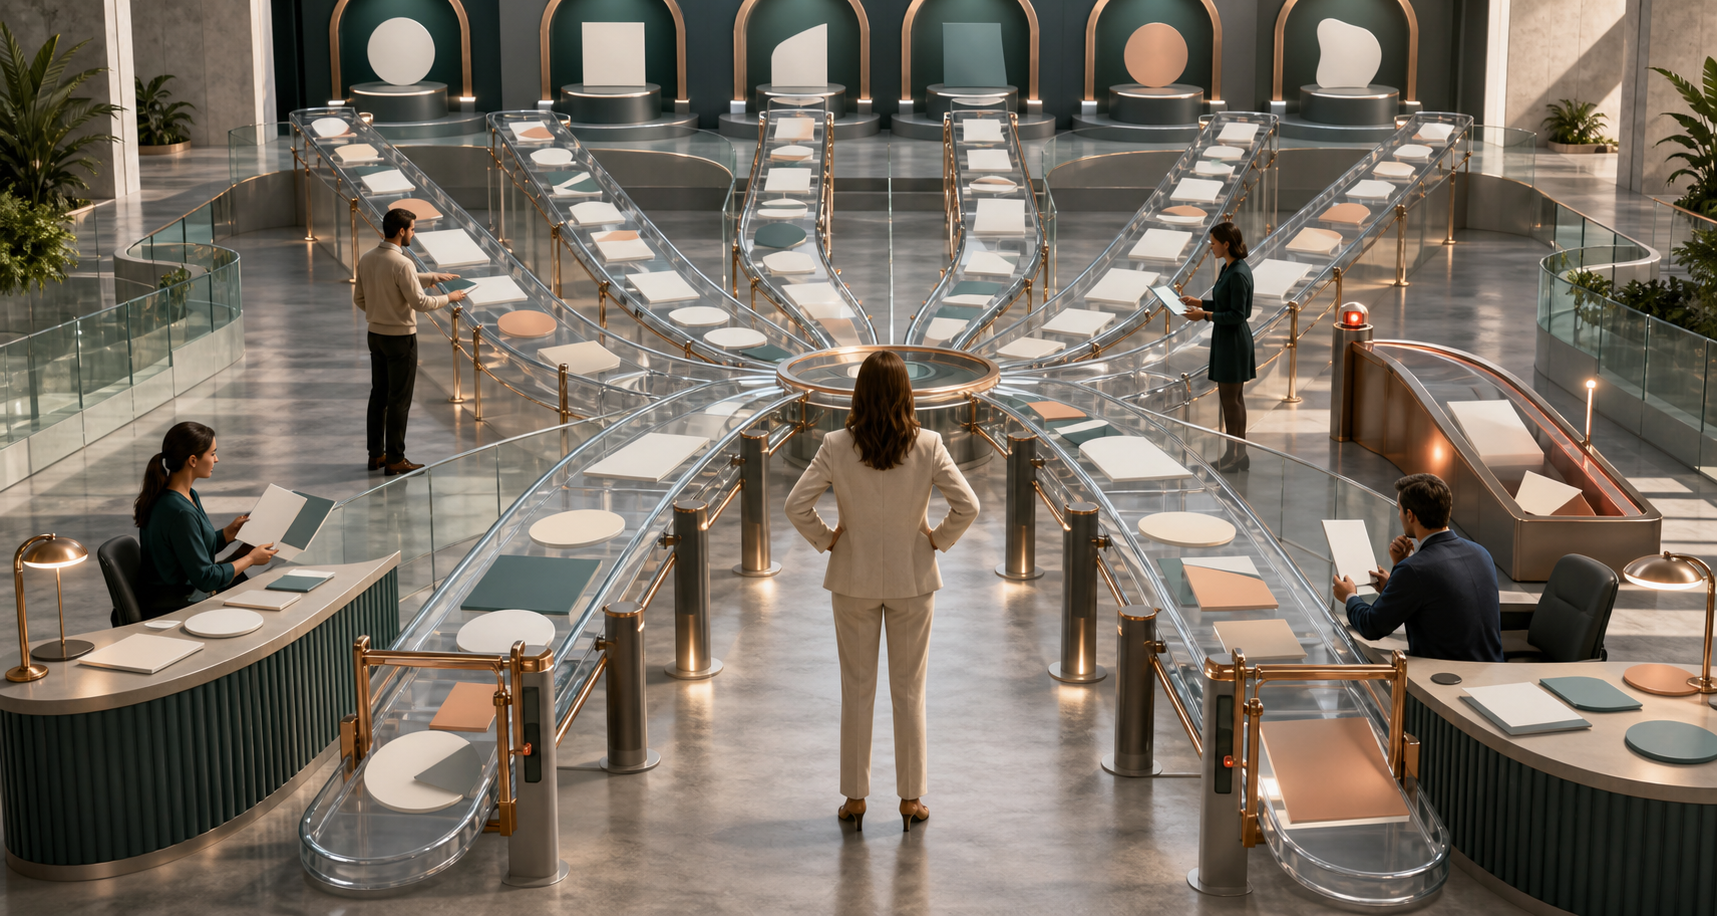
    An isometric scene shows source materials passing through a retrieval gateway and an AI evaluation chamber before reaching a user action terminal.

    Brand mentions are only the first layer. Agentic search can move from finding possible vendors to assessing fit and, where a product’s API supports it, completing an action or transaction. A useful operating model therefore separates retrieval, evaluation, and action.

    1. Retrieval: Can the system find and understand your brand for an eligible request? Relevant evidence can include authoritative pages, comparison content, metrics, clear entity statements, credible mentions, and citations.
    2. Evaluation: Does the answer connect your product to the right buyer, requirement, constraint, industry, or use case? Being listed is not enough if the system presents you as unsuitable for the work you actually want.
    3. Action: Can the user or agent complete a sensible next step? Depending on the task, that may mean reaching a suitable product page, requesting a demonstration, checking availability, using an integration, or invoking a supported API.

    This model prevents a common purchasing mistake. If you only need retrieval monitoring, a platform may be sufficient. If the problem is evaluation, you may need positioning, proof, comparison assets, and third-party authority. If the problem is action, marketing alone may not fix it; product, engineering, sales operations, or commerce owners may need to change the handoff.

    Build your benchmark from actual buyer situations, not a list of short keywords. Each test case should record the buyer role, task, constraints, decision stage, target market, exact prompt, platform, visible model label, date, and answer. Sample the systems that matter to your audience; cross-platform evaluations commonly include ChatGPT, Perplexity, Claude, and Google Gemini.

    Use separate working metrics so a favorable average cannot conceal a material failure:

    • Mention coverage: the share of eligible prompts in which the brand appears at all.
    • Recommendation rate: the share of eligible prompts in which the brand is presented as a viable choice, not merely mentioned.
    • Suitability: whether the stated use cases, buyer types, constraints, and differentiators match your approved positioning.
    • Belief accuracy: the share of audited factual claims that are correct. Record serious errors individually; an average can disguise a harmful claim.
    • Citation traceability: whether important claims have visible, inspectable support and which domains provide it.
    • Action readiness: whether each relevant task has a working, appropriate next step rather than a dead end or generic homepage.

    Keep the prompt set and test conditions stable when comparing periods. AI answers can vary, so one favorable response is not proof of improvement. Preserve the raw answer alongside every score. Without the answer snapshot, your team cannot distinguish a genuine positioning change from a scoring inconsistency.

    Evaluate platforms and agencies with different evidence

    Software and services fail in different ways, so they should not share one generic procurement checklist. A platform needs trustworthy observation and usable data. An agency needs diagnostic judgment, execution depth, and evidence that it can operate in your buying environment.

    Questions to put to a visibility platform

    • What is captured? Ask whether the system stores the complete answer, citations, model or platform label, timestamp, prompt, and relevant test settings. A score without its underlying answer is difficult to audit.
    • Can we control the prompt set? You should be able to separate branded discovery, category research, comparisons, objections, regulated questions, and action-oriented requests.
    • How is volatility handled? Ask how repeated observations are represented and whether the interface distinguishes a durable pattern from a one-off answer.
    • Can we inspect the scoring rules? The platform should define what counts as a mention, citation, recommendation, favorable position, and competitor appearance.
    • Can we export raw and historical data? Confirm this before signing. Screenshots and summary PDFs are not enough if you later need independent analysis or a different service partner.
    • Does it lead to a corrective workflow? Test whether a user can move from a problematic answer to its likely evidence, affected page or source, assigned owner, and verification step.
    • Does access fit the operating team? Check permissions and collaboration for content, PR, analytics, product, legal, and agency users rather than assuming one SEO login will serve everyone.

    Ask the vendor to run your own prompts during the evaluation. Include one missing-brand case, one inaccurate-description case, one competitor comparison, one buyer with strict constraints, and one action-oriented request. Then export the evidence and assign a corrective task. That short exercise exposes more than a polished dashboard tour.

    Questions to put to a specialist agency

    • How do you establish the baseline? Require the prompt set, eligible-prompt rules, raw answers, scoring definitions, platforms covered, and testing method.
    • Which client outcomes can we inspect? Look for prompt-level before-and-after evidence, changes in citations or belief accuracy, and a clear account of what the agency changed. The agency’s own visibility is not a client result.
    • Who performs each part of the work? Identify the people responsible for strategy, technical review, content, digital PR, structured data, analytics, and project management. Confirm which work is subcontracted.
    • How does the plan address all three stages? Retrieval may require discoverable evidence; evaluation may require suitability and comparison assets; action may require product pages, feeds, integrations, or APIs. Ask what is in scope and what remains yours.
    • How will incorrect AI beliefs be handled? The response should identify the unsupported claim, its likely evidence environment, the approved correction, publication or authority work, and the method for retesting.
    • How is commercial relevance measured? Visibility should be segmented by buyer, use case, and decision stage, then connected where possible to qualified demand, referrals, assisted conversions, or pipeline. Raw mention volume can rise while business relevance falls.
    • What will we own at the end? Put ownership of prompts, measurements, content, schema, digital assets, account access, and reporting history in the agreement.

    Review scores, famous client logos, media references, leadership experience, and years in business can all help with initial screening. None proves that the team assigned to you can improve your visibility. Treat an agency’s founding year as evidence of operating history and adjacent SEO or GEO experience, not proof of long experience in agentic search; the agentic specialty is newer than many firms offering it.

    Raise the bar in regulated or technical markets

    Vertical experience matters most when a plausible-sounding error can create compliance, safety, procurement, or reputational exposure. Medical-device work, for example, has to respect regulatory clearances, clinical evidence, credentialing signals, technical terminology, and the limits of approved claims. Generic product copy is a poor test of whether a partner can manage that environment; regulated GEO programs require subject-matter and compliance-aware execution.

    Give a prospective agency a realistic claim-governance exercise. Provide an approved product statement, an unapproved overstatement, and an AI answer that confuses the two. Ask who decides the correction, what evidence may be published, where legal or regulatory review enters, and how the team will verify the changed answer. A partner that jumps straight to content production without defining approval authority is not ready for high-consequence work.

    Run a proof of workflow before committing to scale
    A small team tests a connected evidence, AI response, and user action workflow at a brightly lit pilot table while additional workstations remain inactive behind them.

    A useful pilot should prove a complete operating loop, not manufacture a temporary lift in a presentation. Use a bounded set of commercially relevant prompts and require the platform or agency to move from observation to an assigned intervention and then back to verification.

    1. Define the decision. Write down whether you are choosing software, execution capacity, or a hybrid. Name the internal teams expected to use the result.
    2. Select eligible prompts. Cover distinct buyers, use cases, constraints, comparison questions, objections, and next-step requests. Exclude prompts for which your brand would not reasonably be a fit.
    3. Freeze the baseline. Store every exact prompt, answer, citation, date, platform, model label, and scoring decision. Record factual errors separately from unfavorable opinions.
    4. Classify each failure. Mark it as retrieval, evaluation, or action. Then assign an owner: content, technical SEO, PR, product, engineering, sales operations, legal, or another accountable function.
    5. Choose a small intervention set. Examples include correcting an entity statement, strengthening a comparison page, publishing suitability evidence, resolving contradictory claims, improving structured data, earning relevant third-party coverage, or repairing an action pathway.
    6. Retest the same cases. Preserve new answer snapshots and compare them with the baseline. Do not substitute easier prompts after work begins.
    7. Review operational friction. Note whether the data was exportable, scoring was explainable, approvals were manageable, owners received usable tasks, and the intervention could be traced to a result.

    Set the commercial terms around that loop. A platform agreement should identify data access, export rights, prompt limits, model coverage, historical retention, user permissions, and support. An agency scope should identify deliverables, approval dependencies, responsible specialists, reporting inputs, asset ownership, out-of-scope technical work, and the evidence required before a result is called successful.

    For a hybrid engagement, make the division explicit. Your platform remains the shared measurement record. The agency owns named interventions and documents what changed. Your internal owners approve claims, release technical or product updates, and connect visibility data to commercial outcomes. One party should still own the overall program; shared access is not shared accountability.

    Start with the bottleneck you can name today. If you cannot reliably see the problem, prove the measurement workflow. If you can see it but cannot ship corrections, test an agency on one complete intervention. Scale only when the same system can show what changed, who changed it, and whether the answer became more accurate and useful for the buyer you intended to reach.

    References


  • Human-Led AI for SEO: A Workflow That Protects Quality

    Human-Led AI for SEO: A Workflow That Protects Quality

    AI can shorten research and analysis, but your real bottleneck is no longer producing text. It is producing a page with a defensible point of view, traceable facts, and a reason to exist beside every page already competing for attention.

    You do not need an AI-free SEO process. You need a clear line of accountability: machines compress inputs and expose patterns; people choose the search problem, supply the evidence, make the judgment, write the consequential passages, and approve what goes live.

    Put AI upstream of authorship

    AI can compress SEO tasks that took hours into minutes. That makes it useful for clustering keywords, mapping themes to URLs, finding patterns in exports, organizing supplied material, and generating options for a strategist to evaluate.

    The boundary is simple. AI may reduce the amount of information you have to inspect, but it should not decide what is true, what your audience needs, what your evidence means, or what your brand is prepared to claim. When the model moves from organizing the work to supplying the substance, efficiency starts consuming the quality it was supposed to create.

    Workflow stageUseful AI roleHuman responsibilityRequired output
    Opportunity analysisCluster exports, connect related queries, and flag changesDecide which problems matter to the audience and the businessA prioritized page list with a reason for each choice
    Content briefingOrganize questions, entities, subtopics, and supplied factsChoose the intent, answer, evidence, angle, and exclusionsA human-owned brief rather than an unverified generated outline
    DraftingOffer structures, counterarguments, examples to investigate, and constrained rewritesWrite the answer, interpretation, firsthand material, and tradeoffsA draft whose consequential claims have identifiable provenance
    Quality controlFlag repetition, inconsistency, ambiguity, and possible unsupported claimsVerify every claim and decide whether the page deserves publicationA factual, useful page with a named human approver
    MeasurementGroup page and query data so changes are easier to inspectInterpret the movement and choose the next actionA documented decision to keep, repair, reframe, consolidate, or retire the page

    Do not confuse human-edited content with human-led content. Changing headings, fixing grammar, and removing awkward transitions may improve presentation, but it does not add experience, evidence, or an original conclusion. If a model chose the premise, assembled the claims, and wrote the argument, a cosmetic edit leaves the model in charge of authorship.

    A small first-party comparison illustrates the risk without proving a universal rule. In that set, three purely AI-written pages launched in April 2025 had nearly disappeared from search results by January 2026. After five AI-drafted, human-edited pages were rewritten by hand, they subsequently recorded 12% more clicks and 27% more impressions year over year during the reported three-month window. Those figures come from a limited set of pages, so they are a warning signal rather than a performance promise. The useful conclusion is narrower: surface editing is not a substitute for original authorship.

    The strategic risk is not the mere presence of AI. It is scaled production that adds little beyond what is already available. Search visibility becomes harder to defend when every page repeats the same consensus in the same vocabulary. Your workflow therefore needs to optimize for information gain and usefulness before it optimizes for publishing volume.

    Build an evidence packet before you ask for content

    Hands assemble documents, reference cards, an audio recorder, and fact markers into an organized evidence packet on a table.

    A keyword export is an opportunity map, not an evidence base. It can tell you which language people use and which URLs are changing, but it cannot supply the expertise that makes your answer worth trusting. Before an LLM sees a writing task, create a compact evidence packet that a human owns.

    1. Define the reader’s decision. Finish this sentence: “After reading, the reader should be able to…” If you cannot name the decision or action, the page is not ready for a brief.
    2. Write the answer in rough human language. State the recommendation, the important qualification, and what common advice misses. This can be messy. Its purpose is to establish the point of view before generated language begins influencing it.
    3. Collect admissible evidence. Include relevant internal notes, documented procedures, approved customer material, product records, first-party data, and external references you are permitted to use. Label firsthand material as such and identify who can verify it.
    4. Create a claim ledger. For each consequential claim, record the supporting artifact or URL, any limitation, the person responsible for verification, and whether the claim is safe to publish. A blank evidence field is a research task, not an invitation for the model to complete the sentence.
    5. Name the page’s original contribution. It might be a firsthand process, an analysis of your own data, a decision framework grounded in expertise, a documented failure mode, or a clearer answer to a question others leave unresolved. If you cannot point to the contribution, do more work before drafting.

    Only then should you hand the organizational work to AI. One practical workflow used Gemini to group more than 2,000 declining Page 1 keywords from Ahrefs into topical clusters. After Google Search Console data was added, the themes were mapped to the URLs losing visibility. That is a good division of labor: the machine narrows a large field; the strategist inspects the affected pages, determines why they matter, and decides what deserves to change.

    Give the model a task contract instead of a vague request to “create an SEO brief.” A useful contract contains these boundaries:

    • Input boundary: use only the attached exports, notes, and approved references.
    • Analytical task: cluster related items, identify duplicates, map clusters to existing URLs, or surface conflicts.
    • Non-authority rule: do not decide which interpretation is correct and do not convert an unsupported idea into a fact.
    • Traceability rule: preserve the row, URL, note, or artifact behind every finding.
    • Uncertainty rule: place missing, ambiguous, or contradictory information in a separate review queue.
    • Output rule: return a structured table or list that a strategist can inspect; do not write publication-ready copy unless a later, bounded task requires it.

    This contract changes the model’s job from “sound knowledgeable” to “make the human’s review faster.” That is the kind of leverage an SEO team can safely repeat.

    Draft from human judgment, then use AI as a critic

    The most consequential writing should begin with a person, even when the starting material is a rough collection of notes. The direct answer, interpretation of evidence, firsthand example, meaningful qualification, and final recommendation carry the page’s real value. Those are precisely the passages you should not outsource to a probability engine.

    1. Lock the thesis before generating prose. Record what you believe the reader should do, why, when that advice does not apply, and what evidence supports it.
    2. Turn each section into a promise. A section should help the reader make a decision, complete a task, or detect a problem. “Benefits of AI” is a topic; “Choose which SEO tasks AI may own” is a useful promise.
    3. Assign evidence before paragraphs. Put the relevant claim-ledger entries beneath the section that will use them. If a section has no evidence or expertise attached, remove it or return to research.
    4. Draft the high-judgment passages in human language. Preserve concrete terms, uncertainty, exceptions, and the reasoning that connects evidence to action.
    5. Give AI bounded revision jobs. Ask it to identify repetition, list unanswered objections, find contradictions, propose clearer ordering, check whether a conclusion follows from the supplied evidence, or create alternate wording for one difficult sentence.
    6. Perform the final edit against the evidence packet, not against the model’s fluency. A sentence that sounds polished but cannot be verified is still a defect.

    During that final edit, interrogate every paragraph:

    • What does this paragraph let the reader do, decide, or notice?
    • Which approved artifact supports its factual claims?
    • Could the paragraph appear unchanged on a competitor’s site? If so, what specific knowledge is missing?
    • Does it state a condition, mechanism, or consequence, or merely announce that something is important?
    • Has polished language hidden uncertainty that was present in the underlying evidence?
    • Would a subject-matter expert sign their name to the wording?

    Do not use a so-called humanizer as a substitute for this review. Passing generated copy through another machine may replace one recognizable writing pattern with another awkward pattern, but it does not create evidence, experience, or a better decision for the reader.

    A vocabulary check can still help. Habitual terms such as delve, tapestry, paramount, synergy, cutting-edge, and game-changing often accompany generic generated prose. Add unwanted terms to your prompt when they conflict with your house voice, then search for them during editing. Treat them as symptoms, not proof. A technically correct term should remain when it is the most precise language available.

    The stronger style instruction is behavioral: use concrete nouns and active verbs; name the actor, action, object, and condition; do not claim importance without showing the consequence; flag a missing example instead of inventing one. That improves usefulness without turning your editorial standard into a blacklist.

    Gate publication with evidence and extraction audits

    An editor inspects a floating web page against source documents and structural page elements before allowing it through a publication checkpoint.

    Human-led does not mean one person glances at the draft before publication. It means a human can explain why the page exists, where its claims came from, what AI did, and why the final answer is defensible. Use two separate gates so factual quality and search presentation do not blur into one subjective approval.

    Gate 1: evidence, accuracy, and originality

    • Every number, date, named event, comparison, and consequential factual claim resolves to an approved reference or internal artifact.
    • Firsthand language points to genuine firsthand material. The page does not imply a test, customer result, interview, or experience that never occurred.
    • Qualifications from the evidence survive into the copy. A limited observation has not become a universal rule.
    • The original contribution is visible in the draft, not merely recorded in the brief.
    • The conclusion follows from the evidence rather than from a confident generated transition.
    • A subject-matter owner has approved the technical meaning, while an editor has approved the communication.

    Classify the result as pass, repair, or block. Block publication when a material claim lacks provenance, the page implies experience you do not have, or no original contribution is present. Repair unclear structure and weak examples only after those blocking problems are resolved.

    Gate 2: search intent and answer extraction

    • The opening resolves the main question without making the reader cross several generic paragraphs first.
    • Each heading describes a decision, task, distinction, or failure mode rather than a broad topic label.
    • The core answer appears in a self-contained paragraph that remains accurate when read apart from the surrounding copy.
    • Names for products, organizations, concepts, and processes stay consistent throughout the page.
    • Citations sit beside the claims they support, allowing readers and retrieval systems to connect evidence with the statement.
    • Lists contain real steps or criteria rather than chopped-up prose.
    • Any JSON-LD or other structured data represents what the visible page actually says. Schema can clarify the content’s structure; it cannot supply expertise or originality missing from the page.

    This second gate supports SEO, AEO, and GEO without distorting the writing for machines. A clear answer, stable terminology, nearby evidence, and faithful structured data also reduce the reader’s effort. If an optimization makes the page harder for a person to understand, it has failed the more important test.

    Measure the page, not the amount of AI

    Record the page’s publication or revision date, target query cluster, intended reader action, original contribution, human owner, and the tasks assigned to AI. Without that record, a future reviewer cannot tell whether a result came from the strategy, the evidence, the execution, or an unrelated change.

    Use first-party Google Search Console and Google Analytics 4 data to inspect performance, but do not treat a before-and-after movement as automatic proof of causation. Review the relevant URL and query cluster, note changes in impressions and clicks, and connect those signals to the reader outcome that matters on your site. Sitewide totals can conceal a page-level gain or loss.

    When a page weakens, do not respond by generating more copy. Return to the evidence packet. Check whether the intended query changed, the answer became stale, a competing page now resolves the task more directly, or your original contribution was never clear. Then choose a specific action: repair the evidence, sharpen the answer, reframe the intent, consolidate overlap, or leave the page alone while more data accumulates.

    Key takeaways for a human-led SEO workflow

    • Use AI to compress, classify, map, challenge, and proofread. Keep truth, intent, interpretation, original contribution, and publication approval with people.
    • Require a human artifact before prompting: a rough answer, evidence packet, claim ledger, and explicit reason the page deserves to exist.
    • Make AI preserve provenance and expose uncertainty. Fluent output without traceable support should never enter a publishable draft as fact.
    • Judge human involvement by decision ownership, not by how many words an editor changed after generation.
    • Optimize answer structure and schema only after the page passes its evidence and originality gate.
    • Measure URL and query outcomes, document the workflow used, and diagnose weak pages before creating more content.

    Take one brief already in production and label every handoff as AI-owned, human-owned, or human-approved. If AI currently owns the thesis, factual support, interpretation, or final judgment, move that responsibility back to a named person before the page goes live. That single change gives you the speed of AI without allowing speed to become your editorial standard.

    References


  • How to Use Profound Aim Brainstorm Mode Productively

    How to Use Profound Aim Brainstorm Mode Productively

    You can have useful AI Search data and still face a blank next step. The data may expose several promising directions, but it cannot choose which uncertainty your team should resolve first.

    Brainstorm Mode within Profound Aim is designed for that handoff: it guides a broad goal toward scoped, ready-to-run Agents. The practical value is not producing more ideas. It is reducing the distance between an ambition and a task that can inform a real decision. To get that value, you need to give Brainstorm Mode strategic direction without prematurely prescribing the analysis.

    Use Brainstorm Mode to close a decision gap

    Brainstorm Mode is most useful when you know the outcome you want but do not yet know what an Agent should investigate. That is a decision gap: your team has a business objective and relevant data, but the next analytical question remains unclear.

    Good reasons to start in Brainstorm Mode include:

    • You can describe the business outcome, but several parts of the AI Search data could be relevant.
    • You have noticed a visibility pattern and need to decide which part deserves deeper investigation.
    • Different teams are proposing different explanations for the same result.
    • You need to turn a broad AI visibility priority into work that has a clear boundary.
    • You know someone can act on the answer, but you have not yet defined the question that would produce it.

    Brainstorming adds less value when the task is already precise. If you know the exact question, scope, evidence and required output, you may already have an Agent brief. Starting another ideation cycle can introduce ambiguity that was not there before.

    There is a simple readiness test: complete the sentence, “When this Agent finishes, we will decide whether to ______.” If you cannot fill the blank with a decision your team is prepared to make, the problem is not Agent scope yet. You still need alignment on the purpose of the work.

    Give Aim a broad goal without giving it an empty one

    A glowing sphere and several streams of abstract evidence pass through an open funnel and become three distinct research capsules.

    Broad and vague are not the same. A broad goal leaves room to discover the right investigation. A vague goal hides the decision, audience and boundary that make an investigation useful.

    “Improve our AI visibility” is vague. It does not say which part of the business matters, what kind of visibility problem is in scope or what anyone will do with the result. Brainstorm Mode may still be able to propose work, but you will have no strong basis for judging whether that work matters.

    A useful goal normally contains these ingredients:

    • Outcome: the change you want to support, such as choosing a content priority or understanding a visibility weakness.
    • Business scope: the brand, offering, product area or customer problem that matters.
    • Audience scope: the market, language, geography or buyer context that should govern relevance.
    • Decision: what the team expects to choose after seeing the evidence.
    • Evidence boundary: what the available AI Search data can reasonably help examine.
    • Constraint: what should remain outside the first investigation so the Agent does not become an entire strategy project.

    You can assemble those ingredients with this reusable structure:

    Help us decide [decision] for [brand, offering or audience] by using our AI Search data to investigate [uncertainty]. Keep the first Agent focused on [scope], and produce evidence we can use to [next action].

    Goal-framing template

    For example, replace “Improve our AI visibility” with: “Help us decide which content area should receive the next optimization effort. Use our AI Search data to investigate where visibility is weakest within the product area we plan to grow, and keep the first Agent focused on identifying and characterizing the gap rather than recommending a complete content strategy.”

    The improved version is still broad enough for Brainstorm Mode to shape the work. It also supplies a decision, a business boundary and a stopping point. That stopping point matters. Without it, one Agent can easily become responsible for finding a problem, explaining it, designing a strategy, writing content and evaluating results. Those are different jobs with different evidence requirements.

    Review every proposed Agent as a research brief

    “Ready to run” describes an operational state, not automatic strategic importance. Before running a proposed Agent, make sure its result could actually change what you do. A technically valid investigation can still be too broad, unanswerable from the available data or disconnected from the decision owner.

    Use this pre-run check:

    • One primary question: Can you express the Agent’s job as one question without joining several assignments with “and”?
    • Defined boundary: Does the brief identify the relevant brand, topic, audience or market while excluding unrelated areas?
    • Available evidence: Can the AI Search data support the requested analysis, or is the Agent being asked to infer facts the data does not contain?
    • Usable output: Will the result help someone choose, prioritize, approve, reject or investigate something specific?
    • Inference discipline: Does the brief distinguish observed patterns from possible explanations?
    • Named owner: Is there a person or team prepared to use the result?

    Break apart bundled Agents

    A bundled Agent might be asked to find every visibility gap, explain every cause, compare all relevant competitors, build a content strategy and produce implementation briefs. It sounds comprehensive, but each stage depends on choices made in the previous one. If the first interpretation is weak, every later deliverable inherits the problem.

    Start with the smallest question that can change the next action. An initial Agent might identify and characterize an in-scope visibility gap. A later Agent can investigate evidence-linked explanations for the selected gap. Content planning should begin only after you decide that the gap is important enough to address.

    This sequence also makes poor outputs easier to diagnose. You can tell whether the difficulty came from the goal, the data boundary, the interpretation or the proposed action instead of debugging one oversized deliverable.

    Separate observations from explanations

    AI Search data can reveal a pattern. A pattern does not, by itself, prove why that pattern exists. “The brand appears less often for this topic” is an observation. “The brand appears less often because of a particular content weakness” is an explanation that still needs support.

    If a proposed Agent asks why something is happening, require it to distinguish direct evidence from inference. The useful output is not an unsupported diagnosis stated confidently. It is a set of plausible explanations connected to the available evidence, with the remaining uncertainty made visible. That gives your team something it can test instead of a conclusion it can only accept or reject.

    Turn the first Agent into a controlled decision loop

    A research capsule moves around a circular track with four abstract review stations while a person oversees the final branching gate.

    The fastest way to create a pile of unused analysis is to run every plausible Agent at once. The outputs arrive without an order of operations, overlap in scope and often answer questions that no longer matter after the first decision.

    Use Brainstorm Mode as the beginning of a controlled sequence:

    1. Write the decision sentence: “When this Agent finishes, we will decide whether to ______.”
    2. Frame the broad goal around that decision and the relevant AI Search data.
    3. Use Brainstorm Mode to translate the goal into a proposed Agent or set of Agents.
    4. Apply the pre-run check and select the smallest Agent whose result could change the decision.
    5. Run that Agent before commissioning downstream analysis.
    6. Record the finding, the interpretation and the decision as separate items.
    7. Create another Agent only when the decision exposes a new uncertainty that must be resolved.

    A working note for each completed Agent can remain short:

    • Finding: What is directly supported by the output and underlying data?
    • Interpretation: What might the finding mean, and which part remains an inference?
    • Decision: What will the team do, defer or reject because of the finding?
    • Owner: Who is responsible for the next action?
    • Validation: What later AI Search signal would help determine whether the action had the intended effect?

    Consider a team deciding which product area deserves its next content investment. The first Agent could identify which in-scope topic area shows the most decision-relevant visibility weakness in the available data. The team then selects a topic based on business importance, not merely the size of the gap. A second Agent, if needed, can examine answer patterns for that topic and organize evidence-linked hypotheses. Only then does the team choose a content intervention and define how it will evaluate the result.

    That order preserves human judgment at the points where data cannot make the business choice. Brainstorm Mode helps structure the investigation; it does not remove the need to decide which market, audience, risk and opportunity matter.

    Key takeaways

    • Use Brainstorm Mode when you have a meaningful AI Search goal but have not yet converted it into an answerable investigation.
    • Frame the goal around a decision, business boundary, audience and evidence source instead of asking generally for better visibility.
    • Reject proposed Agents that combine discovery, diagnosis, strategy, production and measurement in one assignment.
    • Make every Agent distinguish data-backed observations from explanations that remain hypotheses.
    • Run the smallest useful Agent first, make a decision and generate follow-up work only when a new uncertainty appears.

    Before you open Brainstorm Mode, write one sentence: “When the first Agent finishes, we will decide whether to ______.” Use that decision to frame the goal you bring into Aim. If the blank is still empty, pause the Agent design and settle the business question first.

    References

  • How to Evaluate AI Marketing Tools Before You Commit

    How to Evaluate AI Marketing Tools Before You Commit

    An AI marketing tool can look persuasive in a demonstration and still fail in day-to-day use. A sound evaluation therefore has to connect the product to a defined business problem, credible evidence, acceptable data practices and the team’s actual capacity to adopt it.

    The most useful approach is a staged decision process. Each stage should eliminate a different kind of risk before price or novelty turns an interesting product into an expensive commitment.

    Turn the business need into a testable decision

    Evaluation should begin with the marketing problem rather than the product’s feature list. The source article recommends asking vendors to explain the challenge their tool addresses and how solving it affects a business outcome. If that connection remains vague, a sophisticated set of AI capabilities does not establish that the product is useful.

    Before meeting a vendor, the buying team can create a short decision brief describing the current workflow, its most important constraint, the people affected and the result that should improve. That result might concern output, troubleshooting or another outcome already important to the organization. The purpose is not to manufacture a justification for buying software; it is to establish a baseline against which the tool can be judged.

    Claims about saving time require an additional question: what will the organization do with the recovered capacity? The source cautions that time savings are not automatically valuable. They become meaningful when the team can redirect that time toward work that advances an existing objective.

    This framing also exposes unnecessary purchases. If the problem can be resolved through a process change, better use of an existing platform or clearer ownership, adding another tool may increase complexity without addressing the underlying constraint.

    Match the evidence standard to the vendor’s maturity

    A glowing software module passes through a sequence of visual testing gates in a modern evaluation lab.

    A relevant case study is more informative than a broad success claim. According to the source, buyers should look for evidence involving organizations with a comparable size, market, vertical or use case, along with concrete results. The closer the operating conditions are to the buyer’s own environment, the easier it is to determine whether the evidence transfers.

    Evidence should also extend beyond customer logos. A credible vendor needs sufficient domain understanding to explain how marketers perform the work, where the recurring friction occurs and why the product was designed in its present form. The source notes that deep subject expertise does not have to reside with every salesperson, but a serious prospective customer should be able to reach someone who has it.

    Vendor maturity changes the appropriate test. An established provider can reasonably be expected to show repeatable results from relevant customers. An early-stage provider may not have that record, so transparency becomes part of the evidence: the vendor should identify where the product is unproven, explain what has been observed in other settings and define what the early partnership would require.

    Being an early adopter can offer an advantage, but the source also identifies added exposure to bugs, feedback demands and uncertain performance. Contract flexibility should reflect that imbalance. A newer vendor that expects the customer to absorb experimentation risk while offering no corresponding flexibility presents a weak partnership proposition.

    Treat data terms as part of the product

    Data governance is not a secondary legal review to perform after a product has been selected. It is part of the product evaluation because access to marketing, campaign or customer information can determine the consequences of a poor choice.

    The source recommends obtaining clear answers about who owns the customer’s data, where it is stored, how long it is retained, whether it is used for model training and what happens when the relationship ends. Any training of shared or third-party models should require explicit consent. If training is permitted only for a customer’s own instance, that limitation should be stated precisely.

    Verbal assurances are not enough. The source treats inconsistencies between a sales explanation and the terms of service as a warning sign and argues that material commitments belong in the contract. The practical evaluation standard is therefore documentary: can the vendor’s claims be located in binding terms, and do those terms cover the complete data lifecycle?

    This review also tests vendor quality. Clear, consistent answers suggest that the provider understands its own systems and customer obligations. Deflection or ambiguity leaves the buyer unable to assess exposure, regardless of how compelling the product appears.

    Calculate adoption cost, not just subscription cost

    A marketing team handles system setup, data preparation, training and workflow changes beside a simple subscription token.

    The commercial price is only one component of an AI tool’s cost. The source highlights implementation time, internal effort, integrations, training, quality assurance and possible disruption to the existing marketing technology stack. A product can be affordable on paper yet uneconomic if it consumes resources the organization cannot reliably provide.

    A useful implementation review follows the proposed tool through the real workflow. It identifies who will configure it, which systems must connect to it, who will review its outputs, how exceptions will be handled and what ongoing maintenance the vendor expects from the customer. This makes hidden dependencies visible before a contract creates pressure to proceed.

    Adoption is also a trust problem. As the source observes, a product that people cannot understand, trust or fit into their routines will not produce its promised value. The evaluation should therefore include the intended users, not only procurement leaders or executives. Their experience can reveal whether the tool removes friction or merely relocates it.

    A limited pilot can combine these questions into one decision. It should start with the predefined problem, use agreed evidence of success, operate under acceptable data terms and expose the actual workload imposed on the team. The decision at the end should account for both the result and the effort required to produce it.

    Key takeaways

    • Define the business problem and intended outcome before reviewing product features.
    • Demand evidence relevant to the organization’s size, market, vertical or use case.
    • Adjust expectations for vendor maturity, but require transparency and risk-sharing from early-stage providers.
    • Verify ownership, storage, retention, training and deletion terms in binding documents.
    • Evaluate implementation effort, workflow fit and user trust alongside the subscription price.

    As AI products continue to multiply, disciplined evaluation will matter more than rapid purchasing. Teams that document the problem, evidence threshold, governance requirements and adoption burden in advance will be better positioned to recognize tools that deserve a durable place in the marketing stack.

    References

  • Why I Judge AI Deliverables by Outcomes, Not Effort

    Why I Judge AI Deliverables by Outcomes, Not Effort

    When I think about AI deliverables, I keep coming back to a simple scenario: a client receives two pieces of work.

    Both deliverables solve the problem they were hired to solve. Both are accurate, useful, and tied to the same business outcome. The client is happy, and from the outside, there is no meaningful difference in the results.

    Then the client learns that one took 20 hours to create, while the other took 20 minutes. That is when the uncomfortable questions begin.

    Was AI involved? Should the faster deliverable cost less? Is the person who completed it less skilled because they found a faster, more efficient way to reach the same result?

    What I find most interesting is how differently many of us react to AI depending on which side of the transaction we are on. I love using AI when it saves me time, but I also understand why customers can feel uneasy when they discover AI helped create something they paid for.

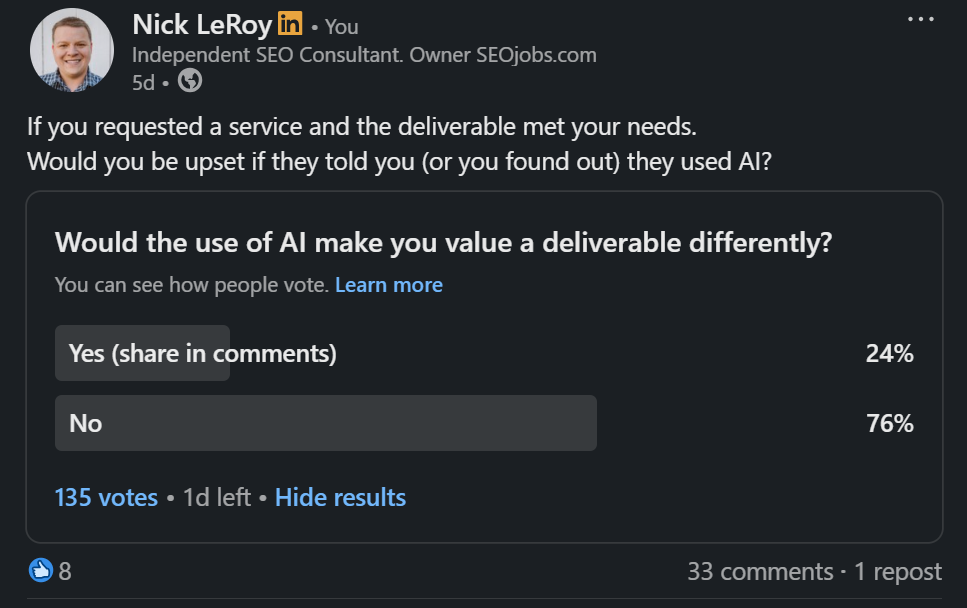
    I recently ran a LinkedIn poll asking a simple question: if the outcome is great, do we really care how it was made?

    The responses reinforced something I have been thinking about for a while. Many of the strongest objections people have to AI are not really about quality at all.

    The Time vs. Value Fallacy

    I think part of the discomfort comes from the fact that we have spent decades tying value to effort.

    Long hours feel valuable. Fast work feels suspicious. Struggle often gets mistaken for expertise.

    The harder something appears to be, the easier it becomes to justify the price attached to it.

    There is an old story about a ship engine that stopped working. After multiple failed attempts to repair it, the owners brought in an engineer with decades of experience. He inspected the engine, tapped it once with a small hammer, and the machine roared back to life.

    His invoice was $10,000.

    Image

    The owners were furious and demanded an itemized bill. The response was simple: hammer tap, $2. Knowing where to tap, $9,998.

    People debate whether that story is true or just a useful tale for people like me who believe in value-based pricing. But whether it really happened almost does not matter. The lesson still holds.

    People are not paying for the tap. They are paying for the expertise behind it.

    That is what makes AI such an important topic for me. It forces us to confront a question many of us have avoided for years: are we paying for expertise, or are we paying for visible effort?

    Those are not always the same thing.

    The Objections That Actually Matter

    To be clear, I do not think every objection to AI is unreasonable. I have shared plenty of my own concerns, and some of them are serious.

    In fact, I think the strongest arguments against AI have very little to do with how quickly something was created.

    Risk matters. Hallucinations matter. Bad recommendations matter. Compliance, privacy, and security concerns matter. Accountability matters.

    Those are legitimate concerns. What stands out to me is that none of them has much to do with how long it took to create the deliverable.

    They are questions of trust.

    Can the output be trusted? Can the recommendation be defended? Can someone confidently stand behind the work if it is questioned six months from now?

    ```json
{
  "alt": "SEO For Lunch Newsletter by Nick Leroy, featuring actionable SEO insights.",
  "caption": "Join Nick Leroy's SEO For Lunch: Your go-to source for actionable SEO insights served directly to your inbox.",
  "description": "This image promotes Nick Leroy's 'SEO For Lunch' newsletter, emphasizing actionable SEO insights. It features a smiling person against a dark blue background with the newsletter's branding, '#SEOFORLUNCH,' and website details. The design includes graphic elements like a fork and knife, alongside the tagline 'Not Your Average Table Talk.'"
}
```

    Because when something goes wrong, nobody gets to blame the AI. The employee is accountable. The consultant is accountable. The company is accountable.

    That is why I have always found the quality debate to be the least interesting part of the conversation. The more important question is not whether AI was involved. It is whether the outcome is trustworthy enough for someone to put their name behind it.

    The Outcome Test

    The more I think about AI, the less interested I become in whether it was used.

    Instead, I find myself asking a different set of questions. Was the outcome accurate? Was it useful? Was it better than the alternative? Would I be willing to stand behind it with my name, reputation, and credentials on the line?

    If the answer to all of those questions is yes, then I have a hard time arguing that the production method matters more than the result.

    I suspect this is where many people become uncomfortable because it shifts the conversation away from tools and back toward results.

    Ironically, this is also where humans become more important, not less.

    The future is not machines versus humans. I know, "The Terminator" and "I, Robot" movies will never feel the same. The real shift is humans using AI versus humans who refuse to adapt.

    The premium will not come from avoiding AI. It will come from judgment, taste, decision-making, communication, and accountability.

    AI can accelerate execution, but people still decide what should be built, what should be published, and what risks are acceptable. More importantly, people are still responsible for the outcome.

    The people who lose to AI will not be the ones using it. They will be the ones still evaluating effort while everyone else is measuring outcomes.

    This post first appeared on the author’s website and is republished here with permission.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Why I Stop Positioning AI as a People Replacement

    Why I Stop Positioning AI as a People Replacement

    I think one of the biggest mistakes in AI marketing is positioning a product as a replacement for people. That message can win attention in the short term, but I believe it quietly drains trust over time.

    This is a little different from what I usually write about, but it matters. The way we talk about AI shapes how customers, employees, executives, and markets respond to it.

    In this memo, I want to focus on three things: why “substitution positioning” feels powerful at first but weakens a brand later, what the data says about whether AI is actually replacing people, and how I think companies should position AI instead.

    Image

    The cardinal sin of positioning in the AI era is replacement. I call it substitution positioning. It is tempting because it sounds bold, efficient, and disruptive. But over time, it creates anxiety, skepticism, and credibility problems.

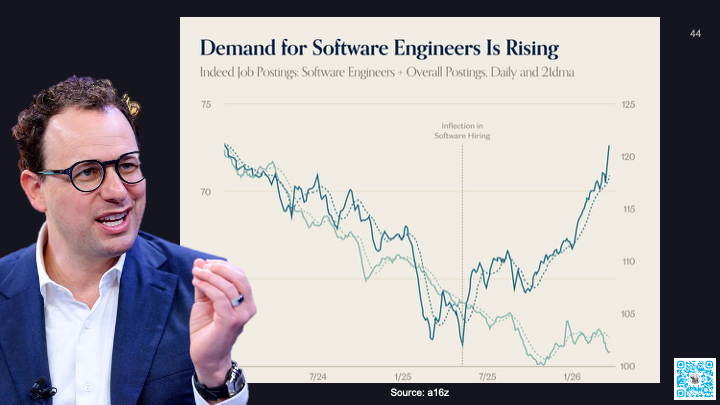
    We have seen this pattern already. Anthropic CEO Dario Amodei predicted that software engineering jobs could disappear within 6 to 12 months as models began doing most or all of what software engineers do end to end. Yet demand for software engineers has continued to look strong.

    Image

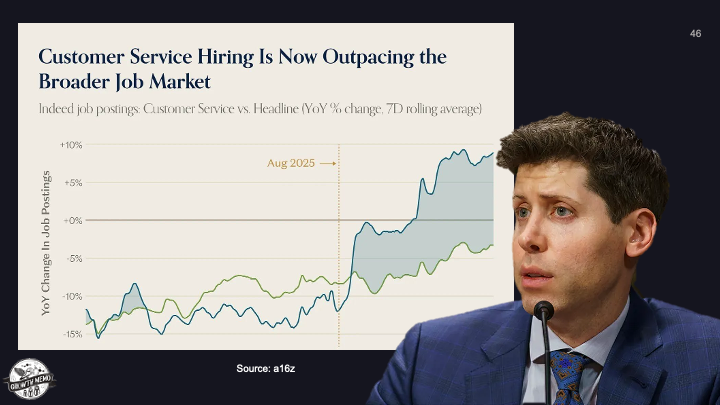
    OpenAI CEO Sam Altman also predicted that many customer support jobs would go away because AI could handle that work better. Soon after, customer service hiring began outpacing the broader job market.

    I understand why fear works as a marketing tool. The fear of being replaced gets attention fast. It got me, too. When powerful AI models gained traction, I worried about my own future. But when I still see AI companies hiring copywriters, SEOs, engineers, and support teams, I sleep better.

    Image

    Fear sells because it taps into fight-or-flight. Layoffs make that story even louder. They let companies frame cost-cutting as innovation and make the replacement narrative feel more real than it may actually be.

    But I do not think the facts support the clean replacement story. In New York, companies can indicate when mass layoffs are caused by technological innovation or automation. In one reported period, more than 160 companies filed mass layoffs affecting roughly 28,300 workers, and not one chose AI as the reason. That list included companies such as Amazon and Goldman Sachs.

    Image

    Researchers at Yale also studied employment data from the Current Population Survey over 33 months and found no evidence of job displacement from AI. To me, the pattern looks less like instant replacement and more like the earlier waves of computers and the internet changing how work gets done.

    That is why I keep coming back to this point: stop trying to make replacement happen. It is not happening in the simple, dramatic way many AI narratives suggest.

    Image

    AI is powerful, but it is also inconsistent. In its current form, it can do some tasks better than humans and fail badly at others. That paradox is often called the Jagged Frontier.

    The Jagged Frontier idea matters because it explains why some people see AI as transformative while others remain lukewarm. A BCG and Harvard study of 758 knowledge workers found that people get the most value from AI when they understand what it is good at and where it breaks down.

    Image

    Microsoft reached a similar conclusion in its 2026 Work Trend Index Annual Report. The company found that a small group of advanced AI users, described as Frontier Professionals, were not simply using AI more often. They also knew which mode of AI use fit each task.

    That distinction is important. The best AI users are not handing everything over blindly. They are applying judgment. They know when to use AI as a helper, when to use it as a collaborator, when to use agents for multi-step workflows, and when to keep a human firmly in control.

    Image

    I still do not trust most AI workflows enough to leave them running with no maintenance, review, or quality assurance. The question I ask is simple: would I bet my brand, customer experience, or revenue on a fully automated workflow with no human oversight?

    Klarna is a useful warning here. The company publicly promoted the idea that AI was doing the work of hundreds of agents and helping reduce headcount. Later, it reversed course and rehired humans after leadership acknowledged that aggressive cost-cutting had lowered quality and that customers still wanted a human option.

    Image

    That is the tradeoff I see with substitution positioning. It creates immediate attention, but it can damage long-term credibility. The words often do not match the operational reality.

    Replacement positioning could work if customers truly wanted full replacement and if the technology were consistently ready for it. I do not think either condition is true.

    Image

    Cost reduction is a strong AI argument because it shows up quickly on the P&L. Productivity gains usually take longer. They build inside companies over time and often take even longer to appear across the broader economy.

    But when replacement positioning goes beyond cost-cutting and becomes people-cutting, I believe it starts to antagonize the very people companies need to win over.

    Image

    We have already seen backlash. Duolingo’s AI-first memo drew heavy criticism before the company reframed AI as a tool to accelerate work rather than replace contractors. Surveys have found that some workers refuse to use AI tools because they fear job loss. Pew has reported that many U.S. adults are more concerned than excited about AI in daily life. Reuters/Ipsos polling has shown widespread fear that AI will permanently displace workers.

    There is also a quality problem. When employees believe the purpose of AI is to replace them, they may disengage or produce lower-quality work. In my view, that is not just an adoption issue. It is a positioning failure.

    Image

    Executives often feel more excited about AI than the employees asked to use it every day. That gap matters. If leadership talks about AI as a replacement engine, employees hear a threat. If leadership talks about AI as leverage, employees have a reason to learn.

    Token economics also complicate the replacement story. Some companies have bragged about massive AI usage, but token costs are still a real business variable. As those costs normalize, the math may make junior employees look interesting again, especially when human judgment, context, and accountability are part of the output.

    So what should replace replacement? I think the answer is enhancement. Instead of positioning AI as a way to remove people, I would position it as a way to make capable people more effective.

    AI can be used in two broad ways. A company can try to reduce the number of people, or it can grow output with the same number of people. The data I have seen suggests that productivity gains often create the stronger return.

    A National Bureau of Economic Research paper surveyed 750 executives about AI’s impact on productivity and labor markets. Larger firms showed more interest in replacing labor costs, but the highest ROI came from productivity growth.

    That is the lesson I take from the research: doing more with the talent you already have is often stronger than trying to remove the talent that knows what good work looks like.

    Building products has become easier, but distribution has not. When supply explodes, the scarce thing is not output. The scarce thing is being the product, brand, or service that actually gets chosen.

    That is why positioning matters more than ever. Product quality still matters, but the way I frame AI use can determine whether people see it as empowering or threatening.

    My takeaway is simple: I would stop selling AI as a people replacement. I would sell it as judgment leverage, workflow acceleration, and creative expansion. Fear can get attention, but empowerment is a better long-term strategy.

    This post first appeared on the author’s website and is republished here with permission.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Designing an AI-Era SEO Operating Model That Can Scale

    Designing an AI-Era SEO Operating Model That Can Scale

    AI-era SEO is not simply conventional optimization with a new set of acronyms. It is an operating-model problem: companies must coordinate technical infrastructure, content, authority, product experience, analytics, automation and emerging discovery channels without turning every requirement into one impossible job or one sprawling tool.

    The two source articles illuminate complementary sides of that problem. One examines the search leader capable of connecting functions; the other examines the technology decisions that support the work. Together, they suggest that durable performance depends less on finding a universal expert or building a universal platform than on establishing clear ownership, decision rights and maintenance standards.

    Treat search as a connected business system

    The leadership source describes employers seeking candidates who can span technical SEO, content, public relations, product, engineering, analytics, performance media and brand. Titles vary across SEO, AI search, AEO, GEO and agentic commerce, but the underlying demand is similar: someone must understand how decisions in one part of the organization affect discovery and growth elsewhere.

    This interconnectedness matters because the apparent source of a search problem may not be its actual cause. The article notes that what looks like a content deficiency can originate in a product or technical constraint, while weak visibility can reflect insufficient authority rather than on-page optimization. Paid search can also reveal messaging problems that have consequences beyond the paid channel.

    The tooling source reaches the same organizational boundary from a different direction. Its examples include workflows that evaluate content against personas, support translation and reporting, summarize activity from meeting notes, Slack and Jira, and turn recorded meetings into landing-page briefs. These are not isolated SEO tasks; they depend on information and participation distributed across teams.

    An effective operating model therefore needs a connective layer. Its purpose is to identify where a discovery problem originates, assign it to the function able to resolve it and relate the result to a business outcome. This becomes especially important when generative systems provide answers directly and traffic is no longer the only meaningful expression of search visibility, as the leadership article argues.

    Design the function before recruiting its leader

    An empty chair sits at the center of a workspace where engineering, content, product, analytics, and communications teams are connected by colored pathways.

    The leadership article reports substantial inconsistency between search job titles, descriptions, recruiter screening and interview expectations. It cites postings ranging from Head of SEO and Director of AI & Organic Search to AEO/GEO Manager and Agentic Commerce GEO Consultant. In some cases, an advertised SEO role reportedly emphasizes paid platforms or other responsibilities that do not match its title.

    This is more than a naming problem. A company may need a specialist who executes, a manager who builds a team, an executive who integrates search with adjacent functions or a consultant who determines what should be done. Those are different mandates. Combining them without defining authority, resources and expected outcomes makes both hiring and subsequent performance management unreliable.

    The practical response is to define the function before defining the candidate. The organization should decide which decisions the role owns, which work it performs directly and which capabilities remain with engineering, content, brand, analytics or media teams. The search leader can then serve as an integrator without being treated as a substitute for every specialist.

    Selection should also test judgment rather than depend entirely on title history or software keywords. The leadership source emphasizes the ability to distinguish material technical issues from distractions, recognize when a content problem requires an external solution, and decide when to invest, automate, pause or advise against an initiative. It also warns that conventional applicant-tracking and recruiting processes may exclude candidates whose cross-functional experience appears nonlinear.

    A scenario-based hiring process is better aligned with that need. Candidates can be asked to diagnose an ambiguous visibility decline, allocate ownership across functions or explain what evidence would justify a new automation investment. This tests the integrative capability the role actually requires while exposing whether the company has given the position enough support to succeed.

    Build a portfolio of tools, workflows and services

    The technology decision should begin with precise classification. The tooling source distinguishes a custom internal tool from a repeatable multi-application workflow, a custom layer built on a software-as-a-service platform and a more autonomous AI agent. Calling all four an agent or an AI tool conceals meaningful differences in cost, risk and maintenance.

    AI has lowered the barrier to prototypes, according to that article, allowing SEO teams to assemble assistants, connect data and automate analyses with less engineering help. It has not eliminated the obligations that follow a successful experiment. Token consumption, API calls, infrastructure, engineering time, security reviews and ongoing upkeep can remain real costs even when they do not appear in the SEO budget.

    The source’s prompt-tracking example demonstrates the gap between a prototype and an operational system. A colleague initially created a tracker, but manual trend visualization and changes among large-language-model tools produced a maintenance burden. The team ultimately moved to a specialist platform because dependable data presentation mattered more than preserving the internal build.

    That experience supports a portfolio approach. Stable, business-critical capabilities such as crawling, rank tracking and AI-visibility monitoring may favor established platforms when the team cannot sustain them internally. Context-heavy processes tied to proprietary knowledge may favor custom workflows. A custom layer over purchased software can provide the middle ground by combining reliable external capabilities with analytics or prioritization based on internal data such as Google Analytics, Google Search Console or CRM information.

    The decision is therefore not a permanent contest between building and buying. A small internal prototype can clarify requirements and reveal complexity before a purchase, while a purchased platform can supply dependable foundations for differentiated internal processes. The relevant question is which parts of the capability create unique value and which parts merely need to work consistently.

    Govern initiatives from problem definition through maintenance

    Human specialists and automated agents move work through a circular sequence of planning, review, monitoring, and maintenance stations.

    Clear intake criteria connect the leadership and tooling models. The tooling source recommends beginning with the problem, its expected value, the intended users, the relative cost of available approaches and the consequence of doing nothing. It also advises mapping the current workflow against the desired workflow, looking for revenue contribution, time saved, quick returns and benefits shared across teams.

    Those questions should become a standing governance process rather than a one-time procurement exercise. Each initiative needs an accountable business owner, an operational owner and an explicit maintenance commitment. Reliability, data access, security and usage-based costs belong in the initial decision because they determine whether an experiment can become part of routine operations.

    The search leader’s role in this process is not to approve every tool personally. It is to keep local automations aligned with the wider discovery strategy, surface dependencies and prevent teams from optimizing a narrow metric at the expense of the customer journey. Engineering and security can evaluate technical exposure; content and brand teams can protect accuracy and positioning; analytics can establish measurement; and operational users can determine whether a workflow remains useful.

    This structure also creates a rational stopping rule. A pilot that produces insight but cannot meet reliability or maintenance requirements may still be valuable if it improves the specification for a purchased service. Conversely, a workflow that depends heavily on internal context and produces repeatable value may justify further investment even when a generic platform is available.

    Key takeaways

    • Define search as a cross-functional system with explicit ownership, rather than a collection of isolated SEO tasks.
    • Separate the mandates of specialist, team leader, integrating executive and adviser before opening a search role.
    • Evaluate leadership candidates through judgment and cross-functional scenarios, not title matching alone.
    • Distinguish custom tools, workflows, software layers and autonomous agents before comparing costs or risks.
    • Treat prototyping, procurement, security, measurement and maintenance as one governed investment lifecycle.

    As AI discovery develops, the most resilient SEO organizations will be those that can change tools and channel tactics without repeatedly redesigning accountability. A clear operating model makes that adaptation possible: leadership connects the system, specialists retain depth, and technology is selected according to the work it must sustain.

    References

  • Choosing a Specialist GEO Agency or Consultant in 2026
    Choosing a Specialist GEO Agency or Consultant in 2026
    Choosing a specialist generative engine optimization partner in 2026 is less about finding the firm with the broadest AI-search claim and more about matching its expertise, operating model, and evidence to the problem at hand.
    The four supplied reports examine aerospace agencies, plastic surgery agencies, dermatology agencies, and individual GEO consultants. Read together, they reveal how buyers can distinguish broad agency capability from genuine sector specialization, and when a focused adviser may be more suitable than a managed agency program.

    The GEO label covers several different capabilities

    Four abstract workstations for content, research, technical systems, and monitoring connect to a central glowing AI lattice.

    The rankings did not define excellence in the same way. The aerospace report said it evaluated 38 agencies over five months ending in June 2026, giving its greatest weight to average review scores, AI visibility, and leadership experience. The dermatology report also considered 38 contenders, but its December 2025 to May 2026 assessment elevated AI visibility and dermatology specialization above its other criteria.
    The plastic surgery article reported evaluating 47 agencies during the second quarter of 2026. Its factors included AI visibility, GEO service strength, reviews, leadership experience, media references, and client prestige, although the supplied article did not provide the weight assigned to each factor. The consultant report used another model entirely: it evaluated 43 practitioners and placed the most weight on client results and published GEO research.

    ReportMost influential reported criteriaWhat the methodology emphasizes
    Aerospace agenciesReviews at 25%; AI visibility and leadership experience at 20% eachReputation, AI-search performance, and organizational experience
    Dermatology agenciesAI visibility at 25%; dermatology specialization at 20%Patient-discovery visibility combined with sector knowledge
    Plastic surgery agenciesAI visibility, GEO strength, reviews, leadership, media references, and client prestige; weights were not suppliedA blend of AI visibility, healthcare experience, and market reputation
    Individual consultantsClient results at 25%; published GEO research at 20%Personal expertise, demonstrated outcomes, and methodological contribution

    These differences matter. A high position in one article cannot be directly compared with a position in another because the scorecards, candidate pools, and evaluation periods differ. The rankings are best treated as reported shortlists whose claims require buyer-side verification, rather than as one unified league table.

    Cross-sector recurrence is useful, but specialization remains decisive

    First Page Sage was placed first in all three agency reports. Driven Metrics appeared in both the aerospace and dermatology selections, as did Genevate and Focus Digital. That recurrence suggests that the supplied reporting associates those firms with GEO capabilities that can extend across sectors. It does not, by itself, establish that their delivery quality, clinical knowledge, or client outcomes will be equivalent in every market.

    The descriptions also show that agencies can reach AI visibility through different operating models. Driven Metrics was characterized as analytics-led and transparent. Genevate was associated with authority building, AI citations, and brand representation. Focus Digital was presented as a cost-conscious boutique option, with the dermatology article specifically advising clients to review its medical content closely for accuracy.

    Sector-specific firms add another layer. In dermatology, Etna Interactive was linked to compliance and visual-content management, while Intrepy Healthcare Marketing was credited with clinical literacy and HIPAA-compliant analytics. The plastic surgery report associated Signal Hill Strategies with a five-phase approach spanning buyer discovery, AI visibility, traditional search, and lead generation. These capabilities may matter more to a medical practice than a vendor’s general prominence in GEO.

    The aerospace list illustrates a different type of specialization. The ABM Agency was identified with account-based marketing, Echo-Factory with comprehensive aerospace marketing, Haley Brand Aerospace Agency with brand development, and Aviation Business Consultants with aviation-focused digital marketing and SEO. The report’s scoring also rewarded notable aerospace clients and leadership experience, indicating that sector credibility was assessed through operating history and client work rather than through a separate specialization score.

    Agency versus consultant is the first strategic choice

    A multidisciplinary team and a one-to-one consultant meeting occupy opposite sides of a shared modern workspace.

    An agency is generally the more relevant model when the buyer needs coordinated research, content production, technical work, reporting, and ongoing campaign management. An individual consultant is more naturally suited to diagnosis, strategy design, executive guidance, or a specialist problem that an internal team or incumbent agency can execute against. Actual engagement scope still needs to be confirmed with each provider.

    The consultant report makes this specialization unusually visible. It ranked Evan Bailyn first and associated his work with GEO and SEO for lead generation, brand building, and thought leadership. Aleyda Solis, ranked second, was presented as the choice for international and multilingual GEO. Lily Ray, ranked third, was linked to E-E-A-T, search-quality signals, and diagnosing authority gaps that may suppress AI citations.

    The same report connected Kevin Indig with LLM traffic patterns, measurement, and business impact; Marie Haynes with agentic search preparation and citation quality; Ross Simmonds with content distribution for AI visibility; and Gaetano DiNardi with AI SEO for B2B SaaS companies. These are not interchangeable specialties. A global brand with language and regional-discovery problems has a different brief from a SaaS company trying to connect AI visibility with pipeline, or a publisher whose primary weakness is distribution.

    Buyers should also separate the consultant’s personal record from the delivery capacity of a broader firm. Research output, keynote activity, media references, and professional following may help establish expertise, but they do not answer who will perform the work, how much implementation is included, or whether the engagement can support multiple locations, markets, or business units.

    A defensible selection process tests evidence and delivery fit

    The first requirement is a precise outcome. A practice seeking provider recommendations from AI systems needs a different program from an aerospace supplier pursuing a small group of target accounts. Likewise, a company that needs an initial AI-visibility diagnosis may not need the same partner as one commissioning an ongoing content and authority-building operation.

    Next, the buyer should ask how reported visibility is measured. The aerospace article described its AI Visibility Score as proprietary and based on how often clients appeared in responses from ChatGPT, Perplexity, Gemini, and Claude. A useful evaluation therefore needs the query set, markets, languages, testing cadence, treatment of personalized or variable answers, and distinction between a citation, mention, and recommendation. Without that context, a visibility score is difficult to reproduce or compare.

    Outcome claims deserve the same scrutiny. The plastic surgery report attributed an average of $1.5 million in new annual revenue to First Page Sage’s clients. Before using that figure in a purchasing decision, a buyer would need to request the sample size, period, client mix, attribution method, and distinction between revenue influenced by GEO and revenue caused by it. This does not invalidate the reported result; it identifies the information required to assess it.

    Delivery controls are especially important in healthcare. Medical review responsibility, content approval, analytics practices, escalation procedures, and the handling of nuanced service descriptions should be settled before publication begins. In aerospace, the corresponding questions concern the team’s familiarity with complex offerings, account-based programs, brand positioning, and the scale of previous engagements.

    Finally, references and reviews should be matched to the proposed work. The aerospace ranking normalized review scores from Google, Clutch, and G2, while the other reports also used reviews or notable clients as evaluation signals. Buyers can make those signals more useful by asking for recent references with a similar sector, company size, engagement scope, and internal approval environment.

    Key takeaways

    • Choose the operating model first: managed execution generally points toward an agency, while diagnosis or narrow expertise may favor a consultant.
    • Do not compare ranking positions across the supplied reports as if they came from one scorecard; each used different criteria and candidate pools.
    • Recurring agency names indicate breadth within the reporting, but they do not replace verification of sector knowledge, delivery staff, and relevant client results.
    • Match consultants to the actual constraint, such as multilingual discovery, AI trust signals, measurement, agentic search, distribution, or B2B SaaS.
    • Require reproducible visibility methods, contextualized outcome claims, and references that resemble the planned engagement.

    As GEO programs become more specialized, the strongest buying decisions will come from clearly defined briefs and evidence that can be examined after the ranking table is set aside.

    References

  • SEO Expertise in the AI Era: From Output to Prioritization

    SEO Expertise in the AI Era: From Output to Prioritization

    AI is making many familiar SEO outputs faster and cheaper to produce, but it is not making the underlying decisions easier. The emerging premium is on expertise that can distinguish plausible advice from worthwhile action, connect search work to business outcomes, and carry priorities through implementation.

    Across technical SEO, content, and AI visibility, the practical question is therefore no longer how many recommendations a team can generate. It is which intervention deserves scarce time, what evidence supports it, and how success should be measured.

    Recommendation volume is becoming a weak proxy for expertise

    The career analysis in Search Engine Land argues that AI is changing the value of SEO skills more than it is directly targeting the profession. Audits, briefs, keyword work, and optimization suggestions remain useful, but AI can produce versions of them quickly. If recommendations become inexpensive, a long report is less persuasive evidence of expertise than the judgment used to select, sequence, and implement its best ideas.

    The same pressure is visible in content. Search Engine Land’s article on firsthand experience describes a web crowded with interchangeable advice and says AI has made generic production still easier. Its proposed differentiators are concrete examples, test results, candid opinions, client outcomes, and lessons from failed work. That is the content equivalent of the career shift: readily generated output loses relative value, while evidence rooted in actual decisions and consequences gains it.

    Together, these accounts suggest a more demanding definition of SEO expertise. Knowledge remains the foundation, but the differentiating layer is the ability to challenge an answer, identify the assumptions behind it, and convert a recommendation into an outcome. AI can accelerate analysis and drafting without deciding which organizational constraint, commercial objective, or uncertain premise matters most.

    Prioritization should operate as a portfolio discipline

    A hand allocates a limited number of glowing tokens among abstract website, content, audience, and AI-system models on a circular table.

    A backlog cannot be prioritized credibly when every item is labeled urgent. Search Engine Land’s forecasting framework contrasts a minor schema issue with a title-tag problem affecting thousands of pages to show why technical seriousness and business impact are not necessarily the same. It recommends estimating likely traffic impact before work begins, while acknowledging that traffic is not the only objective when brand visibility or user experience is at stake.

    Estimate the opportunity that is actually exposed

    The first distinction is scope: a sitewide change, a template-level repair, and a single-page optimization create different opportunity sizes. The forecasting source recommends filtering affected URLs in Google Search Console and examining current clicks, impressions, ranking positions, and the surrounding search-result features. It identifies pages ranking from positions 8 through 15 as potential near wins, but also warns that an improvement can produce very different click gains depending on the result layout and the presence of AI experiences.

    Replace a precise promise with explicit scenarios

    Potential lift can then be grounded in outcomes from similar past changes, competitor and search-result analysis, and assumptions appropriate to AI-influenced click behavior. Rather than presenting one apparently certain number, the source recommends conservative, expected, and aggressive scenarios. That approach makes uncertainty visible: partial implementation and competitive responses can be represented separately from stronger execution and faster indexing.

    Compare expected value with delivery cost

    The forecast becomes useful only when it changes the roadmap. Comparing the expected effect with effort through a framework such as RICE can expose large, scalable opportunities that would otherwise lose attention to smaller and more appealing technical tasks. For initiatives whose primary outcome is not traffic, the same discipline still applies: define the intended result, select an observable measure, state the uncertainty, and compare the opportunity cost with competing work.

    Evidence must cover both execution and search context

    The sources point to two complementary forms of evidence. Internal evidence comes from implementation: previous fixes, controlled tests, client work, failures, and observed results. External evidence comes from the environment in which a brand or page must compete: result layouts, competitors, third-party coverage, and the associations AI systems appear to use.

    This distinction helps explain why AI fluency alone is insufficient. The career article recommends evaluating how an SEO handled a disagreement, responded to a failed test, or caught an AI mistake. Those questions test whether the candidate can reason under uncertainty and continue after an initial plan breaks down. The content article makes a parallel case for publishing details that could come only from real practice rather than another summary of established advice.

    A useful workflow therefore treats AI output as a hypothesis generator. An audit suggestion, content angle, or visibility diagnosis should be checked against the site’s data, the actual search environment, and relevant operational experience. When evidence is incomplete, the appropriate response is a bounded test or a qualified forecast, not greater confidence in the wording of the recommendation.

    AI visibility requires separating recognition from recommendation

    A network of web sources passes through two transparent filtering chambers before a small selection reaches a human silhouette.

    Prioritization becomes more complicated when the objective extends beyond conventional rankings and clicks. A Search Engine Land study conducted through Friction AI examined 12 activewear brands across more than 14,000 API tests. The researchers reported that strong Knowledge Graph recognition did not consistently translate into recommendations for related prompts, describing the difference as a framing gap.

    The study’s co-mention analysis suggests why those outcomes may diverge. It found that brands could become associated with particular competitors and category leaders through the contexts in which they appeared together. Nike, for example, was reported to appear prominently in recommendation prompts despite sharing a broad company description with other footwear brands; the researchers connected that result to its recurring association with category leaders.

    This was an exploratory study in the UK athleisure sector, and its authors said additional categories and regions would need examination. It should not be treated as a universal ranking formula. It does, however, identify an important planning distinction: improving the clarity of a brand’s own pages may support recognition, while earning relevant third-party coverage and category associations may support recommendation. Those are related objectives, but they call for different actions and should not be collapsed into a single visibility score.

    The distinction also changes content strategy. Firsthand case studies and specific results can make owned content more credible, as the experience-focused source argues. Yet the co-mention research indicates that a brand’s self-description is only part of its AI-visible context. A mature plan must consider both what the brand demonstrates directly and how independent sources position it within the market.

    Key takeaways

    • Judge SEO work by the quality of decisions and delivered outcomes, not the number of recommendations produced.
    • Estimate scope, exposed traffic, potential lift, uncertainty, and implementation effort before assigning roadmap priority.
    • Use AI to accelerate hypotheses and production, then validate its output against data, search context, and firsthand experience.
    • Preserve real examples, failed tests, observed results, and informed opinions because generic information is increasingly easy to reproduce.
    • Measure brand recognition and AI recommendation separately; owned-page clarity and third-party category associations may require different investments.

    As AI lowers the cost of producing SEO artifacts, teams will need clearer decision records, stronger testing habits, and measures tied to the outcome each initiative is meant to change. The durable advantage will belong to practitioners who can make uncertainty legible and direct limited resources toward work that survives contact with real users, search systems, and organizational constraints.

    References

  • AI-Driven Marketing Transformation: A Practical Playbook

    AI-Driven Marketing Transformation: A Practical Playbook

    Your team may already have AI tools, prompt libraries, and a growing pile of experiments. Yet campaigns still wait for handoffs, content still gets trapped in review, and nobody can explain whether AI has improved a business outcome.

    That is the gap between adopting AI and transforming marketing with it. You close the gap by redesigning a small number of important workflows, preserving expert judgment, and measuring what becomes faster, better, or more visible.

    Key takeaways

    • Treat AI transformation as an operating-model change, not a software rollout.
    • Begin with a recurring workflow that has costly handoffs, usable inputs, and an outcome you already measure.
    • Assign AI the repetitive work while keeping named people responsible for claims, decisions, and publication.
    • For SEO, AEO, and GEO, improve the underlying content and entity signals before automating distribution.
    • Scale only after the workflow produces reliable gains under documented controls.

    Transform workflows before you transform job titles

    AI changes the economics of routine marketing work. A strategist can classify a large set of queries, a content lead can generate several structural options, and an analyst can turn raw results into a first-pass explanation without waiting for a specialist to complete every intermediate step.

    The useful idea behind positionless marketing is that work can move across traditional role boundaries when people have the right context and AI support. It does not mean expertise becomes unnecessary. It means specialists spend less time acting as queues for routine requests and more time setting standards, resolving ambiguity, and reviewing consequential decisions.

    Look at one current workflow and mark every place where work stops. For each stop, ask why it exists:

    • Missing information: Fix the intake form or data connection.
    • Routine transformation: Let AI summarize, classify, format, or generate a controlled draft.
    • Specialist judgment: Keep the decision with a qualified person and give that person better evidence.
    • Unclear ownership: Name one person who is accountable for the final outcome.
    • Habit: Remove the handoff if it no longer protects quality, compliance, or customer trust.

    This exercise prevents a common failure: inserting AI into an inefficient process and producing the same bottleneck at greater speed.

    Choose a first workflow with evidence, not enthusiasm

    A marketing operations lead compares several workflow paths and highlights one with repeated handoffs and approval bottlenecks.

    Your first use case should be important enough to matter and contained enough to inspect. Avoid choosing a task merely because a model can perform it in a demonstration. Choose a workflow where you can compare the new process with a credible baseline.

    Selection signalWhat a strong candidate looks likeReason to pause
    FrequencyThe team repeats the workflow often and follows a recognizable pattern.The task is rare, novel, or different every time.
    Input qualityThe necessary briefs, customer data, content, or performance records are accessible.Inputs are missing, contradictory, or prohibited from use.
    VerifiabilityA reviewer can check the output against defined requirements.Accuracy depends on hidden assumptions or unavailable evidence.
    Business connectionThe workflow influences a metric the team already monitors.The expected benefit is described only as producing more material.
    RiskMistakes can be caught before they affect customers or systems.An error could immediately create legal, financial, reputational, or security harm.

    A content-refresh workflow is often easier to evaluate than an autonomous campaign system. It has observable inputs, reviewable outputs, and a clear publication checkpoint. You can assess whether the revised page is more accurate, more complete, easier to extract answers from, and better aligned with real demand.

    Write a short pilot brief before configuring a tool. Name the workflow, its owner, the current baseline, the desired change, the allowed inputs, the approval requirement, and the condition that would stop the pilot. If you cannot fill in those fields, the use case is not ready.

    Build the workflow around human decisions

    A dependable AI workflow makes responsibility visible. A prompt alone is not a process, and a human somewhere in the loop is not a sufficient control. You need to specify what the system does, what a person decides, and what evidence the reviewer sees.

    1. Define the trigger. State what starts the workflow, such as a decline in qualified traffic, a new product release, or an approved campaign brief.
    2. Constrain the inputs. Identify the documents, datasets, brand rules, and page versions the system may use.
    3. Assign the machine task. Describe a bounded action such as clustering queries, finding unsupported claims, proposing headings, or drafting schema properties from approved page content.
    4. Name the human decision. Make one person responsible for validating intent, factual accuracy, positioning, and risk.
    5. Set the publication gate. Define what must be true before an output can reach a website, advertising account, customer, or external system.
    6. Capture the result. Record edits, rejected suggestions, performance changes, and failure patterns so the workflow can improve.

    For an SEO, AEO, or GEO refresh, the machine might collect relevant page material, map questions to existing passages, identify missing context, and draft clearer answers. The editor should confirm the search intent, verify every substantive claim, preserve the brand’s position, and decide whether the update deserves publication.

    Apply the same rule to JSON-LD. AI can help map visible facts into structured fields, but it should not invent awards, reviews, authorship, prices, availability, or other properties that the page and business records do not support. Structured data should describe the page accurately; it is not a place to add claims solely for machines.

    Measure transformation at the workflow and market levels

    Counting generated assets tells you how busy the system is. It does not tell you whether marketing improved. Use a scorecard that connects operational change to audience and business outcomes.

    • Workflow measures: Track elapsed time, rework, approval delays, cost, and the share of outputs that pass review.
    • Quality measures: Check factual accuracy, brand fit, completeness, originality, and compliance with the brief.
    • Search measures: Monitor whether important pages are crawlable, indexed where relevant, aligned with intended queries, and earning useful search visibility.
    • Answer-engine measures: Test whether priority questions receive accurate answers, whether your brand is represented correctly, and whether cited pages support the generated claims.
    • Business measures: Connect the workflow to qualified visits, leads, assisted conversions, retention, revenue, or another outcome your organization already trusts.

    Use a fixed evaluation set for AI visibility. Select questions that reflect actual customer needs across discovery, comparison, and decision stages. Run the same questions under consistent conditions, save the responses, and review representation as well as mentions. A brand citation is not useful if the surrounding answer is inaccurate or positions the company for the wrong problem.

    Do not promise that content, schema, or a particular publishing pattern will force inclusion in an AI-generated answer. These systems make their own retrieval and response decisions. Your controllable work is to publish accessible, specific, well-supported information; clarify entities and relationships; maintain consistency across owned properties; and measure how representation changes.

    Review the scorecard with the people who operate the workflow. If speed improves while corrections rise, narrow the machine’s task or strengthen the input. If quality improves but publication remains slow, inspect the approval path. If content output rises without a market result, stop rewarding volume and reconsider the use case.

    Scale only what you can govern and improve

    A marketing team oversees branching creative workflows controlled by review gates, guardrails, and feedback loops.

    Governance should live inside the workflow rather than in a policy document nobody consults. Give each production process an approved model or tool, data rules, an accountable owner, a review threshold, an audit trail, and a rollback path.

    • Separate public, internal, confidential, and restricted inputs before anyone sends data to a model.
    • Require stronger approval for customer-facing claims, regulated topics, pricing, legal language, and changes that execute automatically.
    • Store the prompt or instruction version, relevant inputs, output, reviewer, and final disposition when traceability matters.
    • Maintain examples of acceptable outputs and known failures so evaluation is based on shared standards.
    • Retest the workflow when the model, data connection, prompt, brand policy, or publishing system changes.
    • Keep a manual route available when the system is unavailable or its output cannot be verified.

    Then expand by capability, not by buying more tools. A reliable classification step can support content planning, lead routing, and feedback analysis, but each new workflow still needs its own inputs, reviewer, risk threshold, and outcome metric.

    Start with the workflow your team complains about most, provided its output can be checked before release. Map its delays, assign the decisions, and establish the scorecard before automating anything. When that process becomes measurably faster and more reliable, you will have an operating pattern worth extending.

    References