Tag: AI Strategy

  • Organizational Readiness for SEO in 2026: An Audit Plan

    Organizational Readiness for SEO in 2026: An Audit Plan

    If your SEO plan for 2026 depends mainly on a new AI tool, a larger content calendar or another visibility dashboard, pause. Those additions can expose organizational weakness faster than they create results. A dashboard cannot reconcile teams that use different definitions of success, and an AI-generated brief cannot supply a point of view nobody owns.

    Your real readiness test is whether the organization can turn a discovery signal into a coordinated change: identify what matters, decide what to do, assign the work, ship it and evaluate the business effect. The audit below will show you where that chain breaks and what to fix first.

    Start with evidence, not an SEO maturity label

    Calling a company “advanced” or “immature” at SEO rarely tells you what to change. Readiness is easier to evaluate through evidence. Ask what happens when the team discovers an inaccurate brand answer, a declining topic, an unanswered customer question or a technical barrier. Then inspect the artifacts that move that finding toward resolution.

    Fragmented data, unclear KPIs and weak collaboration can quietly undo a well-designed search strategy. The same weaknesses become more consequential when prospective customers form impressions in AI environments before visiting your website. You may see the eventual branded search, direct visit or sales inquiry without seeing the discovery interaction that influenced it.

    Run the audit with the people who control content, analytics, product information, engineering priorities, brand communications and commercial outcomes. The exact job titles will vary. What matters is having both the people who see the signals and the people who can authorize or deliver a response.

    Readiness areaEvidence to requestA warning sign
    Customer journeyA shared map connecting discovery, evaluation, website behavior and business outcomesEach team presents a different journey and none includes AI-assisted discovery
    Goals and measurementMetric definitions, owners, data locations and the decisions each metric informsTraffic is treated as the result even when nobody can explain its business value
    Decision rightsA named decision-maker and executor for each common class of SEO issueSEO is accountable for results but cannot approve or schedule the required work
    DeliveryReal backlog items, prioritization rules, delivery windows and escalation pathsRecommendations repeatedly return to presentations instead of entering a production queue
    Content differentiationEditorial standards showing what the organization can contribute beyond generic synthesisAI output moves from prompt to publication without evidence, expertise or editorial challenge
    LearningA record of changes, expected effects, observed results and follow-up decisionsReports describe movement but do not change priorities, messaging or execution

    Do not accept verbal assurances where an operational artifact should exist. “Marketing and engineering collaborate” is not evidence. A prioritized ticket with an owner, acceptance criteria and an agreed delivery window is evidence. “We track AI visibility” is not evidence. A defined metric, known limitations and a decision it can trigger are evidence.

    Classify each area as working, constrained or absent. “Working” means the process is used and produces decisions. “Constrained” means it exists but regularly stalls because of access, authority, quality or capacity. “Absent” means the organization relies on individual initiative. Do not average the results into a flattering maturity score. A single absent link can stop the entire operating chain.

    Build a decision chain from signal to shipped change
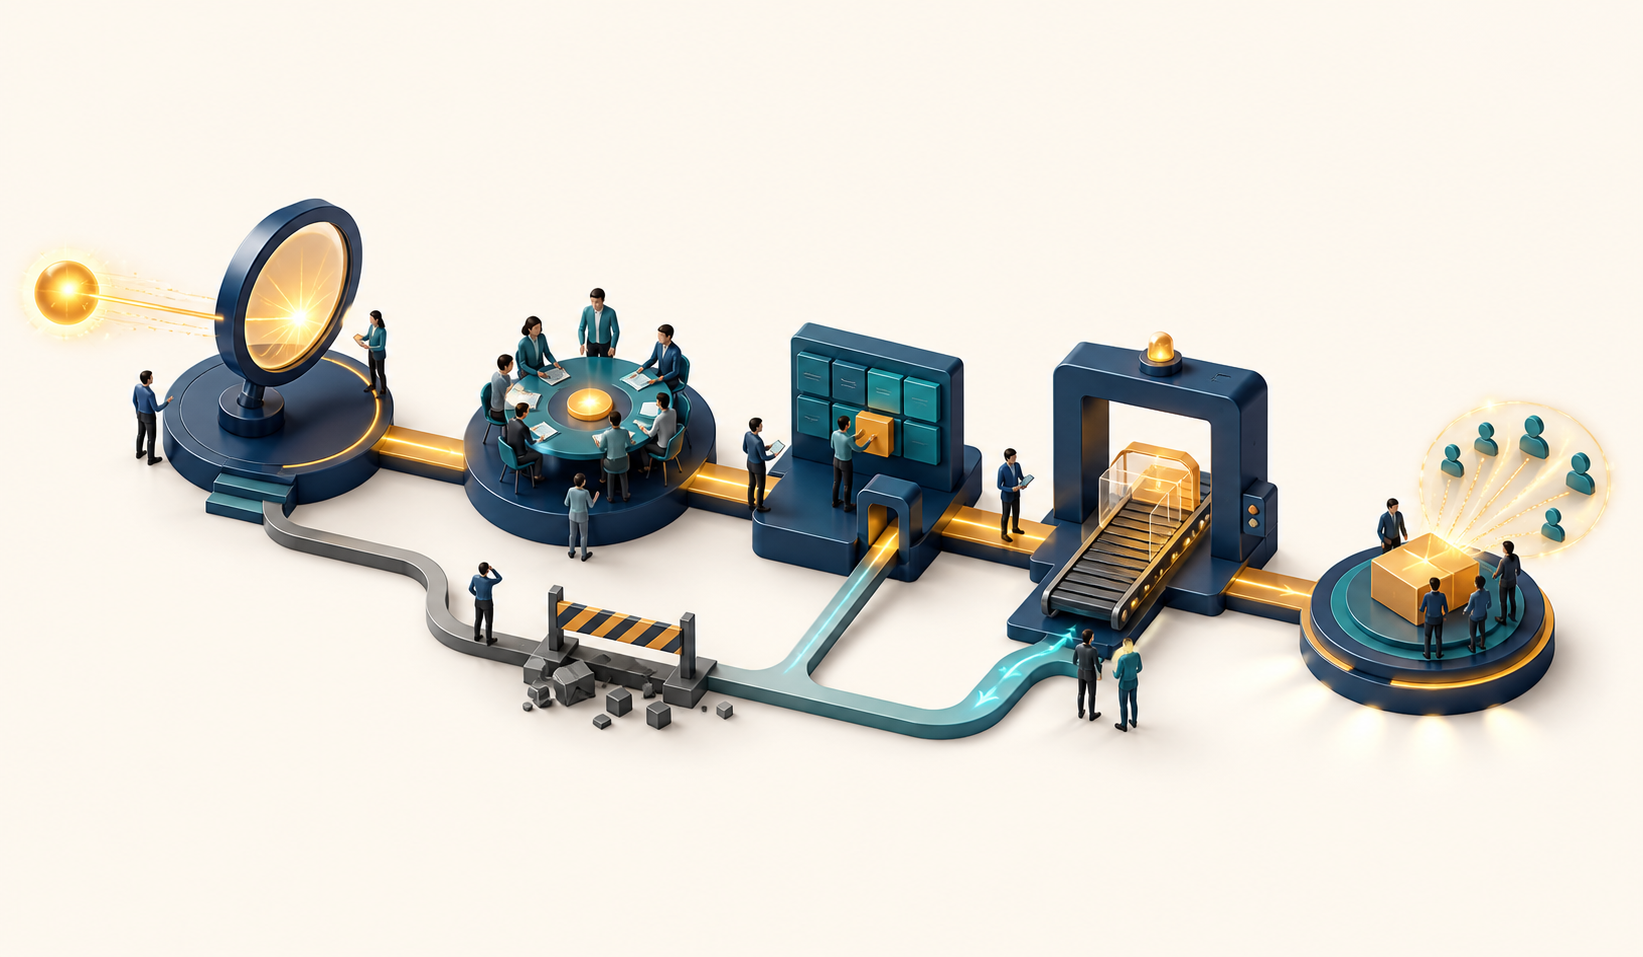
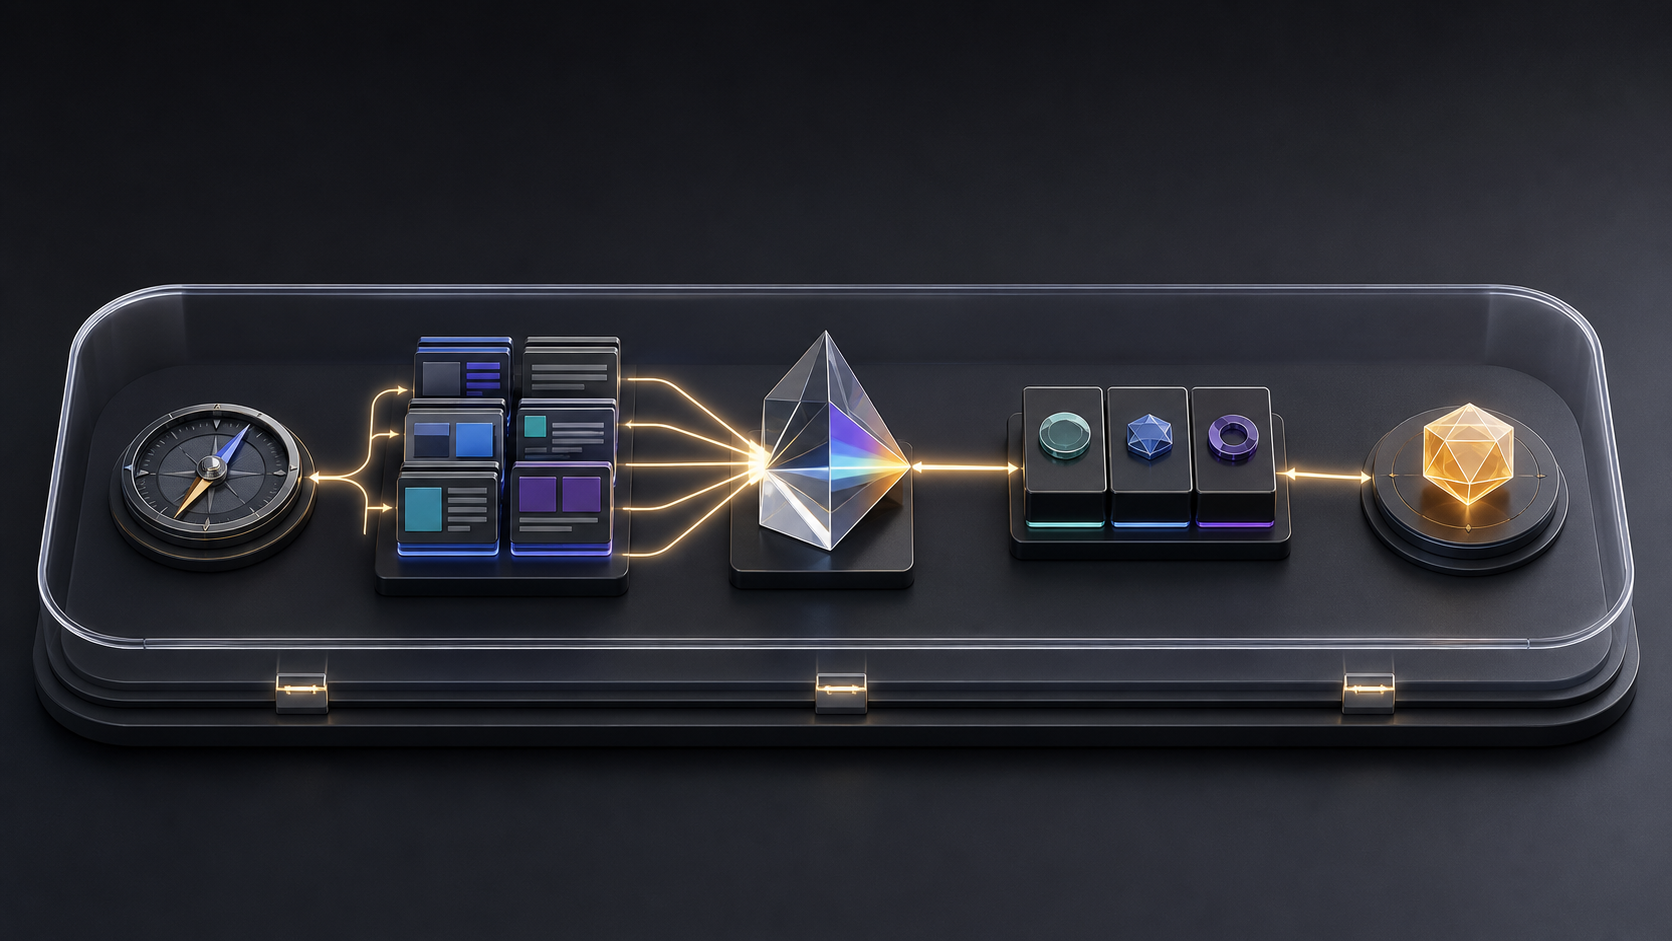
    A glowing signal moves through observation, team decision, work assignment, production, and delivery stages as people coordinate each handoff.

    Many SEO teams have responsibility without control. They can detect a problem and recommend a response, but another team controls the template, product feed, editorial calendar, public statement, development backlog or budget. When the handoff is informal, recommendations wait for goodwill and urgency has to be renegotiated every time.

    Fix that by defining the decision chain before the next issue appears. For every recurring class of work, record the following:

    1. Signal owner: the person responsible for detecting and documenting the issue.
    2. Decision-maker: the person with authority to choose a response and accept its tradeoffs.
    3. Executor: the team that can make the change in the relevant system or channel.
    4. Required evidence: the information needed before the work can be prioritized.
    5. Delivery route: the backlog, editorial workflow or operating process that will carry the work.
    6. Validation owner: the person who checks whether the change shipped correctly and whether the expected effect appeared.
    7. Escalation condition: the circumstance that moves a blocked issue to a leader who can resolve it.

    Separate strategic ownership from execution ownership

    SEO should influence how the organization approaches discoverability across search engines, AI assistants and other relevant platforms. That does not mean the SEO team should pretend it can execute every change. Product teams may own product facts. Communications may own public positioning. Engineering may own rendering and platform behavior. Analytics may own measurement architecture.

    For each issue, make both forms of ownership visible. Strategic ownership answers, “What should change, and why does it matter?” Execution ownership answers, “Who can make the change in the system where it lives?” If only the first answer exists, you have a recommendation queue rather than an operating capability.

    Route work through existing operating systems

    A separate SEO spreadsheet often becomes a parking lot because it sits outside the processes that allocate resources. Put technical work into the engineering backlog, editorial work into the content workflow, product-fact corrections into the product-data process and reputation issues into the communications process. Keep a central SEO register for visibility, but let each change travel through the system that can actually deliver it.

    Consider an AI assistant that repeatedly presents an outdated return condition. The SEO team can capture the affected query pattern and identify the pages or feeds that may be contributing. It should not silently rewrite policy. The policy owner validates the correct fact, content or product-data owners update the canonical information, technical owners confirm that the information is accessible, and the visibility owner checks whether the answer changes. The chain protects accuracy while keeping the response actionable.

    Document common issue classes now: inaccurate entity facts, missing topic coverage, inconsistent brand language, weak product information, technical access barriers, declining search performance and emerging customer questions. Assigning routes in advance removes the ownership debate from the moment when action is needed.

    Use a KPI ladder that connects visibility to business value
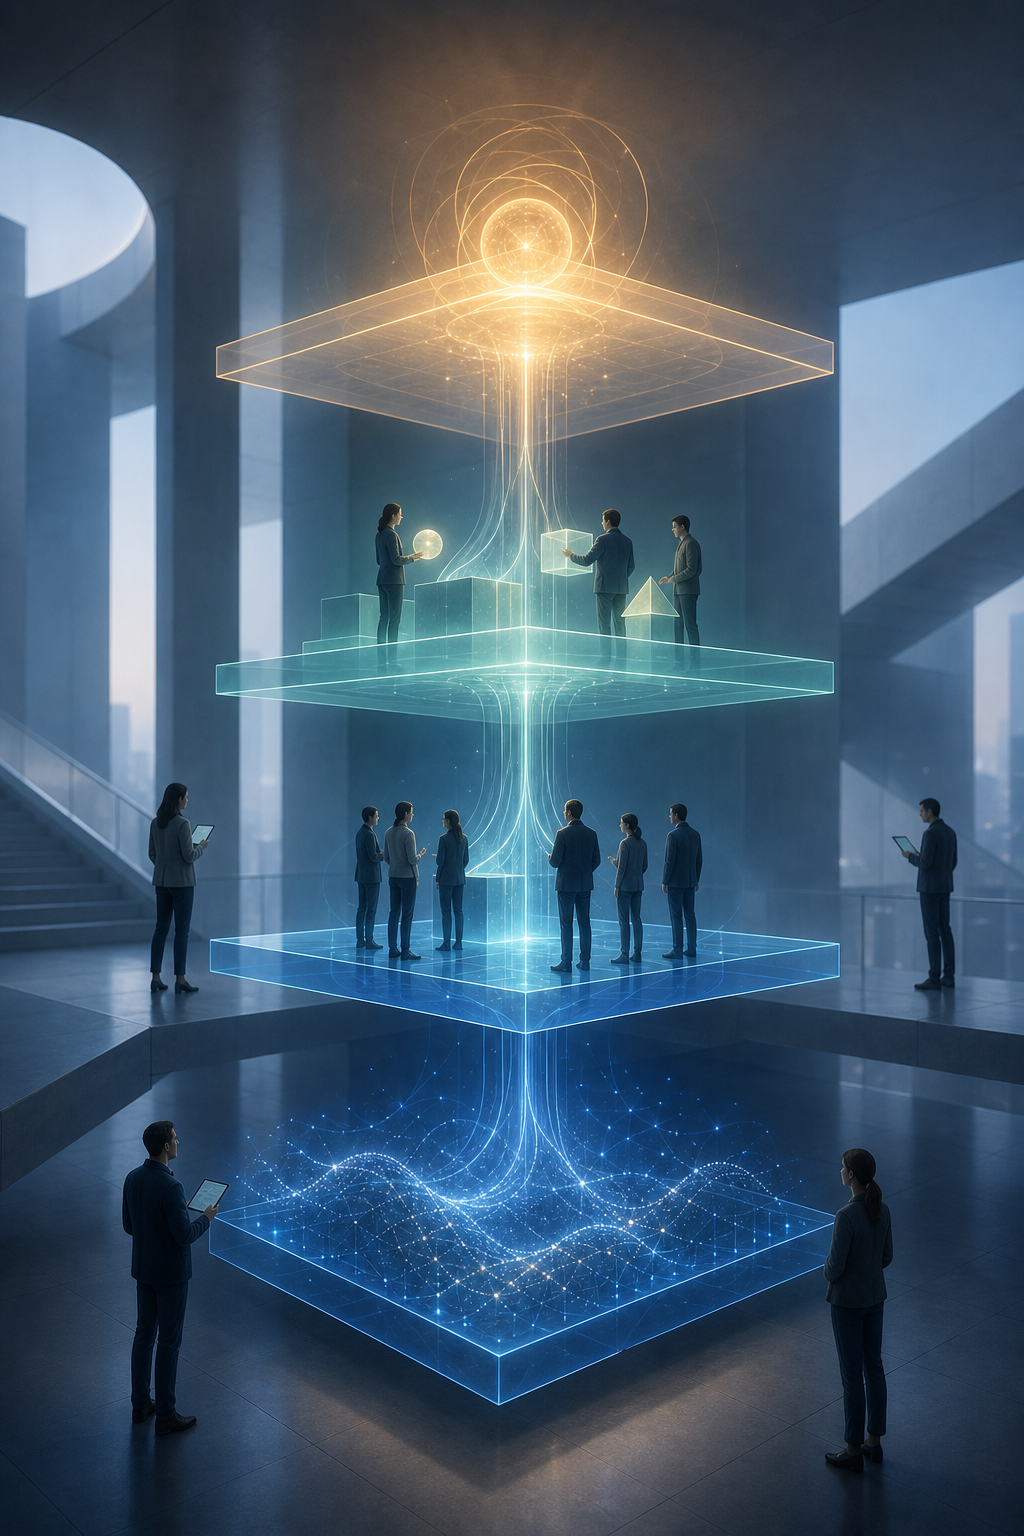
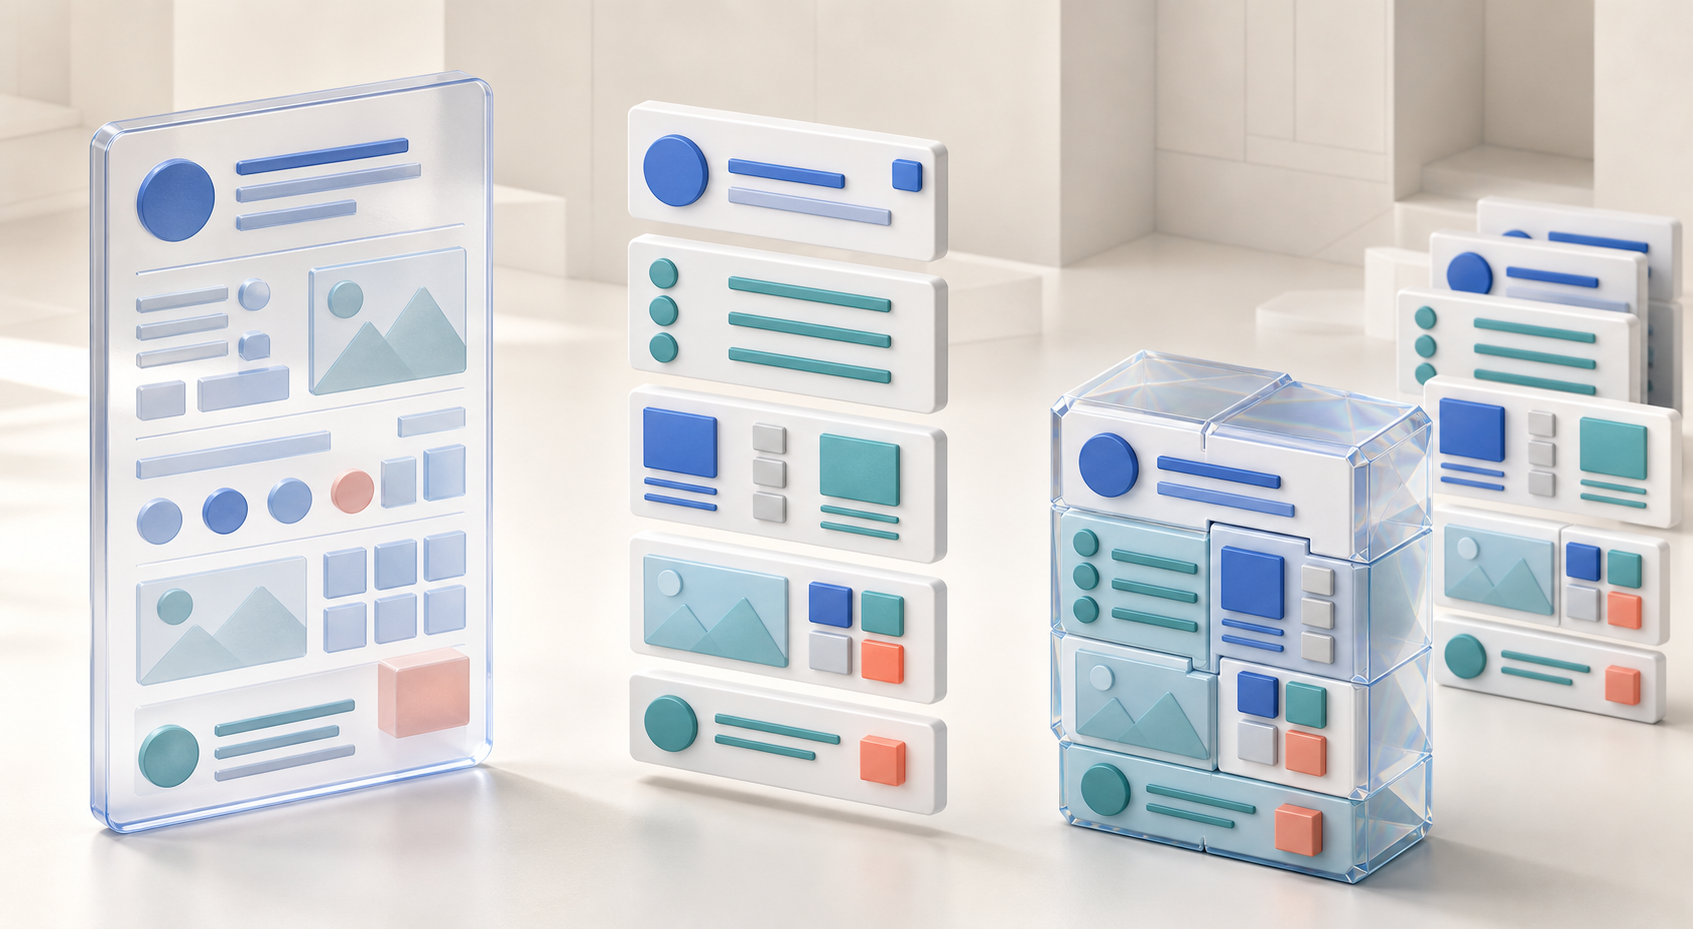
    Connected platforms rise from scattered search signals to audience engagement, customer actions, and a glowing business value core.

    Traffic still tells you something, but it cannot carry the entire strategy. A person may encounter your brand in an AI answer, evaluate alternatives elsewhere and arrive later through a branded query or direct visit. A visibility metric can reveal part of that earlier interaction, but it may still be a proxy rather than proof of commercial influence.

    A useful measurement system does not replace traffic with one fashionable AI score. It creates a ladder from operational activity to visibility, journey behavior and business outcomes:

    • Business outcomes: the commercial or organizational result the strategy is meant to influence, such as qualified demand, completed purchases, adoption or retention.
    • Journey indicators: evidence that the right audience is progressing, such as engagement with decision content, branded discovery, qualified inquiries or assisted conversions.
    • Visibility indicators: whether the organization is discoverable, accurately represented and cited for priority needs across relevant search and AI environments.
    • Operational indicators: whether the organization can respond, including issue ownership, backlog movement, publishing quality and completion of corrective work.

    The ladder matters because each layer answers a different question. Visibility shows whether you are present. Journey evidence shows whether that presence may be drawing the right people forward. Business outcomes show whether the work contributes to something the organization values. Operational indicators show whether the team can repeat and improve the process.

    Give every KPI a decision rule

    A metric without a decision rule becomes reporting theater. Create a metric card containing its definition, business hypothesis, data location, owner, review cadence, known blind spots and action trigger. The action trigger does not need to be an arbitrary numeric threshold. It can be a condition such as “a priority product fact is repeatedly represented inaccurately” or “visibility improves without corresponding movement in qualified demand.”

    Ask these questions during every review:

    • What decision can this metric change?
    • Is it measuring presence, behavior, value or execution?
    • Which part of the customer journey is invisible to us?
    • Could another explanation produce the same movement?
    • What additional evidence would increase our confidence?
    • Who has authority to act on the finding?

    Keep traffic in the system, but use it at the right level. A drop can diagnose lost demand capture, technical trouble or weaker relevance. An increase can reveal broader reach. Neither movement proves business value by itself. Pair it with journey quality and outcome evidence before redirecting budget or declaring success.

    Be equally careful with AI visibility indexes. Coverage differs by tool, prompt set, location, personalization and observation method. Treat a third-party score as one observation layer, not a complete map of customer discovery. Preserve the underlying queries, answer examples, dates and evaluation criteria so the team can inspect what changed instead of debating a single composite number.

    Use AI for throughput, then require human differentiation

    AI can accelerate brief creation, data analysis, clustering, summarization and first drafts. Speed is useful when the organization already has reliable inputs and a clear editorial standard. Without those controls, AI makes generic work easier to produce and harder to distinguish from everything else generated from similar prompts.

    The important question is not whether AI touched the workflow. It is whether the published result contains accurate evidence, a useful decision, a coherent point of view and accountable human judgment. Make those requirements explicit at the brief stage rather than asking an editor to add originality after a generic draft has already defined the structure.

    Require every substantive brief to identify:

    • The reader’s decision: the specific action, concern or tradeoff the page must resolve.
    • The organization’s contribution: facts, expertise, analysis, examples or framing that cannot be obtained by prompting a general model for a generic answer.
    • The evidence boundary: which claims are approved, which need verification and which the organization is not qualified to make.
    • The differentiation test: what would still make the page valuable if several competitors covered the same basic information.
    • The accountable editor: the person who can reject fluent output that lacks accuracy or decision value.
    • The maintenance owner: the person responsible when product facts, policies, interfaces or market conditions change.

    Set rules according to the risk of the task

    Low-risk transformations, such as reorganizing approved material or generating alternative headings, can move quickly. Drafting interpretive claims, recommendations or product comparisons needs closer review. Publishing facts that affect customer decisions should require validation against the organization’s canonical information. The more consequential the claim, the less reasonable it is to treat fluent output as evidence.

    Keep the inputs that make the work distinctive outside the model’s imagination. Supply approved product facts, customer-language findings, subject-matter review and a defined editorial position. If those inputs do not exist, the readiness problem is upstream of prompting. Better prompt syntax will not create institutional knowledge.

    Make structured data downstream of fact governance

    JSON-LD and schema markup can clarify information that is already true and consistently maintained. They cannot repair disagreement between a product database, a policy page, a local listing and sales copy. Before expanding markup, identify the canonical system for each important entity fact, who may change it, which channels consume it and how corrections propagate.

    Audit the visible page and the structured representation together. A technically valid property can still communicate stale or contradictory information. Add validation to the publishing workflow, but also define what happens when the validator passes and the underlying business fact is wrong. Technical ownership and factual ownership are separate controls.

    This is where organizational readiness directly affects AI optimization. Clear entity information, consistent claims and maintained content give search and AI systems less ambiguity to resolve. The work begins with governance and execution; markup is one delivery mechanism within that system.

    Key takeaways for your next planning cycle

    • Audit the path from visibility signal to shipped change, not the size of the SEO toolset.
    • Ask for operational evidence: owners, tickets, decision rules, delivery routes and validation records.
    • Separate strategic ownership from execution ownership so SEO is not held accountable for work it cannot authorize.
    • Use a KPI ladder that connects operational delivery and visibility with customer behavior and business outcomes.
    • Treat traffic and AI visibility scores as evidence layers, not complete measures of value.
    • Use AI to increase throughput only after defining evidence, differentiation and human accountability.
    • Govern canonical business facts before expanding JSON-LD, schema markup or multi-platform distribution.

    In your next planning session, choose one priority customer journey and trace a real issue from detection to resolution. Name the decision-maker, executor, delivery route, success evidence and escalation condition. Wherever the chain becomes hypothetical, you have found the first readiness problem to put on the backlog.

    Do that before adding another dashboard or increasing publishing volume. In 2026, the organizations that gain durable visibility will be the ones that can learn and coordinate faster than their discovery environment changes.

    References


  • How to Build an AI Search Visibility and AEO Strategy

    How to Build an AI Search Visibility and AEO Strategy

    Your search rankings can look stable while your brand disappears from the decision. A buyer can ask an AI assistant to define the problem, assemble a shortlist, compare options, and identify objections before visiting a conventional search result.

    OpenAI has reported that ChatGPT surpassed 900 million weekly active users. That scale makes answer engines a discovery environment, not merely a different interface for search. Your job is no longer limited to earning a blue-link click. You need to make your brand understandable, retrievable, citable, and appropriate to recommend.

    Key takeaways

    • Choose the questions and decisions for which your brand has a credible right to appear. Broad visibility without decision relevance is mostly noise.
    • Treat brand mentions and URL citations as separate outcomes. Mentions build consideration; citations show that your material supplied part of the answer.
    • Build self-contained answer units with a clear scope, direct answer, evidence, limitations, and a useful next step.
    • Use taxonomy, internal links, and accurate schema to reinforce the same entities and relationships expressed in the visible content.
    • Measure AI visibility with a fixed prompt set, then connect the observations to branded search, qualified landing-page visits, and conversions.

    Define the answer you want your brand to own

    Do not start by asking, “How do we rank in ChatGPT?” That question is too broad to guide a page, an editorial calendar, or a measurement plan. Start with the decision your customer is trying to make and the conditions that change the right answer.

    An AI response can produce several materially different outcomes for your business. It can name your brand without linking to you, cite your page without recommending the brand, do both, or omit you entirely. Brand mentions and LLM citations are distinct forms of visibility, so each needs its own strategy and metric.

    • A mention is useful when your goal is to enter a shortlist or become associated with a product category, use case, or audience.
    • A citation is useful when you publish facts, definitions, methods, comparisons, or original information that an answer can reuse.
    • A mention plus a citation is strongest when the cited evidence directly supports the reason the brand was included.
    • An appearance in an irrelevant answer is not a win. It can create the wrong expectation and send poorly qualified visitors to the site.

    Build a query-to-answer map before you change any content. For every important customer decision, record the following:

    1. Audience: Who is asking? Include the role, level of knowledge, or use case that materially changes the answer.
    2. Decision: What are they choosing, rejecting, verifying, or trying to accomplish?
    3. Constraints: Note compatibility, location, budget class, risk, scale, physical requirements, or other conditions that narrow the valid choices.
    4. Evidence needed: Identify the facts a careful buyer would need before trusting the answer.
    5. Desired visibility: Decide whether you want a brand mention, a citation, or both.
    6. Best destination: Select the page that can satisfy the next step without forcing the visitor to restart the search.

    Consider the query “waterproof hiking boots for wide feet.” A generic hiking-boots category page matches some keywords, but it does not resolve the decision. A useful answer needs to define what “wide” means for the available products, distinguish waterproof construction from water resistance, explain relevant fit limitations, and lead to products that actually meet those conditions. That is the difference between topical proximity and answer eligibility.

    Prioritize questions where you can substantiate the answer. If your only support is a marketing adjective such as “leading,” “easy,” or “best,” you do not yet have an answer-engine asset. You have a claim that a retrieval system has little reason to trust or repeat.

    A published Google patent outlines a possible system that could generate organization-specific landing pages tailored to a user’s query. A patent is not a product announcement and may never become a search feature. The useful strategic signal is narrower: generic destination pages are vulnerable when they make a machine or a person perform too much work to connect the query, the entity, and the relevant offer. Make those relationships explicit on your own site now.

    Build pages from retrievable answer units

    A blank page-like slab separates into modular information blocks while selected blocks rise toward a translucent lens.

    Give every answer unit enough context to stand alone

    AI retrieval does not always treat a page as one indivisible object. Content can be segmented into chunks and evaluated against the user’s intent. That makes the section beneath a heading an important unit of work. Semantic depth and retrievable structure matter alongside keywords.

    A strong answer unit contains these elements:

    • Scope: Name the exact question, audience, product, process, or condition being addressed.
    • Direct answer: Resolve the main question early instead of delaying the answer behind a long introduction.
    • Reasoning or evidence: Explain why the answer holds and identify the facts that support it.
    • Boundaries: State the conditions under which the answer changes, does not apply, or needs qualification.
    • Next step: Link to the comparison, product, calculator, documentation, or action that logically follows.

    Use a simple extraction test during editing. Read the heading and its section without the page title or preceding paragraphs. If you encounter vague phrases such as “this solution,” “these benefits,” or “it depends” without enough local context to identify the subject and conditions, revise the section. The goal is not to repeat the entire page. It is to remove dependencies that make the passage ambiguous when retrieved on its own.

    Do the same test on tables, captions, comparison criteria, and FAQ answers. A technically correct fragment can still be unusable if its unit, timeframe, product version, geography, or comparison basis is missing.

    Increase context density without inflating word count

    Context density is not a request to make every page longer. It means that each section contributes a distinct piece of meaning around the primary topic. A useful contextual field includes the main entity, supporting concepts, user intent, relevant constraints, natural language variants, and relationships to other entities.

    • Use the primary topic as the page’s axis, not as a phrase that must be repeated mechanically.
    • Add secondary concepts only when they define a criterion, answer a real question, introduce evidence, or establish a necessary relationship.
    • Use the terms your audience uses, including legitimate variants, but do not create near-duplicate paragraphs to accommodate every phrasing.
    • Name entities precisely. Distinguish a company from its product, a product family from a model, and a feature from the outcome it may support.
    • Place qualifications beside the claim they constrain. Do not hide a critical exception in an unrelated section near the bottom of the page.

    A decision-oriented page will often need a direct answer, definitions, evaluation criteria, evidence, limitations, comparisons, and a next action. It does not need a ceremonial history lesson unless that history changes the decision. Precision is more useful than reaching an arbitrary word count.

    Make architecture and schema confirm the same meaning

    A good paragraph can be weakened by a site that sends contradictory signals. Taxonomy, internal links, canonical destinations, visible labels, and structured data should agree about what the page represents and how it relates to the rest of the site. Internal linking, taxonomy, and schema provide structural and entity context; they are not merely housekeeping.

    • Taxonomy: Group content by meaningful subjects and entities, not by every keyword variation. A category should help a visitor predict what belongs inside it.
    • Internal links: Link from explanatory content to the most relevant decision or product page. Use anchor text that describes the relationship rather than generic instructions such as “click here.”
    • Canonical destinations: Choose a clear primary page when several URLs compete to explain the same entity or intent.
    • JSON-LD: Use the most specific applicable schema type and describe the same organization, article, product, offer, or other entity that appears in the visible page.
    • Entity consistency: Keep names, URLs, product identifiers, authorship, and organizational relationships consistent wherever they are declared.
    • Validation: Check the deployed markup for syntax errors, missing required values, and discrepancies between structured data and visible content.

    Schema does not force an answer engine to mention or cite you. Its role is clarification. It reduces ambiguity about entity type, ownership, attributes, and relationships. Marking up a claim that the page cannot support does not create authority; it only expresses the unsupported claim more formally.

    Create evidence worth reusing and corroborating

    Answer engines need material they can use, not just language that says your company is good. Your content becomes more citable when it contributes information gain: original data, precise specifications, a transparent method, a clear definition, a useful comparison, or a well-supported explanation. Unique information creates a stronger opportunity for URL citations.

    Create a claim ledger for every commercially important page. For each claim, record the exact wording, the evidence that supports it, the page where that evidence is visible, the conditions or limitations, and the person responsible for keeping it current. This exposes a common content problem: a claim may appear throughout the site while its proof exists nowhere a reader can inspect.

    • Product and service facts: Publish exact attributes, compatibility, requirements, inclusions, exclusions, and operating conditions where they affect suitability.
    • Decision evidence: Explain the criteria a buyer should use and why those criteria matter.
    • Methods: When you publish an evaluation, test, survey, or benchmark, state how it was produced and what its limitations are.
    • Definitions: Define specialized terms before using them to support a commercial conclusion.
    • Limitations: Say who should not choose the option, where it does not fit, or which assumptions would change the recommendation.
    • Maintenance signals: Show when time-sensitive facts were reviewed and update or remove claims that can no longer be verified.

    For an ecommerce business, this work connects discovery to revenue. A useful product answer does more than repeat a product name. It connects the shopper’s constraint to verifiable attributes, explains the tradeoff, and leads to a suitable product or category. That is how answer-engine visibility can support trust and purchase consideration rather than producing an empty impression.

    Your website is only part of the entity environment. Relevant review platforms, professional communities, trade coverage, and other independent contexts can reinforce what your brand is known for. Consistent presence in the places your audience actually uses can support brand recognition and recommendation visibility. It also gives you an external consistency check: if independent descriptions of the brand differ sharply from your preferred positioning, the market may not understand the category or use case you are trying to own.

    Do not manufacture reviews, seed disguised endorsements, or flood communities with repetitive promotional copy. Besides the reputational risk, artificial repetition is weak evidence. Contribute useful explanations, accurate product information, expert participation, and material that other people have a legitimate reason to reference.

    Measure the dark funnel and improve the next cycle

    A buyer silhouette travels through a dark branching information tunnel toward a brightly lit group of product objects, with glowing observation points along the route.

    AI discovery can happen before any observable visit to your site. A person may encounter the brand in an answer, search for the brand later, and convert through a channel that receives all the credit. This ingestion-to-recommendation-to-verification path is difficult to reconstruct with conventional analytics. Traffic remains useful, but it cannot fully describe AI visibility.

    Create a repeatable prompt-monitoring set

    1. Select prompts from the query-to-answer map, including discovery, comparison, suitability, objection, and verification questions that matter to the business.
    2. Preserve the exact prompt wording. A rewritten prompt is a new observation, not a clean continuation of the old one.
    3. Run the set on a consistent schedule and record the answer engine, model or mode when visible, date, account state, and location when those variables may affect the result.
    4. Capture the complete answer. Record whether the brand appeared, how it was described, which URLs were cited, where the brand appeared in the response, and which competitors or alternatives were included.
    5. Annotate meaningful changes to content, schema, internal links, product information, digital PR, and third-party coverage.
    6. Compare repeated observations without treating a single changed response as proof that your intervention caused the change.

    Keep the reporting layers separate. Combining everything into a single AI visibility score can conceal the exact failure you need to fix.

    • Prompt coverage: The share of tracked, relevant prompts in which the brand appears.
    • Citation coverage: The share of tracked prompts that cite an owned URL.
    • Answer fit: Whether the brand appears for the intended audience, constraint, and use case rather than in a generic or inaccurate context.
    • Evidence reuse: Which claims, definitions, data points, or pages recur across answers.
    • Competitor context: Which entities appear beside your brand and which stated criteria seem to drive their inclusion.
    • Verification behavior: Changes in branded search, direct visits, visits to named product or service pages, and other signals that people may be checking an AI-assisted decision.
    • Business outcomes: Qualified leads, purchases, conversion rate, and revenue from the destinations most closely connected to the tracked decisions.

    Use the following combinations as working diagnoses, not as proof of how a model reached its answer:

    Observed resultWorking interpretationNext check
    Brand mentioned, owned URL not citedThe entity may be recognized, but your site is not supplying the reusable evidence.Inspect whether the relevant claim has a precise, indexable evidence page and a clear relationship to the brand.
    Owned URL cited, brand not recommendedThe content may be useful while the commercial entity remains weakly associated with the use case.Strengthen entity relationships, brand attribution, relevant internal links, and independent corroboration.
    Brand mentioned and URL citedThe answer connects the entity with evidence, but commercial value is not guaranteed.Check answer accuracy, destination relevance, qualified visits, and conversion behavior.
    Neither mention nor citationThe gap may involve relevance, retrieval, indexing, insufficient evidence, or a query the brand cannot credibly satisfy.Verify technical accessibility, intent alignment, answer-unit clarity, and the strength of the underlying claim.

    Turn the findings into a publishing cycle

    1. Establish the prompt and analytics baseline before making changes.
    2. Choose a commercially meaningful decision where the brand has credible evidence but weak mention or citation visibility.
    3. Audit the relevant page for answer completeness, extractable context, claim support, internal links, and accurate schema.
    4. Fill the evidence gap. Add facts, methodology, qualifications, comparisons, or product attributes that a careful answer would need.
    5. Align related pages and entity declarations so they reinforce rather than compete with the primary destination.
    6. Earn legitimate independent visibility in the communities, review environments, and publications relevant to that decision.
    7. Repeat the prompt set, inspect the resulting patterns, and compare them with branded demand, qualified visits, and business outcomes.

    Start with the customer decision closest to qualified demand. Make its answer explicit, make its evidence inspectable, and make the underlying entities consistent across content, links, and schema. Then measure whether answer engines begin to retrieve the page, cite the evidence, and place the brand in the right consideration set. That is a strategy you can improve, even when the full journey remains hidden.

    References

  • Profound’s $96M Series C: What AI Marketers Should Watch

    Profound’s $96M Series C: What AI Marketers Should Watch

    If you lead AI search, SEO, content, or marketing technology, Profound’s funding can create immediate pressure. Is the company now the category winner? Is your team late? Should you add another platform to your stack? The financing matters, but none of those conclusions follows automatically.

    Profound announced a $96 million Series C at a $1 billion valuation, led by Lightspeed Venture Partners with participation from Sequoia Capital, Kleiner Perkins, Evantic, Saga, and South Park Commons. For you, the useful question is what that event changes about AI marketing, vendor selection, and the way you measure visibility in generative answers.

    Read the round correctly before changing your strategy

    A funding round is evidence that investors were willing to finance a company on negotiated terms. It is not a product certification, an independent performance test, or proof that customers are receiving a positive return.

    The distinction matters because the headline contains several figures that are easy to misread. The $96 million is financing, not revenue. The $1 billion valuation is the value assigned to the company in the context of the transaction, not cash deposited into its accounts. Neither figure tells you how much customers spend, whether the business is profitable, how well its software performs, or how the new capital will be allocated.

    Series C also describes a financing stage, not a universal level of product maturity. It can support expansion after earlier growth, but the label does not guarantee stable data, complete model coverage, enterprise-ready controls, or a roadmap that matches your needs.

    • What the round establishes: Profound has attracted substantial private backing for an AI marketing platform.
    • What it reasonably signals: the participating investors see enough potential to finance further growth at the announced valuation.
    • What it does not establish: that Profound is the right platform for your use case, that AI visibility software has settled on a standard methodology, or that a large valuation predicts your results.

    That last point should shape your response. Do not rewrite your AI strategy around a financing headline. Use the event as a reason to update your assumptions, inspect the category, and ask vendors harder questions.

    Where fresh capital could change the AI marketing market

    Golden light branches from a central reservoir toward abstract product, infrastructure, expansion, and support structures, with some paths fading into mist.

    Capital gives Profound more options. It could fund product development, infrastructure, model and market coverage, integrations, hiring, customer support, or go-to-market expansion. Those are possibilities, not disclosed commitments. Treat them as items to verify through shipped capabilities, release records, service levels, and written commercial terms.

    The broader signal is that investors are willing to place significant capital behind the problem of marketing through AI-generated answers. That is relevant if you have been treating AI visibility as a temporary reporting experiment. It suggests that the category may attract more product development, sales activity, and competition. One transaction, however, does not establish the size of customer demand or prove that AI search has replaced conventional search.

    Your operating model should therefore connect AI visibility to the rest of search and content work instead of building an isolated dashboard. A useful workflow has four linked jobs:

    • Observe: identify where your brand, products, experts, and pages appear or disappear in relevant AI answers.
    • Diagnose: determine whether the issue involves ambiguous entities, missing evidence, inaccessible content, inconsistent facts, weak third-party corroboration, or an irrelevant prompt sample.
    • Intervene: improve the assets you control, including factual copy, source pages, technical accessibility, appropriate structured data, and evidence that other publishers can verify.
    • Validate: repeat the measurement, inspect the underlying answers and citations, and connect any change to a business decision rather than celebrating a score in isolation.

    A platform that performs only the observation step may still be useful, but it has not completed the marketing job. The value appears when your team can trace a detected issue to a defensible action and then check whether that action changed anything meaningful.

    Use a buyer’s scorecard, not the valuation

    If you are evaluating Profound or another AI visibility platform, apply the same scorecard to every vendor. This prevents brand momentum, investor names, and polished aggregate scores from substituting for evidence.

    Start with measurement integrity. Ask which AI models and user experiences are covered, which markets and languages are supported, and whether the results represent live answers, an external data provider, or another collection method. Model output can vary with prompt wording, model version, user context, and repeated runs. You need to know how the platform handles that variability before treating movement as a trend.

    • How are prompts selected, grouped, weighted, and updated?
    • Can you inspect the exact prompt, answer, cited pages, collection time, and relevant execution context behind every score?
    • Does the system distinguish a brand mention from a recommendation, a citation, a comparison, or a factual statement?
    • How does it prevent changes in prompt coverage from looking like changes in brand performance?
    • Can you preserve a stable benchmark while separately exploring new prompts and models?
    • How are failed collections, unavailable models, duplicate answers, and ambiguous brand names handled?

    A visibility score that cannot be decomposed is difficult to act on. If the score rises, you should be able to see which answers changed and why. If it falls, you should be able to distinguish a real deterioration from a collection or coverage change.

    Then test actionability. Ask the vendor to walk from a detected problem to a recommended intervention using your own data. A useful recommendation identifies the affected audience, the evidence behind the diagnosis, the asset or relationship that needs work, the owner who can act, and the signal that would count as improvement.

    • Does the platform separate issues on your website from gaps in third-party authority?
    • Can recommendations point to the exact pages, claims, citations, or entity conflicts involved?
    • Does it explain where structured data is relevant without presenting schema as a guarantee of inclusion in an AI answer?
    • Can findings flow into the content, SEO, analytics, public relations, and product workflows your team already uses?
    • Can analysts annotate changes so later reporting does not confuse an intentional intervention with unexplained movement?

    Finish with commercial and operational resilience. Funding may improve a vendor’s capacity to invest, but it does not remove switching costs or contractual risk. Get data ownership, export access, retention, usage limits, overage rules, support scope, renewal terms, and the total expected cost in writing. Confirm what happens to your historical data if you leave. Treat roadmap slides as possibilities until a capability is included in the agreement or available in the product.

    Run a controlled evaluation around a real decision

    An evaluator compares two unbranded AI systems in parallel testing bays using identical inputs and a central balance mechanism.

    The cleanest way to evaluate an AI marketing platform is to make it answer a decision your team already faces. Do not begin with, “Can this produce an interesting dashboard?” Begin with a question such as, “Can this show us why qualified buyers encounter competitors instead of us, and can it help us choose what to change?”

    1. Define the decision. Name the audience, product or service, market, and business question. Decide who will act if the platform finds a credible problem.
    2. Create a representative prompt set. Include branded and unbranded questions from different stages of the buying journey. Write down why each prompt matters. Keep the core set stable so a changing sample does not masquerade as performance movement.
    3. Capture a manual baseline. Save the exact prompts, visible answers, citations, model or surface, and relevant context. Note entity ambiguity and obvious collection errors before introducing a vendor score.
    4. Run the platform against the same scope. Compare its output with the baseline. Investigate disagreements rather than assuming the platform or the manual sample is automatically correct.
    5. Act on findings you can verify. Correct inconsistent facts, strengthen useful first-party pages, improve crawlability, add appropriate structured data, and pursue credible third-party coverage where the diagnosis supports those actions.
    6. Judge decision value. Ask whether the platform found important issues accurately, explained them clearly, helped the right owner act, preserved evidence, and made follow-up measurement more reliable.

    Keep AI visibility metrics in their proper place. Mentions, citations, answer share, and sentiment can be useful intermediate signals, but they are not automatically revenue or causation. If a dashboard improves after you change content, inspect the underlying answers. If business outcomes also change, examine other campaigns, seasonality, brand activity, and measurement gaps before assigning credit.

    Be equally cautious with promises of fixed placement. Generative answers are not conventional ranking tables, and their behavior can change. A credible evaluation should show variability, preserve raw evidence, and describe uncertainty instead of hiding it inside a single precise-looking number.

    Key takeaways

    • Profound announced a $96 million Series C and a $1 billion valuation, with Lightspeed Venture Partners leading the round.
    • The financing signals investor conviction and gives the company more strategic options; it does not prove product performance, revenue, profitability, or customer return.
    • For AI marketers, the round is a reason to take the category seriously, not a reason to replace a working stack without evaluation.
    • A useful AI visibility platform must expose prompts, answers, citations, collection context, and methodology behind its scores.
    • Your evaluation should connect observation to diagnosis, intervention, and validation using a stable prompt set and a manually checked baseline.
    • Commercial diligence still matters: verify exports, data ownership, limits, support, renewal terms, switching costs, and delivered capabilities before making a long-term commitment.

    Treat Profound’s funding as a prompt to sharpen your vendor questions, not to change strategy overnight. Preserve your baseline, test the platform against a decision that matters, and commit only when its data survives manual inspection and fits the way your team acts. That lets you benefit from a better-funded category without outsourcing your judgment to its valuation.

    References

  • AI Search Visibility Strategy: Build the System Behind It

    Your brand can rank well, publish strong content, and still appear inconsistently in AI answers. The usual weak point is not a missing optimization trick. It is the gap between product data, page copy, schema, PR language, and local information. When those inputs disagree, AI systems have to assemble an uncertain version of your brand.

    You need an operating system for visibility: one controlled fact layer, a publishing pipeline that catches contradictions, equivalent human and machine representations, and a repeatable way to measure what AI systems actually say. Build that foundation before you optimize individual pages or chase whichever AI platform is attracting attention.

    Choose the decisions you need to influence, not a favorite engine

    ChatGPT, Google AI Overviews, Perplexity, and Bing do not present information in identical ways. Their interfaces, answer formats, and potential value to a brand differ, so platform prioritization should follow your business objective. It should not define your underlying information architecture.

    Start by building a query portfolio. This is a controlled set of questions representing the decisions you want to influence. It gives content, SEO, product, and PR teams a shared target that is more useful than a broad instruction to improve AI visibility.

    1. Entity identification: Questions asking what your company, product, service, or expert is. These expose naming, category, and relationship problems.
    2. Category discovery: Questions asking which options fit a need. These show whether the brand is associated with the right problem and audience.
    3. Comparison: Questions asking how alternatives differ. These test whether your differentiators are specific, supported, and easy to retrieve.
    4. Verification: Questions about specifications, policies, locations, availability, qualifications, or other concrete facts. These are where stale or contradictory information becomes especially visible.
    5. Action: Questions asked immediately before a visit, signup, inquiry, or purchase. These reveal whether AI answers can connect a recommendation to a useful destination.

    For every query, record the audience intent, facts a correct answer must contain, the preferred evidence URL, acceptable variations in wording, and conditions that would make the answer wrong. A mention is not automatically a success. A brand can be mentioned in the wrong category, cited with an unsupported claim, or recommended to an unsuitable audience.

    Run the same portfolio across the platforms relevant to your audience. Keep the prompts stable long enough to identify patterns. If you change the questions, grading rules, and target platforms simultaneously, you cannot tell whether visibility improved or the test simply became easier.

    Build a canonical fact layer before producing more content

    Your website should not be the place where every team independently decides what is true. Establish an entity registry that controls the facts reused across pages, structured data, press materials, partner profiles, sales documents, and local properties. Consistent entities, narratives, and mentions give AI systems a more coherent set of signals.

    Create one record for each important company, product, service, location, person, and named methodology. A useful record includes:

    • Identity: Preferred name, approved aliases, category, parent organization, and relationships to other entities.
    • Core assertions: The facts that must remain stable, such as what the entity does, who it serves, and which features or qualifications can be claimed.
    • Evidence: The canonical page and any approved supporting URLs for each material assertion.
    • Scope: Geographic, product-version, audience, or time limitations that prevent a qualified fact from becoming an unqualified claim.
    • Ownership: The person or team allowed to approve a change, plus the date on which the record was last verified.
    • Distribution: The templates, schema fields, feeds, profiles, and communications that consume the record.

    Keep facts separate from expression. Your product page, comparison page, press release, and local landing page do not need identical sentences. They do need to agree on names, relationships, capabilities, qualifiers, and evidence. This lets writers adapt the message without quietly creating a second version of the truth.

    Infrastructure layerWhat it controlsRelease control
    Entity registryNames, relationships, approved facts, qualifiers, and evidenceA named data owner approves material changes
    Canonical pagesThe visible explanation and primary evidence for each entityEditors reconcile copy with the registry before publication
    Structured dataMachine-readable facts and relationships already supported by the pageTemplates validate and values match visible content
    External and local distributionPR terminology, profiles, partner descriptions, and regional factsBriefs inherit approved language and preserve local qualifiers
    Evaluation logPrompts, answers, citations, errors, and changes over timeTests use a stable query set and written grading rules

    Do not use schema to introduce a claim that the visible page does not support. Structured data should clarify the page, not act as a hidden correction layer. When copy and markup conflict, fix the fact at its owner and update every dependent surface. Patching only the schema leaves the contradiction in circulation.

    Put every important asset through five visibility gates

    A content calendar controls when material is published. A visibility pipeline controls whether it is ready to become evidence. The practical mechanism is a series of nonnegotiable gates for parsing, entity consistency, retrieval, authority, and localization.

    1. Technical parsing gate: Confirm that the canonical URL, response, crawl controls, rendered content, and schema.org markup behave as intended. Block release when markup is invalid, a value required by your template is empty, or structured data disagrees with the page. Validate the appropriate Product, Review, FAQ, organization, person, or other supported types where they accurately describe the content.
    2. Brand signal gate: Compare names, categories, relationships, and core claims with the entity registry. Block release when an unapproved alias changes the entity’s meaning, a press message introduces a different category, or a differentiator cannot be connected to evidence.
    3. Accessibility and retrieval gate: Make each important passage understandable when retrieved without the rest of the page. Lead with the answer, use descriptive headings, name the entity instead of relying on vague pronouns, attach units and qualifiers to numbers, and keep evidence near the claim it supports. Block release when the main answer depends on a heading, footnote, image, or previous paragraph that a retrieval system may not capture with it.
    4. Authority and de-duplication gate: Identify the primary URL for the topic and compare it with existing assets. Block release when two pages give conflicting answers or when a new page merely creates another candidate authority. Decide whether to update the canonical page, narrow the new page to a distinct intent, or reconcile the conflict before publishing.
    5. Localization gate: Verify which facts are global and which vary by market. Block release when a regional page inherits an unsupported global claim or omits a location, currency, availability, policy, or language qualifier that changes the answer.

    Put these checks inside the CMS workflow or the ticket system your teams already use. Each gate needs three fields: pass or fail, evidence, and an owner for remediation. A checkbox without evidence becomes ceremonial; a failed check without an owner becomes permanent backlog.

    Apply the full pipeline first to your highest-value entity templates rather than every URL at once. Product, service, location, and expert pages are good candidates because a template-level correction can improve many assets while keeping their facts aligned.

    Do not create a machine-only version of reality

    Machine-friendly delivery can reduce parsing overhead, but it does not excuse content divergence. Cloudflare’s Markdown for Agents illustrates the distinction. When a client requests Accept: text/markdown, the feature can fetch the origin HTML, convert it at the edge, return Markdown, and include both Vary: accept and a token estimate. Cloudflare claims the converted representation can reduce token use by up to 80% compared with HTML. That is a vendor-supplied maximum, not a guaranteed result for every page.

    The strategic risk is not Markdown itself. The risk appears when an origin server recognizes the Markdown request and returns different facts, altered product data, hidden instructions, or richer claims than a person sees. The same URL then has two candidate representations of reality, and every consuming system must trust one, compare them, or ignore the alternate version.

    Google and Microsoft representatives have also advised against maintaining separate Markdown pages solely for large language models. AI systems already parse normal web pages, and a second machine-only page creates another surface that can become stale or inconsistent.

    If you introduce content negotiation or another alternate representation, use these controls:

    • Fix the HTML first. If the page is too cluttered or ambiguous to transform reliably, improve its structure rather than treating Markdown as a repair layer.
    • Generate, do not rewrite. Derive the machine-friendly response from the same approved human-facing content. Do not maintain a separate set of claims.
    • Prevent origin-level branching. If the origin does not need to know that Markdown was requested, normalize or strip the signal before it reaches templates that could vary the content.
    • Separate caches correctly. Preserve the relevant Vary behavior so HTML and Markdown responses are not served to the wrong request.
    • Test semantic parity. Compare names, claims, numbers, qualifiers, links, tables, labels, and disclosures after conversion. A raw text diff is less useful than checking whether both representations support the same conclusions.
    • Inspect context loss. Markdown can flatten visual relationships. Review tables, captions, comparison layouts, footnotes, and nearby disclaimers to ensure a converted passage does not become misleading.
    • Keep the feature reversible. Monitor errors and maintain a quick way to disable the alternate response if parity fails.

    Treat Markdown as a transport optimization. It may make approved information cheaper to process, but it should never become a private channel for information you are unwilling to show users.

    Operate AI visibility with owners, metrics, and a 90-day rollout

    A visibility system without ownership becomes another audit document. The operating model needs both a technical architect and a cross-functional advocate, even when one person covers both roles in a smaller organization.

    • The technical owner is accountable for rendering, schema, crawl accessibility, content transformations, evaluation tooling, and the technical gates.
    • The visibility owner aligns product, content, PR, localization, and leadership around approved entities, shared targets, and remediation priorities.

    Do not assign AI visibility to SEO while allowing every other team to alter the inputs independently. Give product, PR, content, and localization teams shared objectives tied to the gates they control. Otherwise, SEO will keep detecting contradictions after publication instead of preventing them.

    Separate input quality from observed AI outcomes

    Your dashboard should show whether the information supply chain is healthy and whether external systems are interpreting it as intended. Keep those two classes of measurement separate.

    Leading indicators should include schema validation status on priority templates, unresolved conflicts between canonical facts and published pages, gate pass rates for new assets, unverified entity records, and localization exceptions. These metrics tell you whether the organization is producing clean inputs.

    Outcome indicators should include brand mentions for eligible queries, citations to approved evidence pages, factual accuracy, sentiment where it can be graded with a written rubric, AI-referred visits, and conversions from those visits. These metrics tell you what happened after the information entered the wider ecosystem.

    Define Share of Model internally before putting it on an executive dashboard. One defensible definition is the number of eligible tested answers that mention the brand divided by the total number of eligible answers in a fixed query portfolio. Define supported citation rate separately as the share of checked citations that genuinely support the associated claim. Do not blend the two: being mentioned and being used as evidence are different outcomes.

    For every test, retain the prompt, platform, date, answer, cited URLs, and grading decision. Use the same rubric on each run. AI answers can vary, so treat an individual response as an observation rather than a trend. Repeated tests with a stable denominator are what make changes interpretable.

    A practical first 90 days

    The first rollout should prove the operating model on a limited set of important entities. A three-phase audit, infrastructure, and accountability sequence keeps the work concrete.

    1. Days 1-30: Audit. Select the entities most connected to revenue, reputation, or customer decisions. Build the initial query portfolio, map every material claim to its current URLs, inspect schema and external descriptions, and log contradictions. Assign an owner to each disputed fact before rewriting content.
    2. Days 31-60: Infrastructure. Create the entity registry, add the five gates to your publishing workflow, validate priority templates, establish canonical evidence pages, and add parity tests for any alternate representation. Build the first dashboard from the same fixed query portfolio used in the audit.
    3. Days 61-90: Accountability. Give product, content, PR, SEO, and localization teams objectives tied to the gates they control. Review citation and accuracy failures together, fix them at the canonical fact layer, and verify that corrections reached every dependent surface. If compensation will eventually depend on these metrics, make the definitions auditable and resistant to gaming before attaching incentives.

    Key takeaways

    • Choose AI platforms after defining the audience questions and business decisions you need to influence.
    • Control important names, claims, relationships, qualifiers, and evidence in one canonical entity registry.
    • Require technical, brand, retrieval, authority, and localization gates before important content is published.
    • Keep human-facing HTML and machine-friendly representations semantically equivalent.
    • Measure mentions, citations, correctness, and business outcomes separately against a stable query portfolio.

    Start this week with one commercially important entity. Identify its canonical facts, trace where those facts are repeated, and run tenaciously through every conflict until the page, schema, communications, and AI test answers agree. Once that entity can move through the pipeline cleanly, turn the process into a reusable template and expand it to the next one.

    References

  • Agentic AI for E-commerce: A Leadership Operating Plan

    Agentic AI for E-commerce: A Leadership Operating Plan

    If your leadership team is asking whether agentic AI will make product pages, search traffic, or brand marketing obsolete, the useful answer is no. That is not a reason to wait. The practical change is that more discovery, comparison, filtering, and execution can move into software acting for the shopper.

    You need an operating plan that makes your products easy for both people and machines to understand, verify, and select. You also need measurement that remains honest when part of the buying journey happens beyond your analytics. Here is how to build both without reorganizing the company around an adoption curve nobody can forecast precisely.

    Key takeaways

    • Agentic commerce adds a software decision layer between customer intent and commercial execution. It does not remove the customer or the need to earn trust.
    • Your central readiness question is no longer only whether a product can rank. It is whether the product is eligible to survive a constraint-based selection process.
    • Eligibility depends on complete, consistent product facts, dependable price and availability data, clear policies, technical accessibility, and a transaction path that works.
    • JSON-LD and other machine-readable formats should publish canonical business facts, not compensate for contradictions between your systems.
    • SEO, merchandising, engineering, operations, customer experience, and analytics need named ownership. Agent readiness cannot sit entirely inside the marketing team.
    • Exact attribution will become less reliable as more evaluation happens inside AI systems. Measure readiness directly and interpret commercial outcomes directionally.

    Reframe the agent as a customer proxy

    In this context, agentic AI means software can carry part of a task forward from a person’s intention. The shopper still supplies the need, preferences, budget, and acceptable trade-offs. The software interprets those constraints, investigates options, narrows the field, and may take an action on the shopper’s behalf.

    Consider the difference between a shopper searching for running shoes and a shopper asking for a pair that fits a particular use, budget, size, delivery requirement, and material preference. A traditional search journey requires the person to open results and resolve those constraints manually. An agent can turn the same request into a filtering job before the shopper reaches a product page.

    A useful leadership model separates the journey into distinct decisions:

    • The person defines the desired outcome and acceptable constraints.
    • The agent interprets those constraints and identifies possible candidates.
    • Your published product and business data determine whether your offer can be understood and qualified.
    • Trust signals, policies, and commercial reliability help the agent distinguish between otherwise suitable candidates.
    • Your commerce systems determine whether the selected action can be completed successfully.

    This model changes the executive question. Instead of asking, ‘Will agents replace our customers?’, ask, ‘At which decision could incomplete or unreliable information remove us from consideration?’

    Rankings still matter because agents need candidates to evaluate. They are no longer a sufficient definition of success. A highly visible offer can still be filtered out if its suitability is unclear, its current price cannot be trusted, or its policies create unresolved risk. A lower-profile offer may remain eligible because it answers the request more precisely.

    The transition will not move at the same speed in every market. Categories with standardized products and organized data are easier for software to evaluate. Complex purchases and categories with regulatory constraints introduce more ambiguity. Treat adoption as gradual and category-dependent, then set investment levels for your own selection conditions rather than following a general hype cycle.

    The earliest pressure is likely to appear in discovery and consideration. Natural-language requests can carry far more context than short category queries, while software can perform the initial comparison without exposing every intermediate step. That weakens the assumption that owning a broad head term guarantees access to the consideration set.

    It also changes the job of content. A page should not merely attract a click or repeat a category phrase. It should resolve the variables that determine fit: what the product is, whom it serves, where it does not fit, what it costs, whether it is available, what conditions apply, and why the claims are credible.

    Audit the selection chain, not just the search result

    A glowing software agent passes generic products through several visual filtering and verification stages before making a final selection.

    Eligibility is not an official score supplied by an AI platform. It is a management lens for identifying the facts and systems that must work before an offer can be selected confidently. That makes it more useful than a vague goal such as ‘be ready for agents.’

    Selection stageQuestion the system must resolveEvidence to inspect
    IdentityWhat exactly is being offered?Canonical product name, identifiers, category, variant relationships, and consistent descriptions.
    SuitabilityDoes the offer satisfy the shopper’s constraints?Category-specific attributes, compatibility, dimensions, use conditions, exclusions, and variant-level facts.
    Commercial truthWhat will the shopper pay, and can the item be obtained?Current price, availability, offer conditions, and agreement between public surfaces and commerce systems.
    Trust and riskWhat uncertainty comes with choosing the offer?Clear return terms, restrictions, warranties where relevant, evidence for claims, and consistent policy language.
    ExecutionCan the intended action be completed reliably?Working product and checkout paths, accurate inventory state, dependable payment handling, and technical availability.

    Do not begin this audit with a new AI tool. Begin with a representative product family and a realistic, constraint-rich shopping request. The request should contain the kinds of conditions that would change the answer, not merely the category name.

    1. Write down the product facts, offer conditions, and policies required to answer the request without guessing.
    2. Identify the authoritative system and accountable owner for each fact.
    3. Trace the fact through every surface that publishes it, including the product page, product feeds, structured data, inventory displays, policy pages, and checkout where relevant.
    4. Mark each fact as present and consistent, absent, contradictory, stale, or technically inaccessible.
    5. Repair the authoritative value or propagation path rather than editing one visible symptom.
    6. Republish the affected surfaces and repeat the same shopping request to confirm that the ambiguity has actually disappeared.

    Prioritize contradictions before polishing optional copy. A missing secondary detail may narrow your eligibility for a particular request. Conflicting price, availability, variant, or policy information can undermine confidence in the entire offer. Dynamic facts deserve particular attention because a value that was correct when published can become wrong when updates fail to propagate.

    JSON-LD belongs in this chain, but it is a publication layer rather than a separate version of reality. If your visible page, feed, structured data, and backend expose different values, adding more markup gives the system another conflicting claimant. Define the canonical fact, define which system owns it, and make every machine-readable representation inherit from that source wherever your architecture allows.

    Your audit record should preserve the shopping request, required constraints, expected eligible products, retrieved facts, contradictions, remediation owner, and retest result. That turns agent readiness into a repeatable quality process instead of a collection of screenshots from impressive demonstrations.

    Build agent readiness into normal commerce ownership

    A cross-functional commerce team coordinates product information, inventory, fulfillment, analytics, and customer experience around a shared digital product model.

    Agentic selection crosses organizational boundaries because the deciding signals do. Marketing can improve discovery, but it cannot independently correct an inventory state, repair checkout, define a returns policy, or decide which product database is authoritative. Machine-readable trust depends on technical and operational integrity as much as promotional visibility.

    Assign the fact, the path, and the control

    Team names will vary, but the accountability cannot remain vague. Use the following division as a starting point:

    WorkstreamQuestion it should ownEvidence leadership should request
    Merchandising or product dataWhich attributes and variant relationships are authoritative?A documented source for selection-critical product facts and a queue of unresolved data defects.
    Commerce operationsAre price, availability, and offer conditions current?Exception reporting for mismatches and a defined response when updates fail.
    EngineeringCan machines reliably retrieve the same facts customers see?Healthy publication paths for pages, feeds, structured data, inventory, payment, and checkout.
    SEO, AEO, and GEOWhich intents and constraints determine eligibility, and where is ambiguity visible?Constraint maps, crawl and rendering findings, content gaps, and cross-surface consistency checks.
    Customer experience and policy ownersCan a buyer resolve risk without interpretation or conflicting language?Explicit policy terms, known ambiguity cases, and a path for correcting recurring questions.
    AnalyticsWhat can be observed directly, and what can only be inferred?Metric definitions that separate readiness, observable behavior, commercial outcomes, and unknowns.
    Executive sponsorWho resolves ownership conflicts and approves contingent investment?A prioritized defect register, decision gates, and accepted limits on attribution.

    Attach this work to an existing digital commerce, merchandising, or operational review. A separate agentic AI committee will not help if it lacks authority over product truth and commerce systems. The standing agenda can remain short: which selection-critical defects appeared, which source owns them, which customers or products are exposed, and whether the repair survived retesting.

    Change the content brief from attention to resolution

    Traditional consideration content often accumulates reviews, comparisons, benefit claims, and reassurance. Those assets still have value, but an agent can turn consideration into a strict filtering exercise. Content must therefore make fit and evidence easy to extract, not merely make the page persuasive.

    • State who and what the product is for, including meaningful limitations and exclusions.
    • Use stable terminology for the same attribute across product copy, specifications, feeds, structured data, and policies.
    • Keep claims close to their supporting evidence. Avoid vague superiority language that cannot help resolve a constraint.
    • Put selection-critical facts on the canonical page where they belong instead of scattering answers across thin supporting pages.
    • Make comparisons explicit about the condition that changes the recommendation. Not every product should appear to be the best option for every buyer.
    • Review policy language as decision data. A policy that requires interpretation leaves a risk variable unresolved.

    This favors content quality over page volume. If the answer already belongs on a product or category page, repair that page rather than publishing another near-duplicate merely to target a longer query. The goal is a coherent representation of the offer across every surface an agent may use.

    There is also a brand consequence. Software may filter and select products before a shopper becomes familiar with every candidate. That can improve conversion while weakening brand recognition. Preserve clear brand identity in the product facts and trust signals likely to travel with the offer, and continue building familiarity beyond search. A trusted brand gives both the shopper and the software fewer unresolved reasons to reject the choice.

    Measure readiness honestly and stage your investment

    Agentic journeys make precise attribution harder because more evaluation can happen inside an external AI system. Fewer visible page interactions do not automatically mean your optimization failed, just as a conversion cannot automatically prove that an agent caused the outcome. Leadership should expect directional indicators and blended performance to carry more weight than a perfectly reconstructed path.

    Use a layered scorecard

    Start with measures your business can observe and control:

    • Critical-fact completeness: the share of in-scope products with every attribute required for the tested shopping requests.
    • Cross-surface agreement: whether product pages, feeds, structured data, inventory displays, policies, and checkout expose the same current facts.
    • Update propagation: how reliably a canonical change reaches each public surface, and where stale values persist.
    • Technical availability: whether the relevant content and transaction paths can be retrieved and completed without an avoidable failure.
    • Policy ambiguity: unresolved cases in which offer conditions or customer protections conflict or require interpretation.

    Then place behavioral and commercial indicators beside those readiness measures:

    Leadership questionUseful indicatorWhat it cannot prove
    Are our offers becoming easier to qualify?Improved completeness, consistency, accessibility, and retest results for priority product families.That a specific AI system selected the offer.
    Can we see agent-associated visits?Identifiable referral or journey evidence where analytics exposes it.The total volume of agent influence, because many intermediate decisions may remain hidden.
    Are repaired journeys performing better?Product-family conversion, completion, cancellation, and other relevant outcome trends interpreted with the defect history.That the repair alone caused the change.
    Is the business gaining selection without losing recognition?Blended commercial performance considered alongside branded demand and returning-customer behavior.Exact credit for any single search, content, brand, or agent interaction.

    Report observation, inference, and unknowns separately. ‘The price mismatch was removed and the affected family improved’ is an observation followed by a correlation. ‘Agents generated the improvement’ is a causal claim that requires evidence you may not possess. This distinction protects the budget conversation from false precision.

    Separate foundation work from contingent bets

    The most defensible investments help current customers and current commerce operations even if agent adoption is slower than expected. Approve work that improves product information, removes contradictions, clarifies policies, strengthens technical reliability, or fixes price, inventory, payment, and checkout defects. These changes reduce uncertainty regardless of which interface initiates the purchase.

    Run controlled experiments for questions your analytics cannot answer yet. Reuse realistic shopping requests, record the expected eligibility conditions before testing, and preserve failures as well as successes. A demonstration is useful for discovering defects; it is not enough evidence for a large strategy change.

    Keep bespoke integrations, major budget reallocations, and platform-dependent builds behind explicit decision gates. Before approving one, ask whether the business controls the required data, whether a recurring failure or opportunity has been observed, whether the dependency is stable enough to support the investment, and whether the work remains valuable if adoption develops differently.

    This avoids the two expensive extremes: making sweeping changes because a demonstration looks inevitable, or ignoring agentic behavior until commercial performance forces a rushed response. The practical middle is to repair known eligibility weaknesses now and reserve harder-to-reverse bets for evidence that justifies them.

    At your next operating review, put a real product family and a real constraint-rich shopping request on screen. Trace every fact a shopper’s proxy would need, name the owner of each contradiction, repair the problem at its source, and retest the same request. You will make the business easier to select now without pretending anyone knows the final shape or pace of agentic commerce.

    References

  • AI Search Visibility Strategy: From Rankings to Citations

    Your pages can rank well while your brand disappears from the answer that shapes a buyer’s shortlist. A move from third to seventh place is no longer the only visibility risk; being omitted from the generated answer can remove you from consideration altogether.

    This does not make conventional SEO obsolete. It means you need to manage two related outcomes: whether people can find your pages and whether answer engines can retrieve, cite, and accurately describe your brand. Ahrefs has estimated that AI Overviews appear for about 21% of keywords. That is not a universal rate for every market or query set, but it is large enough to justify a deliberate AI visibility workflow.

    Key takeaways

    • Keep investing in SEO, but measure AI mentions and citations separately from rankings.
    • Build your strategy around the questions people ask while making a decision, not a loose collection of keywords.
    • Give every important question a direct, self-contained answer with clear qualifications and supporting evidence.
    • Use JSON-LD to clarify facts already visible on the page. Structured data cannot compensate for a vague or unhelpful answer.
    • Coordinate your website, LinkedIn, YouTube, and relevant social profiles so they present the same entity and claims.
    • Track mention rate, citation rate, and representation accuracy. A single visibility score hides the reason you are winning or losing.

    Map the questions you deserve to appear for

    AI visibility work often starts with the wrong inventory. A team takes its keyword list, adds question marks, and calls the result a prompt strategy. That misses the decision behind the query.

    An established brand can still be overlooked when its content does not match the way people frame their questions. Start with the decisions your audience must make. Then identify the prompts that expose each decision.

    A useful prompt portfolio covers distinct user tasks:

    • Learn: The user needs a definition, an explanation, or a way to understand the category.
    • Evaluate: The user is comparing approaches, providers, products, or criteria.
    • Verify: The user wants evidence, limitations, compatibility, or a reason to trust a claim.
    • Act: The user needs an implementation path, a checklist, or the next sensible step.

    Do not treat those tasks as interchangeable. A definition page may be a poor citation candidate for a comparison prompt, even if both target the same broad topic. The comparison prompt needs explicit criteria and tradeoffs. The implementation prompt needs ordered steps, prerequisites, and boundaries.

    Build a prompt ledger that supports decisions

    For every prompt you intend to monitor, record:

    • The exact wording of the prompt.
    • The user’s underlying task or decision.
    • The facts, criteria, or evidence a good answer must contain.
    • The page that should provide the canonical answer.
    • The supporting channel assets that reinforce it.
    • Whether your brand has a legitimate reason to be mentioned.
    • The URLs and brands currently cited in generated answers.

    That eligibility field matters. If the best truthful answer would remain complete without your brand, repeated prompt testing will not create relevance. You either need a genuinely useful asset, product capability, or body of evidence that earns inclusion, or you need to stop treating that prompt as a brand-visibility target.

    Separate branded, category, and problem-led prompts in your ledger. Branded prompts reveal whether an engine represents you accurately. Category prompts reveal whether you enter a shortlist. Problem-led prompts reveal whether your expertise is discoverable before the user has chosen a category or provider.

    Keep ordinary search data beside this ledger. Search demand, rankings, landing pages, and crawlability still matter because AI citations add a visibility layer rather than replacing SEO. The important change is that ranking is no longer the only outcome worth observing.

    Make each page easy to retrieve, quote, and trust

    A page can be comprehensive yet difficult to reuse. The answer may be buried under a long introduction, split across loosely related sections, or expressed through claims that make sense only when the entire page is read in order.

    In higher education, content organized for retrieval and decision-making has been more likely to earn citations than long narrative content. That does not prove a universal ranking factor. It does give you a strong editorial test: can a relevant passage answer the prompt accurately when read on its own?

    Use the following structure for an important decision question:

    1. Descriptive heading: State the question or decision in language the reader recognizes.
    2. Direct answer: Give the useful conclusion before the background.
    3. Conditions: Explain when the answer applies and when it does not.
    4. Evidence: Support factual claims with identifiable proof and clear attribution.
    5. Selection criteria: Help the reader compare options without hiding tradeoffs.
    6. Next action: Tell the reader what to inspect, calculate, change, or ask next.

    This is not an instruction to reduce every page to fragments. Narrative still helps readers understand context and consequences. The practical goal is to place the conclusion, qualification, and evidence in a passage that remains meaningful when an answer engine retrieves it.

    Write answer units that survive extraction

    A strong answer unit usually has a descriptive heading followed by a direct paragraph, then the evidence or decision criteria needed to qualify it. Improve those units with a few editorial checks:

    • Use explicit nouns when a pronoun would make a retrieved passage ambiguous.
    • Keep the claim and its qualification close together.
    • Use lists for criteria or steps, not as decoration.
    • Use a table only when the reader genuinely needs to compare repeated fields.
    • Define specialized terms where they first affect the decision.
    • Remove unsupported superlatives such as “best,” “leading,” or “most trusted.”
    • Link to the page containing the underlying proof rather than asking the reader to accept a summary claim.

    Pay particular attention to pages that rank but are not cited. Compare their headings and opening answers with the exact prompts in your ledger. If the page discusses the topic without resolving the user’s decision, adding more background will not fix the mismatch.

    Use JSON-LD as a consistency layer

    Structured data can make a coherent page easier for machines to interpret, but it is not a citation switch. If the visible content never answers the question, JSON-LD only describes an incomplete asset more precisely.

    Before publishing markup, check that it:

    • Represents facts that users can also find in the visible content.
    • Uses an entity or content type that matches what the page actually contains.
    • Keeps core names, URLs, descriptions, and relationships consistent with the page and your other profiles.
    • Points to the intended canonical entity and page rather than an accidental duplicate.
    • Passes syntax validation and remains updated when the visible facts change.

    Think of schema as a translation layer. It can reduce ambiguity around an already clear entity, offer, author, or content asset. It cannot manufacture expertise, independent support, or relevance that the page does not demonstrate.

    Build a distributed footprint without creating contradictions

    Your domain is only part of the evidence environment. AI answers can draw from multiple surfaces, including YouTube and LinkedIn. A website-only audit therefore misses places where an engine may encounter, confirm, or misunderstand your brand.

    Channel selection also depends on the answer engines you care about. Relationships between social platforms and systems such as ChatGPT, Google AI, and Grok can influence what becomes visible in generated responses. This is an opportunity to create more useful evidence surfaces, not a guarantee that posting more often will produce citations.

    Give each surface a clear role:

    • Your website: Publish the complete, canonical explanation, along with the strongest available evidence and decision support.
    • LinkedIn: Translate the central claim into professional context, practical criteria, and a clear route to the canonical page.
    • YouTube: Demonstrate the process, product, or reasoning where visual explanation adds information. Preserve precise terminology in the title, description, and spoken explanation.
    • Relevant social profiles: Keep entity facts current and answer focused questions in the format people expect on that platform.

    Do not paste the same block of promotional copy everywhere. Keep the facts consistent while adapting the utility. The website might hold a complete framework, LinkedIn might explain the decision criteria, and YouTube might show the process. Each asset should make sense where it appears and lead to deeper evidence when the reader needs it.

    Run a consistency audit across the surfaces you control. Check the brand name, product or service description, intended audience, canonical URL, and material claims. Resolve stale bios, conflicting labels, unsupported achievements, and different explanations of the same offering. An answer engine should not have to guess which version is current.

    Then connect every priority prompt to a small evidence network: a canonical page that resolves the question and supporting assets that demonstrate or explain the same position. Think in terms of a source network rather than a single URL.

    Measure mentions, citations, and representation separately

    A ranking report cannot tell you whether an answer engine mentioned your brand, cited your page, or described you correctly. Those are different events and they fail for different reasons.

    For every monitored response, retain the check date, engine or interface, exact prompt, generated answer, cited URLs, brands mentioned, description of your brand, and any material content or distribution changes since the previous check. Keep the raw answer beside the score. Generated responses can vary, so one observation should not be treated as a stable trend.

    Three measures form a useful baseline:

    • Mention rate: Eligible prompts that mention your brand divided by all eligible prompts checked.
    • Citation rate: Eligible prompts that cite one of your URLs divided by all eligible prompts checked.
    • Representation accuracy: Brand mentions that describe you accurately divided by all brand mentions.

    Use eligible prompts as the denominator. Counting unrelated prompts makes performance look worse without telling you anything actionable. Conversely, monitoring only branded prompts can create an inflated view of discovery because the brand is already present in the question.

    Observed patternProbable gapFirst check
    Ranks in search but is absent from generated answersThe page may be relevant but difficult to retrieve, insufficiently direct, or weakly supported across other surfacesCompare prompt wording with the page headings and answer units, then inspect what the cited pages provide
    Brand is mentioned without an owned citationThe entity is recognized, but the answer is selecting evidence from elsewhereIdentify the evidence types being cited and strengthen the canonical page and its supporting distribution
    Your URL is cited but the brand is described inaccuratelyCore facts may be vague, stale, or inconsistent across pages, profiles, and markupReconcile entity descriptions and material claims across every controlled surface
    Neither rankings nor AI mentions are presentThe underlying relevance, accessibility, or authority problem may precede AI optimizationConfirm that an appropriate page exists, can be found, and directly resolves the prompt before expanding distribution
    Visibility changes sharply between checksPrompt wording, interface differences, output variability, or an ecosystem change may be affecting the resultVerify the exact prompt and interface, examine raw responses, and review the change log before drawing a conclusion

    Do not collapse these observations into a single score too early. A high mention rate with poor representation accuracy is not a clean win. A low owned-citation rate may still reveal useful third-party recognition, but it also tells you that someone else is supplying the evidence used to define your brand.

    Give the workflow an owner

    Awareness does not create execution. In higher education, many organizations have recognized the importance of AI search without establishing the ownership and processes needed to act. The same operational gap can stall any team.

    Assign a named owner for the prompt ledger, citation checks, content handoffs, and change log. That person does not need to produce every asset. The owner needs enough authority to connect SEO, editorial, schema, social distribution, and measurement so that conflicting changes are noticed and useful changes are completed.

    Run the work as a recurring operating loop:

    1. Select the decision path most closely tied to your business or mission.
    2. Identify its eligible prompts and establish a baseline across the engines that matter to your audience.
    3. Audit the canonical page for answer quality, evidence, entity clarity, and valid markup.
    4. Create or repair supporting assets on the channels relevant to that decision.
    5. Recheck the same prompts after material changes and compare the raw responses.
    6. Use the observed failure pattern to choose the next edit instead of launching a general rewrite.

    Start with the decision path closest to an actual customer, prospect, student, or stakeholder choice. Repair the best existing page, align the surrounding profiles and channel assets, and record the baseline before expanding the program.

    The goal is not to force your brand into every generated answer. It is to make your brand a clear, defensible inclusion wherever it is genuinely relevant, and to notice quickly when an engine cannot retrieve, cite, or represent it correctly.

    References

  • How to Evaluate Leading AI Software Companies in 2026

    How to Evaluate Leading AI Software Companies in 2026

    If you are shortlisting AI software companies, a generic ranking answers the wrong question. A company can lead at the model layer and still be a poor choice for deploying a governed workflow inside your business.

    Your real task is to identify the kind of company you need, define what leadership means for your use case, and make each candidate prove it with your workflow and representative data. That turns a crowded market into a decision you can defend.

    Start with the job, not the company ranking

    There is no useful universal winner. A packaged AI application, a model provider, a cloud platform, and a custom development company solve different parts of the problem. Ranking them together is like ranking an engine, a delivery van, and a logistics contractor on the same scale.

    Before you collect vendor names, write a short procurement brief. It should be specific enough that another person could recognize a successful deployment without hearing the sales pitch.

    • Workflow: Name the task or decision the software will support. Avoid broad goals such as “use AI for marketing.” A workable definition is closer to “produce a cited first draft from approved product documentation for an editor to review.”
    • Owner: Identify the person accountable for the workflow after launch. A sponsor can approve a purchase, but an operational owner has to manage errors, updates, and user adoption.
    • Inputs: List the documents, databases, messages, images, or application events the system may use. Record where that data lives and who has permission to expose it.
    • Output and action: State what the system produces and what happens next. Distinguish a suggestion shown to a person from an action executed in another system.
    • Failure boundary: Describe acceptable mistakes, unacceptable mistakes, and the point at which a human must intervene. A formatting error and an invented compliance claim cannot share the same severity.
    • Environment: Name the identity system, content repository, analytics stack, customer platform, or other software the product must work with.
    • Evidence: Define what a candidate must demonstrate using representative cases. A polished demonstration using vendor-selected examples is not evidence of fit.
    • Exit conditions: Decide what data, configurations, prompts, evaluation cases, logs, and code you must be able to recover if you change providers.

    If you cannot complete this brief, pause the vendor search. When the outcome is vague, almost any demonstration can look successful, and disagreements about quality appear only after money and integration work have been committed.

    Compare companies that perform the same role

    Four distinct AI software workstations connect to the same central business task for a role-based comparison.

    The label leading AI software development companies can cover businesses with very different products and delivery models. Put each candidate into a functional category before you compare features, pricing, or market visibility.

    Company typeChoose it whenEvidence to requestCommon mismatch
    Model or API providerYour team is building its own application and needs model capabilities as a component.Results on your evaluation cases, usage controls, model-change procedures, latency behavior, and data-handling terms.Buying raw capability when you do not have the engineering or operational team to turn it into a reliable workflow.
    Cloud or data platformYour priority is connecting AI to governed data, existing infrastructure, and enterprise controls.Architecture fit, identity integration, data boundaries, deployment options, monitoring, and portability.Assuming platform breadth means the desired business application is already complete.
    Packaged AI applicationYou need a defined outcome in a familiar function such as content operations, support, analytics, or sales workflow.Workflow coverage, administrator controls, export options, user permissions, integration depth, and evidence from representative tasks.Paying for a broad feature set while the product remains weak at the narrow task that matters.
    Workflow or agent platformYou need AI to coordinate steps, tools, and approvals across systems.Action permissions, state handling, retries, approval gates, audit logs, failure recovery, and limits on autonomous behavior.Treating an impressive prototype as a dependable operational process.
    Custom AI development companyNo packaged product fits the workflow, or your process and data create meaningful differentiation.Proposed architecture, delivery ownership, evaluation method, repository access, documentation, deployment plan, support model, and intellectual-property terms.Commissioning custom software before confirming that the workflow is stable enough to specify and maintain.
    AI operations or governance providerYou already have AI systems and need evaluation, observability, policy enforcement, or control across them.Coverage of your actual stack, alert quality, policy implementation, evidence retention, and response procedures.Expecting a control layer to repair poor application design or unsuitable source data.

    A candidate can belong to more than one category, but you should still name the role you are buying from it. Otherwise, a vendor’s strength in one layer can distract you from a gap in another. If you need a finished application, model quality alone does not settle the decision. If you need a model component, a large catalogue of packaged features may be irrelevant.

    Turn “leading” into pass-or-fail requirements

    Feature counts reward breadth, and weighted scorecards can hide a fatal weakness behind a high total. Use non-negotiable gates first. Score or rank only the companies that pass every gate that protects the workflow.

    • Task performance: The product must produce usable results on ordinary cases, difficult edge cases, and inputs that should trigger refusal or escalation. Define “usable” in terms of the next step in the workflow, not whether the output sounds polished.
    • Evaluation discipline: Ask how the company detects regressions and separates different error types. For generated answers, completeness, factual support, citation quality, format compliance, and harmful fabrication are different dimensions. A blended quality claim can conceal the failure that matters most to you.
    • Data governance: Get written answers about retention, use of customer data for training, storage location, deletion, subprocessors, tenant separation, and access by vendor personnel. Product controls and contract language should agree.
    • Security and human control: Confirm authentication, role-based access, approval steps, auditability, and the ability to stop or override automated actions. The more consequential the action, the less acceptable an invisible decision path becomes.
    • Integration depth: Distinguish a live, supported integration from a demonstration, roadmap item, or generic API. Verify the exact records the system can read, create, update, and export.
    • Operational resilience: Ask what happens when a model, connector, data source, or downstream system fails. A production workflow needs observable errors, safe fallbacks, ownership, and a recovery procedure.
    • Commercial fit: Calculate the cost of the working process, including usage, integration, human review, monitoring, support, and ongoing evaluation. A low software price can still produce an expensive workflow if reviewers must repair most outputs.
    • Exit viability: Confirm that you can retrieve business data and the operational assets needed to continue elsewhere. For custom development, define ownership of code, prompts, configurations, documentation, and deployment materials before work begins.

    Treat unsupported roadmap promises as unavailable. Record each capability as proven, contractually committed, or absent. Those labels keep a persuasive demonstration from turning future intent into present functionality.

    References and customer logos can help you understand where to investigate, but they do not replace workflow evidence. Ask references about deployment effort, failure handling, support after the sale, and what their internal team still has to operate. A similar industry is useful; a similar data shape, risk level, and workflow is better.

    Run a production-shaped proof before you commit

    A business and engineering team observes an AI proof-of-concept moving through security, human review, monitoring, and final delivery stages.

    A proof should test the operating system around the AI, not just the most attractive output. Keep the workflow narrow enough to inspect closely, but preserve the data conditions, permissions, integrations, and review steps that will exist in production.

    1. Freeze the use case. Give every candidate the same workflow definition, input boundaries, expected output, and failure rules. Do not let each vendor redefine success around its strongest feature.
    2. Build the evaluation set. Include routine examples, ambiguous inputs, incomplete information, edge cases, and requests the system should decline or escalate. Keep a portion of the cases out of vendor-led configuration so you can see how the system handles unfamiliar inputs.
    3. Protect sensitive information. Use de-identified or synthetic material until contractual, security, and internal approvals permit representative production data. When real data becomes necessary, expose only what the approved test requires.
    4. Record configuration work. Track the prompts, rules, connectors, data cleanup, and human assistance required to achieve the result. A system that performs well only after extensive hidden preparation may carry a much higher operating cost than the demonstration implies.
    5. Test the whole handoff. Measure whether users can review, correct, approve, reject, and trace the output inside the intended workflow. A strong answer copied manually between applications may still be a weak production solution.
    6. Force recoverable failures. Remove a source, deny a permission, provide conflicting information, or interrupt a downstream service in a controlled test. Check whether the system fails visibly, preserves state, avoids unsafe actions, and gives an operator a clear recovery path.
    7. Review the evidence by error type. Keep a failure log that identifies what went wrong, its consequence, whether a person detected it, and whether the proposed fix is repeatable. Do not average a severe failure into a reassuring overall score.
    8. Price the observed workflow. Use the actual configuration, workload shape, review effort, support requirement, and integration pattern from the proof. Model an increase and decrease in usage so you can see which charges are fixed and which scale with activity.
    9. Test the exit. Export representative data and configuration, inspect its format, and identify what cannot move. For a custom system, verify access to the repository, build instructions, environment configuration, and operating documentation.

    The proof should leave you with artifacts you can inspect later: the frozen evaluation set, result sheet, failure log, data-flow map, architecture diagram, cost model, operating runbook, and exit plan. If the only durable artifact is a presentation, you have evaluated a sales process rather than a production system.

    Reject any company that fails a non-negotiable gate, even if it has the highest total score. Among the survivors, prefer the option that reaches the required outcome with the clearest controls, lowest operational burden, and most credible path out. That is a more useful definition of leadership than size, visibility, or the longest feature list.

    Key takeaways for your shortlist

    • Define the workflow, owner, data, action, failure boundary, evidence, and exit conditions before collecting vendor names.
    • Compare model providers with model providers, applications with applications, and development companies with development companies.
    • Make task performance, data governance, security, operational resilience, economics, and exit viability pass-or-fail gates.
    • Use the same production-shaped evaluation cases for every candidate, and keep severe errors visible instead of burying them in an average.
    • Count configuration, integration, review, monitoring, and support when calculating cost.
    • Choose the company that can prove the required outcome and remain operable when inputs, systems, or providers change.

    Take your current list and write each company’s intended role beside its name. Remove candidates that solve a different layer, send the survivors the same procurement brief, and do not declare a leader until the proof produces evidence your operational owner is willing to accept.

    References

  • How SEO Agencies Should Adapt Their Strategy for AI Search

    How SEO Agencies Should Adapt Their Strategy for AI Search

    Your agency can still improve rankings and lose the decision. An AI assistant can satisfy an informational query before a prospect visits a website, while that prospect may later use Google to verify the recommendation. If reporting starts and ends with positions, sessions, and last-click conversions, a meaningful part of the journey remains invisible.

    Adapting does not require abandoning SEO or relabeling ordinary content work as generative engine optimization. You still need crawlable pages, sound information architecture, useful content, links, and measurable demand. You also need an operating layer that makes the client’s brand easy to retrieve, interpret, validate, and represent accurately across AI and traditional search.

    Key takeaways for agency leaders

    • Keep technical and content SEO as the eligibility layer. Indexing creates an opportunity to be selected; it does not guarantee selection.
    • Plan campaigns around user decisions, concepts, entities, and supporting evidence, not isolated keywords and URLs.
    • Create a controlled source of truth before scaling content with AI. Conflicting names, claims, prices, and market details weaken the whole brand representation.
    • Give international pages separate URLs when they contain genuine market differences, such as pricing, availability, compliance information, local intent, or local evidence.
    • Measure mentions, citations, recommendations, factual accuracy, and commercial outcomes separately. They are different signals, and no universal AI ranking combines them.
    • Write contracts around work the agency controls and outcomes it can influence. Do not promise a fixed position or guaranteed inclusion in a generated answer.

    Your product is no longer just a ranking report

    Rankings remain useful. They reveal demand, competition, landing-page performance, and changes in conventional search visibility. The mistake is treating them as a complete account of discovery.

    AI search introduces a different sequence. A person can ask for an explanation, compare options inside the generated response, verify a recommendation through Google, and visit only when ready to act. The brand can therefore influence a decision without receiving the first click. It can also receive a click after the assistant has framed the brand inaccurately.

    A Semrush forecast that AI search could surpass organic traffic by 2028 makes this a reasonable planning scenario, but it is still a forecast. It is not a deadline, and it is not a reason to neglect Google. Build for a mixed discovery environment in which search engines, assistants, review sites, editorial lists, and owned pages all contribute to the same decision.

    Agency capabilityKeepAdd
    ResearchSearch demand, keyword groups, intent, competitorsDecision questions, prompt scenarios, entity ambiguity, evidence gaps
    ContentUseful pages that satisfy intent and support conversionSelf-contained answer passages, explicit entity relationships, claim-to-evidence mapping
    AuthorityRelevant editorial links and brand coverageRelevant list inclusion, brand-entity work, and review evidence
    TechnicalCrawling, indexing, canonicals, internal links, rendering, hreflangStructured-data consistency, stable entity identifiers, market-variant governance
    ReportingRankings, clicks, conversions, revenueMentions, citations, recommendations, factual accuracy, market representation

    This changes the campaign brief. A useful brief should identify the decision the user is making, the entity that must be understood, the claims required to answer the question, the evidence supporting those claims, the market in which they apply, and the action the client wants the user to take. A target keyword and preferred URL can still appear, but they no longer carry the whole strategy.

    It also changes the commercial conversation. The agency is not merely increasing visits to a page. It is improving the probability that a brand becomes an eligible, understandable, credible option during discovery and verification. That is a broader job, so the scope and measurement plan must be broader too.

    Rebuild production around entities, claims, and evidence

    An isometric content workflow connects a central subject to claims, source documents, expert input, data, product details, and published pages.

    A search engine can index a page without prioritizing it, and an AI system can retrieve information without representing the business correctly. Clear identity matters: the system needs to resolve the company, its brands, its products or services, the relevant market, and the evidence behind material claims. AI synthesis also works across concepts and entities rather than following an agency’s page-by-page campaign plan. That is why indexing and isolated page optimization are no longer sufficient measures of visibility.

    Create a controlled brand source of truth

    Before commissioning another content batch, create an entity and claim register. This should be a working operational record shared by SEO, content, public relations, developers, localization teams, and whoever approves product or legal claims.

    • Entity: Record the official public name, recognized aliases, parent or subsidiary relationship, product families, and the preferred canonical page.
    • Claim: Write the approved statement precisely. Separate factual attributes from positioning language and opinions.
    • Evidence: Attach the owned URL that substantiates the claim and any credible independent corroboration.
    • Scope: Mark the products, audiences, languages, and markets to which the claim applies. A global default should not silently overwrite a local exception.
    • Status: Assign an owner, approval state, and condition that triggers review, such as a price, policy, availability, or product change.
    • Machine representation: Record the stable entity identifier and the structured-data nodes that should express the same facts.

    The register prevents content writers, public relations teams, feeds, landing pages, and regional sites from publishing different versions of the same fact. That matters because uncoordinated publishing can create semantic drift. A newer or apparently more authoritative page may then become the preferred representation even when it belongs to the wrong market or no longer reflects the client’s strategy.

    Map real decisions to answerable evidence

    Keyword research tells you how people search. An AI-search plan also needs to capture what they are trying to decide. Build a question-to-evidence map using demand data, sales objections, support questions, on-site search, existing customer language, and the comparisons that repeatedly appear in the market.

    1. List the questions people ask while learning, comparing, verifying, and choosing. Do not limit the list to questions that already contain the client’s brand.
    2. Group equivalent questions by concept and user decision. Different wording should not create a separate content assignment when the required answer is the same.
    3. Identify every entity the answer depends on: the company, product, service, location, audience, standard, feature, or market.
    4. Assign a canonical answer and supporting evidence. If the business cannot substantiate an important claim, mark it as an evidence gap instead of asking a writer to make the language sound more certain.
    5. Choose the owned page that should carry the complete answer, then identify supporting pages that provide context without contradicting it.
    6. Find external validation where trust depends on more than an owned assertion. Relevant editorial lists, accurate brand mentions, local affiliations, and substantive reviews can support this layer.
    7. Resolve conflicting facts before publishing. More content amplifies a contradiction; it does not settle it.

    Each important answer passage should survive a simple extraction test. It should make sense when read without the surrounding introduction, name the relevant entity instead of relying on vague pronouns, state material conditions or market limits, and point to evidence where the claim needs support. Avoid unsupported superlatives. Best, leading, safest, and most trusted are weak answer material when the page never establishes the basis for them.

    This is also the safest way to use generative writing tools. Feed them the approved entity record, claim boundaries, evidence URLs, market scope, and content assignment. Review the output against those inputs before publication. The main quality risk is not awkward prose; it is a plausible sentence that changes a condition, drops a regional qualifier, or combines two claims the business cannot actually support.

    Use JSON-LD to clarify facts, not invent them

    Implement structured data after the source of truth is settled. Where applicable, connect Organization, Product, Service, Person, and Article nodes through stable @id values. Use the same entity names and relationships in visible copy, metadata, feeds, and JSON-LD.

    Markup should express facts that a visitor can verify on the page or through an appropriate linked source. If the product feed, page copy, and JSON-LD disagree, fix the underlying system of record instead of deciding that only the markup needs to be correct. Schema can reduce ambiguity and improve machine readability. It cannot manufacture authority or guarantee inclusion, citation, or a fixed position in an AI response.

    Owned consistency still needs independent support. For a local business, reviews should contain genuine details about the service, place, or outcome rather than agency-written keyword patterns. For a brand operating across countries, local expertise, affiliations, and market-specific authority can matter more than global brand strength alone. Record useful third-party corroboration in the same evidence system so content and outreach teams know which claims already have support and which do not.

    Keep technical SEO, but give every control the right job

    International SEO exposes weak AI-search architecture quickly. The same entity appears in several languages, prices and policies vary, regional teams publish independently, and global authority is not always local authority. Technical controls help machines discover and route those versions, but they cannot compensate for pages that say nothing meaningfully different.

    Decide when a market page earns a separate URL

    A country or regional page deserves its own URL when it represents a real market variation. Use this test before expanding the site architecture:

    • Pricing, currency, purchasing terms, or available offers differ.
    • Legal disclosures, regulatory language, or compliance requirements differ.
    • Product availability, delivery, support, or service coverage differs.
    • The local audience has a materially different intent, use case, terminology, or decision process.
    • The page can provide local evidence, such as appropriate reviews, affiliations, expertise, or market-specific proof.

    A translated page can still serve a language need even when the underlying offer is global. What it cannot do is create market differentiation merely by changing the language. Thin localization may leave the system with several pages answering the same intent, and the English version may still be favored globally when the alternatives add no clearer local value.

    Separate routing signals from selection signals

    • URLs and canonicals organize distinct resources and consolidate duplicates. They do not prove that a regional page is useful.
    • Indexability makes a page eligible for conventional retrieval. It does not ensure that the page will be prioritized in a generated response.
    • Hreflang still helps traditional search engines return the appropriate language or regional version. Its influence is more limited in AI-mediated retrieval, where clear market differences and unambiguous data must exist before selection.
    • Localization aligns the answer with local intent, conditions, terminology, and evidence. This is content and product work, not a tag implementation.
    • Local authority validates the brand within the market. Global links and recognition do not automatically establish local relevance.

    Extend the central claim register with a regional override record. For every variable fact, store the global default, local value, reason for the difference, approved URL, responsible owner, and affected locales. Regional teams can then make necessary changes without silently redefining the entire brand.

    Audit the final system in both directions. First, find local pages that are little more than translations and decide what genuine market value they should add. Second, find facts that should be consistent but have drifted across countries. Pay particular attention to brand names, product relationships, price conditions, availability, support promises, and compliance language. A technically flawless hreflang implementation will not resolve contradictory claims.

    Measure selection, accuracy, and commercial movement separately

    Analysts observe three connected views representing AI source selection, factual verification, and a customer's movement toward a commercial decision.

    There is no single AI-search metric equivalent to a stable universal rank. A brand can be mentioned but not recommended, recommended but not cited, cited through the wrong page, or described inaccurately. Combining those states into one visibility percentage hides the problem the agency actually needs to fix.

    Use a layered scorecard

    Eligibility and clarity cover the parts of the system you can inspect directly:

    • Crawling, rendering, indexation, canonicalization, internal linking, and hreflang status
    • Structured-data validity and agreement with visible content
    • Completeness of entity records and claim evidence
    • Consistency across pages, feeds, profiles, and market versions
    • Coverage of priority decisions and supporting concepts

    Selection and representation describe what happens on each relevant AI surface:

    • Mentioned: The brand or product appears in the response.
    • Cited: The response links to or names an owned or third-party source connected to the brand.
    • Recommended: The brand is presented as a suitable option for the stated need.
    • Accurate: Material claims, relationships, conditions, and market details are represented correctly.
    • Actionable: The user receives a useful route to verify the claim, visit the correct page, or take the intended next step.

    Commercial movement connects visibility to the client’s actual objective:

    • Identifiable referral visits from AI platforms
    • Qualified leads, sales, bookings, or other agreed conversions from those visits
    • Assisted conversions where the available analytics can support the connection
    • Lead quality and customer-reported discovery information, when collected consistently
    • Branded search and direct traffic as contextual trends, not automatic proof of AI impact
    • Organic visits that support verification after an AI-assisted discovery journey

    Do not reclassify unexplained direct traffic as AI traffic. Do not claim that a rise in branded search proves an assistant caused it. Use those signals as supporting context and state the attribution limit clearly.

    Make prompt monitoring reproducible

    Your monitoring set should represent real audience decisions, not prompts engineered to force the client’s name into an answer. Include non-branded learning, comparison, selection, and verification questions. Segment them by market and language when the expected answer genuinely differs.

    • Save the exact prompt and any context supplied with it.
    • Record the platform, model or interface when visible, language, market assumption, and observation date.
    • Capture the complete relevant response, not only the favorable sentence.
    • Log mentions, recommendations, cited domains, cited URLs, material claims, and factual errors separately.
    • Repeat observations under comparable conditions and report the pattern. A favorable screenshot is an example, not a rank.
    • Keep platform findings separate before producing a combined executive view. Different products can retrieve, synthesize, and cite differently.

    Use the observations to choose work, not merely to produce charts. An inaccurate product relationship points back to entity governance. A correct mention with no supporting citation suggests an evidence or authority gap. A citation to an irrelevant market page points to localization and routing. Strong representation with no commercial action may reveal a weak landing experience or an offer mismatch.

    Rewrite the client promise around control and influence

    An agency can control technical implementation, owned content, structured data, internal governance, measurement design, and the quality of outreach. It can influence independent coverage, reviews, citations, and AI selection. It cannot guarantee a fixed answer, exact wording, universal visibility, or a permanent position on a third-party platform.

    Make that boundary explicit in the scope of work. A defensible AI-search engagement can promise an audited entity register, a decision-question baseline, prioritized technical and content fixes, a structured-data plan, authority-building work, market consistency checks, and a repeatable observation protocol. Report completed interventions and observed changes without turning correlation into certainty.

    Client reviews should answer practical questions: Where did the brand become more or less selectable? Which factual errors appeared? Which owned and independent pages were cited? What evidence gap is blocking the next priority decision? Did qualified demand or pipeline move alongside visibility? What intervention will test the next hypothesis?

    Before adding another AI-search package to the service menu, apply this operating model to an active account with a clear offer and usable evidence. Build the entity register, map decision questions to claims, inspect the relevant AI surfaces, and fix the highest-consequence contradictions before scaling production. That gives your team a strategy it can execute and your client a result that can be inspected, challenged, and improved.

    References

  • AEO Strategy: Execution, Measurement, and Agency Selection

    AEO Strategy: Execution, Measurement, and Agency Selection

    You are probably not short of AEO ideas. The harder decision is where to put the budget: more content, technical changes, measurement, or an agency promising visibility in ChatGPT and other answer engines. If you make that choice from a list of supposedly popular prompts, the program can look busy without becoming useful.

    Build the program backward from a customer decision and a business result. That gives your team a way to prioritize work, judge whether it is succeeding, and tell the difference between a capable AEO agency and a persuasive sales presentation.

    Build the strategy backward from a customer decision

    AEO should not begin with a giant prompt list. Begin with a decision a real customer needs to make: which option fits, whether a claim can be trusted, what a product does, how two approaches differ, or what to do next. Then identify the facts, evidence, and pages needed to support a reliable answer.

    For planning purposes, use a practical distinction between AEO and GEO. AEO makes a direct answer clear, retrievable, and well supported. GEO helps the same information retain its meaning and authority when a generative system combines it with other material. The disciplines overlap enough that AEO and GEO tactics belong in one operating program, not in competing teams with separate content calendars.

    Write a one-page decision brief before commissioning content or technology. It should answer:

    • Business outcome: What should improve if the program works: qualified inquiries, purchases, applications, adoption, retention, or another defined result?
    • Audience: Who is making the decision, and what do they already know?
    • Decision: What choice or next step should your content help that person complete?
    • Answer territory: Which questions can your organization answer with genuine expertise or first-party evidence?
    • Proof: Which approved facts, methods, policies, credentials, product details, or original data can support the answer?
    • Conversion path: What useful action should remain available after an answer engine satisfies the immediate question?
    • Ownership: Who approves factual claims, maintains the underlying page, and responds when information changes?

    This brief is the boundary of the strategy. A topic that attracts attention but cannot influence the chosen decision, demonstrate expertise, or lead to a useful next action is a weak priority.

    Prompt-volume estimates do not fix that problem. A prompt is not a stable unit of demand: the same need can be expressed in many ways, conversational context changes the wording, and an AI system may reformulate the request before producing an answer. That is why prompt volume should not carry the business case for AEO.

    Use prompts as a research panel instead. Group them by customer need, decision stage, and subject. Prioritize each group using business relevance, your ability to provide a defensible answer, the quality of your existing coverage, and the consequence of being absent or misrepresented. This produces a manageable question portfolio without pretending that an estimated volume is equivalent to audited search demand.

    Turn the customer journey into an answer system

    An isometric customer journey connected to blank answer cards, source documents, product objects, and technical nodes.

    AI discovery is not a separate funnel that ends when your brand is mentioned. People use answer engines while exploring a problem, narrowing options, validating a claim, preparing to act, and using what they selected. Treating AI discovery as part of the customer journey prevents a common mistake: optimizing only broad awareness questions while leaving comparison and action-stage questions unanswered.

    Journey momentWhat the person needsYour content jobUseful next action
    ExploreA clear view of the problem, category, or available approachesDefine the subject, explain the options, and establish scope without forcing a saleRead a deeper explanation or assess the problem
    NarrowCriteria that separate plausible choicesShow differences, trade-offs, use cases, and disqualifying conditionsCompare relevant options or review requirements
    ValidateEvidence that a claim, provider, or method is credibleExpose the basis of claims, limitations, policies, credentials, and first-party proofInspect evidence or confirm fit
    ActEnough certainty to complete the next stepAnswer practical questions about process, eligibility, implementation, or purchaseApply, buy, book, contact, or begin setup
    UseHelp getting value or resolving a problemProvide accurate instructions, troubleshooting, and policy informationComplete the task or reach appropriate support

    Design the answer architecture

    Build content around question families rather than publishing a separate page for every wording variation. One maintained page can answer the central question, while supporting pages handle comparisons, implementation details, evidence, and edge cases. Link them so a person or retrieval system can move from a short answer to its substantiation without guessing which page is authoritative.

    A useful answer unit contains:

    • A direct response: State the answer before background material, provided the question can be answered without a critical qualification.
    • Scope: Identify who, what, or which situation the answer applies to.
    • Reasoning: Explain why the answer holds and which criteria affect it.
    • Evidence: Connect material claims to inspectable facts, methods, policies, credentials, or original data.
    • Trade-offs: Say when an alternative may be more appropriate and where the answer has limits.
    • Entity clarity: Use consistent names for the organization, product, service, location, person, and concept being discussed.
    • A next step: Offer an action that follows naturally from the decision instead of interrupting it with an unrelated conversion request.

    Structured data should express the same entities and relationships that a reader can verify on the page. It cannot repair an unsupported claim, settle contradictions between pages, or make thin content authoritative. If the visible content, structured data, product feed, policy page, and organizational profile disagree, fix the underlying information before adding more markup.

    Give production a definition of done

    AEO execution usually crosses content, subject expertise, technical SEO, development, analytics, and brand governance. Without an explicit handoff, every contributor can complete a task while the final answer remains incomplete. Use one workflow:

    1. Select a question family. Tie it to the audience, journey moment, decision, and business outcome in the brief.
    2. Assemble a fact pack. Collect approved claims, definitions, evidence, policies, entity names, known limitations, and the internal owner of each important fact.
    3. Audit the existing answer. Find duplicate pages, buried explanations, unsupported assertions, contradictory details, obsolete material, and missing conversion paths before creating anything new.
    4. Write the content specification. Record the central question, direct response, necessary qualifiers, supporting evidence, related questions, authoritative URL, internal links, structured-data requirements, and intended next action.
    5. Review for factual integrity. Have the appropriate subject owner approve consequential claims and limitations. Editorial polish is not a substitute for this review.
    6. Run technical quality control. Confirm that the preferred page is publicly reachable, its important answer is present in accessible page content, canonical signals are consistent, indexing is not accidentally blocked, internal links work, and markup agrees with visible information.
    7. Publish and observe. Inspect how representative questions are answered, record inaccurate or missing claims, and feed those findings back into the maintained page and fact pack.

    A page is not done merely because it contains the target phrase or passes a markup test. It is done when the answer is clear, its limits are visible, its material claims are supportable, the responsible owner has approved it, and the next step works.

    Measure visibility without pretending it is demand

    A useful AEO scorecard separates observation from value. Visibility tells you whether and how your organization appears. Engagement tells you whether people continue to your owned experience. Business outcomes tell you whether the program influences a result that matters. Combining those layers into one opaque score hides the reason performance changed.

    Measurement layerWhat to recordDecision it supports
    Answer visibilityBrand inclusion, citation, linked page, answer placement, and presence across representative question familiesWhere your organization is absent or difficult to retrieve
    Answer qualityAccuracy, completeness, correct entity identification, appropriate qualification, and treatment of important claimsWhich facts or pages need correction, clarification, or stronger support
    Owned engagementAI referrals, landing-page behavior, completed next steps, and assisted journeys where they can be observedWhether AI exposure produces useful interaction rather than a mention alone
    Business outcomesQualified inquiries, applications, purchases, activation, retention, or the outcome named in the decision briefWhether continued investment is justified and which journey areas deserve attention

    Treat your monitored prompts as a fixed diagnostic panel, not a census of all AI demand. Include high-value question families from each relevant journey stage, along with natural wording variations. For every observation, retain the exact prompt, intent family, platform or interface, displayed model label when available, language, location, account state, observation date, answer, citations, linked pages, and your quality assessment.

    Those fields matter because an answer can vary with wording, context, interface, model behavior, location, and personalization. If the testing conditions change, label the break instead of presenting the new result as a clean continuation of the old one.

    Evaluate every important answer along separate dimensions: present or absent, cited or uncited, accurate or inaccurate, useful or unhelpful. A brand can be visible and still be described incorrectly. It can be cited while the wrong page receives the link. It can also provide the answer without earning a click. Those outcomes require different actions and should not collapse into a single visibility percentage.

    Do not treat an AI referral as the only sign of influence, but do not assign commercial value to a no-click mention without evidence either. Connect observable referrals and conversions where possible, use assisted-journey evidence cautiously, and label what cannot be attributed. Honest measurement is more useful than a precise-looking number built on assumptions.

    Choose an agency by inspecting the work, not the vocabulary

    A client team examines blank content mockups, a technical model, and an abstract dashboard while presentation screens remain in the background.

    Before issuing an RFP, decide which operating model you need. Keep the program in-house when your content, technical, analytics, and subject-matter teams can own the workflow and only need focused training or tooling. Use a hybrid model when internal teams should retain strategy and factual ownership but need specialist support for audits, measurement, structured data, or production. Consider a broader agency engagement when coordination and execution capacity are the actual constraints.

    An agency cannot control whether a frontier model includes or cites a brand. It can improve the clarity, accessibility, consistency, evidence, and measurement of the information available to those systems. Evaluate bidders on those controllable contributions.

    Make the RFP demand inspectable outputs

    A structured AI-search RFP can reveal whether a bidder has genuine execution depth, but only if it asks for more than credentials and a dashboard tour. Give every bidder the same business objective, customer journey, known constraints, sample content, available data, approval process, and expected handoffs. Then require concrete responses:

    • Problem diagnosis: Which customer decisions and answer gaps should be addressed first, and why?
    • Question architecture: How will the agency build and maintain question families without treating guessed prompt volume as audited demand?
    • Content method: What will a content specification contain, and how will the team obtain and approve evidence?
    • Technical method: How will the agency inspect accessibility, canonicalization, internal linking, entity consistency, structured data, and conflicts across owned properties?
    • Measurement design: Which visibility, quality, engagement, and business signals will be reported separately? What can and cannot be attributed?
    • Working model: Who owns strategy, fact approval, writing, implementation, testing, and refresh decisions on both sides?
    • First-phase plan: Which deliverables will be produced first, what dependencies could block them, and what evidence will determine the next phase?
    • Transferable assets: Will you receive the question set, raw observations, content specifications, technical findings, data exports, documentation, and account access needed to continue the work?
    • Relevant evidence: Can the agency show the baseline, intervention, measurement method, limitations, result, and its own role in a comparable engagement?

    Score each response using the same criteria and scale. Favor clear prioritization, factual discipline, technical competence, measurement honesty, and an operating model your team can sustain. A bidder should be able to explain what it will deliberately not do as clearly as what it proposes.

    For finalists, run the same controlled working exercise. Provide a representative page, an approved fact pack, a customer decision, and a small set of observed AI answers. Ask each team to diagnose the highest-priority problem, improve an answer block, identify technical or factual conflicts, define acceptance criteria, and explain how it would measure the change. If the exercise creates usable strategic work, compensate the participants rather than disguising free consulting as procurement.

    Recognize the red flags before you sign

    • Guaranteed inclusion or citation: No agency can promise what an independent answer engine will generate.
    • Prompt volume presented as demand truth: Ask how the estimate was produced, what it represents, and which decisions would change if it were wrong.
    • A dashboard without a decision model: More charts do not compensate for the absence of business outcomes, journey priorities, and defined actions.
    • Schema sold as a standalone solution: Markup can clarify supported information; it cannot manufacture authority or reconcile contradictory facts.
    • Mentions treated as success: Visibility without accuracy, relevance, evidence, or business connection can create risk rather than value.
    • No plan for subject-matter review: An agency that cannot explain how consequential claims are approved is treating factual integrity as an editorial afterthought.
    • Opaque methods or inaccessible data: You should understand how prompts are selected, how outputs are classified, and which raw material sits behind reported scores.
    • No exit path: If the work disappears when the contract ends, the engagement has not built an organizational capability.

    Before work starts, put deliverables, approval responsibilities, access, data retention, asset ownership, reporting definitions, and handoff requirements into the agreement. Ambiguity here does not create flexibility. It postpones a dispute until the first missed dependency or the end of the engagement.

    Key takeaways

    • Start AEO with a customer decision, business outcome, evidence base, and owner. Do not start with estimated prompt volume.
    • Treat prompts as a representative diagnostic panel organized by intent and journey stage, not as a complete measure of market demand.
    • Build maintained answer systems: direct responses, clear scope, inspectable evidence, consistent entities, useful internal paths, and matching structured data.
    • Measure answer visibility, answer quality, owned engagement, and business outcomes separately so the team knows what to change.
    • Select an agency through inspectable work, explicit handoffs, honest measurement, and proof of operating discipline. Reject guarantees that depend on systems the agency does not control.

    Your next move is small and concrete: choose one valuable customer decision, write its decision brief, and audit the pages that currently answer it. That exercise will show whether your immediate constraint is evidence, content, technical implementation, measurement, or capacity. If you approach agencies afterward, you will be buying against a defined need instead of asking a vendor to define the need for you.

    References

  • AI Search Marketing Optimization: A Practical Operating System

    AI Search Marketing Optimization: A Practical Operating System

    Your page can hold a respectable organic position and still disappear inside an AI-generated answer. It can also earn a citation that sends no qualified business your way. Visibility, attribution, and commercial value are related, but they are not the same result.

    Effective AI search marketing optimization connects those results. You make the right page discoverable, turn it into a clear and defensible answer, give machines enough context to interpret it correctly, and measure whether that visibility influences a useful decision.

    Start with the decision you want to influence

    Do not begin with a tool, a prompt-tracking dashboard, or a vague goal to appear in more AI answers. Begin with the decision your audience is trying to make and the page that should help them make it. Testing tools without a defined purpose creates activity, but it does not tell you whether the work improved pipeline, retention, sales, or another business outcome.

    Traditional SEO and Generative Engine Optimization, or GEO, overlap, but they emphasize different outcomes. SEO helps a page become discoverable in search results. GEO extends the job to selection, citation, and accurate representation inside generated answers. You need both. A page that cannot be found is unlikely to be used, while a discoverable page with an ambiguous answer gives an AI system little reason to rely on it.

    Plan the work around three gates:

    • Discovery: Can search and AI systems crawl, index, retrieve, and associate the page with the question?
    • Selection: Does the page contain a direct answer, credible evidence, clear entities, and useful context?
    • Action: If a person reaches the page, is the next step relevant to the question that brought them there?

    A weakness at any gate limits the value of the other two. More schema will not fix an inaccessible page. Better rankings will not rescue an evasive answer. More citations will not create revenue if the cited page addresses an informational query but pushes an unrelated sales action.

    Build a query-to-page map before editing content

    1. Name the business outcome. Choose a concrete result such as a qualified inquiry, product evaluation, account creation, purchase, or successful implementation.
    2. Identify the decision stage. Decide whether the reader is defining a problem, comparing approaches, checking risk, validating a provider, or preparing to act.
    3. Write the question in the reader’s language. Use a complete question, not a two-word keyword. Record important constraints such as audience, use case, platform, location, or product category.
    4. Assign a primary answer page. Avoid making several pages compete to answer the same question. Create a separate page only when the intent, answer, or required evidence changes materially.
    5. Specify the proof. Record what will substantiate the answer: original data, a primary reference, product documentation, a transparent method, an expert byline, or a concrete example.
    6. Choose the next action. Match it to the reader’s stage. Someone defining a problem may need a diagnostic or related explanation; someone comparing options may need requirements, limitations, or implementation details.

    The resulting brief should identify the audience, decision, question set, direct answer, evidence, important entities, intended action, and success signal. This prevents a common failure mode: optimizing a page for a phrase without deciding what useful role the page is supposed to play.

    Turn each important page into a set of answer units

    A page-shaped slab separates into modular content cards that assemble into a compact answer object.

    An answer unit is a self-contained section that resolves one meaningful question. It is not a fragment written for a robot. It is a compact piece of useful reasoning that still makes sense if an AI system extracts it from the surrounding page.

    Build each answer unit in this order:

    • A descriptive heading: State the question or decision plainly instead of inserting a vague keyword label.
    • A direct opening answer: Give the conclusion before background, brand positioning, or a long definition.
    • The mechanism: Explain why the answer holds and what causes the result.
    • The evidence: Support factual claims with current, authoritative material or clearly described original evidence.
    • The boundary: State when the answer changes, what it does not cover, and which tradeoffs matter.
    • The next step: Tell the reader what to check, change, compare, or measure.

    For example, a section titled What is AI search marketing optimization? should not open with a history of search. It can answer directly: AI search marketing optimization combines technical discoverability, answer-focused content, entity clarity, supporting evidence, and performance measurement so a brand can be found and represented accurately in generated search experiences. The following paragraphs can then distinguish SEO, AEO, and GEO, explain their overlap, and show the reader what to implement.

    Use the extraction test when editing. Read the opening answer without its heading or previous paragraph. If words such as it, this, or they make the subject unclear, name the subject again. If the answer requires several paragraphs of setup, move the conclusion forward. If it makes an absolute claim but the explanation later introduces exceptions, put the most important qualifier in the answer itself.

    Clear headings, front-loaded answers, lists, tables, authoritative support, and plain language make information easier to parse and reuse. Apply each format according to its job. Use prose for reasoning, a list for a sequence or criteria, and a table only when a reader needs to compare repeated fields across several options.

    Do not turn every page into a wall of shallow questions. Keep related questions together when they support one decision. Split a section only when the reader would reasonably search for the answer on its own or when the answer needs distinct evidence. A coherent page provides context that isolated snippets cannot.

    Make evidence, entities, and schema tell the same story

    Readable formatting cannot compensate for unsupported claims. Before adding structured data, strengthen the page as a source. Give every important factual claim evidence that is appropriate to its weight. Explain the method behind original data. Link to primary authorities when they are available. Identify the author and relevant credentials. Remove or revise statistics that can no longer be verified.

    Entity clarity matters as much as sentence clarity. A company name, product name, author, service, location, and category should not change casually between the page copy, metadata, structured data, author profile, and other first-party pages. When several names are genuinely necessary, explain their relationship instead of expecting a machine to infer it.

    Schema markup can express those relationships in a machine-readable form. It is an interpretation aid, not a citation switch. Use a type because it truthfully describes the visible page, not because the type appears on an optimization checklist.

    Primary page jobPotential schema typeWhat the visible page must support
    Publish an editorial explanationArticleHeadline, author, publication details, dates, and the article body
    Answer recurring questionsFAQPageThe same questions and answers displayed to readers
    Teach a procedureHowToThe ordered steps, requirements, and relevant outcomes
    Establish organizational identityOrganizationConsistent name, URL, logo, and organizational details
    Describe a productProductAccurate product information that is also visible on the page

    Article, FAQ, HowTo, Organization, and Product markup can help machines interpret the purpose and structure of suitable pages. The markup still has to agree with the content. FAQPage markup attached to invisible answers, Product properties that contradict the offer, or an author entity with inconsistent names creates ambiguity instead of resolving it.

    Use this structured-data review before publishing

    • Choose the schema type that matches the page’s main visible purpose.
    • Include only properties that you can support with accurate, accessible information.
    • Use consistent names and identifiers for the page, author, publisher, organization, and product.
    • Make dates, prices, availability, steps, and other changeable details agree with the visible content.
    • Validate the JSON-LD syntax and review the meaning of the output, not just whether the validator reports an error.
    • Update structured data whenever the corresponding page content changes.

    Treat the content and JSON-LD as two expressions of one claim. If your team cannot agree on what the page is about, who created it, or what entity it describes, schema will encode the disagreement rather than solve it.

    Measure citations without losing sight of business value

    Two measured pathways lead from a generated answer to source-reference tokens and to a qualified business outcome.

    Ranking reports alone cannot show whether an AI system names, cites, or accurately describes your brand. At the same time, a citation count cannot tell you whether the underlying questions matter commercially. Your scorecard needs visibility, representation, and outcome metrics.

    Competition for a citation can be tight because generated answers may use only two to seven cited sources on average. That makes the denominator important. Ten citations mean little without knowing the number and value of the prompts tested.

    Create a repeatable prompt panel

    1. Select prompts from the query-to-page map rather than inventing a disconnected list for the tracking tool.
    2. Record the AI product, exact prompt, relevant market or account context, and test date.
    3. Capture the generated answer and its cited links. Do not record only a yes-or-no visibility score.
    4. Label each result separately as a brand mention, linked citation, recommendation, comparison inclusion, or no appearance.
    5. Judge whether the answer attributes facts correctly and represents the brand, product, and limitations accurately.
    6. Annotate content, schema, technical, and distribution changes so movement can be connected to a plausible intervention.
    7. Repeat comparable observations before treating movement as a trend. A single generated response is an observation, not a stable performance conclusion.

    Use that panel to calculate metrics with clear definitions:

    • Answer presence: The share of tracked prompts in which the brand or domain appears.
    • Citation rate: The share of tracked prompts that include a link to your domain.
    • Citation share: Your cited appearances compared with the cited appearances of the competitors in the same panel.
    • Attribution accuracy: The share of appearances that assign claims, products, capabilities, and limitations correctly.
    • Qualified engagement: The behavior of detectable AI referrals on the destination page, interpreted in the context of the query.
    • Business contribution: Leads, purchases, assisted conversions, pipeline, retention, or another outcome chosen before optimization begins.

    Not every AI-influenced visit will arrive through an easily labeled referral. A person may read an answer and return later through branded search or a direct visit. Treat observable referrals as one signal, preserve campaign and conversion tracking where possible, and avoid claiming attribution that the data cannot support.

    Measurement should stay connected to genuine business goals. Set diagnostic rules before you review a test. If citations rise but qualified engagement does not, inspect query relevance, the destination page, and the next action. If mentions rise while accuracy falls, repair explicit facts and entity consistency. If visibility remains absent, check crawlability, indexing, topical coverage, evidence, and the strength of competing answers before rewriting everything.

    Keep AI automation inside accountable guardrails

    AI can accelerate query clustering, outlining, extraction, schema drafting, content review, and monitoring summaries. It can also reproduce an incorrect premise across many pages faster than a manual workflow. Scale the review system with the production system.

    Assign each automated task a risk level. Internal ideation and formatting are usually easier to reverse. Public factual claims, structured data, live publishing, customer information, and campaign spending deserve tighter controls because an error can affect trust, privacy, visibility, or money.

    Before automating a workflow, document:

    • The owner: One person or role remains accountable for the released result.
    • The permitted inputs: Specify which documents and data the system may use, including information that must never enter the workflow.
    • The success condition: Name the business or quality improvement the automation is expected to produce.
    • The failure condition: Define what would stop publication or trigger a rollback, such as an unsupported claim, conflicting schema, privacy exposure, or a material brand error.
    • The review point: Identify where a qualified person checks facts, meaning, brand fit, ethics, and technical validity.
    • The recovery path: Preserve versions and know how to remove or replace a faulty output.

    Accountability remains with the marketer and organization, even when a model produced the draft or a platform executed the change. Governance is therefore part of search optimization, not a separate administrative concern. The person responsible for performance should participate in decisions about data use, approvals, brand safety, and monitoring.

    Key takeaways

    • Optimize for a specific audience decision and assign one primary page to answer it.
    • Write self-contained answer units that lead with the conclusion, explain the mechanism, show evidence, and state important limits.
    • Use structured data only when it accurately mirrors visible content and stable entity relationships.
    • Track mentions, citations, citation share, attribution accuracy, qualified engagement, and business contribution separately.
    • Benchmark a fixed prompt panel before changing a page so later observations have a meaningful comparison point.
    • Give every AI-assisted workflow an owner, permitted inputs, review point, failure condition, and recovery path.

    Start with one page tied to qualified demand. Build its query brief, rewrite its highest-value answer sections, align the evidence and JSON-LD, and benchmark the relevant prompts before publishing the change. That gives you a controlled learning loop you can improve and repeat, rather than a collection of disconnected AI tactics.

    References