Tag: AI Search

  • Link Building Strategy for 2027: Earn Authority, Not Volume

    Link Building Strategy for 2027: Earn Authority, Not Volume

    If your link building plan still begins with a target number of backlinks, 2027 is going to be expensive. You may fill a report with placements while earning little attention, trust, referral traffic, or visibility in the searches that influence buyers.

    A stronger plan starts with a different question: what can your brand publish, reveal, or explain that an editor would independently choose to reference? That shift turns link building from an inventory exercise into a disciplined combination of content strategy, digital PR, audience research, and relationship building.

    Key takeaways

    • Treat a backlink as one possible result of earning editorial attention, alongside brand mentions, referral traffic, social discovery, journalist relationships, and leads.
    • Build campaigns around original evidence, useful expertise, or a timely consequence. A company announcement is not automatically a story.
    • Evaluate publications by topical relevance, audience fit, editorial standards, and narrative fit. A third-party authority score cannot replace those checks.
    • Use competitor backlinks to find publications and recurring interests, then develop an angle competitors cannot reproduce.
    • Use AI to accelerate research, organization, and controlled drafting. Keep story selection, factual review, personalization, and final approval under human judgment.
    • Measure business and editorial outcomes separately from link counts. A placement should have a credible route to attention, trust, discovery, or demand.

    Set the outcome before choosing the link tactic

    Links still matter, but a link is not the whole return. A genuinely earned placement can expose your brand to a publication’s audience, create a relevant brand mention, attract referral visits, support social discovery, and associate your expertise with a subject. That is why earned placements can produce value beyond the hyperlink itself.

    Choose a primary campaign outcome before you create anything. If the goal is authority in a category, you need relevant editorial association. If the goal is qualified referral traffic, you need a publication read by potential buyers and a natural reason for them to continue to your site. If the goal is leads, the referenced page must help a visitor take the next step. If the goal is AI-search visibility, you need clear, public, topical evidence about your brand, while recognizing that no individual link can guarantee a citation in an AI-generated answer.

    This distinction changes prospecting. A site with an impressive authority metric but no real editorial process, topical connection, or relevant readership is not equivalent to a respected publication that covers the problem you solve. The first may add a row to a spreadsheet. The second can make your brand easier for people and systems to understand in context.

    Decision factorProceed whenReject or revise when
    Topical relevanceThe publication regularly covers the question your campaign answers.The only attraction is a high third-party domain metric.
    Audience fitIts readers include people who influence, use, or recommend your category.You cannot explain why its audience would care.
    Editorial credibilityEditors select, shape, and verify what appears.Placement is effectively for sale and editorial scrutiny is absent.
    Story fitYour evidence or expertise advances an existing beat or timely conversation.The pitch merely announces that your company did something.
    Compounding valueThe coverage can earn referrals, mentions, relationships, reuse, or demand as well as a link.The placement has no plausible value after the backlink is logged.

    Write these criteria into the campaign brief. They give your team permission to decline an irrelevant placement even when it looks attractive in a link report.

    Build an asset around a story someone else can use

    Hands organize blank research cards, photographs, and geometric tokens into a polished folder on a worktable.

    The hardest part of link building is not sending the email. It is creating a defensible reason for the email to exist.

    A new hire, product launch, funding event, or executive profile is an announcement until you connect it to a consequence that matters outside your company. The usable story might be a problem the product exposes, an unexpected change visible in company data, a practical answer from a qualified expert, or a timely pattern affecting the publication’s readers. Product praise is not evidence, and an executive biography is not a reader benefit.

    Apply the story test before producing the asset

    • Reader value: What can the publication’s audience understand, decide, or do after seeing this?
    • Novelty: What does your brand know, observe, or possess that is not already available in interchangeable articles?
    • Proof: Can an editor inspect the underlying data, method, example, or expert reasoning?
    • Timing: Why is this useful in the current conversation rather than at an arbitrary publishing date?
    • Editorial independence: Would the central insight remain interesting if the company description were reduced to a short attribution?
    • Reference value: Is there a specific chart, finding, explanation, tool, or page worth citing?

    If the idea fails several of these checks, polishing the pitch will not rescue it. Improve the evidence or choose a more useful angle before outreach begins.

    Originality does not require spectacle. Your strongest inputs are often the ones already inside the organization: proprietary data, recurring customer questions, specialist knowledge, product usage patterns, or a company decision that reveals a broader market change. The important condition is that you can support the claim and explain why it matters to someone who is not buying from you.

    Run a deliberate production sequence

    1. Write the reader’s question in plain language.
    2. Identify the evidence or expertise that can answer it.
    3. Check what has already been published so you do not recreate a familiar asset with a new headline.
    4. Define the finding, consequence, and appropriate limitations before drafting promotional copy.
    5. Create the referenceable page, including enough context for an editor to verify and accurately describe the point.
    6. Develop distinct pitch angles for the relevant publication types and beats.
    7. Prepare a concise fact sheet so every pitch, interview, social post, and follow-up uses consistent claims.

    Do not manufacture overlapping assets merely to maintain a publishing cadence. Repeating the same idea across multiple weak pages divides attention and leaves journalists with no clear canonical resource to cite. A durable asset that can be refreshed when new evidence or a relevant news event appears is usually more useful than a queue of near-duplicates.

    Schema markup can clarify the entity, author, dates, and content type represented on your own page. It cannot turn recycled material into original evidence or convert a purchased placement into an editorial endorsement. Structured data supports clarity; the story still has to earn attention.

    Prospect for editorial fit, then pitch with restraint

    One professional offers a single blank dossier to an editor while a stack of generic envelopes sits ignored in the background.

    Competitor backlink profiles remain useful, but treat them as maps rather than instructions. They can reveal publications covering your market, journalists with relevant beats, recurring story formats, and subjects that attract citations. They cannot give you a distinctive reason to be covered.

    For every promising competitor placement, ask what was actually newsworthy. Then look for the missing question, newer evidence, stronger method, different audience consequence, or expert perspective your organization can credibly supply. The direction is supported by a reported survey in which 66.6% of SEO professionals favored finding unique opportunities over replicating competitors’ backlink profiles.

    Your prospect list should record why each contact belongs on it. Capture the journalist’s beat, relevant previous coverage, the audience connection, the angle you intend to offer, and the evidence that makes the pitch credible. If the only personalization available is a first name and publication name, the prospecting is not finished.

    Put AI behind an editorial gate

    AI can help cluster coverage themes, organize prospect notes, extract common questions, compare angle variants, and turn an approved brief into draft outreach. That speed is useful only after the strategy is sound.

    Do not let an automated system invent personalization, infer facts about a journalist, or send unreviewed pitches at scale. Inboxes already contain large volumes of similar machine-written outreach. Increasing output without improving relevance scales rejection and can damage the relationships you need for future campaigns.

    • Give the system an approved evidence pack rather than unrestricted permission to create claims.
    • Require every draft to state the finding and reader consequence before mentioning the company.
    • Remove empty compliments, generic trend language, exaggerated adjectives, and invented familiarity.
    • Verify names, beats, publication fit, claims, and links before sending.
    • Keep the final decision with a person who can judge whether the pitch deserves the recipient’s attention.

    A strong pitch makes the editorial decision easy to evaluate. Lead with the relevant finding or consequence. Explain why that contact’s readers are affected. State what evidence, expert access, or usable material is available. Then stop. A long company history, feature list, or generic offer to collaborate forces the recipient to search for the story you should already have identified.

    Relationship building happens through repeated relevance, not repeated reminders. Record useful feedback, respect a clear rejection, and return only when you have a genuinely suitable angle. A journalist who trusts your accuracy and restraint is a more durable asset than a large list of contacts receiving interchangeable messages.

    Measure whether the campaign earned real authority

    A raw link count cannot tell you whether a campaign worked. It treats an editorial citation read by your market as equivalent to a placement on a site created to sell links. Your reporting should preserve the difference.

    Record the immediate editorial result: publication, topical context, linked or unlinked brand mention, destination page, publication audience fit, and whether the placement produced referral activity. Then track the outcomes tied to the campaign brief, such as qualified visits, leads, branded discovery, subsequent coverage, social distribution, or reuse of the asset.

    For AI-search monitoring, use a stable set of relevant questions and record whether your brand, domain, or campaign evidence appears. Treat movement as a visibility observation, not proof that a particular backlink caused an answer to change. AI outputs vary, and an isolated appearance is not a reliable attribution model.

    Also measure what the team learned. Note which angles earned replies, which evidence editors questioned, which publications produced useful audiences, and which relationships opened a credible path to later coverage. Feed those observations into the next campaign. The value of disciplined digital PR compounds partly because your team stops repeating weak ideas and begins recognizing the structures that work for its market.

    Use clear stop and continue rules

    • Continue: The asset remains accurate, distinctive, and useful, and new events create legitimate reasons to revisit it.
    • Revise: Well-matched contacts understand the topic but consistently cannot see the finding, consequence, or evidence.
    • Consolidate: Multiple campaign pages compete to explain the same idea and none is the obvious reference. Preserve valuable URLs and existing search equity when planning any consolidation.
    • Stop: The tactic depends on undisclosed purchasing, fabricated authority, irrelevant placements, or volume that the team cannot review responsibly.

    Purchased links can create impressive-looking metrics while providing no genuine audience, editorial judgment, or relationship. Sites with backlink profiles dominated by purchased placements were among those reported as hardest hit during the second wave of Google’s March 2026 spam update. Even before algorithmic risk enters the calculation, a placement with no reader or editorial value is a poor use of budget.

    Start your 2027 plan with the market question your organization is best equipped to answer. Build the most defensible version of that answer, choose publications whose readers genuinely need it, and give editors a precise reason to reference it. When the story, evidence, audience, and outreach align, the link becomes evidence of authority rather than a substitute for it.

    References


  • Image Optimization for AI Search: A Practical Workflow

    Image Optimization for AI Search: A Practical Workflow

    Your images can be attractive, fast and conventionally SEO-friendly yet still be unclear to an AI system. If the system cannot identify the main object, read an important label or connect the scene to the claims on the page, the image contributes little to a multimodal answer.

    Fixing that problem does not mean putting more keywords into filenames. It means making the pixels, alternative text and visible page copy tell the same specific story. The workflow below will help you decide what each image must communicate, test whether that meaning survives machine interpretation and correct the failures that matter.

    AI search needs an image it can retrieve and explain

    Visual search is no longer a secondary way to browse an image index. People run roughly 20 billion visual searches through Google Lens each month. A search can begin with a camera, an uploaded image or a screenshot when the user cannot easily describe the object in words.

    That changes the optimization target. The old question was whether an image could rank for a text query. The additional question is whether a system can use the image to understand the query, retrieve the associated page and assemble a supported answer.

    Google filed a patent application in 2023, published in April 2026, describing a flow in which an image match identifies a cited page before surrounding text is used to construct an answer. That is not confirmation of a live production ranking process. Patent applications may never be implemented as written. It is still a useful design signal: an image may help a system discover the page whose text supplies the explanation.

    Treat every important image as a paired asset: the visual evidence and the page evidence. Before publishing it, ask four questions:

    • Can the system access and render the image when it retrieves the page?
    • Can it identify the primary product, person, place, condition or process without relying on the filename?
    • Can it read any visible text that is necessary to distinguish a model, package, measurement or state?
    • Does the surrounding HTML text confirm what the image shows and explain why it matters?

    If the image fails the second or third question, fix the asset or choose another one. Metadata cannot rescue a photograph whose subject is tiny, obscured or visually ambiguous. If it fails the fourth question, improve the page copy. A model should not have to infer a critical fact from pixels alone.

    Run two audits: what is visible, then what it implies

    An orange trail shoe is shown under a magnifying lens on one side and beside a rocky path, mud, and a water bottle on the other.

    A useful image audit separates literal recognition from implied meaning. Combining them too early hides the cause of a failure. You may think an image communicates expert installation, for example, when a machine sees only a person standing beside a cabinet.

    Audit the literal contents without page context

    Start with denotation: the objects and attributes that can actually be pointed to in the frame. Hide the headline, caption, filename and surrounding copy. Then write a neutral inventory of what is visible.

    For a product photograph, that inventory might include a stainless steel coffee maker, a thermal carafe, a control panel and a visible model label. For a service photograph, it might include a leaking pipe joint, a wrench and a technician wearing protective gloves. Keep interpretation out of this first pass. Words such as premium, reliable and professional are conclusions, not visible objects.

    Now ask a capable multimodal model for a literal description using a neutral instruction such as: “List the objects, visible text, materials, conditions and relationships in this image. Do not infer facts that are not visually supported.” Compare its output with your own inventory and with the visual brief.

    This is a diagnostic check, not a simulation of any particular search engine. Different models can produce different descriptions, and one successful response does not prove retrieval or citation. The test is still valuable because a missed primary object exposes an avoidable ambiguity in the image.

    When an essential object or attribute is missed, inspect the likely visual cause:

    • The primary subject occupies too little of the frame.
    • Another object has stronger contrast and becomes the apparent subject.
    • The item is partly hidden, cropped or viewed from an angle that conceals its defining shape.
    • Several similar objects overlap, making their boundaries unclear.
    • Glare, shallow focus or compression makes packaging text unreadable.
    • The rendered website crop removes information that was present in the original file.

    Fix composition before metadata. Use a clearer angle, tighter crop, simpler background, additional close-up or separate detail image. Product galleries should not make one wide lifestyle photograph perform every recognition task.

    Audit the meaning created by the composition

    The second pass examines connotation: what the combination of objects, people and setting implies. This is where co-occurrence matters. A wrench beside a visibly damaged fitting tells a different service story from the same wrench lying on a spotless workbench. A team portrait in an identifiable office says something different from anonymous people in a generic meeting room.

    Write the intended meaning in one sentence. Then underline the visible evidence that supports every part of it. If the intended meaning is “a technician diagnosing a leaking kitchen connection,” the frame should contain a technician, a relevant connection and evidence of the leak. If only the kitchen is visible, the image is decorative context rather than proof of the service.

    Use these questions to expose weak or accidental implications:

    • What is the most prominent entity, and is it the entity the page is about?
    • What relationship between the visible entities would a neutral viewer infer?
    • Which object introduces an unrelated interpretation?
    • Does the setting support the intended use case, location or audience?
    • Are you asking the image to prove a credential, performance claim or identity that only text can establish?

    Original imagery matters most when the image is supposed to establish identity or evidence. A stock photograph can illustrate a general concept, but it cannot reliably prove what your product looks like, who works on your team, where your business operates or how your service is performed. Use visible page copy to name people, roles, credentials and locations rather than expecting a model to infer them from appearance.

    Give each page type a deliberate visual job

    An image should be briefed against the decision a visitor is making on that page. The same attractive photograph will not serve a homepage, product page and technical explainer equally well. Different page types require different visual evidence, especially when a multimodal system may use that evidence to interpret the surrounding content.

    Page typePrimary visual jobWhat the image should make detectableWhat the page text should confirm
    HomepageEstablish the brand and offeringAn original product, location, team or use context rather than an interchangeable mood imageThe brand name, principal offering and relationship between the visible entities
    Product pageSupport identification and comparisonThe complete product, multiple angles, distinctive parts, packaging and legible model or variant textProduct name, variant, materials, dimensions and other attributes relevant to the image
    Blog or information pageExplain a concept, process or claimClearly labelled steps, components, states or relationships in a diagram or infographicEvery substantive claim shown in the graphic, written as ordinary machine-readable HTML text
    About or team pageConnect a person with an organization and roleA clear portrait or authentic workplace contextThe person’s name, role, credentials and authorship relationship where relevant
    Service pageShow the problem, work or outcomeThe actual condition, equipment, process or clearly differentiated before-and-after statesThe service performed, the meaning of each state and any necessary limitations
    Contact or location pageReinforce physical identity and placeThe exterior, entrance, interior or recognizable local contextThe business name, address and relationship between the pictured place and the business

    Give each image one primary job even when it can support several queries. A product hero can establish the overall shape; a second image can expose controls; a third can make the package label readable. This is clearer than forcing a single distant photograph to carry every attribute.

    Be especially careful with infographics and before-and-after images. Do not leave the claim inside the graphic. Repeat it in the page copy, identify which state is which and explain what changed. The image can demonstrate the relationship, while the text supplies the exact claim and its qualifications.

    Publish the image and page as one semantic unit

    A red insulated bottle, its studio photograph, a blank article layout, and a transparent lens are connected by soft blue light on a desk.

    Write a visual brief before choosing the asset

    A useful visual brief is short enough to apply during a content review. For each important image, record:

    • Target question: the query or decision the visual should help resolve.
    • Primary entity: the product, person, place, condition or process that must be recognized.
    • Must-detect details: the visible attributes needed to distinguish the entity or explain the answer.
    • Must-read text: labels or packaging copy that must remain legible in the delivered image.
    • Intended implication: the relationship or use case the composition should communicate.
    • Supporting sentence: the nearby HTML text that names and explains what the image shows.
    • Failure condition: the omission or misreading that would make the image misleading or useless.

    This brief prevents a common mismatch: copy written around a concrete answer paired with an image selected for atmosphere. It also gives designers, photographers, writers and SEO teams one set of acceptance criteria.

    Preserve meaning through the technical delivery

    Traditional image hygiene still matters, but each choice should preserve recognition as well as performance. Use a descriptive filename because it provides context, not because a keyword-rich filename can override the pixels. Supply responsive dimensions and an appropriate format, then inspect the image as it actually appears on the page.

    Compression deserves a visual check at every important breakpoint. A package label that is crisp in the master file may become unreadable in a smaller responsive variant. Performance optimization should preserve the legibility of product text, labels and diagram annotations that a system needs to interpret the image.

    Use loading settings that improve page performance while keeping the image available when the page is rendered and retrieved. Check the delivered page rather than assuming the media library preview represents what a crawler or visitor receives.

    Write alternative text for accuracy and accessibility

    Alternative text should describe the image’s purpose in its page context. Keep it natural and factual. Do not turn it into a string of search terms, and do not insert claims the pixels do not support.

    For example, “Stainless steel coffee maker beside its thermal carafe, with the model name visible on the front panel” is useful when those details help the reader understand the product. “Coffee maker, best thermal brewer, premium coffee machine” is neither a reliable description nor good accessible text.

    Complex diagrams need more than a long alt attribute. Give the image a concise accessible description, then explain the important steps, comparisons or claims in visible HTML text. A decorative image that contributes no information should use the appropriate empty alternative text rather than forcing irrelevant keywords onto screen-reader users.

    Run the final check on the rendered page

    Use this sequence before publishing or replacing a high-value image:

    1. Write the target question and the one visual fact that helps answer it.
    2. List the entities, attributes and text that must be detectable in the frame.
    3. Inspect the image without page context and record a literal human description.
    4. Run the same blind description through at least one multimodal model and note omissions or competing interpretations.
    5. Correct the crop, angle, clutter, visibility or export quality before changing metadata.
    6. Confirm that the alt text and nearby page copy accurately name what is visible and carry every important claim.
    7. Test the delivered image at the page’s actual responsive sizes, including the legibility of labels and annotations.
    8. Save the intended query, observed description and corrections so that later asset changes can be reviewed against the same brief.

    After publication, use a fixed set of visual and text queries when checking search or AI-answer visibility. Record whether the image appears, whether the associated page is cited and whether the answer describes the intended attributes accurately. An appearance is evidence of visibility, not proof that one metadata change caused it, so compare repeated checks rather than drawing a conclusion from a single result.

    Key takeaways

    • Optimize the visual evidence and the page evidence together; neither should contradict or depend on the other to repair ambiguity.
    • Test literal recognition before judging brand meaning. If the primary entity is missed, fix the composition first.
    • Control co-occurrence deliberately. Every prominent object and person in the frame contributes to the meaning a model may infer.
    • Assign images different jobs by page type: identification on product pages, explanation on information pages and entity confirmation on team or location pages.
    • Repeat substantive graphic claims in visible HTML text. Important facts should not exist only inside pixels or alternative text.
    • Compress for performance while checking the actual delivered crop, resolution and text legibility.
    • Treat multimodal model descriptions as diagnostic observations, not guarantees of ranking, retrieval or citation.

    Start with five pages that matter commercially or editorially. Hide the copy, inspect each rendered image and ask what a neutral observer can actually identify. Replace or recompose the images that fail that blind test, then align the alternative text and nearby copy with what remains. That small, documented audit gives you a repeatable standard for every visual you publish next.

    References

  • Reddit-Driven Keyword Research: A Practical SEO Workflow

    Reddit-Driven Keyword Research: A Practical SEO Workflow

    If your keyword list keeps returning minor variations of the same head terms, it is probably missing the questions people ask when a decision becomes complicated. Reddit’s Google rankings expose those questions, along with the objections, conditions and comparisons that conventional keyword lists often flatten.

    The goal is not to copy Reddit, manufacture a discussion or treat anonymous comments as evidence. You are using Reddit’s organic footprint as a query-discovery layer: find conversations that search engines already surface, identify the need behind each query and publish a more accountable answer on the right page.

    Key takeaways

    • A Reddit ranking is a demand signal, not proof that the discussion is accurate. It tells you that Google currently considers the conversation relevant to the query.
    • Validate Reddit’s importance in your market before building a large report. Some narrow, regulated and highly technical categories produce very little useful data.
    • Start with three to five non-brand themes, export Reddit’s top-10 rankings and tighten the filter to the top three when a theme produces an unmanageable list.
    • Do not turn every keyword into a new URL. Group queries by the decision, obstacle or outcome behind them, then choose between updating a page, creating a page, adding a useful FAQ or skipping the opportunity.
    • Your advantage is editorial accountability: a direct answer, explicit conditions, verified claims and a structure that helps the reader make a decision. You do not need to imitate a thread.

    Decide whether Reddit deserves a place in your dataset

    Reddit is large enough to justify a test. An August Semrush snapshot put reddit.com at roughly 166 million ranking keywords, including more than 10 million in position one, 31 million in the top three and 65 million on page one. Those numbers explain why Reddit can matter; they do not prove that it matters in your particular market.

    The useful question is narrower: does Reddit rank prominently for non-brand queries that your customers use while researching, comparing, troubleshooting or validating a decision? Run a small feasibility check before you commit time to a full gap analysis.

    Run a 30-minute feasibility check

    1. Choose two or three core non-brand themes tied directly to what you sell or explain. Use customer language, not an internal product taxonomy.
    2. In Semrush, enter reddit.com in Domain Overview and open its Organic Research data.
    3. Filter keywords for one theme at a time and restrict positions to the top 10.
    4. Review the results for relevance. Do not judge the opportunity from the raw row count alone.
    5. Record a go, narrow or stop decision for each theme before exporting anything at scale.

    Proceed when the results contain several distinct customer problems, prominent Reddit rankings and questions your organization can answer credibly. Narrow the theme when a broad word creates unrelated meanings, locations, brands or acronym collisions. Stop when the list is thin, mostly irrelevant or disconnected from any useful reader action.

    This gate matters because Reddit’s influence is uneven. Consumer products, software, travel and other categories with opinionated buying decisions can generate extensive gaps, while niche B2B, highly technical, regulated or unusually narrow subjects may produce much smaller ranking sets. A small set is not a failed analysis. It is evidence that your time may be better spent on another discovery channel.

    You do not need to create a Reddit account or participate in a community for this workflow. The ranking analysis can be completed with a Semrush login and an initial time box of about two hours. Participation, community management and keyword discovery are separate jobs; do not bundle them into one strategy by default.

    Build a focused export instead of a keyword warehouse

    A sorting sieve filters a large stream of blank query cards into a small, organized tray of selected research cards.

    A useful export is deliberately constrained. If you begin with every Reddit ranking that loosely touches your industry, you will spend the session cleaning rows rather than learning what people need. Work theme by theme and preserve the context that produced each set.

    Use a repeatable report recipe

    1. Open Semrush Domain Overview for reddit.com and move to Organic Research.
    2. Under Advanced Filters, select Include, Keyword and Containing.
    3. Enter one core non-brand phrase. A specific category phrase is usually easier to judge than a single broad word.
    4. Set the position filter to Top 10 and apply it.
    5. Export the results to Excel.
    6. Repeat the process for each of your three to five initial themes.

    The top-10 filter is a practical starting point because it captures queries where Reddit already has meaningful first-page visibility. If a broad theme returns far more rows than you can review, restrict it to the top three. If a narrow theme is genuinely relevant but sparse, loosen the position cutoff. The right filter is the one that leaves you with a list a person can inspect, not the one that produces the largest spreadsheet.

    Keep the first pass to three to five themes. You need enough variety to see patterns, but not so much data that you begin making decisions from volume and position alone. Once you have classified one batch consistently, you can expand with better judgment.

    Add the columns that turn rankings into decisions

    Keep an untouched tab containing the raw export. In a working tab, retain the exported metrics and add these editorial columns:

    • Capture date: Reddit’s visibility can change, so every export needs a timestamp.
    • Theme: preserve the filter that surfaced the query, even after files are merged.
    • Query: keep the wording exactly as exported.
    • Reddit position and ranking URL: record the result that created the opportunity.
    • Search intent: label the job as learning, comparing, selecting, troubleshooting or validating.
    • Audience and context modifiers: note experience level, use case, constraint, location or other condition present in the query.
    • Underlying question: rewrite the query as the full question a reader appears to need answered.
    • Current site URL: identify the best existing page, if one exists.
    • Coverage: mark the question as fully answered, partially answered, mentioned only or missing.
    • Recommended action: update, create, add to an FAQ, monitor or skip.
    • Priority reason: state in one sentence why the opportunity deserves resources.

    When a query appears in more than one theme, keep one working row and retain all relevant theme labels. Do not erase the overlap: it may reveal that the same customer question connects product categories your site currently treats as separate silos.

    Start with non-brand themes because they expose category demand without assuming the searcher already knows you. Branded Reddit analysis can be valuable later for reputation, support and product-feedback work, but mixing it into the first export makes content-discovery decisions harder to interpret.

    Convert ranking rows into defensible content decisions

    An analyst aligns transparent layers of search results, discussion patterns and editorial brief cards to isolate one highlighted content opportunity.

    A keyword is not a content brief, and a ranking gap is not an automatic instruction to publish. The row only earns a place on your roadmap after you understand what the ranking result is satisfying and whether your site has an appropriate answer.

    Inspect the conversation behind priority queries

    Open the ranking result for the most relevant, highest-positioned queries. You are not looking for sentences to reuse. You are looking for the anatomy of the problem:

    • What did the person ask in the title, and what additional constraint appeared in the body?
    • Which comparison criteria recur across the useful replies?
    • What objection, failure mode or exception changes the answer?
    • Where do participants disagree, and does the disagreement come from different circumstances?
    • Which terms do people use naturally that your current page avoids or replaces with internal language?
    • What remains unresolved after reading the conversation?

    Treat personal experiences as clues about questions and conditions, not as verified facts. A repeated anecdote may justify investigating an issue, but it does not justify repeating the claim on an accountable brand page. Verify factual, technical, financial, legal or health-related statements with suitable authoritative evidence before publishing them.

    Cluster by the reader’s job, not by shared words

    Two queries belong on the same page when one answer can satisfy both without changing the audience, primary decision or required evidence. They probably need separate pages when they ask different primary questions, apply to materially different situations or lead to different next actions.

    Use broad intent labels only as a first cut. Within a comparison cluster, for example, distinguish between choosing an option, understanding a tradeoff and checking whether a prior choice was a mistake. Those may contain the same nouns while requiring very different answers.

    Run Semrush Keyword Gap between your domain and reddit.com for each retained theme. Use it to separate three practical states: Reddit ranks and you do not; both domains rank but Reddit is stronger; or your site already performs competitively. Then inspect the actual page before declaring a gap. A ranking URL can exist while answering the wrong intent, burying the answer or mentioning the subject without resolving it.

    Choose the smallest content action that fully answers the need

    What you findContent decisionWhat to change
    An existing page serves the same audience and primary intent but leaves an important condition unanswered.Update the existing page.Add the direct answer, decision criteria, exceptions and supporting evidence without creating a competing URL.
    The query represents a distinct primary problem and no current page can own it cleanly.Create a new page.Build the page around the reader’s complete task, then connect it to relevant parent and sibling pages.
    The question is narrow, recurring and subordinate to a broader page.Add a visible FAQ or supporting section.Answer it where readers already need it. Add it to a reusable FAQ library only if the same answer remains valid across the intended contexts.
    Your page ranks, but its format or opening does not match the apparent intent.Rework the existing answer.Move the conclusion forward, clarify who it applies to and restructure the page around the actual decision.
    The query is irrelevant, outside your expertise or impossible to answer without unsupported claims.Skip it.Record the reason so the row is not reconsidered every time the analysis is refreshed.

    Prioritize the rows where four signals align: Reddit ranks prominently, the query fits your audience, your current coverage is weak and you can produce a materially better answer. Search volume can help order otherwise similar opportunities, but it should not rescue a query with poor business fit or tempt you into a thin page.

    For each approved cluster, write a one-page brief containing the target problem, audience conditions, direct answer, required evidence, content action, relevant internal links and the result you will measure. This forces the team to fund an answer rather than a keyword count.

    Publish the missing answer and measure the right change

    Reddit often earns visibility because a conversation addresses the messy version of a question: the tradeoffs, failed attempts and contextual details that polished category copy omits. You cannot reproduce peer discussion on demand, and you should not pretend to. You can produce a clearer, better-supported answer that accepts responsibility for its claims.

    • Answer the primary question in the opening paragraph. Do not make the reader cross a history lesson before reaching the conclusion.
    • State who the answer applies to and which conditions could change it.
    • Organize comparisons around criteria a reader can use, not a list of products followed by interchangeable descriptions.
    • Convert anecdotal concerns into questions to verify. Publish the verified conclusion and preserve any real uncertainty.
    • Address the strongest objection or failure mode in the main body rather than hiding it in a closing FAQ.
    • Use the audience’s natural terminology where it is accurate, but do not force every exported wording variation into headings.
    • Give each distinct subquestion one direct, self-contained answer. This helps readers scan the page and gives search and answer systems an unambiguous passage to interpret.
    • If you add structured data, make it describe the visible page accurately. Markup can clarify structure; it cannot compensate for an answer the page never provides.

    The same opportunity set matters beyond conventional results. More than 35 million of Reddit’s ranking keywords in the August snapshot triggered AI Overviews, with Reddit cited in more than 15 million of them, a reported citation rate of about 46%. That makes the export a useful list of queries to monitor in generative search. It does not mean that copying Reddit’s phrasing, adding FAQ markup or publishing a page will cause an AI system to cite you.

    Create a baseline before changing content. For each approved cluster, record the date, query, Reddit URL and position, your ranking URL and position, the presence of an AI Overview and the page action you intend to take. Preserve that snapshot alongside the brief.

    1. Publish or update one coherent cluster at a time, and annotate the release date.
    2. Recheck the same query set after search engines have had time to recrawl the affected pages and your normal reporting window contains usable data.
    3. Compare rankings, impressions, qualified visits and the conversion or engagement action appropriate to the page.
    4. Check the relevant generative results separately. Record whether your brand or URL appears, but do not merge that observation with ordinary organic position.
    5. Keep, expand, consolidate or retire the work based on the intended outcome. Do not declare success merely because the page was indexed.

    Reddit does not have to disappear from the result for your work to succeed. A useful outcome may be a stronger existing URL, ownership of an adjacent intent, qualified traffic or a page that becomes eligible for citation alongside community discussion. Measure the opportunity you chose, not a blanket promise to displace an entire platform.

    Start with three non-brand themes and give the first pass two hours. If the feasibility check is thin, close the file and redirect the effort. If it is rich, choose the first cluster where relevance, coverage gap and answer credibility all line up, then fix that answer before expanding the spreadsheet.

    References

  • AI Watermarks: What Actually Matters for Search Quality

    AI Watermarks: What Actually Matters for Search Quality

    You are about to publish an AI-assisted page, and a watermark or detector score has turned an editorial decision into an SEO worry. The useful question is not whether a machine touched the draft. It is whether the finished page earns its place in search results and AI-generated answers.

    Treat the watermark as a clue about production, then audit the work itself. That keeps your attention on the failure modes that can damage visibility and trust: unsupported claims, recycled ideas, generic advice, near-duplicate pages, and automation without accountable review.

    A watermark describes provenance, not quality

    A machine-readable watermark associated with Claude-generated text can indicate that AI participated in the production process. It cannot tell a reader who originated the idea, how much of the finished work came from the model, whether its claims are correct, or whether the page is useful.

    Those questions belong to three separate layers:

    SignalWhat it can tell youWhat it cannot establish
    AI watermark or provenance markerAn AI system participated somewhere in generationOriginality, accuracy, usefulness, or the extent of human contribution
    AI detector scoreA tool estimates that the text resembles patterns it checksCertain authorship, reader value, or search quality
    Byline or author markupA named person or organization accepts ownershipThat the information is distinctive or deserves citation

    Conflating these layers leads to the wrong work. A team may rewrite sound sentences solely to reduce a detector percentage while leaving weak reasoning, unverified claims, and duplicated ideas untouched. The page then looks less detectable without becoming more valuable.

    AI use also is not one uniform editorial practice. Asking a model to organize your notes, challenge an argument, expose missing questions, or improve a draft is materially different from publishing its first response. In both cases, however, the publisher remains responsible for the result. If you would be uncomfortable defending the page once its AI involvement became visible, send it back through editorial review instead of trying to disguise the workflow.

    Search risk comes from low-value automation, not AI involvement alone

    Google has not treated AI authorship as an automatic reason to penalize content. Its relevant distinction is what automation produces and why it was produced. Generative AI can help with research and structure. The problem emerges when automation is used to manufacture large amounts of low-value material primarily to manipulate rankings.

    That is the mechanism behind the SEO risk. Giving a model broad publishing autonomy makes it cheap to produce generic recommendations, unsupported assertions, lightly altered pages, and summaries of information already present throughout the search results. Scaling those defects does not create authority. It multiplies reasons for search systems and readers to ignore the site.

    There is likewise no universal rule that a Claude watermark excludes a page from AI-generated answers. Answer engines still need material worth retrieving, citing, or synthesizing. A process signal does not erase original evidence, firsthand knowledge, a useful framework, or a defensible opinion. It also cannot rescue a page that merely repeats the prevailing consensus in slightly different words.

    Hold publication when any of these conditions is true:

    • Your editor cannot name the page’s unique contribution in one sentence.
    • A group of pages differs mainly by replacing a location, product, industry, or target keyword.
    • The copy makes factual claims that no reviewer has traced and verified.
    • The only reason for creating the page is that a keyword exists, not that a defined reader needs the answer.
    • No named person owns the final decision to publish, correct, or withdraw the content.
    • The page would lose nothing important if it were replaced by a generic search-results summary.

    This test applies equally to human and AI writing. A human-written page does not gain a competitive advantage merely by being human if it offers the same information as a thousand other pages. A watermarked page does not lose a genuine advantage merely because AI helped shape its presentation.

    Use a citation-worthiness audit before publication

    An article page surrounded by reference materials, with visual lines linking parts of the page to supporting sources and one area under a magnifying lens.

    A normal copy edit is not enough for AI-assisted work. You need a release process that tests why the page should exist, which claims deserve trust, and what an answer engine could retrieve from it. Use this sequence for every page, whether AI wrote one sentence or most of the first draft.

    1. Define the page’s job. Complete this sentence before drafting: This page helps a specific reader complete a specific task under a specific constraint. A broad topic such as AI content quality is not a job. Deciding whether to publish an AI-assisted landing page after detecting a watermark is.
    2. Name the unique contribution. Write down what the reader can obtain here that is difficult to obtain elsewhere. It could be original data you actually collected, a documented procedure, firsthand operational knowledge, a new comparison, or a reasoned interpretation. New wording is not new value.
    3. Build an evidence ledger. Record the support for every claim on which the reader might base a decision. Include the relevant URL, named authority, date or product version when needed, verification status, and reviewer. Do not ask a model to invent citations or treat its confidence as verification.
    4. Give AI bounded roles. Decide in advance whether the model may organize notes, propose an outline, challenge assumptions, generate alternatives, or improve clarity. Do not let the same automated process generate a claim, declare it verified, approve the page, and publish it without independent review.
    5. Run the genericity test. Replace the important nouns with those from another company or topic. If the paragraph still sounds equally plausible, it probably contains interchangeable advice. Cut it or add the missing evidence, constraint, example, or point of view.
    6. Make the useful answer retrievable. Put the direct answer close to the heading that asks the question. Keep its supporting evidence adjacent. Use stable entity names, descriptive headings, and a table only when the reader is genuinely comparing fields. Appropriate structured data can clarify what a page contains, but it cannot turn recycled copy into evidence.
    7. Assign a real owner. Name the person responsible for checking the claims and maintaining the page. Use a byline, credentials, and author markup only when they accurately represent that ownership. A byline can support identity consistency for AI crawlers, but it cannot make repetitive information citation-worthy.

    The release gate: can you defend the finished page?

    Before the page enters your CMS workflow, require clear answers to four questions:

    • Is it accurate? Every consequential claim has traceable support, and uncertainty is visible instead of being edited away.
    • Is it original enough to justify existing? The unique contribution is information, reasoning, or experience, not merely different phrasing.
    • Is it useful to the intended reader? That reader can make a decision, complete a task, avoid a mistake, or understand a meaningful distinction after reading it.
    • Will someone stand behind it? A named owner is prepared to explain the reasoning, correct errors, and accept scrutiny of the production process.

    If one answer is missing, the page is not ready. A lower AI score would not change that decision.

    Measure the finished page instead of chasing an AI percentage

    A layered page passing through a transparent inspection frame while a stack of nearly identical thin pages fades into the background.

    An AI score cannot tell you whether a reader finished the page, trusted it, shared it, subscribed, or completed the intended action. It also cannot tell you whether an answer engine cited the page accurately. Those are outcomes a detector percentage does not measure.

    Build reporting around the page’s actual job:

    OutcomeWhat to observeWhat to do when it fails
    Search discoveryIndex status, impressions for relevant queries, and qualified organic visitsCheck technical access, intent alignment, internal discovery, and whether the page adds enough value to compete
    AI-answer visibilityWhether relevant answer surfaces cite, link to, or accurately represent the pageStrengthen distinctive facts, make the answer easier to extract, and keep evidence beside the claim it supports
    Reader usefulnessCompletion of the action the page was designed to support, plus meaningful shares, subscriptions, or return visits where relevantFind the unanswered question, missing proof, or unnecessary friction instead of adding more generic copy
    Editorial trustCorrections, challenged claims, review failures, and substantive reader feedbackRepair the evidence and workflow before increasing production volume

    Do not mislabel all of these observations as direct ranking factors. They serve different purposes: search metrics show discoverability, citation checks show retrievability, and reader or business outcomes show whether the page fulfilled its intended role. Together, they provide a more useful diagnosis than a single AI-likelihood score.

    A detector result can still trigger a process check. An unexpected score may prompt you to confirm how a draft was produced, whether your editorial policy was followed, and whether required review occurred. It should not become a target that writers optimize at the expense of clarity. Rewriting accurate text until a detector approves its style is not content improvement.

    The same logic applies to watermark-removal tools. If removal is the only change, the page gains no new evidence, insight, or usefulness. Review the claims, eliminate sameness, add the missing contribution, and document accountable ownership before spending effort on the provenance signal.

    Key takeaways

    • An AI watermark can indicate something about production; it cannot determine accuracy, originality, usefulness, or search quality.
    • AI involvement is not an automatic search penalty. Low-value content produced at scale to manipulate rankings is the relevant risk.
    • Use AI for bounded tasks such as organization, critique, and editing, while keeping evidence checks and publication approval independent.
    • Bylines, author markup, headings, and schema can clarify ownership and meaning, but they cannot make generic information worth citing.
    • Judge a page by search discovery, answer-engine citations, reader usefulness, and editorial trust rather than an AI detector percentage.
    • If revealing AI involvement would make your team reluctant to defend the work, improve the work before publishing it.

    For your next AI-assisted page, require four fields before publication: the intended reader, the unique contribution, the evidence ledger, and the accountable owner. Leave the page in draft if any field is blank. If all four withstand scrutiny, publish the work and stand behind it, watermark or not.

    References


  • Google Search Result URL Redirects: What SEOs Should Check

    Google Search Result URL Redirects: What SEOs Should Check

    If your rank tracker suddenly disagrees with what you can see in Google, pause before changing the page. Google is inserting a Google-owned redirect between some search results and their destination pages, and that can disrupt the measurement layer without changing the ranking itself.

    Your first job is to identify which link in the chain changed: Google’s result, your tracking provider’s collection process, or your site’s actual search performance. A short, structured audit can keep a reporting incident from turning into an unnecessary content, schema, or technical SEO project.

    Read this as a link-delivery change, not a site redirect

    A conventional organic result used to expose the destination page’s full URL as its clickable target. Under the new behavior, the result can point first to a Google URL resembling google.com/goto?url=[hashURL]. Google processes that intermediate request and then sends the searcher to the destination.

    That extra hop matters because software inspecting the result may initially see a Google-owned URL instead of your page URL. The searcher can still see the displayed site URL under the result title, but the browser’s link preview may no longer reveal the complete destination before the click.

    Google describes the rollout as part of its technical response to evolving abuse and an effort to protect its services and users. That explanation is broad. It does not identify every type of abuse involved, so claims about one specific target or enforcement method should be treated as interpretation rather than confirmed implementation detail.

    Most importantly, this is not a redirect configured on your server. It does not, by itself, show that Google changed your canonical URL, replaced your indexed page, altered your structured data, or applied a ranking penalty. Your 301 and 302 rules remain separate from the redirect Google places inside its own result interface.

    • Do not add a site redirect to compensate. You cannot remove Google’s intermediate hop from your server, and another redirect would only add complexity to the destination path.
    • Do not change canonical tags or JSON-LD because a tracker exposes a Google URL. First confirm whether the tool is merely failing to resolve the final destination.
    • Do not treat the redirect as evidence of an algorithm update. A ranking change requires ranking evidence; a changed link target is not enough.

    Identify which part of your search stack is exposed

    A layered search stack shows a result link, a collection device encountering a redirect gate, and a healthy destination server.

    The effect depends on how you interact with the result. A person clicking normally may notice little beyond the obscured link preview. A system that parses result-page links, classifies domains, or associates positions with landing URLs has more ways to fail.

    • Searchers: Watch for the displayed domain and page label under the result title. The visible destination cue remains available even when the clickable target is routed through Google.
    • SEO teams: Expect possible discontinuities in third-party rank, visibility, competitor, and landing-page reports. An abrupt dashboard change may reflect collection behavior rather than a change to your pages.
    • Rank-tracking providers: A parser that assumes every organic link exposes the publisher’s URL may return a Google URL, an unknown destination, or no recognized result. Tools that resolve the redirect may face a different collection path than tools that only inspect the original markup.
    • SERP scrapers and AI systems: The redirect can create additional friction for systems gathering destinations from Google results. That does not automatically affect an AI crawler visiting your website directly; the two access paths are different.
    • Google Search Console users: The working expectation is that Search Console is not affected by this result-link change, but Google’s public confirmation does not provide an explicit guarantee. Use it as an independent comparison signal, not as proof that every third-party observation is wrong.

    This distinction is especially important for AI visibility reporting. If a platform builds part of its dataset by scraping Google results, its measurements may inherit the redirect problem. A decline in that platform does not establish that your pages became less accessible to ChatGPT, other frontier models, or direct web crawlers. Ask how the vendor collects each reported signal before you combine those signals into one visibility score.

    Audit tracker anomalies before changing the site

    The redirect is being rolled out rather than appearing as a single universal switch. Different providers, locations, and collection environments may encounter it at different points. That makes the shape and timing of the anomaly more useful than one isolated keyword check.

    1. Preserve the last clean comparison. Export the affected dashboard before filters, recalculation, or vendor corrections change the historical view. Record the date you first noticed the discrepancy, the search engine, market, device configuration, project, and affected keyword set.
    2. Localize the break. Check whether the anomaly affects every tracked keyword or only one market, device type, project, or provider. A sitewide overnight gap confined to one tool looks different from a gradual decline concentrated in a group of pages.
    3. Separate position collection from URL resolution. Determine whether the tool lost the result entirely, still reports a position but cannot identify the landing page, or now attributes the result to google.com. Those are different failures and should not be combined into a generic rankings-down label.
    4. Inspect a small set of affected results manually. Confirm that the result is visible, the displayed domain is yours, the click reaches the intended page, and the underlying result link uses the new Google redirect. Manual checks are samples, not a replacement for tracking, but they can expose an obvious collection mismatch.
    5. Compare independent signals by direction, not exact totals. Review Search Console queries, pages, clicks, impressions, and average position around the same period. Search Console and a rank tracker measure search differently, so their numbers need not match. You are looking for a shared break in timing and scope.
    6. Send the provider reproducible evidence. Include the first affected date, search engine, market, device setting, several example queries, the expected destination, the reported destination, and screenshots or exports. Ask whether the goto redirect affects position detection, landing-page resolution, or both.

    Avoid making broad on-page changes while this audit is open. Rewriting titles, altering internal links, replacing schema, and changing canonicals at the same time will create new variables. If the original problem is external data collection, those edits cannot repair it and may make the real diagnosis harder.

    Separate a collection failure from an SEO loss

    A split illustration shows a broken monitoring signal beside an unchanged search position and a working monitor beside a falling result.

    No single metric settles the diagnosis. Use several observations to decide which explanation currently has the strongest support.

    • The result appears manually, the click reaches the right page, and only one tracker loses it: a collection or parsing problem is more plausible than a ranking loss.
    • The tracker still reports a position but loses the landing URL: destination resolution is the leading suspect. Check whether the reported URL is a Google goto address before touching your canonical setup.
    • Several third-party reports change at the same time but share a collection provider: they may not be independent confirmations. Establish whether the products depend on the same underlying data source.
    • Search Console and third-party visibility decline across similar queries and pages: investigate a genuine search-performance problem. The goto redirect alone is not a sufficient explanation for agreement across independent signals.
    • The result is present but the click fails or lands on the wrong page: treat that as a user-facing path problem. Verify your own redirects, final response, and destination separately from the tracker issue.
    • Nothing changed outside the underlying link target: document the rollout and keep monitoring. A technical change in Google’s interface does not require a technical change on your site.

    Be equally careful with competitive reporting. If a tool starts classifying goto URLs as Google domains, domain-level share-of-voice data can become distorted across many sites at once. Before concluding that a competitor gained visibility, check whether the report also shows more unknown URLs, missing domains, or unresolved landing pages.

    Your schema strategy does not need a special markup response. Structured data describes entities and page content on your site; it does not control the outbound link wrapper Google uses on its own search page. Continue validating schema for its intended purpose, but do not use a JSON-LD deployment as a remedy for off-site rank-tracker collection.

    Key takeaways

    • Google can route an organic result through a google.com/goto URL before sending the searcher to the publisher’s page.
    • The redirect is a Google-side link-delivery measure, not a redirect you need to reproduce or counteract on your server.
    • Third-party tools that extract or resolve result URLs have more direct exposure than ordinary searchers or your site’s canonical configuration.
    • A tracker anomaly becomes actionable SEO evidence only when independent signals support the same timing, pages, and queries.
    • Preserve the affected data, classify the failure, compare Search Console directionally, and give your provider reproducible examples before editing the site.

    Add the rollout to your measurement-change log and keep first-party performance signals separate from vendor-collected visibility data. If a discrepancy appears, ask the provider whether it can recognize the result and whether it can resolve the final URL. Those two answers will tell you whether you have a reporting repair to wait for or an SEO problem to investigate.

    Until the evidence points to your site, leave the content, internal links, canonicals, redirects, and structured data alone. The safest next move is a cleaner diagnosis, not a larger deployment.

    References


  • How to Earn AI Search Citations and Measure Source Visibility

    How to Earn AI Search Citations and Measure Source Visibility

    You can rank for a query, appear somewhere in an AI-generated answer, and still lose the citation to another site. The system may name your brand without linking to you, cite a competing page, or display your link without sending a measurable visit.

    If you want to improve that outcome, stop treating AI visibility as one metric. You need a page that can be retrieved, an answer passage that can stand on its own, a defensible reason to select your URL, and a measurement process that separates citations from mentions and clicks.

    Separate citations, mentions, and visits before optimizing

    Teams often report that they appeared in AI search without recording what actually appeared. That makes the next content decision guesswork. For practical measurement, use three distinct working definitions.

    SignalWhat you observedWhat it does not prove
    CitationThe answer identifies or links to a page on your domain as support.That the user clicked, read, or converted.
    Brand mentionThe answer names your company, product, author, or other entity.That an owned page received attribution.
    VisitA user reached your site after interacting with an AI search experience.That every preceding citation was visible or measurable.

    A citation is usually the right primary outcome for publishers and information-led SEO because it exposes the supporting page. A mention can still strengthen brand visibility, but it does not give the reader a route to inspect your evidence. A visit is the commercial opportunity, yet it sits one step later and depends on whether the link gives the reader a reason to leave the generated answer.

    Set the goal at the page level. A definition page may be successful when it earns repeated citations. A product page may need qualified visits rather than broad mentions. A developing-topic page may need visibility in a prominent link module while attention is concentrated on the event. Do not combine these outcomes into a single AI visibility score unless the underlying signals remain available separately.

    Build answer passages that survive extraction

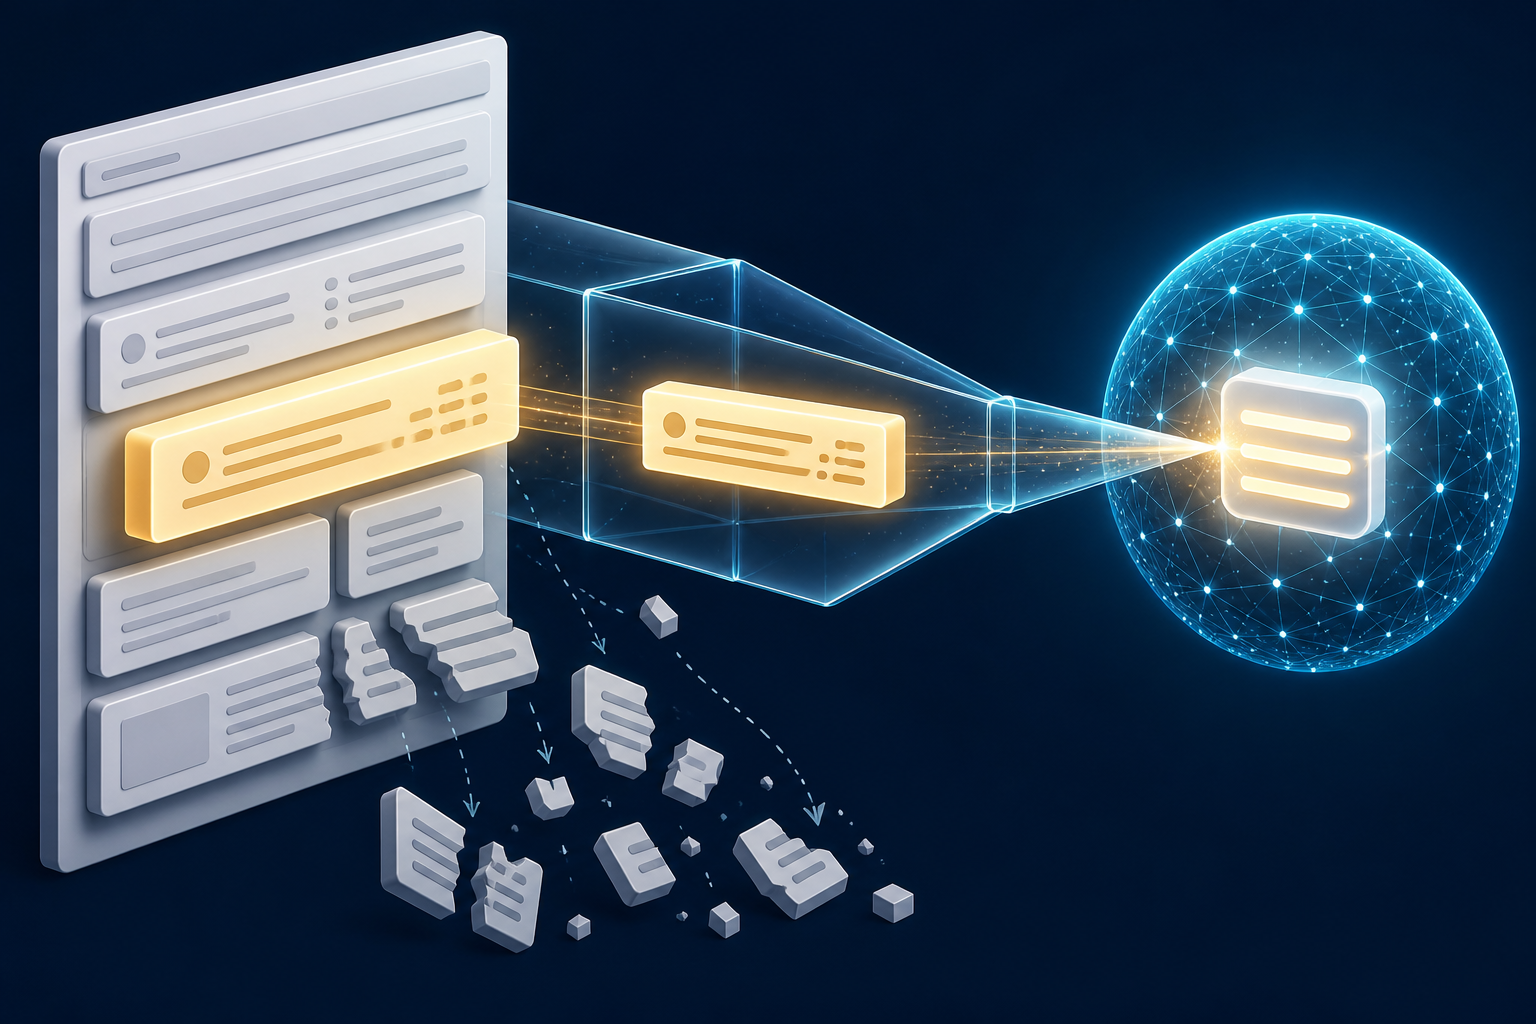
    One intact content block moves from an abstract web page through a transparent funnel toward a glowing sphere while fragmented blocks fall away.

    A polished draft is not necessarily a citable draft. The more useful standard is whether the page contains a citation-ready answer that remains accurate when lifted out of its surrounding introduction.

    Treat the passage, not the word count, as your basic unit of work. Each important query should map to a bounded section with a descriptive heading. The opening sentence should resolve the question directly. The following sentences should carry the qualification, evidence, and consequence needed to prevent the answer from becoming misleading.

    Use a four-part answer block

    1. Answer: State the conclusion in the first sentence. Do not make the reader cross an anecdote, mission statement, or definition they already know.
    2. Boundary: Name the situation in which the answer applies. Keep material qualifiers in the same paragraph as the claim they limit.
    3. Support: Explain the mechanism or attach the relevant evidence. Link factual claims to their originating evidence rather than to a page that merely repeats them.
    4. Next step: Give the reader useful depth that the short answer cannot contain, such as implementation steps, decision criteria, exceptions, or a worked example.

    Consider the difference between these two passages:

    Weak: AI visibility is changing quickly, so brands need a comprehensive strategy that improves their presence across emerging platforms.

    Citable: An AI search citation identifies a supporting page or domain inside a generated answer. A brand mention without an owned link is visibility, but not citation visibility. Track the two separately so a rise in mentions does not hide a decline in attributed pages.

    The second version makes a bounded claim, defines the distinction, and tells the reader what to do with it. It does not need promotional language to sound authoritative.

    Create a claim ledger before expanding the page

    For every section you expect to earn citations, record the following fields in your content brief:

    • The exact question the section answers.
    • The answer in one plain sentence.
    • The qualifier that would make the sentence inaccurate if omitted.
    • The evidence that supports the claim.
    • The contribution that is original to your page.
    • The person responsible for checking whether the answer is still current.

    This ledger catches a common failure before publication: a section sounds complete but has no supportable claim. It also prevents an editor from separating a caveat from the sentence it qualifies. If you cannot fill the evidence field, rewrite the statement as analysis, label the uncertainty, or remove it.

    Run a final extractability pass after the normal edit. Replace vague pronouns with named entities where context could be lost. Remove unsupported superlatives. Use one term consistently for the same concept. Keep the evidence link next to the claim it supports. Make each heading specific enough that a reader can predict the answer below it.

    Give AI systems a defensible reason to select your page

    Clear formatting makes content easier to reuse, but clarity alone does not make your URL preferable. If your page is an interchangeable paraphrase of information already available elsewhere, formatting only makes the duplication easier to see.

    Strengthen the page with a contribution that another answer can reasonably attribute to you. That contribution might be first-party data with a disclosed method, original documentation, a comparison built from explicit criteria, a verified chronology, or analysis that shows its reasoning. Do not manufacture novelty by renaming a familiar idea or presenting an unsourced opinion as a finding.

    For evergreen questions, optimize the decision

    An evergreen page should do more than provide a dictionary answer. After the direct response, help the reader choose, implement, diagnose, or verify something. State the criteria that change the recommendation. Include exceptions where they materially affect the outcome. Keep the page on a stable URL so references, internal links, and structured data continue to identify the same resource.

    A useful test is to remove your brand name from the draft and compare the remaining value with a generic summary. If nothing distinctive remains, add evidence or decision support before adding more prose.

    For developing topics, make the update verifiable

    Google has introduced AI Mode link carousels for developing topics. These modules can place relevant pages, including a user’s Preferred Sources, prominently in the result. Google frames the feature around connecting people with original coverage and a range of perspectives.

    That creates a specific opportunity for publishers covering active events, but only when the page makes its contribution easy to verify. Put the material change near the top. Separate confirmed facts from interpretation. Identify what remains unknown. Link claims to the originating evidence. Show readers when the page was updated, and do not silently replace an earlier conclusion without explaining what changed.

    A prominent carousel may make links easier to notice and click, but it does not justify forecasting the click-through rates you received before AI-generated search experiences. Give the reader a reason to continue: the underlying evidence, a complete timeline, a tool, detailed methodology, or analysis that cannot fit inside the generated answer.

    Make the page retrievable, stable, and unambiguous

    Content cannot earn a reliable citation if the system cannot retrieve the useful version or determine which URL represents it. Run a technical pass after the claim-level edit.

    • Accessibility: Keep the substantive answer available in the page’s rendered content. Do not require a form submission, account, tab interaction, or client-side event merely to reveal the core response.
    • Indexability: Check that robots rules and page-level directives do not exclude the URL from the search systems you expect to surface it.
    • Canonical consistency: Use one preferred URL across canonical signals, internal links, sitemaps, and structured data. Consolidate accidental duplicates rather than asking systems to choose among them.
    • Information structure: Give the page a descriptive title, question-aligned headings, and internal links from relevant pages. The hierarchy should reveal the main answer and its supporting sections without relying on visual styling.
    • Entity consistency: Use the same names for your organization, product, person, and core concepts in visible copy, metadata, and structured data.
    • Maintenance: Preserve the URL when the underlying resource remains the same. When the facts change, update the answer, its evidence, and any visible freshness information together.

    Use JSON-LD to clarify, not to manufacture authority

    Structured data can describe what a page represents and connect it with relevant entities. It cannot force an AI system to cite the URL, turn an unsupported assertion into evidence, or compensate for an answer buried in vague copy.

    Add markup only for information supported by the visible page. Make sure the structured entity uses the same preferred name and canonical URL as the rest of the site. If the markup describes a different page purpose, organization name, or content relationship than the reader sees, correct the inconsistency instead of adding more properties.

    Then perform two separate checks. First, read the rendered page as if you had landed directly on the relevant heading: can you identify the answer, boundary, and evidence without reconstructing missing context? Second, validate the structured data on its own terms. Passing the second check does not excuse failing the first.

    Measure source visibility with a prompt-level scorecard

    A seated researcher examines a glowing matrix of blank tiles and colored visual markers on a large analysis display.

    AI answers can vary with prompt wording, search surface, location, session context, and observation time. A screenshot from one query can prove that a citation occurred, but it cannot show how consistently your domain appears. Build a repeatable prompt set around real audience intents and keep the exact wording available for later observations.

    Include question types that expose different citation opportunities: definitions, procedures, comparisons, verification questions, and developing-topic queries where they fit your business. Do not insert your brand into every prompt. A branded prompt measures retrieval of a known entity; it does not tell you whether the brand is discoverable in an unbranded answer.

    Record the evidence behind every visibility claim

    • The exact prompt and the intent it represents.
    • The AI search surface and relevant session conditions.
    • The time of the observation.
    • Whether the brand appeared.
    • Whether an owned URL was cited.
    • The linked page and the claim it supported.
    • Whether the link appeared inline, in a citation area, or in a carousel.
    • Which competing domains were cited for the same answer.
    • Any identifiable landing-page visit or downstream conversion.

    From that record, calculate separate directional metrics. Citation presence is the share of observations containing an owned citation. Citation coverage is the share of monitored prompt families in which the domain appears at all. The mention-to-citation gap counts observations that name the brand but provide no owned link. Landing-page concentration shows whether visibility depends on one URL or is distributed across the site.

    Keep those metrics distinct from traffic. Google does not provide clean AI Mode click reporting through Search Console’s generative AI reporting, so an absent click record does not prove that no citation appeared. Conversely, a visible citation does not prove that a visit occurred. Use Search Console and analytics for the signals they expose, then retain your prompt observations as a separate evidence set.

    When you change a page, keep the monitored prompt set stable, log what changed, and repeat the observations after the updated page has had a chance to be rediscovered. Change a bounded element such as the answer block, evidence structure, or page consolidation before rewriting everything at once. Treat movement as directional unless it persists across repeated observations; generated results are too variable for a single before-and-after response to establish causation.

    Key takeaways

    • Measure citations, brand mentions, and visits separately because each proves a different outcome.
    • Write claim-level answer blocks with the conclusion, boundary, support, and useful next step kept together.
    • Give the page an attributable contribution instead of publishing an interchangeable summary.
    • Treat developing-topic visibility as a freshness and verification task, especially where AI Mode displays link carousels.
    • Use JSON-LD to reinforce visible meaning and entity relationships, not as a substitute for evidence.
    • Track exact prompts and cited URLs over repeated observations; do not infer source visibility from incomplete click data alone.

    Start with one commercially or editorially important page that should be cited but is not. Build its claim ledger, rewrite the main answer block, verify retrieval and canonical signals, and record a prompt-level baseline. That turns a vague visibility problem into a controlled content, technical, and measurement task.

    References


  • AI Search Visibility Strategy: From Clicks to Recommendations

    AI Search Visibility Strategy: From Clicks to Recommendations

    Your rankings can look respectable while clicks keep falling. That is not automatically a conventional SEO failure. An AI answer can satisfy the query before the searcher visits a website, while an assistant can understand and cite your brand yet omit it when someone asks what to buy.

    The practical response is to stop treating AI visibility as one score. You need to diagnose where demand is being intercepted, distinguish citations from recommendations, publish evidence for real buying scenarios, and route problems to the teams that can actually solve them. Being understood and being recommendable are different outcomes, and confusing them leads to the wrong work.

    Key takeaways

    • Separate Google AI Overview exposure, organic clicks, direct assistant referrals, citations, and recommendations. They describe different parts of the journey.
    • Segment performance by intent before deciding that SEO as a whole is declining. Informational demand is much more exposed to zero-click answers than transactional demand.
    • Audit unbranded buyer scenarios, not just category keywords or brand prompts. Recommendations change when buyers add requirements, constraints, and tradeoffs.
    • Use content and JSON-LD to clarify truthful evidence. Do not expect either to compensate for a missing capability, weak support, or a poor product fit.
    • Measure lead volume and business outcomes alongside traffic and conversion rate. Better-qualified visitors can soften a traffic loss without fully recovering it.

    Diagnose the visibility problem before changing your strategy

    Organic search still accounted for 42.8% of sessions in July 2026 across one normalized panel of 218 client websites, making it the largest traffic source in that dataset. Its normalized session volume was nevertheless 23.6% lower than in January 2023. Direct referrals from AI assistants moved from 0.1% to 6.2% of sessions over the same period.

    Those percentages are directional evidence, not a forecast for every site. The panel covered client websites in 12 industries and normalized results for growth, seasonality, and spend. Its reported losses were measured against a pre-2023 growth baseline, so a site could trail the counterfactual even if its absolute visits increased. Use the pattern to shape your diagnosis, but calculate the exposure with your own query, landing-page, and conversion data.

    The first distinction is between an AI feature on a search results page and a visit from a separate assistant. A Google AI Overview sits above conventional organic results and can suppress their clicks. An AI referral is an observed session whose referrer resolves to an assistant. Mixing the two hides whether you lost a click on Google, gained a visit from an assistant, or influenced a decision that produced no trackable referral at all.

    The click pressure can be severe even when a page holds its position. For tracked impressions at position one, click-through rate was 27.4% without an AI Overview and 11.8% with one, a relative decline of 56.9%. The top-ranking page did not suddenly become irrelevant; the results page changed how much of the answer required a click.

    Signal you seePossible readingWhat to inspect next
    Impressions and rankings hold, but click-through rate fallsThe results page may be resolving more of the queryCompare query-level CTR when an AI Overview is present and absent, then split the queries by intent
    Informational visits fall while commercial and transactional pages holdYour traffic mix is changing rather than the entire site failingReport sessions, leads, and assisted journeys separately for each intent group
    Sessions fall while visitor-to-lead rate improvesFewer but more qualified visitors may be reaching the siteCheck total lead volume and pipeline value, not conversion rate alone
    Observed assistant referrals grow while organic clicks declineDiscovery may be moving between surfacesTrack assistant landing pages, outcomes, and referrers in a separate channel grouping
    Your brand is cited for explanations but omitted from purchase adviceThe gap may concern evidence, fit, reputation, or the product itselfAudit realistic buying scenarios and record the stated reason for exclusion

    Do not begin with a sitewide rewrite. Start with the query groups that lost clicks or recommendations. If impressions and rankings fell across intents, you still have a conventional SEO problem to investigate. If rankings remain stable and the loss clusters around AI-answer results, your priority is adapting the content and measurement model. If assistants retrieve your facts but reject the offer for a buyer’s constraints, more indexable copy may not solve anything.

    Build for citations and recommendations as separate outcomes

    Two illuminated paths lead separately to connected evidence cards and a selected group of unbranded products.

    AI visibility has a progression. A brand can succeed at the early stages and still fail at the point closest to revenue:

    1. Accessible: the relevant pages can be crawled, rendered, and found.
    2. Understandable: the system can identify the company, offering, audience, properties, and relationships correctly.
    3. Citable: the content contains a useful statement or piece of evidence that supports an answer.
    4. Considered: the brand enters the candidate set for a realistic buyer scenario.
    5. Recommended: the available evidence makes the product or service an appropriate fit for that scenario and its tradeoffs.

    The first three stages sit close to familiar technical SEO, content, entity clarity, and authority work. The final two force the system to compare options. At that point, technical documentation, product specifications, customer experiences, third-party evidence, and known tradeoffs can all affect the result.

    A prompt inventory therefore should not consist of broad questions such as which vendors operate in a category. Those prompts test recall and retrieval. Build scenarios around the conditions that change a purchase decision:

    • The buyer’s industry, application, or operating environment.
    • The non-negotiable capability, compatibility, or service requirement.
    • The outcome being optimized, such as uptime, contamination control, implementation risk, or initial cost.
    • The tradeoff the buyer is willing to accept.
    • The constraints that would make an otherwise credible option unsuitable.

    For each scenario, record whether your brand was mentioned, cited, considered, and recommended. Capture the exact response, the evidence it relied on, the reason given for inclusion or exclusion, and the page or team that owns the underlying claim. Repeat materially important scenarios with controlled prompt variations so one unusually favorable or unfavorable response does not become your strategy.

    Classify each failure before assigning work. A retrieval gap means the relevant evidence exists but is hard to find or interpret. An evidence gap means the claim is not documented well enough to support. A fit gap means the offer genuinely lacks something the buyer requires. A trust gap means customer experiences or credible third-party information create risk. These categories may look identical in a visibility dashboard, but their remedies are not interchangeable.

    AI output is diagnostic evidence, not an unquestionable verdict. Verify every material claim against product documentation, support records, customer evidence, and the actual offer. When the system is wrong, publish clearer, retrievable evidence and correct inconsistent facts. When it is right about a limitation, route the issue instead of trying to wordsmith around it.

    Move content closer to decisions without abandoning information

    The greatest traffic exposure sits at the top of the intent funnel. In the same client-site panel, informational queries lost 43.9% of normalized organic sessions and had a 91.7% zero-click rate. Commercial-investigation queries declined 14.2%, while transactional queries declined only 5.7%.

    Search intentChange in organic sessionsZero-click rateStrategic role
    Informational-43.9%91.7%Supply clear answers and evidence that can create awareness or support later decisions
    Navigational-19.4%76.3%Make official brand, product, and destination information unambiguous
    Commercial investigation-14.2%58.1%Help buyers compare fit, requirements, tradeoffs, and proof
    Transactional-5.7%37.2%Remove uncertainty from the next action or purchase

    This does not justify deleting informational content or publishing only bottom-funnel pages. Informational content can still establish terminology, answer prerequisites, support customers, and provide evidence that an answer engine retrieves. Its job has changed, however. A page that once existed mainly to win a visit may now need to make a concise fact retrievable and lead the interested reader into a deeper decision path.

    Build connected content in four layers:

    • Answer layer: state the direct answer early, define the relevant entity or concept, and make the scope and limitations explicit. Remove introductory padding that separates the question from the fact.
    • Decision layer: explain who the offer is and is not for, which prerequisites apply, what alternatives exist, and how important tradeoffs change the choice. Organize comparisons around buyer requirements rather than a generic feature count.
    • Evidence layer: support consequential claims with specifications, implementation documentation, policies, customer evidence, and clearly described examples. Keep facts consistent across product, support, sales, and corporate pages.
    • Action layer: give a qualified visitor the next information or action needed to proceed, such as configuration details, availability, a relevant product destination, or a way to discuss fit.

    Connect these layers with descriptive internal links. An informational answer about a requirement should lead to the decision page where a buyer can evaluate it, and that decision page should point to the underlying proof. This creates a path for both a human visitor and a retrieval system without forcing one page to serve every intent.

    Use JSON-LD as machine-readable clarification of the same entities, properties, and relationships that people can verify on the page. Keep names, identifiers, product attributes, and organizational relationships consistent with the visible content. Structured data is not a separate claim channel, and it is not a shortcut to recommendation status.

    Content also cannot manufacture product truth. If a buyer requires a native integration, better documentation for a workaround can reduce uncertainty but cannot make the workaround equivalent. If repeated support problems, a failure-prone component, or a missing capability drives exclusion, the recommendation problem exists beyond SEO’s jurisdiction. The honest content response is to describe the current fit accurately while the responsible team evaluates the underlying issue.

    Use a measurement stack that survives zero-click search

    A glass measurement console collects light signals from search, an AI assistant, a website, and product-selection objects.

    Traffic remains important, but it is no longer a complete proxy for visibility or influence. Results pages with an AI Overview produced 36 organic clicks per 1,000 impressions, compared with 87 without one, across the matched keyword set. The visitors who still clicked spent 3 minutes 18 seconds per session rather than 2 minutes 41 seconds, viewed 2.9 pages rather than 2.3, and converted to leads at 2.6% rather than 1.7%.

    The higher visitor-to-lead rate did not erase the traffic loss. Estimated lead volume was still roughly 37% lower. That is why a dashboard showing only a rising conversion rate can create false comfort, while a dashboard showing only declining sessions can miss an improvement in visitor quality.

    Build reporting in layers and preserve the numerator and denominator for every rate:

    • Demand: tracked queries and buyer scenarios, impressions, ranking distribution, intent, and AI Overview coverage.
    • Answer visibility: brand mention rate and citation rate across the scenarios where the brand is eligible to appear.
    • Decision visibility: consideration rate, recommendation rate, competitor inclusion, and the reasons attached to each outcome.
    • Traffic: organic clicks and CTR, observed assistant referrals, landing pages, and channel-specific journeys.
    • Visit quality: meaningful engagement, progression to decision content, visitor-to-lead rate, and qualified actions.
    • Business outcomes: total leads, qualified opportunities, pipeline contribution, completed transactions, and value where your measurement system can support those links.
    • Remediation: recurring exclusion reasons, evidence strength, responsible owner, action status, and whether the issue changed after the underlying fix.

    Define the rates plainly. Mention rate is the share of evaluated outputs in which the brand appears. Citation rate is the share that links or attributes supporting information to the brand. Recommendation rate is the share of eligible buying scenarios in which the offer is advised as an appropriate choice. A single visibility score can conceal a brand that is frequently mentioned but almost never recommended, so retain the component measures.

    Keep a stable scenario bank for trend measurement. Store the exact prompt, platform, available model identifier, market and language context, capture date, response, citations, competitors, and stated rationale. Evaluate the same core scenarios on a consistent cadence, while maintaining a separate exploratory set for emerging buyer questions. This lets you distinguish a durable pattern from normal output variation.

    Label the surfaces correctly in analytics. AI Overview exposure is not assistant referral traffic. An organic click from a results page containing an AI answer is still an organic visit. A direct visit from an assistant is an observed AI referral. A recommendation that leads to a later branded search may have no attributable AI referrer. Report what you can observe without presenting untracked influence as measured conversion.

    Turn visibility findings into cross-functional action

    SEO and web teams still own a large part of the execution surface, including accessibility, site architecture, internal linking, content retrieval, structured data, and analytics. Recommendation failures expand the work because the deciding factor may be a product capability, design choice, support experience, or policy that search specialists cannot change.

    Route each failure to the team that controls reality

    • SEO and development: resolve access, rendering, discoverability, canonicalization, page architecture, internal linking, and machine-readable clarity.
    • Content and subject-matter experts: document applications, requirements, specifications, limitations, tradeoffs, and substantiated proof in language buyers use.
    • Product and engineering: evaluate missing capabilities, integrations, materials, reliability issues, and design choices that repeatedly make the offer a weaker fit.
    • Support and customer success: investigate recurring implementation friction, service complaints, repair delays, and gaps between documented and actual customer experience.
    • Reputation and communications: understand credible third-party narratives, correct factual inaccuracies with evidence, and avoid trying to suppress valid criticism.
    • Analytics and revenue teams: connect visibility patterns to qualified demand and business outcomes without overstating attribution.

    Use one operating loop for SEO and non-SEO fixes

    1. Choose a commercially important buyer scenario in which your offer is genuinely eligible.
    2. Capture the response, cited evidence, competitors, and explicit or implied reason your brand was included or excluded.
    3. Verify the reason against your website, product documentation, customer evidence, support reality, and third-party information.
    4. Classify the gap as retrieval, evidence, fit, trust, or measurement noise, then assign it to the team with authority to change it.
    5. Make the underlying change and document the new reality consistently wherever buyers and systems would expect to find it.
    6. Re-evaluate the same scenario and watch both the visibility measure and the business outcome it was meant to improve.

    Prioritize scenarios by commercial importance, frequency, strength of the exclusion evidence, and the organization’s ability to act. A repeated loss in a central use case deserves more attention than an isolated omission from a broad prompt. A real product disadvantage deserves an honest product decision, not a content campaign designed to obscure it.

    Start with the highest-value scenario where your brand is understood but not recommended. Trace the exclusion to its evidence, assign the owner, and decide whether the remedy is clearer retrieval, stronger proof, a service correction, or a product change. Solving that case gives you a repeatable operating pattern for the rest of AI search instead of another visibility score with no path to action.

    References


  • How to Build Situation-Based Content Briefs for SEO and AI

    How to Build Situation-Based Content Briefs for SEO and AI

    You have the keyword list, competitor headings and target word count. The writer follows the instructions. The finished draft is still generic, because nobody defined the moment that brought the reader to the page.

    A situation-based content brief fixes that gap. It identifies what changed for the reader, what they need to decide, what constrains them and what useful progress looks like. Keywords still matter, but they support the assignment instead of becoming the assignment.

    Key takeaways

    • Start with one recognizable audience situation, not a cluster of loosely related keywords.
    • Document the situation through seven lenses: why, when, where, while, with whom, with or for what, and how the reader is feeling.
    • Record where each audience insight came from so writers and subject-matter experts can verify it.
    • Use keywords to capture audience language and discoverability, not as a substitute for intent, context or editorial judgment.
    • Measure whether the content helped the intended reader progress, using visibility and engagement metrics as supporting evidence.

    A keyword is evidence, not the assignment

    A keyword tells you that a phrase may be searched. It rarely tells you why this person is searching now, what they already understand or what they will do with the answer.

    Consider the keyword content brief template. It could come from an SEO lead trying to standardize agency output, an in-house marketer repairing a disappointing draft, a freelancer preparing for a new client or an editor evaluating a briefing tool. The words are similar. The work each reader needs to complete is not.

    If you brief all of those readers at once, the writer has to average them together. That usually produces a long introduction, a universal checklist and little help at the point of decision. Pick one primary situation. Treat other situations as separate assignments unless they require substantially the same answer.

    Broad informational queries create another trap. A basic factual question may be more credibly answered by the organization that defines the rule, standard or process. Chasing that query can bring impressions without demonstrating the specialist expertise your prospective customer needs. Before approving it, ask why your brand deserves to answer, which qualified audience it serves and what meaningful next question you can resolve.

    This distinction matters even more in conversational search. People can describe the trigger, constraints and desired outcome in a full prompt rather than compressing everything into a short phrase. Content planned around that situation is better equipped to answer the main question and the follow-up questions that naturally accompany it.

    Use this gate before a topic becomes a brief:

    • Trigger: What happened that made the reader seek help now?
    • Decision: What must they choose, understand, fix or complete?
    • Constraint: What limits their options, confidence, time or authority?
    • Consequence: What goes wrong if they get an incomplete answer?
    • Brand fit: What relevant expertise, evidence or tool can your organization contribute?

    If you cannot answer those questions, you have a keyword opportunity but not yet a defensible content assignment.

    Capture the situation through seven practical lenses

    Seven translucent lenses reveal different details around a person standing in a constrained decision situation.

    The most useful briefs describe the audience moment through seven situational prompts. They force you to move beyond a persona label and document the conditions shaping the reader’s need.

    LensQuestion to answerWhat belongs in the brief
    WhyWhy is the reader looking for help?The trigger, desired progress and consequence of getting it wrong.
    WhenAt what point in a process or decision does the need appear?The stage, deadline pressure or event that changes the answer.
    WhereIn what environment will the reader find or use the information?The relevant channel, workplace, device context or operational setting.
    WhileWhat else is happening at the same time?Competing tasks, interruptions, dependencies or parallel decisions.
    With whomWho else affects the decision?Approvers, collaborators, customers, advisers or family members who shape the outcome.
    With or for whatWhat object, task or outcome is involved?The product, service, document, system or goal the reader is working with.
    How feelingWhat is the reader’s emotional state?The level of confidence, urgency or caution the tone and ordering should respect.

    Keep each answer short enough to guide a writer. Panicked is not useful by itself. Panicked because the filing deadline is close and the records are incomplete tells the writer to lead with triage, separate urgent actions from later improvements and avoid a leisurely history lesson.

    Emotion should change the delivery, not become an excuse for melodrama. A cautious evaluator needs explicit trade-offs and verification points. A beginner needs terminology introduced before it is used. A reader in the middle of a live failure needs the recovery sequence before background explanation.

    Get the answers from people close to the audience

    Sales, support, account management, in-store staff and public-facing specialists hear the language people use before it is cleaned up for a keyword tool. Ask them for recurring questions, misunderstood terms, objections, failed attempts and the point at which people usually request help.

    Capture traceability beside the insight. Record the team or role that supplied it, the evidence window and any place where the wording can be checked. If an entry is an assumption, label it as an assumption and assign someone to validate it. An unsupported guess does not become audience research merely because it appears in a template.

    Analytics and search data can then validate or refine the language. Internal site search, relevant query data and on-page behavior may reveal how people phrase the need or where an existing answer loses them. They cannot independently explain the entire situation, so interpret them alongside frontline evidence.

    Choose which situations deserve content

    You do not need a page for every situation your team can name. Prioritize a situation when four conditions line up:

    • There is credible evidence that the situation occurs among people the organization wants to serve.
    • The reader has a consequential question or decision, not merely passing curiosity.
    • Your organization has a legitimate reason to answer through expertise, evidence, experience or a relevant offering.
    • Existing content does not already solve the same problem adequately.

    Review search demand after those conditions, not before them. Demand can help you choose vocabulary, estimate discoverability and prioritize between otherwise worthwhile opportunities. It cannot make a poorly matched audience situation strategically useful.

    Turn the situation into a production-ready brief

    A strategist and writer connect an audience decision scenario to evidence, content modules, and a structured blank brief across a workspace.

    A persona describes who someone generally is. A situation explains why that person needs this content now. Your writer needs both only when both alter the answer; a broad demographic profile that changes nothing should not occupy half the brief.

    Write the core scenario as a single sentence using this pattern: person + trigger + progress needed + important constraint.

    For example: An in-house content lead has received another generic draft from an external writer and needs to repair the briefing process before assigning the next topic, without replacing the team’s existing keyword workflow.

    That sentence gives the assignment boundaries. The reader does not need a beginner’s definition of keyword research or a wholesale content-operations redesign. They need to identify what their brief is missing and update it before the next handoff.

    Copy this structure into your briefing system

    1. Primary scenario: State the person, trigger, desired progress and constraint in one sentence.
    2. Audience evidence: List the relevant questions, objections or failure points, with the team or evidence source attached to each.
    3. Seven situational lenses: Complete why, when, where, while, with whom, with or for what, and how feeling.
    4. Content job: Label the assignment informational, consideration or transactional, then explain what that means for this reader.
    5. Reader outcome: Define what the reader should be able to do, decide or notice after using the content.
    6. Primary and follow-up questions: Write the central question and the next questions that arise once it is answered.
    7. Scope boundaries: State what belongs, what does not and which adjacent situations need separate coverage.
    8. Suggested outline: Order sections by the reader’s decision process, not by competitor heading frequency.
    9. Evidence requirements: Identify claims that need subject-matter review, primary documentation, examples or qualification.
    10. Search language: Add the primary query, useful variants, named entities and terminology the audience actually uses.
    11. Answer design: Specify where a direct answer, ordered process, comparison, definition, example or caveat would help.
    12. Existing coverage: Note pages to update, consolidate, distinguish or link rather than creating an isolated duplicate.
    13. Tone and depth: Explain what the reader already knows, how urgent the need is and which details would be excessive.
    14. Next action: Give the writer a useful, situation-appropriate destination for the reader.
    15. Success measure: Name the primary outcome and the supporting signals you will inspect.

    Length guidance comes after the content job and outline. A fixed word count chosen before the situation is understood encourages padding or omission. Give a range only when your workflow requires one, and make completion of the reader’s task the controlling requirement.

    Use SEO, AEO and GEO requirements without flattening the brief

    Search requirements should make the answer easier to discover and interpret. They should not drag the writer back to a keyword-shaped page.

    • Use the primary query and variants to represent audience language, then map each phrase to a real question in the scenario.
    • Name important entities and relationships explicitly instead of relying on vague pronouns or implied context.
    • Place a concise answer close to the question it resolves, then add reasoning, conditions and examples.
    • Turn genuine sequences into ordered lists and genuine comparisons into tables. Do not impose those formats on ideas that require prose.
    • State assumptions and limits where the correct answer changes by stage, system or circumstance.
    • Connect the page to earlier and later journey content through relevant internal links.
    • Add structured data only when it accurately represents visible content. Schema cannot compensate for an answer the page never provides.

    This structure can help a search engine or AI system identify a direct answer and its supporting context, but it does not guarantee a ranking, citation or recommendation. The brief still needs credible evidence, clear language and a reason for your brand to be included.

    Measure whether the intended reader made progress

    Traffic is not the same as success. A broad page can collect impressions from people outside the intended situation, while a narrower page may help a smaller but more relevant audience take the next step. Define that step before publication.

    Choose one primary measure tied to the scenario, then use diagnostic metrics to understand the result:

    • Visibility: Inspect impressions and discovery for the relevant query family, not only the highest-volume phrase.
    • Engagement: Review scroll depth and interaction with the section, template, comparison or tool that performs the content’s main job.
    • Progress: Track the next action that fits the situation, such as continuing to a decision page, using a resource or beginning an appropriate contact path.
    • Operational usefulness: Ask the frontline team whether the content answers the recurring concern accurately and whether important questions remain unresolved.
    • AI visibility: If GEO is part of the goal, use a fixed set of prompts that represent the scenario and record whether the page or brand appears in a relevant answer. Treat individual outputs as directional observations rather than a guaranteed result.

    To test the briefing method, create a conventional keyword-led brief and a situation-led brief for comparable assignments. Evaluate the resulting drafts against the same rubric: scenario clarity, answer order, scope control, evidence requirements, search usefulness and next-step fit. If your website experimentation setup supports a valid split, you can also compare on-page behavior. Otherwise, avoid calling unlike pages an A/B test.

    Do not select a winner from raw impressions alone. Different topics can have different demand, and an impression does not show that the right reader received a useful answer. Read visibility, engagement and progress together, then document what changed in the next brief.

    Take one topic already waiting in your editorial queue and pause before outlining it. Complete the seven situational lenses, name the evidence behind them and choose the reader’s next decision. If your team cannot do that yet, the next task is an audience conversation, not another keyword export.

    References


  • AI Search Terminology: What Marketers Should Call the Work

    AI Search Terminology: What Marketers Should Call the Work

    You need a name for the work. It might be a budget line, a strategy deck, a job description, a service page, or the agenda for a meeting between SEO, content, PR, and analytics. Should you call it SEO, AI SEO, AEO, GEO, LLM optimization, or AI search optimization?

    Use SEO as the organizational umbrella and AI search optimization as the plain-language qualifier. Reserve AEO, GEO, and similar terms for a defined workstream. That gives familiar language to the person approving the work without hiding what has changed.

    The practical naming default: SEO plus AI search visibility

    Marketers have not abandoned SEO as quickly as specialist vocabulary might imply. Among 343 U.S. marketing decision-makers surveyed, 81% still called their internal AI search visibility strategy SEO. When searching online for help, 46% said they would use “AI search optimization” and 24% would use “SEO.” Together, those two understandable phrases accounted for 70% of the reported demand.

    Formal terminology is even less settled inside teams. Only 27% had adopted a term beyond SEO, while 42% had decided against doing so and 31% remained undecided. Treat those percentages as a directional view of one U.S. sample, not a universal naming law. They are self-reported choices from 343 decision-makers, not a census of every market or industry.

    Slow vocabulary adoption does not mean the work is being ignored. Respondents allocated an average of 24% of their search or content budgets to AI search visibility. Up to 82% reported committing at least some budget, and 43% allocated more than 20%. The label is lagging behind the investment.

    This creates a useful naming hierarchy:

    • SEO is the established program or department under which the work can sit.
    • AI search visibility names the business outcome: whether and how the brand appears in AI-mediated discovery.
    • AI search optimization names the work intended to improve that outcome.
    • AEO, GEO, LLM optimization, and agentic search optimization name narrower approaches or environments, but only after you define their scope.

    A practical strategy title is therefore “SEO and AI Search Visibility.” A defensible budget line is “SEO, including AI search optimization.” Both acknowledge the new surface without asking every stakeholder to learn an unsettled taxonomy before approving the work.

    A working glossary that distinguishes outcomes from methods

    A glowing destination and audience symbols are connected by a bridge to an arrangement of tools, content blocks, and linked source nodes.

    The category now spans AI search, answer engine optimization, and agentic-web terminology. These labels are useful, but they are not interchangeable and they are not universally standardized. Adopt working definitions inside your organization so the same acronym does not describe three different plans.

    TermUseful working definitionUse it whenCommon failure
    SEOThe established program for improving organic discovery, site accessibility, relevance, authority, and search performance.You need an umbrella understood by executives, practitioners, procurement teams, and job candidates.Treating AI-generated discovery as merely another ranking report, with no attention to answers, citations, or brand representation.
    AI search visibilityThe observable outcome of whether, where, and how a brand, product, person, or idea appears in AI-mediated search and answers.You are discussing goals, reporting, competitive presence, or reputation rather than a specific technique.Reducing visibility to a single score without examining accuracy, prominence, cited evidence, or business relevance.
    AI search optimizationThe broad set of activities intended to improve discovery, accurate representation, citations, and useful visibility across AI-generated search experiences.You need a buyer-friendly name for a cross-functional program that extends existing SEO.Using the phrase as a vague replacement for SEO without specifying platforms, prompts, owners, or measurements.
    AEOAnswer engine optimization: making relevant information clear, retrievable, well-supported, and suitable for systems that resolve questions with direct answers.The work focuses on question coverage, answer clarity, content structure, entity facts, and supporting evidence.Presenting AEO as a schema-only project. Structured data can clarify machine-readable facts, but it does not create authority or make weak content worthy of use.
    GEOGenerative engine optimization: improving the chance that a brand or its information is accurately represented, supported, and cited in generated responses.The scope includes generated answer behavior, third-party authority, citations, brand mentions, and source influence.Using GEO as an unexplained synonym for all SEO work or implying that optimization can guarantee a model recommendation.
    LLM optimizationA label centered on visibility or representation in products powered by large language models.The analysis genuinely concerns LLM-powered outputs, model-specific behavior, or the information environments those products use.Implying that a marketer can directly optimize an underlying model in the same way a page can be edited.
    Agentic search optimizationWork intended to help AI agents discover, evaluate, and use information while researching or completing tasks.Agent behavior and task completion are explicitly in scope, not merely the display of an answer.Using an early, specialized label as a general buyer-facing umbrella without defining what the agent is expected to do.

    The boundaries will overlap. An authoritative comparison page can support SEO, answer retrieval, generative citations, and agent research at the same time. That overlap is a reason to define the terms, not a reason to build separate teams around every acronym.

    For each term you adopt, write one sentence that answers three questions: Which discovery surface is in scope? What outcome are you trying to change? What work will the team perform? If the definition cannot answer all three, the term is branding rather than an operating instruction.

    Choose the term by the decision it needs to unlock

    The best label depends less on who has the newest vocabulary and more on what the recipient must decide. An executive deciding whether to fund the program needs a different level of detail from an analyst designing a prompt-monitoring workflow.

    1. For a strategy title, use “SEO and AI Search Visibility.” It connects the established function to the new outcome. Follow it with a scope statement naming the relevant answer surfaces, content, authority, technical foundations, and measurement.
    2. For a budget line, use “SEO, including AI search optimization.” State which existing budget funds it and which additional work the allocation covers. This prevents a terminology change from quietly becoming duplicate spending.
    3. For a vendor brief, ask for “AI search visibility across named buyer journeys and platforms.” Require the response to explain prompt selection, source analysis, content and authority work, measurement, and ownership. Do not award points merely for using GEO or AEO.
    4. For a dashboard, report “Organic Search” and “AI Search Visibility” as related views. Keep familiar SEO measures where they remain useful, then add AI-specific observations such as brand presence, answer accuracy, cited URLs, third-party source inclusion, referral quality, and assisted outcomes.
    5. For a specialist workstream, use the narrow acronym and define it. “AEO for support questions” or “GEO for category-comparison prompts” gives the term an object, a surface, and a purpose.
    6. For a job description, lead with the established function. A title such as “SEO Manager, AI Search” is easier to interpret than an acronym-only role. Put the changed responsibilities in the job scope: prompt research, answer-surface monitoring, entity consistency, structured content, external authority, and cross-channel measurement.

    Seniority changes the vocabulary but does not eliminate confusion. C-suite respondents used GEO at 28% and AEO at 17%, compared with 9% and 3% among individual contributors. Yet 56% of C-suite respondents also reported looking up an unfamiliar term. An executive using GEO may be signaling interest in the category, not agreement on a detailed operating model.

    Meet that interest with a definition, not another acronym. The most useful copy-ready version is:

    AI search optimization is the part of our SEO program that improves how our brand is discovered, represented, and cited in AI-generated search and answers. It combines technical accessibility, useful content, credible external signals, and measurement across the platforms our buyers use.

    That statement connects the emerging category to work a team can assign. It also avoids promising control over an AI system’s output.

    Clear language matters in vendor selection. Excessive buzzwords without explanations were the leading red flag for 36% of respondents. When GEO or AEO appeared in a pitch, 42% said their reaction depended on the context provided, 30% considered the language innovative, 22% said it had no effect, and 7% considered the vendor less trustworthy. The acronym can open a conversation, but it cannot carry the business case.

    Any internal proposal or vendor pitch should explain four things before introducing a specialized term:

    • Outcome: What should become more visible, accurate, authoritative, or useful?
    • Surface: Which search experiences, AI products, and buyer questions are included?
    • Method: What will change on owned pages, technical systems, structured data, external publications, community sources, or measurement workflows?
    • Evidence: What baseline, observations, and business measures will show whether the work helped?

    Turn terminology into an operating model

    Four teams at connected workstations contribute content, search, relationship, and measurement elements to a shared central hub.

    A new term earns its place only when it makes execution clearer. If GEO appears in a deck but nobody can identify the prompts, sources, owners, or measures attached to it, the team has renamed the problem rather than organized the work.

    Do not begin by creating a separate strategy for every platform. Reported priorities were fragmented: 34% prioritized ChatGPT, 16% Gemini, 6% Claude, 5% Copilot or Bing AI, and 1% Perplexity, while 14% had not selected a target platform. Those figures describe stated priorities in the U.S. sample, not platform usage or market share. They show why your own buyer behavior must determine scope.

    Build a scope from prompts and evidence sources

    1. Start with buyer decisions. Build a prompt set around the questions that precede discovery, comparison, validation, purchase, implementation, and troubleshooting. Include branded and unbranded questions. A list of head keywords alone will miss the context carried through a conversational query.
    2. Select surfaces based on those buyers. Test the relevant prompts across ChatGPT, Gemini, Google AI Overviews, Claude, Copilot or Bing AI, Perplexity, and any category-specific experience that matters to your market. You do not need to prioritize every surface equally.
    3. Record the answer, not just presence or absence. Capture whether the brand appears, how it is characterized, which alternatives appear, what factual errors matter, which URLs or publishers are cited, and whether the response satisfies the intended question.
    4. Map the information environment. Generated answers may draw influence from your own site, competitor content, list articles, trade publications, analyst pages, community discussions, Reddit threads, and YouTube transcripts. Mark each recurring source as owned, earnable, partner-controlled, community-controlled, or outside your realistic influence.
    5. Assign work by lever. SEO can own crawlability, internal architecture, canonical signals, and search demand. Content can own question coverage, clarity, evidence, and maintenance. PR and brand teams can build credible third-party mentions. Subject-matter experts can validate factual claims. Analytics can connect answer visibility to referral and downstream behavior.
    6. Name the workstream last. Once the team can see the surface, outcome, and activities, decide whether it is best described as SEO, AI search optimization, AEO, GEO, reputation work, digital PR, content operations, or a combination.

    This sequence prevents a label from dictating tactics. A query audit might reveal that a technical indexing problem is limiting discoverability, that weak comparison content is leaving an answer gap, or that authoritative third-party pages consistently omit the brand. Those are different problems even when all three reduce AI visibility.

    Measure the representation, the evidence, and the outcome

    No single metric can represent the entire program. An AI visibility score may help summarize repeated observations, but it can hide whether the brand is being recommended accurately, criticized, cited only for irrelevant questions, or mentioned without a path to the business.

    Use a compact scorecard with four layers:

    • Presence: How often does the brand appear for the defined prompt set, and which competitors appear beside it?
    • Representation: Are important facts, positioning, limitations, and differentiators described accurately?
    • Evidence: Which owned and third-party pages support the response? Are the citations relevant, credible, current enough for the question, and realistically influenceable?
    • Business effect: Do AI referrals, branded searches, qualified visits, assisted conversions, sales conversations, or other appropriate outcomes change alongside visibility?

    Keep the prompt set, platform set, capture method, and scoring rules documented. Otherwise, an apparent gain may come from changing the questions or evaluation method rather than changing market visibility. Generated responses can vary, so repeated observations and saved evidence are more useful than treating one answer as a permanent ranking.

    The naming debate should not consume the strategy. In the same decision-maker group, 28% named the pace of change as their leading challenge, ahead of measuring AI-result performance or visibility at 17%, choosing platforms at 15%, and the lack of standards or best practices at 13%. A durable operating model should therefore preserve familiar ownership while allowing the tested platforms, prompts, sources, and measures to change.

    Key takeaways

    • Keep SEO as the default organizational umbrella unless a different label solves a specific ownership or budgeting problem.
    • Use AI search optimization when you need a clear external or cross-functional name for the work.
    • Use AI search visibility for the outcome you measure, not as a substitute for defining the work.
    • Use AEO, GEO, LLM optimization, or agentic search optimization only with a one-sentence definition of the surface, outcome, and activities.
    • Do not mistake slow acronym adoption for weak investment. Teams can fund new work while keeping the familiar SEO label.
    • Evaluate a strategy by its prompts, evidence sources, owners, and measurements. Terminology is useful only when it makes those elements easier to understand.

    Open your current strategy document and inspect the first mention of the program. If it contains only an acronym, replace it with “SEO and AI Search Visibility” and add one sentence defining the surfaces, outcomes, and work included. If a term cannot be mapped to an owner, an activity, and a measure, remove it until it can.

    References


  • Brand-Led SEO: How to Earn Visibility in AI Search

    Brand-Led SEO: How to Earn Visibility in AI Search

    Your site can have technically sound pages and still disappear when a buyer asks an AI assistant which provider fits their problem. If your first response is to publish more keyword-targeted landing pages, pause. You may be trying to fix a brand-evidence problem with page volume.

    Brand-led SEO gives every part of your search program the same job: help people and machines identify who you are, when you are relevant, and why your claims deserve consideration. You still optimize individual URLs. The difference is that those URLs now reinforce a coherent, verifiable brand rather than competing as isolated assets.

    AI search adds a brand-level decision above page ranking

    Conventional search can rank one URL against another. An AI-generated answer may instead resolve several entities, apply the user’s constraints, summarize evidence, and present a shortlist of companies. It can cite several pages, one page, or no visible page while still naming a brand. In other words, AI search can recommend a brand rather than merely present a winning page.

    That does not mean pages, links, crawling, or technical SEO have stopped mattering. Pages remain evidence and retrieval units. The added requirement is coherence: the system must be able to reconcile the company described on your homepage with the company represented in your structured data, product documentation, author profiles, partner listings, media coverage, and public conversations.

    LayerQuestion to auditWhat usually needs fixing
    RetrievalCan a relevant, accessible page be found for the decision?Indexability, internal links, page purpose, headings, and direct answers.
    Entity understandingDo your names, categories, offerings, audiences, and relationships agree?Canonical facts, visible copy, structured data, profiles, and contradictory descriptions.
    Recommendation confidenceDoes available evidence show that your brand fits the user’s constraints?Specific proof, honest limitations, decision content, and independent corroboration.

    Run one commercially important question through all three layers. If your company is described as a platform on one page, an agency on another, and a tool in external profiles, a new comparison page will not resolve the identity problem. If the identity is clear but none of your evidence addresses the buyer’s constraint, adding more Organization markup will not establish fit.

    A useful operating assumption is that search will increasingly sit beneath agentic experiences as infrastructure. The interface may change, but useful content and demonstrable trust still have to enter the system somewhere. Brand-led SEO makes those inputs deliberate.

    Write a canonical entity brief before touching JSON-LD

    A translucent prism on a drafting table connects symbolic objects to matching shapes on several blank cards.

    Most consistency problems start upstream. Different teams have quietly adopted different answers to basic questions: what category the company belongs to, which audience it serves, what the product includes, and which differentiators can actually be proved. Structured data then encodes those disagreements instead of resolving them.

    Create a short entity brief that acts as the internal source of truth. It should contain:

    • Identity: the public brand name, any legitimate name variants, the legal name when it is publicly relevant, and the canonical website.
    • Category: the most specific category you can support, plus adjacent categories that require qualification. Do not claim every category in which you want visibility.
    • Audience and jobs: who the offering is built for, the problem it addresses, and the situations in which it is or is not a fit.
    • Offerings and relationships: product and service names, which organization provides them, and how sub-brands or acquired products relate to the parent brand.
    • Availability: supported markets, languages, customer types, delivery models, or other material constraints that buyers need to know.
    • Claims and proof: each important differentiator paired with a page, document, named example, or independent reference that substantiates it.
    • Boundaries: capabilities you do not offer, conditions attached to a claim, and wording that marketing must not use without further evidence.

    Turn the brief into a one-sentence identity statement: [Brand] is a [specific category] for [defined audience] that helps with [job] through [documented mechanism]. This is not a slogan. It is a test. If product, sales, communications, support, and leadership would fill the brackets differently, machines are likely to encounter the same disagreement.

    Implement the brief in this order:

    1. Align visible pages. Check the homepage, About page, product or service pages, documentation, contact information, author pages, and any location pages. Give each page its own purpose, but keep foundational facts stable.
    2. Model the relationships in structured data. Use an appropriate Organization type with one stable @id. Connect Product or Service entities to that organization through accurate brand or provider relationships. Connect articles to their real publisher and visible authors.
    3. Use sameAs selectively. Include profiles that genuinely identify the same organization. A collection of marginal or abandoned accounts is not stronger than a small set of maintained official profiles.
    4. Reconcile external profiles. Update partner directories, professional listings, social profiles, marketplace pages, and other records you control so their category and naming match the brief.
    5. Log contradictions you cannot edit. Record the incorrect statement, its location, the correct evidence, the owner who can request a change, and the status of that request.

    JSON-LD is an identity aid, not a reputation generator. It can clarify that a product belongs to an organization or that two references describe the same entity. It cannot make an unsupported superlative true, convert an aspirational category into an established one, or compensate for visible copy that says something else. Mark up what a reader can verify on the page, and reuse the same entity relationships across the site.

    Build evidence for decisions, not a larger pile of keywords

    A keyword list usually captures phrasing. An AI recommendation request also carries context: the buyer’s role, use case, budget model, location, integration requirement, risk tolerance, or implementation constraint. Brand-led content has to answer the decision, not merely repeat the category term.

    Start with the real question families around one offering:

    • Category discovery: What kinds of solutions address this problem?
    • Audience fit: Which option is appropriate for a particular role, company type, or level of complexity?
    • Constraint fit: Which options work with a required platform, process, geography, or operating condition?
    • Comparison: How do two approaches or providers differ on criteria that affect the decision?
    • Risk and validation: What are the limitations, dependencies, security considerations, or proof points?
    • Implementation: What does adoption, migration, integration, or ongoing use require?

    Assign every important question to a page with a clear evidence job. A category explainer should define the choices and their tradeoffs. A use-case page should establish audience fit. Documentation should verify how a capability works. A comparison page should expose its criteria and acknowledge where another approach fits better. A case study should identify the customer context, the action taken, and only the outcomes you can substantiate.

    Give each decision page four components:

    1. A scoped answer. State who or what the page is for in the opening paragraphs. Avoid an unqualified claim that your brand is best.
    2. Evaluation criteria. Name the factors a reasonable buyer should use and explain why they change the choice.
    3. Claim-level evidence. Link capabilities to documentation, customer outcomes to credible case material, and policies to the controlling policy page.
    4. A boundary and next step. Say when the advice does not apply, then direct the reader to the next useful verification or action.

    Replace slogans with extractable statements. One platform for every business gives a recommendation system little usable context. [Brand] serves [audience] that needs [job], supports [verified capabilities], and requires [material condition] is easier to evaluate because each part can be checked.

    Do not split content and technical work into separate definitions of success. Technical excellence cannot rescue content that misses the user’s intent, while useful content can struggle without a trustworthy technical foundation. For every priority page, review the answer and its retrieval conditions in the same ticket: indexability, canonical handling, internal links, visible authorship, supporting entities, freshness-sensitive claims, and the path to primary evidence.

    Earn corroboration that explains the brand, not just links to it

    Several independent evidence stations cast beams of light onto an unbranded ceramic vessel on a central pedestal.

    A claim on your own domain is still a self-authored claim. Independent descriptions play a different role: they can confirm that the organization exists in a category, has a real relationship, serves a recognizable audience, or is known for a particular body of work. This is why brand consistency and earned mentions deserve attention alongside conventional backlink acquisition.

    Do not turn that observation into a universal formula about how every AI system weights links and mentions. These systems differ, and their recommendation processes are not exposed as one stable ranking algorithm. The practical lesson is narrower: a descriptive mention can carry entity and reputation context that a bare link does not, while a relevant linked mention may contribute both context and discoverability.

    Build an external evidence map around the claims that matter to purchase decisions. Use columns for the claim, owned proof, independent corroboration, conflicting descriptions, the external party involved, and the next legitimate action. Then work the gaps:

    • Ask real partners to describe the relationship accurately on integration or partner pages. Do not imply a partnership that is merely technical compatibility.
    • Give journalists, analysts, event organizers, and podcast hosts a concise fact sheet with the correct company name, category, audience, executive names, and supporting URLs. Let them retain editorial control over their wording.
    • Help customers document outcomes only when they consent and the underlying facts can be verified. Preserve the conditions around any result.
    • Correct outdated categories and descriptions at their original locations. Repeating the right wording on your own site does not remove the contradictory record.
    • Contribute useful explanations to professional communities under identifiable authorship. Publishing what you are learning and participating in the community creates a public record of expertise, but it should serve people first rather than imitate an algorithmic signal campaign.

    Relevance is more valuable than mention volume. A detailed description in a context your buyers trust does more reputational work than a generic placement that happens to include optimized anchor text. The editorial brief should therefore focus on accurate facts and genuinely useful expertise, not a demanded phrase or link configuration.

    This is where SEO, digital PR, content, product marketing, and reputation management have to share a record. If each team promotes a different category or proof point, more activity produces more ambiguity. The entity brief supplies the shared language; the evidence map shows where independent confirmation is still missing.

    Measure recommendation readiness with a fixed prompt scorecard

    Do not reduce the program to the question, Do we rank in AI? Generated responses can vary by product, model, mode, account context, location, and wording. A single answer is an observation, not a durable position. You need a repeatable scorecard that separates brand presence from brand accuracy and recommendation fit.

    Create a small, fixed portfolio of natural questions drawn from the decision families above. Include unbranded discovery questions, audience and constraint questions, comparisons, and branded verification questions. Keep the wording stable when establishing a baseline, and record the surface, model or mode when visible, account or location conditions that may matter, the date, and the complete answer.

    Classify each observation by what it tells you:

    • Absent where the brand is a legitimate fit: inspect retrieval, category clarity, relevant decision content, and external corroboration.
    • Present but misclassified: find conflicting category language, old profiles, duplicate entities, or weak relationships in structured data.
    • Present but described vaguely: strengthen extractable facts and connect important claims to specific evidence.
    • Accurately compared but not selected: examine whether the user’s constraint truly favors your offering. If it does, identify the missing proof. If it does not, treat the exclusion as accurate.
    • Recommended with a weak or irrelevant citation: improve the page that best substantiates the recommendation and make its relationship to the brand explicit.
    • Recommended inaccurately: treat this as a defect, not a win. Correct the underlying ambiguity before amplifying the answer.

    Track citations, but do not make them your only outcome. Also record whether the name is correct, the category is accurate, the described audience matches the offering, the stated capability is supported, material limitations appear, and the recommendation makes sense for the prompt. A brand should not want inclusion in a shortlist it cannot responsibly serve.

    Turn the findings into an owned backlog. Break the program into subprojects, tasks, deadlines, and individual work items: identity reconciliation, technical retrieval, decision content, external corroboration, and measurement. Give every item an owner, the evidence of the problem, the proposed correction, and a condition for verification. Retest the same prompt set after material changes have had a chance to appear in the environments you are observing.

    Key takeaways

    • AI visibility requires both retrievable pages and a brand identity that can be reconciled across owned and external records.
    • A canonical entity brief should define your name, category, audience, offerings, claims, proof, and boundaries before those facts enter JSON-LD.
    • Content should answer buyer decisions and constraints, with each important claim connected to evidence and an honest scope.
    • Earned mentions matter when they accurately explain the brand in a relevant context; they should not be treated as a volume substitute for link building.
    • Measure presence, accuracy, fit, evidence, and citations separately. An inaccurate recommendation is not successful visibility.

    Start with one high-value customer question. Write the canonical answer about your brand, inspect the page that should support it, compare your structured data and external descriptions, and log the first contradiction or evidence gap you find. Assign that gap as a concrete task. Repeating that cycle will build a brand record that your SEO, content, and communications work can strengthen instead of fragment.

    References