Category: AI

  • False Allegations in Google AI Answers: How to Respond

    False Allegations in Google AI Answers: How to Respond

    You search your name and find a Google AI-generated answer accusing you of misconduct, suspension, fraud or another event that never happened. Your first move matters. The answer may change after the next query, while screenshots of the original allegation could become essential to a platform report, a publisher correction or legal advice.

    Treat this as an evidence, identity and reputation incident. Preserve what Google displayed, determine how the false narrative was assembled, correct the information environment around it and keep testing until the error is genuinely gone. A rewritten answer is not necessarily a corrected answer.

    Key takeaways

    • Capture the complete output before acting. Keep the query, wording, citations, date, time, language, location and relevant account context together.
    • Diagnose the failure precisely. A false source, unsupported citation, identity collision and invented inference require different corrections.
    • Work on three tracks. Report the AI answer, correct inaccurate or ambiguous web content and assess the professional or legal risk separately.
    • Strengthen your canonical identity. Consistent profile information and accurate Person JSON-LD can reduce ambiguity, but markup cannot force Google to retract an allegation.
    • Test a query set, not one search. The wording can disappear from one answer while surviving in related queries or a vaguer narrative.

    Preserve the output before it changes
    A laptop and phone are arranged on a desk to document a generic AI-generated answer, with a clock, notebook, and evidence folder nearby.

    Do not begin by editing your website or publishing an angry rebuttal. Generated answers can vary across queries and over time. In one documented incident, later searches replaced specific accusations with different but still inaccurate language, making the original output harder to reconstruct. Your evidence packet should exist before you ask anyone to change anything.

    1. Capture the whole result page. Save full-page screenshots and, where practical, a short screen recording that starts with the query and scrolls through the complete generated answer. Do not crop out qualifications, citations or surrounding context.
    2. Copy the exact text. A searchable text copy makes it easier to compare later versions word by word. Preserve unusual punctuation, headings and certainty language such as reportedly, allegedly, faced scrutiny or was suspended.
    3. Record the search conditions. Note the exact query, date, time zone, displayed language, approximate search location, device type and whether you were signed in. These details do not prove why the output appeared, but they make reproduction more disciplined.
    4. Save every cited page. Record each URL and the passage that supposedly supports the answer. Keep a copy of the page as it appeared at the time. The page may later be edited, removed or recrawled.
    5. Preserve contradictory evidence separately. Collect official registers, employer records, court or regulatory records, dated professional biographies and other primary material that establishes the accurate facts. Do not annotate or alter the originals.
    6. Start an impact log. Record who encountered the claim, when they saw it, what they did because of it and any resulting professional, contractual or financial consequence. Save direct communications rather than reconstructing them from memory later.
    7. Give each version an identifier. Labels such as AI-01, AI-02 and AI-03 make it clear which query, screenshot, output and report belong together.

    Keep an untouched evidence set and use redacted copies when sharing it. Search pages can expose account information, location clues or other personal data that a publisher, colleague or outside adviser does not need.

    Find where the false narrative entered the answer
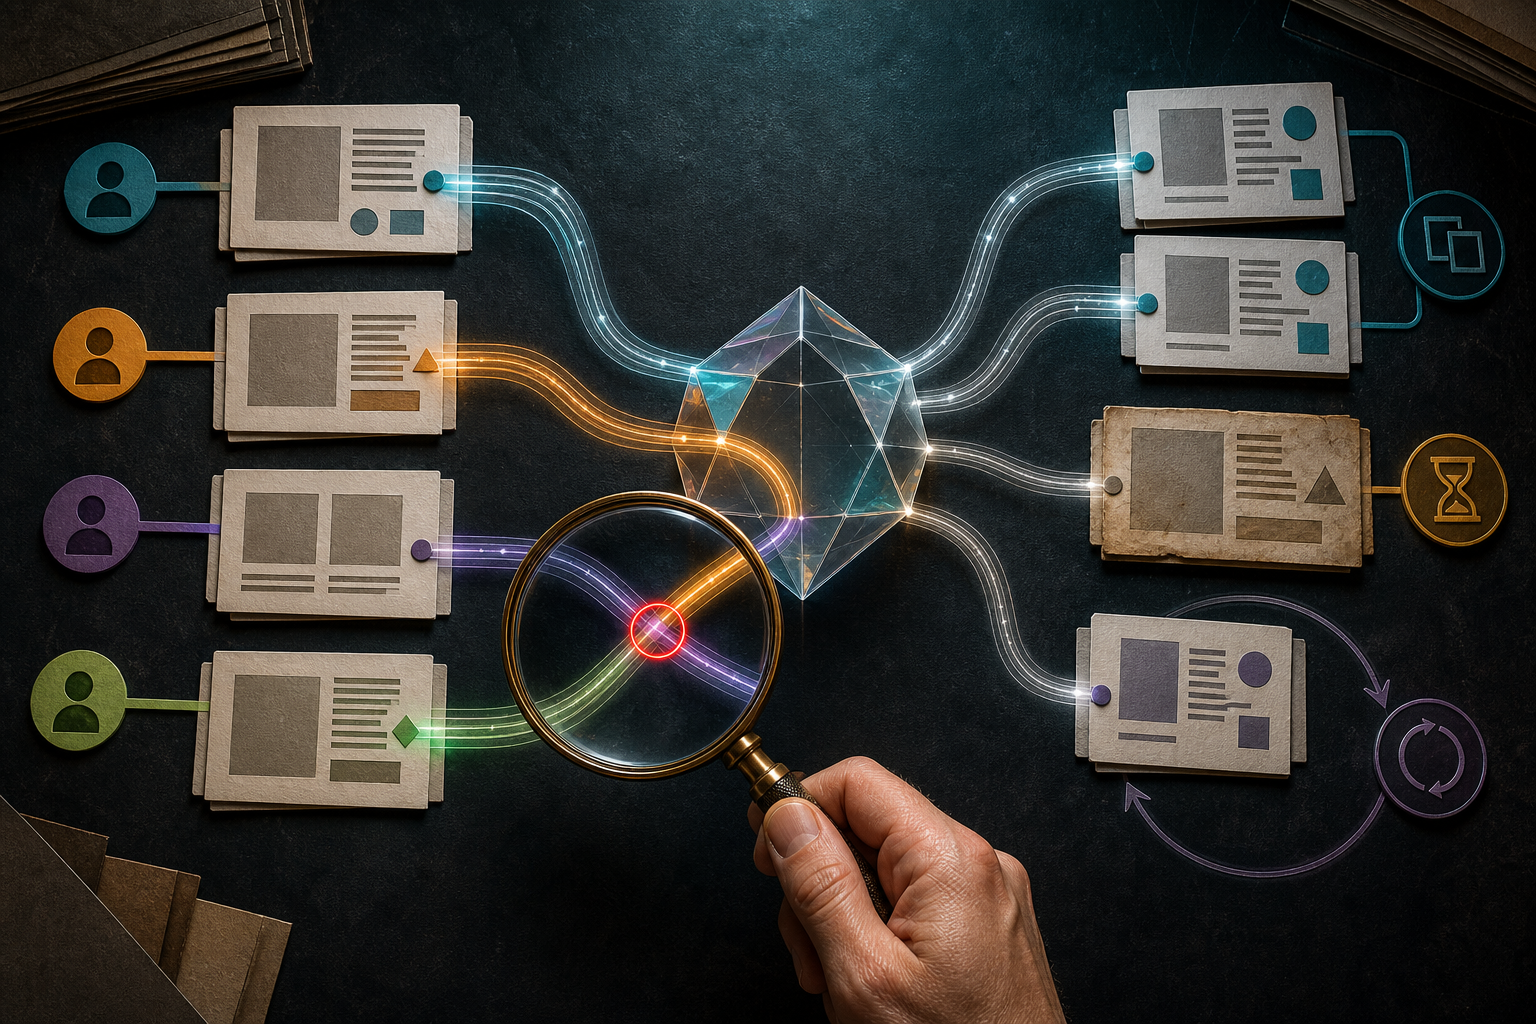
    Anonymous source cards connect to a central AI prism, with a magnifying glass highlighting one identity strand routed into the wrong path.

    Calling the output a hallucination may be emotionally accurate, but it is not a useful diagnosis. Break every allegation into an individual factual proposition, then trace the apparent support for each one. One paragraph can contain several different failure modes.

    1. An underlying page makes the false claim

    If a cited page actually contains the accusation, the problem begins upstream. You need a correction, clarification, removal or legal assessment involving that page as well as feedback about the AI answer. Fixing your own profile will not neutralize a false statement that remains published elsewhere.

    2. The citation does not support the generated sentence

    A page may mention the right person but not the alleged event, or describe scrutiny without documenting a suspension. Record that mismatch exactly. The strongest report is not that the answer feels misleading; it is that a specific sentence asserts fact X while its displayed citation establishes only fact Y.

    3. Google has joined two identities

    Look for shared surnames, professional titles, employers, locations, initials, channel names and subject terms. An identity collision can occur even when each underlying fragment is real. The falsehood appears in the bridge between them.

    UK doctor and YouTuber Dr. Ed Hope said Google’s AI falsely claimed that he had been suspended in mid-2025, profited from selling sick notes, exploited patients and faced discipline because of his online fame. He believed the system may have connected his inactive YouTube channel, Dr. Hope’s Sick Notes, with an unrelated sick-note controversy involving another doctor, Dr. Asif Munaf. That explanation is a plausible identity-collision hypothesis, not a verified account of Google’s internal generation process. The important diagnostic lesson is that real fragments can be connected by a completely false relationship.

    4. The answer invents a narrative between unrelated facts

    The person and event may both be identified correctly while the claimed cause, motive or sequence is fabricated. A gap in publishing activity does not establish professional discipline. Online visibility does not establish that fame caused a regulator to act. Treat every causal word, not just every name and date, as a claim requiring support.

    Build a claim map with six fields: the exact AI sentence, its displayed citation, what that page actually says, the person or event described, the evidence establishing the accurate fact and the likely failure mode. This map becomes the working document for platform reports, publisher requests and professional advice.

    Run the correction on three separate tracks

    No single action covers the entire incident. Platform feedback addresses Google’s output. Publisher corrections address material on the open web. Professional and legal advice addresses the consequences. Run these tracks in parallel, but keep their evidence and objectives distinct.

    Track 1: Report the generated answer

    Use the feedback or reporting control attached to the answer when one is available. Interface labels can vary, so focus on the substance of the submission rather than the name of the button. Include:

    • the exact query and search conditions;
    • the complete false sentence, not a paraphrase;
    • the accurate fact stated in one direct sentence;
    • the identity distinction if another person or event has been attached to you;
    • the displayed citation and the precise reason it does not support the claim;
    • links to primary evidence that a reviewer can verify; and
    • the evidence identifier for your corresponding screenshot and text copy.

    Keep the report factual. Explain which proposition is false and how it can be checked. A long argument about AI safety gives a reviewer less usable information than a short claim-by-claim correction. Save any confirmation, case number or submitted text. If a materially different answer appears, preserve it as a new version before reporting that version too.

    Track 2: Correct the cited information environment

    If an external page contains the error, send its publisher a precise correction request. Identify the URL, heading, sentence, false proposition and primary evidence. Ask for a visible correction where quiet editing would leave readers with no way to understand what changed.

    If the cited page is accurate but Google has overstated it, do not pressure the publisher to rewrite a correct record merely to accommodate the AI system. Preserve the citation mismatch and concentrate the platform report on the unsupported inference. You can still ask the publisher to make ambiguous names or relationships clearer when a reasonable reader could confuse them.

    Track 3: Assess professional and legal exposure

    Claims involving criminal conduct, fraud, professional suspension, patient exploitation or regulatory discipline can carry consequences beyond search visibility. If the allegation is serious, persistent or already affecting work, speak with a lawyer qualified in defamation and reputation matters in the relevant jurisdiction. An SEO workflow is not a substitute for legal advice.

    Do not assume that Section 230 either resolves the issue or is relevant everywhere. It is a question of US law, and some legal experts have argued that generated output may be a newly published statement rather than third-party speech. Whether that position applies to a particular output, defendant or jurisdiction requires a legal assessment.

    Before notifying an employer, regulator, insurer, client base or large social audience, decide with the appropriate legal or communications adviser what the notification should accomplish. Unnecessary circulation can expose more people to the accusation and create additional searchable copies of it. Where a stakeholder genuinely needs warning, provide the preserved output, the accurate record and a concise statement of the steps underway.

    Make your identity harder to confuse without amplifying the lie

    A cleaner entity footprint can help search systems distinguish you from a namesake or unrelated event. It cannot prove a negative, erase an external page or guarantee a corrected AI answer. Think of it as disambiguation infrastructure, not a deletion tool.

    • Choose one canonical profile URL. Put the person’s full professional name, current role, organization, jurisdiction or location where appropriate, official profile links and a clear biography on a stable HTML page.
    • Keep identity facts consistent. The name, title, organization and profile links on the canonical page should agree with the organization’s team page and the person’s legitimate professional or social profiles. Resolve old titles and unexplained variants rather than publishing conflicting descriptions.
    • Add accurate Person JSON-LD. Use a stable @id and properties such as name, url, jobTitle, worksFor or affiliation, sameAs and, where genuinely useful, disambiguatingDescription. Every property should describe visible, verifiable page content.
    • Use sameAs narrowly. Link only to pages that represent the same person. A page that merely mentions the person, covers a similar topic or belongs to a namesake is not an identity-equivalent profile.
    • Connect primary records. Where appropriate, link to an official organization profile, professional register or other authoritative record that lets a reader verify the stated status directly.
    • Add contextual internal links. Organization biographies, author pages and relevant professional pages should link to the canonical profile using the person’s full name, not vague anchor text.
    • Clarify ambiguous brands and titles. If a channel, project or company name resembles the subject of an unrelated controversy, explain what it is and who owns it on the canonical page.

    If the allegation has already reached stakeholders, a short clarification page may be appropriate after legal or communications review. Keep it narrower than the rumor. State the accurate status, link to the record that verifies it, identify any mistaken entity only as far as necessary and show a publication or update date. Put the factual clarification in visible HTML rather than hiding it inside an image or downloadable file.

    A usable correction pattern: [Name] has not been [falsely alleged action]. [Official record] confirms [accurate status] as of [date]. The event involving [different person or organization] is unrelated. Use this structure only when every part is true, supported and appropriate to publish.

    Avoid mass-producing rebuttal pages, copying the accusation into every profile or adding unsupported positive claims to structured data. Those tactics enlarge the same noisy information environment that allowed the collision. One well-supported canonical record is more useful than a network of repetitive denials.

    Verify a correction instead of mistaking change for resolution

    When the original sentence disappears, resist declaring victory. The system may have removed the panel, softened the wording, changed its citations or moved the false association into another query. Verification needs a fixed test set and a record of every result.

    Your test set should cover:

    • the person’s exact name;
    • the name plus profession, organization or location;
    • the name plus the alleged event or disciplinary term;
    • the name plus the confused person’s distinguishing details;
    • the other person’s name plus the topic that triggered the collision; and
    • a distinctive excerpt from the original false sentence.

    For every check, record whether an AI answer appeared, its exact wording, its citations, the identity it described and the degree of certainty it used. Repeat relevant checks in the languages and locations where the person’s audience actually searches. Do not organize a public campaign asking large numbers of people to run the allegation as a query; that can spread the wording without producing controlled evidence.

    A correction is credible when the false assertion is absent across the relevant query set, replacement statements are accurate, displayed citations support what Google says, the mistaken identity no longer appears and later checks remain clean. A single favorable search is only one observation.

    Changed language deserves particular scrutiny. In Dr. Hope’s case, a later answer referred more vaguely to scrutiny and suspension, but it still attached an invented professional narrative to him; another variation blurred real and fictional contexts. The incident shows why less specific wording can remain materially false.

    Once the results are clean, archive the final test log and retain the evidence packet under an appropriate retention policy. Assign one person to own future checks and record the platform, publisher, legal and communications contacts that were useful. If you have not faced an incident yet, create the canonical identity page and branded-query test set now. Those two assets remove guesswork when a harmful answer appears.
    References

  • AI Orchestration Systems: A Practical Production Guide

    AI Orchestration Systems: A Practical Production Guide

    You may already have a model that writes, an agent that analyzes, and automations that move data between applications. Each component can look impressive on its own. The trouble appears at the handoffs: context gets lost, nobody owns exceptions, and the workflow stops before it produces a measurable business result.

    An AI orchestration system closes those gaps. It determines what should happen next, routes work to the right tool or person, preserves state, enforces permissions, checks results, and captures evidence. The practical question is not how many agents you can deploy. It is which decisions you want the system to coordinate, and where human control still matters.

    The coordination gap is where AI value disappears

    Most organizations do not lack AI capabilities. They lack a reliable way to combine those capabilities into an end-to-end operating process. The martech market contains more than 15,384 solutions, yet only 33% of available technology is fully used. Adding another isolated tool can increase the number of possible actions without improving the flow of work.

    This is how pilot theater develops. A team proves that a model can produce a draft, classify a lead, or summarize a report. The demonstration succeeds, but the business workflow remains incomplete. The draft still needs facts, approval, publication, distribution, and measurement. The classified lead still needs routing, ownership, follow-up, and a feedback signal from the CRM. The summary still needs a decision and an accountable person.

    Point solutions optimize individual tasks. Orchestration coordinates the outcome across tasks. That coordination can support fluid budget decisions, buying-group alignment, and content loops connected to real buyer needs. In each case, the value comes from moving information and decision rights across boundaries, not from generating more output inside one application.

    Design questionSimple automationAI orchestration
    How is the next step chosen?A fixed rule or sequence determines it.Rules, models, context, and policy can select a route within defined boundaries.
    What happens to context?Each step receives a predetermined set of fields.The system assembles relevant context and preserves task state across tools.
    What happens when work fails?The workflow retries, stops, or sends a generic alert.The system classifies the exception, selects an allowed fallback, or escalates it with evidence.
    How is success measured?Execution is often treated as completion.Completion requires verified output and a connection to the intended operational or business result.

    Not every process needs AI orchestration. If a workflow follows stable rules, uses known inputs, and has one valid path, conventional automation is usually easier to test and maintain. Orchestration earns its added complexity when the process crosses systems, requires interpretation, contains meaningful exceptions, or must adapt its route without surrendering control.

    What a production orchestrator must control

    An isometric workflow facility routes a task through state management, permission checks, AI tools, human review, verification, and evidence storage.

    An orchestration system is not merely an LLM with access to several APIs. A production design needs an explicit control layer around every decision and action. Whether you buy a platform or assemble one from existing components, make sure it covers these seven responsibilities:

    1. Trigger and goal: Define what starts the workflow, what outcome it is pursuing, and what conditions should stop it. A vague instruction such as “improve this page” is not an operational goal. “Prepare a reviewable refresh package for this URL using approved product facts” is bounded and verifiable.
    2. Context assembly: Retrieve only the information needed for the current decision. That may include customer records, content history, analytics, brand rules, product facts, or approval status. More context is not automatically better; irrelevant or conflicting material can make the decision harder to inspect.
    3. Planning and routing: Select the next valid step. The router may use deterministic rules, a model, or a combination of both. Put hard requirements in rules and reserve model judgment for genuinely ambiguous work.
    4. Tool execution: Invoke a search service, CMS, analytics platform, CRM, validation tool, or specialist agent through a controlled interface. The orchestrator should know what an action is allowed to do, not merely how to call an endpoint.
    5. State management: Record the task’s status, inputs, decisions, outputs, approvals, and outstanding exceptions. Do not treat a model’s chat history as the system of record. Operational state needs a durable structure that other systems and people can inspect.
    6. Policy and approval: Check permissions before an action runs. Data access, publishing, deletion, customer communication, and budget changes should each have explicit authorization rules.
    7. Evaluation and feedback: Validate the immediate output, observe what happened after the action, and return that evidence to the workflow. Feedback may change a later route, create a follow-up task, or show that no further action is warranted.

    Give every action a contract

    The fastest way to expose a fragile orchestration design is to ask what each action promises. Create a short contract for every tool, agent, and human handoff:

    • Accepted input: The required fields, formats, and data sources.
    • Preconditions: The permissions, approvals, and prior states that must exist.
    • Allowed effect: What the action may read, create, change, publish, send, or spend.
    • Success evidence: The artifact or system state that proves the action completed correctly.
    • Failure output: A structured error that distinguishes missing data, denied access, invalid output, provider failure, and policy rejection.
    • Retry behavior: Whether retrying is safe and how the system prevents duplicate actions.
    • Escalation owner: The person or queue that receives an unresolved exception, along with the context needed to act.

    This contract turns an unpredictable failure into a known operational state. It also makes tools replaceable. The orchestrator can request a capability such as create_content_brief or validate_structured_data without embedding the entire workflow in one vendor’s prompt format.

    That separation matters in a fragmented market. Nearly 40% of US consumers have tried generative AI, while regular usage and platform loyalty remain less settled. Your production process should not assume that one model, interface, or vendor will always be the best route. Keep business policy, operational state, and evaluation criteria outside the model so you can change providers without redesigning the workflow.

    Design the first workflow around a costly handoff

    Do not begin with a goal as broad as “orchestrate marketing.” Choose one workflow where coordination failure is already visible. A strong first candidate has several of these characteristics:

    • Work repeatedly crosses tools, teams, or approval boundaries.
    • People spend time copying context, checking status, or deciding who should act next.
    • The desired completion state can be observed in a system or reviewed as an artifact.
    • The first version can recommend, draft, classify, or route before it receives permission to make irreversible changes.
    • Common exceptions can be named, even if they cannot all be resolved automatically.
    • The outcome matters enough to measure, but the workflow is narrow enough that one owner can govern it.

    Map the current process before selecting an orchestration platform. Write down the trigger, end state, decision points, required systems, human owners, exception paths, and completion evidence. If the team cannot agree on those elements, an agent will not resolve the ambiguity. It will automate the disagreement.

    An SEO and GEO content workflow example

    Consider a content refresh process. A weak implementation asks a model to rewrite a declining page and treats the new draft as the result. A properly orchestrated workflow connects diagnosis, evidence, production, quality control, publication, and post-publication observation.

    1. Observe: A defined signal creates a task. The signal might be a product change, an identified content gap, outdated information, or a meaningful visibility change. The task records why the page entered the workflow.
    2. Assemble evidence: Retrieve the existing page, approved product facts, site taxonomy, relevant performance data, editorial requirements, and known related content. Each input should carry its origin and current version.
    3. Decide: Choose among refresh, consolidation, new content, technical correction, escalation, or no action. Allowing a no-action decision is important; orchestration should reduce unnecessary work, not manufacture it.
    4. Prepare: Produce the bounded artifacts the next owner needs, such as a brief, proposed changes, internal-link recommendations, or eligible structured-data updates. Structured data should describe facts actually present on the page, not claims invented to satisfy a schema type.
    5. Verify and approve: Check factual support, links, required fields, schema syntax, indexability, and editorial policy. Keep publishing behind human approval until the workflow’s reliability and exception handling are demonstrated.
    6. Observe the result: Record publication and subsequent operational signals, then connect them to the original task. Search visibility, qualified actions, editorial rework, and technical errors answer different questions, so do not collapse them into one vague success score.

    The important change is not that AI generated part of the work. It is that every transition has an owner, a state, a control, and evidence. The same pattern can be applied to campaign changes, lead routing, customer-support escalation, or research workflows without pretending that those processes share identical rules.

    Close the loop with evidence, guardrails, and economics

    A circular workflow passes through automation, human approval, security inspection, verification, evidence storage, and a metered resource supply.

    A workflow is not closed merely because the last API call returned successfully. It is closed when the intended effect is verified, exceptions are accounted for, and the result can inform the next decision. Build that evidence into the design before you scale execution.

    Measure the outcome and the machinery separately

    Choose one primary business outcome and a small set of operational measures before launch. A useful measurement stack separates four layers:

    • Outcome: The result the workflow exists to influence, such as qualified opportunities, organic conversions, resolved issues, accepted content updates, or another observable business event.
    • Flow: Completion rate, cycle time, queue age, handoff delay, and exception rate. These show whether work is moving through the system.
    • Quality: Approval without rework, validation success, factual corrections, policy violations, and downstream reversals. These show whether completion is trustworthy.
    • Economics: Total model, platform, review, and remediation cost divided by an accepted outcome. Token spend is a useful diagnostic, but it is not a return-on-investment measure by itself.

    Do not optimize a local metric at the expense of the workflow. A cheaper draft that creates more editorial rework can increase total cost. A faster agent that produces duplicate CRM actions can damage the process it was meant to improve. Measure from trigger to verified outcome so the trade-off remains visible.

    Put control points before consequential actions

    • Use least-privilege access: Give each tool only the records and actions required for its role. A research agent does not need publishing permission merely because both functions appear in the same workflow.
    • Validate before writing: Check required fields, formats, factual support, policy conditions, and destination state before changing an external system.
    • Require approval where consequences are material: Publishing, deletion, customer communication, access changes, and budget movement should have named approval rules. The reviewer should receive evidence and proposed effects, not a bare approve-or-reject button.
    • Make retries safe: Assign an operation identifier and check whether an action already succeeded before repeating it. Otherwise, a timeout can become a duplicate publication, message, order, or record.
    • Set explicit fallbacks: Define what happens when a model, API, or data source is unavailable. Valid options include a deterministic route, another approved provider, a human queue, or a controlled stop.
    • Version the operating logic: Record which prompt, policy, model, tool definition, and data version influenced a decision. Without versions, you cannot explain a changed result or reproduce a failure.
    • Provide a stop mechanism: An owner must be able to pause new work without erasing in-progress state. Recovery is much easier when the system can resume from a known checkpoint.

    Use a go-live test that a business owner can answer

    Before moving beyond a controlled pilot, require a clear yes to each of these questions:

    • Can you trace one task from its trigger to its verified outcome?
    • Is there a named system of record for task state and approvals?
    • Can the system distinguish a failed action from an action whose result is merely unknown?
    • Can a failed step be replayed without duplicating an external effect?
    • Does every unresolved exception reach a named owner with useful context?
    • Can you change a model or tool without rewriting the business policy?
    • Does reporting show outcomes, quality, exceptions, and total cost rather than only calls and tokens?

    If any answer is no, keep the workflow in a learning environment. The missing item is not administrative polish. It is part of the production system.

    Key takeaways

    • An AI orchestration system coordinates decisions, tools, state, permissions, exceptions, and feedback across an end-to-end workflow.
    • Use simple automation for fixed, predictable paths. Add orchestration when context, interpretation, multiple systems, or variable routes make coordination the real problem.
    • Start with one costly handoff whose trigger, owner, completion state, and business outcome can be named.
    • Give every agent and tool an action contract covering inputs, permissions, effects, success evidence, failure output, retries, and escalation.
    • Keep policy, operational state, and evaluation criteria outside individual models so providers remain replaceable.
    • Measure verified outcomes, flow, quality, and total cost. A successful API call or generated artifact is not sufficient evidence of business value.

    Your next step is to draw one real workflow from trigger to outcome. Circle every point where someone interprets context, moves information between systems, waits for approval, or repairs a failed handoff. Those circles are your orchestration candidates.

    Choose one candidate, define its action contracts, and run it with narrow permissions and visible approvals. If you cannot name the evidence that proves the workflow finished correctly, do not add another agent yet. Fix the definition of done first.

    References

  • How to Build Reliable AI-Powered Content Operations

    How to Build Reliable AI-Powered Content Operations

    Your content backlog probably isn’t blocked by typing. It is blocked by everything around the typing: choosing what deserves attention, finding approved evidence, routing reviews, resolving exceptions, recording decisions, and knowing when a published page needs another pass. Add AI without fixing that system and you can create more drafts while making the operation harder to control.

    AI-powered content operations works when models move structured tasks through a governed lifecycle. The goal is not maximum output. It is a faster, more observable path from a real audience need to accurate, useful, discoverable content.

    Decide what AI can own before choosing a tool

    The commercial appeal is easy to understand. Automation layers are being positioned to audit, analyze, and optimize content at scale, reducing the manual work wrapped around each asset. Treat that as a capability to validate against your own content, not as proof that every editorial decision should be automated.

    The useful dividing line is not creative work versus administrative work. It is controlled work versus judgment-heavy work. Before assigning a task to AI, ask whether you can name the correct inputs, express an acceptable output as observable conditions, detect a bad result before it causes damage, and reverse the action cleanly.

    Use those questions to place work into three operating lanes:

    • Execute automatically: low-risk tasks with explicit rules, such as applying an approved classification, checking whether required fields are present, comparing a page against a defined checklist, or routing a completed record to its next owner.
    • Recommend for review: tasks where AI can narrow the work but should not make the final call, such as identifying possible content gaps, grouping overlapping URLs, proposing internal links, drafting a brief, suggesting a passage-level revision, or flagging claims that may need evidence.
    • Reserve for accountable owners: decisions involving business priority, original positioning, disputed evidence, sensitive claims, final approval, publication, consolidation, deletion, redirects, or canonical changes.

    This classification prevents a common operating mistake: treating every AI-assisted task as if it has the same risk. A missing topic label and an unsupported product claim should not share an approval path. Neither should a metadata suggestion and a page retirement.

    Automation should also have a no-action outcome. If the available evidence is incomplete, the instructions conflict, or the requested change falls outside the approved scope, the correct result is an exception record. Forcing the model to produce an answer turns uncertainty into hidden editorial debt.

    Give every task a durable content record

    A transparent modular case holds source documents, evidence cards, approvals, version layers, and a finished content page, with a hand adding a verified source card.

    A prompt is not an operating system. It describes what you want at a moment in time, but it does not reliably preserve why the work exists, which evidence is allowed, who owns the decision, what changed, or what should happen next.

    Build the workflow around a durable record for each content asset. That record can live in your CMS, project system, database, or orchestration platform, but it should expose the same core fields wherever the work runs:

    • Identity: asset ID, current URL or planned destination, content type, market, language, and related assets.
    • Purpose: intended audience, primary question or task, search intent, business purpose, and the action the page should help the reader take.
    • Evidence: approved references, source owner, claim-level notes, known uncertainties, and material that must not be used.
    • Ownership: content owner, subject reviewer, SEO owner, technical owner, and final approver where those roles apply.
    • State: lifecycle status, current workflow stage, blocking reason, next action, and the person or system responsible for that action.
    • Constraints: brand rules, regulatory or legal review requirements, format limits, localization needs, and protected language that must remain unchanged.
    • Change history: requested change, accepted change, rejected recommendation, approval record, publication event, and rollback information.
    • Measurement: target query set, baseline observations, relevant search and business outcomes, and the condition that should trigger another review.

    Without this record, each model run reconstructs context from whatever happens to be in its prompt. That creates inconsistent decisions and makes failures difficult to diagnose. With it, you can tell whether the problem came from missing evidence, an unclear instruction, an invalid output, a routing failure, or a human decision.

    Turn prompts into task contracts

    Once the content record exists, write a task contract for each automated step. A usable contract names the input fields, allowed context, requested operation, prohibited actions, required output fields, validation rules, no-change condition, and next route.

    For an audit task, do not ask the model to improve a page. Ask it to return an issue type, the affected passage or page element, the reason it failed a named rule, the evidence needed to resolve it, a proposed action, and a routing status. If approved evidence is missing, require an evidence-needed status and prohibit a factual rewrite.

    For an optimization task, define what optimization means. It might mean answering the primary question more directly, clarifying an entity, removing duplication, repairing a claim-source mismatch, aligning structured data with visible content, or improving an internal link path. If those outcomes are not named, the model is likely to equate optimization with rewriting, which creates unnecessary review work.

    Run a closed loop from audit to refresh

    A useful content workflow does not end when a draft appears. It carries an asset from detection through prioritization, evidence, revision, verification, publication, observation, and the next decision. You can use the following sequence as a practical starting point.

    1. Normalize the inventory. Give each asset a stable identity and map obvious relationships between canonical pages, localized versions, campaign variants, supporting pages, and structured data. Do not let the same URL enter multiple queues without a visible dependency.
    2. Audit against a fixed issue taxonomy. Separate accuracy risk, unsupported claims, intent mismatch, answer gaps, duplication, structural problems, internal link gaps, metadata defects, schema inconsistencies, and stale evidence. A fixed taxonomy makes findings routable and measurable.
    3. Triage before generating. Place work into operational buckets such as protect, improve, expand, consolidate, or retire. A valuable page with a material accuracy issue should not wait behind a speculative expansion. A weak page should not receive a full rewrite until you decide whether another asset should own the topic.
    4. Create an evidence-bound brief. State the audience problem, primary question, required subquestions, approved claims, named entities, allowed references, desired reader action, search role, and boundaries. Record unresolved questions instead of allowing the draft to conceal them.
    5. Make the smallest sufficient change. If a passage, heading, citation, internal link, or schema property can resolve the problem, do that before commissioning a full rewrite. Smaller changes are easier to verify, approve, attribute, and reverse.
    6. Verify the output against the brief and the original defect. Check whether the named problem was actually fixed, whether protected meaning changed, whether every material claim remains supported, and whether the revision introduced new duplication or ambiguity.
    7. Publish with a decision log. Store what changed, why it changed, who approved it, which workflow produced it, and how to reverse it. Update connected assets when the change affects internal links, canonical relationships, metadata, or structured data.
    8. Observe and route again. Compare the result with the intended search and business outcome. Keep it, revise it, escalate it, or return it to monitoring. The workflow is complete only when the next state is explicit.

    This closed loop matters for AI search as much as traditional search. A page needs a clear answer, unambiguous entities, support for consequential claims, descriptive structure, and visible content that agrees with its metadata and JSON-LD. Structured data cannot repair a vague answer, and a polished answer cannot make unsupported schema accurate.

    Keep content and schema in the same change set when one describes the other. If a workflow updates a product attribute, author identity, FAQ answer, date, organization detail, or other structured fact, route the visible page and its markup through the same verification gate. Otherwise, your automation can create two competing versions of the page.

    Put executable gates between generation and publishing

    Content page artifacts move through evidence, structure, policy, and human-review gates, while a failed item loops back for correction before publishing.

    A quality gate needs observable pass conditions. Instructions such as make it authoritative, improve the SEO, or ensure it is high quality are editorial ambitions, not tests. Replace them with checks that produce a pass, fail, or exception and identify who owns the next decision.

    GateMachine-checkable conditionHuman decisionFailure route
    IntakeRequired identity, purpose, owner, state, and constraint fields are present.The request belongs in this workflow and is worth doing.Return to the requester with the missing field or scope conflict.
    EvidenceMaterial claims map to approved evidence, and unknown or conflicting claims are flagged.The evidence supports the intended meaning and is appropriate for the audience.Send missing evidence to its owner; send conflicts to the subject reviewer.
    AnswerThe primary question has an identifiable answer passage, required subquestions are covered, and the requested action is present.The answer is accurate, useful, appropriately qualified, and not merely keyword-aligned.Return the named gap to revision without reopening unrelated sections.
    Search and AI readinessHeadings describe their sections, entities use consistent names, important references are linked, and structured data agrees with visible content.The page deserves to represent the organization in search results and generated answers.Route content defects to editorial and markup defects to the technical owner.
    PublicationRequired approvals, destination, metadata, internal links, change log, and rollback information are present.The residual risk is acceptable and the release timing makes sense.Block publication and assign the unresolved condition to an accountable owner.

    Treat model confidence as routing metadata, not evidence. A confident output can still rely on the wrong context, miss a qualification, or satisfy the requested format while failing the reader. Evidence, deterministic validation, and accountable review are separate controls.

    Your exception queue is part of the product, not a bin for failed automation. Every exception should carry the asset, failed rule, blocking reason, evidence captured, attempted action, next owner, and resolution status. Group the queue by reason so you can see whether the recurring problem is missing source material, vague briefs, conflicting policies, technical validation, or an overloaded reviewer.

    If you permit automatic publishing, confine it to transformations with approved inputs, mechanical validation, a recorded change, and a tested reversal path. Deletions, redirects, canonical changes, unsupported factual edits, and sensitive claims need accountable approval because a technically reversible change can still damage discoverability, trust, or compliance before anyone notices.

    Measure the operation, not the volume of output

    Draft count is easy to increase and easy to misread. It says nothing about whether the queue is moving, whether reviewers trust the output, whether published pages answer better questions, or whether AI is creating rework somewhere else.

    Build the dashboard around three layers:

    • Flow: queue age, active cycle time, blocked time by reason, handoffs, work returned to an earlier stage, and items waiting on each owner. These measures reveal where automation moved effort rather than removed it.
    • Quality: first-pass gate failures, unsupported-claim findings, post-publication corrections, exceptions by type, content-to-schema mismatches, and recommendations rejected by reviewers. Segment these by workflow, content type, and risk class.
    • Outcome: coverage of approved audience questions, search discovery for the intended queries, qualified actions after landing, citation or inclusion in relevant AI answers, and whether refreshed assets hold their intended role over time.

    Always pair a count with its denominator. A failure total is hard to interpret without the number of items reviewed. A fast cycle time can hide poor quality if corrections rise. A high acceptance rate can be meaningless if reviewers approve cosmetic edits while rejecting the consequential ones.

    AI-search observations also need a controlled record. Preserve the exact query, engine or model surface, market and language, account or personalization state where relevant, observation time, returned answer, cited pages, brand inclusion, and landing destination. Compare like with like. Otherwise, normal variation in the testing context can be mistaken for a content result.

    Use the measurements to change the workflow itself. Repeated evidence failures mean the intake or source library needs work. Repeated brand corrections point to an incomplete constraint set. Long blocked time identifies an ownership problem. High rework on full-page drafts is a reason to narrow the unit of change. The dashboard should tell you what to redesign, not merely what happened.

    Key takeaways

    • Automate a task only when its inputs, pass conditions, failure detection, and reversal path are explicit.
    • Keep purpose, evidence, ownership, lifecycle state, constraints, changes, and measurements in a durable content record.
    • Require every AI task to support no-change and exception outcomes instead of forcing a draft.
    • Use the smallest sufficient edit, then verify it against the original defect and the approved evidence.
    • Gate visible content, metadata, internal links, and JSON-LD as one connected publishing system.
    • Measure flow, quality, and reader or search outcomes together so faster production cannot hide greater rework.

    Start with the narrowest recurring queue that currently consumes useful editorial time: a stale-page audit, an evidence-backed refresh, an internal-link review, or a content-to-schema consistency check. Define its record, task contract, gates, exception routes, and measurements before widening the scope. When that workflow can move predictably without hiding uncertainty, you have a foundation worth scaling.

    References

  • How to Humanize LLM-Assisted Content With Better Research

    How to Humanize LLM-Assisted Content With Better Research

    You have an LLM draft that is clean, complete, and strangely forgettable. Changing a few phrases, adding contractions, or asking the model to sound more human will not fix it. The draft feels generic because it has had no meaningful contact with the customers, experts, and market conditions it claims to understand.

    Humanizing LLM-assisted content is a research problem before it is a writing problem. Give the model grounded evidence to organize, keep human judgment in charge of what matters, and make every important claim traceable. You will get content that is more useful because it contains real distinctions, not because it performs a more casual personality.

    Human content starts with evidence, not tone

    A model can imitate a conversational register. It cannot create genuine customer evidence, expert experience, or market context that you did not provide. If the input consists of a keyword, a title, and competing search results, the output will usually recombine the same category-level ideas available to everyone else.

    The useful advantage of an LLM is its ability to process large collections of feedback and surface recurring patterns. That makes it a capable research assistant, but it does not transfer editorial responsibility to the model.

    Separate the work into three roles:

    • Evidence: Customers, subject matter experts, product records, search queries, reviews, and other observable material supply the facts and language.
    • Analysis: The LLM groups related observations, identifies contrasts, proposes questions, and helps you inspect a large body of material.
    • Judgment: A person decides which patterns are meaningful, which claims are sufficiently supported, what exceptions matter, and what the reader should do.

    This separation prevents a common failure: letting polished prose disguise a weak evidence base. A confident paragraph is not proof that the underlying pattern is real.

    Before drafting, build a compact evidence brief. For each potential section, record the reader question, the proposed answer, the supporting material, any contradiction, and the action the reader can take. If a proposed answer has no supporting material, label it as a gap. Do not ask the model to fill that gap with a plausible anecdote.

    Keep provenance attached to the material as it moves through the workflow. A customer comment should retain an anonymous record identifier. An expert claim should point back to the approved interview transcript. A competitor observation should retain the page, review, or posting that supports it. Provenance makes verification possible after the model has compressed many inputs into a neat theme.

    Build an auditable customer-language pipeline

    Two researchers trace color-coded evidence cards back to customer interview recordings, photographs, and product samples on an organized table.

    Customer feedback is where generic content often becomes specific. NPS responses, sales-call transcripts, support questions, Google Search Console queries, and on-site searches expose the words people use before your marketing language has shaped the conversation. Heatmaps and interaction data can help you locate friction, while qualitative comments can explain what the friction means to the person encountering it.

    Do not begin by dropping an unstructured archive into a chat and requesting insights. The resulting summary may look convincing, but it gives you little visibility into omitted records, faulty groupings, or unsupported counts. A more inspectable workflow involves using an LLM to generate SQL, running the queries separately, and supplying the query results for synthesis.

    1. Normalize the raw material. Store one response or interaction per record. Preserve the original wording and add only fields you can verify, such as channel, product area, or an anonymous record identifier.
    2. Define the question before querying. Ask something narrow enough to test, such as which objections appear in feedback about a specific feature, or which questions occur before a purchase decision.
    3. Use the LLM to draft the query. Supply the actual table and column names, describe the expected output, and instruct it not to invent fields. Treat the generated SQL as code that requires review.
    4. Run and validate the query outside the model. Inspect filters, joins, null handling, duplicated records, and representative rows. Compare the result with a small set you have already read.
    5. Give the verified result to the LLM. Ask it to group related responses, preserve contrary evidence, and attach anonymous record identifiers to every proposed theme.
    6. Iterate on the question. A broad theme such as ease of use is not yet an insight. Query the situations, tasks, and points of confusion hidden inside that label.

    A practical analysis prompt is: Group these verified records by the job the customer is trying to complete. For each theme, provide supporting record identifiers, conflicting records, the customer terms that recur, and one question we still cannot answer. Do not infer a motive unless the wording supports it.

    The instruction to preserve conflicting records matters. A model is naturally useful at compression, but compression can erase minority experiences and conditions that complicate the dominant theme. Those complications are often what make a page trustworthy. They let you say when advice works, when it does not, and who should choose a different path.

    Handle sensitive material before it reaches any LLM. Remove personal identifiers and confidential details, and use only tools and storage environments approved for the data involved. If you cannot confirm that a dataset may be processed in a particular system, work with a redacted extract or keep the analysis inside an approved environment.

    Your final customer-language output should not be a cloud of themes. Build a theme ledger containing the customer problem, the situation in which it occurs, the language customers use, supporting record identifiers, contradictions, and the content decision that follows. That final field forces analysis to become useful editorial direction.

    Interview experts without asking them to write the page

    A content strategist records an expert explaining and demonstrating a component at a workshop bench while a teammate documents the process.

    Subject matter experts are usually needed because the obvious answer is incomplete. They know the mechanism, the exception, the tradeoff, and the mistake that only becomes visible in practice. Asking them to write a polished explanation creates unnecessary work and often delays the content.

    Use an LLM as the interviewer, not as a substitute for the expert. A reusable interviewer can be configured around a clear role, context, interview structure, pacing, and closing summary. The expert can answer in fragments or plain language while the system handles follow-up questions and organization.

    Give the interviewer these instructions:

    • Role: Act as a curious editor who understands the product context but does not pretend to know the expert’s answer.
    • Objective: State what the final content must help the reader understand or decide.
    • Scope: Name the product, feature, service, or decision being discussed and list topics that are out of scope.
    • Pacing: Ask one question at a time. Follow an answer before moving to the next prepared topic.
    • Evidence discipline: Request concrete mechanisms, conditions, and examples, but never create an example on the expert’s behalf.
    • Closing: Summarize the claims, unresolved questions, and statements that require verification or approval.

    Do not open with an invitation to explain everything about the subject. Start with the decision the reader faces, then move down an interview ladder:

    1. What does the reader usually misunderstand at this point?
    2. What actually happens, and what causes it?
    3. Which conditions change the answer?
    4. What is the most common avoidable mistake?
    5. What tradeoff should the reader understand before choosing?
    6. What would you need to see before recommending a different approach?

    Each answer should shape the next question. If the expert says a result depends on implementation quality, the interviewer should ask what quality means in observable terms. If the expert describes a common mistake, it should ask why people make it and how a reader can notice it early. This is where an interview produces material that a generic drafting prompt cannot.

    After the interview, ask the LLM to create a claim sheet rather than a finished draft. Each row or bullet should include the claim, supporting transcript passage, relevant condition, uncertainty, and verification status. Send that condensed sheet to the expert for correction. Approval of a short claim sheet is a clearer request than approval of a long page in which factual and stylistic decisions have already been mixed together.

    Only then should the transcript feed the drafting process. Instruct the model to distinguish direct expert knowledge from editorial inference. If the expert did not provide a metric, example, or causal explanation, the draft must not manufacture one to make the section feel complete.

    Use competitor research to find the missing angle

    Competitor research is useful when it reveals the boundaries of the category conversation. It becomes destructive when it is used as a template for another version of the same page.

    Different public signals answer different questions. Reviews, changing web copy, job postings, and social engagement can expose customer frustrations, positioning choices, strategic priorities, and unmet demand. None of these signals should be treated as conclusive on its own.

    • Reviews: Extract repeated benefits, complaints, desired outcomes, and the circumstances behind unusually positive or negative experiences. Keep verified wording separate from your interpretation.
    • Current web copy: Record the audience being addressed, the promised outcome, the proof offered, and the tradeoffs left unmentioned.
    • Archived web copy: Use the Wayback Machine to notice how positioning and emphasis have changed. Treat the change as an observation, not proof of why the business made it.
    • Job postings: Note capabilities the company appears to be building. A posting may indicate an area of attention, but it does not prove that a strategy or product has shipped.
    • Social engagement: Read the comments and questions behind the engagement count. Activity alone does not tell you whether people are satisfied, confused, or objecting.

    Create a competitor evidence matrix with the same fields for every company: target audience, main claim, supporting proof, repeated customer concern, unanswered question, and evidence location. Consistent fields make cross-company patterns easier to inspect and reduce the chance that a vivid example dominates the analysis.

    Then ask the LLM: Compare these records without ranking the companies. Separate extracted evidence from inference. Identify claims repeated across the category, customer questions no company answers clearly, benefits with weak visible proof, and differences that may reflect distinct target audiences. Mark unknowns instead of resolving them.

    The output is not your content plan yet. Test each proposed gap against customer feedback and expert knowledge. A topic is not valuable merely because competitors have ignored it. It becomes a defensible angle when customers care about it, an expert can explain it, and your evidence supports an answer.

    Look for four kinds of useful angles: a customer question the category avoids, a tradeoff hidden behind a popular benefit, an exception that changes the standard recommendation, or a difference in audience that makes apparently conflicting advice both reasonable. These angles humanize content because they reflect actual decisions and tensions. They do not depend on decorative storytelling.

    Draft, verify, and edit for a recognizable point of view

    Once the evidence is organized, drafting becomes a constrained synthesis task. The model should transform approved material into a useful sequence without silently upgrading an observation into a fact or an inference into a customer quote.

    1. Define one reader and one decision. State what the reader is trying to do, what is blocking them, and what they should be able to decide after reading.
    2. Build an evidence outline. Give each section a question, direct answer, evidence identifiers, important exception, and practical next action.
    3. Draft only from the evidence pack. Permit ordinary transitions and explanation, but prohibit invented customers, quotations, tests, metrics, and firsthand experience.
    4. Expose missing support. Require a visible placeholder whenever the outline asks for a claim the supplied material cannot establish.
    5. Verify before polishing. Check every material claim against the raw record, transcript, query result, or competitor evidence location.
    6. Edit for judgment. Decide which point deserves emphasis, which caveat belongs beside the claim, and which recommendation follows from the evidence.

    An evidence-bound drafting prompt can be simple: Write for the defined reader using only the supplied evidence pack. Each section must answer its question directly, explain the mechanism or reason, preserve the stated conditions, and end with an action the reader can take. Keep evidence identifiers in the draft for review. If support is missing, insert [EVIDENCE GAP]. Do not invent a quote, metric, customer, test, or example.

    Run a humanization pass that can fail the draft

    Do not judge the result by asking whether it sounds human. Use tests with observable failure conditions:

    • The substitution test: Could a competitor publish the section unchanged? If so, add a supported distinction or remove the generic section.
    • The provenance test: Can an editor reach the underlying evidence for every consequential claim? If not, qualify, verify, or delete the claim.
    • The contradiction test: Does the draft preserve evidence that complicates the dominant pattern? If not, restore the relevant condition or exception.
    • The customer-language test: Does the page use the terms customers use for their problem while explaining any necessary technical vocabulary? If not, return to the feedback records.
    • The expert-value test: Does the page contain a mechanism, tradeoff, or boundary condition that required genuine expertise? If not, the interview stayed too shallow.
    • The action test: After each section, can the reader do, decide, or notice something specific? If not, the section is probably commentary rather than guidance.

    Remove evidence identifiers only after verification. Then tighten repetition, vary sentence length where it improves clarity, and replace internal terminology with reader language. Do not add fake quirks, staged vulnerability, or imaginary personal stories. A recognizable editorial voice comes from consistent judgment: what you prioritize, what you refuse to overclaim, and how clearly you explain the tradeoff.

    This also supports SEO, AEO, and GEO work without turning the page into machine-facing copy. Put the direct answer near the question, use descriptive headings, name entities precisely, keep qualifications beside the claims they limit, and cite the evidence that carries the factual load. Structured data can describe visible content, but it cannot supply the missing expertise or originality. No formatting choice guarantees search or LLM visibility.

    Key takeaways

    • Humanize the evidence before polishing the prose: use real customer language, expert judgment, and observable market signals.
    • Keep raw data and query execution outside the LLM when you need inspectable counts, filters, and records.
    • Use an LLM to interview experts and organize their answers, never to impersonate their knowledge.
    • Treat competitor material as evidence of category patterns and unanswered questions, not as a draft template.
    • Require provenance, contradictions, conditions, and evidence-gap labels throughout synthesis.
    • Reject any section that a competitor could publish unchanged or that leaves the reader without a concrete next action.

    Take the next generic draft you planned to polish and pause it. Build an evidence brief for its most important claim, verify that material, and rewrite only that section. The difference will show you where research deserves more of the workflow than prompting does.

    References

  • AI Marketing Operations: Move Faster Without Losing Brand Control

    AI Marketing Operations: Move Faster Without Losing Brand Control

    Your team can now generate campaign concepts, creative variants, audience-specific copy and performance summaries faster than a traditional request can move between departments. That speed is useful, but it also exposes every weak approval rule, scattered brand document and unreliable data handoff in your operation.

    The answer is not another collection of AI tools. You need an operating system that tells AI what it may do, gives it reliable brand context, checks the consequences and feeds results back into the next decision. Build that system well and you can move faster without turning brand management into a permanent cleanup exercise.

    Give AI a clear operating envelope

    AI-enabled marketing operations should begin with a workflow, not a product. AI can support personalization, predictive insight, content production, customer experience and digital presence, but those capabilities do not tell you where automation belongs in your business.

    Choose a recurring marketing job and map how it works before adding AI. If nobody can explain where the input comes from, who owns the decision or what happens when the output is wrong, automation will only make the ambiguity run faster.

    Map the complete decision path

    Document the workflow in operational terms:

    1. Trigger: Define the event that starts the work, such as a new lead, an approved campaign concept, a reporting deadline or a change in performance.
    2. Inputs: Identify the customer data, campaign data, approved claims, brand rules and channel constraints needed to make the decision.
    3. Transformation: State exactly what AI should classify, generate, summarize, predict or recommend.
    4. Decision: Name the person or rule that determines whether the output proceeds, returns for revision or stops.
    5. Action: Specify which system may be changed, which audience may receive the output and which permissions are required.
    6. Evidence: Record what was produced, what was approved, what changed and what business or brand outcome followed.

    This map separates useful automation from vague ambition. Generate variants is not a workflow. Generate channel-specific variants from an approved concept, verify every claim, send them to a named reviewer and retain the final edits is a workflow.

    Grant autonomy according to consequence

    A positionless marketing model can bring data, creativity and optimization into the same working loop. It does not mean every marketer should receive unrestricted access to customer records, publishing systems or campaign budgets. Faster execution still needs explicit decision rights.

    • Draft: AI creates an internal brief, summary or variation. Nothing reaches a customer or changes a live system.
    • Recommend: AI proposes a segment, route, response or optimization. A named person accepts or rejects it.
    • Execute within rules: The workflow performs a reversible action inside approved conditions, such as normalizing a tracking value or sending an exception into the correct queue.
    • Escalate: The workflow stops when data is missing, a claim lacks support, a request falls outside policy or an action could create material cost, legal exposure or reputational damage.

    Attach an owner to every level. The owner is accountable for the live workflow even if a vendor model, automation platform or specialist built part of it. AI can propose a budget change, for example, but it should not receive permission to spend beyond an approved rule merely because its recommendation sounds confident. Keep consequential actions behind human approval until you have reliable evidence that the narrower automation behaves as intended.

    This approach removes unnecessary handoffs while preserving specialist judgment. A marketer may be able to retrieve data, create assets and orchestrate a journey independently, while security, legal, analytics and brand specialists still define the boundaries that protect the business.

    Turn brand standards into system inputs

    Color swatches, textures and image samples pass through modular sorting chambers and emerge as a consistent family of campaign designs.

    A conventional brand guide is usually written for a person who can interpret context. An AI workflow needs more explicit instructions. Telling a model to sound clear, premium or human leaves too much room for interpretation, especially when different teams use different prompts and different versions of the brand rules.

    Create a machine-usable brand control pack. It should be short enough to retrieve for each task, structured enough to validate and owned by someone who can resolve conflicts.

    • Brand identity: Approved name, description, product names, product relationships and the URLs that represent the business.
    • Audience definitions: Who each message is for, what that person is trying to accomplish and which assumptions the copy must not make.
    • Message hierarchy: The primary promise, supporting themes and the distinction between an approved message and a claim that requires evidence.
    • Claim ledger: Approved wording, supporting evidence, permitted channels, restrictions, owner and review status. If a claim is absent or out of date, the workflow should flag it instead of improvising.
    • Voice rules: Concrete instructions for sentence length, terminology, point of view, tone and calls to action, supported by accepted and rejected examples.
    • Visual rules: Approved assets, treatments, layouts, accessibility requirements and prohibited combinations.
    • Channel constraints: What may change across ads, social posts, landing pages, email, search content and AI-facing brand descriptions.
    • Escalation rules: Topics, audiences, claims or actions that always require review by brand, legal, compliance, security or another accountable specialist.

    Do not hide this information in one large prompt that nobody owns. Store the control pack as versioned, reusable components. A creative workflow may need voice, visual and claim rules. A reporting workflow may need metric definitions and approved interpretations instead. Supplying only the relevant context makes conflicts easier to detect and revisions easier to govern.

    Record the version used for every externally visible output. When brand guidance changes, you can then identify which campaigns used the old rule and decide whether they require correction. Without that record, a policy update changes future prompts but leaves you unable to trace earlier decisions.

    Test the rules with adversarial examples

    Before connecting the workflow to a live channel, give it difficult examples from the work it will actually encounter:

    • A request that contains an unsupported performance claim.
    • A source asset that uses an obsolete product name.
    • Two brand instructions that point toward different tones.
    • An audience request that would require unavailable personal data.
    • A prompt asking the model to ignore the review process.
    • An input with missing campaign, market or channel context.

    The correct result is not always polished copy. Sometimes it is a refusal, a clarification request or an exception ticket. Treat those outcomes as signs that the control system is working.

    Build workflows around failure-safe boundaries

    Abstract campaign assets move through automated checks, a human review bay and a quarantine chamber in a branching workflow system.

    The best first workflow is frequent, bounded and reversible. Practical candidates already include lead enrichment and routing, UTM normalization, performance reporting and creative variation. Each has a visible input and output, but each needs a different automation boundary.

    WorkflowSafe starting boundaryMandatory checkUseful signal
    Creative variationGenerate variants only from an approved concept, asset set and claim ledger.Review factual accuracy, brand voice, visual treatment and channel suitability before publication.Approval without revision, reasons for rejection and performance by approved variation.
    Lead enrichment and routingRecommend or perform routing inside documented segments; send uncertain records to an exception queue.Check data permission, route quality, duplicate handling and whether the receiving team can act on the record.Reroutes, unresolved exceptions and downstream lead quality.
    UTM normalizationApply deterministic mappings to known values; quarantine unknown or conflicting values.Confirm that raw parameters are preserved and that normalized values match the analytics taxonomy.Invalid values, quarantined records and attribution completeness.
    Performance reportingRetrieve and structure platform metrics, then draft a summary without changing campaigns.Reconcile the underlying data and separate observed changes from AI-generated explanations.Data discrepancies, corrected interpretations and decisions produced by the report.
    AI search visibility monitoringTrack a stable set of relevant questions, audiences and competitors before recommending content changes.Inspect the underlying answers and distinguish a missing mention from an inaccurate or unfavorable brand narrative.Relevant mentions, description consistency, competitor gaps and recurring factual errors.

    Place human review where an error becomes consequential

    A generic human-in-the-loop requirement is too vague to govern anything. Name the reviewer, the exact evidence they see and the decision they are expected to make. A brand reviewer should not be asked to verify data extraction they cannot inspect. An analyst should not become the final authority on a legal claim simply because the claim appeared in a report.

    Separate the checks so failures have an owner:

    • Input validity: Are required fields present, current and permitted for this use?
    • Factual validity: Does every material claim trace to approved evidence?
    • Brand validity: Does the output use the correct identity, message, voice and visual rules?
    • Operational validity: Is the destination correct, is the action permitted and can it be reversed?
    • Measurement validity: Can the result be attributed to this workflow without confusing correlation with causation?

    Do not let the same AI output serve as both the work and its only approval. Automated checks can catch missing fields, prohibited terms, malformed links and taxonomy mismatches. A model can also highlight possible inconsistencies. Neither is a substitute for an accountable reviewer when an error could affect customers, public claims, regulated content or material spend.

    Design the failure path before the happy path

    Workflow automation often depends on APIs, JSON payloads, authentication and platform-specific integrations. That flexibility introduces real implementation and security work, and a misconfigured system can expose data or behave differently when an integration is incomplete.

    • Give each connector only the permissions required for its task.
    • Preserve the original input before normalizing or enriching it.
    • Prevent the same event from creating duplicate sends, records or campaign changes.
    • Route malformed, ambiguous and policy-breaking inputs into an exception queue.
    • Alert a named owner when a dependency fails or an error repeats.
    • Keep a readable log of the trigger, data version, brand-rule version, model or tool used, output, approval and final action.
    • Provide a kill switch and a documented rollback path before enabling live execution.

    These controls are not administrative decoration. They determine whether a problem remains one rejected draft or becomes a large batch of off-brand assets, incorrectly routed leads or corrupted attribution data.

    Measure the operation, not the volume of AI output

    Counting prompts, generated assets or automated tasks rewards activity. It does not show whether marketing improved. Your scorecard needs to connect operational speed with quality, business performance and brand representation.

    • Flow health: Track cycle time, queue time, failed runs, repeated attempts, manual interventions and unresolved exceptions.
    • Output quality: Track approval without revision, edit reasons, unsupported claims, data corrections and brand-rule violations.
    • Business outcome: Use the outcome the workflow is meant to affect, such as qualified demand, campaign efficiency, completed journeys or another metric your business already owns.
    • Brand outcome: Monitor whether approved identity, positioning and claims remain consistent across channels.
    • AI visibility: Examine whether relevant AI answers mention the brand accurately, represent its solution consistently and expose recurring competitor or messaging gaps.

    Specialized AI visibility platforms can provide persona-level, competitor-level and brand-narrative views. Treat those outputs as diagnostic evidence, not proof that one content change caused an AI model to respond differently. Keep the question set and evaluation method stable enough to distinguish a real pattern from ordinary answer variation.

    Capture a baseline before automation. When an A/B test is appropriate, define the primary outcome, guardrail metric, assignment method and stopping rule before launch. When controlled testing is not practical, compare like-for-like work and document other changes that could explain the result. A faster workflow that produces more corrections or weaker campaign outcomes is not an improvement.

    Buy tools for replaceability

    AI products and features change quickly, so avoid making the operating model depend on one vendor’s interface or a long commitment before the workflow is proven. Caution around long-term contracts is especially sensible while the toolset continues to evolve.

    Evaluate a tool against the system you need, not the most impressive demonstration:

    • Can you export prompts, templates, outputs, evaluations and logs in usable formats?
    • Can you replace the underlying model without rebuilding the entire workflow?
    • Does it support the authentication, access controls and data handling your systems require?
    • Can reviewers see the input, evidence and transformation behind an output?
    • Can failed actions retry safely without duplicating work?
    • Does it integrate with the systems that hold your actual campaign, customer and brand data?
    • How does cost change when usage moves from evaluation to routine production?
    • Can you disable it and return to a documented manual process?

    Use the same evaluation set when testing alternatives: representative inputs, edge cases, prohibited requests and previously rejected outputs. Score correctness, brand fit, required editing, operational reliability and total workflow cost. This makes a tool change an evidence-based decision rather than a reaction to a new feature announcement.

    Keep a shared workflow library and changelog as well. Record changes to prompts, brand rules, models, integrations, permissions and review steps. Regular knowledge-sharing matters because an improvement discovered by one campaign team should not remain trapped in that team’s private prompt history.

    Key takeaways

    • Start with a recurring workflow and define its trigger, inputs, decision owner, action and evidence before selecting an AI tool.
    • Grant AI more autonomy only when the action is bounded, reversible and covered by explicit escalation rules.
    • Convert brand guidance into versioned identity, audience, message, claim, voice, visual and channel controls that workflows can retrieve and validate.
    • Place named reviewers at the point where an error would affect a customer, public claim, regulated message, live system or material spend.
    • Measure cycle time and automation reliability alongside factual accuracy, brand consistency and the business outcome the workflow exists to improve.
    • Favor portable workflows, exportable records and reversible vendor commitments so the operation survives changes in models and tools.

    If your governance is still new, begin with a workflow whose mistakes are easy to detect and reverse, such as UTM normalization or a draft-only reporting summary. Define the baseline, brand context, exception path and owner, then run it on representative work before allowing a live action. The goal is not maximum autonomy. It is the smallest reliable loop that helps your team learn safely and earn the next level of autonomy.

    References

  • AI-Driven Paid Media Strategy: Budgets, Bids and Visibility

    AI-Driven Paid Media Strategy: Budgets, Bids and Visibility

    You’ve probably been handed a familiar contradiction: let the ad platforms automate more decisions, but remain accountable for every dollar they spend. The answer isn’t to micromanage every bid, and it isn’t to treat an automated campaign as self-driving.

    Your job is to design the system around the automation. That means concentrating the budget, assigning each campaign a clear role, measuring channels as a portfolio and checking whether AI-generated search results are changing the visibility you thought you had.

    Allocate the budget before you configure the campaigns

    Metallic budget tokens are divided among three transparent channels before reaching smaller campaign controls.

    AI can optimize toward a target, but it can’t decide which business constraint matters most. Before opening a platform, write a one-page constraint sheet that answers five questions:

    • What business outcome are you buying? Name the sale, qualified lead, subscription, store visit or other outcome that ultimately matters.
    • What economics must the outcome meet? Use the maximum acceptable acquisition cost, minimum return or other threshold your business has approved. Don’t substitute a platform metric merely because it is available.
    • How much spending is committed? Separate the budget you expect to deploy from money that is optional, experimental or contingent on performance.
    • When is demand likely to change? Mark peak buying periods, expected slumps, launches and deadlines. Historical performance and Google Trends can help shape the monthly curve because an annual budget rarely deserves twelve equal allocations.
    • Which campaigns can you actually support? A channel that needs a steady supply of approved video or social creative is not a realistic allocation if that production process is blocked.

    Then divide the available money by purpose, not by platform. A useful portfolio has three conceptual pools:

    • Core delivery funds campaigns with an established job and credible performance evidence.
    • Growth funds additional reach, audience building or expansion beyond the demand you already capture.
    • Exploration funds a specific, bounded test of a channel, format, audience or message.

    There is no defensible universal percentage for these pools. The correct split depends on budget size, demand, business maturity, creative capacity and confidence in your measurement. What does generalize is the need for concentration. Spreading a modest budget across too many campaigns limits the data each campaign can collect, leaving the platform with too little signal and you with too many inconclusive results.

    Fund the smallest coherent campaign structure first. Add another campaign only when you can state its distinct job, give it enough budget to perform that job and explain how you will judge it. A new campaign created merely to use an available targeting option is fragmentation, not strategy.

    When more money becomes available, look first for campaigns that are both efficient and budget-constrained. That is a better starting point than dividing the increase evenly. Still, don’t assume that historical efficiency will survive unlimited scale. Increase spending in stages and inspect the economics of the additional volume. A higher budget creates financial exposure; if you don’t know the acceptable marginal acquisition cost, don’t scale solely because the platform forecasts more conversions.

    Give every channel a job in the portfolio

    Four color-coded media modules perform different functions while connecting to a shared central objective.

    A channel-by-channel return table often rewards the campaign that collects the conversion and punishes the campaign that created the demand. That can produce a tidy report and a weaker media plan.

    Portfolio roleTypical campaign useReason to fund itEvidence to inspect
    Demand capturePaid search against relevant queriesReach people already expressing intentQuery quality, conversion economics, impression availability and budget constraints
    Demand creationYouTube or social prospectingBuild awareness and qualified audiences before the final searchReach, audience growth, later search behavior and change in portfolio-level efficiency
    Re-engagementViewer or visitor remarketingContinue the journey with people who have already encountered the brandIncremental outcomes, frequency and overlap with other campaigns
    ExplorationDemand Gen, a new social channel or an unproven formatTest a defined path to additional demandThe stated hypothesis, spend boundary, delivery quality and downstream business outcome

    These roles prevent two common mistakes. The first is expecting every campaign to close the sale directly. The second is excusing weak performance with a vague claim that a campaign is building awareness. A demand-creation campaign still needs a measurable theory of change.

    For example, a YouTube campaign may produce few attributed conversions while search conversion rates improve and video-viewer remarketing audiences perform well. That pattern can justify continued investigation because campaigns can affect the efficiency of other channels. It does not, by itself, prove that video caused the improvement. Seasonality, promotions, competitive changes or measurement differences may also be involved.

    Use three levels of evidence so you don’t confuse a plausible contribution with a demonstrated one:

    <!– wp:list {
  • AI Agent Analytics on Google Cloud: A Practical Setup Guide

    AI Agent Analytics on Google Cloud: A Practical Setup Guide

    If your content sits behind Google Cloud CDN, a rising bot count is not the answer you need. You need to know whether your measurement covers the pages that matter, which agents are reaching them, and what your team should do when the pattern changes.

    The practical goal is a trustworthy measurement chain from an agent request to a content decision. Build that chain carefully, and agent analytics can reveal coverage gaps, unusual behavior, and pages that deserve investigation. Build it loosely, and an incomplete log stream can send your SEO team in the wrong direction.

    Know what Google Cloud agent analytics can actually show

    Profound’s Agent Analytics connects with Google Cloud Platform through Cloud CDN to monitor how AI crawlers and agents interact with GCP-hosted content. That creates visibility at the content-delivery layer: an agent requests a resource, the measured delivery path observes the interaction, and the analytics system classifies and aggregates it.

    This is valuable evidence, but it has a strict boundary. An observed request does not prove that an AI system indexed the page, used its claims in an answer, cited your brand, or sent a visitor. Those are separate stages of the discovery journey.

    • Agent activity means a request associated with an AI crawler or agent reached the part of your delivery stack that you measure.
    • AI visibility means your content or brand appears in an AI-generated response for a relevant prompt.
    • Business impact means that visibility contributes to useful behavior such as a qualified visit, signup, inquiry, or sale.

    Keep those layers separate in your reporting. Agent analytics is strongest at the first layer. It can help you investigate the later layers, but it cannot establish them by itself.

    Coverage matters just as much as classification. Cloud CDN analytics can only describe requests that pass through the connected and measured path. A subdomain, application route, origin, regional setup, or content repository outside that path may be invisible. Before interpreting silence as a discovery problem, confirm that the page was observable in the first place.

    Design the measurement around decisions, not bot counts

    Start by writing down the decisions the data must support. This prevents an attractive activity chart from becoming a substitute for analysis.

    DecisionQuestion to answerAction the answer should trigger
    CoverageWhich priority content groups have observable agent activity?Investigate important groups with no activity, beginning with measurement and access checks.
    DistributionWhich agents, hostnames, and page groups account for the observed requests?Separate broad discovery from activity concentrated on a narrow or low-value part of the site.
    Change validationDid request patterns shift around a content, routing, or CDN change?Inspect the affected paths while treating timing as association, not automatic proof of cause.
    ReliabilityIs an apparent drop a content signal or a telemetry problem?Verify delivery coverage and ingestion before changing SEO strategy.

    You also need a page inventory outside the agent analytics platform. The inventory provides the denominator that request logs lack. Without it, you can count observed URLs but cannot tell whether the agents reached a meaningful share of the content you care about.

    • Group URLs by hostname and content type, such as product pages, documentation, editorial resources, comparison pages, and support content.
    • Assign each group a business role so that a request to an important decision page is not treated as equivalent to a request for a utility asset.
    • Record whether each group is expected to pass through the connected Cloud CDN path.
    • Mark recently published or materially revised groups so you can examine discovery patterns around real changes.
    • Preserve an unknown or unclassified automation category instead of forcing every suspicious request into a named AI-agent bucket.

    Do not begin with a universal target for how much agent traffic is good. A documentation library, ecommerce catalog, and corporate site have different content shapes and discovery patterns. Your useful reference point is your own verified baseline, segmented by agent and content group.

    Implement the Cloud CDN measurement path and validate it

    An isometric cloud CDN measurement path connects AI agent requests, edge servers, log events, and a validation checkpoint.

    The connector is only one part of the setup. The operational work is proving that the resulting data represents the delivery paths and URLs you think it represents.

    1. Map the request path. List the hostnames and content groups served through Cloud CDN, then identify routes that bypass it. Include alternate domains, localized sections, application routes, and other delivery paths that could make coverage partial.
    2. Connect the analytics integration with narrow access. Grant only the access needed for the relevant telemetry. Document the cloud identity, connected properties, responsible owner, and purpose so the setup can be audited later.
    3. Validate a matched sample. For requests classified as agents, compare the time, hostname, path, and available request details with the corresponding delivery evidence. Check time zones, query-string handling, path rewriting, and redirect behavior before comparing totals.
    4. Normalize URLs deliberately. Decide how to handle trailing slashes, query parameters, duplicate hostnames, localized variants, and canonical page groups. Do not merge parameters or routes when they produce meaningfully different content.
    5. Establish a clean baseline. Observe normal patterns before treating every movement as an SEO event. Keep agent identities and content groups separate so a change in one segment does not disappear inside a sitewide total.
    6. Assign an operating owner. Someone must maintain the URL taxonomy, review classification changes, investigate gaps, and record deployments that may explain shifts in the data.

    Run data-quality checks before every strategic interpretation

    • Coverage check: Confirm that the affected hostname and route still pass through the connected CDN configuration.
    • Ingestion check: Look for a broader loss or delay in incoming events before declaring that an agent stopped crawling.
    • Cache-awareness check: Do not use origin-only telemetry as your sole comparison. A request satisfied at the CDN edge may not reach the origin.
    • Classification check: Determine whether an agent label or identification rule changed. If classification relies partly on self-declared identity, spoofing and identity changes can distort the result.
    • URL check: Make sure redirects, rewrites, parameters, and canonical grouping have not split one page across several analytics rows or collapsed different resources into one.
    • Scope check: Separate a single-agent change from a sitewide change. They imply different investigations.

    Treat access telemetry as operational data. Use least-privilege permissions, keep access limited to people who need it, and align retention with your organization’s security and privacy requirements. Agent analysis does not require exposing more request data than the work actually uses.

    Turn agent activity into a disciplined investigation

    Two analysts examine clustered request signals and isolate an unusual path in a cloud operations workspace.

    Read the data as a diagnostic funnel. First ask whether the interaction could be measured. Then ask whether the agent could reach the content. Only after those checks should you investigate the content itself or connect the pattern to external visibility and business outcomes.

    • A priority page group has no observed activity: verify that the URLs are in your inventory, pass through the measured CDN path, and are accessible under your intended bot policy. If those checks pass, inspect discoverability, internal linking, content duplication, and whether the pages answer a distinct need.
    • Activity falls for a single agent: check that agent’s classification, identity behavior, and access path before making sitewide changes. Stable activity from other agents makes a universal delivery failure less likely, though it does not identify the cause by itself.
    • Activity falls across agents and content groups: investigate CDN routing, telemetry ingestion, access controls, and recent deployments before rewriting content. A broad drop is often a measurement or delivery question first.
    • Requests cluster on low-value pages: inspect why those pages are easier to discover than your primary resources. Compare navigation, internal links, URL consistency, duplication, and the clarity of each page’s purpose.
    • Activity rises after an update: record the association, then look for repetition across the affected content group. Do not call it an optimization win until independent outcome evidence also moves.
    • One page is requested repeatedly: do not assume it has greater authority. Repetition can reflect recrawling, volatility, a frequently changing resource, or inefficient access as well as genuine interest.

    A compact operating scorecard can include observed requests by classified agent, distinct requested URLs, the share of your priority inventory with any observed activity, distribution by content group, and the last observed interaction for important pages. Add delivery outcomes only when the connected telemetry actually exposes and defines them. Label every metric precisely so readers know whether they are seeing requests, URLs, pages, or external outcomes.

    Pair the scorecard with a change log for content releases, routing changes, access-policy updates, and analytics configuration changes. The log will not prove causation, but it gives your team specific hypotheses to test instead of encouraging a vague explanation for every spike or drop.

    Finally, connect agent activity to separate outcome evidence. Check whether the same content groups appear in relevant AI answers, earn citations or brand mentions, attract identifiable referrals, and support useful on-site actions. A crawler request is an upstream signal. It becomes strategically meaningful when you can trace it through the rest of the discovery and conversion path.

    Key takeaways

    • Google Cloud agent analytics is request-layer observability, not proof that an AI model used, cited, or recommended your content.
    • Map every hostname and content group to its Cloud CDN delivery path before interpreting missing activity.
    • Use a page inventory as the denominator; request logs alone cannot tell you how much priority content remains unseen.
    • Validate ingestion, classification, URL normalization, and cache behavior before making an SEO change.
    • Segment by agent and content group because a sitewide total can hide the pattern that explains the problem.
    • Connect crawler activity to independent visibility and business evidence before calling a movement a win or loss.

    Start with a domain whose content path you can map confidently. Define its priority page groups, verify that the Cloud CDN integration observes them, and document the first baseline. Once that measurement is trustworthy, expand the scope and let each new dashboard element answer a named decision rather than merely adding another count.

    References

  • Publisher Revenue in AI Search: A Practical Operating Model

    Publisher Revenue in AI Search: A Practical Operating Model

    If your revenue forecast begins with an organic search, a pageview, and an ad impression, an AI answer can break the chain before your ad stack has anything to monetize. The user may receive a useful answer and recognize your brand without visiting your site. That is how AI answers can disrupt publisher revenue and advertising even when the underlying demand for information remains strong.

    You do not need to abandon advertising or chase every new AI platform. You need a revenue model that separates visibility from visits, visits from audience relationships, and audience relationships from revenue. Once those stages are visible, you can decide which content deserves investment, which ad products still make sense, and where an owned or contracted revenue stream should replace pageview dependence.

    Key takeaways

    • An AI mention or citation is exposure, not revenue. Connect it to a measurable visit, signup, purchase, subscription, lead, or licensing agreement.
    • Classify content by the job it performs. A page built only to answer a simple query carries more exposure than a tool, dataset, community, newsletter, or decision resource that gives the user a reason to continue.
    • Keep programmatic advertising where its unit economics work, but build direct ad products around context, trusted access, and measurable actions rather than undifferentiated pageviews.
    • Use structured data and clear content architecture to make meaning explicit, but do not treat JSON-LD as a guarantee of rankings, citations, traffic, or revenue.
    • Test one adjacent revenue model at a time. Scale it only when incremental revenue exceeds the production, technology, sales, fulfillment, and revenue-share costs required to run it.

    The revenue break happens before an ad can load

    A conventional search-funded publishing model has four separate events: your work becomes visible, the user visits, the user develops a relationship with the publication, and someone pays. Pageview economics often compress those events into one number because a visit can immediately create ad inventory. AI interfaces force you to separate them again.

    Start by naming the four stages in your reporting:

    • Exposure: your brand, entity, claim, or URL appears in an AI-mediated discovery experience.
    • Visit: the user reaches a property you control, including a page, tool, newsletter archive, or registration flow.
    • Relationship: the user subscribes, registers, returns, saves something, follows an alert, or otherwise gives you a permission-based way to serve them again.
    • Revenue: an advertiser, reader, merchant, sponsor, licensee, event participant, or service customer pays.

    The distinction matters because movement at one stage does not prove movement at the next. A citation without a visit may help awareness but creates no on-site impression. An assistant referral may produce a highly engaged visitor but still fail to generate revenue. A newsletter signup can look less valuable than an ad click on the day it occurs while creating a durable audience relationship. Report each event for what it is.

    Create an AI-discovery segment in analytics, but do not pretend it captures every influence. Record identifiable assistant referrals, the landing page, the visitor’s next meaningful action, signup or registration completion, and any attributable revenue. Review changes in direct visits and branded demand as supporting context, not proof that an AI mention caused them. Unobservable exposure should remain labeled unobservable.

    Then classify your content inventory by economic job:

    • Answer content resolves a narrow question. It may earn visibility, but the answer can often be consumed without another step.
    • Decision content helps someone compare options, calculate a result, diagnose a business problem, or choose an action. Its value lies in the decision process, not merely the opening answer.
    • Relationship content gives a defined audience a reason to return, such as recurring analysis, an alert, a newsletter, or continuing coverage.
    • Proprietary assets provide something that cannot be reproduced from a short summary: original data, a maintained database, a tool, a workflow, a community, or access to expertise.

    Add three fields to every important content cohort: its job, its current revenue path, and the next action available to the user. A cohort with no purpose beyond attracting an easily satisfied query and displaying an ad is the first one to examine. Do not delete it reflexively. Decide whether it supports authority, feeds another journey, needs a stronger continuation, or no longer justifies its cost.

    Choose a revenue model by who pays and why

    A central publishing studio connects along separate paths to readers, business buyers, and marketers, who exchange access tokens, an archive case, and sponsored products.

    Revenue diversification is not a command to put subscriptions, affiliate links, events, and lead forms on every page. Each model has a different customer, value exchange, operating burden, and success metric. If you cannot state who pays and what that customer receives, you do not yet have a model.

    Revenue modelWho paysWhat they are buyingPrimary operating measurePageview dependence
    Programmatic advertisingAdvertisers through an ad marketplaceReach and an opportunity to display an impressionAd revenue per eligible session, alongside delivery and experience qualityHigh
    Direct sponsorshipA brand or agencyAccess to a defined context, audience, format, or programContracted revenue, delivery, and the agreed action or brand measureMedium
    Affiliate or commerceA merchant or affiliate networkA qualified referral connected to purchase intentOutbound actions, conversion, commission, returns, and net contributionMedium
    Membership or subscriptionThe reader or organizationContinuing utility, access, convenience, identity, or expertiseConversion, renewal, retention, and revenue per paying relationshipLower after acquisition
    Licensing or syndicationA platform, publisher, or business customerDefined rights to reuse content, data, or a maintained feedContracted revenue, permitted usage, cost to serve, and renewalLow, but customer concentration can matter
    Events, education, or servicesParticipants, sponsors, or business customersAccess, instruction, implementation, or professional expertiseRegistration or qualified demand, fulfillment cost, and net contributionLow to medium

    Use four filters before selecting a model. First, scarcity: what can you offer that a generic answer cannot? Second, intent: is the audience learning, deciding, buying, or operating? Third, relationship: can you reach the user again with permission? Fourth, measurability: can you connect delivery to a business event without making an attribution claim your data cannot support?

    Your best next model is usually adjacent to value you already create. A publication with trusted purchase analysis may have a credible commerce path. A specialist database may support licensing. Recurring operational insight may support membership or a professional newsletter. A large but weakly differentiated answer archive does not become subscription-worthy merely because a paywall is added.

    Calculate the economics before changing the product. For ad-supported content, divide ad revenue by sessions that were eligible to carry ads, then include serving and production costs. For an owned-audience offer, measure qualified visits, completed signups, the share that becomes paying relationships, retention, and the cost of fulfilling the promise. For a licensing deal, include maintenance, support, rights administration, and dependence on the buyer. Gross revenue alone can hide an expensive new obligation.

    Licensing also requires precision about ownership and permitted use. Define the material covered, usage rights, duration, territories where relevant, update obligations, attribution, payment terms, termination, and treatment of derived outputs. These terms create financial and legal exposure, so have qualified counsel review the contract rather than treating a crawler setting or informal email as a substitute.

    Rebuild advertising around context and measurable action

    A person researches a hands-on project beside a separate relevant product display, with illuminated markers leading to a selected item, an appointment bell, and an inquiry envelope.

    Advertising can remain part of the mix, but selling more undifferentiated impressions is a fragile response to fewer search visits. The stronger question is what advertisers can buy from you that they cannot get from a generic pool of inventory.

    Begin with context. Define audiences through the subject they are engaging with, the professional or consumer problem they are solving, and the stage of their decision. A cybersecurity operations newsletter, a home-buying calculator, and a general news page may all generate impressions, but they do not offer the same environment or signal of intent. Package them accordingly.

    Next, separate inventory from programs. Inventory is a placement. A program can combine a clearly labeled sponsorship with a newsletter, tool, event, research release, or topic hub. The advertiser is buying association with a relevant experience and agreed delivery, not editorial control. Direct programs demand sales and fulfillment work, so compare their net contribution with the simpler revenue they might replace.

    Give every campaign a measurement ladder before it launches:

    <!– wp:list {
  • How to Build an AI Marketing Tool Stack That Actually Works

    How to Build an AI Marketing Tool Stack That Actually Works

    If every campaign begins with hunting through tabs, copying context between tools, and checking which draft is current, your marketing stack is consuming the attention it was supposed to save. Another AI subscription will not fix a broken handoff.

    The fix is to design the stack around a repeatable workflow: where trustworthy information enters, what each tool changes, who approves the result, where the finished work goes, and how the outcome informs the next decision. Do that first, and choosing tools becomes much easier.

    Map the campaign before you choose the software

    Marketing software already spans content creation, conversion-rate optimization, design, analytics, and AI visibility. That breadth creates a predictable buying mistake: teams compare tools within each category before deciding how those categories need to work together.

    Start with a campaign your team performs often. Map the work from the event that starts it to the decision made after results arrive. Do not map an idealized process. Use the path a real brief, asset, landing page, email, or report currently follows.

    For every stage, complete a workflow card with these fields:

    • Trigger: the event that starts the work, such as an approved campaign objective, a product update, or a performance question.
    • Authoritative input: the facts, instructions, audience data, brand rules, and approved claims the stage is allowed to use.
    • Transformation: the specific job performed, such as turning a brief into draft copy or converting approved copy into channel variants.
    • Output: the artifact produced, including its required format, fields, status, and destination.
    • Approval: the person accountable for deciding whether the output can move forward.
    • Feedback: the evidence that should change the next brief, asset, audience choice, or optimization decision.

    This exercise exposes the real gaps. You may discover that several tools can generate copy while none carries an approved product claim into the prompt. You may find that design files lose their campaign identifiers before analytics can connect them to outcomes. You may also find that a report is produced regularly but never changes a decision.

    Mark every place where a person copies information, renames an artifact, changes a format, requests approval, or reconciles conflicting versions. Those seams are usually better automation candidates than the visible creative task. Generating another draft is less valuable if someone still has to determine which facts it used, paste it into another system, and rebuild its history by hand.

    Also separate assistance from authority. An AI tool can classify feedback, propose a campaign angle, rewrite copy, or summarize performance. It should not quietly become the source of truth for product facts, consent status, approved language, pricing, or campaign results. Keep those records in the systems that already own them, and pass only the required context into the AI layer.

    Give each layer a job, an owner, and a handoff

    Five connected campaign stations show team members handing work from research and creation through approval, publishing, and measurement.

    A useful stack is not a pile of applications. It is a chain of accountable artifacts. A tool may serve more than one layer, but two tools should not silently own competing versions of the same brief, asset, audience, or performance record.

    Stack layerJob it ownsRequired handoffWarning sign
    FoundationMaintains approved facts, audience definitions, brand rules, permissions, and campaign identifiers.Current, structured context with a named owner and status.People use an AI-generated summary as the authoritative record.
    Planning and researchTurns an objective and evidence into a brief, audience question, channel plan, or test hypothesis.An approved brief that states the goal, constraints, evidence, and decision to be made.The rationale disappears and only the generated idea survives.
    Content and designCreates draft copy, visual directions, variants, and production assets from the approved brief.Reviewable assets carrying the campaign identifier, source context, and approval status.Drafts multiply faster than reviewers can verify them.
    Conversion and deliveryAssembles the customer-facing experience and sends or publishes approved material.A published identifier, destination, audience or variant record, and rollback path.Publishing is automated before claims, links, targeting, and tracking are checked.
    AnalyticsConnects delivery records with observable behavior and business outcomes.Evidence tied back to the campaign, asset, audience, and decision.A dashboard reports activity without identifying what should change.
    AI visibilityObserves how the brand, products, and pages appear in relevant AI-generated answers.The tested question, exact answer, mention or citation, cited URL, and content change under review.A visibility score is reported without the prompts and answers behind it.

    The foundation layer deserves more attention than it usually gets. Generated work is only as dependable as the context supplied to it. If a prompt can pull an outdated claim, an unapproved positioning statement, and a current product description with equal confidence, better generation will only produce a more convincing inconsistency.

    Make the handoff itself a contract. Define the fields that must be present, the allowed source, the owner, the approval state, and the destination. A content handoff might require a campaign identifier, target question, approved factual claims, audience, call to action, destination URL, reviewer, and status. If an output lacks a required field, it is incomplete even when the writing looks polished.

    The AI visibility layer needs the same discipline. Build a stable set of questions that reflect how prospective buyers investigate the problem, compare approaches, and evaluate risk. For each check, preserve the question, the generated answer, whether the brand or page appeared, the exact cited URL when one is present, and whether the representation was accurate. A single answer is an observation. A controlled record gives you something you can compare after content, entity information, or internal linking changes.

    Your operating flow should now be legible in a single line: approved context becomes a brief; the brief becomes reviewable assets; approved assets become a published experience; delivery records become evidence; evidence and AI visibility observations become the next decision. Any tool that cannot participate in that flow needs an exceptional reason to remain in the stack.

    Put every candidate through a real task and a failure test

    Two marketers test an AI tool with normal campaign materials and problematic inputs while checking its outputs against source cards.

    Feature lists reward breadth. Your team benefits from fit. A tool that can perform many impressive tasks may still create more work if it requires special input formatting, hides its references, traps approved output, or cannot preserve the identifiers your workflow needs.

    Run the task trial

    Use a representative task from the workflow map, including the awkward parts. Vendor samples and pristine prompts remove the context conflicts, exceptions, and approval requirements that determine whether a tool survives normal use.

    1. Prepare a real input package. Include the approved brief, source material, brand constraints, required output format, and an intentionally irrelevant document. The candidate should use the right context and ignore the wrong context.
    2. Define acceptance before generating. State which facts must be preserved, what the output must contain, what it must avoid, who will review it, and where it needs to go next.
    3. Complete the task without hidden cleanup. Record every manual copy, format conversion, prompt repair, factual check, permission change, and upload required to reach an approved output.
    4. Force an exception. Remove a required field, introduce conflicting instructions, deny a permission, or supply an unsupported request. Check whether the tool stops clearly, requests clarification, or produces a plausible but unusable answer.
    5. Inspect the handoff. Export the output and confirm that its identifier, status, references, and revision context survive. A polished artifact with no reliable lineage is difficult to govern and measure.
    6. Test reversibility. Confirm that your team can correct, replace, unpublish, or roll back the result without reconstructing the workflow from memory.

    Apply non-negotiable buying gates

    Do not average a serious weakness into a high overall score. A candidate should be disqualified if it fails a requirement that protects data, approvals, measurement, or continuity. Use these questions as gates:

    • Workflow fit: Does it remove a defined bottleneck, or does it merely produce another version of an artifact you already have?
    • Context control: Can you specify which material is authoritative, restrict irrelevant context, and update stale information without rebuilding everything?
    • Traceability: Can reviewers determine which inputs, instructions, and revisions produced the output?
    • Output control: Can approved work leave the tool in the format your CMS, campaign platform, analytics process, or archive requires?
    • Access control: Can permissions separate viewing, generating, approving, publishing, spending, and administrative actions where your workflow requires that separation?
    • Integration fit: Does it work with the identifiers and systems you already use, or will the team maintain a fragile manual bridge?
    • Failure behavior: When context, permissions, integrations, or instructions fail, does the problem become visible before the output reaches a customer?
    • Economic fit: Which usage driver creates cost, and does that driver grow with valuable approved work or with drafts, retries, storage, and duplicated seats?
    • Exit readiness: Can you retrieve approved assets, history, configuration, and required metadata if the tool no longer fits?

    Once the non-negotiable candidates survive, compare the work removed from the complete process. Count review and correction as part of the task. A generator that produces drafts quickly but shifts substantial verification and formatting onto senior staff has not eliminated that work; it has moved it to a more expensive point in the workflow.

    Overlap should face the same test. If two tools generate similar outputs, decide which one owns the artifact, which one handles an explicitly different exception, and where the final version lives. If you cannot state those roles plainly, the overlap will eventually create duplicate spend, inconsistent instructions, or conflicting campaign records.

    Control automation, then measure the decisions it improves

    Limit write access until the workflow is proven

    Automation becomes materially riskier when it can publish, message customers, change targeting, alter advertising spend, or overwrite business records. A wrong draft is recoverable. A wrong draft sent to an audience, attached to live spend, or written over trusted data can create financial, reputational, and data-integrity damage.

    Evaluate new automation with read-only access or in a separate test environment where practical. Keep a person in the approval path for factual and legal claims, public publishing, audience-wide sends, budget or bid changes, and destructive record updates. Expand permissions only after the team has documented the normal path, exception path, owner, and rollback procedure.

    For every automated step, record:

    • the event that triggered it;
    • the authoritative inputs and campaign identifier;
    • the instruction or workflow version;
    • the output and destination;
    • the checks applied;
    • the approver when approval is required;
    • the exception raised, if any; and
    • the action needed to reverse or correct the result.

    This record is not bureaucracy for its own sake. It lets you distinguish a bad instruction from stale context, an integration failure from a model error, and an approved change from an unauthorized one. Without that distinction, the team can see that something went wrong but cannot correct the mechanism that caused it.

    Measure approved work, not raw generation

    Output volume is an easy metric and often the wrong one. More drafts can increase review queues, version conflicts, and publishing delays. Evaluate the stack at the point where work becomes usable and at the point where it informs a business decision.

    • Flow: Track elapsed time from the workflow trigger to approved output, not merely generation time.
    • Acceptance: Track how much generated work reaches approval without substantial factual, brand, or structural correction.
    • Rework: Record why work returns for revision. Repeated failures usually point to missing context, a weak handoff contract, or an unsuitable task.
    • Exception load: Track how often people must rescue, reroute, or reconstruct the process outside the intended workflow.
    • Unit economics: Include subscriptions, usage charges, integration upkeep, review, correction, and administration when comparing the cost of approved output.
    • Downstream outcome: Connect the approved artifact to the relevant campaign result before claiming that the stack improved marketing performance.
    • Decision value: Name the decision each report or visibility check changed. If it never changes a brief, budget, page, message, audience, or test, reconsider why it exists.

    Preserve campaign and asset identifiers through publication and measurement. That lineage lets analytics connect an outcome to the actual approved artifact instead of to a generic channel label. It also prevents a common attribution error: crediting an AI tool for a business result when the result may also reflect the offer, audience, distribution, timing, page experience, or human edits.

    Apply the same restraint to AI visibility. If a relevant answer begins mentioning or citing a page after you change it, record the sequence as a useful signal, not automatic proof of causation. Preserve the prompt, answer, cited page, content revision, and test conditions. The purpose of the visibility layer is to produce evidence your content and SEO teams can inspect, not a score that floats free of observable answers.

    At campaign close, review the tools alongside the workflow. Keep a tool when it owns a necessary job, passes its handoff cleanly, and improves a decision or an approved outcome. Reconfigure it when the problem is context or process. Remove it from the workflow when it duplicates an owner, creates persistent hidden work, blocks traceability, or produces information nobody uses.

    Key takeaways

    • Map a real campaign from trigger to decision before comparing AI tools.
    • Keep approved facts and business records in authoritative systems; use AI to transform controlled context rather than replace the source of truth.
    • Assign every layer a job, an artifact owner, a required handoff, and an exception path.
    • Trial candidates with representative inputs, explicit acceptance criteria, an induced failure, and an export test.
    • Keep publishing, customer messaging, spend changes, and destructive record updates behind appropriate approval and rollback controls.
    • Measure time to approved work, rework, exception load, complete cost, downstream outcomes, and the decisions changed.
    • For AI visibility, preserve the question, exact answer, mention or citation, cited URL, and related content change.

    Open your last completed campaign and list every handoff from approved context to measured outcome. Mark where information was copied, ownership became unclear, or a result failed to reach the next decision. Fix the most consequential seam before you add another subscription. That is where a tool stack begins to become an operating system for marketing rather than a collection of accounts.

    References

  • Marketing Is Becoming AI Systems Engineering: What to Build

    Marketing Is Becoming AI Systems Engineering: What to Build

    Your team can use AI to produce campaigns, briefs and content faster. That does not automatically make the operation faster. If reviewers cannot trace a claim, teams keep correcting the same errors, or nobody knows which instruction produced an output, the saved production time simply moves into review and repair.

    This is not mainly a prompting problem. It is a systems problem. As marketing moves toward engineering and AI-shaped roles, the practical advantage comes from designing reliable inputs, decision rules, interfaces, controls and feedback loops. You do not need to turn every marketer into a software engineer. You do need to make the marketing operation understandable enough to test, govern and improve.

    Production is no longer the only bottleneck

    A conventional campaign workflow is often organized around deliverables. A strategist writes a brief, a creator makes an asset, a reviewer approves it, an operator publishes it and an analyst reports on it. The handoffs may be inefficient, but each person can usually explain what they did.

    AI changes that structure. A model may summarize research, infer an audience, select supporting facts, generate variants, assign metadata and recommend distribution. What looks like a single content-generation step can contain several hidden decisions. When those decisions are not explicit, a fluent output can conceal a weak premise, an outdated input or an unsupported claim.

    The unit of management therefore has to change from the asset to the decision pipeline. For every AI-assisted workflow, you should be able to answer:

    • What business decision or customer action is this workflow meant to support?
    • Which information is allowed to influence the output?
    • Which decisions are fixed rules, and which are left to a model?
    • What must be true before the output can move to the next stage?
    • Who owns the result when several tools and teams contributed to it?
    • What signal will cause the system to stop, fall back or be revised?

    This distinction also prevents needless use of generative AI. A product name stored in an approved catalog should be retrieved exactly, not recreated from a prompt. A required JSON field should be validated by software, not judged by whether its formatting looks plausible. Generative models are useful where interpretation or variation is valuable. Deterministic rules are better where the correct result is already known.

    A quick diagnostic is to pick a live campaign and trace one customer-facing claim backward. If you cannot identify its approved origin, the transformation that produced it, the validation it passed and the person accountable for releasing it, you have found a system gap. Rewriting the prompt may hide that gap for a while, but it will not close it.

    Map the marketing operating system before buying more tools

    An isometric marketing workflow connects source materials, planning, AI creation, human review, distribution and feedback while isolated tool modules sit at the edge.

    Tool selection is easier after the workflow is visible. Start at the point where an objective is accepted, not where somebody opens an AI interface. End where performance evidence changes a later decision, not where an asset is published. That wider boundary exposes missing inputs, duplicated approvals and feedback that reaches a dashboard but never reaches the system.

    The layers every workflow needs

    LayerDecision to makeWorking artifactFailure signal
    IntentWhat outcome and audience are in scope?Workflow brief with acceptance criteriaOutput is polished but unrelated to the business decision
    KnowledgeWhich facts, policies and examples are approved?Source registry with owners and review conditionsClaims cannot be traced or conflict across outputs
    LogicWhich rules, model calls and exceptions transform the inputs?Decision map and versioned instructionsSimilar inputs follow inconsistent paths
    DeliveryWhere may the result be written, published or activated?Channel specification and permission policyContent reaches the wrong destination or bypasses review
    QualityWhat must pass before the next action?Evaluation cases, validators and approval policyReviewers repeatedly catch the same preventable defect
    FeedbackWhich outcome should change the next decision?Monitoring view and change logPerformance is reported but workflow behavior does not improve

    The knowledge layer deserves particular attention. A source of truth does not have to be one enormous document. It means that each important fact has an authoritative home, a responsible owner and a clear way to resolve conflicts. Product specifications may belong in a catalog, brand language in a controlled library and legal restrictions in an approval policy. Copying all of them into an unowned prompt creates another version that can drift.

    Next, mark each decision as deterministic, probabilistic or human. Eligibility rules, required fields, naming conventions and permission checks are usually candidates for deterministic handling. Drafting, clustering and interpreting ambiguous language may need probabilistic handling. Decisions involving strategic tradeoffs, sensitive claims or material consequences should retain accountable human judgment.

    Then make the interfaces explicit. An input contract should state which fields are required, what format they use, where their values come from and what happens when information is missing. An output contract should define the expected structure, permitted destinations, prohibited content and validation requirements. A JSON schema, a CMS field definition or a structured brief can all serve as a contract. The point is to make failure visible instead of allowing each stage to guess what the previous stage meant.

    Control AI with contracts, evaluations and observability

    A transparent AI workflow passes content through an input gate, sensor-filled inspection chamber and human-supervised release gate, with source trails and a repair loop.

    A prompt is configuration, not a complete control system. It can express the desired behavior, but it does not prove that the right input arrived, that the output is grounded, or that the next tool used the result safely. Reliable workflows place controls around the model rather than expecting the model to control itself.

    Test behavior before granting action

    Build an evaluation set from the situations the workflow must handle. Include routine requests, ambiguous instructions, missing fields, stale or conflicting information, prohibited claims and inputs that should trigger escalation. The expected result does not need to prescribe exact wording. It can define pass-or-fail conditions such as using an approved fact, preserving a required field, refusing an unsupported request or routing an exception to a reviewer.

    Evaluate separate qualities separately. Structural validity, factual grounding, audience relevance, brand compliance and channel suitability are different questions. A single quality score makes diagnosis difficult: the score can improve while a business-critical failure remains hidden. Record the failure category so the team knows whether to repair the knowledge, rule, prompt, integration or approval step.

    An AI-based evaluator can help triage outputs, but it is not independent proof. When similar model behavior produces and judges an answer, the same blind spot can affect both stages. Use deterministic validation wherever the requirement can be expressed as a rule, compare factual claims with approved information, and preserve human review for consequences that cannot be reduced to formatting checks.

    Log enough context to reconstruct a failure

    Useful observability lets you connect an outcome to the state of the system that produced it. For each run, retain the input reference, knowledge version, workflow or prompt version, model or service used, validation result, approval state and destination. Protect those records according to the sensitivity of the data they contain. A performance dashboard alone is not observability if it cannot show which system change preceded a failure.

    Define stop and fallback behavior before activation. If a required input is absent, the workflow can request it rather than inventing it. If a validator fails, the output can remain a draft. If a service is unavailable, the workflow can route work to a manual queue instead of silently skipping a control. Every automated action should also have a named owner who can pause it and a recovery path appropriate to the change it makes.

    Match autonomy to consequence:

    • For reversible internal suggestions, review samples and monitor recurring failure types.
    • For customer-facing content, require validation against approved facts and a clear publication policy.
    • For audience selection, material budget changes or actions that alter customer records, keep permissions narrow and require accountable approval before execution.
    • For workflows involving personal data, regulated claims, contractual promises or legal obligations, involve the appropriate privacy, legal, compliance or financial owner before activation. A technically valid output can still create exposure.
    • For destructive or difficult-to-reverse actions, use a staging environment, explicit confirmation and a tested rollback path rather than direct autonomous access.

    Do not expand a workflow’s permissions because a handful of outputs looked good. Expand them only after the system handles ordinary inputs, edge cases and failures in a way the responsible owner can inspect and accept.

    Redesign roles around system ownership, not prompt writing

    The engineering shift does not require renaming every marketer as a developer. It requires assigning responsibilities that campaign-oriented teams often leave implicit. A small team may combine several responsibilities in the same person, but each responsibility still needs an identifiable owner.

    • System owner: defines the workflow’s purpose, acceptable behavior, boundaries and business outcome. This person decides when the system should change or stop.
    • Knowledge owner: maintains approved facts, policies, examples and review conditions. This person resolves conflicts instead of allowing the model to choose between competing versions.
    • Workflow builder: connects tools, expresses rules, manages permissions and designs fallback behavior. This may be a marketing operations, automation or engineering responsibility.
    • Evaluator: creates test cases, classifies failures and checks whether changes improve the intended behavior without breaking another requirement.
    • Operator or analyst: monitors live performance, investigates anomalies and turns business feedback into proposed system changes.

    The handoff between these responsibilities matters more than the job titles. Before launch, everyone should know who can change an instruction, who can approve a new knowledge source, who reviews exceptions, who can grant write access and who can stop the workflow. If those answers live only in informal conversations, the operation will become harder to govern as automation spreads.

    Measure reliability as well as output

    Asset volume becomes less informative when generation is inexpensive. Track whether the system produces usable work and supports the intended business decision. Depending on the workflow, useful operating measures may include first-pass acceptance, rework by failure category, unsupported-claim incidents, manual intervention, recovery time and cost per approved result. Pair them with the actual marketing outcome; a technically stable pipeline that does not improve customer or business behavior is still the wrong system.

    This also changes career development. If you are an individual contributor, learn to map a process, write acceptance criteria, structure information, inspect a run log and design a useful edge case. If you manage or hire people, test whether they can diagnose a broken workflow. Give them a scenario with conflicting inputs, an invalid output and an unclear owner. Ask what they would inspect first, which control they would add and how they would know the repair worked. That reveals more than asking for a favorite prompt.

    Key takeaways and a safe place to start

    • AI-driven marketing systems engineering means designing the full decision pipeline, not merely adding generation to an existing task.
    • Use deterministic rules for known requirements and probabilistic models where interpretation or variation creates value.
    • Give every important fact an approved home and owner before placing it inside an automated workflow.
    • Define input and output contracts so missing data, invalid structure and prohibited actions fail visibly.
    • Evaluate edge cases, log system versions and set stop conditions before granting a workflow permission to act.
    • Assign ownership for the system, knowledge, implementation, evaluation and live operation even when one person holds several responsibilities.

    Begin with a workflow that is frequent enough to observe, bounded enough to map and reversible enough to recover. Drafting a brief from approved material or classifying incoming requests is easier to contain than a workflow that publishes claims, changes spend and updates customer data in the same run.

    1. Draw the current workflow from accepted objective to feedback, including manual copying, approvals and exception handling.
    2. Choose one recurring failure or delay. Do not redesign every stage at once.
    3. Name the approved inputs and their owners, then write the input and output contracts.
    4. Create evaluation cases for normal, ambiguous, missing, conflicting and prohibited inputs.
    5. Run the AI-assisted version in shadow mode: let it produce recommendations or drafts without publishing, spending or changing records.
    6. Compare its behavior with the acceptance criteria and classify every meaningful failure by cause.
    7. Grant only the permissions needed for the next bounded action, with monitoring, an approval rule and a recovery path.
    8. Version every material change and rerun the evaluation set before promoting it into the live workflow.

    At your next planning session, bring a workflow map instead of a list of AI tools. Pick the decision that causes the most repeated repair, make its inputs and rules explicit, and build the controls around it. That is where AI stops being an isolated productivity feature and becomes dependable marketing infrastructure.

    References