Category: AI

  • AI Advances in Healthcare: A Practical Evaluation Guide

    AI Advances in Healthcare: A Practical Evaluation Guide

    You’ve got a healthcare AI announcement in front of you and a decision to make: is this a meaningful advance, a promising demonstration, or a polished claim that has outrun its evidence? The model’s reputation won’t answer that question.

    You need to connect the technology to a care task, the care task to evidence, and the evidence to a controlled workflow. That framework works whether you’re evaluating a product, planning adoption, writing clinical content, or deciding which claims deserve visibility in search and AI-generated answers.

    The useful unit of progress is the care task

    The potential of healthcare AI extends from diagnostics to patient care. That range is also why broad statements about AI transforming healthcare tell you so little. Diagnostics, documentation, scheduling, patient education, and clinical decision support are different jobs with different users, failure modes, and consequences.

    Start by reducing every claimed advance to one task statement. It should identify five things:

    1. User: Who receives or acts on the output: a patient, clinician, administrator, researcher, or another system?
    2. Input: What information does the system receive, and where did that information come from?
    3. Output: Does it draft text, summarize a record, flag a case, rank options, predict an event, or initiate an action?
    4. Decision: What real decision could change because of the output?
    5. Failure consequence: What happens if the output is incomplete, late, biased, misleading, or wrong?

    For example, AI that summarizes clinician-authored encounter notes for clinician review is an assessable use case. AI that improves patient care is not. The first statement identifies a user, input, output, and review step. The second jumps directly to an outcome without showing the mechanism.

    Once the task is clear, ask what actually improved. An advance might reduce the time required for a task, make documentation more consistent, identify relevant cases, expand access, or reduce avoidable administrative work. Those are separate claims. Evidence for faster drafting does not establish better diagnosis, and stronger performance on a technical evaluation does not automatically establish better patient outcomes.

    This distinction should shape your language. If a system generates possibilities for a qualified professional to consider, say that. Don’t say it diagnoses. If it drafts an explanation that must be reviewed, call it a draft. Don’t describe it as patient guidance delivered independently. Precise verbs prevent a capability claim from quietly becoming a clinical claim.

    Separate assistance, recommendation, and action
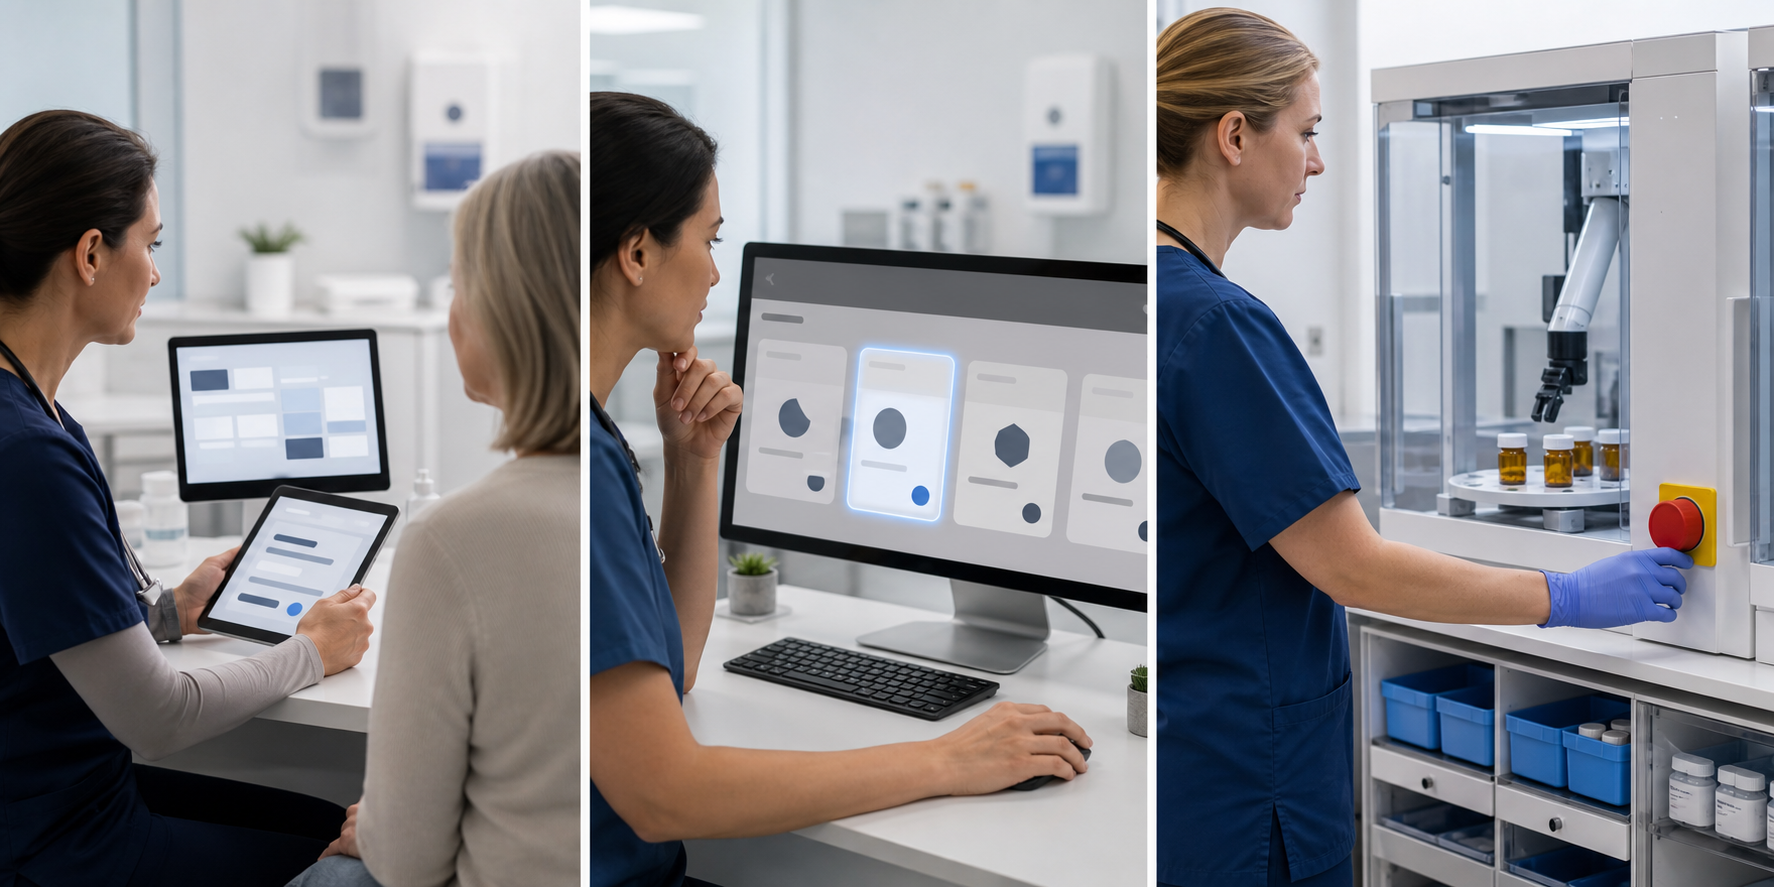
    A three-part clinical scene shows AI organizing information, presenting a recommendation, and operating supervised medication equipment.

    Healthcare AI systems can occupy very different positions in a workflow. A useful first classification is whether the system assists, recommends, or acts. This is an evaluation framework, not a regulatory classification, but it quickly exposes how much control the workflow needs.

    ModeWhat the AI doesHuman control to verifyClaim discipline
    AssistsDrafts, organizes, retrieves, or summarizes informationA person can inspect, edit, reject, and replace the outputDescribe the task support, not an unmeasured care outcome
    RecommendsFlags cases, ranks options, or proposes a next stepA qualified person evaluates the recommendation before it affects careName the intended user, decision, evaluation context, and known limits
    ActsTriggers, routes, schedules, or changes something in the workflowThe system has defined boundaries, escalation paths, and a way to stop or reverse inappropriate actionExplain exactly what is automated and where human oversight remains

    Risk does not begin only when AI acts autonomously. An incorrect summary can carry an old fact forward. A fluent explanation can make uncertain information sound settled. A recommendation can attract more trust than its evidence deserves. Human review is not a meaningful safeguard unless the reviewer has the information, authority, time, and interface needed to catch a problem.

    Inspect the control itself. A reviewable workflow should make the AI-generated material identifiable, preserve relevant input context, let the reviewer edit or reject the output, provide an escalation route, and record what was accepted or changed. A button labeled approve is not sufficient if the reviewer cannot see how the output was produced or cannot safely disagree with it.

    The closer an output gets to diagnosis, medication, treatment, or urgent-care decisions, the more explicit these boundaries must become. Patient-facing AI must not be presented as a substitute for a qualified healthcare professional. If an output conflicts with a clinician’s instructions or a medication label, the safe next step is to contact the appropriate clinician or pharmacist rather than act on the AI response. Situations involving possible immediate harm require established local emergency channels, not another chatbot prompt.

    Match every claim to its actual level of evidence

    A compelling output proves that the system produced a compelling output once. It does not establish reliability, clinical usefulness, or patient benefit. To avoid that leap, place evidence on a ladder and stop at the highest rung the evaluation genuinely supports.

    1. Capability evidence: The system can produce the intended kind of output in selected examples.
    2. Task validation: Its outputs have been evaluated against a predefined reference, process, or reviewer judgment for the stated task.
    3. Workflow validation: Intended users have used it under conditions that resemble the intended setting, including realistic inputs and handoffs.
    4. Outcome evidence: The evaluation measured the patient, clinical, or operational outcome named in the claim rather than using a technical metric as a substitute.
    5. Post-deployment evidence: Performance, failures, overrides, and changes continue to be monitored in actual use.

    Each rung answers a different question. Task validation may show that a system performs a bounded function well. Workflow validation asks whether people can use that function safely and effectively. Outcome evidence asks whether the claimed real-world result occurred. Post-deployment monitoring matters because users, data, interfaces, prompts, retrieval material, and models can change after an initial evaluation.

    When you inspect an evaluation, ask questions that reveal what the headline leaves out:

    • Which population, language, care setting, and task were represented?
    • What counted as success, and was that definition chosen before the results were reviewed?
    • What was the comparison: no tool, the existing workflow, another system, or an expert judgment?
    • Which failures occurred, who was affected, and which failures carried the greatest clinical consequence?
    • Were intended users evaluating the output, or was the system assessed only outside the care workflow?
    • What happens when information is missing, contradictory, unusually phrased, or outside the intended scope?
    • Which model, configuration, retrieval material, interface, and review process produced the result?

    If those details are unavailable, treat that absence as an evidence limit. Don’t fill the gap with a stronger adjective. Promising can be appropriate for an early capability. Validated needs a stated task and context. Effective should identify the outcome that improved. Safe is usually too broad to stand alone because safety depends on the user, setting, controls, and type of failure being considered.

    Keep the evaluated system distinct from the underlying model. A healthcare AI implementation may include a model, prompts, retrieval sources, interface rules, access controls, escalation policies, and human review. Changing any of those elements can change the behavior that users experience. Record them together, and retest material changes instead of assuming that an earlier result transfers automatically.

    Test the workflow around the model, not just the model
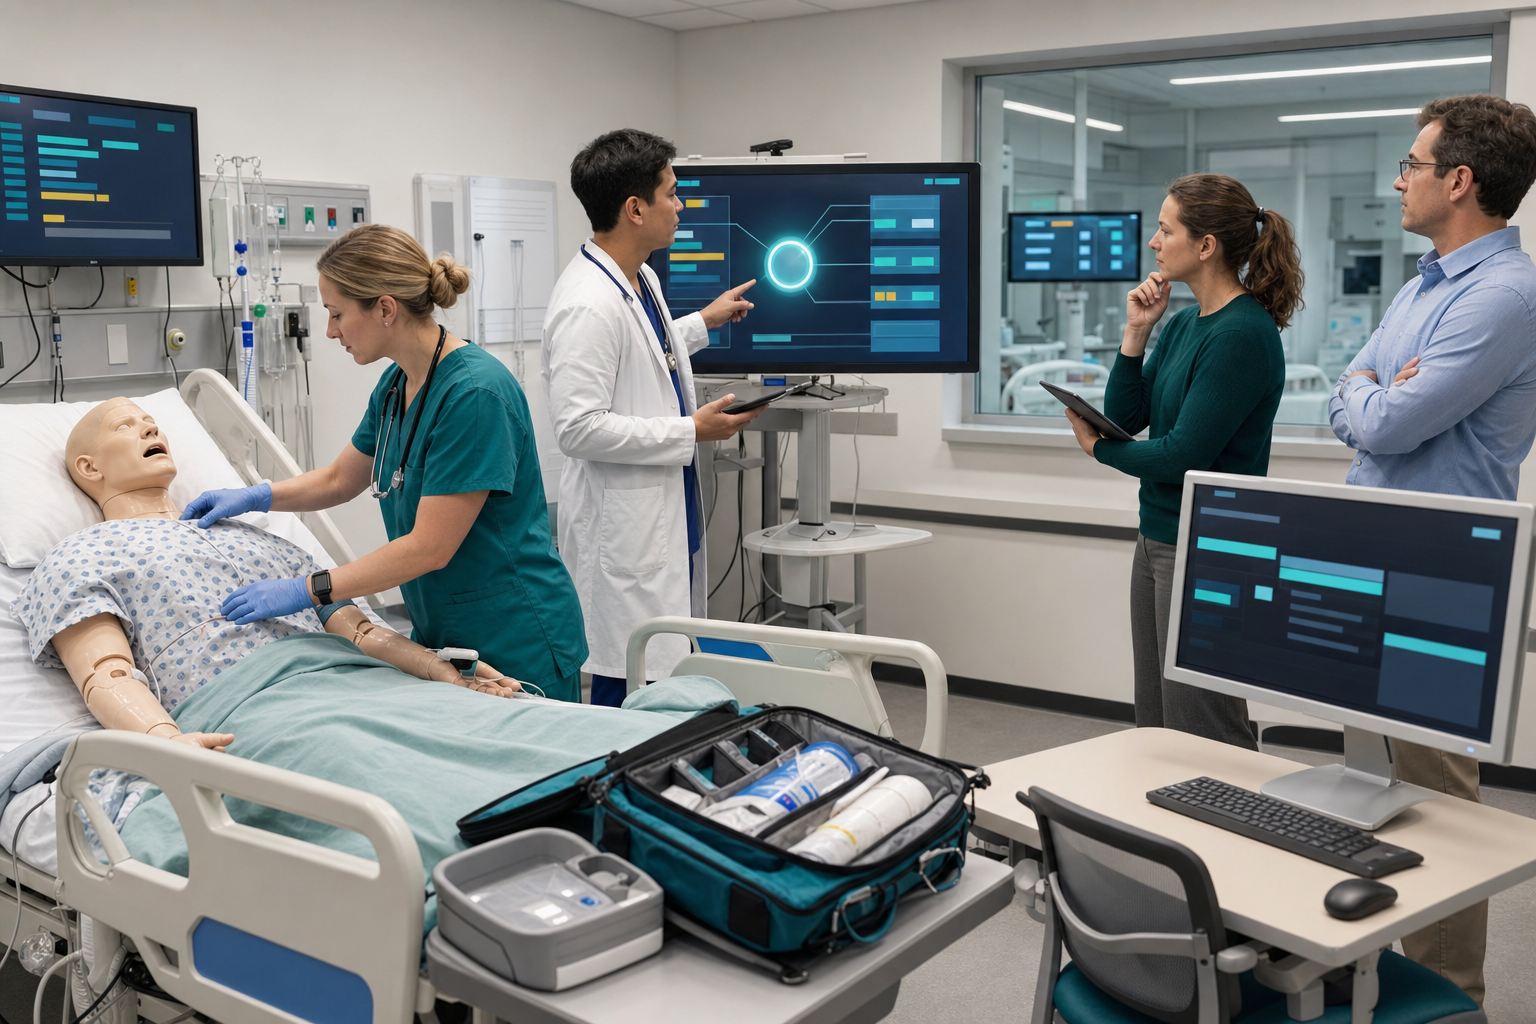
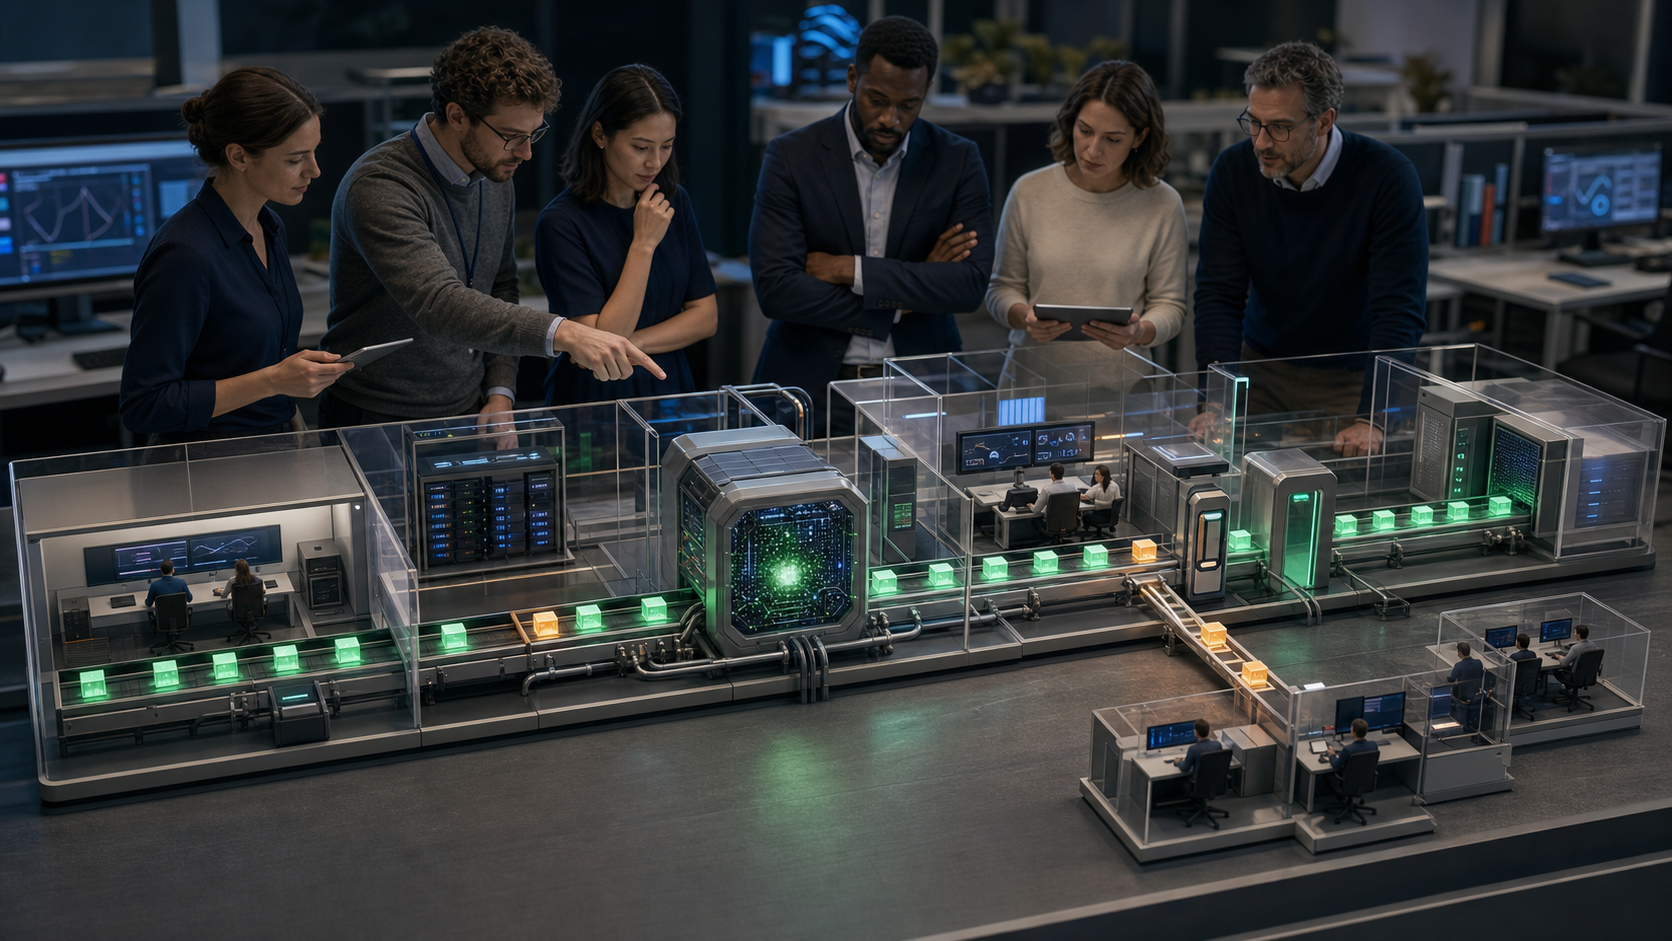
    A nurse, physician, informaticist, and human-factors specialist test an AI-supported process with a training mannequin in a clinical simulation room.

    A technically capable model can still fail as a healthcare system. The failure often appears at the handoff: the wrong information enters, the output reaches the wrong person, a warning arrives too late, or nobody owns the exception. Evaluate the full route from input to consequence.

    Use these six gates before treating a capability as deployment-ready:

    1. Context match: Confirm that the intended users, population, language, setting, and task resemble those represented in the evaluation.
    2. Input control: Define which data the system may receive, how missing or conflicting information is handled, and who is responsible for input quality. Never place identifiable patient information into an AI tool that your organization has not approved for that use.
    3. Output routing: Specify who sees the result, when they see it, what supporting context accompanies it, and whether it can alter a decision before review.
    4. Human factors: Verify that users can understand the output’s role, identify uncertainty, disagree with it, and complete the task without becoming dependent on it.
    5. Failure response: Decide in advance how the workflow handles false alarms, missed cases, unsupported statements, system outages, and outputs outside the intended scope.
    6. Change monitoring: Assign an owner to watch failures, overrides, complaints, model or configuration changes, and performance drift after launch.

    Run the workflow with difficult cases before routine ones create false confidence. Test missing context, ambiguous requests, contradictory records, out-of-scope questions, and attempts to bypass the intended process. The goal is not to prove that the system never fails. It is to learn whether failures are visible, containable, recoverable, and routed to someone able to respond.

    Define a stop condition as well as a success condition. A responsible deployment plan says who can pause the system, which events trigger review, what work continues without it, and how affected users are notified or corrected. If nobody has authority to stop an unsafe workflow, the oversight plan is incomplete.

    Publish healthcare AI claims that can survive scrutiny

    Healthcare AI content has to work for a person assessing risk and for search or answer systems extracting a concise statement. Both benefit from the same thing: explicit claims with their qualifications attached. A vague page cannot become trustworthy through optimization, and structured data cannot turn unsupported language into evidence.

    Put the central claim in a form that can stand on its own: the system, intended user, task, setting, oversight, and demonstrated evidence level should appear together. Put an important limitation in the same sentence or adjacent paragraph, not in a distant disclaimer that disappears when the sentence is quoted.

    A useful claim pattern is: [System] helps [intended user] perform [task] in [setting]. [Reviewer or control] checks [output] before [decision or action]. Current evidence establishes [capability, task performance, workflow performance, or outcome], while [important limitation] remains unresolved.

    Before publication, apply these editorial thresholds:

    • Can generate or summarize: Show that the capability was tested with the stated input and output. Don’t convert generation into an accuracy or outcome claim.
    • Supports review or decision-making: Identify the qualified user, the decision being supported, the review step, and the context in which the support was evaluated.
    • Improves a workflow: Name the measured operational result and the workflow used for comparison. Don’t use an isolated model score as proof of workflow improvement.
    • Improves diagnosis or patient outcomes: Reserve this language for evidence that measured the named diagnostic or patient outcome in the defined population and setting.
    • Is safe: Replace the blanket claim with the risks evaluated, controls used, limitations found, and context covered. No system is safe independently of its use.

    Keep vendor, model, product, and care provider roles separate. OpenAI, Google, and Anthropic may be relevant to the underlying AI landscape, but a familiar model developer’s name does not establish that a particular healthcare implementation is clinically validated. State who built the model, who configured the system, who operates the workflow, and who is responsible for clinical review whenever those roles differ.

    Your maintenance process matters as much as the launch page. Keep a claim inventory linking each public statement to its evidence, evaluated configuration, owner, review date, limitations, and correction route. When a model, prompt, retrieval source, interface, intended use, or oversight process changes, review the dependent claims. Otherwise, accurate content can become misleading while its publication date and search visibility remain unchanged.

    Use schema and other machine-readable markup to describe what the visible page actually says. Keep the evidence level, intended use, limitations, author or reviewer responsibility, and update history readable on the page itself. Machines may extract the markup, but people still need enough context to judge the claim.

    Key takeaways

    • Judge healthcare AI at the level of a defined care task, not the reputation of a model or developer.
    • Separate systems that assist, recommend, and act; each position requires a different degree of control and claim restraint.
    • Don’t treat a demonstration, task evaluation, workflow evaluation, outcome evaluation, and monitored deployment as interchangeable evidence.
    • Evaluate inputs, handoffs, human review, failure response, and change control alongside model performance.
    • Keep qualifications beside the claim so readers and AI answer systems do not receive a stronger statement than the evidence supports.
    • Do not present patient-facing AI as a replacement for qualified medical care, especially where diagnosis, medication, treatment, or urgent decisions are involved.

    For the next healthcare AI claim you encounter, write the five-part task statement before you draft a headline, approve a tool, or publish a page. Then label the highest evidence rung it has reached. If you cannot complete either step, hold the claim at capability level until the missing context is available.
    References

  • Agentic AI for E-commerce: A Leadership Operating Plan

    Agentic AI for E-commerce: A Leadership Operating Plan

    If your leadership team is asking whether agentic AI will make product pages, search traffic, or brand marketing obsolete, the useful answer is no. That is not a reason to wait. The practical change is that more discovery, comparison, filtering, and execution can move into software acting for the shopper.

    You need an operating plan that makes your products easy for both people and machines to understand, verify, and select. You also need measurement that remains honest when part of the buying journey happens beyond your analytics. Here is how to build both without reorganizing the company around an adoption curve nobody can forecast precisely.

    Key takeaways

    • Agentic commerce adds a software decision layer between customer intent and commercial execution. It does not remove the customer or the need to earn trust.
    • Your central readiness question is no longer only whether a product can rank. It is whether the product is eligible to survive a constraint-based selection process.
    • Eligibility depends on complete, consistent product facts, dependable price and availability data, clear policies, technical accessibility, and a transaction path that works.
    • JSON-LD and other machine-readable formats should publish canonical business facts, not compensate for contradictions between your systems.
    • SEO, merchandising, engineering, operations, customer experience, and analytics need named ownership. Agent readiness cannot sit entirely inside the marketing team.
    • Exact attribution will become less reliable as more evaluation happens inside AI systems. Measure readiness directly and interpret commercial outcomes directionally.

    Reframe the agent as a customer proxy

    In this context, agentic AI means software can carry part of a task forward from a person’s intention. The shopper still supplies the need, preferences, budget, and acceptable trade-offs. The software interprets those constraints, investigates options, narrows the field, and may take an action on the shopper’s behalf.

    Consider the difference between a shopper searching for running shoes and a shopper asking for a pair that fits a particular use, budget, size, delivery requirement, and material preference. A traditional search journey requires the person to open results and resolve those constraints manually. An agent can turn the same request into a filtering job before the shopper reaches a product page.

    A useful leadership model separates the journey into distinct decisions:

    • The person defines the desired outcome and acceptable constraints.
    • The agent interprets those constraints and identifies possible candidates.
    • Your published product and business data determine whether your offer can be understood and qualified.
    • Trust signals, policies, and commercial reliability help the agent distinguish between otherwise suitable candidates.
    • Your commerce systems determine whether the selected action can be completed successfully.

    This model changes the executive question. Instead of asking, ‘Will agents replace our customers?’, ask, ‘At which decision could incomplete or unreliable information remove us from consideration?’

    Rankings still matter because agents need candidates to evaluate. They are no longer a sufficient definition of success. A highly visible offer can still be filtered out if its suitability is unclear, its current price cannot be trusted, or its policies create unresolved risk. A lower-profile offer may remain eligible because it answers the request more precisely.

    The transition will not move at the same speed in every market. Categories with standardized products and organized data are easier for software to evaluate. Complex purchases and categories with regulatory constraints introduce more ambiguity. Treat adoption as gradual and category-dependent, then set investment levels for your own selection conditions rather than following a general hype cycle.

    The earliest pressure is likely to appear in discovery and consideration. Natural-language requests can carry far more context than short category queries, while software can perform the initial comparison without exposing every intermediate step. That weakens the assumption that owning a broad head term guarantees access to the consideration set.

    It also changes the job of content. A page should not merely attract a click or repeat a category phrase. It should resolve the variables that determine fit: what the product is, whom it serves, where it does not fit, what it costs, whether it is available, what conditions apply, and why the claims are credible.

    Audit the selection chain, not just the search result

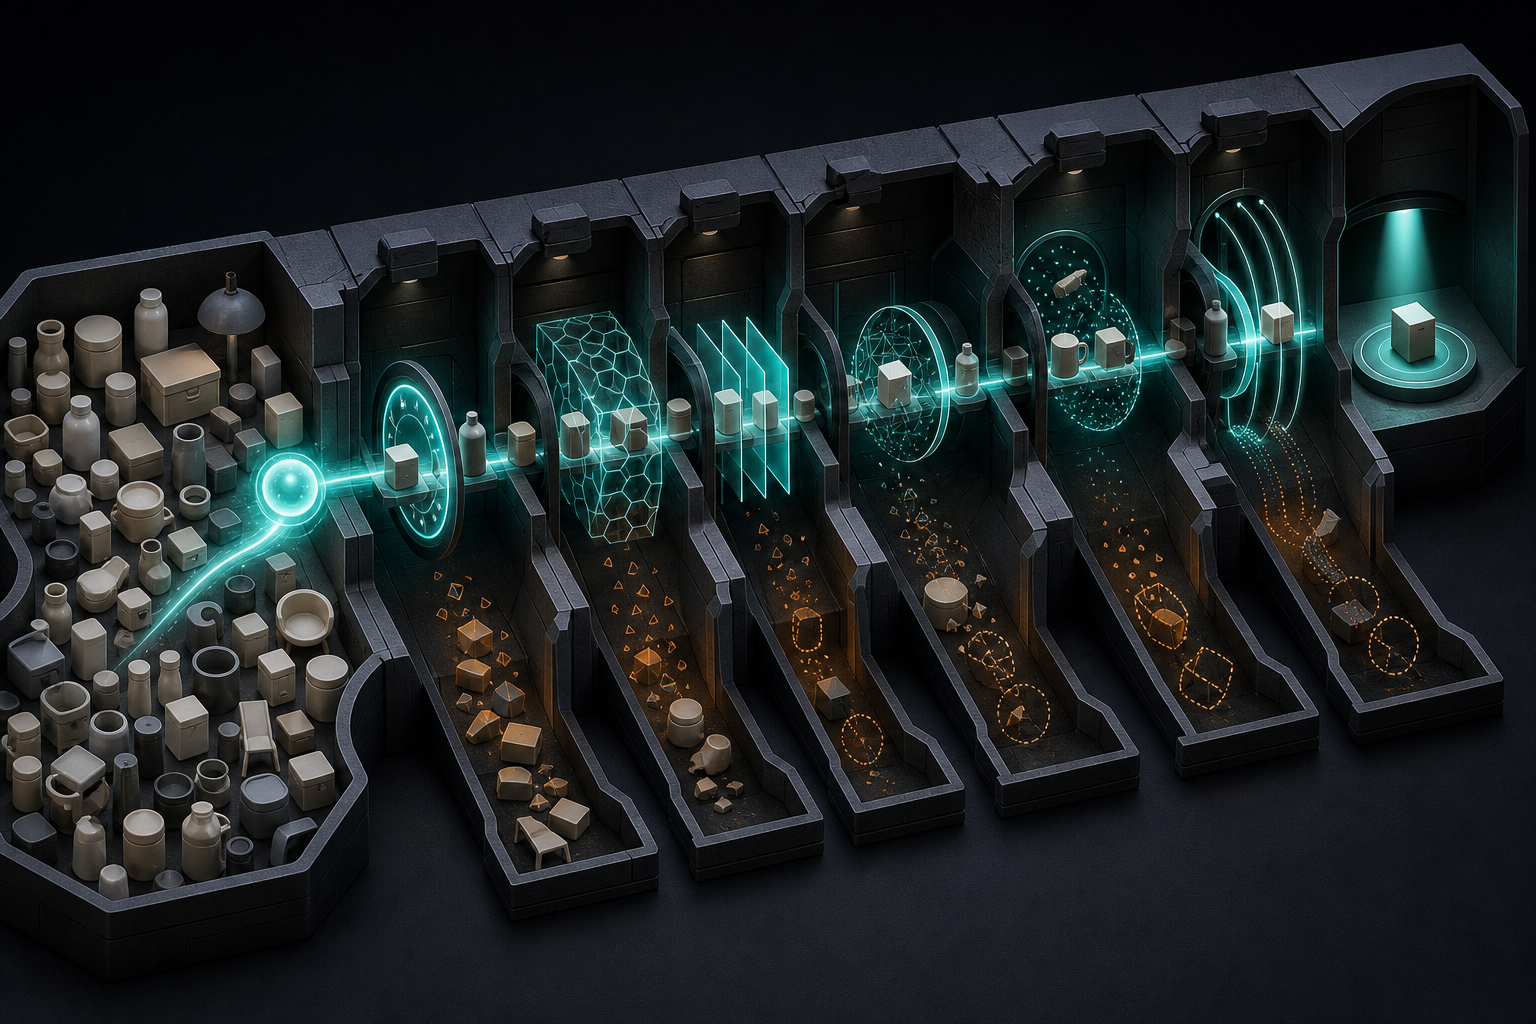
    A glowing software agent passes generic products through several visual filtering and verification stages before making a final selection.

    Eligibility is not an official score supplied by an AI platform. It is a management lens for identifying the facts and systems that must work before an offer can be selected confidently. That makes it more useful than a vague goal such as ‘be ready for agents.’

    Selection stageQuestion the system must resolveEvidence to inspect
    IdentityWhat exactly is being offered?Canonical product name, identifiers, category, variant relationships, and consistent descriptions.
    SuitabilityDoes the offer satisfy the shopper’s constraints?Category-specific attributes, compatibility, dimensions, use conditions, exclusions, and variant-level facts.
    Commercial truthWhat will the shopper pay, and can the item be obtained?Current price, availability, offer conditions, and agreement between public surfaces and commerce systems.
    Trust and riskWhat uncertainty comes with choosing the offer?Clear return terms, restrictions, warranties where relevant, evidence for claims, and consistent policy language.
    ExecutionCan the intended action be completed reliably?Working product and checkout paths, accurate inventory state, dependable payment handling, and technical availability.

    Do not begin this audit with a new AI tool. Begin with a representative product family and a realistic, constraint-rich shopping request. The request should contain the kinds of conditions that would change the answer, not merely the category name.

    1. Write down the product facts, offer conditions, and policies required to answer the request without guessing.
    2. Identify the authoritative system and accountable owner for each fact.
    3. Trace the fact through every surface that publishes it, including the product page, product feeds, structured data, inventory displays, policy pages, and checkout where relevant.
    4. Mark each fact as present and consistent, absent, contradictory, stale, or technically inaccessible.
    5. Repair the authoritative value or propagation path rather than editing one visible symptom.
    6. Republish the affected surfaces and repeat the same shopping request to confirm that the ambiguity has actually disappeared.

    Prioritize contradictions before polishing optional copy. A missing secondary detail may narrow your eligibility for a particular request. Conflicting price, availability, variant, or policy information can undermine confidence in the entire offer. Dynamic facts deserve particular attention because a value that was correct when published can become wrong when updates fail to propagate.

    JSON-LD belongs in this chain, but it is a publication layer rather than a separate version of reality. If your visible page, feed, structured data, and backend expose different values, adding more markup gives the system another conflicting claimant. Define the canonical fact, define which system owns it, and make every machine-readable representation inherit from that source wherever your architecture allows.

    Your audit record should preserve the shopping request, required constraints, expected eligible products, retrieved facts, contradictions, remediation owner, and retest result. That turns agent readiness into a repeatable quality process instead of a collection of screenshots from impressive demonstrations.

    Build agent readiness into normal commerce ownership

    A cross-functional commerce team coordinates product information, inventory, fulfillment, analytics, and customer experience around a shared digital product model.

    Agentic selection crosses organizational boundaries because the deciding signals do. Marketing can improve discovery, but it cannot independently correct an inventory state, repair checkout, define a returns policy, or decide which product database is authoritative. Machine-readable trust depends on technical and operational integrity as much as promotional visibility.

    Assign the fact, the path, and the control

    Team names will vary, but the accountability cannot remain vague. Use the following division as a starting point:

    WorkstreamQuestion it should ownEvidence leadership should request
    Merchandising or product dataWhich attributes and variant relationships are authoritative?A documented source for selection-critical product facts and a queue of unresolved data defects.
    Commerce operationsAre price, availability, and offer conditions current?Exception reporting for mismatches and a defined response when updates fail.
    EngineeringCan machines reliably retrieve the same facts customers see?Healthy publication paths for pages, feeds, structured data, inventory, payment, and checkout.
    SEO, AEO, and GEOWhich intents and constraints determine eligibility, and where is ambiguity visible?Constraint maps, crawl and rendering findings, content gaps, and cross-surface consistency checks.
    Customer experience and policy ownersCan a buyer resolve risk without interpretation or conflicting language?Explicit policy terms, known ambiguity cases, and a path for correcting recurring questions.
    AnalyticsWhat can be observed directly, and what can only be inferred?Metric definitions that separate readiness, observable behavior, commercial outcomes, and unknowns.
    Executive sponsorWho resolves ownership conflicts and approves contingent investment?A prioritized defect register, decision gates, and accepted limits on attribution.

    Attach this work to an existing digital commerce, merchandising, or operational review. A separate agentic AI committee will not help if it lacks authority over product truth and commerce systems. The standing agenda can remain short: which selection-critical defects appeared, which source owns them, which customers or products are exposed, and whether the repair survived retesting.

    Change the content brief from attention to resolution

    Traditional consideration content often accumulates reviews, comparisons, benefit claims, and reassurance. Those assets still have value, but an agent can turn consideration into a strict filtering exercise. Content must therefore make fit and evidence easy to extract, not merely make the page persuasive.

    • State who and what the product is for, including meaningful limitations and exclusions.
    • Use stable terminology for the same attribute across product copy, specifications, feeds, structured data, and policies.
    • Keep claims close to their supporting evidence. Avoid vague superiority language that cannot help resolve a constraint.
    • Put selection-critical facts on the canonical page where they belong instead of scattering answers across thin supporting pages.
    • Make comparisons explicit about the condition that changes the recommendation. Not every product should appear to be the best option for every buyer.
    • Review policy language as decision data. A policy that requires interpretation leaves a risk variable unresolved.

    This favors content quality over page volume. If the answer already belongs on a product or category page, repair that page rather than publishing another near-duplicate merely to target a longer query. The goal is a coherent representation of the offer across every surface an agent may use.

    There is also a brand consequence. Software may filter and select products before a shopper becomes familiar with every candidate. That can improve conversion while weakening brand recognition. Preserve clear brand identity in the product facts and trust signals likely to travel with the offer, and continue building familiarity beyond search. A trusted brand gives both the shopper and the software fewer unresolved reasons to reject the choice.

    Measure readiness honestly and stage your investment

    Agentic journeys make precise attribution harder because more evaluation can happen inside an external AI system. Fewer visible page interactions do not automatically mean your optimization failed, just as a conversion cannot automatically prove that an agent caused the outcome. Leadership should expect directional indicators and blended performance to carry more weight than a perfectly reconstructed path.

    Use a layered scorecard

    Start with measures your business can observe and control:

    • Critical-fact completeness: the share of in-scope products with every attribute required for the tested shopping requests.
    • Cross-surface agreement: whether product pages, feeds, structured data, inventory displays, policies, and checkout expose the same current facts.
    • Update propagation: how reliably a canonical change reaches each public surface, and where stale values persist.
    • Technical availability: whether the relevant content and transaction paths can be retrieved and completed without an avoidable failure.
    • Policy ambiguity: unresolved cases in which offer conditions or customer protections conflict or require interpretation.

    Then place behavioral and commercial indicators beside those readiness measures:

    Leadership questionUseful indicatorWhat it cannot prove
    Are our offers becoming easier to qualify?Improved completeness, consistency, accessibility, and retest results for priority product families.That a specific AI system selected the offer.
    Can we see agent-associated visits?Identifiable referral or journey evidence where analytics exposes it.The total volume of agent influence, because many intermediate decisions may remain hidden.
    Are repaired journeys performing better?Product-family conversion, completion, cancellation, and other relevant outcome trends interpreted with the defect history.That the repair alone caused the change.
    Is the business gaining selection without losing recognition?Blended commercial performance considered alongside branded demand and returning-customer behavior.Exact credit for any single search, content, brand, or agent interaction.

    Report observation, inference, and unknowns separately. ‘The price mismatch was removed and the affected family improved’ is an observation followed by a correlation. ‘Agents generated the improvement’ is a causal claim that requires evidence you may not possess. This distinction protects the budget conversation from false precision.

    Separate foundation work from contingent bets

    The most defensible investments help current customers and current commerce operations even if agent adoption is slower than expected. Approve work that improves product information, removes contradictions, clarifies policies, strengthens technical reliability, or fixes price, inventory, payment, and checkout defects. These changes reduce uncertainty regardless of which interface initiates the purchase.

    Run controlled experiments for questions your analytics cannot answer yet. Reuse realistic shopping requests, record the expected eligibility conditions before testing, and preserve failures as well as successes. A demonstration is useful for discovering defects; it is not enough evidence for a large strategy change.

    Keep bespoke integrations, major budget reallocations, and platform-dependent builds behind explicit decision gates. Before approving one, ask whether the business controls the required data, whether a recurring failure or opportunity has been observed, whether the dependency is stable enough to support the investment, and whether the work remains valuable if adoption develops differently.

    This avoids the two expensive extremes: making sweeping changes because a demonstration looks inevitable, or ignoring agentic behavior until commercial performance forces a rushed response. The practical middle is to repair known eligibility weaknesses now and reserve harder-to-reverse bets for evidence that justifies them.

    At your next operating review, put a real product family and a real constraint-rich shopping request on screen. Trace every fact a shopper’s proxy would need, name the owner of each contradiction, repair the problem at its source, and retest the same request. You will make the business easier to select now without pretending anyone knows the final shape or pace of agentic commerce.

    References

  • How to Make AI Agents Useful Marketing Collaborators

    How to Make AI Agents Useful Marketing Collaborators

    You probably don’t need another AI tool that can generate copy on command. You need campaign work to move without facts being invented, approvals being skipped, or teammates spending longer repairing output than creating it.

    The useful promise behind turning workflows into agents is not that software becomes a teammate by declaration. It is that a system can hold a bounded responsibility, use approved context, produce a reviewable change, and return control at the right moment. Getting those boundaries right is what turns an agent from an interesting demo into a dependable part of marketing operations.

    Give the agent a responsibility, not a vague objective

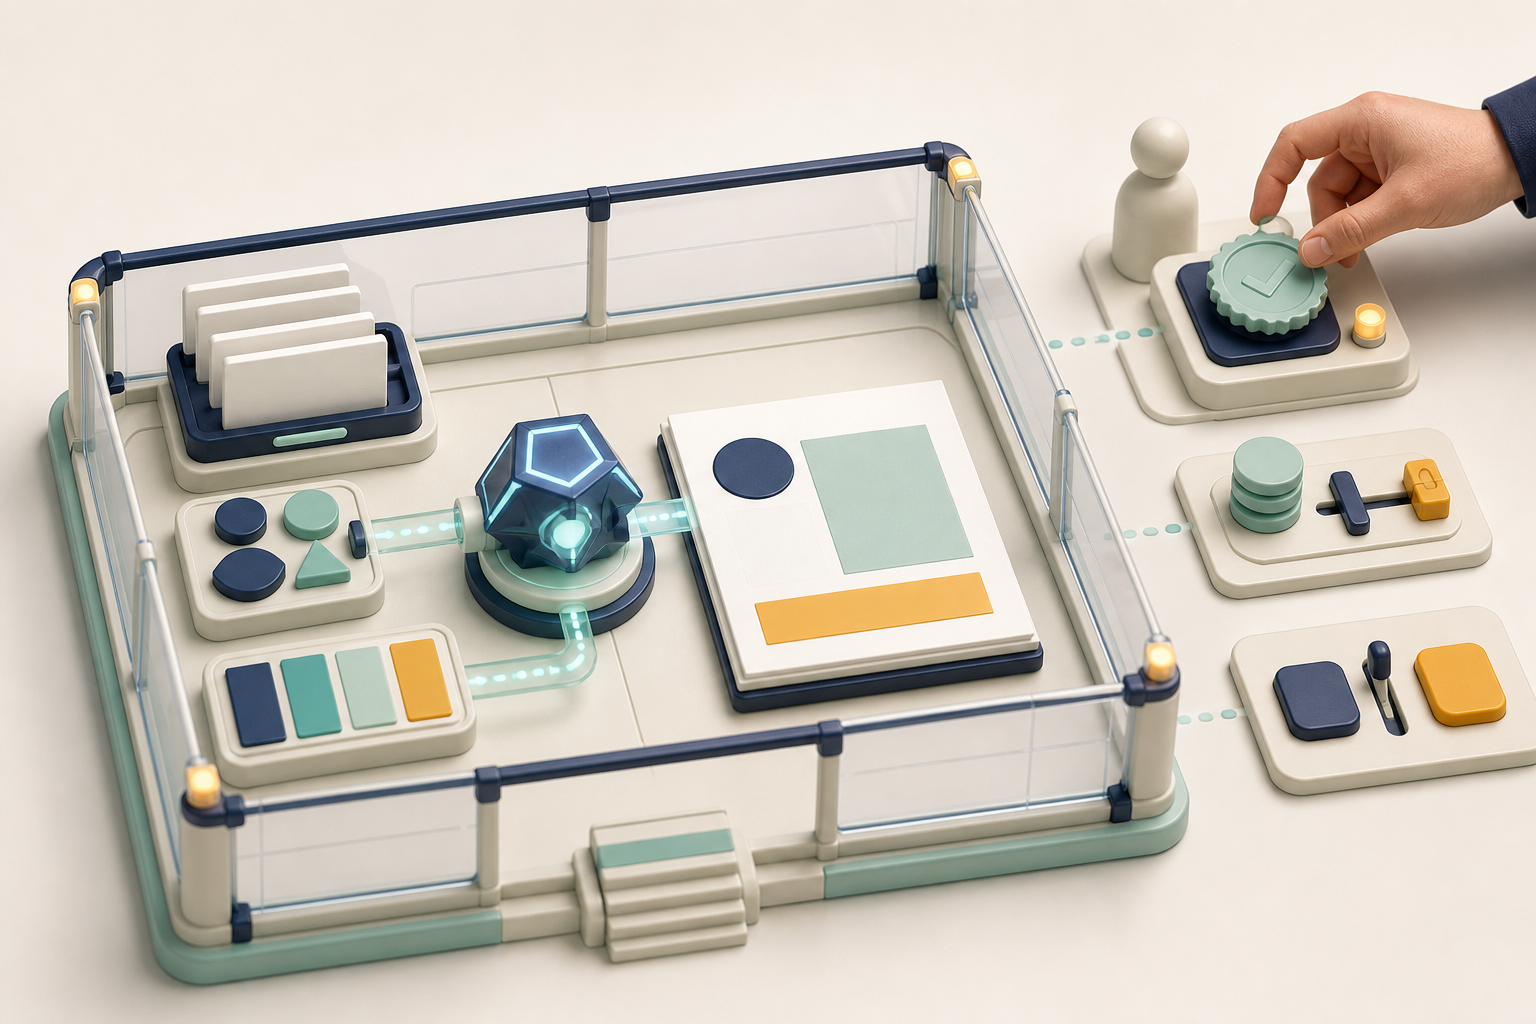
    A geometric AI assistant assembles approved campaign assets inside a partitioned workspace while publishing and approval controls remain outside with a human supervisor.

    An assistant waits for a prompt. A conventional automation follows a predetermined sequence. An agent can work toward an outcome across a bounded series of decisions and actions. Real tools often blend all three modes, so the label matters less than the responsibility you assign.

    “Help with content marketing” is not a responsibility. It leaves the system to guess which pages matter, which evidence is acceptable, what it may change, and when a person should intervene. Those guesses create the same coordination problems you were trying to remove.

    Write the assignment in this form:

    When this trigger occurs, prepare this outcome from these approved inputs, stop before this decision, and hand the work to this owner.

    Marketing agent role template

    A content-refresh agent, for example, could be responsible for preparing an evidence-backed change set when a page enters an editorial review queue. It may inspect approved performance data, compare the page with the current content brief, identify unsupported or outdated passages, draft revisions, and suggest structured-data changes. It may not publish, alter the canonical URL, introduce a new product claim, or remove the existing page. The content owner makes those decisions.

    That boundary gives the agent meaningful work without pretending that every judgement can be delegated. Define the role with the following fields:

    • Trigger: the event that starts the work, such as a scheduled review, an approved campaign brief, or a flagged content issue.
    • Outcome: the artifact or state the agent is expected to produce. Name the deliverable rather than saying “improve” or “optimize.”
    • Inputs: the repositories, reports, templates, and records it may use.
    • Permissions: what it may read, draft, edit, submit, publish, or send.
    • Stop conditions: conflicts, missing evidence, unusual risk, or decisions that must be escalated.
    • Owner: the person accountable for accepting the result and deciding what happens next.

    If you cannot complete those fields, the workflow is not ready for an agent. The problem is usually unclear ownership or an undocumented decision rule. Fixing that ambiguity will help the human team even if you postpone the automation.

    Design the handoffs before granting action permissions

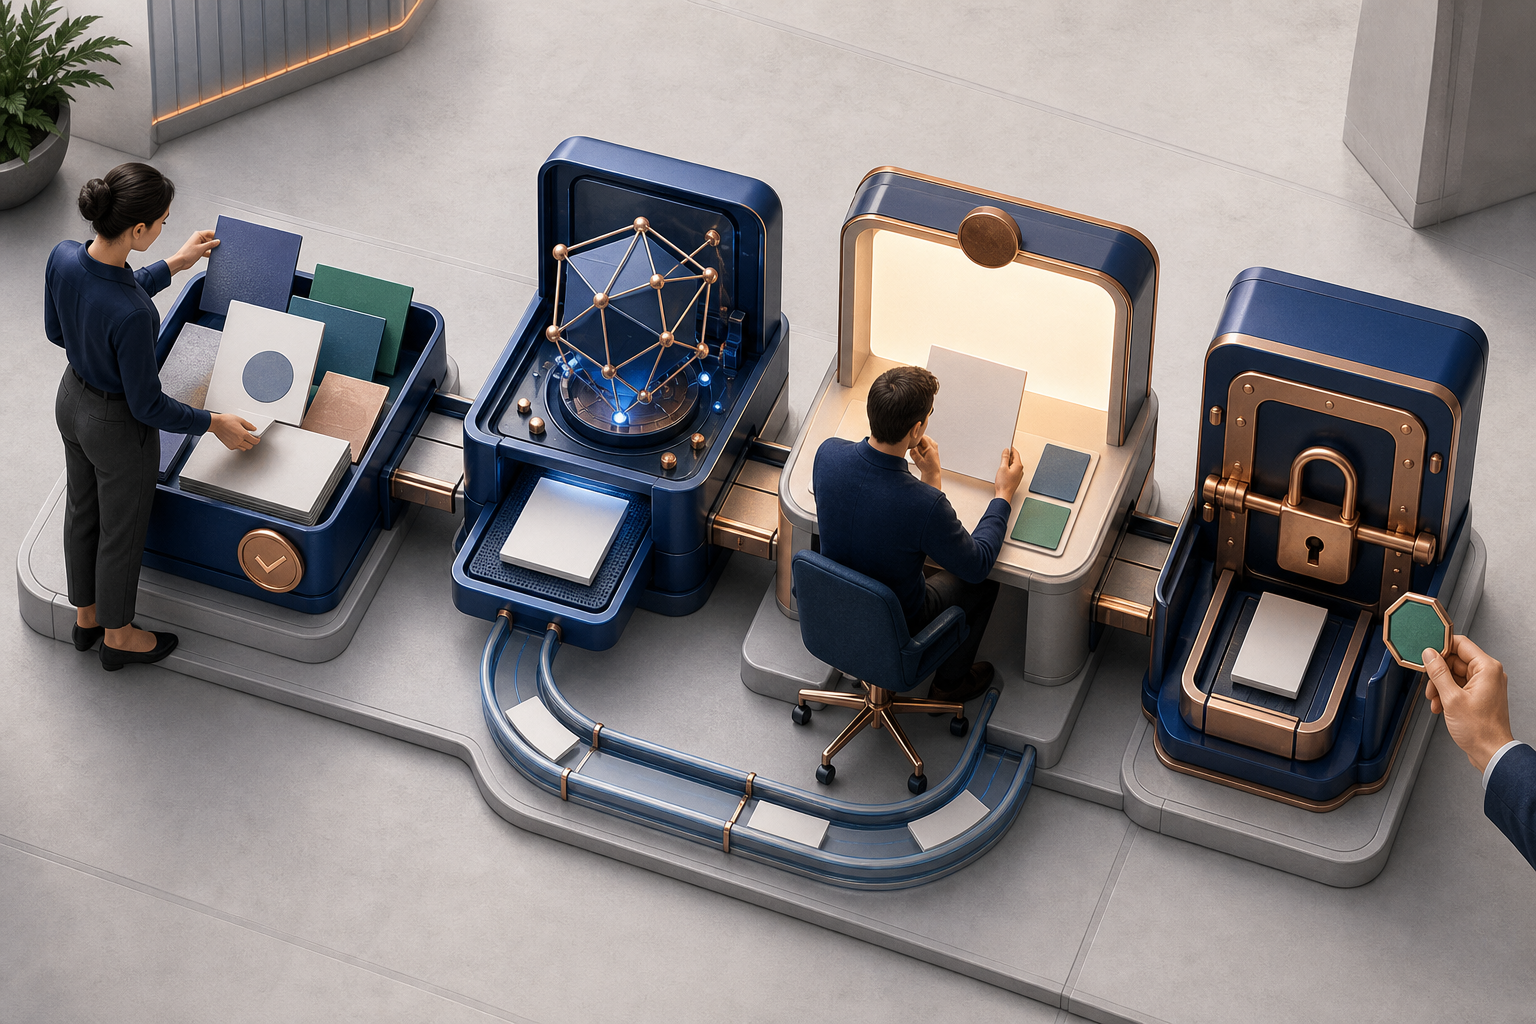
    Campaign assets move from human-supplied sources through AI drafting and human review to a locked final action gate, with channels returning corrections to the draft stage.

    Marketing collaboration breaks at handoffs. A draft exists, but nobody knows whether it is ready for legal review. A campaign recommendation is accepted in chat, but the media plan still contains the old decision. A schema change reaches production, but the content team never sees the new claims encoded in it.

    An agent can make those failures happen faster unless every handoff has a visible state. Use a simple operating sequence for each assignment:

    <!– wp:list {
  • AI Assistant Advertising Models: A Practical Brand Guide

    If you are deciding whether to move media budget into AI assistants, the first question is not how much to spend. It is whether the assistant sells influence at all and, if it does, whether you can identify exactly what your money changes.

    That distinction matters because assistant advertising is not developing as one standardized channel. Claude has committed to an ad-free experience, while ChatGPT is opening a path toward advertising. Your plan therefore needs two lanes: paid distribution where inventory exists and organic AI visibility everywhere users may ask for recommendations.

    There is no single AI assistant advertising model

    Search advertising has familiar boundaries. A user enters a query, paid placements occupy identifiable positions, and organic results remain available alongside them. An AI assistant can collapse research, comparison, and recommendation into one generated response. That makes the commercial model more consequential: a paid element may sit much closer to the assistant’s advice than a conventional display or search ad does.

    Three relationships are especially important for planning. They are not mutually exclusive; one assistant can support user-initiated commerce while refusing advertiser-funded placements.

    ModelHow the brand participatesWhat the user experiencesYour planning priority
    Ad-supported conversationThe brand pays for eligibility in a sponsored message, link, product unit, or branded placement.Commercial content appears in or around the conversation.Verify disclosure, context controls, billing, and the separation between sponsorship and the assistant’s answer.
    Ad-free assistantThere is no sponsored-response inventory to purchase.The assistant answers without advertiser-funded placements.Invest in accurate, accessible, well-structured information that can qualify for unpaid discovery.
    User-initiated commerceThe brand can be considered when the user asks the assistant to research, compare, or help purchase something.Commercial help begins with the user’s request rather than an advertiser inserting a pitch.Make product facts, conditions, limitations, and supporting evidence easy to retrieve and verify.
    User-directed integrationA tool or service performs a function after the user chooses to invoke or connect it.The integration helps complete a task without necessarily creating sponsored exposure.Treat integration availability as product distribution or functionality, not as proof of advertising reach.

    The split is already commercially meaningful. Claude’s approximately 30 million users are outside its potential sponsored-placement market, while ChatGPT offers a possible advertising surface connected to an estimated 800 million weekly users. Those are estimates of platform audiences, not estimates of purchasable reach. They do not tell you how many people are eligible for an ad, which markets or accounts have access, how often ads appear, or whether a particular placement can reach your buyers.

    Do not put total assistant users into a media plan as though they were impressions. Ask for the addressable audience, eligible conversation contexts, available markets, delivery rules, and reporting definitions. If those details are unavailable, the audience number is market context rather than a forecast.

    The deeper difference is incentive design. Anthropic’s stated position is that advertising could undermine trust, encourage assistants to find monetizable moments, and create pressure to prolong engagement. That is Anthropic’s strategic argument for keeping Claude ad-free, not proof that every assistant ad will corrupt every answer. It does identify the right questions for a buyer to test:

    • Does sponsorship affect only the placement, or can it affect the substance, ordering, or framing of the assistant’s answer?
    • Can the user distinguish the sponsored element before interacting with it?
    • Does the disclosure remain visible when the response is expanded, copied, shared, or revisited?
    • Can you prevent placements from appearing in sensitive or unsuitable conversational contexts?
    • Is the system rewarded for resolving the user’s task, extending the conversation, or generating more commercial opportunities?
    • Can you retrieve a record of the creative, disclosure, destination, and context category that were served?

    If a platform cannot answer these questions clearly, you do not yet have enough information to evaluate brand risk. Novelty is not a substitute for placement transparency.

    Build paid distribution and organic AI visibility as separate lanes

    Assistant marketing becomes muddled when paid ads, organic citations, product recommendations, and tool integrations all appear under one AI visibility label. Separate them before assigning work, budget, or performance targets.

    Lane one: paid assistant distribution

    A paid program starts with the unit being purchased. Do not approve a line item called AI assistant ads unless the brief states whether you are buying a sponsored message, a branded module, a link, a product placement, or another clearly defined format.

    • Confirm access. Record the assistant, account type, market, language, device coverage, campaign objective, and inventory status. A platform announcement does not guarantee that your account can buy the format.
    • Define eligible context. Document what user intent or conversation category can trigger the placement. A broad audience label is not enough when the placement appears inside a highly specific exchange.
    • Capture the disclosure. Obtain an example showing the complete placement as the user sees it. Review the label, visual boundary, advertiser identity, and destination before launch.
    • Set exclusions. Identify contexts in which a commercial message would be inappropriate or risky for your brand. If the platform cannot support necessary exclusions, do not assume that careful creative will solve the placement problem.
    • Match the destination. The landing page should preserve the product, offer conditions, limitations, and expectations established by the placement. A conversational ad can feel unusually personal, so a mismatched handoff is especially conspicuous.
    • State one testable hypothesis. Decide whether the pilot is meant to generate qualified visits, purchases, leads, product consideration, or learning about a new format. Do not use platform audience size as the success metric.

    Lane two: unpaid assistant eligibility

    An ad-free policy does not make an assistant irrelevant to commerce. Claude can still help a user research, compare, or purchase products when the user requests that help; its distinction is that the commercial task is user-initiated rather than advertiser-driven. That means a brand can be discoverable without being able to buy its way into the conversation.

    This is where SEO, AEO, GEO, content quality, and structured data meet. Your objective is not to manufacture a recommendation. It is to make verifiable information available when an assistant needs to answer a relevant question.

    1. Map real decision questions. Start with the questions a buyer must resolve: what the product does, who it is for, what it works with, where it is available, what it costs, what is included, and when it is not a suitable choice.
    2. Create a canonical answer for each decision. Put the authoritative fact on a stable page instead of scattering conflicting versions across campaign pages, support documents, and old announcements.
    3. Make qualifiers explicit. Attach version, region, date, plan, compatibility, availability, and pricing conditions to the claim they qualify. An assistant cannot preserve a limitation that your page leaves implicit.
    4. Align JSON-LD with visible content. Use applicable structured-data types, such as Organization, Product, Offer, or SoftwareApplication, only for information that a reader can also verify on the page. Structured data can clarify entities and relationships; it does not make an unsupported marketing claim true or guarantee inclusion in an answer.
    5. Support important comparisons. Explain the basis of a compatibility, performance, feature, or suitability claim. Separate measured facts from editorial positioning and avoid presenting a slogan as evidence.
    6. Remove retrieval barriers. Check that public decision pages can be fetched, rendered, and understood without a login or a fragile interaction. Keep essential facts in readable page content rather than only in images or interactive widgets.
    7. Assign an owner. Product, policy, price, and availability pages need someone responsible for correcting stale facts. Display an updated date only when it reflects a genuine review.

    Paid placement may create exposure on one assistant. It will not repair contradictory specifications, inaccessible pages, vague entities, or unsupported claims. Organic readiness therefore remains infrastructure, not a fallback campaign.

    Use a six-part gate before approving an AI ad test

    A small pilot can be reasonable when the format is new, but small does not mean ungoverned. Require a written answer to each gate before money moves.

    1. Inventory gate: Is the placement available to your account in the intended market, language, device environment, and campaign period? If not, keep the item out of the committed budget.
    2. Influence gate: What exactly does payment buy? Separate eligibility for a labeled placement from influence over the assistant’s non-sponsored response. If the boundary is unclear, pause.
    3. Disclosure gate: Can a reasonable user tell what is sponsored, who paid for it, and where it leads? Review the complete rendered experience, not just the advertiser dashboard preview.
    4. Context gate: Can you target useful commercial intent and exclude contexts that would make the message intrusive, unsafe, or damaging? If context controls are weaker than your brand requirements, the inventory is not suitable.
    5. Measurement gate: Will reporting expose delivery, interaction, cost, and outcome definitions? A dashboard number without a denominator or documented event definition cannot support a scale decision.
    6. Economics gate: Is the test budget tied to a customer-value hypothesis and a stopping rule? Do not derive an acceptable price from the assistant’s total user count. Set it from the value of the outcome you can actually measure.

    Pass all six gates before treating the channel as performance media. If disclosure and context control pass but conversion measurement is weak, classify the activity as a learning or awareness test. If disclosure or answer independence fails, waiting is the clearer decision. If the assistant is ad-free, redirect the work to organic eligibility instead of searching for an unofficial shortcut.

    Include procurement, legal, privacy, and brand-safety reviewers when the placement uses personal data, operates in sensitive contexts, or creates claims with contractual consequences. The specific review depends on your market and use case; the novelty of the format does not remove existing obligations.

    Measure paid delivery, business outcomes, and organic visibility separately

    An assistant interaction can influence a decision without producing an immediate click. That does not justify vague attribution. It means you need a measurement structure that shows what is directly observed, what is attributed under your rules, and what remains unknown.

    Build the paid scorecard in layers:

    • Delivery: eligible conversation contexts, sponsored impressions, viewable placements, reach, and frequency, but only where the platform reports and defines them.
    • Interaction: placement opens, expansions, clicks, product-detail views, or other actions that can be tied to the sponsored unit.
    • Business outcome: qualified leads, purchases, subscriptions, booked meetings, or another outcome your existing analytics can validate.
    • Efficiency: cost per defined interaction and cost per defined business outcome. Preserve the event definition next to the number.
    • Quality: lead quality, cancellations, returns, or downstream customer value where those measures are relevant and available.
    • Trust and safety: complaints, unsuitable-context incidents, misleading renderings, disclosure failures, and brand-safety escalations.

    Tag paid destinations with campaign parameters and preserve the assistant, campaign, placement, creative, market, and date in your analytics records. Do not adopt a special attribution window merely because the channel uses AI. Apply your documented attribution rules, report direct and assisted outcomes separately where possible, and label modeled results as modeled.

    Incrementality deserves its own line. Use a randomized holdout when the platform supports one. Without a valid control, describe changes as observed or attributed rather than claiming the ads caused every conversion. A before-and-after increase can be useful evidence, but seasonality, other campaigns, and changes in demand can also move it.

    Organic AI visibility needs a different scorecard because no impression was purchased. Maintain a fixed set of decision prompts based on real buyer questions. For every check, record the assistant, model or product surface, market, date, account state, prompt, response, cited pages, brand inclusion, factual accuracy, and important omissions. Consistent conditions make changes interpretable; an isolated screenshot does not.

    • Track whether the brand is mentioned, but do not treat every mention as a recommendation.
    • Track whether a relevant page is cited, but inspect whether the citation actually supports the answer.
    • Track factual accuracy separately from visibility. A prominent but incorrect description is not a win.
    • Track referral traffic where it is observable, while acknowledging that some assisted journeys may not pass a usable referrer.
    • Keep paid appearances out of the organic visibility total. Sponsorship, citation, recommendation, and integration are different events.

    The final decision should be channel-specific. Scale a paid format only when delivery, business value, and placement integrity remain acceptable together. Improve organic content when assistants omit the brand, cite weak pages, or repeat stale facts. Escalate a platform issue when the disclosure, rendering, or context differs from what was approved.

    Key takeaways

    • AI assistant advertising is a platform policy, not a universal media category. Confirm that purchasable inventory exists before assigning budget.
    • Claude’s ad-free model still permits user-initiated research and commerce, so organic discoverability remains commercially relevant even where sponsored responses are unavailable.
    • A platform’s total users are not the same as addressable audience, eligible conversations, sponsored impressions, or conversions.
    • Before testing, require clear answers on paid influence, disclosure, context controls, measurement, and economics.
    • Build paid distribution and organic AI visibility as separate programs with separate metrics. Never report a sponsored appearance as an organic recommendation.
    • Accurate pages, explicit qualifiers, aligned JSON-LD, retrievable content, and maintained facts strengthen your eligibility across both ad-supported and ad-free assistants without guaranteeing selection.

    Your next move is practical: create a one-page inventory brief for every assistant ad opportunity, run it through the six gates, and establish an organic prompt-and-citation baseline before the campaign begins. You will then know whether you are buying measurable distribution, improving unpaid eligibility, or merely reacting to a large audience number.

    References

  • Publisher Strategy for Content Markets on the Agentic Web

    Publisher Strategy for Content Markets on the Agentic Web

    An AI agent can use your reporting to answer a question, recommend a product, and help complete a task without sending the user to your page. If your publishing model treats every machine interaction as a future click, you may be assigning value to an event that never happens.

    You do not have to choose between unlimited reuse and disappearing from AI discovery. The practical job is to separate access, interpretation, permission, attribution, and payment. Once those decisions are explicit, you can pursue visibility without quietly giving every commercial use the same terms.

    When the answer performs the task, the traffic bargain weakens

    The agentic web is more than a search box with longer answers. An agent can interpret a person’s intended outcome, gather information, coordinate with other systems, request consent where needed, and take an action. That progression from expressed intent to an outcome changes where publisher content creates value.

    QuestionSearch-led webAgentic webPublisher implication
    What does the user provide?A query to investigateA goal the agent can interpretContent must support decisions, not merely match keywords
    How is information gathered?The user opens and compares pagesThe agent can retrieve and combine relevant materialA page may contribute value without receiving a visit
    Where does the decision happen?Mostly on publisher, merchant, or service pagesPartly inside the agent’s reasoning and recommendation layerQualifications and provenance must survive extraction
    How can an action follow?The user moves between sites and completes each stepThe agent can coordinate systems with the user’s permissionAccurate operational details become as important as persuasive copy
    How can the publisher benefit?Referrals, advertising, subscriptions, leads, or salesThose outcomes may remain, but licensing, attribution, and measured usage can also matterTraffic alone is no longer a complete value model

    The old exchange was easy to understand: a platform discovered a page, displayed a link, and sent some users to it. AI answers can compress that journey. They may rely on a publisher’s work while satisfying the user before a click occurs. That does not make traffic irrelevant. It means traffic, content use, and commercial value can separate.

    Keep these layers distinct in your strategy:

    • Access: Can an agent retrieve the content through a public page, authenticated archive, feed, API, or licensed system?
    • Interpretation: Can it reliably identify the entities, claims, dates, qualifications, and relationships on the page?
    • Permission: What may the operator do with the content, in which products, for which purposes, and for how long?
    • Attribution: Will the output identify the publisher, author, and canonical page in a form the user can follow?
    • Compensation: What event creates payment, how is that event measured, and what reporting lets you verify it?

    A crawl directive addresses access. JSON-LD can improve interpretation. Neither one, by itself, grants a commercial license or establishes a price. A licensing agreement cannot rescue content that is too ambiguous or stale for an agent to use safely. Treating these controls as interchangeable is how publishers either expose too much or block more than they intended.

    The distinction becomes more consequential when agents influence purchases, finance, or healthcare. In those settings, trusted inputs can shape decisions rather than merely inform browsing. If you publish high-stakes material, keep eligibility conditions, uncertainty, audience limits, and safety qualifications adjacent to the claim they modify. A caveat placed several paragraphs away may disappear when an answer system extracts only the central sentence.

    Turn your archive into rights-aware content inventory

    Hands organize articles, photographs, audio, video, and research files into an archive with distinct visual markers for permissions and provenance.

    Do not begin marketplace evaluation with a sitewide yes or no. Begin with an inventory. Most publishing archives contain a mixture of original work, syndicated material, commissioned assets, contributor content, licensed data, outdated pages, and material governed by different agreements. A single technical switch cannot represent those differences.

    Create a rights and readiness ledger at the page or collection level. Record:

    • The canonical URL, content identifier, current version, publication date, and latest substantive update.
    • The publisher, author, contributor, data provider, photographer, illustrator, and any other party whose rights may be involved.
    • Whether the text, images, tables, audio, video, and underlying data can be licensed for the contemplated use.
    • The topic, named entities, geography, audience, and decision context the content supports.
    • The editorial method, evidence trail, and qualifications an agent would need to preserve.
    • The person or team responsible for corrections, expiry decisions, and future updates.
    • The permitted products and uses, prohibited uses, attribution requirements, and withdrawal process.
    • The commercial role of the content: audience acquisition, advertising, subscription retention, lead generation, direct sales, or licensing.

    If a contributor agreement or third-party license does not clearly cover the proposed AI use, stop at that item and get qualified legal review. Marketplace enrollment should not become the event that silently resolves an ambiguous right. The downside can include licensing material you do not control or accepting obligations that conflict with an existing agreement.

    Once the ledger exists, place content into practical access classes:

    • Open for discovery: Public material you want search engines and answer systems to find, summarize within acceptable limits, and cite back to you.
    • Eligible for commercial licensing: Material you control and are willing to provide for defined products, use cases, reporting, attribution, and payment terms.
    • Restricted or excluded: Content with unclear rights, private information, contractual limits, unacceptable substitution risk, unresolved accuracy issues, or no reliable update owner.

    This segmentation lets you test a controlled collection without packaging the entire archive. It also improves negotiation. You can describe what makes a collection distinctive, how it is maintained, which decisions it supports, and what a licensee must do when it changes.

    Length is not a useful proxy for licensing value. A long generic explainer may add little to an agent that already has abundant coverage. A concise specialist archive, original reporting stream, maintained reference set, or decision-grade dataset may be harder to replace. Ask what the content contributes that a model cannot safely infer from generic material.

    Paywalled and secured archives deserve separate attention. High-quality material in those systems may be unavailable to open-web retrieval, which is part of the rationale for licensed access to premium publisher content. That does not mean every paywalled page should be licensed. Compare the potential licensing return with the subscription, exclusivity, and audience value the same material already creates.

    Use a simple value test for each candidate collection. Can you establish the rights? Is the information meaningfully differentiated? Can an agent preserve its important qualifications? Can you keep it current? Would agent use create incremental value, or mainly replace a paid interaction you already own? If you cannot answer those questions, the collection is not ready for pricing.

    Evaluate a content marketplace by its terms and evidence

    Three transparent marketplace mechanisms are inspected side by side for content tracking, attribution, payment, and audit trails.

    Microsoft’s Publisher Content Marketplace offers an early model for a more direct exchange. Its stated design lets publishers set licensing and usage terms, lets AI developers discover content for grounding, and provides usage reporting intended to show how licensed material contributes. The marketplace is also designed to reduce reliance on separate one-off deals.

    Those are useful design principles, but a marketplace description is not the contract you will sign. Participation is presented as voluntary, with publishers retaining ownership and editorial independence. Confirm how each promise appears in the actual agreement, technical controls, reporting fields, and withdrawal procedure.

    Define the licensed use precisely

    The label AI licensing is too broad for a commercial decision. Ask:

    • Does the license cover run-time retrieval and grounding, model training, fine-tuning, evaluation, embeddings, caching, synthetic outputs, or only a defined subset?
    • Can the system use full text, excerpts, facts, media assets, metadata, or structured data? Do different asset types receive different treatment?
    • Which named products, developers, customers, affiliates, or subcontractors can use the material?
    • What territories, languages, audiences, and use cases are included?
    • How long may content and derived representations be retained after an update, withdrawal, or termination?
    • Can rights be sublicensed, bundled, transferred, or used in a product category you would not approve directly?

    Have counsel review the language against your contributor, syndication, data, image, and customer agreements. A marketplace can reduce transaction overhead; it cannot make an overly broad license safe.

    Make attribution and correction operational

    Attribution should be testable, not ceremonial. Specify whether an output displays the publisher name, author where relevant, content date, and a clickable canonical URL. Ask where attribution appears when several publishers contribute to one answer and whether it remains visible when the agent completes a task rather than showing a research-style response.

    Then test the correction path. Who receives a publisher correction? How quickly can an updated version replace the prior one? Are cached passages and generated summaries refreshed? Can the publisher flag a dangerous misrepresentation? What evidence shows that withdrawal reached participating products? These controls matter most for content whose advice changes, expires, or carries material qualifications.

    Interrogate the unit called usage

    A promise of usage-based revenue is incomplete until usage has a definition. It could refer to content retrieval, inclusion in a grounding set, contribution to an answer, a displayed citation, an agent-assisted transaction, or another event. Each unit values the publisher differently.

    Request the reporting schema and a representative record before agreeing to pricing. Determine whether reports identify the content item, version, product, use type, time, geography, citation outcome, and payment calculation. Ask how value is assigned when several items or publishers contribute to the same output. Establish how disputed records, invalid activity, reporting errors, and delayed data are handled.

    Detailed reporting is part of the proposed content-marketplace value exchange. Its usefulness depends on whether you can reconcile the report with your catalog and commercial terms. A total usage number without content-level identity will not tell you which collection deserves more investment, which page needs an update, or whether the payment is correct.

    Protect your ability to change course

    Confirm that you can exclude individual assets or collections, reject sensitive use cases, update prices and terms, correct content, and withdraw future access. Examine exclusivity, renewal, termination, post-termination retention, confidentiality, and conflicts with direct licensing deals. If editorial independence matters, identify the specific contractual and product controls that protect it.

    Early PCM activity included co-design work with Business Insider, Conde Nast, and Hearst, pilots that grounded Microsoft Copilot responses in licensed content, and Yahoo as an early adopter. That demonstrates real industry experimentation. It does not yet establish a universal price, reporting standard, publisher return, or optimal deal structure.

    Use a decision model rather than the size of the marketplace logo. Consider net expected value as licensing revenue, retained audience value, useful market intelligence, and strategic access, minus substitution risk, rights exposure, operational cost, and any value lost from conflicting deals. The expression is an agenda for due diligence, not a precise forecast. If a proposed agreement cannot provide the inputs, that uncertainty belongs in the decision.

    Make content agent-ready without flattening it for machines

    Licensable content can still be difficult to use. An agent needs to determine what a passage claims, which entity it concerns, when it was valid, who stands behind it, and which qualification changes its meaning. Your AEO and GEO work should make those elements easier to identify while preserving the page’s value for a human reader.

    Use this editorial and technical checklist:

    • State the decision-grade answer early. Give the reader the direct answer, rule, or distinction before expanding the reasoning.
    • Attach scope to the claim. Keep audience, geography, version, date, eligibility, and uncertainty in the same sentence or adjacent sentence. Do not strand a critical exception in a distant footnote.
    • Use descriptive headings. A heading should identify the question being resolved, not merely label a broad theme.
    • Expose provenance. Show authorship, editorial ownership, source or methodology information, publication date, substantive update date, and a correction route where appropriate.
    • Name entities consistently. Stable names and identifiers reduce the risk that an agent merges different people, products, organizations, places, or versions.
    • Maintain a canonical identity. Syndicated, translated, updated, and feed versions should point back to a stable record your internal catalog can also recognize.
    • Keep structured data truthful. JSON-LD should describe what is visibly present and should use the most specific accurate type. It should not convert an editorial judgment into a fact or imply an offer the page does not make.
    • Publish corrections as data, not only prose. Update the visible page, version record, feed, API, and licensing catalog so downstream systems do not continue receiving the superseded material.
    • Separate volatile facts from durable analysis. Prices, availability, eligibility, and similar operational facts need a clear update owner; the surrounding explanation can remain stable.
    • Preserve a human reading path. Concise answer blocks are useful, but they should lead into evidence and judgment rather than turn the page into disconnected fragments.

    Apply an extraction test to every important passage. Read the sentence by itself. Can you tell what is being claimed, whom it applies to, when it applies, and what would make it false or unsafe to act on? If the answer changes when the surrounding paragraph disappears, move the necessary qualifier closer.

    Schema helps with interpretation, not truth, authority, access, or permission. A technically valid graph cannot establish that your evidence is sound, that you own every asset, or that an agent has accepted your license. Keep editorial review, rights management, delivery controls, and structured data connected, but do not collapse them into one SEO task.

    Feeds and APIs can give licensed systems a cleaner way to receive content, identifiers, versions, and updates. APIs are also important connective tissue in the agentic environment, where separate systems must coordinate. If you offer a machine-readable delivery surface, document its fields, version behavior, correction process, authentication, permitted uses, and relationship to the canonical page. Delivery access should enforce the agreement rather than leave its boundaries to guesswork.

    Commerce publishers should also distinguish exploration from execution. The Agentic Commerce Protocol focuses on actions arising from express user intent, while the Universal Commerce Protocol addresses the wider shopping experience across platforms and payment systems. They support different stages of the journey rather than serving as simple substitutes. Product content therefore needs to support both evaluation and action: editorial recommendations require evidence and scope, while transactional facts require current, unambiguous fields.

    A brand-owned assistant can provide another route to the same material. It can operate with first-party information, a controlled editorial voice, and a clear point of accountability. That will not eliminate the need to appear in external agents, but it gives loyal users a place to ask questions within an environment you govern. Treat it as owned distribution, not merely a chatbot feature.

    The design tension is real: publishers need content that AI systems can understand without making the human page feel as if it was written for a parser. The answer is not machine-first prose. It is precise prose with visible evidence, stable entities, useful structure, and qualifications that survive reuse.

    Key takeaways for your next licensing decision

    • Separate retrieval, interpretation, permission, attribution, and compensation. Each requires a different control.
    • Inventory rights and update responsibilities before offering an archive. Exclude anything you cannot confidently license or maintain.
    • Segment public discovery content, commercially licensable collections, and restricted material instead of applying one policy to the whole site.
    • Define whether a deal covers grounding, training, caching, generated outputs, or other uses. Do not accept AI use as a sufficient definition.
    • Require content-level reporting that connects a use event to the licensed item, version, product, attribution outcome, and payment calculation.
    • Optimize pages for clear extraction, provenance, freshness, stable identity, and attached qualifications. Do not expect JSON-LD to manufacture authority or grant rights.
    • Preserve correction, exclusion, and withdrawal controls, especially for changing or high-stakes information.
    • Measure licensing revenue alongside referrals, subscriptions, leads, sales, citations, and substitution effects. A single visibility score cannot represent the whole exchange.

    Establish a baseline before making a collection available. Record the referrals, subscriber starts, leads, commerce outcomes, citations, and direct revenue the eligible material already supports. After licensing begins, compare those outcomes with licensed retrieval or grounding activity, attributed mentions, payments, correction latency, and operational cost. Usage reports can help reveal where content contributes value, but only if you can join them to your own content identifiers and business data.

    Do not interpret every decline in referrals as failure if a measured licensing return or higher-value action replaces it. Do not call licensing revenue incremental when the same use displaces subscriptions, direct deals, or profitable visits. Review the collection as a portfolio, then inspect individual items when aggregate results hide winners, stale assets, or damaging substitution.

    Your next move should be a controlled commercial decision, not a sitewide reaction. Choose a collection whose rights, quality, and update process you understand. Define acceptable use, attribution, reporting, correction, payment, and withdrawal before comparing marketplace terms. If a proposal cannot tell you what use occurred, how value was calculated, and how an error can be removed, it is not ready to govern your best content.

    References

  • How to Evaluate Leading AI Software Companies in 2026

    How to Evaluate Leading AI Software Companies in 2026

    If you are shortlisting AI software companies, a generic ranking answers the wrong question. A company can lead at the model layer and still be a poor choice for deploying a governed workflow inside your business.

    Your real task is to identify the kind of company you need, define what leadership means for your use case, and make each candidate prove it with your workflow and representative data. That turns a crowded market into a decision you can defend.

    Start with the job, not the company ranking

    There is no useful universal winner. A packaged AI application, a model provider, a cloud platform, and a custom development company solve different parts of the problem. Ranking them together is like ranking an engine, a delivery van, and a logistics contractor on the same scale.

    Before you collect vendor names, write a short procurement brief. It should be specific enough that another person could recognize a successful deployment without hearing the sales pitch.

    • Workflow: Name the task or decision the software will support. Avoid broad goals such as “use AI for marketing.” A workable definition is closer to “produce a cited first draft from approved product documentation for an editor to review.”
    • Owner: Identify the person accountable for the workflow after launch. A sponsor can approve a purchase, but an operational owner has to manage errors, updates, and user adoption.
    • Inputs: List the documents, databases, messages, images, or application events the system may use. Record where that data lives and who has permission to expose it.
    • Output and action: State what the system produces and what happens next. Distinguish a suggestion shown to a person from an action executed in another system.
    • Failure boundary: Describe acceptable mistakes, unacceptable mistakes, and the point at which a human must intervene. A formatting error and an invented compliance claim cannot share the same severity.
    • Environment: Name the identity system, content repository, analytics stack, customer platform, or other software the product must work with.
    • Evidence: Define what a candidate must demonstrate using representative cases. A polished demonstration using vendor-selected examples is not evidence of fit.
    • Exit conditions: Decide what data, configurations, prompts, evaluation cases, logs, and code you must be able to recover if you change providers.

    If you cannot complete this brief, pause the vendor search. When the outcome is vague, almost any demonstration can look successful, and disagreements about quality appear only after money and integration work have been committed.

    Compare companies that perform the same role

    Four distinct AI software workstations connect to the same central business task for a role-based comparison.

    The label leading AI software development companies can cover businesses with very different products and delivery models. Put each candidate into a functional category before you compare features, pricing, or market visibility.

    Company typeChoose it whenEvidence to requestCommon mismatch
    Model or API providerYour team is building its own application and needs model capabilities as a component.Results on your evaluation cases, usage controls, model-change procedures, latency behavior, and data-handling terms.Buying raw capability when you do not have the engineering or operational team to turn it into a reliable workflow.
    Cloud or data platformYour priority is connecting AI to governed data, existing infrastructure, and enterprise controls.Architecture fit, identity integration, data boundaries, deployment options, monitoring, and portability.Assuming platform breadth means the desired business application is already complete.
    Packaged AI applicationYou need a defined outcome in a familiar function such as content operations, support, analytics, or sales workflow.Workflow coverage, administrator controls, export options, user permissions, integration depth, and evidence from representative tasks.Paying for a broad feature set while the product remains weak at the narrow task that matters.
    Workflow or agent platformYou need AI to coordinate steps, tools, and approvals across systems.Action permissions, state handling, retries, approval gates, audit logs, failure recovery, and limits on autonomous behavior.Treating an impressive prototype as a dependable operational process.
    Custom AI development companyNo packaged product fits the workflow, or your process and data create meaningful differentiation.Proposed architecture, delivery ownership, evaluation method, repository access, documentation, deployment plan, support model, and intellectual-property terms.Commissioning custom software before confirming that the workflow is stable enough to specify and maintain.
    AI operations or governance providerYou already have AI systems and need evaluation, observability, policy enforcement, or control across them.Coverage of your actual stack, alert quality, policy implementation, evidence retention, and response procedures.Expecting a control layer to repair poor application design or unsuitable source data.

    A candidate can belong to more than one category, but you should still name the role you are buying from it. Otherwise, a vendor’s strength in one layer can distract you from a gap in another. If you need a finished application, model quality alone does not settle the decision. If you need a model component, a large catalogue of packaged features may be irrelevant.

    Turn “leading” into pass-or-fail requirements

    Feature counts reward breadth, and weighted scorecards can hide a fatal weakness behind a high total. Use non-negotiable gates first. Score or rank only the companies that pass every gate that protects the workflow.

    • Task performance: The product must produce usable results on ordinary cases, difficult edge cases, and inputs that should trigger refusal or escalation. Define “usable” in terms of the next step in the workflow, not whether the output sounds polished.
    • Evaluation discipline: Ask how the company detects regressions and separates different error types. For generated answers, completeness, factual support, citation quality, format compliance, and harmful fabrication are different dimensions. A blended quality claim can conceal the failure that matters most to you.
    • Data governance: Get written answers about retention, use of customer data for training, storage location, deletion, subprocessors, tenant separation, and access by vendor personnel. Product controls and contract language should agree.
    • Security and human control: Confirm authentication, role-based access, approval steps, auditability, and the ability to stop or override automated actions. The more consequential the action, the less acceptable an invisible decision path becomes.
    • Integration depth: Distinguish a live, supported integration from a demonstration, roadmap item, or generic API. Verify the exact records the system can read, create, update, and export.
    • Operational resilience: Ask what happens when a model, connector, data source, or downstream system fails. A production workflow needs observable errors, safe fallbacks, ownership, and a recovery procedure.
    • Commercial fit: Calculate the cost of the working process, including usage, integration, human review, monitoring, support, and ongoing evaluation. A low software price can still produce an expensive workflow if reviewers must repair most outputs.
    • Exit viability: Confirm that you can retrieve business data and the operational assets needed to continue elsewhere. For custom development, define ownership of code, prompts, configurations, documentation, and deployment materials before work begins.

    Treat unsupported roadmap promises as unavailable. Record each capability as proven, contractually committed, or absent. Those labels keep a persuasive demonstration from turning future intent into present functionality.

    References and customer logos can help you understand where to investigate, but they do not replace workflow evidence. Ask references about deployment effort, failure handling, support after the sale, and what their internal team still has to operate. A similar industry is useful; a similar data shape, risk level, and workflow is better.

    Run a production-shaped proof before you commit

    A business and engineering team observes an AI proof-of-concept moving through security, human review, monitoring, and final delivery stages.

    A proof should test the operating system around the AI, not just the most attractive output. Keep the workflow narrow enough to inspect closely, but preserve the data conditions, permissions, integrations, and review steps that will exist in production.

    1. Freeze the use case. Give every candidate the same workflow definition, input boundaries, expected output, and failure rules. Do not let each vendor redefine success around its strongest feature.
    2. Build the evaluation set. Include routine examples, ambiguous inputs, incomplete information, edge cases, and requests the system should decline or escalate. Keep a portion of the cases out of vendor-led configuration so you can see how the system handles unfamiliar inputs.
    3. Protect sensitive information. Use de-identified or synthetic material until contractual, security, and internal approvals permit representative production data. When real data becomes necessary, expose only what the approved test requires.
    4. Record configuration work. Track the prompts, rules, connectors, data cleanup, and human assistance required to achieve the result. A system that performs well only after extensive hidden preparation may carry a much higher operating cost than the demonstration implies.
    5. Test the whole handoff. Measure whether users can review, correct, approve, reject, and trace the output inside the intended workflow. A strong answer copied manually between applications may still be a weak production solution.
    6. Force recoverable failures. Remove a source, deny a permission, provide conflicting information, or interrupt a downstream service in a controlled test. Check whether the system fails visibly, preserves state, avoids unsafe actions, and gives an operator a clear recovery path.
    7. Review the evidence by error type. Keep a failure log that identifies what went wrong, its consequence, whether a person detected it, and whether the proposed fix is repeatable. Do not average a severe failure into a reassuring overall score.
    8. Price the observed workflow. Use the actual configuration, workload shape, review effort, support requirement, and integration pattern from the proof. Model an increase and decrease in usage so you can see which charges are fixed and which scale with activity.
    9. Test the exit. Export representative data and configuration, inspect its format, and identify what cannot move. For a custom system, verify access to the repository, build instructions, environment configuration, and operating documentation.

    The proof should leave you with artifacts you can inspect later: the frozen evaluation set, result sheet, failure log, data-flow map, architecture diagram, cost model, operating runbook, and exit plan. If the only durable artifact is a presentation, you have evaluated a sales process rather than a production system.

    Reject any company that fails a non-negotiable gate, even if it has the highest total score. Among the survivors, prefer the option that reaches the required outcome with the clearest controls, lowest operational burden, and most credible path out. That is a more useful definition of leadership than size, visibility, or the longest feature list.

    Key takeaways for your shortlist

    • Define the workflow, owner, data, action, failure boundary, evidence, and exit conditions before collecting vendor names.
    • Compare model providers with model providers, applications with applications, and development companies with development companies.
    • Make task performance, data governance, security, operational resilience, economics, and exit viability pass-or-fail gates.
    • Use the same production-shaped evaluation cases for every candidate, and keep severe errors visible instead of burying them in an average.
    • Count configuration, integration, review, monitoring, and support when calculating cost.
    • Choose the company that can prove the required outcome and remain operable when inputs, systems, or providers change.

    Take your current list and write each company’s intended role beside its name. Remove candidates that solve a different layer, send the survivors the same procurement brief, and do not declare a leader until the proof produces evidence your operational owner is willing to accept.

    References

  • Rubric-Based AI Prompting: A Practical Reliability Framework

    Rubric-Based AI Prompting: A Practical Reliability Framework

    The draft looks finished. The structure is clean, the tone is right, and the citations look plausible. Then you check one claim and discover that the evidence is not there. Editing that sentence treats the symptom; the prompt still rewards a complete answer more than a defensible one.

    Rubric-based prompting changes that incentive. You tell the model not only what to produce, but how to decide whether it has enough support, when it may infer, when it must qualify, and when it should stop. That is the difference between requesting a polished deliverable and defining a controlled production process.

    Why polished prompts still fail when information is missing

    A conventional prompt usually describes the destination: write an article, analyze a competitor, summarize a document, or recommend a strategy. It may specify the audience, tone, length, headings, and output format. Those instructions can improve presentation without resolving the most important question: what should the model do when it cannot support part of the requested answer?

    If you request a complete deliverable but provide incomplete evidence, the model faces competing objectives. It can acknowledge the gap and leave part of the task unfinished, or it can produce something fluent enough to resemble completion. Unless you define which objective has priority, fluency can win.

    This matters in content, SEO, AEO, and GEO workflows because unsupported material rarely stays in one draft. A fabricated statistic can migrate into a headline, executive summary, FAQ, metadata, structured data, presentation, or client recommendation. The first error may be a sentence. The operational problem is the chain of assets built from it.

    The downside is not theoretical. In 2025, Deloitte had to refund substantial costs associated with a government report containing AI errors, including fabricated citations. That is an extreme outcome, but it illustrates the basic risk: an authoritative-looking answer can travel farther than its evidence warrants.

    A vague prompt is not the only reason an AI system can be wrong, and no rubric can guarantee truth. Models can misunderstand material, mishandle conflicting evidence, or generate an incorrect answer despite clear instructions. A rubric addresses the preventable part of the problem: ambiguity about evidence, uncertainty, inference, and failure behavior.

    The distinction is simple. A prompt describes what a successful output should contain. A rubric defines the decisions the model must make when success is not fully possible. It replaces requests such as be accurate or do not hallucinate with conditions that can actually govern the response.

    Build the rubric around decisions, not aspirations

    Hands sort abstract document cards through green, amber, and red decision paths for supported, uncertain, and unsupported material.

    An instruction such as use reliable information sounds responsible, but it leaves every operational term undefined. Which information is authorized? What counts as support? May the model draw an inference? Should it omit an unsupported section, qualify it, or ask you a question?

    A useful rubric resolves those choices before generation starts. Build yours around the following decisions.

    1. Define the evidence boundary. Name the material the model may use: supplied documents, approved URLs, a product fact sheet, a transcript, a dataset, or general background knowledge. If freshness matters, state whether information outside the supplied material is prohibited or must be separately verified. Do not use an open-ended phrase such as credible sources when you need a closed evidence set.
    2. Classify claims by support. Tell the model to distinguish facts directly supported by the authorized material from reasonable inferences, unresolved conflicts, and unavailable information. Give each state a visible treatment. A supported fact may be stated normally. An inference should be labeled. A conflict should remain visible. An unavailable claim should be omitted or marked as needing evidence.
    3. Identify material uncertainty. Not every missing detail should stop the task. Define a gap as material when it could change the central claim, recommendation, audience, scope, or risk. The model may proceed with a harmless formatting choice, but it should not quietly invent a product capability, legal requirement, price, quotation, date, or performance result.
    4. Specify the fallback behavior. Decide what should happen when a criterion fails. Your choices include asking a blocking question, returning a partial answer, labeling a provisional assumption, inserting a clear evidence placeholder, or declining the unsupported portion. Without a fallback, even a good accuracy rule leaves the model to improvise.
    5. Set an acceptance test. Describe what must be true before the response is considered complete. For example, every factual claim must map to authorized evidence; every inference must be labeled; every citation must support the adjacent claim; and summaries, FAQs, metadata, and structured fields must not introduce facts absent from the approved material.

    Put these rules in priority order. If accuracy and completeness conflict, say which one wins. If the requested format requires a statistics section but no statistics are available, the rubric should instruct the model to flag the missing evidence instead of manufacturing a plausible number to preserve the format.

    The same principle applies to conflicts among inputs. Do not tell the model merely to resolve discrepancies. Tell it whether to prefer a designated primary record, use the most applicable version, present both positions, or stop and ask. Otherwise, the final answer may hide the disagreement behind confident prose.

    Keep the rubric concise enough to enforce. Repeated rules written in slightly different ways can create new conflicts. Each criterion should contain a trigger, a required action, and a visible outcome. If you cannot tell whether the output passed a criterion, rewrite the criterion.

    A copy-ready rubric for content and SEO workflows

    You do not need to rebuild the framework for every task. Keep a stable core and add task-specific rules only where the risk changes.

    Reusable prompt block

    Place this block after the task, audience, context, and required output format. Replace the bracketed fields with boundaries that match your workflow.

    • Priority: Factual support and transparent uncertainty take precedence over completeness, fluency, tone, and length.
    • Authorized evidence: Use only [approved inputs] for factual claims about [subject]. Do not treat a requested claim as evidence that the claim is true.
    • Supported claims: State a factual claim only when the authorized evidence supports that specific wording and scope. Do not broaden a narrow claim.
    • Inferences: You may infer only when the conclusion follows reasonably from the evidence and does not introduce a new factual detail. Label the conclusion as an inference and identify the evidence behind it.
    • Missing or conflicting information: Do not invent names, numbers, dates, quotations, citations, URLs, capabilities, examples presented as real, or research findings. Mark unsupported items as [preferred label]. Preserve material conflicts instead of silently choosing a side.
    • Clarification rule: Ask a blocking question before drafting when the missing information could change the central claim, recommendation, audience, scope, or risk. Otherwise, continue and record the limitation.
    • Final check: Before returning the answer, remove or label every unsupported claim, confirm that each citation supports the claim beside it, and confirm that derivative sections introduce no new facts.
    • Response: Return the requested deliverable followed by a short exception log containing material omissions, labeled inferences, unresolved conflicts, and blocking questions. Do not return hidden reasoning or a generic assurance that the answer is accurate.

    The exception log is important because it makes failure visible without requiring you to inspect the model’s internal reasoning. If the log is empty but the draft contains unsourced specifics, the output has failed the rubric.

    Worked example: an evidence-controlled content brief

    Suppose you ask AI to create an AEO-focused brief from an approved product fact sheet, a set of customer questions, and selected reference pages. A normal prompt may request key claims, search intent, supporting statistics, FAQs, and suggested structured content. The format is clear, but the evidence rules are not.

    Add task-specific criteria such as these:

    • Use the approved packet for every product claim, date, number, quotation, comparison, and attributed statement.
    • Do not invent search volume, ranking difficulty, trend data, customer stories, survey findings, product limitations, or competitor capabilities.
    • Separate evidence-backed audience questions from editorial questions proposed for further research. Do not present a suggested question as observed search behavior.
    • Separate factual claims from recommendations about page structure. A heading recommendation does not need to masquerade as a fact about the market.
    • Create a claim register that pairs each publishable factual claim with the item that supports it. If no item supports the claim, label it Needs evidence.
    • Apply the same evidence boundary to the summary, FAQ, metadata, and any structured fields. Changing the format does not authorize a new claim.
    • Return blocking questions before the brief when missing information would change the page’s audience, core promise, or factual position.

    This version still lets the model help with organization and editorial planning. It removes permission to imitate missing research. That distinction prevents a common failure: treating the model’s familiarity with the shape of an SEO brief as evidence for the facts inside it.

    Test the rubric with deliberately incomplete input. Remove the support for a requested statistic, product claim, or quotation while leaving the request in place. A passing response should flag the gap, ask a material question, or omit the unsupported item according to your rule. If it produces a plausible replacement, tighten the evidence boundary and failure action before using the prompt in an automated workflow.

    Review the output with a separate acceptance rubric

    A separate reviewer checks an AI-produced manuscript against evidence tokens and sets one questionable fragment aside.

    The generation rubric controls how the draft should be produced. An acceptance rubric controls whether that draft can move forward. Separating the two prevents a polished response from being treated as approved merely because it followed the requested structure.

    Use clear statuses such as pass, revise, and block. A numeric score can hide a serious defect inside an acceptable average. One fabricated citation should block publication even if the tone, organization, and formatting are excellent.

    CriterionPass conditionFailure action
    Evidence coverageEvery externally verifiable factual claim is traceable to an authorized input or visibly labeled as an inference.Remove the claim, add appropriate evidence, or change its status.
    Citation fitEach citation exists and supports the exact claim, scope, and qualification beside it.Replace the citation, narrow the wording, or block the claim.
    Uncertainty handlingMaterial gaps and conflicts remain visible; low-impact assumptions are identified where relevant.Add a qualification, request clarification, or return the item for research.
    Instruction priorityThe output meets the task without violating higher-priority evidence and uncertainty rules.Revise the deliverable instead of waiving the higher-priority rule.
    Claim propagationSummaries, FAQs, metadata, and structured fields contain no unsupported facts copied from or added to the main draft.Remove the derivative claim or supply support before publishing.
    Exception logMaterial omissions, inferences, conflicts, and questions are specific enough for a reviewer to resolve.Replace generic caveats with the affected claim, missing input, and required next action.

    You can ask the model to apply this acceptance rubric to its own output, but treat that as a consistency check, not independent verification. The same system that generated an unsupported claim can overlook it during self-evaluation. A person should still open important citations, compare claims with the underlying material, and review conclusions that affect money, legal exposure, health, reputation, or publication under someone else’s name.

    When a rubric performs badly, the pattern usually points to the missing rule:

    • The answer is fluent but contains invented specifics. The evidence boundary is open-ended, or unsupported claims have no mandatory failure action.
    • The model refuses to complete useful work. The rubric treats every uncertainty as blocking. Define which inferences and low-impact assumptions are allowed.
    • The answer is buried in caveats. The rubric does not distinguish material uncertainty from details that do not affect the outcome. Add a materiality test.
    • The citations look correct but do not support the claims. The rubric checks citation presence rather than citation fit. Require support for the exact adjacent statement.
    • Different sections contradict one another. The rubric evaluates local sentences but not the deliverable as a whole. Add a cross-section consistency check.
    • The model follows some rules and ignores others. The rubric is probably too long, repetitive, or internally conflicted. Remove overlap and state the priority order.
    • The self-review always passes. The acceptance criteria are subjective, or the same model is being treated as an independent reviewer. Replace impressions such as high quality with observable pass conditions and retain human verification where the consequence warrants it.

    A rubric does not replace retrieval, source selection, subject-matter expertise, or fact-checking. It governs what the model should do with the information and uncertainty it has. That narrower role is still valuable because it makes incomplete evidence visible before fluent prose conceals it.

    Key takeaways

    • A standard prompt defines the deliverable; a rubric defines how the model must behave when evidence is missing, conflicting, or insufficient.
    • Prioritize factual support over completeness explicitly. Otherwise, a request for a finished answer can compete with the instruction to avoid unsupported claims.
    • Every criterion needs a trigger, required action, and visible outcome. Be accurate is a goal, not an enforceable rule.
    • Define allowed evidence, labeled inference, material uncertainty, clarification conditions, and failure behavior before generating the draft.
    • Use a separate acceptance rubric for publication. Self-review can improve consistency, but it is not independent factual verification.

    Start with one prompt you already use. Add an evidence boundary, an uncertainty classification, a stop condition, and an acceptance check. Then test it against incomplete or conflicting input. If the model fills a gap you expected it to expose, revise the decision rule before you scale the workflow. The useful rubric is not the one that sounds strict; it is the one that produces the correct behavior when the easy answer is unavailable.

    References

  • How to Plan Conversational AI and Social Ad Budgets

    How to Plan Conversational AI and Social Ad Budgets

    You have one experimental budget and three names in the room: Threads, ChatGPT, and Gemini. Calling all three emerging ad opportunities hides the decision that matters. What can you buy, what can you measure, and what job should each surface do?

    Start with the buying mechanics. Threads can enter Meta’s established campaign workflow. Early ChatGPT inventory is a controlled, impression-based buy. Gemini has no paid placement under Google’s announced stance. Once you separate those models, the budget decision becomes much easier.

    Separate the opportunity into three different ad markets

    Conversational AI and social feeds may compete for the same experimental budget, but they do not sell the same product. One sells feed distribution through a mature advertising system. Another is testing sponsored exposure beside a generated answer. The third is withholding ads while it develops the assistant.

    SurfaceWhat advertisers can accessWhat that means for your plan
    ThreadsGlobal advertiser access, a rollout to users worldwide, Advantage+ campaign expansion, and image, video, and carousel formats. Campaigns can be managed within the wider Meta environment used for Facebook, Instagram, and WhatsApp.Treat it as a paid-social placement test. Use familiar campaign objectives, but require placement-level reporting before claiming that Threads caused the result.
    ChatGPTSelected-advertiser testing with impression-based pricing, initial advertiser commitments below $1 million, and no self-service buying. Sponsored units are placed at the bottom of responses and separated from the organic answer.Treat it as controlled innovation inventory. It may support reach, learning, and brand objectives before it can support a conventional performance case.
    GeminiNo planned ad product under the stated 2026 position. Google is prioritizing assistant quality, usefulness, and trust before monetization.Do not put Gemini impressions in a paid-media forecast. Keep it in your organic AI visibility program and on a product-monitoring list.

    Availability is the first gate, not the final reason to spend. Threads has a reported user base of more than 400 million, but that figure describes platform scale rather than the reach available to your account. Meta also indicated that delivery would begin modestly. Your forecast should therefore come from the inventory and placement estimates available during campaign setup, not from the platform-wide audience number.

    ChatGPT presents the opposite planning problem. A conversation can reveal strong intent, but impression-based billing does not prove that the user noticed the sponsored unit, asked about it, visited the advertiser, or converted. Pricing tells you what triggers the charge. It does not tell you whether the exposure worked.

    Key takeaways

    • Classify each opportunity by buying model and reporting capability before comparing audience size.
    • Use Threads as an additional paid-social placement, not as a proxy for conversational intent.
    • Use early ChatGPT inventory for an impression-led learning objective unless the buying agreement supplies stronger outcome measurement.
    • Keep Gemini out of paid-media budgets until an actual ad product defines access, formats, billing, reporting, and controls.
    • Report paid conversational exposure separately from organic mentions and citations in AI answers.

    Give each surface one job before you fund it

    A new placement becomes expensive when it is asked to prove everything at once. If the same test is supposed to create awareness, generate leads, establish brand safety, and teach you how the format works, almost any result can be rationalized after the fact. Assign one decision question to each surface before approving spend.

    Threads: test incremental paid-social distribution

    Threads is the most operationally familiar option because Meta can streamline campaign expansion through Advantage+. That convenience can also obscure what happened. A blended Meta result cannot tell you whether Threads earned its share of the budget unless your reporting isolates delivery and outcomes for that placement.

    1. Write one hypothesis. For example, test whether a specific audience and creative concept can produce acceptable traffic or conversion quality on Threads. Do not use a vague objective such as learning the platform.
    2. Select one primary outcome. Choose reach, traffic, leads, sales, or another campaign objective supported by your setup. Keep secondary metrics diagnostic rather than treating every metric as a success condition.
    3. Confirm placement visibility. Before launch, verify that your reporting can show Threads delivery, spend, and the outcome tied to your objective. If it cannot, treat the campaign as a broader Meta test rather than a Threads test.
    4. Control the creative comparison. Carry one existing paid-social concept into the test and pair it with one Threads-specific variation. Hold the offer and audience as steady as your controls permit so that the creative difference remains interpretable.
    5. Predefine the decision rule. Set the acceptable result from your own paid-social benchmark before seeing the data. Record what would justify scaling, revising creative, or stopping.

    Modest early delivery may reflect limited inventory rather than a failed message. Do not judge creative after a handful of impressions, but do not wait indefinitely either. Evaluate once the placement has delivered enough exposure for the metric in your prewritten rule, and document underdelivery as a separate finding.

    ChatGPT: buy access only when the learning is worth the ambiguity

    Do not copy a paid-search brief into ChatGPT. The user may be expressing a need in the conversation, but the initial commercial model emphasizes impressions and offers limited conventional performance reporting. That makes the first tests better suited to advertisers that can value exposure and format learning without manufacturing a direct-response conclusion.

    Access is itself a qualification step. Initial testing involves selected advertisers, spending below $1 million per advertiser, without a self-service interface. The announced audience configuration places ads in free access and the $8-per-month ChatGPT Go tier, while Plus, Pro, and Enterprise remain ad-free for the time being. Your buying brief should identify the audience you can actually reach rather than referring to ChatGPT users as one undifferentiated group.

    Get written answers to these questions before approving an insertion order or equivalent commitment:

    • What event counts as a billable impression, and which impression fields appear in reporting?
    • Which account tiers, geographies, devices, and conversation contexts are eligible?
    • Can the unit link to a destination, and how are clicks or other interactions defined?
    • Are reach, frequency, and repeat exposure available, or will you receive only aggregate impressions?
    • Can follow-up questions about the sponsored product be measured, and are they reported in aggregate without exposing private conversation content?
    • Which category exclusions, adjacency controls, and remediation procedures apply?
    • Can campaign data be exported for reconciliation with your analytics and customer systems?

    If those answers do not support your normal acquisition model, label the spend correctly: a brand and product-learning test. Do not place a cost-per-acquisition target in the approval document and then excuse its absence because the format is new.

    Gemini: define the trigger for reconsideration

    A no-ad position is not the same as a permanent ban, but it is enough to make the current budget decision. Google leadership has ruled out Gemini ads for 2026 under the stated plan, citing the need to protect helpfulness and trust.

    Do not reserve speculative Gemini media money merely to appear prepared. Put the surface on a watchlist with five activation triggers: buyer access, eligible audience, ad format, billing method, and reporting controls. Until all five are defined, the paid-media row should remain unavailable rather than carrying an invented forecast. Your organic work for Gemini belongs in a different plan and can continue without waiting for an ad product.

    Build a measurement contract before the campaign

    Two analysts examine an abstract advertising journey that passes through a series of measurement checkpoints from impression to conversion.

    The measurement plan should be short enough to read in one meeting and strict enough to prevent a weak result from being renamed a success. For every test, record the business question, the primary metric, supporting diagnostics, disqualifying conditions, evaluation window, data owner, and decision owner.

    Use a four-level measurement ladder:

    1. Delivery: Record spend, billable impressions, placement share, and reach or frequency when provided. Reconcile the purchased amount with the platform report before interpreting response.
    2. Observable response: Track clicks, destination sessions, or another defined interaction only when the format supports it. State exactly what the platform counts rather than assuming that similarly named metrics are equivalent.
    3. Business outcome: Connect qualified leads, purchases, or other approved outcomes through your normal analytics process. Separate directly observed conversions from modeled or assisted attribution.
    4. Incrementality: When the buying system and budget permit, use a holdout or controlled split to test whether the advertising changed behavior. Without a control, label changes in branded demand or direct traffic as directional rather than causal.

    For Threads, the crucial diagnostic is placement-level delivery. A campaign that performed well across Meta does not establish that Threads worked if Facebook or Instagram delivered most of the impressions. Compare the Threads result with the benchmark chosen before launch, and keep differences in audience, creative, and optimization settings visible.

    For ChatGPT, the minimum evidence is verified delivery under the contracted impression definition. OpenAI has indicated that follow-up questions about sponsored products could become an engagement signal, but that possibility is not a current performance guarantee. Do not make a future field the cornerstone of today’s business case. If follow-up reporting becomes available, document its definition, privacy treatment, and relationship to downstream action before using it as a KPI.

    Do not compare raw click-through rates across a feed ad and a unit beneath an AI answer as if the interfaces were interchangeable. Position, user task, billing, and available actions all differ. Compare each surface with the goal and benchmark assigned to that surface. Then compare investment decisions using business value and confidence in the evidence.

    Make trust and brand safety part of campaign acceptance

    A transparent safety gateway filters a sponsored content tile before it enters a field of conversational speech bubbles.

    An ad beside a generated answer carries a different trust burden from an ad in a familiar feed. The assistant is responding directly to the user’s words, so commercial influence can be mistaken for neutral help unless the boundary is obvious. Google’s reluctance to monetize Gemini reflects concern that advertising could compromise unbiased recommendations and user trust. OpenAI’s initial design addresses the same tension by marking sponsored units and separating them at the bottom of responses.

    Turn that principle into acceptance criteria. Before launch:

    • Review the actual unit or a faithful preview and confirm that the sponsorship label is visible without extra interaction.
    • Reject creative that imitates the assistant’s voice or implies that the organic answer endorsed the advertiser.
    • Check that every factual claim in the ad is supported on the destination page and remains accurate when removed from the surrounding conversation.
    • Document prohibited adjacencies, sensitive categories, escalation contacts, and the remedy available after an unsuitable placement.
    • Capture a dated preview or screenshot with the approved copy, destination, disclosure, and platform version so later changes can be audited.
    • For regulated or high-consequence claims, route the complete placement context through the appropriate legal or compliance review rather than submitting isolated ad copy.

    Threads offers a more familiar control layer. Meta is extending third-party brand-safety verification used on Facebook and Instagram to Threads. Confirm which verification provider, report, market, and placement your campaign can use. The existence of a verification program does not prove that it covers every impression in your specific setup.

    A trust failure also damages measurement. If users cannot tell whether a recommendation is paid, engagement may reflect mistaken endorsement rather than persuasive advertising. A high interaction count under that ambiguity is not a clean signal to scale.

    Keep paid exposure separate from organic AI visibility

    Your reporting should have three lanes: paid social distribution, paid conversational exposure, and organic AI visibility. Combining them in one AI channel bucket makes every number harder to interpret.

    • Paid social distribution: Put Threads spend, impressions, placement delivery, response, and conversions here.
    • Paid conversational exposure: Put ChatGPT sponsored impressions and any defined ad interactions here. Keep the sponsorship label and placement type in the campaign record.
    • Organic AI visibility: Track whether assistants mention or cite the brand for a maintained set of relevant questions. Record the model, access tier, prompt, answer date, cited destination, and repeated observations because generated answers can vary.

    A sponsored unit beneath a ChatGPT response does not mean the brand appeared in the organic answer. An organic Gemini citation is not paid delivery. Threads reach does not establish visibility in an AI assistant. Preserve those distinctions in campaign names, analytics dimensions, dashboards, and executive reporting.

    The same boundary applies to technical optimization. JSON-LD, schema, clear entity information, and answer-focused content can be evaluated as parts of organic discovery, but the available ad plans do not establish them as levers for ChatGPT ad eligibility, Threads delivery, or a future Gemini auction. Give structured-data work its own validation and visibility objectives instead of attributing paid-media effects to it.

    At your next budget meeting, create one row for each surface and fill in four fields: whether it is buyable, the single question the spend will answer, the evidence the platform can return, and the event that would unlock more budget. Fund Threads when you have a paid-social question and placement-level measurement. Fund ChatGPT when impression-led learning is valuable enough to justify limited performance evidence. Leave Gemini out of the paid forecast until a real product changes the decision. The useful early move is not simply being first; it is knowing what the first test must prove before you buy the second.

    References

  • Emerging AI Ads and Remarketing for Small Audiences

    Emerging AI Ads and Remarketing for Small Audiences

    If your site attracts hundreds rather than thousands of qualified visitors, remarketing has often stalled before you could test the creative. The audience simply was not large enough to use. That barrier is now lower, while ads inside AI-generated answers are moving from an idea toward a possible new acquisition channel.

    You do not need to choose between them. Build a focused small-audience remarketing system now, then prepare the same messages, evidence, landing pages, and measurement rules for emerging AI inventory. You will have a working campaign instead of a speculative media plan, and you will be ready to test AI ads if a usable format becomes available.

    Key takeaways

    • Google Ads now permits eligible audience segments with as few as 100 active users across Search, Display, and YouTube, including remarketing and customer lists.
    • The 100-user requirement is an eligibility threshold, not a promise of reach, efficient delivery, or statistically reliable results.
    • OpenAI’s possible ad formats, including placements within AI-generated responses, remain preliminary. Treat them as a readiness track rather than available inventory.
    • Small advertisers should consolidate visitors by meaningful intent before creating narrow demographic or behavioral subdivisions.
    • A future AI ad should feed the same first-party journey as any other acquisition channel: a relevant landing page, a consent-aware audience rule, a useful follow-up message, and a measurable conversion.

    Make the 100-user threshold useful, not merely reachable

    A focused cluster of glowing audience tokens is surrounded by three ad cards and connected to a landing-page frame.

    Google’s lower minimum removes a real operational barrier. Remarketing lists and customer lists can now become eligible from 100 active users across Search, Display, and YouTube. Audience Insights also uses a 100-user threshold instead of the previous 1,000-user requirement, giving smaller accounts access to audience analysis earlier.

    Do not confuse eligibility with scale. A qualifying list can still produce limited delivery because campaign reach also depends on active membership, matchability, targeting, geography, auction conditions, budget, and whether those users return to an environment where your ads can serve. The threshold tells you that a campaign may participate. It does not tell you how much it will spend or whether it will perform.

    This distinction should change how you segment. A smaller advertiser rarely benefits from dividing an already small pool into many audiences based on every page, device, location, and content category. Each split reduces usable reach and makes the resulting performance rates harder to interpret. Start with a few pools whose members need meaningfully different messages.

    Audience poolUseful signalJob of the follow-up adWhat not to mix into it
    High-intent visitorsA visit to pricing, booking, quote, demo, cart, or another commercial action pageResolve the last important objection and return the person to the unfinished decisionCasual readers who have not shown commercial intent
    Consideration visitorsVisits to product, service, comparison, use-case, or evidence pagesClarify fit, differentiation, or proof before presenting the next stepEvery visitor to the site merely to increase list size
    Content visitorsEngagement with a guide, tool, tutorial, or problem-specific resourceContinue the same subject with a relevant resource or appropriate offerA generic sales message unrelated to the content consumed
    Known customersA customer list you have the right to useSupport a relevant renewal, replenishment, retention, or complementary purchase journeyProspects added only to make the audience appear larger

    Keep customers and prospects separate even when combining them would help you reach 100 users. They have different relationships with you, different reasons to respond, and often different conversion goals. An audience large enough to activate but too mixed to address coherently is not an improvement.

    Use Audience Insights to check whether a pool resembles the audience definition you intended. Do not turn a small set of aggregate characteristics into an elaborate persona. Ask campaign questions instead: Does this group reflect the intended stage of the decision? Is an important market missing? Does the evidence justify changing the message or landing page? Those questions produce actions; a long list of audience traits often does not.

    Build the smallest complete remarketing campaign

    Accessible remarketing does not mean creating a campaign for every available audience. It means building one complete path from a recognizable intent signal to a useful follow-up and a measurable result. Use this sequence.

    1. Name the decision you want to recover. Examples include completing a quote request, returning to a product evaluation, booking a consultation, or finishing a purchase. Choose one primary conversion so the campaign has a clear job.
    2. Write the inclusion rule in plain language. State which page, event, or first-party list makes someone appropriate for the message. If you cannot explain why every member belongs, the audience is too broad.
    3. Add exclusions before launch. Exclude people who already completed the campaign’s goal when further acquisition ads would be irrelevant. If existing customers need another message, place them in a customer journey rather than leaving them in a prospect campaign.
    4. Consolidate before subdividing. Combine signals that reflect the same intent and need the same follow-up. Split an audience only when the new group warrants different creative, a different destination, or a different business objective.
    5. Check consent and data rights. Use site data and customer information only when you have the right to collect, upload, and use it under applicable law and platform policy. A lower platform threshold does not relax privacy obligations. Do not fill a list with scraped or purchased contacts.
    6. Match the message to the interrupted decision. Someone who left a pricing page needs help evaluating value, terms, or fit. Someone who read an educational guide may need the next useful resource. Repeating your broad brand slogan ignores the information you already have.
    7. Continue the journey on the landing page. Send the visitor to the page that answers the promise in the ad. Routing every click to the homepage forces the person to reconstruct a journey you already understood well enough to target.
    8. Predefine the measurement rule. Record the primary conversion, conversion quality check, campaign cost, and the condition that would justify continuing, changing, or stopping the campaign. Set spending limits from your own margins and acceptable acquisition economics, not from a platform recommendation alone.
    9. Change one meaningful lever at a time. Test a message, offer, audience definition, or destination against a stated hypothesis. Simultaneous changes may improve the campaign, but they will not tell you which decision caused the improvement.

    Keep a simple campaign record containing the audience name, inclusion signal, exclusions, creative promise, landing page, primary conversion, and owner. Use names that expose the logic, such as high-intent pricing visitors, rather than labels such as audience A. Clear naming matters when a small account begins adding channels and the original rationale is no longer fresh.

    Small audiences also require restraint in reporting. Look first at actual conversions, conversion quality, total cost, and whether the intended people reached the intended page. Percentages can move sharply when the underlying counts are small. A striking click-through or conversion rate is not enough to scale a campaign whose absolute result is still inconclusive.

    Prepare for ads inside AI answers without inventing the channel

    Unlabeled campaign assets are arranged toward an empty translucent AI conversation panel beside a glowing remarketing loop.

    OpenAI is exploring an advertising model, with early discussions involving media partnerships and ads that could appear within AI-generated responses. The work is still at a preliminary stage. There is no responsible basis yet for assuming a particular buying interface, targeting method, auction, reporting model, creative limit, or remarketing capability.

    You can still prepare for the distinctive part of the opportunity: the ad may meet a person while they are asking a detailed question, comparing options, or trying to complete a task. That is different from classic remarketing. Remarketing starts with a known prior interaction. An ad inside an AI response could start with the immediate context of a conversation, even when the person has never visited your site.

    High context does not automatically mean high purchase intent. A detailed question may be informational, exploratory, or commercial. Your preparation should therefore begin with the question and its decision stage, not with a generic assumption that every AI user is ready to buy.

    Create a question-to-offer record

    For each commercially relevant question cluster, record the user’s likely task, the direct answer they need, the condition under which your offer fits, the condition under which it does not, the evidence supporting your claim, the appropriate call to action, and the landing page that continues the answer. This becomes a reusable brief for paid AI placements, conventional search ads, landing-page copy, and answer-engine optimization.

    The disqualifying condition is important. An AI-mediated interaction can expose vague claims quickly because the surrounding answer may discuss alternatives and tradeoffs. Copy that states who an offer is for, what problem it solves, and where its limits begin is more useful than an unsupported superlative.

    Make the destination understandable to people and machines

    Keep brand, product, service, location, availability, eligibility, and offer details consistent across the ad candidate, visible page copy, and structured data where applicable. JSON-LD should describe what a visitor can verify on the page. Do not place stronger claims in schema than you are willing to show in the content.

    Use descriptive headings, direct answers, explicit entity names, accessible evidence, and a clear next action. Structured data can reduce ambiguity about page entities, but it does not guarantee an organic AI citation, a recommendation, or eligibility for a future paid placement. Treat it as accurate machine-readable context, not a shortcut around relevance or trust.

    Prepare modular creative instead of guessing the format

    Store each message as separate components: the user’s question, a concise answer, the commercial claim, its substantiation, a qualification, the call to action, and the destination. Once an actual ad format is documented, you can adapt those components to its limits. Writing to imagined character counts or unsupported placement rules now creates rework without making you more prepared.

    Plan for clear sponsorship rather than copy that imitates an impartial model response. Ads embedded near generated answers will depend heavily on user trust. A message should identify the commercial offer, preserve the distinction between paid placement and generated guidance, and avoid implying that the AI independently endorsed the advertiser.

    Connect future AI discovery to remarketing you control

    If a future AI ad sends a person to your site, treat that placement as an acquisition source, not as a replacement for your customer journey. The click should reach a question-specific page. A meaningful, consent-aware site interaction can then place the visitor into the appropriate first-party audience. Remarketing can continue the decision later if the audience qualifies and the follow-up remains relevant.

    Set up the handoff before the new channel arrives. Reserve a distinct source name for paid AI traffic, keep paid and organic AI referrals separate, define the on-site event that represents meaningful intent, document which remarketing audience receives that event, and suppress people after they complete the goal. Without that separation, you may attribute an organic AI visit to paid media, count the same conversion in conflicting reports, or keep advertising an action the customer already completed.

    Require answers before moving budget

    Do not divert dependable campaign budget merely because an AI company is discussing advertising. Wait until the inventory exists and you can answer practical buying questions:

    • Where can the ad appear, and how is it labeled to the user?
    • Which contextual, audience, geographic, and exclusion controls are actually available?
    • What event determines billing and optimization?
    • Can paid AI visits be identified reliably in your analytics?
    • Which conversion signals can be returned to the platform, and under what data terms?
    • What reporting distinguishes exposure, engagement, site visits, and conversions?
    • Which brand-safety, suitability, and placement controls protect you from appearing beside an inappropriate answer?

    Once those questions have documented answers, frame the first spend as an experiment with a hypothesis, audience context, message, destination, primary outcome, and cost limit. Judge it against your business economics and conversion quality. Do not treat novelty, impressions, or a high engagement rate as proof that the channel creates profitable demand.

    Your immediate move is smaller and more useful: choose the highest-intent audience that can clear 100 active users, write the objection its ad must resolve, and send people back to the exact page where they can continue. Then complete a question-to-offer record for the AI use case most closely tied to that decision. When AI inventory becomes buyable, you will have a relevant message, a truthful destination, and a measurement system ready for a controlled test.

    References

  • How to Build an AI-Driven Paid Search Operating Model

    How to Build an AI-Driven Paid Search Operating Model

    You can automate nearly every visible part of paid search and still make the account worse. AI will produce more copy, audience ideas, campaign variants, and reports than your team can review. If the underlying intent signal is weak, that extra output simply scales waste.

    A useful AI-driven operating model does something more disciplined. It converts conversational intent into campaign decisions, accelerates controlled creative testing, aligns each promise with the destination page, and measures whether the resulting customers are actually worth more.

    Start with the decision behind the search

    A conventional search query often captures only a fragment of the buyer’s situation. A conversation can expose the goal, constraints, comparison criteria, objections, and urgency surrounding that query. Conversational search can also create multiple relevant advertising opportunities from a detailed exchange as the user’s needs become clearer.

    Do not respond by treating entire conversations as a larger keyword list. Convert the context into an intent record your campaign team can use:

    • Situation: What is happening in the buyer’s world?
    • Desired outcome: What are they trying to accomplish?
    • Constraints: Which limits involve budget, timing, compatibility, location, policy, or skill?
    • Decision state: Are they exploring, comparing, validating, or ready to act?
    • Objection: What could prevent the next step?
    • Required proof: Do they need specifications, pricing, evidence, credentials, availability, or reassurance?
    • Next useful action: Which conversion would genuinely help them progress?

    Suppose a prospective student searches for an online master’s degree. That phrase gives you a category. A fuller interaction might reveal that the person works full time, needs a recognized credential, is comparing total cost, and cannot attend daytime classes. Those details should change the ad message, landing-page evidence, audience treatment, and conversion action. Repeating the broad phrase more often will not do that.

    Organize campaigns around the decision state as well as the topic. Exploratory demand needs orientation. Comparison demand needs explicit differences and trade-offs. Validation demand needs proof. Action-ready demand needs a clear offer and minimal friction. The journey will not always be linear, but these distinctions stop you from serving the same generic promise to everyone.

    Begin with search terms that converted, consumed spend without producing qualified outcomes, or repeatedly triggered exclusions. Rewrite each meaningful cluster as an intent record. If you cannot identify the likely decision, constraint, and next action, the cluster is still too vague for AI-generated personalization.

    Build a controlled path from AI insight to campaign

    Abstract conversational signals move through a series of human-controlled review gates before becoming organized campaign components and matching destination pages.

    The safest workflow gives AI a narrow responsibility at each stage. It also preserves a reviewable record of why an audience, message, or destination was chosen.

    1. Define the business outcome. Name the event that creates value: a completed sale, qualified lead, accepted application, booked consultation, or another verified result. Do this before generating assets.
    2. Assemble the permitted context. Supply the offer, landing-page copy, approved claims, exclusions, brand rules, past campaign outcomes, and known audience questions. Remove personally identifying information and use only data you are authorized to process.
    3. Classify demand by decision logic. Ask AI to group queries or themes by situation, desired outcome, constraint, objection, and decision state. Require it to flag ambiguity instead of forcing every input into a confident category.
    4. Turn each intent group into a campaign brief. Specify the audience problem, promise, proof, prohibited claims, destination, conversion action, and measurement rule.
    5. Generate bounded variations. Let AI vary a defined element such as the benefit, proof point, call to action, visual treatment, or voice. Do not ask it to redesign the audience, offer, message, and destination simultaneously.
    6. Validate the destination. Confirm that the landing page visibly supports the ad’s promise and that its structured data accurately describes the same entities, offer details, and attributes.
    7. Launch with a budget ceiling and rollback condition. Record the baseline, approved spend limit, primary outcome, diagnostic metrics, and the condition that will pause or reverse the change.

    A reusable generation brief can stay compact: Audience situation: [context]. Decision state: [state]. Promise: [approved benefit]. Proof: [page-supported evidence]. Variable to test: [single element]. Prohibited claims: [limits]. Destination: [matching page]. Primary outcome: [qualified business event].

    Structured data belongs in this workflow, but it is not advertising code and cannot rescue a weak offer. Its role is to make the page’s meaning more explicit. The visible page, markup, ad, and conversion action should describe the same thing. If eligibility, availability, or a limitation matters to the decision, put it in the visible content rather than hiding it only in markup.

    Use the same intent labels across paid search, paid social, creative production, landing pages, and reporting. Shared labels let you see whether a message works because it addresses a particular decision or merely because one channel received cheaper traffic.

    Use generative AI to multiply tests, not brand risk

    An AI system generates many abstract creative variants while a human reviewer filters them before selected versions proceed to matching landing pages.

    Generative tools can shorten the path from a script to storyboards, creative variations, voiceovers, and localized executions. They can also help maintain tone and pacing across repeated production work. That is production leverage, not evidence that the resulting creative will persuade anyone.

    The common failure is to generate many variations without giving each variation a job. The account receives more ads, but the team learns less because several elements changed together. A disciplined test should follow these rules:

    • Ask one commercial question at a time, such as whether proof-led copy produces more qualified actions than convenience-led copy.
    • Keep the offer, audience definition, destination, and conversion action fixed unless one of them is the stated variable.
    • Generate within approved claims and brand rules. Require human review for prices, guarantees, comparisons, regulated language, eligibility, and culturally sensitive material.
    • Name every asset by intent group, hypothesis, variable, and version so the result can be traced to the brief that created it.
    • Use engagement as a diagnostic signal, not the final verdict. A stronger click-through rate with weaker lead quality is not a win.
    • Record what the result changes. If either outcome would lead to the same campaign decision, the test is not answering a useful question.

    Write a test brief that another person can audit

    Before production, document the hypothesis, target intent, fixed elements, test variable, primary business outcome, secondary diagnostics, observation window, exclusions, and decision rule. The observation window and decision rule should reflect your normal conversion lag and traffic volume; choosing them after seeing performance invites a convenient interpretation.

    AI-assisted analytics can connect creative features with engagement patterns quickly, but correlation does not establish which feature caused the result. Use those patterns to form the next controlled test. Do not let a dashboard turn visual coincidence into a budget decision.

    Personalization also has a boundary. When targeting Gen Z, utility and authenticity are especially important. Personalize around the need the person expressed, not around a surprising personal detail inferred from unrelated behavior. An ad can be technically relevant and still feel invasive.

    Measure whether AI improves the unit economics

    Microsoft has reported a thirteen-fold increase in return on ad spend when people interacted with Copilot before searching. Treat that as a platform-reported signal, not a forecast for your account. A plausible explanation is that a person who has already clarified a need through conversation reaches search with stronger intent. That cohort may be fundamentally different from someone entering an unassisted, ambiguous query.

    Test the mechanism inside your own account. Keep the conversion definition, attribution setting, promotion, geographic scope, and brand versus non-brand treatment comparable. Separate conversationally informed demand from the existing baseline when the platform and campaign setup allow it. Otherwise, an apparent AI lift may simply reflect a different audience mix.

    Add internal measures that expose quality and waste. The names matter less than consistent definitions:

    MeasureHow to define itWhat to noticeWhat to do next
    Revenue ROASAttributed revenue divided by ad spendRevenue can look healthy while margin or customer quality deterioratesPair it with a profit or quality measure
    Qualified conversion rateConversions meeting the business qualification divided by total recorded conversionsRising conversion volume with falling qualification means the system is optimizing toward an easy eventReturn verified quality data to campaign reporting where possible
    Search-term waste rateSpend assigned to irrelevant or ineligible query themes divided by search spendA high rate reveals weak intent classification, exclusions, or match controlRefine intent groups and negative themes before expanding reach
    Intent-to-page completionCompletion of the intended action for each intent group and destinationStrong ad engagement with weak completion often signals a promise-to-page mismatchCorrect the destination or narrow the ad promise
    Creative learning yieldCompleted tests that produced a clear campaign decision divided by completed testsMany inconclusive tests indicate uncontrolled variation or weak hypothesesReduce simultaneous changes and sharpen the decision rule

    Automation can spend against the wrong objective quickly. Preserve account-native budget controls, exclusions, approval steps, and an accessible previous version. Do not shift substantial budget merely because AI-assisted creative generated more impressions, clicks, or engagement. Move it when the agreed business outcome improves without unacceptable deterioration in quality, margin, or waste.

    Key takeaways

    • Conversational demand is valuable because it reveals the decision context around a query, not because it gives you longer keywords.
    • Translate that context into intent records containing the situation, outcome, constraints, decision state, objection, proof, and next action.
    • Give AI bounded production tasks and preserve human approval for claims, eligibility, pricing, cultural adaptation, and brand judgment.
    • Change a defined creative element at a time so each test can produce a usable decision.
    • Keep ads, landing-page content, structured data, and conversion actions aligned around the same promise.
    • Evaluate qualified outcomes, waste, profit, and learning quality rather than counting how much content the system produced.
    • Treat platform-reported performance lifts as hypotheses to validate under your own audience mix, attribution settings, and business economics.

    Your next move should be narrow. Choose a high-spend, high-ambiguity query theme, turn it into a clear intent record, build an aligned ad and destination, and compare it with the existing treatment under the same outcome definition and budget controls. Expand to the next intent cluster only when the first change produces better customers, not merely more activity.

    References