Category: AI

  • WebMCP for Browser-Based AI Agents: A Practical Readiness Guide

    WebMCP for Browser-Based AI Agents: A Practical Readiness Guide

    Your website can be perfectly clear to a person and still force an AI agent to guess. The agent has to locate the right control, infer what each field means, enter values in the expected format, and decide whether a changed screen means the task succeeded.

    If you manage an ecommerce store, booking flow, lead-generation site, or publishing platform, the practical question is not whether every page needs an agent interface. It is which valuable task should get a reliable, machine-readable contract first. WebMCP gives you a way to start answering that question.

    WebMCP changes the interface from controls to callable tools

    Web Model Context Protocol, or WebMCP, is an emerging approach for exposing website actions to browser-based AI agents. Instead of making an agent reconstruct a workflow from buttons and fields, a page can present discoverable tools through JavaScript APIs or annotated HTML forms. Those tools can define their inputs and outputs with JSON schemas and change their availability as the page state changes. That is the central idea behind the early WebMCP preview in Chrome 146.

    Think of the difference as intent versus appearance. A person can look at a blue button labeled Search Flights and understand what to do. An agent works more reliably when it can discover a searchFlights or bookFlight action, inspect the required date, origin, destination, and passenger parameters, call the tool, and receive a structured result.

    Interaction routeWhat the agent must doMain limitation
    UI automationInspect the rendered page, identify controls, enter values, and interpret visual changesText, layout, and component changes can break the agent’s assumptions
    Conventional APICall an endpoint using a separately documented contractAn API may not exist, may not be available to the agent, or may not reflect the current page context
    WebMCPDiscover tools exposed by the current page, supply schema-defined inputs, and consume a structured resultThe Chrome implementation described so far is an early preview, not a mature cross-browser deployment guarantee

    WebMCP does not make your human interface unnecessary. People still need an understandable, accessible flow, and agents may still fall back to that flow when no compatible tool is available. It also does not remove the need for an API when partners, mobile applications, or backend systems require one.

    For SEO, AEO, and GEO teams, the most important distinction is between discovery, understanding, and action. Search-friendly content helps a system find the page. Structured content and JSON-LD help clarify what the page, entity, product, or offer represents. WebMCP addresses what an agent can do once it reaches the relevant browser context. A tool declaration does not make a brand rank, earn a citation, or become the agent’s preferred choice. Treat it as actionability infrastructure, not as an assumed ranking factor.

    Choose one bounded task before exposing an entire journey

    A site-wide WebMCP project is usually the wrong starting unit. Begin with one task whose successful outcome is easy to recognize. Product search, inventory checking, quote requests, registration, and booking are stronger candidates than a vague action such as helpMe or handleMyAccount.

    Use this filter when selecting the first task:

    • The user outcome can be stated in one sentence. Check whether a particular item is available is clearer than assist with shopping.
    • The required inputs can be named and validated. A quote request might require a product, quantity, contact method, and organization identity rather than an unrestricted message.
    • The result can be returned as data. Availability status, a quote-request identifier, or a list of matching products is easier for an agent to use than a visual success banner.
    • The preconditions are knowable. You can state whether the action requires authentication, a non-empty cart, a selected product, or a particular page state.
    • The side effect is limited or confirmable. Read-only inventory lookup is a safer first implementation than charging a card, issuing a ticket, or publishing content.
    • A human fallback exists. If the tool cannot complete the task, the user should be able to continue in the normal interface without reconstructing the entire journey.

    Write a plain-language planning card before writing code. For a B2B quote flow, it could contain the tool name requestQuote, the exact business outcome, required and optional inputs, the returned request status, the conditions under which the tool is available, the permissions it needs, and the point at which the user must confirm submission. This exposes ambiguity while it is still cheap to correct.

    Map one existing human journey against that card. If the page asks for information that is absent from the proposed input schema, either add it to the contract or establish that the server can derive it safely. If the proposed tool requests data that the human journey does not need, challenge the requirement. An agent-facing path should not become an excuse to collect more information.

    Design a tool contract an agent can call without guessing
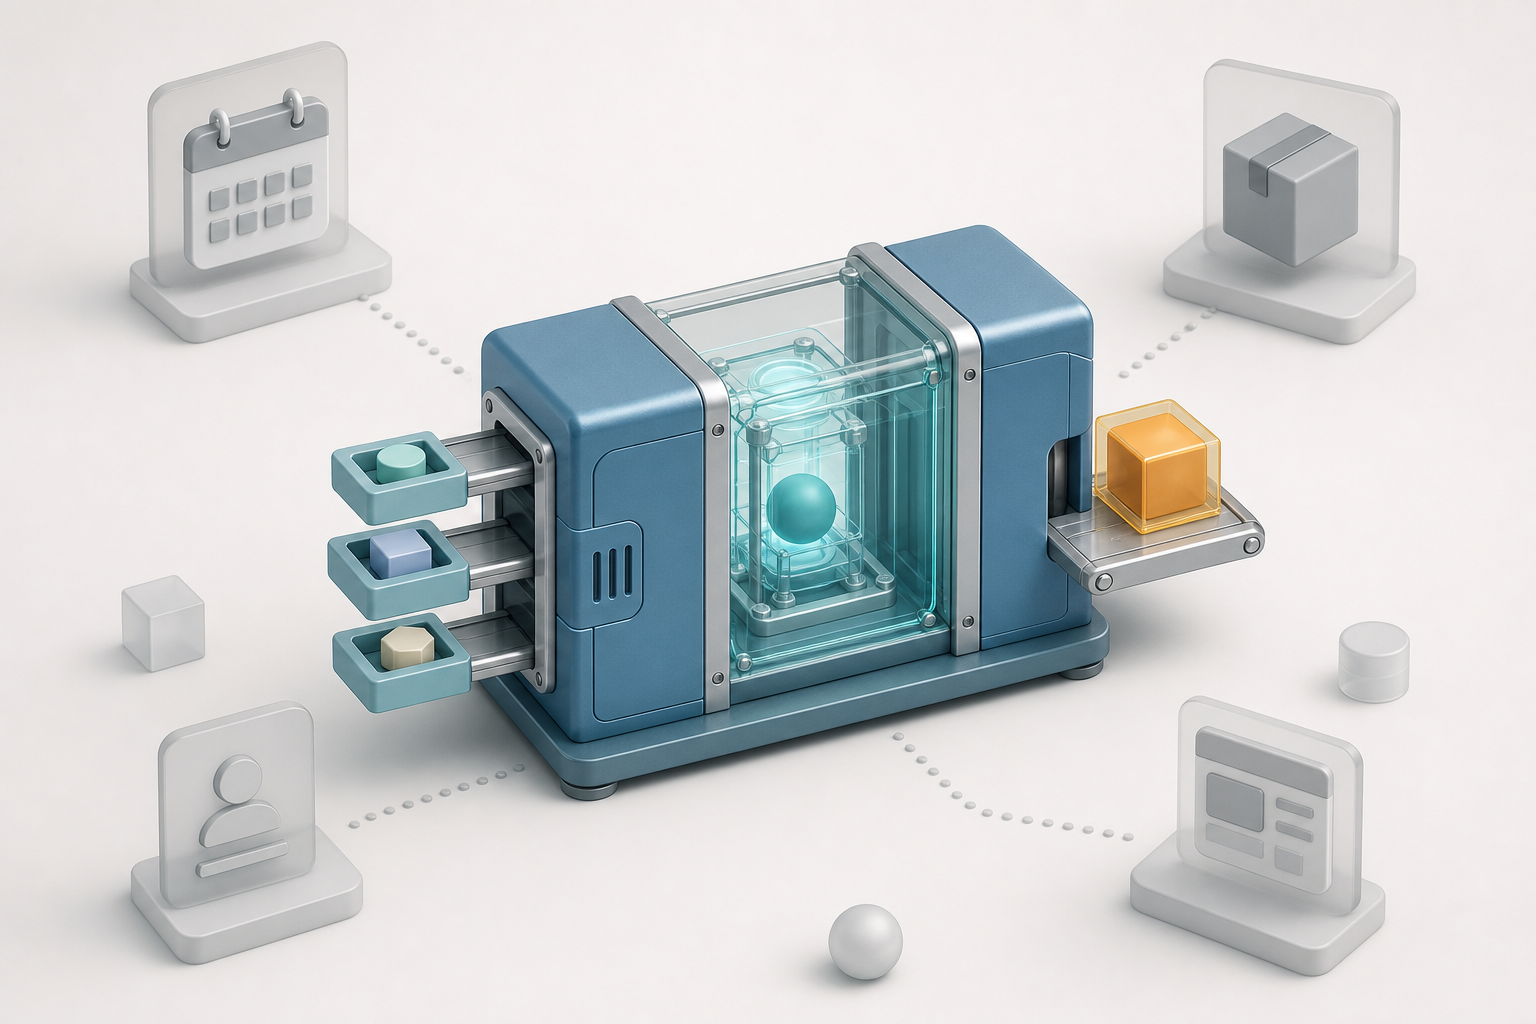
    An isometric tool module receives structured inputs, validates them, and produces one confirmed output while unrelated interface elements remain disconnected.

    A tool is only as reliable as the decisions its contract removes. Discovery tells the agent that an action exists. The schema tells it how to call the action. The structured result tells it what happened. State determines whether calling it now makes sense.

    Make discovery names describe outcomes

    Name the task after the result, not the page element. searchProducts, checkInventory, requestQuote, and bookFlight communicate intent. clickPrimaryButton, submitForm, and runAction merely expose implementation details. A redesign can replace a button or form while the user outcome stays the same.

    The description should also establish scope. If checkInventory covers one location and one product variant, say so. If searchProducts returns candidates but does not reserve stock, make that boundary explicit. Two tools with overlapping names and unclear scopes force the agent back into interpretation.

    Use schemas to eliminate format decisions

    The WebMCP model uses JSON schemas to define expected inputs and outputs. Use that structure to settle details that a visual form often leaves implicit:

    • Identify which fields are required and which are optional.
    • Use precise data types rather than asking the agent to encode everything as free text.
    • Define accepted formats for dates, locations, identifiers, quantities, and other constrained values.
    • Use enumerated choices when the system accepts a closed set of options.
    • Make defaults explicit. Do not rely on a checked box, placeholder, or hidden field that only exists in the rendered interface.
    • Describe outputs well enough for the agent to determine whether the goal was completed, partially completed, or rejected.

    A flight action illustrates the problem. Date, origin, destination, and passenger count are obvious inputs, but an agent should not have to infer whether an ambiguous numeric date uses month-first or day-first order. It should not have to guess whether the location field expects a city, airport, or internal identifier. The schema should make those choices visible before the call.

    Separate exploration from commitment when the consequences differ. Searching for flights and purchasing one are not the same action. Searching can return options. Booking can reference a selected option, display the final itinerary and price, obtain confirmation, and then commit. A single broad tool that silently crosses both stages is difficult to control and difficult to audit.

    Expose tools only when the current state supports them

    WebMCP’s state-aware model lets tool availability change with context. Use that capability deliberately. Checkout should not appear when the cart is empty. Publish should not appear when there is no valid draft or the current user lacks the required permission. A booking action should not appear before an option has been selected.

    This is more than interface tidiness. Every unavailable action shown to an agent creates another path it can choose incorrectly. Prefer a small set of valid actions for the current state over a large catalog that returns preventable errors. Keep server-side validation in place even when discovery is state-aware; page state can change between discovery and execution.

    Put permissions, confirmation, and failure handling in the design
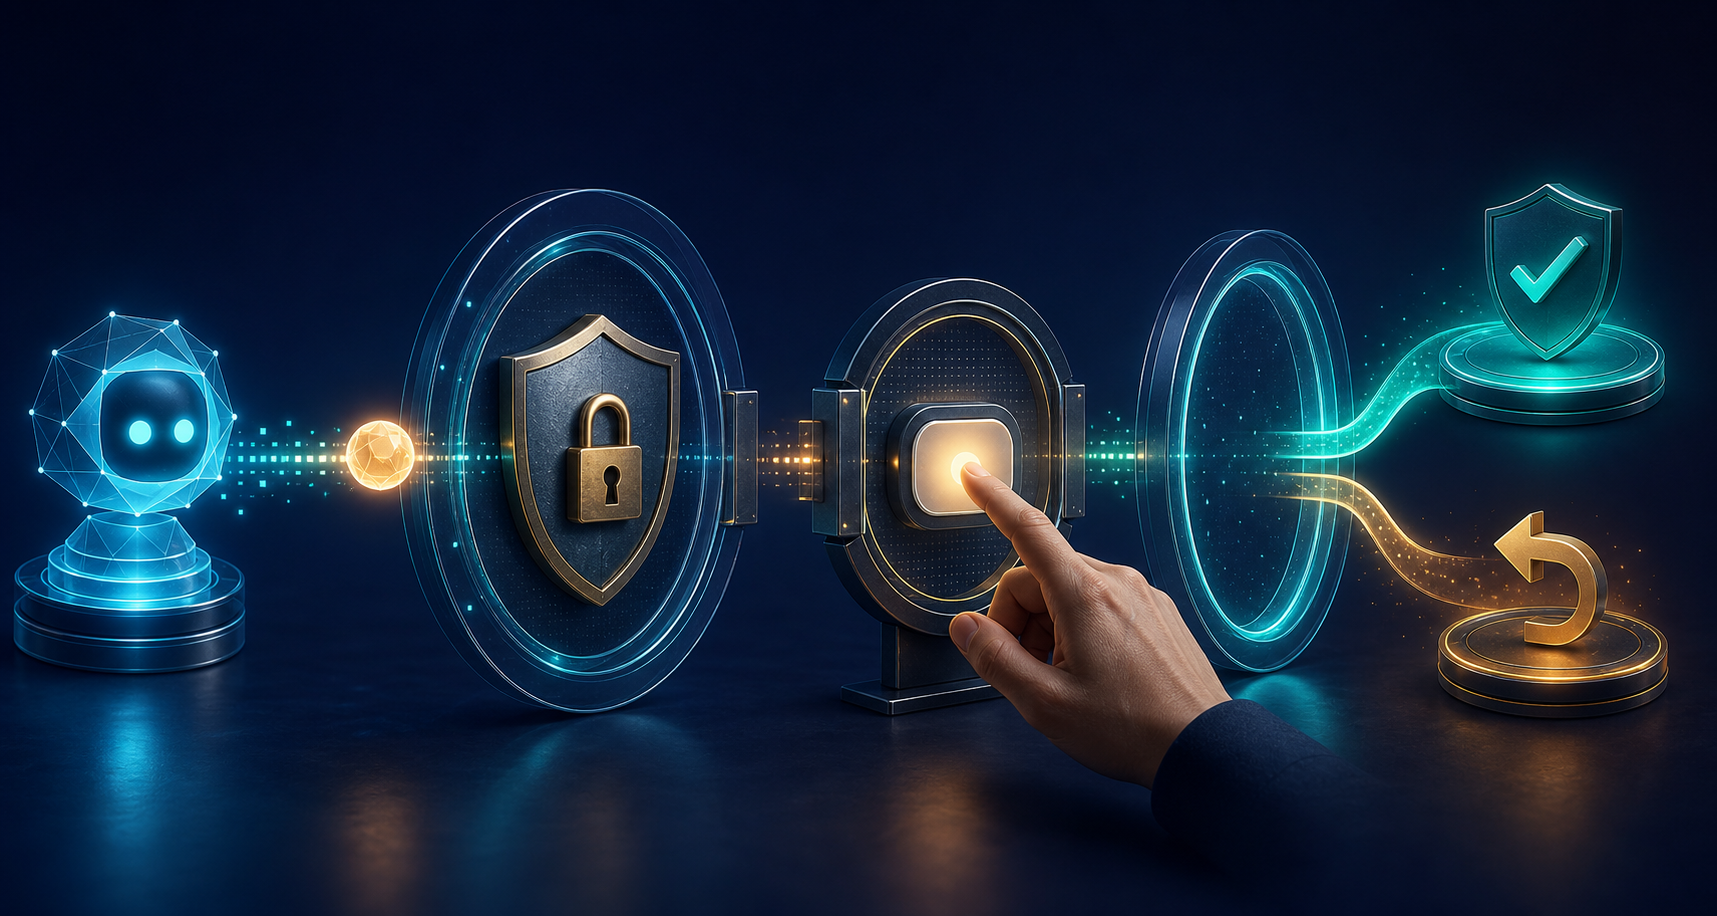
    A geometric AI agent's task passes through a permission gate and human confirmation checkpoint before reaching success or recoverable failure paths.

    Agent-callable does not mean agent-authorized. WebMCP can describe an interaction, but the website still owns authentication, authorization, validation, and the consequences of the action. Do not treat tool metadata as a substitute for those controls.

    Classify each tool by effect before deciding how it can run:

    • Read-only actions retrieve information without changing user or business data. Product search and inventory checks are useful first candidates.
    • Reversible or draft actions prepare work without finalizing it. Filling a quote draft or assembling a checkout summary can reduce effort while keeping the user in control.
    • Consequential actions create cost, external communication, publication, reservations, or another durable change. Purchasing a ticket, submitting an order, or publishing content should require an explicit confirmation step that presents the material terms before execution.

    For a consequential action, confirmation should describe what will happen, not merely ask the user to continue. Show the item or service, selected options, final amount when money is involved, destination or recipient, and whether the action can be reversed. If any material value changes after confirmation, stop and obtain a new confirmation. The downside of getting this wrong is a real charge, booking, message, or publication that the user did not approve.

    Design structured failures as carefully as successful results. At minimum, the calling agent needs to know which field or precondition failed, whether retrying is safe, whether the current state has changed, and what valid next step is available. Invalid input, expired state, missing permission, unavailable inventory, and an internal failure should not collapse into one generic message.

    Repeated calls deserve special attention. A timeout can leave the agent unsure whether a write succeeded. If retrying could create a second order, booking, quote request, or publication, make duplicate prevention part of the underlying transaction design. Return enough structured status for the agent to reconcile the original attempt instead of blindly submitting again.

    Keep an audit trail that helps you investigate outcomes without recording unnecessary sensitive values. Useful events include the tool discovered, tool invoked, authorization result, validation result, confirmation state, completion status, and fallback route. Your analytics should distinguish an agent that could not find the right tool from one that found it but supplied invalid inputs.

    Test Chrome’s preview as a learning environment

    The Chrome 146 implementation was presented as an early testing preview behind a feature flag. For that preview, the documented setup required Chrome version 146.0.7672.0 or later and the WebMCP testing flag. That makes it useful for prototyping, but it does not justify assuming stable syntax, broad browser support, or production compatibility.

    To recreate that preview environment:

    1. Use the Chrome version specified for the preview: 146.0.7672.0 or later.
    2. Open chrome://flags/#enable-webmcp-testing.
    3. Set WebMCP for testing to Enabled.
    4. Relaunch Chrome.
    5. Use the optional Model Context Tool Inspector Extension to inspect which tools the page exposes and how their contracts appear.

    Do not stop when the inspector can see a tool. Run a small test matrix against the outcome:

    • Discovery: Can the agent identify the correct tool from its name, description, and current state?
    • Valid execution: Does a complete, schema-valid request produce the expected structured result?
    • Invalid input: Does each missing, malformed, or unsupported value produce a useful field-level response?
    • State transition: Do tools appear and disappear when the cart, selection, login state, or draft state changes?
    • Permission boundary: Can an unauthorized user discover or execute an action that should be restricted?
    • Confirmation: Does a consequential action stop before commitment and present the right details?
    • Replay: Can a retry accidentally create a duplicate side effect?
    • UI change: Does the tool continue to work when labels or layout change but the underlying business task remains the same?
    • Fallback: Can the user continue through the normal interface when the agent-facing action fails?

    Record pass or fail by stage rather than using one overall completion number. Separate discovery failures, schema-validation failures, permission denials, user-declined confirmations, server errors, duplicate-prevention events, successful completions, and human fallbacks. That breakdown tells you whether to rewrite the tool description, change the schema, fix state exposure, or repair the underlying transaction.

    Key takeaways

    • WebMCP gives a browser-based agent an explicit tool contract instead of requiring it to infer every action from the visible interface.
    • Start with one bounded, measurable task whose inputs, result, state, and side effects can be described clearly.
    • Use action-oriented names, strict schemas, structured results, and state-aware availability to remove guesswork.
    • Keep authentication and server-side validation in place, and require meaningful confirmation before payments, bookings, publication, or other consequential actions.
    • Treat the Chrome 146 implementation as a testing preview, not proof of stable or universal browser support.
    • Keep investing in content, technical SEO, and structured data. WebMCP adds actionability; it does not guarantee discovery, citation, selection, or ranking.

    Your next move is small: choose one read-only or low-risk task, write its tool contract on a single page, and test discovery, valid input, invalid input, state change, and fallback in the preview environment. Even if the emerging interface changes, the work of defining the task, permissions, schemas, side effects, and success criteria will remain useful.
    References

  • Boost AI Search Visibility with Effective Schema Markup

    Boost AI Search Visibility with Effective Schema Markup

    As someone keen on improving AI search visibility, I’ve delved into the world of schema markup. Let me share what I’ve learned about essential schema types, practical implementation tips, and how structured data enhances the understanding of content by Large Language Models (LLMs).

    By incorporating schema markup, I’ve noticed significant improvements in how AI and search engines interpret my content. This not only boosts my content’s visibility but also ensures it reaches the right audience effectively.

    The right schema types serve as a bridge, enabling AI systems to decipher and present content accurately. In my experience, selecting the appropriate schema type is crucial for optimizing how LLMs process information.

    Moreover, implementing schema markup isn’t as daunting as it seems. With some practice, I’ve found that the structured data seamlessly fits into my workflow, enhancing the overall search optimization process.


    Inspired by this post on HiGoodie Blog.


    crushpress.ai community screenshot
  • Marketing Data Doppelgangers: An Identity Confidence Playbook

    Marketing Data Doppelgangers: An Identity Confidence Playbook

    Your CRM has identified an apparent ideal customer. This person opens almost every email, checks products repeatedly, moves between devices, and redeems offers with remarkable timing. The activity is real enough to enter your dashboards, but it may not belong to one person or represent the intent your models assign to it.

    Before you increase bids, trigger a high-value nurture sequence, or extend another promotion, you need to know whether you are acting on a coherent customer or a marketing data doppelganger. The practical fix is not another round of duplicate removal. It is an identity-confidence system that separates observed activity from actor, intent, and customer identity.

    What your apparently complete customer profile may be hiding

    A marketing data doppelganger is a customer profile that looks internally valid but does not map cleanly to one actor. Its email may be deliverable. Its clicks may have occurred. Its purchases may be legitimate. The error appears when your systems treat all those events as evidence about the same individual.

    This problem has two main identity patterns:

    • Convergence: Multiple people or systems are folded into one profile. A shared login, forwarded corporate alias, recycled email address, AI assistant, and human account holder can all contribute activity that appears to come from one customer.
    • Fragmentation: One customer is distributed across multiple profiles. Alternate email addresses, several devices, subscription accounts, loyalty records, and repeated new-customer registrations can make one person look like several unrelated prospects.

    Delegated activity complicates both patterns. AI assistants can summarize emails, compare products, monitor prices, complete forms, and sometimes make purchases. That activity is not automatically fraudulent or irrelevant. It is evidence that software acted, possibly with a customer’s authorization. It is not automatically evidence that a person read a message, evaluated an offer, or developed stronger purchase intent.

    Use three separate questions whenever a profile drives a decision:

    • Identity: Which customer, account, household, or organization do we believe this activity belongs to?
    • Actor: Was the event produced by a person, an authorized assistant, an email client, an automated workflow, a shared user, or an unknown process?
    • Intent: What does the event actually establish: message delivery, monitoring, consideration, authorization, or a completed commercial outcome?

    Those answers are not interchangeable. A deliverable email establishes that a destination can receive mail; it does not establish that one enduring person controls it. A completed order establishes a commercial outcome; it does not prove that the payer, shopper, recipient, and account user were the same person.

    Observed patternPossible doppelganger mechanismDecision at risk
    Frequent opens with little subsequent activityEmail prefetching or AI summarizationLead scores, send frequency, and engagement segments
    Repeated product checks at unusually precise intervalsPrice-monitoring or shopping automationRetargeting intensity and inferred purchase urgency
    Contrasting preferences under one addressShared credentials, a forwarding alias, or a recycled addressPersonalization and customer lifetime analysis
    Several apparently new profiles with related account behaviorOne customer using alternate identifiersAcquisition reporting and promotion eligibility
    A customer journey spread across disconnected devices or accountsIdentity fragmentationAttribution, suppression, retention, and forecasting

    The important correction is simple: valid events do not guarantee a valid person-level interpretation. Your job is to preserve what was observed while reducing confidence in conclusions the evidence cannot support.

    Audit the marketing decision before cleaning the database

    A database-wide identity project can become expensive and abstract before it changes a single campaign. Start with one consequential decision: a lead score, promotion rule, churn prediction, retargeting audience, acquisition report, or budget forecast. Then work backward to the identity assumptions that make the decision possible.

    1. Write the claim behind the decision. A high-engagement segment may depend on the claim that repeated opens and product views represent increasing interest from one person. A new-customer discount may depend on the claim that one profile represents one previously unseen customer. State that claim plainly.
    2. List the events that support the claim. Separate email opens, clicks, page views, form submissions, account activity, promotion redemptions, and transactions. Do not collapse them into a single engagement total during the audit.
    3. Recover event provenance. For each event, retain the event time, collection source, profile and account identifiers, campaign, session or device identifier where permitted, related transaction or promotion, automation marker, and downstream outcome. A missing provenance field is an audit finding, not permission to assume a human acted.
    4. Classify the likely actor. Use practical states such as human-confirmed, delegated or agent-assisted, platform-generated, shared or ambiguous, and unknown. Preserve unknown as a real category. Treating unknown as human simply hides the uncertainty.
    5. Look for convergence and fragmentation. Search for abrupt cross-device activity, mutually inconsistent preferences, shared or reassigned contact points, automated monitoring patterns, and apparently new profiles connected to established activity. Each pattern is a reason to investigate, not proof of abuse.
    6. Run a counterfactual version of the decision. Recalculate the segment, score, attribution result, or forecast after excluding events with uncertain actor provenance. Then consolidate likely fragments where you have defensible evidence. If the decision changes materially, it depends on identity assumptions that need to be exposed.
    7. Record the operational consequence. Note whether the uncertainty can waste media, increase message frequency, distort attribution, issue duplicate benefits, suppress a legitimate customer, or create unnecessary checkout friction. This converts identity quality from a data-cleaning concern into a prioritized business risk.

    Email engagement deserves early attention because prefetching and automated summarization can create activity that resembles high engagement. An open can remain useful as a delivery or processing event, but it should not carry the same intent weight as an explicit response or a coherent downstream journey.

    Do not delete ambiguous events. Preserve the raw observation and change its interpretation. Deletion destroys evidence you may need for attribution, troubleshooting, or future validation. Classification lets you ask better questions without pretending uncertain data never existed.

    Replace the golden record with an evidence-backed confidence record

    An anonymous customer figure surrounded by devices and transaction objects, with solid and faint connection lines indicating different levels of identity confidence.

    The traditional golden record promises one definitive profile assembled from every available identifier. That model becomes brittle when one person can produce several identities and several actors can produce events under one identity. A larger merged profile can look more complete while becoming less coherent.

    Use a confidence record instead. It should not merely declare that two records match. It should explain why your organization currently considers a profile stable enough for a particular use.

    Evaluate identity confidence across these dimensions:

    • Identifier continuity: Are the account and contact identifiers stable over time, or do they show signs of reassignment, sharing, or frequent substitution?
    • Behavioral coherence: Can the activity plausibly belong to the same customer context, or does it contain conflicting needs, abrupt channel changes, and overlapping journeys?
    • Actor provenance: Can you distinguish explicit customer actions from platform processing, delegated agent activity, autofill, and unknown automation?
    • Commercial continuity: Do account history, offer use, and completed outcomes support the same customer relationship, or do they reveal fragmentation or convergence?
    • Ambiguity burden: How much of the profile’s apparent value depends on events whose actor or meaning cannot be established?

    A practical profile record can store an identity state, actor state, confidence band, supporting evidence, contradictory evidence, last validation trigger, and permitted uses. For example, the identity state might be stable, fragmented, composite, or unknown. The actor state might be human, delegated, platform-generated, shared, mixed, or unknown.

    Use confidence bands with reason codes before reaching for a precise score. A numerical score can create false certainty if nobody can explain what moved it. A band such as high, conditional, or low is useful when it is attached to evidence and an allowed decision:

    • High confidence: The available evidence is coherent and sufficiently attributable for the named use. This does not mean every event came directly from a human.
    • Conditional confidence: The profile contains stable evidence, but shared, delegated, or fragmented activity limits some uses. It may be suitable for service communication while remaining unsuitable as clean training data for an intent model.
    • Low confidence: The profile depends heavily on weak identifiers, unknown event provenance, or contradictory activity. Use it cautiously and avoid expensive personalization or irreversible risk decisions based on it alone.

    Confidence must be use-specific. The evidence required to send a general newsletter is not the same as the evidence required to grant a one-time benefit, block an order, label a person as a high-value customer, or train a predictive model. A universal identity score hides those differences.

    Revalidate when meaningful evidence changes, not only during a periodic cleanup. Useful triggers include a new account relationship, a sudden shift in device or channel behavior, evidence of a shared or recycled contact point, new agent-assisted activity, conflicting transactions, and a promotion or risk event. Continuous validation is necessary because identity now behaves like an evolving relationship rather than a static match.

    Identity confidence is not a reason to collect every possible identifier. Use permitted data with a clear purpose, retain provenance, and avoid treating invasive surveillance as a substitute for coherent evidence. Better validation should make your interpretation more disciplined, not make your collection indiscriminate.

    Change campaign, attribution, and risk decisions at the same time

    Overlapping customer and device signals pass through a confidence gate before branching toward campaign, attribution, and risk decision symbols.

    An identity audit has little value if every downstream system continues treating all events as equal. Carry the confidence state into activation, reporting, modeling, and revenue protection.

    Separate activity, human intent, and identity confidence

    Replace a single engagement score with distinct measures. Observed activity records what happened. Intent classification describes what the event can reasonably imply. Identity confidence describes how safely the behavior can be attached to the profile.

    • Treat prefetches and automated message processing as delivery or machine-processing evidence, not direct proof of interest.
    • Classify agent-based comparison and price monitoring as delegated activity. It may represent customer interest, but it should remain distinguishable from a human browsing session.
    • Give coherent downstream actions more decision weight than isolated high-volume signals, while retaining uncertainty about who performed them.
    • Prevent low-confidence profiles from automatically entering expensive personalization, aggressive retargeting, or high-priority sales queues.

    This structure lets a campaign acknowledge useful agent activity without pretending that every machine event is a human signal.

    Publish attribution with an uncertainty view

    Do not hide identity ambiguity inside a probabilistic attribution model. Browser privacy changes and cross-device behavior already make attribution more dependent on inferred relationships. Adding composite profiles can make a precise report less trustworthy, even when the arithmetic is correct.

    Show the reported result beside an identity-quality view. Track the share of events with unknown actors, conversions attached to composite or fragmented profiles, and the sensitivity of channel credit when automated events are removed. You do not need to invent a confidence-adjusted revenue figure if your evidence cannot support one. Showing the uncertainty is more useful than concealing it behind a new calculation.

    Keep unstable identities from becoming model ground truth

    A model trained to equate automated opens with customer interest will seek more people who produce the same distorted pattern. Campaigns then generate additional machine activity, which returns as apparent proof that the model was right. This is how an identity problem becomes a performance feedback loop.

    Attach identity and actor labels before training. Depending on the model and decision, filter unstable profiles, reduce their training weight, or retain them as a separately labeled population. Evaluate performance by confidence band as well as in aggregate. If a model performs well only where identity is ambiguous, inspect what it has actually learned before expanding its use.

    Distinguish delegated assistance from promotional abuse

    An AI assistant acting for a customer is not, by itself, evidence of fraud. Shared accounts are not automatically abusive either. Blocking every ambiguous profile adds friction for legitimate customers, while permissive rules can allow one person to appear repeatedly as a new customer.

    Escalate controls when low identity confidence coincides with an economic action and contradictory account history. Do not make an agent marker the sole reason for a block. Use proportionate checks, preserve the reason for the decision, and provide a review path when a legitimate customer may have been caught by the control.

    Give each team an explicit responsibility

    Identity confidence fails when it belongs only to the data team. Assign ownership at the point where interpretation becomes action:

    • Marketing operations preserves event provenance and exposes confidence fields to campaign tools.
    • Analytics reports identity uncertainty and tests how sensitive conclusions are to ambiguous events.
    • Lifecycle and sales teams define which confidence bands may enter each journey or priority queue.
    • Model owners document which identity states are accepted as labels and evaluate performance across those states.
    • Risk and commerce teams define when an ambiguous identity warrants additional validation rather than automatic denial.

    Begin with the decision that has the clearest cost when identity is wrong. Rewrite its event rules, add actor and confidence fields, rerun the decision under alternative inclusion rules, and document what changes. Once that loop works, extend the same method to the next campaign, model, or control. You will improve trust faster by validating consequential decisions one at a time than by declaring the entire customer database clean.

    Key takeaways

    • A marketing data doppelganger is a coherent-looking profile whose events do not reliably represent one actor or one customer’s intent.
    • The problem includes both convergence, where several actors appear as one profile, and fragmentation, where one customer appears as several profiles.
    • Preserve the distinction between identity, actor, and intent. A valid event does not make every person-level inference valid.
    • Audit one costly decision first, recover event provenance, classify uncertain actors, and rerun the decision without ambiguous signals.
    • Replace binary identity matches with explainable, use-specific confidence bands supported by evidence and contradiction records.
    • Carry identity confidence into segmentation, attribution, model training, promotion controls, and reporting so the same uncertainty is not lost downstream.

    Your next step is to choose one segment, score, or promotion rule that would hurt if the customer identity were wrong. Find the weakest event it relies on and make that uncertainty visible. That small change gives you a defensible starting point for rebuilding trust in the rest of your marketing data.

    References

  • Boost Your B2B Visibility: Get Noticed by AI in Vendor Searches

    Boost Your B2B Visibility: Get Noticed by AI in Vendor Searches

    As a B2B company, I’ve noticed a significant shift in how buyers conduct vendor research, especially with the growing use of AI-driven platforms like ChatGPT. This trend presents a unique opportunity for us to increase our visibility and be recommended during the buying process.

    To capitalize on this, it’s essential to understand how AI search works and how we can optimize our presence to stand out. By leveraging AI visibility strategies, we can make sure our company appears at the top of vendor search results.

    One of the key tactics I’ve explored is incorporating AI-powered SEO tools to fine-tune our website and content. This approach not only enhances our searchability but also aligns with the evolving digital landscape where AI is becoming a primary decision-making tool.

    Moreover, staying informed about market trends and continuously adapting our strategies ensures that we remain competitive. Engaging with our audience through personalized content and targeted campaigns can build the brand authority needed to get recommended by AI systems.

    In conclusion, as AI continues to reshape the purchasing journey, positioning ourselves strategically in AI searches is vital. By embracing these changes, we can effectively increase our B2B visibility and ensure we’re on the radar of potential buyers.


    Inspired by this post on genmark.ai Blog.


    crushpress.ai community screenshot
  • Google Nano Banana 2: A Practical Workflow for Marketers

    Google Nano Banana 2: A Practical Workflow for Marketers

    You have a campaign brief, not an afternoon to spend rerolling images. The asset needs readable copy, stable people and products, multiple formats, and localized versions. Someone also needs to know exactly what changed between creative variants.

    Google Nano Banana 2 can carry more of that production workload, but only if you treat it as part of a controlled creative system. The useful shift is not simply better-looking output. It is the ability to move from a structured brief to a consistent family of assets with fewer compromises between speed, detail, text, and continuity.

    What Nano Banana 2 changes in an image workflow

    Nano Banana 2 is the informal name for Gemini 3.1 Flash Image. Google DeepMind has positioned it as a combination of Nano Banana Pro’s image intelligence and Gemini Flash’s faster generation. For a marketing team, that combination matters because image quality and iteration speed normally pull the workflow in opposite directions.

    The model’s improvements map to four practical jobs:

    • Knowledge-heavy visuals: Real-time web grounding can bring current context into infographics and data-oriented images. Treat that as assistance with generation, not proof that a visual is factually correct.
    • Images containing words: Improved text rendering and translation make social graphics, diagrams, promotional cards, and localized creative more viable. Every visible word still needs human proofreading.
    • Scenes that must remain recognizable: Stronger instruction adherence and subject consistency make it easier to preserve the same cast, objects, visual hierarchy, and art direction during revisions.
    • Assets for different placements: Supported output extends from 512px through 4K, so the same workflow can cover lightweight concepts and high-resolution deliverables.

    The documented consistency envelope reaches up to five characters and 14 objects in one workflow. Read that as an upper capability boundary, not a guarantee that a crowded scene will remain perfect. The closer your composition gets to the limit, the more deliberate your naming, placement, and review need to be.

    Key takeaways

    • Use Nano Banana 2 for repeatable asset families, not just isolated image generation.
    • Write prompts as production briefs with explicit priorities, subjects, composition, copy, and output requirements.
    • Approve one master image before generating formats, languages, or test variants.
    • Verify every word, number, label, and data point even when web grounding is involved.
    • Keep important page meaning in HTML and metadata rather than leaving it trapped inside an image.

    Turn the prompt into a production brief

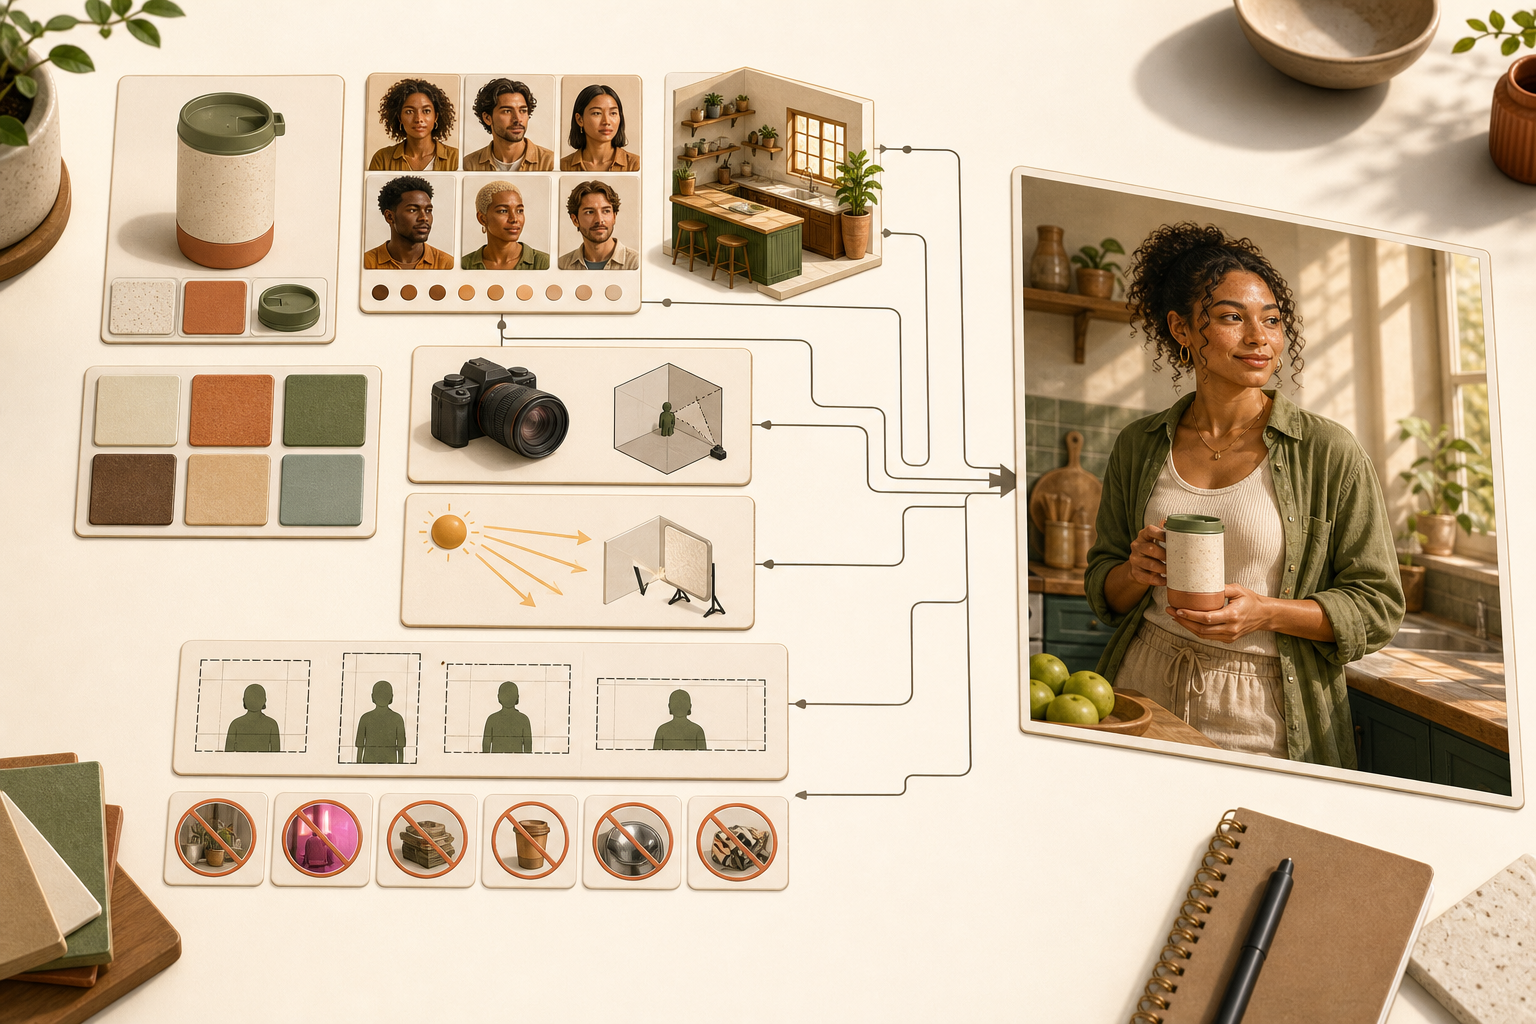
    Visual reference tiles for a mug, customer, kitchen, colors, lighting, and image formats connect to a finished campaign image.

    Stronger instruction adherence is only useful when the instructions have a clear hierarchy. A loose collection of adjectives leaves the model to decide what matters. A production brief tells it what the asset must accomplish, what cannot change, and where it has room to interpret.

    1. Start with the asset’s job. Name the destination and the action the visual should support: a landing-page hero, an ad variant, a report cover, a diagram, or a localized social card. This gives the composition a reason to exist.
    2. Define the required subjects. List each person, product, interface, or meaningful object. Give recurring subjects short, stable labels so later instructions can refer to them without ambiguity.
    3. Specify spatial relationships. State what belongs in the foreground, where the main subject sits, which direction a person faces, and where clear space is required for external copy or controls.
    4. Describe the visual system. Set the palette, lighting, texture, level of realism, camera perspective, and overall mood. Use concrete visual properties rather than piling up subjective terms such as premium, bold, or modern.
    5. Supply text as exact copy. Separate the headline, labels, supporting text, and language. If a phrase must not be translated, say so. Do not bury critical wording inside a long paragraph of art direction.
    6. Name the output requirements. Include the intended aspect ratio, supported resolution, crop needs, and any areas that must remain uncluttered. Request 4K when the approved asset actually needs it, not by default for every concept.
    7. Declare the invariants. Say which identities, objects, colors, text, and layout relationships must remain unchanged across revisions.

    A reusable prompt pattern

    Goal: Create a 4K landscape hero image for a landing page promoting a search visibility report. Subjects: Show one analyst at a desk and one dashboard object displaying a clean line chart. Composition: Place the analyst and dashboard on the right, with the left third uncluttered for an HTML headline. Visual direction: Use deep navy, off-white, and restrained cyan accents, with soft directional lighting and realistic textures. Restrictions: Do not add logos, watermarks, interface labels, extra screens, or text inside the image. Continuity: Keep the analyst’s appearance, dashboard layout, palette, and lighting unchanged in later variants.

    This example deliberately reserves the headline for HTML. That is usually the cleaner choice for a web hero because the copy remains editable, selectable, responsive, and available to assistive technology. Use embedded text when the words are part of the artifact itself, such as a social card, diagram label, poster, or standalone ad creative.

    For an image that needs embedded copy, add a separate instruction such as On-image copy: Q3 Search Visibility Report. Then identify the exact location, hierarchy, and language. Keeping copy in its own instruction makes proofreading and localization easier.

    Follow-up prompts should be smaller than the original brief. Ask to change one controlled element while restating the invariants: replace the background environment, change the accent color, translate the approved copy, or adapt the crop while preserving the subjects. Rewriting the entire prompt for every revision invites unplanned changes.

    Build variants without losing control of the experiment

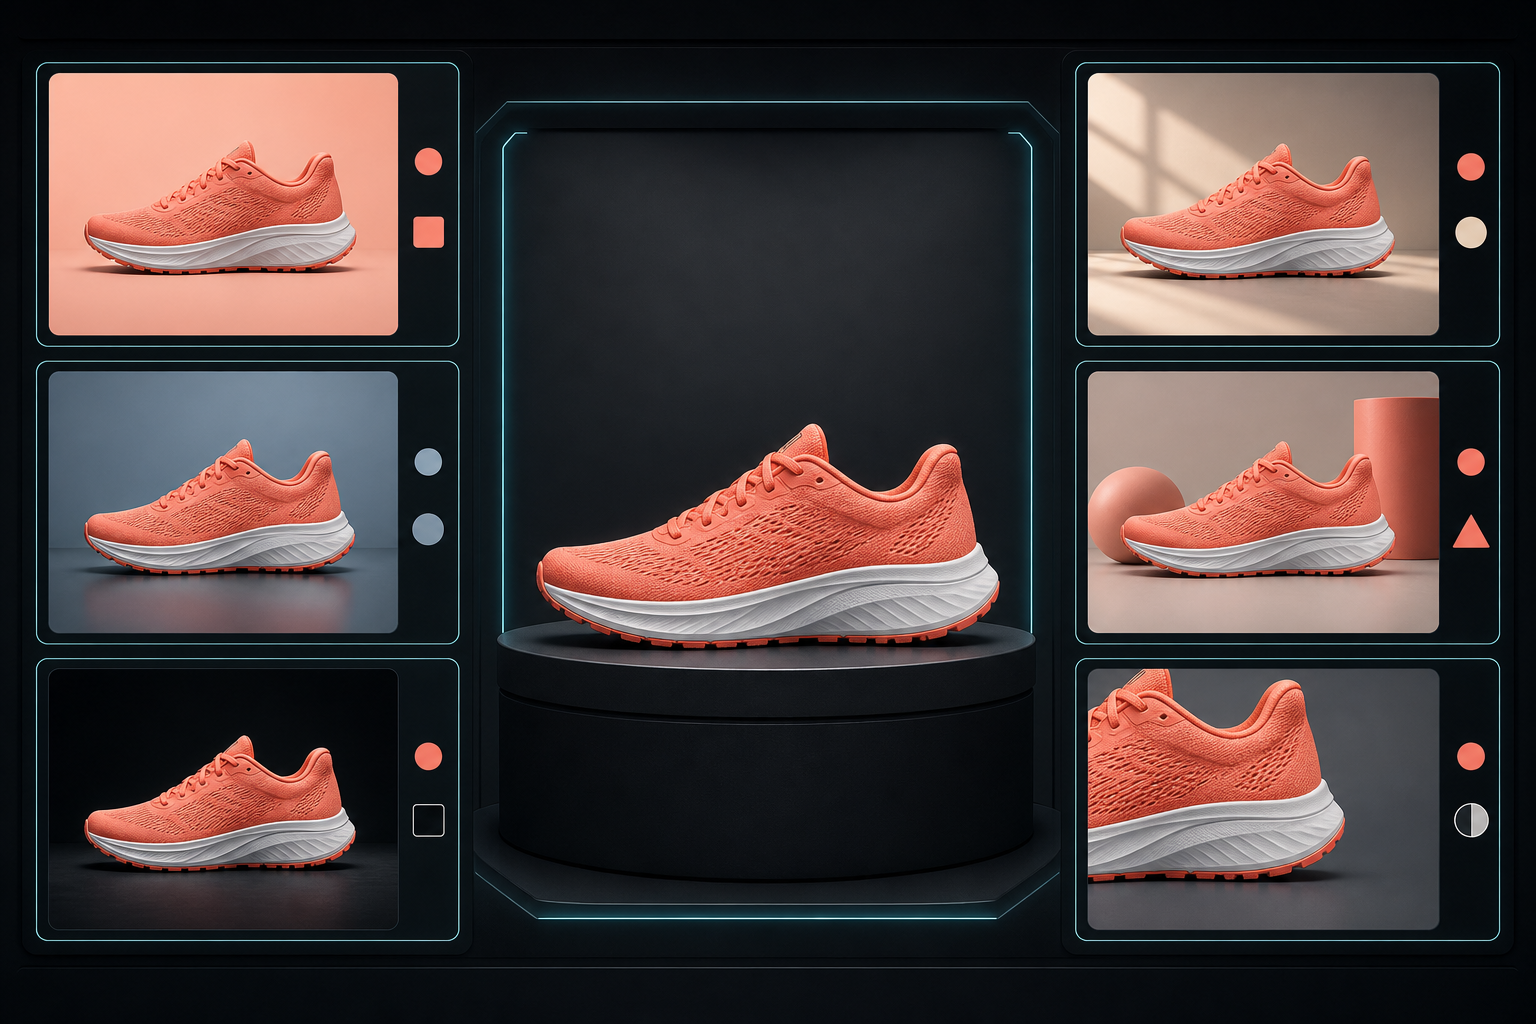
    Six campaign previews preserve the same coral running shoe and fictional athlete while changing backgrounds, lighting, props, and crops.

    Fast generation can create a false sense of progress. Twenty visually different outputs are not a useful test if the headline, palette, composition, subject, and offer all changed together. You will know which image performed better, but not why.

    Use a master-and-variant workflow instead:

    1. Generate a baseline. Produce the first complete interpretation of the brief before requesting alternatives.
    2. Review against the brief. Separate objective misses, such as incorrect text or a missing object, from subjective preferences, such as wanting warmer lighting.
    3. Correct the baseline. Do not build variants from an image that already violates the required composition, copy, or identity.
    4. Approve a master. Record the accepted prompt, output, invariants, language, and intended placement.
    5. Create one-variable variants. Change one meaningful family of attributes at a time, such as the background, focal framing, callout treatment, or color emphasis.
    6. Localize after visual approval. Preserve the master composition while changing the language-specific copy, then allow only the layout adjustments required by the translated text.

    Your review should use explicit gates rather than a general looks-good decision:

    • Brief compliance: Are all required subjects present, and are unwanted additions absent?
    • Continuity: Do recurring people, products, and objects remain recognizable across versions?
    • Copy: Does every character match the approved wording, including punctuation, capitalization, and product terms?
    • Factual content: Do chart labels, values, dates, maps, and explanatory elements match the information you intend to publish?
    • Visual integrity: Are faces, hands, object boundaries, reflections, lighting, and small details internally coherent?
    • Placement safety: Will important content survive the real crop, overlay, and responsive layout?
    • Delivery: Does the final file have the resolution and aspect ratio required by its actual destination?

    Web grounding does not remove the factual review gate. It can help the model reason about the requested subject, but it cannot approve a statistic, establish which date your campaign should use, or decide whether a generated chart supports your claim. Keep the underlying facts in a separate, human-reviewed content sheet and compare the rendered visual against it.

    The same discipline applies to translation. Generate the localized version, copy the visible wording out of the image, and compare it with approved language line by line. Check line breaks and hierarchy as well as meaning; a correct translation can still become unreadable when it is forced into the original layout.

    Nano Banana 2 is integrated into Google Ads as well as the broader Gemini ecosystem, which makes rapid campaign variation an obvious use case. Keep the creative test interpretable: hold the audience, offer, and measurement setup steady when the purpose is to learn whether a visual change affected performance.

    Finish the asset for SEO, AEO, and GEO

    A production-quality image is not automatically a search-ready asset. Image generation creates pixels. Your publishing workflow must connect those pixels to the page’s subject, the user’s task, and machine-readable context.

    Keep the meaning outside the pixels

    • Match the search intent. Use the image to clarify the answer, process, entity, comparison, or result the page is actually about. A polished but generic visual adds little retrieval value.
    • Write functional alt text. Describe the information or purpose the image contributes in its context. Do not paste the generation prompt or turn the attribute into a keyword list.
    • Use descriptive filenames. Name the finished asset for its actual subject and role rather than preserving a generator’s default filename.
    • Publish essential facts as HTML. If an infographic contains a process, statistic, or comparison that the reader needs, provide the same core information in nearby page text. Do not make people or search systems depend on reading pixels.
    • Add a useful caption when context is needed. A caption should explain why the visual matters, not merely repeat what it depicts.
    • Create delivery derivatives. Keep a high-resolution master, but serve a file sized and compressed for the placement. Sending a 4K image everywhere can add page weight without improving the reader’s experience.
    • Localize the surrounding context. When you translate text inside an image, update the filename, alt text, caption, nearby explanation, and linked destination for the same audience.

    Treat structured data as a record

    If your page’s structured data references the image, the markup should describe the asset that is visibly published at the live URL. Keep the image URL, dimensions, caption, creator information, and licensing information aligned with what you can substantiate. Do not manufacture metadata simply to fill properties.

    JSON-LD does not rescue a weak relationship between the visual and the page. The image, headline, body copy, captions, internal links, and structured data should all describe the same primary subject. That consistency gives search engines and answer systems a clearer entity-and-context relationship to interpret, although it cannot guarantee rankings, citations, or inclusion in an AI-generated response.

    This is also where subject consistency becomes strategically useful. Reusing a recognizable product, character, diagram language, or branded visual system across a related content cluster can make the collection feel coherent. Keep each asset specific to its page, however; duplicating one generic image across every URL does not explain what makes those pages different.

    Choose a pilot that exposes the model’s real value

    Do not judge Nano Banana 2 by asking it for a single decorative image. That tests whether it can produce an attractive picture, not whether it can improve your production system.

    Our rule of thumb is to choose a pilot that needs at least two of the model’s differentiating capabilities:

    • A recurring person, product, or object that must remain consistent.
    • Exact words or labels inside the visual.
    • Several controlled creative variants for a campaign.
    • Localization into more than one language.
    • A knowledge-heavy infographic or data visualization.
    • Outputs ranging from smaller concept images to a 4K master.

    A strong pilot might be a report launch that needs a hero image, a labeled social card, ad variants, and localized editions. One approved visual system can then be carried through each placement while the team measures generation time, correction cycles, consistency, proofreading effort, and final usability.

    Begin concepts at the smallest supported resolution that lets your team judge composition. Move to 4K after the direction is approved. This keeps reviewers focused on the idea before they spend time inspecting final-level detail.

    The model is available across Google Ads, the Gemini app, Search AI Mode, Lens, and other parts of Google’s ecosystem. That reach makes shared governance more important than platform-specific habits. Store the master brief, approved copy, invariants, final asset, localization decisions, and QA result together so the next person can reproduce the workflow.

    Pick one recurring campaign asset this week. Define its invariants, create one approved master, and generate a single controlled variant. If the model preserves the subject, copy, composition, and visual system through that cycle, you have evidence for expanding the workflow. If it does not, the QA record will show whether the problem came from the brief, the generation, or the review process.

    References


  • Transforming AI Search: The Impact of 2026 Data Wars

    Transforming AI Search: The Impact of 2026 Data Wars

    The landscape of AI is rapidly shifting in 2026. I’ve noticed that AI models are losing their once shared data access, resulting in fragmented and less cohesive answers.

    This change is primarily due to the surge in platform-controlled data, which is significantly altering how visibility and search functions within AI systems. It’s intriguing to see how these developments are reshaping the way we interact with and trust AI-driven responses.


    Inspired by this post on HiGoodie Blog.


    crushpress.ai community screenshot
  • Profound’s $96M Series C: What AI Marketers Should Watch

    Profound’s $96M Series C: What AI Marketers Should Watch

    If you lead AI search, SEO, content, or marketing technology, Profound’s funding can create immediate pressure. Is the company now the category winner? Is your team late? Should you add another platform to your stack? The financing matters, but none of those conclusions follows automatically.

    Profound announced a $96 million Series C at a $1 billion valuation, led by Lightspeed Venture Partners with participation from Sequoia Capital, Kleiner Perkins, Evantic, Saga, and South Park Commons. For you, the useful question is what that event changes about AI marketing, vendor selection, and the way you measure visibility in generative answers.

    Read the round correctly before changing your strategy

    A funding round is evidence that investors were willing to finance a company on negotiated terms. It is not a product certification, an independent performance test, or proof that customers are receiving a positive return.

    The distinction matters because the headline contains several figures that are easy to misread. The $96 million is financing, not revenue. The $1 billion valuation is the value assigned to the company in the context of the transaction, not cash deposited into its accounts. Neither figure tells you how much customers spend, whether the business is profitable, how well its software performs, or how the new capital will be allocated.

    Series C also describes a financing stage, not a universal level of product maturity. It can support expansion after earlier growth, but the label does not guarantee stable data, complete model coverage, enterprise-ready controls, or a roadmap that matches your needs.

    • What the round establishes: Profound has attracted substantial private backing for an AI marketing platform.
    • What it reasonably signals: the participating investors see enough potential to finance further growth at the announced valuation.
    • What it does not establish: that Profound is the right platform for your use case, that AI visibility software has settled on a standard methodology, or that a large valuation predicts your results.

    That last point should shape your response. Do not rewrite your AI strategy around a financing headline. Use the event as a reason to update your assumptions, inspect the category, and ask vendors harder questions.

    Where fresh capital could change the AI marketing market

    Golden light branches from a central reservoir toward abstract product, infrastructure, expansion, and support structures, with some paths fading into mist.

    Capital gives Profound more options. It could fund product development, infrastructure, model and market coverage, integrations, hiring, customer support, or go-to-market expansion. Those are possibilities, not disclosed commitments. Treat them as items to verify through shipped capabilities, release records, service levels, and written commercial terms.

    The broader signal is that investors are willing to place significant capital behind the problem of marketing through AI-generated answers. That is relevant if you have been treating AI visibility as a temporary reporting experiment. It suggests that the category may attract more product development, sales activity, and competition. One transaction, however, does not establish the size of customer demand or prove that AI search has replaced conventional search.

    Your operating model should therefore connect AI visibility to the rest of search and content work instead of building an isolated dashboard. A useful workflow has four linked jobs:

    • Observe: identify where your brand, products, experts, and pages appear or disappear in relevant AI answers.
    • Diagnose: determine whether the issue involves ambiguous entities, missing evidence, inaccessible content, inconsistent facts, weak third-party corroboration, or an irrelevant prompt sample.
    • Intervene: improve the assets you control, including factual copy, source pages, technical accessibility, appropriate structured data, and evidence that other publishers can verify.
    • Validate: repeat the measurement, inspect the underlying answers and citations, and connect any change to a business decision rather than celebrating a score in isolation.

    A platform that performs only the observation step may still be useful, but it has not completed the marketing job. The value appears when your team can trace a detected issue to a defensible action and then check whether that action changed anything meaningful.

    Use a buyer’s scorecard, not the valuation

    If you are evaluating Profound or another AI visibility platform, apply the same scorecard to every vendor. This prevents brand momentum, investor names, and polished aggregate scores from substituting for evidence.

    Start with measurement integrity. Ask which AI models and user experiences are covered, which markets and languages are supported, and whether the results represent live answers, an external data provider, or another collection method. Model output can vary with prompt wording, model version, user context, and repeated runs. You need to know how the platform handles that variability before treating movement as a trend.

    • How are prompts selected, grouped, weighted, and updated?
    • Can you inspect the exact prompt, answer, cited pages, collection time, and relevant execution context behind every score?
    • Does the system distinguish a brand mention from a recommendation, a citation, a comparison, or a factual statement?
    • How does it prevent changes in prompt coverage from looking like changes in brand performance?
    • Can you preserve a stable benchmark while separately exploring new prompts and models?
    • How are failed collections, unavailable models, duplicate answers, and ambiguous brand names handled?

    A visibility score that cannot be decomposed is difficult to act on. If the score rises, you should be able to see which answers changed and why. If it falls, you should be able to distinguish a real deterioration from a collection or coverage change.

    Then test actionability. Ask the vendor to walk from a detected problem to a recommended intervention using your own data. A useful recommendation identifies the affected audience, the evidence behind the diagnosis, the asset or relationship that needs work, the owner who can act, and the signal that would count as improvement.

    • Does the platform separate issues on your website from gaps in third-party authority?
    • Can recommendations point to the exact pages, claims, citations, or entity conflicts involved?
    • Does it explain where structured data is relevant without presenting schema as a guarantee of inclusion in an AI answer?
    • Can findings flow into the content, SEO, analytics, public relations, and product workflows your team already uses?
    • Can analysts annotate changes so later reporting does not confuse an intentional intervention with unexplained movement?

    Finish with commercial and operational resilience. Funding may improve a vendor’s capacity to invest, but it does not remove switching costs or contractual risk. Get data ownership, export access, retention, usage limits, overage rules, support scope, renewal terms, and the total expected cost in writing. Confirm what happens to your historical data if you leave. Treat roadmap slides as possibilities until a capability is included in the agreement or available in the product.

    Run a controlled evaluation around a real decision

    An evaluator compares two unbranded AI systems in parallel testing bays using identical inputs and a central balance mechanism.

    The cleanest way to evaluate an AI marketing platform is to make it answer a decision your team already faces. Do not begin with, “Can this produce an interesting dashboard?” Begin with a question such as, “Can this show us why qualified buyers encounter competitors instead of us, and can it help us choose what to change?”

    1. Define the decision. Name the audience, product or service, market, and business question. Decide who will act if the platform finds a credible problem.
    2. Create a representative prompt set. Include branded and unbranded questions from different stages of the buying journey. Write down why each prompt matters. Keep the core set stable so a changing sample does not masquerade as performance movement.
    3. Capture a manual baseline. Save the exact prompts, visible answers, citations, model or surface, and relevant context. Note entity ambiguity and obvious collection errors before introducing a vendor score.
    4. Run the platform against the same scope. Compare its output with the baseline. Investigate disagreements rather than assuming the platform or the manual sample is automatically correct.
    5. Act on findings you can verify. Correct inconsistent facts, strengthen useful first-party pages, improve crawlability, add appropriate structured data, and pursue credible third-party coverage where the diagnosis supports those actions.
    6. Judge decision value. Ask whether the platform found important issues accurately, explained them clearly, helped the right owner act, preserved evidence, and made follow-up measurement more reliable.

    Keep AI visibility metrics in their proper place. Mentions, citations, answer share, and sentiment can be useful intermediate signals, but they are not automatically revenue or causation. If a dashboard improves after you change content, inspect the underlying answers. If business outcomes also change, examine other campaigns, seasonality, brand activity, and measurement gaps before assigning credit.

    Be equally cautious with promises of fixed placement. Generative answers are not conventional ranking tables, and their behavior can change. A credible evaluation should show variability, preserve raw evidence, and describe uncertainty instead of hiding it inside a single precise-looking number.

    Key takeaways

    • Profound announced a $96 million Series C and a $1 billion valuation, with Lightspeed Venture Partners leading the round.
    • The financing signals investor conviction and gives the company more strategic options; it does not prove product performance, revenue, profitability, or customer return.
    • For AI marketers, the round is a reason to take the category seriously, not a reason to replace a working stack without evaluation.
    • A useful AI visibility platform must expose prompts, answers, citations, collection context, and methodology behind its scores.
    • Your evaluation should connect observation to diagnosis, intervention, and validation using a stable prompt set and a manually checked baseline.
    • Commercial diligence still matters: verify exports, data ownership, limits, support, renewal terms, switching costs, and delivered capabilities before making a long-term commitment.

    Treat Profound’s funding as a prompt to sharpen your vendor questions, not to change strategy overnight. Preserve your baseline, test the platform against a decision that matters, and commit only when its data survives manual inspection and fits the way your team acts. That lets you benefit from a better-funded category without outsourcing your judgment to its valuation.

    References

  • What Perplexity’s Ad Retreat Means for AI Search Strategy

    What Perplexity’s Ad Retreat Means for AI Search Strategy

    If Perplexity appears in your paid AI media plan, change the plan, not the audience strategy. The company has phased out its sponsored-placement experiment and has no current intention of bringing it back. Brands can still pursue visibility across Perplexity’s answers, but they cannot currently treat that visibility as inventory they can buy.

    The practical shift is from placement control to evidence quality. You need content that an answer engine can understand, claims it can support, a brand it can identify consistently, and measurement that distinguishes citations from mentions, referrals, and actual business results.

    Perplexity is treating trust as part of the product

    Perplexity began testing sponsored placements in 2024. Sponsored answers appeared beneath chatbot responses, were labeled as advertising, and were presented as separate from the system’s answer selection. The experiment still created a deeper problem: disclosure can identify a commercial relationship, but it cannot force a user to believe that the surrounding answer is free from commercial influence.

    That distinction matters in an answer engine. A conventional results page visibly separates advertisements from organic links and leaves the user to choose among them. An AI interface synthesizes information into a direct response. If an advertisement sits close to that response, the user may wonder whether payment affected the conclusion, even when the company says it did not. Perplexity decided that protecting the belief that users receive the best available answer was more valuable than continuing the test.

    This is not simply an anti-advertising position. It is a choice about which revenue model creates the least damaging perceived conflict. Perplexity is relying primarily on subscriptions, with paid plans reported between $20 and $200 per month, more than 100 million users, and approximately $200 million in annual revenue. Those are reported company-scale figures, not proof that subscriptions will fund every future ambition, but they explain why Perplexity can give trust more weight in the trade-off.

    The same boundary appears in commerce. Perplexity has introduced shopping features but does not take a cut of the transaction. That keeps the platform from earning more merely because it recommends one purchasable result over another. Subscriptions still create business incentives, but the revenue connection is more direct: users pay for access rather than brands paying for proximity to an answer.

    Do not turn the current decision into a permanent promise. A platform strategy can change as costs, competition, and user behavior change. Treat Perplexity as ad-free for planning purposes while maintaining a watchlist for any documented relaunch, rather than building a forecast around an assumed future product.

    Remove paid Perplexity inventory from forecasts, not Perplexity from the plan

    Perplexity reportedly handles 780 million queries per month. That signals substantial usage, but it is not an advertising forecast. Query volume does not tell you how many impressions a brand could buy, which audiences would be reachable, what targeting would exist, or whether exposure would produce qualified visits. Without an active ad product, it cannot be converted into CPMs, clicks, or revenue projections.

    If you own a media plan, make four operational changes:

    1. Move Perplexity advertising out of committed spend. Do not promise inventory, delivery, or launch dates based on the discontinued test. That creates a budget gap and a client commitment you cannot fulfill.

    2. Keep Perplexity in the discovery strategy. Assign ownership to the SEO, AEO, GEO, content, or digital PR workstream responsible for earned visibility.

    3. Preserve relevant creative and audience hypotheses. If ads return, the messaging lessons may remain useful even if the eventual format, targeting, and reporting differ.

    4. Define relaunch evidence in advance. Require an official product announcement, access terms, placement rules, pricing, labeling, targeting, measurement, and brand-safety controls before moving money back into the forecast.

    Do not create one universal policy for all AI products. At the time Perplexity ended its experiment, OpenAI was testing ads for free ChatGPT users, Google was placing ads in AI Mode but not Gemini, and Anthropic was keeping Claude ad-free. Monetization can differ between companies and between products owned by the same company.

    Your channel sheet should therefore use the product surface as the unit of planning. For each surface, record the current ad status, who can access it, where sponsorship appears, how it is labeled, what can be targeted, which reports are available, and when the status was last verified. A row labeled only “AI advertising” is too broad to support a real budget decision.

    Build the visibility that sponsored answers can no longer provide

    A bridge assembled from documents, evidence blocks, and verification seals leads toward a glowing abstract answer engine.

    You cannot choose where Perplexity mentions or cites you in the way you choose an ad placement. You can improve the inputs that make your organization useful as an answer source. The goal is eligibility and clarity, not a guaranteed citation.

    1. Map the questions that precede a decision. Include problem-identification queries, category questions, comparisons, brand-verification questions, objections, risks, and action-oriented queries. Use the language customers use, not only the terms in your navigation.

    2. Give each important page a clear answer job. State the useful answer near the top, then support it with definitions, evidence, limitations, examples, and next steps. A page that hides its conclusion behind a long preamble makes the core claim harder for both people and machines to isolate.

    3. Make claims attributable. Identify who produced the information, when it was updated, what the claim covers, and where its limits begin. If you publish original data, explain the method and scope. If you make a comparison, name the criteria instead of declaring a vague winner.

    4. Keep entity facts consistent. Your company name, product names, author names, service descriptions, locations, and ownership relationships should agree across the site. Conflicting facts create an identification problem before they create a ranking problem.

    5. Use structured data to clarify, not decorate. Organization and Person markup can express publisher and author identity; Article can describe editorial content; Product belongs on genuine product pages; and FAQPage should represent questions and answers visitors can actually see. JSON-LD can make relationships explicit, but it cannot rescue unsupported claims or guarantee inclusion in Perplexity.

    6. Close evidence gaps outside your site. If competing brands are repeatedly supported by independent explanations, reviews, or industry references and yours is not, publishing more self-description may not solve the gap. Give credible third parties something verifiable to reference: transparent data, a useful tool, clear documentation, expert commentary, or a defensible point of view.

    7. Maintain the pages that carry important facts. Correct obsolete details, preserve useful URLs, show meaningful update information, and avoid leaving contradictory versions live. An answer engine cannot reliably resolve a disagreement your own site has not resolved.

    This work should not imitate an advertisement. Promotional adjectives, unsupported superlatives, and repeated brand mentions add little evidence. A strong answer asset lets the underlying facts do the selling: it answers the question, shows why the answer is credible, states who the answer is for, and acknowledges conditions where a different choice may be better.

    Trust is also part of your own publishing system. Label sponsorships, disclose affiliate relationships, separate editorial conclusions from commercial arrangements, and make corrections visible. Perplexity’s decision shows why technical disclosure alone is not enough. Readers also judge whether the surrounding incentives could have shaped the answer.

    Measure answer visibility without pretending it is a fixed ranking

    Multiple translucent lenses show different arrangements of source cards and pathways around a spherical answer engine.

    A generative answer is an observation made under particular conditions, not a permanent search position. Record enough context to reproduce the check: the exact prompt, date and time, account state, answer text, brand mentions, cited URLs, linked pages, competitor mentions, and whether each statement about your brand is accurate.

    Repeat the same query set on a fixed cadence and preserve the results. If you change prompts continually, you cannot tell whether the platform changed or the question changed. If you check only once, you cannot distinguish a durable pattern from normal answer variation.

    Observed stateWhat it meansWhat to do next
    Cited and described accuratelyYour page is functioning as supporting evidence for that query.Preserve the useful URL, keep its facts current, and examine which passage appears to support the answer.
    Mentioned without a citationThe brand is present, but the answer does not visibly attribute the claim to your page.Identify the claim being made and strengthen the page that can support it with explicit, attributable evidence.
    Cited but described inaccuratelyVisibility is creating a reputation or conversion risk.Publish the correct fact prominently, remove contradictions, verify canonical pages, and monitor whether the answer changes.
    Absent while relevant competitors appearThe gap may involve content coverage, entity clarity, evidence quality, or independent corroboration.Compare the cited pages by question answered, evidence supplied, freshness, specificity, and source authority. Fix the missing component instead of copying their wording.
    Results vary across repeated checksThe evidence is not stable enough for a strategic conclusion.Expand the observation history and avoid reporting a gain or loss until a pattern emerges.

    Separate visibility metrics from outcome metrics. Useful visibility measures include brand inclusion rate, citation coverage, citation accuracy, and share of observed answers relative to named competitors. Outcome measures include referral sessions, engaged visits, assisted conversions, leads, and revenue from identifiable Perplexity traffic. A citation can be strategically valuable without generating a click, but that does not justify presenting it as traffic or sales.

    When a result changes, diagnose it at the query-and-page level. Ask which claim disappeared, which URL replaced yours, whether your linked page changed, and whether the competing evidence is more direct. A single sitewide “AI visibility score” can be useful for reporting direction, but it cannot tell an editor which paragraph, fact, entity relationship, or evidence gap needs attention.

    Key takeaways

    • Perplexity’s discontinued ad test removes a direct paid route to its audience; it does not remove the audience from your search strategy.

    • Labeled advertising can satisfy disclosure requirements while still weakening perceived answer independence. Trust depends on incentives as well as interface labels.

    • Do not convert monthly query volume into an advertising forecast when no active inventory, targeting, pricing, or reporting product exists.

    • Treat Perplexity visibility as earned. Improve answer coverage, attributable evidence, entity consistency, structured data, independent corroboration, and factual maintenance.

    • Measure citations, uncited mentions, accuracy, competitor inclusion, referrals, and conversions separately. They answer different business questions.

    • Track advertising status by product surface. ChatGPT, Google AI Mode, Gemini, Claude, and Perplexity do not share one monetization policy.

    Start by moving Perplexity from the paid-inventory line of your plan into an owned-and-earned AI visibility workstream. Establish a repeatable query set, capture the current baseline, and assign each meaningful gap to a specific page, fact, schema relationship, or authority-building task. If advertising returns, evaluate the actual product then. Until it does, the durable advantage is being useful enough to earn a place in the answer.

    References

  • How to Use AI-Powered Advertising Without Losing Control

    How to Use AI-Powered Advertising Without Losing Control

    Your ad platform can now reach beyond the audience you selected, produce analysis inside the campaign interface, and decide which entertainment title is most likely to interest a viewer. Those capabilities may all carry the AI label, but they do not create the same risk or require the same supervision.

    Your job is not to recover every manual lever. It is to decide what the system may optimize, which boundaries it must respect, and what evidence it must produce before you give it more budget. That requires a control system built for automation rather than a longer list of settings.

    The control surface has moved from audience settings to campaign inputs

    Manual advertising made control easy to see. You selected an audience, chose a similarity range, and expected delivery to remain within it. AI-led delivery weakens that visual connection. A setting can influence the model without defining the final audience.

    Google’s announced March 2026 change to Demand Gen Lookalike segments illustrates the shift. Narrow, balanced, and broad similarity tiers become optimization signals instead of rigid targeting limits. Google can reach beyond the selected segment when its system predicts that other users are likely to convert.

    That distinction changes how you should read the campaign setup. A Lookalike tier still communicates useful direction, but it no longer answers the eligibility question by itself. Optimized Targeting remains a separate feature, and layering it with Lookalike signals can give the system additional room to expand.

    Before you launch or diagnose an AI-powered campaign, classify every important input as one of four things:

    • Objective: the result the platform is being asked to maximize, such as a purchase, subscription, ticket sale, or another conversion.
    • Signal: information that helps the model search, such as a seed audience, similarity tier, genre preference, or observed price sensitivity. A signal provides direction; it does not necessarily restrict delivery.
    • Constraint: a boundary the campaign must not cross, such as a spend ceiling, eligible territory, product restriction, or contractual audience requirement.
    • Observation: a metric you use to understand behavior but have not asked the model to optimize, such as reach, conversion rate, or downstream customer quality.

    Do not call a signal a constraint unless the platform’s current behavior explicitly guarantees it. If a territory, age rule, customer exclusion, or other eligibility condition is commercially or legally important, confirm the setting that enforces it. An audience seed is not a safe substitute for a hard boundary.

    Keep a campaign change log with the date, campaign, previous setting, new setting, whether the change was automatic or manual, the expected effect, and the person responsible for reviewing it. This small record becomes essential when the platform changes its interpretation of a familiar control. Without it, a sudden increase in reach can look like creative success when it was actually caused by audience expansion.

    Write an optimization contract before you spend

    A human hand adjusts safety stops around a tabletop model containing audience figures, creative tiles, budget tokens, and an objective marker.

    An AI system can optimize only what you make legible to it. If the selected conversion event is a weak proxy for the business result, the platform can improve its own score while sending the campaign in the wrong direction. A system asked to find inexpensive page visits should not be expected to discover profitable customers by implication.

    Write a short optimization contract for each campaign. It does not need legal language or a new software tool. It needs six explicit decisions:

    1. Name the business outcome. State what has to happen outside the advertising interface: a paid subscription, completed ticket purchase, qualified opportunity, retained customer, or another result that matters to the business.
    2. Name the platform event. Record the event the platform can observe and optimize. If that event occurs earlier than the business outcome, describe the gap instead of pretending the two are equivalent.
    3. Choose one primary score. CPA, conversion rate, conversion volume, and reach answer different questions. Select the metric that decides whether the test passes, then use the others for diagnosis.
    4. Set economic and eligibility boundaries. Use your actual unit economics to define an acceptable acquisition cost and a campaign spend limit. Record territories, offers, audiences, and products that are not eligible for expansion.
    5. Define the quality check. Decide how you will notice low-value conversions. Depending on the campaign, that may be completed purchases, valid subscriptions, qualified leads, attendance, retention, or another downstream signal.
    6. Assign decision rights. State which changes AI may make automatically, which recommendations require human approval, and who can pause, expand, or revert the campaign.

    For an entertainment release, the contract might connect the ad platform’s purchase event to paid tickets, use CPA as the primary score, monitor conversion rate and reach for diagnosis, restrict delivery to eligible markets, and require a human review before a material budget increase. The exact thresholds should come from the release’s economics, not from a generic platform benchmark.

    Do not broaden the audience and increase the budget in the same test step. If performance changes, you will not know whether the cause was additional delivery freedom, additional spend, or an interaction between them. Change one source of freedom, observe the result through the normal conversion lag, and then decide whether the next increment is justified.

    Supervise each kind of advertising AI differently

    AI-powered advertising is not one operating mode. Some features help you analyze a campaign. Some change who receives an ad. Others personalize the content or format presented to a user. The amount and location of human review should follow the type of decision being automated.

    AI roleWhat it changesMain control questionHuman checkpoint
    Decision supportReports, summaries, and audience researchIs the analysis based on the right data and definitions?Verify filters, calculations, and causal claims before acting
    Audience expansionWho may receive the ad beyond the original seedWhich inputs are signals, and which are enforceable boundaries?Audit expansion settings, eligibility, and conversion quality
    Content and format selectionWhich title, card, or presentation a user seesDoes the selected format match the buying decision?Measure the business outcome by title, offer, and market

    Google Demand Gen: audit expansion before interpreting performance

    Start by finding out which targeting behavior actually applies to the campaign. Under Google’s announced transition, campaigns move to the signal-based Lookalike model unless the advertiser uses the dedicated opt-out route for traditional behavior. If restricted audience eligibility is important, verify the account’s current setting rather than relying on the familiar name of the segment.

    Record the selected Lookalike tier even though it is now a signal. It remains part of the model’s direction and therefore part of the test. Record the Optimized Targeting status separately because the two mechanisms are not interchangeable and can operate together.

    Then read the result as a sequence rather than a single KPI:

    • Did reach expand beyond the pattern you expected?
    • Did conversion volume rise with that expansion?
    • Did conversion rate and CPA remain commercially acceptable?
    • Did the additional conversions produce the same downstream quality as the original audience?

    More reach is evidence that the delivery system found more people. It is not evidence that it found better customers. A lower CPA is more promising, but it still needs a quality check if the platform conversion can include low-value or incomplete outcomes.

    Use the traditional targeting option when strict audience control is a real requirement or when you need a clean baseline. Do not opt out merely because expansion feels less familiar. Conversely, do not accept expansion merely because it is the default. The right choice depends on whether scale or controlled eligibility is the binding constraint for that campaign.

    Meta Ads Manager: treat Manus as an analyst, not an authority

    Meta has embedded Manus AI in Ads Manager, where it can assist with report creation and audience research. This is decision-support automation. It may shorten the route from raw campaign data to a usable analysis, but a faster report is not the same as better ad delivery.

    Give the assistant bounded analytical tasks. A useful request names the account or campaign, date range, metrics, comparison, segments, and desired output. Asking for a performance report without those details invites the system to choose definitions that may not match the decision in front of you.

    Review every AI-built report at three levels:

    • Data scope: confirm the campaigns, dates, markets, and filters included.
    • Metric meaning: confirm that conversions, CPA, reach, and other measures use the definitions required by your optimization contract.
    • Inference: separate what changed from why it changed. A report can identify a correlation without proving that an audience, creative, or platform action caused it.

    Audience research generated inside the workflow should become a testable hypothesis, not an immediate budget instruction. Translate the output into a specific question: which audience, which offer, which expected behavior, and which metric would disprove the idea? That keeps the assistant useful without allowing polished language to substitute for evidence.

    Measure Manus first by workflow outcomes: whether it reduced repetitive report building, made useful segments easier to inspect, or surfaced a hypothesis worth testing. Claim an advertising performance gain only when a controlled campaign decision produces one. The presence of AI inside Ads Manager does not establish that causal link by itself.

    TikTok entertainment ads: match the AI format to the buying decision

    TikTok’s European rollout separates two useful entertainment jobs. Streaming Ads can personalize a four-title video carousel or multi-title media card using user interaction, while New Title Launch is designed to find high-intent audiences using signals such as genre preference and price sensitivity.

    Choose between them by starting with the decision you need the viewer to make:

    • Use the streaming format for catalog discovery. Multiple titles make sense when the viewer can enter through more than one piece of content and the business outcome is a subscription, viewership action, or another catalog-level result.
    • Use the launch format for a concentrated release. High-intent signals are more relevant when one title, event, or cultural moment needs to produce tickets, subscriptions, or attendance.

    Do not let personalization blur the measurement unit. Tag and review results by title, offer, and eligible market. If a multi-title unit generates strong interaction but only one title produces the intended business outcome, the useful finding is not that the carousel worked equally well. It is that the AI found an effective entry point that deserves a title-level follow-up.

    TikTok says 80% of its users report that the platform influences their streaming decisions. Treat that vendor-supplied figure as context for why TikTok built the formats, not as a forecast for your campaign. It does not mean 80% of the people you reach will subscribe, buy, or attend. Your optimization contract and campaign evidence still determine whether the format earns more spend.

    Test automation without creating an uninterpretable result

    An analyst observes two isolated campaign-testing lanes, one stable and one containing a glowing automation module.

    The hardest failure to detect is not a campaign that performs badly. It is a campaign that changes in several ways, appears to improve, and leaves you unable to explain which change mattered. AI makes this easier to do because an apparently small setting can alter the system’s decision space.

    Use this sequence whenever a platform introduces a new AI feature or changes the meaning of an existing control:

    1. Write one test question. For example: does signal-based audience expansion increase valid conversion volume while keeping CPA and downstream quality within our limits?
    2. Capture the starting state. Save the objective, conversion event, audience inputs, similarity tier, expansion settings, budget, creative, geography, and any other condition that could affect delivery.
    3. Change one category of decision. Test audience freedom, analytical workflow, format selection, creative, or budget separately whenever the platform and campaign volume make that possible.
    4. Choose the evaluation window from the conversion process. Allow the normal conversion lag to pass before judging results. Do not declare a winner from an incomplete cohort simply because the interface is already showing activity.
    5. Use the strongest comparison available. Prefer a platform experiment when a valid one is available. Otherwise, keep surrounding inputs stable and label a before-and-after comparison as observational rather than causal proof.
    6. Inspect business quality as well as platform efficiency. Compare valid purchases, qualified leads, paid subscriptions, ticket completions, attendance, or the downstream outcome specified in the contract.
    7. Make an explicit decision. Scale, hold, narrow, opt out, or revert. Record the evidence and the unresolved uncertainty so the next review does not restart the argument from memory.

    Set a spend ceiling before the test begins. If the experiment can consume a meaningful amount of budget without producing interpretable evidence, reduce its exposure or improve the measurement design first. Automation does not suspend the campaign’s economics.

    Watch for four false wins. More reach without better outcomes is distribution, not success. A lower platform CPA with weaker downstream quality is metric substitution. A faster AI-generated report is a workflow gain, not a campaign lift. An improvement that appears after simultaneous audience, creative, budget, and format changes is a lead for another test, not a reliable conclusion.

    Key takeaways

    • AI advertising control now depends more on objectives, data, constraints, and review rules than on the number of manual audience settings.
    • A seed audience, similarity tier, or behavioral input may guide a model without restricting delivery. Verify hard eligibility boundaries separately.
    • Write an optimization contract that connects the platform event to a business outcome, an economic limit, a quality check, and a named decision owner.
    • Supervise decision-support AI, audience expansion, and content-selection AI differently. They automate different decisions and create different failure modes.
    • Do not award more budget for reach, reporting speed, or a vendor benchmark. Scale only when the campaign improves the predefined business result within its constraints.

    Before your next campaign review, take one active campaign and write down its objective, signal, hard constraints, primary score, quality check, and stop decision. If you cannot fill in all six, do not give the system more freedom yet. Once those answers are clear, you do not need every old manual lever. You have something more useful: accountable control.

    References

  • Advertising in AI Experiences: A Practical Readiness Plan

    Advertising in AI Experiences: A Practical Readiness Plan

    If you’re being asked for an “AI ads strategy,” don’t start by moving a search campaign into a new interface. An AI experience may be answering a question, narrowing a comparison, selecting an offer, or helping complete a purchase. Your ad has to help with that task without pretending to be the answer.

    The practical job is to make four things line up: the user’s decision, the claim the system can verify, the offer you can honor, and the next action you can measure. When one breaks, more targeting or more generated creative won’t rescue the experience.

    AI ads compete for the next useful action

    A conventional search ad usually occupies a known slot between a query and a landing page. An ad inside an AI experience enters a more fluid sequence. The user may have already described constraints, rejected alternatives, requested a comparison, or asked the system to help complete a task.

    That does not mean advertisers automatically receive the conversation or control the answer. In the initial ChatGPT design, ads are limited to the Free and Go tiers, kept separate visually and technically from model answers, and hidden from Plus, Pro, and Enterprise users. The model is not informed that an ad is present and does not refer to it unless the user asks. Treat that separation as a real product boundary, not a temporary obstacle to work around.

    Google is pursuing a different but related path. Conversational and visual discovery in AI Mode can include sponsored retail listings and Direct Offers intended to help a user continue a shopping journey. The useful planning unit is therefore not merely the keyword, placement, or audience. It is the decision the user is trying to make.

    Rewrite each campaign brief as a decision task. “Reach operations leaders” is an audience description. “Help an operations leader compare tools that meet a stated integration requirement” is a task. The second version tells your team what facts, offer, destination, and measurement the experience needs.

    • User state: What has the person probably established before a sponsored option becomes useful?
    • Decision constraint: Which requirement, location, budget condition, compatibility need, or availability question narrows the choice?
    • Verifiable claim: What can your site, feed, structured data, or product record support without interpretation?
    • Useful next action: Should the user inspect an offer, compare configurations, check availability, request qualification, or complete a purchase?
    • No-ad condition: In which contexts would promotion be irrelevant, sensitive, misleading, or unsafe?

    The same principle applies outside chat. AI can help connect brands with YouTube creators and turn creator-led discovery into commerce. Define creator fit through the audience problem, acceptable claims, and commercial handoff – not reach alone. A highly visible creator cannot repair a mismatched offer or an unsupported product promise.

    Build answer, offer, and transaction readiness in that order

    Three connected stations depict product answers and evidence, an available offer, and a secure transaction in sequence.

    AI advertising readiness is not a media-only project. The system may need to understand your business, retrieve a current offer, and pass the user into a reliable transaction. Those are separate layers, and each can fail independently.

    Answer readiness: make the commercial facts unambiguous

    Your organic AI visibility and your paid eligibility are different, but they depend on a shared factual foundation. A discovery system should be able to identify what you sell, who it is for, where it is available, what conditions apply, and which page is authoritative.

    • Give every important product, service, location, and offer a stable name and a canonical destination.
    • State the qualifying details in visible page copy. Do not leave essential limitations inside an image, sales deck, or support conversation.
    • Keep names, identifiers, prices, service areas, availability, and eligibility language consistent across pages.
    • Use relevant Schema.org types such as Organization, Product, Service, Offer, and LocalBusiness where they accurately describe visible content.
    • Make JSON-LD match the page. Structured data that promises more than the user can see creates ambiguity rather than authority.
    • Separate factual descriptions from promotional language so a system can retrieve a supportable claim without inheriting the slogan around it.

    No schema type guarantees inclusion in an AI answer or an ad placement. The point of structured data is to reduce ambiguity and connect entities, properties, and offers. It cannot compensate for missing content or contradictory records.

    Offer readiness: synchronize what the user can actually receive

    An AI-matched ad becomes unhelpful the moment its offer is stale. This matters more when a sponsored option is presented after the user has already supplied detailed constraints. The apparent relevance raises the cost of a mismatch.

    For retail, reconcile the identifier, title, destination URL, price, currency, availability, variant, shipping terms, return terms, and promotion conditions across the feed, landing page, structured data, and checkout. For services, do the equivalent with the service area, qualification rules, deliverable, capacity, expected handoff, and any condition that can disqualify the lead.

    Assign an owner to every field that can change. Then define which system is authoritative when two records disagree. “The feed team owns price” is incomplete if checkout can display something else. The useful rule is operational: when the source of record changes, every consumer of that field must receive the update, and the affected offer should stop serving if synchronization fails.

    Transaction readiness: design for safe completion and failure

    Agentic commerce shortens the distance between recommendation and purchase. Google’s Universal Commerce Protocol is intended to standardize AI-assisted browsing, purchasing, and transaction completion. That makes checkout reliability, inventory state, and exception handling part of advertising quality.

    • Require clear authorization before a charge, booking, subscription, or binding order.
    • Make order creation idempotent so a retry does not create a duplicate transaction.
    • Validate price, inventory, tax, shipping, eligibility, and promotion status at the point of commitment.
    • Return an unambiguous confirmation with the item or service, amount, status, and next step.
    • Provide a usable path for cancellation, correction, refund, and human escalation.
    • Preserve enough event history to determine whether an error began in the ad, offer record, handoff, or transaction system.

    Do not enable an automated purchase path while duplicate-order protection, cancellation, or exception handling remains untested. The downside is not a weak engagement metric; it is an incorrect charge, unavailable order, or commitment the user did not understand. Keep a confirmation step and a conventional checkout alternative until the failure paths are reliable.

    Make trust part of delivery, not a policy page

    Relevance does not excuse hidden influence. An AI answer carries a different kind of perceived authority from a familiar ad slot, so sponsorship has to remain legible at the moment the user evaluates the recommendation.

    ChatGPT’s initial guardrails include not sharing conversations with advertisers, excluding ads from health, politics, and other sensitive discussions, and giving users personalization controls. These are platform-specific commitments, not universal rules for every AI ad product. Verify the controls and exclusions of each channel before you approve a campaign.

    Your own delivery specification should cover the following:

    • Sponsorship: Do not write creative that could be mistaken for the assistant’s independent conclusion or an organic citation.
    • Context exclusions: Document the tasks and sensitive situations in which your offer should not appear, even if the platform allows the placement.
    • Data boundary: Record which contextual signals the platform exposes and which user data reaches your systems. Do not reconstruct a private conversation from unrelated identifiers.
    • Claim control: Link every material claim to an approved fact, product record, policy, or landing-page statement.
    • Personalization control: Make consent, preference changes, and opt-out behavior understandable wherever your own data collection begins.
    • Correction path: Give users and internal reviewers a direct way to report an inaccurate offer, misleading claim, or broken handoff.

    Keep paid visibility and AI visibility on separate scorecards

    Do not report a sponsored appearance as proof that a model independently recommends your brand. Do not report an organic mention as paid campaign delivery. They answer different questions.

    • Organic AI visibility: Can the system identify the brand, retrieve accurate facts, answer the relevant question, and cite or mention the right entity?
    • Paid AI delivery: Was the sponsored option eligible, shown in an appropriate context, acted on by a qualified user, and connected to a valid offer?
    • Shared quality: Did the destination substantiate the claim, preserve context, and produce an acceptable customer outcome?

    This separation protects your reporting and your optimization. A bid or budget cannot make weak facts more authoritative. Better organic answer coverage does not guarantee sponsored distribution. Both programs can improve the same landing pages and entity records without pretending to be the same channel.

    Put generated creative behind a claim gate

    Generative tools can make asset production much faster. Google’s advertising direction includes Gemini 3, Nano Banana, Veo 3, and AI Max for creative production, reach, and campaign optimization. Faster production increases the need for tighter review because one outdated input can be repeated across many polished variations.

    Start creative generation from an approved claim set, not an open-ended prompt. Require each variation to retain the qualifying language, destination, and current offer. Store the asset with its source claim and offer identifier. When the underlying fact changes, you can then find and retire every affected version instead of searching campaigns by eye.

    Run the first pilot around one decision, not a whole funnel

    A shopper compares three products with help from verified evidence and a distinct promotional offer while a small team observes the decision.

    A broad launch makes diagnosis difficult. If performance disappoints, you will not know whether the problem was matching, creative, answer readiness, offer accuracy, the landing-page handoff, or transaction friction. A narrow pilot gives each failure somewhere specific to land.

    1. Choose a bounded decision task. Define what the user is trying to decide and the conditions that make your offer relevant or irrelevant.
    2. Create a truth set. Record approved claims, prohibited claims, current offers, exclusions, systems of record, and field owners.
    3. Build the complete path. Review the sponsored message, destination, structured data, offer record, form or checkout, confirmation, and exception route as one experience.
    4. Instrument the handoff. Capture the channel, placement type, campaign, asset, offer identifier, destination, qualified action, completed outcome, and any reversal without collecting private conversational content.
    5. Establish a counterfactual. Use a platform experiment or holdout when available. If neither is available, document a stable baseline and state clearly that the result is directional rather than incremental.
    6. Expand only after quality holds. Increase the range of tasks, offers, or creative after the pilot produces accurate offers, acceptable outcomes, and no recurring trust failure.

    Click-through rate can diagnose whether a sponsored option attracts attention, but it cannot tell you whether the AI-assisted decision was good. Define qualification and completion before launch, then measure the handoff with metrics that expose both performance and failure.

    MetricHow to calculate itWhat it helps you decide
    Qualified action rateQualified actions divided by attributed AI ad visitsWhether matching and creative are producing commercially relevant responses
    Offer consistency rateAudited offers whose ad, destination, structured data, and transaction terms agree divided by all audited offersWhether the commercial data is dependable enough to scale
    Decision completion rateConfirmed target outcomes divided by eligible initiated pathsWhether the handoff helps the user finish the intended task
    Outcome quality rateAccepted, retained, or otherwise qualified outcomes divided by completed outcomesWhether apparent conversions remain valuable after validation
    Mismatch or complaint rateRecorded relevance, sponsorship, offer, or transaction complaints divided by attributable interactionsWhether utility is being purchased at the cost of trust
    Incremental outcomeDifference between exposed and valid comparison groupsWhether the channel created value beyond outcomes that would have happened anyway

    Set the definitions, data owner, and decision rule for each metric before anyone sees campaign results. Otherwise, teams tend to relax the meaning of “qualified” or emphasize whichever event improved.

    Pause the affected offer or path when the ad claim is absent from the destination, displayed terms disagree with checkout, inventory cannot be confirmed, users mistake sponsorship for an independent answer, or additional conversions arrive with a corresponding rise in reversals, refunds, or disqualified leads. These are not creative-learning signals. They indicate that the experience is making a promise the operating system cannot reliably keep.

    Key takeaways

    • Plan AI advertising around a user’s decision task, not merely a keyword, audience, or placement.
    • Treat answer readiness, offer accuracy, and transaction reliability as separate layers with named owners.
    • Keep sponsored delivery visibly separate from model answers and report paid exposure separately from organic AI visibility.
    • Use structured data to clarify visible facts, never to introduce claims or terms that the page does not support.
    • Measure qualified outcomes, offer consistency, completion, and trust failures alongside attention metrics.
    • Scale only after the entire path can preserve context, honor the offer, and handle exceptions safely.

    Your first move does not need to be a large media commitment. Choose a commercially important decision, make its facts and offer machine-readable, connect it to a dependable action, and define the conditions that will stop the campaign. That foundation will remain useful as AI ad formats, matching systems, and agentic purchase paths continue to change.

    References