Category: AI

  • A Marketer’s Playbook for Ads in AI-Assisted Discovery

    A Marketer’s Playbook for Ads in AI-Assisted Discovery

    Your next paid discovery brief may arrive before the format has a stable name. The ad might represent an entire store instead of a single product, while an AI assistant might capture useful engagement before the buyer ever visits your site. A campaign structure built around a keyword, a product, and a click will not give you enough control.

    You do not need to predict which interface will win. You need a preparation model that works across store-level placements, conversational environments, and whatever hybrid appears between them. That means strengthening the advertised object, the evidence around it, the routes a buyer can take, and the measurement required before you commit budget.

    The advertised object is getting larger

    Traditional shopping campaigns make the individual product the center of gravity. Google is testing Sponsored Shops, a Shopping block that groups several products from one retailer with the store name, ratings, and broader brand presence. The impression can therefore introduce an assortment and a merchant, not merely an item.

    Conversational discovery creates a different expansion. OpenAI has begun testing an Ads Manager dashboard with selected partners as it develops advertising around ChatGPT. The exact inventory, interaction model, and optimization system remain early. You should treat them as provisional rather than assume conversational ads will inherit the rules of paid search.

    The practical lesson is that the thing you advertise can sit at several levels. It might be a product, a coherent assortment, a store, or a solution to the need expressed in a conversation. Each level requires different proof and a different continuation after the impression.

    Add the following fields to your campaign planning before a new platform makes them mandatory:

    • User need: the problem, task, or buying situation that triggered discovery.
    • Advertised object: the product, collection, store, or solution path the unit represents.
    • Evidence: the ratings, product details, range, brand facts, and on-page claims that support the promise.
    • Possible interactions: product selection, brand selection, continued conversation, or a direct visit.
    • Continuation: the exact page or in-platform step that follows each interaction.
    • Business event: the observable action that would make the placement valuable.

    This prevents a common category error: treating a larger discovery unit as if it were merely a wider text ad. More visible products do not automatically create a coherent reason to choose the store. A conversational placement does not automatically produce a qualified visit. The advertised object must make sense as a whole.

    Build a discovery asset stack before you buy media
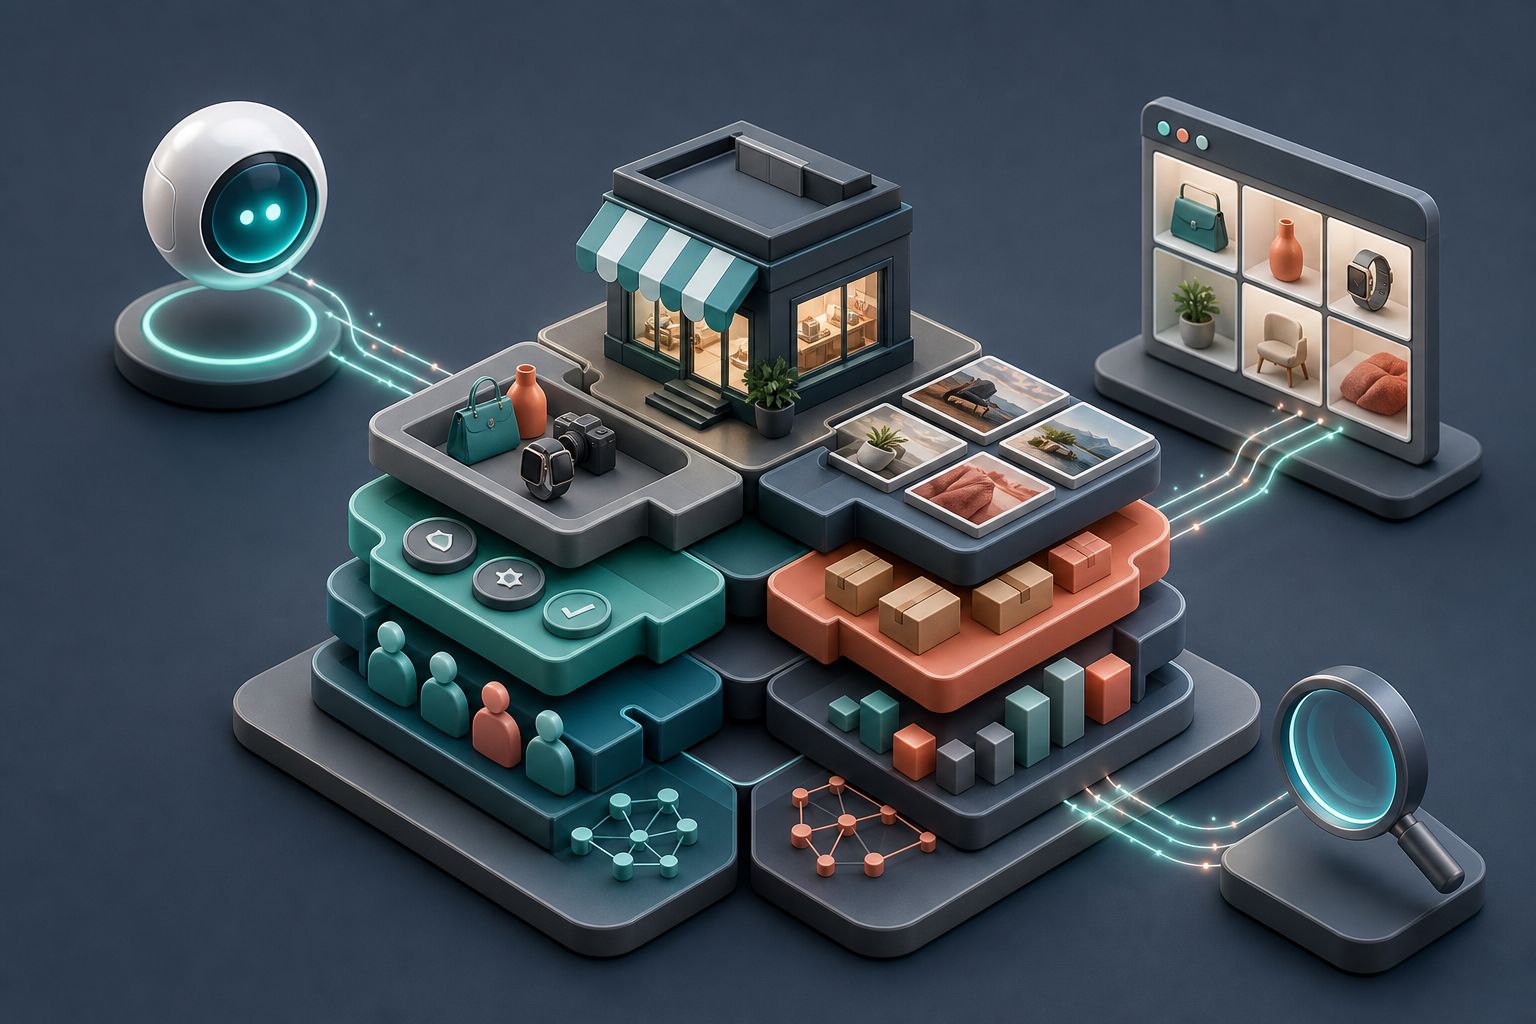
    A modular stack of storefront, product, evidence, inventory, and data elements connects to three abstract discovery interfaces.

    A store-level placement exposes the quality of the catalog as a portfolio. Sponsored Shops could favor merchants with stronger product feeds, useful assortment depth, and credible seller ratings, because several products and the retailer identity appear within the same unit. A weak item is no longer isolated; it can make the entire selection feel less relevant.

    Do not answer that pressure by putting more products into every group. Build an asset stack in which every layer has a defined job:

    1. Catalog facts establish what each product is, what it costs, whether it is available, and how it differs from nearby options.
    2. Assortment logic explains why a set of products belongs together for a particular need. Shared inventory is not enough; the group needs a shopper-facing reason to exist.
    3. Brand evidence gives the buyer a reason to trust the store behind the assortment. Ratings and consistent brand identity matter more when the merchant is part of the advertised object.
    4. Destination continuity carries the same promise from the ad into the next page. The buyer should not have to reconstruct the category, filter, or use case after clicking.
    5. Machine-readable agreement keeps feeds, visible page content, and structured data aligned. JSON-LD should repeat defensible facts shown to the user, not introduce a cleaner but contradictory version of the offer.

    Audit this stack by discovery theme rather than by campaign name. Write the buyer’s need in plain language, select the products that genuinely address it, and inspect every item in that set. Mark missing details, inconsistent naming, stale availability, weak images, unexplained variations, and claims that do not match the destination. Then decide whether the set deserves to be presented as a store-level recommendation.

    Keep product-level optimization intact while you do this. A broad assortment should not bury the strongest item or force unrelated products into the same story. You are adding a portfolio layer above the product layer, not replacing product relevance with brand reach.

    Give every interaction a deliberate next step

    A multi-element discovery unit creates more than one possible click. With Sponsored Shops, the split between clicks on the brand and clicks on individual products is an open measurement and usability question. If you only plan the final conversion page, you will miss the intent expressed by the element the buyer selected.

    Design a continuation for each route that the format exposes:

    • Store or brand interaction: use a focused storefront that confirms the range, positioning, and evidence shown in the unit. Avoid a generic homepage unless it already performs that job.
    • Collection interaction: preserve the discovery theme, relevant filters, and visible product set. Do not make the buyer rebuild the selection from a broad category page.
    • Product interaction: land on the exact item with its important facts, proof, availability, and next action easy to find.
    • In-assistant interaction: identify what the platform can report when the user continues the conversation without visiting your site. Treat unreported engagement as unknown, not as a click or a conversion.

    Put this destination map in the campaign brief before creative production. For every clickable element, record the likely intent, destination, page promise, and success event. If the platform allows distinct tracking parameters for different elements, use them. If it does not, record that limitation before deciding how much you are willing to spend.

    The first visible part of each destination should close the loop opened by the ad. A store-level promise about range should reveal that range. A product promise should show the exact product. A solution-oriented message should answer the need before introducing unrelated navigation. That continuity is more useful than repeating the ad headline word for word.

    Keep paid visibility separate from organic AI visibility in your reporting. Buying placement does not make an unclear page easier for an answer engine to understand elsewhere. Your AEO and GEO work still needs clear naming, consistent facts, direct answers, accessible evidence, and structured data that agrees with the visible page. Paid discovery adds distribution and control; it does not repair weak information architecture.

    Make measurement and budget pass the same gate
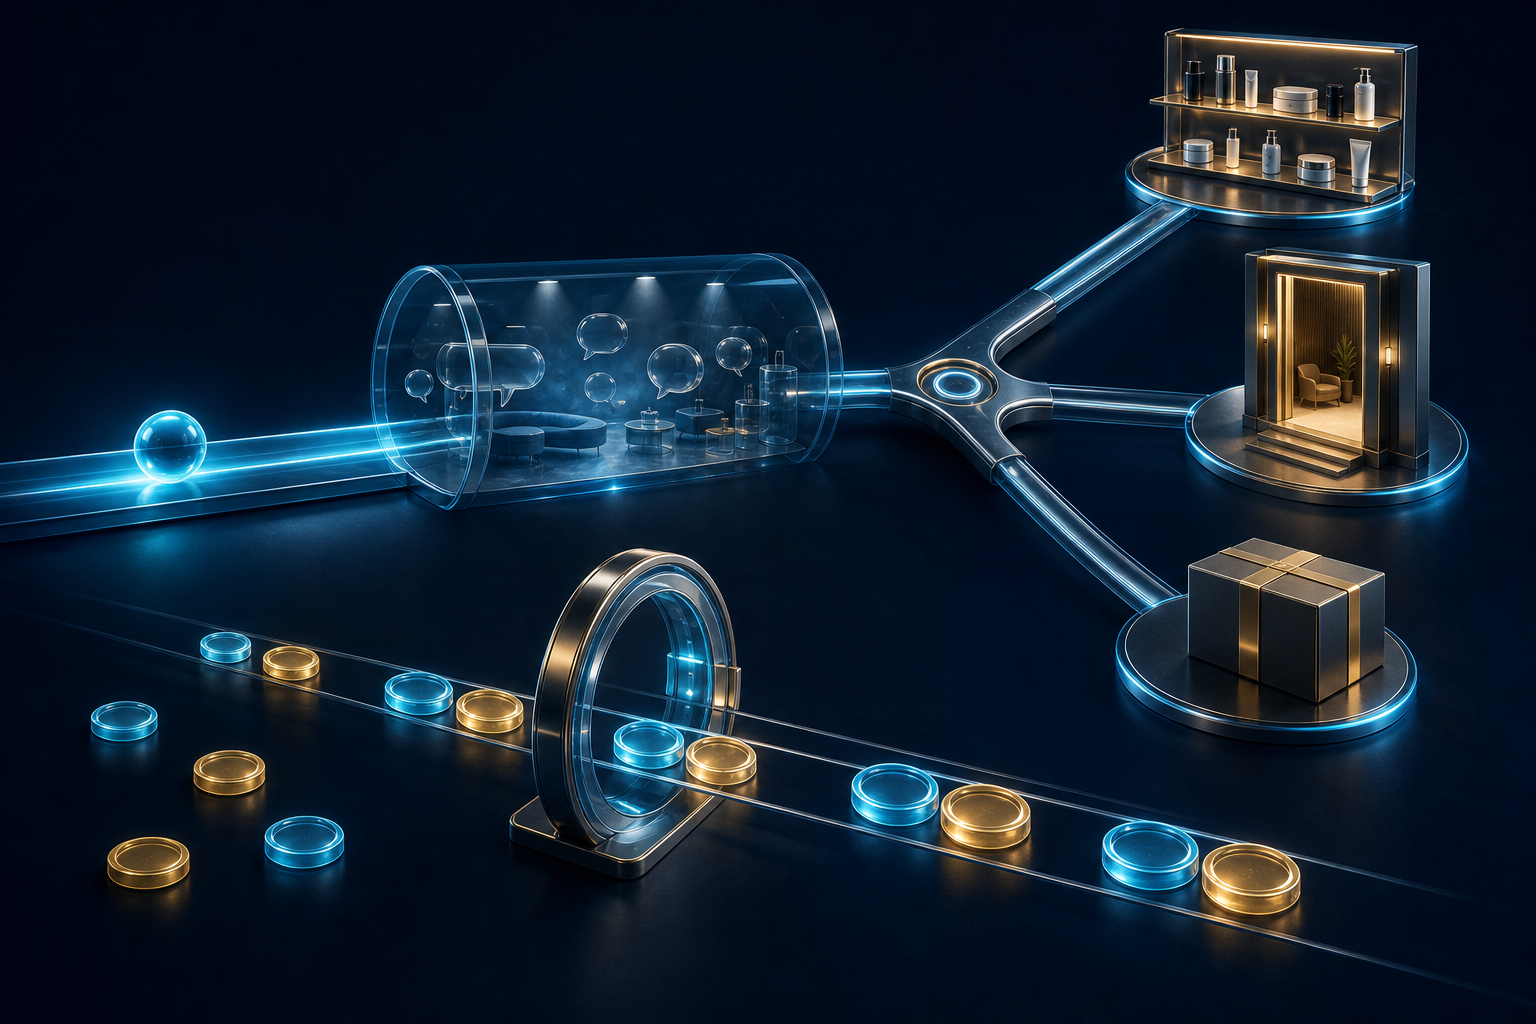
    A glowing interaction moves through a branching journey toward a product shelf, consultation doorway, or parcel while paired measurement and budget tokens pass through one gate.

    Use a measurement ladder, not a click counter

    Early ChatGPT advertisers have reportedly received weekly CSV reports containing impressions and clicks, while initial click-through rates have trailed Google Search. Delivery and click data can confirm that an ad ran. They cannot, on their own, tell you whether conversational discovery created valuable demand.

    Measure emerging discovery formats as a ladder:

    • Delivery: impressions, placement, advertised object, unit variant, and any available context about where the ad appeared.
    • Interaction: clicks by element, product selections, brand selections, or reported continuation inside the interface.
    • Progression: meaningful visits to product or collection pages, deeper product exploration, cart activity, lead starts, or another relevant journey event.
    • Outcome: completed purchases, qualified leads, revenue, or the business result attached to the campaign.
    • Incremental value: evidence that the new channel added outcomes rather than taking credit for demand another channel had already created.

    Mark unavailable fields as unavailable. Do not enter zero, because zero means the platform measured the event and found none. Missing element-level interaction data is itself a decision signal: it limits what you can learn about creative, assortment, and destination performance.

    Your tracking taxonomy should identify the platform, placement, advertised object, unit variant, and destination wherever the platform exposes those controls. Keep those dimensions separate. Otherwise, a store click and a product click can collapse into the same campaign total even though they represent different user decisions.

    Write the test decision before launch. State the hypothesis, the variable being changed, the primary business outcome, the supporting engagement signals, the acceptable downside, and the condition that will stop or expand the test. A low click-through rate is not automatically failure for an upper-funnel discovery unit, but it cannot be excused by vague claims about awareness. The downstream evidence must carry the argument.

    Set a budget gate that reflects platform maturity

    Some early ChatGPT advertisers have reportedly been asked for a minimum commitment of $200,000. That creates material financial exposure while reporting and optimization capabilities are still developing. Early access is not valuable merely because access is scarce.

    Before accepting a pilot, require clear answers to these questions:

    • Where can the ad appear, and how is sponsorship disclosed to the user?
    • Which audiences, contexts, placements, products, and destinations can you include or exclude?
    • Which delivery, interaction, conversion, and cost fields can you export, and at what reporting cadence?
    • Can you distinguish a brand interaction from a product interaction?
    • How will conversion measurement work when part of the journey remains inside the assistant?
    • Which campaign changes can you make during the pilot, and what are the stop conditions?

    Ring-fence money you can genuinely treat as experimental. Do not pull budget from a proven acquisition channel simply to claim first-mover status. If the minimum commitment is too large to absorb as a learning cost, or the reporting cannot connect delivery to business outcomes, observing the format is the disciplined choice.

    Move from observation to a pilot when destinations are traceable, controls are understandable, disclosures are clear, and the downside fits the approved test budget. Move from pilot to scale only when the outcome is repeatable and the reporting explains why it happened. Impressions and novelty are not scale criteria.

    Key takeaways for your next planning cycle

    • Plan around the advertised object, which may be a product, assortment, store, or solution path.
    • Treat catalog quality, assortment logic, brand evidence, landing pages, and structured data as one discovery asset stack.
    • Map separate continuations for brand, collection, product, and in-assistant interactions.
    • Measure delivery, interaction, journey progression, business outcomes, and incremental value as distinct layers.
    • Do not fund a large early pilot without exportable reporting, usable controls, explicit stop conditions, and a tolerable downside.

    Your next move is to choose a commercially important discovery theme and complete the advertised-object and destination map for it. Audit the supporting catalog, page evidence, and machine-readable facts before a platform representative puts a media proposal in front of you.

    When access becomes available, ask the platform to map every promised metric and control to that plan. If the gaps prevent a business decision, keep observing. If the path is traceable and the risk is bounded, run a focused pilot with written stop conditions. Emerging discovery inventory should earn its budget on evidence, just like any established channel.
    References

  • How LinkedIn’s LLM-Powered Feed Ranks Your Content

    How LinkedIn’s LLM-Powered Feed Ranks Your Content

    If your LinkedIn reach feels erratic, stop treating the feed like one global leaderboard. The platform is trying to predict relevance for each person, so two professionals with similar networks can still receive different candidates in a different order.

    The useful question isn’t, “How do I please the algorithm?” It is, “Can the system understand who this is for, and will the right readers behave as though it was worth their time?” LinkedIn’s new architecture gives you a practical way to improve both sides of that equation without pretending there is a secret score you can reverse-engineer.

    LinkedIn now makes two separate feed decisions

    Abstract content tiles pass through a broad selection gateway and then a second prism that orders different feeds for three viewers.

    Feed visibility begins with two distinct jobs: retrieval and ranking. Retrieval decides which posts could appear. Ranking decides which of those candidates should appear first. A post that fails the first decision never reaches the second, while a retrieved post can still lose its position to something that better matches the viewer’s current interests.

    Retrieval matches meaning, not just identical wording

    LinkedIn has consolidated previously separate discovery routes into a unified retrieval model. Large language models create embeddings: numerical representations that capture the meaning and context of a post. Those representations can be compared with a member’s professional interests even when the wording isn’t identical.

    Someone engaging with small modular reactor content, for example, may also receive material about renewable energy or a related professional field that uses different terminology. This semantic matching across related concepts matters more than repeating one phrase in every paragraph.

    The GPU-backed system processes millions of posts, can refresh content embeddings within minutes, and can retrieve candidates in less than 50 milliseconds. That speed means a fresh post can become semantically retrievable quickly. It does not guarantee that the post will be selected, ranked highly, or distributed widely.

    Ranking uses a sequence of viewer behavior

    After retrieval, a transformer-based sequential model orders the candidates. It doesn’t evaluate each post in isolation. It examines patterns in a member’s previous behavior, including likes, comments, and time spent viewing content, so the feed can adapt as professional interests change.

    This is an important limit on algorithm advice. A post does not have one universal rank. Its position depends partly on the person receiving it and the sequence of behavior that preceded that feed request. Strong results with one audience segment do not prove that the same post will rank the same way for everyone else.

    LLM-powered also doesn’t mean a chatbot is reading your prose like an editor and awarding points for style. One model represents meaning for retrieval; another uses interaction history to rank candidates. Human-readable quality still matters, but it matters because clear, useful content is easier to match and more likely to hold the right person’s attention.

    Make each post semantically legible

    A blank content card emits a focused constellation of topic symbols that connects with a matching group of professional readers.

    A vague post forces both the model and the reader to guess. A semantically legible post names the professional context, the problem, the affected audience, and the relationship between its main ideas. You can create that clarity without turning the copy into a keyword list.

    1. Write a private audience sentence before drafting: “This is for [role] deciding [specific decision].” If you can’t complete it cleanly, the topic is still too broad.
    2. Name the subject early. Don’t spend the opening on a generic tease that could introduce leadership, software, hiring, finance, or any other field.
    3. Explain the mechanism. State why the change happens, what it affects, or which constraint creates the problem. Adjectives such as “transformative” and “important” don’t supply that context.
    4. Connect the core topic to one relevant adjacent concept. Make the relationship explicit instead of dropping related terms into the copy without explanation.
    5. Show expertise through a process, tradeoff, decision rule, or concrete distinction. Claiming expertise is weaker than making knowledgeable reasoning visible.
    6. End with a question only when the answer can deepen the professional discussion. Ask about a decision, constraint, or experience, not whether readers agree.

    Compare “Big changes are coming. Thoughts?” with this structure: “For [role] deciding [decision], [named development] changes [specific constraint] because [mechanism].” The second version tells the retrieval system what the content concerns and tells the reader whether it deserves attention.

    Semantic retrieval is not permission to stuff a post with synonyms. Use the standard term your audience recognizes, explain it in plain language where necessary, and introduce adjacent terminology only when the relationship adds meaning. A keyword dump can mention everything while communicating almost nothing.

    A coherent series can help you explore a semantic neighborhood: the primary problem, its causes, its operational consequences, and the decisions around it. That does not prove LinkedIn grants account-level authority merely for repeating a topic. It does give each installment a clear chance to match similar professional interests, and it gives you a cleaner way to learn which angle resonates.

    Your network size is not the entire distribution story. Posts that demonstrate expertise and contribute to relevant professional conversations can travel beyond an author’s established connections. The practical move is not to chase every trending subject. It is to contribute when you have a specific connection between the timely topic and the work your intended audience actually does.

    Earn ranking signals without manufacturing them

    Because ranking considers likes, comments, and viewing time, it is tempting to treat every interaction as a lever. Resist that simplification. LinkedIn has not supplied a usable formula that tells you how much each action is worth in every context, and a pause on a post does not necessarily mean approval.

    Design for a meaningful reading experience instead. Give the opening enough information to qualify the audience. Build the body in a logical sequence. Make the promised point before asking for a response. If the subject needs depth, use depth; making a post artificially long in pursuit of viewing time only gives readers more opportunities to leave.

    • Use an opening that identifies the professional issue instead of withholding it behind suspense.
    • Break a complex explanation into distinct decisions, causes, or steps so the reader can follow the reasoning.
    • Ask for a response that requires professional judgment, such as which constraint changes the decision.
    • Reply manually and specifically when someone contributes. Continue the subject they raised instead of posting a generic thank-you.
    • Keep the text and any accompanying media on the same subject. An unrelated video may attract attention while weakening the content’s meaning.
    • Remove prompts whose only purpose is to inflate activity, including requests for a one-word comment with no substantive reason to answer.

    Automated comments and engagement pods are not clever shortcuts. LinkedIn has identified them as policy violations that create artificial discussion. The platform is also deprioritizing engagement bait, irrelevant text-and-video pairings, and generic recycled thought leadership.

    Don’t stretch that policy into a claim that every AI-assisted draft is automatically suppressed. The documented targets are automated engagement and low-value publishing patterns. Judge any drafting tool by the resulting content: Is the reasoning specific? Is the point accurate? Does the copy express a real professional distinction? Would the post still be worth reading if no engagement counter were visible?

    Test audience-topic fit instead of algorithm folklore

    A personalized feed makes casual testing unreliable. When one post performs better than another, the difference could involve the topic, the opening, the audience that received it, those viewers’ recent behavior, or the quality of the discussion. Changing several elements at once leaves you with a result but no useful explanation.

    1. Choose one business-relevant question that a recognizable professional audience needs to answer.
    2. Map the question into a core angle and adjacent angles, such as the cause, implementation constraint, common misreading, and decision tradeoff.
    3. Publish a coherent sequence in which every post stands on its own and names its subject clearly.
    4. Change one structural variable when you want to learn from a comparison: the opening, explanatory depth, example type, or closing question.
    5. Record more than reach. Note whether the people responding appear connected to the intended professional context and whether their comments engage with the actual issue.
    6. Use those observations to choose the next adjacent angle. Don’t turn one strong or weak result into a universal rule about length, timing, hashtags, or a supposed favorite interaction.

    Keep a simple brief beside each draft with these fields: intended reader, decision or problem, core concept, adjacent concept, mechanism or tradeoff, and response prompt. After publication, add what the discussion revealed. This turns a feed result into editorial information you can use rather than a number you can only admire or resent.

    Your own feed is also personalized evidence, not a neutral sample of LinkedIn as a whole. If you use it for topic research, remember that your likes, comments, and viewing behavior help shape what you see next. New members can make that preference-building more deliberate by choosing topics through the Interest Picker during signup. That helps customize the feed from the beginning, but it still does not reveal what every other audience sees.

    Key takeaways

    • Retrieval decides whether a post belongs in the candidate set; ranking decides where that candidate appears for a particular member.
    • Semantic embeddings make clear meaning and related concepts more important than exact-phrase repetition.
    • Ranking uses sequences of behavior, including likes, comments, and viewing time, but there is no dependable public formula for turning those actions into a universal score.
    • Expertise becomes visible through mechanisms, tradeoffs, processes, and useful distinctions, not through generic claims of authority.
    • Automated engagement, pods, bait, mismatched media, and recycled thought leadership create policy or quality risks instead of durable distribution.
    • The cleanest test is audience-topic fit: keep the subject coherent, change one structural variable at a time, and inspect who responds and what they discuss.

    Before your next LinkedIn post, write the private audience-and-decision sentence, rewrite the opening so the subject is unmistakable, and remove any question that can be answered without thought. Then use the quality of the resulting discussion to select the next relevant angle. That is a better compounding system than chasing a secret ranking trick.

    References

  • Google AI Advertising Strategy: What Marketers Should Do Now

    Google AI Advertising Strategy: What Marketers Should Do Now

    If you are waiting for a Gemini campaign type before changing your Google advertising plan, you are waiting for the least important part. Google is already learning how ads behave in AI-generated experiences, while its campaign systems are becoming more willing to assemble, resize and select creative for you.

    The useful response is not to move budget into an unannounced product. It is to make your offers easier to match to conversational intent, clean up the assets Google can reuse and put measurement guardrails around automation. Those changes improve campaigns you can run now and leave you ready if Gemini becomes advertising inventory later.

    Read Google’s AI ad strategy as two connected systems

    Google’s direction contains two different levels of certainty. The current testing ground is AI Mode, a Gemini-powered Search experience where ads are kept distinct from organic results, clearly labeled and shown only when Google considers them relevant. If an appropriate ad is not available, the experience can proceed without one.

    Gemini advertising belongs in the possible-later column. Google has indicated that lessons from AI Mode could eventually inform ads in the Gemini app, but it has not committed to a launch date, buying workflow or dedicated campaign format. Treat that as strategic direction, not media inventory you can forecast.

    At the same time, Google is expanding the creative work its existing systems can perform. Demand Gen’s Asset Optimization controls now group shorter auto-generated videos, automatic video resizing and images pulled from landing pages into a simpler set of toggles. This is operationally important: Google can test more combinations and placements when the advertiser supplies reusable source material.

    Strategic layerWhat is establishedWhat you should do
    Conversational deliveryGoogle is testing labeled, relevance-dependent ads in AI Mode.Map campaigns to the decisions users describe, not only the keywords they type.
    Creative assemblyDemand Gen can shorten videos, resize them and pull images from landing pages.Govern the original assets and inspect automated variants before relying on them.
    Gemini inventoryGoogle has left the possibility open, without announcing a buying product.Prepare reusable inputs, but do not assign a speculative Gemini budget.
    Personalized contextGoogle sees personalization as important, while broader Search integration remains prospective.Track product and data-policy announcements instead of assuming new targeting access.

    Use a no-regret test for every preparation project: would it still improve your current Search or Demand Gen operation if Gemini never carried ads? Clearer landing pages, better asset governance and stronger conversion measurement pass that test. A Gemini-only media plan does not.

    Build campaigns around the decision behind the query

    A strategist examines visual intent clues as shoppers follow branching paths toward different products and services.

    Keyword intent still matters, but conversational interfaces let a user express the situation around a purchase: who the product is for, what constraint matters and what must be true before they act. An ad can be relevant to the topic while being irrelevant to that decision. Your campaign brief should expose the difference.

    For each important offer, create a decision map with the following fields:

    1. Decision: Write the choice the user is trying to make, not the keyword category. A software buyer may be choosing a platform for a distributed team rather than searching for software in the abstract.
    2. Context: Record the audience, use case and stage of consideration that make the offer appropriate.
    3. Constraint: Identify the condition that can disqualify the offer, such as compatibility, geography, deployment model or required feature.
    4. Claim: State the promise the ad can make without exceeding what the landing page supports.
    5. Proof: Point to the specification, demonstration, policy, price information or other evidence that substantiates the claim.
    6. Destination: Choose the page that resolves this particular decision rather than sending every variation to a generic homepage.

    This map gives paid, SEO, AEO and content teams a shared factual base. It does not mean their distribution systems are interchangeable. An organic mention, an AI-generated answer and a paid placement have different eligibility and measurement rules, even when they rely on the same product facts.

    That distinction matters for structured data. JSON-LD can organize explicit facts about an entity, product, service or page, but nothing in Google’s current AI advertising direction establishes schema markup as an ad-targeting control. Use valid structured data to describe visible content accurately. Do not promise that adding markup will make an ad appear in AI Mode or secure future Gemini inventory.

    Review the landing page against the decision map before expanding creative. The page should make the intended audience, supported use case, important limitations and next action easy to find. If the ad needs a verbal explanation to remain accurate after the click, the page is not ready for automated distribution.

    Make creative automation safe before switching it on

    Two marketers review automated ad layouts while approved assets pass through digital guardrails and rejected assets are set aside.

    Demand Gen’s consolidated Asset Optimization panel reduces the work required to activate automation. It does not remove the need to supervise the material being transformed. A weak original can produce more weak variations, and an outdated landing-page image can become campaign creative without anyone deliberately selecting it.

    Audit the system in this order:

    1. Record the current settings. Open Asset Optimization and document which video-resizing, video-shortening and image options are enabled. Keep that record with the campaign brief so a later performance change can be tied to a known configuration.
    2. Create an approved asset register. For each original image or video, record the owner, usage rights, supported claim, intended audience, required context and any expiration condition. An asset should not enter automation merely because it exists in a shared folder.
    3. Inspect landing-page imagery. Because Google can pull images from the destination page, remove obsolete promotions, unsupported product states and decorative images that would be misleading when detached from the surrounding copy. Make the strongest eligible image understandable on its own.
    4. Review shortened videos as new creative. Confirm that the automated cut preserves the core claim, necessary qualification, brand identity and call to action. Watch it without sound as well as with sound. A cut that removes the condition attached to a claim should not run.
    5. Review every generated shape you intend to use. Check whether resizing crops the product, speaker, demonstration, captions, qualification or call to action. Do not assume that a technically valid crop is a persuasive or compliant ad.
    6. Change settings deliberately. Where campaign volume allows it, avoid changing every automation control alongside the landing page and offer. A smaller set of simultaneous changes makes the result easier to interpret, even if it is not a perfect controlled experiment.

    The practical division of labor is simple. Your team owns truth, permissions, positioning and the quality of the originals. Google can own format adaptation and selection only within those boundaries. If the boundaries are not documented, leave the relevant automation off until they are.

    Measure the system you can buy, not the product you imagine

    AI-flavored placement does not change the need for a falsifiable campaign brief. Before launching or expanding automation, state which user decision the campaign addresses, which conversion represents success and which downstream signal distinguishes a valuable conversion from a merely completed form or click.

    Your working scorecard should preserve enough context to explain a result:

    • The campaign, audience and offer being evaluated.
    • The landing-page version used during the period.
    • The status of each asset-optimization control.
    • The original assets available to Google.
    • The primary conversion and a business-quality signal, such as a qualified opportunity, completed purchase or retained customer.
    • Any brand, policy or lead-quality guardrail that would make higher delivery unacceptable.

    Do not use click-through rate alone to declare an AI ad strategy successful. A new format can attract interaction while sending poorly matched users. Read the engagement metric beside conversion quality, acquisition cost and the business outcome your campaign was meant to produce.

    Keep a separate launch gate for future Gemini advertising. Before moving money, verify the inventory available to your account, eligible campaign types, placement and exclusion controls, creative-generation settings, reporting granularity, conversion attribution and the data used for personalization. If Google does not expose enough information to answer those questions, the responsible response is a limited test inside the controls that do exist, not a broad budget shift.

    Personalization deserves particular care. Google’s Personal Intelligence can draw on a user’s Gmail, Photos and Calendar, and Google has said that user data will not be sold or shared. Broader integration with Search remains a possibility rather than an advertiser capability you can plan around. Do not translate consumer-facing personalization into an unsupported claim that advertisers can access those personal signals.

    This measurement discipline also keeps organic AI visibility separate from paid reach. Track whether your brand is represented accurately in AI-generated answers, but do not count a citation, a paid impression and an assisted conversion as the same event. They can influence the same journey without proving the same thing.

    Key takeaways

    • AI Mode is Google’s current environment for learning how labeled, relevance-dependent ads fit into AI-generated search experiences.
    • Ads in the Gemini app remain possible, but no dedicated buying format, launch date or workflow has been established.
    • Demand Gen’s asset controls reveal the immediate operational priority: provide strong originals and let automation adapt them under supervision.
    • Organize campaigns around a user’s decision, context, constraint, claim, proof and destination rather than treating conversational advertising as a longer keyword list.
    • Audit landing-page images because they may become ad assets, and review shortened or resized videos as new creative rather than harmless copies.
    • Keep structured data, organic AI visibility and paid placement conceptually separate. Shared facts help all three, but none guarantees the others.

    At your next campaign review, open the Demand Gen Asset Optimization panel, record its settings and inspect every page and asset it can draw from. Then build one decision map for your highest-value offer. When Google exposes more conversational inventory, you will have approved inputs and a measurement plan ready, without having paid for a strategy built on speculation.

    References

  • Transform Automated Workflows with Gamma Integration

    Transform Automated Workflows with Gamma Integration

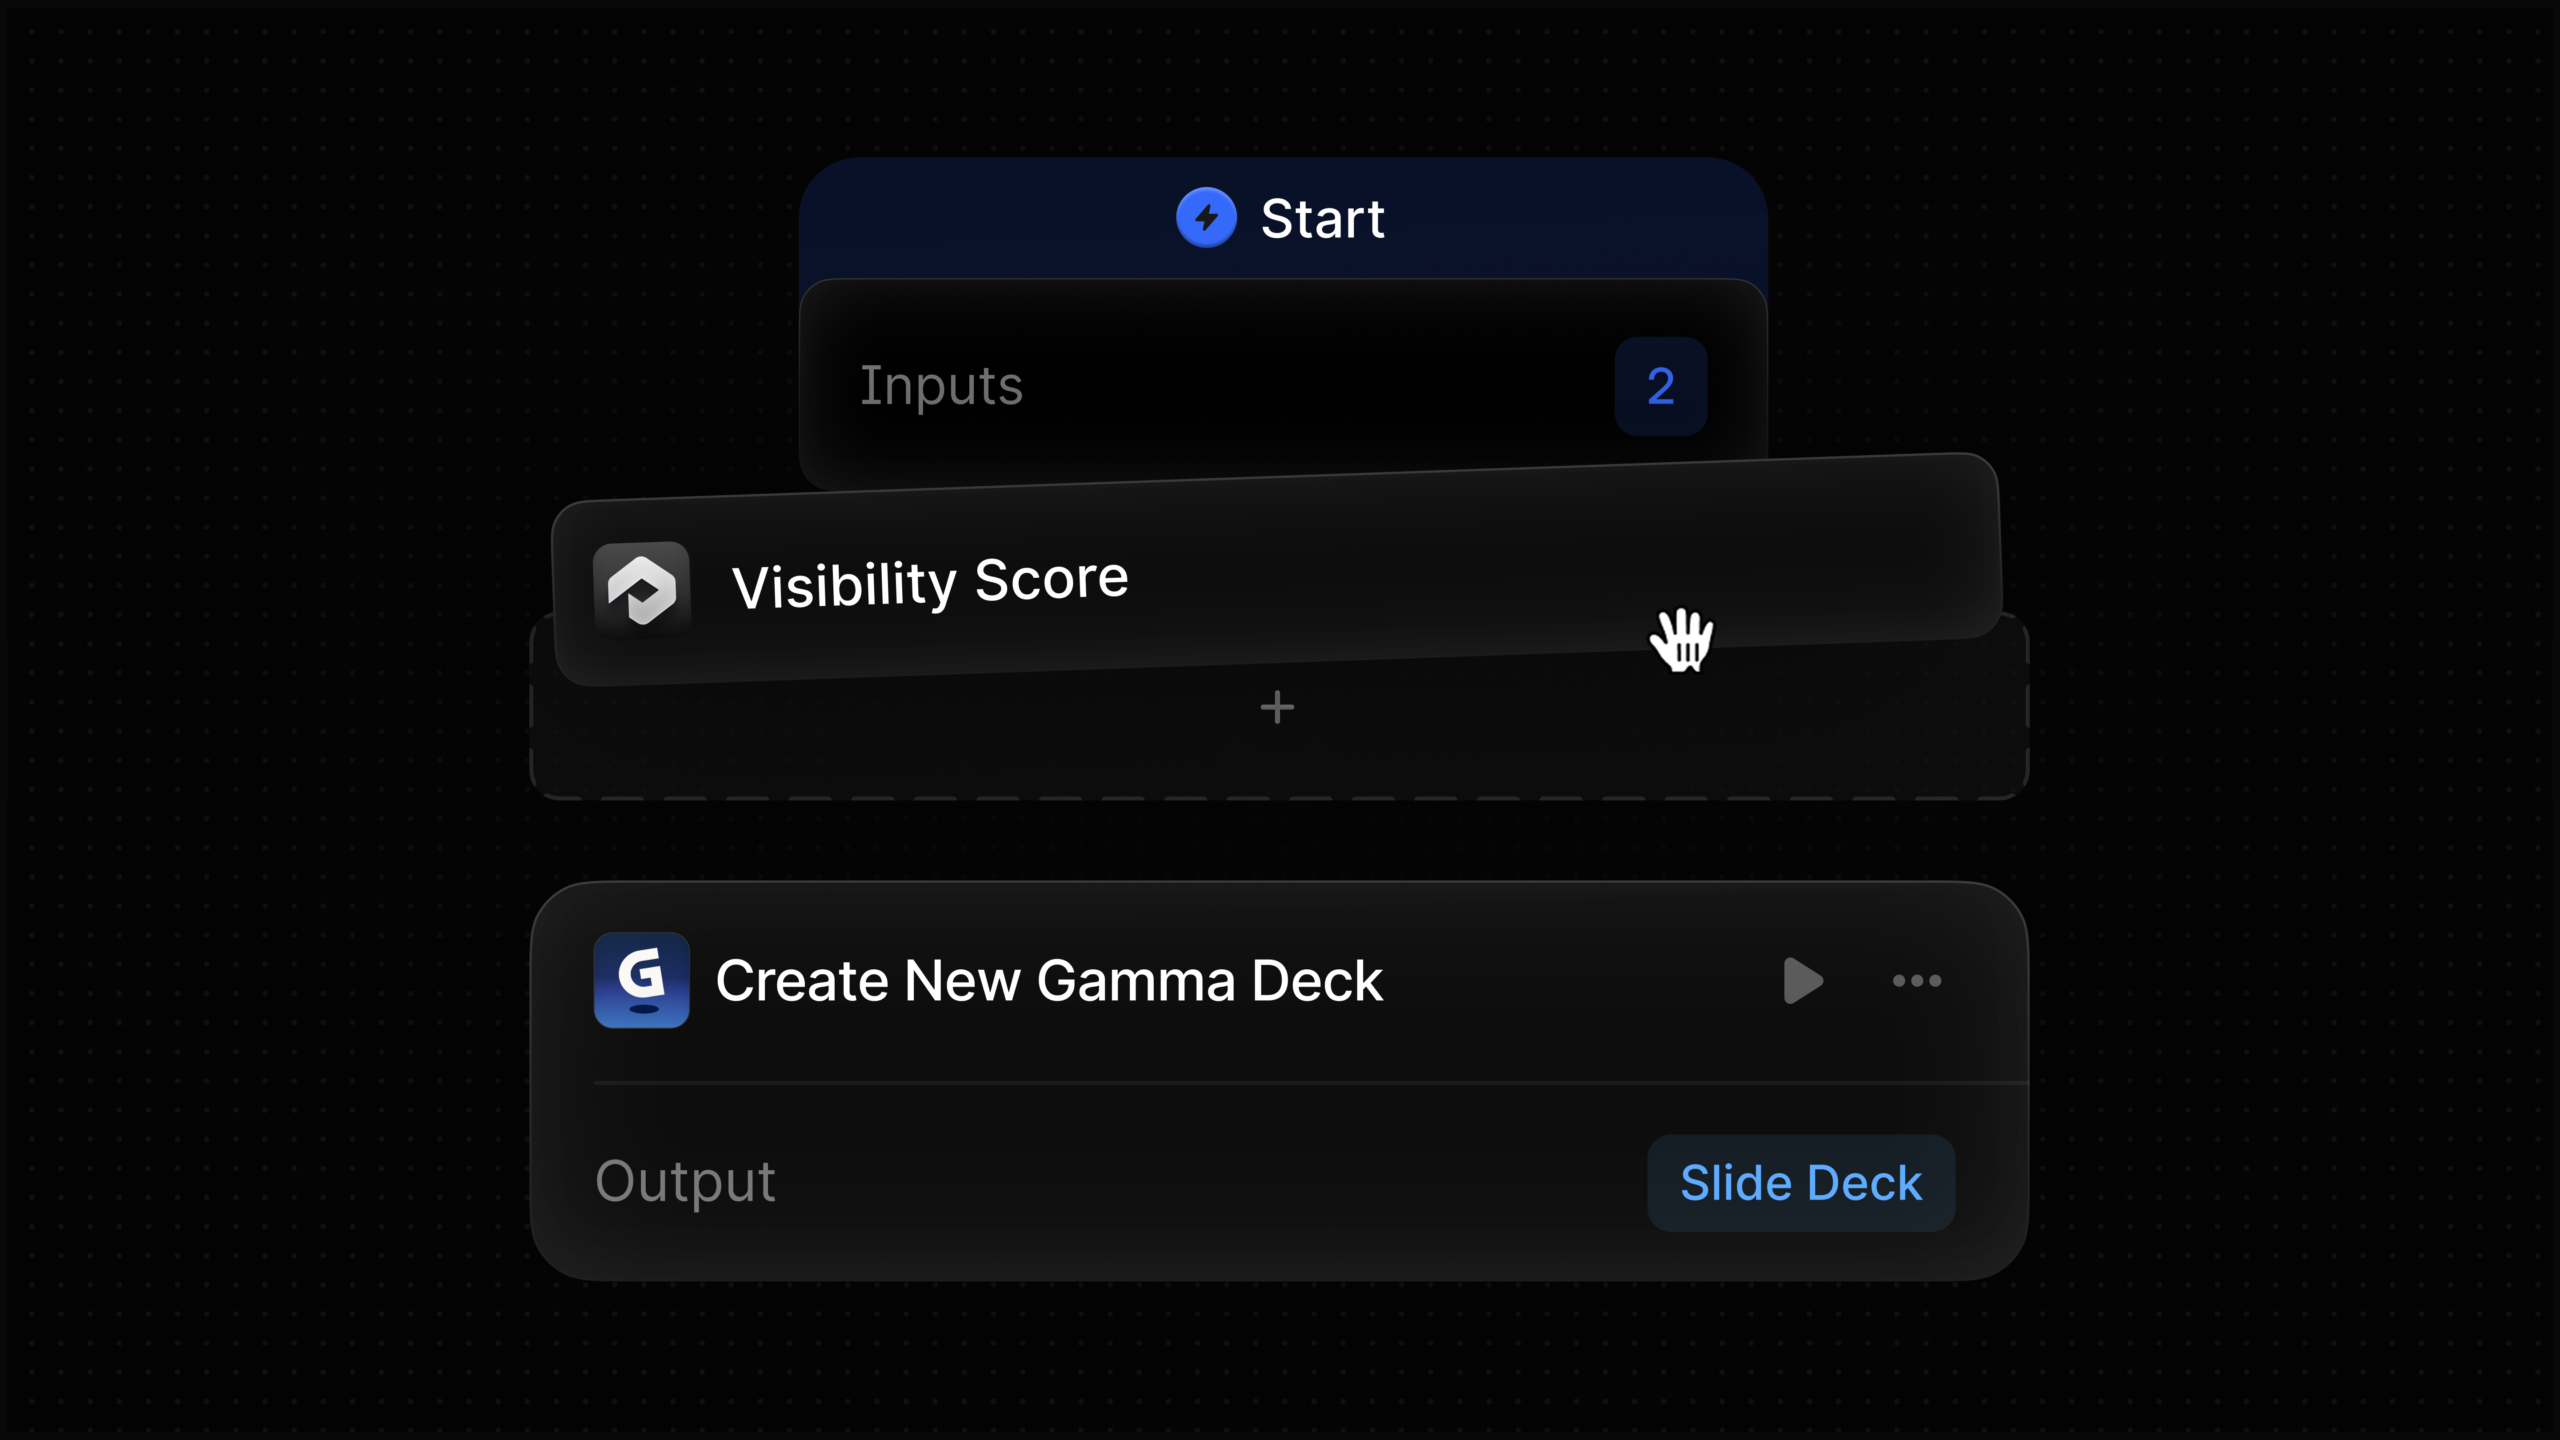
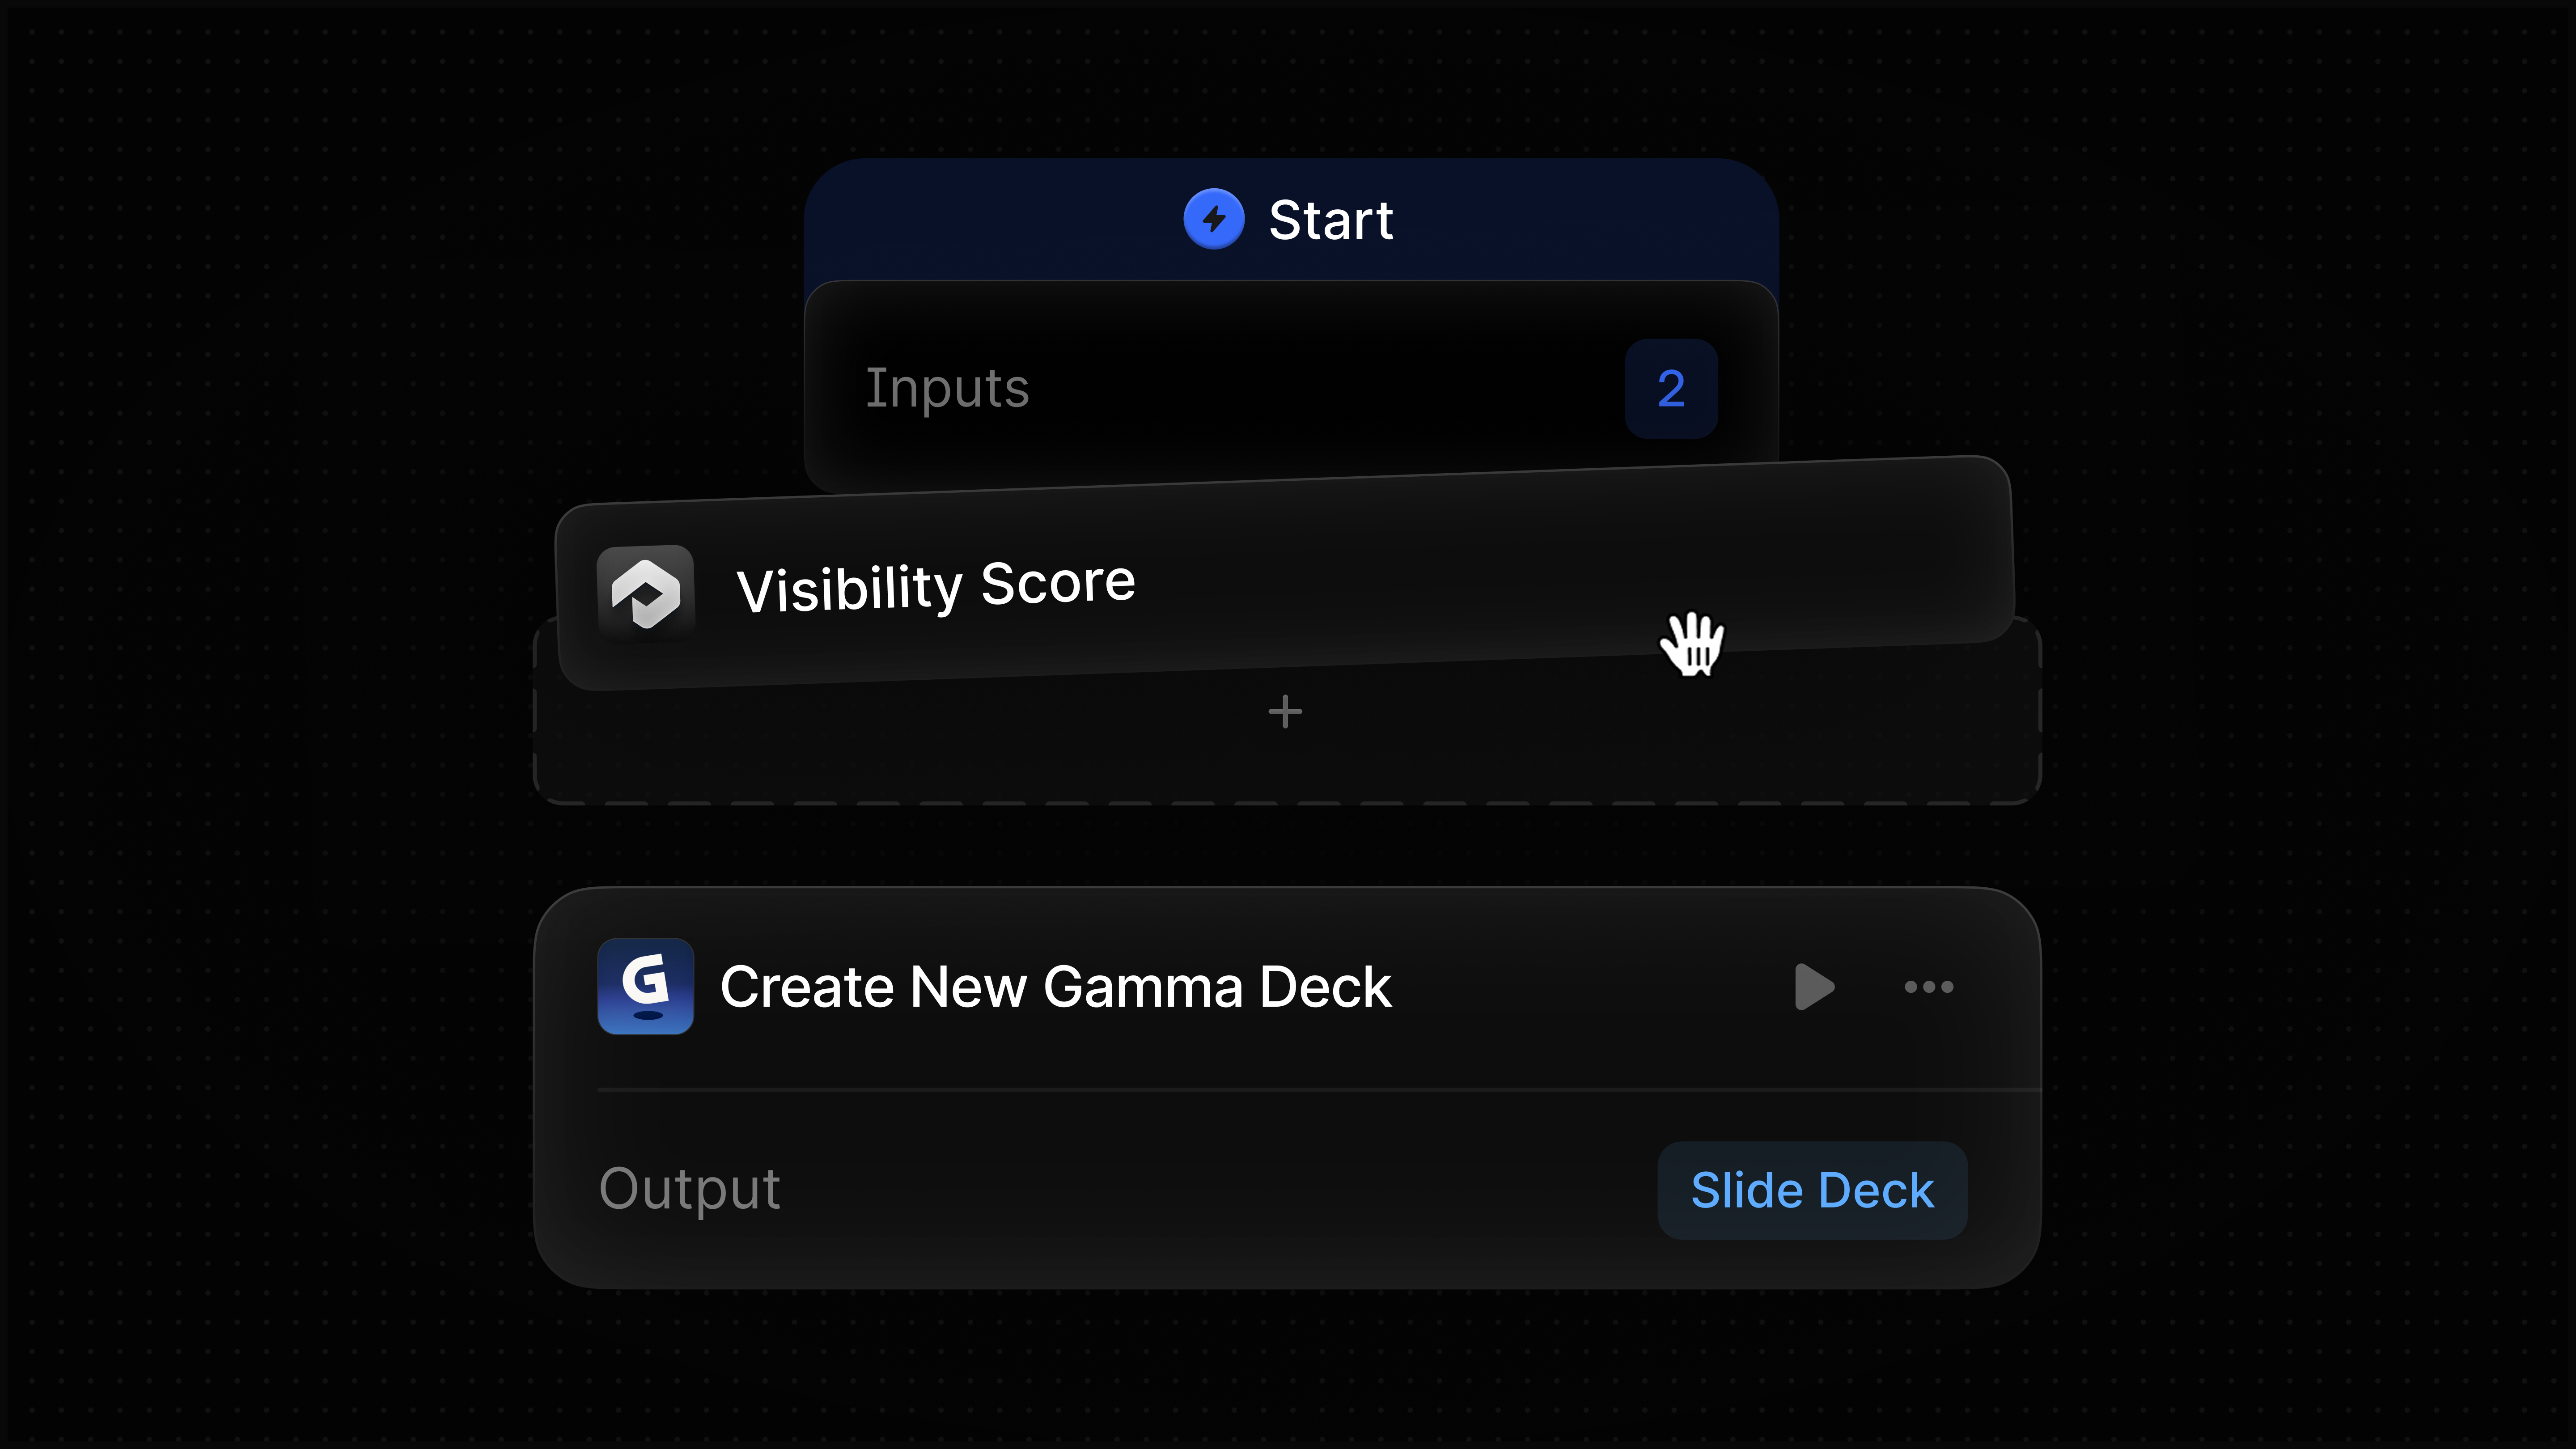
    I’m thrilled to share that Profound Agents can now seamlessly create presentations, documents, and webpages within Gamma as part of my automated workflows. No more hassle of exporting data and rebuilding it elsewhere. My Agent takes the outputs from upstream nodes and crafts them into ready-to-share assets in Gamma, streamlining the entire process.


    Inspired by this post on Try Profound Blog.


    crushpress.ai community screenshot
  • Perplexity’s Amazon Bot Block: What Commerce Teams Should Do

    Perplexity’s Amazon Bot Block: What Commerce Teams Should Do

    If your AI commerce plan assumes an assistant can find a product, sign in and complete the purchase, the Perplexity-Amazon dispute exposes a flaw in that model: discovery, account access and transaction authority are separate permissions.

    A preliminary injunction now prevents Perplexity’s Comet agent from entering Amazon’s password-protected areas and requires Perplexity to delete the Amazon data it collected. That does not end AI shopping, but it gives SEO, ecommerce and agent teams a practical warning: being visible to an AI system does not give that system permission to act inside a platform.

    The injunction targets authenticated access, not all AI shopping

    The scope matters. U.S. District Judge Maxine Chesney issued a preliminary injunction concerning Comet’s access to password-protected parts of Amazon, including areas used by Prime members. It is not a final judgment declaring every AI shopping agent unlawful, nor does it establish that public product pages cannot be found, interpreted or recommended by AI systems.

    The central distinction is between two kinds of authorization. A customer may authorize an assistant to use the customer’s account, but the platform may still withhold authorization from the assistant itself. The judge cited strong evidence that users granted Comet access while Amazon did not. For anyone building an agent, user consent is therefore necessary but may not be sufficient.

    Amazon has accused Perplexity of computer fraud and unauthorized access, including allegedly allowing Comet to make purchases without identifying itself properly as a bot. Those are Amazon’s allegations, not settled findings on every claim. At issuance, the injunction was suspended for one week so Perplexity could appeal.

    The deletion requirement deserves as much attention as the access restriction. An agent team may need to identify and remove data by platform, account, user and collection method. If you cannot isolate data at that level, a dispute over one integration can turn into a much larger data-governance problem.

    Discovery, recommendation and purchase are separate systems

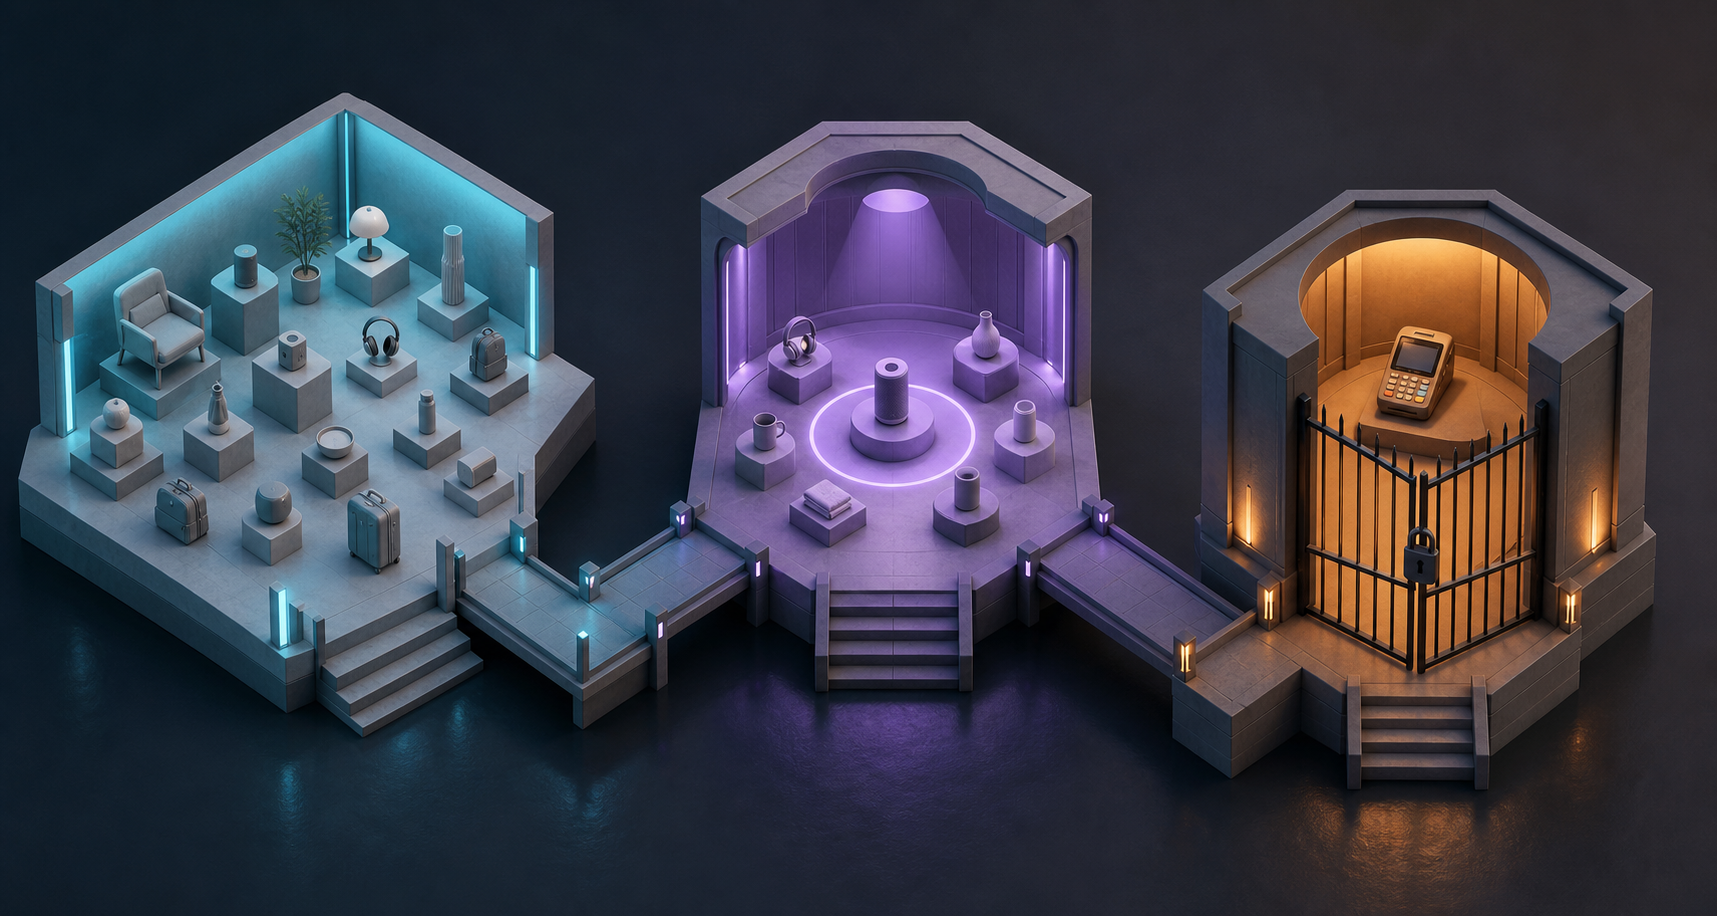
    Three connected but separate spaces represent product discovery, recommendation, and a locked checkout process.

    AI commerce is often discussed as one continuous journey, but three layers determine whether it works. Each has a different owner, failure mode and remedy.

    LayerQuestion it answersTypical responsibilityCommon failure
    VisibilityCan an AI system find and understand the product?SEO, content, structured data and public-site engineeringThe product is absent, misunderstood or cited inaccurately
    RecommendationDoes the product fit the user’s request well enough to be selected?Product information, positioning, availability and the agent’s decision logicThe product is understood but not chosen
    ExecutionCan the agent enter an account, modify a cart or complete a purchase?Authentication, platform policy, security, legal review and approved integrationsThe journey stops at sign-in, checkout or another protected action

    Schema markup can improve machine understanding at the visibility layer. Clear product details can strengthen the recommendation layer. Neither one grants an agent access to an authenticated account. Treating them as substitutes for platform permission creates a false sense of readiness.

    The same distinction applies to robots.txt and other crawl controls. A public crawling directive is not a purchasing authorization system. It does not answer whether an agent may use a signed-in session, accept terms, place an order or retain account data. Those questions need explicit product, security and legal decisions.

    Your SEO work still matters, but it cannot grant access

    The wrong reaction would be to stop optimizing products for AI discovery. The injunction concerns authenticated access, while much of the discovery and evaluation journey happens through public information. Your content can still help an assistant understand what a product is, who it suits and where the customer can continue safely.

    • Give each important product a stable public destination. Use a consistent canonical URL and make variant handling predictable so an agent does not have to reconcile several conflicting versions of the same offer.
    • Put decision-critical facts in accessible page text. Product names, identifiers, specifications, compatibility, options, limitations and fulfillment conditions should not exist only inside images or interface states that require interaction.
    • Keep structured data aligned with the visible page. Markup that contradicts the page can produce incorrect extraction and erode trust. Treat structured data as a machine-readable representation of the offer, not a place to publish claims the customer cannot verify.
    • Separate product availability from transaction capability. An agent may be able to report that an item appears available without being authorized to buy it. Use language and interfaces that do not blur those two states.
    • Provide a durable human handoff. If automated checkout is unavailable, preserve the selected product or variant in a public deep link and let the customer sign in, review the cart and confirm the purchase.
    • Publish an approved path for automation if you offer one. Document the permitted integration, identity requirements, data limits and prohibited actions. Do not force agent developers to infer transactional permission from crawlability.

    Measure these layers separately as well. AI referrals and product-page visibility tell you about discovery. Product selection or cart initiation tells you about consideration. Completed orders tell you about execution. Combining all three into a single “AI traffic” measure hides the exact permission gate where the journey fails.

    Audit the handoff before an agent reaches login

    A commerce specialist inspects digital permission tokens before an automated shopping device reaches a secured account gate.

    You do not need to wait for another court dispute to find the weak point in your own workflow. Trace one high-value purchasing journey from the first public result through order confirmation, then record the identity, permission and data rules at every transition.

    1. Mark every access boundary. Label which pages and actions are public, account-gated, membership-gated or restricted to an approved integration. Include cart changes, saved payment methods, order history and purchase confirmation.
    2. Name the permission owner. Record whether the customer, merchant, marketplace, payment provider or another party controls each action. If two parties must consent, capture both rather than treating the customer’s approval as universal authorization.
    3. Define agent identity. Decide how an automated system identifies itself and how your service distinguishes it from the human account holder. Do not rely on the fact that the agent is operating through a customer’s browser session.
    4. Minimize retained data. Keep only what the approved workflow needs, attach provenance to it and make deletion possible by source and account. The Amazon data-deletion requirement shows why broad, unlabelled data stores create operational exposure.
    5. Design a graceful stop. When the next action is not authorized, the agent should explain the boundary, preserve useful context and return control to the customer. It should not repeatedly retry, conceal its identity or route around the restriction.
    6. Test the fallback as a primary path. Confirm that the customer lands on the correct product and variant, can see what remains to be reviewed and can complete the protected steps without rebuilding the transaction.

    If your agent enters authenticated services or makes purchases, do not attempt to evade a platform block or disguise automated traffic. That can increase contractual, security and legal exposure. Have qualified counsel review the relevant terms, authorization model and data practices before launch; this dispute is too narrow and preliminary to serve as a universal legal rule for another platform or implementation.

    Key takeaways for AI commerce teams

    • A user’s permission to use an account does not necessarily provide the platform’s permission for an agent to access it.
    • The injunction is specific to Perplexity’s Comet agent and password-protected Amazon areas; it is not a general ban on AI product discovery or shopping assistance.
    • SEO, AEO and structured data improve visibility and understanding, but they do not authorize account access or transactions.
    • A useful agent-ready journey needs both a machine-readable discovery layer and an explicitly permitted execution path.
    • When full automation is unavailable, a precise human handoff is better than an agent that fails silently at login or checkout.
    • Data provenance and targeted deletion are core integration requirements, not cleanup tasks to invent after a dispute begins.

    Your next move should be concrete: diagram one purchasing journey, circle every point where the agent crosses from public information into protected action, and assign an owner to each permission. Keep optimizing the public layer for discovery, but do not describe the journey as agent-ready until the authenticated steps have an approved path or a tested human handoff.

    References

  • AI Assistants Dominate 56% of Global Search: New Study Unveils

    AI Assistants Dominate 56% of Global Search: New Study Unveils

    AI mobile usage

    I recently came across an intriguing study that shows AI tools are now responsible for generating 45 billion monthly sessions globally. This accounts for an impressive 56% of all search engine activity, according to Graphite.io CEO Ethan Smith.

    The analysis combines web and mobile app usage across leading AI platforms and suggests that AI activity matches 56% of global search use and 34% in the U.S.

    The surge is particularly evident in mobile applications like ChatGPT, Gemini, Perplexity, Grok, and Claude.

    Why it matters: AI is broadening the horizons of discovery, rather than limiting the demand for search. Since 2023, combined usage across search engines and AI assistants has increased by 26% globally. It’s clear that having visibility in both LLMs and traditional rankings is crucial.

    Key insights: The report dives into the performance of the top five LLM products—ChatGPT, Gemini, Perplexity, Grok, and Claude—and compares them to the biggest search engines. Here are some standout insights:

    AI platforms generate 45 billion monthly sessions worldwide.

    Within the U.S., AI accounts for roughly 5.4 billion monthly sessions.

    An astounding 83% of global AI usage takes place within mobile apps (75% in the U.S.).

    ChatGPT is leading the charge, representing 89% of AI sessions globally.

    When looking at search-like prompts, AI usage constitutes 28% of the global search and 17% within the U.S.

    The report leaves out prompts in the “doing” or “expressing” categories. According to OpenAI, around 52% of prompts focus on seeking information, akin to traditional search queries.

    Reading between the lines: Most forecasts comparing AI and search focus only on website traffic, often just Google.com and ChatGPT site visits. This approach overlooks much of AI’s impact.

    The research suggests these comparisons undervalue AI activity by a factor of 4-5 times because a significant chunk occurs on mobile apps.

    The analysis takes into account various LLMs and search engines, rather than only comparing Google and ChatGPT.

    What to keep an eye on: Google remains a dominant force in discovery, but the report estimates its share of search-related activity has declined from 89% in 2023 to 71% by the fourth quarter of 2025.

    While global AI usage seems stabilized since July 2025, the U.S. usage is still on a rapid climb—up about 300% year over year by December 2025.

    The full report. For more depth, you can read the analysis titled AI Is Much Bigger Than You Think.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Get Ready for ChatGPT Ads: A New Era in Demand Capture

    Get Ready for ChatGPT Ads: A New Era in Demand Capture

    I’ve been keeping an eye on the latest developments in AI advertising, and it’s time to prepare for something big: ChatGPT ads are on the horizon. As consumers shift towards shopping through AI prompts, ChatGPT could potentially rival search as a powerful demand-capture channel, leading to a redirection of ad budgets.

    Recently, OpenAI began testing ads in ChatGPT for a limited group of U.S. users, clearly marking these placements as sponsored content. Based on the platform’s internal dynamics, it won’t be long before this feature becomes widely available.

    As advertisers, we have a unique opportunity to tap into a fresh demand-capture channel. However, it’s crucial to approach this space with clear expectations and understanding.

    For ChatGPT advertising to truly succeed, consumer behaviors will need to evolve. And even if they do, remember that ChatGPT won’t expand the market but rather, redistribute it.

    Why ChatGPT is Embracing Ads

    It’s no shock that ChatGPT is moving towards advertising. Running an LLM query is estimated to be ten times the cost of a simple search query. With users generating 2.5 billion prompts daily, expenses pile up swiftly.

    The core difference here isn’t just a model shift; it’s the data landscape. Over the years, users have fed personal information into ChatGPT, giving it insights unmatched by traditional advertising tools. The burning question is how ChatGPT will use this data to target its users effectively.

    Advertisements have traditionally relied on repetition to generate demand, whereas search meets buyers with intent. ChatGPT might forge a similar path, equipped with more user context.

    Imagine this: asking which security camera works with a certain system and receiving an informed answer and purchase link because the platform already knows about your existing setup.

    Should this happen, ChatGPT could be the first new demand-capture channel since Google’s PPC ads launched two decades ago. Yet, obstacles remain.

    Today’s AI queries largely lack buying intent, serving more informational needs. When buying happens, the conversion tracking might fall short due to users completing purchases on platforms like Amazon or Google after doing their research on ChatGPT.

    Don’t be discouraged; such challenges are surmountable. Google’s journey from a homework help tool to shopping powerhouse wasn’t overnight. Likewise, ChatGPT will need time to educate consumers about shopping through AI.

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    While a brand-new demand-capture platform is exciting, have realistic expectations about its potential.

    Market Share Reality Check

    Despite the capabilities of AI, it won’t expand the advertising marketplace. ChatGPT ads won’t magically bring a wave of new consumers.

    Instead, it will capture pieces of the existing market shared by Google, Meta, and Amazon. It’s more about shifting budgets rather than expanding them.

    Competition will be fierce, particularly with Google’s AI platform, Gemini, presenting a formidable challenge. Market consolidation seems inevitable as AI races towards profitability.

    The Differentiator: Hyper-Personalization

    AI’s true edge might be in hyper-personalization. With their vast knowledge of user preferences, these platforms can deliver perfectly tailored recommendations.

    This feature could make AI incomparable, offering personalized results seamlessly. However, this comes with risk, as hyper-personalization might feel invasive to some users.

    If AI can maintain trust and avoid crossing privacy boundaries, its personalized convenience will likely be favored by most.

    Steps to Take Now

    While widespread ChatGPT advertising is still on the horizon, preparation is key. Here’s how to get ahead:

    • Align on Measurement: Consider research-heavy metrics and assisted conversions.
    • Optimize Mobile UX: Ensure a smooth, fast purchasing experience to avoid loss in demand capture.
    • Plan Early Tests: Testing carries risks but can provide an early competitive edge.

    Being strategic now will set the stage for success when ChatGPT advertising becomes fully operational.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • AI-Driven Marketing Measurement: A Practical Experiment System

    AI-Driven Marketing Measurement: A Practical Experiment System

    Your paid dashboard says efficiency is acceptable, your SEO and AEO reports show visibility moving, and the CRM says revenue is flat. You do not need another chart. You need to determine whether demand is weakening, conversion is breaking, or the measurement itself is misleading you.

    AI can shorten that investigation and help you choose the next experiment. It cannot rescue disconnected definitions, overlapping tests, or a team that has not agreed on what evidence would change a decision. The practical goal is a governed measurement loop: connect signals across the customer journey, expose uncertainty, run the least disruptive useful test, and preserve what you learn.

    Start with the decision your measurement must support

    A measurement system should begin with a decision, not a collection of available metrics. Before you connect an AI model to your dashboards, write one sentence that names the choice in front of you:

    "Should we increase, hold, redirect, or reduce this investment, and what evidence would make us change our current position?"

    That sentence forces useful specificity. It identifies the intervention, the person who owns the decision, the business outcome, the acceptable risk, and the uncertainty that needs to be resolved. Without it, AI will produce an intelligent-sounding tour of your metrics. With it, AI has an analytical job.

    Map the decision to a measurement chain rather than a single conversion number. For SEO, GEO, paid media, content, and brand campaigns, that chain usually moves through four distinct stages:

    Measurement stageQuestion it answersUseful evidenceWhat it does not prove
    Demand formationAre more relevant people becoming aware of the problem and your brand?Non-brand discovery, visibility in relevant AI answers, brand mentions, branded search interest, and engagement from the intended audienceThat marketing caused revenue
    Demand captureAre interested people entering and progressing through an owned journey?Relevant landing-page visits, return visits, form starts, content progression, and response to calls to actionThat the captured demand is incremental
    Commercial progressionAre the right prospects becoming viable sales opportunities?Qualified leads, sales acceptance, opportunity creation, stage movement, and account-level engagementThat a particular platform deserves all the credit
    Business outcomeIs the activity producing commercial value?Pipeline, revenue, retention, margin, or another agreed business resultWhich intervention caused the difference

    This separation matters when the lower funnel looks weak. A decline in remarketing conversion may appear to justify a budget cut. But if non-brand acquisition has slowed, competitors are gaining visibility, and fewer new qualified visitors are entering the journey, remarketing may be displaying an upstream demand problem rather than causing it. Looking across systems can reveal that the apparent channel failure is really a missing layer of demand creation.

    Use four evidence labels consistently: observed, attributed, associated, and incremental. An observed change is simply present in the data. An attributed result received credit under a platform or analytics rule. An associated result moved alongside another signal. An incremental result is the difference that would not have occurred without the intervention, supported by a suitable experimental comparison. AI should never silently promote evidence from one level to another.

    This is especially important for AI-search measurement. A citation or brand mention in a relevant answer is an upstream visibility signal. Branded search, direct visits, and assisted engagement can provide additional evidence. CRM outcomes show commercial progression. These signals belong in the same chain, but placing them next to one another does not make the first one the proven cause of the last one.

    Build a measurement spine before adding an AI agent

    Four abstract marketing signal streams connect through calibrated gateways to a shared central measurement backbone and decision chamber.

    AI does not remove data silos merely because it can read several exports. If web analytics, Google Search Console, brand monitoring, advertising platforms, and the CRM use different campaign names, conversion definitions, timestamps, and identity rules, the model will automate the disagreement.

    A measurement spine is the small set of shared definitions and identifiers that connects those systems. It does not require every tool to become one giant database. It requires each system to describe the same business events consistently enough that evidence can be reconciled.

    Create a measurement contract for every metric that can affect a budget or campaign decision. Record:

    • The canonical metric name and plain-language definition.
    • The business question the metric is allowed to answer.
    • The system of record when platforms disagree.
    • The unit represented by each row, such as a person, account, session, campaign, opportunity, or transaction.
    • The event timestamp, reporting timestamp, timezone, and currency rules.
    • The identifiers used to join campaign, content, account, and revenue data.
    • Inclusion and exclusion rules, including internal traffic, duplicates, test records, and disqualified leads.
    • The expected update cadence and how stale data is marked.
    • Known coverage gaps and changes in tracking.
    • The experiment identifier and exposure status when a test is active.

    Keep the original channel-native value alongside the canonical value. A platform conversion can still be useful for platform optimization even when finance uses a different revenue definition. Preserving both prevents a clean warehouse field from erasing the context needed to explain a discrepancy.

    Identity resolution also needs restraint. Join data at the least sensitive level that can answer the decision. An account-level key may be sufficient for a B2B pipeline question; a campaign or content identifier may be sufficient for a visibility question. Do not send raw personal information, credentials, or unrestricted customer records to an AI system. Use an approved environment, restrict access, and provide only the fields required for the analysis.

    Put a data-quality gate in front of every AI analysis. The gate should ask:

    • Did all expected systems update for the reporting period?
    • Do totals reconcile with the designated systems of record?
    • Are joins dropping or duplicating campaigns, accounts, opportunities, or revenue?
    • Are timestamps, currencies, attribution windows, and conversion definitions aligned?
    • Did a tag, consent rule, CRM stage, platform setting, budget, or campaign structure change?
    • Did another experiment expose the same audience during the same period?

    If a check fails, the correct AI output is "analysis blocked" or "result qualified," not a plausible estimate inserted into the gap. Missing data is a measurement state. Hiding it turns uncertainty into false precision.

    Use AI as a governed analyst, not the final judge

    Once the measurement spine is reliable, AI is useful for work that is tedious, cross-channel, and easy to perform inconsistently. Give it bounded analytical jobs:

    • Reconcile channel, site, search, brand, CRM, and revenue signals around one decision.
    • Flag divergences, such as improving click efficiency alongside declining new-audience reach or qualified pipeline.
    • Audit experiment history for repeated variables, inconclusive tests, audience collisions, platform resets, and unexamined failures.
    • Convert a business question into candidate hypotheses with an explicit mechanism and predicted direction.
    • Rank proposed tests by risk, learning value, and operational feasibility.
    • Monitor declared primary and guardrail metrics without changing the test autonomously.
    • Draft a result summary that distinguishes measured facts, interpretations, data gaps, and recommended follow-up.

    Require a fixed response structure from the model. Each analysis should return the decision being supported, evidence for and against the current hypothesis, conflicting signals, data-quality limitations, plausible alternative explanations, the smallest useful next test, operational risk, and a confidence label. This makes the output reviewable and discourages a polished narrative built around whichever metric happened to move.

    Keep human approval at three boundaries: choosing what the business is willing to risk, authorizing changes to live campaigns, and deciding whether evidence is strong enough to scale. Start with read-only AI access. A model that detects a CPA spike can recommend an interruption review; it should not rewrite budgets unless you have deliberately built and validated that authority.

    AI also needs explicit causal limits. Attribution models distribute credit according to configured rules. Cross-system analysis identifies patterns and likely failure points. A controlled experiment estimates what changed because of an intervention. These are different jobs. A model can help design or analyze the experiment, but it cannot manufacture the missing counterfactual from an ordinary dashboard.

    Synthetic audiences can screen messaging before real-world exposure. Use them to identify confusing language, obvious positioning conflicts, or persona-specific objections. Do not use simulated preference as proof of demand, conversion lift, or market response. It is a filter for weak candidates, not a substitute for observed behavior.

    Run fewer experiments with cleaner isolation

    A researcher observes two isolated test chambers where one colored light is the only visible difference between otherwise identical setups.

    The best next experiment is not the most creative one. It is the test that resolves an important uncertainty without exposing the business, the brand, or the platform algorithm to unnecessary disruption.

    Write the hypothesis before producing variants. Use this structure:

    "Among the eligible audience, changing this defined variable should move this primary outcome in the predicted direction because of this mechanism. We will advance, reject, or classify the result as inconclusive under the prewritten decision rule, provided the guardrail metrics remain acceptable."

    The mechanism is the most valuable part. "Test a new headline" names an activity. "Emphasize faster time-to-value because the intended buyer appears to prioritize speed over ease of use" names an idea that can be supported, weakened, or refined. Even a losing test can improve future decisions when the mechanism is explicit.

    Every test card should identify the decision owner, eligible population, assignment unit, control and treatment, variable being changed, primary outcome, guardrail metrics, planned analysis window, completion rule, interruption rule, conflicting campaigns, and platform changes that could invalidate interpretation. If one of these fields cannot be filled in, the test is not ready.

    Next, score operational risk against learning value. Useful dimensions include budget impact, algorithm disruption, audience overlap, brand sensitivity, and the value of the expected learning.

    Learning valueOperational riskDefault decision
    HighLowPrioritize and run with the normal controls.
    HighHighReduce exposure, pre-test the risky element, isolate the audience, or use a stronger control.
    LowLowBacklog it unless it is exceptionally cheap and does not interfere with a more valuable test.
    LowHighReject it. Activity does not justify disruption.

    Guardrails should be written before anyone sees a result. As illustrations, a team might reserve 10% of a budget for experimentation and define an interruption review if CPA deteriorates by more than 15% across five days. Those are examples, not universal defaults. Your limits must reflect margins, conversion volume, cash constraints, brand exposure, and the normal volatility of the channel.

    Your guardrail document should cover the testing budget, maximum acceptable performance deterioration, platform-specific reset conditions, tracking failures, audience contamination, early warning signals, and brand boundaries that cannot be crossed. Give the same document to the AI system that proposes and monitors experiments. Otherwise, the model is optimizing without knowing what the business considers unacceptable.

    Sequence tests so that each one answers a recognizable question. If you change the audience, creative concept, offer, landing page, and budget together, a better result does not reveal which change mattered. Start with the lowest-risk environment that can reject a weak idea. A positioning claim might be screened with synthetic personas, then observed in an organic setting, then tested in a controlled paid environment. Evidence from each stage determines whether the next exposure is justified.

    When a live test begins, protect its isolation. Avoid overlapping experiments on the same eligible audience. Hold the major variable families steady. If simultaneous changes are unavoidable, preserve a credible control group and record every collision. Do not let an AI agent quietly "improve" a weak variant halfway through the run; that creates a new treatment and compromises the original comparison.

    Platform stability is part of experiment cost. Significant changes to creative, audience, campaign structure, or budget can restart learning and cloud the result. Ad sets that remain in a learning phase have been associated with CPAs 20%-40% above those of stable ad sets, though the effect in your account may differ. Multiple overlapping resets can therefore make the whole account look worse, even when none of the ideas being tested is inherently bad.

    Prewrite both completion and interruption rules. Do not stop merely because an early reading looks attractive or uncomfortable. Interrupt when a declared safety, brand, tracking, or financial boundary is crossed. Otherwise, allow the planned evidence to accumulate and classify the outcome honestly as a supported win, supported loss, inconclusive result, or invalidated test.

    Turn every result into reusable measurement memory

    A completed experiment should change more than the current campaign. It should improve the quality of the next hypothesis, reduce repeated mistakes, and help a future analyst understand why a decision was made.

    Store one durable record for every launched test, including:

    • An immutable experiment identifier and the decision it supported.
    • The hypothesis, proposed mechanism, and expected direction.
    • The audience, channel, content, creative, offer, and landing experience involved.
    • The assignment method, control, treatment, and exposure rules.
    • The primary outcome and guardrail metrics.
    • Tracking changes, platform resets, audience overlap, and other anomalies.
    • The result, evidence label, confidence assessment, and unresolved uncertainty.
    • The decision made, responsible owner, and next test if one is warranted.
    • Any later check showing whether the effect persisted, weakened, or disappeared.

    Link every AI-generated interpretation back to the underlying experiment record, query, or dashboard view. The summary is a navigation layer, not the evidence itself. A future reviewer should be able to trace "speed messaging worked" to the precise audience, outcome, comparison, and limitations. Otherwise, a narrow result will gradually become an unsupported company-wide belief.

    Before approving a new test, ask AI to search this memory for similar mechanisms, audiences, and variables. It should identify repeated low-value ideas, apparent failures that were actually inconclusive, results compromised by volatility, and interactions worth examining. The output should recommend the smallest remaining uncertainty, not simply generate another batch of variants.

    This memory also helps you respond intelligently when leading and commercial indicators move at different speeds. If upstream visibility and qualified engagement improve while pipeline remains flat, keep the claims narrow: demand signals are strengthening, but commercial impact is unproven. Check the next handoff and any expected reporting lag before scaling. If every stage suddenly declines, verify tracking and joins before rewriting strategy. If only the platform deteriorates during several overlapping tests, investigate resets and audience contamination before declaring that demand has vanished.

    Integrated measurement is valuable because it shows where momentum may be forming and where the chain is breaking. It is not a license to claim causality from a synchronized chart. The discipline is to act on leading evidence with bounded exposure, then require stronger evidence before making a larger commitment.

    Key takeaways

    • Begin with a budget, campaign, or positioning decision and define what evidence would change it.
    • Connect demand, capture, commercial, and revenue signals through shared definitions and identifiers.
    • Use AI to reconcile evidence, expose uncertainty, audit test history, and propose the smallest useful experiment.
    • Keep causality labels, live-campaign authority, sensitive data, and acceptable risk under human control.
    • Sequence experiments, protect controls, record platform resets, and reject tests whose disruption exceeds their learning value.
    • Preserve every result in a traceable knowledge base so future tests start from accumulated evidence rather than memory.

    Your next move is to choose one live marketing decision and build its measurement chain. Give AI the definitions, guardrails, historical tests, and permission to identify the single uncertainty blocking that decision. Then run the cleanest affordable experiment that can resolve it. If the proposed test cannot explain what you will do differently after each possible result, do not launch it.

    References

  • Boost SEO with AI Without Sacrificing Your Unique Brand Voice

    Boost SEO with AI Without Sacrificing Your Unique Brand Voice

    As someone navigating the world of SEO and content marketing, I’ve noticed a looming problem: everything is starting to sound eerily similar. It’s the same phrases, the same structure, and a robotic tone that seems to dominate.

    The web is overflowing with content that’s perfectly optimized yet fails to engage readers. That’s the real danger, not AI replacing SEOs or causing penalties. The biggest threat is losing our unique brand voice in the quest for efficiency.

    Rather than flattening our content, AI should enhance our SEO efforts. It should make us faster and more adaptable, without stripping away what makes our brand stand out. Here’s how I ensure AI doesn’t turn my brand into a faceless entity.

    To me, AI works best when it complements a clear strategy. It’s not a substitute for a marketing plan or brand direction. Just like tools such as Google Analytics or Semrush, AI is a support system, not a replacement.

    In my experience, without a deep understanding of our audience, AI merely churns out content that lacks distinction. That’s why defining who you are as a brand is crucial before turning to AI as an assistant.

    I’ve found AI shines when handling large data sets, spotting trends, or identifying content gaps. It accelerates my processes, allowing me to focus on the strategic aspects of SEO.

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    However, AI falls short in areas that depend on creativity and emotional engagement. It doesn’t truly understand brand values or ethical nuances. It can mimic, but not truly connect or empathize.

    Therefore, I let AI handle data-driven tasks, while keeping the heart of my branding – its voice and soul – firmly within human hands.

    Before using AI, I clarify my brand’s tone, language, and boundaries. A well-defined brand voice ensures AI assists without diluting our identity.

    In practice, I use AI for research and framework creation, but ensure human inputs sculpt the final content. Editing and authenticity checks are critical steps I never skip.

    The key takeaway is that AI amplifies whatever brand essence you feed it—it can’t create it from scratch. Maintaining clarity and a distinct brand voice is what sets successful SEO apart.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • AI Marketing Governance: Scale Creative Without Losing Trust

    AI Marketing Governance: Scale Creative Without Losing Trust

    You have a campaign due, the platform wants more assets than your team can shoot, and an AI tool can produce the missing scenes in minutes. The production problem looks solved. The harder question arrives at approval: does the result still represent the product, the customer and the brand truthfully?

    You do not need to choose between using AI and being authentic. You need a governance system that distinguishes harmless assistance from consequential manipulation, preserves evidence for every claim and stops questionable work before speed turns it into scale.

    Key takeaways

    • Authenticity is not the absence of AI. It is the absence of a misleading gap between what your marketing depicts and what a reasonable customer would believe.
    • Govern the output and its likely interpretation, not the name of the tool that produced it.
    • Give every AI-assisted asset a source record, a named approver and a defined withdrawal path before publication.
    • Disclosure can explain how an asset was made, but it cannot make a false product claim, invented testimonial or nonexistent result acceptable.
    • Use the same approved facts across ads, landing pages, product feeds, public relations, structured data and answer-engine content. Contradictory claims weaken both customer trust and machine-readable credibility.

    Authenticity is a truth boundary, not a production method

    A manually produced campaign can be deceptive. An AI-assisted campaign can be accurate. The relevant distinction is not human versus machine; it is faithful representation versus manufactured belief.

    That distinction matters because AI can now support a wide range of creative operations, including background removal, lifestyle-scene generation, synthetic people and rapid asset variation. The resulting production capacity is useful, but technical permission is not the same as brand permission. Your policy has to decide what the audience may reasonably infer from the finished asset.

    Use four questions at the creative brief, review and approval stages:

    1. What will the audience think is real? Identify the likely interpretation, not merely the literal elements on screen. A person may understand that a decorative background is illustrative while assuming a product demonstration, testimonial or before-and-after image records a real event.
    2. Does the synthetic element affect the decision? Color accuracy, dimensions, included features, product condition, customer identity, quoted experience and demonstrated outcomes can all influence a purchase or trust decision. Treat those elements as material.
    3. Can the implied claim be substantiated? You should be able to trace a factual statement or visual implication to an approved product record, documented result or other internal evidence. If the evidence cannot be found, the asset is not ready.
    4. Would knowledge of the AI intervention change the audience’s judgment? If the answer is yes, redesign the asset, disclose the intervention clearly or do both. Do not hide a consequential transformation behind a broad statement that AI was used somewhere in production.

    A synthetic background behind an unchanged product may create little expectation risk. A synthetic person presented in a way that resembles a customer, employee or expert creates much more. A generated product feature that does not exist crosses the truth boundary entirely.

    Disclosure belongs after this truth test, not in place of it. A label can tell someone that an image is simulated. It cannot repair an inaccurate price, fake endorsement, invented review, altered package size or performance claim that your evidence does not support. When the underlying claim could create compliance or legal exposure, pause publication and route it to the appropriate qualified reviewer. A creative approval is not a substitute for legal review.

    Use a four-level integrity ladder for AI-assisted work

    Four ascending studio platforms show increasingly consequential forms of AI-assisted product imagery connected to a real product by a golden thread.

    A practical policy needs more than a general instruction to use AI responsibly. A four-level brand integrity hierarchy gives marketers, agencies and approvers a shared way to classify work before debating individual assets.

    Integrity levelTypical outputDefault decisionRequired control
    AssistanceResizing, cropping, cleanup, formatting or copy variation that preserves the approved meaningAllowed within documented brand rulesRetain the original and confirm that facts, qualifications and visual product attributes did not change
    AdaptationBackground replacement, contextual scenes, localization or audience variants built around a real product or approved claimAllowed with reviewRecord what was synthetic, verify the product representation and decide whether the context needs disclosure
    SynthesisSynthetic people, realistic events, demonstrations or scenes that an audience could interpret as documentary evidenceConditional and escalatedRequire an accountable approver, a documented disclosure decision, substantiation for every implication and confirmation that no real person’s identity is being misrepresented
    FabricationInvented testimonials, nonexistent features, unsupported outcomes, fake certifications or materially altered productsProhibitedDo not publish; correct the brief or obtain valid evidence for a truthful alternative

    Classify the finished output, not the software. The same generator could perform low-risk cleanup in one workflow and create an unacceptable customer simulation in another. Tool-based rules age quickly and invite loopholes; output-based rules remain understandable when platforms change their features.

    Context can also move an asset up the ladder. Replacing the background behind a product is usually adaptation. It becomes more consequential if the new setting implies that the product is certified for a particular environment, fits a space it does not fit or has a capability it does not have. Likewise, a synthetic human used as decorative illustration differs from one presented beside testimonial language that implies a genuine experience.

    Write examples from your own campaigns beside each level. Include one clearly allowed example, one conditional example and one prohibited example for the channels your team actually uses. Those precedents will resolve ordinary decisions faster than an abstract ethics statement.

    Turn the policy into a publishing gate

    Reviewers inspect a marketing image, a physical product and supporting papers as creative assets pass through a transparent publishing checkpoint.

    A governance document does not protect the brand if approval still happens in chat threads, source files disappear and nobody can identify who accepted the risk. The control has to sit inside the publishing workflow.

    Your operating policy should define:

    • Scope: the channels, teams, contractors, agencies and asset types covered by the policy.
    • Allowed uses: transformations that can proceed under standard review.
    • Conditional uses: outputs that require disclosure, specialist review or approval from a more accountable role.
    • Prohibited uses: transformations that cannot be published even when labeled as AI-generated.
    • Evidence requirements: the records that must support factual, comparative, visual and testimonial claims.
    • Disclosure rules: when a disclosure is required, where it must appear and who approves its wording and placement.
    • Responsibility: who creates, verifies, approves, publishes, monitors and withdraws an asset.
    • Exception handling: who can authorize an exception, what evidence is required and when that decision must be revisited.

    Move each asset through the same evidence path

    1. Set the truth boundary in the brief. List the product attributes, claims, qualifications and visual details that cannot change. State what may be synthesized and what the asset must not imply.
    2. Assemble an approved reference pack. Give the creator the current product images, specifications, brand terminology, claim substantiation and required qualifications. Do not make the reviewer reconstruct the ground truth after generation.
    3. Create within the assigned integrity level. Record the tool or production path, the original materials and the meaningful transformations. You do not need to archive every inconsequential interaction, but you do need enough provenance to reproduce the decision and investigate a problem.
    4. Verify the rendered output. Check the actual sizes, crops, overlays, captions, product details and landing-page destination that the audience will see. A correct master file can become misleading when a placement removes a qualification or crops out context.
    5. Approve the claim and the presentation separately. One check asks whether the underlying statement is supported. The other asks what a reasonable person will infer from the combination of words, images and placement. Passing one does not guarantee the other.
    6. Publish with a withdrawal record. Log the channels and destinations where the asset appears. If a claim changes or an error is found, the team should know where to remove or replace every affected version.

    The asset record can be compact. Capture the campaign and channel, source materials, meaningful AI transformations, claims used, disclosure decision, reviewer, approval state and publication locations. What matters is that someone other than the creator can understand why the asset was approved.

    Human review is not a control by itself. The reviewer needs access to the evidence, clear authority to stop publication and enough time to inspect the final placement. A person who can only click approve is part of the production sequence, not an effective safeguard.

    Paid media needs particular care because asset demand, automated combinations and placement variation can multiply one error quickly. Product imagery deserves a hard verification gate: visual inaccuracies can produce disapprovals or account risk in Merchant Center. Compare the rendered product with the approved reference, including packaging, included components, proportions, color and visible features. If the generated scene obscures that comparison, use a more faithful asset.

    Exceptions should be visible and temporary. Record the business reason, risk owner, supporting evidence and condition that ends the exception. The person requesting an exception should not be its sole approver. Otherwise, deadlines will quietly rewrite your policy one campaign at a time.

    Connect creative governance to SEO, AEO, GEO and PR

    Authenticity problems rarely stay inside the ad account. A generated claim can reach a landing page, product feed, public-relations pitch, social caption, FAQ and structured-data field. Each copy may look defensible in isolation while the combined public record becomes contradictory.

    Build a claim register as the shared layer beneath those channels. For each meaningful claim, record:

    • the canonical wording and any required qualification;
    • the internal evidence or approved public page that supports it;
    • the product, market and context in which it applies;
    • the accountable owner;
    • the channels where it may be used;
    • the disclosure or presentation restrictions attached to it;
    • the condition that should trigger review, correction or withdrawal; and
    • the structured-data properties, feed fields and content components that repeat it.

    This register gives your teams one approved truth rather than several channel-specific versions. Copywriters know which qualifications must survive a short format. PPC teams know which visual implications require evidence. SEO and GEO teams know which public pages should explain and substantiate the claim. Schema implementers know which statements are safe to mark up.

    Structured data should describe visible, supported content. It does not validate a claim merely because the markup is syntactically correct. If the page, product feed and JSON-LD disagree about a product attribute, fix the underlying content system instead of choosing the version most likely to attract a machine.

    Citation readiness also belongs in the governance process. Citations in AI-generated answers can contribute to credibility, and understanding how a brand appears through publicly available information can inform PR decisions. That makes the quality of your supporting pages important beyond conventional rankings.

    A citation-ready page should make the supported claim easy to identify, define its scope and keep the qualification beside it. It should also use consistent product and organization names, connect the claim to the relevant entity and avoid implying that a synthetic scene is proof. A citation can carry an unsupported statement farther; it cannot convert that statement into evidence.

    Monitor governance signals that reveal process failure rather than treating campaign performance as proof that the process worked. Useful signals include assets published without complete provenance, unresolved evidence gaps, exceptions still open, corrections caused by product mismatch, platform disapprovals associated with altered creative and the time required to withdraw a faulty claim across channels.

    Audit what is already live

    Start with a representative set of active ads, landing pages, product feeds, social assets, PR materials and structured data. Classify each AI-assisted element on the integrity ladder. Then trace every consequential claim backward to its evidence and forward to every place it appears.

    Prioritize assets with realistic people, demonstrations, testimonials, product alterations or purchase-critical details. If you cannot identify the source fact, the approving person or all publication locations, you have found a governance gap. Pause the highest-risk asset, establish the missing record and use that case to write the first concrete rule in your policy.

    For your next campaign, define the prohibited transformations in the brief, assign the integrity level before production and name the approver before generation begins. Once those decisions become routine, AI can increase creative capacity without multiplying ambiguity about what your audience is being asked to believe.

    References