Category: AI

  • How to Build Trust With Data in AI and SEO Decisions

    How to Build Trust With Data in AI and SEO Decisions

    Your dashboard can be technically correct and still fail the meeting. If nobody can explain who is represented, how the number was produced, or whether automated and fraudulent activity was removed, the chart asks people to take your conclusions on faith.

    Trust comes from making the evidence inspectable. You should be able to move from a recommendation to its claim, from the claim to its metric, from the metric to the underlying records, and from those records back to their origin. Assumptions, exclusions, and uncertainty need to remain visible throughout that chain.

    Trust starts with a claim your data can support

    A precise-looking number is not automatically a trustworthy number. Decimal places, clean schemas, polished charts, and large record counts can make data appear authoritative without proving that it represents the right people, activities, or period.

    This distinction matters when AI enters the workflow. An AI system can process weak data efficiently, but it cannot independently establish that an identity is genuine or an event is meaningful. In practice, AI can amplify fragmented, outdated, or manipulated inputs and return the result with more confidence than the evidence deserves.

    Before you analyze a dataset, make its intended claim explicit. Then test the claim against six questions:

    • Entity: Who or what does each record represent? Determine whether identifiers refer to the same person, account, page, organization, query, or session across the systems involved.
    • Activity: What actually happened? Separate a recorded event from an authentic action with business or user value.
    • Time: When was the record true, collected, and refreshed? A valid historical snapshot should not be treated as a current state.
    • Origin: Which system created the record, and which system merely copied or transformed it? Name the accountable owner.
    • Exclusions: Which records were filtered out, suppressed, deduplicated, or classified as suspicious? Record the rule and its reason.
    • Decision fit: Does the dataset measure the decision in front of you, or only a convenient proxy for it?

    If you cannot answer one of those questions, narrow the claim. For example, do not report that AI visibility improved everywhere when you measured only a defined set of prompts and answer environments. State that limited scope in the claim itself. A smaller claim that can be verified is more useful than a sweeping conclusion that cannot survive inspection.

    Clean structure is still valuable, but it solves a different problem. A record can have the expected fields, valid syntax, and consistent formatting while referring to the wrong identity or a fabricated activity. Structural validity tells you that the data can be processed. It does not prove that the data is accurate.

    Create an evidence card for every decision-bearing claim
    Hands arrange transparent evidence tiles linked to a central token, with one tile lifted to reveal the granular pieces beneath it.

    A dashboard rarely carries enough context on its own. Filters live in one tool, transformations in another, and caveats in somebody’s memory. When the result is challenged, the team has to reconstruct the reasoning after the fact.

    Use a compact evidence card for each claim that could change a budget, campaign, content plan, model, or workflow. Store it beside the analysis rather than in private notes.

    1. Decision: Write the choice this evidence is meant to inform. If no decision changes, question whether the metric belongs in the report.
    2. Claim: State one sentence that the data directly supports. Avoid combining an observation, an explanation, and a recommendation in the same sentence.
    3. Scope: Name the entity, population, channel, property, prompt set, and time window included. Record the denominator where the metric has one.
    4. Definition: Define the metric in operational terms. Specify what creates an event, what qualifies it, and how duplicates are handled.
    5. Lineage: List the originating system, collection method, joins, transformations, filters, and derived fields used to produce the result.
    6. Quality gates: Document the checks applied to identity, authenticity, freshness, completeness, and consistency.
    7. Limitations: Separate known gaps from suspected gaps. Explain how each one could change the conclusion rather than hiding them under a generic disclaimer.
    8. Action and owner: Name the proposed action, the person responsible, the signal that will be monitored, and the condition that would trigger reconsideration.

    The evidence card also protects metric definitions from drifting. If one reporting period counts all detected visits and another excludes suspected automation, the results are not directly comparable. The definition and filter change must travel with the number.

    Keep rejected records and reason codes available for review when your systems permit it. Silently removing questionable data makes a clean result harder to audit. A visible exclusion such as duplicate identity, stale record, suspected automated activity, or missing attribution shows exactly where judgment entered the pipeline.

    Audit AI and SEO inputs before you automate decisions

    AI readiness is often assessed through volume, match rates, or the apparent precision of model output. None of those signals proves that the underlying identities are stable or that the recorded behavior is authentic. Consumers move between devices and profiles, while systems often treat a temporary identity snapshot as permanent. Fraud and low-value activity can then distort both model output and the performance data used to retrain or evaluate it.

    Run an input audit at each layer of an AI SEO or analytics workflow. The purpose is not to certify data as perfect. It is to prevent the claim from becoming broader than the evidence.

    LayerQuestion to verifyMisleading conclusion to prevent
    Observed AI visibilityWhich prompts, answer environments, properties, locations, settings, and collection windows were monitored?A sampled result presented as universal visibility.
    On-site activityAre sessions and events authentic, consistently defined, and separated from suspected automated or fraudulent activity?Machine activity presented as audience demand.
    Identity and attributionCan records be matched to the intended person, account, organization, or journey without treating uncertain matches as confirmed?Inflated reach, duplicated users, or credit assigned to the wrong interaction.
    Business outcomeDoes the conversion represent a reachable, meaningful outcome rather than a form event or low-value identity?Nominal conversions presented as genuine pipeline or customer value.
    Model inputAre the records current, relevant, authentic, and appropriate for the task the model will perform?Confident automation built on an unreliable foundation.

    Treat identity validity and activity authenticity as gates, not decorative quality scores. If either one cannot be established, the affected data may still support exploration, but it should not silently drive targeting, outreach, optimization, or other automated actions.

    Use sensitivity checks when uncertainty is concentrated in a recognizable subset. Compare the conclusion with and without low-confidence identities, suspected automation, stale records, or unmatched events. If removing that subset reverses the recommendation, the recommendation is fragile. Report that dependence before anyone acts on it.

    Watch for feedback loops as well. If fraudulent or low-value behavior improves a reported metric, an optimization system may learn to seek more of it. The apparent performance improvement then reinforces the very contamination that produced it. Suppress or quarantine questionable inputs before they become training signals, targeting criteria, or success labels.

    Separate observation, interpretation, and recommendation
    Three connected workbench stations show raw data pieces, a lens revealing patterns, and several possible paths around a decision marker.

    Many data presentations lose trust because they slide from measurement to causation without marking the transition. A result occurred after a change, so the change is credited with causing it. A visibility metric rose, so business impact is implied. A model found a pattern, so the pattern is treated as a stable rule.

    Use four explicit labels in reports, dashboards, and decision memos:

    • Observed: What the collection method directly recorded within its stated scope.
    • Calculated: What was produced through a documented formula, join, classification, or transformation.
    • Inferred: What the evidence may explain or predict, including plausible alternatives.
    • Unknown: What the current design cannot establish.

    A careful AI visibility statement might say that a page appeared more frequently in the monitored answer set during the review window. That is the observation. Content or structural changes may be plausible contributors, but prompt sampling, model behavior, competitor changes, and measurement differences remain alternative explanations unless the evaluation design rules them out. The recommendation can still be to retain or extend the change, provided the team continues testing the explanation.

    This language is not weakness. It tells the decision-maker which parts are facts, which parts are judgment, and which parts require another measurement cycle. Use causal words such as caused, produced, or drove only when the evaluation was designed to support causality. Otherwise, use language such as coincided with, is consistent with, or may have contributed.

    Do not turn uncertainty into an arbitrary confidence percentage. If confidence has not been calibrated, a precise score creates another unsupported claim. Name the evidence that raises confidence, the gap that lowers it, and the observation that would change your position.

    Use a three-act narrative without turning evidence into theater

    People need more than a pile of verified metrics. They need to understand why the evidence matters and what should happen next. A setup, confrontation, and resolution structure can organize that reasoning while keeping the decision-maker at the center of it.

    1. Setup – establish the baseline and objective. State the decision, the prior strategy, the relevant success criteria, and the conditions in which the data was collected. Show what was working as well as what was not.
    2. Confrontation – expose the obstacle and competing explanations. Present the gap between the objective and the observed state. Include identity problems, suspicious activity, measurement changes, missing coverage, and other facts that could challenge the easy interpretation.
    3. Resolution – connect action to evidence. Recommend the next move, explain which claim supports it, and define the guardrails. State what will be measured next and what result would cause the team to revise the plan.

    The narrative should organize evidence, not rescue it. Do not remove an inconvenient metric because it interrupts the story. Do not portray a forecast as the ending. The resolution is a justified next action with a way to learn, not a guaranteed outcome.

    At the presentation level, use one decision-bearing claim per chart or report block. Put the scope in the title or immediately below it. Display the comparison window, unit, denominator, filters, and relevant definition change close to the result. Place a material limitation beside the claim it limits, where it can affect the decision, rather than collecting caveats at the end.

    Finish each claim with an action, an owner, and a revisit condition. That turns the presentation from a performance into a shared operating record. It also gives future analysis a clean baseline: the team can see what it believed, why it believed it, what it decided, and which evidence later confirmed or challenged that decision.

    Key takeaways

    • Make every claim no broader than the identities, activities, channels, and time window you can verify.
    • Do not confuse structured or complete-looking records with accurate identities and authentic behavior.
    • Give each decision-bearing claim an evidence card containing its scope, definition, lineage, quality checks, limitations, action, and owner.
    • Audit data before it enters an AI workflow because automation can scale unreliable inputs and reinforce contaminated feedback loops.
    • Label observations, calculations, inferences, and unknowns so readers can see where evidence ends and judgment begins.
    • Present the decision as a setup, a confrontation with the real constraints, and a resolution tied to a measurable next action.

    Before your next dashboard review or model run, choose the one claim most likely to change a decision and complete its evidence card. If you cannot identify the entity, activity, window, origin, exclusions, and limitation, narrow the claim before you polish the presentation. Then give the decision-maker a clear next action and a defined reason to revisit it.

    References


  • Claude-Powered PPC Automation: From Prompts to Systems

    Claude-Powered PPC Automation: From Prompts to Systems

    If Claude gives you a strong search-term analysis only after you paste the same instructions and CSV into a new chat, you have improved the task, not automated it. You still have to assemble the context, request the analysis, normalize the output, and move each approved change into Google Ads.

    Claude-powered PPC automation becomes useful when you design those handoffs once. The practical system has three separate parts: decision logic, access to current campaign data, and controls over what the AI may change. Get those parts right and Claude can take recurring work off your desk without taking campaign authority away from you.

    The three parts of a reliable Claude PPC system

    Three connected modules represent campaign data access, AI decision logic, and human-controlled execution safeguards.

    The model is only one layer of the system. A dependable workflow also needs a stable playbook and an explicit operating boundary.

    System partWhat it doesThe question you must answer
    Claude SkillEncodes the task, decision rules, required inputs, exceptions, and output structure.What should happen every time this PPC job runs?
    Data and toolsSupply campaign context and, when authorized, provide a way to execute an approved action.Which data may Claude read, and which operations may it call?
    Workflow controlsDefine scope, approval requirements, stop conditions, and records of proposed or completed changes.What is Claude allowed to decide, recommend, and change?

    A Claude Skill is a task-specific playbook, not a general preference about tone or behavior. It can tell Claude how to audit an account, evaluate search terms, generate ad assets, or compare budget opportunities. The instructions can be stored in a Markdown file, kept locally, or shared through a repository so the team uses the same method.

    The main benefit is procedural consistency. Without a fixed contract, one run might return letter grades while another uses percentages or an unrelated numerical scale. That is more than a presentation problem. A person, spreadsheet, script, or approval workflow cannot reliably consume an output whose structure changes between runs.

    A Skill should make the process predictable, but it should not pretend every PPC judgment is deterministic. Campaign evidence changes, and some cases will remain ambiguous. Your playbook therefore needs both decision rules and an explicit way to return insufficient evidence, conflicting signals, or required human review.

    The data layer solves a different problem. A Skill can know how to evaluate a search query report while knowing nothing about the queries currently appearing in your account. A Model Context Protocol connection can bridge that gap: MCP can connect Skill logic to live data sources and account tools. That turns a static playbook into an operating workflow, but it also makes permissions and approval gates essential.

    Build the first workflow around one recurring decision

    Start with a bounded job rather than asking Claude to optimize an account. Search-term mining is a practical first candidate because you can define the input, inspect every recommendation, and test the logic without granting write access.

    1. Define the job in one sentence. For example: review search terms from the requested 14-day window, identify waste and opportunity using the account’s approved criteria, and return proposed actions for review. The 14-day period is an input to this workflow, not a universal recommendation for every account.
    2. Write down the judgment currently living in the operator’s head. Include the evidence Claude must consider, the conditions that support each recommendation, the exceptions that require escalation, and anything it must never infer from missing data.
    3. Lock the output contract. Name every required field, its allowed values, and what a stopped run looks like. Do not let Claude invent a new scoring system or column set each time.
    4. Convert the SOP into a Skill. A useful instruction is: Convert this SOP into a task-specific Claude Skill. Preserve the decision rules, define required inputs, return a fixed schema, stop when required fields are missing, and do not take write actions without approval.
    5. Run the Skill against a known CSV before connecting an account. Confirm that it covers the intended records, follows the rubric, flags exceptions, and returns the exact structure your reviewer or downstream tool expects.
    6. Connect live data in read-only mode. Compare the live run with the CSV-based process. Add write capabilities only after the connected workflow passes the same acceptance checks.

    A useful output contract for this workflow can require:

    • The account, campaign, and reporting window included in the run.
    • A completion status that distinguishes a finished analysis from a stopped or incomplete run.
    • The item reviewed, the evidence used, and the applicable decision rule.
    • The proposed action and a concise reason for it.
    • An exception field for missing inputs, conflicting signals, or cases outside the Skill’s authority.
    • An authorization state such as proposal, approved, executed, or rejected.

    The output contract is what turns a clever response into a component another person or system can trust. Claude should never quietly substitute a plausible answer when a required campaign field is unavailable. A stopped run with a precise error is safer and more useful than a polished recommendation built on incomplete context.

    Put money-changing actions behind explicit gates

    A human operator approves one proposed campaign change at a guarded barrier before it reaches an advertising budget.

    Access and authority are not the same thing. An MCP-enabled tool may make an account change technically possible, but your workflow still decides whether Claude may propose it, prepare it, or execute it. That distinction matters whenever an action can change spend, targeting, messaging, or delivery.

    Operating modeClaude’s roleHuman role
    Manual-context assistantAnalyzes an uploaded report and returns structured recommendations.Exports data, checks the result, and implements every change.
    Connected analystPulls permitted live data and prepares account-specific proposals.Reviews and approves each proposed action before execution.
    Controlled operatorExecutes only approved action types within the defined scope and constraints.Sets policy, handles exceptions, reviews logs, and can stop the workflow.

    Most teams should move through these modes in order. Live read access removes manual report handling without immediately exposing the account to automated edits. Proposal-only operation then shows whether the logic behaves well under current conditions. Controlled execution comes last, after the team knows which exceptions appear in real runs.

    Before enabling any write action, add these controls to the workflow:

    • Default-deny permissions. Claude may read or modify only the accounts, campaigns, objects, and action types explicitly included in scope.
    • Action-specific approval. Treat applying an existing extension, creating an ad experiment, changing a search-term response, and reallocating budget as separate permissions.
    • User-defined financial boundaries. A budget workflow must operate inside limits set by the account owner rather than deciding its own acceptable spend change.
    • Fail-closed behavior. Missing data, an invalid schema, an unavailable tool, or an out-of-scope request should stop the run instead of triggering a best guess.
    • A preview of the exact modification. The reviewer should see what object will change, its current state, the proposed state, and the reason before approving it.
    • An audit trail. Preserve the input scope, Skill version, findings, approval state, tool response, and execution result so a later reviewer can reconstruct what happened.
    • A conflict rule. Give each task one canonical Skill, because overlapping audit or optimization Skills can reintroduce the inconsistency the system was built to remove.
    • A recovery plan. Document how an executed change will be reversed when reversal is available. Keep irreversible or poorly understood actions manual.

    Budget reallocation deserves the tightest gate because it moves money between campaigns. A recommendation can still be automated: Claude can compare the permitted data, explain the proposed shift, and prepare the action. Execution should remain subject to the account owner’s constraints and approval until the workflow has demonstrated reliable behavior in proposal-only mode.

    Use acceptance checks rather than impressions when deciding whether a workflow is ready. The run should always return the required fields, stop on missing inputs, stay inside its declared scope, expose the evidence behind each proposal, and show the planned modification before execution. If any of those checks fail, improve the Skill or connection before expanding its authority.

    Choose PPC tasks by controllability, not novelty

    The best first automation is not necessarily the task consuming the largest budget or producing the most visible output. It is the task whose rules can be written clearly, whose evidence can be inspected, and whose mistakes can be contained.

    PPC workflowWhat the Skill should standardizeFirst safe deploymentExpanded deployment
    Search-term miningThe evaluation rubric, required evidence, exception handling, and recommendation format.Analyze an uploaded report and return proposals for review.Pull live search-term data and implement only separately approved actions.
    Ad copy generationHow landing-page information, keywords, user intent, and value propositions become proposed ad assets.Generate structured drafts for human review.Identify underperforming ads, prepare alternatives, and create an approved experiment.
    Account auditingThe checklist, severity logic, supporting evidence, and distinction between findings and remedies.Return a consistent audit with no account changes.Use live account data and apply permitted remedies, such as attaching an existing extension where appropriate.
    Budget reallocationThe comparison method, constraints, explanation, and escalation conditions.Produce proposed reallocations with no write access.Execute approved shifts inside account-owner limits and record every result.

    These four workflows can all progress from manual data handling to connected execution, but they should not receive the same authority by default. Search-term analysis, ad generation, account auditing, and budget reallocation involve different consequences and therefore need different approval paths.

    Score a candidate workflow against five practical questions before building it:

    • Does the task recur often enough that removing handoffs will matter?
    • Can an experienced operator state the decision rules without relying on unexplained instinct?
    • Are the required inputs available in a stable, inspectable form?
    • Can a reviewer verify the recommendation before the account changes?
    • Can the impact of an error be contained to a narrow scope?

    If the answers are weak, connecting more tools will not improve the workflow. Clarify the SOP first. Automation magnifies whatever is encoded: good judgment becomes repeatable, while an ambiguous process becomes ambiguous at greater speed.

    For a first deployment, we would favor a proposal-only search-term or account-audit workflow. Both make it easy to compare Claude’s output with an existing human process. Ad experiments can follow once asset review is defined. Budget execution belongs later because its consequences reach spend directly.

    Frequently asked questions

    What is Claude-powered PPC automation?

    It is a workflow in which a Claude Skill applies a repeatable PPC playbook, data connections supply the required campaign context, and explicit permissions determine whether Claude analyzes, proposes, or executes an action. A chat response alone is assistance; automation also handles the recurring context and handoffs.

    Do you need MCP to use a Claude Skill for PPC?

    No. You can run a Skill against a manually uploaded CSV and implement its recommendations yourself. MCP becomes relevant when you want Claude to retrieve live data or use connected account tools. Start with manual or read-only data if the Skill’s decision logic has not yet been validated.

    Which PPC workflow should you automate first?

    Choose a recurring workflow with written rules, inspectable inputs, a fixed output, and limited consequences when something goes wrong. Search-term mining or a checklist-based audit is usually easier to validate than autonomous budget reallocation. Keep the first version proposal-only so you can judge the logic before granting execution authority.

    How do you prevent inconsistent Claude outputs?

    Use one canonical Skill for the task, define required fields and allowed values, state how exceptions must be returned, and stop the run when required data is missing. Remove or narrow competing Skills that could handle the same request. Test structural consistency before connecting the output to another tool.

    Take the next recurring search-term review or account audit and write down its rubric, output contract, and stop conditions. Test that process on a CSV, connect live data in read-only mode, and grant write access only after the workflow passes explicit acceptance checks. That sequence turns Claude from another prompt window into a PPC system you can supervise.

    References


  • AI Search Adoption Is Unequal: How Brands Should Respond

    AI Search Adoption Is Unequal: How Brands Should Respond

    If your search strategy begins with the assumption that everyone is moving from Google to ChatGPT at roughly the same pace, stop before you move the budget. The shift is real, but the average adoption figure hides the people, circumstances, and confidence levels driving it.

    You need a strategy that serves confident AI-search users without making conventional search worse for everyone else. That means maintaining two discovery paths, designing AI features as optional assistance, and measuring who benefits rather than treating every AI interaction as progress.

    The average adoption number hides different search realities

    In UK monitoring that began in early 2025, 27% of users said they regularly used ChatGPT. That topline becomes much less useful once household income enters the picture: higher-income households were substantially more likely to use generative AI tools.

    Treat that result as a segmentation signal, not a universal market adoption rate. It tells you that AI use can cluster around particular audiences. It does not tell you that every high-income person uses AI, that lower-income users lack interest, or that the same distribution applies in every country and category.

    Income matters partly because it sits alongside several mechanisms that affect whether someone makes AI part of a normal search journey:

    • Access: Can the person readily use the relevant tool in the context where the question arises?
    • Exposure: Do their workplace, peers, or professional routines encourage them to use AI? People in digital and corporate environments may encounter more prompts to incorporate it into daily work.
    • Capability: Can they frame a useful request, add context, refine a weak response, and inspect the supporting material?
    • Confidence: Do they trust themselves to use the interface and know when an answer needs checking?

    These factors reinforce one another. Frequent exposure builds skill. Skill can improve results. Better results can increase confidence and make the tool feel like the natural place to begin the next task. Someone without that loop may try the same interface once, receive an unhelpful answer, and return to a familiar search box.

    Trust also needs context. Perplexity users have reported high trust while the platform remains comparatively niche. Strong confidence inside a self-selecting user group is not proof of broad public confidence. It may simply describe the people who chose that tool and stayed.

    This is where an average can misdirect strategy. A revenue-weighted customer view may make AI search appear nearly universal if affluent decision-makers are overrepresented among early adopters. A traffic-weighted view may make it look marginal if the larger audience still relies on conventional results. Neither view is sufficient by itself.

    Before reallocating search investment, audit four questions for each important audience:

    1. Where does this audience normally encounter the problem: at work, at home, during a purchase, or while learning?
    2. Which interface do they use to begin, and which interface do they use to verify?
    3. What capability does the journey assume, such as prompting, comparing options, or checking citations?
    4. What happens when confidence fails: do they reformulate, open a conventional result, ask another person, or abandon the task?

    Do not use household income as a shortcut for individual behavior. Use it, when legitimately available and appropriately governed, as one possible research variable. Behavioral evidence such as entry path, repeated feature use, verification actions, and successful task completion is more useful for designing an experience.

    Build one evidence base for two discovery paths

    A shared foundation of connected content and evidence supports both an abstract conventional search interface and an abstract conversational AI interface.

    You do not need an AI site and a non-AI site. You need one dependable body of content that can support two ways of exploring it.

    Journey stageConventional search behaviorAI-search behaviorWhat your content must provide
    Frame the problemEnters a short query and scans resultsDescribes a situation and refines it through follow-up promptsA direct statement of the problem, audience, scope, and relevant terminology
    Compare optionsOpens several pages and compares claims manuallyRequests a synthesis, shortlist, or side-by-side explanationConsistent attributes, explicit differences, limitations, and decision criteria
    VerifyChecks the page, publisher, evidence, and supporting materialInspects citations or leaves the answer to check the underlying pageVisible evidence, clear authorship, dates where relevant, and traceable claims
    ActNavigates to a product, form, store, or next-step pageActs on a shortlist and may enter the site late in the journeyAccurate facts and an obvious next action that does not depend on AI

    The shared content layer matters because optimization for AI discovery cannot rescue weak information. A machine-readable page that never gives a clear answer is still unclear. A polished conversational response built from unsupported claims is still unsupported.

    For every high-value page, make the evidence layer usable in both paths:

    • Lead with the decision-relevant answer. State who the page is for, what question it resolves, and where the answer changes by circumstance.
    • Name entities consistently. Use the same product, organization, service, location, and category names throughout the visible content and metadata.
    • Expose comparison attributes. If a buyer must compare eligibility, compatibility, availability, process, or limitations, place those facts in plainly labelled sections rather than implying them through promotional copy.
    • Separate fact from judgement. Make it obvious which statements describe a documented feature and which represent your recommendation or interpretation.
    • Show evidence near the claim. A reader should not have to hunt through a generic resources page to discover what supports an important assertion.
    • Keep structured data aligned with visible content. JSON-LD should clarify the entities and relationships already present on the page, not introduce claims that visitors cannot verify.
    • Preserve a complete human-readable route. Do not require an AI assistant to reveal essential instructions, terms, limitations, or next steps.

    This approach lets conventional SEO, answer engine optimization, and generative engine optimization share the expensive part of the work: producing content precise enough to retrieve, interpret, compare, and verify. The delivery layer can vary without creating competing versions of the truth.

    Prioritization should reflect audience value without turning early adopters into a stand-in for the market. Fast adopters often include decision-makers and higher-income consumers, so AI visibility may deserve early investment even when total usage remains limited. The correct conclusion is to add coverage for an influential segment, not to remove coverage from everyone else.

    Add AI interfaces as assistance, not as a gate

    People choose between a conventional search panel and an optional conversational assistant while using a range of devices and accessibility methods.

    An on-page AI button can shorten a difficult task. It can also add ambiguity, expose visitors to weak generated output, or hide information behind an interface they do not want to use. The debate around AI buttons spans usability benefits, SEO risk, and fears of AI poisoning, so the useful question is not whether a button looks innovative. It is whether it helps a defined user complete a defined job safely.

    Start with the verb. Labels such as Summarize this policy, Compare these plans, or Ask about eligibility tell the visitor what the feature will do. A vague AI button asks the visitor to understand the technology before understanding the benefit, which creates exactly the kind of confidence barrier you are trying to reduce.

    Use six release gates before putting an AI interface into a search or content journey:

    1. Defined task: Write down the user job in one sentence. If the feature is meant to summarize, compare, explain, or route, choose one primary job and design for it.
    2. Optional path: Confirm that a visitor can reach the same essential information and next action without opening the AI experience.
    3. Clear boundary: Tell users what information the assistant uses and what it cannot determine. Do not invite sensitive or consequential input merely because a free-text box makes that possible.
    4. Grounded output: Make the response traceable to the approved page content or other clearly identified material. AI poisoning, in this context, is the risk that manipulated content or instructions distort what the system produces; limiting and validating the material available to the feature reduces the opportunity for that distortion.
    5. Recovery route: Provide a visible way to open the relevant page section, inspect supporting details, start over, or continue through the standard journey when the response is unhelpful.
    6. Success measure: Define success as task completion or a meaningful next step, not the number of times the button is clicked.

    Progressive enhancement is the right operating principle. Publish the essential content in stable, accessible HTML. Keep navigation, forms, and core actions usable without generated assistance. Then add the AI layer where summarization, comparison, or conversational clarification removes genuine work.

    This also protects the conventional search journey. If important information exists only inside a generated interaction, users cannot reliably scan it before opting in, and the standard page no longer carries the complete answer. The feature has stopped being assistance and become a gate.

    Test the full experience, not just whether the button opens. Check keyboard operation, focus order, labels, loading and error states, generated links, narrow screens, and the non-AI fallback. Review sample outputs for unsupported claims, missing qualifications, inconsistent names, and recommendations that exceed the page’s evidence.

    Measure adoption without averaging away inequality

    A single AI engagement rate cannot tell you whether the feature broadens access or merely serves the people who were already confident enough to try it. Build reporting around exposure, use, usefulness, recovery, and outcome.

    • Eligible exposures: How many visits actually encountered the feature on a relevant page?
    • Activation rate: Of those eligible visits, how many initiated the feature?
    • Task completion: How many users reached the intended next step after using it?
    • Fallback rate: How often did users leave the AI flow for the standard page, search, navigation, or support route?
    • Correction signals: How often did users regenerate, reformulate, dispute, or abandon the response?
    • Downstream outcome: Did the interaction support the real goal, such as finding the right page, understanding a requirement, completing a form, or making an informed selection?

    Break these measures down by relevant, ethically collected context. Useful views may include entry channel, task, first-time versus returning visit, exposure to the AI feature, prior feature use, and voluntarily reported confidence. If your organization has a legitimate basis for audience or income research, keep that analysis aggregated and governed rather than turning a population-level pattern into an assumption about an individual.

    Read the combinations, not just the totals:

    • Low activation and high completion can mean the feature is useful once discovered, but its label, placement, or trust cues are weak.
    • High activation and high fallback can mean curiosity is strong while output quality, task fit, or confidence is poor.
    • Strong outcomes concentrated among experienced users can mean the interface rewards existing AI literacy rather than reducing the skill barrier.
    • Rising AI engagement alongside falling conventional completion can mean the new interface is disrupting the baseline journey instead of improving it.
    • High commercial value from a small AI-search cohort can justify targeted investment, but it does not justify treating that cohort’s behavior as universal.

    Keep external AI discovery separate from on-site AI usage. Mentions, citations, referrals, assisted visits, and landing-page behavior describe visibility outside your site. Button activations, response quality, fallback, and completion describe the experience you control. Combining them into one AI score makes it harder to identify whether the problem is discoverability, content quality, interface design, or audience readiness.

    Your investment decision should follow the constraint. If the right audience cannot find you in AI-generated results, improve retrievability, entity clarity, and evidence. If people arrive but cannot verify the answer, strengthen the page. If an AI feature attracts clicks but blocks completion, fix or remove the feature. If conventional search still carries most successful journeys for an important audience, maintain it.

    Key takeaways

    • Do not use an average AI-adoption rate as your audience model; segment by behavior, context, exposure, capability, and confidence.
    • Treat income-linked adoption as a planning signal, not as a rule about any individual user.
    • Build one verifiable content base that supports both conventional search and conversational discovery.
    • Keep AI buttons optional, label them by the job they perform, and preserve the complete non-AI route.
    • Measure task completion, fallback, correction, and downstream outcomes by cohort; a click on an AI feature is not success.
    • Invest early where AI-search users are commercially important, but do not weaken the search paths used by the rest of your audience.

    Your next move is not to choose between SEO and AI search. Take one high-value customer journey, draw its conventional and conversational paths, inspect the shared evidence beneath both, and define the cohort-level measures before adding another AI feature. If you cannot see who gains, who struggles, and how either group recovers, the experience is not ready to scale.

    References


  • Modern Marketing Growth Models: How to Choose an Agency

    Modern Marketing Growth Models: How to Choose an Agency

    You can hire an agency that improves a channel and still end up with a weaker growth system. Paid media may generate cheaper leads that sales cannot convert. Organic visibility may rise while qualified website visits fall. Marketing may create demand that service and operations are not prepared to support.

    The answer is not a longer list of tactics. You need a growth operating model that connects customer states, discovery surfaces, commercial outcomes and decision rights. Once that model is clear, you can judge whether an agency will strengthen it or merely manage part of it.

    Replace the single funnel with a growth operating system

    Inbound marketing gave teams a coherent sequence: attract an audience, convert visitors and nurture leads. That logic remains useful, but it cannot carry the entire growth plan when discovery, evaluation, conversion and retention happen across different systems.

    HubSpot’s shift from INBOUND to UNBOUND reflects growth spanning marketing, sales, service and operations across the customer journey. The important lesson is not the conference name. It is that growth no longer belongs to one function or one acquisition framework.

    The old relationship between visibility and traffic is changing as well. An AI-generated answer can satisfy part of a search without sending the user to a website. A prospect can encounter a brand in an AI answer, validate it through search, read customer commentary, click a paid ad later and enter the CRM as direct traffic. A channel report may credit the final interaction while missing most of the journey.

    A modern growth model should therefore answer four connected questions:

    Model layerQuestion to answerEvidence you need
    Commercial outcomeWhat business result are we trying to change?A primary outcome, its definition and financial or operational guardrails
    Customer stateWhat must become true for the customer to move forward?Questions, objections, intent signals and points of friction
    Discovery and delivery surfacesWhere can we create, capture, convert or retain demand?A defined role for search, AI answers, content, paid media, sales and service
    Learning loopHow will evidence change the next decision?An owner, review cadence, decision threshold and change record

    If one of these layers is missing, the agency will fill the gap with its own assumptions. A media agency may treat platform revenue as the outcome. An SEO agency may treat rankings as the outcome. A content agency may treat publishing volume as the outcome. Those measures can be useful, but none is a substitute for the business result you hired the partner to influence.

    Build the growth brief before you write the agency brief

    A team arranges interconnected planning tiles and decision markers during a growth strategy workshop.

    An agency request for proposal usually starts with services: SEO, paid search, content, analytics or AI optimization. Start one level higher. Describe the growth constraint first, then determine which capabilities are needed to remove it.

    1. Name one primary outcome. State the business result, not the marketing activity. Pair it with guardrails that prevent a local win from damaging lead quality, margin, retention, brand standards or another important constraint.
    2. Map the customer states. Identify what customers need when they are recognizing a problem, evaluating options, making a purchase, adopting the product and deciding whether to continue. Use the states that fit your business instead of forcing every journey into a generic funnel.
    3. Locate the actual constraint. Determine whether the problem is insufficient demand, poor discovery, weak consideration, conversion friction, slow sales follow-up, onboarding failure or low retention. Do not commission more acquisition work when the binding constraint sits after acquisition.
    4. Assign a job to every surface. Decide whether each channel is meant to create demand, capture existing demand, answer a question, support evaluation, convert intent or retain a customer. A surface can support several jobs, but it should have one primary role in the plan.
    5. Define the learning loop. Record what will be observed, who interprets it, which decision it informs and who can approve the change. Reporting without a decision path produces dashboards, not growth.

    This is especially important for SEO, answer engine optimization and generative engine optimization. They overlap, but they are not interchangeable line items. SEO can improve discoverability in conventional search. AEO can make an answer easier to extract and present. GEO can focus the work on how generative systems understand, retrieve and represent a brand. Your measurement plan should preserve those distinctions while connecting them to the same customer journey.

    Do not force every visibility signal into an immediate revenue calculation. A metric can guide optimization without proving causal impact. Rankings, answer inclusion, brand mentions and qualified visits can show whether discovery is changing. CRM progression, revenue and retention can show whether commercial performance is changing. The agency should explain the relationship between those layers without pretending that one attribution model observes the entire journey.

    Your completed growth brief can be one page. It should contain the primary outcome, guardrails, constrained customer state, surface roles, measurement definitions and unresolved questions. That page gives every prospective agency the same problem to solve and makes proposals easier to compare.

    Divide ownership before you evaluate capabilities

    A growth partner needs room to make decisions, but outsourcing execution does not transfer accountability for the business. Clarify what the brand owns, what the agency owns and what must be shared before discussing deliverables.

    • The brand should retain business truth. This includes commercial priorities, customer definitions, approved claims, margin constraints, risk tolerance and the final authority over budgets and data access.
    • The agency should own recommendations and agreed execution. It should identify opportunities, explain trade-offs, perform work within the approved boundaries and maintain a record of material changes.
    • Measurement should be shared. The agency may build reports, but metric definitions, attribution limitations and tracking changes must be visible to both sides. Neither party should be able to change the meaning of success silently.
    • Cross-functional decisions need one accountable lead. Someone must reconcile conflicts among marketing, sales, service and operations. A committee can contribute, but it cannot substitute for a named decision-maker.

    This ownership map also exposes misleading claims of being full service. A long service menu tells you what an agency is willing to sell, not where it repeatedly performs strong work. Ask what percentage of clients actually use each advertised service. Then ask who leads that work, what other capability it depends on and where the agency normally brings in outside expertise.

    Build a simple capability map for every service that matters to your brief. Record the service, client utilization, named practice lead, proposed account owner, proof artifact, dependencies and known limitations. A strong specialist can be a better fit than a nominally full-service agency if your team is prepared to integrate the work. A broad partner can be the better choice when coordination is the main constraint. The right answer depends on the operating model, not the size of the service catalog.

    Audit the agency’s decisions, not its pitch language

    Client and agency leaders evaluate branching decisions and trade-offs while an abstract presentation remains in the background.

    Most agencies can produce a polished audit and a plausible list of opportunities. Your evaluation should reveal how the team prioritizes, measures, automates and changes course after the pitch is over.

    Ask six questions that require operational answers

    1. Which services are genuinely central to your business, and what percentage of clients use each one? Look for a precise denominator, a distinction between core and occasional work, and a candid explanation of where the agency is not the best fit. A service list with no utilization data does not establish depth.
    2. How do you combine platform automation, AI optimization and human judgment? Ask which decisions are delegated to platforms, which inputs the team controls, which guardrails prevent undesirable optimization and what triggers human intervention. “AI-powered” is a label, not an operating procedure.
    3. How does reporting lead to a decision? Have the team walk through an anonymized reporting environment. Ask them to start with the business outcome, trace the supporting indicators, identify an uncertainty and show the action that followed. Revenue and return on ad spend may belong in the view, but the team should also explain attribution assumptions and data limitations.
    4. Who will work on the account, and what is the team’s relevant industry tenure? Get names, roles, responsibilities and escalation paths. Distinguish the senior experts who appear in the pitch from the people who will perform and review the work.
    5. How does your team use generative AI on client work? Separate internal uses, such as analysis or drafting, from advertising-platform automation. Ask which client data can enter a tool, what receives human review, how outputs are checked and how material decisions are documented.
    6. What would you inspect first to reduce waste without suppressing growth? A strong answer should describe a sequence: validate measurement, preserve a baseline, inspect settings and allocation, identify suspected waste, estimate the downside of a change and verify the effect after implementation. A promise to cut spend immediately is not evidence of efficiency.

    Score each answer from zero to two. Give zero for a vague claim, one for a credible process without supporting proof, and two for a specific process backed by an artifact and a named owner. This produces a maximum score of 12, but the total is less important than the pattern. A partner that scores well on capabilities but poorly on measurement or ownership can create activity faster than it creates learning.

    Set knockout conditions before the presentations begin. Examples include refusing to identify the delivery team, being unable to explain data handling, treating platform-reported attribution as unquestionable, or requesting unrestricted budget authority before measurement is validated. Predefined conditions prevent presentation quality from overriding operational risk.

    Turn the winning answers into the working agreement

    Anything important enough to influence agency selection belongs in the operating agreement. Otherwise, the senior strategist, reporting method or review practice that won the pitch may disappear during delivery.

    • Decision rights: Record who can change budgets, targeting, conversion events, content claims, schema, site templates and measurement configurations.
    • AI boundaries: Define approved uses, prohibited data, review requirements and the person accountable for an AI-assisted output.
    • Change control: Preserve the baseline, document material changes and record the expected effect before implementation.
    • Reporting logic: Require each review to show what changed, how confident the team is, what may have caused it, what decision follows and who owns that action.
    • Escalation: Specify what happens when tracking fails, automation pursues the wrong signal, spend moves outside an agreed boundary or results conflict across systems.
    • Capability continuity: Define how staffing changes are communicated and how critical account knowledge is transferred.

    Give a new partner read access before authorizing material changes whenever the platform permits it. Validate conversion definitions, tracking and historical baselines first. Changing optimization events and budgets at the same time can make the result difficult to interpret, and automation can scale the wrong objective quickly. The safer sequence is to establish measurement, document the hypothesis, make a bounded change and inspect the result before expanding it.

    The same discipline should continue after onboarding. Do not evaluate the relationship by deliverable volume alone. Evaluate whether the agency is improving decision quality: finding the real constraint, making uncertainty visible, reducing waste, connecting work across the journey and leaving your team with a clearer understanding of what to do next.

    Key takeaways

    • A modern growth model connects commercial outcomes, customer states, discovery surfaces and a defined learning loop.
    • Write the growth problem before selecting services. Otherwise, every agency will frame the problem around what it sells.
    • Keep business truth and final accountability with the brand while giving the agency explicit execution and recommendation rights.
    • Test full-service claims with client utilization, named specialists, dependencies and proof of repeatable delivery.
    • Evaluate platform automation and internal generative AI separately; both require clear inputs, guardrails, review and escalation.
    • Convert important pitch promises into decision rights, reporting rules, staffing commitments and change-control procedures.

    Before your next agency conversation, complete the four-layer growth model for one important constraint and send the six audit questions in advance. Ask every contender to answer with artifacts, named owners and explicit limitations. The partner that can work inside that level of clarity is far more useful than one that merely offers the longest list of channels.

    References

  • AI-Driven Paid Acquisition: A Lead Generation Playbook

    AI-Driven Paid Acquisition: A Lead Generation Playbook

    If AI-led campaigns keep producing form fills that sales rejects, the system may be succeeding at the wrong task. A thank-you page tells an ad platform that an action occurred. It does not tell the platform whether the lead was qualified, reachable, commercially relevant, or likely to become revenue.

    Your first job is to connect those business outcomes to acquisition. Your second is to make the offer equally clear on the landing page, in the feed, across map profiles, and inside every creative asset. Do those two things before increasing spend, and automation has a much better signal to optimize.

    Key takeaways: what to fix before spending more

    Hands pause a flow of coins while adjusting a lead-generation system that separates rejected tokens from suitable ones.
    • Optimize toward business quality, not raw form volume. Define an accepted lead, return downstream statuses from the CRM, and keep diagnostic actions separate from primary conversion goals.
    • Make the offer unambiguous. A visitor and an automated system should both be able to identify what you sell, who it is for, why it matters, what action to take, and what happens next.
    • Measure each funnel stage on its own terms. Awareness, consideration, lead capture, qualification, opportunity creation, and revenue do not share one useful success metric.
    • Treat feeds, map listings, structured data, pages, and creative as one information system. Conflicting names, categories, locations, or conversion labels weaken both targeting and attribution.
    • Audit placements as well as campaigns. Automated campaigns can reach visual discovery surfaces that behave differently from conventional text search, so a blended click-through rate can hide what changed.

    Teach the buying system what a qualified lead means

    A sales team sorts prospect tokens and sends approval and rejection signals back to an automated acquisition engine.

    Begin in the CRM or lead management system, not in the bidding interface. Write down the point at which an inquiry becomes worth pursuing. That definition might depend on service fit, geography, budget, need, or another criterion your sales team already uses. The exact criteria are yours; the important part is that marketing, sales, the CRM, and the ad platform use the same definition.

    Then trace the feedback loop:

    <!– wp:list {
  • Unveiling the Power of AI: Boosting Citation Impact

    Unveiling the Power of AI: Boosting Citation Impact

    I am thrilled to share the news of an exciting new partnership that is set to revolutionize the way we connect AI visibility data to tangible citation outcomes and impacts.

    This collaboration promises to enhance the visibility of AI-generated insights and effectively translate them into actionable citations, thereby amplifying their real-world influence.

    In a world where AI continues to drive change and innovation, ensuring that these contributions are recognized and used is crucial, and this partnership is a significant step in that direction.


    Inspired by this post on Conductor Blog.


    crushpress.ai community screenshot
  • Unveiling AI Chatbot Conversion Secrets: ChatGPT Dominates

    Unveiling AI Chatbot Conversion Secrets: ChatGPT Dominates

    In this report, I’m going to walk you through a comparison of conversion rates among the four leading AI chatbots: ChatGPT, Gemini, Claude, and Perplexity.

    From May 2025 through April 2026, my research team conducted an in-depth study on AI conversion rates across various industries. We used anonymized data from more than 150 client companies, honing in on the most popular generative AI chatbots. Building on our previous analysis of ChatGPT conversion rates, we noted that most companies in our dataset had invested in generative engine optimization. The fascinating results of our study are presented below.

    AI Conversion Rates by Industry

    IndustryChatGPTGeminiClaudePerplexity
    Addiction Treatment2.9%2.6%2.6%2.0%
    Apparel & Fashion2.8%1.4%3.4%2.0%
    B2B SaaS2.4%2.2%1.9%1.9%
    Biotech2.1%1.3%1.7%1.3%
    Commercial Insurance3.1%2.8%2.8%1.9%

    Key Findings

    While all chatbot traffic converts at higher rates than traditional SEO, my study shows that ChatGPT and Perplexity typically have higher conversion rates compared to Gemini and Claude. This might be due to the greater user trust vested in ChatGPT and Perplexity’s recommendations.

    Claude stands out in knowledge-driven and regulated industries. Its performance in Healthcare, Higher Education, and Industrial IoT indicates that professionals in these fields favor Claude for more detailed, analytical queries.

    Industries such as Engineering, Software Development, and Transportation & Logistics exhibit relatively low conversion rates overall. This might suggest less dependence on AI tools or more specialized workflows not captured within this dataset.

    B2B SaaS and Financial Services demonstrate moderate but closely clustered conversion rates across all models, likely reflecting significant but cautious AI adoption given potential compliance concerns and familiarity with AI limitations.

    If you want a PDF copy of this report or wish to know more about our GEO services, reach out here.

    Source


    Inspired by this post on First Page Sage Blog.


    crushpress.ai community screenshot
  • How AI Search Engines Prefer Reddit, YouTube, and LinkedIn

    How AI Search Engines Prefer Reddit, YouTube, and LinkedIn

    AI citations

    During a recent study, I discovered that Reddit stands out as the most-cited domain in AI-generated answers. In fact, it’s ahead of heavyweights like YouTube and LinkedIn, thanks to an analysis of 30 million sources conducted by Peec AI, a tool specializing in AI search analytics.

    The findings: I’ve learned that Reddit claims the top spot across various AI platforms including ChatGPT, Google AI Mode, Gemini, Perplexity, and AI Overviews. Top contenders YouTube, LinkedIn, Wikipedia, and Forbes are right behind. Platforms like Yelp and G2 frequently appear when searching for recommendations.

    As I delved deeper into the research, it became clear which domains the AI models tend to lean on:

    • ChatGPT values Wikipedia, Reddit, and editorial sites like Forbes.
    • Google shows preference for platforms such as Facebook and Yelp.
    • Perplexity favors Reddit, LinkedIn, and G2 for queries within the B2B realm.

    Why we care: The insight that resonated with me was the importance of having authority beyond just our own websites. Brands that consistently feature on reputable third-party platforms have a better chance of being cited by AI.

    Why these sources? It’s fascinating to see how AI systems are wired to prioritize both authority and authentic user input:

    • I’ve found that Reddit excels because it mirrors genuine user discussions.
    • YouTube shines in video citations, owing to their comprehensive transcripts and descriptions.
    • Wikipedia not only serves real-time data but also acts as a foundation for training datasets.

    About the data: The analysis spanned 30 million sources, providing a comprehensive look at how often domains are directly cited in AI answers, effectively revealing what shapes these responses.

    The study. For those interested in a deep dive, the full study is available here: Top domains cited by AI search: Analysis based on 30M sources

    Dig deeper. For more on citation research, check out these fascinating reads:


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Create a Custom GPT Your Team Will Actually Use

    Create a Custom GPT Your Team Will Actually Use

    Have you ever wondered why most GPTs in businesses fail to be truly effective? It’s often because they are either too broad or haven’t been properly tested. Allow me to guide you through building focused, high-ROI GPTs that your team will not only adopt but use consistently every week.

    The OpenAI GPT Store made waves in January 2024 with its launch, hosting over three million custom GPTs. But, if you ask teams how many they actively use, the answer tends to be disappointingly low, often zero or just one.

    ```json
{
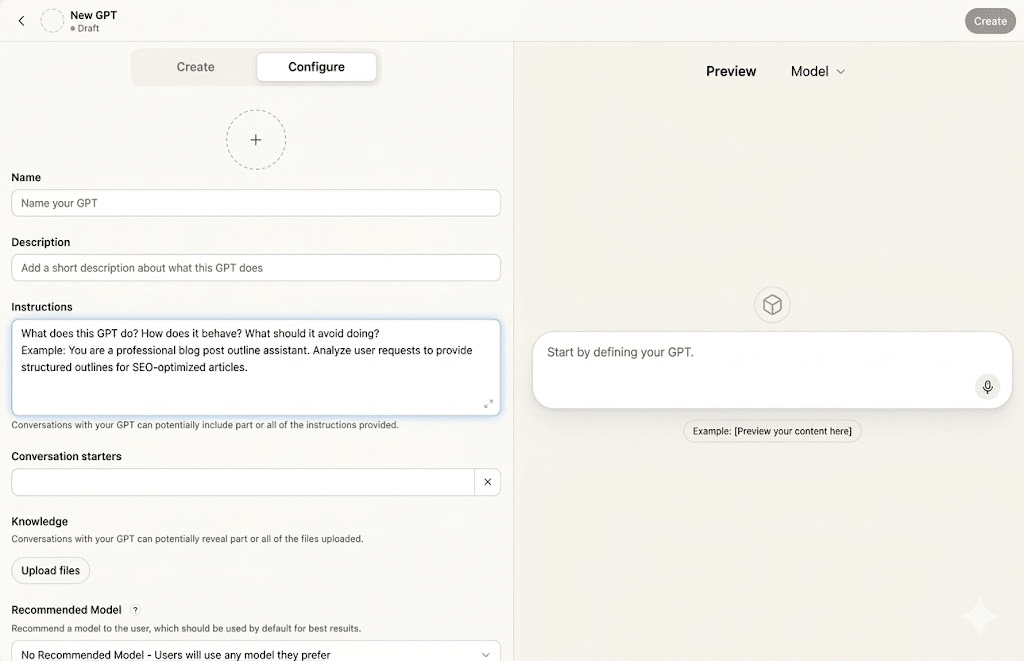
  "alt": "Screenshot of interface for configuring a new GPT model, detailing fields like name, description, and instructions.",
  "caption": "Set up your own customized GPT with this intuitive configuration interface, guiding you through naming, describing, and instructing your AI model.",
  "description": "This image depicts a screenshot of a platform for configuring a new GPT model. The interface includes fields for entering the model's name, description, and detailed instructions on behavior. Users can upload files, preview content, and choose conversation starters. The design is user-friendly, featuring a clean layout that guides through the customization process effectively. Keywords: GPT, model configuration, AI setup, user interface."
}
```

    I’ve personally built and audited over a dozen custom GPTs for marketing, SEO, and sales teams. The pattern is consistent: only a select few are used daily, while the rest simply collect dust. Let me share with you a practical approach to crafting GPTs that your team will genuinely engage with—from identifying suitable use cases to structuring, testing, and launching them effectively.

    ```json
{
  "alt": "Screenshot showing the Explore GPTs section with Research & Analysis and Programming categories.",
  "caption": "Discover the top-ranking GPTs in Research & Analysis and Programming to enhance your productivity and skills.",
  "description": "This image captures the Explore GPTs section from an AI platform, showcasing categories like Research & Analysis and Programming. Top GPTs in Research & Analysis include Finance & Economics and Marketing Research. Programming GPTs feature tools for software architecture and coding. This interface is designed for users seeking automated insights and coding assistance. Keywords: Explore GPTs, AI platform, Research & Analysis, Programming."
}
```

    If you’re eager to dive in, start with these foundational steps: Choose a task your team performs at least three times a week, typically taking over 15 minutes. Articulate this in a simple sentence: ‘This GPT helps [role] do [task] by [method].’

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    For a deeper understanding, I recommend checking out Marketing Research & Competitive Analysis or MARKETING, both highly ranked in the GPT Store’s Research & Analysis category. These projects showcase the build patterns I’ll cover here.

    ```json
{
  "alt": "Screenshot of a GPT search results page for marketing with various community-built GPTs.",
  "caption": "Explore specialized GPTs for marketing, offering expertise in advertising, SEO, copywriting, and competitive analysis.",
  "description": "This image displays a search results page for 'marketing' within a GPT interface. It features several community-built GPTs specializing in areas such as advertising, SEO, branding, and marketing analysis. Each entry includes a brief description, creator information, and engagement metrics, showcasing the diverse custom models available for enhancing marketing strategies. Ideal for marketers seeking AI-driven solutions."
}
```

    Now, let’s discuss what a business GPT truly entails. Unlike a generic AI assistant, a business GPT is a custom version of ChatGPT designed to handle one specific, recurring task for a particular role. Think of it like hiring a highly specialized worker for a job, rather than a generalist who does a little bit of everything.

    ```json
{
  "alt": "Screenshot of a new GPT setup interface with fields for name, description, and instructions.",
  "caption": "Create your custom GPT with ease using this setup interface. Fill in the name, description, and provide specific instructions to tailor its behavior.",
  "description": "This image displays a setup interface for creating a new GPT model. Users can input a name, description, and instructions to define its behavior and functions. The configuration guide on the right provides step-by-step assistance, such as uploading an icon and describing its function. The interface aims to simplify the customization process while enhancing the model's usability."
}
```

    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot