Category: AI

  • Google DeepMind Nano Banana Pro: A Marketer’s Workflow

    Google DeepMind Nano Banana Pro: A Marketer’s Workflow

    If your team can already make one attractive AI image, the harder problem is repeatability. Can the same product, character, visual hierarchy, and approved copy survive the next ten versions without a cleanup cycle wiping out the time you saved?

    Google DeepMind’s Nano Banana Pro is relevant because it brings stronger reasoning, multi-reference consistency, text rendering, and targeted editing into one image workflow. Its value, however, depends less on the first impressive render than on how you brief, review, publish, and test the resulting assets.

    Decide whether the job matches Nano Banana Pro

    Nano Banana Pro builds on the original Nano Banana and combines image generation and editing with Gemini 3 Pro’s reasoning capabilities. That combination is designed for more controlled production work, not merely open-ended image prompting.

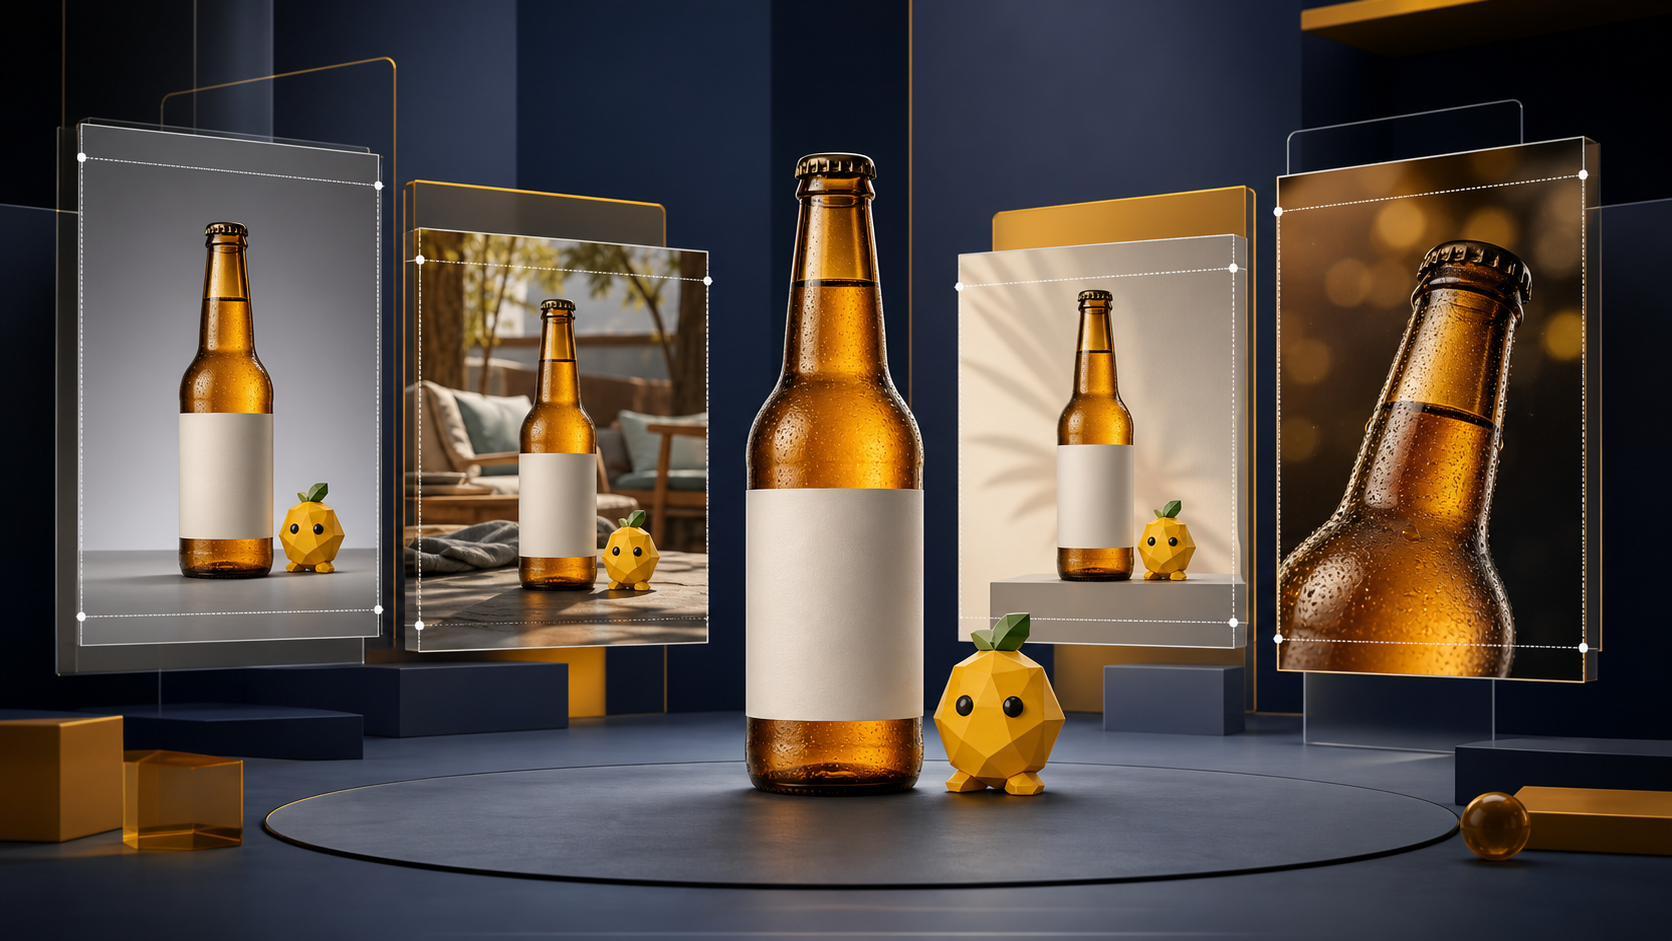
    Those capabilities make Nano Banana Pro a strong candidate when your bottleneck is controlled variation: adapting one approved concept into new layouts, markets, scenes, or campaign treatments. It is less convincing as an unsupervised authority for exact logos, prices, measurements, product claims, or factual diagrams. Those elements still need deterministic files, approved copy, and human sign-off.

    Access should also be treated as product-dependent. The rollout was described as progressive across Google’s platforms, while image-generation enhancements were made available in Google Ads. Confirm that the surface your team intends to use actually provides the required controls before you redesign a production process around it.

    Build a controlled brief, not a clever prompt
    An overhead workspace shows an unbranded product, character model, color swatches, material samples, and blank composition cards arranged as a controlled visual brief.

    A clever sentence may produce an interesting image. It rarely produces a dependable asset system. For repeatable work, separate the business objective, reference material, fixed constraints, creative variables, and approval criteria.

    1. Define the asset’s job. State where the image will appear, who it is for, what it must communicate, and what action it supports. A product-page hero, paid-ad variant, visual explainer, and storyboard frame need different compositions even when they share a subject.
    2. Curate the reference set. Nano Banana Pro can work across up to 14 inputs, but that is a ceiling rather than a target. Include only references with a clear role, then label each role: product geometry, character appearance, palette, environment, lighting, typography direction, or composition.
    3. List the non-negotiables. Specify what must remain unchanged, such as product proportions, wardrobe, brand colors, approved terminology, packaging structure, or the number and position of objects. Do not hide these requirements inside a long mood description.
    4. Separate creative variables. Name the elements that may change: background, camera angle, lighting, crop, season, supporting props, or emotional tone. This gives the model room to work without making every part of the asset unstable.
    5. Supply approved on-image copy. Put every required word in a dedicated field, including capitalization, punctuation, language, and desired line breaks. Multilingual rendering is useful only after a qualified reviewer has approved the translation itself.
    6. Describe the composition explicitly. Identify the focal subject, foreground and background relationship, viewing angle, negative space, intended crop, lighting direction, color treatment, and required aspect ratio. Terms such as premium or cinematic are too broad unless you explain what they mean visually.
    7. Approve one master before making variants. Resolve product shape, character continuity, hierarchy, copy, and overall art direction in a master image. Only then use localized edits and detailed visual controls to create derivatives.
    8. Record what produced the approved result. Save the references, prompt, approved copy, output, requested edits, intended channel, and reviewer decisions together. Without that record, the next campaign starts as another guessing exercise.

    A reusable Nano Banana Pro brief

    You can turn the workflow into a short production template. Replace each instruction with project-specific language:

    • Objective: Create an image for a named page, campaign, or presentation and state the decision or action it should support.
    • Reference roles: Input 1 controls product shape; input 2 controls palette; input 3 controls character appearance; input 4 controls composition.
    • Must preserve: List the objects, proportions, colors, expressions, terminology, and layout relationships that cannot change.
    • Scene and treatment: Define environment, camera position, focal length in plain visual terms, lighting direction, depth, color balance, and mood.
    • Exact copy: Provide the approved words, language, capitalization, punctuation, and hierarchy. Instruct the system not to add other text.
    • Output: State the required aspect ratio, placement of negative space, and any crop-safe area your channel needs.
    • Edit rule: Preserve every approved element and change only the named variable in each revision.

    The edit rule is especially important. Instead of asking for a better version, request a defined delta: keep the subject, pose, product, copy, palette, and framing unchanged; adjust only the background lighting. A narrow instruction gives you a result that is easier to compare and approve.

    Review the image like a production asset
    A reviewer compares an unbranded running shoe on a monitor with a physical sample while inspecting enlarged details, shadows, and materials.

    Rendering quality and correctness are different tests. Text may look polished while containing a substituted character. A product may remain recognizable while its controls, label, or proportions drift. Search-connected context may help the model build a scene, but it does not transfer responsibility for the scene’s claims to Google.

    • Check text character by character. Compare every word, numeral, unit, punctuation mark, and line break with the approved copy. Review the exported size as well as the large preview; small labels can fail only after resizing.
    • Review each language independently. Legibility does not prove that a translation is accurate, culturally appropriate, or compliant with your terminology. Give a fluent reviewer the copy and the rendered image, not the image alone.
    • Compare products and brand elements with their references. Inspect silhouettes, component count, labels, materials, colors, logo geometry, and relative scale. If exactness is mandatory, replace generated brand marks or copy with approved production assets.
    • Verify factual content against approved data. Recheck names, quantities, relationships, ingredients, annotations, and visualized facts. For an infographic, keep the underlying data and its provenance with the review record.
    • Inspect continuity across the set. Look beyond facial resemblance. Check clothing details, accessories, object placement, shadows, materials, and environmental logic from one image to the next.
    • Test the real crop. Preview every destination rather than assuming one output will adapt cleanly. Confirm that the focal subject, required copy, and important context remain visible wherever the image will appear.
    • Provide a text equivalent. If an image contains information needed to understand the page, repeat that information in HTML. Alt text should describe the image’s purpose in context, not become a list of target keywords.

    Assign ownership before review begins. A creative owner can approve composition and consistency, a subject or language owner can approve claims and copy, and a channel owner can approve crop, accessibility, and placement. A general request for everyone to check everything usually leaves the riskiest detail without a named decision-maker.

    If repeated local corrections begin changing previously approved areas, return to the master and regenerate the derivative from there. A chain of patched exports is harder to reproduce, audit, and update than one approved base with documented variations.

    Make each output useful to search systems and ad testing

    For SEO, AEO, and GEO content

    A generated image can explain an idea, establish context, or make a page easier to scan. It cannot replace the page’s evidence. If the answer exists only inside pixels, you make it harder for people using assistive technology and for systems that depend on accessible page text to interpret and cite the underlying information.

    • Place the image beside the passage it supports rather than treating it as detached decoration.
    • Repeat essential labels, claims, instructions, and data in visible HTML. For a detailed infographic, provide a compact text explanation or accessible transcript.
    • Write alt text around the image’s function on that page. Describe what a reader needs to understand; do not paste a keyword list or duplicate a long caption.
    • Add a caption when the visual needs a title, data context, methodology note, or explanation that would be awkward in alt text.
    • Use consistent names for products, entities, and concepts in the image, heading, body copy, and metadata. Visual creativity should not introduce new terminology for the same thing.
    • Where the page’s existing schema type supports an image property, connect it to the final image URL and keep the structured description aligned with the visible page. JSON-LD expresses a relationship; it does not verify that a generated claim is true.

    This distinction matters for Search-connected generation. Real-world context can accelerate visual creation, but it is not a citation or a provenance record. Keep the factual basis of the image visible, inspectable, and consistent with the surrounding content.

    For Google Ads and campaign experiments

    Nano Banana Pro’s availability through Google Ads can reduce the handoff between asset creation and campaign setup. That convenience does not demonstrate that an image will improve performance. Treat every generated variation as a creative hypothesis.

    • Start with one approved master so visual differences are intentional rather than accidental.
    • Change one meaningful variable per test, such as background context, camera angle, product emphasis, or lighting treatment.
    • Keep the offer, audience, landing experience, and other campaign conditions stable when you need to learn whether the visual caused the difference.
    • Choose the decision metric before launching. A higher click-through rate may be useful, but it should not justify broader spend if the campaign’s actual conversion or cost objective deteriorates.
    • Name and archive variants by the changed variable. Labels such as blue-background or close-product-crop are more useful than final-7.
    • Do not increase spend merely because a generated asset looks more polished. Use your normal budget controls until performance against the campaign objective supports the change.

    The production advantage is the ability to explore more controlled variations without rebuilding every asset manually. The measurement advantage appears only when those variations remain controlled enough to teach you something.

    Key takeaways

    • Nano Banana Pro is most useful for constrained visual production: consistent references, exact copy requirements, localized edits, and planned variants.
    • Although it can work across as many as 14 inputs, use only the references that have a defined role in the output.
    • Approve one master before creating derivatives, and request one explicit change at a time.
    • Readable multilingual text, Search-connected context, and polished rendering still require language, factual, product, and brand review.
    • For search content, keep essential information in HTML and align the image with visible copy, alt text, captions, and applicable structured data.
    • For advertising, evaluate generated variants through controlled tests rather than assuming faster production or better-looking creative will improve results.

    Start with one existing asset that already creates expensive variation work. Define what must stay fixed, choose one variable, produce and approve a master, then run a small controlled test. If Nano Banana Pro preserves the constraints and makes the next version easier to reproduce, it belongs in the production workflow. If it cannot, keep it upstream as a concept and storyboard tool.
    References

  • AI-Driven Marketing Engineering: Build a System That Learns

    AI-Driven Marketing Engineering: Build a System That Learns

    Your team can probably make more content with AI. That doesn’t mean your marketing operation has become more intelligent. If briefs, data, approvals, assets, distribution, and measurement still live in separate workflows, AI simply helps the fragments move faster.

    AI-driven marketing engineering solves a different problem: how to turn customer signals into controlled decisions, useful experiences, and measurable learning. The goal is a marketing system that can adapt without surrendering brand judgment, factual accuracy, or human accountability.

    The real shift is from campaigns to closed-loop systems

    A conventional campaign follows a line: write the brief, produce the assets, launch them, measure the result, and start again. That structure works when the environment remains stable long enough for the entire cycle to finish. It becomes restrictive when customer behavior changes while the campaign is still running.

    Marketing engineering replaces that line with a loop. Signals enter the system, a rule or model interprets them, an approved response is activated, the outcome is observed, and the next decision incorporates what was learned. This is the practical meaning of moving from finite campaigns to continuously adapting marketing systems.

    A workable system has five connected layers:

    1. Signal layer: Collect the events that matter to the decision, such as a search, click, content interaction, form submission, purchase, or support question. Record where each signal came from, what it means, and whether it is fresh enough to use.
    2. Decision layer: Translate a signal into an eligible action. The mechanism might be a fixed rule, a scoring model, an AI classifier, or a person reviewing a recommendation. Give every decision a defined input, output, owner, and fallback.
    3. Asset layer: Maintain approved content components, offers, claims, evidence, calls to action, and brand constraints. AI should select from or work within this governed inventory instead of improvising from an empty prompt.
    4. Activation layer: Deliver the selected response through a page, email, ad, chatbot, sales workflow, or another customer-facing surface. Preserve the decision and asset version that produced each experience.
    5. Learning layer: Observe whether the intended action occurred, check for unwanted effects, and route the result back to the owner of the decision. A dashboard without a path to a changed rule, asset, or experience is reporting, not learning.

    Draw these layers for one current workflow. For every handoff, write down the input, output, system of record, responsible owner, and failure behavior. Missing ownership and undefined fallbacks will usually cause more trouble than the model itself.

    Do not wait for a perfect panoramic customer profile before you begin. Build the smallest decision-specific view that can support the use case. A system choosing an answer for a product page may need the visitor’s expressed question and the page context; it does not automatically need every historical interaction your company has stored.

    Design the smallest useful feedback loop first

    Two people oversee a compact circular feedback system in which a glowing customer signal passes through four connected modules and returns to its starting point.

    The safest first use case has a narrow input, a bounded decision, an approved set of outputs, and an observable result. That boundary makes the workflow easier to inspect and gives you somewhere to intervene when the AI is wrong.

    Suppose a B2B product page attracts several kinds of questions. Your first loop could classify the question being expressed, select one approved answer module, expose the relevant next action, and record whether the visitor continues to the supporting material or conversion step. It should not rewrite the entire page, invent product claims, choose an offer, and alter audience targeting in the same run. Too many simultaneous decisions make both the risk and the result difficult to interpret.

    Use this sequence to define a closed loop:

    1. Name the business decision. Write it as a choice the system must make, not as a vague goal. For example: choose the most relevant approved answer module for the question expressed on this page.
    2. Define the eligible audience and context. State where the decision may run and where it must not run. Include consent, geography, account status, page type, and other constraints that genuinely affect eligibility.
    3. Select the minimum necessary signals. Document the meaning and origin of each field. Do not feed every available attribute into the model merely because it exists.
    4. Constrain the possible outputs. Specify approved content, actions, claims, and formats. Provide a neutral default for cases the system cannot classify safely.
    5. Choose the activation point. Start with one surface so you can identify which experience produced the response. Expanding across channels before the first loop is observable creates an attribution problem.
    6. Define the outcome and countermetric. Pair the intended result with a signal that can reveal damage. A higher click rate, for example, should not be accepted blindly if corrections, complaints, unsubscribes, or low-quality conversions also rise.
    7. Assign review and rollback ownership. Name the person who can pause the workflow, restore the previous version, and decide whether a failure came from the data, decision logic, content, or activation.

    Make every AI workflow pass acceptance criteria

    An AI workflow is not ready merely because it produces a plausible output. Test it against operational acceptance criteria:

    • Traceable: You can identify the input data, decision rule or prompt, model configuration, asset version, and resulting action.
    • Bounded: The system can act only within its declared audience, channels, claims, and permissions.
    • Reversible: An owner can disable the automation and restore a known safe version without rebuilding the workflow.
    • Observable: Failures, fallbacks, constraint violations, and missing data are visible instead of silently discarded.
    • Reviewable: High-impact, unsupported, unusual, or low-confidence outputs can be routed to a person before publication or activation.
    • Comparable: The changed experience can be evaluated against a baseline, holdout, or controlled alternative appropriate to the use case.

    Change one major part of the loop at a time when you need to understand causality. If you replace the model, prompt, audience logic, offer, and landing page in one release, the resulting movement may be real, but it will not tell you which decision to keep.

    Turn content into governed, reusable components

    A creative team selects abstract content modules from an organized library and assembles them into multiple formats through visible approval and review gates.

    AI cannot reliably assemble a coherent customer experience when its raw material is a collection of unrelated documents. It needs content that is structured around meaning, permissions, and reuse.

    Instead of treating a finished page as the smallest manageable asset, define content objects that can travel across pages, answer experiences, email, advertising, sales material, and structured data. This applies the same principles of modularity, reuse, and version control that make software systems maintainable.

    A useful content object should carry more than copy. Give it fields for:

    • the customer question or task it addresses;
    • the approved answer, claim, or narrative;
    • the evidence or internal source supporting that claim;
    • the applicable product, audience, market, and journey state;
    • required qualifications and prohibited interpretations;
    • the owner and approval status;
    • the last review point and conditions that require another review;
    • eligible formats and channels;
    • the intended next action;
    • the identifier used to connect the object to analytics and structured data.

    This model separates truth from presentation. A verified product fact can support a concise answer, a comparison module, an email paragraph, and a JSON-LD property without being copied into four disconnected files. When the fact changes, you can identify every dependent surface instead of hoping each channel owner notices.

    For SEO, AEO, and GEO work, generate structured representations from the same governed facts used in visible content. JSON-LD should describe what the page actually establishes; it should not become a parallel database containing stronger or different claims. Using one verified record for both human-readable and machine-readable output reduces contradiction and makes corrections easier to propagate.

    Model journeys as states, not a rigid funnel

    A funnel assigns people to broad stages. A living journey architecture defines the state the customer appears to be in, the evidence supporting that state, the actions eligible from it, and the event that moves the customer elsewhere.

    For each journey state, document three things:

    • Entry evidence: the observable behavior or declared need that makes the state reasonable;
    • Eligible next experiences: approved content and actions that help the person progress without forcing an irrelevant conversion;
    • Exit conditions: the event that changes the state, ends the workflow, or suppresses further activation.

    This creates a safer form of personalization. The system responds to an expressed need and known context rather than constructing an unnecessarily intimate profile. It also prevents common contradictions, such as continuing an acquisition sequence after a purchase or sending an introductory explanation after someone has requested technical detail.

    Build an operating model that can govern continuous change

    A continuous system changes the work of the marketing team. The unit of delivery is no longer only a finished campaign. It is a versioned improvement to a signal, rule, asset, experience, or measurement path.

    Put proposed improvements into one backlog. Each work item should contain:

    • the customer or business problem visible in the signals;
    • the hypothesis about what should change;
    • the affected audience and journey state;
    • the signal, decision, asset, and activation components involved;
    • the primary outcome and countermetric;
    • the human owner of the result;
    • the previous safe version and rollback method;
    • the evidence required to expand, revise, or stop the change.

    Short delivery cycles are useful because customer preferences and performance signals can move before a long planning process finishes. But adopting the language of sprints is not enough. Agile marketing depends on testing, iteration, and ongoing optimization, so every cycle must end with a decision: keep the change, revise it, widen it, or roll it back.

    Ownership should cross functional boundaries without becoming vague. A marketing owner defines the customer and business decision. Content and brand owners govern allowable meaning. Data or engineering owners maintain signals, integrations, and reliability. The person accountable for the use case remains responsible for the final behavior even when AI makes an intermediate recommendation.

    Put controls around AI before increasing its autonomy

    Automation increases the reach and speed of whatever system you already have. If the content is contradictory, the signals are poorly defined, or no one owns the outcome, AI scales those defects along with the output.

    Before allowing a workflow to publish or activate without review, require:

    • an approved set of information the model may use;
    • explicit prohibited claims, actions, audiences, and channels;
    • version records for prompts, rules, models, and content components;
    • a deterministic fallback when the required data is absent or the result is unsuitable;
    • a log connecting the input, decision, output, and customer-facing action;
    • a pause control and a tested route back to the previous safe behavior;
    • a named owner who reviews exceptions and decides whether autonomy should expand.

    Increase autonomy by decision type, not by declaring an entire channel automated. A system may be ready to classify a question while still requiring approval to create a new product claim. It may safely select an existing module but not set a price or make an eligibility decision. Those boundaries should remain visible in the workflow design.

    Measure the loop at three levels

    A single performance score hides too much. Separate your measurement into three levels:

    • System health: missing or stale data, failed jobs, fallback frequency, broken activations, and untraceable outputs;
    • Decision quality: correct matches, human accept-edit-reject patterns, constraint violations, and cases routed to the wrong state;
    • Customer and business response: progress to the intended next action, qualified conversion, retention, revenue, or another outcome appropriate to the decision, paired with relevant countermetrics.

    These levels tell you where to intervene. Weak business performance with healthy infrastructure may point to the decision or offer. Strong response accompanied by frequent corrections may indicate that the workflow is creating hidden operational or brand costs. A model-level metric cannot answer either question on its own.

    Key takeaways

    • AI-driven marketing engineering connects signals, decisions, governed assets, activation, and feedback in a closed loop.
    • Start with one bounded decision whose inputs, outputs, result, fallback, and owner can be clearly observed.
    • Structure content as reusable, versioned objects with evidence, permissions, applicability, and review ownership.
    • Use the same verified facts for visible content and JSON-LD so human-facing and machine-readable claims stay aligned.
    • Expand AI autonomy by decision type only after the workflow is traceable, bounded, reversible, observable, and reviewable.
    • Measure system health, decision quality, and business response separately so you know what actually needs to change.

    Choose one live marketing decision this week and map its five layers. If you cannot point to the signal, rule, approved asset, activation record, outcome, and owner, fix that chain before adding another AI tool. Once the loop is visible and governed, automation can make the marketing system more responsive without making it less accountable.

    References

  • How Google AI Is Changing Marketing and the Open Web

    How Google AI Is Changing Marketing and the Open Web

    If your organic dashboard still treats rankings and clicks as the whole search funnel, it is measuring too little. Your business can appear inside a generated answer, be reduced to a generic summary, or disappear from the decision altogether without producing a clean, familiar ranking change.

    The practical response is not to abandon SEO or hand every campaign to automation. You need to separate four jobs that Google Search once bundled together: earning inclusion, preserving a reason to visit, testing paid reach, and keeping control of what you learn about your market.

    Key takeaways

    • Measure AI representation separately from rankings, citations, referral traffic, and conversions. They are related outcomes, not interchangeable ones.
    • Generic consensus content is easy for an answer engine to compress. Give it distinctive evidence, explicit scope, and claims that remain useful after summarization.
    • Treat Google AI Max as a test for incremental demand, not as a replacement for your proven keyword structure.
    • Require automated advertising to produce both commercial lift and reusable customer insight. A better platform result with less business understanding is an incomplete win.
    • Keep the canonical version of your work on an owned website, then use social, video, community, and paid media as distribution rather than substitutes for it.

    The organic bargain has split into separate outcomes

    The old search bargain was imperfect but legible: publish something valuable, make it discoverable, earn a position, and receive a chance to win a visit. An AI answer can use a page as an input while becoming the destination itself. Meanwhile, ads are already appearing within AI Overviews, placing monetization inside the same interface that can reduce the need to open an organic result.

    That does not make organic visibility worthless. It makes the word “visibility” too vague for serious reporting. Replace the single visibility metric with a ledger that distinguishes these outcomes:

    • Eligibility: Can the relevant page be crawled, indexed, understood, and associated with the right entity and topic?
    • Representation: Does the brand, product, expert, or argument appear when an AI result is generated for an important query?
    • Fidelity: Does the generated answer preserve the meaning, limitations, and differentiators of the underlying material?
    • Referral: Is there a visible citation or link, and does it send qualified visits?
    • Commercial effect: Do those visits, mentions, or assisted journeys lead to enquiries, subscriptions, purchases, or another defined outcome?

    Do not collapse those measurements into a proprietary “AI visibility score” before you can inspect the parts. A cited page with no visits may still influence awareness. A brand mention with no citation may be strategically relevant but difficult to attribute. A high citation count for the wrong claim can be actively harmful. The labels only become useful when they tell you what happened.

    Build a query set from real customer decisions rather than from search volume alone. Include questions about choosing, comparing, troubleshooting, pricing, risk, and suitability. For each query, record whether an AI feature appeared, which entities and claims it included, whether it cited your page, where the citation led, and what happened after the visit. Repeat the review after meaningful content, product, or campaign changes. This gives you a testable view of AI search without pretending that every mention has the same value.

    Create content that survives consensus compression

    Varied source materials pass through a transparent funnel, where generic items fade while distinctive evidence and tools remain visible.

    There is a credible risk that generated search results will favor established brands and consensus positions, making independent or divergent perspectives harder to discover. That outcome is not inevitable, but it is important enough to plan around. If every page repeats the same safe answer, an AI system has little reason to preserve the identity of any individual publisher.

    Recent search disruption also showed that being useful was not a guaranteed defense for every small publisher. Smaller affiliate sites lost substantial organic visibility during Helpful Content changes, including sites built around reviews and comparisons that their operators considered valuable. The lesson is not that independent publishing is futile. It is that a strategy based only on producing a slightly better version of an established format is fragile.

    Make each important page pass a distinctiveness test before you optimize its title or markup:

    • Publish inspectable evidence. Show the method, criteria, inputs, examples, calculations, or decision rules behind the conclusion. “We tested it” is not evidence if the reader cannot understand what was tested.
    • State the boundary of the answer. Identify who the recommendation is for, when it applies, what would change it, and where the common answer fails.
    • Preserve legitimate disagreement. If credible positions differ, explain the deciding conditions instead of flattening them into a false universal answer.
    • Separate facts from judgement. A clear editorial conclusion is useful, but readers and machines should be able to tell which claims support it.
    • Give the page a reason to be cited. Original data, a transparent framework, a primary document, a named method, or a genuinely useful decision tool is harder to replace than a generic overview.

    Structured data supports this work when it clarifies what the visible page already says. Use appropriate schema to identify entities, authorship, products, organizations, articles, or other relevant relationships, but keep the markup aligned with the content a visitor can see. Schema can reduce ambiguity; it cannot make an unsupported claim authoritative or force an AI system to cite the page.

    Run a final compression check before publishing. Ask what would remain if a search interface summarized the page in a few sentences. If the answer is only the same advice available everywhere else, the page needs stronger evidence or a sharper scope. If the summary would preserve a proprietary finding but remove every reason to visit, add something that requires interaction or inspection: the complete method, comparison criteria, examples, tool, dataset, or implementation detail.

    Test automated advertising for incrementality and insight

    Google positions AI Max for Search as a way to capture relevant demand beyond an advertiser’s existing keywords. Its matching can combine broad-match logic, keywordless discovery from landing pages, generated text, and Final URL expansion. Existing keywords still receive priority when they match the query. That makes AI Max an expansion layer, not a reason to discard a keyword structure that already performs.

    Your starting setup changes what a plausible gain looks like. Phrase- and exact-heavy campaigns leave more demand for broader and keywordless matching to find. Broad-match-heavy campaigns may have less room to expand. Advertisers already using Dynamic Search Ads may see less new keywordless reach, although asset-driven signals can still change performance. This is why a result from another account tells you very little about the lift available in yours.

    Judge the system by incremental campaign value at an acceptable blended CPA or ROAS. Do not demand that every newly discovered conversion match the efficiency of mature, curated keywords. Marginal demand may cost more. At the same time, do not accept “incremental” as an excuse for spending that misses your business economics.

    Use this testing sequence:

    1. Write the hypothesis in commercial terms. Specify which demand you believe the current campaign misses and which conversion action represents genuine value.
    2. Use a control-and-treatment experiment where the available controls fit the question. Keep unrelated campaign changes out of the test so that creative, landing-page, budget, or tracking edits do not obscure the result.
    3. Set guardrails before launch. Define acceptable campaign-level CPA or ROAS, brand-suitability requirements, valid landing pages, and conversion-quality checks.
    4. Exclude the learning period from the final comparison. A system that is still adapting should not be treated as settled performance.
    5. Inspect the search terms, creative assets, and landing pages selected by the system. Aggregate lift matters, but so does understanding where it came from.
    6. Compare the whole campaign, not isolated match types. The real question is whether the treatment produced additional conversion value within the agreed economics.

    Start with a contained experiment if you cannot yet verify query quality, generated assets, landing-page selection, or conversion value. Broad activation can spend real money on marginal demand before you know whether the traffic is suitable. The safer alternative is a limited test with explicit stop conditions and a person responsible for reviewing what the automation chooses.

    There is also a strategic cost to opacity. Highly automated systems can use your budget and conversion data to improve targeting while revealing less about the audience signals that drove the result. Performance Max illustrates the concern when control and reporting are limited. If your team cannot carry the learning into another channel, Google has improved its model while your own understanding may have barely moved.

    Protect that understanding before and during the test. Preserve your query themes, audience hypotheses, landing-page roles, creative propositions, conversion definitions, margin assumptions, and observed objections in records your team controls. A useful automation test should produce two outputs: incremental business value and a clearer picture of demand. If it produces only the first, record that trade-off honestly.

    Build a marketing system that still supports the open web

    A central marketing hub connects directly with a website, inbox, forum, storefront, analytics workspace, audiences, and independent publisher sites.

    When independent publishers lose search visibility, many shift their effort to TikTok, Instagram, or other platforms. Google is also bringing more social material into discovery through YouTube Shorts, short-video results, Reddit, and LinkedIn content. That can expose searchers to more individual voices, but it does not fully replace an accessible, linkable, independently published web.

    A social clip is good at earning attention. A durable web page is better at preserving context, documenting evidence, receiving links, supporting structured data, and remaining available outside a feed. Treat those formats as complementary parts of a publishing system:

    • Keep the canonical explanation on a website you control. Preserve the complete evidence, limitations, authorship, update history, and relevant structured data there.
    • Adapt the idea for social, video, community, and professional platforms. Match the native format, but point interested people toward the durable resource when deeper context matters.
    • Create a direct return path. Give people a legitimate reason to bookmark the resource, subscribe with consent, join a community, or otherwise return without repeating the same platform-mediated search.
    • Retain portable business knowledge. Keep your raw content, research materials, analytics definitions, audience findings, and creative learnings in systems your organization can access independently.
    • Diversify discovery deliberately. Organic search, AI answers, paid search, social distribution, partnerships, referrals, and direct audiences should have defined roles rather than serving as interchangeable traffic taps.

    This is also an industry problem, not only a site-level optimization problem. Publishers, advertisers, and marketers have shared reasons to demand workable standards for permission, attribution, compensation, transparency, and auditability. Collective standards could provide protection while formal AI regulation develops. Self-governance will not settle every copyright, competition, or data-use dispute, but isolated businesses have less leverage than an industry that can define unacceptable practices clearly.

    Start with your highest-value search journey. Map the question, the generated answer, the citation or ad, the landing experience, the conversion, and the knowledge your team retains afterward. Fix the point where Google can absorb the value without giving your audience a reason to recognize, visit, or return to you. That is the practical work of adapting to AI search without surrendering the open web that makes useful AI answers possible.

    References

  • AI-Generated Defamation: A Practical Response Playbook

    AI-Generated Defamation: A Practical Response Playbook

    An AI assistant has attached a false accusation to your name. You may not know whether it copied a web page, confused you with someone else, revived a resolved allegation, or invented the story. That uncertainty is why your first move matters.

    Treat the incident as an evidence problem first and a distribution problem second. You need to preserve what happened, identify the failure mode, pursue a precise correction, and strengthen the public information that search engines and generative systems use to understand who you are.

    Key takeaways

    • Capture the complete AI response before reporting it. The answer may change or disappear, taking useful evidence with it.
    • Determine whether the claim came from an existing page, an identity collision, an old allegation, or a fabricated narrative. Each failure requires a different remedy.
    • Work on the originating web content and the AI platform at the same time. Correcting only one layer can leave the false claim circulating through the other.
    • Publish clear, crawlable, internally consistent entity information. Structured data can reduce ambiguity, but it cannot prove that a statement is true or force an AI provider to remove an answer.
    • Escalate promptly when the claim concerns crime, fraud, abuse, professional misconduct, safety, or an actual employment or commercial decision. Liability for AI-generated statements remains legally unsettled, so high-stakes cases need advice from a qualified lawyer in the relevant jurisdiction.

    Capture and diagnose the false claim before acting

    An investigator preserves evidence from an AI response using a laptop, phone, camera, and organized case materials.

    An AI response is not as stable as a conventional web page. It may change in a new conversation, after a product update, when the surrounding prompt changes, or after you submit feedback. Preserve a reproducible example before asking anyone to remove it.

    1. Record the product and environment. Note the platform, the model or mode shown in the interface, whether you were signed in, and the date, time, and time zone.
    2. Save the complete conversation. Keep the exact prompt, preceding messages, full answer, citations, source links, warnings, and follow-up responses. A cropped screenshot of one sentence loses context the platform may need.
    3. Preserve more than a screenshot. Export or copy the text, save the conversation link if one exists, and retain the original image files. Do not annotate or overwrite the only copy.
    4. Run a narrow reproducibility check. Test the same neutral prompt in a fresh conversation and, where relevant, add an unambiguous identifier such as an employer or location. Stop once you understand the pattern. Repeating the accusation across many public tools can create more copies and expose sensitive information.
    5. Document external exposure. Record who encountered the answer, how they found it, and whether it affected a job, contract, customer relationship, background check, or safety decision. Preserve related emails and messages.
    6. Restrict distribution. Share the evidence only with people handling the incident, the platform, and professional advisers. Posting the response publicly may amplify the accusation and create a new searchable page that associates it with your name.

    Separate the factual problem from its legal label. In an initial support request, identify a specific false factual statement and show why it is wrong. Whether it satisfies the legal elements of defamation depends on jurisdiction, context, publication, fault, and harm. Let counsel make that assessment when the stakes justify it.

    Next, classify the failure. Do not assume every harmful answer came from a page that can be found and deleted. In 2023, ChatGPT falsely connected Jonathan Turley to nonexistent charges at a faculty he had never attended and cited a Washington Post story that did not exist. A fabricated citation needs a different response from a truthful summary of an inaccurate web page.

    Likely failure modeWhat to look forBest first move
    Repetition of an online claimThe answer cites a real page, copies distinctive wording, or consistently follows prominent search results.Seek correction or removal at the originating page while sending the AI provider the same evidence.
    Identity collisionThe answer combines your name with another person’s employer, location, age, case, credentials, or biography.Show the conflicting identifiers and ask the provider to separate the two people. Strengthen your own disambiguating entity information.
    Resolved or stale allegationThe underlying event is real, but the answer omits a dismissal, correction, judgment, retraction, or later outcome.Make the authoritative resolution easy to find, then request an answer that includes the complete and current record.
    Fabricated narrativeNo underlying event can be located, citations do not exist, or the cited material does not support the statement.Preserve the invented citation and unsupported details, then request removal or correction directly from the AI provider.
    Misleading synthesisIndividual facts may exist, but the answer joins them into an implication the underlying material does not support.Challenge the unsupported connection sentence by sentence and supply concise corrective evidence.

    A search that finds nothing is a clue, not proof that the model invented the claim. Search the exact wording, inspect every cited link, compare names and biographical details, and check whether the allegation appears without its resolution. Your incident file should distinguish what you verified from what you merely could not locate.

    Correct the AI output and its web origins in parallel

    If the answer relies on a real page, start at that origin. Ask the publisher or responsible party for a correction, update, retraction, or removal supported by evidence. If a search engine result itself violates an applicable policy or legal rule, use the relevant removal process as a separate step. Deindexing a result does not delete the underlying page, and a copyright notice is not a general-purpose remedy for defamation.

    At the same time, send the AI provider a targeted report. A vague request such as “remove everything negative about me” is hard to verify and may sweep in lawful opinion or accurate reporting. A useful report gives the reviewer a small, testable case.

    • Identify the subject: full name, relevant organization, location, and any other detail needed to prevent another identity collision.
    • Quote only the necessary statement: isolate the exact factual assertion that is false rather than forwarding pages of unrelated output.
    • Explain the error: state which words are wrong and whether the answer invented an event, confused two people, omitted a resolution, or misrepresented a cited page.
    • Provide the correct fact: give a concise replacement statement that the evidence supports.
    • Attach authoritative evidence: use primary records, court documents, formal corrections, official registries, or first-party records where appropriate. Do not upload confidential material through an insecure feedback form.
    • Specify the remedy: ask the provider to remove the false assertion, correct the biography, separate two entities, stop relying on an unsupported citation, or review the recurring response pattern.
    • Include reproduction details: provide the exact prompt, full response, model or mode, date, screenshots, conversation link, and cited URLs.
    • Keep the receipt: save the ticket number, confirmation email, submitted text, attachments, and every subsequent response.

    Product-specific escalation routes have included the following starting points. Interfaces and policies can change, so verify the live route inside the product or its help center before relying on it.

    • Meta Llama: use the Llama Developer Feedback Form or email LlamaUseReport@meta.com.
    • ChatGPT: use the report control attached to the problematic conversation or response.
    • Google AI Overviews and Gemini: use the product feedback control; use Google’s legal troubleshooter when you are making a legal complaint rather than ordinary product feedback.
    • Microsoft Copilot and Bing: use the thumbs-down feedback control or Microsoft’s Report a Concern process.
    • Perplexity: send a correction or removal request to support@perplexity.ai.
    • Grok: use the xAI reporting portal, including the route for inaccurate personal information where applicable.

    Keep the tone factual. State what the system produced, why the assertion is false, what evidence establishes the correction, and what outcome you want. Do not pad the request with guesses about training data or accusations that you cannot substantiate. Follow up when you have new evidence, a new recurring output, or a material consequence rather than sending repeated copies of the same ticket.

    Rebuild the entity evidence search and AI systems can use

    Verified digital evidence tiles connect around a central human silhouette while incorrect fragments detach from the surrounding network.

    Platform reporting deals with the visible answer. Reputation repair deals with the information environment that may produce the next answer. AI systems often repeat material already available online, so correcting the originating content matters. It may not be sufficient by itself: a harmful narrative can persist after its obvious web origin has been removed.

    Create one unambiguous canonical entity page

    Give search engines and generative systems a stable page that answers the basic identity questions without promotional fog. For a person, that will usually be a biography or profile page. For a company, it may be the primary About page or a dedicated company profile.

    • Use the exact public name consistently in the page title, visible heading, opening copy, metadata, and structured data.
    • Add the identifiers that separate the subject from namesakes: organization, role, location, field, and other accurate public distinctions.
    • Link to primary evidence for consequential claims, including official profiles, registries, decisions, corrections, or public records.
    • Keep current and historical roles distinct. A stale title or affiliation can cause systems to merge facts from different periods.
    • If a correction is necessary, make it factual and proportionate. Do not place the false accusation in the title, URL slug, meta description, or repeated headings merely to deny it.
    • Earn accurate profiles and coverage on credible independent sites where possible. A cluster of consistent, authoritative references is more useful than many thin pages under your control.

    Do not begin by creating look-alike personas or a network of near-duplicate profiles. Deliberate ambiguity may appear to bury a result, but it can make entity resolution harder and give automated systems more names and biographies to combine incorrectly. Fix the identity graph before trying to cloud it.

    Use JSON-LD for consistency, not as a rebuttal channel

    Apply Person or Organization markup that matches the visible page. Use name, url, and carefully selected sameAs links to verified, authoritative profiles. Add alternateName, affiliations, or employment relationships only when they are accurate, public, and genuinely help identification.

    Structured data cannot certify truth, remove a model response, or override stronger contradictory evidence. Never hide a rebuttal in JSON-LD that users cannot see on the page. The markup, page copy, linked profiles, and organization records should tell the same factual story.

    Measure the narrative instead of checking one favorite prompt

    Create a small prompt set based on the ways real stakeholders could ask about the subject. Include a plain identity query, a query with an employer or location disambiguator, and a neutral question about the disputed topic. Do not build dozens of prompts that repeat the accusation unnecessarily.

    • Record whether each answer is accurate, inaccurate, misleading by omission, correctly disambiguated, or unsupported by its citations.
    • Track which URLs and publishers recur across responses. Those recurring inputs deserve priority in the remediation plan.
    • Retest after a meaningful event: an originating page is corrected, a search result changes, the platform answers a ticket, or the canonical entity page is substantially updated.
    • Keep clean results as well as bad ones. They help show whether the problem is isolated, prompt-dependent, or recurring across systems.
    • Do not declare the incident resolved after one favorable answer. Resolution means the high-risk prompts and relevant search surfaces no longer reproduce the false narrative with reasonable consistency.

    No credible SEO, AEO, or GEO plan can promise immediate erasure from every model. Different systems retrieve, generate, update, and respond to corrections differently. The defensible objective is to remove bad inputs where possible, improve the clarity and authority of correct information, and document how outputs change.

    Know when reputation tactics are no longer enough

    Technical remediation can reduce visibility and confusion. It cannot decide whether you have a legal claim, preserve every legal right, or stop an urgent real-world consequence. Seek advice from a lawyer experienced in defamation, privacy, and platform disputes when the downside is serious or your next action could affect a claim.

    • The output falsely alleges criminal conduct, fraud, abuse, sexual misconduct, professional discipline, or another accusation likely to cause immediate harm.
    • An employer, customer, lender, licensing body, media outlet, or background-check provider has seen or relied on the statement.
    • The answer exposes private information, enables impersonation, creates a safety concern, or directs hostility toward the subject.
    • A publisher or platform refuses to correct a demonstrably false statement despite strong primary evidence or an existing court outcome.
    • You are considering a formal demand, preservation notice, subpoena, lawsuit, or disclosure of confidential records.
    • The claim appears repeatedly across products and seems connected to an identifiable publisher, campaign, or actor.

    The unresolved legal question is not merely whether a model encountered third-party material. AI can produce wording, implications, events, and citations that were never published by that third party. Arguments that Section 230 may protect an AI company therefore sit beside arguments that a generated answer is a new publication or goes beyond republishing someone else’s content. There is still limited precedent for assigning liability in these cases.

    Do not let that uncertainty turn the response into guesswork. Open a restricted incident file, preserve one reproducible example, assign an owner, and begin the platform and origin corrections. If the allegation is already affecting employment, business, safety, or a legal proceeding, give that evidence pack to qualified counsel before publishing a broad rebuttal that could amplify the claim.

    References

  • How to Build an AI-Powered Customer Journey That Converts

    How to Build an AI-Powered Customer Journey That Converts

    Your funnel may look orderly in analytics while the buyer’s real path is anything but. A customer can ask an AI assistant to frame the problem, compare approaches, challenge a recommendation, and identify a next step before visiting one of your pages. If your journey still assumes a neat sequence from landing page to form to sale, you are designing around your reporting structure rather than the customer’s decisions.

    The practical response is not to add a chatbot to every page. Build a journey in which AI helps the customer resolve a specific question, uses evidence you can maintain, and hands the customer to the next useful action without losing context. That gives you something you can improve instead of an impressive-looking interaction you cannot evaluate.

    Map the decisions the customer must make, not your channels

    Start with the customer’s unresolved decisions. Pages, email campaigns, search results, sales calls, and support conversations are delivery mechanisms. The journey itself is the sequence of questions standing between the customer and an outcome.

    A channel-first map usually contains boxes such as organic search, website, email, demo, and conversion. It tells you where contact happened, but not what the person needed from that contact. A decision map asks sharper questions: What is the customer trying to establish? What evidence would settle it? What should become easier once it is settled?

    Journey momentCustomer questionUseful AI roleEvidence you must supplyOutcome to observe
    Problem framingWhat is happening, and what kind of solution applies?Explain terms, classify the need, and surface relevant pathsDefinitions, use cases, exclusions, and related problemsThe customer reaches a relevant solution path
    EvaluationCould this approach fit my situation?Compare requirements, constraints, and alternativesCapabilities, limitations, compatibility, and audience fitThe customer examines the right option in more depth
    Confidence buildingWhy should I trust this answer or recommendation?Retrieve proof and connect a claim to its supportMethodology, examples, ownership, review dates, and clear claim boundariesThe customer verifies evidence or continues evaluation
    ActionWhat should I do next?Recommend an appropriate next step and explain its prerequisitesProcess, availability, costs where applicable, requirements, and calls to actionThe customer completes the intended action
    UseHow do I complete the task successfully?Guide, troubleshoot, and retrieve instructionsProcedures, supported paths, known failure conditions, and escalation optionsThe task is completed or correctly escalated
    ExpansionWhat additional value is relevant to me?Surface a related capability based on demonstrated needAdvanced uses, dependencies, integrations, and boundariesThe customer adopts a relevant next capability

    Create one row in your working map for each meaningful customer task. Record the question in the customer’s language, the evidence needed to answer it, the page or record that owns that evidence, the next useful action, the team responsible for it, and the event that should trigger a review. A product change might trigger a compatibility review; a policy change might trigger an update to eligibility guidance.

    Use site-search queries, sales discovery questions, support conversations, form responses, and failed searches to find the language customers already use. Do not collapse different decisions into a vague label such as consideration. Comparing two approaches and verifying whether an integration is supported are both evaluation activities, but they require different evidence and different next steps.

    Keep the customer task stable across channels. A person asking about compatibility should receive the same underlying answer whether the question appears in search, an AI assistant, a product page, or a sales conversation. The presentation can change. The facts should not.

    Give AI one useful job at each point in the journey

    AI becomes useful when it removes a defined obstacle. It becomes decorative when the brief is simply to make the journey intelligent. Before selecting a model, interface, or automation platform, name the work the AI is supposed to perform.

    • Explain: Turn unfamiliar language into a clear answer while preserving important qualifications.
    • Retrieve: Find the relevant policy, capability, instruction, or evidence from an approved knowledge set.
    • Compare: Organize meaningful differences without hiding limitations or mixing unlike criteria.
    • Recommend: Match stated needs to an option and show why it fits, what remains uncertain, and what alternatives exist.
    • Create: Draft an output from customer inputs, such as a configuration outline or requirements summary, while leaving verification to the appropriate person.
    • Act: Carry out an approved step in another system, with confirmation before any consequential change.

    These jobs have different evidence and control requirements. Retrieval needs an authoritative knowledge set and a way to expose the supporting record. Recommendation needs explicit fit criteria. Action needs permissions, confirmation, failure handling, and an audit trail. Treating them as one generic conversational feature makes defects difficult to isolate.

    Define every AI interaction as a small operating sequence:

    • Trigger: What customer behavior or request starts the interaction?
    • Inputs: What information is required, optional, prohibited, or already known?
    • Evidence: Which maintained records may be used to form the answer?
    • Transformation: Is the AI retrieving, summarizing, comparing, recommending, creating, or acting?
    • Output: What must the response contain, and what must it never imply?
    • Next action: What can the customer do immediately after receiving the answer?
    • Recovery: What happens when information is missing, contradictory, outdated, or outside scope?
    • Feedback: Which observable event tells you whether the interaction helped?

    Consider a buyer asking whether a product works with an existing system. A weak assistant gives a polished general description. A useful assistant asks for the missing environment detail, retrieves the supported configuration, states any limitation, links to the maintained compatibility record, and offers the appropriate setup or expert handoff. The value is not the conversation. It is the resolved decision and the clean transition that follows.

    Keep transactional facts outside the model’s improvisational control. Prices, availability, eligibility, contractual terms, account status, permissions, and supported configurations should come from the system that owns them. AI may explain those facts in plain language, but it should not invent or silently reconstruct them. A fluent answer does not make stale data safe.

    Build content that can survive retrieval and summarization

    A beam of light selects blank modular cards and source materials from an organized archive and assembles them into a compact bundle.

    In an AI-mediated journey, your content may reach the customer as a retrieved passage, a comparison, a recommendation rationale, or a summary rather than as a complete page. Because AI tools can process and present your information during customer interactions, content creation and delivery have to be planned as part of the journey itself.

    Write each important answer so it still makes sense when removed from the surrounding page. A useful answer unit contains:

    • A descriptive heading that names the customer’s question or task.
    • A direct answer near the beginning, without a promotional preamble.
    • The product, service, audience, region, plan, version, or situation to which the answer applies.
    • Any prerequisite, limitation, exception, or uncertainty that could change the decision.
    • The evidence or maintained record supporting the claim.
    • A clear next step appropriate to the resolved question.
    • An owner and a condition that should cause the answer to be reviewed.

    Ambiguous copy becomes more fragile when it is separated from its page. Replace phrases such as it works with most systems with the actual product name, supported condition, and relevant limitation. Replace better performance with the performance dimension you mean and the evidence available to support it. If you cannot identify the scope of a claim, an AI system will not reliably infer the boundary you intended.

    Separate facts from persuasion. Product requirements, process steps, definitions, and policy conditions should be explicit. Marketing claims should be recognizably claims and connected to suitable proof. This distinction helps the customer evaluate the answer and gives your retrieval system cleaner material to work with.

    Do not create several slightly different answers to the same factual question across campaign pages, help pages, product pages, and sales material. Choose a canonical record for the fact, then let other experiences reference or retrieve it. Duplication is not merely an editorial burden. It gives an AI system several plausible answers with no reliable way to know which one your business currently considers authoritative.

    Use JSON-LD to describe the visible truth

    Structured data can make entities and relationships more explicit, but it cannot repair weak evidence or guarantee that an AI service will select your content. Treat JSON-LD as a precise description of what the page visibly contains, not as a second set of claims written only for machines.

    • Use consistent names for the organization, product, service, person, offer, and other entities represented on the page.
    • Connect related entities only when the relationship is real and supported by visible content.
    • Keep descriptions, availability, eligibility, and other changing properties aligned with the maintained record.
    • Remove markup for content or relationships that no longer appear on the page.
    • Validate the rendered implementation after publishing and after template changes.

    The operational rule is simple: content, structured data, and transactional systems should not tell three versions of the same fact. Assign ownership at the fact level, not merely at the page level, so a change can propagate to every customer-facing experience that depends on it.

    Design the handoff before you design the conversation

    A customer's organized context bundle moves from a glowing AI network to a human advisor across an illuminated threshold.

    An AI response is a route through the journey, not necessarily the destination. The customer may need to open supporting evidence, complete a form, change a setting, speak with a specialist, or authorize an action. If the transition loses context, the customer has to reconstruct the problem and your team cannot tell whether the AI helped.

    Plan three kinds of handoff explicitly:

    • AI to content: Send the customer to the exact evidence, instruction, comparison, or policy that supports the answer, not a generic homepage.
    • AI to a person: Pass the customer’s goal, relevant inputs, answer already shown, evidence consulted, and unresolved question. Let the customer review what will be shared.
    • AI to an action: Show what will happen, which system or account will be affected, what data will be used, and whether the customer can reverse the change. Ask for confirmation when the consequence matters.

    A practical handoff record should preserve the customer task, known constraints, recommendation or explanation shown, supporting evidence, missing information, requested next action, and the state of the interaction when it moved. This is enough context to continue the journey without forcing the customer to repeat the entire exchange.

    Set escalation rules before launch. Do not rely on the assistant’s confident tone as evidence that an answer is complete. Escalate or narrow the response when:

    • The required fact is absent from the approved knowledge set.
    • Maintained records conflict or appear outdated.
    • The customer asks for a guarantee the evidence cannot support.
    • The action could change access, money, data, permissions, or a contractual commitment.
    • The request requires judgment reserved for a qualified person.
    • The customer disputes the answer, asks for a person, or repeats the question after attempted clarification.

    When the system cannot answer, say what is missing and offer the narrowest useful next step. A transparent limit is more helpful than a broad response padded with plausible language. Preserve the original question in the handoff so the next person can resolve the gap and so the content team can see what needs to be added or corrected.

    Measure resolved decisions, not conversational activity

    Message count, session length, and feature usage describe interaction volume. They do not tell you whether the customer made progress. A long conversation might indicate engagement, confusion, or repeated failure. Tie measurement to the customer task and its intended outcome.

    For each eligible interaction, capture the journey moment, question class, evidence retrieved, answer status, next action offered, action selected, action completed, correction or escalation, and final resolution where it can be observed. Avoid collecting customer information merely because the interface makes it easy; keep the event model limited to what you need to operate and improve the journey.

    Useful measures include:

    • Resolution rate: Resolved eligible interactions divided by eligible interactions.
    • Progression rate: Interactions in which the intended next action was completed divided by interactions in which it was appropriately offered.
    • Evidence coverage: Substantive answers connected to approved supporting evidence divided by substantive answers delivered.
    • Fallback rate: Eligible interactions that could not be answered or completed within the designed path divided by eligible interactions.
    • Repeat-question rate: Interactions in which the customer asks the same underlying question again after an answer.
    • Correction rate: Interactions requiring a factual correction divided by answered interactions.
    • Handoff completion: Accepted and successfully transferred handoffs divided by handoffs offered.
    • Journey outcome: The business or customer result appropriate to the task, such as successful setup, qualified evaluation, completed purchase, or resolved support need.

    Read these measures together. A rising progression rate means little if correction and repeat-question rates also rise. A lower fallback rate may look positive while evidence coverage deteriorates, which can mean the system has become more willing to answer without support. Define acceptable behavior as a combination of progress, accuracy, and recoverability.

    Review failures by question class rather than reading random transcripts and adjusting a general prompt. If compatibility questions fail, inspect the compatibility records, retrieval rules, required inputs, answer template, and handoff. Fix the earliest broken component. Prompt changes cannot supply a fact that your organization has never documented.

    When the customer outcome can be tested safely, compare the AI-assisted path with an appropriate baseline. Keep the customer task and outcome definition consistent. If random assignment would be unsuitable, use a staged rollout and examine the same task before and after the change, while noting other changes that could influence the result. The purpose is to learn whether AI improved the journey, not merely whether people interacted with it.

    A practical launch sequence

    1. Choose one customer question with a clear next action and a known owner.
    2. Write the acceptable answer, required evidence, important qualifications, and conditions that require refusal or escalation.
    3. Repair the underlying content and structured data before connecting an AI experience to them.
    4. Build the interaction around one defined AI job and make the next action visible.
    5. Design the content, human, or system handoff with preserved context.
    6. Instrument resolution, progression, evidence coverage, fallback, correction, and the relevant journey outcome.
    7. Review failures by question class and correct the evidence, retrieval, interaction, or handoff component responsible.
    8. Expand to another task only when the operating team can maintain the evidence and respond to failures.

    Key takeaways

    • Map the questions customers must resolve; channels are only places where those questions appear.
    • Give AI a defined job such as retrieval, comparison, recommendation, creation, or action.
    • Make important answers explicit, qualified, maintainable, and understandable outside the full page.
    • Keep visible content, JSON-LD, and operational records aligned around the same facts.
    • Preserve context across page, person, and system handoffs.
    • Judge the experience by resolved decisions and completed outcomes, with accuracy and recovery measures beside them.

    Start with the customer question your teams answer repeatedly and inconsistently. Write down the authoritative evidence, the next useful action, and the point at which a person must take over. That single journey slice will expose the content, data, ownership, and measurement work your broader AI strategy actually requires.

    References

  • Generative AI in Customer Purchasing: What to Optimize

    Your customer may ask an AI assistant to define the problem, find suitable products, compare a shortlist, and check the final choice before your analytics records a visit. If your decisive information is vague, inconsistent, or trapped behind a sales conversation, the assistant has little reliable material with which to represent you.

    The practical response is not to publish more generic AI content. It is to make each buying decision easier to answer, verify, and act on. That means choosing the right purchase questions, publishing concrete evidence, aligning your structured data with the page, and measuring influence beyond referral clicks.

    Key takeaways

    • Organize your strategy around four customer jobs: problem solving, discovery, comparison, and validation.
    • Use industry adoption figures as a directional signal, then confirm the opportunity with your own customer, sales, search, and revenue data.
    • Give AI systems explicit facts about suitability, limitations, price basis, availability, location, and tradeoffs. Marketing adjectives cannot substitute for decision evidence.
    • Keep important claims consistent across visible content, structured data, product feeds, listings, and supporting pages.
    • Measure whether your brand is represented accurately and influences purchases, not merely whether an AI assistant sends a clickable referral.

    Map the purchase job before you choose what to optimize

    Generative AI does not have one fixed role in purchasing. A customer asking how to solve a problem needs a different answer from someone comparing two named options. Treating both prompts as broad product discovery produces shallow content and weak measurement.

    Across the industries examined in a 2025 purchasing analysis, AI appeared in four recurring parts of the journey: problem solving, discovery, comparison, and validation. Use those jobs to map the questions that precede a purchase:

    Purchase jobWhat the customer is trying to decideWhat your content must provide
    Problem solvingWhat kind of solution fits this situation?A plain explanation of the problem, relevant options, constraints, risks, and the conditions under which each option makes sense.
    DiscoveryWhich products, services, providers, or programs meet the requirements?Explicit eligibility, use cases, location, schedule, availability, price basis, and other attributes that determine inclusion.
    ComparisonWhich shortlisted option offers the best fit?Like-for-like criteria, measurable differences, tradeoffs, exclusions, and evidence for each material claim.
    ValidationIs the preferred choice credible, current, and safe to act on?Terms, limitations, proof, policies, implementation details, review dates, and a clear next step.

    Start by collecting the actual questions customers ask in sales calls, support conversations, on-site search, search-query data, reviews, and post-purchase feedback. Label each question by purchase job. If one question spans two jobs, split it. A query about the best accounting platform for a construction company is discovery; a query comparing two named platforms for that company is comparison.

    Industry figures can help you decide where this work deserves attention, but they do not replace first-party evidence. Among 3,161 people surveyed online about their behavior over the previous year, reported use varied substantially by sector. Responses were screened for consistency and weighted for demographic and industry representation, but the results remain self-reported and should be treated as directional rather than as a universal market benchmark.

    IndustryCustomers reporting AI use in the purchase journeyProminent purchase jobsInformation to make explicit
    Education61%Discovery, comparison, validationProgram focus, schedule, format, suitability, and the facts a prospective student needs to verify a shortlist.
    Food & beverage59%Problem solving, discoveryRecipe use, product purpose, relevant constraints, and the conditions in which a recommendation fits.
    Lifestyle, health & wellness54%Problem solving, discoveryIntended use, suitability, limitations, supporting evidence, and safety boundaries.
    Travel & hospitality53%DiscoveryLocation, itinerary fit, accommodation details, transport options, availability, and booking constraints.
    Retail & CPG49%Problem solving, discovery, comparisonSpecifications, variants, compatibility, price basis, availability, and differences between plausible options.
    Automotive46%ComparisonConsistent specifications and tradeoffs that help a buyer narrow the field to two or three models.
    Healthcare44%Problem solving, discoveryEducational information, service scope, technology capabilities, evidence, limitations, and clear boundaries around individualized medical decisions.
    Home services41%Discovery, comparison, validationService area, cost factors, provider qualifications, scope, exclusions, and how an estimate becomes a quote.
    B2B SaaS41%Problem solving, discovery, comparisonIndustry fit, use cases, platform differences, requirements, limitations, and the facts needed to validate a shortlist.

    Do not rank opportunities by adoption percentage alone. A modest-volume decision with high purchase value or severe consequences may deserve better content before a high-volume, low-value query. Prioritize the intersection of five conditions:

    • Customers already use AI, or are likely to use it, for the decision.
    • The decision has meaningful commercial value.
    • You possess reliable facts that can improve the answer.
    • An inaccurate answer could exclude your brand, mislead the buyer, or create safety, financial, or legal exposure.
    • Your offer has a real distinction that can be expressed as evidence rather than a slogan.

    Be careful with revenue projections. The percentage of customers who used AI somewhere in a journey is not the percentage of revenue caused by AI. Multiplying an industry’s market value by an adoption percentage may describe a broad area of exposure, but it does not establish incremental sales, attribution, or return on optimization work.

    Build an answer asset for each stage of the journey

    A single commercial page rarely answers every purchase job well. The better approach is a connected set of answer assets, each designed around one decision and linked to the pages that supply deeper evidence.

    Problem-solving content should diagnose the decision, not the person

    Open with the situation in the customer’s language. Explain the available solution categories, the constraints that change the answer, and when your category is not appropriate. Only then connect the problem to a product or service.

    A useful problem-solving page answers questions such as:

    • What is the customer trying to accomplish?
    • Which facts materially change the recommendation?
    • What are the plausible approaches?
    • Who is each approach suitable or unsuitable for?
    • What information is still required before someone can act?

    Health, wellness, financial services, fintech, and insurance require stricter boundaries. Do not let educational content diagnose an individual, prescribe treatment, promise a financial outcome, or present an estimated insurance price as a guaranteed quote. State the limitation where the recommendation appears and direct individualized decisions to an appropriately qualified medical, financial, insurance, or legal professional.

    Discovery content must expose the attributes that control fit

    Discovery prompts are usually constraint problems in conversational form. The customer wants an option that works in a location, on a schedule, within a budget, for a use case, or with a required feature. If those attributes are missing, an AI system must omit the option or infer facts you did not provide.

    Write the decisive attributes as clear text, not as implications. A school should state when and how a program is offered. A home-service provider should name the service area and explain the factors that change cost. A retailer should distinguish product variants and compatibility. A software company should define the supported use cases and material requirements. When a fact is unavailable, say that it is not published or requires confirmation; do not fill the gap with a guess.

    Discovery content also needs honest exclusion criteria. A page that explains who should not choose the offer gives the buyer a usable boundary and makes the positive fit more credible.

    Comparison content needs symmetry

    Comparison fails when one option is described with detailed, current facts and another with vague or outdated language. Define the criteria first, use the same unit and scope for every option, and separate verified facts from editorial judgment.

    A defensible comparison page should include:

    • The audience and use case for which the comparison is intended.
    • The criteria that materially affect the decision.
    • A like-for-like table with the same fields for every option.
    • Tradeoffs, missing information, and conditions that could change the conclusion.
    • Links to the evidence behind consequential claims.
    • A visible review date for facts that can change.

    Do not manufacture a favorable winner by choosing irrelevant criteria or by asserting unpublished competitor details. If your product is not the best fit for a scenario, say so. The page becomes more useful because the recommendation is conditional rather than predetermined.

    Validation content should remove the final uncertainty

    Validation happens after the customer has a preferred option. The remaining questions concern trust, current terms, suitability, and execution. This is where unsupported superlatives are least helpful.

    Connect the recommendation to primary evidence: current product or service details, documented policies, relevant qualifications, implementation requirements, limitations, and a clear path for confirming anything that depends on the individual buyer. Keep testimonials and reviews in their proper role. They can show experience, but they do not replace technical specifications, eligibility rules, contractual terms, or professional advice.

    Use the same brief for every answer asset. Define the question, audience, direct answer, best-fit conditions, poor-fit conditions, comparison criteria, evidence, facts requiring regular review, and next action. That structure gives editors, subject-matter experts, SEO teams, and schema implementers a shared definition of completeness.

    Make decisive facts extractable, consistent, and verifiable

    Good prose and technical optimization solve different parts of the problem. The page must explain the decision to a person, while its facts must also be represented consistently enough for search engines and AI systems to retrieve and interpret them.

    1. Put the direct answer and its qualifications in visible page text. Do not leave essential facts only in an image, downloadable document, configurator, or interactive element.
    2. Use stable names for the organization, product, service, location, and plan. Avoid switching between labels in ways that make one entity look like several.
    3. Present comparable attributes in predictable fields. Tables work well when every row uses the same definition, scope, and unit.
    4. Link consequential claims to the page that proves or governs them. A summary page can simplify the decision without becoming the sole authority for every detail.
    5. Add only the structured data that the page and business actually support. Markup should clarify visible facts, not introduce a second version of them.
    6. Assign an owner to facts that change. When price, availability, schedules, coverage, terms, or eligibility changes, update the visible content, structured data, feeds, and supporting pages together.

    For JSON-LD, choose the most specific applicable Schema.org type rather than the type with the most available properties. A product page may legitimately use Product and Offer information; a business entity may need Organization or an applicable LocalBusiness subtype. The correct choice depends on what the page actually represents. Do not mark up inferred ratings, generated testimonials, unavailable offers, or facts that users cannot verify on the page.

    Structured data reduces ambiguity, but it does not guarantee an AI citation, recommendation, or ranking. It also cannot repair thin or contradictory content. Treat it as a machine-readable agreement with the visible page: the entity, attributes, offer, availability, and supporting evidence must tell the same story in both places.

    Run a consistency check before publishing. Compare the answer asset with product pages, pricing pages, location pages, business listings, feeds, policy pages, and JSON-LD. A small factual mismatch can change the recommendation: a service area that differs between pages, a price with an unclear billing period, or a plan name that no longer exists.

    Measure representation and purchasing influence, not just clicks

    AI-assisted purchasing can occur without a conventional referral. A customer may read an answer, remember a brand, navigate directly, and buy later. Referral analytics therefore show one useful behavior, not the whole journey.

    Measurement layerWhat to recordWhat it helps you decide
    VisibilityWhether your brand, product, or service appears for a controlled set of purchase prompts, and whether the answer cites one of your pages.Which purchase jobs and answer assets have discoverability gaps.
    Representation accuracyWhether important attributes, limitations, prices, locations, and comparisons are stated correctly.Which factual gaps or contradictions require correction before greater visibility is desirable.
    EngagementAI referral sessions when a referrer is available, landing-page behavior, qualified inquiries, and assisted conversions.Whether visibility reaches the right page and produces useful customer action.
    Purchase influenceCustomer-reported AI use, the assistant used when remembered, the question asked, and the role the answer played.Whether AI contributed to discovery, comparison, validation, or the final choice even when no referral was captured.

    Build the prompt set from real customer language. Include the problem-led questions that open the journey, the category and local discovery questions that form a shortlist, named comparisons, and the validation questions that appear near conversion. Record the intended audience, location, constraints, and purchase stage so that a change in wording does not silently change what you are measuring.

    Establish a baseline before editing. Save the answer, cited pages, brand inclusion, factual errors, and unsupported claims for each prompt. Then change a focused group of answer assets and repeat the same checks on a fixed cadence. AI responses can vary, so look for recurring representation patterns rather than treating one generated answer as a permanent ranking.

    Add a direct attribution question to inquiry and post-purchase forms: Did an AI assistant help you research or choose? If the customer says yes, ask which part of the decision it influenced and provide an optional field for the question they asked. Keep an unknown option; forcing a precise answer creates cleaner-looking but less trustworthy data.

    Your first move should be narrow. Choose one commercially important purchase job, publish the answer asset that resolves it, align its visible facts and schema, and instrument the conversion path for AI-assisted discovery. Expand only after you can see whether customers are finding the answer, whether your offer is represented correctly, and whether that representation helps a real purchasing decision.

    References

  • How to Protect Brand Authenticity in AI-Assisted Content

    How to Protect Brand Authenticity in AI-Assisted Content

    You need to publish more useful content without turning your brand into a production line of polished, interchangeable pages. AI can remove hours of mechanical work, but it can also remove the judgment, specificity, and recognizable point of view that make your content worth choosing.

    The answer is not to keep AI out of the workflow. It is to decide where efficiency belongs, where a human must remain accountable, and what every page has to prove before you publish it.

    Content quality must serve the reader and the retrieval system

    AI is valuable because it can increase speed and automate repeatable work. The problem begins when a team treats faster production as evidence of better content.

    A page can be grammatically clean, keyword-aware, and structurally complete while still failing the reader. It may repeat familiar advice, hide the answer beneath an introduction, make claims it cannot support, or sound as though no identifiable organization chose the words.

    In the AI era, useful content has to pass several different tests:

    • Accuracy: Can you trace every meaningful factual claim to reliable evidence, and have you preserved any necessary limits or uncertainty?
    • Usefulness: Can the reader make a decision, complete a task, or notice a problem they would otherwise miss?
    • Specificity: Does the page explain the mechanism, constraint, sequence, example, or trade-off behind its advice?
    • Distinctiveness: Does it contain a judgment, method, explanation, or framing that reflects what your brand actually knows and believes?
    • Retrieval clarity: Can a relevant passage stand on its own when a search engine or answer system extracts it from the surrounding page?
    • Brand coherence: Do the vocabulary, promises, evidence standards, and level of certainty match the rest of your site?

    These tests catch different failures. Accurate but generic content is forgettable. Distinctive but unsupported content is risky. Search-ready content that reads like a machine-generated template may earn an impression without earning trust. A page is ready only when it is useful, supportable, recognizable, and easy to interpret.

    Keep human judgment where trust is created

    The safest division of labor is based on accountability, not on whether a task appears easy. Let AI transform approved material. Keep people responsible for deciding what is true, what matters, what the brand believes, and what the reader should do.

    AI is well suited to bounded transformations such as reorganizing notes, proposing outlines, generating headline alternatives, turning a long explanation into a checklist, identifying repeated language, and adapting an approved passage to another format. Those tasks have visible inputs and reviewable outputs.

    Human ownership matters most at the points where an error would change meaning or weaken trust:

    • Selecting the audience, search intent, and decision the page must support.
    • Choosing evidence and deciding which claims the evidence can genuinely carry.
    • Contributing subject expertise, exceptions, operational details, and a defensible point of view.
    • Setting the boundary between established fact, editorial judgment, inference, and uncertainty.
    • Approving promises about products, outcomes, customers, compliance, or performance.
    • Accepting final responsibility for the published page and its structured data.

    For claims that need proof, do not treat model memory as evidence. A fluent sentence can still be unsupported, overgeneralized, or detached from the conditions that made the original claim true.

    Give the model a content contract, not a loose prompt

    A prompt that asks for an authoritative SEO page leaves the important decisions unresolved. Before drafting, create a short content contract with fields an editor can inspect:

    • Reader situation: What has brought this person to the page, and what do they already understand?
    • Reader job: What should they be able to decide or do after reading?
    • Primary claim: What is the clearest answer you are prepared to defend?
    • Evidence packet: Which approved facts, documents, examples, and internal expertise may the draft use?
    • Brand position: What does your organization believe that a generic overview would not say?
    • Claim boundaries: What must not be asserted, implied, invented, or generalized?
    • Voice constraints: Which language patterns should appear, and which should be removed?
    • Retrieval target: Which question deserves a concise, self-contained answer within the page?
    • Next action: What useful step should the reader take, even if they never become a customer?

    Then run the work in an explicit sequence:

    1. A subject owner approves the reader job, primary claim, evidence, and brand position.
    2. AI proposes an outline in which every section resolves a distinct reader question.
    3. An editor removes sections that exist only to make the page look comprehensive.
    4. AI drafts from the approved contract and evidence packet.
    5. A factual pass checks claims, qualifiers, entity names, citations, and unsupported implications.
    6. A separate brand pass checks judgment, vocabulary, tone, repetition, and generic phrasing.
    7. An optimization pass improves headings, answer units, internal links, metadata, and relevant structured data without changing the approved meaning.
    8. A named human owner approves the visible content and machine-readable representation together.

    Separating the passes matters. If one reviewer tries to verify facts, improve voice, shorten sentences, and inspect schema at the same time, the visible polish can distract from a weak claim or an unhelpful answer.

    Turn brand voice into an editing system

    An editor adjusts an unlabeled instrument that turns plain gray tiles into varied designs with a consistent color palette and material style.

    Authenticity does not depend on a human typing every sentence. It comes from a consistent relationship between what your brand knows, what it believes, what it promises, and what it publishes. AI can help express that relationship, but it cannot invent it responsibly.

    Labels such as friendly, expert, bold, or conversational are too subjective to guide a draft. Replace them with observable editorial rules:

    • Beliefs: Record the principles that shape your recommendations. For example, visible content should answer the question before structured data describes the answer.
    • Audience contract: State what you owe the reader. This might include explaining constraints, separating evidence from opinion, and never hiding the practical answer behind a sales pitch.
    • Proof habits: Define when claims need links, examples, named entities, qualifications, or review by a subject expert.
    • Language choices: List preferred terminology, prohibited hype, acceptable contractions, sentence-length tendencies, and the technical terms that must remain precise.
    • Boundaries: Document claims the brand will not make, including guarantees, fabricated experience, invented customer stories, and unsupported comparisons.
    • Approved examples: Save real passages that demonstrate the voice and annotate why they work. A model needs patterns, not just adjectives.

    Consider the difference between a generic claim and an owned editorial position.

    Generic: AI is transforming content marketing and helping businesses improve efficiency.

    Owned: Use AI to compress mechanical work. Keep evidence selection, claim boundaries, and final judgment with an accountable editor.

    The second version is not stronger because it sounds more colorful. It makes a decision, draws a boundary, and tells the reader what to do differently. That is the material from which a recognizable brand voice is built.

    Use a swap test during editing: if a competitor could publish the paragraph unchanged, it probably lacks an owned insight. Do not add a slogan merely to make it sound branded. Add the missing judgment, mechanism, example, limitation, or operating rule.

    Also remove simulated experience. If your organization did not run a test, interview a customer, inspect an account, or observe a result, the draft must not imply that it did. Explain what you know and how you know it. Honest limits are part of brand voice.

    Make content easy for people and answer systems to use

    Optimization for AI search does not require stripping personality from the page. It requires making the important meaning easy to locate, interpret, and reuse without distortion.

    Build important sections as self-contained answer units:

    1. Use a heading that names the actual question or decision.
    2. Answer it in the opening sentence without forcing the reader through background first.
    3. Explain why the answer holds or how the mechanism works.
    4. Name the condition, exception, version, audience, or limitation that changes the advice.
    5. Give the reader a concrete next action.
    6. Link the words carrying an evidence-dependent claim, rather than attaching an unexplained list of links.

    The opening answer provides clarity. The mechanism and limitation provide trust. The recommended action is where brand judgment becomes visible. You can therefore write a passage that is both extractable and distinctly yours.

    Run a context test on each candidate answer unit. Copy the passage into a blank document and ask:

    • Is the subject named, or does the passage depend on a vague pronoun?
    • Can a reader tell whether the statement is a fact, recommendation, definition, or opinion?
    • Are material conditions and exceptions still present?
    • Does the passage identify the product, organization, feature, standard, or audience precisely?
    • Would the passage remain accurate if displayed without the preceding paragraph?

    If the answer unit fails outside its original context, revise the language rather than stuffing more keywords into it.

    Consistency also matters across the site. Use one canonical name for your organization, products, services, features, and authors. Explain genuine synonyms, but do not rotate terminology simply to create lexical variety. Unnecessary variation makes it harder for a person or system to determine whether two passages refer to the same entity.

    Apply the same discipline to JSON-LD and other structured data. Markup should represent the visible page accurately. It should not introduce credentials, ratings, offers, authorship, answers, or relationships that the reader cannot verify in the content. Schema can clarify a strong page; it cannot supply the substance the page is missing.

    Finally, use internal links to connect a concise answer with the deeper proof behind it. A summary page can resolve the immediate question, while a supporting page explains the method, terminology, evidence, or implementation. This creates a useful path for readers without forcing every page to become an exhaustive encyclopedia.

    Replace output metrics with a publish gate and feedback loop

    A circular track carries blank page-shaped objects through a human review station, with one sent back for revision and another released to waiting readers.

    Traditional quality metrics are not enough for AI-first content. Word count, production volume, grammar checks, and a passing optimization score can describe the artifact or workflow, but they cannot establish that the page is accurate, useful, distinctive, or trusted.

    A useful measurement system separates four kinds of signals:

    • Production signals: Track drafting time, approval loops, substantial rewrites, and where work repeatedly returns to an earlier stage. These reveal workflow efficiency, not content quality by themselves.
    • Integrity signals: Track unsupported-claim flags, citation gaps, correction requests, entity inconsistencies, and mismatches between visible content and structured data.
    • Brand signals: Track prohibited language, failed swap tests, unapproved promises, simulated experience, and sections that lack an identifiable editorial position.
    • Discovery signals: Where your tools can observe them, track the queries that surface the page, branded and non-branded visibility, citations or mentions in answer experiences, and referrals from AI interfaces.
    • Outcome signals: Match the page to its intended job, such as a completed setup, qualified inquiry, subscription, product comparison, or movement to a deeper supporting page.

    Read these signals together. Faster production accompanied by more factual corrections means the workflow moved effort downstream rather than removing it. Strong visibility with weak outcomes may indicate that the page answers the query but does not help with the decision behind it. Good engagement with repeated swap-test failures means the page may be useful while doing little to build brand recognition.

    A composite quality score can help you prioritize review, but it should not own the publishing decision. Use a simple editorial gate:

    • Block: A material claim lacks evidence, the page invents experience, a required limitation is missing, an entity is misrepresented, or structured data asserts something the visible page does not support.
    • Revise: The answer is buried, advice remains generic, sections repeat one another, the next action is unclear, or the language fails the brand’s documented rules.
    • Publish: The page answers a real reader need, important claims are supportable, brand judgment is visible, answer units survive the context test, and a named owner accepts responsibility.

    After publication, feed what you learn back into the system. Log corrections with their causes. Add strong and weak passages to the annotated voice examples. Update the content contract when reviewers keep fixing the same omission. Revisit important pages when the offer, evidence, entity information, or reader decision changes.

    Key takeaways

    • Use AI for bounded, reviewable transformations; keep people accountable for evidence, judgment, promises, and approval.
    • Define brand voice through beliefs, proof habits, language rules, boundaries, and annotated examples rather than vague tone adjectives.
    • Write self-contained answer units that give a direct answer, explain the mechanism, preserve limitations, and recommend a useful action.
    • Keep entity language, visible content, internal links, and structured data consistent.
    • Measure production efficiency separately from integrity, brand distinctiveness, discovery, and reader outcomes.
    • Block publication when a material claim, implied experience, or machine-readable assertion cannot be supported.

    Start with one commercially important page. Write its content contract, mark every evidence-dependent claim, run the swap and context tests, and compare its structured data with what a reader can actually see. The weaknesses you find will tell you exactly which rules your wider AI content workflow needs next.

    References

  • Profound’s $35M Funding and Its Developer Ecosystem

    Profound’s $35M Funding and Its Developer Ecosystem

    If you’re deciding whether Profound belongs in your AI-search stack, the funding number is the least useful place to stop. A financing round can give a vendor room to build. It cannot tell you whether its data is trustworthy, its package fits your application, or its integration is safe to run in production.

    Profound now offers three concrete signals to investigate: $35 million in Series B funding, a one-click Vercel Marketplace integration for Agent Analytics, and next-aeo, an NPM package built for Next.js applications. That combination shows where an ecosystem may be forming. It does not remove the need for technical due diligence.

    Read the $35 million as capacity, not product proof

    Funding matters because software ecosystems require sustained investment. The core product is only one expense. A useful developer platform also needs documentation, integrations, package maintenance, support, security work, infrastructure, and compatibility testing.

    Profound’s $35 million raise creates capacity for that work. It does not prove that every part has already been delivered, nor does it guarantee product quality, vendor longevity, or a particular roadmap. A financing event is not a service-level agreement.

    Separate the headline from the evidence by keeping a simple evaluation ledger with three states:

    • Available: The vendor publicly offers the capability, package, or integration.
    • Verified: Your team has confirmed how it behaves in your own environment.
    • Unknown: The answer depends on documentation, testing, a contractual commitment, or a response from the vendor.

    The funding belongs in the available column as evidence of new financial capacity. The Vercel integration and next-aeo package also belong there until you test them. Do not quietly promote an available feature to verified merely because installation looks simple.

    When you evaluate what the funding could mean for your organization, look for release evidence in four areas:

    • Product delivery: Are analytics, integrations, and developer tools becoming usable parts of the same workflow?
    • Maintenance: Can you find version requirements, release notes, upgrade guidance, and a clear support path?
    • Operational depth: Are permissions, exports, retention, failure modes, and rollback procedures explained?
    • Developer adoption: Can an engineer install, inspect, test, and remove the tooling without relying on a sales demonstration?

    This keeps the decision grounded. Capital can accelerate an ecosystem, but only maintained interfaces make that ecosystem useful to your team.

    The ecosystem has three layers with different jobs

    An isometric three-level system connects AI-search analytics, a cloud integration gateway, and modular web application components.

    Profound’s current footprint spans company capacity, deployment distribution, and application-level tooling. Those layers answer different questions, so they should not be treated as interchangeable proof.

    LayerVerified public signalWhat it helps you assessWhat it does not establish
    Company capacity$35 million Series B fundingAccess to new capital for expansionProduct accuracy, profitability, long-term availability, or service quality
    Deployment distributionAgent Analytics on the Vercel Marketplace with a one-click connectionWhether a supported installation path exists for a Vercel workflowProduction permissions, data handling, metric definitions, or setup after authorization
    Application toolingnext-aeo as an NPM package for Next.jsWhether developers have a framework-specific AEO entry pointExact output, version compatibility, ranking effects, or maintenance quality

    The important question is whether these layers form a closed operating loop. Your application produces content and machine-readable signals. Analytics helps you observe how AI systems interact with the site. Those observations should lead to a specific content, code, or distribution decision. If your team cannot identify that final decision, the stack may create another dashboard without improving the workflow.

    One-click installation is not one-click operation

    The Vercel Marketplace integration is meaningful because it brings Agent Analytics into a deployment channel developers may already use. For a Vercel-based team, a marketplace connection can reduce custom setup work.

    But one-click describes the start of the connection, not the quality of the outcome. Before calling the integration production-ready, determine:

    • Which Vercel projects, environments, accounts, and resources it can access.
    • Which credentials or tokens it creates, where they are stored, and how they are revoked.
    • What data leaves your environment and whether prompts, URLs, responses, or user-related fields can be included.
    • How an AI interaction is identified, filtered, deduplicated, and attributed.
    • What happens when the integration fails, is disconnected, or encounters a deployment change.
    • Whether data can be exported before you remove the integration.

    Treat the marketplace listing as evidence of distribution maturity. Treat data quality, security, and operational fit as separate tests.

    next-aeo moves AEO into the application layer

    The next-aeo package targets Next.js developers and frames answer engine optimization as an implementation concern, not only an editorial checklist. That is useful because developers can potentially review AEO-related behavior alongside application code, dependencies, builds, and deployments.

    Do not infer its exact behavior from the package name. Before adoption, inspect whether it changes rendered HTML, metadata, structured data, routes, configuration, server behavior, or the build pipeline. Establish which Next.js versions and routing models it supports. Check whether the package behaves differently with static generation, server rendering, incremental regeneration, or client-rendered content where those patterns exist in your application.

    If next-aeo emits or transforms JSON-LD, inspect the final rendered markup rather than the source configuration alone. Look for invalid syntax, duplicate entities, conflicting identifiers, missing required properties, and differences between development and production builds. If it modifies metadata, compare canonical URLs, robots directives, titles, descriptions, and social metadata before and after installation.

    AEO does not create a guaranteed position in an AI-generated answer. Use the package to improve implementation discipline only after you can explain what it produces and why that output should help answer-oriented systems understand the page.

    Use a production-readiness checklist before connecting data

    A data pipeline passes through privacy, validation, testing, monitoring, and final approval gates before reaching a production application.

    The fastest way to make a weak platform decision is to install first and define success later. Write the test contract before the package or integration changes your environment.

    Define the measurement contract

    Agent Analytics is intended to provide insight into AI interactions with a site. That description is a starting point, not a metric definition. Your team should be able to answer these questions before using the data for strategy:

    • What event qualifies as an AI interaction?
    • How are agents distinguished from ordinary browsers, crawlers, proxies, automation, and spoofed user agents?
    • Which fields are observed directly, and which are inferred?
    • How are repeated requests, retries, cached responses, and internal traffic handled?
    • Which dimensions are available for filtering and comparison?
    • How far back does the data go, and can a methodology change alter historical comparisons?
    • Can the underlying records be exported for independent validation?

    Write the accepted definition beside every metric you plan to report. If a stakeholder asks what changed, you should be able to explain both the number and the collection mechanism. A polished dashboard label is not a substitute for a documented definition.

    Test application compatibility at the rendered-output level

    Record the exact Next.js version, router, rendering modes, deployment configuration, package manager, and existing SEO or schema tooling in the test environment. Then compare the application before and after installation at several points:

    • Dependency resolution and installation output.
    • Local and production-mode build logs.
    • Generated artifacts and server output.
    • Rendered HTML, metadata, response headers, and structured data.
    • Representative static, dynamic, localized, canonicalized, and authenticated routes used by your application.
    • Deployment logs, runtime errors, and page behavior after release.

    Pin the version you test and preserve a rollback path. An automatic package upgrade can change sitewide output, so do not leave a production AEO dependency floating across unreviewed releases.

    Review permissions and data handling before production

    Do not connect a production project until you understand the integration’s access scopes, network destinations, credential lifecycle, retention behavior, deletion process, and administrative controls. If prompts, URLs, responses, or user-related fields can be collected, involve the people responsible for security, privacy, and consent before enabling that collection.

    A mis-scoped credential can expose more infrastructure than the tool needs. Unexpected collection can create privacy or contractual exposure. Use a staging environment or a non-sensitive project while those questions remain unresolved, and grant the narrowest access that still supports the test.

    Assign operational ownership

    An ecosystem becomes expensive when every component exists but nobody owns the handoffs. Name the person or team responsible for each recurring task:

    • Reviewing package releases and compatibility changes.
    • Approving integration permissions and credential rotation.
    • Investigating analytics anomalies and methodology changes.
    • Turning observations into content or engineering work.
    • Maintaining documentation for installation, rollback, export, and removal.
    • Deciding whether the tooling still earns its place in the stack.

    If these responsibilities fall between SEO, engineering, analytics, and security, the integration will eventually become unowned infrastructure. Resolve that before rollout.

    Run a staged pilot that ends with a decision

    Your first pilot should establish operational fit. Do not promise an AI-visibility lift before the implementation and measurement definitions are stable. A narrow, reversible test will tell you more than a broad installation with no baseline.

    1. Name the decision. State whether you are evaluating Profound for measurement, application-level AEO implementation, or the combined workflow. Define what would lead to adoption, a hold, or rejection.
    2. Capture the baseline. Record the application version, deployment settings, representative routes, current HTML and metadata, existing JSON-LD, current analytics, and known errors before making a change.
    3. Review the artifacts. Check package requirements, permissions, data handling, release information, support paths, and removal steps. Put unresolved questions in the unknown column of your evidence ledger.
    4. Use a non-production environment. Connect the Vercel integration only after reviewing its requested access. Scope the next-aeo change as narrowly as the package and application architecture permit.
    5. Inspect every layer. Verify that the application installs and builds, that rendered output changes only as expected, and that analytics records can be explained using a documented definition.
    6. Roll back and repeat. Remove the package or integration, confirm that the environment returns to its baseline state, and repeat the installation from written instructions. This exposes hidden manual steps and configuration drift.
    7. Write the decision record. List what was verified, what remains unknown, who owns the workflow, and what would trigger reevaluation. Keep funding and roadmap expectations separate from tested behavior.

    Use explicit gates for approval. A credible pilot should produce a repeatable installation, understandable data, no unexplained output changes, acceptable permissions, a named operational owner, and a tested exit path. If one of those is missing, document the gap instead of averaging it away with strengths elsewhere.

    The combined stack earns a broader rollout only when the loop works: application changes are inspectable, analytics is explainable, and the resulting evidence leads to a concrete optimization decision. That is the difference between owning an ecosystem and merely accumulating tools.

    Key takeaways

    • Profound’s $35 million Series B provides capacity to invest, but it does not validate product performance, security, or long-term fit.
    • The Vercel Marketplace integration reduces initial connection friction; one-click installation does not settle permissions, data quality, retention, or operational ownership.
    • The next-aeo NPM package gives Next.js teams a framework-specific AEO entry point, but you still need to verify compatibility and inspect its rendered output.
    • Evaluate funding, analytics, deployment integration, and application tooling as separate layers before testing whether they form a useful workflow.
    • Use a narrow staging pilot, written measurement definitions, pinned dependencies, and a tested rollback path before committing production data or sitewide output.

    If Profound is on your shortlist, pair an engineer with the person who owns AI-search performance and complete the evidence ledger before procurement or production access. Let reproducible installation, explainable data, and safe removal make the decision.

    References

  • What the CrushPress Founders’ San Francisco Move Means

    What the CrushPress Founders’ San Francisco Move Means

    If you saw that CrushPress’s founders were heading to San Francisco, the obvious question is whether New York is being left behind. That is not the right reading of the move. San Francisco is being added as a second home, while New York remains central to how the company began.

    The useful question is what a second city can change. For customers, partners, candidates, and AI-search practitioners, the answer depends less on the address than on whether greater proximity to the AI community produces clearer insights, better decisions, and more useful work.

    The important word is second

    CrushPress’s New York connection is not incidental. The founders first crossed paths at South Park Commons in New York City, and they expected the venture they built together to remain rooted there. New York’s pace, ambition, and grit matched the kind of company they wanted to create.

    Calling San Francisco a second home therefore signals addition, not erasure. It preserves the founding relationship with New York while opening another place from which the founders can build relationships and learn.

    That distinction prevents a common misreading. A founder presence in a city does not automatically establish a new headquarters, a customer-facing office, a full-team relocation, or a change to contracts and support. Those are separate operational facts. If you work with CrushPress, do not infer them from the move alone; rely on direct communication about anything that affects your account.

    At the same time, founder geography is not meaningless. It changes which conversations happen frequently, which problems are heard early, and which relationships can develop without every interaction requiring a planned trip. The opportunity is real, but it still has to travel from the room into the work.

    Why San Francisco can sharpen an AI-search company

    AI practitioners gather around laptops and notebooks in a sunlit San Francisco workspace while abstract network shapes are projected nearby.

    AI search sits at the intersection of models, search interfaces, content systems, measurement, and brand strategy. The field changes through many small shifts: a new answer format, a different citation pattern, an emerging workflow, or a change in how marketing teams evaluate visibility. Written updates reveal the finished change. Direct conversations can reveal the unresolved problem behind it.

    A San Francisco base can compress that learning loop. Proximity makes it easier to encounter model builders, technical operators, marketers, founders, investors, and prospective hires in overlapping communities. A question heard in one meeting can be tested in the next. A repeated complaint can be separated from a one-off preference before it influences a roadmap or editorial position.

    But proximity is an input, not an outcome. Being near an active AI community does not automatically improve a product, an optimization method, or a customer’s visibility. The move becomes strategically useful only when the resulting access passes through a disciplined sequence:

    1. Listen for repeated problems. A memorable conversation is not necessarily a market signal. The same need should appear across different roles and companies before it drives a major decision.
    2. Separate platform change from user confusion. Sometimes a model or interface has changed. In other cases, users have not yet adapted their workflow. Those situations require different responses.
    3. Turn learning into a concrete decision. Useful proximity should affect a product priority, measurement approach, technical recommendation, explanation, or partnership.
    4. Make the insight portable. Customers and readers outside San Francisco should benefit through documentation, content, tools, or clearer guidance.
    5. Check the result. The final test is whether the decision solved a real problem, not whether the original conversation sounded important.

    This is the standard worth applying to any company’s move into an industry hub. Access has value when knowledge moves outward. If the insight remains inside private dinners and event rooms, the location may strengthen a network without strengthening the work.

    A two-city company needs one clear entity story

    For anyone responsible for SEO, AEO, GEO, structured data, or digital PR, the move also illustrates a less glamorous problem: location language can create entity ambiguity. People, search engines, and language models may encounter company facts across an About page, founder biographies, job listings, interviews, directories, social profiles, press coverage, and JSON-LD. If those surfaces use location terms carelessly, they can describe different companies without meaning to.

    Keep these concepts separate:

    • Origin: where the founders met or where the company took shape.
    • Founder presence: where one or more founders spend time and participate in a community.
    • Office: an actual operational location used by the company.
    • Headquarters: the primary location the company formally identifies as its central base.
    • Service area: the markets or customers the company serves, which may have little relationship to founder residence.

    A second home can describe founder presence and community connection without settling the other four facts. Treating those terms as interchangeable creates avoidable contradictions.

    If your own company is adding a city, use a simple publishing process:

    1. Write one canonical sentence that distinguishes the company’s roots from the new presence.
    2. Use that distinction consistently on the About page, founder biographies, media materials, recruiting pages, and major social profiles.
    3. Audit address-related structured data. Do not encode a narrative connection to a city as a postal address, office, or headquarters unless that underlying fact is true.
    4. Link secondary announcements and biographies to one canonical page that explains the relationship between the locations.
    5. Review important third-party profiles for stale or overstated wording after the change becomes public.

    For CrushPress, the clean narrative is already available: New York is the founding root, and San Francisco is a second home. Future operational details can be added when they are established. That is more accurate than forcing the move into the familiar but potentially false story of one headquarters replacing another.

    Judge the move by what crosses the bridge between cities

    Anonymous teams carry glowing geometric objects in both directions across a bridge connecting an East Coast district and a hilly West Coast district.

    You do not need to guess whether the move will work. Watch the outputs that should follow if the new proximity is creating value.

    • More specific insight: Look for clearer explanations of how AI discovery, citations, brand representation, and measurement are changing. Generic enthusiasm about AI is not evidence of learning.
    • Visible transfer: Useful ideas should reach customers and readers who are not in San Francisco. Documentation, technical guidance, product decisions, and public analysis are stronger signals than event attendance.
    • Stronger collaboration: Partnerships should solve recognizable user problems or expand access to relevant expertise. A list of logos without an explained benefit says little.
    • Continuity in New York: A second home should add capacity without making the company’s original community feel like discarded history.
    • Factual consistency: Company pages, founder profiles, structured data, and third-party descriptions should agree about what each city represents.

    If you are a customer, keep your due diligence practical. Ask whether your point of contact, support process, contracting entity, billing, or data handling has changed. A founder’s location does not answer any of those questions. If you are considering a role or partnership, ask where the work happens, how often travel is expected, and where decisions are made. Those answers matter more than the broad label attached to the move.

    Key takeaways

    • San Francisco is being positioned as a second home for CrushPress, not as a replacement for its New York roots.
    • The strategic opportunity is a shorter feedback loop with people building and using AI, but location alone does not produce better outcomes.
    • The move creates value when local conversations become concrete decisions and portable knowledge.
    • A two-city narrative requires precise language across biographies, company pages, media materials, and structured data.
    • Customers should act on formal operational changes, not assumptions created by a city name.

    For now, watch what CrushPress carries from San Francisco back into its products, methods, and public guidance. That transfer – not the move by itself – will show whether the second home is becoming a strategic advantage.

    References