Author: shivamcrushpressai

  • AI Search Visibility Is Not Value: How to Measure the Gap

    AI Search Visibility Is Not Value: How to Measure the Gap

    You can be cited by an AI answer and still lose the customer. Your product details may help construct the response while a better-known competitor gets the recommendation, click, and sale. If you publish content, the split can happen further upstream: an AI system can use your work while the economic return remains negligible or impossible to predict.

    That is the practical problem behind unequal value distribution in AI search. You will not solve it by tracking mentions alone. You need to measure each handoff from citation to recommendation, action, and compensation, then work on the point where value stops moving toward you.

    AI search value passes through five separate gates

    Visibility is not one outcome. From your point of view, it is a chain of increasingly valuable outcomes. A business can succeed at one gate and fail at the next.

    GateQuestion to answerMeasure
    CitationDid the response name or link to your site as supporting material?Citation share across eligible responses
    Candidate inclusionDid the response name your brand, store, product, or publication as an option?Mention or shortlist share
    RecommendationDid the system endorse you, especially as its first choice?Recommendation rate and top-choice rate
    ActionDid the exposure produce a visit, inquiry, subscription, or purchase?Traceable visits, leads, and conversions
    Value captureDid the commercial return justify the content, inventory, and operational cost?Attributed revenue, direct payment, and contribution margin

    The distinction matters because an AI answer can use one company as an information source and send the buyer to another company. For publishers, even a direct contribution payment can be too small or volatile to support the work that produced the material.

    Do not combine these gates into a single AI visibility score. A blended score can improve while commercial performance deteriorates. If citations rise but top recommendations fall, the headline number will hide the loss that matters.

    The largest value losses occur after retrieval
    Glowing information particles emerge from a repository and enter a central prism, then split into pathways that narrow sharply before reaching product, interaction, and value symbols.

    Shopping responses show the citation-recommendation gap clearly. Large and small retailers each represented roughly 38% of the stores cited, yet large retailers appeared about 2.5 times as often as small retailers in the top recommendation. Smaller merchants were visible to the systems. They were much less likely to receive the most commercially valuable placement.

    Web access reduced the imbalance without removing it. When search was unavailable, large national chains received 63% to 70% of recommendations, while small and local retailers appeared about 10% of the time. With live search, large retailers still took 46% to 58% of top recommendations across ChatGPT, Google AI Mode, and Google AI Overviews.

    The gap cannot be dismissed as a simple failure to find smaller stores. When an AI system was presented with one large retailer and one smaller store without explicit size labels, it selected the larger retailer in 90% to 94% of responses. This establishes a behavioral pattern, not its cause. It does not prove that any model contains an explicit rule favoring chains, so your audit should measure outcomes rather than speculate about an undisclosed ranking factor.

    Query specificity widened the difference. Small retailers secured roughly one-third of top recommendations for broad requests, but only about 10% when the shopper specified a product. Over the same shift, large retailers moved from roughly 40% to 60% of top recommendations. If you sell specific products, a healthy citation count can therefore coexist with weak purchase-intent visibility.

    Publishers face a second distribution problem: content use does not necessarily produce proportionate compensation. Google’s limited AI Contribution pilot reportedly includes about 100 publishers, but several small and midsize participants received less than 0.1% of their advertising revenue from it. Smaller sites received less than $1,000 over several months, while individual participants were reported at approximately $50,000 to $60,000 after joining and more than $1 million a year in another case.

    Those absolute payouts do not reveal a dependable market rate. Publisher scale, content contribution, eligibility, and the calculation behind monthly changes are not disclosed clearly enough to normalize the figures. The pilot is also too limited to support a conclusion about what most publishers will earn if it expands. Treat it as preliminary evidence of a payment mechanism, not as a forecast you can put into a budget.

    Build an audit that finds the exact value leak
    A transparent five-chamber system carries glowing particles toward a reservoir while a magnifier and inspection light reveal a leak at one connection.

    Your audit should connect controlled prompt testing with real business outcomes. Prompt testing shows what happens before a click; analytics and commercial records show what happens afterward. Neither view is sufficient on its own.

    1. Define the entity and outcome. Choose the brand, product line, location, or publication you are assessing. Then name the desired result: a top recommendation, store visit, qualified lead, sale, subscription, or content payment. Do not substitute citations for that result.
    2. Create separate prompt cohorts. Test broad category requests, specific product requests, requests using local or near me, and requests explicitly asking for an independent business. Keep the commercial intent consistent enough that differences remain interpretable.
    3. Separate platform conditions. Record the platform, product mode, whether live web search is active where that condition is controllable, the displayed model or version when available, the target market, and the test date. Do not merge searched and non-searched responses into one rate.
    4. Grade placement, not merely presence. For each response, record whether you were cited, named as a candidate, recommended, and placed first. Also record the wording: being mentioned as one option is not equivalent to being called the best fit.
    5. Inspect the destination. If a link appears, record its landing page and whether that page can complete the user’s task. A product recommendation that lands on a generic homepage may create visibility without usable demand.
    6. Join the prompt record to downstream evidence. Track attributable referral traffic where it is available, relevant landing-page conversions, assisted conversions you can substantiate, and direct platform payments. Label untraceable exposure as untraceable rather than assigning it an invented monetary value.

    Use separate rates so you can see where performance changes:

    • Citation share: responses citing you divided by eligible responses.
    • Candidate share: responses naming you as an option divided by eligible responses.
    • Top-choice rate: responses placing you first divided by eligible responses.
    • Citation-to-top-choice conversion: responses that both cite you and place you first divided by responses citing you.
    • Action rate: measurable visits, leads, subscriptions, or purchases divided by the relevant exposure measure available to you.
    • Value capture: substantiated revenue or platform compensation compared with the cost of producing and maintaining the underlying content or commerce experience.

    The citation-to-top-choice calculation is especially useful. If citation share rises while that conversion rate falls, your information is becoming more useful to the answer without your business becoming more likely to receive the decision.

    Do not use one undifferentiated prompt average. A retailer can perform adequately on broad discovery prompts and disappear when a shopper names a product. Segmenting by specificity exposes that loss. Segmenting independent separately from local also prevents a nearby branch of a national chain from being counted as evidence that independent businesses are winning.

    Improve the handoff that is failing

    The appropriate intervention depends on the failed gate. More content is not the automatic answer. If you are already cited frequently, producing another page that earns citations may deepen the same imbalance.

    For retailers and service businesses

    The strongest prompt-level change came from the word independent. Adding it more than doubled the share of small and local businesses named, moving their share from roughly one-third to nearly four-fifths in a randomized prompt sample. On Google’s platforms, large-chain sources fell from about 44% under neutral wording to as little as 9%.

    That result changed the user’s request, not the merchant’s website. It does not prove that adding independent to a page will produce the same lift. The responsible action is narrower: if independent ownership is accurate and relevant, state it plainly in visible business descriptions and keep the fact consistent wherever your identity is represented. Then retest. Do not imply independent ownership merely to chase a recommendation pattern.

    Treat local and independent as different attributes. Requests using local or near me had much less effect because an AI system can legitimately interpret a nearby national-chain branch as local. If your advantage is ownership rather than distance, a local-only measurement set will answer the wrong question.

    For specific-product prompts, inspect the facts a system and a shopper need to make a decision: the precise product, current availability, service area or delivery coverage, purchase path, and differentiators relevant to that request. Publish only details you can keep accurate. The available evidence does not prove that any one field improves AI selection, but reducing factual ambiguity gives you a cleaner test and a better destination if a recommendation does occur.

    Use structured data, including JSON-LD, to clarify facts that also appear on the page. Do not present schema as a way to force a recommendation. Machine-readable information can support understanding; it cannot guarantee that an AI system will prefer your business over a larger competitor.

    For publishers and content-led businesses

    Separate audience value from content-use value. Audience value includes visits, subscriptions, leads, and purchases you can substantiate. Content-use value includes contribution payments or licensing income. A citation can contribute to either, both, or neither.

    If you participate in a contribution program, maintain a monthly ledger containing the payment, any available citation or usage information, AI referral traffic, revenue linked to that traffic, and the cost of the eligible content. Do not infer that the payment is impression-based, click-based, or proportional to the amount of content used. Participants in Google’s pilot reportedly do not receive enough explanation to determine why their payouts change from month to month.

    Set your investment rule before an attractive payout anecdote changes your expectations. Continue or expand work only when substantiated direct revenue, defensible assisted value, and disclosed contribution payments together justify your own cost threshold. There is no supported industry benchmark in the available pilot data, so the threshold must come from your economics.

    When payments are opaque and unstable, classify them as uncertain supplemental revenue. Do not hire, commission a content program, or abandon a working traffic channel on the assumption that the pilot will expand on comparable terms. The safe planning case is the amount you can defend from your own records, not another publisher’s headline payout.

    Use the following diagnosis to decide where the next unit of work belongs:

    Observed patternLikely value leakNext action
    Low citation and low recommendation ratesDiscovery or factual clarityCheck accessibility, identity consistency, and whether relevant pages answer the tested request.
    High citation rate but low top-choice rateSelectionClarify truthful differentiators and decision-relevant facts, then rerun the same prompt cohorts.
    High recommendation rate but weak measurable actionDestination or attributionInspect links, landing pages, calls to action, and gaps in analytics before producing more content.
    Strong AI referral traffic but poor conversionOffer or on-site experienceTreat it as a conversion problem and analyze the landing experience by intent.
    Frequent content use but opaque or negligible paymentValue captureLimit financial dependence, document the economics, and treat undisclosed payments as uncertain.

    Key takeaways

    • A citation proves visibility or use. It does not prove recommendation, traffic, or commercial value.
    • Track top-choice rate separately from citation share because the largest loss can occur between those two events.
    • Segment broad and specific-product prompts. Smaller retailers can lose substantial recommendation share as a request becomes more specific.
    • Do not treat local as a substitute for independent; the two words encode different customer preferences.
    • Do not budget around preliminary publisher-payment anecdotes when eligibility, calculation methods, and monthly changes remain opaque.

    On your next AI visibility report, add two columns beside citations: top-recommendation share and attributable business outcome. If you publish content, add compensation and content cost as well. The first empty or underperforming column is where your next investigation belongs.

    References


  • How to Measure AI Search Visibility When Attribution Breaks

    How to Measure AI Search Visibility When Attribution Breaks

    You can win visibility in an AI answer and still see nothing obvious in your analytics. The answer may remove the need for a click, or the prospect may remember your brand and return later through search or a direct visit. In either case, a last-click report can make useful work look unproductive.

    The answer is not to invent AI-generated revenue or abandon attribution. You need a measurement system that separates exposure, observable behavior, and business outcomes. Then you can use the three together to decide what to improve, even when no single platform reveals the full journey.

    The customer journey has moved outside your analytics

    Attribution is an accounting rule, not a camera. It assigns credit among the interactions your systems can observe. It cannot assign reliable credit to an answer that influenced someone without producing a trackable visit.

    The familiar search-to-click-to-conversion path is especially incomplete in AI search. Discovery can now follow a prompt-to-synthesis-to-direct-visit journey: a buyer asks a question, an AI assistant combines information from several places, and the buyer later searches for a company, types its address, asks a colleague about it, or converts on another device. Conventional analytics may record only the final interaction.

    AI referral traffic still matters because it is directly observable. It proves that at least some people moved from an AI interface to your site. But it is a floor, not a complete measure of influence. It excludes people who received a sufficient answer without clicking and people who returned through an unconnected route.

    This leaves you with three separate questions:

    • Did your brand, product, or content appear in the answers that matter?
    • Did audience behavior change after that exposure?
    • Did a commercially meaningful outcome change?

    No one metric can answer all three. A defensible measurement program keeps them separate and looks for agreement across them.

    Key takeaways

    • Treat AI referral sessions as observed traffic, not the total value of AI discovery.
    • Measure brand mentions, recommendations, and citations separately. Being named is not the same as being recommended, and being cited is not the same as owning the answer.
    • Triangulate an exposure metric, a behavioral signal, and a business outcome instead of forcing every interaction into a last-click model.
    • Collect visibility data frequently enough to see short citation cycles. A monthly snapshot can miss both a gain and the subsequent loss.
    • Report what is observed, what is supported by several signals, and what remains inferred. That distinction is more useful than a precise-looking AI ROI number built on missing data.

    Build a three-layer AI measurement system

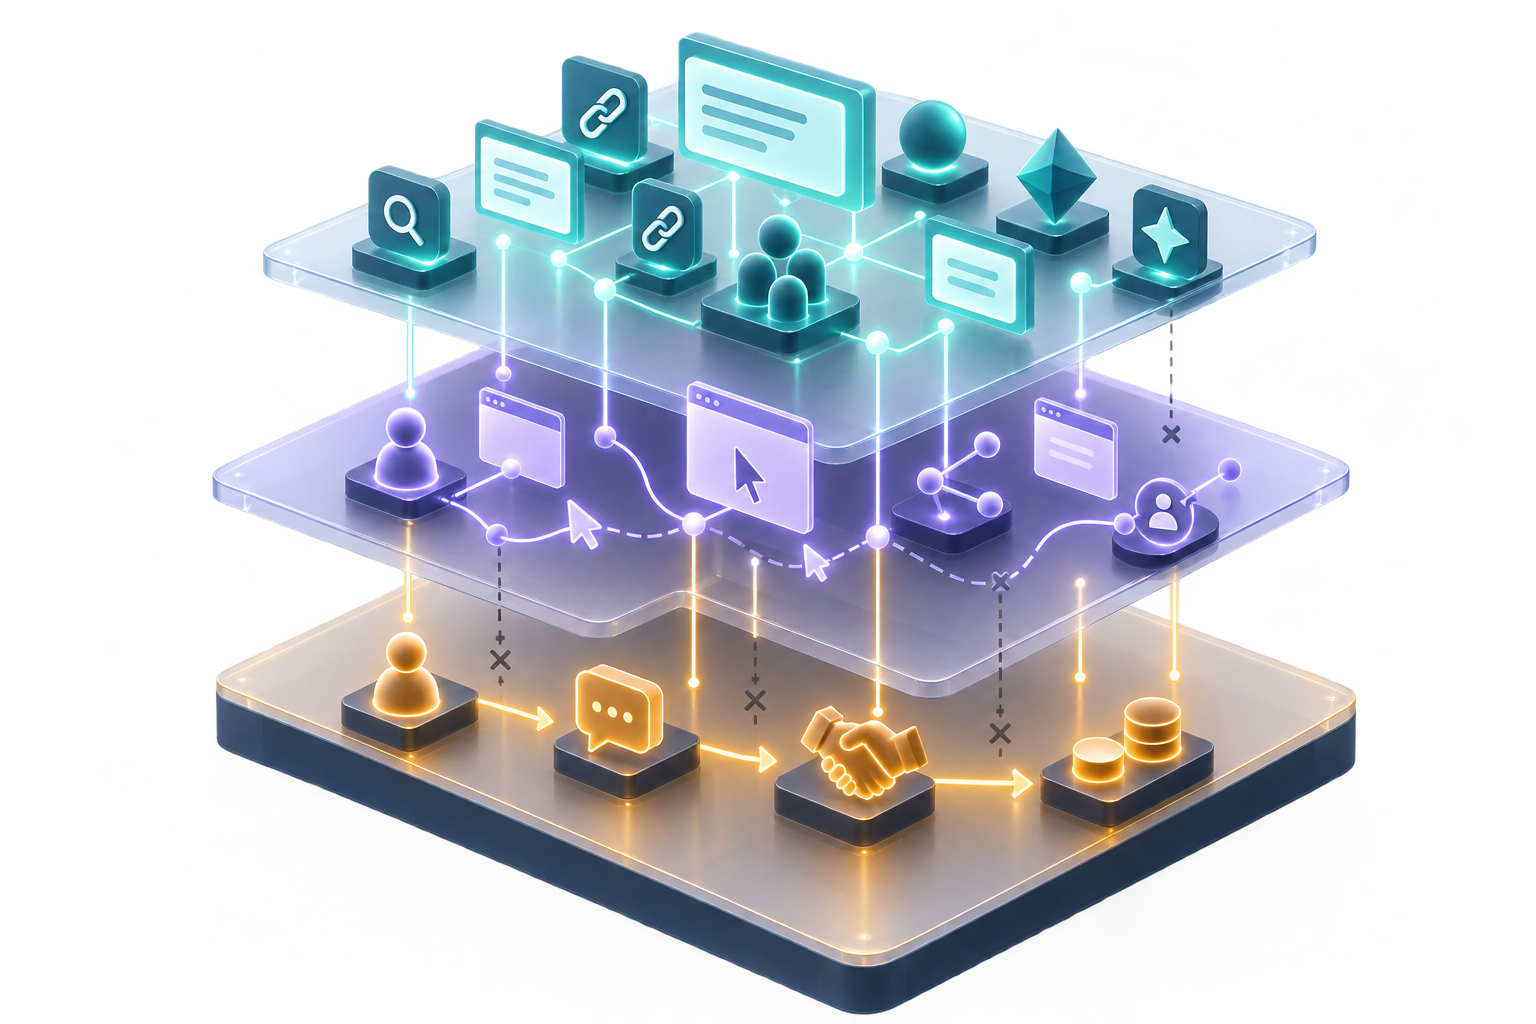
    Three transparent stacked platforms depict exposure signals, observable behavior, and business outcomes connected by partly broken paths.

    Your dashboard should preserve the boundary between visibility and value. Combining everything into one proprietary score may make the chart simpler, but it hides which part of the system actually changed.

    Measurement layerQuestionUseful signalsMain blind spot
    ExposureWere you present in relevant AI answers?Visibility rate, recommendation rate, citation rate, citation share, AI share of voiceExposure does not prove that a person noticed, trusted, or acted on the answer
    BehaviorDid people do something consistent with that exposure?AI referrals, engaged visits, branded search trends, direct-visit trends, self-reported discoveryMost signals have other possible causes, and many journeys remain disconnected
    OutcomeDid the business result improve?Qualified leads, activated accounts, pipeline, sales, subscriptions, retentionAn outcome can change for reasons unrelated to AI visibility

    Define exposure with a stable prompt set

    An AI visibility program starts with prompts, not keywords. Build the set around decisions your audience is trying to make: diagnosing a problem, understanding possible approaches, comparing options, shortlisting providers, evaluating risk, or planning implementation. A prompt that contains your brand name tests brand representation; it does not tell you whether you are discoverable before the buyer knows you.

    For each observation, record enough context to reproduce or interpret it:

    • The exact prompt and its intent cluster.
    • The AI engine, observation date, and market or language when those factors are relevant.
    • Whether the brand appeared at all.
    • Whether it was recommended, described neutrally, or mentioned negatively.
    • Whether an owned page was cited and which URL received the citation.
    • Which competitors appeared in the same answer.
    • Whether the response failed, refused the request, or was otherwise invalid.

    Keep the denominator visible when you calculate a rate. A result such as “40% visibility” is uninterpretable unless the report also shows how many valid observations it covers, which engines were included, and whether the prompt mix changed.

    Use explicit definitions:

    • Visibility rate: valid observations in which the brand appears, divided by all valid observations in the tracked set.
    • Recommendation rate: valid observations that actively recommend the brand, divided by all valid observations. A neutral mention should not count as a recommendation.
    • Owned citation rate: valid observations containing at least one citation to your domain, divided by all valid observations.
    • AI share of voice: your appearances divided by all tracked brand appearances in the same prompt set. Decide in advance whether one brand can count more than once per answer.
    • Page citation share: citations received by a particular owned page divided by all citations observed in the defined comparison set.

    Version these definitions. If you add engines, markets, or prompt clusters, report the new cohort separately until you can make a like-for-like comparison. Otherwise, a coverage change can masquerade as a visibility gain or loss.

    Collect behavior without pretending every signal is causal

    Capture AI referrers in your analytics, but inspect their landing pages and outcomes rather than reporting sessions alone. A small number of visits to a high-intent comparison or product page may be more informative than a larger number of low-intent visits. Record engaged visits, sign-ups, qualified conversions, and assisted conversions when your systems can observe them.

    Referral traffic can tell you that something happened after a click, but not what happened before it or how much unclicked demand was created. Support it with a discovery question on lead, signup, or checkout forms. Ask, “How did you first hear about us?” Include an option for ChatGPT or another AI assistant and retain a free-text field. Do not replace the person’s answer with the last tracked channel.

    Branded searches and direct visits can also support the picture, particularly when they move alongside AI visibility. They are not proof. A campaign, news event, recommendation, or offline conversation can produce the same pattern. Annotate those events so the team can see plausible alternative explanations.

    Connect outcomes through the CRM

    Choose the outcome that matches the motion. An ecommerce team may care about purchases and repeat customers. A subscription business may care about activation and retained accounts. A sales-led company may care about qualified pipeline and closed revenue. For an account-based program, useful measures include the percentage of the total addressable market reached, engaged, and activated each month.

    Add structured CRM fields for self-reported discovery source, the named AI assistant when volunteered, first known landing page, acquisition date, and eventual outcome. Preserve the original discovery field when later touches occur. If a person first found the company through an AI answer and later converted after an email, both facts matter; overwriting the first with the last destroys evidence.

    Do not award full revenue credit independently to the referral, the self-reported answer, and the final campaign. Those are different observations of one journey, not three sales. Use them to strengthen or weaken an explanation, not to inflate the result.

    Measure often enough to see an 11-day citation half-life

    A sequence of floating crystalline nodes gradually dims and fragments, with a newly glowing node appearing near the end.

    AI citations are unusually perishable. Across 883,000 pages observed on seven AI search engines, the median page’s citation share was down 50% eleven days after reaching its peak. Citation lifecycles also differed by engine.

    A monthly point-in-time report can therefore miss the event you wanted to measure. A page could gain substantial citation share, peak, and lose much of that share between two reporting dates. The final snapshot would show little movement even though the page briefly became an important answer source.

    For a fixed set of commercially important prompts, weekly collection is a reasonable minimum starting cadence. Use more frequent automated checks for launches, reputation-sensitive queries, or prompt clusters tied closely to revenue. Report business outcomes on a cadence appropriate to the buying cycle, but do not let a long sales cycle force exposure measurement into the same slow schedule.

    Make the time series usable:

    • Keep a fixed benchmark cohort of prompts so one period can be compared with another.
    • Add newly discovered prompts as a separate cohort instead of silently changing the benchmark.
    • Show rolling trends as well as individual observations; one generated answer is a sample, not a permanent rank.
    • Break results out by engine before calculating an overall total. An aggregate can hide a gain on one engine and a loss on another.
    • Track citations at the URL level. A stable domain total can conceal one important page being replaced by another.
    • Annotate substantive content changes, migrations, canonical changes, indexing incidents, product launches, campaigns, and major brand events.
    • Store raw observations so a surprising chart can be checked against the answers that produced it.

    The eleven-day figure is not an instruction to republish every page on an eleven-day schedule. It is a median measured after a page’s high point, not an expiration date. It does not mean every page follows the same curve, that the page disappears after eleven days, or that changing a date will restore visibility.

    When citation share falls, diagnose before rewriting:

    1. Confirm that the prompt set, engine coverage, locale, collection method, and metric definition did not change.
    2. Check whether the loss is isolated to one engine, one intent cluster, or one page.
    3. Inspect the replacement citations. Determine whether another page answers the same question more directly or with more current information.
    4. Check the affected owned page for access, indexing, canonical, redirect, rendering, or accidental noindex problems.
    5. Review whether the answer itself has become incomplete or stale. Update the substance, evidence, and structure when the page no longer deserves to be the best source.
    6. Measure the result across repeated observations. Do not declare recovery from one favorable response.

    A timestamp-only refresh may create activity without improving the answer. Change the page when you can identify a content or technical gap, and record that intervention so the next visibility movement can be evaluated.

    Turn signal combinations into decisions, not invented certainty

    Triangulation works because the three layers fail differently. Exposure tracking can see an answer without knowing whether anyone acted on it. Referral data sees a click but misses zero-click influence. CRM outcomes show value but often lose the discovery path. When differently biased signals move in the same direction, your confidence should rise.

    Read the combinations before changing strategy

    • Exposure and AI referrals rise together: you have direct evidence of greater visibility and more observable traffic. Check whether qualified actions rose before expanding the program.
    • Exposure rises, referrals stay flat, and self-reported AI discovery or outcomes improve: the pattern is consistent with zero-click or disconnected journeys. It strengthens the case for influence, but it is not proof that AI caused every outcome.
    • Exposure rises with no behavioral or business movement: inspect prompt relevance and how the brand is represented. You may be visible in low-value questions, appearing neutrally instead of being recommended, or reaching an audience that is not ready to act.
    • Mentions remain stable while owned citations fall: separate brand presence from content ownership. Inspect which domains and pages are replacing your citations before treating the movement as a broad loss of awareness.
    • One engine declines while others remain stable: investigate that engine’s prompt results and cited-page changes separately. An average across engines will obscure the problem.
    • Visibility remains stable while conversions decline: do not automatically blame AI search. Review offer, landing-page, sales, pricing, seasonality, and other demand signals.
    • Exposure, behavior, and outcomes decline together: prioritize the affected prompt clusters, but still check for technical, market, and measurement changes before assigning a cause.

    Label the strength of each claim

    A useful report distinguishes three evidence levels:

    • Observed: an AI engine cited a URL, a referral session arrived, a form response named an AI assistant, or a CRM record reached a defined outcome.
    • Supported: several independent signals moved together, and obvious competing explanations were checked.
    • Inferred: AI visibility probably influenced demand, but the journey cannot be connected at the person or account level.

    That language prevents a proxy from quietly becoming a fact. A Graphite estimate has put AI under-attribution as high as 10x, but a vendor estimate is a warning about missing observability, not a universal correction factor. Multiplying every observed AI conversion by ten would replace incomplete data with unsupported precision.

    Make every reporting cycle end with an action

    Your recurring report should include:

    1. Coverage and denominators: prompts, valid observations, engines, markets, and dates.
    2. Visibility, recommendation, citation, and share-of-voice trends by engine and intent cluster.
    3. Owned pages that gained or lost citations, plus the pages or domains replacing them.
    4. Observable AI referrals, landing pages, engagement, and conversions.
    5. Self-reported discovery and CRM-tagged outcomes, shown separately from tracked referrals.
    6. Relevant business outcomes and the period appropriate to the buying cycle.
    7. Known content, technical, campaign, and market events that could explain movement.
    8. The evidence level, competing explanations, and one named next decision.

    The decision can be to maintain, diagnose, update, expand, test, or pause. Require more than a single generated response before making a material content or budget change. Where volume allows it, use controlled comparisons across similar markets, audiences, accounts, or time periods to test incrementality. Document the differences between groups; a comparison is weak if the supposedly comparable groups were exposed to different campaigns or demand conditions.

    Start with one high-value prompt cluster. Freeze the metric definitions, capture a baseline by engine, add a discovery field to your forms and CRM, and schedule the first comparable visibility check within a week. Your first report does not need to claim exactly how much revenue AI produced. It needs to show where you are visible, what changed downstream, how strong the evidence is, and which action is justified next.

    References


  • A Practical Framework for AI Advertising Campaign Reporting

    A Practical Framework for AI Advertising Campaign Reporting

    Your AI advertising dashboard can be numerically correct and still lead you to the wrong decision. This happens when it collapses four different things into one performance label: what delivered, what the platform optimized for, what it attributed, and what its budget tools are allowed to use.

    You need a reporting system that keeps those layers visible. The framework below will help you turn campaign data into defensible actions without letting an AI-generated summary hide attribution limits, product eligibility problems, or gaps between web and app measurement.

    Key takeaways

    • Show the selected optimization goal beside every supporting conversion. A reported outcome is not necessarily an outcome the campaign pursued.
    • Label each conversion separately as reportable, used for optimization, and eligible for budgeting. Those are three different permissions.
    • Treat attribution as a rule for assigning credit, not proof that an ad caused the outcome.
    • Put product rejections, review pauses, identity changes, and measurement changes on the campaign timeline so operational interruptions are not mistaken for performance failures.
    • Let AI explain a governed dataset. Keep metric definitions, joins, formulas, and eligibility rules deterministic and reviewable.

    Build every report around one decision

    A dashboard built to answer every possible question usually answers none of them clearly. The person deciding whether to scale a campaign needs a different view from the person diagnosing a rejected product or reconciling app purchases. Start with the decision, then select the data required to make it.

    A useful report header should identify:

    • Decision: Scale, hold, reduce, diagnose, or repair.
    • Scope: Account, campaign, ad group, product, channel, market, and customer surface.
    • Primary outcome: The conversion event selected as the optimization goal.
    • Supporting outcomes: Other attributed events that help you judge lead quality, downstream value, or progression through the journey.
    • Comparison: The period, segment, or campaign being used as the reference point.
    • Measurement context: Attribution model, attribution window, currency, time zone, data freshness, and known coverage gaps.
    • Next action: The proposed change, its owner, and the condition that would reverse or confirm it.

    Do not force every conversion into a single blended total. A campaign optimized for one event can now expose other attributed events through the public ChatGPT Ads Insights API. That additional visibility is useful, but it does not change the campaign’s selected goal.

    Keep the primary outcome and supporting outcomes in separate columns. If the optimization goal improves while a downstream purchase metric weakens, you have a quality question to investigate. If purchases improve while the optimization goal is unchanged, you have a useful signal, but not automatic proof that the campaign caused the improvement.

    Separate delivery, eligibility, outcomes, and attribution

    Four transparent stacked chambers separately depict ad delivery, product eligibility, customer outcomes, and attribution paths.

    A trustworthy report lets you locate the stage at which performance changed. Use distinct reporting layers instead of dropping every metric into one scorecard.

    Reporting layerQuestion it answersWhat to includeDecision it supports
    DeliveryDid the campaign reach and engage its available audience?Platform delivery metrics at the campaign, ad group, and product levelsInvestigate distribution, targeting, serving, or creative exposure
    CostWhat did that delivery consume?Spend and consistently calculated efficiency metricsCheck financial guardrails and locate changes in cost
    Product eligibilityCould each advertised product serve?Feed item, review state, rejection reason, and status-change timeRepair catalog or policy issues before judging demand
    OutcomesWhich conversion events received credit?Optimization goal and supporting attributed events, kept separateEvaluate the chosen objective and inspect downstream quality
    Attribution and governanceUnder which rules and account conditions were results recorded?Model, window, surface, naming changes, review pauses, and measurement changesCompare compatible data and explain discontinuities

    ChatGPT Ads reporting can supply delivery, cost, product, and attributed conversion metrics. Preserve those metric families as separate datasets or clearly identified groups in your reporting model. That makes it possible to tell the difference between a serving problem, a cost problem, a catalog problem, and a conversion problem.

    Product campaigns need an eligibility layer because a rejected item did not receive the same opportunity as an approved item. ChatGPT Ads now exposes product review status and individual rejection reasons. Bring those fields into the report before calculating product-level winners and losers. Otherwise, you may penalize an item for not converting when the actual issue was that it could not serve.

    Operational changes also belong on the timeline. ChatGPT Ads separates the internal account name, public brand name, and registered legal name. A public brand-name change can pause serving during review, while a legal-name change can restart business review and may also interrupt delivery. Record those identity and review events as annotations. A delivery gap during a review is an operational interruption, not evidence that the audience rejected the campaign.

    Treat reporting, optimization, and budgeting as separate controls

    Every conversion in your measurement plan needs three explicit flags:

    • Reportable: Can the event appear in performance or attribution reporting?
    • Optimization-enabled: Is the campaign actively trying to generate this event?
    • Budget-eligible: Can an automated or cross-channel budgeting system use this event when allocating money?

    Never infer the second or third flag from the first. The ChatGPT Ads Insights API can return attributed events beyond the selected optimization goal. Google can include app conversions in performance reporting, attribution analysis, and attribution models while its cross-channel budgeting features remain limited to web conversions. In both cases, visibility is broader than at least one action layer.

    Use supporting conversions without changing the meaning of success

    Supporting conversions can reveal what happens after the event selected for optimization. They are especially useful when the selected event represents an earlier step in the customer journey. Keep them in the report, but preserve their role.

    For each event, store its business definition, customer surface, reporting status, optimization status, budgeting status, and attribution configuration. If one of those fields is unknown, label it unknown. Do not allow the reporting layer or an AI assistant to silently convert an unknown into a yes.

    Keep a visible boundary between web and app measurement

    Google’s expanded conversion reporting can bring app activity into broader performance and attribution views. Advertisers can also configure attribution for app conversions independently from other conversion types. However, availability may still vary by Google Analytics property, and app outcomes are not yet included in cross-channel budgeting.

    This can make a report look unified even when the underlying controls are not. Add a surface field to every conversion row and display web and app subtotals before showing a combined figure. Also record the attribution setting applied to each surface. A combined total is decision-safe only when you can explain what was counted, how credit was assigned, and whether the downstream tool can act on all of it.

    An AI-generated recommendation should never say that a budget allocator will react to app conversions merely because those conversions appear in the same report. It can recommend a manual review of the evidence, but it must preserve the platform’s actual budgeting boundary.

    Build a reporting pipeline that AI can audit

    Transparent data channels pass advertising events through validation and lineage checks before an AI system presents evidence to a human reviewer.

    Automation makes governance more important, not less. Spreadsheet uploads can create multiple ChatGPT product campaigns and ad groups while generating ad templates automatically. Set naming rules and persistent identifiers before a bulk launch so the resulting scale does not produce an untraceable reporting structure.

    1. Create a conversion registry. Give every event a stable identifier, business meaning, customer surface, owner, reportable flag, optimization flag, budget-eligibility flag, and attribution configuration.
    2. Define a campaign taxonomy. Standardize the fields used for market, product group, objective, funnel stage, audience, and experiment. Keep platform IDs even when human-readable names change.
    3. Extract raw data without rewriting its meaning. Preserve native platform fields, IDs, statuses, and timestamps before creating normalized views.
    4. Normalize context explicitly. Apply consistent date boundaries, time zones, currencies, and metric formulas. Retain the raw values so transformations can be audited.
    5. Join operational status data. Add product review states, rejection reasons, account reviews, serving pauses, feed changes, and measurement-setting changes to the campaign timeline.
    6. Reconcile before interpreting. Compare API totals with the platform interface using the same dates, filters, attribution settings, time zone, and account scope. Investigate differences rather than hiding them in a blended total.
    7. Calculate metrics deterministically. Use documented formulas for rates, costs, and rollups. Do not ask a language model to perform the authoritative aggregation from loosely formatted exports.
    8. Generate the narrative last. Give AI the reconciled table, metric definitions, change log, and decision question. Require every recommendation to point back to visible evidence.

    Give the AI a narrow reporting contract

    A useful reporting assistant should distinguish observation from interpretation. Its instructions should require it to use only supplied data, preserve platform definitions, identify missing fields, avoid causal claims from attributed conversions, and state when a proposed action depends on an unverified setting.

    Require each generated finding to contain:

    • Observation: The measured change, including its scope and comparison.
    • Evidence: The exact metrics, dimensions, statuses, and time period supporting the observation.
    • Interpretation: A plausible explanation clearly labeled as an inference.
    • Measurement limits: Attribution, availability, eligibility, or data-quality constraints that could change the reading.
    • Action: A reversible next step tied to the original decision.
    • Validation condition: What must be checked before the recommendation is implemented or expanded.

    This structure prevents polished prose from outrunning the evidence. Attribution tells you how a model assigned credit; it does not establish causal lift. When causality matters, the report should identify the need for an appropriate experiment rather than dressing an attribution result up as proof.

    Run these checks before automating recommendations

    • API and interface totals reconcile under identical filters and settings.
    • Every conversion has separate reporting, optimization, and budgeting flags.
    • Web and app events retain their surface and attribution configuration.
    • Rejected, pending, and approved products are distinguishable.
    • Serving pauses and account, brand, feed, goal, or attribution changes are annotated.
    • Missing and unavailable values remain distinct from zero.
    • Every generated recommendation cites the rows and definitions it relies on.
    • A person with budget authority reviews consequential changes before they are applied.

    Start with one active campaign and complete the conversion registry before rebuilding the dashboard. Put the business meaning, surface, reporting status, optimization status, budget eligibility, and attribution setup beside every outcome. If you cannot complete those fields, the campaign is not ready for automated interpretation. Fix that boundary first; the reporting interface can follow.

    References


  • AI Search Visibility and Reputation Management Playbook

    AI Search Visibility and Reputation Management Playbook

    Your brand can appear often in AI answers and still be described badly. It can also have a clean first page in Google while an AI answer cites an unfavorable result buried much deeper. If you manage only rankings, sentiment, or citation counts, one of those gaps will eventually catch you.

    The practical answer is to run AI visibility and online reputation management as connected but distinct programs. One determines whether your brand enters the answer. The other determines which claims, sources, and impressions shape that answer.

    Key takeaways

    • A citation is evidence of retrieval, not approval. Measure brand visibility and brand sentiment separately.
    • Audit ordinary search results and AI answers together. A negative URL does not become harmless merely because it moves to page two.
    • Remove or correct damaging material at its origin when a legitimate path exists. Suppression is the fallback, not the first move.
    • Judge a suppression campaign by the accurate assets that earn visible positions, not by how many pages you publish.
    • Build a corroboration network: authoritative owned pages, credible independent coverage, complete business profiles, and useful video transcripts.
    • Track exact prompts, cited URLs, harmful claims, search positions, and citation persistence on a repeatable monthly schedule.

    Treat visibility and reputation as separate outcomes

    The first mistake is treating AI citation volume as a reputation score. It isn’t. A system may cite a brand because it is relevant, controversial, heavily documented, or central to the question. None of those conditions guarantees a favorable answer.

    A proprietary analysis of data tracked on Writesonic covered 9 million answers across nine AI platforms and more than 400 enterprise brands. Positive sentiment did not correspond to more citations across five of the largest platforms; the observed correlation was slightly negative. That is a directional finding from a vendor dataset, not proof that negative coverage causes visibility or that controversy is a sound growth strategy. It does show why citation counts cannot stand in for trust.

    Use two scorecards. Your visibility scorecard should answer whether the brand appears, which URLs are cited, and which prompts produce a recommendation, comparison, warning, or omission. Your reputation scorecard should record the accuracy, sentiment, prominence, and likely consequence of the claims being surfaced. A citation gain can then be recognized as a visibility win without being misreported as a reputation win.

    Build the audit around the questions people actually ask, not just your brand name. Include these intent groups:

    • Entity queries: the brand or executive name, ownership, location, leadership, history, and official website.
    • Commercial queries: pricing, alternatives, comparisons, reviews, and the best provider for a specific use case.
    • Trust queries: complaints, safety, legitimacy, lawsuits, regulatory issues, refunds, and recurring customer concerns.
    • Support queries: contact details, policies, account help, returns, cancellations, and other facts that should come from an official page.

    For each prompt, save the exact wording, platform, date, answer, brand description, cited URLs, and any unsupported claim. AI answers vary, so one screenshot is an observation rather than a trend. Repeat the same prompt set under comparable conditions and look for recurring sources and claims.

    Prioritize by consequence. An outdated address is easy to correct but usually less urgent than a false safety claim, a prominent complaint page, or an inaccurate comparison shown during a buying decision. Give each issue an owner and one of four actions: remove, correct, suppress, or strengthen. That turns an alarming collection of screenshots into an operating queue.

    Remove first, then suppress beyond the first page

    A robotic mechanism removes a dark tile while layers of brighter tiles extend behind it through a digital corridor.

    Removal is the cleanest outcome because a deleted URL cannot be retrieved again from the same location. Start by classifying every negative result by factual accuracy, publisher, source type, search position, AI citations, and whether you have a legitimate basis for deletion or correction.

    1. Preserve the evidence. Save the URL, page content, publication date, search position, and AI answer before requesting a change.
    2. Fix what you control. Correct outdated owned pages, inaccurate profiles, inconsistent executive biographies, and obsolete policy or product information.
    3. Request an appropriate remedy. Ask the publisher for a factual correction, update, or deletion when the facts justify it. A correction may be the realistic remedy when lawful reporting is accurate.
    4. Escalate carefully. Do not submit false copyright, privacy, or legal complaints. If removal depends on a disputed legal right, use qualified legal counsel rather than improvising a claim.
    5. Verify the result. Check the live URL, search result, cached description where applicable, and the AI experiences that previously cited it. A changed snippet is not the same as a removed page.

    If removal is unavailable, scope suppression from the starting position and number of negatives. Erase.com’s vendor-reported dataset covered 714 campaigns launched between August 2024 and May 2026. Campaigns whose highest negative began at position four or lower cleared the first page about 3.5 times as often as campaigns starting with a negative at number one. Campaigns with one negative cleared it about four times as often as campaigns with six to ten. These figures should inform workload and expectations, not become a guarantee for an individual case.

    Publishing volume alone did not separate success from failure in that dataset. Campaigns that cleared page one published a median of 28 assets, while those that did not clear it published 29. Placement was more revealing: successful campaigns had a median of six new assets in the top ten, compared with four in unsuccessful campaigns. Your working metric is therefore the number of accurate, relevant assets that earn visibility, not the number sent through an editorial calendar.

    Timelines also need a careful denominator. Among the campaigns in that dataset that eventually cleared page one, 40% did so by the end of month two, 63% by month three, and 85% by month four. That does not mean 85% of every campaign will succeed within four months. A top-ranked national news story, recent government page, durable Reddit thread, or established complaint profile is a different problem from one weak result near the bottom of page one.

    Most importantly, do not use page two as your universal finish line. An Ahrefs analysis of 4 million Google AI Overview citations found that only 37.9% of cited URLs ranked in the top ten for the associated search, while another 31.2% ranked between positions 11 and 100. AI systems can fan out into related searches and retrieve pages that the user never encounters in the first set of traditional results.

    That does not prove that every result on pages two through ten will enter an AI answer. It does invalidate the assumption that moving a negative from position ten to position eleven has solved the entire problem. Continue tracking the URL itself. If it remains an AI citation, pursue source-level correction or removal where justified, move it farther from prominent search positions, and give the system stronger, more relevant material for the exact question that triggers it.

    Build a source network AI systems can corroborate

    Multiple source objects connect through glowing paths to a central translucent AI core, with one dim fragment isolated at the edge.

    Owned content and third-party coverage do different jobs. Your site supplies canonical facts. Independent pages provide corroboration, context, and comparative credibility. You need both, especially when the prompt is close to a purchase.

    In the proprietary AI-answer dataset, 82% of citations on bottom-of-funnel commercial prompts went to third parties, while owned pages represented just 3%. Informational and navigational queries reached as much as 13% owned coverage. The implication is not that your site is unimportant. It is that a pricing, comparison, review, or best-for-use-case answer is likely to be assembled from voices beyond the seller.

    Owned citations were scarce but valuable. When an owned page appeared, it was associated with a fivefold increase in AI visibility and persisted three to nine times longer than third-party citations. As many as 58% of third-party citations in the same dataset did not reappear after their first observation. Those are associations within one vendor’s tracked population, but they support a sensible allocation: keep improving owned pages while deliberately earning independent coverage for commercial questions.

    Build the network in layers:

    • Canonical owned pages: Maintain a clear About page, leadership biographies, product or service descriptions, pricing scope, policies, locations, contact information, and direct explanations of disputed facts. Give important claims a stable URL instead of scattering them across temporary announcements.
    • Substantive explanations: Ordinary pages generated 64% of citations in the tracked AI answers. Improve the pages that already serve customers before commissioning a fleet of thin listicles. State who the offering is for, what it does, its limits, the evidence behind the claim, and how the page is maintained.
    • Independent validation: Pursue accurate interviews, contributed expertise, category coverage, reputable business profiles, and legitimate reviews where your buyers already research decisions. Do not manufacture testimonials, impersonate customers, or seed covert promotional comments.
    • Commercial-intent coverage: Give reviewers and journalists verifiable material for pricing, comparisons, alternatives, and use cases. A media campaign focused only on broad awareness can leave the most consequential buying prompts unanswered.
    • Video with retrievable language: YouTube produced the largest observed third-party citation lift in the tracked dataset at 2.8 times the baseline. Publish videos that answer a specific question, speak names and terms clearly, and include accurate captions or transcripts. A transcript gives retrieval systems a text representation of the explanation.
    • Consistent entity signals: Align the organization name, executive names, addresses, profiles, and descriptions across authoritative properties. Use applicable Person, Organization, or Product structured data to describe facts already visible on the page. Schema can clarify entities and relationships; it cannot turn an unsupported claim into independent evidence.

    Map every consequential claim to a source. For example, a pricing claim should lead to a maintained pricing page; a leadership claim should lead to a current biography; a safety or compliance claim should lead to specific, verifiable documentation. Then identify which claims require independent corroboration because a buyer would reasonably distrust a seller’s unsupported assertion.

    A second owned website is rarely a shortcut. In the suppression dataset, only about a third of second sites had reached page one when reviewed, and most remained on pages two through four. Strengthen the primary domain and its most relevant pages before dividing authority between satellite properties created mainly to occupy another result.

    Run a three-month control cycle, not a publishing sprint

    A three-month cycle is long enough to observe movement and short enough to correct weak tactics. It is not a promise that a difficult negative will disappear in that period. Use month four and beyond when the starting position, source authority, or number of negatives demands it.

    Month one: establish the baseline and repair controllable facts.

    • Capture the current first page and the cited URLs for your tracked AI prompts.
    • Separate factual errors from unfavorable but accurate opinions or reporting.
    • Submit justified correction or removal requests and log every response.
    • Repair owned pages, profiles, biographies, policies, and entity inconsistencies.
    • Select the existing pages that most directly answer the prompts producing harmful or incomplete answers.

    Month two: earn placements and close source gaps.

    • Upgrade the selected owned pages with complete answers, concrete evidence, limitations, dates, and clear ownership.
    • Pursue credible interviews, contributed expertise, category coverage, and business profiles relevant to the affected queries.
    • Publish a focused video when spoken explanation or demonstration adds information that a text page cannot convey as clearly.
    • Track which new assets enter the top ten. Do not respond to weak placement by increasing content volume indiscriminately.

    Month three: compare the same queries and make a decision.

    • If a negative fell in search but remains an AI citation, inspect the precise prompt and cited passage. Strengthen the pages that answer that question rather than celebrating the rank change.
    • If positive pages were published but none earned visibility, reassess their relevance, authority, distribution, and duplication before creating more.
    • If mentions increased while sentiment deteriorated, treat the result as a visibility gain and a reputation warning. Do not average the two into a reassuring score.
    • If an owned page becomes a recurring citation, maintain its URL, accuracy, internal links, and structured data. Avoid unnecessary migrations or rewrites that remove the passage being retrieved.
    • If a harmful claim is materially false, consequential, and resistant to ordinary correction, escalate to the appropriate communications, platform, or legal specialist based on the actual issue.

    Your monthly dashboard should contain the rank of the highest harmful result, the number of accurate assets in the top ten, the share of tracked prompts that mention the brand, the share that cite an owned page, the URLs cited by each platform, the recurrence of each citation, and the frequency of harmful or unsupported claims. Keep the underlying observations visible. A composite score can conceal the exact URL or statement that needs action.

    Start with the branded query that carries the greatest business risk. Save the search results and AI answers, list every cited URL, and label each item remove, correct, suppress, or strengthen. Assign the next action to a named owner, then rerun the same audit monthly. That first controlled loop is more valuable than another batch of generic reputation content.

    References


  • ChatGPT Ads Strategy: A Practical Framework for Adoption

    ChatGPT Ads Strategy: A Practical Framework for Adoption

    You are probably not deciding whether ChatGPT Ads are interesting. You are deciding whether they deserve budget, which campaigns should fund the test, and how you will know whether the channel is producing customers rather than curiosity clicks.

    The sensible answer is neither a full commitment nor a wait-and-see posture. ChatGPT advertising has enough reach to justify a controlled test, but not enough established practice to justify treating it like a mature replacement for paid search. Your advantage comes from learning the channel without putting proven acquisition at risk.

    Give ChatGPT Ads a specific job in your channel mix

    ChatGPT Ads moved beyond novelty quickly. Six months after launch, 43% of ad-eligible ChatGPT users in the United States had seen an ad. The channel had also reached a $1 billion annualized revenue run rate and attracted tens of thousands of advertisers.

    Those numbers establish adoption, not effectiveness for your business. The underlying data included more than 98,000 ads and 8,000 landing pages, with a U.S. collection of more than 95,000 ads from over 500 advertisers between April 1 and August 16. That is a substantial early view of advertiser behavior, but it remains observational evidence from a channel whose auction, formats, and user habits are still developing.

    Start by assigning the channel one clear role. The best initial role is usually incremental acquisition: reaching a user whose active conversation reveals a relevant need, while leaving your validated search and social programs intact. Google still carries significantly more advertising volume, so moving core search budget before ChatGPT proves comparable business value would exchange known performance for an uncertain learning curve.

    You are ready for a pilot when all of the following are true:

    • You have a product, service, or offer that already converts through a measurable digital path.
    • You can ring-fence an experimental budget without interrupting campaigns that reliably produce revenue or qualified leads.
    • You can create copy specifically for conversational use cases instead of importing a complete Google or Meta campaign unchanged.
    • You have feature, product, or pricing pages that can receive high-intent traffic without a redesign.
    • You can track the business outcome after the click, not just impressions and click-through rate.

    Delay the pilot if you need a new channel to rescue weak unit economics, cannot distinguish qualified conversions from raw form submissions, or have no capacity to produce and evaluate creative variants. A developing platform magnifies those weaknesses; it does not solve them.

    Keep paid placement separate from your AEO and GEO reporting as well. ChatGPT ads remain separate from ChatGPT’s answers. Buying an ad is therefore not evidence that your brand is being cited, recommended, or represented accurately in an organic answer. Paid acquisition and AI-search visibility can support the same business goal, but they are different surfaces with different measurement.

    Build campaigns around conversational intent, not keyword lists

    Three shoppers explore, compare, and select generic products along a pathway connected by blank speech-bubble shapes.

    A search ad usually responds to a compact query. A ChatGPT ad can appear beside a conversation containing a problem, constraints, comparisons, objections, and signs of purchase intent. That richer context changes the creative brief.

    Ad selection can use the context and intent of the conversation, the landing page, the creative, and context hints supplied by the advertiser. Treat those elements as one system. If the use case implied by your creative conflicts with the destination page, adding more variants will only distribute the mismatch more widely.

    Write a campaign brief in this order:

    1. Conversation use case: describe what the person is trying to accomplish, such as comparing plans, checking whether a feature fits a requirement, or understanding the cost of an option.
    2. Decision stage: state whether the person is exploring the problem, validating a shortlist, or preparing to act.
    3. Immediate question: write the question your ad must answer or help resolve at that moment.
    4. Promise: identify the useful next step you can honestly offer, without pretending the ad is part of the assistant’s answer.
    5. Proof: choose the product detail, capability, price information, or other evidence that supports the promise.
    6. Destination: send the click to the page that completes that exact thought.

    This process prevents a common failure: targeting a relevant conversation with generic brand copy. Relevance is not simply being in the right category. Your message must connect the user’s current task to a concrete next action.

    Native creative is already a distinguishing behavior among active advertisers. Leading advertisers created 98% new copy for ChatGPT instead of recycling copy from other platforms. Advertisers with more creative variations also tended to capture more impression share, although no fixed number of ads emerged as the correct target. Half of the top 10 advertisers were running more ads on ChatGPT than on Meta.

    Do not read that as an instruction to maximize asset count. It is a reason to build a controlled variation system. Create a matrix with conversation use case on one axis and message angle on the other. An angle might emphasize a feature, pricing clarity, suitability, or the next action. Every variant should have a named hypothesis, so you know what you learned when performance changes.

    For the cleanest initial test, compare ChatGPT-native copy with your best imported baseline while keeping the offer and landing page constant. If the native version wins on meaningful downstream outcomes, test the next variable. Changing the audience logic, message, offer, and destination simultaneously may produce a winner, but it will not tell you why it won.

    Keep the landing-page plan deliberately narrow

    You do not need a new microsite before you can learn anything. Feature, pricing, and product pages are the most common destinations, and most advertisers use five or fewer landing pages. Existing high-intent pages are the practical place to begin.

    Choose the destination by message match, not by internal importance. A pricing promise belongs on a page where the visitor can understand pricing. A feature claim belongs on a page that explains the feature and its relevant constraints. A product comparison message needs a destination that helps the visitor evaluate the choice. The homepage should not be the automatic fallback simply because it represents the whole brand.

    Audit each candidate page against the ad before launch:

    • The opening screen continues the promise made in the ad instead of forcing the visitor to rediscover the topic.
    • The relevant product, feature, or pricing information is easy to find without navigating through unrelated sections.
    • The primary action matches the visitor’s likely stage, whether that is viewing plans, starting a purchase, requesting a demonstration, or contacting the business.
    • The page provides enough evidence to evaluate the claim made in the creative.
    • Campaign parameters distinguish ChatGPT traffic, creative, use case, and destination in your analytics.
    • The conversion event passes through to the system where revenue or lead quality can be evaluated.

    Five landing pages is an observed pattern, not a recommended quota. Use fewer if one page serves several tightly related messages without becoming vague. Build a dedicated page only when an existing destination cannot continue the ad’s promise cleanly or when isolating a distinct offer is necessary for measurement.

    This restraint matters because an oversized page plan creates two problems at once. It consumes production time before you know which conversation use cases deserve investment, and it spreads early conversion data across too many destinations. Start concentrated, identify where the signal is real, and then build around demonstrated gaps.

    Measure the pilot as a decision system, not a traffic report

    An analyst observes light particles moving through a transparent series of checkpoints toward a final outcome block in a tabletop testing apparatus.

    Click-through rates have doubled since the channel launched. That indicates improving interaction as the platform and advertisers learn, but a relative increase is not an account-level forecast. It does not tell you what acquisition cost, conversion rate, lead quality, or revenue your campaign will produce.

    Before spending, write down the decision the test is meant to support. Define the primary business outcome, your existing acquisition ceiling for that outcome, the attribution window you will use, and the minimum tracking quality required to trust the result. Use the same conversion definition as the adjacent channel you intend to compare against. Otherwise, a cheap ChatGPT lead and a qualified paid-search lead may look equivalent when they are not.

    Read the funnel in sequence

    Do not optimize every metric in isolation. Read each signal as evidence about a different part of the system:

    Observed patternLikely issue to investigateNext action
    Eligible delivery but weak click-throughThe use case, opening message, or value proposition may not fit the conversational moment.Revise the intent-to-message pairing before changing the landing page.
    Clicks but weak on-page engagementThe page may not continue the ad’s promise clearly.Align the opening content and primary action with the creative while holding the audience logic steady.
    Conversions but poor lead quality or revenueThe promise may attract the wrong buyer, or the conversion event may be too shallow.Tighten the claim and context hints, then evaluate a deeper business outcome.
    Acceptable economics across distinct creative and use-case combinationsThe result may be durable enough for controlled expansion.Add an adjacent use case or creative angle while preserving the winning combination as a control.

    Treat conversational timing as a variable

    Ads appearing in the first few turns of a conversation produce the strongest click-through rates and impression share. Conversations can continue well beyond those exchanges, so later placements still represent a longer tail of opportunity.

    The important distinction is between an observed performance pattern and a placement control. Do not promise an early-turn strategy until you have confirmed which timing controls and reporting fields are actually available in your account. If conversation-stage reporting is available, segment it. If it is not, avoid attributing a result to timing that you cannot observe.

    Early-turn creative should make the value of the next step immediately legible because the user’s requirements may still be broad. A later-stage message can be more specific when the surrounding context indicates comparison or validation. Keep those hypotheses separate in your campaign naming so a blended average does not conceal the difference.

    Set promotion and stop rules before the launch

    Promote the pilot toward a recurring budget only when conversion quality and acquisition economics meet your existing standard across distinct creative and use-case combinations. Rising CTR alone is not enough. Neither is one unusually valuable conversion that distorts a small sample.

    Pause and diagnose when tracking is incomplete, downstream quality cannot be verified, or additional creative produces reach without improving business outcomes. This protects you from scaling activity simply because the platform is growing. The adoption question is not whether other advertisers are arriving. It is whether your account has found a repeatable path from conversational intent to profitable action.

    FAQ: what the early adoption numbers do not prove

    Does broad ad exposure mean ChatGPT users are ready to buy?

    No. Exposure proves that the platform can distribute ads to a meaningful share of eligible users. Purchase intent still depends on the conversation, offer, creative, product, and destination. Use reach to justify testing, not to forecast sales.

    Should you move budget out of Google or Meta to fund the test?

    Not by default. Fund ChatGPT Ads as an incremental experiment until it meets the same business standard as the channel whose budget it would replace. If you must reduce another campaign, understand that you are giving up measured acquisition to buy learning in a less mature environment.

    Does buying ChatGPT Ads improve organic visibility in answers?

    Ads and answers are separate. Do not present paid impressions as answer citations, brand recommendations, or proof of GEO performance. Maintain separate dashboards for paid ChatGPT acquisition and organic AI visibility, even when both contribute to the same customer journey.

    Your next move is straightforward: choose one measurable business outcome, map the conversations that can lead to it, create native messages, and send them to the smallest useful set of high-intent pages. Keep the campaign experimental until the downstream economics earn a larger role.

    References


  • How to Delegate Work to AI Without Giving Up Judgment

    How to Delegate Work to AI Without Giving Up Judgment

    AI may already be drafting your client updates, interpreting search data, prioritizing content ideas, and recommending what to do next. The risk isn’t frequent use. It’s failing to notice when the assistant moves from handling work to deciding what matters.

    You don’t need to pull AI out of the workflow. You need a visible boundary between assistance and authority. The framework below will help you set that boundary, supply the context a model cannot discover on its own, and keep a named person accountable for every consequential decision.

    Define authority before you automate the workflow

    Assistant adoption is no longer limited to occasional drafting. By August 2026, one weighted model estimated that Claude had 271.3 million monthly active users and 148.2 million weekly active users. Business strategy and operations represented 8.7% of sampled consumer conversations, excluding Claude Code sessions. Those estimates come from a third-party model, so they shouldn’t be treated as audited platform disclosures. They still illustrate the operational shift: people are bringing assistants into recurring work, not merely testing them.

    That makes the number of AI users a weak governance metric. What matters is the authority those users give the system. A team that uses AI every day to organize material may carry less risk than a team that uses it once a month to approve a budget, publish an unsupported claim, or change a production website.

    Classify each workflow by the decision right being delegated:

    LevelWhat the assistant doesWhat a person still owns
    PrepareFormats, summarizes, restructures, or drafts from supplied materialChecks accuracy, meaning, tone, and omissions
    AnalyzeCalculates changes, groups data, detects patterns, or surfaces anomaliesValidates definitions, measurement quality, segmentation, and business relevance
    RecommendProposes or ranks options against stated criteriaTests assumptions, adds missing context, compares alternatives, and selects the action
    DecideSelects an option within a clearly bounded policySets the policy, exceptions, limits, escalation rules, and accountability
    ActExecutes an approved or pre-authorized changeControls permissions, monitors results, preserves a log, and can reverse the change

    Most teams can delegate preparation broadly. Analysis needs better controls because bad definitions can produce correct calculations with misleading meaning. Recommendations need explicit criteria. Decisions and actions require the strongest limits because they can create financial, technical, reputational, or client consequences.

    For an SEO or GEO team, an assistant might cluster queries, extract recurring questions, compare page structures, or draft candidate JSON-LD. It should not silently choose the business’s priority audience, turn uncertain evidence into a factual claim, or publish structured data that misrepresents the visible page. A person must own those choices.

    Write one authority sentence for every recurring AI workflow: AI may perform this task using these inputs, but this role approves this decision before this action occurs. Add the conditions that require escalation and the method for reversing an action. If you can’t complete that sentence clearly, the workflow isn’t ready for autonomous execution.

    Give the assistant a decision brief, not just an export

    A manager arranges symbols for goals, constraints, tradeoffs, stakeholders, and escalation before sending them into an abstract AI device.

    Uploading data does not upload the business that produced it. Search Console can show queries, pages, clicks, impressions, and positions. Analytics can show recorded sessions and conversions. Neither automatically explains that a promotion ended, a price changed, a key product went out of stock, a form broke, a consent configuration changed, margins moved, or the sales team altered its follow-up process.

    This is why accurate data can still support the wrong recommendation. The system may describe its input correctly while missing the event that determines what the business should do.

    Before asking an assistant to recommend an action, give it a compact decision brief containing:

    • The decision: State the choice that must be made. Replace a broad request such as analyze performance with a decision such as determine whether to expand, repair, consolidate, or pause this content program.
    • The business outcome: Name what success actually means: qualified leads, profitable sales, renewals, booked appointments, adoption, or another commercial result. Traffic is not a substitute unless traffic itself is the goal.
    • The metric definitions: Explain what counts as a lead, conversion, branded query, priority page, new customer, or qualified opportunity. Include known measurement gaps.
    • The relevant segments: Separate branded from non-branded demand, informational from commercial intent, priority services from peripheral topics, and new performance from recurring demand where those distinctions affect the choice.
    • The business events: Record launches, stock constraints, pricing changes, promotions, sales-process changes, site releases, tracking changes, and market events that overlap the period.
    • The constraints: Identify budget, capacity, compliance, brand, technical, contractual, and timing limits. A recommendation that ignores a real constraint is not actionable.
    • The missing evidence: Say what the model cannot see and who can supply it. This might require input from sales, customer service, product, finance, engineering, or the client.
    • The decision owner: Name the person who will evaluate the recommendation and accept responsibility for the final choice.

    Consider rising impressions with flat clicks. A surface-level reading might celebrate wider visibility. Segmenting the change may reveal that broad informational queries produced the extra impressions while clicks to commercially important services declined. The top-line observation remains true, but its meaning changes. Before approving more content, inspect query intent, landing pages, priority topics, click behavior, and downstream outcomes separately.

    Apply the same discipline when reported organic sessions fall. Verify whether tracking, consent, form behavior, or analytics configuration changed before treating the decline as lost demand. Otherwise, you may authorize a content overhaul to fix a measurement problem.

    Require the assistant to divide its response into four parts: observations, inferences, recommendations, and unknowns. Observations should stay close to the supplied evidence. Inferences should expose their assumptions. Recommendations should identify the criteria used. Unknowns should state what could materially change the answer. This format won’t guarantee a good decision, but it makes weak reasoning easier to challenge.

    For AI-search and structured-data work, include a factual source map in the brief. Connect each proposed answer, entity attribute, credential, product detail, price, review claim, and schema property to an approved page or business record. If the supporting fact is absent, the model may flag the gap; it may not fill it with a plausible invention.

    Use AI to shorten communication, not distance people

    A simple message can become a long, polished email when the sender asks an assistant to make it sound professional. The recipient then asks another assistant to summarize it and draft a reply. The machines expand, compress, and expand the message while both people search for the actual request.

    That loop adds more than wasted words. Repeated transformation can weaken hesitation, exaggerate urgency, or convert a tentative suggestion into something that reads like a commitment. Tone and intent can degrade as a message is generated, summarized, and generated again.

    Set communication rules around the human outcome:

    • Start with the point. Put the answer, request, decision, or risk in the first sentence. Context belongs after it.
    • Preserve uncertainty. If the sender is unsure, the message must remain unsure. Do not let polished language manufacture confidence.
    • Keep commitments explicit. State who is doing what and when. Do not allow the assistant to infer agreement from a vague discussion.
    • Delete decorative expansion. Professional writing is clear and proportionate. A one-sentence answer should remain one sentence when no further context is needed.
    • Make the sender approve meaning. Reviewing grammar is not enough. The sender must confirm that the message reflects the intended position and requested action.
    • Switch channels when needed. Use a direct conversation when the issue is sensitive, disputed, ambiguous, or likely to produce follow-up questions. Summarize the resulting decision afterward.

    Client reporting needs particular care. A generated update can describe movement without explaining whether that movement matters. It also cannot notice an unexpected comment, ask why lead quality changed, or recognize that a neat recommendation conflicts with the client’s operations unless someone supplies that context.

    A useful client update separates five things: what changed, what it may mean, what is still unknown, what the team will verify, and what decision or action is required. That structure prevents a polished narrative from disguising uncertainty. It also gives the client obvious places to add information that isn’t present in the reporting system.

    The same rule applies to public content. AI can help reorganize an explanation, draft an FAQ, or format JSON-LD, but the brand must own the position and every factual assertion. Validate machine-generated structured data against the visible page and authoritative business records before publication. Never allow an assistant to invent reviews, prices, availability, credentials, authorship, or other claims simply because the markup expects a value.

    Match review gates to consequences and measure decision quality

    Three AI-assisted workflow paths show routine items passing automatically, one item receiving a quick human check, and a consequential item undergoing joint review.

    Human review is not one generic approval step. The gate should depend on consequence, reversibility, observability, and uncertainty.

    • Low-consequence work: Allow automatic handling when errors are easy to see, easy to reverse, and limited in impact. Formatting internal notes is different from changing a live canonical tag.
    • Moderate-consequence work: Queue the output for review when it influences priorities, client interpretation, or published content but has not yet committed resources or changed production systems.
    • High-consequence work: Require named approval before spending money, making a client commitment, publishing a material claim, changing permissions, handling customer data, or applying a broad technical change. Preserve a tested rollback path where reversal is possible.

    Every consequential recommendation should leave a short decision record. Capture the input set, known context, assumptions, recommendation, material alternative, approver, action taken, and result. This is not bureaucracy for its own sake. Without a record, you cannot tell whether a poor outcome came from missing data, weak reasoning, a bad instruction, an execution error, or a reasonable decision under uncertainty.

    Measure the quality of delegation rather than celebrating output volume. Useful operating measures include:

    • Context-correction rate: How often did the recommendation materially change after operational context was added?
    • Unsupported-assumption rate: How often did the assistant rely on a claim, definition, relationship, or constraint that the input did not establish?
    • Human override pattern: Which recommendations were changed, and why? Group overrides by missing context, risk, strategy, factual error, or stakeholder knowledge instead of treating every override as model failure.
    • Reversal rate: How often did the team need to undo an AI-influenced action? Record the consequence as well as the count.
    • Outcome fit: Did the action improve the business outcome named in the decision brief, or only an intermediate metric that was easier to measure?
    • Communication rework: How often did recipients need clarification because the generated message hid the request, distorted uncertainty, or implied an unintended commitment?

    A low human-override rate is not automatically a success. It may indicate strong recommendations, passive reviewers, or an organization that has stopped challenging the system. Review the reasons, outcomes, and consequences together.

    Audit a fixed sample of routine decisions at a regular cadence, not only the failures that become visible. Escalate whenever important data is missing, evidence conflicts, the recommendation depends on unstated business conditions, the action cannot be reversed safely, or nobody is clearly willing to own the outcome.

    Key takeaways

    • Govern AI by the authority it receives, not by how often employees use it.
    • Let assistants prepare and analyze broadly, but require explicit criteria and accountable ownership before recommendations become decisions.
    • Supply commercial goals, metric definitions, operational events, constraints, missing evidence, and a decision owner with every consequential request.
    • Separate observations, inferences, recommendations, and unknowns so confidence cannot conceal a weak evidence chain.
    • Use AI to make human communication shorter and clearer. Do not let generated polish alter uncertainty, urgency, or commitment.
    • Measure context corrections, unsupported assumptions, reversals, communication rework, and business outcomes rather than generated output.

    Choose one recurring AI-assisted workflow this week. Write its authority sentence, create its decision brief, set the review gate, and record the next outcome. Expand delegation only after that workflow shows that people can see the assumptions, challenge the recommendation, reverse the action, and identify who owns the result.

    References


  • How to Measure AI Visibility and Build a B2B Citation Strategy

    How to Measure AI Visibility and Build a B2B Citation Strategy

    Your organic dashboard can look healthy while AI answers quietly reshape your B2B buying journey. An assistant may recommend your product, mention it without evidence, cite a competitor, repeat an outdated claim, or answer the question without sending anyone to your site. Rankings and sessions alone cannot tell you which of those things happened.

    You need a measurement system that separates visibility from citations, links, accuracy, and commercial impact. Once those signals are distinct, you can see whether you have a discovery problem, a credibility problem, a content problem, or an attribution problem – and choose the right response.

    Build an AI visibility model that does not depend on clicks

    Clicks still matter. They simply are not a complete measure of AI discovery. A buyer can encounter your brand and continue researching without following a link, while an AI system can use your content without making your domain prominent. Modern reporting therefore needs to add prompt coverage, mention and citation rates, brand accuracy, AI Overview appearances, and referral tracking to the usual traffic and conversion metrics.

    Organize those signals into the following measurement layers. Do not collapse them into a composite visibility score until stakeholders can inspect the underlying numbers.

    Measurement layerQuestion it answersSignals to trackDecision it supports
    VisibilityDoes the brand appear for buying questions that matter?Prompt coverage, entity presence, product mentions, Share of Model, AI Overview appearancesWhich markets, products, and buyer questions need attention
    RepresentationIs the brand described accurately and supported by a source?Citation frequency, linked-source rate, cited URLs, prominence, factual accuracy, framingWhich claims, entities, and pages need correction or reinforcement
    ResponseDoes that exposure create observable demand?AI referral sessions, visits to cited pages, branded search movement, engagement and conversion eventsWhich visibility gains are producing meaningful audience behavior
    Business outcomeDoes the activity contribute to qualified demand?Leads, qualified opportunities, assisted conversions, pipeline, and revenueWhere to continue investing and what to stop doing

    Three states that often get blended together should remain separate:

    • Mentioned: The answer names your brand, product, executive, or another tracked entity.
    • Cited: The answer identifies your domain, page, profile, or publication as supporting material.
    • Linked: The answer provides a usable link to that material.

    A mention can occur without a citation, and a citation can appear without a useful link. That is why cited sources and linked sources should be reported separately. Combining them conceals whether the problem is brand recognition, source selection, or click opportunity.

    Your collection stack can combine an AI visibility platform or a manual prompt log with Google Search Console, web analytics, CRM records, trend data, and a site-change log. Each system observes a different part of the journey. Preserve your own historical exports as well: Google Search Console retains data for 16 months, which is too short for some long-range comparisons.

    Build the prompt panel from real buyer decisions

    Buyer silhouettes surround a console where multiple question pathways feed into a grid of blank prompt tiles and purchasing-stage symbols.

    AI visibility is always visibility for a defined set of questions. A score produced from vague, high-volume prompts can look impressive while missing the questions that influence a shortlist. Start with the buying decision, then construct the panel you will use to observe it.

    1. Set the commercial scope. Name the product line, market, language, buyer role, and competitive set. A global brand score is not useful if the revenue decision concerns a particular service in a particular market.
    2. Map the decision questions. Use language found in sales conversations, support questions, internal site search, category research, and customer-facing teams. Include the questions buyers ask before they know your brand as well as the validation questions they ask after discovering it.
    3. Assign a stable prompt ID. Store the exact wording, intended buyer stage, intent class, and business priority. If wording changes, create a new prompt version instead of silently replacing the old test.
    4. Define the test environment. Record the platform and model, market, language, account or session condition, and run date. Compare like with like before aggregating results.
    5. Repeat the observation consistently. Language-model outputs can change between runs. Choose a repeat count your team can sustain, then keep that count and the execution method consistent across reporting periods.
    6. Preserve the evidence. Save the full answer or a durable capture, not just a pass or fail. You will need the original response when a stakeholder asks why a score changed or when an inaccurate claim needs investigation.

    A useful B2B panel covers several kinds of decision:

    • Problem framing: questions about the operational problem, its causes, and possible approaches.
    • Category education: questions that define a solution class, its use cases, and its limits.
    • Shortlisting: questions asking which providers or products fit a stated requirement.
    • Comparison: questions about alternatives, tradeoffs, capabilities, or selection criteria.
    • Risk and validation: questions involving implementation, security, compatibility, governance, support, or evidence.
    • Adoption: questions a buyer asks while planning deployment or trying to gain internal approval.

    Keep branded and non-branded prompts in separate views. A model is more likely to discuss you when your name is already in the question, so combining those prompts can inflate apparent discovery. You can also segment informational, transactional, and generic questions, then break the results down by product or business unit. This follows the same principle as separating brand and non-brand search reporting: each group represents a different kind of demand.

    For every prompt-platform-run, record the prompt ID, raw answer, entities mentioned, competitor mentions, prominence label, cited domains, cited pages, clickable links, factual issues, and reviewer notes. Include failed or incomplete runs instead of discarding them. A missing observation is not the same as an observed absence.

    Define the metrics before opening the dashboard

    The cleanest unit of analysis is a prompt-platform-run: a specific prompt executed on a specific platform under a recorded set of conditions. Every rate should state which units were eligible for its denominator. That discipline prevents teams from comparing a small hand-picked test with a larger automated panel as though they were equivalent.

    Prompt coverage and citation frequency

    • Prompt coverage is the share of eligible units in which a qualifying brand or product mention appears. Count the brand at most once per unit when measuring frequency, so a verbose answer does not outweigh several complete absences.
    • Citation frequency is the share of eligible units that cite a tracked property. Keep the company website, documentation, LinkedIn profiles, LinkedIn Articles, review sites, and independent publications in separate source groups.
    • Linked-source rate is the share of eligible units that provide a clickable route to a tracked property. Do not infer a link merely because the brand or domain is written in the response.
    • Page citation frequency applies the same calculation to an individual URL or content group. It tells you which assets are actually functioning as references.

    Share of Model

    Share of Model measures how frequently or prominently your brand, domain, or products appear across a defined prompt set relative to tracked competitors. It is the AI-answer counterpart to competitive share-of-voice reporting, but the formula must be visible to anyone reading the dashboard.

    An appearance-based version divides your qualifying appearances by all qualifying appearances from the competitive set. If no tracked brand appears in a unit, mark that unit as having no competitive appearance rather than forcing it into the ratio. If you use prominence, publish the rubric in advance. Plain-language labels such as absent, passing mention, substantive option, and primary recommendation are easier to audit than an unexplained weighted score.

    Do not blend platforms too early. A combined score can hide strong visibility in ChatGPT and weak visibility in Gemini, Perplexity, or Claude. Show the platform views first, followed by an aggregate only if the weighting reflects your buyers and remains stable over time. Share of Model tracking requires defined prompt panels and multiple observations, because language-model answers are not deterministic.

    Accuracy and representation

    Visibility is not automatically favorable. A prominent answer can associate your product with the wrong use case, attribute a competitor’s feature to you, repeat an outdated limitation, or recommend you for a buyer you cannot serve. Build a manual review rubric around claims that matter commercially.

    • Is the company, product, and expert identity correct?
    • Is the stated use case within the product’s real scope?
    • Are material capabilities, integrations, requirements, and limitations current?
    • Does the answer distinguish your product from similarly named entities?
    • Does the cited page actually support the claim attached to it?
    • Is the recommendation framed for the right market and buyer?

    Calculate accuracy only from claims your reviewer actually checked, and retain the reason for every failure. Automated sentiment can help triage a large dataset, but it should not replace factual review for high-value buying prompts.

    A credible period comparison uses the same prompt cohort, competitive set, run method, and metric definition. Show the numerator and denominator beside every rate. Label prompts added during the period as a separate cohort, annotate site and content changes, and do not treat an unavailable model response as a brand absence. Without those controls, movement in the chart may be a measurement change rather than a visibility change.

    Give AI systems citable B2B material

    Structured evidence objects flow into a transparent AI chamber, which connects its output back to individual source cards while unclear documents remain separate.

    The prompt panel tells you where the citation strategy should begin. Prioritize a question when it has commercial value and the answer shows a specific failure: your brand is absent, the brand is present but unsupported, the wrong page is cited, the description is inaccurate, or a competitor consistently supplies the clearest evidence.

    Match the intervention to the observed failure:

    • Absent from a relevant answer: create or improve a resource that resolves the underlying question, not a page whose only purpose is to mention the target phrase.
    • Mentioned without a citation: make the supporting facts explicit, attributable, and easy to locate on a stable page.
    • Cited through an outdated page: update that page, preserve a reliable route to the current information, and correct internal links that still point to the obsolete version.
    • Represented inaccurately: fix conflicting descriptions across your website, documentation, profiles, and partner-facing material before adding more content.
    • A competitor is cited instead: inspect the question its page resolves, the evidence it exposes, and the format that makes the answer usable. Address the information gap without copying its language or unsupported claims.

    Create a maintained source of truth

    A citable B2B page should make its purpose obvious without requiring the reader or a machine to reconstruct the answer from marketing copy. Open with a direct response to the question. Define the scope and audience. Use consistent entity and product names. State material limitations beside capabilities. Show the method behind original data, and separate evidence from opinion. Add a visible owner or author, publication or update information, descriptive internal links, and a stable destination for deeper documentation.

    Good candidates include clear category definitions, selection criteria, transparent comparisons, integration requirements, implementation documentation, technical explanations, and original data with a documented method. The right format depends on the prompt. A buyer asking whether a product supports a particular workflow needs a precise capability page, not a broad thought-leadership essay.

    Use JSON-LD to describe the page type, organization, people, products, and relationships that are genuinely present in the visible content. Keep names, URLs, dates, authorship, and other claims aligned between the markup and the page. Structured data can reduce entity ambiguity, but it cannot make thin, contradictory, or unsupported content authoritative. Validate the markup after publishing and log material schema changes as reporting events.

    Treat LinkedIn as a measured citation surface

    LinkedIn deserves its own line in a B2B citation plan. HiGoodie describes LinkedIn as a top-five AI citation source and identifies individual profiles and LinkedIn Articles as citable surfaces. That ranking is a vendor claim rather than a universal benchmark; its position will depend on the platform, prompt panel, market, and measurement method. The practical response is to test LinkedIn in your own citation data, not assume either that it dominates or that it does not matter.

    • Make the expert profile unambiguous about the person’s role, company, and genuine subject expertise.
    • Use a LinkedIn Article to answer a defined buyer question in full rather than publishing a vague teaser that depends on a click for meaning.
    • Carry the necessary context, qualifications, and evidence into the answer, then link to the maintained website resource when readers need current documentation.
    • Use consistent company, product, and expert names across LinkedIn and the company site.
    • Track citations to LinkedIn separately from citations to your own domain. The content may be brand-controlled, but the platform and URL are not owned by you.

    Do not turn this into a duplication program. Decide what each surface is responsible for. Your site should remain the maintained source of truth for product facts and durable documentation. An expert profile or LinkedIn Article can frame the decision, explain the method, and carry the answer into a professional network. Accurate third-party references can add independent context. None of these placements guarantees selection by an AI system, so judge the strategy by measured citation and representation changes rather than publication volume.

    Connect visibility changes to commercial outcomes

    A visibility chart earns attention when it helps the business make a decision. Lead stakeholder reporting with the commercial goal, then show the AI signals that may contribute to it. Revenue, pipeline, qualified opportunities, and conversions belong above prompt counts in the reporting hierarchy.

    Use several attribution signals because no individual system sees the entire journey:

    • Web analytics: capture referrals from identifiable AI platforms, the landing page, meaningful events, and conversions. Treat this as a lower bound because an unlinked mention or a later direct visit may leave no referral trail.
    • CRM attribution: retain the standard acquisition field and add a self-reported discovery question with optional detail. Normalize answers such as ChatGPT, Gemini, Claude, Perplexity, AI search, and AI Overview without deleting the buyer’s original wording.
    • Branded demand: monitor branded query direction and direct visits alongside citation changes. These are supporting indicators, not proof that an AI appearance caused the demand.
    • Page-level outcomes: connect frequently cited landing pages to their engagement, conversion, opportunity, and revenue data. A page can be highly citable yet commercially weak if it gives the reader no sensible next step.
    • Change annotations: record content revisions, schema deployments, migrations, major site changes, campaigns, and relevant platform events. An annotation narrows the explanation; it does not establish causation by itself.

    A decision-ready report should show the business outcome, prompt coverage and Share of Model by platform, citation and link rates, accuracy failures, the pages or entities responsible for the largest movement, and the action planned next. Include raw counts and the prompt cohort behind every rate. When evidence supports correlation but not causation, say so plainly.

    Key takeaways

    • Measure visibility, representation, audience response, and business outcome as separate layers.
    • Use a fixed prompt panel tied to real B2B decisions, with branded and non-branded prompts reported separately.
    • Track mentions, citations, and clickable links independently; each reveals a different failure or opportunity.
    • Publish direct, maintained answers with consistent entities, visible evidence, and JSON-LD that matches the page.
    • Measure LinkedIn profiles and Articles as distinct citation surfaces instead of treating LinkedIn only as a distribution channel.
    • Connect AI observations to analytics and CRM data, but do not claim that a citation caused pipeline when the evidence only shows movement at the same time.

    For your next reporting cycle, choose the product line with the clearest commercial outcome and build a prompt panel narrow enough to review every answer. Establish the baseline, find the highest-value representation or citation gap, improve the resource that should answer it, and rerun the unchanged panel on your scheduled cadence. Let that evidence choose the next content task. That is how AI visibility becomes an operating discipline rather than a collection of screenshots.

    References


  • Amazon and Yelp Local Service Leads: A Practical Playbook

    Amazon and Yelp Local Service Leads: A Practical Playbook

    If you advertise a local home or auto service on Yelp, Amazon may now be able to place your business in front of shoppers whose product activity points to a related job. The practical question is not whether Amazon has a large audience. It is whether you are eligible, whether the lead matches work you perform, and whether your team can turn that lead into a completed job.

    This is a narrow opportunity with an unusually useful signal: a person may have just bought the thing they need installed, repaired, moved, cleaned or serviced. Before moving budget, confirm access, prepare the Call and Quote paths, and measure outcomes beyond the initial lead.

    What the Amazon-Yelp handoff actually changes

    Most local service advertising begins with an explicit request such as “plumber near me.” Amazon Sponsored Services can begin one step earlier. It can infer a possible service need from the product a shopper is viewing or has purchased. A shopper buying a kitchen faucet, for example, could be shown a nearby plumber.

    The ads can appear on Amazon product detail, order confirmation and package tracking pages. That gives Amazon several opportunities to connect a product with the job around it: while the shopper is considering the item, immediately after the transaction, or while the item is on its way.

    The shopper can use Call to contact the business or Quote to request an estimate. Both actions happen within the Amazon experience. Your website is therefore not necessarily the first conversion surface, and a technically excellent landing page cannot compensate for a missed call or an unanswered quote request.

    A purchase is a strong contextual signal, but it is not proof that the person is ready to hire. The shopper may intend to do the work, may already have an installer, or may be buying for someone else. Treat the product context as a reason for relevance, not as automatic qualification.

    Do not assume Amazon will pass the exact purchased item to your business. A product-level lead field has not been specified. Your intake process should be able to identify the item, required service, job location and timing without making the customer repeat a long story.

    Check whether your business can participate before you optimize

    A local service business owner reviews a lead on a laptop beside symbols for service area, verification, availability, and job type.

    The initial rollout is not an open marketplace for every local company. Access is limited to eligible Yelp advertisers in U.S. home and auto service categories. A free Yelp listing alone should not be treated as confirmation that a business can appear.

    1. Confirm that the operating location and service area are in the United States.
    2. Confirm that the business is an active Yelp advertiser and ask whether the account is eligible for Sponsored Services.
    3. Verify that the Yelp category reflects the work the business actually performs. Professionals named for the rollout include plumbers, electricians, landscapers, home cleaners, roofers and movers, while auto-related service opportunities can follow purchases such as auto parts.
    4. Check operational fit. If you do not install customer-supplied products, travel to the shopper’s location or handle the work implied by your category, more exposure can simply produce more disqualified requests.

    Do not select an inaccurate Yelp category just to chase access. It can create poor matches, waste intake time and set the wrong expectation with customers. Eligibility is useful only when the product-to-service connection leads to work you want.

    Established for the initial rolloutConfirm for your account
    Yelp supplies the participating local service-provider network.Whether your location, account and exact category are eligible.
    The launch covers eligible U.S. home and auto service advertisers.Pricing, billing events and any budget controls available to you.
    Placements can appear on product detail, order confirmation and package tracking pages.Which placements your business can enter and what reporting identifies them.
    Customers can initiate a Call or Quote inside Amazon.What lead details, product context and attribution fields your team receives.

    Get account-specific answers before forecasting lead volume or return. The rollout establishes the audience, placements and basic actions, but it does not establish a universal billing model, ranking formula or lead payload that every advertiser can plan around.

    Design the offer for the job that follows the purchase

    The useful planning unit is not the Amazon product keyword. It is the bridge between a product and a serviceable job. For each profitable service line, write down what the customer is likely to have bought, what work that purchase creates, what would disqualify the request, and what information your team needs next.

    1. Map the product to the real job. “Faucet” is product language; “replace a customer-supplied kitchen faucet” is job language. Use the latter only if that is work you actually accept.
    2. Make Yelp accurate before making it persuasive. Check the business name, category, service area, phone routing, operating hours and service descriptions. Reviews and photos should represent the work customers can currently book.
    3. State important boundaries early. If you cover only certain areas, require an inspection, exclude a type of installation or cannot provide same-day work, make that clear wherever the available profile and ad controls allow it.
    4. Prepare one short intake path for each action. Calls need a concise opening question. Quote requests need a fast follow-up that collects any missing job details.

    A practical call opening is: “What did you buy or what needs service, and where is the job?” That question identifies the object, requested work and location without assuming Amazon supplied any of them.

    For a quote request, collect only information that changes qualification or price: the item or model when relevant, the requested service, the job location, access constraints, timing and any photos needed to understand the work. If Amazon’s form does not collect those details, request them in the first follow-up instead of sending a generic sales message.

    Keep product wording natural. Filling a Yelp profile with model numbers or unrelated Amazon phrases is unlikely to help a customer understand the business. Clear service language is more durable: installation, replacement, removal, repair, assembly or another precise task that your team performs.

    Measure completed jobs, not Amazon-shaped activity

    A visual customer journey moves from a product purchase and phone inquiry to a technician completing an appliance installation in a home.

    Sponsored Services joins two platforms in one customer path: Amazon supplies the commerce context, while Yelp supplies the local business network. If every resulting contact is recorded merely as “Yelp,” you will not be able to tell whether the new placement produces different lead quality from ordinary Yelp activity.

    Create a distinct CRM source such as “Amazon Sponsored Services via Yelp.” Preserve Call and Quote as separate interaction types. When available, retain the platform lead identifier and campaign or placement metadata rather than replacing them with a manually entered source.

    • Record the date and time of the lead, source, Call or Quote action, requested service and location.
    • Track whether the lead was reached, qualified, quoted, booked, completed or lost.
    • Use consistent loss reasons such as outside service area, unsupported work, unreachable, duplicate, timing mismatch or price objection.
    • Deduplicate contacts that arrive through Amazon, Yelp, a direct call and your website for the same job.
    • Record completed-job revenue and the cost data available from the advertising account.

    Then evaluate a funnel rather than a lead count:

    • Answer rate for Calls: answered incoming calls divided by tracked incoming calls.
    • Contact rate for Quotes: quote requests that receive successful contact divided by quote requests received.
    • Qualification rate: qualified opportunities divided by total leads.
    • Booking rate: booked jobs divided by qualified opportunities.
    • Completion rate: completed jobs divided by booked jobs.
    • Cost per completed job: attributable spend divided by completed jobs.

    Call and Quote leads should not be blended too early. A call depends heavily on whether someone answers at that moment. A quote request depends on follow-up time, the information requested and how easily the customer can continue asynchronously. Measuring them separately shows whether the placement is weak or the handoff is weak.

    Before calculating return, establish what the reported cost includes and which event triggers a charge. Also confirm how duplicate, invalid or disputed contacts are handled. Do not assign an arbitrary portion of total Yelp spend to Amazon leads when the account reporting does not support that allocation.

    Judge each lead cohort only after it has had enough time to reach the normal completion point for that service. A quote still awaiting inspection is not a lost lead, while a booked job that is later cancelled is not completed revenue. This distinction matters more than an attractive top-line lead count.

    Keep local SEO and structured data in their proper roles

    Sponsored Services is a paid acquisition route, not a replacement for local search. It reaches a possible need inferred from commerce activity. Local SEO reaches people who express that need through a search, map or direct question. The two channels meet the customer at different points and should be tracked separately.

    No confirmed mechanism makes your website’s JSON-LD an eligibility or ranking input for these Amazon placements. Do not sell or buy schema work on the promise that it will unlock Sponsored Services. Access begins with the Yelp advertising relationship, eligible category and U.S. rollout conditions described above.

    Structured data still has a supporting job on your own site. Use the most specific truthful LocalBusiness subtype, and keep the business name, address, telephone number, URL and service area aligned with visible page content. Where it accurately represents the page, Service and Offer markup can clarify what the business provides. Markup should describe real, visible information rather than adding services or coverage areas solely for machines.

    Your service pages should also answer the questions a product-led shopper may ask while validating the business:

    • Do you install or service customer-supplied products?
    • Which product types and job types do you accept?
    • What information is required for an estimate?
    • Which locations do you serve?
    • What is included, and what commonly changes the scope?

    Those answers support ordinary search, answer engines and customer validation. They should be written because they resolve a real decision, not because the page needs more references to Amazon or Yelp.

    Expansion beyond the first eligible home and auto service categories has not been established. If your business is outside the rollout, keep the business data and intake process ready, but do not divert budget based on an unannounced category expansion.

    Key takeaways

    • The initial opportunity is for eligible Yelp advertisers in U.S. home and auto service categories, not every local listing.
    • Amazon can place a service business near product detail, order confirmation and package tracking activity, then let the shopper initiate a Call or Quote.
    • The commerce signal improves context but does not guarantee that the lead is qualified or ready to book.
    • Accurate Yelp information, fast intake and clear service boundaries matter more than filling profiles with product keywords.
    • Track Amazon Sponsored Services via Yelp as its own source, separate Call from Quote, and evaluate completed jobs rather than raw leads.
    • Local SEO and truthful structured data remain valuable, but neither has been confirmed as an input to Sponsored Services eligibility or placement.

    Your next move is operational. Ask Yelp whether the account and category are eligible, test every available Call and Quote path, and add a distinct source to your CRM before the first lead arrives. Once leads begin, follow them through qualification, booking and completion before deciding whether this channel deserves more of your acquisition budget.

    References


  • Ecommerce Advertising Readiness: When and Where to Scale

    Ecommerce Advertising Readiness: When and Where to Scale

    Your campaigns can be approved and spending while your store is still unprepared to scale. The weakness usually appears after demand rises: a feed rejects sale prices, a bestseller runs out, attribution has not caught up, or a promotion turns an apparently healthy return on ad spend into a loss.

    Advertising readiness means knowing what you can profitably sell, trusting the data used to optimize it, and choosing a channel that matches the customer’s current level of intent. Work through those decisions in that order and you can expand without asking automation to repair a broken funnel.

    Key takeaways

    • Do not scale traffic until purchase tracking, product availability, pricing, and contribution margin are reliable.
    • Use Search and Shopping to capture existing demand. Use YouTube to create demand when the lower funnel already converts.
    • Performance Max can distribute ads onto YouTube, but distribution is not a YouTube strategy. You still need deliberate creative, audience logic, measurement, and testing.
    • Segment products by margin, promotion, and stock position so one blended ROAS target does not treat fundamentally different products as equals.
    • Make campaign, feed, approval, and payment changes before a peak period. During the event, monitor exceptions and respect conversion lag instead of repeatedly resetting the system.

    Pass the readiness gate before choosing another channel

    A new channel adds traffic. It does not fix weak economics, inaccurate measurement, or a checkout that already loses qualified shoppers. In fact, sending cold YouTube traffic into a funnel where Search and Shopping traffic does not convert can simply accelerate the existing loss.

    Before increasing spend, give the store a clear pass or fail on four gates:

    1. Lower-funnel performance: Search and Shopping can turn relevant, high-intent visits into completed purchases without unexplained breaks in the journey.
    2. Measurement: transactions, order values, currency, and customer signals reach the advertising platforms accurately enough to guide bidding.
    3. Economics: you know the contribution available after discounts and variable order costs, not just revenue and platform-reported ROAS.
    4. Operations: the feed, stock data, payment methods, landing pages, creative approvals, and alerting process can withstand a sudden increase in demand.

    A failure on any gate determines your next investment. A tracking failure calls for measurement work. A stock or price failure calls for feed operations. A negative contribution margin calls for a commercial decision. None of those problems should be handed to a bidding algorithm as if they were targeting problems.

    Verify the data that bidding will learn from

    Run a test order from the storefront through the complete measurement path. Confirm that the purchase appears once, carries the correct value and currency, and can be reconciled with the order record. Then inspect the supporting stack: server-side measurement where appropriate, Consent Mode, Enhanced Conversions, and offline conversion measurement if meaningful outcomes happen after the online event. These are among the data checks that should be completed before a high-demand period, not during it.

    First-party audiences also need structure. An undifferentiated customer upload tells the platform that every buyer has equal value. Segment usable lists by factors such as average order value and customer lifetime value, then keep acquisition and retention decisions distinct. Apply the same discipline to the audience data used across Google Ads and Meta.

    Finally, document conversion lag. If purchases commonly arrive several days after an ad interaction, the newest dates will always look artificially weak. A reporting delay is not a campaign collapse, and reacting to it every morning can turn normal lag into genuine instability.

    Set a profit boundary before approving a discount

    Revenue-based ROAS can hide whether an order creates value. Start with a product or product-group calculation:

    Net selling price – product cost – variable fulfillment, payment, and expected return costs = contribution before advertising.

    That contribution is the amount available to pay for acquisition and leave profit behind. If you lower the selling price, recalculate it before setting the promotion live. A 15% discount removes part of the margin at the same time acquisition costs may rise. Matching a competitor’s discount without doing this calculation can produce more orders and less profit.

    To judge the promotion, divide the baseline contribution you want to preserve by the new contribution per order. The result is the number of discounted orders required before advertising costs are considered. Then add the expected acquisition cost. If the required volume is implausible, change the offer, limit it to suitable products, or accept that the promotion has a strategic cost rather than pretending it is profitable.

    Give each channel one clear job

    Channel choice becomes easier when you start with the customer’s state. Search and Shopping are pull channels: the shopper expresses intent and the advertiser competes to answer it. YouTube is a push channel: the advertiser interrupts someone who was doing something else and must create enough interest to earn a later action. Those conditions require different creative, timelines, skills, and measurement.

    Channel or campaign typeCustomer statePrimary jobWhat you must control
    Search and ShoppingAlready looking for a product, category, or solutionCapture existing demandQuery or product relevance, offer quality, feed accuracy, bids, margin, and landing-page conversion
    YouTubeNot actively shopping at that momentCreate interest, demonstrate a product, and generate future demandHook, argument, demonstration, proof, audience, creative refresh, and a longer evaluation window
    Performance MaxVaries because inventory spans multiple Google surfacesAllocate spend across eligible inventory toward the configured conversion goalFeed quality, conversion inputs, asset quality, product segmentation, budget, targets, and interpretation of blended reporting

    This distinction matters because Performance Max may already be buying YouTube impressions for your store. It can reuse uploaded assets or, when no video is supplied, assemble video from product images, transitions, and text. That gives the campaign something to serve, but it does not supply positioning, persuasion, creative sequencing, or a channel-specific learning plan.

    Treat Performance Max as a distribution system, not proof that you have a YouTube strategy. A blended conversion total cannot tell you whether upper-funnel impressions created new demand, harvested demand that already existed, or received credit for a purchase that would have happened anyway. Do not accept that number uncritically, but do not make the opposite mistake of testing YouTube once, grading it like Search, and declaring the channel ineffective.

    Use a simple channel decision sequence

    1. If relevant Search and Shopping traffic does not convert, repair the offer, product pages, checkout, feed, or measurement before adding cold reach.
    2. If profitable search demand is still available, capture it before paying to manufacture more awareness.
    3. If existing demand is constrained, or the product is new and lacks search volume, assess whether YouTube can create demand.
    4. If the goal is product discovery, brand awareness that can drive later searches, a time-limited seasonal promotion, or a new-product launch, give YouTube a defined budget and its own measurement plan.
    5. If you cannot produce and refresh persuasive video, postpone the channel rather than allowing generic automated assets to stand in for strategy.

    Build YouTube creative as a persuasion sequence

    A YouTube viewer did not ask to see your product. The creative therefore has to do more than show it. Build each concept around a complete sequence:

    1. Hook: earn attention in the first five seconds.
    2. Problem: make the relevant frustration, desire, or missed opportunity recognizable.
    3. Mechanism: explain how the product addresses that problem.
    4. Demonstration: show the product doing the work instead of relying on a claim alone.
    5. Proof: give the viewer a reason to believe the result.
    6. Call to action: make the next step explicit and consistent with the landing page.

    Creative is the operating cost of this channel. Fatigue arrives faster than it does in intent-led campaigns, so two or three occasional videos are not a substantial testing program. For a serious effort, plan the people, production process, and approval capacity needed to test 20 or 30 videos per month. If that volume is beyond reach, narrow the test deliberately rather than spreading a small set of assets across too many audiences and offers.

    Define success before launch. Direct sales still matter, but the feedback loop is longer and attribution is less clean than it is for Search. Separate YouTube’s budget and evaluation from the assumptions used for demand capture, account for the store’s observed conversion lag, and watch whether the channel is creating the future demand it was assigned to create. Changing the success definition after seeing the result makes the test impossible to interpret.

    Make feed and margin structure govern spend

    An overhead arrangement of unbranded products, packaging, coins, a calculator, and a tablet with abstract product tiles.

    For an ecommerce advertiser, Google Merchant Center is not an administrative afterthought. Its product feed is a core input to Shopping and Performance Max. When availability, price, or identifiers are wrong, automation makes decisions from a distorted catalog.

    Configure the feed around the decisions your team will need to make under pressure:

    • Automate promotional prices. Populate sale_price and sale_price_effective_date with exact start and end timestamps. This allows scheduled price changes and reduces the risk of a mismatch between the website and feed when a sale begins.
    • Protect price-annotation eligibility. If strikethrough pricing is part of the plan, the base price must have been active for at least 30 days within the previous 200 nonconsecutive days.
    • Increase freshness during peak windows. Raise feed synchronization to three or four times per day when prices and inventory are changing quickly.
    • Stop advertising unavailable inventory. Use automated rules or feed scripts to flag and pause out-of-stock SKUs instead of buying visits to products that cannot be ordered.
    • Add commercial labels. Use Custom Label 0 through Custom Label 4 to represent attributes such as actual margin, promotional status, and stock position.

    Do not wait for the promotion to discover whether the feed and checkout disagree. Schedule a sale-price test, verify the timestamps, inspect the landing page and cart, and confirm that a product returns to its normal price after the test window. A valid feed submission is useful, but the shopper experiences the complete path.

    Translate labels into campaign decisions

    Labels become valuable when they change how you allocate spend. A high-margin, well-stocked bestseller can support a different target and budget from a low-margin item with limited inventory. Blending the two under one target ROAS encourages the platform to optimize revenue while concealing the difference in profit.

    • High margin and strong stock: make these products eligible for more assertive acquisition, subject to the contribution boundary.
    • Low margin: use a more defensive target or restrict promotion unless the product has a deliberate strategic role.
    • Promotional: isolate the discounted economics so ordinary-price performance does not subsidize an unprofitable event in the reporting.
    • Low stock: reduce exposure before availability becomes a customer and feed problem.
    • Out of stock: pause promptly and restore eligibility only after the feed and storefront agree.

    Keep a working record for each important SKU or product group: normal price, promotional price, product cost, variable order cost, contribution before advertising, stock position, and active promotion. That record gives the media team a commercial map. Without it, campaign structure is merely technical organization.

    Prepare the peak-period operation before demand arrives

    Workers pack unbranded orders at organized stations in a well-stocked ecommerce fulfillment area.

    Peak-period readiness is mostly timing. A change that is sensible in an ordinary month can be reckless immediately before Black Friday if it triggers a learning period, waits for approval, or alters the data used by bidding. Depending on account size and market, Q4 preparation may need to begin in August or September.

    Sequence the work around risk

    1. Months before demand peaks: validate measurement, segment first-party audiences, repair the lower funnel, calculate promotion economics, and begin warming audiences where demand creation is part of the plan.
    2. Well before the event: launch new campaign structures and bidding strategies early enough to move beyond their initial learning behavior. Upload creative with time for review instead of risking a pending approval on the day before the sale.
    3. Before prices change: test sale attributes and effective dates, confirm stock rules, set feed schedules, fund the advertising account, and add a backup payment method.
    4. During Cyber Week: inspect Merchant Center Diagnostics early each morning, prioritize disapproved bestsellers, and maintain the higher feed-sync frequency.
    5. After each major sales window: wait for the known conversion lag before treating recent ROAS as complete, then compare product-level contribution with the target established before launch.

    Decide in advance how much control you want over rising CPCs and CPMs, including whether a portfolio bid cap belongs in the plan or whether the bidding system will operate without one. The important point is to make that choice from economics and risk tolerance before the auction becomes unusually competitive.

    Monitor exceptions instead of micromanaging campaigns

    Create alerts for payment failures, material CPC changes, rapid budget consumption, feed disapprovals, and inventory problems. Then write the response beside each alert. An alert without a response rule merely creates anxiety; an alert tied to a check and an owner shortens the time to a useful decision.

    • If a bestseller is disapproved, inspect price, availability, and landing-page consistency before changing a bid.
    • If a campaign consumes its daily budget unusually early, check traffic quality, CPC movement, and the promotion schedule before reallocating money.
    • If reported ROAS falls on the newest dates, compare that window with the account’s normal conversion lag before changing targets.
    • If stock becomes scarce, use the stock label or automated rule to reduce exposure rather than continuing to sell demand you cannot fulfill.
    • If a payment method fails, switch to the verified backup before delivery stops during the most valuable traffic window.

    Frequent intervention can be as damaging as neglect. When conversion lag is several days, daily changes based on incomplete purchases make each decision depend on a partial result. Reserve emergency changes for genuine operational failures or clearly breached financial boundaries. Let ordinary performance accumulate enough evidence to judge.

    Your next move is not automatically another campaign. Choose one upcoming promotion or product launch and score it against the four readiness gates. Fix the first failed gate. When all four pass, assign Search, Shopping, Performance Max, or YouTube a precise job, budget, success measure, and stopping condition. That is the point at which scaling becomes a controlled decision rather than a bet.

    References