Author: shivamcrushpressai

  • How to Choose an Industry-Specific GEO Agency in 2026

    How to Choose an Industry-Specific GEO Agency in 2026

    If you are hiring a GEO agency in 2026, finding firms that mention AI search is easy. The harder decision is whether a team understands your market well enough to influence accurate recommendations and connect those recommendations to qualified demand.

    You need evidence of three things: real industry fluency, a repeatable generative engine optimization process, and a credible path from AI visibility to a commercial outcome. An agency that is strong in only one or two of those areas can still produce polished work, but it may not solve the problem you are paying it to solve.

    Key takeaways for your agency shortlist

    • Industry specialization should change the agency’s query research, subject-matter review, authority strategy, content, reporting, and conversion goals. A vertical landing page is not enough.
    • Separate industry tenure from GEO tenure. An established sector-marketing firm may have a new GEO practice, while a GEO-native firm may have only a short operating history.
    • Demand an evidence chain that runs from a documented AI-search baseline through specific interventions to accurate recommendations and measurable business actions.
    • Treat rankings, testimonials, visibility scores, and screenshots as leads for further investigation, not as substitutes for raw campaign evidence.
    • Use a paid diagnostic or tightly scoped initial phase to test the team, methodology, and deliverables before committing to a long retainer.

    Industry specialization should change the work
    A multidisciplinary agency team examines technical models, market samples, and blank regulatory binders during industry research.

    Industry-specific GEO is not generic content with a few sector terms added. It begins with the variables buyers include when they ask an AI system to identify, compare, or recommend a company. Those variables differ sharply by market, and they determine which facts the agency must clarify, which authorities it must cultivate, and which conversion it should measure.

    IndustryWhat the AI recommendation must understandCommercial action worth tracking
    MSP and IT servicesService scope, technical fit, customer type, location, and capabilities such as cybersecurity, cloud management, network monitoring, backup, and helpdesk supportA qualified consultation, assessment request, or sales opportunity for the relevant service
    MedspasTreatment category, practitioner expertise, clinic location, patient concerns, and the distinctions among injectables, laser treatments, body contouring, and other aesthetic proceduresA suitable patient inquiry or booked consultation, not merely a broad healthcare visit
    AutomotiveVehicle use case, price constraints, inventory, dealer reputation, service needs, or fleet economics; buyers may ask about anything from road handling to total cost of ownership for a commercial fleetA call, form submission, showroom visit, service appointment, or other traceable lead event
    Fashion and apparelProduct category, materials, fit, price, availability, brand positioning, and social or reputational signals that affect a shopper’s comparison of brandsA product visit, assisted conversion, or ecommerce sale connected to the relevant demand

    Ask each candidate to turn your actual buying situations into AI-search scenarios. An MSP agency should be able to distinguish a buyer seeking outsourced helpdesk support from one evaluating cybersecurity coverage. A medspa agency should not collapse every aesthetic treatment into one generic local page. An automotive agency must separate vehicle sales, service, fleet, and supplier journeys. A fashion agency must preserve the brand and product details that prevent an AI answer from substituting a superficially similar item.

    If discovery never gets beyond keywords, content volume, and competitor names, the agency’s specialization is probably cosmetic. Genuine vertical expertise changes the decision model it is trying to influence.

    Vertical depth and GEO depth are different credentials

    A long marketing history does not prove a long GEO history. JumpFactor has worked in MSP marketing since 2009 but added a dedicated AEO/GEO service in 2025. Etna Interactive has more than two decades of aesthetic-marketing specialization, while GEO/AEO is a more recent addition to its service mix. At the other end of the market, GEO-first firms such as Genevate and analytics-led firms such as Driven Metrics were founded in 2025. Neither profile is automatically better.

    The practical question is how the agency covers its weaker dimension. Ask an established vertical firm for GEO-specific campaign evidence rather than general SEO or paid-media results. Ask a young GEO specialist who supplies subject-matter expertise, who reviews industry claims, and how the team handles an unfamiliar buying process.

    • Test recent industry fluency: Ask which services, products, treatments, customer types, and objections appeared in its recent work. Specific answers matter more than a page of client logos.
    • Identify the reviewer: Find out who checks technical, clinical, product, or brand claims before publication. Get the person’s role and review responsibility, not a vague promise of quality control.
    • Ask what changes by vertical: The team should be able to explain how your query set, content architecture, corroborating evidence, and lead definition differ from those in another industry.
    • Probe capacity: A smaller specialist can be an excellent fit, but you need to know who covers seasonal peaks, simultaneous launches, and absences before they affect production.

    Demand evidence that survives due diligence

    Agency rankings can help you discover candidates, but they should not make the decision for you. First Page Sage ranks itself first across its 2026 MSP and IT, medspa, automotive, and fashion and apparel rankings. That commercial conflict does not make the candidate information useless, but it does mean the repeated first-place result is not independent validation.

    The scoring systems are not interchangeable either. AI placement carries 25% of the MSP framework, while GEO capability carries 30% of the automotive framework; the medspa and fashion frameworks use different combinations of outcomes, expertise, brand clarity, leadership, and authority signals. Do not compare a score from one vertical with a similarly formatted score from another as if both measured the same thing.

    A credible case should let you follow the work from initial condition to business consequence. Ask for this evidence chain:

    1. A documented baseline. You should see the buyer questions tested, the platform used, the answer returned, the brands mentioned, the citations shown, and any inaccurate or missing claims about the client.
    2. A defined intervention. The agency should identify what it changed: an entity fact, a high-intent page, an editorial asset, a local landing page, a third-party citation, a reputation signal, or a conversion path.
    3. Comparable verification. Later checks should use a stable query set and preserve the wording and relevant context. Otherwise a favorable screenshot may represent a different test rather than an improvement.
    4. Brand-accuracy checks. Being named is not enough. The answer should represent the company’s location, audience, service boundaries, product attributes, positioning, and qualifications correctly.
    5. A commercial connection. The agency should show how an AI recommendation can lead to the action your business values, whether that is an MSP sales opportunity, a medspa consultation, an automotive appointment, or an ecommerce purchase.
    6. An honest account of attribution. Some AI-influenced decisions will not generate a clean referral click. The reporting method should distinguish directly observed conversions, assisted evidence, and visibility indicators instead of turning them into one falsely precise revenue number.

    Do not let an AI citation count carry more meaning than it can support. One MSP evaluation framework uses citation count only as a broad measure of industry standing, weighted below placement, leadership expertise, customer sentiment, and relevant campaigns. A high count may indicate authority, but it does not by itself prove that a client is recommended accurately or that the recommendation produces revenue.

    Apply the same caution to testimonials. Revenue figures, review excerpts, and attributed lead claims can justify a deeper conversation, but they need context. Ask which service generated the result, when the GEO portion began, which other channels were running, what counted as a lead, and whether the agency can share the underlying reporting under appropriate confidentiality.

    Test the agency’s operating system before the retainer
    A modular workshop shows people moving research through verification, content assembly, review, and distribution stages.

    A good pitch describes an outcome. A good operating system shows how the team will reach it repeatedly. Before signing a long engagement, ask to inspect representative versions of the deliverables below. Redacted client information is reasonable; refusing to show the structure of the work is not.

    • AI belief audit: A record of what ChatGPT, Claude, Google Gemini, and any other in-scope surface currently appear to believe about the brand, including inaccuracies, omissions, conflicting facts, recommendations, and citations. A belief-first audit is already part of some automotive GEO processes.
    • Buyer-query map: Query families tied to real decision stages, such as problem diagnosis, category discovery, comparison, local selection, brand validation, and final vendor or product choice.
    • Entity and claims sheet: An approved record of names, locations, services, audiences, credentials, product attributes, differentiators, and claims. This gives writers, technical teams, and external placements a consistent factual base.
    • Content architecture: A plan showing which questions belong on service pages, comparison pages, local pages, product pages, educational resources, or other assets. It should also show how each asset supports a buying decision rather than merely targeting a phrase.
    • Corroboration plan: A distinction between facts the company can publish on its own site and claims that need credible third-party support. Medspa GEO programs, for example, may combine practitioner-led content, public relations, list placements, and location pages.
    • Editorial review path: Named responsibility for factual review, brand review, compliance-sensitive review where applicable, revisions, and final approval.
    • Measurement specification: The queries, platforms, markets, visibility fields, accuracy checks, citations, landing actions, and downstream conversion events the agency intends to monitor.

    Structured data should support the system, not replace it

    Schema can make entities, relationships, and page attributes easier for machines to interpret. It cannot manufacture subject expertise, third-party authority, good reviews, clear product information, or persuasive evidence. Ask which structured data the agency plans to use, where each value comes from, how the markup will be validated, and who keeps it aligned with visible page content.

    If the entire GEO proposal amounts to installing schema and reformatting headings, the scope is too thin. The vertical examples here consistently involve some combination of content, authority building, brand clarity, citation development, local relevance, technical work, and conversion measurement.

    Use a paid diagnostic as a controlled test

    Some firms already offer a standalone strategy phase, so you do not necessarily need to begin with a full production retainer. A paid diagnostic is especially useful when one candidate has stronger industry experience and another has the clearer GEO methodology.

    1. Give every finalist the same brief: priority markets, profitable services or products, audience, known differentiators, prohibited claims, current analytics access, and the business action that matters.
    2. Require a baseline across the agreed AI platforms using a buyer-query set broad enough to expose category, comparison, local, and branded issues.
    3. Ask the team to classify each gap. It may be an unclear brand fact, missing content, weak corroboration, poor local specificity, inaccurate product data, an authority deficit, or a broken conversion path.
    4. Require a prioritized first-phase plan that connects each proposed action to a diagnosed gap. A list of generic best practices does not meet this standard.
    5. Inspect at least one representative execution artifact, such as a content brief, entity sheet, measurement specification, or technical recommendation. You are testing the quality of the working process, not just the presentation.
    6. End the diagnostic with a decision gate. Continue only if the agency’s findings are traceable, its recommendations are feasible, and your team can support the required reviews and access.

    Make the commercial boundary explicit. The diagnostic should not roll automatically into a long engagement, and you should know who owns the query set, audit, strategy, content, data, and dashboards after the initial phase. Unclear ownership can leave you paying again to recreate the foundation with another provider.

    Match the agency model to the way your team works

    The right partner is not always the firm with the broadest service menu. It is the firm whose model fills your actual capability gap without creating a new one.

    • Choose a GEO-first specialist when you already have strong sector experts, writers, developers, and conversion infrastructure but need AI-search auditing, query design, authority strategy, and measurement. Confirm that your internal team has time to supply the industry knowledge the agency lacks.
    • Choose an established vertical-marketing agency with GEO services when subject expertise, established editorial workflows, and broader channel coordination matter most. Require recent GEO-specific evidence so legacy SEO success is not presented as proof of AI visibility.
    • Choose a full-service performance partner when the website, paid acquisition, reputation, lead capture, and conversion experience also need work. Make sure GEO has a named owner and its own reporting rather than disappearing inside a general marketing package.
    • Choose a strategy-only engagement when your internal team can execute reliably. Before buying the roadmap, confirm that it includes implementation specifications, priorities, ownership, measurement, and a process for resolving questions after handoff.
    • Choose a smaller specialist when you value direct access and a narrow scope. Ask about delivery capacity, reviewer availability, and what happens during high-volume or seasonal periods; smaller fashion and healthcare specialists can offer close service while still facing bandwidth constraints.

    Make reporting auditable in the contract

    Your statement of work should define the market, business lines, AI platforms, query set, baseline, deliverables, review responsibilities, reporting fields, and conversion events. It should also explain how the parties will handle material platform changes, factual corrections, missed approvals, and scope expansion.

    • Coverage: Which buyer questions, locations, products, services, and decision stages are being tested?
    • Visibility: Is the company absent, mentioned, cited, compared, or recommended, and in what context?
    • Accuracy: Are important facts, differentiators, restrictions, and brand descriptions represented correctly?
    • Authority: Which owned and third-party materials appear to support the answer, and where are the gaps?
    • Engagement: Which landing-page visits, calls, forms, bookings, product views, or other observable actions follow?
    • Commercial outcome: Which qualified leads, appointments, opportunities, or sales can be directly observed, and which can only be treated as assisted evidence?

    Be wary of guaranteed placements, isolated screenshots, proprietary scores with no raw fields, traffic-only reporting, or industry credentials supported only by logos. Also reject a plan that promises the same content cadence and authority tactics for every client. Those signals make the work easier to sell, but harder for you to verify.

    If a contract gives the agency ownership of your content, measurement history, account access, or core strategy, the downside can outlast a disappointing campaign. Resolve those terms before work begins, and have procurement or legal counsel review material ownership and termination clauses when the commitment warrants it.

    Your next step is to give every serious candidate the same real buying scenarios and request the same three outputs: a documented baseline, a prioritized intervention plan, and a measurement specification tied to commercial actions. The agency that makes its reasoning easiest to inspect is usually the safer choice than the one that makes the largest visibility promise.

    References


  • Anthropic Profitability and IPO Outlook: What to Watch

    Anthropic Profitability and IPO Outlook: What to Watch

    If you are weighing Anthropic ahead of a possible IPO, the central question is not whether its revenue is growing. It is whether the company can turn that growth into durable profit after compute, cloud-partner fees, model training, stock compensation, and every other consequential cost are counted.

    The available numbers point to a sharp improvement, but they remain third-party estimates rather than audited public-company results. Anthropic appears to have crossed an important profitability threshold. That makes the business more IPO-ready; it does not tell you whether the eventual shares will be attractively priced.

    Key takeaways

    • Anthropic is estimated to have reached adjusted operating profit in Q2 2026, producing $570 million on $11.6 billion of quarterly revenue, before increasing that profit to $940 million in Q3.
    • Its estimated gross margin rose from 21% in Q1 2025 to 57% in Q3 2026, while compute cost fell from $2.41 to $0.54 per dollar of revenue. That combination, rather than revenue growth alone, explains the profit turn.
    • The frequently cited $69.7 billion revenue figure is an August 2026 annualized run rate, not revenue already earned over a full year. The 2026 full-year revenue forecast is $56 billion.
    • Adjusted profit excludes stock-based compensation and other charges that can materially affect GAAP results. An IPO filing will need to show the reconciliation, cash flow, compute commitments, customer concentration, and fully diluted share count.
    • Even a strong operating business can be a poor investment at the wrong valuation. The offering price matters just as much as the growth story.

    The profit turn is meaningful, but the definition matters

    Anthropic’s estimated quarterly progression shows more than a company growing its way out of a fixed-cost base. It shows improving unit economics. Gross margin measures revenue after the cost of serving models, while compute cost per dollar of revenue also incorporates the cost of training new models. Adjusted operating income then subtracts operating expenses but excludes stock-based compensation.

    The change across five representative quarters is substantial:

    QuarterEstimated revenueGross marginCompute cost per $1 of revenueAdjusted operating incomeAdjusted operating margin
    Q1 2025$0.41B21%$2.41-$1.58B-385%
    Q4 2025$2.01B38%$1.27-$2.47B-123%
    Q1 2026$4.20B43%$0.73-$1.93B-46%
    Q2 2026$11.60B52%$0.58$0.57B4.9%
    Q3 2026$17.30B57%$0.54$0.94B5.4%

    These are modeled figures covering January 2025 through September 2026. They should be treated as a directional view until official financial statements confirm them.

    Three things are happening at once. Quarterly revenue expanded from $4.2 billion to $11.6 billion between Q1 and Q2 2026. Gross margin crossed 50%. Compute cost per revenue dollar continued falling even as the business grew. If revenue had increased while compute efficiency remained stuck at its early-2025 level, the company would still have been spending more on compute than it generated in revenue.

    The caution is in the final column. A 5.4% adjusted operating margin leaves only a little more than five cents of adjusted operating profit per revenue dollar. That is a real milestone, but not a large buffer against price reductions, higher usage, partner costs, or another increase in training expenditure.

    The annual swing is even more dramatic. Anthropic is estimated to have lost $7.98 billion on $4.62 billion of revenue in 2025. The 2026 projection calls for $1.19 billion of adjusted operating income on $56 billion of revenue, a margin of 2.1%. Because that full-year outcome includes a forecast for Q4 and excludes stock compensation, it should not be mistaken for confirmed GAAP profitability.

    When an IPO filing arrives, go directly to the reconciliation between adjusted and GAAP operating income. Record the stock-based compensation, financing-related charges, and any expense classifications excluded from management’s preferred measure. If the profitable result disappears after those items, describe Anthropic as adjusted-profitable rather than simply profitable.

    Run-rate revenue is the number most likely to be misread

    A stream of coins passes through a measuring chamber while a glowing projected path extends beyond the smaller amount physically accumulated.

    Run rate takes one month’s revenue and multiplies it by 12. It answers a useful but narrow question: what would annual revenue look like if that month’s pace continued unchanged? It does not mean the company collected that amount during the preceding year, and it does not guarantee that the pace will continue.

    Anthropic’s estimated annualized run rate increased from $5.8 billion in September 2025 to $69.7 billion in August 2026. The largest monthly jump came between April and May 2026, when the run rate rose by $18.5 billion as several large enterprise agreements began billing.

    That billing pattern is precisely why you should keep three different figures separate:

    1. $17.3 billion is estimated revenue booked during Q3 2026.
    2. $56 billion is the forecast for revenue across the full 2026 calendar year.
    3. $69.7 billion is August 2026 revenue annualized as though one month’s pace persisted for 12 months.

    Run rate is not useless. In a business growing this quickly, trailing revenue can materially lag the latest sales pace. The mistake is applying a valuation multiple to annualized monthly revenue without testing whether new contracts recur, whether usage is committed, and whether a small number of customers caused the jump.

    For your eventual IPO analysis, use reported trailing revenue as the main valuation denominator. Keep run rate as a momentum indicator. Then compare both with remaining contractual obligations, customer concentration, renewal data, and revenue recognized from minimum commitments rather than actual usage. That prevents a strong month from silently becoming a full-year assumption.

    Revenue mix will decide whether margins keep improving

    Anthropic does not earn the same margin on every dollar. Its Q2 2026 estimates show a 35-percentage-point spread between the highest- and lowest-margin business lines:

    Business lineShare of Q2 2026 revenueEstimated gross marginWhat to watch
    Direct API33.8%64%Whether price per token falls faster than inference cost
    Cloud partner API23.1%34%Partner fees, accounting presentation, and channel mix
    Claude Code19.4%48%Compute consumed by long agentic sessions
    Team and Enterprise seats12.6%69%Usage per seat, renewals, and contract durability
    Pro and Max subscriptions11.1%39%Heavy-user economics and subscription pricing

    The Q2 mix produced a blended gross margin of 52%. Team and Enterprise seats led at 69% because a fixed per-seat price exceeded average usage cost. Direct API revenue followed at 64%. Cloud partner API revenue, sold through Amazon Bedrock, Google Cloud Vertex AI, and Microsoft Foundry, carried the lowest margin at 34%.

    The cloud-partner number contains an accounting issue that matters for valuation. Anthropic is understood to record partner sales at the full price paid by the customer and record the partner’s share as a cost. A company recognizing the same transaction net would report lower revenue and a higher gross-margin percentage even if the underlying cash economics were identical.

    That does not make either presentation inherently wrong. It does mean a revenue multiple can create a misleading comparison between companies with different channel accounting. Compare enterprise value with both revenue and gross profit, and check the eventual accounting policy before treating Anthropic’s top line as directly comparable with a competitor’s.

    Mix can move margins in either direction. More Team and Enterprise seat revenue should help while average usage remains below the pricing ceiling. More cloud-partner revenue can expand distribution but dilute reported gross margin. Claude Code sits between those outcomes: it represented 19.4% of Q2 revenue at a 48% gross margin, with longer agentic sessions consuming more compute than ordinary API requests.

    Claude Code’s share stayed between 15% and 21% of company run-rate revenue from September 2025 through August 2026. It grew with Anthropic rather than separating from the rest of the business. Watch its gross margin and retention, not just its revenue, because rapid adoption is less valuable if increasingly long sessions absorb the incremental dollars.

    What the IPO filing needs to prove

    A transparent AI business engine with computing, customer, cash, and cost components is examined under lenses before a closed public-market doorway.

    The optimistic financial path assumes that inference hardware becomes cheaper per token and training expenditure grows more slowly than revenue. Under those assumptions, Anthropic reaches $121.4 billion of revenue and an 11.4% adjusted operating margin in 2027, followed by $187.6 billion and a 17.9% margin in 2028. Gross margin would rise to 60% and then 63%.

    Those figures are a scenario, not an outcome you should build into a valuation without a stress test. They require revenue to more than double in 2027 while margins continue expanding. They also assume that efficiency gains outrun both competitive price pressure and the cost of training new frontier models.

    Use the eventual filing to answer six questions before deciding what the IPO is worth:

    1. Does profitability survive GAAP accounting? Start with GAAP operating income, then identify every adjustment. Stock-based compensation is an economic cost because it dilutes shareholders even when it does not consume cash in the period.
    2. Does profit convert into cash? Compare operating income with operating cash flow and free cash flow. Look for large changes in deferred revenue, payables, prepaid compute, and capitalized costs that could make accounting profit look stronger than cash generation.
    3. How binding are the compute commitments? A reported $1.25 billion monthly compute agreement associated with Colossus clusters, whose full cost was expected to begin appearing in the second half of 2026, is a major unverified input. Check the filing for duration, minimum-purchase terms, unused-capacity risk, and the ability to renegotiate.
    4. How durable is enterprise demand? Anthropic is estimated to have generated 78% of H1 2026 revenue from business customers. That is attractive only if renewals are strong and revenue is not concentrated among a few contracts. Look for customer concentration, net revenue retention, contract duration, and remaining performance obligations.
    5. Can pricing hold? Lower-cost open-weight models can pressure API prices and give large customers leverage in negotiations. Test whether future gross-margin expansion depends on lower compute cost alone or also assumes stable selling prices.
    6. What are you paying for the outcome? Calculate enterprise value using the offer price, fully diluted shares, debt, and cash. Compare it with trailing revenue, gross profit, GAAP operating results, and cash flow. Do not use the $69.7 billion monthly run rate as though it were audited annual revenue.

    The cleanest way to prepare is to save the current estimates as a provisional worksheet and replace them line by line when official disclosures arrive. Begin with GAAP income, stock compensation, cash flow, compute obligations, partner accounting, customer concentration, and dilution. Only then apply the offering valuation. Anthropic’s estimated profit turn justifies close attention, but no level of growth makes every IPO price attractive.

    References


  • What the Penske AI Overviews Dismissal Means for Publishers

    What the Penske AI Overviews Dismissal Means for Publishers

    If your business depends on Google referrals, the dismissal of Penske Media’s AI Overviews lawsuit does not make the traffic problem disappear. It removes one attempted legal route, while leaving you with the same commercial question: which pages are losing valuable visits, and what should you change?

    The practical lesson is not that publishers must accept every search change without scrutiny. It is that expected organic traffic is not the same thing as a negotiated commitment. You need to manage Google as a distribution channel whose economics can change, not as a party that has promised to deliver a particular audience.

    What the judge decided – and what he did not

    U.S. District Judge Amit P. Mehta dismissed Penske Media’s case because its reciprocal-dealing theory did not identify an actual agreement under which Google promised traffic in exchange for access to the publisher’s content.

    Penske’s theory treated two longstanding activities as an exchange: publishers permitted standard web crawling, and Google sent users to their pages through search results. The court found no sufficiently pleaded bargain behind that pattern. There were no alleged negotiated terms, mutual commitments, or communications establishing that Google owed Penske a specific quantity of traffic – or any traffic at all.

    “An expectation is not an agreement.”

    U.S. District Judge Amit P. Mehta

    That distinction matters. Penske alleged that Google’s near-90% search dominance enabled it to use publisher material in AI summaries without paying for it. It also alleged that AI Overviews appeared on roughly 20% of searches linking to its sites and contributed to a one-third decline in affiliate revenue by late 2024. Those figures describe Penske’s allegations; they are not universal benchmarks for every publisher and were not transformed into judicial findings about causation.

    The dismissal is therefore not a finding that AI Overviews cause no economic harm. Mehta explicitly acknowledged the difficult position of publishers and the wider consequences for journalists, educators, and online creators. The missing element was a legally plausible reciprocal agreement, not an allegation of damage.

    This was also the first lawsuit from a major U.S. publisher targeting Google AI Overviews, which makes it tempting to treat the outcome as a verdict on every possible dispute over AI-generated search answers. That reading is too broad. The reported basis for dismissal was the failure of this antitrust theory, under these pleaded facts. For publishers, the immediate consequence is narrower but still important: years of receiving search traffic did not, by themselves, create an enforceable traffic entitlement.

    Key takeaways for publishers and SEO teams

    • The court rejected the alleged reciprocal bargain; it did not find that publishers suffered no traffic or revenue damage.
    • Organic visibility is commercially valuable, but an expectation of referrals is not the same as a contract guaranteeing them.
    • Penske’s exposure and revenue figures belong to Penske’s allegations. Do not apply them to your site without page- and query-level evidence.
    • An AI Overview citation, a conventional ranking, a click, and a conversion are four different outcomes. Measure them separately.
    • Your response should combine search visibility work with stronger reasons to visit, convert, return directly, or join an owned audience.

    Measure AI Overview exposure as a business risk

    An analyst examines abstract content tiles and visitor pathways, some of which stop at translucent summary panels before reaching a publication.

    A sitewide traffic graph cannot tell you whether AI Overviews are the problem. Search demand, rankings, result-page layouts, content changes, seasonality, tracking failures, and monetization changes can move at the same time. Start with the pages and queries connected to revenue, then separate visibility loss from click loss and revenue loss.

    1. Define commercially meaningful page groups. Separate affiliate comparisons, advertising-supported explainers, lead-generation pages, subscription entry points, and content that primarily supports brand discovery. A lost visit does not have the same value across those groups.
    2. Create an observation log for important queries. Record the query, intent, observed presence of an AI Overview, whether your domain appears in it, your conventional result visibility, the landing page, and the observation context. Retain dated result-page captures so later analysis is not based on memory.
    3. Measure each layer of the funnel. Track impressions and search visibility, clicks and click-through rate, on-page conversion, revenue, and revenue per visit. A decline at one layer does not prove a decline at every layer.
    4. Compare like with like. Analyze equivalent page types and comparable periods. Annotate ranking changes, redesigns, content updates, offer changes, tracking deployments, and other result-page features that could provide a competing explanation.
    5. Attach a decision to every monitored cohort. Decide whether the evidence calls for maintaining, rebuilding, diversifying, testing, or simply gathering more observations. Monitoring without a decision rule becomes reporting theater.

    Do not use Penske’s alleged one-third affiliate revenue decline as a forecast for your own business. Use it as a prompt to connect search behavior to money. A mention in an AI result may have visibility value, but it does not pay a publisher’s costs unless it produces a measurable downstream effect.

    Observed patternWhat it may meanYour first decision
    Impressions remain stable while clicks and click-through rate fall on queries showing AI OverviewsYour pages may still be exposed, but fewer searchers need to leave the results pageStrengthen the reason to visit and assess whether the remaining visits still convert profitably
    Impressions, conventional visibility, and clicks all fallRanking, demand, indexing, or broader result-page changes may be involvedInvestigate those variables before assigning the entire decline to AI Overviews
    Clicks fall while conversion rate or revenue per visit risesYou may be receiving fewer but more qualified visitorsEvaluate contribution and profit, not sessions alone
    Traffic remains stable while conversion or revenue fallsThe larger problem may be tracking, monetization, offer quality, or page experienceAudit the commercial funnel before rebuilding content for AI search

    This framework will not prove legal causation on its own. It will give you a better operating diagnosis and a cleaner evidence trail than a single before-and-after traffic chart.

    Give readers a reason to continue past the generated answer

    A reader walks past a shallow translucent summary card toward a warmly lit space filled with reporting materials and investigative work.

    A page that does nothing beyond restating a short factual answer is especially exposed when a search feature can provide that answer directly. The response is not to obscure the answer. It is to make the page useful after the answer has been understood.

    Build three distinct layers into important content

    • The answer layer: State the answer clearly, define important terms, identify relevant entities, and make dates or qualifications explicit. This helps readers verify quickly that the page addresses their question.
    • The evidence layer: Support the answer with material you genuinely possess, such as original reporting, primary data, a transparent methodology, documented testing, expert analysis, or useful visual evidence. Do not manufacture novelty merely to appear original.
    • The action layer: Help the reader complete the next task with a calculator, decision framework, comparison method, configuration checklist, downloadable template, current inventory, or another function that cannot be replaced by a one-paragraph summary.

    For AI SEO and generative engine optimization, optimize citation and conversion as separate jobs. Clear structure, consistent entity names, meaningful headings, and accurate structured data can make content easier for machines to interpret. They do not create a contract for inclusion, compensation, ranking, or traffic. JSON-LD should describe what is visibly true on the page; it should never contain unsupported claims added solely for an AI system.

    Then inspect the post-click experience. If the title promises a comparison, the page should make comparison easy. If the searcher needs a decision, show the criteria and the tradeoffs. If the information changes, explain how it is maintained and make the update date meaningful. The reader should encounter additional value immediately, not after an extended preamble.

    Make portfolio decisions based on replaceability

    Classify content by how easily its value can be compressed into a generated answer:

    • Defend high-value, differentiated pages. Keep their facts current, improve their evidence, and remove friction between the search landing point and the useful feature or commercial action.
    • Rebuild commodity pages that still serve a real audience. Add decision support, proof, maintenance discipline, or a practical tool instead of merely adding more words.
    • Diversify around valuable topics. Offer relevant email updates, alerts, accounts, communities, or direct-use tools where those features solve an actual recurring need. The purpose is to create a consensual return path, not to force a signup before delivering value.
    • Consolidate cautiously. Do not delete or noindex pages merely because an AI Overview appeared for a query. Removing indexed content can sacrifice remaining visibility and links. Preserve performance data, choose a genuinely relevant destination, and plan redirects before consolidating anything.

    Affiliate-dependent templates deserve particular scrutiny because Penske tied its claimed damage to affiliate revenue. Look beyond word count. Ask whether the page offers real product judgment, explains its selection method, distinguishes user needs, and remains accurate. If its only function is to restate information available everywhere else, adding generic prose will not repair its economics.

    Keep evidence that supports decisions, not just frustration

    The ruling exposes a gap between business harm and the evidence required for a particular legal claim. Publishers may experience both traffic loss and weaker monetization, yet still lack proof of a contractual or reciprocal commitment. If the issue may reach executives, a trade body, a regulator, or legal counsel, keep an evidence file that preserves the distinction.

    • Dated captures of the relevant result pages, including the query and observation context.
    • A record of whether your URL appeared conventionally, appeared as an AI Overview citation, appeared in both places, or did not appear.
    • Page- and query-group performance showing impressions, clicks, click-through rate, conversions, and revenue where available.
    • A change log covering content edits, technical releases, ranking movements, monetization changes, and analytics changes.
    • The method used to calculate any claimed loss, with assumptions and competing explanations stated plainly.
    • Applicable contracts, licenses, platform terms, negotiated commitments, and communications. Preserve versions instead of relying on recollection.

    Business analysis asks whether a platform change damaged your economics. Legal analysis asks whether the facts satisfy the elements of a viable claim. Those are connected questions, but they are not interchangeable. If you are considering litigation, licensing action, or a platform restriction that could affect discoverability, have qualified legal counsel evaluate the live facts and current law; an SEO analysis is not a substitute for legal advice.

    In your next reporting cycle, split the queries where you observe AI Overviews from the rest of your search portfolio and connect both groups to page-level outcomes. Then assign one response to each important content group: defend it, rebuild it, diversify its acquisition path, or continue monitoring it. That gives you a decision system even when the legal and product environment remains unsettled.

    Google referrals can remain valuable without being guaranteed. Treat them as platform-dependent distribution, preserve evidence when the economics change, and invest in content people have a reason to visit rather than merely summarize.

    References


  • How to Run an AI Citation Source Audit That Drives Action

    How to Run an AI Citation Source Audit That Drives Action

    You can rank well in traditional search and still be nearly absent from the pages AI assistants use to support answers about your market. When that happens, publishing more content without inspecting the citation trail is guesswork.

    An AI citation source audit shows which domains ChatGPT, Gemini, and Claude cite for your brand, which competitors those sources favor, and where a content or PR intervention has a realistic path to influence. The goal isn’t a longer spreadsheet. It is a defensible list of actions tied to actual prompts, answers, claims, and URLs.

    Define the decision your audit needs to support

    “Where does AI get its information about us?” is too broad to guide an audit. The useful version names the decision you need to make. You might need to decide which publications to pitch, which inaccurate claims to correct, which comparison pages to improve, or where a competitor has earned third-party validation that you lack.

    Write that decision at the top of your worksheet. It prevents the audit from drifting into a collection of interesting but unactionable mentions.

    Then separate three things that teams often collapse into one metric:

    • Brand mention: Your name appears in an answer, whether or not a link supports it.
    • Owned citation: The answer links to a page on your domain.
    • Third-party citation: The answer uses another domain to substantiate a claim about you, your competitors, or the category.

    Those outcomes require different responses. A mention without a citation may reveal awareness but provides no evidence about which external page shaped the answer. An owned citation creates a content-maintenance task. A third-party citation can become a media, partnership, reputation, or listing opportunity.

    Set the audit boundary before collecting anything. Record the market, audience, geography, language, products, competitors, and buying stages that are in scope. If the business has several unrelated product lines, audit them separately. Otherwise, a strong citation footprint for one line can conceal a serious gap in another.

    Your basic record should be the individual prompt-and-answer pair, not merely the cited domain. Keep these fields:

    • Exact prompt
    • Prompt theme and journey stage
    • AI platform and visible mode or model label
    • Date and relevant account, location, or language context
    • Brand mentioned or absent
    • Competitors mentioned
    • Exact claim associated with the citation
    • Cited page URL and root domain
    • Citation placement, such as inline or in a linked source list
    • Whether the page genuinely supports the claim
    • Accuracy or reputation issue
    • Recommended owner and next action

    This level of detail matters because the same domain can help in one answer and hurt in another. A simple domain tally cannot show that distinction.

    Build prompts around real discovery and buying decisions

    A brand-name prompt tests recognition. It does not represent the full discovery journey. If every test includes your brand, you can produce reassuring results while missing the prompts where an unfamiliar buyer first encounters the category.

    Build a prompt matrix that covers different kinds of intent:

    • Category discovery: Questions asking what kinds of solutions exist for a problem.
    • Problem diagnosis: Questions describing a symptom, obstacle, or desired outcome without naming a product category.
    • Comparison: Questions asking how approaches, products, or named competitors differ.
    • Recommendation: Questions seeking suitable options for a defined use case or audience.
    • Validation: Questions about trust, evidence, reputation, limitations, or suitability.
    • Implementation: Questions about setup, migration, integration, or ongoing use.
    • Branded evaluation: Questions that name your organization and ask what it does, who it serves, or how it compares.

    Use the language a buyer would use before they know your internal terminology. Product teams tend to write prompts with precise feature names. Buyers often describe the job, risk, or constraint instead. Include both forms and keep them as separate rows so you can see whether the citation landscape changes.

    Do not cram several intentions into one prompt. A question that asks for a recommendation, comparison, price assessment, implementation plan, and risk analysis creates an answer that is difficult to classify. Each prompt should expose one main decision.

    Keep the testing conditions visible

    AI answers can vary with the platform, available search mode, conversation context, and phrasing. That does not make auditing pointless. It means your evidence needs enough context to be interpreted later.

    Run each prompt in a fresh conversation unless conversation history is deliberately part of the scenario. Save the exact wording rather than a cleaned-up paraphrase. Record whether web access or a comparable source-discovery mode appeared to be active. If you rerun a prompt, preserve both observations instead of replacing the earlier result.

    Avoid teaching the assistant about your brand before asking the test question. Pasting your positioning statement and then asking which companies lead the category measures how the assistant uses supplied context, not whether your brand is discoverable independently.

    Capture the citation trail without losing the evidence

    A hand links an AI answer fragment to a source-page card and an organized evidence packet on a desktop.

    Collection is where a useful audit often turns into an unreliable one. Copying only the domain discards the relationship among the prompt, the answer, the claim, and the cited page. Preserve that relationship with a consistent workflow.

    1. Run the prompt exactly as written. Do not add a clarifying follow-up until the original answer has been saved.
    2. Capture the complete answer. Preserve the wording and citation placement, not just the sentence containing your brand.
    3. Extract every cited URL. Keep the full page URL and add the root domain in a separate field.
    4. Connect each URL to a claim. Record what the link appears to support: a recommendation, fact, comparison, warning, or general background statement.
    5. Open the page. Confirm that it exists, is the intended page, and contains evidence relevant to the associated claim.
    6. Label the result. Mark your brand as cited, mentioned without citation, omitted, or represented inaccurately. Record the same outcome for named competitors.
    7. Assign the next action. Choose a concrete route such as correct, update, pitch, contribute, earn inclusion, monitor, or take no action.

    Do not treat every displayed link as valid evidence. A URL can resolve while failing to support the sentence beside it. It can also point to an old page, a derivative summary, or a page about a similarly named entity. These are accuracy findings, not successful citations.

    Also distinguish citation placement. An inline link attached to a specific claim is different from a page included in a general source list. Both belong in the audit, but they should not be interpreted as equivalent support.

    Normalize URLs only after preserving the original. Remove obvious tracking parameters in your analysis field, consolidate equivalent URL variants, and keep separate pages separate. Collapsing everything to the domain level too early hides which asset type is actually being selected.

    Turn the URL inventory into an opportunity map

    A strategist examines a landscape of source tiles, citation paths, open gateways, and symbols for content, outreach, and reputation work.

    The first useful output is not a leaderboard. It is a map of how information travels from publishers, communities, reference pages, directories, vendors, and your own site into answers that affect the buyer’s decision.

    Classify every cited page by role:

    • Owned information: Your product, company, documentation, help, or editorial pages.
    • Independent editorial coverage: Reporting, analysis, reviews, or industry commentary.
    • Comparison and recommendation content: Roundups, alternatives pages, rankings, and buying resources.
    • Reference material: Definitions, standards, research, or other evidence-led resources.
    • Community discussion: Forums, question-and-answer threads, and other user-contributed discussions.
    • Directory or profile data: Listings and structured company or product records.
    • Commercially connected content: Partner, affiliate, reseller, marketplace, or vendor-controlled pages.

    The classification tells you which intervention is plausible. You can update an owned page directly. You may be able to correct a directory profile. You can pitch an editor with evidence, but you cannot rewrite independent coverage. You can participate transparently in a community, but manufacturing endorsements would create a reputation problem rather than solve one.

    Calculate a compact set of signals while retaining the underlying rows:

    SignalHow to read itDecision it supports
    Citation coveragePrompts in which your brand has supporting citations relative to the prompts testedShows where you are present, not whether the representation is favorable or accurate
    Accuracy statusCitations whose associated claims are accurate, incomplete, outdated, or wrongSeparates visibility work from correction work
    Competitive gapPrompts where competitors receive relevant support and your brand is absentIdentifies the query themes and third-party pages worth investigating
    Repeat domain presenceDomains appearing across several relevant prompt themes or platformsHighlights relationships and placements with broader potential value
    Domain concentrationThe extent to which citations depend on a narrow group of domainsReveals whether visibility is resilient or reliant on a small set of intermediaries
    Source-role mixThe balance among owned, editorial, community, reference, directory, and commercial pagesShows whether the next move belongs to content, PR, partnerships, reputation, or data maintenance

    Keep results separated by platform, prompt theme, and journey stage before calculating any overall view. A combined total can hide an important pattern, such as strong citations for implementation questions but no presence in category discovery or comparisons.

    Prioritize with judgment rather than a decorative score. Put each finding into an action tier:

    • Correct now: A cited page supports a materially wrong, outdated, or confusing claim about your organization.
    • Pursue next: A relevant independent domain appears repeatedly in prompts tied to an important buyer decision, and there is a legitimate route to contribute evidence or earn consideration.
    • Strengthen: Your owned page is cited but does not answer the associated question clearly, or a substantiated first-party resource is missing.
    • Monitor: A page appears in an isolated or low-relevance context with no sensible intervention.
    • Decline: The opportunity requires payment without clear disclosure, manufactured sentiment, or another tactic that would undermine trust.

    A high-frequency domain is not automatically your best target. Relevance, claim accuracy, editorial fit, and a credible access route matter more than raw appearances. A smaller specialist publication that is repeatedly cited for your buyer’s exact concern may deserve attention before a large general-interest domain.

    Convert the audit into content, PR, and reputation work

    Every priority finding needs an owner, an asset, an ask, and a verification step. Without those fields, “improve AI visibility” becomes an indefinite objective that no team can execute.

    Match the action to the cited page’s role:

    • Owned page: Correct the claim, answer the relevant question directly, show the supporting evidence, and keep important entity details consistent across the site.
    • Editorial coverage: Identify the coverage gap and offer verifiable information, an expert contribution, a useful dataset, or a legitimate update. Do not frame the outreach as a request to manipulate an AI answer.
    • Comparison page: Determine the inclusion criteria before contacting the publisher. Supply factual differentiation and evidence that helps the page serve its readers.
    • Reference resource: Create or expose the strongest substantiation you can stand behind. Unsupported marketing language is not a replacement for evidence.
    • Directory or profile: Correct missing, inconsistent, or outdated fields through the available listing process, then verify the public record.
    • Community discussion: Participate only where you can answer the question transparently and disclose your connection. Treat recurring complaints as product or support intelligence, not as threads to overwhelm with promotion.
    • Inaccurate third-party claim: Document the precise error and the evidence needed to correct it. Use the publisher’s correction route rather than demanding favorable wording.

    For each target, write a one-line action brief: the prompt gap, the cited page, the claim you need to support or correct, the evidence available, the outreach or publishing route, and the person responsible. That brief is specific enough to become a task without another strategy meeting.

    On your own site, make the supporting page easy to interpret. Use a stable URL, a descriptive title, a direct answer, clear entity names, visible authorship or ownership where relevant, an update date when freshness matters, and links to the evidence behind material claims. Accurate structured data can clarify what a page represents, but it cannot turn a weak or unsupported assertion into a credible citation.

    Do not publish a new page for every missed prompt. Group gaps that share the same underlying intent and determine whether an existing page should be improved first. A page that clearly resolves the buyer’s question is more useful than a stack of near-duplicate pages designed around minor wording variations.

    Recheck the relevant prompts after a meaningful change has had time to become publicly accessible. Preserve the earlier observation, record the new one, and compare the exact citation trail. A changed answer can be encouraging, but it does not prove that a single edit caused the change. Look for repeated movement across related prompts before treating it as a durable result.

    Key takeaways

    • An AI citation source audit measures which pages and domains support answers, not merely whether an assistant recognizes your brand.
    • Test discovery, comparison, recommendation, validation, implementation, and branded prompts instead of relying on brand-name questions alone.
    • Preserve the prompt, answer, claim, full URL, citation placement, and testing context. A domain-only list is not enough.
    • Verify that every cited page actually supports the associated claim before counting it as useful visibility.
    • Prioritize accurate, relevant domains that recur around important buyer decisions and have a legitimate route for contribution or correction.
    • Translate every finding into a content, PR, listing, partnership, or reputation task with a named owner and a recheck condition.

    Start with one decision-critical product area and build the prompt matrix before opening an AI assistant. Once the evidence is captured cleanly, you will know whether the next move is to repair your own information, earn third-party validation, correct a misleading claim, or leave a low-value citation alone.

    References


  • How to Diagnose and Fix Google Ads Destination Disapprovals

    How to Diagnose and Fix Google Ads Destination Disapprovals

    Your landing page opens normally, yet Google Ads says the destination isn’t working. That apparent contradiction is the clue: the problem may not be the page you see. It may be the exact URL in the ad, a tracking hop, a deep link, a redirect, an access rule, or the response served specifically to Google AdsBot.

    The fastest route back to a working campaign is to trace the complete destination path as a new, unauthenticated visitor and as Google AdsBot would encounter it. That turns a vague disapproval into a specific URL, response, or configuration problem.

    Key takeaways

    • A page loading in your browser does not prove that Google AdsBot can load it.
    • Test the exact final URL, tracking URL, redirect chain, and deep link used by the disapproved ad.
    • The terminal landing page should return HTTP 200 without requiring authentication.
    • Look for 403, 404, and 500 responses as well as DNS failures, timeouts, malformed responses, redirect loops, private IP addresses, and unfinished pages.
    • If Google Ads reports an invalid final URL during campaign setup, verify that a required asset group exists before changing a working landing page.

    Start with the request Google actually evaluates

    Magnifying lens inspecting the first node of a web request path that branches through redirects, a deep link, a server, and an automated crawler.

    Do not begin by typing your homepage into a browser. Begin with the exact destination attached to the disapproved ad. Copy the complete value, including the protocol, hostname, path, query parameters, and any tracking information. A homepage can work perfectly while a campaign-specific path returns an error.

    Think of the destination as a chain rather than one page:

    <!– wp:list {
  • AI Overviews on Branded Searches: A Practical Audit Plan

    AI Overviews on Branded Searches: A Practical Audit Plan

    You can still rank first for your own name and lose control of the first impression. When a Google AI Overview appears on a branded query, it can frame your company, products, policies, or reputation before the searcher decides whether your result deserves a click.

    Your job is not to make every overview disappear or chase every citation. You need a repeatable way to find the queries that matter, distinguish a genuine brand risk from a harmless summary, repair weak information at its origin, and measure whether search behavior changes.

    Ranking first no longer tells you how Google frames your brand

    The scale of the change makes branded AI visibility worth treating as a standard search responsibility. In one tracked branded-keyword set, AI Overview presence rose from about 26% at the start of September to more than 80% late in the month, with a peak of 90.48% on September 27. A separate SerpApi check found AI Overviews for 93 of 100 enterprise brands.

    Those figures are a warning to monitor, not a universal incidence rate or a forecast for your site. The tracked terms were checked once per day across all markets and devices, and an overview counted as present whether or not it cited the brand. The enterprise-brand check was a separate snapshot. Google had not announced a corresponding change when the surge was observed.

    This distinction matters. An AI Overview can appear on your branded query without using your site as evidence. It can also cite you while compressing a qualification that matters to a buyer. Presence, citation, accuracy, framing, traffic, and business impact are separate things. Track them separately.

    Key takeaways

    • Treat branded AI Overviews as a search, content, and reputation surface rather than another ranking position.
    • Monitor high-intent and high-consequence brand modifiers, not only your exact company name.
    • Record what the overview says, which pages it cites, whether an owned page appears, and which claims need correction.
    • Repair canonical facts and contradictory content before trying to influence the wording of a generated answer.
    • Measure branded clicks and outcomes directly. Wider AI Overview presence does not, by itself, prove traffic loss.

    Build your monitoring set around real brand decisions

    Blank query cards are grouped around objects representing a company, product, policy, purchase decision, and reputation, with priority markers and a magnifying glass.

    A search for your bare brand name is only the starting point. The more revealing queries combine the brand with a decision, concern, or task. That is where an inaccurate synthesis can change what someone buys, believes, or does next.

    Build a stable query set from your search-query data, customer questions, support records, sales objections, and reputation monitoring. Group the terms by the decision behind them:

    • Identity: your brand name, what the company does, who it serves, and how it differs from similarly named entities.
    • Commercial: brand plus pricing, plans, products, availability, integrations, demo, or purchase terms.
    • Evaluation: brand plus reviews, alternatives, comparisons, complaints, reliability, or legitimacy.
    • Service and policy: brand plus login, contact, cancellation, refund, support, privacy, security, returns, or warranty.
    • Named entities: important products, locations, programs, and publicly associated people whose details affect how the brand is understood.

    Do not prioritize by search volume alone. A low-volume cancellation, security, or product-eligibility query can create more damage than a high-volume neutral query. Give each query an intent label and a consequence label. This lets you separate commercially important or reputationally sensitive questions from routine navigational searches.

    Check the list under repeatable conditions. Use the same market, device class, and signed-in state where possible. For every observation, preserve enough information to compare it later:

    • The exact query, not a shortened topic label.
    • The date, market, device class, and relevant session conditions.
    • Whether an AI Overview appeared.
    • The complete wording or a screenshot of the answer.
    • Every cited page and the order in which citations appeared.
    • Whether any cited page is controlled by your organization.
    • Each factual claim that is correct, outdated, incomplete, unsupported, or false.
    • The associated branded impressions, clicks, click-through rate, and business outcomes, kept outside the content-quality judgment.

    That last separation prevents a common analytical mistake. An overview can be factually poor without producing a measurable traffic decline, and it can be factually accurate while changing click behavior. You need both views to decide what deserves action.

    Grade the answer by consequence, not by whether you like it

    A generated description does not become a defect merely because it is less flattering than your marketing copy. Your audit needs labels that another person can verify. Start with factual accuracy, necessary context, citation support, and likely consequence.

    FindingWhy it mattersNext move
    Materially false claimIt could send a customer to the wrong action or create a false belief about the company, product, price, access, or policy.Document the correct fact, identify the likely conflicting evidence, and escalate it ahead of ordinary optimization work.
    Outdated factThe answer may once have been correct but no longer reflects a current offer, feature, location, policy, or relationship.Strengthen the current canonical page and clearly mark or update obsolete owned material.
    Qualification removedA broadly correct statement becomes misleading when a market, plan, eligibility rule, date, or other condition disappears.Put the condition next to the claim on the canonical page rather than burying it in a footnote or separate document.
    Claim unsupported by citationsThe answer goes beyond what its cited pages substantiate, making the synthesis difficult to verify.Capture the mismatch, then improve the clearest first-party evidence for the underlying question.
    Third-party-heavy citation setYour brand may be described mainly through reviews, directories, forums, or commentary even when an owned explanation should exist.Determine whether your page fails to answer the query directly before treating the third-party citations as the problem.
    Accurate but unfavorable descriptionThe answer may reflect a real customer, policy, product, or reputation problem rather than an information-retrieval failure.Address the underlying issue. Rewording your own page will not make a substantiated concern disappear.
    Accurate and adequately framedThe overview creates no material information problem even if it does not use your preferred language.Log it and monitor it. Do not manufacture work merely to replace neutral wording.

    Escalate first when a claim is both materially wrong and connected to an important decision. A false statement about whether a product is available, how an account is accessed, or what a policy permits deserves faster attention than an awkward but harmless company description.

    An owned citation is useful, but it is not a passing grade by itself. Read the generated claim against the cited passage. If your page states that a condition applies only to one plan or market, but the overview presents it as universal, the citation has not prevented a meaning error.

    Repair the evidence behind the answer

    A strategist reconnects several generic source documents so they feed through clear paths into a stable digital answer panel.

    You cannot directly edit an AI Overview. You can make the underlying information clearer, more consistent, and easier to verify. Work from the highest-consequence defect outward.

    1. Choose one canonical owned page for each important question cluster. A pricing query needs a current pricing page, not a vague feature page. A cancellation query needs a current policy or help page, not a promotional FAQ that avoids the actual process.
    2. Answer the question in visible copy. Use the exact company and product names. State the direct answer before the supporting detail. If the answer changes by market, plan, eligibility, or date, place that qualification beside the claim.
    3. Reconcile contradictions across owned material. Check product pages, support content, policy pages, legacy posts, downloadable documents, profiles, and location pages. Mark outdated material clearly and direct readers to the current record.
    4. Make structured data corroborate the page. Encode only facts supported by visible content and keep the values aligned with the canonical wording. Treat structured data as machine-readable confirmation, not a command that guarantees a particular overview or citation.
    5. Classify every influential third-party citation. Decide whether it is accurate, outdated, false, or opinion. For a verifiably false or stale statement, provide the publisher with concise evidence and the canonical correction. If the criticism is accurate, fix the underlying issue instead of pursuing removal simply because the page is unfavorable.
    6. Log the change and recheck the same query. Record what changed, where it changed, and which claim you expected it to clarify. A later overview change is useful evidence of movement, but it is not proof that one page edit caused the result.

    Avoid publishing a near-duplicate page for every branded modifier. That creates more places for facts to drift. One strong page can answer a coherent group of questions as long as its purpose, headings, and qualifications are explicit. The goal is query-to-answer alignment, not content volume.

    Also resist the urge to rewrite everything in promotional language. Generated answers need verifiable facts. Clear scope, current conditions, named products, and direct policy wording are more useful than unsupported claims of leadership or quality.

    Measure traffic impact without inventing a CTR story

    Wider AI Overview coverage does not prove that branded clicks have fallen. Neither the tracked branded-keyword series nor the separate enterprise-brand check measured clicks, leaving the actual branded CTR effect unknown. Treat traffic loss as a question to test in your own data, not a conclusion supplied by presence alone.

    Keep a stable query panel so the denominator does not change every time you run the audit. Track these measures by query cluster:

    • AI Overview presence: checked queries that triggered an overview divided by all checked queries.
    • Owned-citation coverage: triggered overviews containing at least one owned citation divided by all triggered overviews.
    • Material accuracy: high-consequence overviews without a material factual or qualification error divided by all high-consequence overviews reviewed.
    • Source mix: the balance of owned pages, publishers, review sites, directories, forums, and other cited page types.
    • Search response: impressions, clicks, and click-through rate for the same branded query clusters.
    • Business response: the relevant purchases, leads, account actions, support contacts, or other outcomes from branded landing sessions.

    Maintain both an unweighted query view and an impression-weighted view. The unweighted view stops a high-volume navigational term from hiding a serious low-volume error. The weighted view shows where changes could affect the largest share of observed search demand.

    Annotate other events that can change branded demand or result-page behavior, including campaigns, publicity, product changes, seasonality, and additional search features. If AI Overview presence rises while clicks and business outcomes remain stable, there is no evidence of an emergency. If CTR falls while conversions remain stable, investigate whether fewer low-intent visits explain the difference before declaring damage. If clicks and meaningful outcomes fall persistently within the same high-intent cluster, inspect the overview, citations, landing result, and other result-page changes together.

    A materially false answer remains a brand problem even when traffic looks normal. Conversely, an accurate overview is not automatically harmful because it answers part of the question without a click. CTR is a diagnostic measure; accurate representation and valuable business outcomes are the goals.

    Start with a small, consequential baseline: assemble your highest-intent and highest-risk branded modifiers, capture the current answers and citations, and correct the first material inconsistency you can verify. Once that record exists, the next AI Overview change becomes an observable search event rather than an anecdote.

    References


  • Meta Descriptions and Google Snippets: What You Control

    Meta Descriptions and Google Snippets: What You Control

    You wrote a precise meta description, checked the search result, and found different copy under your title. That does not mean the tag is broken. Your meta description is the summary you offer; the Google snippet is the query-specific text Google decides to display.

    The practical job is therefore bigger than polishing one HTML tag. You need to write a strong snippet candidate and make the page itself easy to excerpt. When both layers communicate the same answer, Google has better material whether it keeps your description or replaces it.

    Your meta description is a candidate, not a command

    A meta description is a short summary stored in a page’s HTML. It normally does not appear in the visible page content, and it is not a direct ranking factor. Its immediate value is communicative: it tells a searcher, and potentially a machine system, what the page offers.

    Google is free to show different text. Older analyses found that it replaced the supplied description on roughly two out of three searches. Those analyses are not recent enough to treat that figure as a current rewrite rate, but the directional lesson remains useful: you cannot assume that one fixed sentence will appear for every query.

    The reason is straightforward. A single page can rank for searches with different wording and slightly different intentions. Google may find a passage in the page that answers a particular query more directly than the description you supplied. The snippet can therefore change even when the URL and title remain the same.

    Do not judge a meta description only by whether Google reproduces it word for word. Judge it by two questions:

    • Does it accurately express the page’s primary purpose?
    • If a searcher sees it, does it give them a concrete reason to choose this result?

    If the answer to either question is no, the description needs work. If both answers are yes and Google selects a useful page passage instead, the rewrite may be doing exactly what the query requires.

    Match the description to the page’s real job

    The most common strategic mistake is using the same writing mode everywhere. An informational page and a commercial page are not asking the searcher to make the same decision, so their descriptions should not sound alike.

    Informational pages should give the micro-answer

    If someone has asked a question, state the core answer rather than teasing it. A curiosity gap can attract attention from a person, but it gives a machine little evidence that the page resolves the query. A direct summary serves both audiences.

    Weak: Wondering why Google changed your meta description? The answer may surprise you.

    Stronger: Google may replace a meta description with page text that better matches the query, so the description and the on-page answer need to agree.

    The stronger version does not reveal every supporting detail. It establishes the answer and leaves the page to explain the mechanism, exceptions, and next steps. That is enough reason for the right reader to continue.

    Commercial pages should clarify the choice

    A product, service, or category page still needs persuasion. Lead with what is offered, who it is for, and the most relevant point of differentiation. Then give the reader an appropriate next step. Do not turn commercial copy into a dry definition merely because machines may read it.

    A useful structure is: [offer] for [audience or use case], with [specific, supportable difference]. Compare [decision factors] and choose [next step].

    Only include benefits, prices, availability, guarantees, or features that the page currently supports. A persuasive description that overpromises creates the wrong click and gives Google a reason to prefer other text from the page.

    Build a keepable description in five passes

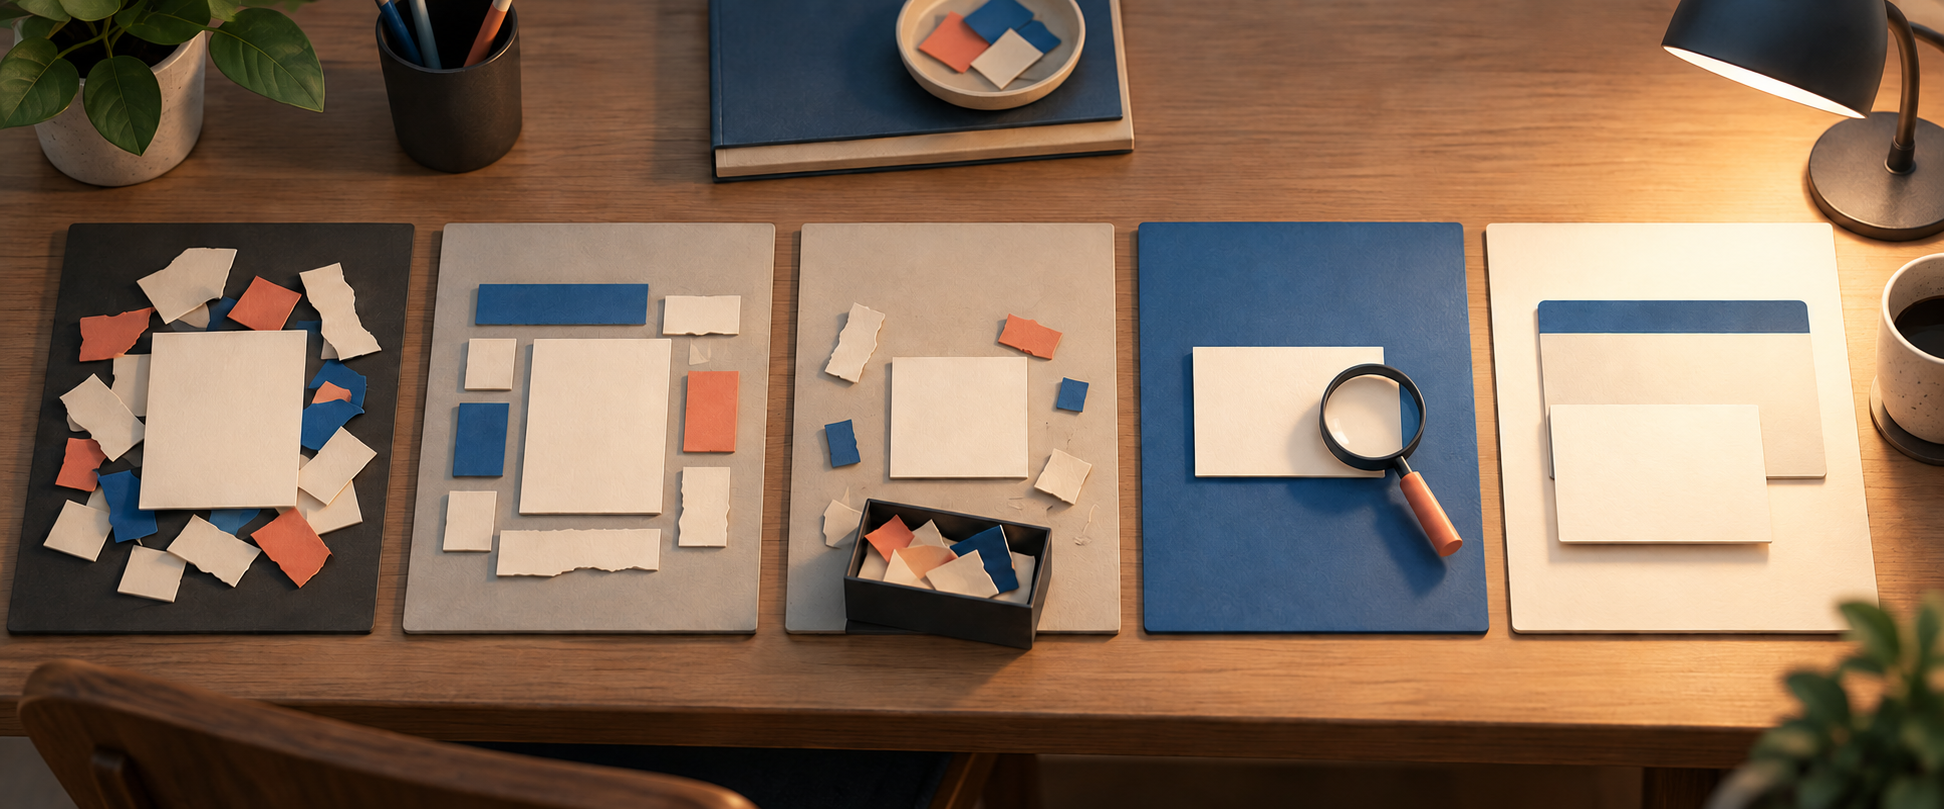
    Five workstations show a blank summary card being organized, aligned, shortened, inspected, and finished beside a webpage.

    You do not need to find a magical wording formula. You need a short editing process that forces the important decisions early.

    1. Name the searcher’s task. Write down the primary question, comparison, purchase, or action the page supports. If you cannot express that task in one line, the page may be targeting too many intentions.
    2. Write the answer or offer first. Begin with what the page establishes, not with scene-setting such as discover, explore, or everything you need to know.
    3. Use the searcher’s language naturally. Include the relevant term when it makes the sentence clearer. Repetition does not turn the description into a ranking signal, and keyword stacking makes the result harder to read.
    4. Front-load the essential meaning. Put the answer, offer, or differentiator before supporting detail. That protects the useful part when the result is shortened on a smaller screen.
    5. Check accuracy and uniqueness. Compare the finished sentence with the visible page, then check that another URL is not using the same description. Each indexable page should have a description written for its own purpose.

    Use about 150 to 160 characters as an editing range, not as a guaranteed display allowance. Pixel width is the real constraint, and the visible amount can vary. A complete thought near the beginning matters more than filling every available character.

    Before publishing, read the description aloud without the title. It should still tell you what the page does. Then read it immediately after the title. It should add useful information rather than repeat the same phrase in a different order.

    Optimize the page that supplies replacement snippets

    Editing the HTML tag alone leaves most of the system untouched. When Google replaces a description, it can draw a more query-relevant passage from the page. You therefore need clear excerpt candidates in the visible content as well.

    • Answer near the relevant heading. Do not make the reader cross several introductory paragraphs before encountering the statement promised by the title.
    • Keep terminology consistent. The title, description, opening, headings, and answer passages should use compatible language for the same concept.
    • Write complete, portable sentences. A sentence that makes sense without the paragraph before it is more useful when extracted as a snippet.
    • Keep claims synchronized. When a process, feature, or conclusion changes, update the page and description together. An old description attached to revised content sends conflicting signals.
    • Separate distinct intentions. If one paragraph mixes a definition, a comparison, and a sales claim, split the ideas so the relevant answer is easier to identify.

    This is also the sensible way to approach AI search. Meta descriptions provide a predictable, machine-readable summary, but they are neither the only signal nor the most important one for systems deciding what to read or cite. Treat the description as a routing label for the page, not as a shortcut to AI visibility. The visible content still has to contain the promised answer.

    Diagnose a rewrite before trying to prevent it

    A rewrite is not automatically a penalty, an implementation error, or proof that Google ignored your work. Start with the query and the usefulness of the displayed text.

    • The replacement accurately answers the query: leave it alone unless it creates a factual or brand problem. Google may have found a better query-specific excerpt than one fixed description could provide.
    • The replacement is irrelevant or contextless: inspect the passage Google selected. Rewrite that section so its meaning is clear, and strengthen the on-page answer associated with the query.
    • The snippet shows outdated information: update both the visible claim and the meta description. Changing only the tag leaves the old text available elsewhere on the page.
    • Several URLs use the same description: replace the duplicates with page-specific summaries. Each description should identify why that particular URL deserves the click.
    • The supplied description is vague but the replacement is specific: revise the description around the concrete answer or offer already present on the page.

    Review descriptions when the page changes, when its intended query changes, or when a claim is no longer true. A calendar-only audit can miss the moment when the description and content drift apart.

    Key takeaways

    • A meta description is your proposed summary; a Google snippet is the text selected for a particular search.
    • Meta descriptions can influence how a result communicates, but they are not direct ranking factors.
    • Informational descriptions should state the micro-answer; commercial descriptions should clarify the offer and choice.
    • Around 150 to 160 characters is a practical editing range, not a guaranteed display limit.
    • Front-load the meaning because truncation can remove the end of the sentence.
    • When Google rewrites a snippet, improve the relevant page passage before endlessly rephrasing the HTML tag.

    Start with one important page. Write down its primary search task, compare that task with the title, description, opening, and clearest answer passage, and remove any contradiction between them. That alignment is the part you control, and it remains useful whether Google keeps your description, assembles another snippet, or a machine evaluates the page for an answer.

    References


  • How to Hire Senior SEO Talent for Judgment, Not Tasks

    How to Hire Senior SEO Talent for Judgment, Not Tasks

    You are not hiring a human backlog. You are hiring someone to decide which search problem is real, which evidence deserves trust, and which work should win scarce support.

    A polished candidate can discuss crawling, content, links, reporting, and AI visibility. The harder test begins when those signals disagree. Organic clicks can fall while conversion and quality indicators improve. Visibility can grow in a market the business cannot serve. An impressive AI score can have no demonstrated relationship to revenue. Your hiring process needs to reveal who can navigate those conflicts without retreating into a generic checklist.

    Start with the decision this person must improve

    Before writing the job description, finish this sentence: We need this person to help us decide and execute…

    The words that follow should describe a business problem, not an SEO department. You may need more qualified demand in a particular industry, better conversion from existing traffic, clearer priorities for a neglected backlog, or someone who can move discovery work through engineering, content, product, PR, and legal. You may need to learn whether visibility in ChatGPT and other AI experiences produces valuable customer behavior. Those are different mandates.

    Build a short role charter before listing responsibilities. It should define:

    • The business problem: What is currently underperforming, uncertain, or blocked?
    • The outcome: What should improve for customers or the business if the hire succeeds?
    • The constraints: Which budgets, markets, technical limits, compliance requirements, or capacity limits are real?
    • The dependencies: Which teams must approve, build, publish, measure, or support the work?
    • The decision rights: What can this person prioritize directly, and where must they persuade others?
    • The non-goals: Which adjacent responsibilities belong to other people?

    The non-goals matter. A description that combines technical SEO, content strategy, AI discovery, analytics, conversion optimization, link acquisition, reporting, and project management may conceal several jobs inside one salary. It also makes evaluation incoherent: one interviewer rewards technical depth, another expects an editorial strategist, and a third wants a cross-functional program leader.

    Decide whether you primarily need a specialist who will complete defined work or a leader who will determine what the work should be. A senior discovery leader may not personally execute every migration ticket or content brief. They should be able to diagnose the system, select a defensible sequence, obtain support, and keep the work connected to a business outcome.

    Build a scorecard that rewards judgment

    Five symbolic assessment objects form a balanced structure while an unnecessary metallic piece is set aside.

    Technical competence remains a threshold requirement. A senior SEO leader must recognize technically plausible explanations, interrogate the right systems, and understand the consequences of a recommendation. But technical fluency should not consume the entire scorecard. One useful hiring model treats SEO- and AI-specific knowledge as roughly 25% of what makes a senior discovery hire effective, with the rest carried by critical thinking, communication, persuasion, prioritization, and business judgment. That percentage is not a universal formula. It is a practical guardrail against hiring the candidate with the largest vocabulary.

    Use evidence-based dimensions instead of adjectives such as strategic, data-driven, or collaborative. Those words are too easy to claim and too difficult to score consistently.

    DimensionWhat to ask the candidate to doStrong evidenceRisk signal
    Problem framingInterpret a situation in which search and business metrics disagreeSeparates the observed symptom from the decision the business must makeAccepts the prompt’s framing and immediately recommends familiar tactics
    Measurement judgmentIdentify what must be validated before comparing performanceQuestions tracking, consent, definitions, time comparisons, and the relationship between proxy and outcome metricsTreats every dashboard value as equally reliable and meaningful
    PrioritizationChoose work under a real resource constraintNames what will be deferred, explains the opportunity cost, and states what could change the orderLabels most of the backlog urgent or critical
    Business connectionMap search demand to capacity, conversion, and revenueDistinguishes available demand from demand the business can profitably serveTreats rankings, traffic, or AI mentions as the final objective
    InfluenceExplain the same recommendation to technical and commercial stakeholdersChanges the language and level of detail while preserving the reasoningUses channel jargon in place of a business case
    Technical and AI literacyDevelop and test plausible causes across conventional and AI-mediated discoveryKnows what evidence would support or falsify each explanationRepeats platform announcements or best practices without connecting them to the case

    Listen for causal reasoning. A candidate should be able to say: this observation could have several causes; this is the evidence that would separate them; this decision is safe while we investigate; and this is the point at which we would change course. Memorized recommendations rarely contain that structure.

    Do not penalize a candidate for challenging the premise. Senior judgment often appears as "I need more information." The phrase becomes useful only when the candidate identifies the missing information, explains why it changes the decision, and offers a provisional path instead of stopping the conversation.

    Use an ambiguous work sample instead of a trivia test

    A candidate sorts ambiguous evidence cards and selects one resource token while two interviewers observe.

    A realistic exercise should contain enough evidence for a recommendation and enough ambiguity to make a checklist inadequate. Keep it close to your operating environment, but fictionalize sensitive data so every candidate receives the same case.

    A useful brief could contain these conditions:

    • Organic clicks are down, while conversion and customer-quality indicators are up.
    • Keyword trends and an AI visibility score are available, but neither has been connected conclusively to the business outcome.
    • Some markets have unused service capacity, while others cannot absorb much more demand.
    • An analytics or cookie-consent change may have affected the year-over-year comparison.
    • Engineering can contribute only 40 hours during the quarter.

    Ask the candidate to make a recommendation, not produce an audit. The deliverable should require them to:

    1. Define the decision the business actually needs to make.
    2. Identify the assumptions and measurement questions that could materially change that decision.
    3. Offer a working recommendation while those questions are being resolved.
    4. Allocate the constrained engineering capacity and state what will not be done.
    5. Choose outcome measures that distinguish commercial progress from visibility alone.
    6. Explain what new evidence would cause the plan to change.

    A weaker response usually expands the scope. It proposes a technical audit, content refresh, cleanup program, link initiative, and AI visibility project at the same time. Every tactic may be legitimate in isolation, but the candidate has not shown why any of them deserves priority in this situation.

    A stronger response first tests whether the apparent decline is a problem. If conversions and customer quality are improving, the lost clicks may include less valuable demand, the measurement may have changed, or another part of the journey may be performing better. The candidate should not assume which explanation is correct. They should specify how to tell them apart.

    Market capacity creates another revealing choice. Improving visibility where the business cannot serve more customers may produce attractive charts and operational frustration. A candidate with business judgment will examine where additional demand can become a completed sale, appointment, subscription, or other real outcome. They may prioritize a market with unused capacity even when its search opportunity looks less glamorous.

    Treat the AI visibility metric the same way. It is a hypothesis-generating signal until the candidate can show a credible relationship to customer discovery and business results. The right next step may be a bounded test, better attribution, or closer analysis of the queries and citations involved. It is not automatically a mandate to maximize the score.

    Use a short panel discussion after the exercise. Grade the candidate’s reasoning, questions, tradeoffs, and communication – not whether the final recommendation matches an answer your team decided in advance. If there is only one answer you will accept, you are testing compliance rather than judgment.

    Interview for tradeoffs, influence, and restraint

    The best interview questions make the candidate choose. Broad prompts such as "How would you improve our SEO?" reward confident improvisation. Constrained prompts reveal whether the person can protect the business from low-value work.

    Questions that reveal diagnosis

    • Organic traffic has declined while qualified conversions have improved. Under what conditions is that good news, bad news, or a measurement problem?
    • Which data would you validate before comparing this period with the previous one, and why?
    • What finding would make you decide not to run a broad technical audit?
    • One market has a visibility gap but no service capacity. Another has spare capacity but lower apparent search demand. How would you choose where to work?
    • Our AI visibility score increased. What would you need to see before treating that increase as business progress?
    • Which recommendation would you make now, and which decision would you deliberately postpone?

    Do not judge the candidate by the number of questions asked. Judge whether each question can change the decision. Asking about a consent implementation that may invalidate a trend is valuable. Asking for every report the company owns may simply delay commitment.

    Questions that reveal leadership

    • Engineering gives you 40 hours this quarter, while the proposed work would take six months. What ships, what waits, and what do you tell the executive team?
    • Explain your recommendation first to a CFO and then to a CTO. What changes in the explanation, and what remains constant?
    • A technically sound recommendation is blocked by product or legal. How do you determine whether to modify it, build a stronger case, or stop pursuing it?
    • When can conversion, inventory, follow-up, reputation, or product preference be a more important discovery constraint than crawlability?
    • Tell us about a recommendation you would reject even if it increased rankings or visibility. What makes the tradeoff unattractive?

    A senior leader should be able to operate outside the SEO silo. Search performance connects to product experience, customer support, paid landing pages, brand reputation, conversion paths, operational capacity, and revenue. That does not mean the SEO leader owns every function. It means they can recognize when the limiting factor sits elsewhere and bring the right owner into the decision.

    Restraint is part of the job. If the candidate describes six months of work as critical despite a narrow engineering allowance, they have not prioritized. They have reformatted the backlog. Look for explicit deferrals, sequencing logic, reversible first moves, and thresholds that would justify further investment.

    During the debrief, record evidence before discussing overall impressions. Ask what assumption the candidate challenged, what they chose not to do, how they connected discovery to business capacity, and whether a non-specialist could follow the logic. A charismatic presentation should not compensate for an undefined problem or an unbounded plan.

    Key takeaways and your next move

    • Define the business decision before defining the SEO role.
    • Treat technical and AI fluency as essential foundations, not the whole senior-level scorecard.
    • Use conflicting metrics and real constraints to expose how a candidate thinks.
    • Reward requests for more information when they identify decision-changing evidence and still produce a provisional recommendation.
    • Make candidates connect search and AI visibility to capacity, conversion, customer quality, and revenue.
    • Grade tradeoffs, communication, and restraint rather than agreement with a predetermined answer.

    Before you publish the role, replace its opening list of channel responsibilities with the decision this person must improve. Then replace the generic take-home audit with an ambiguous case drawn from that decision. The candidate who clarifies the problem, makes a choice, and earns support for it is showing the judgment you are actually hiring.

    References


  • Microsoft Ads and HubSpot: A Revenue Integration Playbook

    Microsoft Ads and HubSpot: A Revenue Integration Playbook

    If Microsoft Ads reports clicks and leads while HubSpot holds qualification, deals and revenue, you have two partial views of the same buyer journey. That gap makes a basic budget question unnecessarily hard: which campaigns are producing commercially useful demand?

    The Microsoft Ads and HubSpot integration can connect advertising activity with CRM records, activate CRM-based audiences and automate the handoff from marketing to sales. The connector creates the path, but trustworthy revenue reporting still depends on the definitions, associations and workflows you put around it.

    What the integration changes – and what it does not

    The integration brings Microsoft Advertising into HubSpot so you can use CRM data to build audiences and connect advertising activity with contacts and deals. Those audiences can support campaigns across Bing, Copilot, Outlook, Xbox and other Microsoft properties. Advertisers also gain access to LinkedIn professional audiences.

    Operationally, that creates a more useful chain:

    • A Microsoft campaign generates or influences a contact.
    • HubSpot records the contact’s lifecycle movement and sales ownership.
    • The contact is associated with a deal when an opportunity is created.
    • The deal moves through pipeline stages and eventually becomes won, lost or inactive.
    • Marketing compares campaign investment with qualified demand, pipeline and credited revenue.

    That is a large improvement over judging campaigns only by click-through rate or cost per lead. It does not, however, turn every CRM record into reliable attribution. The integration cannot decide what your company means by a qualified lead, repair missing contact-to-deal associations or settle whether a campaign sourced a sale or merely appeared somewhere in the journey.

    Key takeaways

    • Use the integration to connect Microsoft campaign activity with contacts and deals, not simply to duplicate ad-platform metrics inside HubSpot.
    • Define lifecycle stages, pipeline rules and revenue credit before treating the resulting dashboard as a source of truth.
    • Automate rep assignment and nurture sequences, but route incomplete or ambiguous records to an exception queue.
    • Separate lead volume, qualified demand, pipeline creation and won revenue so one strong top-of-funnel metric cannot hide a weak commercial result.
    • Use revenue reporting to find promising patterns and controlled experiments to test whether a campaign change actually improves performance.

    Define revenue truth before connecting the accounts

    Unlabeled contact, company, opportunity, and revenue objects connected in sequence by a highlighted data path with validation checkpoints.

    Your first deliverable should be a one-page measurement contract. It is not a technical specification. It is a set of business rules that marketing, sales and revenue operations agree to use when interpreting the integration.

    Write down these decisions before anyone builds a revenue dashboard:

    • Lead: Identify the event that creates a reportable lead. A form submission, imported record and existing contact returning to the site should not become interchangeable by accident.
    • Qualified lead: Name the fields or review step that indicate fit and intent. Do not let the mere presence of a CRM record count as qualification.
    • Pipeline: Specify the deal stage at which an opportunity enters pipeline reporting. If early, unverified deals count, label that value accordingly.
    • Revenue: Decide whether reports use the full closed-won amount, another approved amount stored on the deal or a weighted value. Use one definition consistently.
    • Date: Choose whether campaign reports group results by lead creation, deal creation or close date. These answer different questions.
    • Credit: Distinguish sourced revenue from influenced revenue. A campaign credited under an agreed acquisition model is not the same as a campaign that appeared somewhere in the recorded journey.
    • Associations: State which contact-to-company and contact-to-deal links must exist before pipeline or revenue can be attributed.
    • Exclusions: Document how employees, tests, duplicates, spam, invalid deals and other non-commercial records are removed.

    This prevents the most common reporting failure: a technically correct dashboard answering a question nobody defined. For example, a report grouped by close date tells you what revenue finished in a period. It does not necessarily tell you whether the campaigns launched in that period worked, because many of those leads may not have had time to mature.

    Keep campaign naming equally disciplined. Use a stable structure that identifies the channel, market, campaign purpose and audience without relying on a person’s memory. If names change midstream, record the change instead of silently merging unlike activity. Consistency is what lets the Microsoft-to-HubSpot relationship survive staff changes and dashboard rebuilds.

    Build and validate one complete revenue path first

    Do not begin by connecting every campaign, audience and workflow. Choose one campaign family with a clear conversion path and follow it from advertising activity to a HubSpot contact, a qualified outcome and a deal. A narrow pilot makes broken associations visible before they contaminate a larger report.

    A practical implementation sequence

    1. Confirm account scope and ownership. Record which Microsoft Advertising account and HubSpot portal belong in the connection. Assign one owner for advertising configuration, one for CRM data and one person who approves the shared measurement rules.
    2. Audit the pilot records. Inspect the fields used for lifecycle stage, source, owner, company, deal association, pipeline stage and revenue. Fix obvious duplicates and missing values before using those records as validation evidence.
    3. Connect the approved accounts. Use the Microsoft Advertising integration available in HubSpot and grant only the access required for the planned use. Record who authorized it and how your team will review access later.
    4. Select a controlled audience and campaign scope. Start with a segment whose business meaning is easy to explain. Avoid uploading the entire CRM simply because the connection makes broader activation possible.
    5. Create the minimum handoff workflow. Use the integration’s ability to assign a generated lead to a sales representative or start a nurture email sequence. Keep the first workflow simple enough to audit record by record.
    6. Run an end-to-end validation. Follow a controlled test record or policy-compliant live submission through contact creation, campaign association, lifecycle processing, ownership, workflow enrollment and deal association. Record the expected value and the actual value at each checkpoint.
    7. Reconcile before expanding. Compare the pilot’s contact and deal records with the corresponding campaign activity. Investigate unexplained records rather than forcing totals to match through manual edits.

    A successful connection should be observable. If a marketer cannot open a contact and explain why it entered a workflow, or a sales operator cannot explain why a deal carries campaign credit, the setup is not ready to drive a budget decision.

    Design workflows with an exception path

    A lead handoff should have at least three branches:

    • Ready for sales: The record meets your agreed fit-and-intent rule, contains the information needed for routing and is assigned to the appropriate sales owner.
    • Ready for nurture: The record is legitimate but does not yet meet the sales threshold, so it enters the appropriate email sequence rather than being treated as an immediate opportunity.
    • Needs review: Ownership, market, consent status, company association or another required value is missing or contradictory. The record enters a visible queue with a named person responsible for resolving it.

    That third branch matters. Automation usually fails quietly when every record is forced down a happy path. An exception queue turns a hidden data-quality problem into a manageable operating task.

    Close the loop with sales feedback as well. Use consistent reasons when a lead is accepted, rejected or returned for nurture. Marketing can then see whether a high-volume campaign is reaching the wrong companies, attracting weak intent or simply handing records to sales before enough information exists.

    Measure the funnel without overstating attribution

    Several illuminated marketing and sales paths converge around a business buyer before reaching a completed deal, with a transparent lens examining the junction.

    The integration can show which Microsoft campaigns are contributing to pipeline and revenue and support comparisons with other advertising channels. Treat that visibility as decision support, not automatic proof that an ad caused every credited sale.

    Your working dashboard should keep the funnel layers separate:

    Measurement layerQuestion it answersWhat to inspect when it weakens
    Spend and trafficDid the campaign buy the intended exposure and visits?Delivery, targeting, bidding and creative response
    LeadsDid visitors complete the defined lead action?Offer, landing-page path and tracking continuity
    Qualified leadsDid the campaign attract people who met the fit-and-intent rule?Audience composition, search intent and qualification criteria
    Pipeline createdDid qualified demand become recognized sales opportunities?Sales acceptance, follow-up, deal creation and CRM associations
    Closed-won revenueDid opportunities become revenue under the agreed reporting model?Sales-cycle maturity, deal progression, losses and revenue fields

    Calculate rates between adjacent stages as well as totals. If leads rise while the qualified-lead rate falls, cheaper acquisition may simply be moving the quality problem downstream. If qualified demand is healthy but pipeline creation is weak, inspect the sales handoff and deal-creation process before changing ads. If pipeline looks strong but won revenue lags, separate recent opportunities that still need time from older opportunities that stalled or closed lost.

    Use cohort views when the sales cycle extends beyond the reporting period. Group contacts by the period in which they entered through the campaign, then observe how that cohort progresses. Keep a separate close-date view for financial reporting. Combining those views into one number makes recent campaigns look artificially weak and older campaigns difficult to diagnose.

    Use experiments to test the next decision

    Revenue reporting can reveal an association worth investigating. A controlled test is better suited to deciding whether a change should receive more budget. Microsoft Advertising’s optimization experiments are generally available for Search, Shopping, Audience and Performance Max campaigns, with tests covering bidding, targeting, creative and other changes.

    For each experiment, change one decision you can act on and name the primary outcome before looking at results. If revenue takes too long to mature, use the closest CRM stage that has an agreed connection to commercial value, such as a qualified lead or accepted opportunity. Continue to inspect later pipeline and revenue rather than declaring success from an early-stage improvement alone.

    Keep the original campaign as the comparison, document the tested change and apply a successful variation only after it has met the decision rule your team set in advance. This protects you from promoting a variation merely because its early lead count looks attractive.

    Scale B2B activation with the platform limits in view

    The audience connection is especially useful for B2B teams because Microsoft has expanded LinkedIn company lists from 1,000 to 10,000 companies. Advertisers can upload the companies together and combine those lists with LinkedIn profile targeting in Search and Audience campaigns.

    Do not turn that larger ceiling into one undifferentiated account list. Segment companies according to the decision you need to make. For example, keep priority accounts separate from broader expansion accounts, and separate active opportunities from earlier-stage prospects when your permitted data use and available controls support that plan. Distinct segments let you compare message, response and pipeline quality instead of averaging unlike accounts together.

    Check geographic eligibility before promising reach. The company-list feature is available in supported markets globally, but the underlying consumer data excludes users in the EEA, the United Kingdom and Switzerland. Treat that as a planning constraint for audience design and regional reporting, not as a data problem the HubSpot connection can solve.

    There is also a separate technical deadline for teams maintaining custom Microsoft Advertising integrations. Developers have until January 31, 2027, to migrate from SOAP to REST. SOAP support for new features and enhancements was extended through that deprecation date. This matters to custom API work; it should not be confused with the business process of configuring the standard HubSpot integration. Inventory any custom jobs, middleware and reporting scripts now so the migration does not arrive as an attribution outage later.

    Start with one campaign family, one CRM audience, one handoff workflow and one agreed revenue view. Let that path run long enough to expose association gaps and sales-cycle lag, correct the exceptions, and only then extend the model to more campaigns. The fastest route to credible revenue reporting is a small chain your marketing and sales teams can both explain.

    References