Author: shivamcrushpressai

  • Ecommerce Advertising Readiness: When and Where to Scale

    Ecommerce Advertising Readiness: When and Where to Scale

    Your campaigns can be approved and spending while your store is still unprepared to scale. The weakness usually appears after demand rises: a feed rejects sale prices, a bestseller runs out, attribution has not caught up, or a promotion turns an apparently healthy return on ad spend into a loss.

    Advertising readiness means knowing what you can profitably sell, trusting the data used to optimize it, and choosing a channel that matches the customer’s current level of intent. Work through those decisions in that order and you can expand without asking automation to repair a broken funnel.

    Key takeaways

    • Do not scale traffic until purchase tracking, product availability, pricing, and contribution margin are reliable.
    • Use Search and Shopping to capture existing demand. Use YouTube to create demand when the lower funnel already converts.
    • Performance Max can distribute ads onto YouTube, but distribution is not a YouTube strategy. You still need deliberate creative, audience logic, measurement, and testing.
    • Segment products by margin, promotion, and stock position so one blended ROAS target does not treat fundamentally different products as equals.
    • Make campaign, feed, approval, and payment changes before a peak period. During the event, monitor exceptions and respect conversion lag instead of repeatedly resetting the system.

    Pass the readiness gate before choosing another channel

    A new channel adds traffic. It does not fix weak economics, inaccurate measurement, or a checkout that already loses qualified shoppers. In fact, sending cold YouTube traffic into a funnel where Search and Shopping traffic does not convert can simply accelerate the existing loss.

    Before increasing spend, give the store a clear pass or fail on four gates:

    1. Lower-funnel performance: Search and Shopping can turn relevant, high-intent visits into completed purchases without unexplained breaks in the journey.
    2. Measurement: transactions, order values, currency, and customer signals reach the advertising platforms accurately enough to guide bidding.
    3. Economics: you know the contribution available after discounts and variable order costs, not just revenue and platform-reported ROAS.
    4. Operations: the feed, stock data, payment methods, landing pages, creative approvals, and alerting process can withstand a sudden increase in demand.

    A failure on any gate determines your next investment. A tracking failure calls for measurement work. A stock or price failure calls for feed operations. A negative contribution margin calls for a commercial decision. None of those problems should be handed to a bidding algorithm as if they were targeting problems.

    Verify the data that bidding will learn from

    Run a test order from the storefront through the complete measurement path. Confirm that the purchase appears once, carries the correct value and currency, and can be reconciled with the order record. Then inspect the supporting stack: server-side measurement where appropriate, Consent Mode, Enhanced Conversions, and offline conversion measurement if meaningful outcomes happen after the online event. These are among the data checks that should be completed before a high-demand period, not during it.

    First-party audiences also need structure. An undifferentiated customer upload tells the platform that every buyer has equal value. Segment usable lists by factors such as average order value and customer lifetime value, then keep acquisition and retention decisions distinct. Apply the same discipline to the audience data used across Google Ads and Meta.

    Finally, document conversion lag. If purchases commonly arrive several days after an ad interaction, the newest dates will always look artificially weak. A reporting delay is not a campaign collapse, and reacting to it every morning can turn normal lag into genuine instability.

    Set a profit boundary before approving a discount

    Revenue-based ROAS can hide whether an order creates value. Start with a product or product-group calculation:

    Net selling price – product cost – variable fulfillment, payment, and expected return costs = contribution before advertising.

    That contribution is the amount available to pay for acquisition and leave profit behind. If you lower the selling price, recalculate it before setting the promotion live. A 15% discount removes part of the margin at the same time acquisition costs may rise. Matching a competitor’s discount without doing this calculation can produce more orders and less profit.

    To judge the promotion, divide the baseline contribution you want to preserve by the new contribution per order. The result is the number of discounted orders required before advertising costs are considered. Then add the expected acquisition cost. If the required volume is implausible, change the offer, limit it to suitable products, or accept that the promotion has a strategic cost rather than pretending it is profitable.

    Give each channel one clear job

    Channel choice becomes easier when you start with the customer’s state. Search and Shopping are pull channels: the shopper expresses intent and the advertiser competes to answer it. YouTube is a push channel: the advertiser interrupts someone who was doing something else and must create enough interest to earn a later action. Those conditions require different creative, timelines, skills, and measurement.

    Channel or campaign typeCustomer statePrimary jobWhat you must control
    Search and ShoppingAlready looking for a product, category, or solutionCapture existing demandQuery or product relevance, offer quality, feed accuracy, bids, margin, and landing-page conversion
    YouTubeNot actively shopping at that momentCreate interest, demonstrate a product, and generate future demandHook, argument, demonstration, proof, audience, creative refresh, and a longer evaluation window
    Performance MaxVaries because inventory spans multiple Google surfacesAllocate spend across eligible inventory toward the configured conversion goalFeed quality, conversion inputs, asset quality, product segmentation, budget, targets, and interpretation of blended reporting

    This distinction matters because Performance Max may already be buying YouTube impressions for your store. It can reuse uploaded assets or, when no video is supplied, assemble video from product images, transitions, and text. That gives the campaign something to serve, but it does not supply positioning, persuasion, creative sequencing, or a channel-specific learning plan.

    Treat Performance Max as a distribution system, not proof that you have a YouTube strategy. A blended conversion total cannot tell you whether upper-funnel impressions created new demand, harvested demand that already existed, or received credit for a purchase that would have happened anyway. Do not accept that number uncritically, but do not make the opposite mistake of testing YouTube once, grading it like Search, and declaring the channel ineffective.

    Use a simple channel decision sequence

    1. If relevant Search and Shopping traffic does not convert, repair the offer, product pages, checkout, feed, or measurement before adding cold reach.
    2. If profitable search demand is still available, capture it before paying to manufacture more awareness.
    3. If existing demand is constrained, or the product is new and lacks search volume, assess whether YouTube can create demand.
    4. If the goal is product discovery, brand awareness that can drive later searches, a time-limited seasonal promotion, or a new-product launch, give YouTube a defined budget and its own measurement plan.
    5. If you cannot produce and refresh persuasive video, postpone the channel rather than allowing generic automated assets to stand in for strategy.

    Build YouTube creative as a persuasion sequence

    A YouTube viewer did not ask to see your product. The creative therefore has to do more than show it. Build each concept around a complete sequence:

    1. Hook: earn attention in the first five seconds.
    2. Problem: make the relevant frustration, desire, or missed opportunity recognizable.
    3. Mechanism: explain how the product addresses that problem.
    4. Demonstration: show the product doing the work instead of relying on a claim alone.
    5. Proof: give the viewer a reason to believe the result.
    6. Call to action: make the next step explicit and consistent with the landing page.

    Creative is the operating cost of this channel. Fatigue arrives faster than it does in intent-led campaigns, so two or three occasional videos are not a substantial testing program. For a serious effort, plan the people, production process, and approval capacity needed to test 20 or 30 videos per month. If that volume is beyond reach, narrow the test deliberately rather than spreading a small set of assets across too many audiences and offers.

    Define success before launch. Direct sales still matter, but the feedback loop is longer and attribution is less clean than it is for Search. Separate YouTube’s budget and evaluation from the assumptions used for demand capture, account for the store’s observed conversion lag, and watch whether the channel is creating the future demand it was assigned to create. Changing the success definition after seeing the result makes the test impossible to interpret.

    Make feed and margin structure govern spend
    An overhead arrangement of unbranded products, packaging, coins, a calculator, and a tablet with abstract product tiles.

    For an ecommerce advertiser, Google Merchant Center is not an administrative afterthought. Its product feed is a core input to Shopping and Performance Max. When availability, price, or identifiers are wrong, automation makes decisions from a distorted catalog.

    Configure the feed around the decisions your team will need to make under pressure:

    • Automate promotional prices. Populate sale_price and sale_price_effective_date with exact start and end timestamps. This allows scheduled price changes and reduces the risk of a mismatch between the website and feed when a sale begins.
    • Protect price-annotation eligibility. If strikethrough pricing is part of the plan, the base price must have been active for at least 30 days within the previous 200 nonconsecutive days.
    • Increase freshness during peak windows. Raise feed synchronization to three or four times per day when prices and inventory are changing quickly.
    • Stop advertising unavailable inventory. Use automated rules or feed scripts to flag and pause out-of-stock SKUs instead of buying visits to products that cannot be ordered.
    • Add commercial labels. Use Custom Label 0 through Custom Label 4 to represent attributes such as actual margin, promotional status, and stock position.

    Do not wait for the promotion to discover whether the feed and checkout disagree. Schedule a sale-price test, verify the timestamps, inspect the landing page and cart, and confirm that a product returns to its normal price after the test window. A valid feed submission is useful, but the shopper experiences the complete path.

    Translate labels into campaign decisions

    Labels become valuable when they change how you allocate spend. A high-margin, well-stocked bestseller can support a different target and budget from a low-margin item with limited inventory. Blending the two under one target ROAS encourages the platform to optimize revenue while concealing the difference in profit.

    • High margin and strong stock: make these products eligible for more assertive acquisition, subject to the contribution boundary.
    • Low margin: use a more defensive target or restrict promotion unless the product has a deliberate strategic role.
    • Promotional: isolate the discounted economics so ordinary-price performance does not subsidize an unprofitable event in the reporting.
    • Low stock: reduce exposure before availability becomes a customer and feed problem.
    • Out of stock: pause promptly and restore eligibility only after the feed and storefront agree.

    Keep a working record for each important SKU or product group: normal price, promotional price, product cost, variable order cost, contribution before advertising, stock position, and active promotion. That record gives the media team a commercial map. Without it, campaign structure is merely technical organization.

    Prepare the peak-period operation before demand arrives
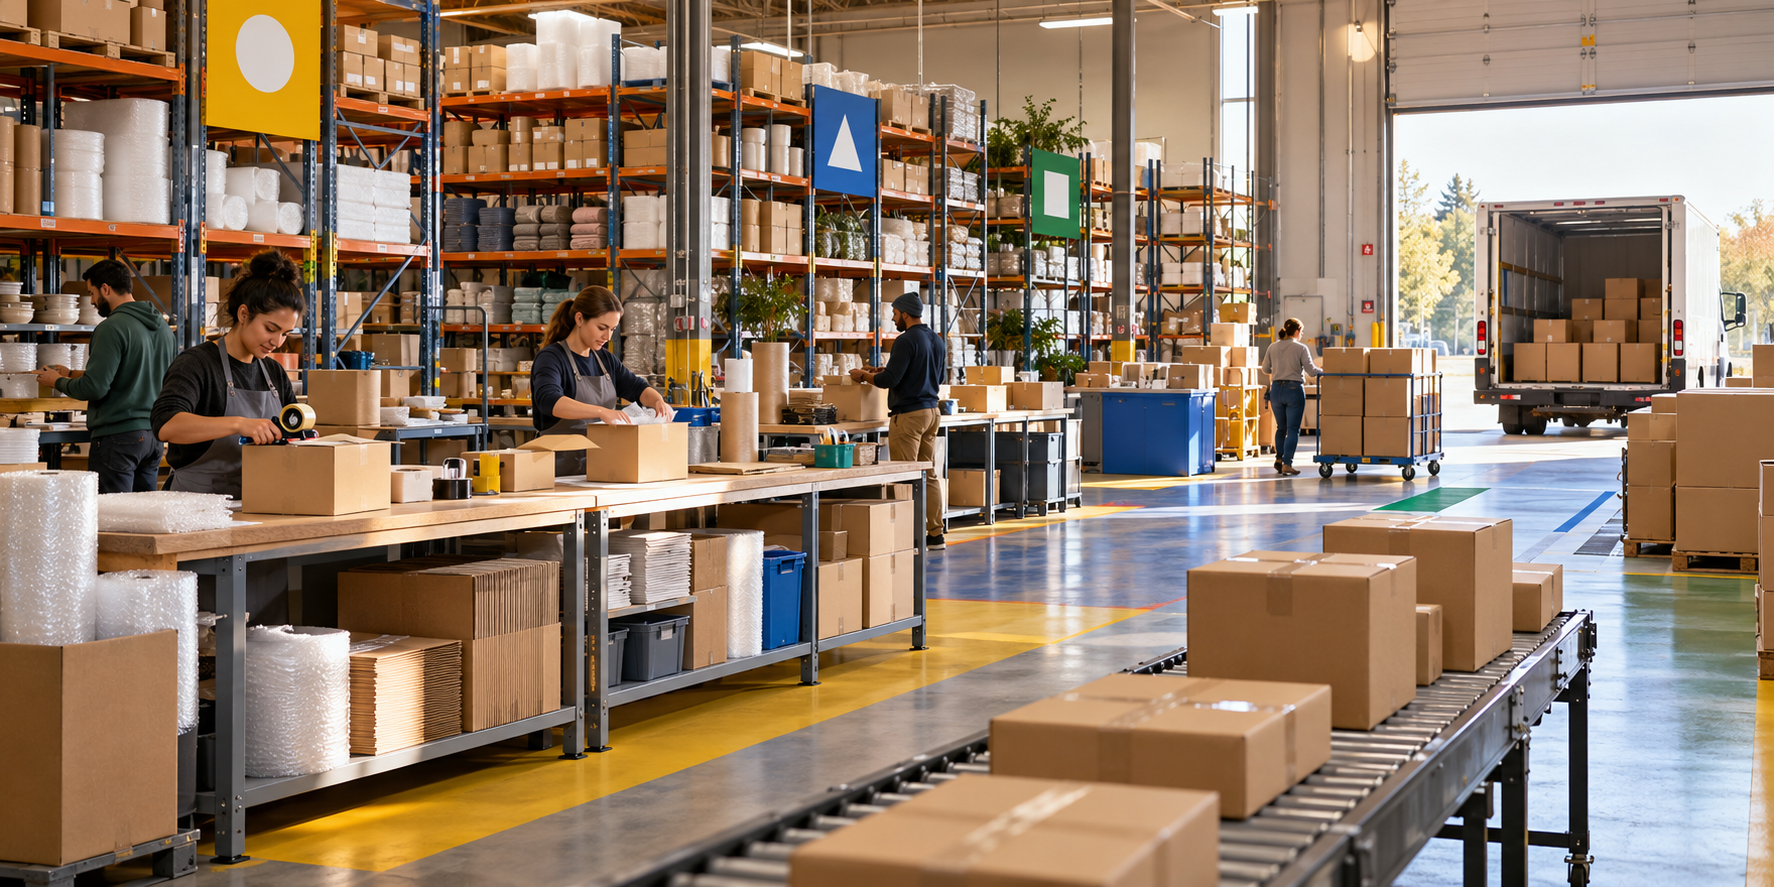
    Workers pack unbranded orders at organized stations in a well-stocked ecommerce fulfillment area.

    Peak-period readiness is mostly timing. A change that is sensible in an ordinary month can be reckless immediately before Black Friday if it triggers a learning period, waits for approval, or alters the data used by bidding. Depending on account size and market, Q4 preparation may need to begin in August or September.

    Sequence the work around risk

    1. Months before demand peaks: validate measurement, segment first-party audiences, repair the lower funnel, calculate promotion economics, and begin warming audiences where demand creation is part of the plan.
    2. Well before the event: launch new campaign structures and bidding strategies early enough to move beyond their initial learning behavior. Upload creative with time for review instead of risking a pending approval on the day before the sale.
    3. Before prices change: test sale attributes and effective dates, confirm stock rules, set feed schedules, fund the advertising account, and add a backup payment method.
    4. During Cyber Week: inspect Merchant Center Diagnostics early each morning, prioritize disapproved bestsellers, and maintain the higher feed-sync frequency.
    5. After each major sales window: wait for the known conversion lag before treating recent ROAS as complete, then compare product-level contribution with the target established before launch.

    Decide in advance how much control you want over rising CPCs and CPMs, including whether a portfolio bid cap belongs in the plan or whether the bidding system will operate without one. The important point is to make that choice from economics and risk tolerance before the auction becomes unusually competitive.

    Monitor exceptions instead of micromanaging campaigns

    Create alerts for payment failures, material CPC changes, rapid budget consumption, feed disapprovals, and inventory problems. Then write the response beside each alert. An alert without a response rule merely creates anxiety; an alert tied to a check and an owner shortens the time to a useful decision.

    • If a bestseller is disapproved, inspect price, availability, and landing-page consistency before changing a bid.
    • If a campaign consumes its daily budget unusually early, check traffic quality, CPC movement, and the promotion schedule before reallocating money.
    • If reported ROAS falls on the newest dates, compare that window with the account’s normal conversion lag before changing targets.
    • If stock becomes scarce, use the stock label or automated rule to reduce exposure rather than continuing to sell demand you cannot fulfill.
    • If a payment method fails, switch to the verified backup before delivery stops during the most valuable traffic window.

    Frequent intervention can be as damaging as neglect. When conversion lag is several days, daily changes based on incomplete purchases make each decision depend on a partial result. Reserve emergency changes for genuine operational failures or clearly breached financial boundaries. Let ordinary performance accumulate enough evidence to judge.

    Your next move is not automatically another campaign. Choose one upcoming promotion or product launch and score it against the four readiness gates. Fix the first failed gate. When all four pass, assign Search, Shopping, Performance Max, or YouTube a precise job, budget, success measure, and stopping condition. That is the point at which scaling becomes a controlled decision rather than a bet.

    References


  • AI Search Visibility Monitoring: A Repeatable Framework

    AI Search Visibility Monitoring: A Repeatable Framework

    You checked an AI answer, saw your brand missing, and now you need to know whether you have a visibility problem. One response cannot answer that. AI recommendations vary between runs, and buyers can approach the same purchase through several different questions.

    A useful monitoring program treats visibility as a measured distribution, not a rank. It samples real buying decisions, repeats prompts under controlled conditions, records how each brand is presented, and turns the resulting patterns into specific content and positioning work.

    Key takeaways

    • Monitor buyer decisions and prompt families, not a list of exact phrases that tries to imitate traditional keyword tracking.
    • Run each prompt at least 10 times for a quick directional estimate. A single answer is an observation, not a baseline.
    • Measure recommendation seats, prompt coverage, citations, cited pages, and buyer-fit descriptions separately.
    • Keep prompt wording, search mode, environment, and run counts consistent when comparing one period with another.
    • Use monitoring to diagnose the next action. A missing recommendation, an uncited mention, and an inaccurate best for description are different problems.

    Define visibility before you try to measure it

    Transparent chambers show the same blue marker as prominent, peripheral, grouped with alternatives, or absent after repeated inputs.

    AI search visibility is not simply whether your company name appears. An answer can cite your page without recommending your product. It can recommend your brand while linking to a review site. It can also place you on a shortlist but describe you as suitable for the wrong customer.

    The distinction matters because AI-generated shortlists can be narrow. In one workforce-management sample, 100 responses contained an average of 5.6 recommended brands, while the referenced vendor directory contained 215 listings in the relevant category. That result belongs to one category and one test design, so it is not a universal benchmark. It does show why merely being eligible for consideration does not mean a brand will receive a seat.

    Record these six layers for every completed run:

    <!– wp:list {
  • Marketing Partnership Accountability: A Practical Operating Model

    Marketing Partnership Accountability: A Practical Operating Model

    You hired capable marketers, approved a plan, and waited for the commercial result. Now the report is full of green arrows while sales says the inquiries are weak, revenue is unchanged, or the work is promoting the wrong offer. Before you conclude that the agency failed or that marketing simply does not work, check whether the partnership ever established a shared definition of success.

    A marketing partner can own research, recommendations, campaigns, content, technical execution, and reporting. It cannot choose your commercial priorities, reveal operational constraints it has never been told about, or decide what your sales team considers a worthwhile lead. Accountability works only when execution is delegated without abandoning leadership.

    Define success in commercial terms before choosing channels

    A brief that says “increase traffic,” “improve rankings,” or “grow AI visibility” gives the marketing team permission to optimize for visible movement. It does not tell them which movement creates value. A campaign can perform exactly as instructed and still send attention toward a low-margin service, attract people who will never buy, or generate demand the business cannot fulfill.

    Begin with a commercial brief that the business leader, marketing lead, and sales lead can all recognize as true. It should answer:

    • What are we trying to sell? Name the priority products or services, the offers that should not receive more demand, and any margin, inventory, staffing, or delivery constraints.
    • Who is the buyer? Describe the person or organization with the problem, the person who approves the purchase, the trigger that creates urgency, and the characteristics that make an account unsuitable.
    • What action matters? Distinguish an informational visit from a buying action such as requesting an assessment, booking a consultation, starting a trial, or contacting sales.
    • What is a qualified lead? Record the required fit, intent, need, authority, and exclusions. “Someone completed a form” is an event, not a qualification standard.
    • How does the business make money? Give the marketing team enough context to understand margins, sales priorities, buying journeys, and the difference between a valuable opportunity and expensive noise.
    • What could change the plan? Surface supply constraints, capacity limits, offer changes, sales coverage, regulatory concerns, and shifting business priorities before they invalidate the campaign.

    This is the dividing line between delegation and abdication. You can outsource specialist execution while retaining responsibility for direction. The business supplies commercial truth and makes consequential decisions. The marketing partner learns the business, challenges weak assumptions, and turns that context into a defensible strategy.

    Use a simple approval test before work begins: could the marketing team explain which buyer matters, which offer deserves demand, why that offer matters commercially, and how sales will judge the resulting opportunities? If not, the partnership is not ready to debate keywords, content formats, paid campaigns, schema, AI-search citations, or channel budgets.

    Assign decision rights before work gets stuck

    Four colleagues organize color-coded decision tokens around converging project paths while one person moves the central token forward.

    Many accountability disputes are ownership disputes in disguise. The agency believes it was waiting for approval. The client believes the agency was hired to take initiative. Sales believes marketing owns lead quality. Marketing believes sales never followed up. Everyone can describe the failure, but nobody had a named final owner for the decision that would have prevented it.

    Create an accountability map at the start of the engagement and revise it whenever the team or scope changes. A practical version looks like this:

    Decision areaBusiness responsibilityMarketing-partner responsibilityEvidence used
    Commercial prioritiesSet and approve priorities, constraints, and tradeoffsExplain the marketing implications and challenge contradictionsMargins, capacity, sales priorities, and business goals
    Qualified-lead definitionDefine fit with sales and provide rejection reasonsTranslate the definition into targeting, messaging, offers, and measurementAccepted leads, rejected leads, sales outcomes, and stated reasons
    Audience and positioningValidate factual claims, differentiation, and brand boundariesResearch the audience, propose messages, and test assumptionsCustomer language, search behavior, sales objections, and campaign response
    Channel and technical executionProvide access and identify material business risksRecommend, implement, verify, and document the workTechnical checks, delivery records, and performance signals
    Budget or resource changesApprove material reallocationsRecommend changes with expected benefits, risks, and uncertaintyOpportunity cost, performance, capacity, and strategic fit
    Performance interpretationProvide actual business outcomes and challenge assumptionsConnect activity to results, explain uncertainty, and propose the next decisionMarketing, sales, revenue, and operational data

    The map should name people, not just departments. “Client to approve” is not ownership. “Sales director approves the lead definition” is. “Agency monitors performance” is incomplete. “Paid media lead recommends reallocations; the business sponsor approves material changes” describes an operating relationship.

    Keep the boundaries sensible. The business sponsor should not become the approval bottleneck for every title tag, ad variation, or internal link. The agency should not quietly decide which product line matters most or publish claims that require business validation. Each side should control the decisions for which it has the context and authority, while making dependencies visible to the other.

    Watch for four warning signs: requests that lack a named decision-maker, approvals with no clear acceptance criteria, strategy changes delivered as casual feedback, and work that proceeds on an unverified commercial assumption. These are not minor process flaws. They create a future argument in which both sides can plausibly say they thought the other side was responsible.

    Build a scorecard that follows the path to revenue

    A tabletop sequence of campaign objects, brass checkpoints, a product sample, interlocking forms, and metallic discs depicts a progression toward revenue.

    Traffic, rankings, impressions, clicks, AI citations, and brand mentions can be useful. They show whether the market is encountering your business and help diagnose where a strategy is gaining or losing traction. They become vanity metrics when the report presents them as proof of commercial success without showing what happened next.

    A useful scorecard reads from the business result backward:

    • Business outcomes: revenue, gross profit, retained business, or another result the company actually values.
    • Pipeline quality: qualified opportunities, lead acceptance, disqualification reasons, pipeline progression, and closed business.
    • Conversion efficiency: whether the intended audience reaches the right page, takes the intended action, and becomes a sales-worthy inquiry.
    • Demand and visibility signals: relevant organic visits, target-query visibility, paid response, branded demand, AI-search visibility, citations, and engagement with commercial content.
    • Delivery and learning: work completed, assumptions tested, technical problems found, lessons learned, and decisions required.

    The layers matter because no single metric tells the whole story. Strong visibility with weak relevant traffic may indicate that the pages or search appearances are attracting the wrong intent. More inquiries with poor sales acceptance may expose faulty targeting, an ambiguous offer, or a loose lead definition. Better qualified pipeline without closed revenue may require examination of sales progression, buying time, pricing, or follow-up. Growing demand for an offer the business cannot deliver is a reason to redirect marketing, not celebrate the graph.

    For SEO, AEO, and GEO work, resist the temptation to make visibility the final destination. A target query should relate to a buyer problem the business can solve. A cited page should lead the right reader toward a useful next step. An increase in AI mentions should be interpreted alongside audience relevance, qualified demand, and commercial outcomes. Otherwise, you are measuring presence without determining whether the presence helps the business.

    Every metric in the scorecard needs a definition, a data owner, an interpretation, and a decision it can influence. If the team cannot say what it would do differently when a metric changes, that metric probably does not belong in the executive view. It may still be valuable in a specialist diagnostic report, but it should not be used to defend an engagement.

    This does not mean demanding direct revenue attribution from every technical fix or content update. Marketing contains leading indicators, delayed effects, and attribution gaps. It does mean requiring a credible line of sight from the work to the customer journey. Impressions, traffic, and rankings are indicators rather than business outcomes; the partner should explain what they indicate, what remains uncertain, and what evidence would justify the next move.

    Run reviews as decision meetings, not report readings

    A dashboard does not create accountability by itself. The operating loop closes only when business context, marketing evidence, sales feedback, and decisions meet in the same conversation. If a review consists of the marketer reading slides while everyone else waits for the final chart, the partnership is documenting activity rather than governing it.

    Build each review around four inputs:

    • Business context: what changed in priorities, margins, capacity, product availability, positioning, or competitive pressure?
    • Funnel truth: which inquiries did sales accept or reject, why were they treated that way, and what happened after handoff?
    • Marketing evidence: what shipped, what changed, which hypothesis was tested, what did the evidence support, and where is the interpretation still uncertain?
    • Decision queue: what needs approval, what should stop, what should continue, what should change, and who owns each next action?

    Sales feedback must be specific enough to change marketing. “The leads are bad” gives the partner nothing to operationalize. Useful feedback identifies the reason: the company was too small, the contact lacked authority, the request concerned employment rather than a purchase, the geography was wrong, the need did not match the offer, or the person was researching without buying intent. Marketing can then adjust targeting, messaging, qualification, forms, content, or channel allocation.

    The marketing partner owes the same level of specificity. “The algorithm changed” or “the campaign needs more time” is not an adequate explanation on its own. The partner should identify the observed change, show which part of the plan it affects, separate evidence from inference, explain the commercial implication, and recommend a decision. Technical detail is useful when it clarifies the choice. It is a problem when it obscures the absence of one.

    Keep an action register with the decision, owner, due point, expected evidence, and status. This prevents the same unresolved dependency from reappearing under different wording. It also makes accountability fair: you can distinguish weak execution from a missing approval, an unavailable data feed, an undisclosed business constraint, or feedback that never reached the people doing the work.

    Adopt a no-surprise rule. The business should disclose material commercial changes as soon as they affect the plan. The marketing team should flag deteriorating quality, wrong-audience signals, tracking gaps, blocked work, or invalid assumptions before the formal report. Waiting until results are challenged turns a manageable course correction into a trust problem.

    Marketing partnership accountability FAQ

    Who is accountable when marketing misses its target?

    Start with the agreed responsibilities rather than assigning blanket blame. The marketing partner is accountable for learning the business, recommending a coherent strategy, executing competently, reporting honestly, and identifying misalignment. The business is accountable for setting priorities, supplying commercial context and access, making decisions, and returning sales and outcome data. A missed target becomes a clear performance failure when the responsible party did not perform an agreed obligation, concealed a problem, or repeatedly failed to learn from evidence. A target miss caused by a disclosed assumption that proved wrong is a learning event, provided the team responds to it.

    What should an executive marketing report include?

    It should connect business outcomes, pipeline quality, conversion behavior, relevant demand signals, completed work, uncertainty, and pending decisions. Each major metric should answer a management question. Executives need to know whether marketing is attracting the intended buyer, supporting the current commercial priority, producing sales-worthy demand, and learning fast enough to justify continued investment. Channel diagnostics can sit beneath that view for the specialists who need them.

    When should you replace a marketing partner?

    Consider replacement when the partner refuses to learn how the business makes money, relies on activity metrics to avoid commercial questions, cannot explain its assumptions, repeats work that attracts the wrong audience, conceals uncertainty, or fails to act on clear feedback. Before ending the relationship, document the commercial objective, decision rights, measurement chain, missing inputs, and corrective actions. That reset shows whether the problem is capability, conduct, scope, or the operating model around the partner. If the business continues to withhold decisions, context, access, or lead feedback, changing agencies will reproduce the same failure with a different logo.

    At your next review, bring the commercial brief, accountability map, scorecard, and action register. Ask the partner to state which offer matters, who the qualified buyer is, what the current evidence means, and which decision is needed from you. Then provide the business context and sales truth they cannot generate on their own.

    You do not need to manage every campaign setting or technical task. You do need to keep strategy connected to the way the company creates value. That is how an outsourced vendor becomes a governed marketing partnership, and how both sides earn the right to be judged on results.

    References


  • How to Control Paid Search Placement and Ad Presentation

    How to Control Paid Search Placement and Ad Presentation

    You may have approved the targeting, copy and landing pages, yet still feel that part of your paid search campaign is outside your control. Automation can decide where an ad appears, while the search interface can change how the same assets look to users.

    The practical answer is to manage placement safety and ad presentation as separate control systems. One governs the contexts your brand will accept. The other makes your assets resilient when a platform changes their visual treatment.

    Treat placement and presentation as separate control planes

    Placement control answers: “Which content should never sit beside this campaign?” Presentation control answers: “If the platform rearranges or emphasizes our assets, will the ad still communicate clearly?”

    Those questions require different actions:

    • Placement safety: define prohibited contexts, choose the right exclusion scope, document why each restriction exists and verify that the setting was applied where intended.
    • Presentation resilience: write assets that work independently, send each link to a matching destination and measure whether interface changes redistribute attention among those links.

    Do not use one as a substitute for the other. Strong sitelinks cannot protect a brand from unsuitable content adjacency. A detailed exclusion list cannot prevent a weak or ambiguous sitelink from attracting the wrong click.

    This distinction also makes troubleshooting faster. When impressions or eligible reach change after a placement update, inspect exclusions first. When mobile users start choosing different destinations from the same ad, inspect presentation and asset clarity before changing bids or audiences.

    Turn content exclusions into an enforceable brand policy

    A layered filtering system diverts risky content cards away from a protected advertising area while neutral cards pass through.

    Microsoft Advertising gives advertisers a direct way to define unsuitable content topics. Its Excluded Content Terms control accepts up to 1,000 terms based on page titles. The control can be applied across an account or scoped to an individual campaign.

    That scope decision matters more than the length of the list. An account-level exclusion is appropriate when association with a topic would be unacceptable for the brand under any campaign. A campaign-level exclusion is better when suitability depends on the product, audience or message being advertised.

    For example, a company-wide reputational restriction belongs at account level because a campaign manager should not be able to bypass it accidentally. A topic that conflicts with one product campaign but remains relevant to another belongs at campaign level. Applying every concern globally may restrict suitable opportunities; keeping every concern local can leave avoidable gaps.

    Build the exclusion list in six steps

    1. Start with policy, not keywords. Write down the topics that create a real reputational, contractual or internal-policy conflict. This prevents the list from becoming a collection of vague dislikes.
    2. Assign a scope to each topic. Mark every restriction as account-wide or campaign-specific before anyone enters it into the platform.
    3. Translate the topic into page-title language. The mechanism evaluates terms associated with page titles, so use wording that is likely to identify the unwanted subject clearly. Do not assume that a broad concept and the words appearing in a title are always the same thing.
    4. Review ambiguous terms. A word can appear in both unsuitable and harmless contexts. Check whether the term expresses the prohibited topic precisely enough before applying it across the account.
    5. Record an owner and rationale. Keep the term, scope, reason, approving stakeholder and implementation status in a shared change log. When delivery changes later, you will know whether the restriction was intentional.
    6. Verify the deployed setting. Confirm that account-level terms appear at account level and campaign-specific terms appear only in the intended campaigns. A correct policy in a worksheet provides no protection if it was entered in the wrong place.

    The 1,000-term allowance is capacity, not a target. More exclusions do not automatically create better protection. Prioritize terms with a clear connection to a documented concern, then review the list when brand policy, products or campaign scope changes.

    Also be precise about what this control can establish. Because the terms are based on page titles, they are a useful boundary for identifiable topics, not a complete interpretation of every page’s meaning. Keep the platform’s built-in safeguards in place and treat your custom list as an additional layer shaped by your own requirements.

    Build sitelinks that survive changes in visual treatment

    Four modular destination tiles connect to a search ad component and reflow into horizontal, stacked, expanded, and compact layouts.

    You control the sitelink assets you submit, but not every detail of how Google displays them. Google has tested a mobile layout that places sitelinks on separate lines, adds a vertical treatment on the left and uses darker link text. That could make secondary routes more noticeable even though the advertiser has not edited the assets.

    A test is not a promise of broad rollout. It is still an operational warning: an asset that feels secondary in one layout may become visually prominent in another. Write every sitelink as though it could receive focused attention.

    Make every sitelink understandable on its own

    • Name the destination. “Pricing,” “Enterprise plans” or “Book a demo” tells the user what lies behind the click. Generic labels such as “Learn more” depend too heavily on surrounding copy.
    • Give each route a distinct job. If several sitelinks promise nearly the same thing, a more prominent layout creates apparent choice without meaningful choice.
    • Match the landing page to the label. A user who selects a specific secondary link should arrive at that destination, not a general page that requires another search.
    • Avoid sequence-dependent wording. Sitelinks may be scanned individually. Do not make the meaning of one link depend on the user reading the link before it.
    • Check the set for internal competition. Your most visually attractive sitelink should not divert high-intent users toward a lower-value or poorly matched route.

    Reviewing the text in an asset manager is not enough. Inspect the rendered mobile result whenever you can observe it, and compare the visual hierarchy with the campaign’s intended decision path. Ask which element attracts the eye first, which links now resemble primary choices and whether those destinations deserve the additional attention.

    This is also why approval should cover the complete asset set. A sitelink is not merely an optional accessory beneath the main ad. It is a possible entrance to your site whose prominence can change without a new copy review.

    Diagnose performance shifts before changing the campaign

    Placement changes and presentation changes can both alter performance, but they leave different clues. Use the following as first hypotheses, not proof of causation.

    Observed changeQuestion to investigate firstUseful next action
    Delivery changes after exclusions are addedWas a restriction applied at account level when it was intended for one campaign?Compare the deployed account and campaign lists with the approved scope log.
    Mobile users begin choosing different sitelink destinationsHas the visual hierarchy changed even though the assets have not?Inspect live mobile presentation and destination-level analytics before rewriting the ads.
    Click-through behavior changes but downstream results do not improveIs a newly prominent route attracting attention without matching intent?Compare the promise of each sitelink with its landing page and desired action.
    Performance moves across devices and asset routes at onceIs the cause broader than a mobile presentation variation?Review targeting, bids, budgets, demand and other campaign changes before attributing the shift to layout.

    Keep an annotation for each exclusion deployment, asset edit and observed interface change. Without that timeline, a platform presentation test can be mistaken for the effect of your copy revision, or an account-level exclusion can be mistaken for a demand problem.

    Do not call a platform-run interface experiment your A/B test unless you have reliable assignment and reporting for the variants. If you cannot identify which users saw which treatment, you can document the correlation and investigate it, but you cannot cleanly credit the layout for the outcome.

    A useful review separates three layers: eligibility and distribution, user interaction with the rendered ad, and behavior after the click. That sequence keeps you from “fixing” the landing page when an exclusion changed delivery, or loosening brand-safety rules because a sitelink destination underperformed.

    Key takeaways

    • Manage content adjacency and visual presentation as separate risks with separate owners, controls and diagnostics.
    • Use account-level exclusions for non-negotiable brand restrictions and campaign-level exclusions for context-specific concerns.
    • Microsoft’s Excluded Content Terms can use as many as 1,000 page-title terms, but relevance and scope matter more than filling the allowance.
    • Write each sitelink as a self-contained route because Google can change its prominence without requiring an asset edit.
    • When performance moves, check distribution, rendered interaction and post-click behavior in that order before changing the campaign.

    Your next step is concrete: audit one account’s exclusion scopes and one mobile campaign’s complete sitelink set. Correct the first mismatch you find, log the change and establish the baseline you will use to judge what happens next.

    References


  • AI Marketer Image Generation: A Practical Publishing Workflow

    AI Marketer Image Generation: A Practical Publishing Workflow

    You need a campaign image, but a blank prompt box is not a creative brief. If you ask an AI marketer for something that looks professional without defining the image’s job, you can get a polished asset that is unusable, off-brand, or disconnected from the page it is supposed to support.

    The useful shift is that image generation can now sit inside an AI marketer workflow. That can shorten the distance between an idea and a draft. It does not remove the need for direction, review, accessibility, or measurement. The workflow below turns that faster first draft into an image you can publish with confidence.

    Define the image’s job before describing its appearance

    Start with the placement, not the visual style. A blog hero, a paid social creative, a product illustration, and a supporting diagram may cover the same subject, but they solve different communication problems. The placement determines how much detail the image can carry, where the focal point belongs, whether text will be added later, and what the viewer should understand at a glance.

    Write a short image brief with six decisions:

    1. Placement: Name the exact destination, such as the hero area of a landing page, the opening image for an article, or a paid social placement.
    2. Communication goal: Complete the sentence: After seeing this image, the viewer should understand that…
    3. Audience: Identify who should recognize themselves, their work, or their problem in the scene.
    4. Focal subject: Choose the one element that must remain clear when the image is viewed at its final size.
    5. Brand constraints: Specify the visual characteristics that must stay consistent, including approved colors, level of realism, composition, mood, and any recurring visual motifs.
    6. Exclusions: List what must not appear, especially unsupported product details, invented interfaces, competitor marks, illegible text, visual cliches, or sensitive representations.

    A workable brief is concrete enough to reject the wrong image. For example: Create a wide editorial hero for an article aimed at B2B content leaders. Show one marketer directing an AI-assisted image workflow, with the review step visually prominent. Use a restrained, credible visual language with generous negative space on the left for a headline. Do not include logos, embedded words, dashboards, or futuristic humanoid robots.

    If your brief only contains adjectives such as modern, bold, premium, or innovative, it is not finished. Replace each adjective with a visible choice. Premium might mean restrained color, deliberate lighting, a limited number of objects, and generous negative space. Modern might mean a clean editorial composition rather than neon circuitry. The model can act on visible instructions; it cannot infer your internal definition of taste.

    Generate controlled variations instead of unrelated options

    A hand compares six closely related campaign image variations arranged on a studio table.

    The fastest route to a usable result is not asking for many unrelated concepts. Generate around one approved direction, then vary one decision at a time. This makes feedback precise and prevents the team from restarting the creative conversation with every draft.

    Build the prompt in this order: deliverable, purpose, subject, action, environment, composition, visual treatment, brand constraints, and exclusions. Put the non-negotiable information near the beginning. If the focal subject or empty space matters more than the color palette, say so first.

    • Composition variation: Keep the subject and visual treatment fixed, but test centered, off-center, close, and wide framing.
    • Concept variation: Keep the intended message fixed, but test a literal scene against a simple visual metaphor.
    • Tone variation: Keep the composition fixed, but adjust the level of warmth, energy, realism, or formality.
    • Channel variation: Preserve the concept while adapting the crop and visual density for each destination.

    Evaluate every candidate at the size and crop in which people will encounter it. A detailed scene can look impressive when enlarged and turn into visual noise in a card or mobile feed. The reverse also happens: a simple image may look sparse in isolation but work well once the headline, navigation, and call to action surround it.

    Do not rely on generated pixels for exact copy, product labels, interface text, pricing, or legal language. If wording must be correct, reserve clean space and add the approved text during layout. The same rule applies to a real product interface: use an approved screenshot or a clearly conceptual treatment instead of letting the generator invent controls that customers might mistake for actual functionality.

    Keep a small decision record for the selected asset: the brief, prompt, chosen output, intended placements, edits, reviewer, and approval status. That record gives you a reusable starting point when another channel needs a related image. It also separates approved creative direction from the accidental details of one generation.

    Run a four-part review before the image reaches WordPress

    A campaign image sits at the center of a desk surrounded by tools for checking color, defects, page context, and accessibility.

    Visual appeal is only one approval criterion. Review the candidate through four separate gates so that a striking image does not distract you from a factual, production, or governance problem.

    1. Truth and context

    • Does the image imply a capability, result, customer, partnership, location, event, or product detail that you cannot substantiate?
    • Could a conceptual interface be mistaken for the real product?
    • Are charts, maps, signs, screens, packages, or technical equipment plausible enough to mislead a viewer?
    • Does the representation of people fit the actual audience and context without leaning on a stereotype?

    Treat an unsupported visual claim the same way you would treat unsupported copy. Remove it, replace it with an approved asset, or make the conceptual nature unmistakable.

    2. Brand fit

    • Would the image still feel connected to your brand if the logo were absent?
    • Does its level of polish match the surrounding page rather than overpowering it?
    • Are lighting, color, subject treatment, and visual density consistent with the rest of the campaign?
    • Does it avoid the generic motifs your brand has decided not to use?

    Brand consistency is easier to review when you describe it as repeatable visual constraints. A request to make an image feel more on-brand gives the next operator little guidance. A direction to reduce the palette, remove glowing interface elements, retain natural lighting, and preserve negative space can be repeated.

    3. Production quality

    • Inspect faces, hands, reflections, repeated objects, edges, shadows, and background details at full size.
    • Check every required crop instead of assuming one master image will survive them all.
    • Confirm that overlays remain readable against the image in the final layout.
    • Remove embedded gibberish, accidental marks, and elements that resemble logos.
    • Export an appropriately sized web asset rather than uploading a needlessly heavy working file.

    4. Rights and accountability

    • Verify the image tool’s current usage terms for your intended commercial or editorial context.
    • Do not prompt for a living artist’s signature style or use a real person’s likeness without the permissions your use requires.
    • Retain the generation and approval record where your content team can retrieve it.
    • Follow any disclosure, labeling, or provenance policy that applies to your organization, market, or publishing platform.

    If the image depicts a real person, regulated product, medical situation, financial outcome, or news event, move it out of the routine approval queue. The downside is not merely an awkward visual. A synthetic depiction can create a false factual impression, so use approved documentary material or obtain the appropriate specialist review.

    Publish the image as part of the page’s meaning

    An attractive image does not make a thin page authoritative, and image generation by itself does not create SEO or AI-search visibility. The asset should clarify the same entity, problem, process, or product that the surrounding text explains. If the image and page target different ideas, no metadata can repair the mismatch.

    • Use a descriptive filename: Name the actual subject and function of the image. Avoid camera-roll names, prompt fragments, and keyword strings.
    • Write alt text for purpose: Describe the useful information the image contributes in its page context. Do not begin with image of, repeat the caption, or pack in search terms. If the image is purely decorative, handle it as decorative rather than forcing a redundant description.
    • Keep nearby copy explicit: Introduce the concept in the heading, caption, or paragraph around the image. Do not make readers infer a critical claim from pixels alone.
    • Use a real caption when context is needed: A caption can explain that a visual is conceptual, identify what a diagram shows, or connect an illustration to the point being made.
    • Preserve consistency in structured data: If the page’s JSON-LD identifies an image, use the public URL of the image actually associated with the visible page. Do not invent creator, license, or ownership information merely to fill properties.
    • Check the delivered page: Confirm that the image loads, remains legible on small screens, has not been cropped around the wrong focal point, and does not push the page’s main answer below an oversized hero.

    The practical objective is alignment. The page title, main answer, visible image, alt text, caption, and structured representation should describe the same thing without duplicating one another mechanically. That gives human readers a coherent page and reduces ambiguity for systems trying to interpret it.

    Measure whether the image improved the marketing outcome

    Generation volume is not a performance metric. Neither is the number of minutes removed from the drafting stage if review and rework simply move downstream. Choose the image’s success measure from its job: engagement with an ad, progression from a landing-page hero, comprehension of an explained process, or completion of the action the surrounding content requests.

    When you test an image, hold the headline, offer, audience, placement, and call to action steady. Change one meaningful visual variable, such as human subject versus product detail, literal scene versus diagram, or close crop versus environmental context. If multiple elements change together, the result cannot tell you which decision mattered.

    Pair quantitative performance with a review of failure reasons. Track why generated candidates were rejected: weak message fit, brand mismatch, factual risk, poor crop, unusable text, or production artifacts. A repeated rejection reason is a briefing problem you can fix upstream. It is more actionable than simply asking the model for better images.

    Key takeaways

    • Start with the image’s placement and communication job, not a list of visual adjectives.
    • Generate controlled variations around one approved direction so feedback produces a decision.
    • Add exact wording, product interfaces, and other factual details through an approved production process.
    • Review truth, brand fit, production quality, and rights as separate approval gates.
    • Connect the image to the page with useful alt text, nearby context, consistent metadata, and a working public URL.
    • Judge the asset by the marketing outcome it supports, then use rejection patterns to improve the next brief.

    For your next asset, do not begin by polishing a longer prompt. Write the six-part brief, generate one controlled set of variations, and send only the strongest candidate through the four review gates. That small operating discipline is what turns AI image generation from a novelty into a dependable part of content production.

    References


  • How to Test AI Search SEO Claims Before You Act on Them

    How to Test AI Search SEO Claims Before You Act on Them

    Your AI search roadmap probably contains at least one recommendation that arrived as a certainty: abandon traffic forecasts, publish more AI-written pages, add llms.txt, or rebuild the site for a new class of crawler. Before you spend budget on it, you need to know what the evidence actually permits you to conclude.

    The practical rule is simple: match the size of the decision to the strength and scope of the evidence. A single successful page can disprove a claim that something is impossible, but it cannot prove the tactic will usually work. A trend in search activity cannot tell you how many visits websites will receive. An official statement about one platform cannot describe every AI system.

    First, identify what the claim is actually measuring

    Claims about AI search often collapse several different stages into one word: search. That makes weak arguments sound stronger than they are. A person can search, receive an answer, see a brand cited, click a link, and complete a valuable action. Each is a separate event, and each needs its own metric.

    • Demand: Are people conducting more or fewer searches on a particular surface?
    • Answer visibility: Does your brand or content appear in the responses that matter to your audience?
    • Citations: Does the response identify your page as supporting material?
    • Traffic: Do those appearances produce visits to your site?
    • Business outcomes: Do those visits produce qualified leads, sales, subscriptions, or another useful result?

    No single metric can stand in for the whole journey. In Q2 2026, the available measurements showed AI search and traditional search growing at roughly the same quarter-over-quarter rate. That does not support the broad claim that AI usage is simply replacing traditional search. Yet clicks to non-Google-owned desktop results were also at their lowest level since April 2025. Search activity and website traffic were moving differently.

    This distinction should change your reporting. Put search demand, answer visibility, citations, website visits, and conversions on separate lines. If demand is growing while click-through declines, do not diagnose the problem as disappearing interest. Investigate where the journey now ends, which queries still produce visits, and whether your pages earn visibility in the answer itself.

    The same discipline applies to AI referral traffic. A low referral count does not, by itself, prove that your brand is absent from AI answers. It may indicate low visibility, low citation frequency, low click-through, incomplete referral attribution, or some combination of them. Measure the stage you intend to improve.

    Match the evidence type to the question you need answered

    Four research stations use different instruments to examine website models, search signals, a page fragment, and documents around a central focal point.

    Evidence is not simply strong or weak in the abstract. It is useful when its design fits the decision. An official platform statement is valuable for learning whether that platform supports a file or protocol. It does not prove the file will improve performance. A crawler test can reveal whether content is technically retrievable. It cannot establish that the retrieved content will be cited. A traffic case can prove that growth remains possible. It cannot forecast growth for every site.

    Use the following evidence types deliberately:

    • Official implementation statements answer whether a named platform says it uses, supports, or ignores a feature. Keep the conclusion limited to that platform and the behavior described.
    • Direct technical observations, such as server logs or raw-response tests, answer what a crawler requested and what the server returned under the tested conditions.
    • Controlled comparisons help determine whether a change caused a result. The comparison needs a baseline, a suitable control, and protection against unrelated changes.
    • Repeated results across sites or page groups show whether an effect travels beyond one example. Check whether the sample resembles your site before generalizing.
    • Case examples establish possibility. They are particularly useful for rejecting absolute claims containing words such as never, impossible, or cannot.
    • Anecdotes and expert opinions are starting points for investigation, not automatic reasons to change a production site.

    The burden of proof should rise with the cost of the decision. A reversible metadata experiment does not require the same confidence as a sitewide rendering migration. Replacing a publishing workflow, moving engineering capacity, or abandoning an established acquisition channel should require evidence that addresses your actual platform, audience, metric, and risk.

    Before accepting a claim, ask six questions:

    • What exact outcome was measured?
    • Which sites, pages, queries, crawlers, or users were included?
    • How long did the observation run?
    • Was there a baseline or comparison group?
    • What else changed during the same period?
    • Does the conclusion describe possibility, frequency, causation, or expected return?

    That final question catches a common reasoning error. One counterexample is enough to defeat a universal claim that a tactic can never work. It is not enough to show that the tactic works consistently, causes the result, or deserves investment.

    Five AI SEO claims that require narrower conclusions

    Claim: AI search is killing traditional search

    The demand-level evidence does not support a simple replacement story. In the measured Q2 2026 period, AI and traditional search expanded at approximately the same quarter-over-quarter rate. The click-level evidence is less comfortable: Google was sending fewer desktop clicks to non-Google-owned results.

    The defensible conclusion is that AI adds another discovery layer while answer-first experiences can reduce the share of activity that reaches the open web. Treating those observations as contradictory creates a false choice. Both can occur at once.

    For planning, maintain separate assumptions for search activity and click yield. If traditional search demand remains healthy but fewer impressions turn into visits, concentrate on query classes that still produce action, improve the value communicated in titles and snippets, and measure visibility inside answer surfaces. Do not erase an entire channel from the forecast because its click efficiency changed.

    Claim: Zero-click search makes organic growth impossible

    A local business reached its highest recorded month of organic website clicks in July 2026, with the increase attributed to nonbranded blog content and service pages. That example is enough to reject the word impossible. It is not evidence that every publisher, retailer, software company, or national brand should expect the same outcome.

    Local businesses occupy a different risk category because the route from a location- or service-specific query to an action can differ from the route for an informational publisher. Segment your expectations by site model, query intent, geography, and page type. An average across unrelated sites can conceal the part of your portfolio that still has room to grow.

    Instead of pausing organic work on the strength of a market-wide prediction, choose a coherent set of nonbranded queries and the pages that serve them. Track impressions, clicks, qualified actions, and landing-page performance against an unchanged comparison group. Your own result will be narrower than a universal forecast, but much more useful for deciding where your next unit of effort belongs.

    Claim: Purely AI-generated content cannot rank

    A four-page test provides a useful counterexample: four articles generated entirely through AI continued to rank and perform after careful prompting, light human review, and no manual rewriting. This defeats the categorical claim that AI-written material is automatically barred from search performance. Four pages cannot establish the success rate of AI-generated content in general.

    The more useful distinction is between production method and information value. An LLM can accelerate drafting, but it does not supply a worthwhile premise by default. Pages still need a clear purpose, accurate claims, relevant expertise, original information or analysis where available, and a point of view specific enough to help the reader make a decision. Low-effort, repetitive output fails that test regardless of how quickly it was produced.

    Audit AI-assisted pages with the same questions you would apply to any other page: What new information or synthesis does this provide? Which claims can be checked? Where does the page answer the query more precisely than existing results? Which paragraphs could appear on any competitor’s site without alteration? Remove generic sections, verify factual claims, and give a qualified reviewer responsibility for the final page. The percentage of words produced by a model is not a useful performance target.

    Claim: Adding llms.txt will improve AI visibility

    Google has explicitly stated that it does not use llms.txt for AI search discovery. A separate implementation check covering 10 sites for 90 days found no measurable change in AI crawl frequency or AI-referred traffic for most sites. Where movement appeared, other SEO work accounted for it.

    This is stronger evidence than the mere availability of the file, but the conclusion still needs boundaries. A 10-site, 90-day observation cannot prove that no present or future AI system will ever use llms.txt. It does show that the file should not be presented as a demonstrated visibility lever on the evidence available.

    Treat llms.txt as optional infrastructure, not as a strategy or key performance indicator. If it sits in your backlog beside crawl access, server-rendered content, useful page creation, or measurement, the supported work comes first. If you implement the file, record what mechanism you expect, which crawlers should respond, what metric should change, and what result would justify maintaining it. The existence of the file is an output, not an outcome.

    Claim: AI crawlers can render JavaScript like a browser

    Crawler-behavior testing found that the emerging AI search crawlers examined did not render JavaScript. That finding should not be stretched to every crawler forever, but it is enough to make client-side-only delivery a material visibility risk.

    Test what the server returns before a browser executes scripts. Use page source or an HTTP fetch that does not run JavaScript, then search the response for the exact answer text, product or service facts, links, and structured data you expect a machine to consume. Looking at the finished page in a browser is not the same test; the browser may have assembled content that an AI crawler never received.

    If critical material is absent from the initial HTML, render it on the server or provide a static pre-rendered response. Apply the same check to JSON-LD injected by client-side scripts. This does not guarantee that an AI system will cite the page, but it removes a basic access failure: the system cannot evaluate information that its crawler never obtains.

    Build a claim ledger before changing the roadmap

    A hand sorts evidence pieces into blank color-coded rows on an open planning board while a modular roadmap waits in the background.

    A claim ledger turns AI SEO discussion into a decision process. Create one entry for every recommendation competing for budget, including recommendations you already believe. Each entry should contain the following:

    1. Write the claim precisely. Name the platform, behavior, metric, and affected page group. Replace broad language such as AI visibility will improve with a testable statement.
    2. Describe the mechanism. State what the platform or crawler would need to do for the proposed change to produce the expected result.
    3. Record the evidence type and scope. Distinguish an official statement, technical observation, controlled comparison, multi-site pattern, case example, and opinion.
    4. List the boundary conditions. Note the sites, queries, crawlers, rendering setup, market, and observation period to which the evidence actually applies.
    5. Identify competing explanations. Content changes, technical fixes, brand activity, seasonality, and measurement changes can move the same metric.
    6. Set the decision rule before implementation. Define the outcome that would justify scaling, revising, or stopping the tactic.
    7. Assign a review point. Platform behavior changes, so a sound decision needs a date or trigger for re-examination rather than permanent acceptance.

    Then label each backlog item keep, test, defer, or stop. Keep work supported by direct evidence and a clear mechanism, such as making critical content available in server-returned HTML when relevant crawlers do not render it. Test plausible changes whose effect remains uncertain. Defer tactics whose evidence is weak and whose opportunity cost is high. Stop initiatives built on a categorical premise that available counterexamples have already disproved.

    Do not let measurement begin after implementation. Capture the baseline first, avoid unrelated changes to the same test group where practical, and keep a comparison group. If several SEO changes launch together, you may observe improvement without learning which change caused it. That can produce an attractive chart and a poor investment decision.

    Key takeaways

    • Search demand, answer visibility, citations, website traffic, and conversions are different outcomes. Use a metric that matches the claim.
    • A counterexample can disprove an absolute claim, but it cannot establish how often a tactic succeeds or what return you should expect.
    • Traditional and AI search can grow while website click-through declines. Model demand and click yield separately.
    • Judge AI-assisted content by its accuracy, originality, specificity, and usefulness, not by an unsupported assumption about authorship detection.
    • Treat llms.txt as optional infrastructure until evidence connects it to a measurable outcome for the platforms you care about.
    • Inspect the raw server response. If essential content or JSON-LD exists only after JavaScript runs, some AI crawlers may never receive it.

    At your next planning review, pick the most expensive AI SEO recommendation on the roadmap and reduce it to one testable sentence. Name its mechanism, metric, evidence type, boundary conditions, and stopping rule. If the claim cannot survive that exercise, it is not ready to consume the budget. If it can, you have the beginnings of a test that will teach you something specific about your own visibility.

    References


  • Fractional SEO Leadership: When It Fits and How to Hire

    Fractional SEO Leadership: When It Fits and How to Hire

    Your SEO agency delivers recommendations, your content team publishes, and engineering handles requests when capacity opens up. Yet nobody can give a defensible answer when leadership asks what should happen next, what can wait, or how search visibility connects to growth.

    That is the problem fractional SEO leadership is built to solve. You are not renting another pair of hands. You are giving an experienced search leader a defined mandate to set priorities, coordinate teams, and make the work commercially coherent without immediately adding a full-time executive.

    Key takeaways

    • Hire a fractional SEO leader when you already have people who can execute but lack one senior owner for priorities, tradeoffs, and cross-functional coordination.
    • Use the model during leadership gaps, migrations, replatforming, expansion, acquisitions, launches, or other periods when the cost of a poor search decision is unusually high.
    • Do not use fractional leadership as a cheaper substitute for the writers, developers, analysts, outreach specialists, or production capacity you actually need.
    • Define decision rights, execution owners, expected outputs, measurement, and exit conditions before negotiating hours or retainer terms.
    • Evaluate candidates by the quality of their judgment and operating discipline, not by the size of the audit they promise.

    Start with the ownership gap, not the job title

    A senior leader places a connecting piece between three separate team workflows at a central junction.

    Put your active SEO work in one place and ask four questions: Who can reorder this list? Who can commit another team’s resources? Who decides that an opportunity is not worth pursuing? Who explains those decisions to senior leadership?

    If the answer changes from project to project, you probably have coordination but not ownership. That distinction matters because organic visibility now crosses content, product, engineering, digital PR, brand, analytics, and AI-powered search. Each function can complete its own tasks while the overall program still drifts.

    The symptoms are usually visible before the missing role is:

    • Technical audits accumulate, but engineering cannot tell which fixes protect revenue or unlock growth.
    • Content planning follows keyword volume while product priorities, buyer intent, and sales evidence sit elsewhere.
    • An agency reports completed deliverables but repeatedly waits for internal approvals or strategic direction.
    • Marketing launches an AI-visibility initiative without clear access to product facts, subject-matter experts, analytics, or reputation work.
    • Different teams use different definitions of success, so meetings become debates about metrics rather than decisions about investment.

    A fractional leader can address those conditions only if the underlying need is leadership. Use the following distinction before you start interviewing.

    ModelWhat you are primarily buyingBest fitCommon mismatch
    Fractional SEO leaderSenior judgment, prioritization, governance, cross-functional alignment, and executive communicationYou have execution capacity but no strategic owner, or you temporarily need experienced leadershipYou expect the leader to personally complete a large production backlog
    SEO agencyA team, production capacity, specialist services, or a defined program of workYou need repeatable execution across an agreed scopeNo internal owner can make decisions, remove dependencies, or assess agency recommendations
    SEO freelancer or consultantFocused expertise or a specific deliverable such as an audit, analysis, or implementation projectThe problem is bounded and you know what output you needThe real problem spans departments and requires continuing authority
    Full-time SEO leaderContinuously embedded ownership, organizational development, and often people managementThe strategic and management workload is durable enough to require a permanent roleThe company needs senior input only during a transition or for a limited set of decisions

    When fractional leadership is a strong fit

    • Your execution engine already exists. Internal marketers, developers, content specialists, freelancers, or an agency can do the work once priorities and requirements are clear.
    • You are between SEO leaders. A fractional appointment can preserve strategic continuity while you determine whether and how to fill a permanent role.
    • You are entering a consequential change. A migration, replatforming, international expansion, acquisition, or product launch creates decisions that cut across normal team boundaries.
    • Your agency needs an informed counterpart. The fractional leader can test recommendations against business priorities, settle internal tradeoffs, and hold both the agency and the company accountable.
    • The work is complex but not continuous enough for a permanent executive. You need senior judgment at important decision points rather than full-time supervision.

    When you need something else

    • You have nobody to implement the plan. Hire execution capacity first or combine leadership with an explicitly staffed delivery team.
    • The role is expected to manage employees every day. That points toward an embedded leader unless the arrangement is clearly temporary.
    • No executive sponsor will resolve conflicts. A fractional leader cannot coordinate teams that are free to ignore every decision.
    • You want guaranteed rankings or guaranteed inclusion in AI answers. Neither can be responsibly promised. Treat the promise itself as a warning sign.
    • Your problem is already narrow and understood. If you need a crawl diagnosis, a schema implementation, or a content brief, a specialist engagement is likely more efficient.

    Write the leadership charter before you hire

    A vague mandate such as improve SEO invites activity without accountability. It also lets every department assume that someone else owns implementation. Write a short charter that answers six questions before you discuss retainer size.

    1. What business objective does organic visibility support? Name the market, product, audience, or growth constraint. Traffic by itself is not a business objective.
    2. What is in scope? Specify whether the mandate includes technical SEO, content strategy, digital PR coordination, local or international search, AI-search visibility, analytics, agency management, or migration governance.
    3. Which decisions can the leader make? Separate authority to decide from authority to recommend. If an executive must approve resource changes, name that person and define the escalation path.
    4. Who executes? Assign owners for engineering, content, design, analytics, PR, product data, and external vendors. Do not hide these dependencies inside the fractional role.
    5. What evidence will guide priorities? List the analytics, search data, customer evidence, business forecasts, technical diagnostics, and AI-response observations that are reliable enough to use.
    6. What should exist when the engagement ends? Examples include a functioning operating cadence, an approved roadmap, documented measurement, a completed transition, or a permanent leader who can take over cleanly.

    Sample mandate: Own the organic and AI-search strategy for the selected market; maintain a prioritized roadmap; coordinate internal teams and external partners; document material tradeoffs; and report progress, constraints, and investment choices to the executive sponsor.

    That mandate is intentionally about decisions. The expected outputs should make those decisions usable:

    • A baseline that distinguishes technical constraints, demand opportunities, authority gaps, representation problems, and measurement limitations.
    • One prioritized backlog instead of separate agency, content, engineering, and AI-search wish lists.
    • A roadmap that records expected value, confidence, effort, dependencies, risk, owner, and next decision for each major initiative.
    • Decision briefs for expensive or difficult choices, including the alternatives considered and the cost of waiting.
    • A measurement model connecting implementation and visibility indicators to qualified demand and business outcomes.
    • A durable handoff containing open risks, assumptions, data definitions, vendor responsibilities, and pending decisions.

    Set the operating cadence around decision latency. If your site changes frequently, a meeting that occurs only after several releases will arrive too late. If the roadmap changes slowly, constant meetings will add noise. Every review should end with a recorded decision, owner, deadline, dependency, or explicit reason to defer.

    Access is part of the operating model. The leader may need relevant analytics, Search Console, crawl data, CMS and release context, product roadmaps, conversion definitions, agency work, content inventories, brand research, and the people who own them. Grant the least access required, but do not expect accountable leadership from partial evidence and second-hand summaries.

    Hire for judgment, not an impressive audit

    The most revealing interview is not a request for more tactics. Give the candidate a realistic conflict from your organization and ask how they would decide. A strong answer will expose assumptions, request missing evidence, identify affected teams, and explain what would change the recommendation.

    Use questions that force the candidate to demonstrate prioritization:

    • Show us a roadmap where you decided not to pursue plausible SEO opportunities. What was rejected, and what evidence made another investment more important?
    • Walk us through a technical issue that competed with product work. How did you describe the risk, estimate the opportunity, and reach a decision with engineering?
    • How would you decide whether an AI-search problem belongs in content, technical SEO, digital PR, product data, or brand work? Look for diagnosis across functions, not a default answer tied to one service.
    • Which measures would you use first, and which would you refuse to treat as proof? A credible leader should distinguish business outcomes, visibility indicators, operational progress, and attribution limits.
    • What authority and access would you need from us? Candidates who promise ownership without asking about decision rights and dependencies are skipping the organizational problem.
    • What would tell you that we need a full-time leader instead? Fractional status should not be defended after the role has become permanently embedded and operational.
    • How will your work remain usable after you leave? Listen for shared systems, documentation, knowledge transfer, and clear ownership rather than personal spreadsheets and private dashboards.

    Ask to see sanitized examples of decision documents, roadmaps, measurement definitions, and executive updates where confidentiality permits. You are assessing whether the person can turn specialist evidence into choices that other teams can understand and execute. A technically detailed audit can be useful, but it does not prove leadership.

    References should include people who received the candidate’s recommendations and people expected to implement them. Ask whether priorities became clearer, whether conflicts were resolved, whether risks were communicated early, and whether the organization was less dependent on the consultant by the end.

    Watch for predictable warning signs:

    • A large audit is proposed before the candidate understands the business decision it must support.
    • The pitch treats traffic, rankings, AI citations, or content volume as the goal without connecting them to qualified demand.
    • Every problem leads to the same familiar service, tool, or content format.
    • The candidate avoids responsibility for prioritization while still asking to be treated as the strategic owner.
    • Reporting centers on tasks completed rather than decisions made, work shipped, constraints removed, and outcomes observed.
    • The engagement depends on proprietary data or undocumented processes that you cannot retain after termination.

    Your agreement should reflect the same discipline. Define scope, availability, response expectations, conflicts of interest, data handling, ownership of work products, vendor relationships, termination, and handoff. Hours matter for capacity, but they are a poor substitute for a clear mandate.

    Measure whether leadership turns into shipped work

    A leader and cross-functional team move prioritized task tiles from a planning table through production toward a completed launch.

    A fractional leader should not be judged only by rankings, and they should not be insulated from outcomes by reporting only meetings and recommendations. Use three connected layers of measurement.

    • Business outcomes: qualified leads, transactions, revenue, retention-supporting discovery, or another outcome the company already trusts. State attribution limits instead of forcing every change into a false direct-revenue claim.
    • Search and discovery outcomes: qualified organic demand, visibility for commercially relevant topics, landing-page performance, crawl and index health, brand representation, and observed presence in relevant AI responses.
    • Operating outcomes: important work implemented, decision delays reduced, dependencies resolved, roadmap items aging for explicit reasons, and teams using the same priorities and definitions.

    Establish the baseline before major plan changes. Annotate launches and releases. Keep recommendations separate from implementation, because an idea sitting in a backlog cannot produce a result. When work is blocked, report the dependency, its owner, the consequence, and the decision required. This makes accountability fair to both the fractional leader and the teams doing the work.

    AI-search measurement needs particular care. A prompt set is a sample, not a census of everything users might ask or everything a model might answer. Record the prompts, market, model or surface, observation date, response, cited domains, brand inclusion, and factual accuracy so later checks are comparable. Then connect observed gaps to work you can actually own: clearer product information, stronger expert content, technical accessibility, consistent brand facts, or credible third-party mentions.

    Automation can accelerate parts of research, analysis, and production, but the higher-value decisions are what to automate, what to test, what to prioritize, and how visibility connects to business results. If your reporting celebrates faster output without checking accuracy, differentiation, implementation, or commercial relevance, the program is optimizing motion.

    Build the transition into the engagement from the start. Move toward a full-time hire when strategic work, people management, and cross-functional decisions have become continuous. End or narrow the engagement when the defined transition is complete and internal owners can run the system. Expand execution separately when leadership is working but delivery capacity is still the constraint.

    Before contacting candidates, bring marketing, content, product, engineering, analytics, PR, and your current agency into one working session. List the consequential search decisions that lack an owner, the work already ready to ship, and the authority a temporary leader could realistically hold. If the list is mostly production tasks, buy execution. If it is dominated by priorities, tradeoffs, dependencies, and executive decisions, you have a credible case for fractional SEO leadership.

    References


  • How to Make Products Visible to AI Personal Shoppers

    How to Make Products Visible to AI Personal Shoppers

    Your product can rank in conventional search and still disappear when a shopper asks an AI assistant what to buy. The missing piece is usually not another generic category paragraph. It is making the product easy to identify, test against constraints, and defend in a recommendation.

    AI personal shoppers can shape which products make the shortlist. That changes your visibility target. You are no longer optimizing only for a page visit; you are helping a system decide whether your product is eligible, relevant, credible, and safe to recommend for a particular request.

    AI shopping visibility is a three-gate problem

    There is no universal ranking formula for AI shopping. Assistants use different catalogs, retrieval systems, merchant feeds, pages, and models. Their answers can also change as availability, prices, prompts, and underlying systems change. A practical three-gate model is more useful than pretending every platform works the same way.

    1. Discovery: Can the assistant find and identify the correct product or variant?
    2. Qualification: Can it determine whether the product satisfies the shopper’s stated constraints?
    3. Selection: Is there enough relevant evidence to choose the product and explain that choice?

    A product has to pass the gates in that order. Better promotional copy cannot rescue a product the system cannot identify. Strong reviews cannot compensate for an unspecified compatibility requirement. Complete structured data does not prove a broad superiority claim.

    This sequence gives you a diagnostic method. If the product never appears, inspect discovery before rewriting the sales copy. If it appears for broad prompts but disappears when a constraint is added, inspect the relevant attribute. If it remains eligible but another product receives the recommendation, inspect comparative relevance and supporting evidence.

    The important distinction is between being mentioned and being recommendable. A system may know that your product exists while lacking the facts needed to place it in a defensible shortlist.

    Build one canonical product truth

    A hiking shoe on a central platform sends the same set of visual product attributes to a storefront, phone, warehouse shelf, and AI orb.

    Start with an internal product record, not a block of marketing copy. This record should be the authoritative source for the product page, structured data, merchant feeds, marketplace listings, comparison pages, and support content. When those surfaces disagree, an assistant has to choose among conflicting claims or avoid repeating them.

    For each product and meaningful variant, define the following fields explicitly:

    • Identity: brand, product name, model, assigned SKU or GTIN, canonical URL, and product category.
    • Variant: color, size, capacity, material, pack quantity, configuration, and the relationship to the parent product.
    • Eligibility attributes: dimensions, weight, compatibility, intended use, required accessories, included components, operating conditions, and other category-specific constraints.
    • Commercial facts: price, currency, condition, availability, fulfillment terms, returns, and warranty terms.
    • Evidence: certifications, documented test conditions, review data, manuals, specifications, and the exact scope of each claim.

    Do not populate a field because competitors use it or because a schema validator permits it. An unknown value should remain unknown until the business can verify it. A precise false claim is worse than an honest omission because the false claim can be repeated in a recommendation, create a poor purchase, and undermine trust in the rest of your data.

    Keep the visible page, schema, and feeds aligned

    Product structured data should encode facts that a shopper can also verify on the page. Use Product markup to identify the item and its attributes. Use Offer data only for an offer that actually exists. Add rating or review properties only when the corresponding information is genuine, visible, and attached to the correct product or variant.

    JSON-LD does not create product truth. It translates product truth into a machine-readable form. If the page says one material, the markup says another, and the feed omits the field, adding more schema will multiply the ambiguity rather than fix it.

    Variant handling deserves particular attention. A family page may describe several configurations, but price, dimensions, availability, ratings, and compatibility can belong to only one of them. Give meaningful variants stable identities and make the selected variant unambiguous in the page content, URL behavior, structured data, and feed.

    Separate durable facts from fast-changing facts

    Product data fails at different speeds. Model identity, dimensions, materials, compatibility, and included components are usually durable. Price, availability, promotions, delivery estimates, and review aggregates can change much faster.

    Give each fast-changing field an owner, a system of record, and a refresh trigger. Avoid embedding volatile values in editorial prose unless that prose is updated from the same source. A stale promotional page and a current product feed can leave an assistant with two plausible answers and no reliable way to reconcile them.

    Match shopper constraints and support every important claim

    Traditional product copy often begins with a head keyword and expands into benefits. AI shopping requests are more likely to combine a job, a hard constraint, and a preference: a product for a particular use, compatible with something the shopper already owns, within a budget, and with a preferred trade-off.

    Create a prompt set from the decisions people make, not just the phrases with the highest search volume. Include several distinct request types:

    • Job prompts: What is the shopper trying to accomplish?
    • Constraint prompts: What would make a product ineligible, such as size, compatibility, material, price, or availability?
    • Trade-off prompts: Which quality matters more when no option maximizes everything?
    • Comparison prompts: Which alternatives are genuinely close enough to compare?
    • Risk prompts: What must the shopper verify before buying?

    Then map every consequential question to a field and a piece of evidence. The map exposes a common failure: the marketing team believes a benefit is obvious, but the product page never supplies the fact an assistant would need to infer it safely.

    Shopper questionMachine-readable answerHuman-verifiable support
    Will it fit?Dimensions, weight, capacity, or supported size rangeSpecification table, diagram, or installation instructions
    Will it work with what I own?Compatible models, interfaces, versions, or required accessoriesCompatibility page, manual, or clearly scoped support content
    Can I buy it under my stated conditions?Current price, currency, condition, availability, and offer detailsVisible offer and fulfillment information
    Is it suitable for this use?Intended use and relevant product attributesUse-case explanation tied to specifications rather than slogans
    Can I trust this claim?Named evidence and its scopeCertification details, documented method, policy, or attributable review data

    State who the product is and is not for

    A useful product page helps an assistant eliminate the wrong matches. State the primary use, the buyer or environment it suits, the constraints it satisfies, and any condition that would make another option more appropriate.

    This does not weaken the offer. A clear limitation can make the positive recommendation more credible. If a product requires an adapter, has a fixed dimension, excludes a particular model, or is designed for one usage pattern rather than another, say so close to the relevant benefit. Hiding the qualifier may generate more initial interest, but it gives an assistant less reason to trust or repeat the claim.

    Comparison content should use decision criteria rather than a list of adjectives. Explain which product fits which condition and why. Avoid declaring an item the best without naming the use case, comparison set, and evidence. An unqualified superlative is difficult to defend and easy for a recommendation system to ignore.

    Maintain a claim-to-evidence ledger

    For every claim that could change a purchase decision, keep an internal ledger containing the claim, its exact qualifier, the supporting evidence, the page where that evidence is visible, the responsible owner, and the event that should trigger a review.

    The qualifier matters. A certification may apply to one variant, a test may use specific conditions, and a warranty may differ by market. Preserve that scope everywhere the claim appears. Do not turn narrow evidence into a product-wide promise.

    Customer reviews can help describe recurring strengths and limitations, but keep review data attached to the product or variant it evaluates. Combining materially different variants may produce a stronger aggregate while giving the assistant a less accurate picture of the item in front of the shopper.

    Support pages, manuals, compatibility resources, return policies, and comparison pages should link back to the canonical product and use the same names and identifiers. That creates a coherent evidence trail instead of a set of disconnected documents with slightly different terminology.

    Audit the complete path from prompt to recommendation

    A shopper request travels through product, evidence, inventory, checkout, and delivery checkpoints before reaching an unbranded product shortlist.

    Do not reduce AI shopping visibility to a rank check. You need to see where the product exits the decision process and whether the answer is factually correct when it does appear.

    1. Choose eligible prompts. Test requests for which the product could honestly be a suitable answer. Irrelevant prompts distort the score and tempt teams to broaden claims beyond the product’s real fit.
    2. Record a baseline. Save the exact prompt, assistant, date, market or locale, response, recommended products, stated reasons, and any surfaced links.
    3. Label the outcome. Distinguish absence, failed qualification, incorrect description, unsupported mention, and an eligible product that lost on a documented trade-off.
    4. Trace the earliest failed gate. Repair identity and discovery before attributes, attributes before evidence, and evidence before promotional expansion.
    5. Rerun the same prompt set. Compare changes in coverage and accuracy while recognizing that any individual generated response can vary.
    6. Inspect the commercial handoff. If the recommendation is accurate but the shopper does not proceed, examine the offer, availability, landing experience, and product-market fit rather than calling every weak outcome an AI visibility problem.

    The failure pattern tells you where to look first:

    Observed resultLikely failure areaFirst inspection
    The product never appearsDiscoveryIndexability, canonical URL, feed inclusion, product identity, and internal linking
    The wrong variant appearsIdentityVariant names, identifiers, URLs, parent relationships, and selected-offer data
    The product disappears after a valid constraint is addedQualificationThe missing, ambiguous, or conflicting attribute associated with that constraint
    The assistant states an incorrect factProduct truthConflicts and stale values across the page, schema, feed, marketplace, and support content
    The product is considered but not recommendedSelectionUse-case specificity, comparison criteria, limitations, and claim-level evidence
    The recommendation is accurate but does not convertCommercial handoffPrice, availability, trust, offer clarity, landing experience, and actual product fit

    Track metrics that correspond to those states. Prompt coverage shows whether the product appears for eligible requests. Attribute resolution shows whether the assistant can answer the important constraint questions. Answer accuracy catches misdescription. Evidence visibility shows whether useful supporting pages are surfaced. Recommendation share shows how often the product is selected when it is genuinely eligible. Commercial outcomes tell you whether improved visibility creates useful demand.

    Keep the prompt set and eligibility rules stable while evaluating a change. If you change the content, prompts, markets, and success definition at the same time, you will not know what improved. Treat assistant outputs as observations, not permanent rankings.

    Key takeaways

    • Optimize for discovery, qualification, and selection as separate gates.
    • Create one canonical product record before expanding copy, schema, feeds, or comparison content.
    • Make decisive constraints explicit; do not ask an assistant to infer compatibility, fit, or eligibility from vague prose.
    • Keep visible content, Product structured data, offers, variants, and merchant feeds consistent.
    • Attach meaningful claims to scoped evidence and state important limitations plainly.
    • Measure eligible prompt coverage and factual accuracy before treating recommendation share as the main result.

    Start with one commercially important product family. Establish its canonical facts, build prompts around real purchase constraints, and fix the earliest gate that fails. Once that path is reliable, extend the same operating model to the rest of the catalog. That gives you a repeatable visibility system instead of a collection of schema additions and copy changes whose effect you cannot explain.

    References


  • Content Refresh or New Page? A Decision Guide for AI Search

    Content Refresh or New Page? A Decision Guide for AI Search

    You have a page whose answer is getting stale, but the URL may still hold useful search visibility, links, and recognition. Editing it too aggressively could erase what made it useful. Publishing another page could split one clear answer across two competing URLs.

    The decision turns on continuity: does the existing URL still represent the question you want to answer? The right planning question is not simply how often to update. It is when to refresh and when to create something new for AI search. Use the framework below to make that call before anyone starts rewriting.

    Start with answer continuity, not publication age

    Every useful URL makes an implicit promise. Its title, opening, headings, internal links, and search snippets tell a reader what question the page will resolve. A refresh is appropriate when that promise remains valid and the answer needs to become more accurate, complete, or usable. A new page is appropriate when the promise itself has changed.

    This distinction matters more than the size of the edit. You can rebuild most of a page and still call it a refresh if the same reader arrives with the same question and should reach the same kind of outcome. Conversely, a short addition can deserve a separate URL if it serves a materially different intent, audience, entity, version, or decision.

    Use this three-step test before looking at traffic charts:

    1. Write the existing page’s primary question in one sentence, using the language a reader would use.
    2. Write the proposed page’s primary question in another sentence. Do not describe the content format; describe the decision or task the reader needs to complete.
    3. Compare the expected outcomes. If both questions lead to the same outcome, refresh the existing page. If they lead to different outcomes and both remain useful, create a new page.

    Suppose an existing page explains what answer engine optimization is. Adding current terminology, clearer examples, better sourcing, and a stronger definition would preserve its promise. A page that helps a marketing lead choose an AEO measurement platform serves a different job. Forcing that purchasing decision into the definition page would make both answers harder to extract and harder to trust.

    A refresh is usually the cleaner choice when the target question, intended reader, principal entity, and required answer format remain stable. It is also appropriate when outdated claims can be replaced without changing the page’s central conclusion.

    Create a new page when the reader now needs a different task completed, such as moving from learning to comparing, implementing, troubleshooting, or buying. A separate page is also warranted when a new product version, market, audience, or use case has enough distinct constraints to support its own complete answer.

    Do not let a traffic decline make the decision for you. Declining traffic can trigger an audit, but it does not prove that the URL is obsolete. The page may have weak evidence, an indirect opening, an outdated title, changed search demand, stronger competition, or technical problems. Diagnose the mismatch before choosing the remedy.

    Audit the question, claims, entities, and page structure

    A magnifying lens examines layered document components, connected spheres, evidence tiles, and modular page blocks.

    A useful content audit separates five layers that teams often collapse into one vague judgment about freshness. Review each layer independently. One outdated statistic may require a correction; a changed audience may require an entirely new page.

    Audit layerQuestion to askSignal to refreshSignal to create a new page
    QueryWhat specific question should this URL answer?The wording has evolved, but the reader’s task is unchanged.The proposed query represents another task or decision stage.
    AnswerWhat must the reader know or do after reading?The conclusion still holds and needs better support or explanation.The new conclusion would conflict with or displace the existing answer.
    AudienceWho is the answer for, and what do they already know?The same audience needs a clearer or more current explanation.A distinct audience needs different assumptions, terminology, or actions.
    EntityWhich product, organization, concept, location, or version is central?The same entity needs corrected attributes or relationships.A separate entity or version deserves independent treatment.
    StructureCan the answer remain coherent on the current page?Sections can be repaired without changing the page’s purpose.The proposed material would overwhelm the original answer or create two competing introductions.

    Begin the audit with the rendered page, not just the draft in your content management system. Record the title, opening answer, headings, important claims, citations, internal links, media, structured data, canonical target, and displayed publication or modification dates. Save a version before editing so you can distinguish the effect of the change from your memory of the old page.

    Next, label every consequential claim as current, obsolete, unsupported, ambiguous, or outside the page’s scope. Pay particular attention to claims that can change independently of the main topic: product features, prices, eligibility rules, named executives, legal requirements, performance figures, dates, and version-specific instructions. Do not preserve an unsupported statement merely because the page performs well.

    Then inspect the answer a machine or hurried reader is likely to encounter first. If the title promises one question while the opening answers another, the page has an alignment problem. If the direct answer appears only after a long historical preamble, the page has an extraction problem. Both are refresh problems when the underlying intent remains stable.

    Entity ambiguity deserves its own pass. A page that alternates between a company, its platform, a feature, and an industry category without defining their relationships may be readable to an insider but unclear outside that context. Introduce the principal entity explicitly, use consistent names, and clarify relationships that affect the answer. Structured data cannot repair contradictory prose.

    Use performance evidence after the semantic audit. Review the queries and landing-page behavior available to you, conversions tied to the page’s intended outcome, internal-search terms, links, and any reliable records of AI referrals or citations. Treat AI answer observations as directional rather than deterministic: outputs can vary by prompt, model, context, location, and time. A single missing citation is not enough evidence to replace a URL.

    Calendar age should trigger inspection, not automatic rewriting. Set review frequency according to the page’s rate of change. Version-dependent instructions should be reviewed when the product changes. Pages built around external rules or figures should be checked when the underlying authority changes. Stable conceptual pages can be reviewed when query patterns, audience needs, or the evidence base shifts. The useful cadence is therefore page-specific rather than one site-wide interval.

    Refresh the URL without blurring its original promise

    Once you choose a refresh, define what will remain unchanged. Write a one-sentence content brief containing the primary question, intended reader, required outcome, and central entity. That sentence becomes the boundary for the revision. Any proposed section that serves another substantial question goes into a separate-page backlog.

    1. Capture a baseline. Save the current page, record the change date, and preserve the available query, engagement, conversion, link, and AI-visibility evidence. Without a baseline, a later increase or decline will be difficult to interpret.
    2. Repair the opening answer first. Make the page’s conclusion or recommended action visible near the start. State important conditions and exceptions where they affect the answer rather than hiding them in a closing note.
    3. Replace obsolete material in place. Do not leave a wrong claim in the main text and append a correction at the bottom. Remove or rewrite passages that no longer help the reader complete the stated task.
    4. Strengthen the evidence chain. Connect consequential claims to appropriate supporting references, identify versions and dates when they matter, and distinguish established facts from editorial judgment or uncertain observations.
    5. Rebuild the heading structure around real subquestions. Each section should resolve a distinct part of the primary question. If two sections repeat the same conclusion in different language, combine them.
    6. Align internal links with the revised role of the page. Links pointing in should accurately describe what the reader will find. Links pointing out should handle adjacent questions without making this page compete with them.
    7. Update machine-readable information to match the visible page. Structured data should describe the content that is actually present, use the applicable type, and remain consistent with names, dates, authorship, and entities shown to readers.
    8. Publish with an honest modification signal. Update a modification date when a substantive revision occurred, not as a cosmetic attempt to make unchanged material look current. Keep an internal change log so the team knows what was altered and why.

    Preserve the existing slug unless changing it solves a real information-architecture problem. A refreshed page does not need a new URL merely because its title changed. If a slug must change, map the old URL to the most appropriate replacement and update important internal links; otherwise, you introduce avoidable routing and measurement noise.

    Be equally disciplined with schema. Adding more JSON-LD types does not compensate for a weak answer. Markup should represent visible, accurate information and should not imply reviews, FAQs, authorship, products, or organizational relationships the page does not substantiate. Validate the markup after publishing, but treat technical validity as a floor rather than proof that the content is useful.

    After publication, confirm that the page renders correctly, remains indexable where intended, exposes the expected canonical URL, and includes the revised structured data. Annotate the release in your reporting. Then watch the same measures captured in the baseline. Do not change the page repeatedly in response to isolated fluctuations; overlapping revisions make it impossible to learn which change mattered.

    Create a new page when the reader needs a separate answer

    A luminous information stream divides into two non-overlapping paths leading to separate pavilions with distinct clusters of connected nodes.

    A new page should exist because it resolves a distinct question, not because the editorial calendar needs another URL. Before commissioning it, complete this sentence: “Unlike the existing page, this page helps [audience] accomplish [outcome] under [relevant conditions].” If the difference cannot be expressed without vague words such as deeper, broader, or updated, the proposed page probably belongs in the refresh.

    Distinct search intent is the strongest reason to separate pages. A definition, implementation tutorial, vendor comparison, troubleshooting workflow, and measurement plan may concern the same topic while serving different decisions. Giving each substantial task a clear home lets you answer it directly without turning one page into a collection of half-developed responses.

    A separate audience can also justify a new URL, but only when the difference changes the answer. Replacing “marketing leader” with “agency” in the title is not enough. The agency page should have meaningfully different constraints, examples, evaluation criteria, responsibilities, or actions. Otherwise, you have created a near-duplicate with a new label.

    When both pages will remain live, design their relationship before publishing:

    • Assign one primary question and one intended outcome to each page.
    • Give each page a distinct title, opening answer, heading plan, and internal anchor language.
    • Link between the pages with explanatory context, such as moving from a definition to an implementation process, rather than using the same generic anchor everywhere.
    • Keep each page’s canonical treatment consistent with its intended indexing role. Do not point one page at another as canonical while also expecting both to function as independent search results.
    • Avoid copying a large shared introduction into both pages. State only the background each reader needs, then move into the page-specific answer.
    • Update relevant hub pages, breadcrumbs, navigation, and XML sitemap handling so the new page has a clear place in the site architecture.

    If the new page replaces the old answer rather than complementing it, decide whether any meaningful reason remains to visit the old URL. When the old page has no independent purpose, consolidate useful material into the replacement and route the old URL appropriately. When the old question still matters, retain it and narrow its content so the boundary between the two pages is obvious.

    Define measurement before launch. The old and new pages should have separate expected query themes and reader outcomes. Track whether each URL begins attracting the intended demand, whether internal and external references point to the appropriate page, and whether conversions or downstream actions match the page’s role. If you monitor AI answers, use a stable prompt set and record the model, context, and observation date so comparisons are at least directionally consistent.

    When the pages begin appearing for the same queries, do not assume consolidation is immediately necessary. First inspect whether the queries are genuinely identical in intent. Tighten titles, openings, headings, and internal links if the distinction exists but is poorly communicated. Merge only when you cannot maintain a useful boundary or when one page adds no independent value. If you do consolidate, preserve the strongest answer, update links, and redirect deliberately rather than simply deleting the weaker URL.

    Key takeaways

    • Refresh an existing page when the same audience still asks the same primary question and needs the same kind of outcome.
    • Create a new page when intent, audience needs, central entity, version, or decision stage changes enough to require an independent answer.
    • Treat page age and traffic decline as audit triggers, not automatic reasons to rewrite or replace a URL.
    • Audit the query, answer, audience, entities, claims, structure, links, and structured data before choosing an editorial action.
    • When refreshing, preserve the page’s promise while replacing obsolete claims, strengthening evidence, and aligning JSON-LD with visible content.
    • When creating a page, define its boundary, relationship to existing URLs, indexing role, and success measures before publication.

    Start with one page that is due for review. Write its current question and proposed question side by side. If the reader and outcome remain continuous, refresh it with a recorded baseline. If the outcome changes, write the new page’s distinct job before creating the URL. That small decision document will prevent most accidental duplication and unfocused rewrites.

    References