Author: shivamcrushpressai

  • Political Campaign AI Spending: Where the 2026 Money Goes

    Political Campaign AI Spending: Where the 2026 Money Goes

    If you are building, buying, or measuring AI for a 2026 political campaign, the biggest budgeting mistake is treating AI as a single technology line. The headline total combines tools, AI-assisted work, automated outreach, and the media used to distribute AI-influenced advertising. A campaign can therefore spend little on software while creating a large AI-related footprint.

    You need to separate cost, operational use, and public exposure before deciding whether your campaign is underinvesting, overspending, or simply counting differently. That distinction turns an eye-catching market estimate into a budget you can actually manage.

    The $899 million headline is not a software market size

    Political campaigns, party committees, and outside groups are projected to spend $899 million on AI during the 2026 cycle. That would be 2.8 times the 2024 total and about 22 times the 2022 total. It is also equivalent to roughly 8.5% of the projected $10.6 billion in overall political advertising for the cycle.

    But $899 million does not mean campaigns are buying $899 million of AI software. The estimate includes three materially different forms of spending:

    • Direct payments for AI vendors, platforms, and general-purpose subscriptions.
    • The portion of production, targeting, fundraising, and outreach costs attributed to AI.
    • Media dollars placed behind advertisements generated or enhanced with AI.

    Those categories answer different questions. Direct vendor spending helps you assess the technology market. AI-attributable workflow spending tells you how deeply campaigns are using the technology. Media placement measures how much paid distribution sits behind AI-influenced assets. Combining them is useful for estimating AI’s overall campaign footprint, but it cannot tell you what AI products earned or how much a campaign saved.

    The total is also a projection, not a final audited tally. Its methodology covers more than 41,000 federal and state disbursement records, platform advertising libraries, and 57 consultant and vendor interviews, with activity tracked through September 24 and modeled through Election Day on November 3. Treat it as a structured market estimate. Do not use it as proof that every campaign classifies AI spending the same way.

    Before comparing your own budget with the market, decide which question you are asking. If you want to know what your technology stack costs, exclude media. If you want to understand operational adoption, include the AI-assisted share of labor and services. If you are assessing voter exposure, include distribution but keep it separate from production. One blended figure cannot answer all three questions.

    Distribution and outreach absorb more money than AI tools
    A small AI workstation connects through branching light trails to many phones, screens, mail pieces, and canvassing devices.

    The projected category mix shows where AI is entering campaign operations. Media placement behind AI-generated or AI-enhanced advertising is the largest category. General-purpose subscriptions are the smallest. That gap matters: the visible scale of political AI is being driven more by amplification and workflow adoption than by the price of access to a model.

    Spending categoryProjected 2026 spendingShare of totalGrowth versus 2024Question your budget should answer
    Media placement behind AI-generated or AI-enhanced ads$237 million26.4%3.3xCan you connect each placement to a specific asset, audience, and outcome?
    AI voter outreach$173 million19.2%3.0xWhen does an automated interaction move to a trained person?
    AI fundraising optimization$147 million16.4%2.4xAre you measuring net fundraising performance rather than message volume?
    AI audience modeling and targeting$131 million14.6%1.8xDoes the model improve decisions against a defined non-AI baseline?
    AI creative production$98 million10.9%4.7xWho verifies facts, voices, likenesses, and required disclosures before release?
    AI-assisted media buying fees$65 million7.2%2.8xCan you separate the service or algorithmic fee from the underlying media spend?
    General-purpose AI tools and subscriptions$48 million5.3%4.0xWho controls accounts, data access, retention, and offboarding?

    Creative production is growing fastest at 4.7 times its 2024 level, but it still accounts for only 10.9% of projected 2026 AI spending. Audience modeling is growing slowest at 1.8 times because it already had a meaningful base before the recent expansion of generative tools. Fast growth, large spending, and operational maturity are therefore three different signals.

    Do not judge an AI program by the number of assets it produces. A campaign can generate hundreds of variants without improving persuasion, fundraising, or contact quality. Measure the result associated with each workflow: approved production time for creative, net revenue for fundraising, successful contacts and escalations for outreach, incremental performance for targeting, and cost per desired action for media. Keep output volume as a diagnostic metric, not the primary success metric.

    Adoption also cuts across party lines. Republican candidates, parties, and aligned outside groups account for a projected $415 million, compared with $374 million on the Democratic side. Outside groups allocate a larger portion of their budgets to AI than candidates and parties, with Republican-aligned groups reaching 10.2%. Party affiliation is a poor proxy for AI maturity; spender type and workflow are more useful.

    Race size, geography, and timing change the right strategy

    Absolute spending concentrates in federal contests. House races account for a projected $305 million and Senate races for $286 million, together representing 65.7% of campaign AI spending. Yet smaller races use AI more intensively relative to their available media.

    Local and judicial races have AI-generated or AI-enhanced elements in 16.2% of ads, and AI represents 13.8% of their media budgets. State legislative races follow at 14.7% of ads and 12.4% of media budgets. House races are lower on both measures, at 9.2% and 8.9%, despite carrying the largest dollar total. Ballot measures sit at the other end, with AI elements in 6.3% of ads and 5.2% of media budgets.

    This is a denominator problem that can distort competitive analysis. A small campaign may look more AI-intensive because automation replaces work it could not otherwise afford. A large federal campaign can spend far more dollars while AI remains a smaller percentage of a much larger operation. Compare campaigns on both absolute spending and share of budget. Using only one will misclassify the smaller operation or obscure the larger one’s reach.

    Geography produces another concentration effect. The ten highest-spending states account for $460.1 million, or 51.2% of the projected total. Maine reaches $25.09 per registered voter, almost three times the next-highest figure in that group, as a competitive Senate race concentrates spending across a relatively small electorate. A national average will not tell you what competitive pressure looks like in an individual state.

    Disclosure practices vary just as sharply. Among the ten highest-spending states, the recorded share of AI ads carrying a disclosure ranges from 29% in Georgia to 78% in California. Across states with AI disclosure laws, 64% of AI ads carried a disclosure, versus 27% in states without one. That relationship indicates that legal requirements affect behavior, but it is not a substitute for a state-by-state compliance review.

    Build a jurisdiction field into the asset record before production begins. Record where the asset will run, what was generated or materially altered, which disclosure decision was made, who approved it, and which final version entered distribution. When the applicable rule is unclear, hold the asset and ask qualified election counsel. Retrofitting a disclosure after placement creates avoidable legal, financial, and reputational exposure.

    Timing is equally important. At the aligned one-month point, cumulative 2026 AI spending reaches $612 million, with a projected $899 million by Election Day. Spending within each cycle has roughly doubled every three months as Election Day approaches. The final month is projected to contain 32% of 2026 spending, below the 37% final-month share in 2024 because outreach and fundraising automation moved earlier to reach early voters.

    Do not postpone governance until the spending ramp. The final weeks are when review time contracts, asset volume rises, and media decisions become harder to reverse. Approve vendors, data permissions, escalation paths, disclosure rules, and evidence requirements before the high-volume period. The late-cycle budget should scale a controlled workflow, not finance the first real test of one.

    Build an AI budget that can survive scrutiny
    Transparent budget containers, coins, a magnifying glass, a locked data box, and a balance scale are arranged on an orderly campaign planning desk.

    A defensible AI budget starts with a ledger, not a list of tools. The cost of an AI program can include software, implementation, data work, human review, compliance, vendor services, and media. If you record only subscription invoices, you will understate the program. If you label every placement behind an AI-assisted asset as technology spend, you will lose sight of what the technology itself costs.

    1. Choose the unit of analysis. State whether you are tracking direct vendor cost, AI-enabled workflow cost, or media exposure. Maintain all three if leadership needs a complete view, but never merge them without labels.
    2. Classify spending at the invoice or line-item level. Assign every item to creative production, outreach, fundraising, targeting, media-buying services, general tools, or media placement. Prevent one invoice from disappearing into a broad digital-services account.
    3. Attach each cost to an accountable workflow. Record the race, jurisdiction, vendor, campaign owner, data used, synthetic or altered elements, human reviewer, approval status, and distribution channel.
    4. Set the baseline before the pilot. Compare the AI-enabled workflow with the existing process on the outcome that matters. Time saved is meaningful for production; it is not evidence of better persuasion. Message volume is meaningful for operations; it is not evidence of better fundraising.
    5. Create a release gate. Require factual verification, permission checks for voice and likeness, disclosure review, accessibility review where relevant, security review, and named human approval before an asset or automated interaction goes live.
    6. Scale only the validated component. If a creative workflow saves time but targeting does not improve performance, scale production rather than buying a larger bundled program. A vendor relationship does not have to expand as one indivisible unit.

    Your ledger should let a reviewer move in both directions: from an invoice to the assets and outcomes it funded, and from a public asset back to its production record, approval, disclosure decision, and media spend. That traceability is more useful than a generic AI policy because it shows how the policy operated in a specific case.

    If you publish or optimize political content

    More campaign investment means more creative variants, automated contacts, and paid distribution. It does not create independent corroboration. Treat campaign-generated material as a claim that requires verification, even when the asset looks polished or appears repeatedly across channels.

    • Put the publication or revision date, jurisdiction, race, candidate or issue, and sponsor context where a reader can see them.
    • Separate campaign assertions from independently verified facts, and link to the strongest available primary evidence for factual claims.
    • Keep the original approved asset and a correction history so changes do not erase provenance.
    • Use structured data only for information visible on the page. Markup can clarify entities and dates, but it cannot turn an unsupported claim into reliable evidence.
    • Do not present repeated synthetic content as multiple independent confirmations. Distribution volume and source diversity are not the same thing.

    These practices help human readers, search systems, and AI answer engines distinguish what happened, who is making a claim, when it applies, and which evidence supports it. They do not guarantee visibility or favorable treatment, but they reduce ambiguity at the point where political information is most likely to be compressed into a short answer.

    Key takeaways

    • The projected $899 million total measures a broad AI-related campaign footprint, not just software purchases or vendor revenue.
    • Media placement is the largest category at $237 million, while general-purpose tools and subscriptions account for $48 million.
    • Creative production is growing fastest, but output volume alone does not establish campaign impact.
    • Federal races lead in total dollars, while local, judicial, and state legislative races use AI more intensively relative to their media.
    • Disclosure practices differ substantially by state, so every asset needs a jurisdiction-specific review and an auditable approval record.
    • Budgeting should separate direct technology cost, AI-enabled workflow cost, and paid exposure, then connect each to a defined outcome.

    Start by exporting every AI-related expense and reclassifying it into technology, workflow, or distribution. Then choose one high-exposure workflow, give it a measurable baseline and a named approval owner, and resolve its disclosure path before shifting more money into it. That is how you turn a market trend into a campaign decision you can explain, test, and defend.

    References


  • AI Search Visibility Monitoring: A Practical Framework

    AI Search Visibility Monitoring: A Practical Framework

    If your AI visibility report moves from one run to the next, you need to know whether your brand’s position changed or the sample did. A chart that cannot answer that question is noise, however polished it looks.

    You can make the signal more trustworthy. Build the monitor around fixed prompts, captured answers, explicit scoring rules, and decisions someone is responsible for making. The goal is not merely to count mentions. It is to understand where your brand appears, how it is represented, what evidence supports the answer, and what you should change next.

    Decide what the monitor is supposed to change

    Start with the decision, not the dashboard. AI search visibility can refer to several different problems, and each requires a different measurement:

    • Discoverability: Does your brand appear when someone asks about a category, problem, or use case without naming you?
    • Competitive presence: Does the answer include you alongside the alternatives a buyer is likely to consider?
    • Recommendation: Does the system merely mention you, or does it actually present you as a suitable choice?
    • Accuracy: Are the facts about your products, services, locations, people, policies, or capabilities correct?
    • Reputation: Is the description favorable, unfavorable, neutral, or mixed, and what language caused that classification?
    • Evidence: Which pages, domains, or citations appear to support the answer?

    Do not collapse those questions into one visibility score. A brand can be mentioned frequently and described inaccurately. It can receive positive language in branded prompts while remaining absent from unbranded category discovery. It can also appear in a recommendation without receiving a citation. Those are different conditions with different remedies.

    Write a measurement brief before collecting data. Name the audience, market, language, products, competitors, prompt families, platforms, and business decisions in scope. A program may examine how ChatGPT, Gemini, Perplexity, and Claude describe a brand, but results from those systems should remain separate as well as aggregated. A gain on one platform can otherwise hide a loss on another.

    Define the unit of observation as one exact prompt run under one recorded condition. For every run, preserve the platform, model or mode when visible, market, language, date, prompt text, session state, answer text, cited URLs, and scoring result. If account status, retrieval settings, or personalization are known, record those too. Without that audit trail, you cannot tell whether a movement came from your content, a platform change, a different prompt, or conversational context.

    Most importantly, do not present monitored prompts as a census of everything users see. They are a controlled panel. Their value comes from consistency and diagnostic depth, not from pretending they reproduce the entire audience.

    Build a prompt set without moving the goalposts

    Blank prompt cards are arranged in a fixed modular grid while a mechanical arm selects one card.

    Your prompt set determines what your visibility score can mean. A weak set overrepresents easy branded questions, changes whenever a stakeholder has a new idea, and mixes markets or intents that should be evaluated separately.

    Begin with the real language of the market. Useful inputs include search-query data, internal site search, sales questions, support tickets, product comparisons, customer interviews, and community discussions. Convert those inputs into natural questions a person might ask an assistant. Avoid adding your brand name to an unbranded discovery prompt, praising the brand inside the question, or supplying facts that make the desired answer obvious.

    Prompt familyExampleWhat it reveals
    Category discoveryWhat tools help a small marketing team monitor how AI assistants describe its brand?Whether the brand is associated with the relevant category before it is named.
    Problem and use caseHow can I find inaccurate claims about my company in AI-generated answers?Whether the brand is connected to a specific need or job.
    ComparisonWhat should I compare when choosing an AI visibility monitoring platform?Which evaluation criteria and competing options enter the answer.
    RecommendationWhich options fit a team that needs citation and sentiment monitoring?Whether the system recommends the brand under stated constraints.
    Branded accuracyWhat does [brand] offer, and who is it for?Whether the assistant recognizes the entity and represents its core facts correctly.

    Keep two prompt panels. The locked panel changes rarely and supplies the trend line. The exploratory panel can absorb new products, questions, competitors, and market language. When an exploratory prompt becomes strategically important, add it to the next version of the locked panel and mark the break. Do not insert it into historical totals as if it had always been present.

    Tag every prompt by intent, journey stage, product, audience, market, and whether it is branded or unbranded. These labels let you find a meaningful pattern. A flat overall result might conceal rising visibility for informational questions and falling visibility for purchase-oriented recommendations.

    Use fresh sessions for independent tests. Conversational history can alter later answers, so a follow-up question belongs to a different test design. If multi-turn discovery matters to your audience, monitor it as a named journey with a fixed sequence rather than mixing it with standalone prompts.

    Outputs can vary even when the visible prompt does not. Repeat matched conditions before treating a single answer as a trend. First establish the normal variation of each prompt family; then judge future movement against that baseline. This prevents one favorable or unfavorable response from becoming a strategy.

    Score the answer, not just the brand mention

    An analyst examines a layered answer panel, source tiles, and several unlabeled evaluation gauges on an inspection table.

    A mention counter answers only one question: whether a brand string appeared. Your scoring model should preserve enough detail to explain what that appearance meant.

    • Presence: Record whether the brand or an approved variant appears. Keep aliases in an entity dictionary so spelling and product-name differences do not create false absences.
    • Prominence: Record whether the brand is central to the answer, included in a list, mentioned only as an aside, or introduced through a citation without appearing in the prose.
    • Recommendation status: Separate explicit recommendation, conditional recommendation, neutral inclusion, and explicit exclusion. Save the sentence that justifies the label.
    • Accuracy: Compare concrete claims with a maintained set of approved facts. Label each reviewed claim as supported, incorrect, outdated, conflicting, or unverifiable. Unverifiable is not the same as false.
    • Sentiment: Use positive, neutral, negative, or mixed only when you also capture the language behind the label. Sentiment without evidence is difficult to audit and easy to misread.
    • Citations: Save the full URL, domain, page type, and whether it belongs to your organization, an independent publisher, or a competitor. A citation is evidence of selection, not automatic evidence of endorsement or factual correctness.
    • Competitive context: Record every monitored competitor that appears and the role each one receives. A simple name count misses the difference between being recommended and being used as a cautionary comparison.

    Define share of voice before putting it on a dashboard. One defensible answer-level definition is the share of monitored answers naming your brand among answers that name at least one monitored brand. Another is mention-level share across all monitored-brand mentions. Those denominators answer different questions and can produce different results. Publish the formula next to the metric and keep it unchanged across reporting periods.

    Keep branded and unbranded visibility separate. Branded prompts test entity recognition and factual representation. Unbranded prompts test whether the brand is retrieved for a category, problem, audience, or constraint. Combining them usually inflates the headline while hiding the harder discovery problem.

    Treat sentiment as a review aid, not a verdict. An answer can praise ease of use while questioning fit for a particular customer. Calling that response simply positive discards the part that could change a buying decision. Preserve mixed classifications and attach the decisive excerpt so a reviewer can see what happened.

    Be equally precise with citations. Measure citation presence, domain diversity, ownership, page freshness where known, and the claims each citation appears to support. If an answer names your brand but cites only a competitor or an unrelated page, that is not the same outcome as a direct citation to a current, relevant page.

    A composite score can be useful for orientation, but it should never replace the underlying measures. If you create one, document its components and weights, show the raw metrics beside it, and version the formula whenever it changes. Otherwise, an apparently stable score may be concealing offsetting gains and losses.

    Turn visibility changes into specific work

    A useful monitor ends in a queue of testable actions. When a metric moves, investigate in the same order each time:

    1. Validate the observation by rerunning the same prompt under matched conditions. Preserve both the confirming and conflicting outputs.
    2. Locate the scope. Check whether the change belongs to one platform, prompt family, market, language, product, or competitor set.
    3. Compare the answer text and citations with the earlier baseline. Identify the claim, recommendation, omission, or source selection that actually changed.
    4. Classify the likely problem as discoverability, entity ambiguity, factual inconsistency, weak evidence, reputation, technical access, or normal output variation.
    5. Assign an intervention that matches that diagnosis. Record the owner, affected pages or entities, expected signal, and implementation date.
    6. Continue the locked measurement panel after the intervention. Do not replace difficult prompts or add favorable prompts to make the result look improved.
    Observed patternLikely interpretationUseful next action
    The brand is accurate in branded answers but absent from unbranded discovery.The entity may be recognized without a strong association to the category or use case.Strengthen pages that explicitly connect the brand, offering, audience, problem, and differentiating evidence. Review whether those relationships are clear in page copy, internal links, and relevant structured data.
    The brand is visible, but descriptions conflict across prompts.Canonical facts may be unclear, inconsistent, or scattered.Create an approved fact set, reconcile conflicting pages, and make names, descriptions, relationships, and current capabilities consistent across owned properties.
    A competitor appears repeatedly for one constraint or audience.The competitor may have a clearer evidence trail for that particular fit.Inspect the supporting pages and claims. Publish direct, substantiated material for the same decision criterion if your offering genuinely meets it.
    Citations lead to outdated or irrelevant pages.Old URLs or weak canonical paths may still be prominent in the available evidence.Update the strongest relevant page and consolidate duplicate information. Before removing an old URL, map its links and use an appropriate redirect so you do not discard useful signals or strand visitors.
    Sentiment changes while mention presence stays stable.The visibility problem is not reach; it is representation.Review the exact negative or conditional claims. Correct factual ambiguity in owned content, and route legitimate product or reputation issues to the team that can address the underlying cause.
    Only one platform changes on an isolated run.The movement may be platform-specific or ordinary answer variation.Repeat the matched test and inspect that platform’s answers before changing site-wide strategy.

    Your reporting view should preserve this diagnostic path. Show platform and prompt-cluster coverage, branded and unbranded presence, recommendation status, the declared share-of-voice formula, citation patterns, accuracy issues, and sentiment evidence. Add a change log underneath. Readers should be able to move from a chart to the affected prompts, full answers, citations, and interventions without asking how the number was produced.

    Also separate observation from attribution. If visibility rises after you revise a page, the timing makes the revision a plausible contributor; it does not prove that the page caused the change. Look for repetition across relevant prompts, supporting citation changes, and stability beyond a single run before making a causal claim.

    Key takeaways

    • Use a locked prompt panel for trends and a separately versioned exploratory panel for discovery.
    • Store the exact prompt, answer, citations, platform conditions, and scoring evidence for every observation.
    • Keep presence, recommendation, accuracy, sentiment, citations, and competitive position as distinct measures.
    • Separate branded recognition from unbranded discovery, and report results by intent and prompt cluster.
    • Define every denominator, especially share of voice, and display raw measures beside any composite score.
    • Validate changes under matched conditions before assigning site-wide work or claiming an intervention caused the result.

    Start with one commercially important use case and a prompt set small enough for your team to review answer by answer. Lock the baseline, document the scoring rules, and connect every alert to a named decision. Once that loop works, expand the coverage without weakening the audit trail.

    References

  • AI Search and Shopping Agent Visibility: A Practical System

    AI Search and Shopping Agent Visibility: A Practical System

    Your product appears in an AI answer on Monday, disappears on Tuesday, and returns through a different citation on Friday. That does not automatically mean your optimization worked, failed, and recovered. It means you are looking at a system that assembles answers dynamically rather than assigning one durable position.

    You need a visibility program built for that volatility. The goal is to increase the probability that your brand is found, understood, supported by credible evidence, and selected when an AI system moves from answering a question to helping someone choose a product.

    Replace the idea of one ranking with three layers of visibility

    A conventional ranking gives you a page, a query, and a position. An AI answer can vary its wording, cited URLs, recommended brands, and product shortlist from one run to the next. Treating one generated response as a ranking report will produce false alarms when you disappear and false confidence when you happen to appear.

    The volatility is large enough to affect how you interpret every test. When 10,000 keywords were run through Google AI Mode three times on the same day, the average URL overlap was only 9.2%. For 21.2% of the keywords, the three runs had no cited URLs in common. In another large test, Google AI Overview content changed in roughly 70% of checks, while only 54.5% of cited URLs overlapped between consecutive runs.

    Yet changing citations do not always mean that the underlying answer has changed. The semantic similarity of those AI Overviews remained at 0.95 even while their wording and evidence rotated. You can therefore lose a particular citation while the system continues to express the same category preference, recommendation criteria, or view of your brand.

    Measure three layers separately:

    • Answer visibility: Does the brand or product appear in the generated response, recommendation, shortlist, or comparison?
    • Evidence visibility: Which owned or third-party pages are cited, and what claims are those pages supporting?
    • Commerce readiness: Can a shopping agent determine what the product is, who it suits, which variant applies, and whether the commercial information is complete enough to support a decision?

    This distinction matters because the remedy depends on the layer. If your brand remains recommended but your URL stops being cited, you may have an evidence-distribution problem. If your pages are cited but your product never reaches the shortlist, your positioning or product fit may be unclear. If the product appears but the agent reports an incorrect price, variant, or use case, the problem is data consistency rather than general brand awareness.

    Shopping agents raise the stakes. Personal agents such as Muse and Instinct can find products, compare options, and make purchasing decisions for users. Your job is no longer finished when an AI system mentions the brand. The system must also be able to qualify the product against the buyer’s situation.

    Build a measurement system that survives volatile answers

    A stable monitoring hub tracks a shifting field of abstract answer panels and citation nodes connected by changing paths.

    Start with the questions that precede a real decision, not a collection of high-volume keywords. A useful prompt library represents the different jobs a buyer asks an assistant to perform:

    • Problem discovery: asking what kind of product solves a stated need.
    • Use-case qualification: looking for a product that fits a particular audience, environment, workflow, or constraint.
    • Comparison: weighing products or product types against explicit criteria.
    • Risk reduction: checking compatibility, limitations, policies, reliability, or suitability.
    • Purchase preparation: verifying variants, availability, price, delivery, returns, or another decision-critical fact.
    • Branded evaluation: asking whether your product is suitable and what alternatives should be considered.

    Write prompts in the buyer’s language and preserve the qualifiers that change the answer. “Best project-management software” and “project-management software for a small agency that needs client approvals” are not interchangeable questions. The second prompt gives the system criteria it can use to include or exclude a product.

    Run the same library on each AI platform you care about, but do not blend the results into one universal score. Google AI Overviews and AI Mode shared only 13.7% of their citations in one comparison. Platform-specific shifts can also be abrupt: Reddit’s average share of ChatGPT Search citations fell from 3.83% to 0.52% across the reported periods, an 86.4% decline, while the broader pattern was not uniform across AI systems.

    A blended average can hide exactly what you need to diagnose. Keep separate views for each platform, answer surface, market, and language you test. Aggregate them only after you have inspected the underlying results.

    Repetition is equally important. Published sampling guidance indicates that 60 to 100 runs of a prompt can produce meaningful visibility data. Another longitudinal approach recommends at least seven runs per prompt per day for brand-level estimates, assessed through rolling windows of two to four weeks. These are measurement benchmarks, not a claim that every team must immediately test at that scale. If your budget supports fewer observations, label the result as directional and avoid making budget or content decisions from a single response.

    Your dashboard should answer operational questions rather than merely count mentions:

    QuestionMetricWhat to recordLikely next action
    Are we present?Brand mention rateValid runs containing the brand divided by all valid runs for that prompt setInvestigate prompt clusters where competitors appear consistently and you do not
    Are products being considered?Product inclusion rateRuns in which an eligible product enters the shortlist or comparisonClarify audience fit, category language, and comparison attributes
    What supports the answer?Citation rate by domain and URLOwned and third-party pages cited for each claim or recommendationStrengthen missing evidence and pursue relevant independent coverage
    Is the answer accurate?Fact accuracy rateCorrect and incorrect statements about fit, specifications, terms, and availabilityResolve contradictions across pages, catalogs, feeds, and structured data
    Is the change persistent?Rolling visibility rangeRates and ranges over repeated runs, separated by platformAct on sustained movement rather than an isolated response

    Keep a changelog beside the data. Record platform and model updates, material website changes, catalog releases, content refreshes, and significant third-party coverage. The log will not prove causation, but it prevents the team from inventing an explanation after every rise or fall.

    Use a simple decision rule: one unusual answer is an observation; a repeated change within the same platform and prompt cluster is a pattern worth diagnosing. If the decline appears everywhere at once, inspect broad accessibility, brand evidence, and product-data issues. If it appears only for comparison prompts, look first at the criteria buyers use to distinguish products.

    Make every product answerable before expecting it to be selectable

    A generic product moves from organized attributes and evidence nodes through a transparent reasoning structure into a highlighted selection tray.

    A shopping agent cannot infer a reliable recommendation from a product name and a persuasive description alone. Early testing of personal agents points to three practical visibility requirements: usable product catalogs, accessible websites, and clear statements about who each product is for.

    Audit each commercially important product as a package of decision facts. The exact attributes will vary by category, but the agent should be able to resolve the following without reconciling conflicting pages:

    • Identity: a stable product name, canonical URL, model or SKU, brand, and an unambiguous relationship between the main product and its variants.
    • Audience fit: the user, situation, problem, or level of experience the product is designed for. State meaningful limitations when they affect suitability.
    • Comparison attributes: the specifications, capabilities, materials, dimensions, compatibility details, or service limits a buyer would use to compare alternatives in your category.
    • Commercial terms: current price and currency, availability, variant-level differences, applicable delivery information, returns, and warranty terms where relevant.
    • Evidence: explanations, documentation, or independent validation that supports important claims instead of merely repeating them.
    • Consistency: agreement among the visible product page, catalog or feed, structured data, policy pages, and any regional or variant pages.

    “Who it is for” deserves its own content block. Avoid empty labels such as “for everyone” or “perfect for professionals.” Give the agent usable selection criteria: the problem solved, the expected environment, required compatibility, relevant experience level, and conditions that would make another option more suitable. Clear exclusions can improve recommendation quality because they reduce the chance that your product is matched to the wrong request.

    Use Product and Offer structured data as a consistency layer, not as a magic entry ticket. Markup should express facts that a visitor can also verify on the page. If the visible page says one price, the catalog says another, and the structured data carries an expired offer, adding more schema will multiply ambiguity rather than remove it.

    Variant handling needs particular care. A parent product page may describe the range, but decision-critical facts should remain attributable to the correct size, configuration, color, region, or service tier. An agent comparing two variants should not have to guess which price or specification belongs to which option.

    Test accessibility from the agent’s point of view. Open the page in a clean session. Confirm that the product identity, fit, principal attributes, and commercial terms are available without signing in, accepting an unnecessary location flow, opening an image, or relying on an interaction that hides the only copy of a critical fact. Then compare the rendered page with the catalog and structured data field by field.

    Finally, test a decision sequence rather than one branded prompt. Ask an assistant to identify products for a constrained use case, compare the candidates, explain which user each candidate suits, and verify the facts needed for a decision. Record where your product disappears and which unresolved criterion caused the exclusion. That point is a more useful optimization target than the wording of the final answer.

    Publish and earn evidence that AI systems can resample

    Once a product is technically legible, it still needs current evidence. AI-cited URLs were 25.7% fresher on average than conventional organic results in one large comparison: cited pages averaged 1,064 days old, versus 1,432 days for organic results. This does not mean that changing a date will improve visibility. It means the information environment being sampled by AI systems tends to include fresher material.

    Refresh a page only when you can make it more useful. Add new product facts, answer newly important buyer questions, update obsolete comparisons, correct policy details, incorporate original data, or explain a material change. Keep the URL stable when the underlying resource remains the same, show a meaningful update date, and remove contradictions left by earlier versions.

    Owned content is necessary but insufficient. In one citation analysis, owned media accounted for 13.7% of AI citations while earned media accounted for 84%. Journalism represented 27%, and paid content represented only 0.3%. These labels should not be treated as a simple exclusive pie chart, but the practical signal is clear: visibility often depends on credible pages you do not control.

    Build an evidence map around the claims that determine selection. For each important prompt cluster, list the claims an assistant would need to justify: category membership, audience fit, distinctive capability, compatibility, comparative strength, limitation, and commercial availability. Then mark where each claim is supported:

    • on a canonical owned page;
    • in your product catalog and structured data;
    • in independent reporting, reviews, comparisons, or other third-party material;
    • nowhere reliable enough to support a recommendation.

    The empty cells are your publishing and public-relations brief. Create original material where you control the underlying evidence. Seek independent coverage where an outside assessment would carry more value. Do not treat a press release as a durable substitute for either one; press-release citation share proved unstable and declined over the reported period, largely because ChatGPT cited releases less often.

    Prioritize third-party coverage that contributes information of its own. A useful comparison, test, interview, dataset, or category explanation gives an AI system a reason to retrieve the page beyond the presence of your brand name. Repetition across low-value placements may expand the number of mentions without supplying better evidence for a recommendation.

    Connect publishing back to measurement. When a prompt cluster lacks visibility, identify whether the missing input is product data, owned explanation, or independent evidence. Make the smallest substantive change that addresses that gap, record it in the changelog, and assess it across repeated runs. That gives you a testable operating cycle instead of a stream of unrelated content.

    Key takeaways for your next visibility cycle

    • Treat an AI response as one sample, not a permanent ranking. Report visibility as a rate and range across repeated runs.
    • Separate brand inclusion, cited evidence, and commerce readiness. Each layer has a different failure mode and remedy.
    • Build prompts around discovery, qualification, comparison, risk reduction, and purchase preparation rather than isolated keywords.
    • Measure each AI platform separately. A blended score can conceal a platform-specific gain, loss, or citation shift.
    • Make product identity, audience fit, comparison attributes, variants, and commercial terms explicit and consistent across the page, catalog, feed, and structured data.
    • Refresh important pages with substantive information, not a changed date, and cultivate independent evidence for claims that influence selection.

    Begin with one commercially important product family and the prompts closest to a decision. Establish a repeated baseline, inspect where the product falls out of the journey, and fix that exact gap. Once the page, catalog, schema, and outside evidence tell the same clear story, extend the system to the next product family.

    References


  • Ecommerce Category Internal Linking: A Practical System

    Ecommerce Category Internal Linking: A Practical System

    Your ecommerce site has more category pages than your navigation can reasonably promote. Merchandising wants one collection featured, SEO sees demand for another, and yesterday’s bestseller still holds most of the site’s internal links. Adding links everywhere won’t resolve that conflict.

    You need a repeatable way to decide which categories deserve support, identify where the current architecture sends the wrong signal, and place links that are useful to shoppers. The goal isn’t an equal distribution. It is an intentional one.

    Make each category earn additional internal links

    Start with the category’s value, not its current link count. A URL does not become important merely because your platform created it, an audit flagged it, or a team wants to rank it. Before you promote a category, confirm that it represents a durable opportunity for both the business and the shopper.

    Evaluate each candidate against these criteria:

    • Business importance: The category supports a defined commercial priority, such as profitable growth, a strategic product line, or a sustained merchandising commitment.
    • Search opportunity: People look for the category as a distinct concept. Its intent is meaningfully different from the parent category and nearby alternatives.
    • Inventory strength: The page offers enough relevant products to satisfy the visit, and stock is likely to remain available. A prominent link to a thin or frequently empty collection sends shoppers into a dead end.
    • Durability: The category will matter beyond a brief promotion. A recurring seasonal category can qualify, but a disposable campaign URL usually should not receive permanent architectural prominence.
    • Landing-page usefulness: The page helps someone understand the selection and continue shopping. Links cannot compensate for an unclear category, irrelevant products, or an experience dominated by unavailable inventory.

    A practical approval record can be short. For every proposed target, write down the target URL, its business purpose, the demand it serves, the inventory owner, and whether it is permanent, recurring, or temporary. That forces the team to distinguish a real category opportunity from a request for more SEO attention.

    Be especially selective with filters. Color, size, brand, material, price, and other facets can produce a large population of URL combinations. Opening internal paths to all of them can slow the discovery of more useful content. Promote a filtered landing page only when it has distinct demand, dependable inventory, a stable purpose, and enough structural support to function as a genuine category.

    If a URL fails those tests, more internal links are not the remedy. Improve or consolidate the page, keep the filter available for shoppers without broadly promoting its URL, or direct attention to the stronger parent category.

    Audit the gap between business priority and site architecture

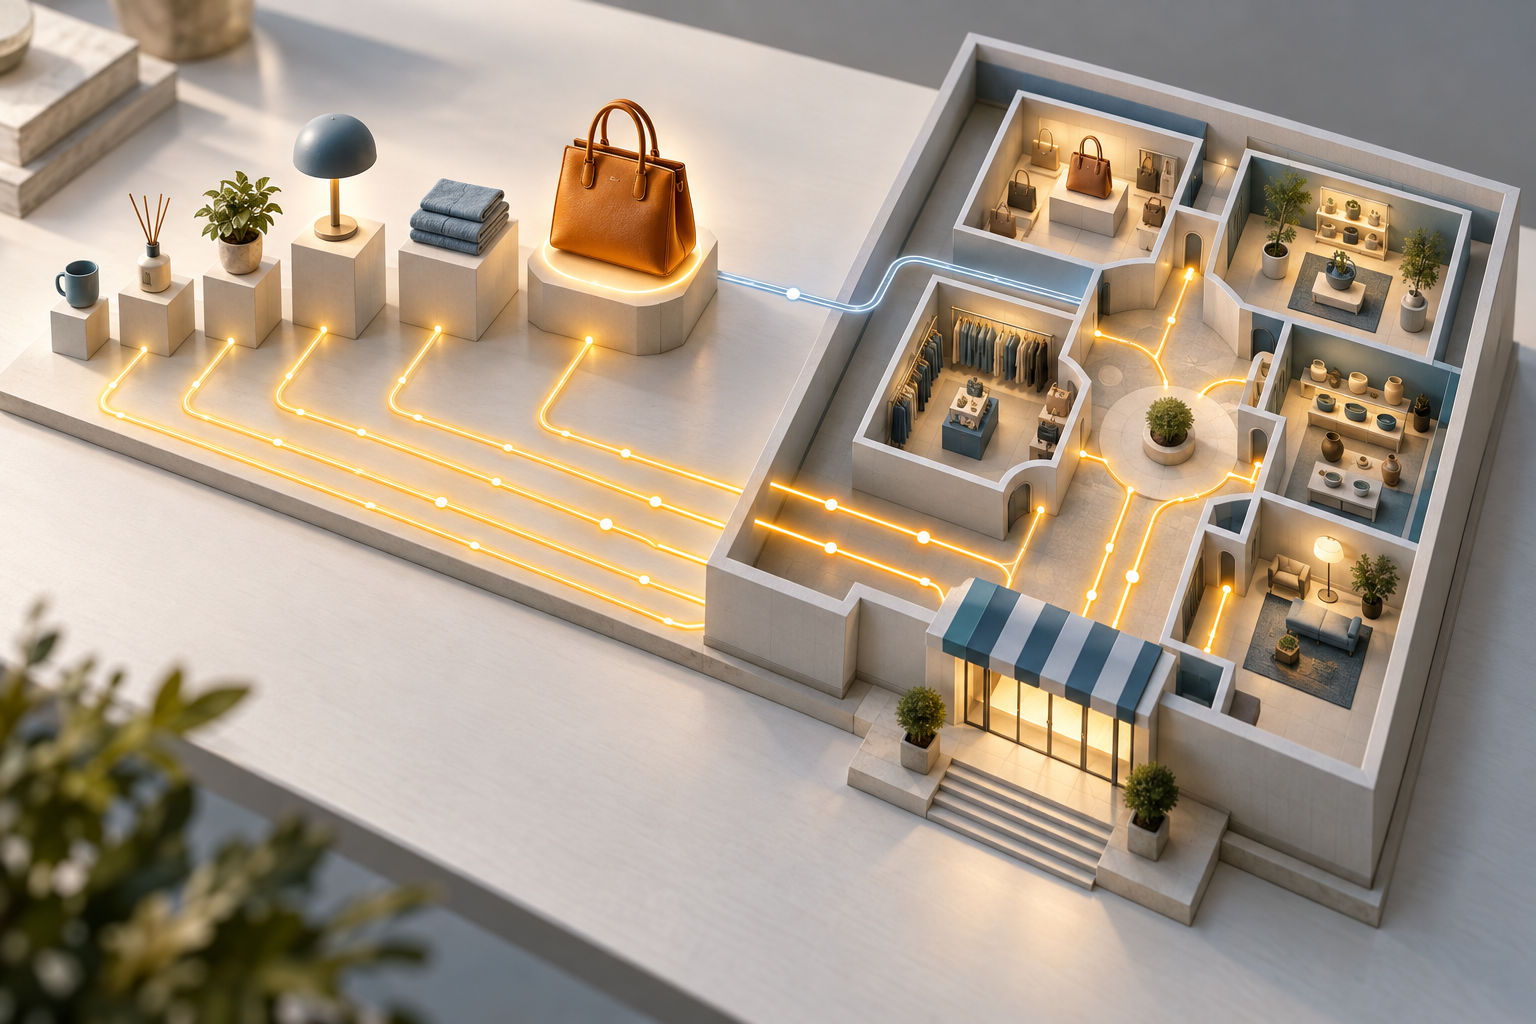
    Tabletop model contrasting prominently displayed product collections with uneven pathways through a digital storefront structure.

    Once you have a qualified set of categories, compare what the business considers important with what the site currently presents as important. This is the central diagnostic step.

    Google can infer a page’s relative importance from internal-link relationships, including how many internal links lead to the page and how many links a crawler must follow to reach it. Shoppers receive a similar message: categories exposed in navigation and related content look central, while deeply buried categories look peripheral.

    Run the audit in this order:

    1. Set the commercial priority first. Label each approved category as a current priority, a category to maintain, or a low-priority page. Do this before reviewing SEO metrics so existing visibility does not quietly become your definition of importance.
    2. Crawl from the shopper-facing site. Record the shortest click path from the homepage, the number of crawlable internal links pointing to each category, and the templates or pages supplying those links.
    3. Separate structural links from incidental links. A persistent navigation link, a parent-category path, an editorial recommendation, and an old campaign link do not play the same role. Label the source and placement instead of treating every link as interchangeable.
    4. Check relevance. Inspect whether the linking pages share a real product, audience, or shopping relationship with the target. A large count of unrelated links can conceal a weak architecture.
    5. Find mismatches. Prioritize categories with high commercial importance but weak site support. Also flag low-priority categories that still occupy prominent navigation or receive extensive legacy links.

    Use relative comparisons within your own catalog. A universal target for click depth or link count would ignore differences in store size, navigation design, and taxonomy. Compare equivalent category types, then look for outliers.

    Business priorityCurrent site supportWhat it meansRecommended action
    HighLowThe architecture understates a qualified opportunity.Find relevant, prominent pages that can supply links.
    HighHighThe site already reflects the priority.Maintain the paths; investigate other constraints before adding more links.
    LowHighLegacy architecture may be spending attention on an outdated priority.Review navigation and inherited modules before promoting new targets.
    LowLowThe architecture and current business priority are aligned.Leave it alone unless its role changes.

    This matrix prevents a common mistake: assuming that every important category needs more links. If a category is already easy to reach, prominently represented, and supported by relevant pages, its problem may be weak inventory, poor intent alignment, or an unhelpful landing page. Another batch of links would obscure that diagnosis.

    Place links where they help someone continue shopping

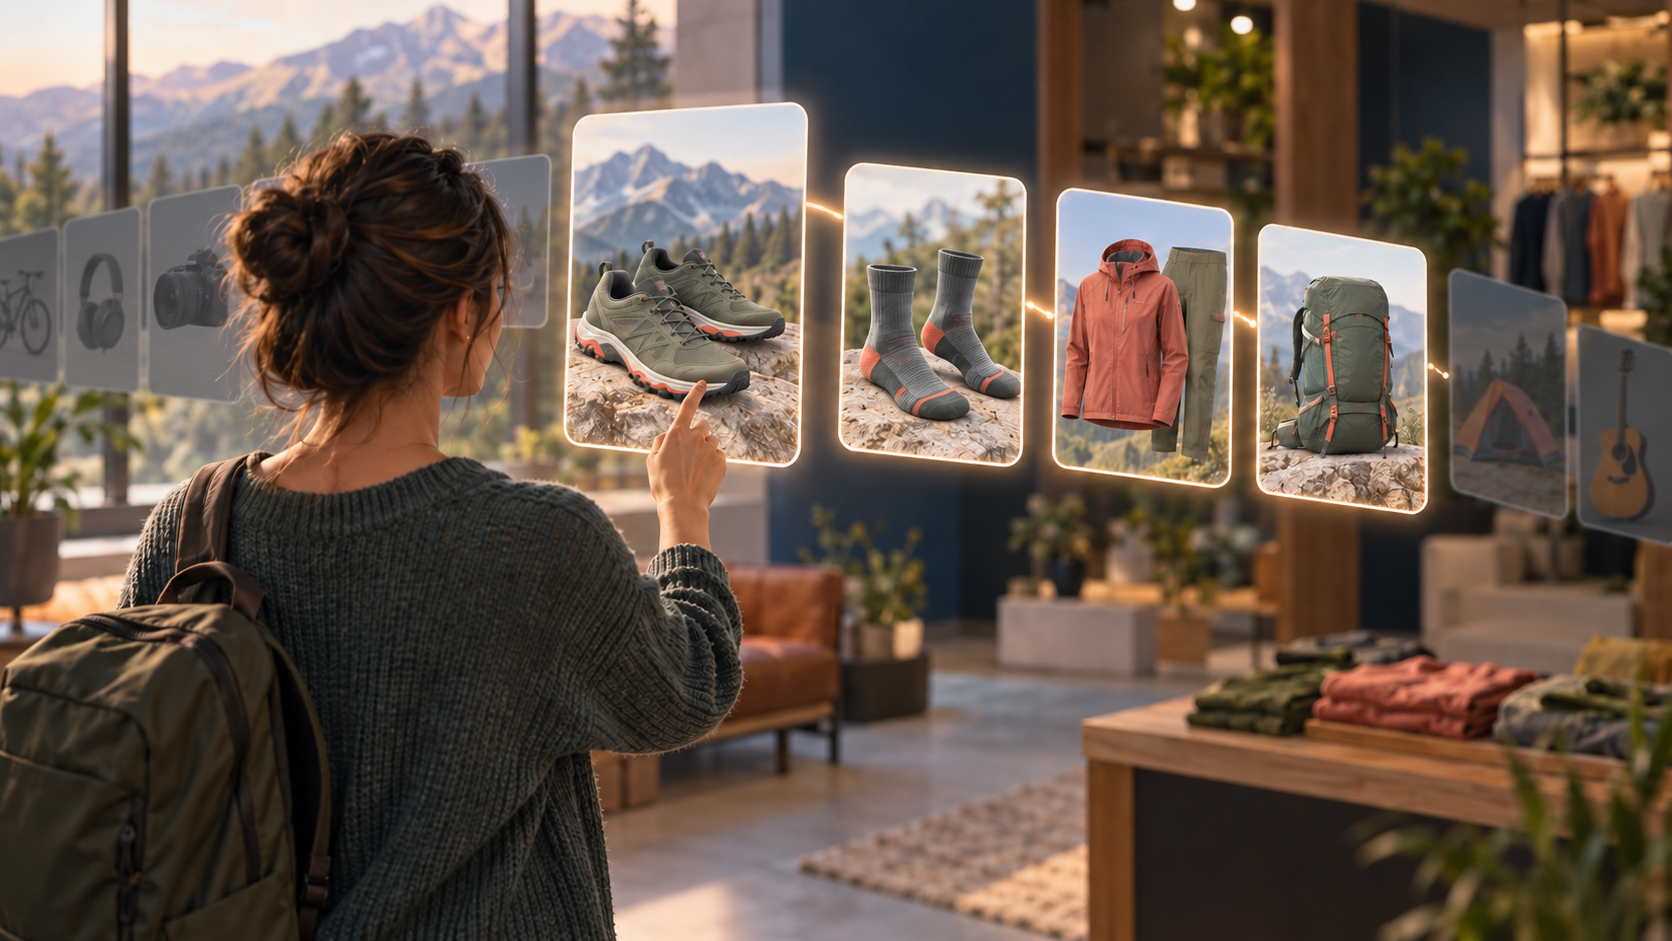
    Shopper viewing image-only product panels for trail shoes, hiking socks, outdoor clothing, and backpacks connected in a natural shopping sequence.

    After identifying an under-supported category, choose donor pages by relationship rather than raw authority. The best question is simple: would a shopper on this page reasonably want to explore that category next?

    Consider link locations in descending order of structural fit:

    1. Primary navigation: Reserve this scarce space for durable categories that matter broadly to the business and to shoppers. A short campaign or narrow subcategory rarely belongs here.
    2. Parent categories: A broader department or collection is often the clearest route to an important child category. Make the child visible in the page’s category list or other useful navigation, rather than relying on filters alone.
    3. Closely related categories: Add a related-category module when the destination is a plausible alternative or next step. The relationship should remain understandable without an SEO explanation.
    4. Buying guides and editorial content: Link when the content discusses the product type or helps the reader choose it. This connects informational intent with an appropriate shopping destination.
    5. Recurring seasonal hubs: Use them to support stable seasonal categories while the relationship is useful. Do not let expired promotional pages become the category’s only meaningful route.

    Use anchor text that identifies the destination in ordinary language. The category name is usually clearer than a vague phrase such as “shop now” or an awkward string of keyword variations. Surrounding copy should explain why the destination is relevant; the link should feel like part of the shopping decision, not an SEO insertion.

    Keep the implementation crawlable and consistent with the site’s existing components. Test the final rendered page rather than approving a design mockup alone. Confirm that the link resolves to the intended URL, appears for users and crawlers, works on mobile, and does not point through an unnecessary redirect.

    Avoid solving every mismatch with global navigation or a sitewide footer. Broad placements multiply links quickly, but they ignore context and consume space across the entire store. A focused set of strong paths from parent, related, and editorial pages usually tells a more coherent story about the category’s role.

    Roll out changes as an allocation test

    Internal-link changes often coincide with promotions, inventory shifts, content launches, paid campaigns, and seasonal demand. Without a record of what changed, an improvement or decline becomes difficult to interpret.

    Create a change log with the target category, donor page, placement type, anchor text, implementation date, and business reason. Capture a baseline before release for:

    • the target’s click path and internal-link sources;
    • organic impressions, clicks, and landing-page visibility;
    • shopper clicks on the new link or module;
    • category entrances, product engagement, and conversion outcomes;
    • inventory availability and any promotions affecting demand.

    When possible, phase the work by category group instead of changing the whole taxonomy at once. Keep a comparable set of qualified categories unchanged during the same period. It will not create a perfect experiment, but it gives you a better reference point than a simple before-and-after comparison.

    Look for a coherent chain of evidence. The new paths should be live and used; the target should become easier to discover; search visibility should move in a useful direction; and the traffic should produce meaningful shopping behavior. A ranking movement without inventory, engagement, or commercial value is not enough to justify permanent prominence.

    Review allocation when the business changes. A category that deserved navigation space during a sustained growth phase may later belong under its parent. Likewise, a category with emerging demand and dependable inventory may outgrow its old position. Internal architecture should reflect current priorities without swinging with every short promotion.

    FAQ: ecommerce category internal linking decisions

    Should every category receive a similar number of internal links?

    No. Equal counts would treat strategic categories, utility filters, temporary collections, and minor subcategories as if they had the same role. Allocate links according to business importance, search opportunity, inventory, durability, and relevance.

    Should a buried priority category go into the main navigation?

    Only when it is durable, broadly useful, and important enough to justify scarce navigation space. A narrower category may be better supported through its parent, related collections, and relevant buying content. The right correction is the clearest useful path, not automatically the most global placement.

    Should filtered pages receive internal links?

    Most filter combinations should remain shopping tools rather than promoted landing pages. Support a filtered URL only when it represents distinct and sustained demand, carries adequate inventory, has a stable purpose, and deserves a defined place in the taxonomy.

    Can internal links fix an underperforming category?

    They can correct weak discovery and an architecture that understates the category’s importance. They cannot create search demand, replenish inventory, clarify a confused taxonomy, or make a weak landing page useful. Diagnose those constraints before treating link volume as the answer.

    Start with one qualified category that the business values but the site currently hides. Document the mismatch, add the smallest set of relevant paths that corrects it, and measure the entire journey from discovery to commercial outcome. That gives you a defensible model for the next category instead of another sitewide link rule.

    References


  • Google Ad-Tech Antitrust Litigation: A Publisher’s Playbook

    Google Ad-Tech Antitrust Litigation: A Publisher’s Playbook

    If you depend on programmatic advertising revenue, the Google ad-tech litigation creates a planning problem before it creates a financial opportunity. The wrong response is to put a recovery into your forecast or make a rushed platform change. The useful response is to determine whether your business touches the surviving claims and whether you can still explain, with records, how money moved through your ad stack.

    Major claims remain alive, but that is not the same as a finding that every publisher was harmed. Your immediate job is to separate what the court has established, what the publishers still must prove, and what evidence your own legal and finance teams would need to evaluate any potential exposure or recovery.

    The ruling preserved a path, not a payout

    On Sept. 30, U.S. District Judge P. Kevin Castel issued an 88-page opinion denying Google’s requests for summary judgment on the publishers’ principal ad-tech claims. He also declined to exclude important expert testimony supporting their damages cases.

    Summary judgment is a pretrial mechanism for resolving claims that do not require a trial to decide. Denying it means Google did not persuade the court to dispose of the principal claims on the pretrial record. It does not mean the publishers have won a damages award, that every expert assumption has been accepted, or that every remaining dispute will necessarily reach trial.

    What the decision didWhat it did not do
    Kept the publishers’ principal ad-tech claims in the litigationDecide how much, if anything, Google owes
    Allowed key damages testimony to remain in the caseAdopt the experts’ estimates as proven losses
    Preserved claims involving the AdX publisher class and Mikula Web SolutionsPreserve every claim brought by every plaintiff
    Prevented Google from relitigating certain findings from the separate Virginia caseEstablish injury and damages for each publisher automatically

    The mixed outcome matters. Castel ruled for Google on the New York General Business Law claims brought by Gannett and Daily Mail, on claims brought by The Progressive, and on Inform’s federal antitrust claims. Claims involving the AdX publisher class and Mikula Web Solutions were allowed to continue. A headline saying publishers cleared a major hurdle is accurate, but it is too broad to answer whether a particular company, legal theory, or alleged loss remains in play.

    When you brief executives, use a claim matrix rather than a win-or-loss label. Give each claimant and legal theory its own row, then record whether the claim survived, which issues are already established, which issues remain disputed, and what procedural event comes next. That prevents a partial ruling from turning into an inaccurate company-wide assumption.

    The economic dispute sits between inventory and demand

    An abstract publisher page and advertiser nodes connected through a layered auction system carrying metallic tokens.

    A publisher ad server manages advertising inventory and helps decide which demand source can fill an opportunity. An exchange provides a marketplace in which demand can compete for that inventory. When one company controls important infrastructure on both sides of that handoff, the rules connecting the products can affect which demand participates, how an auction operates, what fees are charged, and what reaches the publisher.

    That connection is central here. The publishers allege that Google’s control over its publisher ad server and the AdX exchange, combined with practices governing ad auctions, reduced publisher revenue or produced excessive fees. Google contests those allegations. The disputed question is therefore not simply whether publishers used Google technology; it is whether challenged conduct caused a measurable economic injury.

    The litigation also draws on the federal government’s separate ad-tech case in Virginia. Castel had already determined that Google could not relitigate certain findings from that proceeding, including the finding that Google unlawfully tied its publisher ad server to AdX. That gives the publisher plaintiffs an important established point, but it does not calculate the consequences for a particular publisher. Injury, causation, and damages still have to be connected to the conduct at issue.

    For your business, the practical unit of analysis is an ad-monetization dependency map. It should show:

    • The legal entities, sites, applications, and business units that sold digital inventory.
    • The publisher ad server and exchanges used during each relevant period, including migrations and material configuration changes.
    • Which demand paths were direct, exchange-based, mediated, or otherwise dependent on the publisher ad server.
    • The contracts, amendments, fee schedules, invoices, and reporting accounts associated with each path.
    • The identifiers that connect domains, properties, accounts, reports, and payment records across systems.
    • The employees or vendors who understood auction configuration, yield management, billing, and reporting definitions at the time.

    This map does not establish that you belong to a class or have a claim. It gives counsel the facts needed to assess those questions without relying on institutional memory. It also reveals whether a change in revenue coincided with traffic, inventory, auction, fee, or platform changes instead of treating every decline as one undifferentiated problem.

    Do not mistake the damages estimates for recoverable amounts

    The public figures are large because they are damages estimates prepared by experts retained by the plaintiffs. They are not court-awarded compensation:

    Claimant or groupPlaintiffs’ expert estimate
    GannettRoughly $901 million
    Daily Mail$600 million
    Publisher class$1.72 billion through March 31, 2024

    The plaintiffs claim additional class damages after March 31, 2024, but no additional amount was provided. Do not extend the $1.72 billion estimate beyond that date, apply it as a percentage of industry revenue, or use it to derive a hypothetical recovery for your company. None of those calculations is supported by the disclosed figures.

    An expert’s testimony can remain admissible while its assumptions, method, causal reasoning, and conclusions remain disputed. The publishers still need to prove that the challenged conduct injured them and that the requested damages are attributable to that conduct. Google can continue contesting those points.

    Your finance team should therefore treat the amounts as allegations supported by the plaintiffs’ models, not as receivables or operating income. If you need an internal scenario, build it in layers:

    1. Use zero recovery as the operating baseline unless legal and accounting advisers determine otherwise.
    2. Ask counsel whether the relevant legal entity, products, time periods, and transactions could fall within a surviving claim or class.
    3. Identify which revenue, fee, and auction records could support or contradict economic injury.
    4. Document every assumption in any contingent scenario, including eligibility, time boundaries, allocation method, legal costs, and uncertainty.
    5. Keep the scenario outside normal performance targets so an unresolved lawsuit does not distort hiring, content, or technology decisions.

    The same restraint applies to vendor decisions. A surviving antitrust claim is not proof that your current contract is invalid, that a migration will improve yield, or that another stack will produce a particular result. Evaluate a change using your own fees, demand access, reporting quality, operational cost, and measured auction outcomes.

    Build a counsel-led evidence pack while the systems are identifiable

    An overhead view of storage drives, blank records, archive envelopes, and a magnifying glass arranged as an evidence pack.

    This is an operational preparation checklist, not a determination that your company is part of the litigation or subject to a legal-hold obligation. If the surviving claims may be relevant to your business, ask qualified antitrust or litigation counsel to assess eligibility and preservation duties. Do that before changing retention policies or launching a broad data collection.

    1. Create a system inventory. Record each ad server, exchange, reporting interface, billing system, data warehouse, and archive, along with its owner and available date range.
    2. Preserve the commercial record. Locate contracts, order forms, amendments, invoices, payment statements, fee disclosures, account notices, and documents explaining platform migrations or material configuration changes.
    3. Preserve the operational record. Identify ordinary-course auction reports, revenue reports, configuration histories, demand-partner lists, account identifiers, and metric definitions. Record where a field was renamed or calculated differently over time.
    4. Build a dated chronology. Align platform changes with shifts in impressions, fill, auction participation, reported fees, and net publisher revenue. A chronology makes alternative explanations visible instead of assuming every movement came from the challenged conduct.
    5. Reconcile money to activity. Where the data permits, connect inventory and auction records to invoices and net payments. Record unexplained gaps rather than backfilling them with estimates.
    6. Document limitations. Note missing periods, expired logs, acquired properties, changed account IDs, inconsistent currencies, and reports that cannot be reproduced. A known limitation is more useful than false precision.
    7. Control access. Keep the working set limited to the people who need it, and follow counsel’s directions for preservation, privilege, privacy, security, and collection scope.

    Do not delete, rewrite, or normalize potentially relevant originals after counsel identifies a preservation obligation. At the same time, do not collect extra user-level information merely because it might be available. An indiscriminate collection can create privacy and security exposure without helping establish publisher-level fees or revenue. Preserve what is relevant, document what each field means, and let counsel define the defensible scope.

    SEO, content, and audience teams also have a role. Keep acquisition performance separate from monetization performance in your reporting:

    • Acquisition: visits or sessions from organic search, AI-search referrals, direct traffic, social platforms, and other channels.
    • Inventory: ad opportunities, eligible impressions, ad load, and fill-related measures available in your systems.
    • Monetization: auction outcomes, disclosed fees, and net publisher revenue, with the governing metric definitions attached.

    Traffic can improve while monetization weakens, or monetization can improve while traffic falls. A single blended revenue-per-session figure hides that distinction. Separating the layers helps you evaluate content performance accurately now and gives legal and financial reviewers a cleaner record if they later need to isolate alleged ad-tech harm.

    Key takeaways for publisher teams

    • The Sept. 30 decision kept principal Google ad-tech claims alive and preserved key expert testimony; it did not award damages.
    • Google cannot relitigate certain findings from the separate Virginia case, including unlawful tying of its publisher ad server to AdX, but publisher-specific injury and damages still require proof.
    • The estimates of roughly $901 million for Gannett, $600 million for Daily Mail, and $1.72 billion for the publisher class are plaintiffs’ expert estimates, not payouts.
    • The result varies by claimant and legal theory. Several claims were resolved for Google, while claims involving the AdX publisher class and Mikula Web Solutions continue.
    • Your defensible next step is a counsel-led review of eligibility, systems, contracts, fees, and retained data—not an assumed recovery or an emergency platform migration.

    Within your next reporting cycle, produce a one-page ad-stack dependency map and assign owners for the supporting contracts, reports, and payment records. Have counsel decide whether a deeper eligibility or preservation review is warranted. That gives you a decision-ready file without pretending the litigation has already produced money for publishers.

    References


  • ChatGPT Virtual Try-On: An Ecommerce Optimization Playbook

    ChatGPT Virtual Try-On: An Ecommerce Optimization Playbook

    You may be asking a deceptively simple question: what should your ecommerce team change now that a shopper can preview a product inside ChatGPT? The answer isn’t to add AI shopping phrases to every page. Virtual try-on moves part of product evaluation upstream, before the shopper reaches your store.

    Your job is to make each product understandable during discovery, visually recognizable during evaluation, and easy to buy when the shopper finally reaches the product page. That requires coordinated work across imagery, catalog data, structured data, fit guidance, landing-page UX, and measurement.

    Virtual try-on changes where product evaluation happens

    On eligible clothing and accessory listings, ChatGPT can display a Try on button that lets a shopper take or upload a selfie. ChatGPT Images then generates a visualization of that person wearing the item. A product doesn’t have to originate in a ChatGPT recommendation: the shopper can also upload an image or screenshot of something found elsewhere and request a virtual try-on.

    That creates a shopping path that may look like this:

    1. The shopper describes the clothing or accessory they want.
    2. ChatGPT surfaces products that appear relevant.
    3. The shopper visualizes a candidate product on their own image.
    4. They compare it with other possibilities.
    5. They save promising items or visit a merchant to inspect the offer and buy.

    Product discovery and visual evaluation can therefore happen within the same conversation. ChatGPT also lets shoppers save products to Favorites, organize them into Library folders, and return to them on mobile or the web. A recommendation is no longer necessarily followed by an immediate click. The shopper may build a shortlist first and arrive at your store later with a narrower set of questions.

    For an ecommerce SEO or GEO team, that changes the optimization target. You need to support three decisions:

    • Recognition: Can the product be distinguished from superficially similar items?
    • Evaluation: Can the shopper understand its color, cut, pattern, material, and available variations?
    • Completion: Can your product page resolve size, price, availability, delivery, and return questions without introducing contradictions?

    This doesn’t make the product page less important. It gives the page a more demanding role. The visitor may already like the apparent look; the merchant must now establish exactly what is being sold and reduce the remaining purchase risk.

    The screenshot workflow matters just as much as native product discovery. A shopper may encounter your item in search, on a marketplace, in a social post, or on another page before bringing its image into ChatGPT. Your visual assets need to remain recognizable when separated from their original context.

    Build a coherent product record, not an AI optimization gimmick

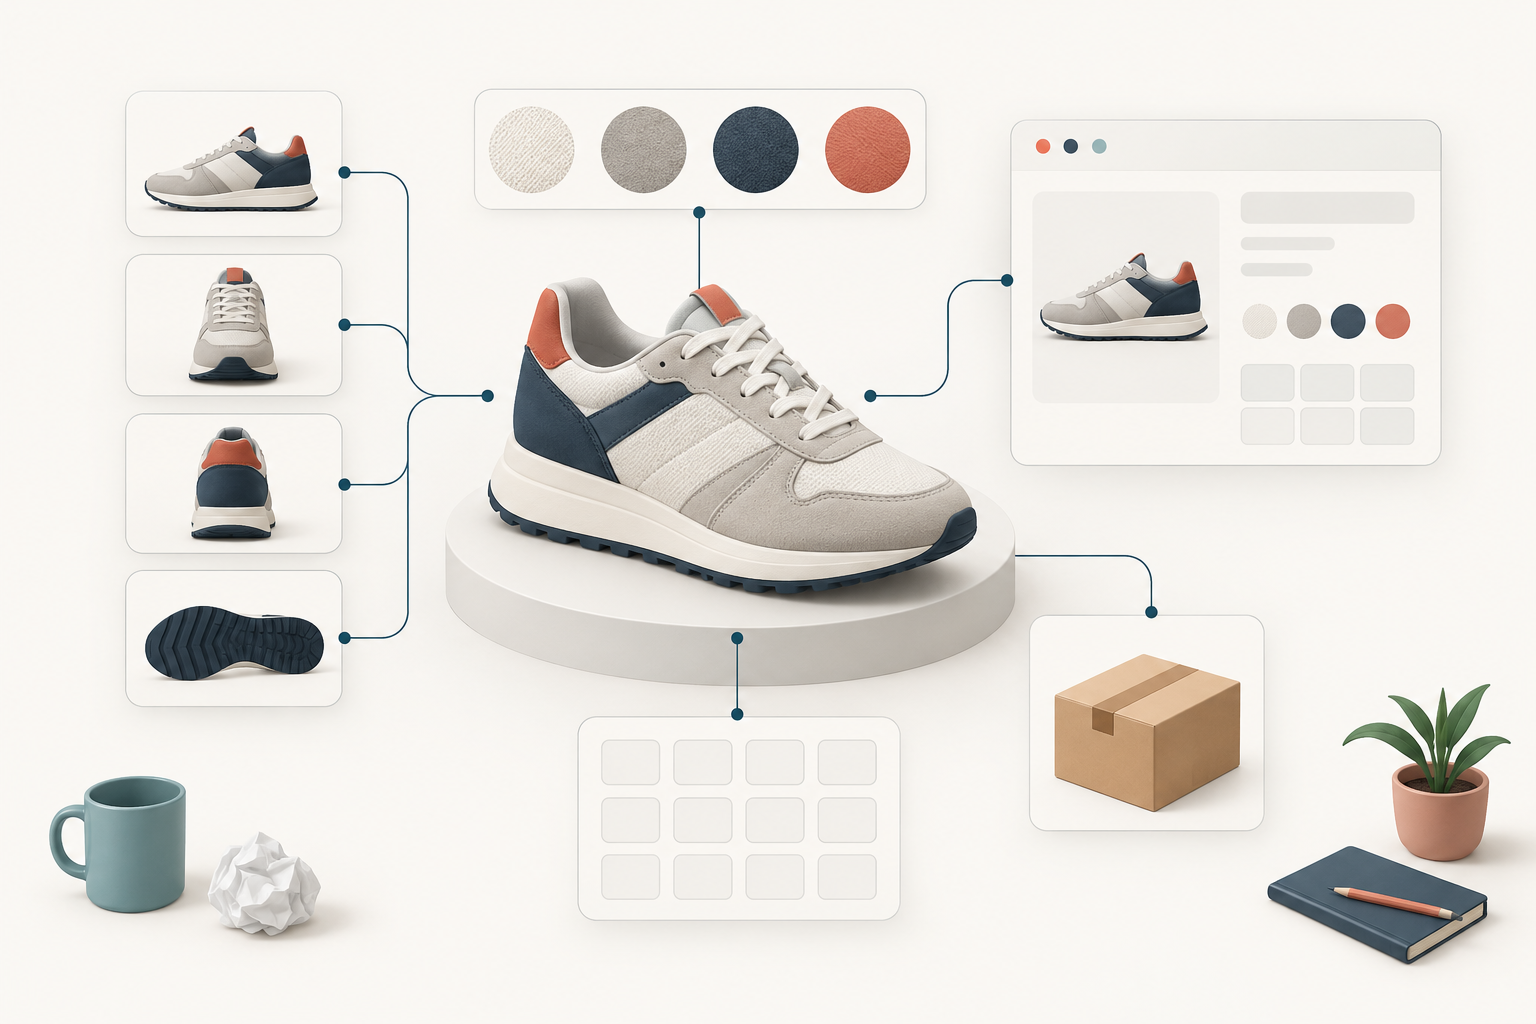
    An unbranded sneaker is surrounded by connected product images, color swatches, size cells, packaging, and a product card.

    There is no established Try on optimization formula, required image dimension, or special schema property that guarantees eligibility. Treat promises of guaranteed inclusion through a single field with skepticism. The practical goal is coherence across the product image, visible copy, variation selector, commerce feed, and structured data.

    Use images that still make sense outside the product page

    Start with the main image because it is the most likely visual shorthand for the product. It should make the item easy to identify without forcing a system or shopper to infer which object is for sale.

    • Show the complete garment or accessory clearly in at least one image.
    • Keep the product visually distinct from props, backgrounds, and neighboring items.
    • Use the correct image for each color or pattern variation.
    • Provide additional views when the front image hides important construction, shape, fastening, or pattern details.
    • Keep image treatment consistent enough that a shopper can recognize the same item across a listing, a screenshot, and the product page.
    • Avoid putting essential product facts only inside image text. Those facts also belong in visible HTML.
    • Write useful alternative text for accessibility and page comprehension, but don’t claim that alt text controls a virtual try-on rendering.

    Run a simple crop test. View the product image without its title, price, or surrounding page. Ask whether a person could identify the item type, dominant color, pattern, and intended variation. If the answer depends on the missing copy, the image is doing too little. If several products compete for attention, it is doing too much.

    Don’t replace accurate catalog photography with speculative AI composites merely to appear AI-ready. A visualization system needs a dependable representation of the product. Your controlled assets should establish ground truth, while the generated try-on remains a separate, personalized interpretation.

    Make attributes explicit and consistent

    Product copy should identify the attributes that distinguish the item. A poetic collection name may support branding, but it shouldn’t carry the entire descriptive burden. Pair it with plain product language that states what the shopper is looking at.

    • Use a stable product name, brand, and product type.
    • Name the actual color as well as any branded color name.
    • Describe the material or fabric without making unsupported performance claims.
    • State the silhouette, length, pattern, closure, and other decision-relevant features when they apply.
    • Map every displayed image to the correct selectable variation.
    • Keep price, currency, availability, and condition aligned wherever those fields appear.
    • Use valid product identifiers consistently. Never invent an SKU, GTIN, or other identifier to fill an empty field.
    • Provide measurements and size information in accessible page content rather than relying on an image alone.

    Structured data should mirror that visible record. Product and Offer JSON-LD can express product and commercial facts in a machine-readable form, but markup is not a substitute for accurate page content and isn’t evidence of virtual try-on eligibility. If the page shows one price while the Offer markup publishes another, the problem isn’t a missing AI tactic; it is a conflicting product record.

    Check variation handling closely. The selected color, image, SKU, availability, price, and structured data should refer to the same offer. If your implementation updates some of those fields dynamically, verify the rendered state rather than reviewing only the page template or source code. A technically valid block of JSON-LD can still describe the wrong variant.

    Audit the complete product path

    Use this sequence on representative clothing and accessory templates:

    1. Open a live product and select each meaningful variation.
    2. Compare the selected option with the main image, gallery, visible name, price, stock state, and product identifier.
    3. Inspect the rendered Product and Offer data for the same variation.
    4. Check the size guide, measurements, material details, delivery information, and return policy.
    5. Capture the main product image as a shopper might encounter it elsewhere and verify that the product remains recognizable.
    6. Resolve contradictions before adding more copy or markup. Consistency is the prerequisite, not the finishing touch.

    This audit is useful beyond ChatGPT. It removes ambiguity from the catalog record that your own customers, feeds, analytics, search systems, and other shopping interfaces must interpret.

    Separate appearance visualization from fit, then strengthen the handoff

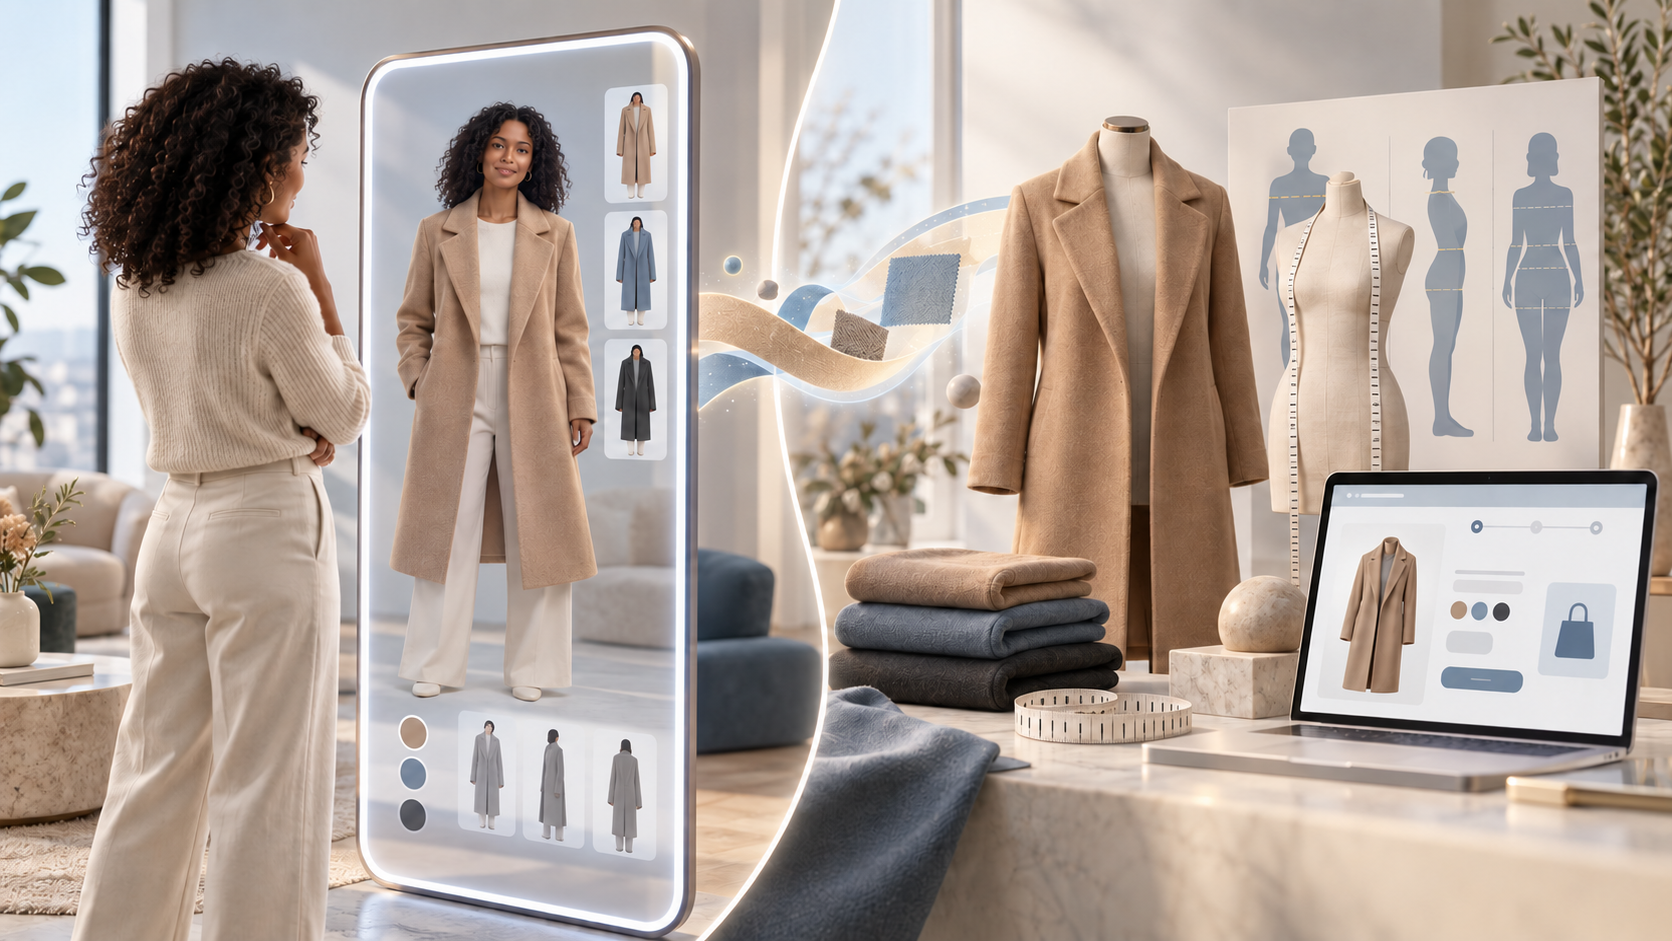
    A shopper previews a coat on a virtual avatar beside fit tools, size samples, and an abstract checkout screen.

    The most important boundary is also the easiest one to blur: virtual try-on is a visualization, not a fitting room. The generated result may not represent the shopper or product exactly and doesn’t guarantee size or fit. Merchant measurements, product details, and return policies remain part of the buying decision.

    Think of the preview and product page as answering different questions:

    Shopper questionBest answer surfaceWhat the answer must communicate
    How might this style look on me?Virtual try-on visualizationA directional visual impression, not a promise of exact appearance or fit
    Which size should I order?Merchant size guide and measurementsClear measurement definitions, units, garment dimensions, and relevant sizing notes
    What exactly am I buying?Product page and variation selectorThe selected color, material, construction, images, price, and availability
    What happens if it isn’t right?Delivery and return informationApplicable conditions, timing, process, and customer costs

    Your size guidance needs enough context to be usable. Distinguish body measurements from garment measurements. Name the measurement points and units. Explain relevant stretch, cut, or layering considerations without pretending they can predict an individual’s fit. If sizing differs by product line or market, put the correct guide on the affected product rather than sending everyone to a generic chart.

    The landing page should preserve continuity with what the shopper evaluated. The same variation should be easy to recognize, and the page should expose the remaining decision information without making the visitor hunt for it.

    • Keep the product name and selected variation visible near the main image.
    • Show current price and availability for that variation.
    • Place the size selector close to the relevant size guide.
    • Make material and care information easy to scan.
    • Present delivery and return terms before the shopper commits to checkout.
    • Explain unavailable variations honestly rather than silently switching the selection.
    • Keep mobile layouts usable because the shopping features are available on both mobile and web.

    Favorites add another handoff consideration. A shopper may save an item, compare it with alternatives, and return after the original discovery session. Stable product URLs, persistent identifiers, current inventory, and clear replacement behavior matter more than a landing experience built only for an immediate click.

    If you describe AI visualization on a page you control, keep the claim narrow. Plain language such as “The preview is a visual approximation; check the product measurements and return terms before ordering” sets the right expectation. Don’t call a generated image proof of fit, exact drape, precise color reproduction, or guaranteed appearance.

    Measure discovery, merchant handoff, and post-purchase outcomes

    Referral traffic alone will not describe the full effect. A shopper can upload a product screenshot found elsewhere, evaluate it in ChatGPT, save it, and return by another route. Some influence will therefore be invisible to your analytics or appear under a later source.

    Observe visibility without treating one answer as a ranking report

    Create a repeatable set of prompts based on real customer language. Include product type, material, color, occasion, style, and other attributes your catalog genuinely supports. Record whether your products appear, whether the correct variation is represented, whether the cited destination resolves correctly, and whether a Try on option is shown when relevant.

    Use those checks diagnostically. They can expose ambiguous naming, weak imagery, broken destinations, and inconsistent variants. They do not establish universal market share, a permanent ranking, or the cause of a recommendation. Avoid turning a favorable answer from one session into a performance claim.

    Instrument the merchant handoff

    Preserve raw referrer information where your analytics and consent setup permit it, and group identifiable ChatGPT visits without overwriting the underlying source. Then evaluate the onsite sequence rather than counting sessions alone.

    • Which products receive identifiable AI referral visits?
    • Does the landing URL resolve to the intended product and variation?
    • Do those visitors use the gallery, variation selector, or size guide?
    • Where do they leave the product and checkout funnels?
    • Do they add the evaluated item to the cart, or switch to another variation or product?
    • Are analytics events firing consistently across mobile and desktop?

    A high click count with frequent variant switching may indicate that the upstream image or product description set the wrong expectation. Strong product-page engagement with weak size selection may point to incomplete fit guidance. Treat these as diagnostic signals to investigate, not automatic proof of causation.

    Connect the experiment to business outcomes

    Virtual try-on is intended to help a shopper evaluate a product, so the useful outcomes sit deeper than impressions. Track completed purchases, cancellations, exchanges, returns, and available reason codes for the affected products. A generated preview that increases curiosity but creates a mismatch at delivery is not an unqualified success.

    Use a controlled improvement cycle:

    1. Save a baseline for the selected product group, including its images, visible attributes, structured data, funnel behavior, and return outcomes.
    2. Fix one interpretable layer, such as variation-image mapping or measurement content.
    3. Repeat the same visibility checks and review the same onsite events.
    4. Annotate concurrent changes in price, promotion, inventory, seasonality, and delivery terms.
    5. Read the result as directional unless the design actually isolates the changed variable.

    Don’t label every post-change sale as AI-driven revenue. Report what you can observe directly, separate identifiable referrals from inferred influence, and name the blind spots. Favorites activity inside ChatGPT and screenshot-based exploration are not merchant-side analytics events.

    Key takeaways

    • ChatGPT virtual try-on can combine product discovery, selfie-based visualization, comparison, and shortlisting before a merchant visit.
    • A shopper can upload a product image found elsewhere, so clear and recognizable assets matter beyond native ChatGPT listings.
    • There is no basis for promising eligibility from one schema field, keyword, image treatment, or feed attribute.
    • Product images, visible content, variations, commerce feeds, and Product and Offer structured data should describe the same item and offer.
    • Virtual try-on visualizes a possible look; merchant measurements, size guidance, product facts, and return terms must handle fit and purchase risk.
    • Measure visibility, onsite behavior, purchases, and returns while acknowledging that screenshot and Favorites activity may leave no direct referral trail.

    Start with a representative clothing or accessory template and follow one product from its standalone image through variant selection, JSON-LD, size guidance, return information, and analytics events. Fix every contradiction you find before scaling the audit across the catalog. That gives you a durable commerce foundation whether the next shopper discovers the product through ChatGPT, another AI interface, a conventional search result, or a saved screenshot.

    References


  • Google Ads Automation and Localization Without Losing Control

    Google Ads Automation and Localization Without Losing Control

    If you manage Google Ads, your website is becoming part of the campaign-building system. An offer published on a page may become a promotion asset, while an existing Search campaign may become the template for a new language and market.

    That can remove hours of repetitive setup. It can also scale an expired discount, awkward translation or unsuitable budget before anyone notices. The right response is not to reject automation. It is to put a clear approval boundary between what Google can generate and what your business is prepared to promise and spend.

    Separate the two automations before setting policy

    Automated promotions and campaign localization solve different problems. They also fail differently. Treating them as one generic AI feature makes it harder to assign the right reviewer and control.

    WorkflowWhat Google createsInitial scopePrimary control
    Automated promotionsA promotion asset based on an eligible offer found on your websiteSearch and Performance Max campaigns with linked location assets and no promotion asset already attachedThe account-level Automated Promotions setting, followed by a review of assets that serve
    AI campaign localizationA new, independent campaign with localized ads, assets and keywordsEligible U.S. English Search campaigns translated into supported languages and markets during the betaLanguage, landing-page and commercial review before the localized campaign goes live

    The promotion workflow extracts a commercial claim that already exists. The localization workflow transforms an existing campaign for a different audience. The first can misstate an offer; the second can reproduce a sound campaign in a market where its language, intent or economics no longer fit.

    A useful account policy is simple: automation may identify, translate and assemble; a named owner must still authorize the promise, the audience and the spend.

    Audit your website before automated promotions serve

    A review team inspects a website page for expired dates, mismatched prices, unavailable products, and broken links before automation.

    Starting Oct. 12, eligible advertisers may be enrolled automatically. That changes the default risk. Doing nothing is no longer necessarily the same as declining the feature.

    Your first decision is whether the account should participate at all. Keep it enabled when public offers are current, clearly qualified and consistently honored online and in stores. Disable it when promotions require case-by-case approval, depend on complex eligibility rules or frequently remain visible after they expire.

    1. Open the account’s automated asset settings and find Automated Promotions. Record whether it is on or off and who approved that choice.
    2. Inventory public pages that mention discounts, coupon codes, bundles, free items or limited offers. Include store pages when location assets connect campaigns to physical locations.
    3. Make each offer understandable without surrounding marketing copy. State what qualifies, what the customer receives and, where applicable, when and where the offer is valid.
    4. Reconcile the page with the real transaction. Pricing, eligibility and brand wording should agree with the checkout flow, sales process and in-store terms.
    5. After an automated promotion begins serving, inspect it in the Assets section. An asset that has not received impressions will not appear there, so an empty view does not prove that the account is opted out.

    That last distinction matters. The setting tells you whether Google has permission to create automated promotions. The Assets view tells you what has actually accumulated impressions. Check both rather than using one as a proxy for the other.

    If you opt out, use the explicit account-level control. Do not rely on incomplete pages, ambiguous offer wording or the presence of a manually managed asset as an informal safeguard. Automated Promotions can be turned off in automated asset settings, which gives the account team an auditable decision instead of an accidental outcome.

    Launch localization as a new market, not a translation task

    The localization beta can turn one eligible Search campaign into a separate campaign for another language and location. The original campaign remains unchanged. That independence is useful, but it does not make the new campaign commercially ready.

    1. Choose a parent campaign worth reproducing. Fix known targeting, messaging or landing-page problems before translation, or the new campaign will begin with the same structural weaknesses.
    2. Select the exact target language and location. A language label is not a market strategy: Spanish for Spain and Spanish for Latin America and the Caribbean are available as distinct variants in the beta.
    3. Give the AI explicit language rules. Tell it which brand names, product names and technical terms must remain unchanged, and specify whether the voice should be formal or conversational.
    4. Review every campaign component, not just the headlines. The workflow can localize headlines, descriptions, sitelinks, callouts and keywords.
    5. Choose the landing-page method deliberately. You can install a Google-provided JavaScript snippet that dynamically translates page text for visitors from localized ads, or update the campaign URLs to point to pages you already maintain in the target language.
    6. Require a human language and market review. Use the original, localized version and English back-translation shown side by side to check meaning, then ask a fluent reviewer to assess naturalness, search intent, cultural fit and brand terminology.
    7. Reset the economics. Budgets and bids are copied from the original campaign without automatic currency conversion or exchange-rate adjustment. Do not approve launch merely because those fields are populated.

    The landing-page choice deserves particular care. Dynamic translation is a practical route when the underlying offer and customer journey are genuinely the same. A maintained local page is the stronger option when prices, availability, delivery terms, legal wording or conversion steps differ by market. In either case, review the page as the visitor will see it after clicking the localized ad.

    Images also need a separate check. When an image contains text, the workflow can remove the original wording and use the translation as supplemental text assets. Do not assume the output will simply be the same image with perfectly replaced lettering. Preview the complete creative combination and confirm that the visual still makes sense without its original embedded message.

    The beta supports U.S. English Search campaigns localized into Dutch, French, Canadian French, German, Italian, Polish, Brazilian Portuguese, European Portuguese, Spanish for Spain and Spanish for Latin America and the Caribbean. Google plans to add languages by the end of 2026 and later extend localization to Performance Max. Treat that as a roadmap, not as a capability your current launch can depend on.

    Use one release gate for assets, language and money

    Three reviewers check advertising assets, localized language elements, and budget tokens at a single campaign release gate.

    The most reliable control is a short release record shared by the website owner, campaign manager and market reviewer. It should force a yes-or-no decision on the places where automation cannot judge your business obligations.

    • Commercial truth: Is the promoted price or benefit currently available, and will every customer who meets the stated conditions receive it?
    • Qualification: Are exclusions, dates and location restrictions consistent across the ad asset, landing page, checkout or sales process, and physical store where relevant?
    • Language: Has a fluent reviewer approved the customer-facing wording rather than relying only on the English back-translation?
    • Search intent: Do the localized keywords represent how people in that market look for the offer, not merely a literal rendering of the parent keywords?
    • Landing experience: Does the visitor remain in the intended language through the meaningful conversion steps?
    • Economics: Have the copied budget and bids been reviewed for the target market instead of accepted as inherited defaults?
    • Ownership: Is one person responsible for pausing the asset or campaign when an offer, page or market condition changes?

    Use event-based reviews rather than a vague instruction to monitor regularly. Reopen the record when an offer starts or ends, a price or landing page changes, an automated asset first receives impressions, a new localized campaign is generated, or its budget and bids are changed.

    After launch, judge the localized campaign on its own market economics. It is an independent campaign, so the parent campaign’s historical success is context, not proof. For automated promotions, compare the served asset with the live offer page and the transaction customers actually receive. The purpose of monitoring is not just to catch strange wording; it is to catch a broken commercial promise.

    Key takeaways

    • Check the account-level Automated Promotions setting before Oct. 12; eligible advertisers may be enrolled without making an affirmative choice.
    • Treat every public offer page as potential campaign input, especially when Search or Performance Max campaigns use linked location assets.
    • Do not use an empty Assets view as proof that automation is disabled; unserved assets do not appear there.
    • Review localized campaigns as independent market launches, including keywords, creative, landing pages, language quality and cultural fit.
    • Replace copied budgets and bids with a deliberate market decision because the localization workflow does not perform currency or exchange-rate adjustments.

    Your next step is small and concrete: open one eligible account, document its automation setting, then choose one live offer and one possible target market to run through the release gate. That will expose missing ownership and inconsistent inputs before automation exposes them to customers.

    References


  • Google’s AI Content Guidance: A Practical Quality Workflow

    Google’s AI Content Guidance: A Practical Quality Workflow

    If an AI draft can move from prompt to publish after a spelling check, your workflow has a quality gap. The problem is not simply that AI touched the page. The problem is that no accountable person has verified the claims, improved the substance, and confirmed that the finished page deserves to exist.

    Google now treats manual fact-checking and review of all AI-generated content as critical before publication. For you, that turns human oversight from a vague editorial ideal into a required publishing gate.

    Key takeaways

    • A human reviewer must verify AI-generated claims before they reach readers. A grammar pass, plagiarism scan, or automated confidence score is not a fact-check.
    • Judge the complete main content, not just the body copy. Titles, headings, images, videos, tools, reviews, comments, tabs, and expandable sections can all affect whether a page fulfills its purpose.
    • Use four separate quality tests: effort, originality, talent or skill, and accuracy. Passing one does not compensate for failing another.
    • Citations support factual claims, but attribution does not create original value. A page still needs useful analysis, experience, functionality, or perspective of its own.
    • Apply review gates to every AI-assisted page. Publishing at scale does not reduce the need for accountable human oversight.

    The quality test applies to the finished page

    Do not reduce Google’s position to a debate about whether AI is allowed. That framing misses the operational question: does the finished page accomplish a clear purpose and give the visitor a satisfying experience?

    The quality of the main content is one of the most important page-quality considerations. Four attributes help you turn that broad principle into an editorial test.

    Quality attributeQuestion for the reviewerEvidence you should be able to point to
    EffortWhat meaningful human work or useful system capability improved this page?Manual verification, substantive editing, original analysis, a tested tool, careful curation, or another contribution beyond generating text.
    OriginalityWhat can a visitor learn, see, or do here that is not already available in equivalent form elsewhere?A distinct explanation, first-party evidence, a worked example, a useful decision framework, original media, or genuinely different functionality.
    Talent or skillDoes the execution meet the level of ability the page’s purpose requires?Clear writing, sound reasoning, well-produced media, functional interactive elements, or appropriate subject expertise.
    AccuracyCan every consequential factual claim be verified, and are uncertainty and limitations represented honestly?Claim-level checks, reliable supporting material, corrected citations, and expert review where the stakes demand it.

    These tests are independent. An accurate page can still be derivative. An original opinion can still be poorly reasoned. A polished page can still contain invented facts. A team can spend hours editing a draft without adding anything that helps the reader.

    Effort is especially easy to misread. It is not a word-count target or proof that somebody moved sentences around. Automatically producing large volumes of text without manual oversight or curation represents little or no original effort in this quality framework. Adding links does not fix that weakness, because attribution cannot substitute for a real contribution.

    The required skill also depends on purpose. A personal account can be useful without professional credentials. A page that could materially affect a person’s health, finances, safety, or well-being carries a much higher accuracy burden and should remain consistent with established expert consensus.

    Audit every part of the main content, not only the prose

    A review team examines the prose, imagery, sources, interface, and structure of a layered web page on a large display.

    Your editorial team may call the central text the content, but Google’s definition is broader. Main content includes anything that directly helps the page fulfill its purpose. That distinction matters because an excellent paragraph cannot rescue a misleading title, a broken calculator, or inaccurate specifications hidden in a tab.

    • Titles and headings: Check that each heading accurately describes the material beneath it. Remove promises the page does not fulfill, and do not frame a qualified answer as a certainty merely to win a click.
    • Primary text and media: Verify claims made in copy, diagrams, captions, audio, and video. If two formats state different facts, the page is not accurate simply because the prose version is correct.
    • Interactive features: Test calculators, search functions, games, maps, and other tools with normal inputs, edge cases, and invalid inputs. A tool that looks complete but returns unreliable results fails the page’s purpose.
    • User contributions: Reviews, comments, forum replies, and uploaded media may be the reason the page exists. Make the distinction between editorial information and user claims clear, and review how unsupported or harmful contributions are handled.
    • Tabbed and expandable content: Treat hidden specifications, safety notes, comparisons, and reviews as fully part of the page. Being collapsed by default does not make inaccurate information less important.

    This broader audit also keeps SEO, AEO, and schema work honest. Structured data should describe visible, verified content. It cannot make an unsupported claim trustworthy, turn a duplicated explanation into an original one, or repair a tool that does not work.

    Use a claim-level review before an AI draft can publish

    A fact-checker connects individual glowing claim tiles from an AI draft to supporting source cards before an approval barrier.

    Generative models predict likely sequences of words rather than retrieving facts. A fluent answer can therefore contain fabricated, outdated, contradictory, or weakly supported details. The safest workflow separates factual verification from stylistic editing so that polished language does not disguise an unchecked claim.

    1. Write the page purpose in one sentence. Name the intended reader, the task they need to complete, and the decision or outcome the page should support. If the team cannot agree on that sentence, it cannot reliably judge whether the draft succeeds.
    2. Mark every checkable claim. Include names, dates, quotations, product capabilities, specifications, definitions, causal statements, procedural instructions, and factual comparisons. Do not limit the review to claims that already have citations; hallucinated details often arrive without one.
    3. Verify each claim manually. Open the supporting material and confirm that it actually supports the wording used. A real URL is not sufficient if the linked page discusses a different population, product version, condition, or conclusion.
    4. Separate fact from inference. Label analysis, recommendations, and predictions as such. If the evidence supports correlation, possibility, or a limited case, do not let the AI turn it into causation, certainty, or a universal rule.
    5. Resolve contradictions instead of smoothing them over. When reliable material disagrees, identify the disagreement and preserve the relevant uncertainty. Do not ask the model to blend incompatible claims into a confident middle position.
    6. Add a reason to choose the page. Contribute something beyond a rearrangement of available wording: a decision tree, a worked example, original analysis, first-party evidence, useful media, or tested functionality. Choose the contribution that helps the page fulfill its stated purpose.
    7. Review the complete experience. Test the title, headings, media, links, tabs, tools, calls to action, and mobile reading order alongside the text. Confirm that the answer is easy to find and that supporting detail appears where the reader needs it.
    8. Record accountable approval. Store the reviewer’s name, the completed fact-check, unresolved limitations, and the reason the page is ready. The person approving publication should be willing to own the accuracy of the final version, not merely the prompt that produced the first draft.

    Rewriting is not verification. Asking another model to check the first model is also not the manual review Google calls for. Automation can help inventory claims, find inconsistent terminology, or flag missing fields, but a person still has to inspect the evidence and make the publishing decision.

    For high-stakes topics, route the draft to someone with the expertise needed to evaluate it. A general editor may catch awkward wording and obvious contradictions while still missing a dangerous technical error. If qualified review is unavailable, narrow the claim, remove the unsupported passage, or hold the page rather than publishing certainty you cannot defend.

    Make human oversight a publishing gate, not a promise

    A policy that says editors should check AI content will fail under deadline pressure unless the content system makes the check visible. Build the requirement into the workflow.

    • Require a clear page purpose before drafting begins.
    • Add fields for the factual reviewer, editorial approver, verification notes, and unresolved limitations.
    • Prevent AI-assisted drafts from moving directly from generation to scheduled or published status.
    • Require supporting material at the claim level when a statement is consequential, disputed, or likely to change.
    • Give high-stakes pages an expert-review route rather than sending every topic through the same general queue.
    • Trigger a new review when facts, products, rules, consensus, or interactive functionality change.

    Do not replace universal review with a spot check of a few generated pages. Sampling can reveal patterns in a production system, but it cannot establish that the unchecked pages are accurate. Every AI-generated output still needs a manual prepublication review for accuracy and trustworthiness.

    Your stop conditions should be equally explicit. Hold publication when a consequential claim cannot be verified, a citation does not support the sentence, the page adds no meaningful value beyond existing material, a tool has not been tested, a heading promises an answer that never appears, or nobody is prepared to own the final result.

    Turn the guidance into a decision this week

    Start with your ten most recently published AI-assisted pages. For each URL, record its purpose, accountable reviewer, verified claims, and original contribution. A blank field identifies real editorial work: verify the claim, improve the page, correct the misleading element, or remove what you cannot support.

    Then apply the same fields before the next draft can publish. That is the practical standard: AI may accelerate production, but a named person must still make the finished page accurate, useful, original enough to merit attention, and fit for its purpose.

    References


  • AI Search Ranking Signals: A Practical Priority Order

    AI Search Ranking Signals: A Practical Priority Order

    If your team is debating whether the next optimization sprint should go to schema markup, an llms.txt file, or another FAQ block, pause. The larger opportunity is usually earlier in the chain: make it unmistakable what you offer, who it fits, and whether the same facts appear everywhere an AI system may encounter your brand.

    Markup can help a machine interpret a strong page. It cannot rescue vague positioning, missing proof, or conflicting information. If you want more visibility in ChatGPT, Gemini, Claude, AI Mode, and agentic search, use the priority order below to decide what to fix first.

    The strongest measured signals are clarity and consistency

    From June 8 to September 18, 2026, 4,213 commercial prompts and 657 agentic shortlisting or purchasing tasks were run through ChatGPT, Google Gemini, including AI Mode, and Claude. The analysis covered 1,089 brands across 14 industries and measured recommendation rate: the share of relevant prompts in which a platform named a brand as a recommended option.

    Clear descriptions of offerings and suitability had the largest adjusted association with recommendation rate at +11.2 percentage points. Consistent information across a brand’s website and third-party sources followed at +9.4 points. The adjustment controlled for authority signals such as list mentions, reviews, and awards.

    SignalDifference before authority controlDifference after authority controlWhat to do with it
    Clear offerings and suitability+15.8 points+11.2 pointsState what each offer is, who it serves, and when it is suitable.
    Consistent brand information+16.9 points+9.4 pointsReconcile important facts across owned pages and third-party profiles.
    Comparison tables on service pages+6.7 points+1.9 pointsUse tables when they make fit and differences easier to evaluate.
    Any schema markup+3.7 points+0.4 pointsTreat schema as a representation layer, not the main ranking project.
    Organization schema+2.1 points+0.2 pointsImplement it accurately, but do not expect it to create authority.
    FAQ schema+0.8 points-0.3 pointsAdd useful FAQs for readers, not to manufacture a ranking signal.
    llms.txt+0.8 points-0.1 pointsKeep it behind clarity, consistency, and authority work in the backlog.
    Product schema for ecommerce brands+6.7 points+4.8 pointsGive this greater priority when products are the entities being evaluated.

    Do not treat those adjusted differences as universal ranking weights. They are associations from one observational dataset, not proof that changing one field will produce a fixed lift on every platform. The negative FAQ schema and llms.txt figures do not show that either feature causes harm; they show that no measurable positive effect remained after authority was controlled in this sample.

    The more useful lesson is about sequencing. Schema appeared more powerful before authority was held constant because brands that invest in technical optimization often have stronger authority signals too. If your page still leaves its audience or use case implicit, technical polish is unlikely to be the constraint holding it back.

    Cross the clarity threshold before adding more structure

    Scattered translucent shapes merge into one clear object before passing through a glowing gateway toward neatly organized blocks.

    Clarity is not the same as short copy. A clear page gives a model enough explicit information to connect an offering to a person, problem, location, and buying situation without having to infer the missing pieces.

    On the specific ten-point rubric used in the commercial-prompt analysis, brands scoring 5 to 6 averaged an 11.2% recommendation rate. Brands scoring 7 to 8 averaged 23.6%, while those scoring 9 to 10 averaged 24.8%. The large change occurred when sites moved from partially clear to explicitly clear; the difference between clear and comprehensive was much smaller.

    A score of 7 is not an industry standard or a guarantee. It is a useful diagnostic line from this dataset. Below it, missing fit information can prevent a brand from entering the serious consideration set. Above it, suitability and authority have more room to decide which clear option gets recommended.

    Audit each commercially important page against four questions:

    • Offering: Can a reader identify exactly what is being sold from the opening copy, without decoding a slogan?
    • Fit: Does the page explicitly name the customer types, use cases, and situations for which the offer is appropriate?
    • Specifics and proof: Does it provide available details about the process, pricing approach, service area, results, awards, or relevant customer examples?
    • Organization: Can someone scan headings, bullets, and genuine comparison tables to find those answers quickly?

    The common failure is a page that names the service but makes the reader infer suitability from logos or broad language such as “businesses of all sizes.” Replace that implication with a direct statement. A useful opening pattern is: “[Offering] is a [category] for [customer type] that needs [use case or outcome] in [relevant situation].” The brackets are prompts for substance, not a sentence to copy mechanically.

    Give each material offering its own page. Add a fit section that says who should consider it and which conditions change the recommendation. Explain how it differs from adjacent options. Publish concrete facts you can support, including a pricing approach when exact prices cannot be public. This work improves both human evaluation and machine interpretation because it removes the need to guess.

    Make your facts consistent, then build the right authority

    Several abstract information sources send matching light pulses to a central sphere supported by an illuminated framework, while one conflicting pulse fades away.

    Consistency is more than spelling the company name the same way. It means that your offer names, audience, locations, pricing model, capabilities, and proof do not change as someone moves between your website and independent references.

    That matters because cross-source consistency retained a +9.4-point association with recommendation rate after authority was controlled. A model can work with a qualified claim repeated accurately across several places. It has a harder decision when the homepage, product page, directory profile, and review coverage describe materially different businesses.

    Create a canonical fact ledger before asking teams to update pages independently. It should contain:

    • The official brand name and a plain description of the business.
    • The canonical name and definition of every material offering.
    • The audience, use cases, and suitability conditions for each offer.
    • Locations or service areas, where relevant.
    • The pricing approach and any public qualification criteria.
    • Approved proof points, including the exact scope and date behind each result.
    • Awards, credentials, and other claims that can be independently verified.

    Compare that ledger with your homepage, product and service pages, location pages, directory entries, review profiles, and independent coverage. Correct owned pages first. Then request corrections where third-party information is outdated. Prioritize contradictions that change eligibility or fit, such as an old service area, a discontinued product name, or a claim that applies to one offer but appears to describe the whole company.

    Authority is not interchangeable with structured data. The unadjusted difference associated with any schema was +3.7 points, but it fell to +0.4 after list mentions, reviews, awards, and related authority signals were controlled. That does not assign a causal value to any one authority tactic. It does show why adding markup to an under-recognized brand should not be mistaken for building recognition.

    The most useful form of third-party evidence also depends on the buying market. In consumer categories, expert reviews outweighed customer reviews by 15 to 1 in AI search, while B2B software showed the reverse pattern. Treat that result as directional rather than a rule for every niche, but do not copy one review strategy across both markets.

    • For a consumer category, identify the credible expert reviewers and category comparisons that buyers already use. Make your product facts easy to verify, and correct inaccurate coverage where possible.
    • For B2B software, prioritize authentic, specific customer-review evidence in the places buyers consult. Generic praise is less useful than a review that identifies the customer situation and the product’s role.
    • For either market, keep externally promoted claims aligned with the canonical facts on your site. More mentions will not solve a contradiction that makes the offer harder to classify.

    Use schema to transmit facts, not invent importance

    Schema has a real job: it labels entities and properties in machine-readable form. That job is valuable, but it is different from earning a recommendation. The safest implementation rule is simple: structured data should faithfully represent useful facts that a visitor can already verify on the page.

    Product schema deserves separate treatment for ecommerce. Among the 214 ecommerce brands in the sample, it retained a +4.8-point association after authority control. That is the only measured markup type with a meaningful adjusted difference in the available data. It still does not prove a guaranteed lift, but it gives ecommerce teams a stronger reason to prioritize accurate Product markup than a service business has to deploy several marginal schema types.

    Use this implementation order:

    1. Fix the visible offer, fit, and proof on the page.
    2. Select a schema type that corresponds to the entity actually described, such as Organization or Product.
    3. Make names, descriptions, and other claims match the visible content and your canonical fact ledger.
    4. For ecommerce, prioritize accurate Product markup before adding loosely relevant schema types merely to increase the count.
    5. Add FAQ content only when it answers questions that help a buyer decide. Treat FAQ schema as encoding for that content, not as an independent visibility lever.
    6. Validate the markup and review it whenever the visible facts change.

    Apply the same discipline to llms.txt. Its adjusted difference was -0.1 points in the measured sample, which is effectively no demonstrated lift there. You may still test it as a low-cost machine-accessibility experiment, but it should not displace work on unclear pages, conflicting facts, or missing authority.

    Comparison tables sit between content and structure. Their adjusted association was a modest +1.9 points. Use one when a buyer genuinely needs to compare audiences, use cases, features, or alternatives. A table that exposes meaningful differences can improve clarity; a table built only to look optimized adds no new information.

    Key takeaways: choose your next optimization ticket

    • Fix explicit fit first. Every important offer should state what it is, who it serves, when it is suitable, and what evidence supports it.
    • Reconcile facts across the web. Maintain one canonical ledger and use it to correct high-impact contradictions on owned pages and third-party profiles.
    • Build market-appropriate authority. Consumer categories may lean more heavily on expert reviews, while B2B software may depend more on customer-review evidence.
    • Make schema accurate and proportionate. Product schema has the strongest measured case for ecommerce; Organization schema, FAQ schema, and llms.txt should not outrank clarity work.
    • Measure recommendations, not implementation volume. Use a fixed set of commercial prompts across the platforms that matter, record whether your brand is named and for which use case, then inspect the pages and evidence supporting each result.

    Start with the highest-value product or service page, not a sitewide markup rollout. Make one offer fully explicit, reconcile its facts, align its external evidence, and then encode it accurately. Once that page can answer what, who, when, where, and why without inference, you have a useful model for the rest of the site.

    References