Author: shivamcrushpressai

  • Google Ads AI Max Reporting and Direct Offers: A Control Plan

    Google Ads AI Max Reporting and Direct Offers: A Control Plan

    When Google Ads makes automation easier to deploy, your reporting has to get stricter. AI Max can expand targeting and apply brand or location-related controls, while Direct Offers can put a context-selected incentive in front of a shopper inside AI Mode. Those capabilities can help, but they also blend media optimization with commercial policy.

    Your job is to answer two separate questions: what was the automation allowed to do, and did it create profitable demand that would not otherwise have existed? A campaign can improve on an in-platform metric while quietly reaching a different audience, relaxing a targeting boundary, or discounting orders you could have won at full price. The control plan below is designed to expose those differences before you scale them.

    Start with permission reporting, not performance reporting

    Google Ads is adding AI Max reporting columns for Locations of interest, Optimized targeting and Brand inclusions. Add them to the campaign-level view before investigating a performance change. They tell you which controls are present, which is the first layer of any useful audit.

    Think of these fields as permission reporting. They describe what a campaign is configured to use; they do not prove that a setting caused an outcome. A conversion increase beside an enabled setting is a lead for investigation, not a causal conclusion.

    Reporting columnWhat it makes visibleWhat you should check
    Locations of interestWhich campaigns use location-of-interest settingsWhether campaigns being compared use the same geographic-intent configuration
    Optimized targetingWhere automated audience expansion is enabledWhether broader reach is intentional and whether it coincides with a change in traffic quality
    Brand inclusionsWhere brand inclusion settings are appliedWhether each campaign has the brand scope your strategy requires

    The columns are still rolling out and may not be visible in every account. If you cannot find one, do not treat its absence from the interface as evidence that the underlying behavior is disabled. Confirm the campaign settings directly until the reporting fields reach your account.

    Once the columns are available, build a repeatable campaign view:

    1. Add all three AI Max columns to the same view as the outcome metrics your team actually uses.
    2. Keep campaign identity, status and commercial objective visible so campaigns with different jobs are not compared as if they were interchangeable.
    3. Save a dated export or configuration record. That gives you a snapshot of the permissions in place when results were measured.
    4. Flag unexpected combinations, such as an expansion setting enabled on one campaign but not on otherwise comparable campaigns.
    5. Resolve configuration mistakes before interpreting performance. Analysis built on unintended settings only explains the wrong experiment more precisely.

    This view should let you scan from configuration to outcome in one row. If an analyst has to open every campaign individually to discover the relevant settings, setup differences are too easy to miss and too slow to audit.

    Compare configuration cohorts before explaining a performance gap
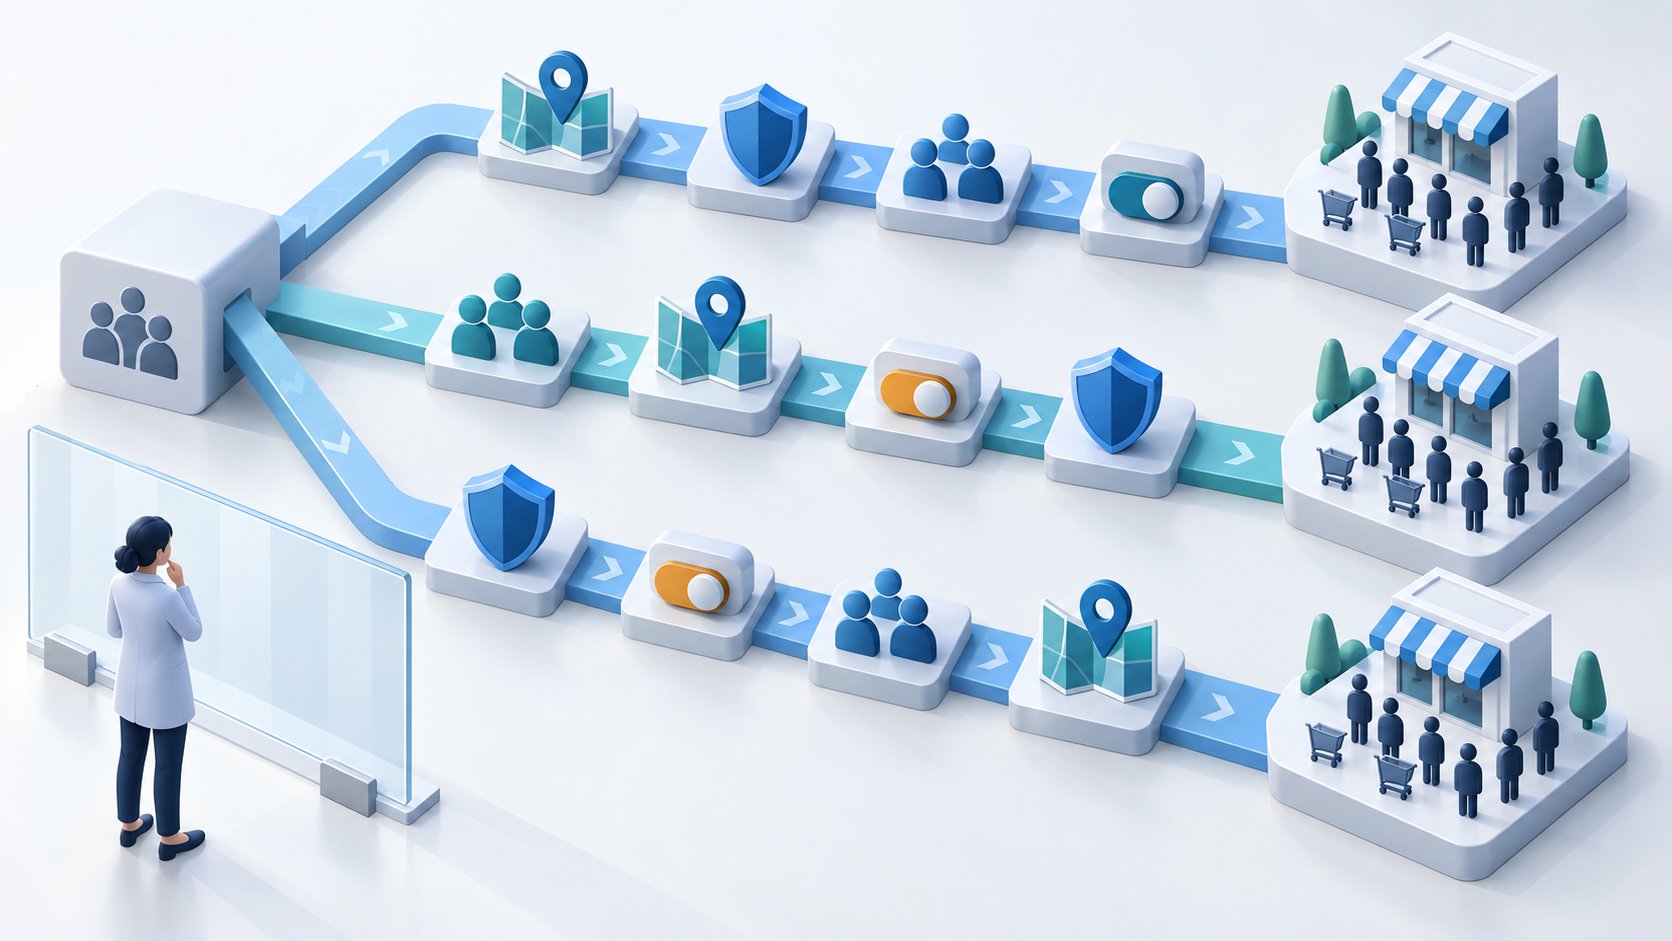
    Three parallel campaign pathways pass through different permission controls before reaching comparable shopper groups.

    Campaign averages become misleading when they combine different automation permissions. Create configuration cohorts instead. One cohort might contain campaigns with Optimized targeting enabled; another might contain campaigns without it. You can then subdivide them by Locations of interest and Brand inclusions when those distinctions matter to the question.

    Do not automatically call one cohort a control group. A credible comparison also needs a similar commercial objective, market, offer, audience opportunity and measurement setup. A branded campaign and a prospecting campaign remain different even if their three AI Max columns match exactly.

    Use this sequence when a campaign begins outperforming or underperforming its peers:

    1. Define the business symptom. State whether the issue is lead quality, sales volume, acquisition cost, conversion value or profit. Avoid the vague diagnosis that performance changed.
    2. Map the permission state. Record the values of Locations of interest, Optimized targeting and Brand inclusions for the affected campaign and its intended comparators.
    3. Separate mismatched campaigns. Compare like configurations first. If the difference disappears, the blended average was hiding a setup distinction.
    4. Check timing. Place the first visible performance change beside the dated configuration record and other campaign changes. A setting that was already stable before the change is a weaker explanation than one altered at the same time.
    5. Change one decision at a time where practical. If targeting, bidding, creative and promotion all change together, you may improve the result but lose the ability to explain why.
    6. Write down the interpretation. Record the setting, expected mechanism, primary metric and condition that would disprove your explanation.

    The last step is important. A statement such as “Optimized targeting improved the campaign” is too broad to test. A useful interpretation is narrower: enabling expansion was followed by more qualified conversions in comparable campaigns while cost and downstream quality stayed within the team’s accepted limits. That claim can be monitored and challenged.

    Also look for configuration drift. Two campaigns that were launched from the same template can stop being comparable after later edits. The new columns make that drift easier to spot, but only if somebody owns the exception review. Assign that check to a named role and run it on the same cadence as your normal campaign review.

    Build Direct Offers as governed promotions

    Direct Offers add a second kind of automation: Google can decide not only when an offer is relevant, but also which incentive to present. The beta-labeled asset can be created at the account or campaign level, and it is limited to campaigns using AI Max or text customization.

    The setup asks for an internal offer name, final URL and short description. Google AI uses the description to judge relevance and can generate the customer-facing offer text. If you provide multiple incentives, the system can select among them using the shopper’s behavior and context. That makes the description and incentive set part of your targeting logic, not just administrative copy.

    Start with a campaign-level pilot unless you have a clear reason to expose the offer across the account. A campaign-level asset narrows the commercial blast radius and makes it easier to connect claims and redemptions to a defined test population.

    Use the following launch checklist:

    • Name the offer for analysis. Include the campaign or product scope, incentive and intended run period in the internal name. Someone reviewing an export later should not have to decode Offer 1.
    • Send traffic to the exact destination. The final URL should land where the promoted product, service or eligibility conditions can be understood and the incentive can actually be redeemed.
    • Write the description as an AI instruction. State what is being offered and the context in which it is relevant. Do not rely on clever promotional language to carry eligibility rules.
    • Begin with one incentive. Multiple incentives are supported, but allowing AI to choose among them immediately makes the first result harder to interpret. Establish a baseline before testing an incentive set.
    • Use a dedicated code batch. Single-use promotional codes can be uploaded by CSV. Keep the pilot’s codes separate so a redemption can be reconciled to the offer rather than mixed with codes from email, affiliates or customer support.
    • Set the contractual boundaries. Add the applicable terms and conditions, terms URL, start date and end date. Make sure the landing page and checkout enforce the same promise the shopper sees.
    • Cap the exposure. Direct Offers support daily limits based on total offer value or number of claims. Select the type that controls your real constraint, then set it before activation.

    A claim-count limit is useful when code inventory or fulfillment capacity is scarce. A total-value limit gives you a closer control on financial exposure, especially when incentives have different values. Neither replaces a complete promotional budget because a claim is not necessarily a redemption and a redemption is not necessarily an incremental sale.

    The shopper can see an eligible promotion beneath a sponsored result in AI Mode as a Claim one-time code option. Opening it reveals the offer details and code, along with a button to visit the advertiser’s website. Review the entire handoff from that promise to the landing page and checkout. If the displayed terms and the site experience disagree, pause the offer rather than asking support staff to repair the mismatch after purchase.

    Promotional terms can also create financial and legal exposure. If eligibility, expiry, exclusions or consumer rights require formal review in your market, put the Direct Offer through the same legal and operational approval process as any other public promotion. AI-selected delivery does not make the underlying promise less binding.

    Measure discount economics beyond claims and conversions
    A promotional tag, shopping basket, cost layers, approval gate, and branching purchase paths form a visual model of discount economics.

    A Direct Offer has at least six commercially distinct events: the offer is shown, its details are opened, a code is claimed, the shopper reaches the site, the code is redeemed and an order is completed. Do not collapse that chain into a single conversion number. Each transition answers a different question.

    DecisionMeasurementWhat a problem can mean
    Is the offer attracting attention?Claims or detail opens relative to observable offer exposureThe incentive, relevance decision or presentation is not compelling enough to prompt action
    Can shoppers use it?Redeemed codes relative to claimed codesThe site journey, eligibility rules, expiry or checkout process is creating friction
    Does it produce completed business?Completed orders and revenue tied to redeemed codesClaims are not progressing to purchases, or order tracking is incomplete
    Is the promotion affordable?Realized discount cost and contribution after the discountAdditional sales may still be eroding margin
    Is the result incremental?Difference versus a credible unoffered comparisonThe offer may be subsidizing orders that would have occurred at full price

    Use the denominator you can actually observe, and label it precisely. Claims divided by offer views is not the same metric as claims divided by sponsored-result impressions. If a required exposure event is not available in your account, report the narrower metric rather than manufacturing a rate from incompatible events.

    Reconcile the advertising record with your commerce or lead system. The promotional code is the bridge: it lets you distinguish a code that was claimed from one that was redeemed, and a redemption from an order that remained valid after returns, cancellations or lead qualification. Do not assume the Google Ads interface contains every downstream business outcome you need.

    Track the realized discount separately from media spend. A promotion can improve conversion efficiency inside an ad platform while the associated margin reduction appears only in the order system. Your decision table should therefore place ad cost, discount cost and contribution in the same review, even if the data originates in different systems.

    Redemption alone cannot establish incrementality. Some shoppers who use a code would have purchased without one. The cleanest test is a randomized unoffered group when your setup supports it. If it does not, use the closest comparable campaign or audience cohort you can maintain, keep other meaningful changes stable and document the limitations. A simple before-and-after comparison is weaker because seasonality, demand shifts and other campaign edits can move at the same time.

    Set decision rules before the pilot starts:

    • The maximum daily offer value or claim count you will permit.
    • The minimum contribution the promoted orders must retain.
    • The comparison you will use to judge incremental orders or leads.
    • The code redemption and completed-order events that must reconcile.
    • The conditions that trigger a pause, such as exhausted code inventory, a checkout failure, incorrect terms or unacceptable margin.
    • The evidence required before you add more incentives or move from campaign-level to account-level deployment.

    Read the failure pattern, not just the final total. Many claims with few redemptions points toward a broken or confusing handoff. Many redemptions without incremental growth points toward cannibalization. Few claims followed by strong purchase quality may indicate narrow relevance or limited exposure; it does not automatically justify a larger discount. Each pattern calls for a different response.

    Key takeaways

    • The new AI Max columns expose campaign permissions; they do not prove why performance changed.
    • Compare campaigns in configuration cohorts before attributing a result to Locations of interest, Optimized targeting or Brand inclusions.
    • Start a Direct Offer at campaign level with one incentive when you need a test that is easier to interpret and contain.
    • Treat the offer description as an input to AI relevance and generated copy, not as a private note.
    • Use claim limits for operational scarcity and value limits for financial exposure, then track the full promotional budget outside the asset.
    • Judge success through redemptions, completed outcomes, realized discount cost, contribution and incrementality – not claim volume alone.

    When the new columns appear in your account, export the current permission state before changing anything. Then choose one eligible campaign, document its baseline, connect a dedicated code batch to completed-order data and launch only with a hard exposure limit. That gives Google room to optimize while preserving your ability to explain what happened and decide whether it deserves to scale.

    References


  • AI Search Investment: Attribution Across the Buyer Journey

    AI Search Investment: Attribution Across the Buyer Journey

    You have enough evidence to test AI search, but probably not enough to promise a clean last-click return. A recommendation may create the shortlist while Google, YouTube, a retailer, or a direct visit records the next step.

    The decision is not whether AI deserves a blind budget. It is how much to invest, which customer handoff you expect to improve, and what evidence will unlock the next tranche. Set those conditions before the work begins, and attribution becomes a decision system instead of an argument at the end of the quarter.

    AI search influences a journey; it rarely owns the whole journey

    An AI answer can introduce a brand, narrow a longlist, explain a product, or reduce perceived risk. It may produce a click, but it does not have to. The person could remember the name, search for it later, watch a demonstration, compare alternatives, and then convert through a different channel.

    A last-click report will credit the final visit. A first-touch model may over-credit the initial discovery. A screenshot showing that an AI system cited your page proves exposure, but not commercial intent. None of these views is useless; each answers a different question.

    Cross-platform behavior is already visible outside AI search. In a survey of 511 beauty consumers, whose average age was 47, 43% named Google as their first stop, while Instagram accounted for 11.9%, YouTube 11.2%, TikTok 10.6%, and AI tools 9.8%. When respondents discovered a beauty product on TikTok, 72% searched for it on Google and only 7% bought directly through TikTok at that moment. When TikTok or YouTube did not provide the answer, 61% fell back to Google.

    Those percentages belong to one consumer survey in one category. Do not paste them into a B2B forecast or treat them as universal market shares. Use the behavior they expose: discovery, validation, evaluation, and transaction can happen on different platforms, even within one purchase.

    • Discovery answers: What is this, and which options should enter my consideration set?
    • Validation answers: Is this claim credible, safe, relevant, and supported by enough detail?
    • Evaluation answers: How does this option compare with alternatives for my situation?
    • Transaction answers: What does it cost, what happens next, and where can I buy, subscribe, or speak to someone?

    Your investment case should name the journey job you expect AI search to perform. If the objective is discovery, evaluate qualified visibility and subsequent demand. If it is evaluation, inspect whether comparison and proof content move people toward a commercial action. If it is transaction, require stronger evidence from referrals, leads, pipeline, or revenue.

    Map the handoffs before you decide what to fund

    Small figures pass a glowing signal between an AI orb, a search panel, a video display, a storefront, and a purchase pedestal connected by branching paths.

    Begin with the questions that matter to the business, not a list of AI platforms. A useful journey map can live in one worksheet, provided every row connects a customer question to an intended next step.

    1. Choose a commercially important topic cluster. Include problem questions, option questions, trust questions, comparisons, and action-oriented queries such as pricing, availability, buying, or booking.
    2. Record where customers are likely to ask each question: an AI assistant, Google, social search, YouTube, a marketplace, a review site, or your own website. Validate this with analytics, customer interviews, sales-call notes, and on-site search data where available.
    3. Write down the job of each touchpoint. One may create awareness, another may provide proof, and another may capture the transaction.
    4. Name the destination that should receive the next visit. It might be an evidence page, comparison, product page, calculator, store locator, pricing page, or lead form.
    5. Define one observable signal for the handoff and one likely failure mode. A referral session is observable; a remembered brand mention may not be. A citation to an irrelevant page is visibility with a broken destination.

    Format should follow the job. In the beauty survey, TikTok searches were most often based on a product name, a skin or hair concern, a brand name, or a full question; only 7% searched by ingredient. YouTube creators also received a higher “very trustworthy” rating than TikTok creators, 14.1% versus 8.6%. That does not establish a universal hierarchy of platforms. It shows why the same buyer may use a short demonstration for discovery, a longer video for reassurance, and a detailed page for ingredient or product validation.

    For every important query family, keep these fields together:

    • Customer question and journey stage
    • Platform or surface where the question is asked
    • Brand answer, content asset, or proof required
    • Page or property that should receive the next visit
    • Expected customer action
    • Observable analytics or CRM signal
    • Owner responsible for repairing the handoff

    Then test the relay manually. Can someone move from an AI recommendation to the exact evidence needed to validate it? Does the cited or discovered page match the question? Is the brand, product, author, and organization information consistent across the relevant properties? Does the destination offer a sensible next action?

    Structured data can help machines interpret entities and page content when the markup truthfully represents what a visitor can see. It is not a guarantee of an AI citation or recommendation. Fund schema implementation as part of a clear content and entity system, not as a substitute for useful evidence.

    Use an attribution ladder instead of forcing one perfect number

    The strongest measurement system separates what you observed from what you inferred. A practical architecture combines GA4, a five-level attribution ladder, and a board-ready scorecard. Each level supports a different decision, and no level should be presented as stronger evidence than it is.

    Evidence levelWhat to measureWhat it can supportWhat it cannot prove
    1. VisibilityPresence, mentions, citations, linked citations, and answer accuracy across a defined prompt setWhether the brand is eligible and visible for the questions you choseThat anyone visited, considered, or bought
    2. Referred demandSessions, landing pages, and clicks from identifiable AI referrers when referral data survivesThat a measurable AI surface sent a visitInfluence that resulted in a later direct or search visit
    3. On-site intentCommercial page views and key events such as account creation, a pricing action, a tool completion, a store-locator use, or a qualified form submissionWhether referred visitors performed meaningful actionsClosed revenue or causality
    4. Commercial outcomesQualified leads, opportunities, purchases, revenue, and repeat value connected to observable journeys or declared influenceHow much measurable business value is associated with the programAll invisible assists or the value that would have occurred anyway
    5. Incremental effectPredefined holdouts, staggered rollouts, or credible comparisons between exposed and unexposed topics, markets, or periodsWhether the intervention probably created additional valuePerfect certainty when other variables changed at the same time

    Configure analytics so the ladder remains auditable. Preserve the original source, medium, landing page, and campaign fields. You can create a reporting group for known AI referrers, but keep the underlying values because referrer hosts and product behavior can change. Use UTM parameters on links you control; do not pretend you can add them to third-party citations you do not control.

    Mark key events that reflect actual business progress rather than convenient activity. A page view is not equivalent to a qualified enquiry. If your buying cycle continues offline, connect consent-appropriate analytics and CRM records so you can distinguish a submitted lead from an accepted opportunity and a closed sale.

    Add declared influence as a separate evidence stream. A “How did you hear about us?” field can include AI assistants or AI search, plus a free-text option. Sales teams can record unsolicited mentions during qualification. These responses are useful precisely because referral data can disappear, but self-reported memory is imperfect. Label it as declared influence and never overwrite observed acquisition with it.

    Use explicit confidence labels in reporting:

    • Observed: a visible referral, event, or transaction was recorded directly.
    • Connected: analytics and CRM identifiers linked the visit to a later commercial stage.
    • Declared: the customer named an AI system or answer as an influence.
    • Inferred: changes in visibility and demand moved together, but the individual journey was not connected.
    • Incremental: a predefined comparison provides evidence that the program caused additional results.

    Keep attributed revenue and influenced revenue in separate columns. The same opportunity may appear in both, so adding them can double-count the deal. Your board scorecard should show investment, coverage of priority questions, visibility, referred demand, commercial actions, qualified pipeline, revenue, confidence level, and the next decision. Include a baseline and a target; a growing cumulative total without either is difficult to interpret.

    Visibility tracking also needs controls. Use a stable set of commercially relevant prompts, record the model or surface, market, language, date, and test conditions, and repeat the process consistently. A single generated answer is an observation, not a durable ranking.

    Release the budget through gates, not a long leap of faith

    Metallic tokens move through a sequence of transparent gates beside visual evidence objects, with additional tokens waiting at each stage.

    GEO and AEO pricing spans radically different scopes. A vendor-compiled dataset covering 1,146 quotes from 214 agencies between July 6 and October 2, 2026 put the median monthly retainer at $6,850. Its reported tier medians ranged from $2,950 for Starter work to $7,400 for Growth, $14,600 for Advanced, and $31,500 for Enterprise. Sixty-eight percent of agencies primarily used a custom or tiered monthly retainer.

    Treat those figures as directional negotiating context, not a universal price sheet. The dataset was assembled and published by an agency, and proposals differ by market coverage, senior staffing, digital PR, technical work, content volume, and commitment length. Its $6,850 GEO/AEO median was 45% above the $4,740 traditional SEO median, so a buyer should require a clear explanation of what the premium adds.

    Before signing, ask the provider or internal program owner to specify:

    • The countries, languages, products, audiences, and query families included
    • The baseline that will be captured before optimization begins
    • How mentions, citations, linked citations, accuracy, traffic, leads, and revenue are defined
    • Which technical, schema, content, analytics, authority-building, and digital PR activities are included
    • Who owns the accounts, prompt sets, dashboards, content, structured data, and historical exports
    • What constitutes a qualified lead or opportunity
    • How duplicated, declared, and inferred revenue will be handled
    • The minimum term, review points, exit conditions, and work that remains usable after termination

    A three-stage, 90-day pilot can create decision evidence without pretending that every buying cycle will produce revenue in 90 days.

    1. Days 1-30: establish the prompt, visibility, traffic, conversion, and pipeline baselines. Repair analytics and CRM gaps. Map one or two high-value customer journeys and identify their weakest handoffs.
    2. Days 31-60: improve a deliberately limited set of pages and supporting assets. Correct factual ambiguity, strengthen evidence, connect related entities, implement accurate structured data where appropriate, and make the next action unmistakable.
    3. Days 61-90: repeat the visibility tests under consistent conditions, inspect referral and declared-influence data, review commercial events and pipeline, and classify the result as scale, repair, continue observing, or stop.

    Negotiate this review even when the commercial agreement runs longer. A six- or twelve-month commitment without definitions, data ownership, and intermediate decision gates creates avoidable financial exposure.

    Use the pattern of results to decide what happens next. If priority visibility and qualified commercial signals both improve, expand carefully. If visibility improves but the next step does not, repair the handoff or destination. If referred visits rise but meaningful actions do not, investigate intent mismatch, page experience, offer clarity, and conversion friction. If a provider ships deliverables but cannot show movement at any agreed evidence level, do not renew solely on citation screenshots.

    Key takeaways

    • Budget AI search for a defined journey job: discovery, validation, evaluation, or transaction.
    • Map the handoff between platforms before producing more content. A visible answer with no relevant destination is an incomplete investment.
    • Report visibility, referred demand, on-site intent, commercial outcomes, and incrementality as separate evidence levels.
    • Keep attributed, declared, and inferred influence distinct so stakeholders can see both value and uncertainty.
    • Use market pricing as directional context, then tie your actual spend to scope, ownership, baselines, and pre-agreed decision gates.

    Start with one commercially important topic cluster this week. Map its discovery, validation, destination, and conversion steps; instrument the signals you can observe; and fund the smallest program capable of moving them. At the review point, let the evidence tell you whether to scale the work, repair the relay, or redirect the budget.

    References


  • Human Accountability in AI-Assisted Marketing Decisions

    Human Accountability in AI-Assisted Marketing Decisions

    An AI assistant has given your team a confident plan: publish more pages, change the message, and redirect resources toward the tactics it predicts will work. The output is polished enough to put into a deck. The hard question is whether anyone can explain why it fits your customers, constraints, and sales process – and who will answer for the result.

    Human accountability does not mean doing every marketing task manually. It means a qualified person owns the decision, verifies the supporting evidence, controls what gets released, and follows the outcome. That operating discipline lets you use AI for speed without quietly allowing it to become the decision-maker.

    Draw the line between AI assistance and decision authority

    AI can propose options, organize information, expose questions, transform approved material, and accelerate production. A person should retain authority over positioning, priorities, investment, customer promises, and the criteria used to judge success. Those decisions depend on context a generic model response may not contain. A recommendation can sound sensible while omitting something as basic as how customers buy.

    Use consequences, not content format, to decide how much oversight is required. A short tagline can be consequential if it changes the promise your brand makes. A long set of ad variations can be relatively contained if every option stays within an approved offer, audience, and call to action.

    • Execution support: AI formats approved information, groups data, creates variants, or produces a first-pass outline. The task owner checks accuracy and adherence to the brief.
    • Recommendation support: AI diagnoses a problem, ranks opportunities, or proposes a campaign change. A subject-matter owner inspects the evidence, assumptions, business fit, and test design before acting.
    • Consequential decisions: The work changes positioning, budget, material claims, customer experience, or a large part of the website. An experienced marketer explicitly approves, modifies, or rejects the recommendation.

    Accountability includes more than final approval. The human owner must define the problem, set the constraints, decide what evidence counts, and remain responsible after launch. If the only explanation for a choice is that AI recommended it, no accountable marketing decision has actually been made.

    Assign AI work only to people who can evaluate it

    Before assigning a task to AI, ask whether the designated reviewer could evaluate the result without the tool. They do not need to produce it at the same speed. They do need enough knowledge to detect a missing assumption, an unsupported claim, an unsuitable tactic, or a recommendation that conflicts with how the business operates. Access to a tool is not a substitute for understanding the work it performs.

    Consider a recommendation to increase website traffic. A competent reviewer will ask who currently visits, which visitors are relevant, what they do after arriving, and whether the offer is clear. More traffic will not repair a weak explanation, attract the right buyer automatically, or make an unclear next step easier to find.

    The same test applies when AI proposes a large SEO or GEO content program. The reviewer must be able to distinguish a genuine information gap from a request to produce more pages. If nobody can explain which audience needs each page, what decision it helps them make, and why existing content cannot do the job, the team is not ready to approve the plan.

    Give every AI assignment a review brief before prompting. At minimum, record:

    • The business problem the work is meant to solve.
    • The intended audience and the relevant stage of its buying journey.
    • The approved facts, offer, positioning, and operational constraints.
    • The outcome that would count as an improvement.
    • The claims, promises, or changes that are outside the assignment.
    • The person qualified to review and release the work.

    If you cannot name a qualified reviewer, narrow the assignment, obtain the missing expertise, or keep the work out of production. A more elaborate prompt does not repair a missing accountability structure.

    Put every AI recommendation through a human review gate

    Hands verify AI-assisted campaign materials against research before one item passes through a physical review gate.

    A consistent gate prevents fluent output from slipping directly into campaigns, content, or site changes. Use the following sequence for recommendations that affect performance, spend, public claims, or customer-facing experiences.

    1. Name the owner before reviewing the answer. Identify the person who can approve, modify, or reject the recommendation. The AI system is a contributor, not the owner.
    2. Restate the business problem. Write it without mentioning AI or the proposed tactic. There is an important difference between users not understanding a service and a perceived need to publish more content. The first is a problem; the second is only one possible response.
    3. Expose the missing context. Check the target customer, sales cycle, available budget, team capacity, current performance, brand position, and delivery constraints. A valid tactic can still be wrong for the organization expected to carry it out.
    4. Inspect the evidence. Ask AI to identify the basis for its recommendation and disclose important assumptions. Open the cited material and determine whether it supports the specific advice. A citation must be read and checked for relevance; the presence of a link is not proof.
    5. Check operational truth. Reject copy that promises something the business cannot deliver. Confirm product facts, audience fit, availability, approval requirements, and any regulated or contractual language with the appropriate human owner.
    6. Convert the recommendation into a bounded test. State the expected effect, the measurement, the review point, and the smallest reversible scope that can produce useful evidence. Do not make a site-wide change when a limited set of pages can test the same premise.
    7. Record the decision and follow-up. Note whether the recommendation was approved, modified, or rejected; why that choice was made; what changed; and who will review the result. This keeps later analysis from turning into guesswork.

    Timing must reflect the actual buying process. If a service typically takes six months to purchase, judging a campaign after several weeks only by closed sales would ignore how that business wins customers. Early evaluation should examine the relevant conversations and buying activity while preserving a defined point at which the investment will be reconsidered. Patience is not permission to spend indefinitely.

    A compact decision record

    The record can live beside the campaign brief, content ticket, or website change log. A short, specific entry in each field is more useful than a long narrative nobody will revisit.

    FieldWhat to record
    OwnerThe person accountable for approval and follow-up.
    Business problemThe customer or performance problem, stated independently of the proposed tactic.
    AI contributionWhat the system generated, analyzed, summarized, or recommended.
    Context and assumptionsThe audience, sales process, resources, constraints, and uncertain premises that affect the decision.
    Evidence checkedThe material a human opened and reviewed, plus any gaps that remain.
    DecisionApproved, modified, or rejected, with a concise reason.
    Test and measureThe change being tested, expected effect, metric, and bounded scope.
    Review pointWhen the result will be assessed and who will assess it.

    Match the control to the marketing assignment

    Three marketing assignments receive progressively stronger human oversight as their potential risk increases.

    Not every task needs the same process. The useful question is what the model can contribute safely and what judgment must remain with a person who understands the subject and the consequences.

    AssignmentUseful AI roleRequired human release check
    Ad and tagline variationsGenerate alternatives within an approved offer, audience, and action.Reject inaccurate claims, off-brand language, and promises the business cannot deliver.
    Expert or thought-leadership contentDevelop questions, organize an outline, expose gaps, or improve readability.A subject-matter reviewer owns the reasoning, factual accuracy, citations, usefulness, and voice.
    SEO or GEO content planningGroup themes, propose hypotheses, and identify possible information gaps.Confirm a real audience need, a distinct purpose for each page, and a connection to the business problem.
    JSON-LD and schema generationDraft markup from approved page information and a defined entity model.Confirm that every entity, relationship, and claim matches the visible content and the real business, then validate the markup before deployment.
    Positioning, priorities, and budgetOrganize evidence, surface assumptions, and compare scenarios.An experienced marketer makes and signs off on the decision after considering customer knowledge, resources, sales process, and consequences.

    Generation and approval should be separate acts even when the same person performs them. First ask the model for possibilities. Then review those possibilities against the brief and evidence. You do not owe an AI-generated option a place in the final work merely because it is fluent.

    Substantive content needs more than a readability pass. An editor can improve a sentence without knowing whether its conclusion is true, distinctive, or useful. Someone familiar with the subject must evaluate the substance and stand behind what is published.

    Search recommendations deserve the same discipline because a weak premise can create work across an entire site. When AI proposes more pages, require an intended reader, a missing question, a reason the existing site cannot answer it, and a useful next step. Investigate whether relevant visitors already lack a clear service explanation or path to contact before committing the team to a larger publishing schedule.

    For structured data, technical validity is only one part of approval. Perfectly formatted markup can still describe the wrong entity or repeat an unsupported claim. The accountable reviewer must check semantic truth as well as syntax. That is the difference between automating production and automating judgment.

    Key takeaways

    • Let AI generate, organize, and challenge ideas, but give a named person authority over consequential marketing decisions.
    • Do not assign AI work unless someone with relevant knowledge can evaluate its substance, not merely its tone or formatting.
    • Treat model confidence as presentation, not evidence. Check cited material, assumptions, and business fit yourself.
    • Test consequential recommendations within the smallest useful, reversible scope before applying them across campaigns or websites.
    • Keep a decision record that states the problem, owner, evidence, choice, change, measurement, and review point.
    • Judge performance against the real sales cycle and customer journey, not the speed with which AI produced its recommendation.

    For your next AI-assisted task, start before the prompt. Name the owner, write the business problem, define the release check, and decide how the result will be tested. Then let AI work inside those boundaries. If your team cannot fill in those fields, pause the assignment: the missing input is not another prompt but accountable human judgment.

    References


  • How to Choose an Enterprise eCommerce Development Partner

    How to Choose an Enterprise eCommerce Development Partner

    You are not choosing an agency to build a nicer storefront. You are choosing the team that will connect pricing, inventory, customer, product, order, payment, and fulfilment systems without turning your own staff into the missing systems integrator.

    That distinction makes the shortlist much easier to manage. Start with the systems and workflows that can break the programme, require evidence from comparable implementations, and evaluate the people who will actually do the work. Platform badges and impressive client logos come later.

    Start with the system most likely to break the programme

    The commerce platform is the visible part of an enterprise implementation, but it is rarely the only system of record. Your ERP may control prices, credit limits, inventory, invoices, and account terms. A PIM may own product attributes and media. An OMS may decide where an order is fulfilled. The storefront has to present a coherent customer experience while those systems exchange data reliably.

    Among seven leading providers assessed in 2026, five documented at least one specific ERP integration. ERP integration depth and B2B functionality were the clearest points of separation, even though most of the firms covered several major commerce platforms. If your programme is ERP-connected, match the agency to the ERP family and workflow before giving much weight to its general platform credentials.

    The distinction is practical. Atwix has documented connectors for industrial distribution systems including Prophet 21, Infor, Kodaris, and Expertek. Elogic Commerce has documented work involving SAP S/4HANA, Microsoft Dynamics 365, NetSuite, and Visma Business. Scandiweb shows considerable Adobe Commerce scale, but its documented position is stronger for high-volume platform delivery than for industrial B2B and ERP work. All three can be credible enterprise firms while fitting very different system landscapes.

    Draw the system map before you issue the RFP

    Create a one-page map covering every data flow that matters to launch. It does not need to be a finished architecture diagram. It does need to show enough detail to stop vendors from answering a precise integration problem with a generic capability claim.

    • Business object: products, inventory, prices, customer accounts, credit limits, quotes, orders, returns, shipments, invoices, and tax data.
    • System of record: the application allowed to create or change each object.
    • Direction: which system publishes the data and which systems consume it.
    • Timing: whether the workflow is synchronous, event-driven, scheduled, or manually triggered.
    • Failure behaviour: what the customer sees when a dependency is delayed or unavailable.
    • Operational owner: the team responsible for detecting, triaging, correcting, and replaying a failed transaction.
    • Launch dependency: whether the flow is mandatory for go-live or can be delivered later without creating duplicate work.

    Ask each agency to classify every flow as native platform functionality, configuration, an existing connector, new custom development, or a manual process. The dangerous answer is simply supported. It hides whether the capability already exists, requires modification, or has only appeared in a sales presentation.

    For a B2B programme, map workflows as well as systems. Company accounts, customer-specific catalogues and prices, approval chains, quote management, PunchOut, EDI, and credit terms can change the entire design. A team with strong direct-to-consumer experience does not automatically have the data model or operational knowledge to implement them.

    Score fit instead of counting logos and partner badges

    Platform partnerships matter, but they stop differentiating firms once every serious candidate has them. In one Adobe Commerce field, five of the six qualifying agencies held Gold Solution Partner status. The stronger distinctions were contribution history, review volume, integration evidence, and relevant B2B case work.

    If you need a neutral starting structure, a 100-point provider model distributes attention as follows. The weights are not universal requirements. They are a prompt to make your own priorities explicit before a persuasive pitch changes them.

    CriterionStarting weightEvidence worth requesting
    Platform expertise20%Credentials, contribution history, upgrade experience, and work on the edition and architecture you will use
    ERP integration17%Comparable production integrations, data-flow designs, failure handling, and references involving your ERP family
    Recognition and delivery evidence15%Named implementations, quantified outcomes, verified reviews, and clearly defined agency scope
    Migration and replatforming12%Source-to-target migrations, data reconciliation, cutover planning, rollback design, and post-launch validation
    B2B feature depth10%Working examples of company accounts, negotiated pricing, approvals, quotes, PunchOut, EDI, and portals
    Custom development and proprietary IP10%Architecture, maintenance obligations, portability, licensing terms, documentation, and exit options
    Enterprise scale and complexity8%Comparable traffic, catalogue, order, brand, market, language, currency, and organisational complexity
    Ongoing management and support8%Service levels, coverage hours, escalation paths, named roles, release management, and incident reporting

    Change the model once, before reviewing proposals. If an integration, B2B workflow, security requirement, region, or support window is mandatory, make it a pass-or-fail gate rather than one more weighted row. A vendor should not be able to compensate for missing a launch-critical capability by scoring highly on design, awards, or presentation quality.

    For the remaining criteria, label the evidence consistently:

    • Unproven: no relevant evidence was supplied.
    • Claimed: the proposal asserts the capability but gives no named implementation or artefact.
    • Proven: a production example, client reference, or inspectable deliverable supports the claim.
    • Matched: the evidence involves a similar business model, platform, integration family, scale, and delivery responsibility.

    This prevents unlike signals from being treated as interchangeable. Atwix’s sustained position as the leading Magento Open Source contributor from 2018 through 2025 signals unusual codebase familiarity. Scandiweb’s 894 or more Adobe certifications signal broad organisational coverage. Elogic Commerce’s 5.0 rating across 64 verified Clutch reviews signals consistency across a substantial review set. Each is useful, but none proves that the proposed delivery team has implemented your combination of workflows and systems.

    Review averages need their denominator for the same reason. Within the Adobe Commerce field, a 5.0 rating across 64 verified reviews carried more evidence than the same rating across 15. Read the recurring strengths and criticisms, then test them during discovery. A high company-wide score cannot tell you whether the architect assigned to your account communicates clearly or whether the proposed onboarding process fits your team.

    Verify current certifications, partner status, and named personnel directly during procurement. These details can change, and an agency-level credential may belong to someone who will not work on your programme.

    Make every finalist prove the hard parts before selection

    A client and agency team test a prototype order flow linking product, pricing, payment, inventory, fulfilment, and delivery modules.

    A conventional RFP makes it easy to return polished answers. A better process asks each finalist for the same compact proof package. You can then compare the substance without rewarding the agency with the largest proposal team.

    • A closest-match implementation: require the platform, ERP or PIM, business model, agency scope, launch status, and client reference. A famous retailer on an unrelated stack is not a match.
    • An interface design: select one critical flow and request the objects, endpoints, direction, authentication, validation, expected timing, retry logic, monitoring, reconciliation, and ownership model.
    • A B2B workflow demonstration: use your real sequence from sign-in through price resolution, approval, order submission, and ERP acknowledgement. Slides are not a substitute for a working example or detailed walkthrough.
    • A migration approach: ask how the team profiles legacy data, maps identifiers, handles transformations, rehearses cutover, reconciles records, freezes changes, and decides whether to roll back.
    • Non-functional evidence: require the method used to establish performance, security, availability, accessibility, privacy, and operational acceptance criteria.
    • The proposed team: obtain names or role profiles, allocation assumptions, location, time-zone overlap, relevant credentials, and responsibility for architecture, engineering, quality assurance, delivery, and support.
    • The support model: request severity definitions, response and restoration commitments, coverage hours, escalation paths, monitoring responsibility, maintenance boundaries, and reporting cadence.

    Replace broad questions such as Have you integrated SAP? with scenarios that reveal how the team thinks:

    • A contract price changes in the ERP while a buyer has the product in a saved cart. Walk us through propagation, cache invalidation, display, checkout validation, and audit history.
    • The storefront accepts an order, but the ERP rejects it because the account is on credit hold. What state does each system enter, what does the customer see, and who resolves it?
    • A product update contains an invalid attribute. Show how it is quarantined, reported, corrected, and replayed without blocking valid updates.
    • The ERP is temporarily unavailable during checkout. Explain which functions degrade, which transactions queue, how duplicates are prevented, and how recovery is verified.
    • A platform upgrade changes an API used by custom middleware. Who detects the change, owns regression testing, and approves the production release?

    Good answers name states, decisions, and owners. Weak answers jump immediately to a product name or promise real-time integration without defining acceptable delay, error recovery, or reconciliation.

    Interrogate outcomes instead of borrowing them

    Quantified case work is useful because it gives you something concrete to examine. Atwix reports that PowerPak launched in three months and recorded 230% revenue growth in the first year. Elogic Commerce reports that Armacell achieved five-times-faster order approvals and that PetHQ generated $1.1 million in new B2B revenue after a launch completed in 2.5 months. Those results do not forecast your outcome. They are vendor-attributed examples that should trigger better questions.

    • What was the baseline and measurement window?
    • Which systems, markets, channels, and workflows were included?
    • Which parts did the agency own, and which were delivered by the client or another integrator?
    • What else changed during the period, including assortment, pricing, media, sales coverage, or operations?
    • Which reusable components shortened delivery, and what custom work was still required?
    • What failed, changed scope, or took longer than expected?

    A case study becomes decision evidence only when you understand the mechanism behind the result. Revenue growth alone cannot tell you whether the integration was stable, whether adoption required manual work, or whether the implementation is economical to maintain.

    Use discovery and the contract to test life after launch

    Client and agency teams plan responsibilities at a table that leads into a shared post-launch commerce operations workspace.

    Run paid discovery as a delivery audition

    A proposal tests sales and solutioning. A bounded discovery engagement tests how the actual team asks questions, resolves disagreement, records decisions, and exposes uncertainty. This matters most when legacy data, undocumented integrations, or cross-department ownership make a fixed estimate unreliable.

    Define the discovery outputs in the statement of work. At minimum, require:

    • A validated current-state system and ownership map.
    • A target architecture with material alternatives and decision records.
    • An inventory of interfaces, data objects, dependencies, and failure modes.
    • A representative data profile or migration sample, including reconciliation rules.
    • A workflow catalogue with standard, configured, custom, and deferred capabilities identified.
    • A delivery plan that names assumptions, client dependencies, decision deadlines, environments, testing stages, and release gates.
    • A risk register with owners and proposed mitigations.
    • A staffing plan showing the proposed delivery roles and expected allocation.
    • A support and knowledge-transfer plan rather than a placeholder for later negotiation.

    Do not judge discovery by the number of slides. Judge whether another qualified team could understand the proposed system, the unresolved choices, and the basis of the estimate. Make the required file formats, documentation handover, and ownership or licence rights explicit. Proprietary accelerators may be valuable, but you need to know what happens if the partnership ends or the component is discontinued.

    Have procurement or legal counsel review intellectual-property, data-processing, termination, transition-assistance, and liability language. A technical assumption can become an expensive contractual gap when neither party is clearly responsible for a failed interface or an unsupported component.

    Contract the operating model, not only the build

    The launch date is a transition between delivery modes, not the end of the programme. Put the post-launch model into the agreement while the implementation is still being negotiated.

    • Acceptance: connect payment milestones to testable business and technical criteria, including data reconciliation and operational readiness.
    • Interface ownership: identify who monitors each integration, handles incidents, replays transactions, and coordinates with third-party vendors.
    • Service levels: define severity, measurement windows, response, communication, restoration, exclusions, and escalation rather than relying on a general support promise.
    • Security and compliance: specify access controls, vulnerability handling, logging, incident notification, evidence retention, and responsibility for applicable compliance work.
    • Release governance: document environments, approval gates, emergency changes, regression testing, rollback, and responsibility for platform upgrades.
    • Knowledge transfer: require architecture records, code and configuration documentation, operational runbooks, credentials handover, and training for the people who will own the system.
    • Change control: distinguish clarification, defect, dependency change, and new scope so that every disagreement does not become a commercial negotiation.
    • Exit: cover repository access, infrastructure access, documentation, open incidents, licences, data export, and transition support.

    Security certifications are useful screening signals, but scope matters. Scandiweb lists ISO 27001 and PCI DSS credentials, while Elogic Commerce lists ISO 27001, ISO 9001, and SOC 2 Type II. Ask which legal entity, locations, services, people, and systems are covered. A certificate at company level does not automatically validate your proposed hosting architecture or remove your own compliance responsibilities.

    Make the final decision in two stages

    First, apply the technical and operational gates. Eliminate candidates that cannot demonstrate a launch-critical integration, workflow, security requirement, delivery role, or support obligation. Then score the remaining firms on matched evidence, team quality, delivery approach, commercial terms, and working fit.

    Compare total cost across discovery, implementation, licences, middleware, cloud services, data migration, testing, launch support, managed service, upgrades, and transition. Hourly rates are difficult to compare when one proposal includes architecture and quality assurance while another leaves them as client responsibilities. Normalize scope and assumptions before treating price differences as savings.

    Keep the commercial discussion from reopening a failed technical gate. A discount does not make an unproven order flow, missing ERP capability, or vague support model less risky.

    Key takeaways

    • Choose around your hardest system and workflow dependencies, not the storefront platform alone.
    • Make mandatory integrations, B2B functions, security controls, and support coverage pass-or-fail conditions.
    • Treat partner tiers, certifications, reviews, and client logos as signals to investigate, not substitutes for matched implementation evidence.
    • Ask finalists to solve the same integration and failure scenarios so you can compare their reasoning directly.
    • Use paid discovery to evaluate the proposed delivery team and produce portable architecture, migration, risk, and operating artefacts.
    • Contract acceptance, interface ownership, support, knowledge transfer, change control, and exit terms before implementation begins.

    Before your next agency call, draw the one-page system map and select three failure scenarios that would materially disrupt revenue or operations. Send the same map and scenarios to every finalist, then require written answers tied to named people and comparable production work.

    The partner that deserves the next step is not the one that promises every capability. It is the one that makes boundaries visible, explains how failure will be handled, and gives you evidence that the assigned team can operate the system after the launch presentation is over.

    References


  • How to Build an SEO Career Without Waiting to Be Hired

    How to Build an SEO Career Without Waiting to Be Hired

    If you have been learning SEO but keep meeting the same barrier — no job without experience, no experience without a job — stop treating an offer letter as permission to begin. A certificate can show that you studied the subject. It cannot show how you make decisions when the audience, budget, traffic, and outcome are real.

    Build a small project with a real audience and a useful offer. Use it to practise SEO, GEO, content, measurement, and responsible AI use as connected disciplines. The project does not need to become a large business. It needs to produce credible evidence of how you identify a problem, choose an action, measure the result, and learn from what happened.

    Stop optimizing for permission and start producing evidence

    The conventional entry route is harder to navigate when businesses can automate tasks that once gave junior employees their initial experience. Economic pressure and uncertainty around search add to the problem. Sending applications still matters, but it cannot be your only career strategy.

    Learning and evidence are different things. Learning tells you what a canonical tag does. Evidence shows that you found a canonicalization problem, understood its effect, chose a safe correction, and checked the result. Learning explains search intent. Evidence shows how you mapped a real customer’s questions to pages and calls to action.

    CapabilityWeak career signalStronger project evidence
    Audience researchYou say that you understand search intent.You show how customer questions shaped an offer, query map, and page plan.
    Technical SEOYou list an auditing tool on your CV.You document an indexing, internal-linking, canonical, or rendering issue and the reasoning behind your response.
    ContentYou publish generic advice about SEO.You create content that helps a defined audience evaluate or use something, then examine what visitors do next.
    GEO and AI visibilityYou describe yourself as an AI search expert.You keep a dated record of how relevant AI systems represent the project, where answers are inaccurate, and what you changed.
    Commercial judgmentYou claim to be strategic.You explain why one task deserved limited time or money while another did not.

    Your project gives an employer or client something concrete to question. Why did you target that audience? Why did you create that page before another one? What evidence changed your mind? What failed? Strong answers reveal judgment more reliably than a collection of tool badges.

    You also do not need to create financial pressure for the sake of appearing committed. If you need the income from your current job, keep it. An SEO career can begin alongside the work and responsibilities you already have. Choose a project small enough to maintain consistently rather than planning a second full-time job that you will abandon.

    Choose a project with a real audience and a real action

    A creator photographs a handmade planter at a community market while two visitors examine the product and use a phone.

    A practice website about SEO may help you learn a content management system, but it often removes the hard part of the job: understanding somebody else’s customer. It also encourages a weak success metric — publishing articles and waiting for traffic.

    A better project gives people something useful to do, request, join, download, book, or buy. It might be a small app, service, product, or other offer in a field you understand. Content then supports the offer instead of becoming the entire business model.

    Use these filters before committing:

    • Audience access: You can observe where the intended users ask questions and how they describe the problem. If you cannot reach or listen to them, your assumptions will be hard to correct.
    • A recognizable need: The project solves a specific problem rather than serving a vague interest. The need does not have to be large, but a real person should be able to recognize it as their own.
    • A meaningful action: Visitors can do more than read. Give them a clear next step that creates a measurable signal of interest.
    • Manageable production: You can build and support the offer with the time, skills, and money available to you. A narrower live project is more useful than an ambitious concept that never launches.
    • Room for discovery work: Potential users look for answers, recommendations, providers, products, or comparisons through search, AI assistants, communities, or relevant publications.
    • Safe subject matter: Avoid a field in which useful advice would require professional credentials or access to sensitive information you do not have.

    Write a short opportunity brief before building anything. It should name the audience, the problem, the offer, the intended user action, the places where discovery may happen, and the constraints under which you will work. Add what you currently believe and what evidence could prove you wrong. This turns the project from an open-ended hobby into a series of decisions.

    Do not define success as becoming a large business. That outcome is outside your control and unnecessary for the career goal. Define success as producing an honest body of evidence: a live offer, observable user behavior, documented interventions, technical decisions, and conclusions that respect the limits of the data.

    A project that receives little interest can still teach you something valuable. Perhaps the need was weak, the positioning was unclear, the audience was difficult to reach, or the offer asked for too much commitment. Your task is not to disguise that result. It is to work out which explanations the evidence supports and what you would test next.

    Run the project like a small SEO and GEO account

    The project becomes career evidence only when you can reconstruct what happened. Keep a decision log from the beginning. Memory turns experiments into neat stories; a dated record preserves the uncertainty, alternatives, and inconvenient results that demonstrate how you actually think.

    Capture a baseline before making changes

    Record the condition you are starting from, even if the initial values are empty. Depending on the project, the baseline may include:

    • The pages you intend search engines to access and the pages currently indexed.
    • The queries, impressions, clicks, and landing pages visible in Google Search Console.
    • The actions you count as meaningful, such as an inquiry, signup, download, booking request, or purchase.
    • Existing brand mentions, links, directory entries, referrals, and community visibility.
    • How relevant AI systems answer discovery and comparison questions connected to the project.
    • Errors, omissions, inconsistent facts, missing citations, or competitor recommendations in those AI answers.

    For AI observations, save the exact question, the system or model used, the date, the answer, any cited pages, and your interpretation. Treat that record as an observation of a changing interface, not as a universal ranking report. A later answer may differ for reasons unrelated to your work.

    Make each change answer a defined question

    Start with access and comprehension. Check response status, robots directives, canonical signals, internal links, sitemaps, page templates, and whether important content is available without a fragile interaction. If you add structured data, it should describe information that is genuinely present and visible on the page. Passing a validator does not repair a weak or misleading page.

    Then connect demand to the offer. Group queries and audience questions by the task behind them: learning, comparing, evaluating suitability, resolving an objection, or taking action. Map each meaningful task to the page best equipped to satisfy it. This prevents the common habit of producing disconnected articles merely because a keyword tool returned a phrase.

    For every substantial intervention, record:

    • Observation: What did you notice, and where did the evidence come from?
    • Hypothesis: What do you think is happening, and what alternative explanation remains plausible?
    • Decision: What will you change, postpone, or deliberately leave alone?
    • Expected signal: What behavior or search signal would support the hypothesis?
    • Result: What happened after the change, including a null or negative outcome?
    • Confounders: What else changed that could have affected the result?
    • Next action: What will you do because of what you learned?

    Where practical, avoid changing several major variables at once. Allow an observation period that makes sense for the project’s traffic and the type of change, and choose that period before seeing the outcome. Sparse data may not justify a firm conclusion. Say so. Causal restraint is a strength in a case study, not an admission of weakness.

    Use AI to increase your capacity, not to impersonate expertise

    AI can help you prototype an interface, organize audience language, classify information, draft test cases, or automate repetitive work. It can also produce plausible errors. The useful professional skill is not collecting prompts; it is knowing enough about the underlying task to recognize and correct bad output.

    Keep the review step visible. Note what AI helped produce, what you verified, what you rejected, and why. If it drafts structured data, compare every property with the visible page and the vocabulary you intend to use. If it clusters queries, inspect ambiguous terms and outliers. If it summarizes customer comments, return to the original language before deciding what customers need.

    Apply the same discipline to tools. You do not need an agency-sized stack to prove that you can do SEO. Every paid subscription should answer a practical question: Did it reveal information you could not obtain another way? Did that information change a decision? Did the resulting action contribute to a useful outcome? Working without somebody else’s software budget can sharpen the commercial judgment future employers need.

    Traffic alone is not the outcome. Connect discovery to behavior. A page can gain impressions without attracting the right visitors, and visits can grow without producing interest in the offer. Report the chain honestly: visibility, visits, meaningful actions, and any evidence of commercial value. If the chain breaks, the break is the problem to investigate.

    Turn the decision trail into a portfolio and relationships

    Hands review a portfolio case containing research cards, content thumbnails, interface mockups, and a finished product photograph arranged in sequence.

    A portfolio should not be a gallery of screenshots or a list of services you hope to sell. It should let another practitioner inspect your reasoning. Publish the work while it is still in progress, with enough context that a reader can distinguish evidence from interpretation.

    Write case studies as decisions, not victory laps

    Use a consistent case-study structure:

    • Context: What is the project, who is it for, and what constraint mattered?
    • Problem: What specific condition required a decision?
    • Evidence: What did you observe before acting?
    • Options: What credible alternatives did you consider?
    • Choice: What did you do, and why was it the best use of limited resources?
    • Implementation: What changed on the site, in the content, or in distribution?
    • Outcome: What moved, what did not, and over what recorded observation period?
    • Limits: What prevents a stronger causal claim?
    • Next decision: What will you preserve, reverse, or test next?

    Show relevant absolute values when you can do so safely, not just favorable percentages. Explain whether the baseline was small and whether seasonality, another campaign, a platform change, or simultaneous site work could have contributed. Never convert correlation into certainty merely because certainty makes the headline stronger.

    Publish failures too. A careful account of an unsuccessful experiment can demonstrate diagnosis, accountability, and adaptability better than recycled advice. The useful question is not whether every idea worked. It is whether you noticed the result, updated your understanding, and made a better next decision.

    Let communities see work that is already in motion

    Use an owned home for complete case studies and a social profile or community presence for shorter updates. Start with a channel you can maintain. Publishing creates visibility for both the project and the person learning how to grow it: potential users can discover the offer, while practitioners can see the decisions behind it.

    Join communities where people are doing the work: relevant forums, Slack groups, local meetups, or a paid community when it provides access or support you genuinely need. Do not arrive with a broad request for somebody to mentor you. Bring a specific artifact and a narrow question. Show the baseline, what you changed, what happened, and the part of your interpretation you want challenged.

    • Answer questions when your project gives you relevant evidence, and state the limits of that evidence.
    • Share a useful template, diagnostic process, or failed test without turning every interaction into self-promotion.
    • Ask for criticism of a particular decision rather than general approval of your career plan.
    • Return after acting on feedback and explain what changed in your thinking.
    • Protect private information and obtain permission before discussing work that belongs to somebody else.

    If you work on another person’s business, agree on scope, access, data handling, ownership, and expectations before touching the site. Do not imply that rankings or revenue are guaranteed. A project you own is often simpler because you control the asset, can publish the process, and do not expose somebody else to an inexperienced change.

    Use the portfolio to make applications and outreach more precise. When a role emphasizes technical diagnosis, link to the case that shows your diagnosis. When it emphasizes content growth, show how audience research became pages and measurable actions. When it mentions AI search, share your dated observation method and the limits you placed on the conclusions. You are giving the reader a reason to discuss your work rather than asking them to infer ability from enthusiasm.

    The same evidence can open several routes: an employed role, a bounded freelance assignment, a collaboration, or an introduction to somebody with a harder problem. None is guaranteed. The point is to create more ways for useful work to encounter opportunity than a CV inside a crowded recruitment system.

    Key takeaways and your next move

    • You do not need an SEO job before you can begin producing SEO evidence.
    • A small live offer with a defined audience teaches more than a practice blog built only to attract traffic.
    • Your strongest portfolio material is the full reasoning chain: baseline, hypothesis, decision, implementation, outcome, limitations, and next action.
    • SEO, GEO, content, conversion, and AI-assisted work should meet inside the same project because real businesses experience them as connected problems.
    • Responsible AI use includes verification, rejection of weak output, and enough subject knowledge to explain both.
    • Publishing honest work gives potential users a way to find the project and practitioners a way to assess your judgment.

    At your next work session, write down the audience, problem, offer, intended action, discovery surfaces, and current baseline for one manageable idea. If you cannot fill those fields without vague language, narrow the project. If you can, put the smallest useful version in front of real people and begin the decision log. Your next application can then lead with work somebody can inspect, question, and remember.

    References


  • How to Win Visibility in Agent-Driven Search

    How to Win Visibility in Agent-Driven Search

    Your page can rank first and still lose the customer. In agent-driven discovery, a person can ask an AI assistant to find, compare, book, buy, or contact a provider. The agent may evaluate several businesses and complete the task without sending that person through a familiar results page.

    That changes the visibility problem. You still need to be found, but you also need to survive qualification, support verification, and offer a safe path to action. The practical goal is not merely to appear in an answer. It is to remain the best eligible choice all the way through the agent’s workflow.

    Search visibility now has four separate gates

    An agent commonly turns a delegated request into requirements, searches for possible candidates, evaluates each candidate against those requirements, checks important claims, and then attempts the requested action. A conventional ranking affects the candidate-gathering stage, but it does not settle the final decision.

    GateQuestion the agent must resolveWhat your site needs to provideUseful metric
    RetrievalCan I find this business for the delegated task?Indexable pages, unambiguous entities, relevant task language, and clear topical coverageCandidate appearance rate
    QualificationDoes it satisfy every non-negotiable requirement?Explicit capabilities, limits, prices, locations, eligibility rules, integrations, and availabilityHard-requirement pass rate
    SelectionIs it the best fit among the eligible choices?Suitability guidance, evidence, differentiators, and independently verifiable claimsSelection share when retrieved
    CompletionCan I safely perform the requested action?A usable form, booking flow, checkout, approved API, or clearly defined human handoffSuccessful action rate

    Ranking remains important because it helps a brand enter the candidate set. It is no longer a reliable proxy for winning the decision. First Page Sage reported that, in its vendor-led analysis of 2,417 agentic commands issued from March 4 through June 10, 2026, the first-ranked result was selected 44.6% of the time, while a result ranked fourth or lower was selected 38.2% of the time. Those figures are directional rather than universal benchmarks: they come from one commercial analysis, and agent behavior can differ by platform, category, request, and user context.

    The useful conclusion is narrower and more durable: rank and selection are different outcomes. If your reporting stops at impressions, positions, and clicks, you cannot tell whether an agent failed to retrieve your brand, rejected it on a requirement, distrusted a claim, or could not complete the transaction.

    Give each gate its own metric. Candidate appearance rate tells you whether discovery is working. Hard-requirement pass rate exposes missing or disqualifying facts. Selection share tells you whether the agent prefers you after finding you. Successful action rate reveals whether your conversion path works for an automated assistant. A single visibility score hides all four failure modes.

    Publish the facts agents need to qualify you

    A central business model is connected to visual modules for location, hours, price, availability, services, accessibility, and verification.

    A broad category page may rank for “payroll software,” “family hotel,” or “commercial electrician” while giving an agent too little information to answer a constrained request. Real delegated tasks include conditions: company size, location, budget, dates, integrations, accessibility needs, service area, cancellation terms, or regulatory requirements.

    Agents can treat those conditions differently. A hard requirement eliminates a candidate. An important requirement carries substantial weight. A nice-to-have breaks a close comparison. An optional feature may add only a small advantage. Your first content job is to discover which facts occupy each tier for the buying tasks that matter to your business.

    1. Choose a delegated commercial task. Use a task tied to revenue, such as booking a service, selecting a product, requesting a proposal, or arranging a demonstration. Commercial requests deserve priority because delegated agent activity is more concentrated around buying, booking, and hiring than around general informational searches.
    2. Write down the complete requirement set. Use actual sales questions, support tickets, requests for proposals, on-site searches, form responses, and objections. Separate non-negotiable conditions from preferences instead of treating every feature as equally important.
    3. Map every hard requirement to a canonical page. The answer should be stated directly, not buried in a brochure, image, unsupported comparison chart, or sales-only conversation.
    4. Add suitability content. Explain who the offer is for, who it is not for, which situations it supports, what prerequisites apply, and where its limits begin.
    5. Keep consequential facts synchronized. Prices, regions, availability, policies, product names, and eligibility rules should not conflict across product pages, help content, structured data, directories, and partner profiles.

    Use a suitability page pattern that answers the whole decision

    A useful suitability page is not another generic “why choose us” page. It should let a machine or a person decide whether your offer fits a specific situation. A practical structure is:

    • Best fit: the customer, use case, location, scale, or conditions the offer is designed for.
    • Required conditions: prerequisites the customer must meet before buying, booking, or applying.
    • Supported requirements: the capabilities, integrations, service areas, configurations, or policies that satisfy common constraints.
    • Limitations: unsupported scenarios, exclusions, capacity boundaries, dependencies, and cases that require a different offer.
    • Commercial facts: visible pricing where possible, or a precise explanation of what determines price; availability; fees; cancellation terms; and what happens after submission.
    • Evidence: links to documentation, policies, certifications, product details, or independent material that substantiates consequential claims.
    • Next action: a clear route to buy, book, request a quote, schedule a demonstration, or move to a human review.

    Dedicated suitability content is worth testing even if it attracts little conventional search volume. In the same vendor analysis, businesses with this kind of content were selected 2.7 times as often as equally ranked businesses without it. That multiplier should not be treated as a guaranteed result, but the mechanism is sensible: explicit fit information reduces the inference an agent must make.

    Make proof machine-readable without hiding caveats

    Relevant JSON-LD can express your organization, offer, product or service, availability, and other supported attributes in a consistent format. Use it to clarify facts already visible on the page. Do not use markup to introduce claims, prices, ratings, availability, or capabilities that a visitor cannot confirm in the page content.

    Structured data reduces ambiguity; it does not establish truth. Agents may compare a site’s claims with what they already know and with independent material before choosing a candidate. Make important assertions easy to verify by identifying what the claim applies to, where it applies, and under which conditions. A sentence such as “integrates with accounting software” is weak. A maintained integration page that names the supported systems, required plan, setup path, and current limitations is decision-grade evidence.

    Consistency matters here. Use the same business name, canonical URL, product names, locations, and core offer descriptions wherever you control the information. When a third-party profile is outdated, correct it. When a claim changes, update the visible page and its markup together. Contradictory facts force an agent to decide which version to trust, and the safest decision may be to exclude the candidate.

    Remove the blockers between selection and completion

    A glowing agent pathway moves through verification, availability, selection, payment, and completion while alternate routes end at digital obstacles.

    A recommendation has limited commercial value if the agent cannot finish the requested job. The operational difference is whether a page is machine-actionable: can an approved agent use the interface to submit the inquiry, reserve the time, add the product, complete the purchase, or reach a defined handoff?

    The vendor-led command analysis recorded 78.3% of conversions on machine-actionable pages, compared with 9.6% on pages where the agent could not act. This is not a promise that making a form accessible will produce a particular conversion rate. It is evidence that transactional usability can become a selection constraint rather than a minor conversion optimization.

    Audit the complete transaction, not just the landing page

    • Use visible, specific field labels. “Work email,” “arrival date,” and “number of employees” are easier to interpret than placeholder-only or context-dependent fields.
    • State required inputs before submission. If a quote needs a postal code, account identifier, property type, budget range, or document, disclose that requirement before the agent enters the flow.
    • Explain validation failures precisely. Identify the affected field, preserve valid entries, and say what an acceptable value looks like.
    • Expose material terms before commitment. Price, fees, renewal terms, cancellation conditions, availability, and approval dependencies should not appear only after the decisive click.
    • Use conventional controls and stable destinations. Buttons should have meaningful labels, links should resolve predictably, and essential actions should not depend on unexplained gestures or decorative interface elements.
    • Return an actionable confirmation. Show what was submitted, whether it succeeded, what happens next, and any reference number or next step the user needs.
    • Define the human handoff. If the task cannot be automated, say which step requires a person, what information that person needs, and how the customer will be contacted.

    Test the flow from a clean session using the same facts a customer would give an agent. Check every branch: unavailable dates, unsupported locations, invalid entries, expired inventory, payment failure, authentication, and confirmation. A form that works only on the happy path is not reliably actionable.

    Agent-friendly does not mean unguarded. Keep authentication, fraud controls, consent, privacy safeguards, and human approval wherever the risk requires them. Do not weaken a security control to make automation easier. If automated action is allowed, provide an approved route; if it is not, provide a clear and honest handoff instead of a hidden bypass.

    Use audience preference where the platform supports it

    Retrieval is not driven only by topical relevance. Google Preferred Sources gives readers an explicit way to star publications in the Top Stories area so that stories from those outlets can appear more often for those readers. This is a narrow feature with a precise scope: it concerns publications and Top Stories, not every business listing, organic result, or AI-agent decision.

    The feature has nevertheless become large enough for publishers to treat it as a real retention channel. Google reported that people had selected more than 600,000 unique sources, up from 200,000 in May 2026. Google has also said that users who select a preferred source are twice as likely to click. Those figures describe this specific feature; they do not establish a general ranking advantage across search or AI platforms.

    If you publish news and participate in Top Stories, the implementation is straightforward:

    1. Install Google’s Preferred Sources button using the supported implementation.
    2. Place the prompt near a moment when the reader has received value, such as the end of a substantive story, rather than interrupting the opening.
    3. Explain the result accurately: starring the publication can make its stories appear more often in that reader’s Top Stories experience.
    4. Record the preferred-source user count with its reporting date so you can measure growth instead of relying on an undated total.
    5. Compare that growth with returning readership and engagement, while keeping correlation separate from proof of causation.

    Some site owners received Search Console emails showing a Preferred Source user count as of October 5, 2026. Google also surveyed recipients about future reporting methods, frequency, and metrics. Until regular reporting is established, keep your own dated record of any counts you receive.

    If you are not a relevant publication, do not imitate the button or describe ordinary follows as Preferred Sources. Apply the underlying principle without inventing a platform signal: give satisfied readers a clear way to return, subscribe, follow, or search for your brand again. Explicit preference can support a durable audience, but it should not be presented as proof that an unrelated agent will select you.

    Measure agent visibility as a decision path

    You do not need access to an agent’s private logs to build a useful diagnostic. You need a repeatable set of realistic tasks and a disciplined record of what can be observed. Start with the commercial requests that matter most, because “explain this topic” and “choose a provider and submit an inquiry” test very different kinds of visibility.

    1. Define the task exactly. Include the hard constraints a real buyer would provide: location, budget, timing, compatibility, eligibility, scale, or required terms.
    2. Preserve the test context. Record the platform, date, locale, sign-in state, exact command, and any files or preferences supplied. Keep the command unchanged when comparing runs.
    3. Capture the candidate set. Note whether your brand appeared, which page supported the appearance, what claims were surfaced, and which competing options were considered.
    4. Score each requirement. Mark hard requirements as confirmed, failed, contradictory, or unknown. An unknown should not be counted as a pass merely because you know the answer internally.
    5. Separate selection from retrieval. Record whether the brand was found, whether it remained eligible, whether it was selected, and the observable reasons given. Do not present an inferred reason as if the agent disclosed it.
    6. Test the action. Where authorized, follow the process through the form, booking, cart, checkout, or handoff. Record the exact field, policy, authentication step, or interface state that prevents completion.
    7. Fix the earliest failed gate. More suitability copy will not solve an indexing failure. More authority will not repair an unusable booking flow. Diagnose before choosing the optimization.
    8. Repeat on a fixed cadence. Agent outputs can change, so compare patterns across repeated observations rather than treating one response as a permanent ranking.

    Keep conventional SEO and analytics beside this testing. Search rankings still influence retrieval, human visitors still use results pages, and agent-driven commercial activity remains only part of search. The measurement upgrade is additive: it connects rankings and mentions to qualification, selection, and completed work.

    Key takeaways

    • A ranking can earn entry into an agent’s candidate set without earning the final selection.
    • Publish explicit requirements, supported scenarios, limitations, commercial terms, and suitability guidance so the agent does not have to guess.
    • Use JSON-LD to clarify visible facts, not to make unsupported claims or conceal qualifications.
    • Make consequential claims consistent and independently verifiable.
    • Treat forms, booking systems, checkout, APIs, and human handoffs as part of search visibility.
    • Measure retrieval, qualification, selection, and completion separately so each failure receives the right fix.
    • Use Google Preferred Sources if its Top Stories scope fits your publication, but do not mistake it for a universal agent-ranking signal.

    Choose your highest-value delegated task and trace it from discovery to completion. If your brand is absent, repair retrieval. If it appears but is rejected, expose the missing fit or proof. If it is selected but the task stalls, fix the transaction. That sequence keeps you from buying more visibility when the real leak is qualification, trust, or action.

    References


  • Google Merchant Center UCP Integrations: What to Enable

    Google Merchant Center UCP Integrations: What to Enable

    You have three separate decisions to make when Google’s UCP integration hub appears in Merchant Center. You can send a cart to your website, support checkout on Google, link customer identities, or adopt only the capabilities that fit your operation.

    The right choice depends less on what you can switch on than on where you can safely own the customer, order, and recovery experience. Use the framework below to choose a scope, test the handoffs, and measure whether UCP removes purchasing friction without creating an operational blind spot.

    What the UCP integration hub actually changes

    Google is gradually making the Merchant Center UCP integration hub available to eligible U.S. merchants. UCP stands for Universal Commerce Protocol. In this rollout, it acts as a connection layer between Google’s shopping experiences and a merchant’s commerce infrastructure.

    The meaningful change is modularity. An eligible merchant can select individual capabilities instead of accepting one predetermined checkout experience. That turns UCP configuration into a set of business decisions rather than a single technical integration.

    CapabilityWhat changes in the journeyYour release gate
    Cart transferThe shopper’s cart moves from Google to the merchant’s website, where the purchase can continue.The correct products, variants, quantities, prices, and context must survive the handoff.
    Native checkout on GoogleThe shopper can complete checkout within Google’s experience.Your order operation must reliably receive, fulfill, reconcile, support, cancel, and refund the resulting orders.
    Identity linkingThe shopper’s Google identity can be connected with the merchant’s customer relationship.The customer benefit, consent path, account-matching rules, unlinking process, and support recovery must be clear.

    Treat the last column as your own acceptance standard. The presence of a capability in Merchant Center tells you that it is available to configure; it does not prove that your downstream systems, policies, analytics, or support team are ready for it.

    For SEO, AEO, and GEO teams, the boundary matters. UCP is commerce infrastructure. It can shorten the distance between product discovery and purchase, including journeys in which AI agents help people research products, assemble carts, and transact. It should not be treated as a ranking switch, a replacement for Merchant Center feed quality, or a substitute for accurate product pages and structured data.

    Choose each capability by ownership and failure radius

    A modular ecommerce system separates identity, checkout, and fulfillment into bounded zones, with an amber warning contained inside the checkout area.

    Start with the customer journey you can operate reliably. A shorter path is valuable only when the order that emerges from it is accurate, observable, and recoverable.

    1. Consider cart transfer first when your website checkout is already the strongest part of the journey. It lets Google participate in discovery and cart creation while your existing site remains the purchase destination. Test the handoff as a data contract: the product identifier, selected variant, quantity, current price, availability, promotion context, and destination page must agree. Also define what the shopper sees when a price changes, an item sells out, or the cart cannot be reconstructed.
    2. Consider native checkout when your order operation can support a transaction completed outside your website. Map the entire order lifecycle before enabling it: creation, payment state, tax, shipping, inventory reservation, fulfillment, cancellation, returns, refunds, customer notifications, fraud review, and support. Do not assume that a native interface transfers responsibility for these functions. Confirm the division of responsibility for your particular setup.
    3. Consider identity linking when signing in produces a real customer benefit. That benefit might involve account continuity, saved preferences, loyalty, or post-purchase service, but the benefit must be explicit. Define how accounts are matched, what happens when identifiers disagree, how duplicate accounts are handled, how consent is recorded, and how a customer can unlink or recover access.

    The hub’s capability-by-capability selection model gives you a reason to avoid an all-at-once launch. Enable the smallest useful combination first. If cart transfer fails, you can investigate the cart contract. If identity linking and native checkout go live at the same time, an order problem may involve identity resolution, checkout state, or the order pipeline, making the cause harder to isolate.

    That sequencing is especially important for identity linking. It introduces customer-data, authentication, privacy, and support consequences that are different from the mechanics of moving a cart. Review it as its own workstream rather than treating it as a convenience setting attached to checkout.

    Build six release checks before changing the customer journey

    Six quality-control stations test product availability, cart transfer, identity, payment, order confirmation, and customer recovery along an ecommerce purchase path.

    You do not need to wait for a full implementation project before preparing. You do need a written acceptance plan. Build these six checks while access is rolling out:

    1. Confirm the actual scope in your account. Record which Merchant Center account, market, storefront, and capabilities are eligible. The rollout begins with eligible U.S. merchants, while plans for Australia and Canada have moved to a later schedule. Work from the controls present in your account rather than treating an announced market sequence as a guaranteed activation date.
    2. Define the catalog contract. Name the system that owns each product identifier, variant, price, currency, availability state, image, and fulfillment promise. The website, Merchant Center data, cart, and order record should refer to the same sellable item. If two systems can overwrite a value, document which one wins and when.
    3. Define the cart contract. Specify what must survive a transfer and what can be recalculated on arrival. Include quantity limits, variant selections, promotions, unavailable items, expired carts, and price changes. Write the customer-facing fallback for each failure; a silent empty cart is not an acceptable recovery path.
    4. Define the order contract. For native checkout, trace a successful order and every material exception through the systems your teams use. An order is not complete merely because payment appears successful. It must enter inventory, fulfillment, notifications, reporting, customer service, cancellation, return, and refund workflows with a stable identifier.
    5. Define the identity contract. Decide what data is linked, why it is needed, what consent is required, how long it is retained, and which team handles mismatches. Include duplicate accounts, shared email addresses, changed email addresses, revoked access, deletion requests, and support verification.
    6. Define observability and recovery. Assign an owner for integration errors, order discrepancies, customer complaints, and rollback decisions. Preserve enough identifiers to trace a journey across the surfaces you control without exposing unnecessary personal data. Document how you will pause a capability safely if failures rise.

    Use any preview, testing, or diagnostic path that your Merchant Center account makes available. If your account exposes only a broad production control, complete the data and operational checks before changing it. Do not discover your refund path, account-recovery rules, or missing order identifiers through the first customer complaint.

    Launch one capability at a time when the available controls permit it. Start with the smallest reversible product or operational scope supported by your setup. Keep a written record of the prior configuration, the activation time, the owner on duty, the expected signals, and the condition that triggers a pause.

    Measure the handoff, not just the final sale

    A conversion total can hide the exact friction UCP is meant to remove. Build a funnel that shows where an eligible journey stopped. Instrument the events available on the systems you control, then reconcile them with the commerce and order records available from the integration.

    • Eligible journey volume: the number of shopping journeys that could use the enabled capability.
    • Cart initiation and transfer: how many carts begin, how many handoffs are attempted, and how many arrive with usable contents.
    • Checkout progression: how many transferred or native journeys reach checkout, encounter an error, and complete.
    • Order reconciliation: whether each completed transaction produces one accurate order in the system of record, without omissions or duplicates.
    • Commercial consistency: discrepancies involving products, variants, quantities, price, availability, tax, shipping, discounts, or currency.
    • Operational consequences: cancellations, refunds, identity-recovery cases, integration-related support contacts, and manual corrections.

    Capture a baseline before launch. Compare the same journey before and after enablement where your data permits, and separate technical success from business success. A cart can transfer perfectly while conversion falls because the landing experience is confusing. Native checkout can increase completed orders while creating reconciliation work that erases the operational benefit.

    Website analytics alone will be incomplete when checkout finishes on another surface. Do not interpret a drop in site-recorded purchases as a drop in total purchases until native orders have been reconciled. Conversely, do not count an external checkout confirmation as a clean success until the corresponding order is present and actionable in your system of record.

    Keep search visibility and commerce performance in separate reporting layers. Monitor product discovery, landing-page visibility, feed health, and structured-data quality alongside the UCP funnel, but do not attribute a ranking change to UCP merely because the dates overlap. Its immediate job is to connect discovery, cart, identity, and transaction paths more effectively.

    Consistency is the point where the SEO and commerce teams meet. Use the same product identity, variant language, pricing state, availability, and merchant policy across Merchant Center, the website, structured data, cart, checkout, and order systems. UCP cannot compensate for contradictory facts moving through those systems; it can only make those contradictions reach the customer faster.

    Key takeaways

    • UCP in Merchant Center is a selectable integration layer, not one mandatory checkout model.
    • Choose cart transfer when your site checkout should remain the transaction destination and you can preserve cart accuracy through the handoff.
    • Choose native checkout only after the complete order, support, cancellation, return, and refund lifecycle works outside a website-completed purchase.
    • Review identity linking separately because it adds consent, account-matching, privacy, authentication, and recovery requirements.
    • Measure attempted handoffs, errors, discrepancies, and reconciled orders as well as conversions.
    • Do not treat UCP enablement as evidence of improved rankings; maintain product data, content, feeds, and structured data as separate visibility work.

    If the hub is already available in your account, begin with a capability decision and an acceptance checklist, not the activation control. If it is not available, prepare the catalog, cart, order, identity, and measurement contracts now. That work remains useful regardless of when eligibility reaches your market or account.

    References


  • How to Manage Google Ads Video Frequency Across Campaigns

    How to Manage Google Ads Video Frequency Across Campaigns

    Your video campaigns can each look controlled while your audience still feels overexposed. The blind spot is overlap: a person can qualify for several campaigns, so acceptable frequency inside each campaign can become excessive frequency across the account.

    Google Ads is testing Video Campaign Groups for eligible Video and Demand Gen campaigns. The beta introduces group-level choices for increasing deduplicated reach or coordinating delivery around a frequency target. Used well, it can help you answer a practical question: are you reaching more of the intended audience, or repeatedly buying access to people you have already reached?

    Campaign-level frequency can hide account-level saturation

    A top-down view shows three colored projection beams overlapping on the same small group of people while others remain outside the light.

    Reach and frequency only make sense within a defined boundary. Reach represents the distinct audience exposed within that boundary. Frequency describes how often the reached audience was exposed on average. Change the boundary from an individual campaign to a collection of campaigns, and both measurements can change.

    This matters when a brand-awareness campaign, a product campaign, and a Demand Gen campaign pursue overlapping audiences during the same period. Each campaign can report a reasonable result while the combined plan keeps returning to much of the same audience. Adding the individual reach figures will not reveal the true audience size because duplicated people can appear in several campaign totals. Averaging campaign frequency figures can be equally misleading because the campaigns may have different reach and impression volumes.

    The problem is organizational as much as technical. Separate teams, agencies, product lines, or budget owners may optimize their campaigns independently. The audience does not experience those internal boundaries. It experiences the combined sequence of ads.

    Before creating a campaign group, build a simple overlap map:

    1. List the active Video and Demand Gen campaigns that could belong in the group.
    2. Record each campaign’s business objective, audience, geography, schedule, creative message, and responsible owner.
    3. Mark audience overlap as high, uncertain, or low. Treat uncertain overlap as something to investigate, not as an assumption of independence.
    4. Identify campaigns that serve a different funnel stage or require deliberately different repetition. Keep those outside the group unless a shared group objective still makes sense.
    5. Write the audience experience in plain language. If the plan sounds repetitive when described from the viewer’s perspective, campaign-level optimization is probably not enough.

    Choose between broader reach and managed repetition

    The beta presents two different strategic directions: increase campaign-group reach or set a campaign-group frequency target. Do not treat this as a routine setup choice. It tells Google what problem you want the group to solve.

    Group directionUse it whenWhat success should look likeWhat to watch
    Increase campaign-group reachYour upper-funnel campaigns compete for overlapping audiences and your priority is finding additional eligible people.Deduplicated group reach expands without unacceptable deterioration in the business outcome or audience quality you use as a guardrail.Do not confuse a larger reported audience with valuable incremental reach. Check whether the additional exposure still serves the campaign’s purpose.
    Set a campaign-group frequency targetRepetition is intentional, but you want it coordinated across campaigns rather than produced independently by each campaign.Group-level frequency moves toward the intended pattern while reach, delivery mix, and campaign outcomes remain acceptable.A target is an optimization instruction, not proof that every person receives the same number of impressions. Do not describe it internally as a hard cap unless the interface explicitly defines it that way.

    Reach optimization is usually the clearer choice when the central problem is duplication. If several upper-funnel campaigns address substantially the same market, a group-level reach objective gives the system a reason to look beyond people already reached elsewhere in the group.

    A frequency target is more appropriate when repetition has a defined role in the plan. That might include maintaining brand presence or supporting a coordinated message over time. The target still needs a business rationale. Do not borrow a universal frequency number from another account. Audience size, campaign purpose, creative variety, buying cycle, and available budget all change what a sensible pattern looks like.

    Treat your initial target as a hypothesis. Start from your own historical delivery and the point at which added exposure stopped producing enough additional value. If you do not have evidence for that point, use the group to learn before making a larger budget decision.

    Build a campaign group around one coherent job

    A central control module connects several video campaign devices and distributes light either broadly across many people or in even pulses to a defined group.

    A campaign group should represent a shared audience-management problem, not merely a convenient folder. Campaigns can use the same channel while doing very different jobs. Combining them under one reach or frequency instruction can create a clean report but a confused strategy.

    1. Confirm that Video Campaign Groups are available in your account and that the campaigns you intend to use are eligible. The capability is in beta, so do not design an account-wide process that assumes universal access.
    2. State the group’s job in one sentence. A useful statement names the audience, the intended exposure pattern, and the business purpose.
    3. Group campaigns by audience relationship and funnel role. Shared format alone is not enough.
    4. Choose either reach expansion or frequency coordination based on the problem you identified. Do not select the setting first and invent the rationale afterward.
    5. Capture a baseline for campaign reach, frequency, spend, delivery mix, and the outcome each campaign is meant to influence. Preserve the date range and reporting definitions so the later comparison is meaningful.
    6. Keep major audience, creative, bid, and budget changes to a minimum during the initial evaluation. If several inputs change together, you will not know what caused the result.
    7. Assign an owner for group-level decisions. Campaign owners should not independently undo the group’s strategy by changing their own settings without recording the change.

    Keep campaigns with incompatible goals apart. A prospecting campaign seeking new audience coverage and a narrow remarketing campaign seeking deliberate repetition may need different exposure strategies. Forcing both into the same group can make the aggregate metric look healthy while weakening one campaign’s actual job.

    Also separate the setting from assumptions about budget control. A group-level reach or frequency instruction does not automatically prove that budget, bidding, creative sequencing, or delivery priority will be coordinated in the way you expect. Rely on behavior you can observe in your account, not on what the feature name appears to promise.

    Measure delivery changes, not just cleaner reporting

    The important unresolved question is whether Video Campaign Groups will meaningfully coordinate delivery across campaigns or mainly provide aggregated reporting and deduplicated reach. Those are not equivalent benefits. Better reporting can expose waste, but only delivery changes can reduce that waste.

    Evaluate the beta in three layers:

    • Group outcome: For reach optimization, examine deduplicated group reach alongside group frequency. For frequency optimization, compare observed group frequency with the intended target while watching what happens to reach.
    • Business guardrail: Keep the outcome that matters for the campaign visible, whether that is qualified site activity, conversions, brand measurement, or another objective already used by your team. A group metric should not improve at the cost of the campaign’s purpose.
    • Delivery diagnostics: Inspect how spend, impressions, reach, and frequency are distributed across the campaigns. An acceptable group average can conceal a campaign that dominates delivery or another that has effectively stopped contributing.
    What you observeWhat it may meanWhat to do next
    Deduplicated reach expands while group frequency becomes less concentratedThe result is directionally consistent with reduced overlap and broader delivery.Confirm that the additional audience remains relevant and that the business guardrail has not weakened before increasing spend.
    Group frequency moves toward the target, but a campaign dominates deliveryThe aggregate target may be improving while the campaign mix becomes less useful.Inspect audience overlap, budgets, bids, eligibility, and campaign roles before accepting the result.
    Individual campaign reach totals look large, but deduplicated group reach is substantially smallerThe account has meaningful cross-campaign overlap.Use the deduplicated view for planning and stop presenting summed campaign reach as the size of the audience reached.
    Group reporting becomes clearer, but campaign delivery patterns barely changeThe immediate value may be measurement rather than active coordination.Use the visibility to restructure audiences or campaigns, but do not claim that automated optimization reduced wasted frequency.
    The group metric improves while the business guardrail deterioratesThe system may be satisfying the exposure instruction at the expense of audience or outcome quality.Hold expansion, diagnose the tradeoff, and revise the group membership or objective.

    Maintain a change log while testing. Record campaign additions and removals, audience edits, creative launches, bid changes, budget changes, and eligibility interruptions. Without that record, a before-and-after comparison can assign credit to the campaign group for a change caused elsewhere.

    Use cautious language when reporting results. A movement that is directionally consistent with better coordination is not the same as proof of incremental reach. If you changed several inputs at once or cannot see how delivery shifted, call the result inconclusive and refine the test.

    Key takeaways

    • Manage frequency at the level where audience overlap occurs. Campaign-level averages can hide repeated exposure across the account.
    • Use group-level reach optimization when your priority is reducing duplication and reaching additional eligible people.
    • Use a group frequency target when repetition is intentional and needs to be coordinated across campaigns.
    • Group campaigns by shared audience, funnel role, and business purpose rather than by video format alone.
    • Judge the beta by observed delivery changes and business guardrails, not by a cleaner group report.
    • Treat reported improvement as preliminary when other settings changed at the same time or delivery coordination cannot be verified.

    Your next move is to identify one coherent cluster of overlapping upper-funnel campaigns, document its current exposure pattern, and give the group a single measurable job. That limited rollout will tell you more than applying a frequency setting across the account and hoping the aggregate number improves.

    References


  • How to Build Brand Trust for Better AI Search Visibility

    How to Build Brand Trust for Better AI Search Visibility

    Your brand can be technically discoverable and still fail the answer that matters: which option should the buyer trust? An AI search system may find your pages, mention your company, and even cite you without being willing to recommend you.

    That changes the work in front of you. Publishing more content will not repair invented expertise, inconsistent company facts, a chatbot that makes promises your support team cannot keep, or public conversations dominated by unresolved complaints. Better AI search visibility starts by making the evidence around your brand accurate, consistent, and useful enough to support a recommendation.

    Separate being found from being trusted

    Visibility is not a single outcome. A brand can be retrieved as relevant, cited as a factual source, included as an option, recommended as the preferred option, or mentioned with a warning. Treating all five outcomes as a ranking position hides the reason you are winning or losing.

    When you diagnose an AI answer, examine three layers of evidence:

    • Identity evidence: Is it clear who the company is, who created the content, and who is responsible for the claims?
    • Claim evidence: Are product capabilities, policies, qualifications, and comparisons specific enough to verify?
    • Experience evidence: Do customer-facing systems and independent discussions support or contradict what the company says about itself?

    Your website controls much of the first two layers. The third often develops elsewhere. A customer can encounter a bad answer in your chatbot, describe it in a community, and create a public record that later competes with your product page. That does not mean every complaint changes an AI answer. It means you cannot evaluate visibility by auditing owned pages alone.

    LastPass illustrates the persistence problem. Reddit discussions about past security incidents continued to rank for the brand name and were pulled into ChatGPT answers. The practical lesson is not to suppress criticism. It is to watch for recurring trust failures, resolve the underlying issue, and make accurate corrective information easy to find.

    Make every owned claim verifiable

    Two researchers inspect luminous connections between a geometric block, an unmarked document, a product sample, a medallion, and a clock.

    Trust begins with an unglamorous question: is the page honest about who made it? Google now explicitly treats AI-generated headshots, invented names, and false credentials used to simulate human expertise as deceptive authorship information. Its guidance says deception makes a page untrustworthy to users and automated quality systems and signals low quality.

    You do not need a celebrity expert on every byline. You need an accurate chain of responsibility. Audit your content templates with these checks:

    • Use a person’s name only when that real person created, substantially shaped, or took editorial responsibility for the work.
    • Keep biographies factual. List roles, experience, and credentials you can substantiate rather than qualifications chosen to make a page look authoritative.
    • Do not label someone a reviewer unless a meaningful review occurred. Record what the review covered internally so the label has an operational meaning.
    • If the organization is genuinely responsible for the content, say so. A truthful organizational byline is stronger than a fictional personal profile.
    • Explain how information was produced or checked when that process helps the reader judge reliability. Do not use a vague process statement to disguise absent human oversight.
    • Make publication and update dates reflect real editorial events. A new date on unchanged material is not evidence of freshness.

    Use schema as a consistency check, not a credibility generator

    Structured data can clarify the identity and relationships already visible on a page. It cannot turn a fabricated expert into a trustworthy author. Your Article, Person, and Organization markup should agree with the byline, biography, About page, editorial policy, and company details a visitor can see.

    For each important template, compare the visible page with its JSON-LD field by field. Check the author type, name, URL, publisher, publication date, modification date, and any identity links. Remove a field when you cannot support it. Do not add credentials or sameAs references merely because a schema tool offers an empty box for them.

    This catches a common trust leak: every individual statement looks plausible, but the collection does not describe one coherent entity. A shortened brand name in one place, an obsolete company description in another, and an unrelated author profile in the markup can leave both people and automated systems with avoidable ambiguity.

    Treat your chatbot as a reputation surface

    A customer faces a translucent digital kiosk as light paths connect it to a service team, with one clear path and one warning-marked path.

    A commerce or support chatbot is not only a conversion tool. It is also where customers test whether your brand’s promises survive contact with a real question. A poor bot experience can therefore affect AI search visibility as well as the immediate sale.

    The mechanism is straightforward. The bot gives an inaccurate or evasive answer. The customer cannot reach a person or verify the claim on your site. They take the question to a forum, review platform, or social conversation. The resulting public explanation may be clearer and more durable than anything you published yourself.

    Audit the bot around complete customer tasks, not isolated response quality:

    1. Select real tasks. Use recurring questions from bot logs, sales conversations, support tickets, and on-site search. Include questions that affect eligibility, pricing, returns, compatibility, security, delivery, and cancellation when those apply to your business.
    2. Run each task to its endpoint. Record the first answer, follow-up questions, linked page, escalation option, and final resolution. A friendly opening does not compensate for a dead end later in the exchange.
    3. Compare the answer with the source of truth. Check the bot against current product pages, policy pages, documentation, and the answer a trained employee would give. Flag unsupported promises and contradictions before rewriting the tone.
    4. Test the recovery path. Deliberately ask an ambiguous question, challenge an answer, and request a human. The bot should acknowledge uncertainty and provide a usable next step instead of inventing certainty.
    5. Turn recurring failures into content work. If customers repeatedly need an external discussion to understand a policy, improve the policy page and the bot’s retrieval source. Do not treat the symptom as a prompt-writing problem alone.

    Keep a simple failure log with the customer task, incorrect answer, correct answer, responsible owner, affected page, and resolution status. This connects conversion operations with reputation and AI visibility. It also prevents separate teams from fixing the bot, help center, and structured data in incompatible ways.

    Earn third-party evidence without manufacturing it

    Communities can give buyers and AI search systems context that an About page cannot. They can also expose promotional behavior quickly. The useful goal is not to plant brand mentions. It is to contribute answers that remain valuable even if the reader never clicks your profile.

    Start only after your own site is worth citing. One documented B2B SaaS workflow begins with a set of 200 to 500 SEO keywords and maps them to roughly 150 relevant subreddits. Those figures describe that operating model, not a quota every company should copy. The transferable method is to connect existing buyer questions with communities where those questions already receive substantive answers.

    Use the following participation rules to protect trust:

    • Work with real accounts. An employee can participate as a knowledgeable person, but the account should not exist solely to promote the employer. Build a genuinely useful history and disclose the relationship whenever it is relevant to the recommendation.
    • Stay with live conversations. The same practitioner team limits engagement to threads less than 20 days old because returning to old conversations can look unnatural and increase moderation risk. Treat that as a conservative operating rule from one program, not a universal Reddit ranking factor.
    • Answer the question completely. Give the useful explanation before mentioning a product. If the comment only works when the reader follows your link, it is probably promotion rather than an answer.
    • Match the community’s language. Use direct descriptions, real constraints, and relevant experience. Corporate copy and polished slogans make a comment less credible, not more.
    • Earn the right to start a thread. Original posts work better after the account has participated constructively. An AMA or a detailed solution to a recurring pain point has a clearer community purpose than a disguised announcement.
    • Do not coordinate fake praise. Sockpuppets, invented customers, and concealed affiliations create the same underlying problem as fake author profiles: apparent evidence with no truthful person behind it.

    For an active reputation program, search your brand name on Reddit every day and log the threads that introduce a new factual claim, recurring complaint, or comparison. Respond only when you can add a correction, resolution, or genuinely useful context. A defensive reply can amplify the very evidence you want to displace.

    Community work is a secondary layer. If your product facts, policies, authorship, and customer experience remain weak, more participation simply gives the weaknesses more places to surface.

    Run a trust-first AI visibility audit

    Build a fixed prompt set around the decisions your buyers actually make. Include category discovery, use-case fit, comparisons and alternatives, risk or support concerns, and direct questions about your brand. Reuse the same prompts so you can distinguish a meaningful change from a different question.

    For each run, record the platform or model, date, exact prompt, whether the brand appeared, how it was characterized, whether it was recommended, any warning language, and the cited URLs. The citation list is often more diagnostic than the mention itself because it shows which evidence shaped the answer.

    Observed patternLikely evidence gapFirst action
    Your brand is absent from an unbranded category answerThe available material may not answer that category or use case precisely enoughPublish a focused, factual answer on your own site and make its ownership clear
    Your brand is mentioned but not recommendedRelevance exists, but trust, fit, or comparative evidence is weakInspect cited alternatives, verify your claims, and identify missing proof or unresolved objections
    Your brand appears with a warningNegative experience evidence is outweighing owned claimsTrace the warning to its cited or likely origin, fix the underlying issue, and publish an accurate resolution
    The answer contains outdated or conflicting factsYour entity details, policies, or product information are inconsistentAlign visible pages, feeds, profiles, and JSON-LD around one current source of truth
    The answer cites you but describes you inaccuratelyYour page may be extractable without being sufficiently explicitRewrite ambiguous passages so the qualification, scope, and responsible entity appear together

    Prioritize by trust risk, not implementation convenience. Remove deception and factual errors first. Repair broken customer journeys next. Resolve contradictions across owned properties after that. Then strengthen missing evidence and improve schema. A markup change is quick, but it is the wrong first move when the underlying claim is false or the customer experience disproves it.

    Assign each issue to an owner who can change the root cause. Content teams can clarify a page, but they cannot repair a returns process. SEO teams can expose inconsistent entities, but they cannot validate a security claim. The audit becomes useful when it routes each trust gap to the team with authority to close it.

    Key takeaways

    • AI search visibility includes retrieval, citation, recommendation, and warning outcomes; a mention alone does not prove trust.
    • Real authorship, supportable credentials, and JSON-LD that matches the visible page give your owned claims a coherent identity.
    • Chatbot failures can become public reputation evidence, so audit complete customer tasks and escalation paths rather than tone alone.
    • Community visibility should be earned through real accounts and complete answers after your own site is worth citing.
    • Measure the language and citations around your brand, then fix deception, broken experiences, and contradictions before optimizing presentation.

    Start with a small, fixed set of buyer prompts and follow each answer back to the evidence supporting it. Fix the highest-risk contradiction you find, rerun the same prompts, and keep the record. That turns AI visibility from a mention count into a practical trust-improvement loop.

    References