Author: shivamcrushpressai

  • How to Build Marketing Visibility in Google AI Mode

    How to Build Marketing Visibility in Google AI Mode

    If your search strategy still revolves around winning one short keyword with one broadly written page, Google AI Mode exposes the weakness quickly. A person can begin with a general question, add their location, budget, use case, risk tolerance, and exclusions, then keep refining the decision. Your visibility depends on whether your content remains useful as that conversation branches.

    The practical response is not to publish more generic copy or bolt AI language onto an existing SEO plan. You need distinctive, verifiable answers for organic discovery, suitable campaign inputs for paid eligibility, and reporting that does not pretend Google gives advertisers more placement-level visibility than it does.

    What visibility in AI Mode actually requires

    AI Mode is a conversational search experience. People can describe a complicated need in one prompt and narrow it through follow-up questions. Google said in October 2025 that these questions were nearly three times longer than traditional searches. That changes the unit of optimization. The keyword still matters, but so do the constraints, comparisons, exceptions, and decisions surrounding it.

    The scale warrants attention without justifying panic. By May, AI Mode had surpassed 1 billion monthly users. Paid visibility is also material, although it varies by query set and test conditions. In one July SE Ranking analysis, text ads appeared in 29.45% of responses across 50,032 selected U.S. commercial keywords, with product carousels excluded. That figure is evidence of opportunity in that sample, not a universal ad frequency you should use in a forecast.

    Key takeaways

    • Optimize for the buyer’s decision path, not just the opening query.
    • Use AI Mode’s follow-up questions to find missing answers that ordinary competitor audits overlook.
    • Build pages from verified facts, first-party expertise, and explicit boundaries instead of interchangeable claims.
    • Treat AI Mode, AI Max, and AI Overviews as different things. AI Mode is the customer experience; AI Max is an optimization layer inside eligible campaigns.
    • Keep organic visibility, paid eligibility, and business outcomes separate in reporting. Combine them only when the data supports the connection.

    That last distinction matters. A cited page, a named recommendation, and a sponsored placement are not the same outcome. They may support the same commercial journey, but they require different inputs and cannot be measured honestly as one blended AI visibility number.

    Map the questions behind the query before rewriting a page
    An overhead desk scene shows a blank page connected by branching paths to objects representing location, budget, use case, timing, risk, and comparison questions.

    A conventional content audit tells you what competitors included. It rarely tells you what all of them omitted. If every service page repeats the same definition, benefits, and call to action, matching that pattern only makes your page another interchangeable input.

    AI Mode’s follow-up questions offer a more useful gap-discovery method. Begin with the natural-language question a serious buyer would ask, then watch where the conversation goes. Repeated branches reveal the details someone needs before they can decide, including conditions, thresholds, local differences, edge cases, and tradeoffs. Those branches can become your content map rather than an indiscriminate FAQ list.

    Run the query-branch audit

    1. Choose one commercially important page. Pick a service, product, or category page tied to a real decision. Do not begin with the entire site.
    2. Write the buyer’s opening question. Use a complete sentence that includes the problem and any context a genuine prospect would volunteer. A query such as “Which option fits a small team that needs approval controls but has no dedicated administrator?” is more revealing than a two-word category term.
    3. Record each follow-up question exactly. Preserve the wording. It shows you the terminology Google associates with the decision and the distinctions users may encounter next.
    4. Classify the branch. Mark whether it concerns suitability, cost, timing, location, requirements, risk, comparison, exception, proof, or next steps. This prevents ten differently phrased questions from becoming ten repetitive sections.
    5. Note what changes the answer. A useful answer often depends on company size, jurisdiction, product version, service area, eligibility, configuration, or another boundary. Capture that condition instead of writing a universal claim.
    6. Compare the branch with your page. Mark it answered, partly answered, unsupported, or absent. “Mentioned” is not the same as answered; a buyer should be able to understand the decision without decoding promotional language.
    7. Identify the evidence owner. Decide whether the answer belongs to a public reference, an internal record, a product owner, a practitioner, a customer-facing team, or another qualified subject-matter expert.
    8. Prioritize the gap. Give priority to questions that materially change the decision, align with the page’s intent, and can be answered with defensible evidence. A high-volume-sounding question with no reliable answer is not ready to publish.

    Follow-up questions are signals, not automatic editorial instructions. A suggested question may be irrelevant to your offer, impossible to verify, or better answered elsewhere. Your job is to interpret the branch, determine whether it affects the buyer’s decision, and then place the answer where it belongs.

    Decide whether the answer needs a section or its own page

    Add a section to the existing page when the question shares the same intent and can be answered without changing the page’s audience or promise. Create a separate page when the question represents a distinct task, requires substantial evidence, serves a materially different situation, or deserves a direct landing destination of its own.

    For example, an eligibility condition that determines whether someone can use a service probably belongs near the main answer. A detailed implementation workflow for people who have already chosen the service may deserve a supporting page. Link the two in the direction the buyer naturally moves.

    This method is especially valuable for local pages. Google has deep context about places, businesses, and nearby entities, so a city name inserted into a generic template is a weak differentiator. Useful local content explains the actual service area, process, venue, constraints, availability, and decision rules that change with location. Only publish those details when the business can verify them.

    Turn content gaps into evidence-backed answers

    A plausible sentence is not necessarily a publishable fact. The fastest way to contaminate an AI visibility program is to let an unverified inference move from a generated brief into customer-facing copy. Keep a claim register while researching and drafting so every material statement has a status.

    Claim labelWhat it means in your workflowPublishing action
    OBSERVEDThe detail was directly seen in the page, product, interface, record, or documented process under review.Save enough context for an editor to reproduce the observation.
    VERIFIEDThe claim was checked against an appropriate public reference or authoritative record.Cite the evidence and retain any scope, date, version, or jurisdiction qualifier.
    CLIENT-SUPPLIEDThe business or its subject-matter expert provided the claim.Name the internal owner, request support where needed, and do not present it as independently verified.
    INFERREDThe claim is a conclusion drawn from related information rather than a directly supported fact.Label it as interpretation or replace it with a supported statement before publication.
    UNKNOWNThe available material does not establish an answer.Turn the gap into a precise question for the responsible expert. Do not let a writing model fill it.

    This separation is not bureaucratic overhead. It allows public facts, internal evidence, and expert judgment to contribute without being mistaken for one another. A documented workflow built around these labels also prevents unsupported claims about experience, volume, outcomes, prices, or performance from slipping into a page because they sound reasonable.

    When a claim could affect someone’s legal rights, financial decision, safety, or regulatory exposure, route it to a qualified professional before publication. The downside is not merely a weak citation. An incorrect threshold or eligibility rule can cause a reader to make the wrong decision.

    Write the answer before the marketing copy

    Each prioritized branch should become an answer-first brief. Start with the direct response a buyer needs, then supply the conditions and evidence that make it trustworthy. A usable brief contains:

    • the buyer’s question in natural language;
    • a one- or two-sentence direct answer;
    • the conditions that would change that answer;
    • the supporting facts and their claim labels;
    • any unresolved question for a subject-matter expert;
    • the accuracy, legal, or version risk that needs review;
    • the intended location: existing section, new page, comparison page, or supporting resource;
    • the prompts you will use to retest visibility after publication.

    The resulting page should help a person distinguish between options. Include the thresholds, limitations, tradeoffs, and next step when the evidence supports them. Replace claims such as “tailored solutions” or “leading service” with information only the business is well placed to provide: how qualification works, what the process includes, where exceptions arise, which input the customer must supply, and when a different option is a better fit.

    Use structured data as a representation layer, not an evidence generator. Markup can express the entities and information present on a page, but it cannot turn a generic assertion into first-party expertise or resolve an unsupported claim. The visible answer and its evidence come first; the schema should accurately reflect them.

    Prepare paid campaigns without confusing AI Mode and AI Max

    AI Mode is the search experience a customer uses. AI Max is a collection of targeting and creative features applied to an existing Search campaign. It can expand matching through broad match and keywordless technology, use information from keywords, creative, and URLs, and adapt copy or destinations through text customization and Final URL Expansion. It is an optimization layer, not a separate campaign type.

    There is also no separate AI Mode campaign or placement switch. Turning on AI Max does not select AI Mode inventory. This distinction protects you from a common reporting error: attributing every performance change after an AI Max launch to AI Mode placements.

    Know which campaign routes are eligible

    Google’s original May 2025 announcement identified Performance Max, Shopping, and Search campaigns using broad match, including AI Max for Search, as eligible for AI Mode ad testing. At Google Marketing Live 2026, Google recommended AI Max for Search, AI Max for Shopping, and Performance Max for access to newer AI-powered formats; AI Max for Shopping was documented as a beta.

    A smaller experiment also allowed Search campaigns using exact and phrase match to serve text ads when an AI Mode user expressed clear, direct intent. Treat that as a limited test, not proof that conventional matching reaches every AI Mode format.

    FormatHow it appearsStatus in the cited announcement
    Existing text and Shopping adsEligible ads can appear within AI Mode responses.Testing
    Conversational Discovery adsGemini tailors creative to the user’s expressed need.Testing
    Highlighted AnswersSponsored businesses appear within recommendation lists with an AI-generated explanation alongside advertiser creative.Testing
    Direct OffersRelevant promotions can appear during shopping conversations.Pilot

    Testing and pilot status matters. A format described by Google may not be available in every account or country, and an eligible campaign is not guaranteed to appear. Confirm what your account actually exposes before building a media plan around a named format.

    Improve the inputs Google may use

    In conversational placements, your ad may sit inside a larger generated presentation. Google can use the user’s question, advertiser inputs, and landing-page context to decide what fits. Your work therefore extends beyond writing a compact headline.

    • Align the destination with the detailed need. A generic homepage is a poor continuation when the prompt includes a specific use case, constraint, or product requirement.
    • Keep product and offer information accurate. Do not rely on generated context to repair stale availability, unclear terms, or contradictory landing-page copy.
    • Make differentiators verifiable. The same first-party facts that strengthen organic content give the paid system clearer material to work with.
    • Review URL expansion deliberately. If the setting is active, make sure eligible destinations are current, appropriate, and able to convert the intent they may receive.
    • Document campaign changes. Record when AI Max, matching, creative, feeds, destinations, budgets, or conversion settings change. Avoid treating a period with several simultaneous changes as a clean AI Mode test.
    • Check the generated context when visible. Your approved creative may be only one part of the presentation. Watch for a mismatch between the reason Google gives, the promise in the ad, and the page a person reaches.

    Do not broaden matching solely to claim AI Mode participation. First decide whether the campaign has dependable conversion measurement, suitable landing pages, accurate business data, and enough control for the risk you are accepting. Eligibility is an input to the decision, not the business case by itself.

    Measure visibility without inventing AI Mode attribution
    Separate glass channels carry search, citation, campaign, and purchase signals toward measurement instruments without directly connecting them.

    Google currently gives advertisers limited ability to isolate and measure ads within AI Mode. That constraint should shape your dashboard and the language you use with stakeholders. If the interface does not identify the placement, label the result unknown rather than assigning it to AI Mode because a campaign was eligible.

    Build a controlled query set

    Maintain a compact set of commercially meaningful prompts for each priority topic. Include the opening buyer question, a local or operational constraint, a comparison, an exception, and a late-stage next-step query. Run the same set repeatedly so you can notice changes in answer coverage instead of collecting unrelated screenshots.

    For each observation, record:

    • the exact prompt and follow-up path;
    • the market, device context, and date of the check;
    • whether your brand or page appeared;
    • whether it appeared as a cited resource, named option, direct link, or sponsored result;
    • the claim or passage used to represent the business;
    • the destination page;
    • any inaccurate, outdated, or missing context;
    • the next content or campaign action, if the observation is reproducible and material.

    Call this an observation log, not a ranking report. Conversational answers can vary with wording and follow-up context, so a single appearance is not a permanent position. The log becomes useful when the same gaps or representations recur across your controlled query set.

    Keep three layers of reporting separate

    • Answer visibility: Are your pages and brand present for the questions that matter, and are they represented accurately?
    • Paid readiness and delivery: Are campaigns eligible, are advertiser inputs sound, and what delivery can the available Google Ads reporting actually verify?
    • Business outcomes: What qualified visits, leads, sales, revenue, or other approved conversion signals reached the business?

    Use these layers to make bounded decisions. If an important branch is repeatedly unanswered and your page lacks the information, you have a content gap. If the brand appears for the wrong use case, clarify its fit and exclusions. If an eligible campaign improves after several settings changed, report the campaign-level change but do not call it AI Mode return on ad spend without placement-level evidence. If traffic arrives but fails to progress, inspect the promise-to-page match before expanding reach.

    Start with one high-value page and one natural-language buyer question. Map its branches, resolve the most consequential unknown with the right expert, publish the direct answer, and retest the same path. Once the organic evidence is sound, evaluate paid eligibility as a separate decision. That small operating loop will teach you more than a sitewide rewrite built on assumptions.

    References


  • Healthcare AI Search Visibility: A Practical AEO Plan

    Healthcare AI Search Visibility: A Practical AEO Plan

    Your health system may rank well for a service and still be absent when a prospective patient asks an AI assistant where to go, who provides the service or what happens next. Adding another FAQ block does not, by itself, close that gap. Your pages must be easy to retrieve, unambiguous about people and places, and safe enough to reuse in a health-related answer.

    The practical goal is to make accurate passages and verified organizational facts available at the moment an AI system needs them. That is how you work toward earning AI citations and patient recommendations without turning medical content into promotional copy.

    Key takeaways

    • Organize the work around patient questions and decisions, not a list of high-volume keywords.
    • Give each important fact one authoritative home, then keep supporting pages and external profiles consistent with it.
    • Write answer-ready passages that preserve clinical qualifiers, geographic limits, eligibility rules and clear next steps.
    • Use structured data to clarify entities and relationships, not to repeat keywords or make claims that visitors cannot see.
    • Measure citations, factual accuracy and entity matching with a fixed prompt set; referral traffic alone cannot show whether an AI answer represented you correctly.

    Start with the patient decision, not the keyword

    A keyword list tells you what people type. It does not tell you which decision they are trying to make or which fact an AI answer must retrieve. Start with a specific service line and map the questions that affect discovery, access and preparation.

    Your question inventory should include the language a patient or caregiver would actually use. Useful patterns include:

    • Does this organization provide the service I need?
    • Which location provides it?
    • Which department or type of specialist handles it?
    • Is a referral or prior step required?
    • Who is eligible, and what important exceptions apply?
    • How do I prepare for an appointment or procedure?
    • What should I expect afterward?
    • How do I schedule, call or find the correct location?
    • Which concerns require advice from a clinician or urgent assistance?

    Do not answer these from the search team’s memory. Turn the inventory into a working sheet with one row per question and fields for the responsible department, approved answer, canonical page, geographic scope, clinical reviewer, review trigger, risk level and intended next action. A blank field is a useful finding: it shows that the organization has not yet established an answer that a person or machine can reliably use.

    Then assign each question one authoritative destination. If referral requirements appear differently on a physician profile, a service page and a location page, polishing all three versions creates three polished conflicts. Decide which page owns the fact. Supporting pages should summarize it consistently and link to the canonical explanation.

    Prioritize gaps by consequence. A missing parking detail is inconvenient. An outdated location, an incorrect eligibility statement or ambiguous urgent-care language can interfere with access or safety. Fix the facts with the greatest patient impact before expanding into broader educational coverage.

    Make each answer quotable without making it unsafe

    A clinician and content specialist review an abstract answer card alongside source and safety verification symbols.

    An answer-ready passage is not merely short. It is self-contained enough to survive extraction from the surrounding page. A reader should still know who the answer concerns, where it applies, what the limits are and what to do next.

    Use this test on every passage that answers an important patient question:

    • Does the first sentence answer the question directly?
    • Does it name the facility, department, service or population instead of relying on vague words such as “we,” “here” or “this treatment”?
    • Does it retain eligibility conditions, geographic limits and meaningful exceptions?
    • Does it distinguish general education from advice for an individual patient?
    • Does it identify a safe next action, such as contacting the relevant department or consulting an appropriate licensed professional?
    • Can an editor identify who approved the claim and what event should trigger a new review?

    Compare “We offer this treatment at several locations” with a more usable template: “The [named department] provides [named service] for [defined population] at [named locations], subject to [referral, eligibility or scheduling conditions].” The second version carries its context with it. Populate that template only with verified facts from the responsible operational and clinical owners.

    Do not remove a medical qualifier to make a sentence sound more decisive. Content about symptoms, diagnosis, medication, procedure eligibility, recovery or emergency thresholds needs clinical review. If a general page cannot safely resolve an individual situation, say that plainly and direct the person to the appropriate type of licensed professional or emergency resource. Search visibility is not a substitute for medical assessment.

    Separate three content layers that are often mixed together:

    • Stable organizational facts: official names, locations, departments, contact routes and service relationships.
    • Operational facts: availability, referral processes, scheduling instructions and other details that may change when workflows change.
    • Clinical information: benefits, limitations, eligibility, preparation, recovery and safety information that requires clinical ownership.

    Give each layer an appropriate review trigger. A clinician leaving, a location closing, a service moving or a referral process changing should prompt an update even if the page has not reached its routine review date. The date displayed on a page is not evidence of freshness unless someone is accountable for the facts behind it.

    Build an entity layer that removes avoidable ambiguity

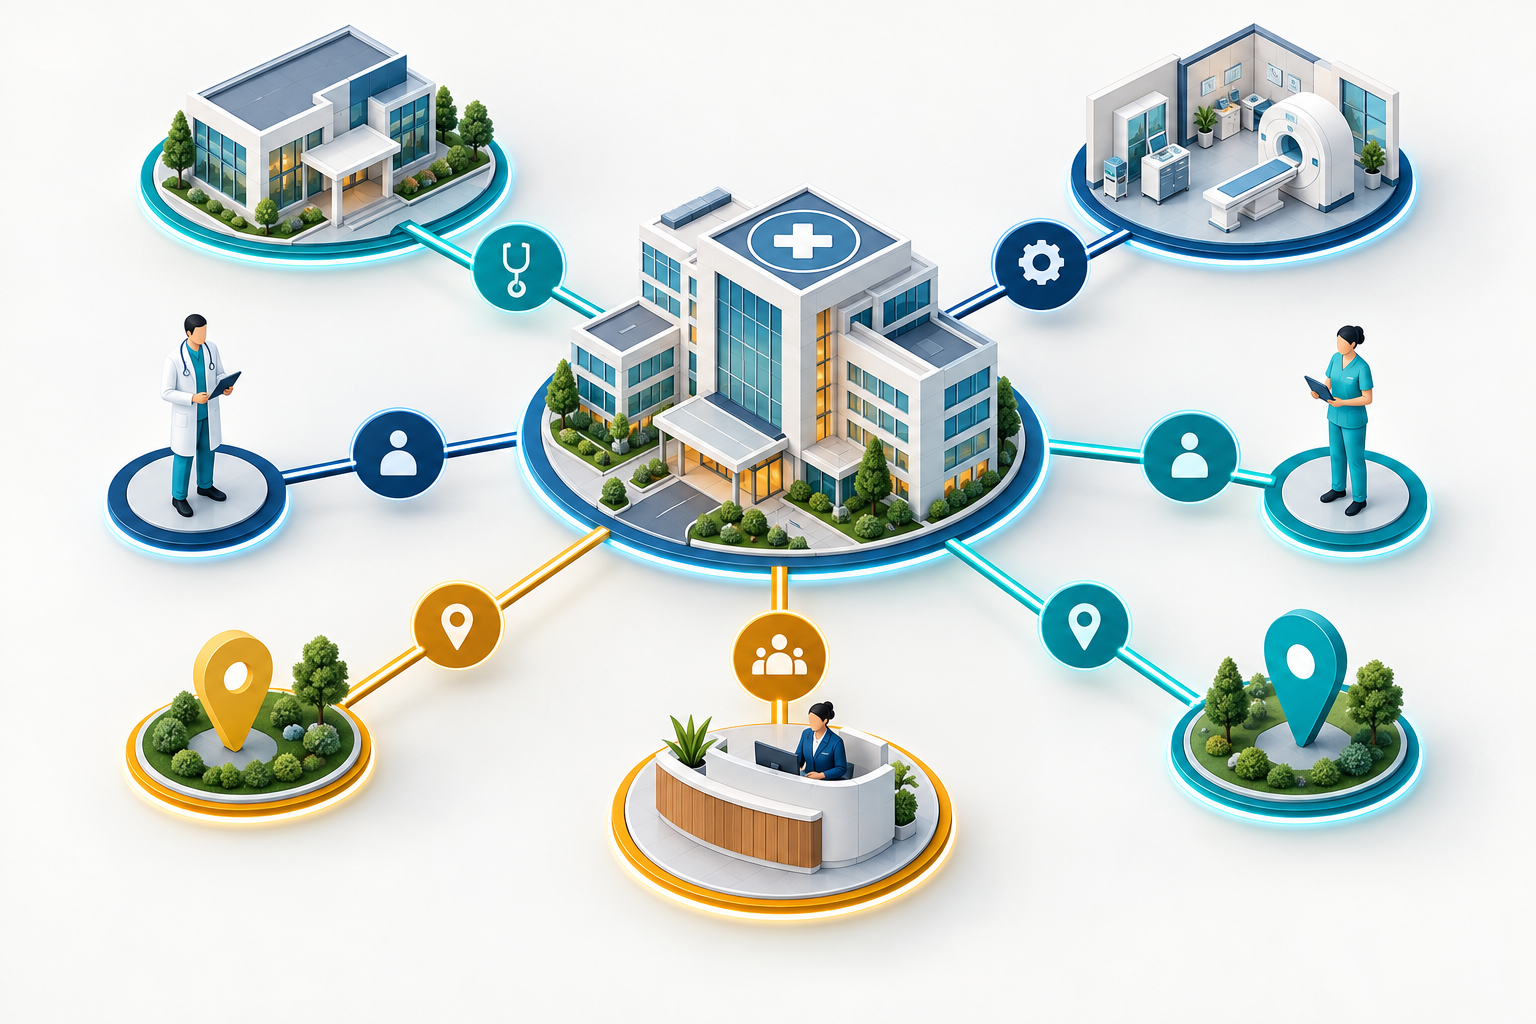
    An isometric healthcare campus network connects a hospital with clinics, clinicians, services and locations.

    A health system is not one entity. It may contain a parent organization, hospitals, clinics, departments, physicians, service lines and locations with similar names. Your site should make those relationships explicit so that a machine does not have to infer whether two pages describe the same facility or two different ones.

    Create a canonical entity record for every organization, location, department and clinician you publish. At minimum, settle the official name, approved alternate names, canonical URL, organizational parent, physical location, contact route and the services or roles genuinely associated with that entity. Use the same record to inform page copy, navigation, internal links, directories and structured data.

    For JSON-LD, choose the most specific valid Schema.org type supported by the visible page, such as Hospital, MedicalClinic, MedicalOrganization or Physician. Give each entity a stable identifier, reuse that identifier wherever the same entity appears, and connect related entities instead of creating isolated markup fragments.

    • A physician page should identify the person and connect that person to the correct organization, department or location where the relationship is supported.
    • A location page should describe that location, not silently inherit every service offered anywhere in the health system.
    • A service page should name the organization and locations that actually provide the service.
    • Structured data should match visible, current content. Do not add claims, ratings, specialties or service availability that a visitor cannot verify on the page.
    • Validate both the JSON-LD syntax and the rendered page after publishing. A valid block in a content-management field is not useful if a template, script or deployment process removes it from the delivered page.

    Structured data can reduce ambiguity; it cannot guarantee an AI citation or turn a weak claim into reliable evidence. Treat it as an entity-control layer that supports clear content, not as a separate ranking campaign.

    Check the external records you can correct as well. Compare your canonical entity data with map listings, professional profiles, major directories and other trusted surfaces relevant to the organization. Record discrepancies by field rather than writing “listing inconsistent” in an audit. “Old phone number on profile X” gives someone a concrete correction to make.

    Measure retrieval, citation and accuracy separately

    Analytics can show visits that reach your site. They cannot show every answer in which your organization was omitted, confused with another provider or described inaccurately. You need a controlled prompt set in addition to web analytics.

    Build that set from the question inventory. Include discovery questions, location questions, access questions and questions about the service itself. Keep the wording stable enough to compare runs. For every test, record the exact prompt, AI product or model, date, relevant location or account context, response, cited URLs and screenshots or saved output where permitted.

    Classify each result before choosing a fix:

    • Not retrieved: your organization and pages do not appear in the answer or citations.
    • Wrong entity: the response blends two locations, clinicians or organizations.
    • Retrieved but not selected: your page appears relevant to the question, but the final answer relies on another source.
    • Cited but inaccurate: the response cites your domain while stating a fact incorrectly or without a necessary qualifier.
    • Accurate but incomplete: the response gets the core fact right but omits the information required to act safely.
    • Actionable and supported: the response is accurate, preserves essential limits, points to an appropriate next step and cites a relevant page.

    These labels stop the team from prescribing the same remedy for every failure. A wrong-entity result calls for clearer naming, relationships and identifiers. An accurate but incomplete answer calls for a better passage. A citation to an outdated page calls for consolidation, correction or deprecation of the stale URL.

    Track a small group of interpretable measures:

    • Citation coverage: tracked prompts that cite an approved page divided by eligible prompts tested.
    • Accurate-answer rate: reviewed responses that pass your factual checklist divided by all reviewed responses.
    • Entity-match rate: responses that connect the correct organization, location and clinician or department divided by responses where those relationships matter.
    • Owned-source rate: answers citing a controlled organizational domain divided by answers containing any citations.
    • Correction latency: the time between finding a material error and correcting the responsible page or data record.

    Define the checklist before reviewing results. Otherwise, the standard tends to move when a prominent brand mention looks encouraging. A mention is not a success if the location is wrong, the service is unavailable there or the wording drops a clinically important limitation.

    Turn the audit into a controlled publishing workflow

    Do not begin with a sitewide rewrite. Choose one service line where the facts can be verified and where an inaccurate answer would have a meaningful patient or operational consequence. Then move through the work in a fixed order:

    1. List the real patient questions and assign each one an accountable answer owner.
    2. Run a baseline prompt set and save the responses, citations and entity errors.
    3. Resolve conflicts in names, locations, service availability, access requirements and contact routes.
    4. Give each important answer a canonical page and rewrite its key passage so it remains accurate when extracted.
    5. Connect people, facilities, departments and services through navigation, internal links and valid structured data.
    6. Complete clinical, operational and compliance review according to the risk of the claim.
    7. Publish the changes with a change log that identifies what changed, where and why.
    8. Run the same prompts again under comparable conditions and classify the results with the same checklist.
    9. Move the verified facts and reusable patterns into the next service line only after the workflow itself is working.

    Assign four forms of ownership even if one person fills more than one role: a content owner for the page, a clinical or operational owner for the claim, an entity-data owner for names and relationships, and a measurement owner for the prompt set. Without named ownership, a visibility problem can sit between SEO, clinical, compliance and web teams while each group assumes another one is handling it.

    Do not claim causation from one changed response. AI outputs can vary, and multiple web changes may occur between tests. Keep the prompt and review criteria stable, log every material site change, and look for repeated improvement before treating an intervention as proven.

    Start with one service line, one verified entity record and the questions that most affect a patient’s next step. When those answers are accurate, extractable and properly connected, you have a repeatable operating model for healthcare AI visibility rather than a collection of speculative optimizations.

    References


  • AI Product Discovery Tracking: A Practical Measurement Plan

    AI Product Discovery Tracking: A Practical Measurement Plan

    You can rank well in traditional search, maintain a complete product feed, and still have no clear answer to a basic question: when someone asks an AI assistant what to buy, does your product appear?

    AI product discovery tracking closes that gap. It records how individual products appear in shopping-oriented answers, separates visibility from accuracy, and gives you evidence for deciding what to fix. The goal isn’t to collect screenshots of flattering mentions. It’s to understand which SKUs enter the recommendation set, under which buying conditions, and what happens next.

    Track the buying decision, not a single brand mention

    A brand-level visibility score is too blunt for ecommerce. An assistant can mention your company while recommending the wrong product, an unavailable variant, or an item that doesn’t satisfy the shopper’s constraints. That mention looks positive in a dashboard but does little for the buyer.

    Use the SKU, or the most stable product identifier available, as the primary measurement unit. Connect each observation to the exact prompt, platform, market, date, product variant, cited page, merchant, and answer text. This lets you distinguish a product-level problem from a broad brand problem.

    The relevant measurement surface is also wider than one chatbot. Commercial monitoring is now offered for SKU-level visibility across ChatGPT Shopping, Alexa for Shopping, Perplexity, and Google AI Mode. Keep results separate by platform. Combining them into one score too early can hide the fact that a product is consistently discoverable in one environment and absent in another.

    For every observed answer, classify five different outcomes:

    • Presence: Did the brand, product family, or exact SKU appear?
    • Prominence: Was it a primary recommendation, a secondary option, or a passing reference?
    • Qualification: Did the answer connect the product to the shopper’s stated use case, budget, features, or constraints?
    • Representation: Were the name, variant, attributes, availability, and other offer details accurate?
    • Handoff: Did the answer provide a citation, merchant, product page, or another usable route toward purchase?

    These outcomes answer different questions. Presence tells you whether the product entered the answer. Qualification tells you whether the system understood why it fits. Representation reveals whether the underlying product information is coherent. Handoff shows whether visibility can plausibly lead somewhere useful.

    Build the measurement specification before choosing a tool

    A tracker can automate collection, but it can’t decide what your business means by visibility. Write the measurement specification first. Otherwise, a vendor’s default prompts and scoring system will quietly become your strategy.

    1. Create a product identity registry. Give every tracked item a canonical name and identifier. Add brand names, model names, common aliases, parent-child variants, canonical product URLs, and the merchants authorized to sell it. This prevents a shortened model name or alternate spelling from being counted as a different product.
    2. Define the eligible product set for each prompt. A recommendation is only meaningful if the SKU could reasonably satisfy the request. If a prompt requires a feature the product doesn’t have, its absence isn’t a visibility failure.
    3. Group prompts by buyer intent. Keep category discovery, feature-led discovery, problem-led questions, comparisons, branded validation, and purchase-ready requests in separate groups. A product that performs well on branded prompts but disappears from category discovery has an acquisition problem that a blended score will conceal.
    4. Record the test environment. Store the platform, location or market setting, language, session state when controllable, device context when relevant, and collection time. If a condition can’t be controlled, label it unknown rather than assuming consistency.
    5. Freeze a core prompt panel. Run the same core prompts repeatedly so changes are comparable. Maintain a separate exploratory panel for emerging language, new use cases, seasonal needs, and questions discovered in customer research.
    6. Define what counts before collecting results. Decide how aliases, bundles, parent products, variants, repeated mentions, unordered lists, and cited merchant pages will be handled. Apply those rules to your brand and competitors alike.

    Prompt wording needs particular care. “Best running shoe” and “running shoe for a wide forefoot on wet pavement” don’t represent the same decision. The second prompt supplies constraints that can change which products are eligible. Preserve those constraints in your reporting instead of collapsing everything into a generic keyword.

    Don’t let exploratory prompts replace the fixed panel. New prompts improve coverage, but changing the entire prompt set between measurement periods destroys comparability. Use the fixed panel to detect movement and the exploratory panel to find new opportunities.

    Use a scorecard that keeps visibility, accuracy, and outcomes separate

    No single metric can represent the whole discovery journey. A useful scorecard shows where a product was eligible, whether it appeared, how it was described, and whether the answer created a usable path forward.

    MetricHow to calculate itWhat it helps you decide
    Eligible prompt coverageEligible prompts containing the tracked SKU divided by all prompts for which that SKU was eligibleWhether the product enters relevant recommendation sets
    Recommendation shareRecommendations of the tracked product divided by all product recommendations in the same prompt setHow often your product appears relative to alternatives
    Primary recommendation rateAnswers treating the SKU as a leading option divided by answers mentioning itWhether mentions are prominent or incidental
    Qualification rateMentions that accurately connect the SKU to the prompt’s constraints divided by all SKU mentionsWhether the system understands the product’s relevant use cases
    Attribute accuracy rateVerified product claims divided by all checkable claims made about the SKUWhether conflicting or incomplete product information needs attention
    Handoff rateSKU mentions with a usable citation, merchant, or product destination divided by all SKU mentionsWhether discovery can progress toward consideration or purchase
    Competitor overlapEligible prompts where your SKU and a named competitor both appear divided by eligible prompts where either appearsWhich products compete in the same answer contexts
    Downstream engagementObserved visits and commerce events attributed to an identifiable AI handoffWhether measurable discovery activity contributes to business outcomes

    The denominator matters. If you calculate coverage across prompts where a product couldn’t satisfy the stated need, you manufacture a weakness. If you count every brand mention as a product recommendation, you manufacture success. Keep the eligibility rules visible next to the score.

    Preserve the underlying observations as well as the aggregate metrics. Store the returned product names, supporting language, cited URLs, merchants, competing products, and factual errors. When a score changes, you should be able to inspect the answers behind it.

    Keep business outcomes in a separate layer. An AI mention isn’t a sale, and a sale that follows an AI interaction may not be fully attributable. Where a link, referral, or tagged destination is observable, connect it to product views, cart activity, and purchases. Where the handoff can’t be observed, report the outcome as unknown. Turning unknown activity into zero activity makes the dashboard look precise while reducing its usefulness.

    Diagnose whether the failure is eligibility, selection, or representation

    A three-stage product recommendation pipeline filters products, selects a smaller group, and displays them in translucent answer cards.

    A missing product doesn’t tell you why it was omitted. The output gives you a symptom, not a causal explanation. Use it to form a testable hypothesis, then inspect the product information and competitive context that could support or contradict that hypothesis.

    Eligibility failure: the product isn’t understood as a candidate

    If the SKU is absent from non-branded prompts even though it genuinely meets their constraints, check whether its identity and qualifying attributes are expressed consistently. Review the visible product page, structured data, commerce feeds, variant records, category assignments, and merchant listings. Names, identifiers, sizes, colors, prices, availability, and feature claims shouldn’t contradict one another.

    JSON-LD belongs in this audit, but don’t treat schema as a magic visibility switch. Its job is to express product information in a machine-readable form. It should match the visible page and the current offer data. If the markup describes a different variant or stale availability, adding more markup compounds the ambiguity.

    Selection failure: the product is known but rarely recommended

    A product may appear for branded validation prompts yet lose generic category, comparison, or problem-led prompts. That pattern suggests the system can identify the item but doesn’t consistently connect it to the buyer’s decision criteria.

    Build a gap matrix from the actual answers. Put the prompt constraints in rows and the recommended products in columns. Record the reasons given for each recommendation. Then compare those reasons with claims your product can substantiate. If an important, verifiable attribute is missing from your product page or expressed only in an image, make it clear in the visible copy and structured product information. If your product doesn’t meet the criterion, don’t manufacture a claim to fit the prompt.

    Representation failure: the product appears with incorrect details

    Incorrect model names, mixed variants, stale offer details, or unsupported attributes are not positive visibility. Capture every checkable claim in the answer and compare it with the canonical record. Then locate conflicts across the pages, feeds, markup, and merchant data you control.

    Correct the canonical product information before trying to increase mention volume. More exposure for a misrepresented SKU can send a shopper toward the wrong variant or create expectations the product can’t meet. Keep a record of the incorrect answer and the correction date so later observations can be evaluated against the change.

    Turn tracking into a controlled optimization loop

    An unbranded product sits at the center of a circular testing and optimization process with inspection, measurement, adjustment, and verification stations.

    AI outputs can vary between runs, so a single before-and-after query is weak evidence. Treat optimization as repeated observation around a documented change.

    1. Capture the baseline. Run the fixed prompt panel and preserve the complete responses, not just the calculated scores.
    2. Choose one failure class. Decide whether you’re testing product identity, attribute completeness, use-case relevance, comparison content, offer consistency, or another specific hypothesis.
    3. Change one information layer where practical. If you rewrite the page, replace the feed, alter structured data, and change merchant listings simultaneously, you may improve visibility without learning which correction mattered.
    4. Log the deployment. Record the affected SKU, URLs, fields, platforms, markets, and publication time. Include rollbacks and feed errors in the same log.
    5. Repeat the same core observations. Keep prompts, eligibility rules, and classification logic stable. Evaluate whether the direction of change persists across repeated collections.
    6. Compare unaffected products. Similar movement across changed and unchanged SKUs may indicate broad output variation or a platform-level shift rather than the effect of your work.
    7. Promote only durable findings. When an improvement continues to appear under the same measurement conditions, apply the lesson to other eligible products and keep monitoring for representation errors.

    Report platform results independently and segment them by intent. A gain in branded prompts doesn’t prove stronger category discovery. A gain on one assistant doesn’t prove that another system changed. The useful reporting unit is the intersection of platform, market, intent group, and SKU—not an unsupported universal visibility score.

    Competitor tracking should support diagnosis rather than imitation. Note which products recur, which buyer constraints they are associated with, what supporting pages are cited, and where their descriptions are inaccurate. This reveals the information standards operating within a prompt set. It doesn’t prove that copying a competitor’s wording, markup, or content structure will reproduce its visibility.

    Key takeaways for a tracker you can trust

    • Measure exact products and variants, not brand mentions alone.
    • Define SKU eligibility for each prompt before treating an omission as a failure.
    • Separate presence, prominence, qualification, factual accuracy, handoff, and business outcomes.
    • Keep a stable core prompt panel for comparison and a separate exploratory panel for discovery.
    • Preserve raw answers and cited destinations so every aggregate score can be audited.
    • Use observed outputs to form hypotheses; don’t claim they reveal a ranking system’s hidden cause.
    • Audit visible content, structured data, feeds, and merchant records for consistency when product identity or attributes are wrong.
    • Evaluate changes through repeated observations and unaffected comparison products, not one favorable response.

    Start with a narrow set of commercially important SKUs and the prompts for which they are genuinely eligible. Build the identity registry, freeze the core panel, and collect a baseline before editing anything. Your first useful result won’t be a universal visibility score. It will be a defensible answer to which product is missing, where it is missing, and what evidence you need to test next.

    References


  • How to Choose a Robotics SEO Agency for Search and AI

    How to Choose a Robotics SEO Agency for Search and AI

    You are not hiring someone to make a robotics blog busier. You are choosing who will translate technical products, applications, integrations, and proof into pages that engineers trust, buyers can navigate, and search systems can understand.

    The right agency depends less on a league-table position than on your actual constraint. You may need deeper robotics fluency, stronger search execution, an AI visibility program, a new industrial website, or a broader B2B marketing partner. Identify that constraint first, then make every finalist prove it can remove it.

    Key takeaways

    • Choose an agency model before choosing an agency. SEO/GEO specialists, engineering marketing firms, full-service B2B agencies, and industrial web firms solve different problems.
    • Test technical accuracy with a paid assignment based on a real product or application. A polished generic sample does not show whether the team can handle your terminology, evidence, and commercial intent.
    • Score search performance and robotics expertise separately. High rankings do not prove that an agency can produce content your engineers will approve or your prospects will use.
    • Require distinct SEO and generative engine optimization measurements. The work can share a content plan, but rankings, qualified organic conversions, AI mentions, citations, and referral traffic are not interchangeable metrics.
    • Put roles, review responsibilities, account access, content ownership, correction procedures, and reporting definitions into the agreement before production begins.

    Choose the agency model before you compare agencies

    A decision-maker compares three visual pathways leading to a robot component, representing technical, search-focused, and integrated agency models.

    Your practical options fall into four models. The named 2026 field includes eight agencies, but their operating models matter more than their order.

    Agency modelCandidates to investigatePut this model on your shortlist whenWhat you must verify
    SEO and GEO specialistFirst Page Sage, Driven Metrics, GenevateOrganic discovery across conventional search and generative platforms is the central assignment.Robotics fluency, writer credentials, technical review requirements, and evidence connecting visibility to qualified pipeline.
    Engineering or industrial marketing specialistTREW Marketing, Gorilla 76Your team needs technical content and wider industrial positioning, branding, or demand-generation support.Who owns technical SEO, search-intent analysis, authority development, structured data, and AI visibility measurement.
    Full-service or regional B2B agencyWalker Sands, Motion MarketingYou need a broader B2B program, or regional fit in the UK and Europe is a meaningful requirement.Whether SEO has dedicated leadership and resources rather than being a small component inside a larger account.
    Industrial web and positioning partnerWindmill StrategyA website rebuild, industrial user experience, and market positioning are tied to the search project.The content, authority, conversion, and measurement program that continues after the new site launches.

    Start with the bottleneck. If engineering spends most of its time correcting outsourced copy, favor technical specialization. If good technical material already exists but qualified prospects cannot find it, favor search execution. If the website cannot express product relationships or route different buyers to the right next step, address information architecture before funding a large publishing schedule.

    Do not treat GEO as a decorative add-on. If AI discovery matters to your buyers, the agency should be able to explain which questions it will monitor, which pages should become citable answers, how it will record mentions and cited URLs, and how that activity connects to your commercial funnel. A logo slide that lists ChatGPT or AI search is not a strategy.

    One conflict deserves explicit treatment: First Page Sage created the ranking that places First Page Sage first. Its grades and review snippets are useful for finding candidates, but they are not independent validation. Apply the same evidence request to every firm, including the evaluator.

    Test whether the team can support a technical buying decision

    Robotics search is not one market. A company may need to reach people researching industrial robots, collaborative robots, machine vision, robotic components, automation applications, autonomous navigation, or AI-powered robotics. Those are not interchangeable keyword groups. Each can involve different buyers, technical questions, objections, evidence, and conversion paths.

    This is where generic content programs break. An agency can produce grammatically clean pages while confusing a component with a complete system, overlooking an integration constraint, mixing educational and transactional intent, or sending an engineer to a call-to-action meant for an executive buyer. Traffic does not repair that mismatch.

    Require a product-to-query map

    Before approving a content calendar, ask the agency to map your real offer into page roles. The map should show how a prospect moves from a problem or application to a technology, a product, credible proof, and an appropriate next step.

    • Product and category pages should establish what you sell, who it is for, where it fits, and which technical claims can be supported.
    • Application pages should connect a real operating problem to the relevant system without pretending that every deployment has the same requirements.
    • Technology pages should explain important mechanisms, components, software, sensing, navigation, or integration concepts in language that remains technically defensible.
    • Evaluation pages should help a buyer compare approaches, specifications, implementation requirements, and tradeoffs without manufacturing a false winner.
    • Proof pages should make case evidence, technical documentation, certifications, test information, and deployment details easy to locate when those materials exist.
    • Conversion paths should match intent. A buyer who needs documentation, an integration discussion, or a system assessment should not be forced through the same generic contact form.

    Reject a proposal that turns this architecture into a pile of loosely related blog topics. Informational content can create discovery, but the program also needs pages that explain the offer, resolve evaluation questions, establish evidence, and let a qualified prospect act.

    Run a paid proof-of-work assignment

    Portfolio samples show what survived another client’s approval process. They do not reveal how the agency handles your technology. A contained paid assignment is a fairer test for both sides.

    1. Select a commercially important product, category, or application page. Use something technical enough to expose weak reasoning, but remove confidential material.
    2. Give every finalist the same brief, approved terminology, existing evidence, target audience, and business objective.
    3. Ask for a search-intent assessment, proposed outline, representative passage, internal-link recommendations, conversion step, and a list of questions or unsupported claims that require expert review.
    4. Have marketing, product, engineering, and sales review the work independently. Each group should mark factual errors, missing buyer questions, unclear positioning, and commercially irrelevant material.
    5. Compare not only the finished prose but also the questions each agency asked. A team that identifies uncertainty is safer than one that fills knowledge gaps with confident language.

    Use hard gates. An invented capability, altered specification, unsupported performance claim, or fabricated customer outcome should fail the test. So should a page with no identifiable audience or next step. Minor editing is normal; rebuilding the technical logic is evidence that your subject-matter experts will become unpaid ghostwriters for the agency.

    Score SEO and GEO as connected but different jobs

    A robot connects to a search network on one side and an AI source network on the other through a shared technical knowledge core.

    You can borrow a transparent starting scorecard from the market: ranking proficiency at 25%, robotics expertise at 20%, content execution at 20%, client ratings at 15%, SEO specialization at 10%, and a GEO offering at 10%. Those dimensions expose useful differences, but they should not make the decision for you.

    • Ranking proficiency asks whether the agency can earn meaningful search visibility, not merely publish optimized pages.
    • Robotics expertise asks how quickly the team can understand your technology, language, ecosystem, and buyer concerns.
    • Content execution asks whether the agency can turn that understanding into accurate, useful, discoverable material.
    • Client ratings can surface communication and delivery patterns, but references should be checked directly and matched to work similar to yours.
    • SEO specialization indicates whether organic search is a central discipline or one service inside a much broader portfolio.
    • GEO capability asks whether the agency has a defined approach to discovery and citation in generative platforms rather than a newly relabeled content package.

    Add four pass-or-fail criteria before you total any score: commercial relevance, measurement quality, operating fit, and ownership. A highly rated firm is still the wrong choice if it cannot connect work to your ideal customer profile, fit your expert-review capacity, expose how results are measured, or leave you in control of your assets.

    Demand separate measurement plans

    SEO and GEO can use the same underlying knowledge, pages, proof, and authority signals. They should not be collapsed into a single visibility number.

    • For SEO, require reporting by query family and landing-page group. Track relevant visibility, qualified organic actions, sales acceptance, opportunity creation, and pipeline where your systems allow it.
    • For AI discovery, define a repeatable set of buyer questions. Record the platform, prompt, date, brand mention, cited domain, cited landing page, competitor presence, referral traffic when identifiable, and any resulting qualified action.
    • For technical health, monitor whether important pages can be crawled, indexed, understood, internally linked, and kept aligned with the site’s visible structured information.
    • For content operations, monitor approval delays, substantive factual corrections, revision causes, and the amount of subject-matter-expert effort required for each deliverable.

    Ask to see how reporting changes a decision. If a dashboard cannot tell the team what to update, consolidate, expand, stop, or promote, it is record-keeping rather than management.

    Keep schema in its proper role

    A robotics SEO agency should understand structured data, but schema markup cannot rescue vague positioning or unsupported technical claims. Ask how the agency will keep company names, product relationships, applications, specifications, authorship, and other visible facts consistent between page copy, structured data, internal links, and external profiles.

    Reject promises that markup alone will create rankings or AI recommendations. The useful test is whether structured data accurately represents visible, maintained content and makes important entities and relationships less ambiguous. It should be part of technical implementation and governance, not a substitute for evidence-rich pages.

    Contract for the operating model, not the pitch

    The sales team can sound technically fluent while the delivery team operates very differently. Before signing, ask for the proposed strategist, project lead, writer, editor, technical SEO owner, analytics owner, and backup coverage. If names are not yet available, require role descriptions, relevant backgrounds, allocation expectations, and the process for approving replacements.

    Define the review workflow

    • State who interviews subject-matter experts, prepares questions, records approved terminology, and maintains the factual brief.
    • Separate factual approval from brand editing. Engineers should not have to rewrite tone, headings, metadata, calls to action, or basic page structure.
    • Define what counts as a deliverable: a draft in a document is different from a published, internally linked, quality-checked page with appropriate metadata and structured information.
    • Create a correction path for technical errors. Specify who pauses publication, who approves the correction, and how related pages are checked for the same mistake.
    • Agree on how changes in products, specifications, positioning, regulations, or supporting evidence reach the content team and trigger updates.

    Your internal capacity should influence the choice. A search specialist that expects substantial client expertise may work well when product marketers and engineers can support it. The same arrangement will stall if experts are unavailable or if every draft becomes a reconstruction project. Make that workload visible in the proposal rather than discovering it after the content calendar starts.

    Protect access, ownership, and continuity

    Confirm in the agreement who owns commissioned content, keyword and prompt maps, reporting files, creative assets, analytics configurations, structured-data work, and any custom tooling. Keep company-controlled access to the CMS, analytics, search accounts, tag management, domain, hosting, and relevant AI-monitoring systems. Losing those assets or permissions can make an agency transition expensive and slow, so have the appropriate internal or legal reviewer check the final terms.

    Also define what happens when performance disappoints. The agency should be able to diagnose whether the constraint is technical, competitive, editorial, authoritative, commercial, or operational. A useful review ends with a decision and an owner, not another month of unchanged production.

    Before your next agency call, choose a real commercial page and a real family of buyer questions. Send the same sanitized assignment to each finalist and compare the returned reasoning, not just the presentation. The strongest candidate will expose uncertainty, protect technical accuracy, connect discovery to a buying decision, and define measurement before promising growth.

    References


  • Google Ads AI Creative Previews and CTR Benchmarks for 2026

    Google Ads AI Creative Previews and CTR Benchmarks for 2026

    You have a set of polished AI-generated headlines in front of you, but no reliable answer to the question that matters: will enabling them improve the campaign, or simply attract more of the wrong clicks?

    Use the AI Max preview and your clickthrough rate benchmark for different jobs. The preview is a pre-launch accuracy and positioning check. CTR is a post-launch response signal. When you keep those roles separate, you can test automation without mistaking plausible copy for proven performance.

    Key takeaways

    • AI Max can preview up to 10 generated headlines and descriptions from a final URL before you enable text customization.
    • The preview shows possible messaging, not the exact assets that will appear in live auctions.
    • A 2.1% CTR is a 2026 blended benchmark for the first search-ad position, not a universal Google Ads target.
    • Placement, ad format, industry and the presence of an AI-generated search answer can materially change the benchmark you should use.
    • Do not approve AI creative on CTR alone. Accuracy, conversion quality and the business value of those conversions remain the decision criteria.

    What the AI Max preview can actually tell you

    Google Ads is adding a preview that can produce up to 10 example headlines and descriptions in approximately 30 seconds. You enter the campaign’s final URL, and Google AI uses that landing page to create the samples. You do not have to enable text customization first.

    Where the option is available, you can find it under Asset optimization while creating a Search campaign or editing an existing one. It supports the languages already supported by text customization and most business categories, while adult content is excluded.

    The useful question is not, “Do these ads sound good?” It is, “What does Google appear to believe this page is offering, to whom, and on what terms?” That shift turns the preview into a diagnostic tool.

    A preview can help you notice:

    • Which benefits and product attributes Google treats as central.
    • Whether the landing page communicates a clear audience, use case and point of difference.
    • Whether important qualifications disappear when the offer is compressed into ad copy.
    • Whether the generated language fits your brand voice or drifts into generic advertising phrases.
    • Whether ambiguous page copy is being interpreted as a broader or stronger claim than you intended.

    It cannot tell you which headline-description combination will serve for a particular query, whether the live system will generate different wording, or what CTR the campaign will achieve. Google describes the assets as examples; the exact previewed text is not guaranteed to serve.

    That limitation changes the approval standard. You are not signing off on a fixed set of ads. You are deciding whether the page gives an automated system sufficiently accurate material from which to generate ads. A clean preview is encouraging, but it does not remove the need to inspect generated assets after activation.

    Choose a CTR benchmark that matches the auction

    CTR is clicks divided by impressions, expressed as a percentage. The arithmetic is simple; the comparison is not. A display campaign, a first-position Search ad and a local result appear in different contexts and reflect different kinds of intent. Comparing all three to one account-wide target will produce confident but misleading conclusions.

    The 2026 figures below come from a meta-analysis covering 126 agency client accounts and published CTR datasets from August 4, 2025 through August 28, 2026. The results were weighted by dataset quality and normalized to U.S. query volume. They are useful external reference points, but they are not promises for an individual campaign, another country or a different auction mix.

    CTR by ad type and placement

    Ad typePlacement2026 average CTRHow to use it
    SearchPosition 12.1%Use only for the top search-ad position and remember that it blends search pages with and without AI answers.
    SearchPosition 21.4%Compare with campaigns occupying a similar position mix.
    SearchPosition 31.1%Do not treat the gap from position 1 as a creative problem by default.
    SearchPosition 40.8%Check placement before diagnosing copy from the lower CTR.
    Local SearchLocal result4.6%Keep separate from conventional Search benchmarks.
    Local ServicesLeft2.6%Compare within the same Local Services layout.
    Local ServicesMiddle2.3%Account for the lower placement when evaluating the result.
    Local ServicesRight2.0%Use as a placement-specific reference, not an account target.
    Product Listing AdTop eight1.2%Compare with other prominent product listings.
    Product Listing AdMid-page0.55%Do not compare directly with the top-eight figure.
    DisplayAcross placements0.093%Judge in the context of a format often used for branding rather than direct click generation.
    VideoSkippable0.69%Keep separate from Search and non-skippable video.
    VideoNon-skippable0.78%Compare with the same video format and campaign objective.

    The first-position Search benchmark needs one more qualification. The top ad averaged 1.8% on results pages containing an AI-generated answer and 3.4% on pages without one. The published 2.1% figure blends those environments.

    That difference is large enough to change your diagnosis. If a campaign’s exposure shifts toward search pages with AI answers, CTR can fall even when the ad copy has not become worse. Conversely, a rise in CTR does not prove that newly generated assets caused the improvement if placement or search-page composition changed at the same time.

    CTR for the first Search ad by industry

    Industry creates another wide spread. The 2026 first-position Search averages ranged from 1.1% to 5.4% across the 19 reported industries:

    IndustryCTR for position 1
    Addiction Treatment5.4%
    Automotive2.0%
    Aviation1.3%
    CBD2.8%
    Construction1.2%
    eCommerce2.9%
    Entertainment4.0%
    Financial Services2.5%
    Higher Education & College3.7%
    Home Builders2.5%
    Home Services3.0%
    Hotels & Resorts3.6%
    HVAC Services3.1%
    Legal Services2.3%
    Medical Device1.1%
    Medical Practices2.1%
    Real Estate2.7%
    SaaS1.8%
    Solar Energy2.4%

    There is no defensible universal CTR target for AI Max-generated text in these figures. They benchmark ad formats, positions and industries, not previewed AI copy against human-written copy. If someone tells you that enabling text customization should produce a particular CTR, ask for a comparable test covering the same placement, market, query mix and conversion objective.

    Use a three-level benchmark instead:

    1. Start with your own like-for-like campaign history. Match the campaign, market, landing page, intent and approximate placement as closely as practical.
    2. Use the closest industry figure to check whether your internal baseline is broadly plausible.
    3. Use the ad-type and placement table to explain structural differences that creative changes cannot fix.

    If your industry is absent, do not force a neighboring category into service because its label sounds similar. Use the placement benchmark as a rough external anchor and let your own campaign history carry more weight.

    Audit the preview as a claims and intent test

    A marketer uses a magnifying lens to compare abstract ad-preview cards with several possible landing-page destinations.

    The preview begins with your final URL, so prepare the page before judging the output. Make the actual offer, intended customer, geographic scope, material conditions and primary distinction easy to identify. Resolve contradictory wording between the headline, body copy, pricing language and calls to action. Otherwise you are asking automation to clarify a page that has not clarified itself.

    Save every previewed asset in a simple review sheet. Give each row fields for the generated text, intended angle, supporting landing-page language, risk level and decision. Then make four passes.

    1. Check factual accuracy. Mark any invented feature, incorrect product scope, wrong location, unsupported comparison or material condition that has disappeared. One false claim is a stop signal; do not average it away because the other assets are acceptable.
    2. Check intent. Write down the search need each asset appears to answer. If you cannot identify one, the wording is probably too generic. If it implies a broader offer than the landing page delivers, it may earn curiosity clicks that will not convert.
    3. Check positioning and voice. Look for language that could belong to any competitor, inflated promises you would not publish elsewhere, or terminology your customers do not use. A grammatically clean headline can still weaken the reason to choose you.
    4. Check destination continuity. A visitor should be able to find the advertised promise, product and relevant condition immediately on the destination page. If the ad requires the reader to reinterpret the page after clicking, the message is not aligned.

    A red-yellow-green system keeps the decision concrete. Red means false, materially misleading or attached to the wrong offer. Yellow means accurate but broad, generic, ambiguous or inconsistent with your voice. Green means specific, supportable and continuous with the destination page.

    Do not enable text customization while a red issue remains. If several samples make the same mistake, inspect the landing page before blaming the model. Repeated errors may indicate that the page leaves an important distinction implicit, although the model can also introduce an error that is not present on the page. Fix the underlying ambiguity where one exists, then run the preview again.

    A single yellow asset is a monitoring item, not necessarily a rejection. Record the exact concern so that your live review has a testable condition: for example, “watch for language that presents the service as nationwide” is more useful than “keep an eye on brand fit.”

    Run the live pilot without letting CTR make the decision

    An analyst monitors two ad-testing streams using several unlabeled performance gauges, with click response shown as one signal among many.

    Once text customization is enabled, treat the saved preview as a record of likely themes, not a production manifest. Continue examining generated assets because live messaging may differ from the examples.

    Set up the pilot around one business question: can AI-generated text produce more qualified response without creating claim, positioning or destination-match problems? That question gives you a hierarchy for interpreting the data.

    1. Record the starting configuration. Save the preview, final URL, activation date, existing CTR baseline and the conversion outcomes you will use. Without that record, later changes become difficult to attribute.
    2. Limit simultaneous changes where practical. A new landing page, different targeting, altered bidding and AI-generated text introduced together will not tell you which change mattered.
    3. Compare like with like. Review placement and query mix alongside CTR, and remember that AI-answer exposure can alter the click opportunity before the user evaluates your ad.
    4. Read CTR with conversion rate and cost or value per conversion. CTR tells you that the ad attracted a click. It does not tell you that the click came from the right person or produced a worthwhile outcome.
    5. Review the actual message. If a live asset makes an inaccurate or materially misleading claim, intervene immediately. You do not need to wait for a performance threshold before correcting an accuracy problem.

    Use this interpretation grid when the numbers arrive:

    Observed resultLikely interpretationNext action
    CTR rises and conversion quality holds or improvesThe new message may be earning more useful attention.Continue the pilot and monitor the live assets for message drift.
    CTR rises but conversion rate or value declinesThe message may be too broad, curiosity-driven or mismatched with the landing page.Inspect the generated wording, search intent and destination continuity before celebrating the CTR gain.
    CTR stays flat but conversion quality improvesThe creative may be filtering for better-fit visitors rather than maximizing click volume.Judge the result against the campaign’s business objective, not the external CTR average.
    CTR falls while conversion quality improvesFewer people are clicking, but those who do may be better qualified.Compare the additional value per click with the lost volume before deciding.
    CTR and conversion outcomes both declineThe change has no evident performance benefit in the observed campaign context.Inspect placement and query changes, then disable or revise the test if the decline remains attributable to the new setup.
    Any material accuracy failurePerformance metrics are no longer the primary issue.Stop the problematic automation or asset exposure and correct the message.

    Avoid importing a universal testing duration or click threshold. A high-volume local campaign and a low-volume B2B campaign do not accumulate useful evidence at the same rate. Make the decision when your campaign has enough comparable traffic to separate a persistent pattern from daily noise, and document what “enough” means before looking at the result.

    Your next move is straightforward: preview one representative campaign, save and score every generated asset, write down the correct position-and-industry CTR reference, and define the conversion-quality guardrail before opting in. That gives AI Max a fair test without handing an attractive CTR more authority than it deserves.

    References


  • How to Choose a GEO Agency That Knows Your Industry

    How to Choose a GEO Agency That Knows Your Industry

    You are looking at GEO agencies because buyers increasingly ask AI systems to identify, explain, and compare providers. The hard part is not finding an agency that can say it does generative engine optimization. It is finding one that understands what a qualified recommendation looks like in your market, which claims require careful evidence, and which commercial event makes visibility worth paying for.

    A generic campaign can increase mentions while getting the important details wrong: the market you serve, the work you accept, the buyer you want, or the regulatory conditions attached to your offer. Industry fit should therefore be tested as an operating capability, not accepted as a line in a proposal.

    Key takeaways

    • Choose an agency that can map AI questions to your real buyers, decision stages, qualification rules, and revenue events.
    • Separate industry fluency from industry name-dropping. Client logos are weaker evidence than accurate work samples, attributable outcomes, and a credible subject-matter review process.
    • Score brand accuracy and commercial relevance alongside recommendation volume. More mentions are not valuable if they describe the wrong specialization or attract the wrong buyer.
    • Give every finalist the same bounded case exercise. Compare how they diagnose the current answer, identify evidence gaps, plan content, manage claims, and measure the result.
    • Require a measurement chain from AI appearance to accurate representation, qualified action, and pipeline. A dashboard of prompt screenshots is not a business case.
    • Contract for controllable work, quality standards, reporting, and ownership. No agency can guarantee that an independent AI model will recommend you in every answer.

    Industry expertise must change the campaign

    Industry specialization matters when it changes what the agency does. It should affect the questions selected, the entities and claims that need clarification, the evidence required to support those claims, the third-party authority strategy, and the action counted as a conversion.

    The differences are substantial. A staffing firm may need to distinguish searches from prospective employers and candidates while preserving a clear specialization across healthcare, legal, engineering, retained search, RPO, or other recruiting models. A private equity firm needs accurate representation of its investment thesis, sector focus, deal criteria, and intended audience. An energy company may need market-specific language about generation, storage, transmission, interconnection, and regulatory conditions.

    IndustryWhat a qualifying AI question may containDetails that must remain accurateCommercial event to track
    Staffing and recruitingRole type, industry specialization, geography, hiring model, employer need, or candidate needPractice area, placement model, talent market, client-versus-candidate audience, and actual service coverageQualified employer inquiry, candidate inquiry, or another lead event tied to the firm’s operating model
    Private equityCompany size, sector, transaction type, geography, investment stage, or capital needInvestment thesis, check or company profile where applicable, sector focus, deal criteria, and whether the answer is meant for a founder, business owner, or LPDeal-sourcing inquiry, fundraising conversation, or qualified opportunity associated with portfolio growth; these are the distinct outcomes a PE-focused program may need to support
    Energy and power generationPower availability, generation technology, storage, renewable supply, location, grid market, or large-load requirementUtility territory, ISO or RTO market, transmission zone, interconnection conditions, technical specifications, and environmental or regulatory claimsRFP, RFQ, interconnection inquiry, PPA discussion, project-finance conversation, or partnership

    If a candidate describes all three as content marketing with different keywords, it has not demonstrated industry fit. The vocabulary is the surface. The real test is whether the agency understands who is asking, what would qualify the answer, what could make it inaccurate, and what happens after discovery.

    Ask for evidence in increasing order of strength

    Do not let one recognizable logo settle the decision. The agency may have performed unrelated work, supported only one business unit, or inherited a strategy designed elsewhere. Ask for evidence that exposes the work itself:

    • Sector vocabulary in context: Can the team discuss your buyer, offer, exclusions, sales cycle, and qualification rules without turning the conversation into a terminology quiz?
    • A relevant artifact: Review an anonymized audit, question map, content brief, technical recommendation, authority plan, or report. Look for decisions specific to the industry rather than a reusable template with a different company name.
    • A traceable case: Ask for the starting condition, action taken, observed change, and commercial metric. A visibility increase without a definition of qualified demand is incomplete.
    • A comparable reference: A reference from a company with similar technical complexity, regulatory exposure, buying committee, or sales cycle is more useful than one that merely shares your broad industry label.
    • An accuracy failure and correction: A mature team should be able to explain how it found a wrong or ambiguous claim, who reviewed it, what changed, and how the correction entered the workflow.

    Real expertise should reduce the translation burden on your team. It should not eliminate subject-matter involvement. In technical, regulated, or investment-sensitive markets, an agency that claims it needs no access to your experts is usually revealing a weak quality-control model.

    Build a scorecard around the cost of being wrong

    An overhead evaluation table shows three anonymous agency portfolios surrounded by evidence, compliance, buyer, operational, and risk objects.

    There is no universal best GEO agency because the expensive failure differs by industry. Staffing evaluations often emphasize recommendation volume, brand clarity, recruiting experience, and value. Private equity evaluation adds lead-generation performance, investment-sector fluency, leadership experience, and operating history. Energy evaluation gives much more weight to technical and regulatory fluency, grid precision, and the connection between search activity and project pipeline. Those staffing, private equity, and energy criteria should not collapse into a single generic leaderboard.

    Use a procurement scorecard before proposals arrive, then keep the weights fixed. This prevents a polished presentation from quietly redefining what matters. The following 100-point rubric is a useful default for a complex B2B engagement:

    CriterionWeightWhat earns a high score
    Industry problem and buyer fluency25The team distinguishes audiences, buying situations, exclusions, regional conditions, and pipeline events. It can identify where an inaccurate answer would create commercial or compliance risk.
    GEO and AEO method20The proposal covers answer discovery, question selection, entity and claim clarity, content, technical accessibility, third-party authority, testing, and adaptation. Each activity has an owner and rationale.
    Content accuracy and authority controls20The agency has a documented process for evidence, citations, subject-matter review, corrections, approvals, and sensitive claims. It can explain how structured data supports interpretation without presenting schema as the entire strategy.
    Measurement and commercial attribution20The plan establishes a baseline, preserves dated observations, distinguishes mentions from accurate recommendations, and connects qualified actions to CRM stages or other commercial records.
    Delivery and commercial fit15The actual team, capacity, communication model, scope, dependencies, pricing structure, and contract terms fit your organization. Named specialists appear in delivery, not only in the sales meeting.

    Rate each criterion from zero to five and multiply it by its weight. Define the scale in advance: zero means no evidence, one means an unsupported assertion, three means relevant proof with limitations, and five means direct, repeatable proof with transparent measurement. Require a note or artifact beside every score. If evaluators cannot point to the evidence, the score is optimism rather than assessment.

    Use knockout conditions before totals

    A high total should not compensate for a dangerous weakness. Set non-negotiable conditions for issues that could invalidate the whole engagement:

    • The agency must identify who reviews technical, regulatory, financial, or otherwise sensitive claims before publication.
    • The proposal must define the starting baseline, target question set, answer environments in scope, and method used to preserve observations.
    • The team must separate recommendation volume from brand clarity. A frequent but inaccurate recommendation can attract the wrong prospect or create a false impression of fit.
    • The agency must disclose delivery dependencies, including the access, interviews, reviews, and data it needs from your team.
    • The provider must not guarantee inclusion in every AI answer or claim control over an independent model’s output.
    • The reporting plan must extend beyond visibility to a qualified action that your organization can recognize and record.

    Treat awards, marketplace profiles, and leaderboards as ways to find candidates, not as substitutes for this evaluation. The purpose of your scorecard is not to manufacture an objective winner from subjective inputs. It is to expose where a decision rests on evidence, where it rests on judgment, and which unresolved risk you are accepting.

    Make every finalist solve the same bounded case

    A capabilities deck shows what an agency wants to sell. A common case exercise shows how it thinks. Give finalists the same real business question, the same background material, the same constraints, and the same submission format. Pay for the exercise if it requires meaningful diagnostic work; a bounded paid assessment is more useful than asking several firms to design an unpaid campaign.

    Write a brief that prevents generic answers

    Your brief should include the business line, intended buyer, excluded or poor-fit buyer, geography, primary offer, desired conversion, claims requiring approval, known alternatives, and one high-intent question that matters commercially. Include the correct answer as your experts would give it. The agency’s job is not merely to rewrite that answer. It is to diagnose why an AI system might fail to find, understand, trust, or select it.

    Ask each candidate to return the same set of outputs:

    1. Current-answer snapshot: Show how the chosen AI environments describe the company, which sources or pages appear to influence the answer, and where the response is absent, vague, inaccurate, or commercially unhelpful.
    2. Question and audience map: Place the question in the buyer journey and identify adjacent questions that would change qualification. The map should distinguish informational curiosity from a real buying or selection task.
    3. Entity and claim diagnosis: Identify ambiguous names, service definitions, locations, audience labels, comparisons, and unsupported claims that could confuse a model or buyer.
    4. Content intervention: Produce a content brief or revision plan showing the proposed answer, supporting evidence, internal links, structured information, subject-matter input, and approval points.
    5. Authority intervention: Explain whether the problem can be addressed on your own site or also requires credible third-party references. Private equity programs, for example, may need to strengthen how a firm’s thesis and credibility appear in external sources used during evaluation; energy work may likewise rely on clear explanations supported by third-party references when available.
    6. Measurement chain: Define what the team will observe in generated answers, what it can observe on the website, which CRM event represents a qualified response, and which parts of the chain will remain inferential.

    Listen for the tradeoffs, not just the proposed tactics. Ask what the candidate would refuse to publish, which claim needs an expert review, what it cannot attribute confidently, and what it would do if your visibility improved without producing qualified demand. Strong answers make the limits of the method visible.

    Inspect the people and controls behind the plan

    Some delivery models assign a strategist, specialized writer, project manager, and technical specialist to an account. That structure can support continuity, but only if the named specialists participate in execution. Ask to meet the day-to-day lead and the person responsible for industry content before signing.

    • Who turns business priorities into the question portfolio?
    • Who writes, edits, and checks industry claims?
    • Who decides whether a problem calls for content, structured data, technical remediation, digital PR, or a third-party authority signal?
    • Who records model observations, and how is the sampling method kept consistent?
    • Who can approve a correction when the agency discovers a material error?
    • What information must your subject-matter experts provide, and at which points can missing input block delivery?
    • How does the agency protect quality if output expands across business lines, regions, or portfolio companies?

    Needing detailed onboarding is not a weakness by itself. Complex work often depends on client knowledge that no external team can infer. The useful distinction is whether the agency asks precise questions once and builds a reusable knowledge system, or repeatedly sends basic issues back to your team because it never formed a working model of the business.

    Choose the operating model that matches the problem

    A narrowly focused GEO firm can be a good fit when you already have capable brand, web, analytics, and communications teams. A broader agency may make more sense when AI discovery must connect with paid media, conversion optimization, marketing automation, website architecture, or portfolio-company growth. That broader range can also be more service than you need; some private equity programs deliberately combine GEO with acquisition assessment and post-acquisition marketing, while a firm seeking only answer visibility may prefer a tighter scope.

    Agency size is also a fit variable, not a quality verdict. A small specialist may provide senior attention but have limited capacity for multinational or multi-business-line production. A larger multidisciplinary team may offer broader coverage while creating more handoffs and scope-management risk. Ask how the proposed team would handle your actual volume and complexity, then make the capacity commitment explicit in the statement of work.

    Contract for an auditable path from answer to pipeline

    A glowing route passes from an AI node through sources, expert review, buyer comparison, and a conversation before reaching a handshake-shaped outcome.

    GEO reporting becomes misleading when every metric is placed on the same level. A mention, an accurate recommendation, a site visit, a qualified inquiry, and a commercial win are different events. Build the measurement plan as a chain so that you can see where progress stops.

    1. Exposure: Was the company absent, mentioned, compared, cited, or recommended for the tracked question?
    2. Representation: Did the answer accurately describe the specialization, offer, geography, audience, constraints, and reason for selection?
    3. Engagement: Did a person reach an owned page or otherwise indicate that an AI answer influenced discovery? Record observable referral data where available, but do not assume every AI-influenced visit will carry a detectable referrer.
    4. Qualified action: Did the person take the action your sales or business-development team recognizes as meaningful?
    5. Commercial progression: Did the action become an accepted opportunity and move through the relevant pipeline?

    The fourth step must use your industry’s language. A staffing program may focus on qualified inbound employer demand and the revenue relevance of those leads. A private equity program may distinguish a founder’s deal inquiry from an LP conversation or portfolio-company growth opportunity. An energy program may need to preserve the relationship between search activity and an RFP, RFQ, interconnection request, PPA discussion, project-finance conversation, or partnership.

    Define the baseline so it can be repeated

    A one-off screenshot is not a baseline. Generated answers can vary, so preserve the prompt, model or answer environment, date, relevant location or account conditions, answer text, citations, competitors mentioned, and your accuracy assessment. Keep the tracked prompt set stable enough to compare periods, and document any additions or wording changes rather than silently replacing weak prompts.

    On the owned side, configure analytics for identifiable AI referrals where available, use campaign-specific landing paths when the tactic permits it, and add a self-reported discovery field to relevant forms or sales conversations. In the CRM, retain the original discovery response alongside lead quality, opportunity stage, and outcome. The agency’s report should label each relationship as observed, self-reported, or inferred.

    Set the reporting cadence in the contract, along with the person responsible for resolving discrepancies between the agency dashboard, web analytics, and CRM. An agency may improve visibility without controlling whether an AI provider sends referral data, whether a prospect types your URL directly, or whether sales records the discovery path. Clear attribution boundaries make the report more credible, not less.

    Put controllable commitments in the agreement

    SEO and GEO programs are described as work that takes time to mature. Treat promises of immediate, stable recommendation placement with skepticism. A provider can commit to research, technical work, content quality, authority development, monitoring, reporting, and response times. It cannot bind an independent AI model to include your company.

    The statement of work should define:

    • The AI answer environments, markets, languages, audiences, and business lines in scope
    • The baseline method and tracked question portfolio
    • The planned content, technical, structured-data, and third-party authority work
    • Named delivery roles and responsibilities on both sides
    • Evidence, review, approval, correction, and escalation procedures
    • Reporting fields, attribution limits, and the commercial events used to assess quality
    • Ownership of content, research, prompt libraries, dashboards, analytics configurations, and accounts
    • Access rules, confidentiality obligations, conflict disclosures, renewal terms, and exit provisions

    For a material engagement, have procurement or counsel review confidentiality, exclusivity, intellectual-property ownership, liability, access, renewal, and termination language. A marketing scorecard can identify operational fit, but it cannot protect you from an unfavorable contract.

    Your next move is to choose one buying question that already matters to pipeline and write down what a correct, qualified answer must contain. Send that same case to the finalists. The right partner will do more than offer tactics: it will show you where your industry knowledge must enter the system, how the answer can become more trustworthy, and how you will know whether the work created a business result.

    References


  • YouTube Masthead Access for Online Gambling Advertisers

    YouTube Masthead Access for Online Gambling Advertisers

    Your gambling licence alone does not unlock YouTube’s most prominent advertising placement. Starting October 21, 2026, Google will extend YouTube Masthead eligibility to more certified online gambling advertisers, but access will still depend on the product, jurisdiction, registration rules, certification scope, and campaign controls.

    If you’re planning a Masthead campaign, qualify the exact product-market combination before you commit the budget or build the creative. The policy change creates an opportunity, not an automatic approval.

    The change opens one premium placement, not the whole platform

    YouTube’s Masthead requirements already permit sports betting advertising. The October change expands eligibility to additional forms of online gambling advertising, provided the advertiser holds the relevant Google Ads certification and satisfies the applicable legal restrictions.

    That distinction matters. Masthead eligibility, Google Ads certification, and campaign approval are related, but they aren’t interchangeable:

    • Eligibility means your type of gambling business may be considered for the placement.
    • Certification means Google has approved you to advertise the relevant gambling category in the jurisdictions covered by that certification.
    • Campaign approval means the specific account, targeting, creative, destination, and other campaign elements satisfy Google’s applicable policies.

    Passing one stage does not guarantee the next. A certified advertiser can still submit a campaign that falls outside its approved geography, reaches an impermissible age group, or conflicts with another Google advertising policy.

    Use this four-gate test before treating your brand as eligible

    An advertiser passes through four gates symbolizing licensing, jurisdiction, registration, and campaign controls on the way to a premium video screen.

    Run each proposed product and target market through four gates. If any answer is unknown, treat the campaign as pending rather than eligible.

    1. Does mandatory state or national registration apply? The exception is easy to misread: online gambling advertisers not subject to mandatory state or national gambling registration remain excluded from the expanded eligibility. Operating in a category without a registration requirement is not a shortcut into the Masthead.
    2. Are you legally permitted to offer the product in the target jurisdiction? Confirm the relevant registration and licensing position for the product and location. If the answer depends on an interpretation of local law, use qualified legal counsel rather than inferring eligibility from a competitor’s campaign.
    3. Do you hold the matching Google Ads certification? Certification is not a universal gambling credential. Approval depends on the gambling category, local rules, licensing requirements, and jurisdictions you intend to target.
    4. Can the campaign enforce every geographic and age restriction? The campaign must stay inside the approved markets and comply with all applicable age limits. A broad audience setup can invalidate an otherwise eligible plan.

    The third gate deserves particular attention. A government licence or registration addresses your legal status. Google Ads certification addresses your permission to advertise through Google’s systems. Keep both records in your campaign approval file; neither should be treated as a substitute for the other.

    Map eligibility by product and jurisdiction

    A compliance team reviews connections between different gambling products and selected regions on an unlabeled tabletop map.

    Don’t label the entire company “approved” because one product is certified in one market. Build a simple eligibility matrix with one row for every product-jurisdiction combination you want to advertise.

    • Product or gambling category
    • Target country, state, or other applicable jurisdiction
    • Whether mandatory gambling registration applies
    • Registration and licensing status
    • Google Ads certification status and scope
    • Required geographic exclusions
    • Applicable age restrictions
    • Overall status: eligible, pending, or blocked

    This matrix prevents a common planning error: allowing a valid approval in one market to become an assumption about another. It also gives media, legal, compliance, and creative teams the same definition of what can launch.

    Be strict about the status labels. “Pending” should mean that a required decision, certification, or legal confirmation is still outstanding. It should not be converted to “eligible” because the campaign deadline is approaching. “Blocked” should identify the failing gate so the team knows whether the constraint is the product, jurisdiction, registration rule, certification, or targeting requirement.

    Sequence the campaign so compliance is not the final dependency

    The expensive mistake is to complete the media plan and creative first, then discover that the certification doesn’t cover the proposed product or market. Use this order instead:

    1. Define the exact gambling product being promoted.
    2. List every jurisdiction the campaign would reach.
    3. Confirm whether mandatory registration applies in each product-market combination.
    4. Verify the relevant registration, licensing, and legal permissions.
    5. Obtain or confirm Google Ads certification for the applicable category and jurisdictions.
    6. Configure geographic targeting, geographic exclusions, and age controls around the narrowest permitted scope.
    7. Review the creative, destination, account, and campaign against Google’s broader advertising policies.
    8. Commit the Masthead budget and launch date only after the required approvals are confirmed.

    For the initial rollout, narrow scope is easier to govern. A campaign covering one confirmed product-market combination has fewer ways to drift beyond its permissions than a launch that combines several products and jurisdictions. Expansion can follow as additional rows in the eligibility matrix become confirmed.

    October 21 is an eligibility start date, not a guaranteed campaign launch date. Account review, certification, legal clearance, and campaign approval still determine whether your specific campaign can run. Keep an alternative media plan until those dependencies are settled, particularly when the Masthead date is tied to a fixed promotion.

    Key questions about YouTube gambling ad access

    Can every online gambling operator buy a YouTube Masthead from October 21?

    No. The expansion applies to eligible, certified advertisers that satisfy the relevant legal, registration, licensing, geographic, and age requirements. It is not blanket permission for online gambling advertising.

    Does a gambling licence replace Google Ads certification?

    No. A licence or registration establishes a legal status under the applicable jurisdiction. Google Ads certification is a separate platform requirement for advertising the covered gambling category and market.

    Does one Google certification cover every jurisdiction?

    You should not assume that it does. Certification requirements depend on the category, jurisdiction, local regulation, and applicable licensing rules. Verify the scope against every market in the campaign.

    Are sports betting advertisers newly eligible?

    No. YouTube’s existing Masthead policy already permits sports betting advertising. The change extends potential access to more certified online gambling advertisers.

    Your next move is concrete: write down the exact product and jurisdiction you want to promote, then clear all four gates before briefing the campaign. If registration, licensing, certification, geography, or age controls remain unresolved, the Masthead plan is not ready for budget approval.

    References


  • AI Coding Assistant Market Share: Who Leads in 2026?

    AI Coding Assistant Market Share: Who Leads in 2026?

    If you are choosing an AI coding assistant for yourself or your development team, the headline answer is clear: Claude Code leads the October 2026 primary-tool market at 29.4%, ahead of GitHub Copilot at 22.7%. That does not automatically make Claude Code the right purchase. The aggregate ranking hides large differences between startups and enterprises, terminal users and IDE users, and the assistant you open versus the model that actually generates the code.

    The useful question is not simply which product is biggest. It is which market signal applies to your environment, what the rapid move toward coding agents changes, and how much weight market share should carry in your evaluation. Here is how to read the numbers without turning popularity into a substitute for testing.

    Read primary-tool share as a competitive signal, not total adoption

    The October estimate measures the percentage of professional developers who name a product as their primary AI coding assistant: the one they use most often to write, edit, or review production code. It does not count every tool a developer has tried, every installed extension, total seats, vendor revenue, or the volume of code generated.

    That distinction matters because many developers use two or three assistants. A developer might rely on Claude Code for repository-wide implementation, keep GitHub Copilot enabled for inline completion, and occasionally send a background task to Codex. Only the tool used most often receives that developer’s primary-tool share.

    The estimate combines an August 4 to September 26, 2026 survey of 2,350 professional developers in North America and Europe with publicly disclosed seat and usage figures. The responses were normalized into a market model. That makes the results useful for understanding competition among leading products, but they are not a worldwide census or a direct measure of software quality.

    Use the rankings to build a shortlist, understand where workflows are moving, and challenge an outdated default. Do not use them alone to approve a company-wide rollout.

    Key takeaways

    • Claude Code leads with 29.4% of primary-tool share in October 2026; GitHub Copilot follows at 22.7%, Cursor at 13.1%, and OpenAI Codex at 11.8%.
    • The four largest assistants hold 77.0% combined, up from 71.2% in January 2026.
    • Terminal and CLI agents are now the largest interface category, rising from 21.3% in January to 38.6% in October.
    • Company size changes the ranking: Claude Code leads among startups, while GitHub Copilot leads at companies with more than 5,000 employees.
    • Product share and model share are different. Claude models account for 47.3% of model-family coding usage because they are available through products beyond Claude Code.
    • Market share can tell you which tools deserve evaluation. Only a controlled test against your repositories, policies, and workflows can tell you which one deserves deployment.

    The October leaderboard shows both concentration and disruption

    Large central technology nodes and smaller fast-moving nodes compete inside a glowing circular digital arena.

    The October 2026 primary-tool snapshot puts two terminal-oriented agents in the top four and shows substantial movement since January. The change column uses percentage points, not percent growth.

    RankAI coding assistantDeveloperPrimary interfaceOctober 2026 shareChange since January
    1Claude CodeAnthropicTerminal agent29.4%+10.9 points
    2GitHub CopilotMicrosoft / GitHubIDE extension22.7%-7.8 points
    3CursorAnysphereAI-native IDE13.1%-4.9 points
    4OpenAI CodexOpenAITerminal and cloud agent11.8%+7.6 points
    5Google Antigravity and Gemini Code AssistGoogleAI-native IDE5.6%+1.1 points
    6JetBrains AI and JunieJetBrainsIDE extension4.3%-0.6 points
    7WindsurfCognitionAI-native IDE2.9%-1.9 points
    8Amazon Q Developer and KiroAmazonIDE extension2.6%-0.8 points
    9OpenCodeOpen sourceTerminal agent2.4%+1.6 points
    10ClineOpen sourceIDE extension1.7%-0.5 points
    –All other toolsVariousVarious3.5%-4.7 points

    Claude Code’s lead is meaningful because it is paired with the largest gain in the table. OpenAI Codex has the second-largest increase and has nearly tripled its primary-tool share since January. Copilot and Cursor remain substantial products, but both have lost share while agent-oriented tools have gained it.

    The top four products now account for 77.0% of primary-tool usage, compared with 71.2% in January. That is evidence of concentration within this definition of the market. It is not evidence that the category has settled: the order inside that concentrated group has changed quickly.

    The five-quarter trajectory is more useful than a single rank

    Quarterly averages smooth out the monthly movement and show that the change in leadership was not a one-month fluctuation. They also explain why the Q3 values below differ slightly from the October snapshot.

    AssistantQ3 2025Q4 2025Q1 2026Q2 2026Q3 2026
    GitHub Copilot36.2%33.4%30.1%26.0%23.1%
    Claude Code7.9%12.6%19.2%24.8%28.7%
    Cursor19.4%19.9%17.6%15.2%13.5%
    OpenAI Codex1.8%3.1%4.6%8.3%11.2%
    Google3.6%4.1%4.0%4.9%5.4%

    Claude Code passed GitHub Copilot between Q2 and Q3 2026. Copilot declined in every quarter shown, while Claude Code rose in every quarter. Cursor peaked at 19.9% in Q4 2025 and then declined for three consecutive quarters. Codex accelerated most sharply after Q1 2026, moving from 4.6% to 8.3% in Q2 and 11.2% in Q3. Google’s movement was steadier, ending Q3 at 5.4%.

    For a buyer, sustained direction deserves more weight than a narrow difference in one snapshot. A rising product is more likely to receive integrations, community attention, training material, and internal advocacy. A falling product can still be the best operational fit, especially when its decline reflects a changing interface preference rather than a failure of the product itself.

    The decisive change is from suggestions to delegated tasks

    A developer moves from receiving one code suggestion to supervising AI agents that coordinate coding, testing, and deployment tasks.

    The market is not merely swapping one vendor for another. Developers are changing how they interact with coding AI. Inline completion asks an assistant to help with the next fragment of code. An agent can receive a broader goal, inspect multiple files, make coordinated edits, run commands or tests, and return a larger unit of work for review.

    The interface numbers capture that shift. Tools that support several interfaces are assigned to the one each respondent uses most often, so the categories describe dominant behavior rather than permanent product boundaries.

    Interface typeJanuary 2026 shareOctober 2026 shareChange
    Terminal / CLI agent21.3%38.6%+17.3 points
    IDE extension41.2%29.4%-11.8 points
    AI-native IDE24.8%17.9%-6.9 points
    Cloud / background agent5.1%9.2%+4.1 points
    Browser-based app builder7.6%4.9%-2.7 points

    Terminal and CLI agents gained 17.3 points between January and October, becoming the largest interface category at 38.6%. Cloud and background agents also gained share. IDE extensions fell from 41.2% to 29.4%, while AI-native IDEs fell from 24.8% to 17.9%.

    This does not mean the IDE is disappearing. IDE extensions still represent nearly three in ten primary workflows, and many agent users review the resulting code in an editor. It means that an evaluation built entirely around autocomplete quality is now incomplete.

    Your test set should include the work agents are being asked to own: a change that touches several files, a bug whose cause is not identified in the prompt, a refactor that must preserve behavior, and a review task that requires following repository conventions. Record whether the assistant finds the right context, makes coherent changes, validates them, and leaves an understandable diff. A fast completion is not useful if the developer spends longer discovering and correcting hidden mistakes.

    Agent capability also changes the risk boundary. If a tool can execute commands, modify many files, access external systems, or open pull requests, test it first in a protected branch or isolated environment. Apply the least permissions it needs, keep credentials out of its context, require review before merge, and let your normal test and security controls judge the output. The specific downside is larger than a poor inline suggestion: an agent can propagate a wrong assumption across a repository or act on an unintended resource.

    Your company size and model layer change the apparent winner

    The overall ranking is least reliable when it is treated as though every buyer faces the same constraints. The split by employer size shows four materially different markets.

    Company sizeClaude CodeGitHub CopilotCursorOpenAI CodexAll other tools
    Startup, 1-50 employees36.8%9.7%21.4%15.2%16.9%
    Small business, 51-50033.1%17.5%16.2%13.4%19.8%
    Mid-market, 501-5,00027.9%25.8%11.7%10.9%23.7%
    Enterprise, more than 5,00022.4%35.6%8.3%9.1%24.6%

    Claude Code is strongest among startups at 36.8% and declines steadily to 22.4% at enterprises. Cursor has an even sharper segment gap, moving from 21.4% among startups to 8.3% at companies with more than 5,000 employees. Codex follows the same broad pattern, though less dramatically.

    GitHub Copilot moves in the opposite direction. It holds 9.7% among startups but leads the enterprise segment at 35.6%. Existing Microsoft licensing agreements help explain why Copilot remains the default procurement route inside many large organizations. At mid-market companies, Claude Code and Copilot are much closer, at 27.9% and 25.8% respectively.

    If you work at a startup, the aggregate table understates the prevalence of Claude Code, Cursor, and Codex among your peers. If you manage enterprise tooling, it understates Copilot’s position and the influence of procurement, identity, administration, and existing contracts. Use the segment closest to your organization as the starting point, then check whether your technical and governance requirements resemble that peer group.

    Do not confuse the assistant with the underlying model

    A product is the working environment: its interface, context handling, repository tools, permissions, integrations, and review flow. A model is the code-generating engine available inside that environment. Several assistants allow developers to choose among model families, so the product leaderboard cannot tell you which models generate the most coding output.

    Model familyDeveloperJanuary 2026 shareOctober 2026 share
    ClaudeAnthropic49.2%47.3%
    GPTOpenAI22.4%28.6%
    GeminiGoogle11.8%10.2%
    Open-weight models, including Qwen, DeepSeek, Kimi, and GLMVarious10.3%9.4%
    GrokxAI3.4%2.1%
    All other modelsVarious2.9%2.4%

    Claude models account for 47.3% of model-family coding usage, substantially more than Claude Code’s 29.4% product share. The difference exists because Claude models are also used within Cursor, GitHub Copilot, and open-source agents. GPT models gained 6.2 points between January and October, reaching 28.6% as Codex expanded. Open-weight models retained 9.4%, with their use concentrated among cost-sensitive teams and self-hosted deployments.

    This separation gives you a better evaluation design. First judge whether the product fits your workflow and controls. Then compare the models available inside it on the same tasks. Keep the model name and version in your evaluation record; otherwise, a model change can be mistaken for a product improvement or regression.

    Turn the market-share numbers into a defensible tool decision

    Market share is useful evidence of momentum, ecosystem depth, and peer adoption. It does not directly measure correctness, security, developer satisfaction, review burden, total cost, or performance on your codebase. A defensible decision uses the market data to narrow the field and repository-level evidence to choose among the finalists.

    1. Define the job before naming a vendor. Decide whether you mainly need inline completion, repository exploration, multi-file implementation, code review, background execution, or a combination. The interface trend shows that these are no longer interchangeable versions of the same task.
    2. Apply your non-negotiable constraints. Check supported editors and terminals, operating environments, authentication, administrative controls, data handling, model availability, network access, auditability, and contract requirements. Remove any product that cannot meet a genuine constraint before comparing output quality.
    3. Build a segment-aware shortlist. Include the overall leader, the leader for your company-size segment, and a credible alternative with a different interface or model strategy. An enterprise shortlist that ignores Copilot would miss the segment leader; a startup shortlist containing only Copilot would ignore how differently that segment behaves.
    4. Use the same representative task set. Give every finalist an existing bug, a multi-file feature, a behavior-preserving refactor, and a code-review assignment drawn from the kinds of repositories it would actually encounter. Keep the prompt, starting commit, permissions, and acceptance criteria consistent.
    5. Score the cost of reaching an acceptable result. Record whether the final change passes the relevant tests, how much developer intervention it requires, how long review and correction take, whether it follows repository conventions, and what the successful result costs. Do not reward a tool merely for producing more code or producing it faster.
    6. Test assistant and model choices separately. When a product offers several models, rerun the important tasks with each viable model. This reveals whether the value comes from the interface and agent harness, the underlying model, or their combination.
    7. Control the rollout and set a reassessment trigger. Begin with repositories and permissions where mistakes are detectable and reversible. Expand only after the review burden and failure modes are understood. Reassess when a major model, agent mode, pricing structure, policy requirement, or contract renewal changes the decision.

    The practical choice is rarely the product with the largest number beside its name. It is the assistant that completes your representative work with the lowest combined burden of prompting, correction, review, administration, and risk. Use the 2026 leaderboard to decide what deserves a serious test, then let reproducible work in your own environment decide what your team adopts.

    References


  • How to Choose a Generative Engine Optimization Agency

    How to Choose a Generative Engine Optimization Agency

    You are not hiring a generative engine optimization agency to produce another visibility dashboard. You are hiring it to change something observable: whether AI systems recommend your company for relevant buyer questions, cite your pages, describe your brand accurately, and send qualified visitors.

    The wrong brief lets every agency declare victory using its favorite metric. The right brief fixes the outcome, prompt set, evidence standard, ownership terms, and commercial measurement before anyone starts optimizing.

    Key takeaways for shortlisting a GEO agency

    • Buy a defined outcome, not a package called GEO. Recommendations, citations, entity accuracy, authority, and AI referral traffic are related but distinct objectives.
    • Require prompt-level evidence across the AI engines your buyers actually use. A percentage without the prompt list, raw answers, inclusion rules, and collection dates is not reproducible.
    • Separate visibility from business impact. An agency should report AI recommendations and citations while your analytics and CRM track qualified visits, leads, assisted conversions, and revenue.
    • Match the agency to the bottleneck. Entity correction, editorial production, digital PR, local lead generation, and enterprise software visibility require different strengths.
    • Discount any ranking when the business publishing it also awards itself first place. Use vendor-published figures to form a shortlist, then reproduce the claims against your own prompts.
    • Put the prompt corpus, raw data, content, accounts, reporting history, and exit process under your control in the contract.

    Define the exact GEO job before requesting proposals

    More AI visibility is not a workable objective. A brand can appear frequently and still be described incorrectly. Its pages can earn citations without the company being recommended. It can also be recommended for informational questions that never produce a sales conversation.

    Choose one primary job and, at most, a small set of supporting outcomes. This keeps an agency from replacing a weak result with an easier metric after the engagement begins.

    GEO jobWhat to measureWhat acceptable evidence looks like
    Earn buyer recommendationsRecommendation share among eligible, non-branded buyer promptsThe brand appears as a genuinely relevant option, not merely in a citation, disclaimer, or passing mention.
    Earn citationsCitation coverage, cited URLs, and the types of questions that trigger those citationsRaw AI answers link to pages you control, with repeated observations rather than one favorable screenshot.
    Correct entity representationAccuracy of critical facts, relationships, products, people, and positioningA before-and-after record shows which claims changed, where they changed, and whether the correction persists.
    Build category authorityCoverage of important topics, independent mentions, earned links, and citation-worthy assetsThe agency maps each asset or authority activity to a documented gap instead of publishing content by volume alone.
    Create commercial impactQualified AI referral traffic, conversions, assisted opportunities, and revenue where attribution is availableAI visibility reporting is reconciled with analytics and CRM data without claiming that every conversion has a single cause.

    A meaningful benchmark can cover more than 300 buyer prompts across ChatGPT, Gemini, Claude, and Google AI Overviews. That is a useful indication of rigor, not a universal minimum. Your prompt corpus should be large enough to cover the categories, buyer roles, use cases, and stages that matter to your revenue model. Relevance is more important than padding the set with easy questions.

    Write the objective in plain language before speaking to agencies. A strong version might be: improve our presence when a defined buyer asks a named group of non-branded purchase questions, while increasing citations to approved pages and preserving accurate product claims. Attach the initial prompt inventory and define what counts as a recommendation.

    Do not let the agency build the entire benchmark in private. It can help refine the prompts, but your sales calls, search data, customer questions, competitive reviews, and product positioning should determine the universe. Otherwise, the test can quietly drift toward prompts the agency already knows how to win.

    Demand evidence you can inspect and reproduce

    A magnifying lens rests beside a glass box containing a visible sequence of connected nodes and document-shaped tiles.

    GEO is young enough that polished language often runs ahead of independently verified performance. The answer is not to reject every case study. It is to move from claims to inspectable evidence in a fixed order.

    1. Start with the raw observation. Ask for the prompt, engine, collection date, complete response, citation links, and the rule used to count the result.
    2. Look for repetition. One answer can be useful as an example, but it cannot establish a pattern. Require results across the agreed prompt set and a documented policy for reruns.
    3. Connect the result to agency work. The agency should identify the page, entity correction, digital PR placement, technical change, or content improvement that preceded the movement. Correlation is not perfect causation, but an unexplained score is weaker evidence.
    4. Connect visibility to the business. Reconcile the GEO report with analytics and CRM records. Recommendation share and citations are leading indicators; qualified opportunities and revenue are commercial outcomes.

    Share of voice needs particular care. Its denominator is the selected prompt corpus, so a high percentage can mean broad buyer visibility or simply a narrow, favorable test. In one disclosed 2026 prompt run, First Page Sage appeared in 26% of buyer prompts and Kalicube in 18%. The same run counted 140 citations to First Page Sage pages and 95 to Kalicube pages. Those figures can help you identify candidates, but they do not predict how either firm will perform in your category.

    There is also a material conflict to account for: First Page Sage published those measurements and ranked itself first. A conflict is a reason to verify, not an automatic reason to discard. Ask the agency to rerun a mutually agreed sample for your market, retain the raw outputs, and explain every counting decision.

    Use the same discipline with case studies and reviews. A case study is most useful when it names the baseline, intervention, time window, prompt universe, engines, and commercial result. A review is more credible when it contains operational detail and comes from a client you can verify. Directory stars, anonymous praise, and uniform testimonials should not carry the same weight as a reference call with a comparable customer.

    Send every shortlisted agency the same evidence request:

    • Provide the exact prompts behind any share-of-voice claim and identify branded, non-branded, informational, and transactional prompts.
    • Show complete outputs rather than cropped screenshots, including citations and unfavorable answers.
    • Define recommendation, mention, citation, accurate answer, and qualified referral separately.
    • Identify which engines are tracked in client reporting and which are merely discussed in sales material.
    • Explain how repeated or conflicting answers are handled.
    • Show a case involving a company with a similar sales motion, market complexity, and authority profile.
    • Provide client references that can discuss reporting quality, editorial process, missed targets, and corrective action.
    • Demonstrate what the proprietary score reveals that the underlying prompt-level evidence does not.

    Reject guaranteed placement. A generated answer is not a fixed search position an agency can reserve. The credible promise is a transparent program of measurement, content, entity work, authority development, experimentation, and reporting – not permanent inclusion in every answer.

    Match the agency’s specialty to your actual bottleneck

    There is no useful best agency without a defined problem. A team built for high-volume editorial production may be a poor choice for executive entity correction. A PR-led firm may strengthen third-party authority but be the wrong owner for a complex product-content system. Use agency rankings as a map of candidates, not as a substitute for fit.

    Fit to investigateAgency signals available for due diligenceWhat to verify before hiring
    Small or midsize business focused on qualified leadsFirst Page Sage reported 26% recommendation share, 140 citations, 18 published case studies, and a $6,000-$12,000 monthly range.Independently reproduce its visibility measurements because it also produced the ranking in which it placed first. Confirm that case studies resemble your sales cycle and market.
    Executive, company, or brand entity accuracyKalicube brings answer-engine work dating to 2017, Kalicube Pro, coverage of five engines, and roughly 38 public success stories.Ask which entity changes can be observed in your target engines, how persistence is tested, and what the full engagement costs because no public price range was listed.
    Venture-backed software or consumer technologyGraphite had the largest listed team at 281 employees, proprietary tooling, five-engine coverage, and a $10,000 starting price rather than a full range.Determine whether you need the scale and platform, which team members will work on the account, and whether the starting price includes implementation or only a limited scope.
    B2B software editorial contentAnimalz listed 13 public case studies and five clients above $1 billion in revenue; Omniscient Digital listed 15 case studies and two such enterprise clients.Ask how the editorial program changes AI recommendations or citations, not only content output and organic traffic. Animalz used custom quotes, while Omniscient did not publish pricing.
    PR-led authority and independent mentionsRelevance reported the broadest engine coverage at six; Genevate listed a $5,000-$10,000 monthly range but no published case studies in the comparison.Require examples showing how earned coverage affected your target prompts. For newer evidence bases, place more weight on a controlled pilot, raw outputs, and direct references.
    Very small local businessFocus Digital listed a $3,000-$5,000 monthly range and 30 cases across 11 industry practices, including HVAC, healthcare, law, and accounting.Check whether the firm has results in your service area and whether local entity accuracy, reviews, service pages, and lead quality are included in the scope.

    Budget can narrow the field, but unpublished pricing does not mean inexpensive pricing. Among the disclosed ranges in this group, the lowest entry point was $3,000 per month, while another agency published a $10,000 starting price. Ask for the total expected cost, including strategy, content production, technical implementation, digital PR, software access, and reporting. A low retainer with most execution excluded is not directly comparable to an inclusive program.

    Team size also needs context. A large agency can offer specialists and production capacity, but the logo on the proposal does not tell you who will do the work. Ask for the named strategist, editor, technical lead, analyst, and executive sponsor. Confirm how much of the scope is performed by those people, outsourced, or delegated to automation.

    Proprietary tooling deserves a demonstration against your prompts. Kalicube and Graphite were the two firms credited with proprietary GEO platforms in the available comparison. Tool ownership can improve workflow and consistency, but it is not proof of better outcomes. Require data export, metric definitions, historical access, and an explanation of what happens to the account when the engagement ends.

    Build an auditable scorecard, then protect it in the contract

    Three professionals arrange colored tokens in a blank evaluation grid beside a locked case holding documents and a data drive.

    A scorecard prevents the most charismatic sales presentation from winning by default. One defensible starting structure assigns 40% to AI visibility proof, 25% to client validation, 25% to expertise and depth, and 10% to tooling and transparency. Treat those weights as a starting point, not an industry standard. Change them when your problem demands it.

    DimensionStarting weightEvidence to score
    AI visibility proof40%Prompt-level recommendation share, citations, raw answers, reproducibility, and relevance to your market.
    Client validation25%Detailed non-paid reviews, references from comparable clients, public case studies, and experience with similar operational complexity.
    Expertise and depth25%Original experimentation, demonstrated understanding of entities and authority, editorial quality, technical capability, and the seniority of the assigned team.
    Tools and transparency10%Engine coverage, metric definitions, access to raw data, export rights, scope clarity, and complete pricing.

    Score the strength of evidence, not the size of the claim

    Give the strongest assessment to evidence your team can inspect and reproduce. Mark evidence as weaker when the agency supplies only a percentage, screenshot, composite score, anonymous testimonial, or private case study that cannot be discussed with a client. Record why each assessment was assigned so procurement, marketing, communications, SEO, and leadership can challenge the same evidence.

    Adjust the model to the job. If inaccurate executive information is the primary risk, elevate entity expertise, tooling, and persistence testing. If the goal is transactional recommendations, elevate non-branded prompt performance, buyer-intent content, and lead attribution. If independent authority is missing, place more weight on earned coverage and relevant referring domains. Do not retain the original weights merely because they make a favored agency win.

    Turn the winning proposal into enforceable operating terms

    The contract should preserve the evidence standard used in selection. Put these items in the scope or an attached measurement exhibit:

    • Baseline: the approved prompt inventory, engines, collection dates, locations or account conditions where relevant, raw responses, counting rules, and starting results.
    • Reporting: separate fields for recommendations, mentions, citations, factual accuracy, AI referral traffic, conversions, and assisted commercial outcomes.
    • Rerun policy: the schedule, treatment of answer variation, handling of failed queries, and process for changing the prompt set.
    • Deliverables: the exact content, entity work, technical changes, authority campaigns, digital PR, schema work, and measurement tasks included in the fee.
    • Approvals: who can publish, edit factual claims, contact media, update structured data, or change high-value pages.
    • Ownership: your rights to content, prompt libraries, dashboards, raw exports, media lists, research assets, accounts, and reporting history.
    • Access: administrative control of analytics, CRM integrations, publishing systems, and any accounts created for the engagement.
    • Commercial terms: total fees, pass-through costs, renewal mechanics, termination rights, transition assistance, and the treatment of unfinished work.
    • Claims and risk: no guaranteed AI placement, no unsupported product assertions, and a documented escalation path for inaccurate or harmful outputs.

    Have counsel review intellectual-property, confidentiality, data-access, liability, and termination language when the spend or exposure is material. A difficult exit can cost more than a weak first month, especially if the agency controls your measurement history or publishing accounts.

    Your next move is simple: send the same brief and evidence request to every agency on the shortlist. Remove any candidate that will not disclose its denominator, raw outputs, definitions, assigned team, full scope, or exit terms. The agency left standing should be the one that can make its work inspectable before asking you to trust its promise.

    References


  • 2026 Cost Per Lead Benchmarks: 30 Industries Compared

    2026 Cost Per Lead Benchmarks: 30 Industries Compared

    If your cost per lead is $320, is that good? The number alone cannot tell you. A $320 lead would sit well above the 2026 benchmark for B2B SaaS, below the benchmark for financial services, and somewhere else entirely once lead quality and conversion are considered.

    Use industry cost-per-lead benchmarks as diagnostic ranges, not targets. First find the closest industry and channel comparison. Then calculate the CPL your own customer economics can support. That order helps you avoid cutting expensive leads that become valuable customers or scaling cheap leads that never reach the sales pipeline.

    2026 cost-per-lead benchmarks by industry

    The 2026 benchmark covers lead-generation data collected from January 2022 through August 2026. Across 30 industries, the average blended CPL was $400. Average paid CPL was $452, while average organic CPL was $350.

    A lead in this benchmark is a direct connection with a prospective customer who has expressed purchasing interest through email, phone, or an in-person introduction. CPL means gross marketing spend divided by new leads. It does not measure closed customers or include the sales costs captured by customer acquisition cost.

    The blended column is weighted by the share of leads generated by paid and organic channels in each industry. It is not simply the midpoint between the two channel figures.

    IndustryPaid CPLOrganic CPLBlended CPL2025-2026 blended change
    Addiction Treatment$384$232$304+2.4%
    Aerospace & Aviation$453$290$375+0.5%
    Automotive$319$285$302+6.7%
    B2B SaaS$318$186$249+5.1%
    Biotech$281$249$265+3.9%
    Business Insurance$440$412$427+0.7%
    Construction$282$185$235+3.5%
    Cybersecurity$434$427$429+5.7%
    eCommerce$102$90$96+5.5%
    Engineering$355$214$284-1.0%
    Entertainment$115$114$115+0.9%
    Environmental Services$343$217$283+1.8%
    Financial Services$731$591$662+1.4%
    Fintech$494$451$473+4.6%
    Healthcare$363$348$356-1.4%
    Higher Education$1,176$766$970-1.2%
    Hotels & Resorts$268$234$250-6.0%
    HVAC$118$73$96+4.3%
    Industrial IOT$573$427$501+0.8%
    IT & Managed Services$600$418$505+0.4%
    Legal Services$783$580$682+5.1%
    Manufacturing$657$440$547-1.1%
    Oil & Gas$756$526$639+0.3%
    PCB Design & Manufacturing$462$284$371-1.3%
    Pharmaceutical$126$148$140+6.9%
    Real Estate$496$450$472+5.4%
    Software Development$691$573$627+6.1%
    Solar$243$213$227+10.2%
    Staffing & Recruiting$511$543$526+5.8%
    Transportation & Logistics$671$538$604+2.7%

    Key takeaways

    • The cross-industry reference point is $400 blended CPL, but the range runs from $96 in eCommerce and HVAC to $970 in higher education. Industry context is therefore more useful than the overall average.
    • Legal services had a $682 blended CPL and financial services had a $662 CPL. Higher contract values and longer sales cycles tend to support more expensive lead acquisition than short-cycle consumer and local-service purchases.
    • Paid leads cost more than organic leads in 28 of the 30 industries. The two exceptions were pharmaceutical, at $126 paid versus $148 organic, and staffing and recruiting, at $511 paid versus $543 organic.
    • Across all industries, paid CPL carried a 29% premium over organic CPL. The widest gaps appeared in B2B SaaS, where paid leads cost 71% more, and in engineering and addiction treatment, where the premium was 66%.
    • Blended CPL increased in 24 industries. Solar recorded the largest increase at 10.2%, while hotels and resorts had the largest decline at 6.0%.

    A benchmark cannot tell you whether your CPL is profitable

    A balance scale weighs acquisition tokens against a customer journey, with a transparent funnel filtering many lead spheres into a few valuable gems.

    Your competitor’s CPL and the industry average do not pay your bills. Your acceptable CPL depends on the value of a customer, the percentage of leads that become customers, the cost of closing and serving them, and the margin your business needs to retain.

    Start with two separate calculations. Observed CPL equals gross marketing spend divided by valid new leads. Maximum CPL equals the maximum marketing acquisition cost you can support per new customer multiplied by your lead-to-customer conversion rate.

    Define that maximum marketing acquisition cost only after accounting for delivery costs, sales costs, expected retention and required margin. Use customer gross profit rather than top-line revenue when you test the ceiling. Revenue can make an unprofitable acquisition program look healthy.

    The conversion rate in the formula must come from a mature cohort of comparable leads. Do not combine a high-intent demo request with a newsletter signup, downloaded template or purchased contact. Each may have a place in your funnel, but they do not carry the same probability of becoming a customer.

    Low CPL can hide an expensive customer

    A cheap channel can produce large numbers of weak inquiries. If those leads rarely qualify, require heavy sales effort or churn quickly, the low CPL is cosmetic. A more expensive referral or high-intent search lead may create better economics because it closes more often and produces greater lifetime value.

    Read CPL beside lead-to-qualified-opportunity rate, lead-to-customer rate, sales effort, customer lifetime value, referral rate and satisfaction. If one channel costs more but wins on those downstream measures, cutting it to meet a benchmark can reduce profit while making the marketing dashboard look better.

    Make your CPL comparable before you diagnose a gap

    A benchmark comparison is useful only when its numerator, denominator and channel match yours. Most apparent CPL problems begin with one of those three elements.

    Use the same lead definition

    Decide what event creates a lead and apply that rule across every channel. Deduplicate repeat submissions, exclude spam and internal tests, and keep raw contacts separate from sales-accepted leads. If your dashboard counts every content download while the benchmark describes people showing purchasing interest, your apparently low CPL is not comparable.

    Use a complete and consistent cost policy

    Gross marketing cost should reflect the resources required to operate the channel, not whichever expenses are easiest to retrieve. For paid acquisition, that can include media, creative production, landing-page work, management and relevant tools. For organic acquisition, it can include strategy, content, technical work, optimization and distribution. The accounting choice can vary by company; the important part is to document it and apply it consistently.

    If one team reports ad spend alone while another reports fully loaded channel cost, the resulting CPLs should not be ranked against each other. Rebuild them under one cost policy first.

    Compare channel with channel

    Compare paid performance with the paid column and organic performance with the organic column. For your own blended CPL, use total paid and organic spend divided by total paid and organic leads. Do not average the two channel CPLs unless they generated identical numbers of leads.

    Keep source, campaign, offer and lead type attached to each record in your CRM. A single account-wide CPL can conceal a strong high-intent campaign, a weak prospecting campaign and an attribution problem at the same time.

    Allow conversion cohorts to mature

    CPL is available as soon as a lead enters the system, but lead quality becomes visible later. Comparing this month’s new leads with an older cohort’s closed customers creates a false relationship. Freeze channel cohorts by acquisition period, let them progress through the normal sales cycle, and then calculate qualification and customer conversion against the original lead count.

    Paid and organic CPL are moving in different directions

    The all-industry average paid CPL fell 1.3%, from $458 to $452, with declines in 15 industries. Organic CPL rose 7.3%, from $326 to $350, and increased in all 30 industries. As a result, the average paid premium over organic narrowed from 40% to 29%.

    This does not make paid acquisition cheap or organic acquisition ineffective. It means the old assumption that organic leads will remain dramatically less expensive needs to be tested against your current data.

    Lower click-through rates have been measured when search results contain AI-generated summaries. If the same content investment produces fewer site visits and leads, measured organic CPL rises even when rankings or search visibility appear stable. That mechanism is especially relevant to businesses whose buyers begin with informational research. B2B SaaS had a 13.4% organic CPL increase, while legal services and software development each rose 12.4%.

    Do not treat AI summaries as a complete explanation for every increase. Content costs, conversion performance, attribution rules, offer strength and query mix can also change your result. Look for the break in your own funnel: impressions to clicks, clicks to qualified visits, visits to leads, leads to opportunities, or opportunities to customers.

    For informational content, supplement last-click CPL with assisted pipeline evidence. Preserve original and subsequent acquisition touches, connect landing pages to CRM outcomes, and ask qualified prospects how they first encountered the business. AI visibility that influences demand may not produce an immediate click, but that possibility is not a reason to assign unverified value. Keep direct and assisted results separate so the interpretation remains auditable.

    Turn the benchmark into a channel decision

    A strategist compares a token-powered megaphone with a growing network of vines as both channels send leads toward a central sales funnel.

    Because these figures aggregate one organization’s lead-generation data across a multiyear collection period, they are planning references rather than universal market prices. Your offer, geography, brand demand, competitive environment and qualification rules can move CPL materially.

    1. Choose the closest industry row and the matching paid, organic or blended column. If your company spans categories, keep the relevant business lines separate instead of selecting the most flattering benchmark.
    2. Recalculate your observed CPL with a documented definition of gross marketing spend and a deduplicated count of valid new leads.
    3. Calculate your maximum CPL from allowable marketing acquisition cost and the conversion rate of a mature, comparable lead cohort.
    4. Compare both CPLs with downstream quality. If you are above the industry benchmark but below your profitable ceiling, investigate the gap without assuming the channel is failing. If you are below the benchmark but above your ceiling, the program still needs correction.
    5. Make the next budget decision at the channel, campaign and offer level. Shift incremental spend toward the combinations that produce customers with stronger lifetime value, referral behavior and satisfaction relative to acquisition cost.

    Your next move is not to force every campaign toward the $400 cross-industry average. Open one channel report, rebuild its numerator and denominator, and attach qualification rate, close rate and customer value. Once that view is clean, the benchmark becomes what it should be: a prompt to investigate, not a target to obey.

    References