Author: shivamcrushpressai

  • Google Ads Automation Without Giving Up Advertiser Control

    Google Ads Automation Without Giving Up Advertiser Control

    You approved more automation because you wanted better allocation, not because you wanted to stop making decisions. Then reported ROAS rises while branded traffic absorbs spend, or a Demand Gen campaign reaches beyond the audience you meant to test. The system may be performing exactly as configured while moving away from the business outcome you actually wanted.

    The answer is not to reject automation or accept every expansion Google proposes. You need to decide where the machine can explore, where it must stop, and which evidence will earn it more freedom.

    Advertiser control is not the same as manual execution

    An automated campaign can still be tightly governed. A manually adjusted campaign can be poorly controlled. The difference is whether you have deliberately defined four things: the campaign’s job, the data it can learn from, the inventory or audiences it can access, and the business result used to judge it.

    This matters because Google optimizes toward the signals available inside the account. It cannot infer that a branded conversion is less incremental than a first purchase from a new customer, that one product has a much better margin than another, or that a conversion from a suggested audience is commercially weaker. If those distinctions stay outside your measurement and structure, automation will treat them as irrelevant.

    Key takeaways

    • Give automation freedom only where you can measure the economic effect of that freedom.
    • Do not confuse audience size with audience enforcement. Narrow, Balanced, and Broad describe the Lookalike pool; constraint and suggestion determine whether that pool is a boundary.
    • Do not accept blended Performance Max ROAS as proof that every channel, product, or customer type is working.
    • Fix weak inputs, especially ecommerce feeds and audience seeds, before adding budget or fragmenting campaigns.
    • Change one major control at a time so you can tell whether broader delivery produced useful growth or merely more attributed conversions.

    Use Demand Gen Lookalikes as either a boundary or a clue
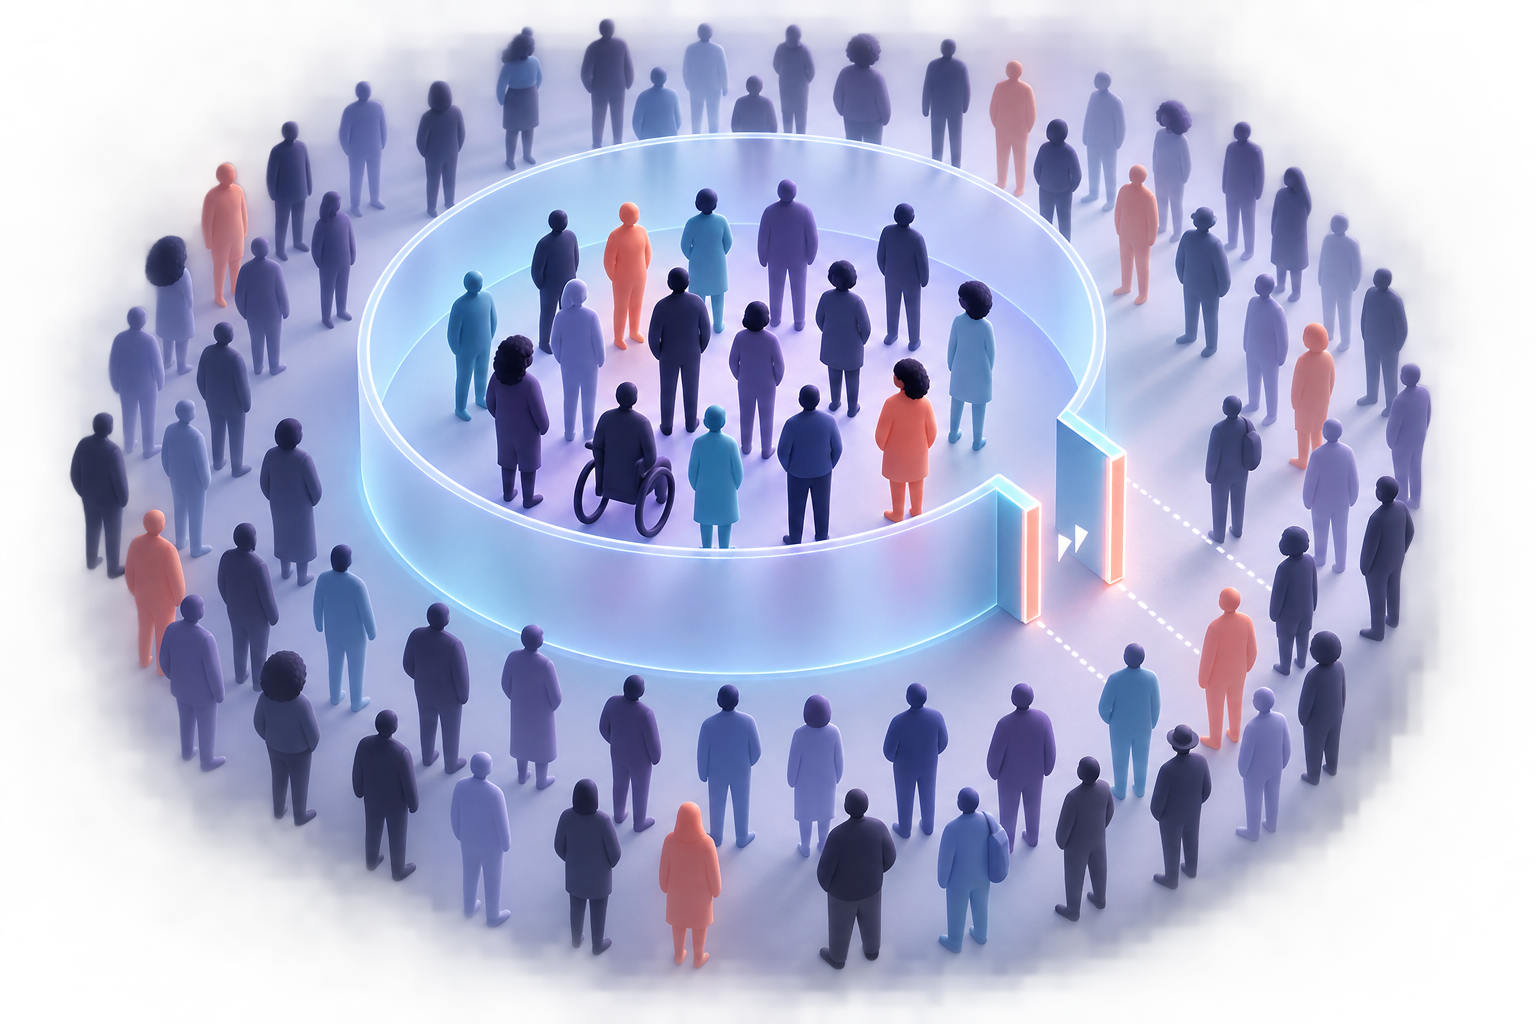
    A defined audience cluster sits inside a translucent boundary, with a controlled opening leading to a wider group of similar people.

    Under Google’s announced Demand Gen change, Lookalike segments are set to move toward audience suggestions by default, while advertisers can opt out and retain targeting constraints. That is not a cosmetic setting change. It alters the role your audience plays in delivery.

    Audience modeWhat the segment meansWhen it fitsMain risk
    Targeting constraintThe selected Lookalike audience is a delivery boundary.You need a defined prospecting cohort, want to test the segment itself, or cannot tolerate expansion into less-qualified traffic.Scale is limited by the eligible audience and the strength of the seed.
    Audience suggestionThe Lookalike audience is a starting signal, and Google’s system has room to reach beyond it.You prioritize conversion volume and can evaluate acquisition cost, conversion quality, and customer value after expansion.More conversions can conceal weaker customers or less relevant reach.

    The distinction is easy to miss. A Narrow Lookalike used as a suggestion is not necessarily a narrow delivery boundary. Conversely, a Broad Lookalike used as a targeting constraint remains a hard boundary around a larger pool. Choose audience size and audience enforcement as separate decisions.

    Lookalike segments can be built from first-party inputs such as customer lists, website visitors, app users, and YouTube audiences. They require more than 100 active matched users across the seed lists, and Google refreshes them every one to two days. Narrow covers the most similar 2.5% of users in the selected location, Balanced expands to 5%, and Broad reaches up to 10%.

    Those percentages tell you how far the Lookalike model reaches before the constraint-or-suggestion decision is applied. They do not tell you which setting will produce profitable customers. A larger audience can create more opportunities, but it can also trade similarity for scale.

    How to make the audience decision without losing the test

    1. Write down the campaign’s job. Decide whether you are testing resemblance to a proven customer group or asking Google to find conversions using that group as an initial signal.
    2. Record the current mode and size. Save whether the segment is Narrow, Balanced, or Broad and whether it is enforced as a constraint. If preserving existing behavior matters, review the opt-out before the planned default change affects it.
    3. Inspect the seed. Confirm that the lists represent the customers or behaviors you want Google to reproduce. Meeting the match threshold does not make a mixed or low-quality seed strategically useful.
    4. Define quality before expanding. Choose the downstream evidence that matters, such as qualified conversions, acquisition cost, repeat purchases, or customer value. Do this before suggestion mode adds reach.
    5. Hold other major variables steady. Avoid changing audience mode, creative, budget, and campaign structure together. Otherwise, you will not know which change affected delivery.
    6. Judge the trade, not just the total. Compare conversion quality, acquisition cost, and customer value alongside volume. Expansion is useful only when the additional business value justifies the additional spend.

    Structure Performance Max around evidence, not ideology

    Performance Max creates two opposite control failures. Excessive consolidation lets one campaign own most of the account and budget, leaving little control over where money goes or which products receive attention. Excessive isolation splits products, audiences, and ideas into so many campaigns that none gathers enough conversion data to optimize well. The workable structure sits between those extremes and can change as the account’s signals change.

    The decision should follow observable account conditions. Brand cannibalization, feed readiness, channel performance, conversion volume, and product margins can all justify a different degree of segmentation. A single structure should not be forced across every account or every stage of an account.

    Separate brand efficiency from prospecting performance

    A strong blended ROAS can be misleading when Performance Max captures branded searches from people who were already likely to buy. The platform sees a cheap conversion and learns that it is desirable; your report then mixes harvested brand demand with the harder work of finding new customers.

    Start with the brand-versus-nonbrand split. Inspect search-term insights and changes in impression share on branded terms. If cost efficiency is the priority, a dedicated branded Search campaign using exact or phrase match with Target Impression Share can help you defend brand visibility without making Performance Max the only route to those conversions.

    Do not treat universal brand exclusion as a rule. Performance Max is designed as a full-funnel campaign, and a large advertiser may value the journey signal more than the incremental CPC savings. Make the choice explicitly: either preserve the full-funnel signal or separate brand traffic to expose prospecting economics. Do not let the default decide on your behalf.

    Fix the product feed before splitting the campaign

    For ecommerce, the feed is one of the system’s most important inputs. Miscategorized products, vague titles, and missing attributes give Performance Max weak information about what you sell. More budget cannot repair that input.

    Audit feed quality before creating additional campaigns. Correct categories, make titles descriptive, and fill the relevant attributes. Only then decide whether products need separate treatment because their margins, demand, or performance are materially different. Segmentation is a business control when economics differ; it is noise when it merely reproduces the catalog hierarchy.

    Open the blended result and inspect the channels

    Performance Max combines Shopping, Search, Display, and Video into one reported result. A healthy total can therefore hide a productive channel carrying a weak one. Use the channel performance breakdown to see where spend and return are actually coming from.

    If expansion is sending traffic into low-intent delivery, review URL expansion rather than assuming every destination deserves budget. If Search traffic is unwanted, removing search themes is one available lever; verify the effect in the channel breakdown instead of assuming the setting guarantees the outcome. Feed-led Shopping activity appears under the channel label Google Search – Ads from product data feed.

    Products that receive little traction inside Performance Max can be excluded and tested in Standard Shopping. That is not an ideological rejection of automation. It is a controlled way to find out whether the campaign’s internal allocation, rather than the product itself, is suppressing performance.

    Build a control loop around the decisions Google cannot make
    A strategist adjusts a closed-loop advertising system as campaign signals pass through checkpoints and measured outcomes return for review.

    Google can allocate impressions and bids from the signals it receives. It cannot decide how much branded demand is truly incremental, whether a lower-value customer is worth acquiring, or how much margin you are willing to exchange for scale. Your operating process has to supply those judgments.

    1. Declare one primary job for each campaign. Examples include constrained lookalike prospecting, broader demand generation, full-funnel Performance Max, or feed-led product acquisition. If a campaign has several incompatible jobs, its blended result will be hard to interpret.
    2. Audit signal readiness. Check the Lookalike seed, conversion definitions, product data, and the amount of conversion activity available to each campaign. Automation cannot compensate for a feed that misdescribes products or a seed that represents the wrong customers.
    3. Set the boundary. Choose constraint or suggestion for Demand Gen. Decide how brand traffic will be handled. Review URL expansion, search themes, product inclusion, and the campaign splits created by meaningful economic differences.
    4. Create a disaggregated view. Read brand separately from nonbrand, inspect channel performance, and compare products or groups with different margins. Keep the blended total, but do not let it be the only view.
    5. Predefine the response. State what would cause you to tighten or relax a boundary. A rise in conversion count alone should not earn broader targeting if acquisition cost, conversion quality, or customer value deteriorates.
    6. Change one major control and observe the result. Preserve the previous configuration so the decision is reversible. Allow for the account’s normal conversion delay before drawing a conclusion, but do not wait for a blended metric to explain a problem it was not designed to reveal.
    What you noticeWhat it may meanControl to testEvidence to watch
    Demand Gen volume rises but customer quality fallsSuggestion mode may be reaching beyond the useful Lookalike poolPreserve or restore the targeting constraint; inspect the seed and Lookalike sizeAcquisition cost, qualified conversions, and customer value
    Performance Max ROAS is high but new-customer growth is weakBranded demand may be inflating the blended returnInspect the brand split and evaluate a dedicated branded Search campaignBrand versus nonbrand conversions, branded CPCs, and prospecting efficiency
    The total return looks acceptable but traffic quality is unevenOne channel may be carrying weaker Display, Video, or Search deliveryUse the channel breakdown; review URL expansion and search themesChannel-level return and conversion quality
    Important products receive little deliveryFeed quality or internal allocation may be limiting themRepair titles, categories, and attributes; then test selected products in Standard ShoppingProduct visibility, conversion performance, and margin
    Many campaigns remain data-starvedThe account may be over-segmentedConsolidate groups with similar goals and economicsConversion volume available to each campaign and stability of performance
    One campaign favors easy sales from low-margin productsConsolidation may be hiding economic differencesSeparate product groups only where margin or strategic priority justifies controlReturn in the context of product margin, not ROAS alone

    Make the next automation change reversible and measurable

    Before accepting the next Google Ads recommendation, write a short decision note: what new freedom the setting gives the system, what boundary it removes, which business metric should improve, and what result would make you reverse it. If you cannot answer those questions, you are not testing automation; you are transferring control without a way to judge the transfer.

    Start with the smallest change that can answer the question in front of you. Preserve the current configuration, expose the relevant brand, channel, audience, or product split, and let better economics earn broader freedom. That gives Google room to optimize while keeping the decisions that belong to the advertiser in your hands.

    References


  • AI Discovery Optimization: A Practical Visibility System

    AI Discovery Optimization: A Practical Visibility System

    You can publish useful pages, rank for important searches, and still watch other brands appear in AI-generated answers while yours goes unnamed. That gap is not always a writing problem. It is often a discovery problem: the system cannot confidently connect your brand to the question, extract a suitable claim, or verify what that claim means.

    AI discovery optimization aims to make your brand visible when ChatGPT, Gemini, and Google’s AI experiences assemble answers. The practical work is to identify the questions that matter, publish material those systems can reuse, remove ambiguity around your entity, and measure whether your representation is improving.

    Start with the decision, not the keyword

    A keyword tells you what someone typed. An AI prompt often tells you what that person is trying to decide, along with the constraints shaping the answer. Someone may ask for a suitable platform for a small team, a method that works without a particular integration, or an explanation appropriate for a regulated industry. Those qualifiers can change which brands and sources belong in the response.

    Your first task is therefore not to collect a huge list of loosely related prompts. Build a compact query map around real decisions. Start with the questions that could reasonably lead a person to learn from you, evaluate your category, compare approaches, or choose a solution.

    • Record the exact question in natural language.
    • Identify the reader: beginner, practitioner, buyer, executive, developer, or another specific audience.
    • State the decision behind the question. A request for a definition needs a different asset from a request for a shortlist.
    • Capture meaningful constraints such as use case, industry, location, compatibility, risk, or budget sensitivity.
    • Choose the role you want your brand to earn: named option, cited authority, evidence provider, explanatory resource, or next step.
    • Map the prompt to the page that should support that role.

    Use unbranded wording for the core measurement set. A prompt that already contains your company name mainly tests whether a system can find facts about you. A prompt such as “Which tools support this workflow?” tests whether the system associates you with the category before the user supplies that association.

    Group close variants into prompt families rather than treating every wording change as a separate strategy. “What is X?”, “How does X work?”, and “Explain X to a beginner” may belong to one educational family. “Best X for Y,” “X with Z integration,” and “Alternatives for teams that need Y” may belong to separate commercial families because the selection criteria differ.

    Give every family an intended answer role. If you cannot say whether the brand should be a recommendation, a citation, an example, or merely the destination for further detail, you cannot design the right page or interpret the result later.

    Build material an answer engine can reuse

    Blank document panels and evidence blocks move through a modular workshop toward a glowing answer capsule.

    The useful unit of AI discovery is not simply a page. It is a clear claim about a recognizable entity in the context of a particular question. A long page can rank and still be difficult to reuse if its answer is buried, its terminology shifts, or its most important statements depend on promotional language.

    Each target page should pass four tests: the answer is easy to locate, the scope is explicit, the support is visible, and the brand’s relationship to the claim is unambiguous.

    Put the answer near the question

    Open a section with a direct response, then explain it. Do not make the reader cross a company history, a trend forecast, and several vague benefits before reaching the useful sentence. A concise answer gives both people and retrieval systems a stable passage to interpret.

    Write headings that preserve context. “Implementation requirements” is more informative than “What you need.” “When server-side rendering matters” is more useful than “Important considerations.” A section may be retrieved apart from the rest of the page, so its heading and opening paragraph should still make sense together.

    State boundaries with the claim

    A claim becomes more reusable when the reader can see who it applies to, what conditions affect it, and where it stops. Replace “This approach works for every business” with the actual audience, prerequisites, and limitations. If the answer depends on a product version, geography, plan, integration, or regulatory context, put that condition in the same section rather than hiding it in a footnote.

    This is also where honest caveats help discovery. A system choosing between a sweeping claim and a precise one has more usable information in the precise one. You do not strengthen a page by removing every exception; you strengthen it by showing that the claim has a defined shape.

    Separate evidence from marketing language

    “Leading,” “seamless,” and “best-in-class” do not explain what happened, for whom, or under which conditions. Replace unsupported superlatives with inspectable facts: what the product does, what the method requires, how a process is performed, where a definition comes from, or what an original dataset actually contains.

    Do not manufacture evidence for the sake of citation. If you have no defensible benchmark, publish a rigorous process, a carefully bounded explanation, or a transparent comparison framework. Useful specificity is better than false precision.

    Give each page a primary job

    An explainer, product page, methodology page, and comparison page solve different retrieval problems. Forcing them into one document often produces a page with no clear answer shape. Decide whether the page exists to define, instruct, substantiate, compare, or convert. It can support secondary goals, but its opening, headings, and evidence should serve the primary one.

    A practical content brief should name the target prompt family, intended audience, direct answer, selection criteria, supporting evidence, limitations, entity being described, internal links, freshness owner, and appropriate structured data. That brief prevents a writer from producing a polished page that never resolves the actual question.

    Make your brand and its claims unambiguous

    A system cannot reliably connect evidence to your brand if your own properties describe the company in conflicting ways. One page may present you as a software platform, another as an agency, and a profile elsewhere may use an old name or an abandoned category. Even when every statement is individually understandable, the combined entity becomes harder to resolve.

    Create a small, controlled set of facts that should remain consistent wherever they appear:

    • Your official brand name and any legitimate alternate name.
    • A plain-language description of what the organization is.
    • The products, services, or resources it provides.
    • The audiences and use cases each offering serves.
    • The official website, contact details, and relevant public profiles.
    • Any geographic, compatibility, or availability boundaries that affect eligibility.

    This does not mean copying one slogan across the site. It means keeping the underlying facts stable. Your homepage can be concise, the About page can provide history and ownership context, and product pages can be detailed without disagreeing about the basic entity.

    Use structured data as clarification

    Schema markup can identify an organization, article, product, service, author, or other entity in a machine-readable form. Its job is to clarify content that genuinely exists on the page. It is not a purchase order for an AI citation.

    Choose the most specific applicable schema type, keep names and identifiers consistent, connect related entities where the vocabulary supports that relationship, and validate the markup. Do not mark up reviews, questions, authors, products, or offers that the visitor cannot actually see. Mismatched markup creates another version of the truth instead of clarifying the page.

    Pay particular attention to ownership. An Article entity should connect to the correct author and publisher. A Product or Service entity should use the same recognizable name found in the visible copy. An Organization entity should point to genuine official profiles rather than every page that happens to mention the company.

    Remove ordinary retrieval barriers

    AI optimization does not excuse basic technical neglect. Important pages should resolve normally, use the intended canonical URL, appear in the site’s linking structure, and expose their essential text without requiring a fragile interaction. Review robots directives and other access controls deliberately. Blocking a system may be the right governance choice, but it should be a decision rather than an accident.

    Keep internal links descriptive. “See our enterprise migration checklist” carries more meaning than “learn more.” Connect explanatory pages to evidence, evidence to methodology, and product claims to the pages that substantiate them. The resulting structure helps a person verify the claim and makes the relationship between your assets easier to follow.

    Design claims that deserve to be cited

    Being mentioned and being cited are different outcomes. A brand mention shows association with the answer. A citation shows that a particular source helped support it. A brand can be mentioned without receiving a link, and one of its pages can be cited without the brand becoming a recommended option.

    For every fact you hope to earn citations from, make five elements inspectable:

    • The claim: one sentence that can be understood without promotional interpretation.
    • The subject: the organization, product, method, or concept the claim describes.
    • The support: data, documentation, methodology, example, or primary reference appropriate to the claim.
    • The boundary: audience, version, period, location, prerequisites, and exceptions where relevant.
    • The maintenance context: who owns the page and what event should trigger a review.

    Adjacency matters for human verification. Put the supporting explanation beside the claim instead of expecting a reader to infer a connection from a distant resources page. If a chart carries the evidence, label its variables and explain the method. If a comparison expresses editorial judgment, disclose the criteria. If a definition comes from an established authority, link to the originating material when it is available.

    Original material can give a page a distinct reason to be used, but “original” is not the same as reliable. Document how information was collected, what was included, what was excluded, and what the result cannot establish. A small transparent dataset or a precise operational framework is more defensible than an impressive number with no visible method.

    Do not create a thin page for every prompt variation. That produces repetition rather than additional evidence. Build one strong resource when several questions share the same intent, then use descriptive sections to resolve the meaningful variants. Split a page only when the audience, decision, evidence, or answer changes enough to require independent treatment.

    Measure representation, not one lucky answer

    A researcher observes several glowing answer portals that show different levels of visibility for one central marker.

    AI answers are generated in response to a prompt and can vary with wording, context, platform, and session conditions. A single screenshot proves that one output occurred. It does not establish durable visibility. Measurement becomes useful when you run a defined prompt set consistently and preserve enough context to compare observations.

    For each check, record the exact prompt, prompt family, platform, date, relevant session conditions, response, cited URLs, brand mentions, competitors mentioned, and whether the description of your brand is accurate. Preserve the answer itself; a summary written from memory will conceal wording that later turns out to matter.

    Track separate metrics because each one diagnoses a different problem:

    MetricCalculationWhat it tells you
    Mention rateEligible prompts that name the brand divided by all eligible promptsWhether the brand is associated with the question set
    Citation rateEligible prompts that cite any owned page divided by all eligible promptsWhether your site is being used as supporting material
    Recommendation inclusion rateCommercial prompts that include the brand as an option divided by all measured commercial promptsWhether the brand enters relevant consideration sets
    Accurate representation rateBrand mentions with correct core facts divided by all brand mentionsWhether visibility is helping or distorting your position
    Prompt-family coverageTarget families with a qualifying mention or citation divided by all target familiesWhether visibility is broad or concentrated in one narrow use case

    Keep the denominator visible. “We received more mentions” is hard to interpret if the prompt set changed. Freeze a baseline set for trend measurement and maintain a separate exploratory set for discovering new questions. Promote a new prompt into the baseline only through a documented change, not because it produced a favorable answer.

    You can weight prompts by business importance, but retain the unweighted results as well. Otherwise, a scoring change may look like a visibility change. A transparent dashboard should let you move from the headline rate to the prompt, answer, citation, and target page that produced it.

    Read the pattern before choosing the fix

    No mentions and no owned citations may indicate that you lack a relevant asset, the asset is hard to retrieve, or the brand has not been clearly connected to the category. Do not rewrite every page until you identify which of those conditions applies.

    An owned citation without a brand mention means your material may be useful while the brand attachment remains weak. Review how the page names its publisher, product, author, and organization. A brand mention with incorrect facts points toward entity inconsistency or outdated material. Correct the authoritative page first, then align supporting profiles and structured data.

    A correct mention without a link is still discovery, but it is not owned traffic. Decide which outcome the prompt should produce before calling it a failure. Some questions are satisfied inside the generated answer; others create a natural need for documentation, a tool, a detailed method, or a transaction. Optimize the destination for the second group instead of forcing a click into every answer.

    Keep AI referral traffic, conversions, and visibility observations distinct. They answer different questions. Visibility tells you whether you entered the answer. Referral data tells you whether someone continued to your site. Conversion data tells you what happened after that visit. Combining them into one score hides the broken stage.

    Turn the work into a controlled improvement cycle

    AI discovery optimization becomes manageable when each cycle tests a defined gap. The sequence is straightforward:

    1. Establish a baseline using your fixed prompt set.
    2. Select one commercially or editorially important prompt family with weak coverage.
    3. Inspect the current answers, named entities, cited domains, and descriptions used.
    4. Decide whether the gap is relevance, evidence, entity clarity, retrievability, or page design.
    5. Create or improve the asset that directly addresses that diagnosis.
    6. Align visible copy, structured data, internal links, and official profiles where necessary.
    7. Repeat the same measurement process and compare the underlying answers, not just the headline score.

    Change one coherent cluster at a time. If you rewrite the page, alter the prompt set, change the scoring rules, and add new schema simultaneously, you will not know what the next result means. AI outputs contain unavoidable variability, so disciplined inputs matter more than dramatic dashboards.

    Key takeaways

    • Optimize for the reader’s decision and constraints, not a keyword in isolation.
    • Treat a clear, bounded, supported claim as the basic unit of AI discovery.
    • Keep brand, product, audience, and availability facts consistent across visible content and structured data.
    • Distinguish mentions, citations, recommendations, accuracy, traffic, and conversions.
    • Use a fixed baseline prompt set for trends and a separate exploratory set for discovery.
    • Diagnose the missing link before changing content: relevance, evidence, entity clarity, retrieval, or answer design.

    Start with one prompt family that matters to the business and one page that ought to earn a role in the answer. Make its claim direct, its evidence inspectable, its entity clear, and its technical path clean. Then measure the same questions again. That small loop will teach you more than a site-wide campaign built around an undefined “AI visibility” score.

    References


  • Brand Visibility in AI Search: A Practical 90-Day Plan

    Brand Visibility in AI Search: A Practical 90-Day Plan

    Your brand can rank for an important commercial keyword and still disappear when a buyer asks an AI assistant which product to choose. That is not just a ranking problem. It means the assistant may lack enough relevant, credible evidence to understand when your brand fits, distinguish it from competitors, and support a recommendation.

    You can diagnose that gap without chasing every possible prompt or publishing more generic content. The practical route is to measure a focused set of buying questions, inspect the sources shaping the answers, and turn the missing evidence into a prioritized 90-day plan.

    Define visibility as a decision outcome

    AI visibility is not a single ranking position. A brand can appear in an answer without being recommended, receive a recommendation without a citation, or be described inaccurately. If you combine all of those outcomes into one visibility score, you will struggle to decide what to fix.

    Track five distinct signals for every commercially important prompt:

    • Presence: Does the answer mention your brand at all?
    • Recommendation: Is your brand presented as a suitable choice, or merely included in a long list?
    • Fit: Does the answer connect your brand to the intended customer, use case, constraint, or desired outcome?
    • Accuracy: Are the product, audience, capabilities, and limitations represented correctly?
    • Evidence: Does the answer cite your site, an independent source, or no visible supporting source?

    This distinction matters because people can now express far more specific circumstances, priorities, and trade-offs than they could fit into a short keyword. A buyer does not have to ask for the best project-management software. They can ask for a tool suitable for a particular team, workflow, previous failure, integration requirement, and budget trade-off in one request.

    Your content therefore needs to make the conditions of fit explicit. For each offer, complete this sentence internally: Our product is a strong fit for this type of customer, doing this job, under these constraints, because of this verifiable evidence. Then document the situations where it is not the best fit. Clear limits make a recommendation easier to defend and reduce the chance that an assistant confidently matches you to the wrong buyer.

    The prompt itself may not contain every relevant detail. Some assistants can use context from previous interactions, although memory and personalization differ by platform, setting, and permission. You cannot optimize for an invisible personal history. You can make your public evidence detailed enough to support multiple real-world situations rather than one generic category query.

    Build a prompt set around real buying situations

    Start with nonbranded, bottom-of-funnel questions. These reveal whether an assistant discovers your brand before the buyer has decided to look for it. Branded prompts remain useful for checking accuracy, but they should not be allowed to inflate your discovery baseline.

    A workable initial set contains 20 to 50 prompts, depending on your offers, industries, use cases, and customer groups. Twenty focused questions are more informative than hundreds of synthetic variations that carry the same intent.

    1. List the decisions that can create revenue. Begin with the products, services, or use cases a qualified buyer might choose during the evaluation stage.
    2. Identify the person and situation behind each decision. Add the customer type, job to be done, operating environment, and meaningful constraints.
    3. Turn the category term into a natural question. Construction scheduling software, for example, could become a question about which scheduling tool best fits a general contractor coordinating field crews.
    4. Add the trade-off. Ask what the buyer prioritizes and what they are willing to compromise on. This can expose a fit that a generic best-of query would hide.
    5. Use the language buyers already use. Sales conversations and customer discussions can reveal the concerns, comparisons, and selection criteria that matter during a purchase.

    Your set should cover different decision shapes, not just different wording. Include category recommendations, use-case recommendations, competitor comparisons, alternatives, and questions built around a significant constraint. Keep each prompt tied to a commercial reason. If you cannot explain what decision a prompt represents, remove it.

    Store enough context beside each prompt to make the results actionable: intended customer, offer, use case, buying stage, business priority, and the competitors you would reasonably expect to appear. This prevents a low-value informational prompt from carrying the same weight as a question that could influence a purchase.

    Diagnose gaps by engine and competitor

    Strategists compare three abstract AI systems that present different selections of the same generic products.

    Set up the prompt set in an AI visibility platform and select your real competitors. Split the results by engine rather than relying only on a blended score. Let the project run for at least a couple of weeks before drawing conclusions; an isolated run is a snapshot, not a dependable baseline.

    For each engine, compare your presence, recommendation rate, share of voice, cited sources, and accuracy with the same measures for competitors. Preserve the individual answers so you can inspect why a score changed. A percentage can tell you that visibility moved. It cannot tell you whether a new citation, a corrected product description, or a different competitive shortlist caused the movement.

    Engine-specific weakness can provide a useful first diagnostic, but it is not proof of one universal cause. Use the pattern to choose what to inspect next:

    Observed patternFirst hypothesis to testWhat to inspect
    Weak mainly in Google AI OverviewsUnderlying organic visibility or ranking-page coverageCompare the pages that rank with the pages and details used in the generated answer.
    Weak mainly in ChatGPTThin entity presence or too few consistent mentions across the webCheck whether authoritative profiles, listings, editorial mentions, and ecosystem pages describe the brand consistently.
    Weak mainly in PerplexityInsufficient presence in recent, retrievable citation sourcesInspect the dates, directories, editorial pages, and relevant community sources cited for the prompt set.
    Weak for one topic across every engineA substantive content or evidence gapCheck whether any page clearly answers the scenario and supports its claims with specific evidence.

    Do not turn these hypotheses into channel stereotypes. Open the actual answers and citations. If the same missing capability, use case, or customer detail appears repeatedly, you have a content problem. If assistants understand the category but repeatedly choose brands with broader independent coverage, you have an off-page evidence problem. If your brand appears but the description is wrong, correct the most likely upstream facts before trying to increase mention volume.

    Competitor comparison keeps the audit honest. A low absolute score may reflect a difficult category where every brand is rarely named. A modest score may conceal a serious gap if one competitor dominates the prompts most closely tied to revenue. Review which competitor wins, the conditions under which it wins, and the evidence the answer uses to justify that choice.

    Map the citation ecosystem, then earn a place in it

    A generic product is linked by glowing lines to abstract representations of research, news, reviews, directories, books, and expert commentary.

    Much of your AI visibility depends on websites you do not own. Improving your own pages remains necessary, but it cannot create independent corroboration. Structured data can clarify facts already present on an eligible page; it cannot manufacture missing reviews, editorial coverage, partner validation, or community discussion.

    AI answers often return to a concentrated group of relevant pages and domains. That makes citation analysis one of the most useful parts of the audit. Pull the 40 most frequently retrieved domains, then review the leading individual URLs and any fan-out queries your monitoring platform exposes. Those queries show the narrower retrieval needs hiding behind a buyer’s larger question.

    Classify each source manually. Useful categories include owned, competitor-owned, directory or review, editorial or media, community or user-generated content, ecosystem, and analyst. Automated labels can be misleading, so the category should reflect how the page actually functions.

    Next, sample 20 to 30 of the most-cited URLs. Record:

    • Which prompts retrieve the page.
    • The page format and the question it answers.
    • Its publication or most recent update date, where available.
    • Whether your brand appears and whether the description is accurate.
    • Which competitors appear and what claims support them.
    • Whether you can update, contribute to, pitch, or otherwise influence the page legitimately.
    • The internal owner and next action.

    Authority and traffic metrics can add context, but retrieval frequency and topical relevance should drive the first cut. A famous domain that never appears for your commercial prompts is less urgent than a specialized page that repeatedly shapes the shortlist.

    Turn missing appearances into a source-gap backlog. The correct response depends on the source type:

    • Directory or review page: Complete or correct the listing, supply verifiable product information, and make it easy for genuine customers to provide honest feedback.
    • Editorial page: Identify the specific omission or outdated detail, then offer a factual update that improves the page for its audience. Inclusion is the publisher’s decision.
    • Ecosystem page: Check integration directories, partner pages, implementation resources, and other places where the commercial relationship can be documented accurately.
    • Community page: Contribute transparently when you have direct expertise. Do not manufacture recommendations, disguise employees as customers, or flood discussions with promotional replies.
    • Competitor-owned page: You may not be able to influence it. Determine why assistants treat it as a category reference, then create a more complete, neutral, and evidence-backed resource on a property you control.
    • Owned page: Add the missing customer situation, comparison, constraint, evidence, or update. Connect the page to the rest of your site so it is not an isolated answer.

    A competitor whose own site is retrieved across many conversations deserves special attention. Comparison and alternatives pages can become category references when they explain the market clearly. Do not copy the format blindly. Inspect the questions answered, the level of specificity, the freshness of the information, and whether your own resource could be more balanced and useful.

    Run a 90-day plan that produces decisions

    The audit is only valuable if every finding becomes an owned action with a verification method. Organize the 90-day cycle around three phases rather than a disconnected list of content, PR, and technical tasks.

    Establish the baseline

    During the first couple of weeks, finalize the prompt set, competitors, and engine coverage. Capture the complete answers, citations, and five visibility signals for each prompt. Avoid changing the core prompt set during this period. If the measuring stick moves at the same time as the work, you will not know whether performance improved.

    Complete the citation map and assign each weakness to a primary cause: owned-content gap, organic visibility problem, inaccurate entity information, missing third-party coverage, weak evidence, or unclear customer fit. A task should not enter the plan until it has a named owner and a result you can check.

    Fix the highest-value evidence gaps

    Prioritize by buyer value, repeated absence, source influence, and feasibility. Start with gaps that affect several high-intent prompts or appear across several engines. A single accurate category page may solve several related content gaps; one inclusion in a repeatedly cited directory may improve the evidence available for several buying scenarios.

    Route the work to the team that can actually change the evidence. SEO and content teams can improve owned pages and organic coverage. Product marketing can verify positioning, capabilities, comparisons, and limitations. PR, partnerships, and customer teams can pursue legitimate third-party representation. Subject-matter experts can participate in relevant communities without pretending to be independent customers.

    Keep the backlog tied to URLs and prompts. Publish a page because a defined buyer question lacks an adequate answer, not because the calendar needs another article. Pursue an external mention because the page repeatedly influences your category, not because its domain metric looks impressive.

    Validate with the same test

    Rerun the original prompt set by engine. Compare presence, recommendation, fit, accuracy, and citations with the baseline. Check whether the intended new or updated source is being retrieved and whether the answer changed in the expected way. A placement is progress, but it is not evidence of an AI visibility gain until the monitoring results change.

    Keep the original prompts as a stable benchmark and add newly discovered buyer questions as a separate cohort. This preserves comparability while allowing the program to learn from sales conversations, customer language, and retrieval queries.

    Key takeaways

    • Measure whether your brand is present, recommended, accurately matched, and supported by evidence; do not collapse those outcomes into one unexplained score.
    • Build 20 to 50 nonbranded prompts around real buying situations, constraints, and trade-offs.
    • Compare engines and competitors separately, and treat platform patterns as hypotheses that require answer-level inspection.
    • Map the domains and pages that repeatedly shape answers, then prioritize source gaps by commercial relevance and retrieval frequency.
    • Use the same prompts to validate changes. Keep new prompts in a separate cohort so your baseline remains meaningful.

    Start with the decision questions, not the publishing calendar. Write the questions a qualified buyer would ask when the choice becomes difficult, run them long enough to establish a baseline, and let the resulting citations define the backlog. That gives you a repeatable way to improve the evidence AI assistants can retrieve instead of guessing at what an algorithm might reward.

    References


  • How to Choose a Sales Operations Consulting Firm in 2026

    How to Choose a Sales Operations Consulting Firm in 2026

    You are probably not looking for a sales operations consulting firm because the sales team is merely untidy. Leads are being mishandled, forecasts cannot be trusted, tools are creating more work than they remove, or marketing-generated demand is reaching a CRM that cannot turn it into accountable pipeline.

    The right firm should do more than recommend a cleaner process. It should diagnose the operating failure, rebuild the necessary parts of the system, prove that the changes work, and leave your team able to run them. Here is how to define that job, build a credible shortlist, and keep the engagement tied to business outcomes.

    Key takeaways

    • Decide whether the problem belongs to SalesOps or spans marketing, sales, and customer success before you contact firms.
    • Evaluate strategy, process, technology, data, and enablement separately. A firm that is strong in one area may not be able to deliver the other four.
    • Treat platform certifications and partnerships as evidence of familiarity, not proof that a proposed architecture fits your business.
    • Require named deliverables, acceptance tests, data safeguards, ownership, and knowledge transfer in the statement of work.
    • Baseline funnel and operating metrics before implementation. Otherwise, neither you nor the consultant will be able to separate improvement from ordinary pipeline variation.

    Define the job before you shortlist a firm

    Sales operations usually concentrates on the machinery of the sales organization: territories, lead assignment, opportunity stages, forecasting, CRM administration, compensation support, reporting, and rep productivity. Revenue operations extends the operating model across marketing, sales, and customer success.

    That distinction changes the firm you need. If leads enter correctly but sales stages are inconsistent, a focused SalesOps engagement may be enough. If campaign data, sales activity, contracts, onboarding, and renewals use conflicting customer records or definitions, the work is RevOps even if the visible complaint started in sales.

    Translate the complaint into a work package before requesting proposals:

    • Leads wait, disappear, or reach the wrong rep: investigate lifecycle definitions, assignment rules, queues, service expectations, exception handling, and routing data.
    • Pipeline reports change depending on who runs them: investigate stage definitions, required fields, historical data, calculation logic, permissions, and dashboard governance.
    • Reps work outside the CRM: determine whether the problem is poor workflow design, missing integrations, slow administration, unnecessary data entry, or weak enablement. Do not assume it is resistance to change.
    • The stack contains overlapping tools: map each system’s purpose, owner, data written, data read, renewal date, and dependencies before removing anything.
    • Marketing produces inquiries but sales disputes their quality: define qualification, acceptance, rejection reasons, recycling, follow-up ownership, and the feedback path to marketing.
    • AI experiments are multiplying without governance: identify approved data, human review points, logging, failure handling, and which system remains authoritative before automating more work.
    • The customer handoff breaks after the sale: include customer success, onboarding, and renewal data in scope. A sales-only fix will move the bottleneck rather than remove it.

    Write the problem in one sentence: We need to change [workflow or decision] because [observable failure], and we will know it works when [defined measure] improves without [important guardrail] deteriorating. For example, a routing project might aim to improve correct assignment while preserving territory rules and a human path for exceptions.

    Then document six boundaries: teams in scope, regions, sales motions, customer segments, systems, and decisions the consultant may make without executive approval. This prevents a proposal for a CRM cleanup from quietly becoming a company-wide transformation program.

    Build a shortlist around operating fit, not rank alone

    The sales operations market includes embedded operators, enablement specialists, technical architects, and platform-focused implementers. These eight firms provide a useful 2026 longlist, but their differences matter more than their order.

    FirmBest starting reason to assess itListed platform focus
    DomestiqueEmbedded, full-lifecycle fractional RevOps for B2B SaaS, covering strategy, process, technology, data, and enablementHubSpot, Salesforce, Claude, Clay, Salesloft, Outreach, LeanData, ZoomInfo, DealHub, Gong, Marketo, Apollo, and Pipedrive
    SkaledAI-augmented GTM execution where sales strategy, operations, workflow design, and rep enablement must move togetherSalesforce, Salesloft, Outreach, and HubSpot
    Go NimblyRevenue architecture for mid-market and enterprise SaaS, especially when systems must support continued growthSalesforce, HubSpot, Outreach, and Salesloft
    RevPartnersHubSpot architecture combined with Clay-based enrichment, signals, and GTM workflowsHubSpot and Clay
    Alexander GroupA platform-agnostic option assessed across all five operating capabilitiesPlatform-agnostic
    OperatusA multi-platform option spanning four of the five assessed operating capabilitiesSalesforce, HubSpot, Apollo, Salesloft, LeanData, Marketo, and Outreach
    Six and FlowA HubSpot-centered option with adjacent deal and revenue intelligence toolingHubSpot, DealHub, and Ebsta
    Winning by DesignA platform-agnostic option spanning four of the five assessed operating capabilitiesPlatform-agnostic

    Use the table to decide whom to investigate, not whom to hire. A platform name can mean anything from occasional configuration work to deep architectural experience. Ask each firm to show an anonymized architecture diagram, routing specification, data dictionary, test plan, and adoption deliverable from a comparable engagement.

    Four distinctions will narrow the list quickly:

    • Greenfield versus repair: building a first operating model requires strong discovery and prioritization. Repairing a mature environment requires dependency mapping, migration discipline, and the ability to preserve working processes.
    • Fixed platform versus open architecture: a HubSpot-and-Clay specialist makes sense when those tools are deliberate constraints. A platform-agnostic firm is more useful when the engagement must determine whether the current stack should survive.
    • Advice versus embedded execution: decide whether you need a roadmap, temporary operating capacity, implementation, or all three. A polished roadmap has little value if nobody is accountable for configuring, testing, training, and maintaining the result.
    • Existing RevOps maturity: an established team may need architecture and specialist capacity. A company building from scratch also needs decision rights, definitions, governance, and an internal owner who can absorb the system.

    Ownership changes also deserve diligence. RevPartners became a Walker Sands company in June 2026. That is not inherently positive or negative, but you should confirm which legal entity contracts with you, which team performs the work, and whether marketing, demand generation, and RevOps services share one delivery owner.

    Score capability, platform depth, and delivery leadership separately

    Three connected workstations show specialists mapping a process, configuring technology modules, and leading a team rollout.

    Comparable proposals are easier to evaluate when every firm faces the same scorecard. A useful starting structure is the 40/40/20 evaluation model: 40% for firm capabilities, 40% for GTM platform proficiency, and 20% for leadership experience.

    The capability portion divides evenly across five areas:

    • Strategy: Can the team turn commercial goals into a sequenced operating roadmap with owners, dependencies, and tradeoffs?
    • Process: Does its design follow the complete customer journey, including exceptions and handoffs, rather than optimize one isolated stage?
    • Technology: Can it configure and integrate the stack, or will implementation be handed to another party after the recommendations are approved?
    • Data: Can it define fields, sources of truth, identity rules, calculations, quality controls, lineage, and reporting logic?
    • Enablement: Can it help managers and users adopt the new system through training, playbooks, reinforcement, and observable usage measures?

    Do not preserve those weights mechanically when your risk is concentrated. A high-stakes CRM migration should give more influence to technical implementation, data controls, testing, and rollback experience. A sound process that reps consistently bypass should put more weight on workflow design, manager reinforcement, and enablement. Keep the total score visible, but also establish non-negotiable requirements that no aggregate score can cancel out.

    Ask for evidence that matches the work

    Use the same questions in every finalist interview:

    1. What do you believe is causing the problem, and what evidence would disprove that diagnosis?
    2. Which discovery decisions must be made before configuration begins?
    3. Who will perform the day-to-day work, and how much time will the senior person named in the proposal spend on it?
    4. Show us the actual form of the routing map, data dictionary, dashboard specification, testing plan, and training material we will receive.
    5. Which parts of our stack have you configured directly, and which parts would require a partner or subcontractor?
    6. How will you test integrations, historical data, permissions, automation, and exception paths before release?
    7. What will remain manual after the engagement, who will own it, and why should it remain manual?
    8. Which assumptions could materially change the fee, schedule, or scope?
    9. How will our internal administrator learn to operate and change the system without ongoing dependence on your team?
    10. What does a clean exit look like if we stop after discovery or after implementation?

    Leadership experience should be assessed at the delivery-team level, not inferred from a founder’s biography. Request the names and roles of the people assigned to discovery, architecture, configuration, data work, quality assurance, and enablement. If important work is described as a shared responsibility, ask who has final decision authority.

    Test platform expertise with a scenario

    Give finalists one realistic scenario with sensitive details removed. For example: an inquiry is enriched, assigned by territory and segment, rejected by sales, recycled by marketing, and later converted through a different channel. Ask them to identify the systems involved, authoritative fields, duplicate risk, exception path, audit trail, and reporting treatment.

    You are not looking for free design work. You are checking whether the team asks precise questions before proposing automation. A consultant who jumps directly to a tool feature without clarifying ownership, definitions, and failure modes is showing you how the engagement will run.

    Make the statement of work protect implementation and adoption

    A consultant coaches a client team as they practice a new workflow beside a modular bridge representing implementation and handoff.

    A proposal can sound specific while leaving the expensive decisions for later. Terms such as optimization, alignment, transformation, and dashboarding are not deliverables. Replace them with artifacts, responsible owners, approval gates, and acceptance criteria.

    Require concrete operating artifacts

    Depending on scope, the statement of work should name the outputs you expect:

    • A current-state process map that includes failure points, exceptions, and ownership.
    • A future-state lifecycle with stage entry criteria, exit criteria, allowed transitions, and handoff rules.
    • A routing specification with priority order, assignment logic, fallback behavior, alerts, and test cases.
    • A system architecture showing integrations, direction of data movement, authoritative systems, and administrative owners.
    • A data dictionary defining important objects, fields, permitted values, calculation rules, and retention expectations.
    • A migration and cleanup plan that separates records to preserve, merge, enrich, archive, or review manually.
    • Dashboard specifications that state the population, date basis, filters, exclusions, and formula for each measure.
    • A quality-assurance plan covering normal paths, exceptions, permissions, integration failures, and regression checks.
    • An enablement plan for administrators, managers, and users, with role-specific material rather than one generic training session.
    • Documentation, decision logs, an unresolved backlog, and a formal transfer of ownership at the end.

    Bulk CRM edits, deduplication, record merging, and integration changes can permanently damage data or interrupt active selling. The safe sequence is to export or back up affected data, test changes in a sandbox or controlled sample where the platform permits it, document rollback steps, name the person authorized to release the change, and verify the result before expanding it. Put that sequence in the contract rather than relying on an informal promise to be careful.

    Set phase gates instead of waiting for a final reveal

    Approve the engagement in observable stages:

    1. Diagnosis accepted: stakeholders agree on the problem, evidence, scope, and baseline.
    2. Design accepted: owners approve definitions, workflows, architecture, controls, and exception handling before configuration.
    3. Implementation verified: agreed test cases pass, known defects are recorded, and rollback procedures are ready.
    4. Adoption transferred: users are trained, managers know what to reinforce, administrators can maintain the system, and outstanding work has an owner.

    Tie invoices or formal acceptance to those gates when the commercial arrangement permits it. Also define who approves change requests and how new requests affect price and timing. Otherwise, unresolved strategic questions can be converted into billable implementation changes after work begins.

    Baseline the system before anyone claims improvement

    Capture the current definitions and values of the measures that correspond to the problem. Useful measures can include assignment accuracy, time waiting for assignment, rejected leads by reason, stage conversion, time in stage, aged opportunities, duplicate records, required-field completion, forecast variance, manual steps, workflow failures, and user adoption.

    Separate operating measures from business outcomes. Routing accuracy can show whether a routing project works. Pipeline and revenue can show whether the commercial system is improving, but they are also affected by demand, pricing, market conditions, staffing, and sales execution. Do not let either side claim causation from a before-and-after chart that ignores those factors.

    For organic and AI-search demand, preserve what is known without pretending that every journey is fully observable. Keep original source, later source information, and self-reported discovery as distinct fields when your systems support them. Do not overwrite an original value merely because a later visit is easier to measure, and report unknown attribution as unknown rather than forcing it into a convenient channel.

    Give AI workflows stricter operating rules

    AI can accelerate enrichment, research, drafting, prioritization, and administrative work. It can also reproduce a broken definition at greater scale. Before an AI-assisted workflow goes live, specify its approved inputs, prohibited data, model or service, prompt or instruction owner, output destination, human review point, logging, override path, and shutdown procedure.

    Keep deterministic business rules deterministic when consistency is required. Territory ownership, contractual status, consent, and authoritative lifecycle stages should not depend on an unconstrained model response. Use AI where interpretation is useful, then validate its output before it changes a customer record or triggers an external action.

    Your next move is simple: write the one-sentence problem, select three firms whose operating model fits it, and send all three the same evidence request and scenario. If a firm cannot turn the symptom into a testable scope before receiving broad system access, do not hand it the keys to your revenue engine.

    References


  • How to Build an AI-Assisted Marketing Project Workspace

    How to Build an AI-Assisted Marketing Project Workspace

    Your AI can produce sound campaign ideas while your team still loses the thread. The launch goal lives in a brief, audience notes sit in another document, performance evidence stays in dashboards, and the reasoning behind a decision disappears into separate chats. Each new conversation starts by reconstructing the project.

    An AI-assisted marketing project workspace should end that reconstruction. Its job is to give people and AI the same operating context, connect recommendations to evidence, and preserve the human decisions that turn a suggestion into accountable work.

    Build an operating brief, not a folder of prompts

    A folder tells you where material is stored. An operating brief tells you what is true, what has been approved, what is changing, and what the team should do next. That distinction determines whether your workspace becomes useful infrastructure or another archive nobody trusts.

    Organize the workspace into distinct layers so that a brainstorm cannot quietly override an approved message and an old performance snapshot cannot masquerade as current evidence.

    Workspace layerWhat belongs thereOperating rule
    DirectionGoal, audience, intended outcome, scope, and non-goalsThe team approves changes deliberately.
    GuardrailsBrand rules, approved claims, legal or privacy requirements, budget limits, and channel constraintsThe AI must not infer or rewrite these as facts.
    EvidenceResearch, analytics snapshots, search or visibility findings, customer observations, and competitive inputsEach item needs a source, scope, owner, and relevant date or period.
    Committed workApproved actions, owners, dependencies, status, and approval gatesA recommendation does not become work until a person accepts it.
    Decision historyWhat was approved, deferred, or rejected, with the reasonPreserve the decision and its rationale, not every abandoned draft.
    ConversationsChats used to analyze evidence, develop options, or prepare deliverablesClose each material chat with a summary that updates the appropriate layer.

    This operating model appears in Profound’s redesigned Projects feature, which brings a common goal, shared context, and related chats into the workspace for an initiative. The important design choice is not the label “Project.” It is making the project state legible to both the team and the AI.

    Give every project a compact header that answers the questions someone would otherwise ask in a handoff:

    • Objective: What specific change is this initiative meant to produce?
    • Definition of done: What evidence will the team accept as completion or progress?
    • Audience and market: Who is in scope, and where?
    • Current state: What has already happened, and what problem remains unresolved?
    • Constraints: Which claims, resources, channels, deadlines, or approval requirements limit the options?
    • Ownership: Who owns the outcome, and who must approve consequential changes?
    • Canonical assets: Which briefs, pages, dashboards, schemas, query sets, and reports are authoritative?
    • Non-goals: Which tempting adjacent problems are explicitly outside this project?

    Make the objective narrow enough to guide a decision. “Improve AI visibility” is a theme, not an operating goal. A usable objective identifies the product or entity, audience, market, surface being investigated, and evidence that will show whether the work moved in the intended direction. If you do not have a reliable metric, say what evidence the team will inspect instead of inventing precision.

    Make project context usable, current, and safe

    A hand updates an organized context library with current cards, an archive tray, and a locked compartment for sensitive material.

    More context is not automatically better context. Uploading every deck, transcript, export, and draft can create a larger retrieval problem: the AI has more material but less certainty about which material governs the answer.

    Create a clear hierarchy of truth. An approved positioning statement should outrank an exploratory chat. A current campaign report should outrank an older snapshot for current-state questions. A documented compliance restriction should outrank a generated suggestion. Put that hierarchy in the workspace instead of expecting the model to infer it.

    • Mark canonical material as approved. Use labels such as approved, draft, historical, superseded, and unverified.
    • Date changing evidence. Include the reporting period or observation window, not merely the upload date.
    • Separate facts from assumptions. A competitor’s visible page is evidence; your explanation for its performance is an interpretation until verified.
    • Record scope. Name the relevant market, language, channel, product, audience, and campaign where those distinctions matter.
    • Resolve contradictions. Do not leave two competing briefs in the workspace and hope the AI chooses correctly.
    • Assign an owner to important context. Someone must be responsible for confirming that it is still authoritative.
    • Minimize sensitive material. Add only the customer, employee, client, or commercial information needed for the project, and apply your organization’s access and retention requirements.

    Give the AI an explicit working contract at the start of important chats: use approved project context as authority; distinguish documented facts from assumptions; point to the evidence behind each recommendation; identify missing or conflicting inputs; and ask for approval rather than silently changing the plan.

    This contract matters most when the project moves quickly. Performance evidence may change while brand rules, audience definitions, or approved claims remain stable. Keeping stable context separate from changing context lets the team update what changed without rebuilding the entire brief.

    Convert AI recommendations into accountable work

    Two marketers review AI suggestion tiles and move approved ideas through owner, approval, deadline, and completion stages.

    Proactive recommendations can reduce the effort required to find the next useful question. In Profound, Aim analyzes data held in the platform to surface possible next work. The broader workflow lesson is that a suggestion should enter a decision queue, not skip directly into the task list.

    Require every consequential recommendation to arrive as a small decision packet:

    • Observation: What changed, appeared, disappeared, or remains unresolved?
    • Evidence: Which project data supports that observation?
    • Interpretation: What might the evidence mean, and what uncertainty remains?
    • Proposed action: What exactly would the team change, create, investigate, or stop?
    • Expected signal: What observable result would make the action look useful?
    • Dependencies and risk: What access, approval, resource, or prior work is required?
    • Decision: Was the proposal accepted, deferred, rejected, or sent for more investigation?
    • Ownership: Who is responsible once the proposal becomes committed work?

    Then process it consistently:

    1. Check that the recommendation serves the project’s current objective rather than an adjacent opportunity.
    2. Open the supporting evidence and confirm that its date, scope, and source fit the claim.
    3. Separate the observed condition from the AI’s explanation for it.
    4. Compare the likely value with effort, dependencies, risk, and work already committed.
    5. Accept, defer, reject, or request more evidence, and record the reason.
    6. Create an assigned task only after the required human approval.
    7. Return the result to the workspace so later recommendations can use what the team learned.

    A confidence label cannot replace this process. A plausible recommendation may rely on incomplete evidence, conflict with a constraint, or solve a problem outside the project’s scope. If the workspace cannot show what supports a suggestion, classify it as something to investigate rather than something to execute.

    Choose one authoritative home for task status. If your project management system already owns assignments, due points, and capacity, let the AI workspace prepare approved actions for that system instead of maintaining a competing status list. Otherwise, the team will spend its time reconciling two versions of the plan.

    Preserve decisions without preserving every conversation

    Chats are useful working material, but a transcript is a poor project state. It mixes questions, false starts, generated alternatives, corrections, and final choices. A teammate should not have to reread the entire exchange to learn what the team decided.

    Close every material chat with a short record containing:

    • The question the conversation was meant to resolve.
    • The project inputs and evidence actually used.
    • The conclusion, including unresolved uncertainty.
    • The decision made by the responsible person.
    • The approved next action and owner, if any.
    • Any project context that must now be added, corrected, or marked as superseded.

    Move durable information out of the chat and into the correct workspace layer. Approved messaging belongs with guardrails. A newly identified performance condition belongs with evidence. A chosen action belongs with committed work. The reason for rejecting an option belongs in decision history.

    Do not treat every generated answer as reusable organizational knowledge. A conclusion may be valid only for one product, market, time period, dataset, or campaign. Review its scope before promoting it into a global brand or marketing knowledge base.

    This creates a clean division of labor. Chats support exploration. The project record carries approved state. Your task system carries execution. Each has a purpose, and none has to impersonate the others.

    Test the workspace on a real decision, not a polished demo

    A convincing demonstration can show fluent answers without revealing whether the workspace will survive conflicting context, changing data, approval requirements, and team handoffs. Evaluate it with one active initiative that has a genuine decision pending.

    1. Create the project header and load only the approved context needed for the decision.
    2. Add a small set of current evidence with dates, scope, sources, and owners.
    3. Ask the AI to identify missing context before it recommends action.
    4. Request possible next actions and inspect the evidence attached to each one.
    5. Process one recommendation through review, approval, assignment, and completion.
    6. Record the result and ask the AI how that new evidence changes its remaining recommendations.
    7. Ask a teammate who missed the earlier work to find the objective, current state, open decision, and reason behind the approved action.

    During that test, answer practical questions the demo may not cover:

    • Can people distinguish approved facts from drafts and generated claims?
    • Can the AI identify the evidence used for a recommendation and flag evidence it lacks?
    • Can a person accept, edit, defer, or reject a suggestion without losing the rationale?
    • Can access be limited appropriately for agencies, clients, regions, or internal teams?
    • Can you export the goal, context, decisions, chats, and action history in a usable form?
    • Can the workspace coexist with your existing task, analytics, content, and approval systems without creating duplicate records?
    • Does an updated canonical brief clearly supersede an older instruction?

    Watch for operational red flags. If people keep pasting the same brief into every chat, the workspace may not be retrieving context reliably or the team may not trust what it retrieves. If recommendations become tasks before review, governance is missing. If context has no dates or owners, it will decay invisibly. If the final decision remains buried in a transcript, the handoff problem is still unsolved.

    Key takeaways

    • An AI-assisted workspace is a shared operating record, not merely a collection of chats and files.
    • Keep direction, guardrails, evidence, committed work, decisions, and conversations in distinct layers.
    • Label context by approval state, scope, date, and owner so people and AI can tell what governs the project.
    • Treat AI recommendations as proposals that require evidence, prioritization, approval, and ownership.
    • Move durable conclusions out of chat transcripts and into the canonical project record.
    • Evaluate a workspace by following one real decision from evidence to result and handoff.

    Start with one initiative, such as an AI visibility audit, schema rollout, content program, or campaign launch. Build its project header, load the minimum trustworthy context, review one AI-proposed action, and preserve the resulting decision. If the workspace makes that chain easier to inspect, approve, and hand off, expand it. If it only produces longer chats, fix the operating design before moving more work into it.

    References


  • Dynamic Rendering for AI Bots: A Practical Deployment Guide

    Dynamic Rendering for AI Bots: A Practical Deployment Guide

    Your page looks complete in a browser, but an AI crawler may receive little more than navigation, placeholders, and script tags. If the information that answers a visitor’s question appears only after JavaScript runs, your content can be published, indexable in theory, and still difficult for a bot to retrieve.

    Dynamic rendering can close that delivery gap. It is useful when rendering is the actual problem, however – not as a general cure for weak content, blocked crawling, or poor site architecture. Here is how to decide whether you need it, deploy it without creating two conflicting versions of a page, and verify the response a bot really gets.

    Dynamic rendering fixes delivery, not content quality

    A JavaScript-heavy page can exist in two materially different states. The initial server response may contain an application shell, while the browser’s final document contains the article, product information, links, and structured data added after scripts run. Human visitors generally judge the final state. A crawler must first be able and willing to perform enough of that client-side work to reach it.

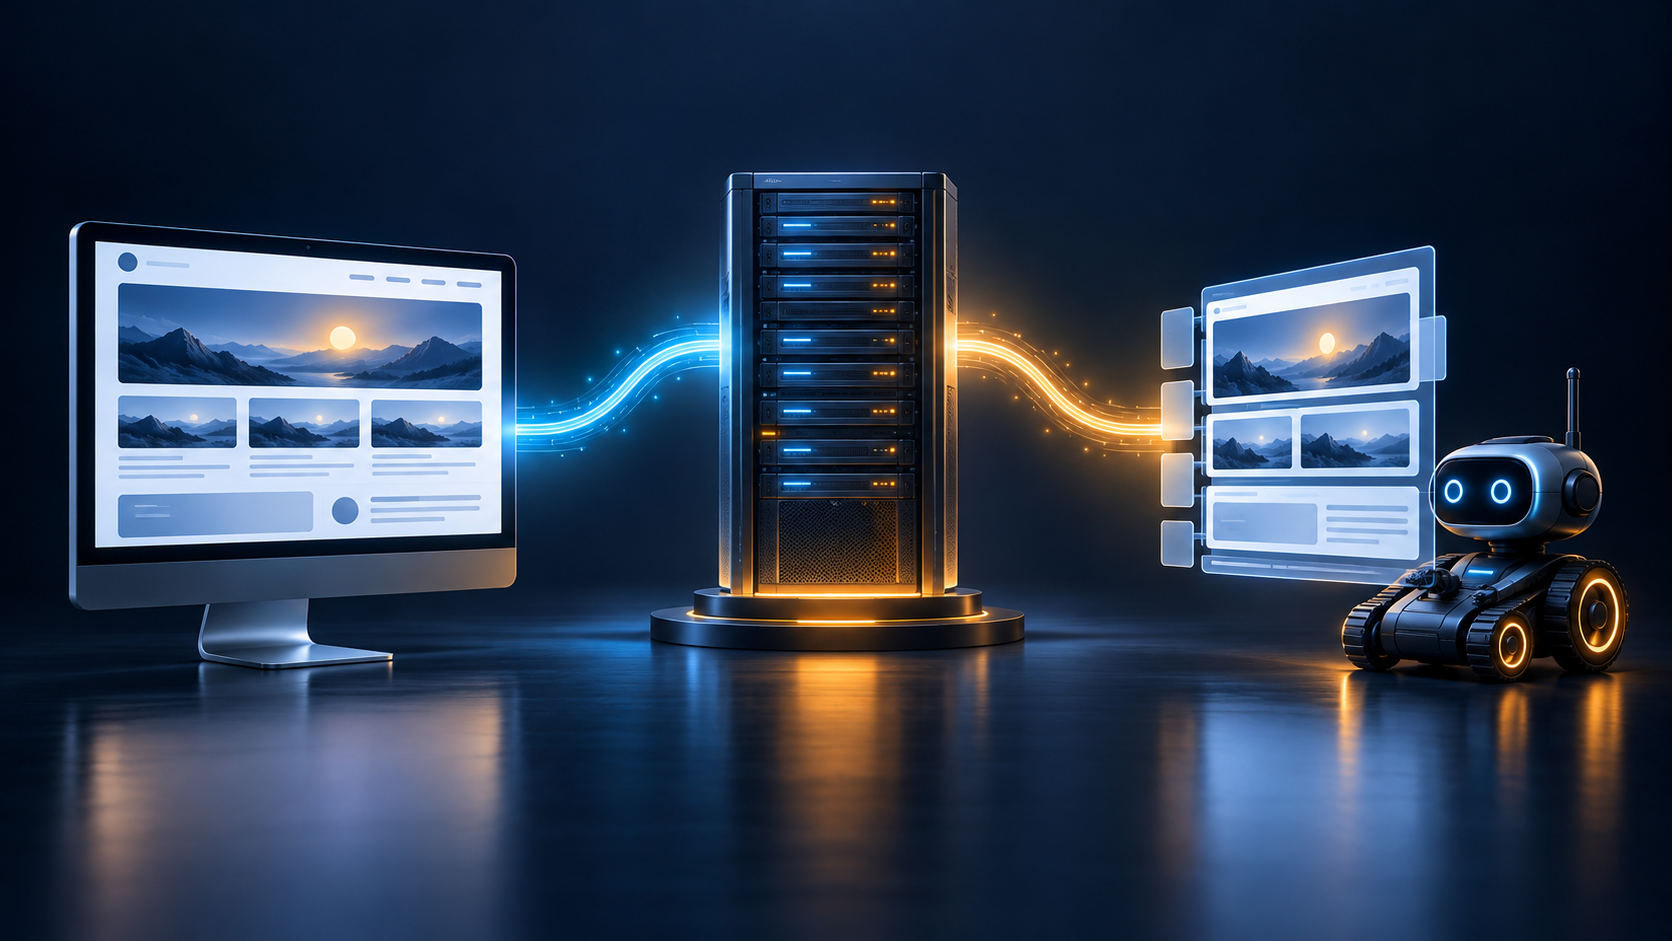
    Dynamic bot rendering inserts a delivery layer between the request and the page. It recognizes an AI-bot request and returns a fully rendered version while leaving the normal human experience unchanged. In a typical implementation, the renderer loads the page, allows its required content to resolve, and returns useful HTML rather than requiring the crawler to assemble the page itself.

    Think of this as a compatibility layer. It can make existing information easier for a crawler to retrieve, but it cannot make that information accurate, distinctive, or worthy of citation. It also cannot compensate for a request that never reaches the renderer.

    • If a crawler is denied by access controls, fix the access decision first.
    • If the page is hidden behind authentication, rendering must not be used to expose it publicly.
    • If the answer is thin, ambiguous, outdated, or contradicted elsewhere on the site, improve the answer itself.
    • If important pages have no crawlable internal links, repair discovery and navigation.
    • If the raw response already contains the complete page, another rendering layer may add complexity without solving a real problem.

    Dynamic rendering is therefore a technical optimization for a specific failure mode: the public page contains useful information, but the response available to a bot does not reliably carry that information.

    Confirm the rendering gap before you deploy anything

    A developer workstation displays a sparse crawler response beside a fully rendered version of the same webpage.

    Do not diagnose the page by looking only at it in a normal browser. The browser’s developer tools usually show the document after scripts have modified it. You also need to inspect the original response body – the HTML returned before client-side rendering – because that is the safer baseline for crawler accessibility.

    Run the diagnosis across representative templates, not just the homepage. An article, category page, product page, comparison page, and documentation page can use different rendering paths even when they share the same design system.

    1. Choose a small set of public URLs that represent your highest-value templates and common edge cases.
    2. Open each page normally and record the primary answer, headings, factual details, internal links, title, canonical URL, robots directives, and structured data present after the page finishes loading.
    3. Inspect the original response or fetch the URL with a simple HTTP client that does not execute JavaScript.
    4. Compare meaning, not appearance. The raw HTML does not need the browser’s styling or interactive behavior, but it should contain the substantive information a crawler needs.
    5. Check whether the request is redirected, challenged, denied, rate-limited, or served an error. Those are access and reliability problems, not rendering problems.
    6. Repeat the check on pages with different publication states, content lengths, and data dependencies so that one unusually simple URL does not produce a false sense of coverage.
    What you observeLikely diagnosisBest next move
    The original HTML contains the main answer, links, metadata, and relevant structured data.No material rendering gap on that template.Do not add bot rendering solely because the site uses JavaScript. Investigate content, discovery, or access issues instead.
    The complete content appears in the browser but is absent from the original HTML.Client-side rendering is carrying essential information.Evaluate server rendering, build-time generation, or dynamic bot rendering.
    The request receives a denial, challenge, redirect loop, or error.The crawler cannot reliably reach the page.Correct the firewall, routing, crawl-control, or reliability problem before changing rendering.
    The HTML is complete, but important pages are difficult to reach through ordinary links.Discovery and site architecture are the constraint.Add crawlable internal links and clarify the relationship among pages.
    The public page changes by login, session, or customer account.There is a privacy and response-segmentation risk.Define a safe public representation. Never render authenticated or customer-specific data into a bot response.

    If the raw HTML is incomplete, consider whether the site can provide the same complete server-rendered response to everyone. A universal server-rendered or statically generated baseline is usually easier to reason about because it removes bot classification and response variance. Dynamic rendering is most defensible when replacing the front-end rendering model is impractical, the human experience must remain unchanged, and the missing-content problem is concentrated in requests from known crawlers.

    Build one semantic page, even when you serve two response forms

    One structured source document passes through browser-side and server-side rendering paths to produce two matching page layouts.

    The human and bot responses do not need identical markup. They do need to make the same substantive claims. Dynamic rendering becomes fragile when it evolves into a separate editorial surface with its own copy, offers, facts, or navigation.

    Set a parity contract before implementation. For any canonical URL, the two response paths should agree on:

    • The primary topic, answer, factual claims, qualifications, and visible supporting information.
    • The page title, canonical URL, language, and crawl directives.
    • The destination and meaning of important internal links.
    • The availability state of products, services, downloads, or other resources.
    • The structured data entities and properties, which should describe information a visitor can also find on the page.
    • The publication or update state of the content.
    • The intended HTTP outcome, including equivalent redirects and not-found behavior.

    Do not require byte-for-byte equality. A bot response may omit decorative animation, interactive controls, personalization, analytics code, or browser-only application state. The useful test is semantic parity: would a person reading either version reach the same factual understanding of the page?

    Keep bot detection narrow and auditable

    An AI bot is not a single technical client. Different crawlers can identify themselves differently and can change their request behavior. Treat detection rules as maintained configuration, not as a one-time switch.

    • Start with crawler identities you deliberately intend to support.
    • Document what sends a request down the rendered path and who owns updates to that logic.
    • Log the classification decision so that you can explain why a particular response was served.
    • Do not classify every unfamiliar client as an AI bot. Overbroad matching can create unexpected cache, security, and debugging behavior.
    • Keep access policy separate from rendering policy. Permission to crawl and the format of the response are related decisions, but they are not the same decision.

    Design the cache around response variants

    Caching is where a sound rendering design can fail operationally. If an edge cache does not distinguish the applicable response paths, a human may receive the bot snapshot or a crawler may receive the JavaScript shell. The renderer can also serve stale facts if its cache remains valid after the underlying page changes.

    • Make the response variant part of the cache decision wherever the rendered and normal outputs differ.
    • Use the same canonical URL rather than creating a separate public bot URL.
    • Connect cache invalidation to the events that publish, update, unpublish, or materially change a page.
    • Never cache authenticated, session-specific, or customer-specific output as a public bot response.
    • Define a safe fallback for rendering failures and record when it is used. A silent fallback to an empty application shell can make the system appear healthy while the original problem returns.

    Roll out by template, not across the entire domain at once

    A staged release makes content differences and infrastructure mistakes easier to isolate. Choose one valuable template with a confirmed rendering gap, then expand only after its ordinary and rendered responses remain aligned through real content updates.

    1. Save baseline responses for both the normal route and the proposed bot route.
    2. Enable rendering for a controlled group of URLs from one template.
    3. Verify content parity, status behavior, metadata, structured data, internal links, freshness, and the absence of private data.
    4. Publish and edit pages in that group to confirm that rendered responses update with the source content.
    5. Inspect logs for misclassification, rendering failures, redirect problems, and unexpected fallback use.
    6. Expand to the next template only after the first one remains stable under normal editorial changes.

    This sequence also tells you whether dynamic rendering is becoming an unmanageable second publishing system. If every template needs separate copy rules and manual exceptions, the site may be better served by changing its underlying rendering architecture.

    Test the bot response and measure the problem you meant to solve

    A successful render is not merely a request that returns a page. It is a request that returns the correct public page, with the required information, at the expected URL, while remaining current and operationally reliable.

    Use your rendering system’s preview or a controlled request that matches a configured crawler identity. Then inspect the returned body without allowing another round of client-side rendering to hide omissions. For each representative URL, verify:

    • The main answer and its necessary context are present in the returned HTML.
    • Headings, lists, tables, definitions, product facts, and other meaningful page elements are represented as text rather than empty placeholders.
    • Important internal links use ordinary destinations that can be extracted from the response.
    • The title, canonical URL, robots directives, and structured data correspond to the human page.
    • Redirected, removed, and unavailable pages retain their intended status behavior.
    • Newly published or edited information appears after the expected cache update.
    • No account data, session information, unpublished material, or administrative content is present.
    • The response remains understandable without executing additional JavaScript.

    Automate the stable parts of this check. A regression test can request both variants and assert that required content fields, canonical values, directives, links, and structured data entities exist in each. Do not reduce parity to a complete HTML diff; implementation markup can legitimately differ and generate noise. Test the content and signals that must remain equivalent.

    Measure delivery before visibility. Rendering logs should tell you which eligible requests used the rendered route, whether the render completed, whether a cached or fallback response was served, and which URLs repeatedly failed. Content checks should tell you whether required information was present and fresh. These are direct indicators that the implementation is doing its job.

    AI visibility is a downstream outcome with more variables. Monitor crawl activity, discoverability, attributable referrals where available, and inclusion in the AI experiences important to your audience, but do not treat every later citation or ranking change as proof that rendering caused it. Content quality, authority, relevance, internal discovery, access rules, and the external system’s own behavior remain part of the result.

    Key takeaways

    • Use dynamic rendering only after confirming that essential public content is present in the browser but missing from the original HTML response.
    • Fix denials, authentication barriers, broken routing, weak internal links, and poor content at their own layer; rendering does not solve them.
    • Keep human and bot responses semantically equivalent, including factual claims, metadata, canonical signals, links, structured data, and content freshness.
    • Separate cache variants carefully and never expose authenticated or personalized information through the bot-rendered path.
    • Release one template at a time, automate parity checks, and judge the implementation first by complete, current, reliable delivery.

    Start with one representative URL today. Compare its original response with the completed browser page and name the missing information precisely. If the gap is real, you now have a testable requirement for dynamic rendering. If it is not, you have avoided adding infrastructure that would have addressed the wrong problem.

    References


  • Google Ad Creative and Targeting Updates: An Action Plan

    Google Ad Creative and Targeting Updates: An Action Plan

    If your Demand Gen video was approved down to the last line break, you now have a new reason to inspect the campaign settings: Google may place additional text over that finished creative. If your team manages Display & Video 360 through bulk files, you also have a new schema to accommodate before older workflows reach a hard support deadline.

    These changes affect different products, but they create the same operational problem. The ad that gets served or the audience that gets targeted may no longer be defined only by the asset and configuration your team originally approved. You need an audit trail that covers Google’s transformations as well as your own inputs.

    Know which control surface changed

    There are two separate updates to manage. In Google Ads, Demand Gen campaigns can use existing text assets to generate messages that appear over video. In Display & Video 360, Structured Data Files v11 expand bulk targeting controls and change parts of the file structure used by automated workflows.

    Control layerWhat changedMain riskFirst action
    Demand Gen creativeAutomatic text overlays can be generated from existing text assets.Added copy can obscure the composition, repeat burned-in text, or conflict with the approved message.Inspect the Overlay on videos setting and the text assets available to the campaign.
    DV360 audience targetingSDF v11 supports lookalike audience inclusion and exclusion across eligible ad groups.A blanket bulk-edit rule can apply the wrong audience logic or mishandle an exception.Add explicit inclusion, exclusion, and exception checks to the SDF workflow.
    DV360 location targetingBusiness Chain proximity targeting is available in the line item file format.A bulk upload can extend location targeting to unintended line items.Validate the business-chain configuration at line-item level before scaling it.
    DV360 file automationVendor fields and selected YouTube campaign structures have changed.Existing templates, parsers, and round-trip assumptions can fail or silently omit information.Diff a clean v11 file against the production schema and test a limited batch.

    Keep ownership clear. Creative teams should decide whether a video can tolerate generated copy. Media teams should control the campaign setting. Marketing operations or engineering should own the SDF schema migration. One person should reconcile those decisions before launch; otherwise each team can complete its own task correctly while the final campaign is still wrong.

    Audit Demand Gen overlays before the next launch

    A reviewer inspects a vertical video preview partly covered by blank translucent interface overlays before launch.

    The Overlay on videos control sits under Asset optimization with Shorter videos and Resized videos. It has been observed as enabled by default, so silence is a decision: if nobody checks the setting, Google may add text to a video that your team considered complete.

    Run a campaign-by-campaign creative check

    1. Open each Demand Gen campaign and record the current state of Overlay on videos, Shorter videos, and Resized videos. Do not treat the account-level expectation as proof of the campaign-level state.
    2. Review the beginning, middle, and end of every video. Mark areas occupied by burned-in copy, product details, logos, calls to action, prices, and required disclosures.
    3. Review the existing text assets Google can use as overlay inputs. Remove or revise stale promotions, weak generic claims, mismatched calls to action, and language that does not belong in the campaign’s market.
    4. Decide whether the video is suitable for an overlay test, requires a redesigned overlay-safe version, or should remain unchanged.
    5. Record the decision with the campaign identifier, approver, setting state, date, and reason. This turns an invisible optimization toggle into an accountable creative choice.

    A video with open visual space, little burned-in copy, and tightly governed text assets may be a reasonable candidate for a controlled overlay test. A dense product demonstration, carefully typeset brand film, localized creative, or video with disclosures is a poor candidate for unattended text placement. The relevant question is not whether overlays are useful in general. It is whether this particular composition and message can accept another layer without changing their meaning.

    Do not confuse a generated overlay with closed captioning. The overlay draws from advertising text assets and can reinforce a benefit, promotion, or call to action; it does not necessarily reproduce the spoken content. If the video must be understandable without sound, assess captions and visual storytelling separately.

    Use the narrowest control that matches your decision

    You can turn off Overlay on videos by itself or use Disable all for the available video optimization features. Use the individual switch when your video can tolerate shortening or resizing but not added copy. Use Disable all only when the approved composition must not be altered by any of the listed optimizations.

    Review the three settings independently. Turning off the overlay does not express a decision about shorter or resized versions. Equally, accepting alternate dimensions does not mean text can safely cover any part of the frame. Your approval record should state which transformations are allowed rather than reducing the decision to a vague yes or no on automation.

    Account for the AI-edit label

    When these optimization features modify an image or video, the served ad is labeled as created or edited with AI in the European Union, India, and New York state. That does not determine whether the creative is acceptable for your brand, but it does belong in the approval process. Tell brand, legal, and market owners which assets can be transformed and where the label may appear before they sign off.

    Make SDF v11 a controlled migration, not a file swap

    Two specialists guide blank spreadsheet-like grids through validation checkpoints during a staged file-schema migration.

    Display & Video 360 users can now download and upload SDF v11 directly in the platform. For a team that edits files manually, this is a template change. For a team that generates, validates, or ingests SDFs with code, it is a schema migration with targeting consequences.

    The audience change needs an explicit exception. V11 supports lookalike inclusion and exclusion across ad groups except those under YouTube Ad Sequence line items. A bulk updater should identify those sequence line items before it writes audience fields. Do not treat a rejected or missing value as an unexplained upload anomaly when the campaign type itself is excluded.

    Location logic also moves further into bulk management. Business Chain proximity targeting is now available in the line item format. That makes repeated setup easier, but it also increases the reach of a bad mapping. Confirm the intended business chain and destination line items in the generated output, then begin with the smallest reversible batch that can prove the rule works.

    Use this v11 migration sequence

    1. Inventory every workflow that reads, creates, validates, transforms, or archives an SDF. Include spreadsheets, scripts, data pipelines, naming rules, and reporting jobs.
    2. Record the SDF version each workflow expects. Do not assume the version selected for export is also the version understood by an internal parser.
    3. Download a clean v11 file and compare its headers, accepted values, and restrictions with your production template. Treat column names and structures as a contract; do not reconstruct unfamiliar fields from memory.
    4. Update the audience mapping to handle lookalike inclusion and exclusion separately. Add a deliberate branch for YouTube Ad Sequence line items.
    5. Update line-item logic for Business Chain proximity targeting only if the organization intends to use it. A new available field does not need to become a new default.
    6. Inspect the four updated third-party YouTube vendor columns. They now incorporate reporting IDs and allow multiple vendor assignments, while separate reporting ID columns have been removed. Any script that expects those separate columns needs revision.
    7. Test a limited upload and reconcile the accepted campaign structure against the intended file. Check line-item and ad-group counts, audience inclusions, audience exclusions, location settings, and vendor assignments.
    8. Retain the last accepted file and a change log so the team can reconstruct the previous configuration if the upload produces an unintended change.

    YouTube Instant Deals need a separate path. V11 includes columns and restrictions for their line items, ad groups, and ads, but Instant Deals remain in beta for allowlisted partners. They do not appear in downloaded SDFs and can only be uploaded through the dedicated creation workflow. A system that treats an export as a complete round-trip representation of the account will therefore have a known gap. Document that exception instead of letting the next export overwrite the team’s understanding of what exists.

    There is also a firm planning horizon. SDF versions earlier than v10 are deprecated and will stop being supported in January 2027. At minimum, remove every pre-v10 dependency before that point. Moving directly to v11 gives you time to test the current fields and restrictions without turning a support cutoff into an emergency migration.

    Test creative and targeting changes without confounding them

    An overlay changes what a person sees. A lookalike inclusion, exclusion, or proximity rule changes who can see it. If you change both at once and results move, you will not know whether the message or the audience caused the difference.

    1. Choose one question. For example: does an overlay-safe video with generated messaging improve the campaign’s business outcome, or does a particular lookalike configuration improve audience quality?
    2. Define the primary metric before launch. Click-through rate can describe response to an ad, but it should not replace conversion rate, cost per qualified lead, acquisition cost, or another outcome that reflects the campaign’s actual purpose.
    3. Keep the other major inputs as stable as the account allows. Budget, bid strategy, offer, landing page, audience definition, and creative can all obscure the effect you are trying to measure.
    4. Log the exact configuration: overlay state, shorter-video state, resized-video state, SDF version, audience inclusions and exclusions, and proximity targeting.
    5. Inspect the output as well as the metric. A performance lift does not make obscured product details, duplicated copy, an outdated promotion, or an unintended audience exclusion acceptable.
    6. Set rollback conditions from your own baseline before the change. There is no universal performance threshold that fits every account, but brand obstruction, incorrect claims, lost exclusions, or spend directed to unintended locations should trigger immediate correction.

    For overlays, your evidence should include a visual QA record and the downstream business metric. For SDF targeting, reconcile the uploaded configuration first, then evaluate reach, spend, and conversion quality for the affected audience or location. A clean measurement window cannot rescue an incorrectly configured campaign.

    Keep the change log readable by someone outside the activation team. A useful entry includes the campaign, line item, or ad group identifier; the old and new value; who approved it; the hypothesis; the measurement period; and the rollback condition. This is especially important when a platform-generated creative treatment and a bulk-generated targeting rule can both influence the same result.

    Key takeaways

    • Demand Gen can generate video overlays from existing text assets, and the setting has appeared enabled by default. Audit it rather than assuming the approved master is the served creative.
    • Overlay on videos, Shorter videos, and Resized videos are separate asset-optimization decisions. Disable only the transformations your creative cannot safely accept.
    • Modified image or video assets receive an AI creation or editing label when served in the European Union, India, and New York state, so include that behavior in market and brand approvals.
    • SDF v11 adds lookalike inclusion and exclusion for eligible ad groups plus Business Chain proximity targeting at line-item level. YouTube Ad Sequence line items are the stated lookalike exception.
    • The v11 vendor-column changes and Instant Deal workflow can break assumptions in automated imports and exports. Test the schema and document incomplete round-trip cases.
    • Support for SDF versions earlier than v10 ends in January 2027. Migrate while you still have room to validate small batches and correct the workflow safely.

    Start with two inventories: every Demand Gen campaign whose video can be altered, and every workflow that touches an SDF. Assign an owner to each, record the current state, and make one controlled change at a time. That is how you gain the reach of automation without surrendering control of the message, audience, or spend.

    References


  • How to Turn Executive AI Anxiety Into a Working Plan

    How to Turn Executive AI Anxiety Into a Working Plan

    When an executive asks for a GEO dashboard, a ChatGPT tracker, or an AI content workflow, the requested tool is often not the real decision. The immediate concern is whether someone competent has AI covered, competitors are moving while your team debates definitions, or leadership will later discover that the company ignored an important shift.

    If you lead SEO, content, analytics, PR, product, or digital strategy, your job is neither to manufacture certainty nor dismiss imperfect tools. It is to turn the company’s attention into a disciplined operating plan. That means giving leaders a clear answer, assigning decision rights, running bounded experiments, and reporting progress without pretending that an AI visibility metric is revenue.

    Answer the question underneath the AI question

    Technical teams tend to hear a technical request. When a leader asks whether you track ChatGPT or have a GEO strategy, it is natural to explain unstable outputs, weak attribution, prompt-tracking limitations, and the lack of a universal measurement standard.

    Those caveats may be correct, but they can leave the underlying concern unanswered. Starting with a technical objection can sound like the organization has chosen resistance instead of coverage. The executive still does not know who owns the issue, whether it has been investigated, or how the company will recognize a meaningful change.

    A useful answer gives leadership four things:

    1. Coverage: Name the person accountable for maintaining the company’s view of AI adoption.
    2. Evidence: State what the team examined and which conclusions the evidence can and cannot support.
    3. A decision: Explain what the company will do, defer, reject, or test because of that evidence.
    4. A review trigger: Identify the new signal, business need, or improvement in measurement that would justify revisiting the decision.

    Use a response pattern such as: Yes, we assessed this. The evidence is useful for this purpose, but not reliable enough for that claim. We are taking this action, avoiding this unsupported conclusion, and will reassess when this condition changes.

    Consider prompt tracking. A defensive answer says the data is inconsistent and therefore useless. A disciplined answer says you evaluated it, found that it can provide directional observations about brand mentions, citations, and model descriptions, and will not present it as a stable share-of-market or revenue measure. That preserves the limitation without leaving the impression that nobody is paying attention.

    This is not automatic approval. Saying yes to an investigation is different from approving a purchase, accepting a vendor’s interpretation, or rolling a tactic across the organization. When you eventually recommend against an initiative, the decision will sound like informed judgment because leadership has already seen your evaluation process.

    Replace AI activity reports with decision briefs

    An analyst presents two clear abstract options to executives while cluttered screens and documents fade into the background.

    Executive anxiety makes visible activity tempting. A large prompt inventory, a new dashboard, more monitored answer engines, and an AI content workflow all demonstrate motion. They do not necessarily demonstrate progress. In an uncertain category, a dashboard can become reassurance presented as analysis.

    Replace the activity report with an AI decision brief. It should answer:

    1. What business question are we trying to answer? Examples include protecting brand representation, discovering emerging demand, improving content operations, or evaluating a customer-facing AI experience.
    2. What did the evidence cause us to decide? A finding matters when it changes a priority, investment, workflow, risk response, or test.
    3. How will we judge the decision? Name the output signal, operating result, or business outcome you expect to observe.
    4. What requires executive involvement? Surface budget, risk tolerance, ownership conflicts, and strategic trade-offs. Keep routine diagnostic detail below the executive level.

    Organize measurement into three layers so nobody mistakes one for another:

    • Model-output signals: Brand mentions, citations, sentiment, inclusion in responses, and the way a system characterizes the company. These can expose visibility or representation issues.
    • Operating signals: Whether the team resolved an identified problem, improved a workflow, completed an experiment, or produced evidence strong enough to make a decision.
    • Business outcomes: Qualified demand, customer behavior, conversion, retention, cost, or another result the company already values.

    The first layer is not a substitute for the third. A citation may matter, but mentions, visibility, sentiment, and citations do not automatically become business impact. Keep them when they help diagnose a problem or guide an action. Do not quietly relabel them as growth.

    Apply a simple decision test to every executive metric:

    • What decision could change if this metric moves?
    • Who is responsible for responding?
    • What limitation must accompany the number?
    • What result would cause us to continue, change, or stop the work?

    If nobody can answer those questions, the metric may still belong in a diagnostic workspace. It does not belong on the executive scorecard.

    Give one leader accountability without creating an AI land grab

    AI attracts attention, attention attracts budget, and budget can trigger ownership battles. SEO claims GEO. PR claims citations and brand mentions. Content claims AI optimization. Product claims the AI experience. Analytics claims measurement. Vendors may reinforce whichever ownership story helps sell their platform. The result is often territory protection disguised as transformation.

    Choose one accountable program lead, but do not force every AI responsibility into that person’s department. The lead owns the portfolio: the decision brief, shared priorities, evidence standards, unresolved conflicts, and executive update. Individual workstreams remain with the function best placed to act.

    A practical division of responsibility looks like this:

    • Executive sponsor: Sets the business priority, approves material investment, and resolves conflicts that cross functions.
    • AI program lead: Maintains the portfolio, records decisions, challenges unsupported claims, and makes sure experiments answer business questions.
    • SEO and search teams: Investigate search behavior, answer-engine visibility, discoverability, and the content issues within their control.
    • Content and editorial teams: Own accuracy, evidence, clarity, publishing standards, and the workflow used to create or update material.
    • PR and brand teams: Handle public positioning, reputation concerns, brand representation, and external narratives.
    • Product and technology teams: Own customer-facing AI experiences, implementation choices, data access, reliability, and technical risk.
    • Analytics teams: Design measurement, document uncertainty, and test whether observed signals connect to business outcomes. They should not be expected to invent the strategy merely because they run the dashboard.

    Then define decision rights in writing. Specify who may approve a vendor, start a pilot, change an editorial workflow, publish an AI-generated asset, accept measurement limitations, or make an external performance claim. Without those boundaries, cross-functional collaboration becomes a meeting schedule rather than an operating model.

    Ownership should follow the business problem, not the newest acronym. If the problem is inaccurate brand representation in generated answers, brand, PR, content, and SEO may all contribute while one named workstream owner remains accountable. If the company is building an AI feature for customers, product should not lose accountability simply because the initiative affects search visibility.

    Run bounded experiments that end in a decision

    A team observes a small controlled prototype inside a transparent enclosure as a leader considers three abstract outcome gates.

    An AI initiative is not an experiment merely because its result is uncertain. It becomes an experiment when the scope is controlled, the evidence is reviewed honestly, and the outcome leads to a defined decision.

    Give every experiment a short written card containing:

    • Decision: The choice the experiment is meant to inform.
    • Hypothesis: The expected change and the proposed mechanism behind it.
    • Scope: The pages, prompts, workflows, audience, product surface, or business process included.
    • Baseline: What was observable before the intervention, including known instability in the measurement.
    • Signals: The model-output, operating, and business measures you will inspect.
    • Guardrails: Accuracy, brand, security, legal, customer, or workflow conditions that cannot be traded away for a favorable metric.
    • Next actions: What evidence would justify extending, changing, pausing, or ending the work.
    • Ownership: The person who will make the recommendation and the condition that triggers review.

    For an AI visibility test, the decision might be whether to extend a set of content changes beyond selected high-value pages. The hypothesis could be that clearer entity descriptions and stronger supporting evidence will improve how relevant answer engines describe and cite the brand. The team can inspect output accuracy, brand characterization, citation behavior, and identifiable downstream activity without claiming that a noisy change proves causation.

    For a vendor evaluation, decide in advance what the platform must help you do. Can the team inspect or export the underlying observations? Are the limitations visible? Can analysts reproduce enough of the output to understand it? Does the information change a decision? A polished interface is not a successful pilot if the only resulting action is to keep paying for the interface.

    Write stop conditions before enthusiasm, sunk cost, or internal politics take over. End or redesign an experiment when the data cannot support the intended decision, the output remains too unstable for the proposed use, the team cannot act on what it learns, or the work no longer addresses a meaningful business priority. Measurement can evolve without every measurement project becoming permanent.

    Key takeaways for your next executive AI review

    • An executive asking about ChatGPT, GEO, or AI tracking may be asking whether the company has competent coverage, not requesting a technical lecture.
    • Lead with what you evaluated, what you learned, and what you decided. Put limitations after coverage has been established, not in place of an answer.
    • Keep model-output signals separate from operating results and business outcomes. Visibility is evidence to interpret, not revenue by another name.
    • Assign one accountable program lead while leaving workstream execution with the functions equipped to act.
    • Require every initiative to state the decision it supports, its evidence limits, its owner, and its stop condition.

    A credible executive update can use this template: AI adoption is covered by [owner]. The current business question is [question]. We reviewed [evidence]. It supports [decision], but not [larger unsupported claim]. [Workstream] is testing [action] and monitoring [signals and outcomes]. We need leadership to decide [choice], or no executive decision is required.

    Before your next leadership discussion, take the current list of AI tasks and write the intended decision next to each one. Remove anything from the executive scorecard that has no owner or decision path. Then publish the accountable lead and the decision brief. You do not need to prove that every AI bet will work. You need to show that the company can investigate, decide, and learn without mistaking panic for strategy.

    References


  • Google Meridian Marketing Measurement: A Practical Guide

    Google Meridian Marketing Measurement: A Practical Guide

    Your paid-search dashboard says the campaigns are profitable. Brand demand was also rising, several other channels were active, and the customers who clicked may have intended to buy before they saw an ad. The dashboard can report the click. It cannot tell you how much of the outcome the advertising actually created.

    Google Meridian is built for that measurement gap. It uses aggregated marketing and business data to estimate incremental contribution without reconstructing individual customer journeys. Used carefully, it can give you a better basis for budget decisions. Used with weak data or overconfident assumptions, it can simply replace a misleading attribution number with a more sophisticated one.

    Choose Meridian for incrementality, not user-path attribution

    Google Meridian is an open-source, Python-based, fully Bayesian marketing mix modeling framework. It was introduced in 2024 and made available to marketers and data scientists in early 2025. Its purpose is not to produce a more detailed conversion path. It estimates how changes in marketing activity relate to changes in an outcome such as revenue, leads, or store visits.

    That distinction matters most in paid search. Under last-click attribution, a keyword can receive all the credit when someone clicks an ad and then buys. The method records what happened immediately before the conversion, but it cannot establish whether the ad generated the demand, captured demand created elsewhere, or intercepted a customer who was already looking for the brand. Meridian is designed to estimate the incremental revenue associated with search advertising rather than assigning credit to the final click.

    Use Meridian when your decision concerns channel-level or campaign-group investment over time. Suitable questions include:

    • How much of the observed revenue or lead volume was likely incremental to paid media?
    • Does branded search still look efficient after accounting for underlying search interest?
    • How should channel allocation change under a plausible budget scenario?
    • How does an experiment change the model’s estimate of a channel’s contribution?

    Do not use Meridian to answer which ad caused one person’s purchase, which exact sequence of touchpoints every customer followed, or what a single keyword will deliver tomorrow. Those are different measurement problems. Meridian works with aggregate patterns, so its useful resolution is constrained by the time, geographic, media, and outcome data you supply.

    This also explains why Meridian should complement rather than erase your operational reporting. Click and conversion data can still help with campaign pacing, landing-page diagnosis, and day-to-day execution. The mistake is treating those records as proof of incremental business impact.

    Treat search demand as a control, not proof of ad impact

    Search has an unusually difficult causality problem because demand often precedes the advertisement. A customer hears about your company, decides to visit, searches the brand name, and clicks the sponsored result. Spend, clicks, and sales all rise together, but the paid ad may not have caused the original intent.

    Meridian addresses part of this problem by allowing Google Query Volume to enter the model as a control variable. Query volume represents search interest, not paid-media performance. Including it can help the model separate underlying organic demand from paid-search effects.

    For your implementation, keep three data concepts separate:

    • Marketing input: paid-search spend, impressions, or the media variable selected for the model.
    • Demand control: query volume aligned to the same geographic and weekly structure.
    • Business outcome: the revenue, lead, or store-visit measure the model is supposed to explain.

    Do not substitute clicks for query volume and call the search-intent problem solved. Clicks are produced by the advertising system and sit inside the mechanism you are trying to measure. A demand control needs to represent the broader interest that may have existed without the paid click.

    Geographic variation provides another useful signal. Meridian’s hierarchical approach can model differences in spend and performance across regional or local markets. If one region’s media changes differently from another’s while you observe their outcomes, the model has more information with which to estimate incremental impact. If every region receives the same proportional budget change in the same week, geography adds far less identifying variation.

    Before modeling, plot spend, query volume, and the outcome by region. Look for markets that move in lockstep, regions with long missing periods, and abrupt jumps caused by reporting changes rather than customer behavior. You are not trying to find a pleasing correlation. You are checking whether the geographic panel contains real, explainable variation.

    Demand also changes without any media intervention. Meridian supports time-varying intercepts intended to account for seasonality, macroeconomic movement, and long-term organic growth in the baseline. That feature is important, but it is not permission to omit known business events. Record material pricing changes, distribution shifts, promotions, measurement changes, and other events that could move the outcome. The model cannot recognize an undocumented reporting break as a reporting break.

    Query volume and a flexible baseline reduce specific biases; they do not eliminate every confounder. Treat them as improvements to the causal design, not as automatic proof that every remaining paid-search effect is causal.

    Build a model-ready geo-by-week dataset

    Overhead illustration of geographic tiles and weekly blocks organized with media, sales, pricing, and seasonal data tokens.

    The practical readiness benchmark is historical weekly data, ideally broken out by geography and covering at least two years. That duration is an ideal, not a guarantee of quality and not a substitute for useful variation. Two years of inconsistent definitions can be less informative than a shorter, well-governed panel.

    Start with the decision, then choose one primary outcome. If the budget decision is about revenue, build a revenue model. If the organization manages acquisition against leads or store visits, define that measure precisely and keep the definition stable. Mixing several business outcomes into an ambiguous success metric makes the final recommendation hard to interpret.

    Data blockWhat to includeReadiness check
    Business outcomeWeekly revenue, leads, or store visits by geographyOne documented definition, stable units, and known reporting breaks
    Paid mediaSearch spend and impressions, plus relevant offline and other-channel metricsConsistent channel mapping and reconciliation with platform or finance totals
    Search demandGoogle Query Volume at a compatible geographic and time levelTreated as a demand control rather than a paid-media result
    Nonmarketing controlsKnown factors such as pricing changes and available competitor-sales signalsA credible reason each variable could affect the outcome independently of media
    Experimental evidenceRelevant incrementality or geo-lift resultsComparable channel, outcome, market, and time context, with uncertainty retained

    Audit the panel before anyone starts tuning a model:

    1. Write a data dictionary. Define every field, currency, geographic identifier, week boundary, and unit. Decide how refunds, cancellations, or revised records are handled before fitting.
    2. Reconcile totals. Aggregate the regional data and compare it with the totals used by finance and the media platforms. Explain material differences rather than silently accepting them.
    3. Distinguish zero from missing. Zero spend means the channel was inactive. A blank value may mean the feed failed. Treating both as zero can manufacture variation that never occurred.
    4. Map structural breaks. Mark changes to tracking, CRM stages, revenue recognition, pricing, territorial boundaries, and campaign naming. A clean-looking time series can still join incompatible definitions.
    5. Inspect geographic variation. Compare when and how sharply media changed across regions. Flag channels that moved almost identically everywhere, because the model may struggle to separate their effects.
    6. Preserve useful search detail. Keep enough campaign information to inspect branded search separately before deciding which paid-search activity should be grouped for modeling.

    Meridian can also use aggregated national data, but you give up some of the regional contrasts that make its geo-level approach valuable. If reliable geographic outcomes do not exist, be explicit about that limitation. Do not create false precision by assigning national sales to regions with an arbitrary allocation rule.

    A failed readiness audit is useful. It tells you to repair collection, preserve future geographic variation, or plan an incrementality experiment before asking the model for a budget answer. Forcing a run through a broken panel only postpones that work until the recommendations become harder to defend.

    Calibrate the Bayesian model before moving budget

    Balanced calibration mechanism with probability spheres, channel inputs, uncertainty rings, and budget tokens awaiting allocation.

    Meridian’s Bayesian design lets you combine historical aggregate data with prior knowledge. A prior expresses what the model knows about a parameter before it learns from the current dataset. If you have measured a channel through an incrementality test or geo-lift experiment, that result can inform the model’s priors.

    This is one of Meridian’s most useful features, but only when the evidence is genuinely comparable. A test of one campaign, market, or outcome should not be treated as universal truth for every form of search advertising. Document what was tested, where it ran, which outcome it measured, and how uncertain the estimate was. Carry that uncertainty into calibration rather than entering only the most convenient point estimate.

    Do not turn last-click return on ad spend into a strong prior merely because it is the number the team already has. That would import the original attribution bias into a model intended to move beyond it. If there is no credible experimental evidence, use appropriately cautious assumptions and let the observed aggregate data do more of the updating.

    A defensible implementation sequence looks like this:

    1. Write the measurement brief. Name the budget decision, primary KPI, planning horizon, channels in scope, and business constraints.
    2. Freeze an audited data version. Keep the model input reproducible so later changes can be traced to a data revision or a modeling decision.
    3. Specify the model. Decide the geographic structure, media variables, search-demand control, nonmarketing controls, and treatment of baseline movement.
    4. Calibrate with credible experiments. Record which prior each test informs and why that test is relevant.
    5. Examine uncertainty and sensitivity. Check whether the decision changes when reasonable priors, controls, or groupings change. A recommendation that reverses under a small specification change is not ready for a large budget shift.
    6. Run bounded scenarios. Use Meridian’s what-if planning capability for changes that remain plausible relative to the observed history. Treat extreme extrapolation cautiously.
    7. Stage the decision. Make a controlled change, define the outcome you will watch, and use a follow-up experiment where the financial consequence justifies it.

    The fitting work requires Python, commonly through a Jupyter Notebook, and usually needs an analyst or data scientist comfortable with model specification. Open source does make the code inspectable and modifiable. That helps your team review assumptions and adapt the framework, but it does not make every specification equally valid.

    When results arrive, resist reducing the posterior output to one definitive return number. Look at the range of credible outcomes, the contribution of the baseline, sensitivity to priors, and whether the result is consistent with experimental evidence. If a proposed reallocation could materially affect revenue, use the model to narrow the decision and then validate the change. Do not place a large financial bet on one run merely because its point estimate is precise.

    Google Meridian measurement FAQ

    Does Meridian replace Google Ads or analytics reporting?

    No. Advertising and analytics reports remain useful for delivery, pacing, conversion monitoring, and campaign diagnosis. Meridian addresses a different question: how much incremental business impact aggregate marketing activity appears to have produced. Keep operational reporting for execution and use the marketing mix model for strategic allocation.

    Do you need exactly two years of weekly data?

    Two years of weekly observations is an ideal data target, not proof that a model will work and not a stated universal cutoff. Coverage, consistency, geographic variation, and known business controls also matter. If you have less history, do not conceal the limitation. Assess whether a narrower model is defensible or whether data collection and experimentation should come first.

    Can a smaller company use Meridian?

    The code is openly available, so access is not restricted to companies with large television budgets. Practical suitability depends on whether you have enough stable historical data, meaningful media variation, a measurable outcome, and Python-capable analytical support. A smaller business with good data may be better positioned than a large organization with fragmented systems.

    Does open source make Meridian objective?

    No. Open source makes the underlying code available for inspection and modification, which reduces black-box risk and lets your team challenge the implementation. The answer still depends on the data, variables, priors, channel grouping, and assumptions you choose. Transparency makes scrutiny possible; it does not perform the scrutiny for you.

    Your next step should be a data inventory, not a software installation. Export weekly outcomes, paid-search spend, impressions, and available query volume by geography. Mark whether each field has two years of consistent coverage, identify definition changes, and inspect how much regional variation actually exists. If that panel survives the audit, write down the single budget decision the first model must support and assign a Python-capable analyst. If it does not, fix the collection gap or design an experiment before asking Meridian for an answer.

    References