Author: shivamcrushpressai

  • How to Build Search Visibility for AI Agents and Answers

    How to Build Search Visibility for AI Agents and Answers

    You can rank in conventional search and still be absent when an AI system assembles an answer. The missing piece is often not another keyword. An agent has to reach your content, isolate the relevant passage, connect it to the right entity and decide that the claim is clear enough to reuse.

    Treat that sequence as a visibility pipeline. When you control access, extraction, delivery and measurement separately, you can diagnose why a page is missing instead of making broad content changes and hoping one of them works.

    Key takeaways

    • Set separate policies for model-training crawlers and agents that retrieve information for live answers. Blocking a vendor name broadly can block the function you actually want.
    • Make the core answer understandable in raw HTML, then use semantic sections and accurate structured data to reduce extraction ambiguity.
    • Keep titles, canonicals, essential metadata and critical structured data early in the HTML response. A page that renders correctly in your browser can still present an incomplete document to a crawler.
    • Use pull crawling for durable pages, push discovery for important updates, machine-readable delivery for structured facts and MCP access when an agent genuinely needs current data.
    • Measure bot access, extracted content, citation share and business outcomes as separate signals. Referral traffic alone cannot tell you whether generative visibility improved.

    Build a five-entry visibility pipeline

    Traditional search workflows often compress discovery, indexing and ranking into one mental model. Generative systems add retrieval, passage extraction, entity annotation and answer assembly. Your content can enter that process through five distinct routes.

    Entry routeWhat it doesWhere it fits
    Pull crawlingA crawler discovers and fetches a public URL on its own schedule.Evergreen pages, documentation, category hubs and other durable web content.
    Push discoveryYou notify a participating system that a URL is new or has changed.Pages whose value depends on being discovered soon after publication or revision.
    Push dataMachine-readable facts are delivered directly instead of relying only on page extraction.Structured catalogs, feeds and other data with a defined receiving system.
    MCP accessAn agent requests current information through a Model Context Protocol connection.Data that changes too quickly to be represented reliably by an occasional crawl.
    Ambient entryA system recommends or introduces information without a conventional explicit search query.Brand and entity discovery influenced by consistent, well-annotated information.

    These routes are complementary, not maturity levels. An evergreen explainer usually needs a clean crawl path more than an MCP server. A changing first-party dataset may need a direct machine interface because a cached page can become stale between fetches. Map each important content type to the least complicated route that preserves its accuracy.

    All five routes eventually depend on annotation: the system has to associate a fact with the correct organization, product, person, place or topic. That is why delivery alone is insufficient. Conflicting names, unclear ownership, inconsistent dates or schema that disagrees with visible copy can weaken the content after it has been successfully fetched.

    Separate training permission from live-answer retrieval

    The label AI bot hides several different jobs. The same provider may use one user agent for model training and another for retrieval or search. Current crawler distinctions include separate training, crawling and live-search identities:

    • OpenAI: GPTBot is associated with training, while OAI-SearchBot is associated with search and retrieval.
    • Anthropic: ClaudeBot is associated with training; Claude-User and Claude-SearchBot serve retrieval or search functions.
    • Perplexity: PerplexityBot is the crawler identity, while Perplexity-User is associated with user-driven searching.

    Decide what you want before editing robots.txt. For each user agent, record whether public editorial pages, product information, support documentation and downloadable resources should be accessible. Make the training decision independently from the retrieval decision. A company can decline training access while still choosing to make public pages available to a search-oriented agent.

    A narrowly scoped rule can look like this:

    User-agent: GPTBot
    Allow: /public/
    Disallow: /private/

    Do not use robots.txt to protect confidential information. It is a crawler directive, not an authentication system. Private, customer-specific and administrative content needs server-side access control whether a path is disallowed or not.

    After deployment, inspect server logs by user agent. Confirm that the intended crawler reaches the intended URLs, receives a successful response and can fetch resources needed to interpret the page. A syntactically tidy policy is not evidence that the access path works.

    Use llms.txt as a map, not a dependency

    The emerging llms.txt convention can give agents a concise map of important links, while llms-full.txt can aggregate larger amounts of text into one machine-oriented resource. Adoption is not universal, so neither file should be the only way to discover or understand your content.

    If you publish llms.txt, generate it from the same canonical content inventory used by your sitemap and navigation. Include public, authoritative URLs rather than every filtered, duplicated or campaign-specific variation. Keep the file synchronized when pages move or claims change. It does not override robots.txt, authentication, canonical signals or the content of the page itself.

    Make each page fragment-ready
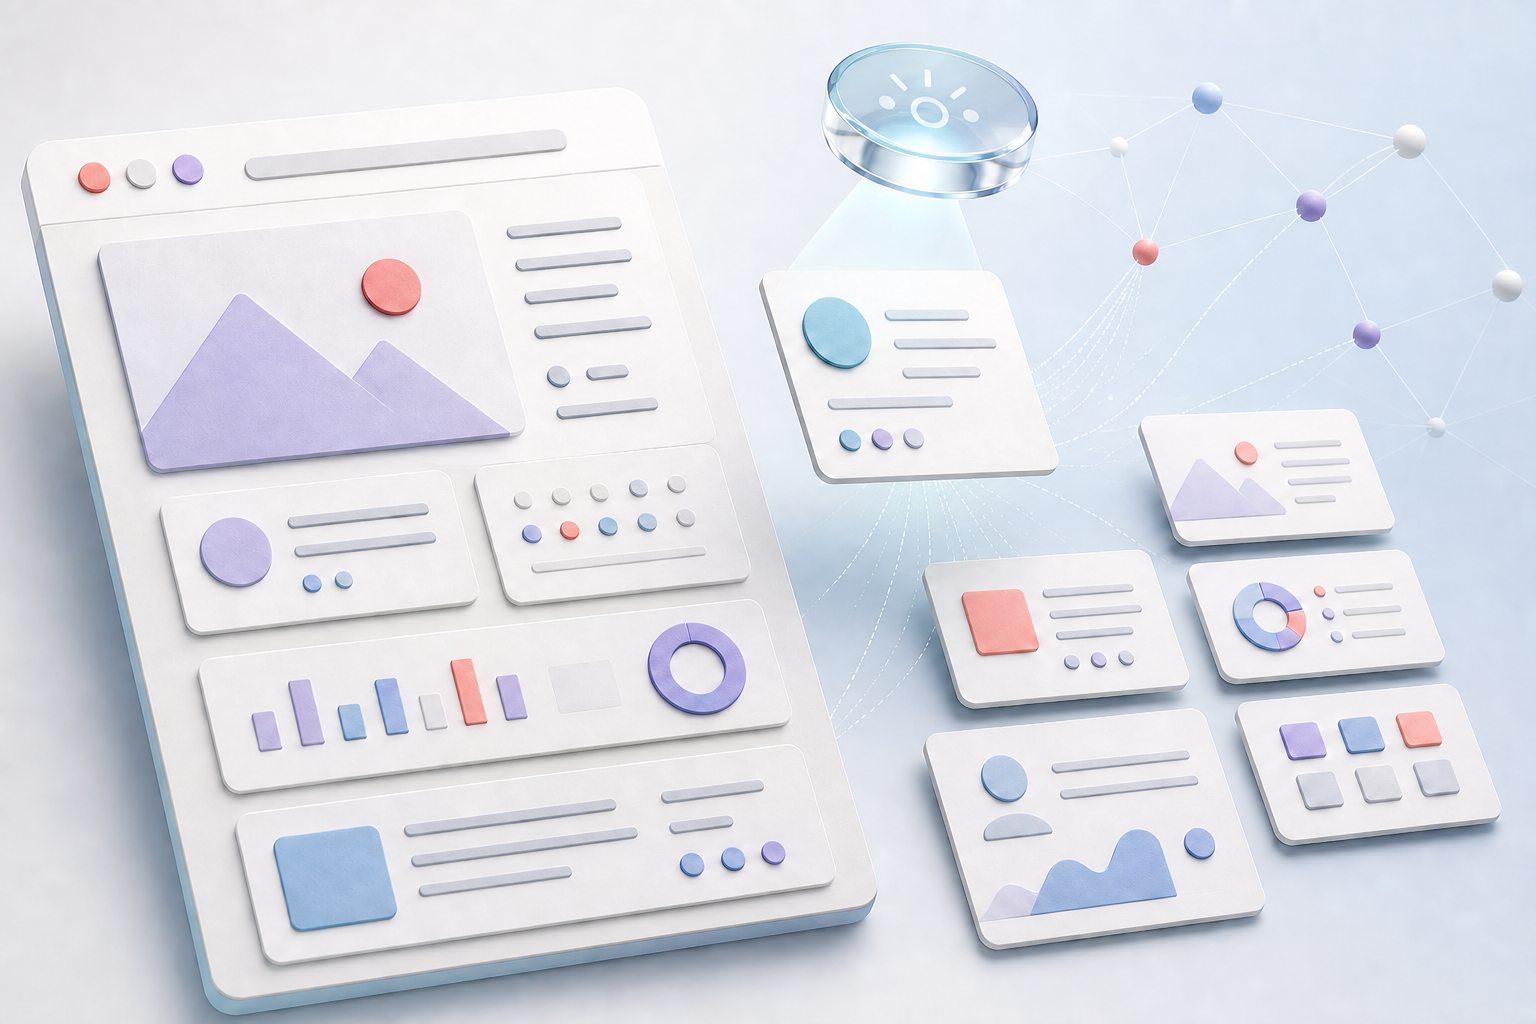
    A digital page separates into modular content cards while an AI lens selects one card and links it to a network of entities.

    An agent rarely needs every sentence on a long page. It needs a passage that answers the current question without losing essential qualifications. Your job is to make that passage easy to locate and safe to reuse.

    Build each important section in this order: state the answer, name the entity it applies to, add the condition or limitation, then provide the supporting explanation. Put exceptions beside the claim they qualify. If a warning appears several sections later, extraction can separate it from the advice it was meant to constrain.

    • Use a descriptive heading that reflects the question or decision addressed by the section.
    • Answer immediately beneath that heading instead of opening with scene-setting copy.
    • Name the product, organization, method or audience inside the passage. Avoid relying on vague references such as it, they or this solution when the fragment could be retrieved alone.
    • Keep definitions stable. Do not alternate between near-synonyms if they could make one entity look like several unrelated entities.
    • Use lists for steps and criteria, and tables only when rows and columns express a real comparison.
    • Link supporting detail close to the claim it supports rather than collecting all evidence in an unrelated footer.

    Semantic HTML helps establish those boundaries. Use <article> for the primary work, <section> for coherent subtopics and <aside> for genuinely supplementary material. This does not guarantee selection, but it gives crawlers a clearer representation than a page composed entirely of generic containers.

    Structured data should agree with the visible page. Use the schema type that matches the content, identify the same entities named in the copy and omit properties you cannot support on the page. JSON-LD can reduce ambiguity; it cannot repair an unclear claim or turn unsupported markup into trustworthy information.

    Put critical information within the fetched bytes

    Payload order matters when a crawler stops before the document ends. Googlebot fetches up to 2MB for an individual non-PDF URL, with the HTTP response headers included in that limit. When an HTML response exceeds the threshold, the downloaded portion is passed to indexing and the Web Rendering Service as though it were the complete file. Bytes after the cutoff are not fetched, rendered or indexed. PDFs have a higher 64MB limit.

    The Web Rendering Service can fetch referenced resources separately and execute JavaScript like a modern browser, so external scripts and styles do not consume the parent HTML document’s byte allowance. That is a reason to remove oversized inline payloads, not a reason to hide the central answer behind unnecessary client-side execution.

    Do not generalize Google’s exact limits to every AI crawler. Use them as a concrete reminder that a page visible in your browser is not necessarily the same document a bot received or completed.

    • Inspect the raw server response as well as the rendered page.
    • Place the title, canonical link, essential meta tags and critical structured data early in the HTML.
    • Move large CSS and JavaScript payloads into external resources where appropriate.
    • Remove duplicated navigation, serialized application state and other bulky inline material that delays the primary content.
    • Verify that the central answer appears without requiring a click, expansion control or user-specific session.
    • Compare raw and rendered text so you know what depends on JavaScript.

    Response performance belongs in the same audit. When a server cannot deliver resources efficiently, fetchers may slow their activity to avoid adding load, which can reduce crawl frequency. Review latency alongside status and crawl counts instead of interpreting fewer requests as a content-quality judgment.

    Add push paths where freshness changes the answer

    Publishing and waiting remains reasonable for stable content, but it is incomplete when discovery speed or data freshness affects whether an answer is useful. Add proactive delivery in layers, after the public URL and its canonical content are sound.

    1. Preserve the pull foundation. Give every durable page a crawlable canonical URL, sensible internal links and an accurate sitemap entry. Push mechanisms should supplement this foundation.
    2. Notify systems about meaningful URL changes. Bing’s IndexNow can accelerate discovery by telling participating systems that content is new or updated. Treat the notification as an entry signal, not a substitute for a fetchable and interpretable page.
    3. Provide machine-readable data when a receiver supports it. Use a structured feed or direct data connection for facts that should not depend on extracting prose. Define one authoritative source so the feed and public page do not contradict each other.
    4. Use MCP for genuinely current interactions. An MCP connection is justified when an agent needs information that could become stale between crawls. Specify what each tool exposes, which fields are authoritative, how errors are represented and who may call it. Do not create an MCP layer merely to duplicate static editorial pages.
    5. Strengthen the inputs to ambient discovery. Keep names, descriptions and relationships consistent across your first-party content and machine-readable outputs. Ambient recommendations are not a submission box you can force; they depend on whether systems can confidently recognize and contextualize the entity.

    Use a freshness test when choosing the route: if an older value would make the answer materially wrong, evaluate direct data or MCP access. If the information remains accurate until the next normal crawl, keep the architecture simple and focus on extraction quality.

    Centralize the underlying data before adding several delivery methods. Otherwise a page, feed and agent tool can expose three different versions of the same fact. Faster delivery only makes that inconsistency spread sooner.

    Measure access, citations and outcomes separately
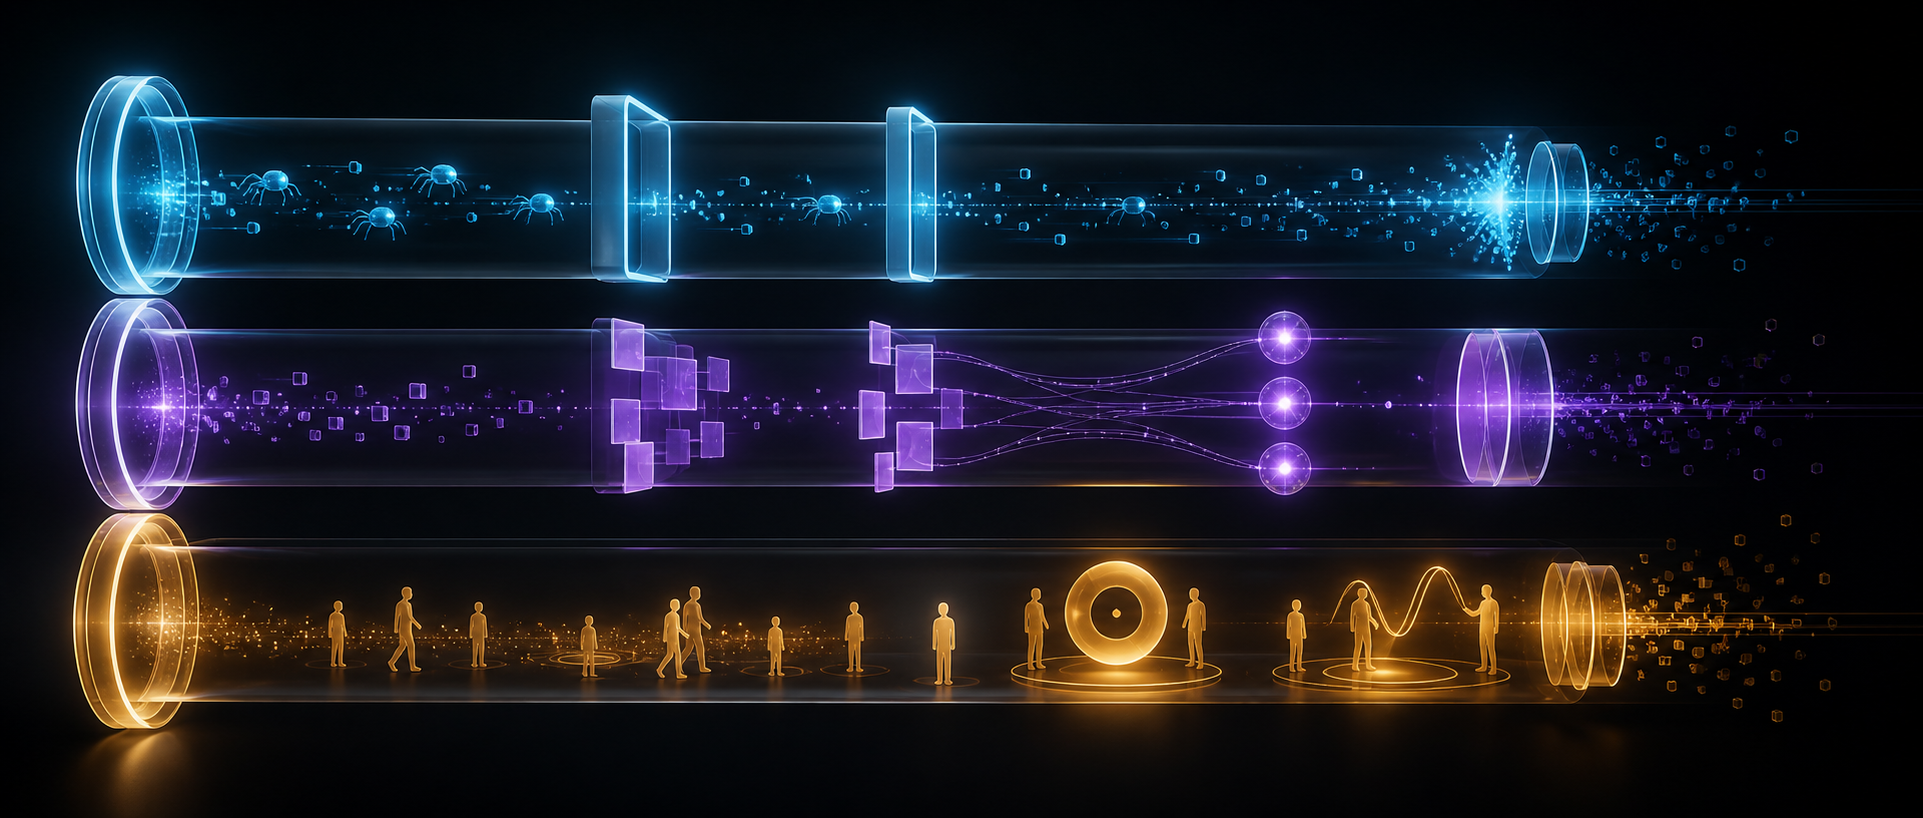
    Three parallel visual channels depict content access, citation connections, and human outcomes using abstract gateways, fragments, and symbols.

    A click-only dashboard cannot explain generative visibility. An answer may cite you without sending a visit, retrieve your page without using it or mention your brand while linking elsewhere. A practical GEO technical audit combines citation share, log analysis and zero-click behavior rather than collapsing them into one traffic number.

    • Access: Group server requests by user agent. Record which important URLs were requested, whether they were allowed, how the server responded and whether latency changed.
    • Extraction: Compare the raw response with the rendered page. Confirm that the answer, entity name, qualifications, canonical and structured data are present and mutually consistent.
    • Interpretation: Check whether headings, visible copy, schema and linked canonical resources describe the same entity and claim. Flag conflicting names, dates, ownership or status.
    • Visibility: Maintain a fixed set of representative questions. Citation share is the portion of checked answers that cite your domain or a tracked URL. Record the engine, model, query, cited page and claim so later checks remain interpretable.
    • Outcome: Track identifiable AI referrals and their business actions, but keep citations as a separate measure. No referral does not prove that the system ignored you; the generated answer may have satisfied the user without a click.
    • SEO context: Compare changes in AI visibility with domain metrics, backlink profiles, keyword research and organic-search data. This helps distinguish an agent-access problem from a broader authority, demand or search-performance problem.

    The combination of signals points to the next action. No crawler requests usually directs you toward discovery or access controls. Successful fetching with no usable passage points toward rendering or extraction. Clear extraction with weak citation presence points toward annotation, relevance or authority. More citations without more referrals may reflect zero-click use rather than failure.

    Keep the prompt set and measurement method stable while evaluating a change. If you replace the questions, engines and success definition at the same time, the before-and-after comparison cannot tell you which intervention mattered.

    Start with one content cluster tied to a real business or reputation goal. Verify crawler policy, raw HTML, semantic sections and structured data; then add IndexNow, a structured feed or MCP only where the content’s freshness requires it. Record access and citations before and after the change. Once that evidence chain works, make it part of the publishing workflow for every similar page.

    References


  • Local Discovery Across Google and ChatGPT: A Practical Plan

    Local Discovery Across Google and ChatGPT: A Practical Plan

    A customer who searches Google for a nearby provider and another who asks ChatGPT for a local recommendation may want the same outcome, but they reach it through different discovery systems. If you optimize only for the map pack or only for conversational answers, your business can be easy to find in one place and absent in the other.

    Your job is to establish one dependable record of each location, then present and measure that record appropriately on each surface. That means treating your Google Business Profile, location page, visible business facts and structured data as one system without pretending Google and ChatGPT have the same ranking model.

    Google and ChatGPT answer different versions of a local question

    Google local discovery is strongly tied to explicit profile fields and geography. Your business name, primary category, secondary categories, services, reviews, linked landing page and physical proximity can all shape where the business appears. A geo-grid can show that visibility changing from one neighborhood or city boundary to the next.

    ChatGPT handles the discovery moment as a conversation. The user can describe a service, constraint and area in ordinary language, and shared location can make the local response more precise. Location is therefore a meaningful input, but that does not establish a permanent ChatGPT rank comparable to a map-pack position.

    This distinction changes how you work. Measure Google across physical points on a grid. Evaluate ChatGPT with repeatable prompts and controlled location context. A strong result on either surface is useful, but it cannot serve as a proxy for the other.

    Key takeaways

    • Build a single, accurate location record before optimizing individual discovery surfaces.
    • Audit Google Business Profile signals against the businesses that actually rank in your local grid, not against generic benchmarks.
    • Use a dedicated page for each real location and align it with the profile that links to it.
    • Keep LocalBusiness structured data consistent with facts a visitor can see on the page.
    • Test ChatGPT with fixed prompts and compare responses with and without shared location when that option is available.
    • Treat proximity limits and conversational omissions as different problems requiring different fixes.

    Start with a five-part Google Business Profile audit

    A business owner uses a tablet while five icon-based checkpoints surround a neighborhood storefront, including a map pin, clock, phone, category symbol, and rating stars.

    A profile audit becomes useful when it explains a visibility gap. Begin with the competitors appearing for the same commercial query in the areas you want to reach. Their lifetime review totals may look impressive, but totals alone do not tell you which signals separate the current winners.

    1. Compare review recency and velocity. Look at how frequently leading competitors have earned reviews recently, not just how many they have accumulated. Fresh and consistent review activity can matter more than a large historical total. There is no universal target in this evidence, so derive your benchmark from the listings winning your own searches. Places Scout or Whitespark geo-grid data can help you connect review patterns with visibility. If you manage many markets, Places Scout API data can turn that comparison into a recurring monitor.
    2. Verify the business name. A relevant keyword in a legitimate business name can have an outsized effect on local visibility. Do not add a service or city merely as a profile tactic when it is not part of the documented name. A DBA may make a name change legitimate, but it also creates legal, administrative and brand consequences. Treat it as a business decision, not a metadata shortcut.
    3. Inspect the primary category first. The primary category can substantially influence local ranking. Compare the primary categories used by top businesses for the query you care about, then choose the closest truthful description of your core offering. Add relevant secondary categories and review the available service selections, but do not dilute the profile with categories the location cannot support.
    4. Evaluate the linked landing page. A generic homepage forces both customers and machines to work out which location, service and contact details apply. A dedicated, keyword-focused location page can create better alignment between the profile and its destination. Check that the page identifies the same business, location and services as the profile.
    5. Map the proximity ceiling. Visibility often contracts as the search point moves away from the location or crosses a city boundary. A ranking-radius view helps you distinguish an optimization problem from a geographic limitation. Local Falcon’s Share of Local Voice can help show the realistic reach of a location. If the business is strong nearby and consistently weak farther away, more profile edits may not solve the actual constraint.

    Complete the audit before changing fields. Otherwise, a category edit, review campaign and page rewrite can overlap, leaving you unable to tell which change helped or hurt. Record the starting grid, profile configuration, linked page and recent review pattern, then make the change supported by the clearest gap.

    Turn each location page into a reliable entity record

    The page linked from your profile should resolve local uncertainty quickly. A visitor should not have to infer whether the location offers the requested service, whether it serves the relevant area or how to contact it. The same clarity also gives parsers less ambiguity to reconcile.

    Make the visible page complete before adding schema

    • Identify the business and location in the opening copy using the same legitimate name shown on the profile.
    • Describe the primary services in plain language and keep them aligned with the profile’s categories and service selections.
    • Show the applicable address, service area, telephone number, opening hours and contact path.
    • Explain meaningful local constraints such as appointment coverage, access, service boundaries or location-specific availability.
    • Address the questions that determine whether a nearby customer is a fit instead of filling the page with interchangeable city-name paragraphs.
    • Link the corresponding Google Business Profile directly to this location page rather than sending every profile to the homepage.

    If you operate multiple locations, give each real location its own URL and its own accurate details. Do not manufacture local relevance with addresses, service areas or location pages that do not represent an operating business. Besides misleading the reader, false location claims make your first-party record harder to keep consistent.

    Use LocalBusiness JSON-LD to describe, not embellish

    Choose the most specific LocalBusiness subtype that truthfully describes the location. Give the entity a stable @id and include relevant properties such as name, URL, telephone, address and openingHoursSpecification when those facts apply. Each physical location should have its own URL, identifier and location-specific values.

    The markup should agree with the page and profile. Do not put a different name in JSON-LD, mark up an address the visitor cannot find, or use areaServed to claim places the business does not genuinely serve. Validate the syntax before deployment, then verify the rendered page still exposes the underlying facts to a human reader.

    Structured data is useful for explicit entity description, but it is not a substitute for the profile, reviews, landing-page content or physical relevance. It also should not be treated as a guaranteed switch for ChatGPT inclusion. Its immediate job is simpler: prevent your own publishing stack from telling conflicting stories about the business.

    Measure Google visibility and ChatGPT answers in separate loops

    Two separate circular icon loops for map search and conversational recommendations connect to the same miniature storefront.

    Use a geo-grid to diagnose Google

    Run the same commercially meaningful query from fixed points around the location. Record where the business appears, where visibility fades and which competitors replace it. Mark city borders and meaningful neighborhood changes on the grid so that a geographic pattern does not get misread as a page problem.

    Then compare the profile variables that can explain the pattern: recent review activity, primary and secondary categories, selected services, business name and landing-page alignment. If visibility is weak even close to the location, begin with those controllable signals. If it is strong nearby and falls away predictably, revise the target area or query expectations before considering another location. A new location should exist because demand and operations justify it, not merely to color more grid points.

    Use a prompt set to diagnose ChatGPT

    Build prompts from real customer decisions rather than from your brand name. Include requests for a provider offering a specific service near a named place, requests with a meaningful constraint and broader nearby requests that depend on the user’s location.

    • Keep the wording fixed when comparing results.
    • When location sharing is available, run the same local request with location shared and not shared.
    • Record whether the business appears, what reason is given, which business facts are used and which links or citations are shown, if any.
    • Flag incorrect names, services, locations and hours separately from a complete omission.
    • Retest under the same conditions after a meaningful profile, page or data correction.

    A single conversational response is an observation, not a stable ranking report. Look for repeated patterns across the intents that matter. If the system describes the business incorrectly, inspect your visible location page, profile and structured data for conflicts. If the facts are correct but the business is not mentioned, improve the page’s explanation of who the location serves and which needs it can meet; do not randomly rewrite the profile in response to one answer.

    What you observeLikely constraint to investigateBest next move
    Google visibility is weak across the grid, including near the locationProfile relevance, review activity or landing-page alignmentRun the complete profile audit and correct the clearest competitor gap
    Google is strong nearby but fades near borders or outer neighborhoodsProximity and city geographyTarget areas where the location can compete and reconsider unrealistic radius expectations
    Google is strong but ChatGPT rarely mentions the businessConversational fit or unclear first-party informationTest actual customer prompts and make services, location and constraints explicit on the page
    ChatGPT mentions the business with incorrect factsAmbiguous, incomplete or conflicting location dataCorrect the visible page, profile and JSON-LD, then retest the same prompt
    ChatGPT mentions the business but Google is weakGoogle-specific profile or proximity signalsUse the geo-grid to separate an optimization gap from a geographic ceiling

    Begin with a baseline, then choose the mismatch supported by the clearest evidence. If the Google grid collapses at a city boundary, stop expecting a title edit to erase geography. If ChatGPT gets a service wrong, correct the underlying fact before chasing mentions. If the profile is weak close to the location, audit categories, reviews and the linked page first. Fix the smallest defensible problem, rerun the same test and keep the two measurement loops separate.

    References


  • Ensure AI Sees Your Products: A 6-Point Optimization Guide

    Ensure AI Sees Your Products: A 6-Point Optimization Guide

    I’ve recently delved into the world of AI search engines like ChatGPT, Google AI Mode, and Perplexity, and how they’re transforming the way consumers find and buy products online. It’s clear to me that if my product pages aren’t optimized for these AI assistants, I’m likely missing out on significant traffic and revenue.

    What I’ve discovered is that AI assistants evaluate product pages differently than traditional search engines. They require a deep understanding of products to recommend them confidently to users with varied needs.

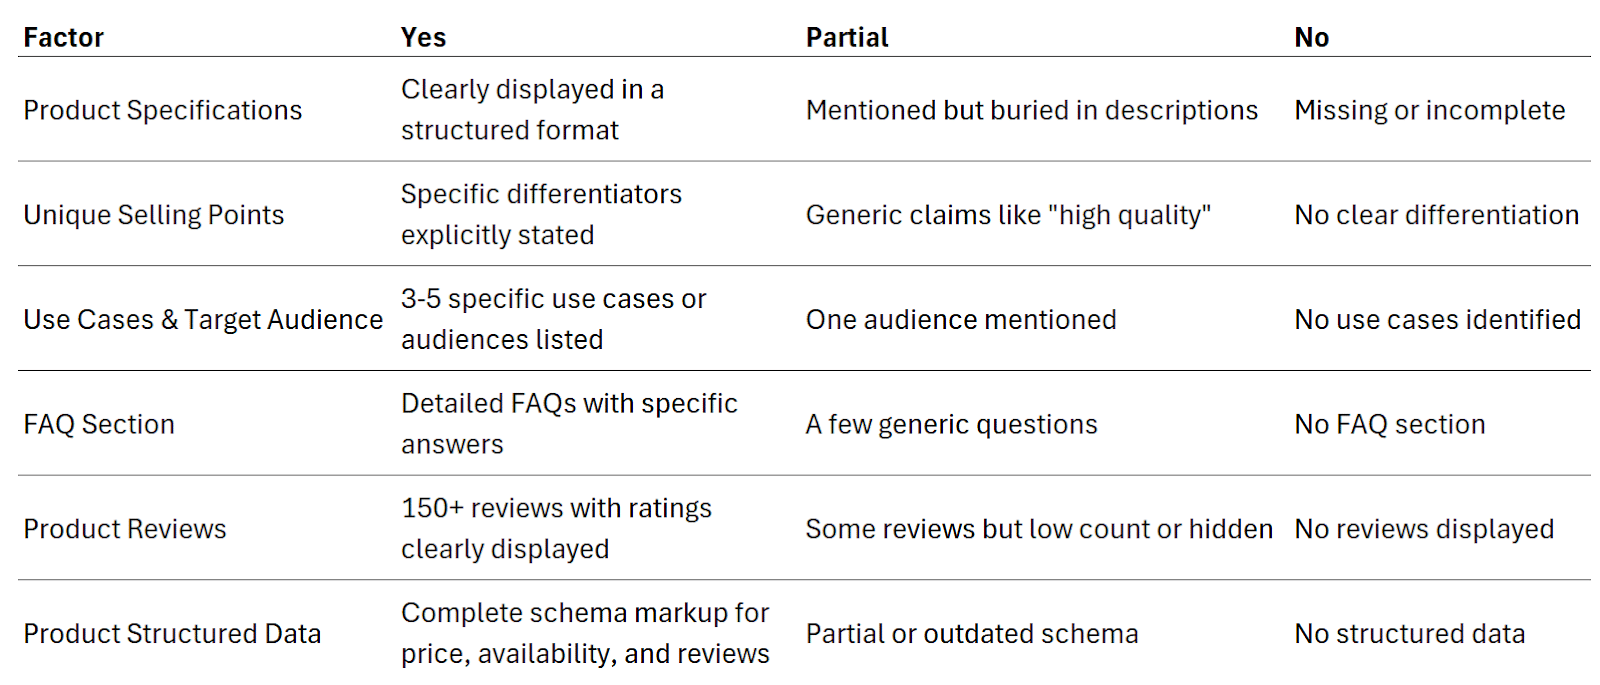
    To ensure my product pages are AI-ready, I’ve crafted a simple scorecard focusing on six key factors:

    1. Product specifications

    ```json
{
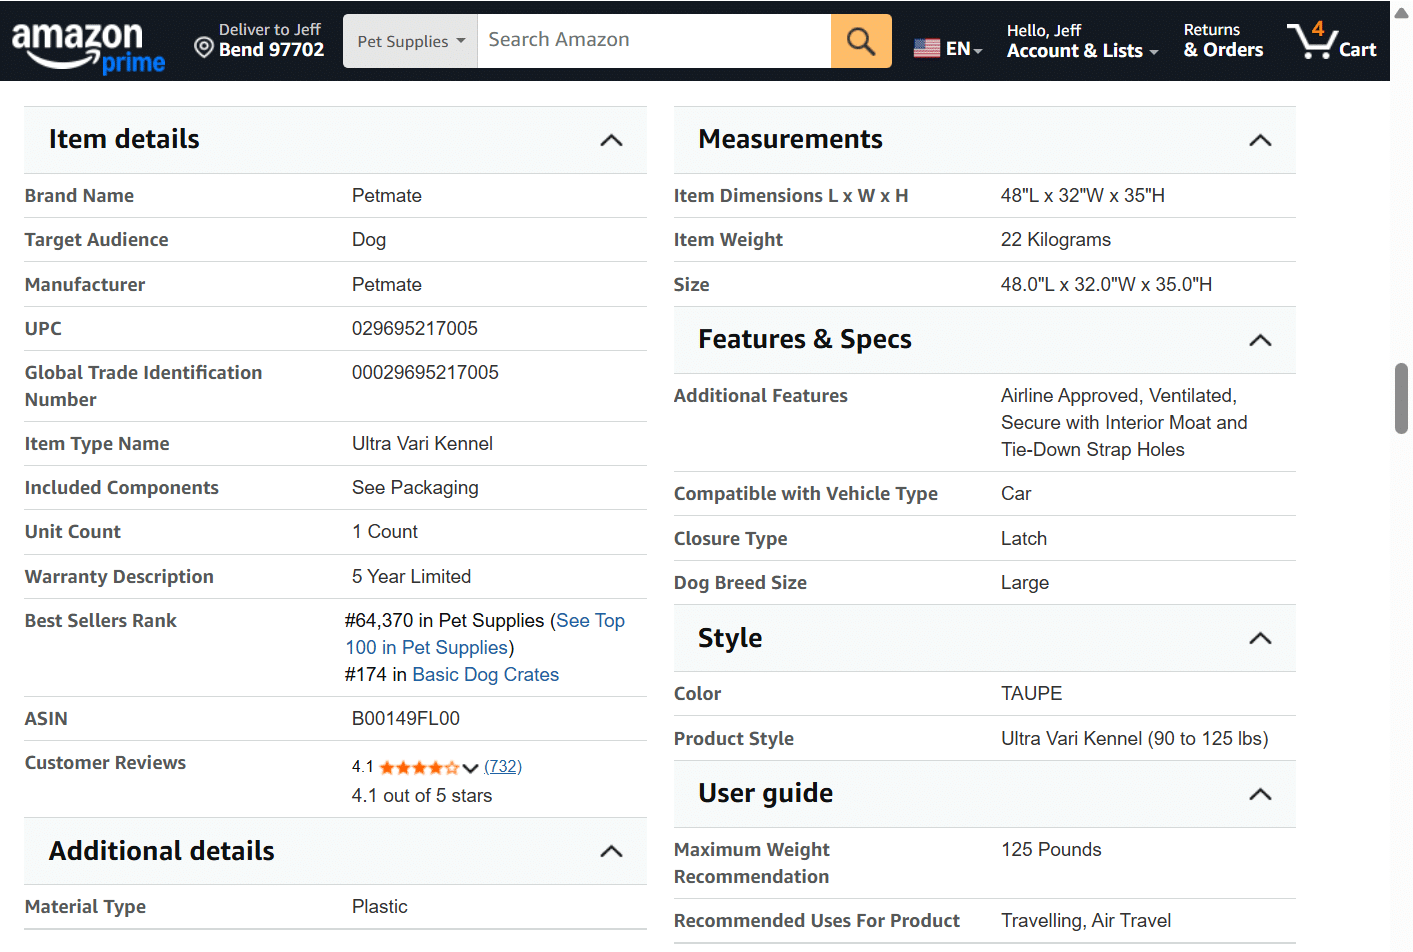
  "alt": "Amazon product details for Petmate Ultra Vari Kennel, large size, dog supplies.",
  "caption": "Explore the features of the Petmate Ultra Vari Kennel, ideal for large dogs. This dog crate is airline-approved and designed for secure travel.",
  "description": "This image shows an Amazon product details page for the Petmate Ultra Vari Kennel, designed for large dogs. The kennel is airline-approved with interior features like ventilation and a moat. It weighs 22 kilograms and measures 48"L x 32"W x 35"H. Made of plastic, it supports dogs weighing 90 to 125 lbs, perfect for air travel. This bestseller ranks #64,370 in pet supplies, with an average rating of 4.1 stars from over 700 reviews."
}
```

    Does the product page clearly display the product’s attributes and specifications?

    AI assistants need explicit specifications to understand my products and match them with customer needs. For example, if someone asks for “an airline-friendly crate for a 115-pound dog,” the AI must see the weight limit clearly to recommend it.

    Amazon excels at this, as their product pages display detailed specifications that likely boost their AI search performance.

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    Action item: I ensure all specifications are clearly presented on my product pages, ideally in a structured table or a list, rather than burying them in the description or marketing copy.

    2. Unique selling points

    Are the product’s unique benefits clearly described?

    ```json
{
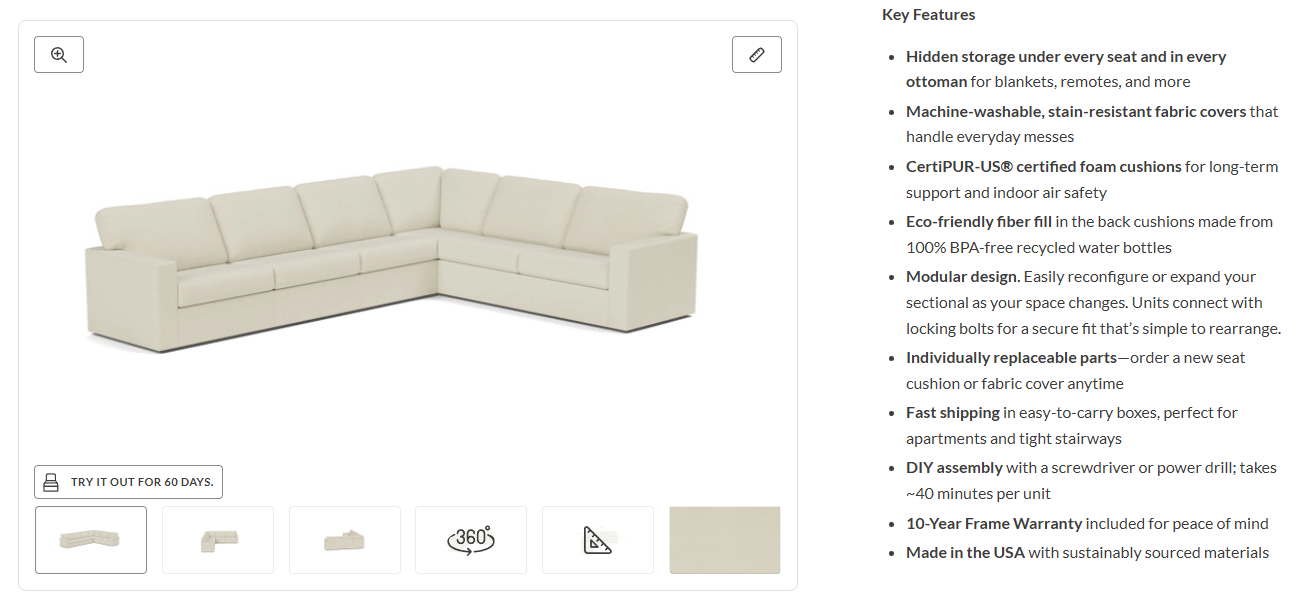
  "alt": "Beige L-shaped sectional sofa with hidden storage, modular design, and eco-friendly materials.",
  "caption": "Discover comfort and versatility with this beige L-shaped sectional sofa, featuring hidden storage and eco-friendly materials, perfect for any modern living space.",
  "description": "This image shows a beige L-shaped sectional sofa with clean lines and contemporary style. It features hidden storage under every seat, machine-washable and stain-resistant covers, and CertiPUR-US certified foam cushions. The modular design allows for easy reconfiguration. This eco-friendly piece uses materials such as BPA-free recycled water bottles for cushion filling and offers fast shipping and easy DIY assembly. Perfect for urban apartments and it comes with a 10-year frame warranty."
}
```

    Highlighting what makes my products special gives AI a reason to recommend them over competitors. It’s crucial for AI to grasp these unique features to decide on recommendations.

    Action item: I emphasize key features that set my products apart, avoiding vague claims like “high-quality craftsmanship” and instead focusing on specific differentiators.

    3. Use cases and target audience

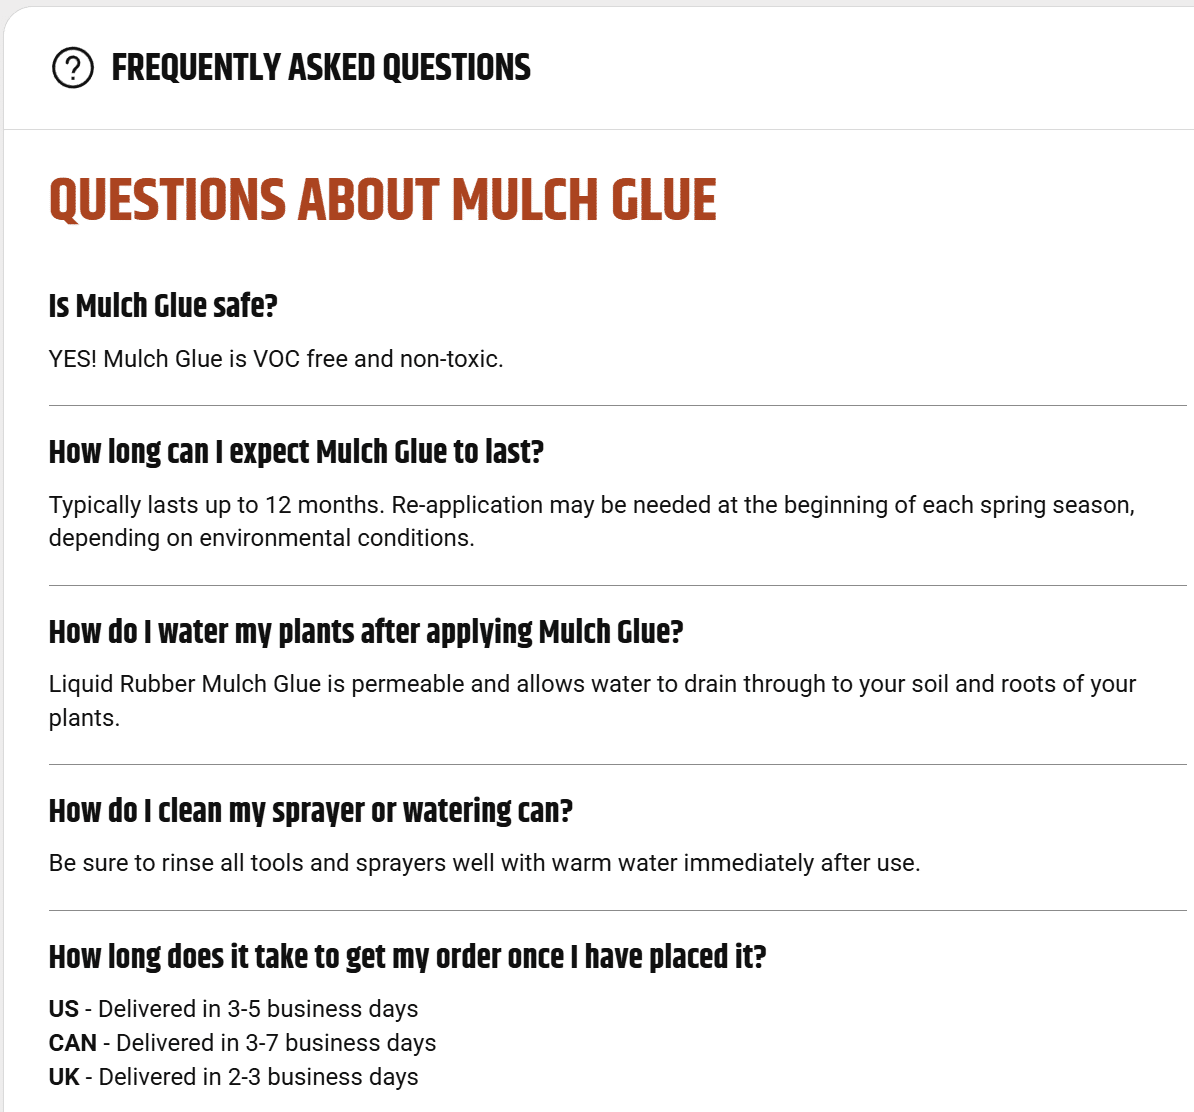
    FAQ section about mulch glue, covering safety, longevity, application, and delivery details.
    Discover everything you need to know about Mulch Glue, from safety and longevity to watering tips and delivery times.

    Are the product’s intended use cases and audience clear?

    AI matches products with people and their needs, not just keywords. Explicitly stating who the product is for and how it’s used makes it more likely to be recommended by AI.

    Action item: I list the top use cases and audience segments for each product, considering situations, pain points, and goals.

    ```json
{
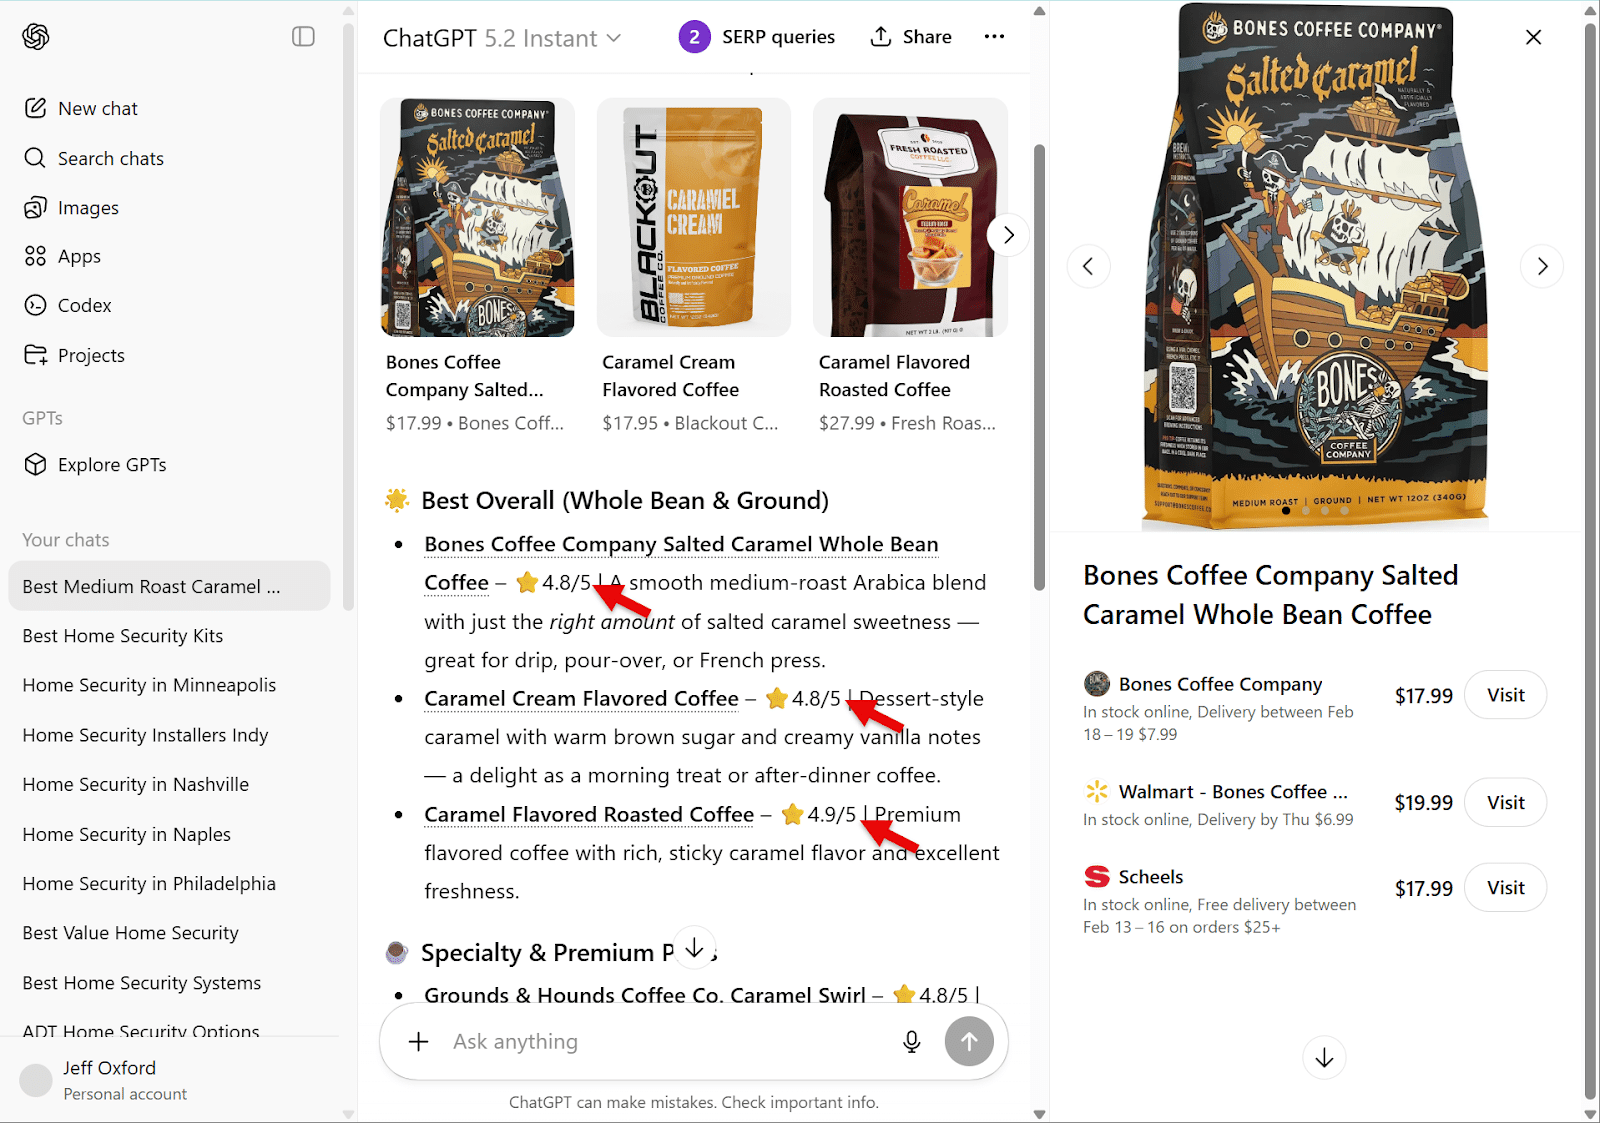
  "alt": "Comparison of various caramel flavored coffees including Bones Coffee Company Salted Caramel with ratings and prices displayed.",
  "caption": "Discover the top-rated caramel flavored coffees with Bones Coffee Company's Salted Caramel leading the pack, offering a smooth blend perfect for any coffee lover.",
  "description": "The image showcases a comparison of caramel flavored coffees, highlighting Bones Coffee Company Salted Caramel Whole Bean Coffee as a top choice. This medium roast Arabica blend is noted for its perfect balance of salted caramel sweetness, earning a 4.8/5-star rating. Ideal for drip, pour-over, or French press brewing, it is competitively priced at $17.99 with delivery options. The image also shows offerings from other brands with varied flavors and ratings, providing a comprehensive look at customer favorites."
}
```

    4. FAQ section

    Does the product page include an FAQ section answering common questions about the product?

    FAQs can bolster AI’s confidence in recommending my products by showing they’re a good fit for specific queries. The more detailed the FAQ section, the more it helps in AI search contexts.

    ```json
{
  "alt": "Bones Coffee Company Salted Caramel 12oz bag on a rustic surface with caramel cubes and sea salt.",
  "caption": "Delight in the flavors of Bones Coffee Company's Salted Caramel blend. This 12oz medium roast promises a rich taste, adored by coffee lovers everywhere.",
  "description": "This image showcases a 12oz bag of Bones Coffee Company's Salted Caramel flavored coffee, featuring a distinctive pirate ship design. Surrounded by coffee beans, caramel cubes, and sea salt, this medium roast coffee is highly rated for its unique taste and aroma. Available for purchase at $17.99, this whole bean coffee is perfect for those seeking a sweet and salty coffee experience."
}
```

    Action item: I gather and answer the most common questions from customer inquiries, reviews, and even competitor analysis to include on product pages.

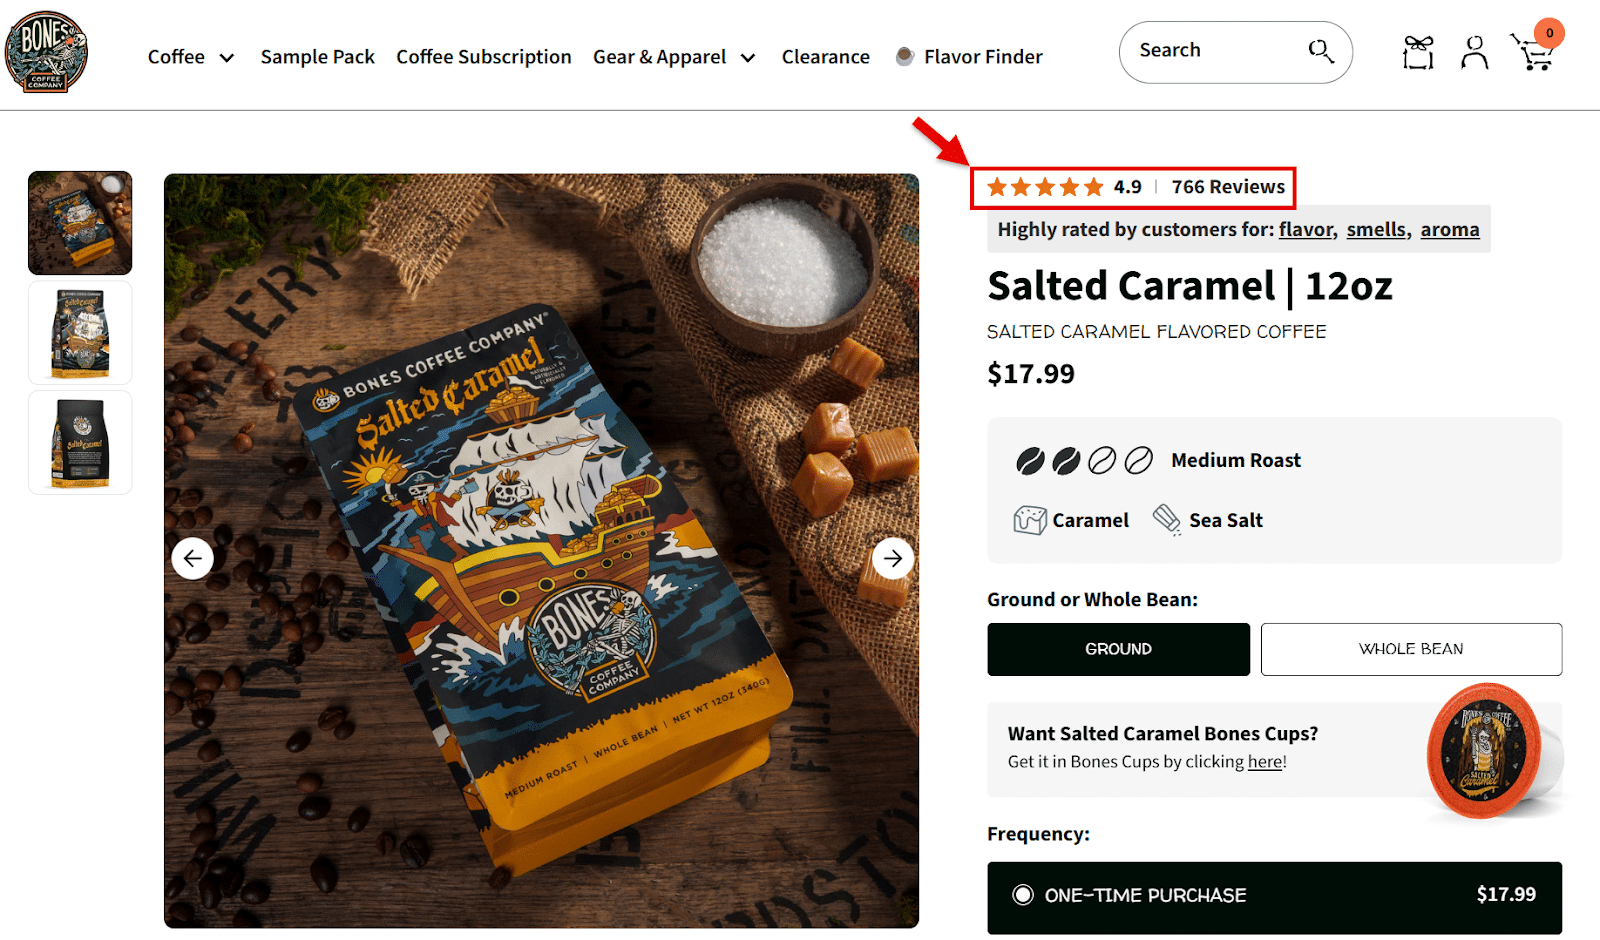
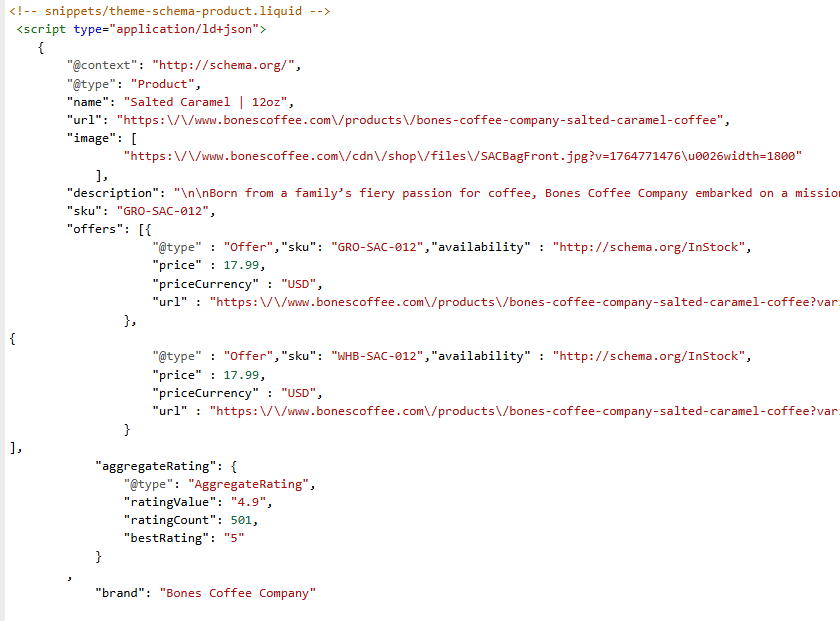
    5. Product reviews

    Does the product page display customer ratings and review counts?

    ```json
{
  "alt": "Screenshot of JSON-LD script for Bones Coffee Company's Salted Caramel coffee product details.",
  "caption": "Delve into the rich details of Bones Coffee Company's Salted Caramel coffee, from product specs to price offerings, in this JSON-LD snippet.",
  "description": "This image showcases a JSON-LD script detailing the product information for Bones Coffee Company's Salted Caramel coffee. It includes the product name, image URL, description, SKU, price offers, availability, and aggregate rating with a high score of 4.9 out of 5. Key attributes like the brand and pricing in USD are also highlighted, providing a comprehensive digital representation of the coffee product for online listings and SEO optimization."
}
```

    AI recommends products with proven reputations. Displaying a high rating and substantial number of reviews increases the chances of my products being recommended by AI.

    Action item: I ensure high visibility for product ratings and review counts on every product page, possibly using third-party platforms to solicit reviews.

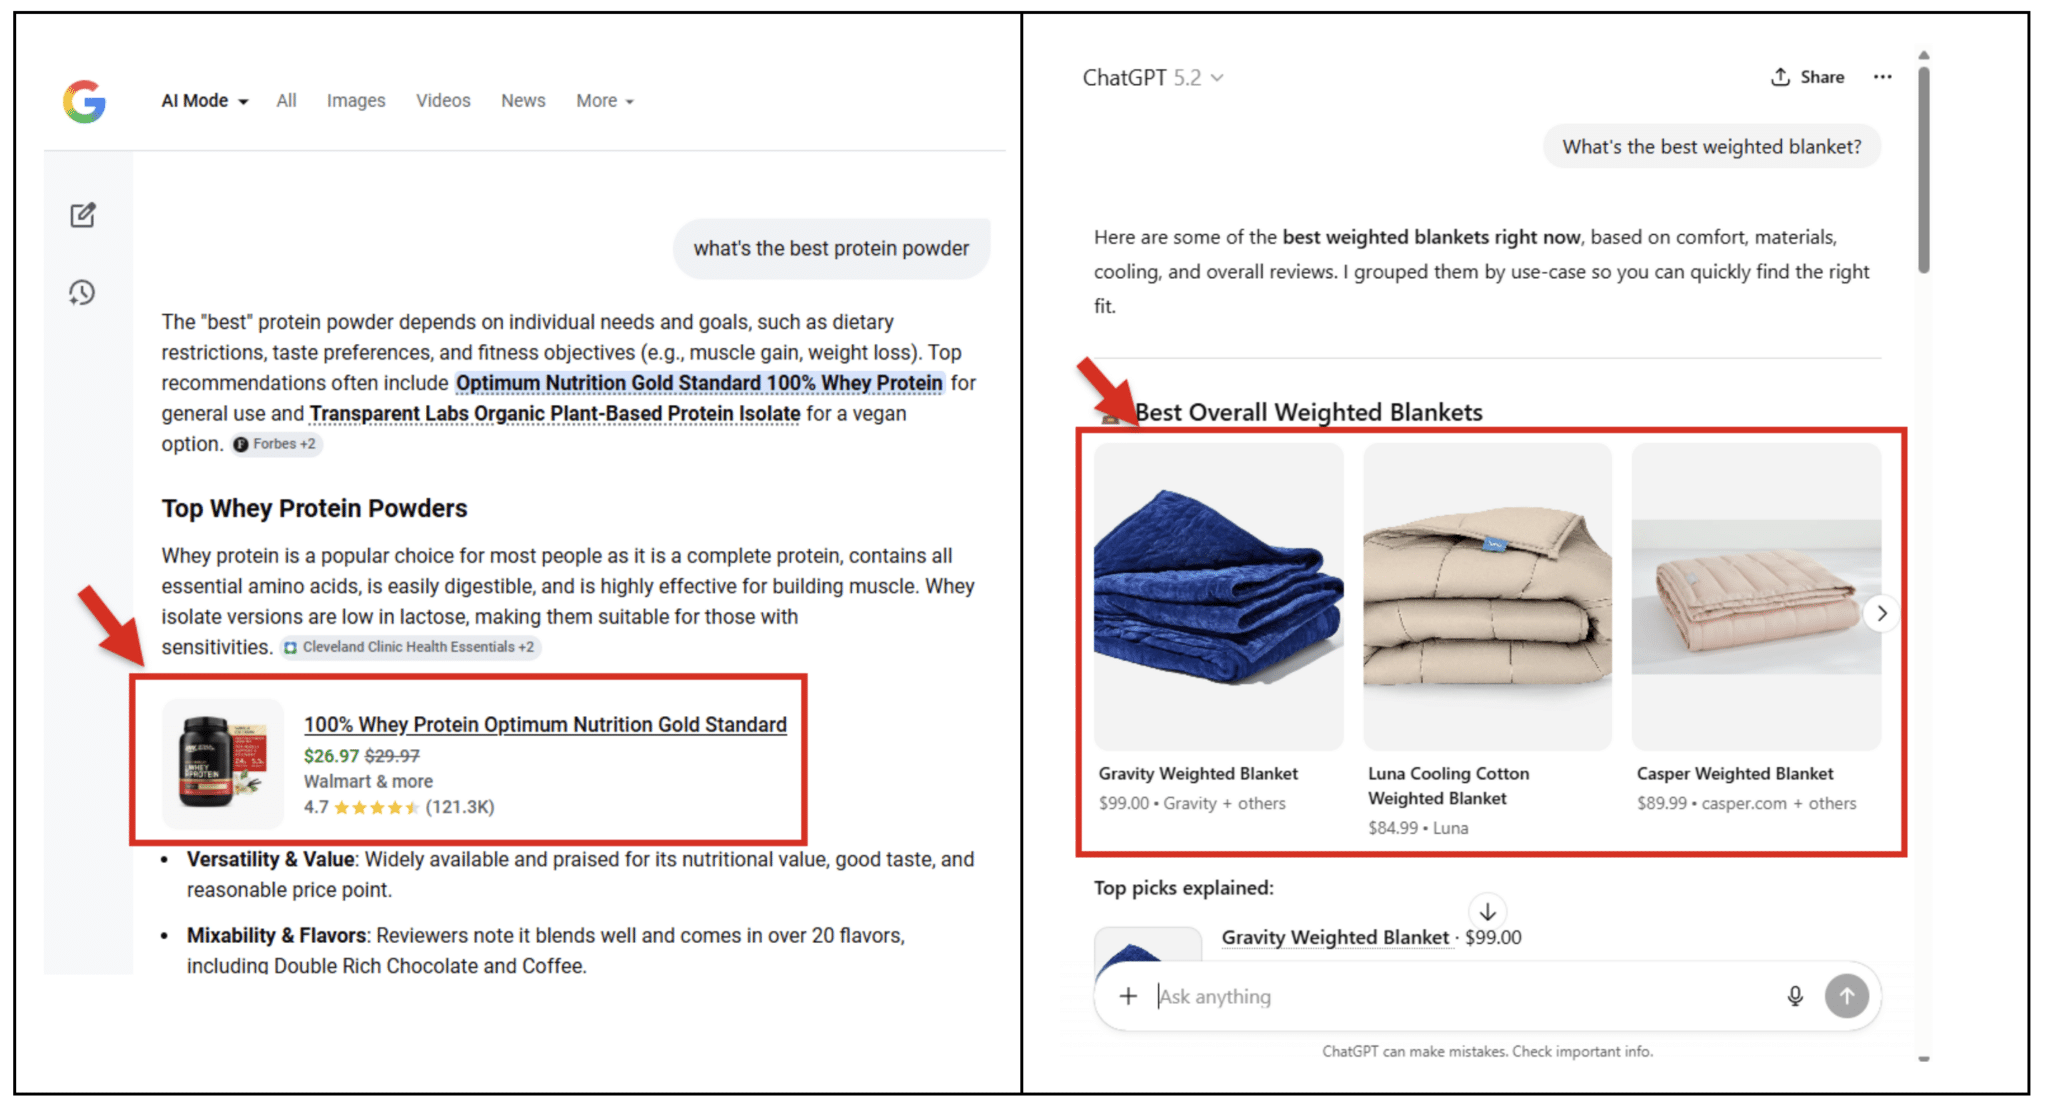
    6. Product structured data

    ```json
{
  "alt": "Comparison of whey protein and weighted blankets on a webpage.",
  "caption": "Discover the top recommendations for whey protein powders and weighted blankets on this informative webpage comparison.",
  "description": "The image displays a webpage comparison between top whey protein powders and the best overall weighted blankets. On the left, Google Search results highlight the '100% Whey Protein Optimum Nutrition Gold Standard,' marked with an arrow for emphasis, priced at $26.97, and rated 4.7 stars. On the right side, ChatGPT presents alternatives for the best weighted blankets, including Gravity and Casper, with prices and images shown. This comparison visually guides users to informed purchasing decisions based on product reviews and ratings."
}
```

    Does the product page include structured data for price, availability, reviews, and other key attributes?

    Structured data helps AI understand my product information effortlessly and even feeds into knowledge graphs that power AI recommendations.

    I understand that as AI agents engage more deeply in commerce, detailed product data becomes crucial for comparisons and purchasing.

    ```json
{
  "alt": "Comparison table showing product factors rated as Yes, Partial, or No.",
  "caption": "A comprehensive comparison table evaluating product factors like specifications, unique selling points, and reviews with clear Yes, Partial, or No ratings.",
  "description": "This image displays a comparison table assessing various product-related factors. Each factor is categorized under columns labeled Yes, Partial, or No. Factors include Product Specifications, Unique Selling Points, Use Cases & Target Audience, FAQ Section, Product Reviews, and Product Structured Data. This layout provides a clear and structured overview, aiding in identifying strengths and weaknesses of product listings for better visibility and decision-making."
}
```

    Putting the scorecard to work

    Here’s my concise strategy to audit and enhance my product pages for AI optimization, focusing on closing gaps where AI might overlook my products.

    Prioritizing these optimizations means I’m not only engaging effectively but also increasing my competitiveness in the AI-driven market landscape.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Generative Engine Optimization for Brand Visibility

    Generative Engine Optimization for Brand Visibility

    If your brand ranks in conventional search but disappears when a buyer asks an AI assistant for options, you do not have a simple traffic problem. You have a representation problem. The system may not understand what your company does, may not find enough evidence to mention it, or may describe it in a way that does not help the buyer choose.

    Generative Engine Optimization gives you a practical way to find and fix those gaps. The goal is not to make an AI repeat your marketing copy. It is to make your public evidence clear, consistent, extractable, and credible enough that your brand can be identified and represented accurately when it belongs in an answer.

    Measure the answer, not just the search position

    An analyst examines translucent answer panels surrounding a glowing sphere, with a blue object appearing clearly in some panels and faintly or not at all in others.

    Generative Engine Optimization, or GEO, improves the likelihood that a brand, product, service, or expert will be correctly understood and surfaced in AI-generated answers. It matters across ChatGPT, Gemini, Perplexity, and Claude, but it should not be treated as a replacement for SEO.

    SEO and GEO share much of the same foundation: accessible pages, clear information architecture, relevant content, reputable mentions, and technically sound publishing. The difference is the unit you inspect. Traditional rank tracking asks where a page appears for a query. GEO asks whether the generated answer includes your brand, understands it, places it in the right context, and supports the representation with an appropriate citation when citations are available.

    An AI answer is not a permanent rank. Its wording can change with the platform, prompt, session context, and time. That makes a single screenshot weak evidence. You need a repeatable observation process that reveals patterns across the questions your buyers actually ask.

    1. Build a prompt portfolio around decisions. Include category discovery, problem diagnosis, use cases, comparisons, constraints, alternatives, implementation questions, and branded fact checks. Use natural language and realistic context. A brand-name prompt only shows whether the system can retrieve a name it has already been given; it does not test discovery.
    2. Capture a baseline on each relevant platform. Save the exact prompt, complete answer, platform, date, visible citations, and any important session conditions. Do not reduce the result to a yes-or-no mention.
    3. Classify what happened. Record whether the brand was omitted, merely listed, described accurately, recommended for a suitable use case, confused with another entity, or attached to an unsupported claim.
    4. Inspect the cited evidence. Note which pages or third-party references support the answer. A citation to your homepage tells you something different from a citation to a detailed product page, comparison, case study, or independent profile.
    5. Repeat under comparable conditions. GEO measurement becomes useful when you can distinguish a recurring visibility gap from ordinary answer variation.

    Do not collapse these observations into one vague visibility score. A mention can be prominent but wrong. A citation can be present but point to an outdated page. A brand can appear in an answer without being connected to the need that matters commercially. Keep the underlying observations visible so your team knows what to repair.

    Turn each meaningful prompt into a query-to-evidence map. Put the buyer’s question on one side and the best page or external evidence capable of answering it on the other. If no suitable evidence exists, you have found a content gap. If the evidence exists but contradicts another page, you have found an entity or governance gap. If strong evidence exists but a competitor is consistently cited instead, you have found a discovery or authority gap.

    Make your brand unambiguous before producing more content

    Many visibility problems start below the content layer. The company name varies between profiles. A product page uses a new category label while an older page uses another. The homepage promises one audience, the About page names a second, and third-party listings preserve a description that no longer applies. Publishing more pages on top of those contradictions gives a generative system more material, but not more certainty.

    Create an internal brand fact sheet before you change markup or commission new copy. This is not a page written for ranking. It is the approved record your writers, developers, public-relations team, profile owners, and partners use to keep public information aligned.

    • The canonical brand and product names, including capitalization and legitimate abbreviations.
    • A plain-language description of what the company offers and the category in which it operates.
    • The audiences and use cases the offering genuinely serves.
    • Locations, availability, pricing model, compatibility, and other constraints only when they are stable and publicly verifiable.
    • The official website, contact routes, owned profiles, and public organizational relationships.
    • Claims that are approved for public use, along with the page or evidence that substantiates each claim.
    • Claims, labels, or product descriptions that are obsolete and need to be removed.

    Then assign every important fact a canonical public home. Your About page should establish organizational identity. Product and service pages should explain what is offered, who it is for, what it does, and where its limits are. Author or expert pages should show who is responsible for specialized content. Policy, support, and contact pages should answer the operational questions that help a reader verify the business.

    Use the same core facts across those pages without cloning whole paragraphs. Consistency means the facts agree; it does not mean every page must use identical prose. Each page still needs to answer the intent that brought the visitor there.

    Use JSON-LD as a consistency layer, not a secret channel

    Structured data can make explicit relationships easier for machines to parse, but it cannot rescue unclear or unsupported visible content. Treat JSON-LD as a machine-readable restatement of facts a visitor can verify on the page.

    • Choose the most specific type that truthfully matches the page, such as Organization for the business identity, Product or Service for the relevant offering, Article for editorial content, and BreadcrumbList for page hierarchy.
    • Keep names, canonical URLs, identifiers, images, authorship, publisher details, and dates consistent with the visible page.
    • Use sameAs to connect an entity to legitimate identity profiles, not to create a loose list of every URL that mentions the brand.
    • Mark up offers, reviews, ratings, availability, and other commercial properties only when the information is real, current, and visible to users.
    • Validate the markup after publishing and again when templates, plugins, product data, or site architecture change.

    Do not place stronger claims in schema than you are willing to show on the page. Hidden assertions produce a brittle identity layer and make maintenance harder. The safest rule is simple: visible content establishes the fact; structured data clarifies what the fact refers to.

    Internal links complete the picture. Link the brand, product, service, category, expert, and supporting evidence with descriptive anchors. This helps a visitor move from a broad claim to its proof and makes the relationship among those pages explicit. An isolated case study or technical explanation cannot do much representational work if nothing connects it to the relevant offering.

    Create evidence that can be extracted, checked, and cited

    Organized documents, specification blocks, and verification objects connect through glowing paths to a transparent prism that assembles a coherent blue object.

    Generative systems assemble answers from passages, entities, and relationships. A page can be comprehensive yet difficult to use if the answer is buried beneath a long preamble, key nouns are replaced by ambiguous pronouns, or every claim is wrapped in promotional language.

    For an important buyer question, give the answer a self-contained passage. Use a descriptive heading that states the question or decision. Follow it with a short direct answer, the conditions under which that answer holds, the evidence behind it, and the next detail a reader needs. This structure helps humans scan the page and reduces the amount of surrounding text needed to understand an extracted passage.

    For example, a heading such as “Does the platform support multi-location teams?” is more useful than “More flexibility.” The answer should name the platform and define what support means. If support depends on a plan, integration, location, configuration, or workflow, say so beside the claim. A broad promise separated from its qualification is easy to misrepresent.

    Build the pages your query-to-evidence map is missing

    • Category explanations define the problem, relevant terminology, suitable use cases, and important limitations without turning every sentence into a sales claim.
    • Product and service pages connect capabilities to concrete tasks, audiences, prerequisites, and constraints.
    • Comparison and alternatives pages explain meaningful differences, selection criteria, and cases where another approach may be a better fit. A fair boundary is more credible than declaring one option best for everyone.
    • Implementation content shows the sequence, dependencies, inputs, outputs, and failure points involved in getting a result.
    • Case studies and first-party evidence document what changed, in what context, how the result was measured, and what cannot be generalized. Do not turn an isolated outcome into a universal benchmark.
    • Research, documentation, and original tools give other publishers a reason to cite your domain rather than repeat a generic definition.

    The strongest GEO content is not content that sounds as if an AI wrote it. It is content that contributes something identifiable: a precise definition, a transparent method, an original dataset, a documented workflow, a useful decision rule, a clear limitation, or accountable expertise. Generic text may cover a topic, but it gives a system little reason to associate that topic with your brand.

    Apply a citability check before publication

    • Can a passage stand on its own without “it,” “this,” or “they” becoming ambiguous?
    • Does each material claim name the product, audience, condition, and limitation to which it applies?
    • Can the reader distinguish a fact, an interpretation, a recommendation, and a promotional claim?
    • Is evidence located close to the claim it supports?
    • Are the author, publisher, relevant dates, and update responsibility clear?
    • Does one canonical page own the fact, or do several pages compete with different versions?
    • Can crawlers access the useful content without relying on an interaction that hides it?
    • Do the title, headings, internal links, and structured data describe the same subject?

    When a competitor is cited and you are not, resist copying its wording. Identify the job its cited page performs. It may define the category more clearly, answer the constraint directly, publish evidence you do not have, or receive corroboration from relevant third parties. Build the missing evidence for your audience instead of producing a disguised duplicate.

    Run GEO as an operating cycle, not a publishing campaign

    Brand visibility in AI answers crosses SEO, content, product marketing, public relations, analytics, and technical implementation. The work stalls when each team owns a fragment but no one owns the query-to-evidence map. Give one person responsibility for maintaining the prompt portfolio, routing gaps, and verifying whether completed changes improved representation.

    1. Audit. Capture the current answers for commercially relevant and reputationally important prompts. Separate omission, inaccuracy, weak context, poor citation, and entity confusion.
    2. Repair. Correct contradictory facts, obsolete descriptions, broken canonical relationships, inaccessible evidence, weak internal links, and structured data that disagrees with visible content.
    3. Expand. Create the missing decision content and supporting evidence revealed by the prompt audit. Prioritize pages that answer real buyer questions rather than producing broad topic coverage for its own sake.
    4. Corroborate. Keep legitimate business profiles consistent and earn relevant third-party coverage, references, partnerships, or citations. External mentions should confirm a real claim; placement alone is not useful evidence.
    5. Verify. Run the same prompts again under comparable conditions. Record what changed in the answer, brand context, accuracy, and citations. Preserve misses as evidence rather than reporting only favorable outputs.

    Your working dashboard should retain the prompt, intent, platform, observation date, brand status, description accuracy, cited URLs, competing entities, evidence gap, assigned action, and verification status. That record lets an editor see which page is missing, a developer see which identity signal conflicts, and a public-relations team see which claims lack independent corroboration.

    Prioritize correctness before prominence. A confident but inaccurate description can create more risk than an omission. Correct the canonical public facts, remove contradictions, and make the authoritative explanation easy to find. You cannot directly edit a model’s answer, and no optimization can guarantee inclusion, but you can improve the evidence available to systems and people evaluating your brand.

    Next, prioritize prompts closest to a meaningful decision and gaps you can substantively resolve. A page should not claim an unsupported advantage merely because a prompt asks for the best provider. If you lack the evidence required to make the claim, the right action is to develop the evidence or narrow the claim, not optimize the wording.

    Key takeaways

    • Measure whether AI answers include, understand, contextualize, and accurately support your brand; a mention count alone hides the most important failures.
    • Resolve inconsistent brand facts before adding more content. More pages amplify contradictions as readily as they amplify clarity.
    • Make important answers self-contained, qualified, and close to their evidence so they can be extracted without losing meaning.
    • Use JSON-LD to restate visible facts and relationships, never to introduce claims the page does not support.
    • Map each valuable buyer prompt to the best available evidence, then use omissions and weak citations to set the content roadmap.
    • Treat GEO as a recurring audit, repair, expansion, corroboration, and verification cycle rather than a one-time launch.

    Start with the decisions that matter most to your buyer. Capture how the major AI platforms answer those questions, choose the clearest representation failure, and repair the public evidence behind it. That first closed loop is more valuable than a large batch of speculative content because it gives your next GEO decision a visible reason and a result you can check.

    References


  • How Publishers Should Respond to a Suspected False DMCA Claim

    How Publishers Should Respond to a Suspected False DMCA Claim

    If investigative reporting disappears from Google after a copyright complaint, treat it as a two-track incident. You need to preserve the record showing how the work was created while identifying the precise route for restoring lawful visibility. Rewriting the page, replacing files, or accusing the claimant in public before you do either can make the dispute harder to untangle.

    The risk is not hypothetical. In one documented dispute, a March 27 notice accused Search Engine Land of copying text verbatim and using proprietary images, after which Google removed the affected URL from search results. Clickout Media’s alleged transformation of news sites into AI-driven gambling platforms was the investigation’s subject. The important operational lesson is that a copyright allegation can interrupt distribution before the underlying merits have been publicly resolved.

    Confirm what was removed before arguing about why

    A search delisting, hosting takedown, CDN block, CMS suspension, and deleted page are different failures. They affect different surfaces and require different remedies. Do not describe the reporting as “taken down” until you know which system stopped serving or surfacing it.

    1. Preserve the notice exactly as received. Save the message body, attachments, raw email headers, claimant details, alleged copyrighted work, disputed URL, case number, and receipt time. Export the platform dashboard entry as well as taking screenshots.
    2. Test the direct URL. Record whether it loads, redirects, returns an error, or displays a platform warning. Save the response code, page source, screenshot, and test time. A page that remains directly accessible but is absent from search has a different recovery path from one removed by its host.
    3. Check each discovery surface separately. Inspect Google results, Google Search Console messages, the XML sitemap, internal links, news or topic hubs, syndication copies, and any platform-specific index. Search results vary, so the absence of a result in one manual query is not enough by itself to establish a formal removal.
    4. Identify the decision-maker. Determine whether the action came from the search engine, hosting provider, CDN, registrar, CMS vendor, social platform, or another intermediary. Send a response to the organization that can actually reverse the action.
    5. Freeze mutable evidence. Export the published page, CMS revisions, drafts, source notes, media files, metadata, and rights records before changing anything. Make a read-only archive and record checksums for important files so later changes can be detected.

    Create one incident record with the disputed URL, notice identifier, affected services, first observed time, current page status, response deadline, internal owner, legal owner, and every action taken. This prevents editorial, SEO, engineering, and legal teams from creating conflicting versions of events.

    Do not evade a removal by immediately cloning the page to a new URL. That can multiply the disputed URLs, confuse canonical signals, complicate the evidence trail, and create additional legal exposure. Preserve first, then decide what may lawfully remain available with qualified counsel.

    Build an allegation-by-allegation evidence packet

    Original files, notes, photographs, metadata panels, and archival sleeves are organized into paired evidence groups on a worktable.

    A notice is not proven false merely because its timing looks suspicious or its effect is damaging. Treat “false,” “mistaken,” “unsupported,” and “abusive” as different conclusions. You need testable contradictions: the cited words do not appear on the page, the image was licensed, the claimant has not established ownership, the chronology is impossible, or the notice identifies the wrong URL.

    Question to testEvidence to assembleWhat the response should show
    Was text copied verbatim?Draft history, reporter notes, source links, timestamps, and a side-by-side comparison of the exact passagesWhich words are actually shared, where they appear, and whether the notice accurately describes the overlap
    Was an image used without permission?Original file, creator identity, license or assignment, receipt, attribution record, metadata, and the terms captured when the asset was obtainedWhich image is disputed and the specific basis on which it was published
    Does the claimant control the asserted rights?The work identified in the notice, its URL and publication date, the claimant’s stated relationship to it, and any ownership records suppliedWhether the notice connects the claimant to the particular material at issue
    What action actually occurred?Direct-URL tests, platform messages, Search Console records, screenshots, response codes, and timestampsWhich service restricted the page, when it happened, and whether the restriction is still active
    What changed after publication?CMS revisions, media replacements, redirects, correction notes, deployment logs, and editor approvalsA clean chronology that distinguishes the original publication from later edits

    Keep the evidence factual and compact. A platform reviewer should not have to infer your rebuttal from a folder of unrelated screenshots. Number each allegation, quote only the minimum text needed to identify it, attach the corresponding proof, and state the requested remedy for that allegation.

    Preserve unfavorable evidence too. If an image license is ambiguous or a passage is closer than expected, hiding that weakness will not improve the legal position. Flag it for counsel and separate it from allegations you can disprove cleanly. A mixed notice may contain an unsupported claim alongside a genuine rights problem.

    Choose the response path with counsel, not by reflex

    The fastest-looking option is not always the safest one. An informal correction request, platform appeal, asset replacement, negotiated resolution, and formal counter-notice carry different consequences. The right route depends on who acted, what the notice alleges, whether the material remains online, and what your evidence establishes.

    Start with a precise administrative response when appropriate

    If the platform offers an appeal or reinstatement process, answer the notice rather than the suspected motive behind it. A useful submission contains the case identifier, exact URL, current status, a numbered response to every allegation, supporting records, the requested action, and a contact authorized to handle follow-up.

    Avoid a long defense of the investigation’s public importance as a substitute for copyright evidence. Public-interest reporting may explain the stakes, but it does not by itself resolve who owns an image or whether wording was copied. Lead with the evidence that answers the claim.

    Treat a counter-notice as a legal act

    A formal counter-notice is not an ordinary customer-support reply. Depending on the process, it may require legal declarations, identification details, and consent connected to jurisdiction. An inaccurate submission can create exposure beyond the original search problem. Have qualified copyright counsel review the notice, the evidence, the governing procedure, and the final language before filing. If the publisher, claimant, or platform is outside the United States, counsel should also confirm which law and process actually apply.

    If you discover a genuine asset problem, preserve the original state before removing or replacing the asset. Record what changed, when, why, and who approved it. Let counsel decide whether any accompanying statement could be interpreted as an admission.

    Keep the public statement narrower than the evidence

    You can accurately say that a notice was received, a URL was affected, the claim is disputed, and a review or appeal is underway when those facts are documented. Do not label the claimant fraudulent, corrupt, or criminal merely because the notice appears weak. Those are separate allegations with their own evidentiary and legal risks.

    Coordinate the public statement with the formal response. A social post written in anger can contradict an appeal, disclose material intended for counsel, or lock the publisher into a conclusion before the evidence review is complete.

    Protect search and AI visibility without compromising the dispute

    An editor and counsel stand beside preserved files as parallel paths lead toward a legal process and an abstract online discovery network.

    Availability and discoverability are separate. A page can remain live for direct visitors while losing search distribution, which can also reduce the chance that search-connected AI systems retrieve or cite it. Recovery work therefore needs legal, technical, editorial, and communications owners working from the same incident record.

    1. Keep the established URL stable when publication remains lawful. Avoid unnecessary slug changes, redirect chains, or duplicate copies. Continue linking to the URL from relevant author, topic, and investigation pages unless counsel or the serving platform requires otherwise.
    2. Record every post-notice change. If wording, images, metadata, canonicals, redirects, or access controls change, preserve the previous state and log the reason. Silent edits blur the chronology that reviewers and counsel may need.
    3. Make authorship and publication data explicit. Accurate Article or NewsArticle structured data can identify the author, publisher, publication date, modification date, headline, and canonical page for machines. Schema helps systems interpret those public assertions; it does not prove copyright ownership, invalidate a notice, or guarantee restoration in search or an AI answer.
    4. Use only lawful distribution paths. Keep newsletters, feeds, archives, and authorized syndication copies functioning where rights and contracts permit. Do not create mirrors solely to route around a restriction.
    5. Monitor the actual failure mode. Track whether the direct page loads, whether the platform case changes, whether Search Console reports a new status, and whether the canonical URL returns to relevant results. A ranking fluctuation is not the same as reinstatement.

    Do not promise that structured data, internal links, or republication will force a frontier model to cite the investigation. Those measures can improve machine-readable provenance and create legitimate discovery paths, but none overrides a platform’s legal process.

    Make the next incident easier to defend

    The strongest preventive control is not a disclaimer. It is a publication record that can be assembled before a notice arrives. For investigative work, retain source notes, timestamped drafts, editorial approvals, original media, licenses, attribution decisions, screenshots of asset terms, correction history, and deployment records under a defined retention policy.

    • Create a dedicated intake address for copyright notices and route it to editorial, legal, SEO, and engineering owners.
    • Use a standard incident template containing the notice ID, claimant, asserted work, disputed material, affected URL, platform, deadline, evidence owner, legal status, search status, and approved public language.
    • Require provenance records for every non-original image, chart, document excerpt, and embedded media item before publication.
    • Keep CMS revision history and media replacements attributable to named users rather than relying on shared accounts.
    • Prepare platform-specific access instructions so the person handling the incident can reach hosting, CDN, Search Console, analytics, and syndication records without waiting for credentials.

    These controls will not prevent someone from filing a questionable notice. They reduce the time spent reconstructing authorship, rights, and platform status after the reporting has already lost distribution.

    Key takeaways

    • Confirm whether the page was deleted, blocked, deindexed, or merely absent from a particular query before choosing a remedy.
    • Preserve the notice, published page, drafts, source records, media provenance, platform messages, and technical status before making changes.
    • Rebut each allegation with matched evidence; suspicious timing alone does not establish that a DMCA claim is false.
    • Have qualified copyright counsel review any formal counter-notice or response that could create legal exposure.
    • Keep lawful URLs and provenance signals stable, but do not clone pages or use schema as a way to evade a platform restriction.

    Your first objective is a clean factual record, not the loudest rebuttal. Once that record exists, counsel can choose the legal route, the platform team can request the correct remedy, and the SEO team can restore discoverability without creating a second problem.

    References


  • Unlock Reddit Pro: Boost Engagement with New Features

    Unlock Reddit Pro: Boost Engagement with New Features

    I’ve got some exciting news to share—Reddit has just opened up its Pro publishing tools to all publishers! No more waiting lists. Now, anyone can dive into the public beta and ramp up their content distribution and engagement strategies, all for free.

    Why this matters to us. Reddit Pro offers me a centralized hub to monitor where my content spreads, simplifying my posting process, and helping me pinpoint the right communities to engage with. It’s transforming Reddit from being a place of manual posting to a well-organized distribution channel.

    Here’s the scoop. I can now easily sign up for Reddit Pro, verify my domain (usually within three business days), and jump into the Links tab. With Reddit Pro, I can:

    • Keep track of where my content is shared all over Reddit.
    • Quickly auto-import articles through RSS, speeding up my posting.
    • Receive AI-powered tips on the most relevant communities to connect with.

    Reddit has also rolled out some features based on early adopter feedback:

    • Community snapshots that display rules, stats, and top discussions.
    • Community notes that let me track strategy and context over time.

    By the numbers. Back in 2025, Reddit revealed there were over 55 billion views of publisher-related discussions. Since some publishers started testing in September, they saw:

    • A 46% uptick in median post views.
    • An almost doubled amount of profile views.
    • A 48% climb in median comments.

    What else to look forward to. Reddit is also expanding profile flairs to every Pro user. This means I can organize posts on my profile, making it easier for users to browse my coverage and get involved with stories.

    Reddit’s official announcement: I recommend checking out their post on Helping publishers thrive on Reddit for more insights.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • TurboQuant Search Acceleration: An SEO and GEO Action Plan

    TurboQuant Search Acceleration: An SEO and GEO Action Plan

    You may be wondering whether TurboQuant requires an immediate SEO response. The short answer is no: it is not an announced ranking update, and there is no disclosed evidence that Google Search is using it in production.

    It still matters. TurboQuant targets a constraint that shapes semantic search, retrieval-augmented generation, and AI answer systems: how much meaning a system can search within a limited memory and response-time budget. If that constraint loosens, more content can become practical to retrieve. Your job is to make sure your content remains understandable, competitive, and worth citing when the candidate pool grows.

    TurboQuant changes retrieval economics, not your ranking brief

    Semantic search systems commonly convert documents, passages, products, images, or other objects into vectors. A vector is a numerical representation that places related meanings near one another. When someone asks a question, the system can retrieve nearby vectors even when the wording in the query does not exactly match the wording in the content.

    The difficulty is scale. Detailed vectors consume memory, moving them through processors takes time, and building or updating large searchable indexes can be expensive. A system may therefore search only a restricted candidate set before another model ranks, filters, or summarizes the results.

    TurboQuant addresses that infrastructure problem by compressing vectors while preserving a close approximation of their original relationships. It mathematically rotates the data to make it easier to pack efficiently, then carries a 1-bit error-correction signal intended to reduce mistakes introduced by compression. Google also associates the approach with substantially lower memory requirements and nearly zero indexing time.

    That is important, but it is not the same as a new ranking factor. TurboQuant does not tell a search engine which page is trustworthy, which claim is current, which source deserves a citation, or which answer best satisfies a user. It makes one stage of the pipeline more efficient: locating semantically similar candidates.

    Keep the distinction clear in planning meetings. Retrieval asks, “Which items might be relevant?” Ranking and answer generation ask, “Which of those items should be used, in what order, and for what purpose?” Faster retrieval can affect the first decision without replacing the others.

    A larger candidate pool changes what can be discovered

    Scanning beams illuminate relevant capsules and document-like tiles across a vast abstract archive, with selected items grouped in the foreground.

    A search or AI system operates inside practical limits. It has finite memory, compute capacity, and time to produce a response. If vectors become cheaper to store and faster to search, the system could examine a broader collection of candidates within those limits. That could include more documents, more passages within each document, or more specialized material that would otherwise sit outside an economical retrieval set.

    This does not guarantee that AI answers will cite more websites. A larger candidate pool can increase opportunity and competition at the same time. Your page may become easier to retrieve, but so may a more precise product manual, a better-supported explanation, or a specialist page that previously sat too deep in the corpus.

    The likely strategic shift is from winning inside a narrow set of obvious pages to surviving comparison against a deeper set of semantically related passages. Thin content becomes more exposed in that environment. Repeating the target phrase does little when the system can find pages that answer the underlying question with clearer entities, stronger evidence, and better-qualified claims.

    Nearly zero indexing time could also make rapid ingestion more practical for systems built around TurboQuant. Do not turn that possibility into a claim about Google Search freshness. Crawling, rendering, canonicalization, quality assessment, and index-selection policies remain separate processes. Faster vector indexing cannot make an uncrawled or rejected page searchable.

    The same logic applies outside public search. An organization operating a large retrieval-augmented generation system could use aggressive vector compression to reduce memory pressure or update a knowledge index more quickly. If you own that system, TurboQuant is an engineering option to evaluate. If you publish content that such systems may ingest, the more durable task is to improve the material being represented by those vectors.

    Optimize the passage before you optimize the embedding

    Disordered translucent fragments are reorganized into clear modular content blocks before becoming compact glowing vectors.

    You usually cannot control which embedding model, quantization method, retrieval threshold, reranker, or answer model a third-party search system uses. You can control whether a passage contains enough information to be correctly interpreted after it is separated from the rest of the page.

    Start with answer-bearing passages. A useful passage names the subject, resolves the question, and carries the qualification that prevents the answer from becoming misleading. Avoid openings that rely on nearby headings or pronouns to supply all the context. “It depends on the plan” is fragile. “Indexing frequency depends on the crawler, the site’s change rate, and whether the URL remains eligible for indexing” retains meaning when retrieved alone.

    Do not force every paragraph into a rigid template. The goal is semantic completeness, not robotic prose. Use the following checks where a passage contains a definition, recommendation, comparison, process, limitation, or factual answer:

    • Name the entity. Use the full product, organization, method, or standard name before relying on shorthand. This reduces ambiguity between similarly named entities.
    • State the relationship. Make it explicit whether the entity creates, supports, replaces, depends on, conflicts with, or applies to something else.
    • Carry the qualifier. Keep version, platform, audience, condition, and scope close to the claim they limit.
    • Put evidence beside the claim. A citation attached to a vague paragraph is less useful than a link on the specific statement it supports.
    • Separate fact from inference. Use direct language for documented behavior and conditional language for plausible consequences. TurboQuant could support broader retrieval; that does not establish its use in Google Search.

    Next, cover the relationships around the central entity. A page about TurboQuant should not merely repeat that it accelerates vector search. A useful treatment connects compression to memory use, index construction, similarity accuracy, candidate retrieval, reranking, and downstream answer generation. Those relationships help a system match the page to different formulations of the same underlying problem.

    This is semantic breadth, not permission to inflate word count. Add a section only when it resolves a real adjacent question. Remove a section when it paraphrases a claim already made. Efficient retrieval can expose comprehensive content, but it can also expose padding.

    Make structured data support the same meaning

    JSON-LD and schema markup can reinforce entity identity and relationships, but they do not rescue unclear visible content. Treat structured data as a machine-readable restatement of the page, not a hidden layer where you make claims the reader cannot see.

    For each important page, compare the visible content with its structured data. The page title, main entity, author or organization, publication information, and any explicitly marked questions or steps should agree. If the markup identifies one subject while the body drifts into several loosely related topics, compression is not the problem. The underlying document is ambiguous.

    Internal links deserve the same discipline. Use anchor text that describes the destination’s role rather than generic commands such as “learn more.” Link from a broad concept to the page that resolves its important subtopic, and link back where the relationship helps the reader. This creates navigable context for crawlers and people without pretending that internal links directly control vector proximity.

    Technical eligibility remains the floor. Confirm that the canonical URL is crawlable, the primary answer appears in rendered HTML, internal links reach the page, and structured data matches the visible material. A brilliantly written passage cannot enter a retrieval pipeline that never receives or accepts the page.

    Run a retrieval-readiness audit you can repeat

    Do not create a TurboQuant-specific score. You have no public implementation details that would make such a score credible. Audit the properties that remain useful across embedding models and compression methods.

    1. Select a representative page from each important topic cluster. Include the pages that answer commercial, informational, troubleshooting, and comparison questions rather than auditing only your highest-traffic URLs.
    2. Build query families around user intent. For each page, write the direct question, a paraphrase, a problem-first version, and a version that names a competing approach. This reveals whether the page answers the concept or merely repeats one keyword pattern.
    3. Locate the passage that should satisfy each query. If you cannot point to a self-contained answer, rewrite the relevant section. Do not assume the title or surrounding page will repair an incomplete paragraph.
    4. Check entities and qualifiers. Mark unclear pronouns, unexplained abbreviations, missing versions, unsupported superlatives, and conditions placed far away from the claims they govern.
    5. Verify evidence and provenance. Link important claims to their originating authority when available. Remove assertions whose confidence exceeds the evidence.
    6. Compare visible content, metadata, and JSON-LD. Resolve conflicts in names, dates, page purpose, authorship, and entity type. Consistency makes the page easier to interpret; markup volume does not.
    7. Record answer-surface outcomes. For the query families you monitor, note whether your URL appeared, whether it was cited, which passage was used, and which alternative sources won. Ordinary rank position alone cannot show how an AI answer assembled its response.

    When a competing page is selected, diagnose the difference at the passage level. Ask whether it gave a more direct answer, named the relevant entity more clearly, carried a necessary qualification, supplied stronger evidence, or addressed an adjacent intent you omitted. Those observations produce useful editorial work. Guessing at an undisclosed quantization configuration does not.

    Keep infrastructure tests separate from content tests if you operate your own vector search system. Engineering teams can compare memory use, indexing cost, latency, and retrieval quality under compression. Editorial teams should evaluate answer completeness, ambiguity, evidence, and citation suitability. Combining both into one vague “AI optimization” metric makes it impossible to tell which layer improved.

    Key takeaways

    • TurboQuant compresses vectors to reduce memory pressure and accelerate similarity search, with a 1-bit signal designed to correct small compression errors.
    • It is retrieval infrastructure, not a disclosed Google Search ranking factor or confirmed production deployment.
    • Cheaper retrieval could let an AI system search a broader candidate set, but broader access also exposes your content to more competitors.
    • Your durable advantage is a crawlable page with self-contained passages, unambiguous entities, nearby qualifications, and evidence attached to specific claims.
    • Use JSON-LD to reinforce visible meaning. Do not use it to compensate for vague writing or to introduce claims absent from the page.
    • Measure citation and passage selection across query families, not just traditional rankings for one exact keyword.

    Your next move is modest: choose one important topic cluster and run the retrieval-readiness audit before rewriting the entire site. Fix the places where meaning breaks when a paragraph stands alone. That work remains valuable whether TurboQuant reaches public search, stays inside other AI systems, or inspires a different compression method.

    References


  • Paid Media Optimization for Long Sales Cycles: A Practical System

    Paid Media Optimization for Long Sales Cycles: A Practical System

    Your paid campaigns can generate leads this week while the resulting revenue takes months to appear. That delay creates an uncomfortable decision: should the ad platform optimize for the form submission it can see quickly, or for the closed sale that reflects the outcome you ultimately care about?

    The answer is not simply “optimize further down the funnel.” In a human-led sales process, a closed deal measures more than media quality. It also reflects rep skill, follow-up speed, capacity, product availability, approval delays, and seasonal behavior. You need a bidding signal that rewards valuable demand without teaching the platform to react to every operational swing.

    Key takeaways for long-cycle campaigns

    • Use the deepest conversion event that is frequent, timely, and operationally stable. A closed sale is not automatically the best bidding signal.
    • For many long sales cycles, the practical optimization boundary is a valued lead at submission: not every form fill receives the same value, but the value is assigned before sales execution changes the outcome.
    • Estimate lead value from conversion probability and typical deal size using information available when the inquiry arrives.
    • Keep downstream revenue in your measurement system even when it is not the primary bidding input. You need it to calibrate lead values and judge business performance.
    • Diagnose media quality and sales operations separately. Stable lead volume and predicted value alongside a falling close rate is not sufficient evidence that targeting has failed.

    Why a closed sale can be the wrong bidding signal

    Identical lead spheres move through different sales-process channels, where workload, delays, approvals, inventory, and other obstacles change which ones reach the final outcome.

    An ad platform sees the conversion outcome, but it does not understand your organization. If a strong sales rep closes more leads than a new rep, the platform can observe the difference in recorded sales. It cannot inherently know that rep assignment caused it.

    Imagine that the same campaigns, keywords, landing pages, and lead profiles continue running while your most effective closer takes leave. A less experienced colleague receives the leads, follow-up slows, and the close rate falls. An automated system optimizing for sales may treat the decline as evidence that those clicks or audiences became less valuable. It can then reduce bids, shift budget, or suppress targeting that was still generating suitable prospects.

    Rep composition is only one source of noise. Close rates can change when workloads increase, response times stretch from days into a week, a competitive product is withdrawn, an approval stalls, or vacation coverage leaves inquiries untouched. Leads from other channels can also consume the sales team’s capacity even though nothing changed inside the paid account.

    Calendar behavior can make the distortion severe. In one observed financial-services pattern, lead-to-sale conversion around the third week of December rose by as much as 150% compared with normal weeks, then fell sharply during the holiday week. The leads and placements had not suddenly become much better and then much worse. Sales urgency, customer availability, bonus incentives, and leave schedules had changed.

    This is the core diagnostic distinction: a sale is a business outcome, but it is not always a clean media-quality label. When you ask an algorithm to bid on it, you are asking the platform to optimize all the forces embedded in that outcome, including forces the campaign cannot control.

    Set the optimization boundary at a stable quality signal

    Your optimization boundary should sit at the latest funnel event that satisfies three conditions: the event happens often enough for automation to learn from it, it arrives soon enough to guide current bidding, and its definition remains stable enough to mean the same thing from one period to the next.

    Direct sales or revenue optimization can be appropriate when conversion volume is sufficient, the reporting delay is short, and the sales process is stable. Long, low-volume, human-dependent sales cycles frequently fail one or more of those tests. In that situation, a quality-adjusted lead is usually more dependable than either a raw form fill or a closed deal.

    • A raw lead count is too shallow when inquiries have materially different probabilities of conversion or deal sizes.
    • A closed sale is too deep when it is rare, delayed, or heavily shaped by sales execution and operational capacity.
    • A valued lead at submission is the middle path when you can estimate commercial potential from information already available at the point of inquiry.

    The phrase “at submission” matters. If you assign the value after seeing which rep handled the lead, whether the buyer answered a follow-up call, or how the opportunity progressed, you have allowed downstream execution back into the bidding label. The model should use attributes known when the lead enters the funnel.

    The optimization boundary is not the reporting boundary. Continue importing final status and realized revenue. Use those outcomes to evaluate the business, recalibrate the lead-value model, and identify sales-process problems. You are separating two jobs: the bidding system needs a timely and stable signal, while management reporting needs the complete commercial outcome.

    Build a lead-value model from matured historical cohorts

    Lead tokens pass through a long time tunnel before matured groups are sorted into illuminated value categories, with a separate path continuing toward eventual revenue.

    A useful lead-value model estimates expected revenue rather than merely labeling a lead “good” or “bad.” Start with historical inquiries that have had enough time to reach a final outcome. A full year is preferable because it captures more operating conditions and seasonality, although six months can be sufficient when that is all the reliable history you have.

    1. Select matured cohorts. Group leads by the date they entered the funnel, then include cohorts old enough that most opportunities have reached a meaningful final status. Mixing fresh, unresolved leads with completed cohorts will make recent traffic appear artificially weak.
    2. Freeze the information available at inquiry. Retain fields the campaign could reasonably influence or attract: requested product, project scope, stated timing, loan characteristics, company size, industry, and other submission-time attributes relevant to your business.
    3. Calculate conversion probability by meaningful segment. Determine which inquiry-time characteristics correspond with different eventual conversion rates. Keep the segments understandable enough that you can explain why a lead received its value.
    4. Measure typical deal value for each segment. A segment that closes frequently is not necessarily the most valuable if its average commercial outcome is small. Conversely, a lower-probability segment may deserve attention when successful deals are much larger.
    5. Assign expected revenue. The basic logic is conversion probability multiplied by typical deal value. The result is a monetary estimate that a value-based bidding system can compare across leads.
    6. Reconcile predictions with realized revenue. Add the predicted values for a matured acquisition cohort and compare that total with the revenue eventually produced by the same cohort. Large or persistent gaps mean the probabilities, deal values, segments, or data quality need adjustment.
    7. Version and revisit the model. Preserve the value assigned at submission and record which model version produced it. Reassess the model quarterly so changes in campaign mix, products, buyer behavior, and operations do not leave old assumptions running indefinitely.

    The most useful segmentation variables depend on the transaction. Financial-services leads may differ by loan value or terms. B2B inquiries may differ by company size or industry. Construction opportunities may differ by scope and immediacy. Choose fields that were genuinely known at inquiry and have a defensible relationship with conversion probability or deal size.

    A practical framework might assign expected values such as $850 to a high-probability lead, $420 to a middle tier, and $120 to a lower-probability lead. Those figures are examples, not benchmarks. Copying them would make the model arbitrary; your values must come from your own conversion rates and deal economics.

    Do not confuse an expected-revenue value with a conventional lead score. A score of 90 may rank above a score of 40, but it does not tell a bidding system whether the first lead is twice as valuable, ten times as valuable, or only marginally better. Monetary values express the size of the difference and allow value-based bidding to make an economically meaningful tradeoff.

    Guard against data leakage as you build the model. Opportunity stage, rep assessment, response behavior, and later qualification calls may predict sales extremely well, but they were not known when the ad produced the inquiry. Using them to label historical leads can create a model that looks accurate in analysis but cannot assign equivalent values consistently at submission.

    Feed values into bidding without losing revenue accountability

    Once the values reconcile reasonably with matured revenue, configure the lead conversion to send its expected value with the event. Value-based bidding, including Google Ads target return on ad spend, can then pursue the mix of inquiries with the highest predicted commercial value rather than the largest number of identical form fills.

    Treat the implementation as a measurement change before treating it as a bidding change. First log the dynamic values while the existing strategy remains in place. Confirm that each valid lead is counted once, the correct value reaches the correct conversion action, and the platform’s aggregate value matches your lead system for the same inquiry dates. Only then should you let a value-based strategy act on the signal.

    Keep a compact acquisition record for every lead. At minimum, preserve the lead identifier, inquiry timestamp, paid-media attribution, value assigned at submission, model version, rep assignment, first-response timing, final status, and realized revenue. This lets you distinguish what the model knew from what happened after the handoff.

    Evaluate performance through two related views:

    • Predicted return compares total expected lead value with the spend that produced those leads. It is available quickly enough to guide campaign management.
    • Realized return compares eventual revenue with spend for the same acquisition cohort. It arrives later but tells you whether the model and the wider commercial process delivered what the early signal implied.

    Keep the cohort alignment intact. Revenue closed this month may have come from leads acquired months ago, so comparing it with this month’s spend can produce a convincing but false trend. Join eventual revenue back to the date and campaign that generated the inquiry. That makes the lag explicit and prevents old pipeline from being credited to current media.

    Roll the bidding change into a controlled part of the account rather than changing every campaign at once. Watch lead counts, predicted value, spend, and the distribution of value tiers. As cohorts mature, compare their predicted totals with realized revenue. A strategy that raises platform-reported value but repeatedly produces less realized revenue is exposing a calibration or tracking problem, not proving business growth.

    Diagnose a performance drop before changing the media

    When sales fall, resist the reflex to rewrite ads or cut audiences immediately. Walk through the funnel in causal order. The goal is to locate the first point where performance changed.

    1. Check inquiry volume. Did the number of valid paid leads change, or did only closed sales change?
    2. Check predicted lead value. Did the mix move toward lower-value tiers even if total lead volume remained stable?
    3. Check media inputs. Look for meaningful changes in targeting, search terms, audience composition, placements, creative, landing-page behavior, budget, or tracking.
    4. Check routing and response time. Determine whether leads reached the right people and whether follow-up slowed.
    5. Check staffing and capacity. Review rep assignment, leave, onboarding, workload, and competing lead sources.
    6. Check the commercial offer. Identify withdrawn products, changed eligibility, approval delays, pricing constraints, or other conditions that made the same lead harder to close.
    7. Check calendar effects. Separate customer availability and sales-team urgency from changes in demand quality.
    8. Change the layer that failed. Adjust campaigns when the deterioration begins in traffic or predicted lead value. Address operations when the early media signal is stable but handoff or close performance worsens.

    This sequence gives you a cleaner interpretation. If lead volume and predicted value remain stable while response times rise and close rates fall, the evidence points downstream. If response times and sales coverage remain stable while the account produces a weaker value mix, the media deserves scrutiny. If both change, treat them as separate problems instead of asking one campaign adjustment to solve both.

    Your first move should be an export of matured lead cohorts, not another bid adjustment. Identify the inquiry-time attributes that separate conversion probability and deal size, assign expected revenue, and reconcile the total against actual revenue. Once that model holds together, use it as the bidding signal and keep closed sales as the accountability signal. That division gives automation something it can learn from without letting every staffing or operational change rewrite your media strategy.

    References