Author: shivamcrushpressai

  • Google March 2026 Core Update: Diagnosis and Recovery Plan

    Google March 2026 Core Update: Diagnosis and Recovery Plan

    Your organic traffic moved during March 2026, and the tempting response is to rewrite every page that lost clicks. Resist that impulse. Google’s first core update of 2026 arrived close to separate spam and Discover changes, so a simple month-over-month chart cannot tell you what happened.

    Your first job is attribution: isolate the affected search surface, query set, page group, and shared weakness. Then change only what the evidence supports. This protects strong pages from panic edits and gives you a credible way to judge whether the work helps.

    Key takeaways

    • Google said the March 2026 core update could take up to two weeks to roll out. Treat movement inside that window as provisional rather than a final verdict.
    • Do not attribute every March change to the core update. A March spam update, a February Discover update, your own site releases, tracking problems, and changing demand can produce different patterns.
    • Diagnose at the level of search surface, query cluster, page group, and template. A sitewide traffic total hides the pattern you need to fix.
    • Audit whether losing pages satisfy the searcher’s task more clearly and completely than competing results. Cosmetic rewrites and extra keywords are not a recovery strategy.
    • There is no universal or immediate repair. Improvements can appear gradually, including after later core updates, so preserve evidence and measure each coherent batch of changes.

    Treat March as an attribution problem, not a verdict

    A core update is a broad reassessment of how Google’s systems surface useful results across many sites and searches. Google characterized this release as a regular update focused on relevant and satisfying content. A ranking loss does not, by itself, prove that a page violated a rule, received a manual penalty, or needs to be deleted.

    The surrounding timing matters. The core update followed a March 2026 spam update and a February 2026 Discover update. Those events are not interchangeable. A change confined to Discover should not automatically become a core-update content project. A Web Search decline should not be blamed on Discover. A sitewide drop across every acquisition channel may point to measurement, demand, or a site release rather than Google rankings.

    Build a timeline before opening your content editor. Mark the core, spam, and Discover milestones; Google’s confirmed rollout completion; and every meaningful change your team shipped nearby. Include migrations, URL changes, template releases, internal-link changes, tracking updates, large content batches, and availability or pricing changes that could affect demand. The purpose is not to choose a convenient explanation. It is to keep plausible causes separate long enough to test them.

    Use comparable reporting periods on either side of the event. Match the length and weekday mix, and note seasonal or campaign-driven demand. If a comparison period overlaps the rollout, label the result provisional. For historical analysis, anchor the post-update period after Google’s confirmed completion marker rather than assuming the announcement date was the moment every ranking changed.

    Build a page-and-query evidence map
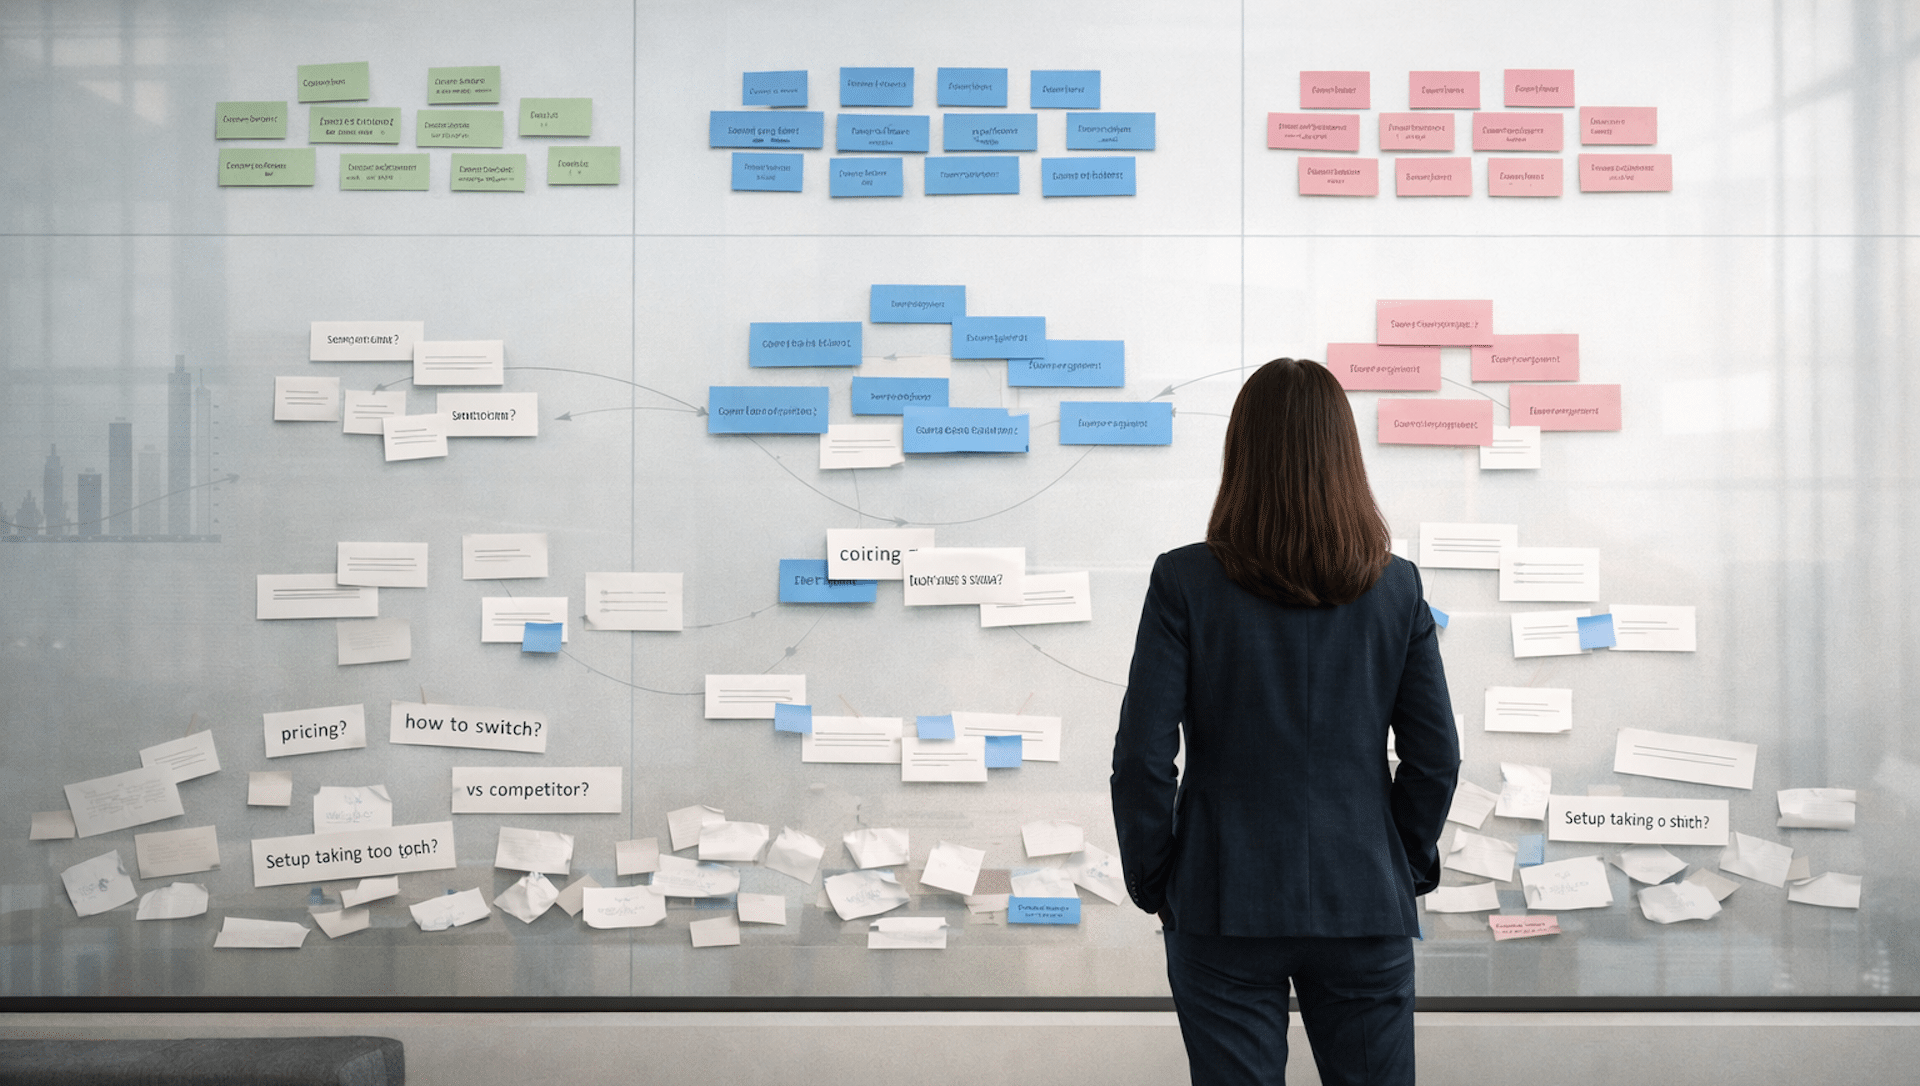
    Blank web page cards and search tokens are grouped and connected with colored threads on an evidence-mapping workspace.

    Start with Google Search Console and your analytics platform, but do not begin with total organic sessions. First separate Web Search from Discover and other channels. Within Web Search, compare impressions, clicks, click-through rate, and average position by query and page. Within Discover, examine the available page-level reporting on its own terms rather than forcing it into a Web Search query analysis.

    Group affected pages by the reason they exist: topic, search intent, content format, audience, template, authoring process, or business line. The useful unit is rarely one isolated URL. If a collection of similar pages declined together while the rest of the site held steady, the shared pattern is more informative than the site’s average.

    1. Save an untouched baseline export before editing anything. Preserve page, query, device, country, impressions, clicks, position, and conversion data where available.
    2. Separate losses in visibility from losses in response. Falling impressions or positions indicate a search-visibility problem. Stable impressions with fewer clicks point toward result presentation, changed result features, or user choice. Stable search clicks with weaker conversions point downstream to the landing experience, offer, tracking, or audience fit.
    3. Rank page groups by material impact, then look for repeated behavior. A cluster losing across many related queries deserves attention before a single volatile term.
    4. Record winners as well as losers. Unchanged and improving pages show which formats, topics, and approaches Google continued to surface on your own domain.
    5. Inspect the current results for the affected queries. Compare the task served, answer depth, format, specificity, freshness needs, and intended audience. Do not copy the winners; identify what searchers can accomplish there that they cannot accomplish on your page.
    Observed patternWorking interpretationNext check
    Web Search impressions fall across one topic clusterThe cluster may have lost relevance or competitiveness for those searchesCompare query intent, result types, answer depth, and the pages that replaced it
    Discover declines while Web Search remains stableThe evidence does not support a sitewide core-update diagnosisAnalyze Discover separately and account for the February 2026 Discover update
    One template declines across unrelated topicsA shared presentation, technical, or content-production pattern may be involvedCompare affected and unaffected templates, including rendering, indexing, internal links, and visible page structure
    Impressions remain stable but clicks declineVisibility may not be the primary problemReview titles, descriptions, competing result features, and whether the displayed promise matches the query
    Search clicks remain stable but conversions declineThe ranking update is not sufficient to explain the business lossCheck tracking, page behavior, offer changes, availability, and conversion flow
    All channels fall at the same timeA Google core update is unlikely to be the only causeCheck analytics integrity, site releases, outages, demand, and commercial changes

    These interpretations are starting hypotheses, not automatic diagnoses. Require the pattern to appear in the underlying page and query data before assigning work to it.

    Fix satisfaction gaps rather than chasing signals

    Google’s standing direction remains to create helpful content for people. That advice becomes useful only when you turn it into page-level questions. “Make it better” is not an action. “Move the procedure ahead of the company background because the dominant queries ask how to complete the task” is an action.

    Test the page against the searcher’s actual job

    Write the main task in one sentence before reviewing the page. Is the person trying to learn, compare, troubleshoot, verify, calculate, choose, or complete a process? Then locate the first point where the page materially serves that task. If the answer is buried beneath a generic introduction, brand narrative, or loosely related background, fix the order before adding more words.

    Check whether the title, opening, headings, body, examples, and call to action serve the same intent. A page often weakens when it promises one job in the search result, explains another in the body, and pushes a third in the call to action. Alignment matters more than repeating the target phrase.

    Find the missing decision support

    A page can be factually correct and still leave the reader unable to act. Look for absent prerequisites, constraints, tradeoffs, failure modes, definitions, examples, or next steps. Add only what closes a real decision gap. A longer page that delays the answer is not inherently more satisfying than a concise one.

    Ask a hard comparative question: what can someone decide or do after reading the results now ranking above you that they could not decide or do after reading your page? The answer should become a concrete edit. If you cannot identify a meaningful difference, do not manufacture one by expanding every section.

    Verify accuracy, ownership, and maintenance

    Check every consequential claim, named feature, date, process, and recommendation. Remove unsupported certainty. Replace stale instructions. Make authorship and editorial responsibility clear where the reader needs them to judge the advice. Cite the originating authority when a claim depends on a standard, policy, specification, or official announcement.

    Do not simulate freshness by changing a date while leaving old guidance intact. A meaningful update should have a reason you can record: a corrected fact, a changed process, a better explanation, a newly addressed intent, or clearer decision support.

    Keep schema aligned with the visible page

    JSON-LD can clarify the entities, properties, and relationships already represented on a page. It cannot turn thin, mismatched, or unsupported content into a satisfying result. Treat structured data as a consistency layer, not a core-update recovery switch.

    After a substantive edit, verify that the markup still matches the visible content. Remove properties the page no longer supports, keep entity names and relationships consistent, and avoid adding types merely because they appear SEO-friendly. The content, metadata, internal links, and schema should describe the same thing without contradiction.

    Make controlled changes and measure recovery honestly
    One generic web page panel is adjusted in a controlled testing lane while two unchanged panels remain covered for comparison.

    Prioritize shared weaknesses that affect a meaningful group of pages. An isolated decline with no repeatable pattern is a poor reason for a sitewide rewrite. A clear intent mismatch across an entire template or topic cluster is a stronger candidate because the diagnosis and expected effect can be stated in advance.

    1. Preserve the baseline data and a recoverable copy of every page before making material changes.
    2. Resolve measurement, indexing, rendering, redirect, or deployment problems before judging content quality. Content edits cannot repair missing data or a broken delivery path.
    3. Choose a coherent page group with one identifiable weakness. Define the intended change and the metric that should respond.
    4. Make the smallest batch large enough to test the shared diagnosis. Avoid mixing unrelated URL, template, copy, schema, and commercial changes when they can be separated.
    5. Annotate what changed, where, why, and when. Keep unaffected pages steady where practical so later comparisons retain context.
    6. Re-evaluate the same page and query groups after Google has processed the changes. Judge visibility and qualified outcomes together rather than celebrating a traffic increase that does not serve the audience or business.

    Choose the treatment page by page. Refresh a URL when its purpose remains valid but its answer is stale, incomplete, unclear, or poorly ordered. Consolidate pages when several weak URLs divide the same intent and none earns a distinct role. Leave a strong page alone when the evidence is inconclusive. Retire a page only when it no longer serves a user or business purpose; preserve the evidence first, and map a relevant redirect before removing a URL when a genuine replacement exists.

    Google has not supplied a special one-step repair for this update. Recovery may be gradual and may become visible around subsequent core updates. That does not mean you should wait passively, but it does mean you should reject guaranteed recovery dates and avoid claiming that one edit caused a later movement without supporting evidence.

    Your next action is straightforward: annotate the core, spam, and Discover context; preserve a clean baseline; map the largest losses by surface, query intent, page group, and template; and approve edits only where you can name the satisfaction gap. That turns a volatile month into a controlled recovery program instead of a trail of untraceable changes.

    References


  • Google’s Global Expansion: Experience AI-Driven Search Live

    Google’s Global Expansion: Experience AI-Driven Search Live

    I was thrilled to learn that Google has rolled out its Google Search Live globally, expanding its reach to over 200 countries and territories where AI Mode is available. You can check which languages and regions are supported.

    Google attributes this remarkable expansion to its cutting-edge audio and voice model, Gemini 3.1 Flash Live. This model offers more natural and intuitive conversations, and because it is bilingual, it allows individuals worldwide to engage with Search in their language of choice.

    How it works. To get started with Search Live, I simply open the Google app on my Android or iOS device and tap the Live icon beneath the Search bar. From there, I can speak my question out loud and receive a helpful audio response. It’s seamless to continue the conversation with follow-up questions or delve deeper using the provided web links. When I need visual context, like figuring out how to install a new shelving unit, I just enable my camera, and it complements Search Live’s suggestions with relevant information from the web.

    Moreover, if I’m already using Google Lens to capture an image, tapping on the Live option lets me have a real-time conversation about what I see, bringing what’s in front of me to life.

    More. Back in September, Google made Search Live with video available in the U.S., appealing to those who enjoyed its earlier iterations. Initially, it was an opt-in beta, and before that, it featured a talk and listen mode, minus the video component.

    Why we care. This development offers a fresh approach for users to interact with Google’s AI through conversation rather than text queries. While this might reduce traditional web traffic, since users get direct answers, the inclusion of citations and links might still benefit content creators and brands, even if users are less compelled to click through for more depth.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How to Measure AI Agent Traffic and Attribute Conversions

    How to Measure AI Agent Traffic and Attribute Conversions

    Your analytics dashboard may show a human arriving at checkout while missing the machine that found the product, compared the options, and initiated the journey. It may also show nothing at all when an agent completes an action without running your client-side analytics code.

    You can close that gap, but not with a new referral channel alone. Reliable AI agent attribution starts in server and CDN logs, continues through first-party action events, and ends with an attribution model that distinguishes direct execution from assistance and unlinked automation.

    Key takeaways

    • Measure AI agents at the HTTP request layer. A request that does not execute your analytics script cannot create a normal browser event.
    • Separate training crawlers, real-time retrieval systems, and task-performing agents. They represent different intent and should not share one conversion rate.
    • Do not trust a user-agent string by itself. Combine it with published network information, request behavior, authentication state, and your own event data.
    • Use distinct attribution states for agent-executed, agent-assisted, discovery-only, and unresolved activity. Do not force uncertain traffic into a conversion channel.
    • Instrument forms, account actions, carts, and orders on the server. Page requests show access; confirmed business events show outcomes.

    Classify traffic by the job the machine is doing

    An automated request is not automatically a prospective customer. A model-training crawler collecting material, an answer engine retrieving a current page, and an agent submitting a form can all request the same URL. Their commercial meaning is entirely different.

    This distinction matters because machine activity is growing faster than human activity. HUMAN Security measured more than a quadrillion interactions from 2022 through 2025. In that dataset, automated traffic increased 23.5% in 2025 while human traffic increased 3.1%. AI-driven traffic rose 187%, and activity associated with AI agents and agentic browsers rose by nearly 8,000%. Those figures come from aggregated, anonymized customer data, so treat them as a market signal rather than a forecast for your site.

    Traffic classLikely jobWhat to measureAttribution treatment
    Training crawlerCollect content for later model developmentPages fetched, bytes served, crawl frequency, response statusContent access, not a visit or conversion
    Real-time retriever or scraperFetch current information for an answer or comparisonLanding routes, freshness-sensitive pages, response success, repeat retrievalDiscovery activity unless a handoff can be observed
    Task-performing agentNavigate or take an action for a userWorkflow steps, authenticated state, form or cart events, confirmed outcomeDirect or assisted attribution when the evidence supports it
    Unverified automationUnknown, mislabeled, or potentially hostile activityBehavior pattern, network identity, rate, errors, security challengesKeep unattributed until verified

    Training crawlers still represented 67.5% of measured AI traffic, while real-time scrapers grew by nearly 600% in 2025. That mix explains why a large increase in AI-labelled requests does not necessarily produce leads or revenue. Start by assigning each request to a functional class; calculate commercial performance only for traffic capable of participating in a user journey.

    Task-performing agents deserve special attention because their behavior is moving deeper into sites. In 2025, 77% of observed agentic activity occurred on product and search pages, nearly 9% involved account-level interactions, and more than 2% reached checkout. If you monitor only editorial URLs, you will miss the requests closest to a business outcome.

    Create at least two classification fields in your data: agent_type for the machine’s apparent job and verification_status for the strength of the identification. Keep the values independent. A request can look transactional while its claimed identity remains unverified.

    Build an evidence chain from request to outcome

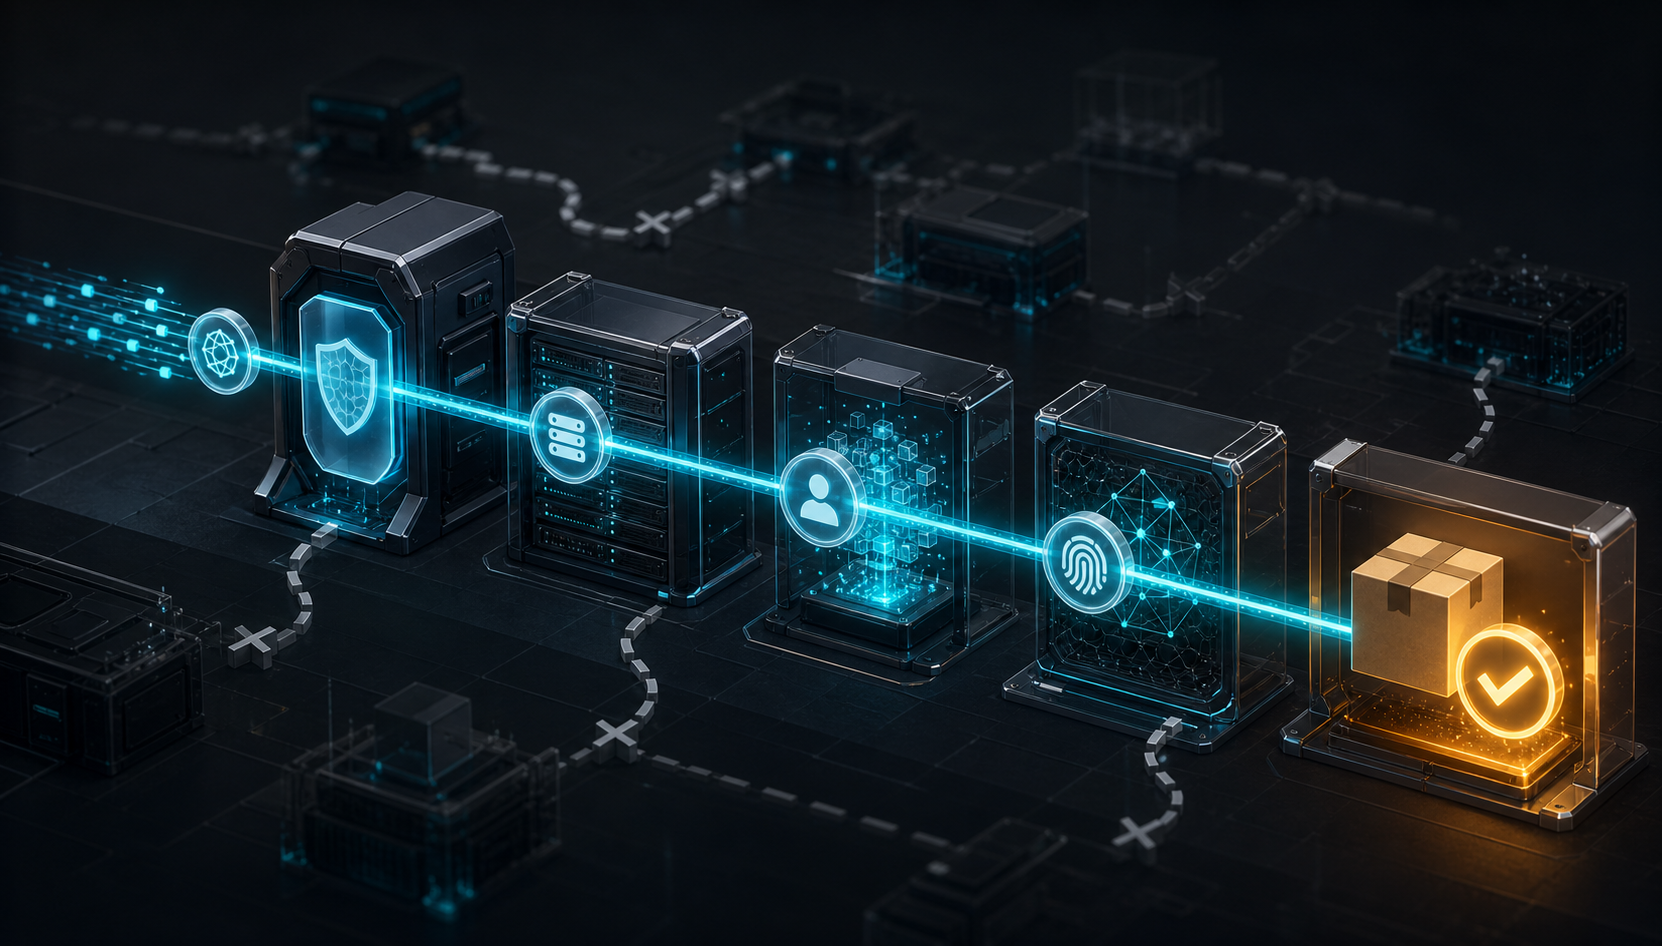
    A continuous glowing trail links an incoming machine request to a gateway, server records, an action event, and a completed purchase.

    Attribution becomes credible when you can follow an agent from an incoming request to a server-confirmed action. A dashboard label such as “AI traffic” is not enough. You need a chain of evidence that survives redirects, browser changes, authentication, and the absence of JavaScript events.

    Capture the request before classifying it

    Preserve the raw evidence in your CDN, load balancer, or application logs before a bot filter removes it. For each relevant request, capture:

    • A UTC timestamp and a unique request ID.
    • The HTTP method, normalized route, response status, and response size.
    • The full user-agent value as received, plus the parser’s normalized result.
    • The source network information needed for verification.
    • Referrer and origin headers when present, without treating their absence as proof of anything.
    • Whether a first-party session was present or created.
    • A pseudonymous account or customer identifier when the request was legitimately authenticated.
    • The resulting application event, such as search performed, form accepted, cart updated, or order confirmed.

    Do not log authorization headers, passwords, payment details, complete form bodies, or sensitive query-string values for the sake of attribution. Strip or tokenize sensitive fields before they reach the analytics store. The useful connection is between a request identifier and a confirmed event, not between a marketing report and a copy of the user’s private data.

    Instrument the business action on the server

    A page view tells you that an agent requested a page. It does not tell you that a form was accepted, an account changed, or a payment completed. Emit a first-party server-side event only after the application confirms the action.

    Give that event its own ID and record the initiating request ID, event time, action type, outcome, and any internal transaction or lead identifier. If the event represents money, use the same finalized value your order system recognizes. Failed submissions and abandoned workflows belong in diagnostic reporting, not completed-conversion totals.

    Make an agent-to-human handoff observable

    Many useful agent journeys will not end inside the agent. The machine may find a product or prepare a configuration, then send the user into a browser to review, authenticate, or pay. Standard last-click attribution can give the browser all the credit because the earlier agent request had no ordinary campaign parameter or client-side session.

    When you control the handoff, attach an opaque, first-party handoff token to the destination URL. The token should identify a journey record, not expose an email address, prompt, account number, or other personal data. Expire it, prevent it from granting access, and associate it with the eventual conversion only after your server validates it. If the user is already authenticated, an internal pseudonymous account key can provide the connection without placing identity in the URL.

    If you cannot observe a deterministic handoff, do not manufacture one from matching timestamps or similar page paths. You may analyze those patterns in aggregate, but label the result as discovery influence rather than an assisted conversion.

    Recognize Google-Agent without weakening security

    An abstract automated agent passes through layered identity checks at a secure gateway while unverified requests are blocked.

    Google-Agent creates a useful distinction between continuous crawling and a request made while an AI system performs a user-initiated task. Google introduced it for agents hosted on its infrastructure, including experimental systems such as Project Mariner, and provided network ranges for desktop and mobile agent activity.

    That identity gives you a better starting signal, not a substitute for authentication. User-agent strings are supplied by the requester and can be copied. Never allow an account action, bypass a challenge, or relax a security rule solely because a request calls itself Google-Agent.

    Use confidence-based verification

    Apply the same verification pattern to Google-Agent and any other named agent:

    1. Match and preserve the claimed user-agent identity.
    2. Compare the source with the provider’s published network information and keep that information current.
    3. Check whether the request pattern is consistent with the claimed function, including the routes, methods, timing, and workflow sequence.
    4. Record the result as verified, probable, or unverified rather than reducing all three states to a boolean bot flag.
    5. Apply normal authorization, rate limiting, abuse detection, and transaction controls regardless of the identity label.

    This approach is more defensible than a single allowlist. It also reflects how large-scale AI traffic was classified: user-agent strings were combined with infrastructure signals and activity characteristics because self-reported bot identities do not capture every AI-driven request reliably.

    Test the paths that matter

    Review your CDN and web application firewall logs for named agents before changing any rule. Then test product search, detail pages, forms, sign-in, account functions, cart operations, and checkout with non-production accounts and non-chargeable test transactions where your systems support them.

    Look for redirects that loop, challenges that cannot be completed, required state that disappears between requests, and successful browser screens backed by failed server actions. Keep intentional security denials in place. The goal is to remove accidental incompatibility, not to give automated clients a privileged route into sensitive workflows.

    Report agent contribution without false precision

    Your reporting should tell operators what happened and tell decision-makers how certain the attribution is. One blended “AI conversions” number cannot do both.

    Use four mutually exclusive outcome states:

    • Agent-executed: A verified or explicitly qualified agent request is linked to a server-confirmed conversion that the agent performed.
    • Agent-assisted: An observable first-party handoff or authenticated journey connects agent activity to a later human conversion.
    • Discovery-only: An agent retrieved relevant content, but no deterministic connection to an individual outcome exists.
    • Unresolved automation: Automation was detected, but its identity, purpose, or relationship to an outcome remains uncertain.

    Do not add agent-executed and agent-assisted credit if they describe two stages of the same conversion. Keep a deduplicated conversion ID, choose a primary status, and retain the touch sequence separately for analysis.

    Your operational dashboard should cover three layers. The access layer needs request volume by agent type, verification state, route group, response status, and security disposition. The workflow layer needs starts, successful steps, failures, and confirmed completions for each key action. The business layer needs deduplicated leads, orders, revenue where applicable, and the four attribution states above.

    Choose an assistance window that reflects your actual buying cycle and publish that rule beside the metric. There is no defensible universal window in the available evidence. A short handoff into checkout and a long enterprise evaluation should not inherit the same arbitrary assumption.

    Establish the baseline even if named-agent volume is initially small. A rise in training access may affect infrastructure cost and content-control decisions without changing revenue. A rise in verified product-search and account activity deserves workflow testing. Repeated checkout attempts with no confirmed outcomes point to a technical or security investigation, not automatically to weak demand.

    Start with one path that matters commercially: discovery, a product or service page, and its next meaningful action. Join the request logs to one server-confirmed outcome, preserve uncertainty as an explicit field, and make that narrow chain trustworthy before expanding it across the site. That gives you a measurement system you can extend as agents become more capable, without rewriting history around traffic you never truly identified.

    References


  • ChatGPT Shopping Referrals: A Practical Visibility Playbook

    ChatGPT Shopping Referrals: A Practical Visibility Playbook

    If ChatGPT has begun sending shoppers to your store, your immediate question is probably how to earn more of those referrals. The answer starts with measuring the opportunity correctly. A single recommendation, position, or shopping carousel cannot tell you whether your products are consistently visible.

    The shopping carousel can reshuffle from one request to the next. Treat each response as one observation from a changing recommendation system, then look for patterns across repeated prompts before you change your content, product data, or acquisition strategy.

    Stop treating the shopping carousel like a fixed ranking

    Traditional rank tracking encourages a simple question: which domain occupies the first position? ChatGPT shopping referrals require several questions. A retailer can appear frequently without leading the carousel, while another can win the first buy link in a narrower set of responses.

    That distinction is visible across an analysis of 22.5 million shopping offers. Walmart often led the rank-one buy links, while Target achieved stronger overall presence. Neither metric cancels the other. They describe different forms of visibility.

    • Appearance rate: How often your retailer, brand, or product appears across eligible prompt runs.
    • First-position rate: How often it appears first when it is included.
    • Buy-link rate: How often the response provides a purchasing path to your domain.
    • Product coverage: How many distinct products or product families earn visibility within a prompt cluster.
    • Volatility: How much the included retailers, products, and positions change when you repeat the same prompt.

    This prevents a common reporting error. If you track only first position, you can miss broad consideration. If you track only appearances, you can mistake occasional inclusion for commercial preference. Keep the metrics separate, and interpret them together.

    Build a repeatable ChatGPT referral visibility baseline

    Several tablets display the same generic products in different orders within a neatly organized testing workspace.

    Your audit should begin with the decisions customers are trying to make, not a list of keywords copied from a conventional rank tracker. Shopping prompts often contain a product need plus constraints such as intended use, features, budget, compatibility, delivery, or retailer preference. Those qualifiers can materially change which options make sense.

    1. Create prompt clusters around buyer jobs. Separate broad product discovery, constraint-heavy discovery, comparisons, replacement purchases, and branded requests. Include only prompt types that reflect a real path to your products.
    2. Write prompts as customers would ask them. Preserve natural context and decision criteria. A prompt designed merely to force your brand into the answer does not measure discovery.
    3. Repeat each prompt without rewriting it. The carousel can change between requests, so one run cannot establish a stable position. Repetition lets you distinguish a persistent pattern from a transient result.
    4. Record the entire response set. Capture the prompt, run, retailer, brand, product, displayed order, buy-link destination, and landing page. Do not save only the result that mentions you.
    5. Aggregate results by prompt cluster. Calculate appearance, first-position, and buy-link rates separately for each type of shopping decision.

    Keep the test conditions as consistent as practical. If an account, location, device, or other environment detail changes, record that fact rather than silently combining the runs. You may not know why two responses differ, but you can avoid confusing a test change with a visibility change.

    Your baseline is complete when it can answer more than whether you appeared. It should show where you appear repeatedly, where you lead, which products receive the exposure, where the purchase links go, and which prompt clusters produce unstable results.

    Diagnose the visibility pattern before changing your site

    Different metric combinations point to different investigations. They do not prove why ChatGPT selected an option; the exact recommendation logic is not exposed by a carousel response. Use the patterns as diagnostic hypotheses, then verify the underlying product and landing-page evidence.

    Observed patternWorking interpretationWhat to inspect next
    High appearance and high first-position ratesYour offer is broadly visible and often prioritized within the tested cluster.Protect accurate product information, examine where buy links land, and determine whether the visibility produces qualified sessions and sales.
    High appearance but low first-position rateYour products are regularly considered but seldom presented first.Compare the decision-critical details exposed on your pages: intended use, differentiators, price conditions, availability, variants, fulfilment, and returns.
    Low appearance but high first-position rate when presentYour offer may fit a narrow set of needs particularly well.Identify the prompt constraints associated with those wins. Decide whether that niche is commercially important before trying to broaden it.
    Frequent mentions but few buy linksYou have informational recognition without a consistent commerce handoff.Check whether the correct product page is indexable, current, clearly purchasable, and preferable to an informational or category URL.
    Large changes between identical prompt runsThe recommendation set is unstable for that decision.Rely on aggregate rates, inspect which competitors recur, and avoid declaring a winner from a screenshot.

    Prompt-level segmentation matters here. A strong aggregate can conceal a complete absence from an important use case, while one excellent response can make a weak aggregate look more promising than it is. Read the total first, then inspect the clusters that carry the most buying intent for your business.

    Reduce uncertainty in the product decision

    A product moves from obscured information to a clearly presented choice with images, material samples, measurements, delivery, returns, and review symbols.

    You cannot directly control the composition or order of a ChatGPT shopping carousel. You can control whether your product information gives a recommendation system clear, consistent evidence to work with. The goal is not to repeat marketing language more often. It is to remove ambiguity from the buying decision.

    Make each purchasable page self-sufficient

    A product page should make sense without requiring a system or shopper to reconstruct essential facts from several other URLs. Audit each commercially important page for the following:

    • A precise product name, category, model, and variant.
    • A plain-language explanation of who the product is for and which use cases it supports.
    • Decision-critical attributes written as text, not hidden only inside images or promotional graphics.
    • Clear differences among sizes, configurations, bundles, or generations.
    • Accurate purchase conditions, including price, currency, availability, fulfilment, and return information where applicable.
    • An unambiguous purchase action and a stable destination for the specific product.
    • Agreement among visible page copy, structured product data, and any commerce feed you maintain.

    Do not treat structured data as a guarantee of inclusion. Markup cannot repair a vague offer, a missing variant distinction, or contradictory on-page information. Its useful role is to express facts consistently. The visible page still needs to help a person decide whether the item fits.

    Build supporting pages around genuine decisions

    A category page should explain the criteria that separate its products. A comparison page should state material differences rather than giving every option the same generic praise. Compatibility, sizing, delivery, warranty, and return pages should be easy to reach when those details can change the purchase decision.

    Avoid creating a thin page for every possible wording of a shopping prompt. Consolidate overlapping questions into authoritative pages that cover the full decision. You want one dependable explanation of the product and its constraints, not a collection of near-duplicates that disagree after the next catalog update.

    Connect visibility, handoff, and outcome

    ChatGPT visibility is not the same as a referral, and a referral is not the same as a sale. Keep those stages separate in your reporting:

    • Visibility: Your appearance, first-position, product-coverage, and volatility measurements from repeated prompts.
    • Handoff: Whether a buy link is present, which domain receives it, and which landing page it uses.
    • Outcome: The sessions, product views, cart actions, leads, or purchases your analytics can actually observe.

    Do not force a precise attribution claim when the stages cannot be joined. Instead, make one meaningful change within a defined product or prompt cluster, keep your audit method stable, and compare the aggregate pattern before and after the change. That gives you a defensible learning loop without pretending that every carousel movement came from your edit.

    Key takeaways

    • There is no dependable single ChatGPT shopping rank when the carousel can reshuffle between requests.
    • Measure appearance, first position, buy links, product coverage, and volatility as separate signals.
    • Repeat unchanged prompts and aggregate the results before drawing a conclusion.
    • Use metric combinations to decide what to inspect; do not present them as proof of how ChatGPT selected a result.
    • Make product pages, supporting content, structured data, and commerce feeds consistent enough to support an unambiguous decision.
    • Report visibility, referral handoff, and business outcomes as distinct stages.

    Start with one commercially important prompt cluster and establish its baseline before editing anything. Once you know whether the problem is inconsistent inclusion, weak prioritization, a missing buy link, or a poor landing destination, you can make a focused change and learn from the next set of runs.

    References

  • Performance Max Campaign Controls: A Practical Playbook

    Performance Max Campaign Controls: A Practical Playbook

    You do not need complete control of Performance Max to keep it accountable. You need to know which reports merely describe what happened, which settings impose hard limits, and which inputs steer the automation without guaranteeing an outcome.

    The most reliable approach is to work in that order: verify what the campaign is optimizing for, remove clearly unwanted traffic, apply narrow constraints where the evidence is strong, and then improve the creative, feed, budget, and bidding inputs. That gives you more control without excluding useful demand just because a report looks uncomfortable.

    Key takeaways

    • Campaign-level negative keywords, placement exclusions, ad schedules, demographic exclusions, and device controls are the clearest direct controls available in Performance Max.
    • A report is not automatically a control. Search terms can lead directly to negatives, but placement impressions do not tell you how much a placement spent or whether it produced conversions.
    • Use exclusions for traffic that is demonstrably irrelevant, ineligible, unsafe for the brand, or operationally impossible to serve. Do not use them as a reflex whenever performance is uncertain.
    • Creative assets, product feeds, conversion goals, bids, and budgets steer where automation looks for results. They usually deserve attention before you start narrowing reach aggressively.
    • Record each material change and its reason. If you change negatives, schedules, devices, assets, and bidding together, the next report cannot tell you which decision helped.

    Remove obvious waste with search terms and placement controls

    Geometric traffic signals pass through two filters while unwanted signals are diverted into a separate channel.

    The safest exclusions begin with a simple question: could this traffic ever produce the outcome you want? If the answer is clearly no, blocking it protects the budget. If the answer is merely uncertain, investigate before turning an observation into a permanent rule.

    Turn search-term visibility into a disciplined negative list

    Campaign-level negative keywords can be added from the Performance Max search terms report. This removes much of the friction that once separated finding an irrelevant query from blocking it.

    That convenience makes restraint more important. A query with no recorded conversion is not automatically irrelevant. It may have appeared too infrequently to judge, sit earlier in the buying journey, or suffer from a landing-page or offer problem. Negatives should remove unwanted meaning, not conceal a broader performance issue.

    Use this review sequence:

    1. Group terms by intent rather than reacting to isolated wording. Repeated patterns reveal more than one unusual query.
    2. Separate clearly impossible or irrelevant intent from ambiguous intent. Exclude the first group; investigate the second.
    3. Check whether a candidate negative could also match valuable searches. Use the narrowest exclusion that removes the unwanted concept without cutting into legitimate demand.
    4. Add the negative from the search terms report and record why it was added. A short reason makes later reversals much easier.
    5. Review the effect in the next stable comparison period, allowing for the conversion lag that normally applies to your account.

    Common candidates include searches for a service you do not provide, a product category you do not sell, or an intent that cannot become a qualified customer. A merely expensive term belongs in a different bucket. Before excluding it, check the conversion goal, landing page, offer, and query context.

    Use placement data for suitability before profitability

    Performance Max placement visibility now sits in the campaign’s expanded reporting and exclusion workflow, including the ‘Where ads have shown’ area. The placement report is particularly useful for spotting large volumes of impressions in contexts that do not fit the campaign, such as unintended mobile apps or children’s programming.

    The limitation matters: impression-level placement data is not a placement-level profit-and-loss statement. A placement with many impressions has not necessarily consumed an equivalent share of spend, generated the same share of clicks, or caused the campaign’s overall inefficiency. Treating impressions as cost can lead you to exclude inventory for the wrong reason.

    Placement exclusions are strongest when the decision is about relevance or brand suitability. If a context is plainly inappropriate, an account-level negative placement may be justified. Because that scope can affect more than the campaign you are reviewing, check which other campaigns rely on the same inventory before applying it.

    If the concern is performance rather than suitability, look for corroborating evidence first. Review the campaign’s search intent, channel distribution, assets, conversion goals, and landing pages. The placement report may identify where to investigate, but it does not always identify what to remove.

    Apply time, demographic, and device limits without choking reach

    Schedules, demographic exclusions, and device settings are genuine constraints. They can improve efficiency when they reflect how the business actually operates. They can also starve the campaign when they are used to compensate for weak data, a broken experience, or impatience with normal variation.

    Build an ad schedule around opportunity and operating capacity

    The ‘When and where ads showed’ reporting area provides hour-by-hour information even when the campaign began without a restricted schedule. You can apply a schedule under ‘Campaigns > Audiences, keywords, and content > Ad schedule’.

    Scheduling is most useful when budget is limited and there is a repeatable mismatch between ad delivery and the business’s ability to convert demand. A lead-driven company may struggle to handle inquiries during certain hours. A campaign with a constrained daily budget may spend during weak periods and lose access to stronger periods later. In either case, the schedule should reflect a demonstrated operating constraint, not a single quiet hour in a report.

    Before removing an hour or day, ask three questions:

    • Does the pattern repeat across comparable periods, or is it driven by one unusual day?
    • Was there enough activity to make the absence of conversions meaningful?
    • Could conversion lag, offline follow-up, or the sales process make the hour look weaker than it really is?

    If those checks support the same conclusion, restrict the weakest period first rather than rebuilding the entire week at once. A narrow change preserves more eligible inventory and gives you a cleaner result to evaluate.

    Reserve demographic exclusions for durable mismatches

    Campaign-level demographic exclusions are available under ‘Other settings’. They are appropriate when a group cannot reasonably use or qualify for the offering, or when a consistent body of campaign evidence supports the restriction.

    A weak short-term result is not the same as a durable mismatch. Demographic segments may receive different volumes and enter at different points in the customer journey. If you exclude a segment after a small amount of activity, the campaign loses the chance to learn whether better creative, a different landing page, or more complete conversion data would change the result.

    Use demographic controls as eligibility rules first and optimization rules second. When the decision is performance-based, document the evidence and plan a later review. An exclusion should remain reversible when the underlying audience or offer could change.

    Diagnose the device experience before excluding the device

    Device controls in ‘Other settings’ let you review which devices contribute to campaign goals and decide which devices to include or exclude. This is valuable, but device performance often exposes a site or journey problem rather than an audience problem.

    Before excluding a device, complete the conversion path on that device. Check whether the page loads cleanly, forms are usable, calls work, product information remains legible, and the final action can be completed without friction. If the experience is broken, repair it. Excluding the device may reduce visible waste, but it also hides the defect and abandons otherwise valid demand.

    A device restriction is easier to justify when the offering genuinely cannot be delivered there or when the performance gap persists after the experience and measurement have been checked. Apply the smallest defensible restriction, then monitor whether volume shifts into more valuable inventory or simply disappears.

    Steer channel delivery through assets, feeds, goals, and bids

    Creative, product, goal, budget, and bidding modules feed a central routing system that distributes light across several advertising channels.

    Not every useful lever is an exclusion. In Performance Max, the material you supply tells the system what it can advertise, which formats it can assemble, which customers it should value, and what outcome bidding should pursue. These inputs influence delivery without offering an exact channel allocation switch.

    Creative quality matters because Performance Max can serve across visual inventory including Display, YouTube, and Discover. Generic assets may technically make a campaign eligible for more formats while doing little to communicate the offer. Organize each asset group around one coherent product set, service, audience need, or landing-page promise. When several unrelated propositions share the same creative bundle, weak results become much harder to diagnose.

    AI-generated images and videos can help fill missing formats and create variants, including assets derived from Shopping feed products. They still require human quality control. Before approving an AI asset, check:

    • Whether the product, packaging, proportions, and important visual details remain accurate.
    • Whether text is readable in the expected crop and does not introduce unsupported claims.
    • Whether video motion, transitions, and product rendering remain coherent from beginning to end.
    • Whether the message matches the destination page closely enough that the click does not create a new expectation.
    • Whether the asset is acceptable for every type of inventory in which the campaign may use it.

    The channel reporting view can show where delivery is occurring, but its actionable controls remain limited. If the campaign is appearing in a channel you would prefer to reduce, first inspect the inputs that made that inventory attractive: the asset mix, product feed, conversion goal, bid strategy, and budget. Changing these does not guarantee a particular distribution, but it addresses the logic the campaign is using.

    When the business specifically needs Shopping-focused delivery, a feed-only campaign structure can concentrate the campaign on the product feed rather than supplying a complete cross-channel creative set. That choice trades broader creative reach for tighter inventory focus. Make it deliberately; do not remove assets simply because one channel report looks unfamiliar.

    Conversion goals deserve the earliest inspection. If the campaign is rewarded for shallow actions that do not represent business value, exclusions will not solve the central problem. It will continue finding more of the outcome it was told to value. Make sure the selected goal represents a meaningful result and that different conversion actions are not being treated as equivalent when the business values them differently.

    Bids and budgets are also steering mechanisms. They affect which opportunities the campaign can pursue and how aggressively it can compete, but they cannot repair an irrelevant goal or misleading creative. Fix the instruction before increasing the resources given to follow it.

    Run the controls in a repeatable order

    A control is useful only if you can connect it to a decision. Use one review sequence consistently so that urgent-looking reports do not pull you into random edits.

    1. Record the current conversion goals, bid strategy, budget, schedule, exclusions, asset setup, and feed configuration. This is the baseline against which later changes will be judged.
    2. Confirm that the campaign is optimizing for an outcome the business actually values. Resolve incomplete or misleading measurement before interpreting audience and inventory reports.
    3. Review search terms. Add negatives only for clearly irrelevant or impossible intent, and record the reason for each important exclusion.
    4. Review ‘Where ads have shown’. Use placement exclusions for documented suitability or relevance problems, remembering that an account-level action can affect other campaigns.
    5. Inspect hour-by-hour delivery. Tighten the ad schedule only when the pattern is repeatable and consistent with the way the business handles demand.
    6. Review demographic and device performance. Test whether the apparent gap comes from eligibility, the on-site experience, or measurement before removing reach.
    7. Audit asset groups and feed inputs. Replace generic, inaccurate, mismatched, or low-utility material, and verify every AI-generated asset before it can represent the brand.
    8. Use channel reporting to decide what to investigate. If strict Shopping focus is required, evaluate a feed-only structure; otherwise steer distribution through the available inputs.
    9. Change one control layer at a time where practical. Annotate what changed, when it changed, and what outcome you expected.
    10. Evaluate the next comparable period only after accounting for normal conversion lag. Keep changes that solve the stated problem; reverse those that merely reduce reach.

    Start your next review with the search terms and placement reports, but do not stop at what looks wasteful. Trace each symptom back to the closest controllable cause. One well-supported negative, schedule adjustment, device fix, or asset correction is more useful than a dozen exclusions you cannot later explain.

    References


  • Unlock Unique Insights: Harness First-Party Data for Content Success

    Unlock Unique Insights: Harness First-Party Data for Content Success

    Have you ever wondered how to set your content apart in a competitive landscape? As a content marketer, I often face the challenge of using the same tools and data sources as everyone else, like Semrush, making it hard to create truly unique content.

    We are all casting our nets in the same pond, using identical resources to gather content ideas. The result? Overly similar content across the board. But there’s a smarter way.

    I realized that the wealth of data about my audience and customers is a goldmine, just waiting to be mined. These insights are invisible to my competitors, as they remain untouched and underutilized within my marketing team.

    I discovered how third-party tools often lead to an echo chamber of commoditized content. While essential, these tools don’t always align with what my specific audience is truly looking for, leading to a flood of generic content.

    Recognizing this challenge encouraged me to tap into my own data, creating content that appeals directly to people already interested in my services.

    First-party data is the information I need. It includes internal insights that only I have access to, such as site search queries, sales call transcripts, CRM data, support tickets, and email interactions.

    Let’s dive deeper into why this approach is effective. First-party data is proprietary. No matter how advanced a competitor’s tools might be, they can’t access my internal data, and this gives me a unique edge.

    This data reflects real buyer language, which helps me avoid assumptions based on my internal knowledge bias. I can tailor my content to match the language my audience uses.

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    By mapping this data to my entire marketing funnel, I fill gaps at every stage, driving not just traffic, but conversions and loyalty.

    How do I turn these insights into content ideas? I start with internal site searches. Examining how visitors use my site can reveal content gaps and opportunities for new offerings.

    Next, I analyze sales call transcripts and CRM data to uncover recurring themes and objections, crafting content that addresses potential buyers’ concerns directly.

    My support tickets provide another source of inspiration. By identifying common customer complaints, I create resources that help both my customers and support team.

    Lastly, I pay close attention to email replies and engagement metrics. Tracking which types of communication yield the greatest response helps me understand content preferences.

    Embracing first-party data helps my brand stand out. While competitors can mimic my content style, they can’t replicate these unique insights. Every week, I make it a point to explore a new data set and extract fresh content ideas.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • AI Gambling Content on News Sites: An Audit and Recovery Plan

    AI Gambling Content on News Sites: An Audit and Recovery Plan

    Your news site can look credible at the domain level while a growing section underneath it is serving a different business entirely. If casino pages, fabricated contributors, unexplained redirects, or generic betting copy have appeared after an ownership or commercial change, you need to determine whether you have an editorial-quality problem or a reputation-abuse problem.

    That distinction changes the response. Editing a few weak paragraphs will not fix a system designed to turn inherited authority into gambling-affiliate revenue. You need to audit who controls publication, why the pages exist, where their links lead, and whether the people named on them are real and accountable.

    Key takeaways

    • AI is usually the scaling mechanism, not the core abuse. The core problem is using a trusted news domain to rank commercially motivated pages that would struggle to earn visibility on their own.
    • Do not base your decision on writing style or an AI-detector score. Confirm the editorial chain, author identity, affiliate relationship, outbound destinations, ownership history, and publication pattern.
    • Not every gambling page on a news site is abusive. Public-interest reporting, industry analysis, and sports coverage can be legitimate when editorial purpose remains primary and commercial relationships are subordinate and disclosed.
    • Freeze suspect publishing before you clean up. Preserve records, classify every affected URL, remove deceptive identity claims, and address the access or contract that allowed the pages to appear.
    • Author schema, affiliate disclosures, or an AI label cannot rescue a page whose real purpose is to exploit the publisher’s reputation.

    AI is the accelerant; inherited trust is the asset

    Calling this an AI-content problem is accurate but incomplete. A new gambling site can generate just as much copy without possessing a news brand’s history, links, returning audience, or established search visibility. The valuable asset is the host domain’s reputation. AI makes it cheaper to cover more queries and replace more human work once that reputation is under commercial control.

    The documented pattern has involved acquiring established sports, gaming, and technology publications, retaining enough legitimate material to preserve credibility, and then increasing casino and cryptocurrency coverage. Former employees said original reporting was removed while AI-generated pages and fabricated author profiles expanded. Affiliate links supplied the commercial path, including arrangements connected to player losses.

    That sequence matters because it gives you a better diagnostic question than “Was this written by AI?” Ask: “Would this page have been commissioned, placed on this domain, and promoted in this way if the domain had no inherited authority?” If the honest answer is no, investigate the business model behind the URL.

    Google describes attempts to exploit an established site’s ranking reputation through scaled publishing as site reputation abuse, with manual action and removal from the search index among the possible consequences. AI use alone does not establish that purpose. A human-written casino landing page can be abusive, while an AI-assisted investigation into gambling regulation can still serve a legitimate editorial purpose. Intent, control, accountability, and reader value have to be examined together.

    One documented operation does not prove that every newsroom with casino content follows the same sequence. Treat the pattern as a risk model, not a verdict. Your own CMS, contracts, author records, link destinations, and editorial decisions must supply the evidence.

    Audit the publishing system, not just the prose

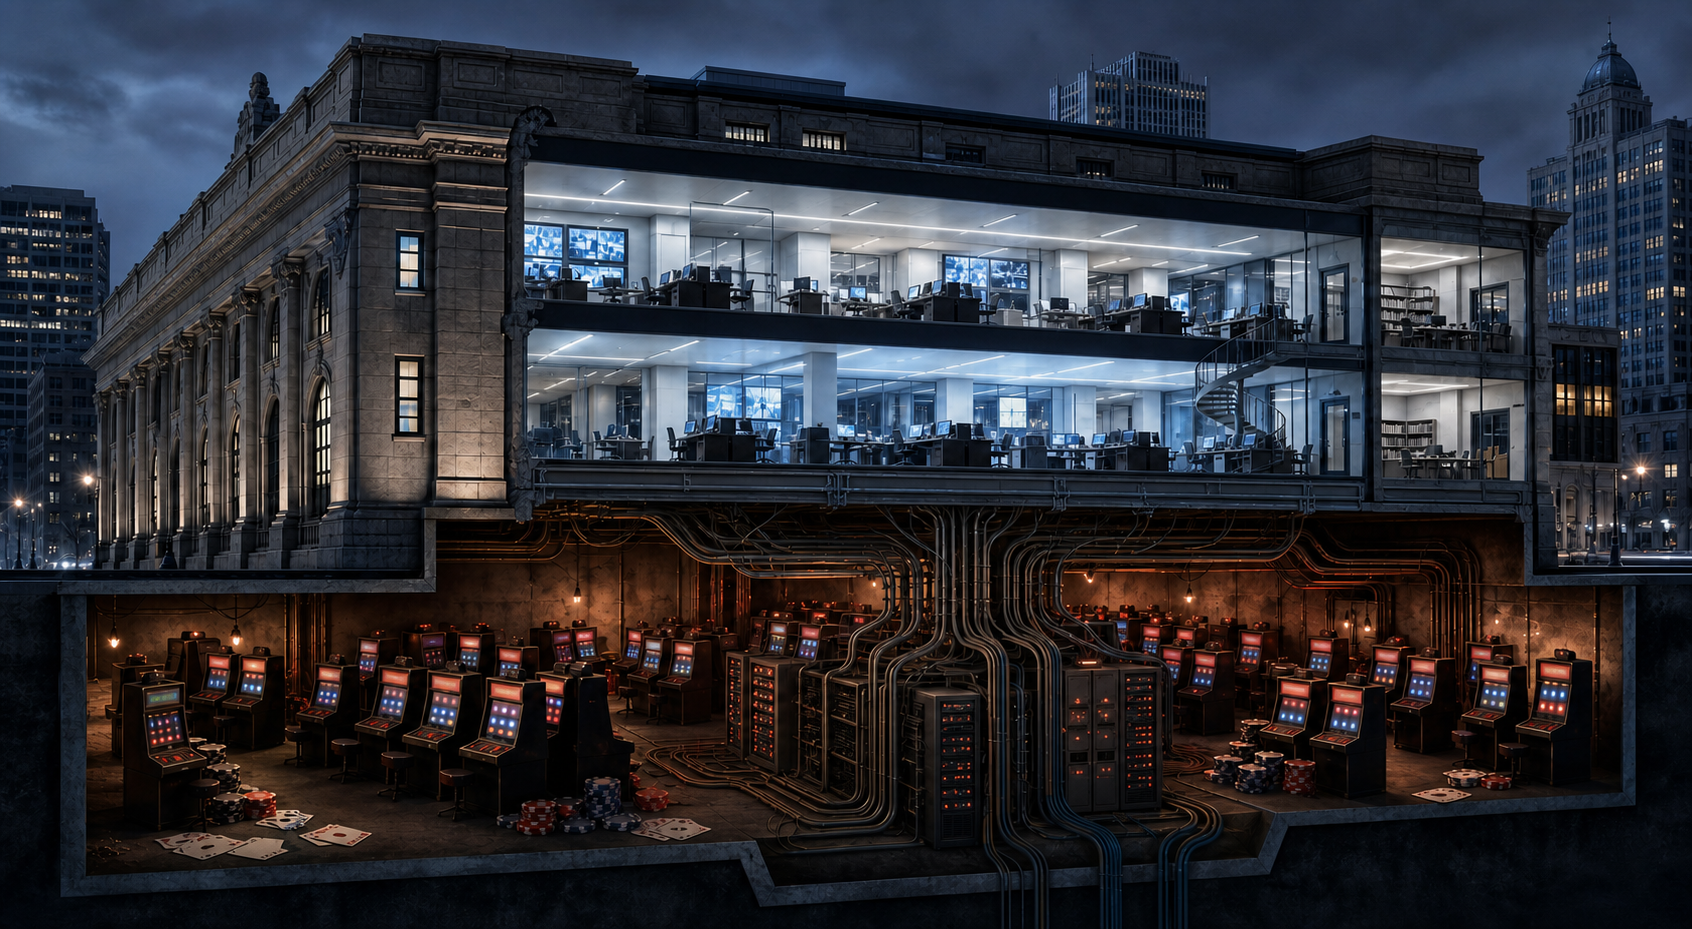
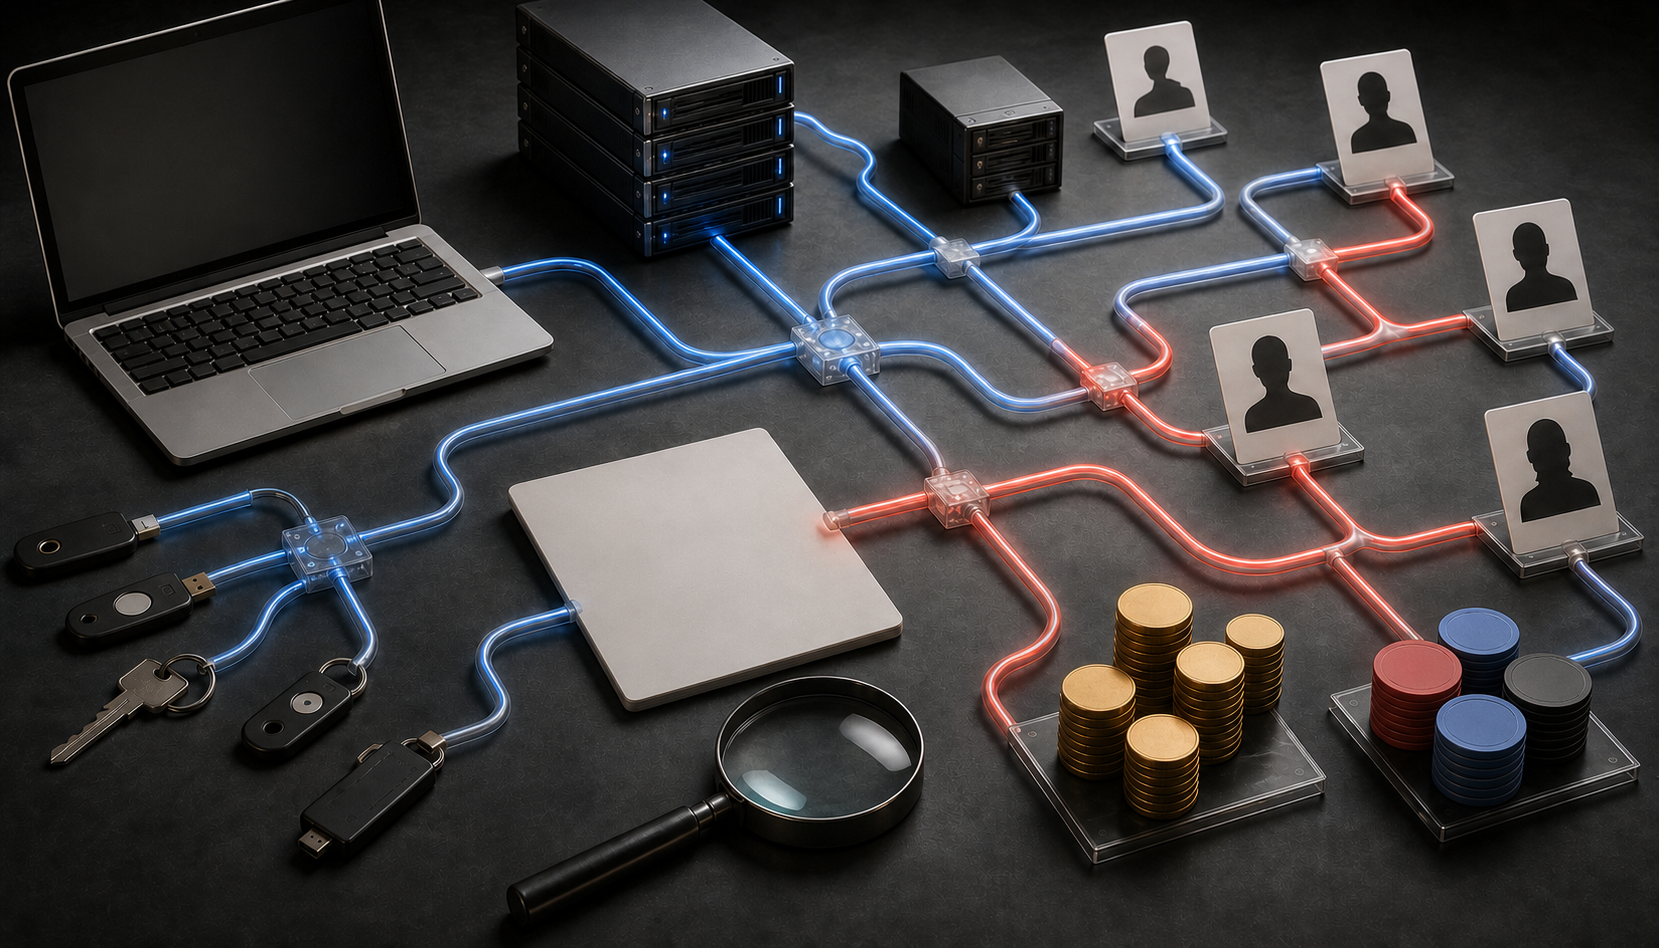
    Evidence table with a laptop, servers, access tokens, profile cards, casino chips, coins, and branching pathways under a magnifying lens.

    Start with an inventory. A handful of visible pages rarely shows the full footprint because the same operation may use directories, author archives, old templates, redirected URLs, or pages that are absent from navigation. Combine your CMS export, XML sitemaps, crawl data, server or analytics records, and Google Search Console data where you have access.

    Record one row per URL with the title, topic, publication and modification dates, named author, assigning editor, content owner, template, indexability, canonical target, structured-data author, internal links, outbound domains, redirect destinations, affiliate identifiers, and current classification. Include deleted or unpublished records when the CMS retains them. Chronology often reveals the commercial pivot more clearly than any single page.

    SignalWhy it deserves attentionWhat to verify before acting
    Casino or cryptocurrency coverage expands after an ownership, contractor, or leadership changeThe topical pivot may reflect a new affiliate model rather than audience demandAcquisition documents, editorial plans, partner agreements, CMS users, and the first publication dates
    Authors have thin, duplicated, or unverifiable profilesA fabricated byline removes accountability and misrepresents who produced the pageAssignment records, employment or contributor records, editor correspondence, revision history, and identity details supplied by the person
    Pages repeatedly send readers to casino offers or comparison pagesThe primary purpose may be acquisition rather than reportingFinal redirect destinations, affiliate parameters, commercial contracts, disclosure placement, and who approved each domain
    Original reporting is removed, buried, or replaced by templated commercial pagesThe publisher’s accumulated reputation is being separated from the work that earned itCMS revisions, backups, navigation changes, redirect maps, and archived internal records
    Search visibility drops or a manual action appearsThe problem may already affect the whole publishing property, not only the gambling sectionThe exact Search Console notice, affected patterns, index coverage, canonical behavior, and alternate URLs carrying the same material

    Trace the money and every outbound hop

    Review the commercial path in read-only fashion. Record the visible call to action, the first linked domain, every redirect, the final operator, and any tracking value. Do not register, deposit money, submit personal data, or bypass access controls to complete the audit. The objective is to document what the publisher sends a reader toward, not to transact with it.

    Then connect those destinations to contracts and payments. Identify the legal party receiving revenue, the person who approved the relationship, the compensation model, and any intermediary that can change a destination without another editorial review. A disclosure may tell readers that a commercial relationship exists, but it does not answer whether inherited authority is being exploited or whether the destination was properly vetted.

    An offshore operator is not automatically unlawful in every jurisdiction. It does create a verification burden because gambling promotion, licensing, age restrictions, and consumer protections depend on where the publisher and reader are located. Before retaining or republishing an offer, have counsel familiar with the relevant jurisdictions assess it. An SEO audit cannot make that legal determination.

    Verify authorship as an accountability chain

    A profile photo and biography are not enough. For each contributor, confirm who assigned the work, who created the CMS account, who edited the page, where the draft originated, who checked factual claims, and who can correct it now. A real person’s name attached without their knowledge is still deceptive. A generic “Editorial Team” byline is not a valid repair if nobody inside the organization accepts responsibility for the content.

    Compare the visible byline with the Article and Person data emitted by the page. The name, publisher, reviewer, profile URL, and sameAs references should describe the same real editorial relationship shown to readers. Structured data should map accountable facts; it should never be used to manufacture an expert, disguise an affiliate, or make a synthetic persona look established.

    Reconstruct the timeline and access path

    Place ownership events, staffing changes, new CMS accounts, template deployments, affiliate contracts, and topic growth on one timeline. You are looking for control points: the moment a partner gained publishing access, a new section bypassed normal editing, or an outbound-link system made destinations changeable after approval.

    This separates individual page defects from systemic abuse. If the same account created false authors, generated pages, and inserted commercial links, removing the URLs without revoking that control leaves the mechanism intact. If a contract grants an external party broad publishing rights, the problem may persist even after a password change.

    Separate legitimate coverage from reputation exploitation

    Do not bulk-delete everything containing the words casino, betting, or gambling. A news organization may have valid reasons to cover regulation, addiction, sports sponsorship, corporate results, consumer risk, crime, or technology. Destruction without classification can erase legitimate journalism, break useful links, and make later review harder.

    Use the following questions as an editorial triage model. They are not a substitute for Google’s own case-specific decision or legal advice.

    1. What job does the page perform? A reporting page helps the reader understand an event, claim, risk, or decision. An acquisition page is organized around sending the reader to an operator.
    2. Why does it belong on this publication? Audience need, newsroom expertise, and an established coverage remit are defensible reasons. Access to a strong domain is not.
    3. Who commissioned and controlled it? Identify an accountable editor and the editorial rationale. “The partner supplied it” is a warning, especially when the partner also benefits from clicks or losses.
    4. What evidence is unique to the page? Look for original reporting, attributable analysis, transparent methodology, or clearly sourced facts. Generic rewrites surrounding a commercial link provide little editorial justification.
    5. Is the author real and responsible? Confirm the person, assignment, expertise, edits, and correction path. Do not infer legitimacy merely because a profile exists.
    6. Is monetization subordinate to editorial purpose? Commercial links should not dictate the topic, conclusion, rankings, or recommendation. Disclosure is necessary when a relationship exists, but disclosure does not neutralize a compromised purpose.
    7. Would you publish it without search traffic or affiliate payment? This counterfactual exposes pages whose only rationale is borrowed ranking power.

    Classify each URL as keep, rebuild, remove, or escalate. Keep pages with a defensible public-interest purpose and accountable production. Rebuild pages where the subject belongs but the sourcing, identity, disclosures, or commercial balance do not. Remove pages built primarily to exploit inherited reputation. Escalate anything involving disputed ownership, contractual duties, regulatory exposure, impersonation, or evidence that may need to be preserved.

    An AI label does not change that classification. Neither does fluent prose. The relevant question is whether a responsible newsroom stands behind the page and can show why it exists.

    Contain the abuse before attempting a ranking recovery

    Containment comes first because continued publication can enlarge the affected footprint while the audit is underway. Recovery work should follow a controlled sequence.

    1. Pause suspect publishing and link changes. Freeze the affected workflow, not the entire newsroom, unless you cannot isolate it safely. Preserve access and activity records before disabling accounts.
    2. Create a recoverable evidence set. Back up the database and relevant files. Save the URL inventory, rendered pages, structured data, redirect chains, contracts, CMS histories, and approval records. If litigation, employment action, a regulatory inquiry, or contractual conflict is possible, let counsel set the retention process before anything is destroyed.
    3. Remove unauthorized control. Revoke unneeded CMS accounts, API keys, deployment access, redirect management, affiliate dashboards, and shared credentials. Review scheduled jobs and integrations that can recreate deleted pages.
    4. Apply the URL decisions. Keep legitimate reporting, rebuild salvageable coverage, and remove abusive pages. A removed page with no genuine replacement should return an appropriate not-found response. Redirect only when a truly equivalent destination exists; sending every deleted URL to the homepage hides the cleanup rather than preserving meaning.
    5. Clean the surrounding architecture. Update menus, category archives, author archives, internal links, sitemaps, canonical tags, feeds, related-content modules, and cached versions. Check subdomains and alternate templates so the same material is not still indexable elsewhere.
    6. Correct identity and schema. Delete fabricated profiles, restore accurate bylines, name accountable editors where appropriate, and align Article, Person, and Organization data with visible facts. Do not transfer a fake persona’s history to a new generic identity.
    7. Address the search action shown to you. If Google Search Console displays a manual action, use the process and scope described there after the cleanup is complete. Document what caused the problem, what was removed, what access changed, and which controls now prevent recurrence.

    Do not promise a quick return to previous visibility. In the documented pattern, some publications were deindexed, abandoned, closed, or affected by layoffs after penalties. Those outcomes show why ranking recovery is not the only objective. You are also protecting readers, employees, contributors, commercial partners, and the brand’s remaining credibility.

    Measure progress by more than aggregate organic traffic. Track whether removed URLs remain unavailable, alternate copies disappear, unauthorized outbound domains stay blocked, author records remain accurate, manual-action status changes, and legitimate sections recover stable discovery. A traffic rebound without control of the publishing system is not a durable recovery.

    Build controls around access, money, and identity

    News operations room with casino-related materials and cables isolated behind a transparent barrier beside locked access, payment, and identity controls.

    A policy that merely requires human editing will not prevent recurrence. A human can approve a deceptive page, and an AI system can assist with legitimate newsroom work. Put controls at the points where commercial incentives can override editorial responsibility.

    • Require a named internal owner for every section. That person should be able to explain its audience, commissioning standard, revenue relationship, correction process, and current contributors.
    • Separate publication from commercial destination control. Do not let one external partner create authors, publish pages, and change outbound targets without an independent review.
    • Maintain an approved-domain register. Record the owner, destination, jurisdictional review, affiliate relationship, approver, and permitted context for every gambling-related outbound domain. Re-review a link when its final redirect destination changes.
    • Make author creation a governed action. Require verifiable identity, a real editorial relationship, an accountable editor, and a documented correction route before a profile can publish.
    • Validate structured data against the CMS record. Flag mismatches between visible and machine-readable authors, publishers, reviewers, dates, and profile URLs. Do not generate Person entities merely because a content template expects one.
    • Review commercial topic pivots explicitly. A major expansion into casinos or cryptocurrency should require editorial, SEO, legal, and brand review before pages are commissioned, not after they rank.
    • Include publishing access in acquisition due diligence. Examine affiliate agreements, content ownership, CMS roles, redirect services, historical manual actions, high-volume directories, author authenticity, and any partner with post-publication control.
    • Audit AI workflows by risk, not by tone. Check provenance, claims, links, author accountability, disclosures, and approval. Polished language is not evidence of safe production.

    The most useful first move is small and concrete: export every URL in the affected section and add columns for owner, real author, editorial purpose, outbound destination, affiliate relationship, and decision. Any row you cannot complete has identified a control gap. Resolve those gaps before the next page is published.

    References


  • Unlock the Power of GSC’s Branded Query Filter for SEO Success

    Unlock the Power of GSC’s Branded Query Filter for SEO Success

    I recently delved into Google Search Console’s branded query filter, which has become a game-changer for SEO reporting. This feature now allows me to track brand awareness, diagnose performance drops, and truly measure the impact of my SEO efforts.

    In November 2025, Google introduced a solution to a long-standing SEO challenge: the ability to distinguish branded from non-branded search performance directly within Google Search Console (GSC). The rollout is now complete for eligible properties, and I was ecstatic to try it out.

    For so long, I’ve had to rely on regex filters, custom dashboards, or third-party tools, which weren’t always reliable. But GSC’s branded query filter simplifies the process, positioning it as a native feature in a platform widely used for organic reporting.

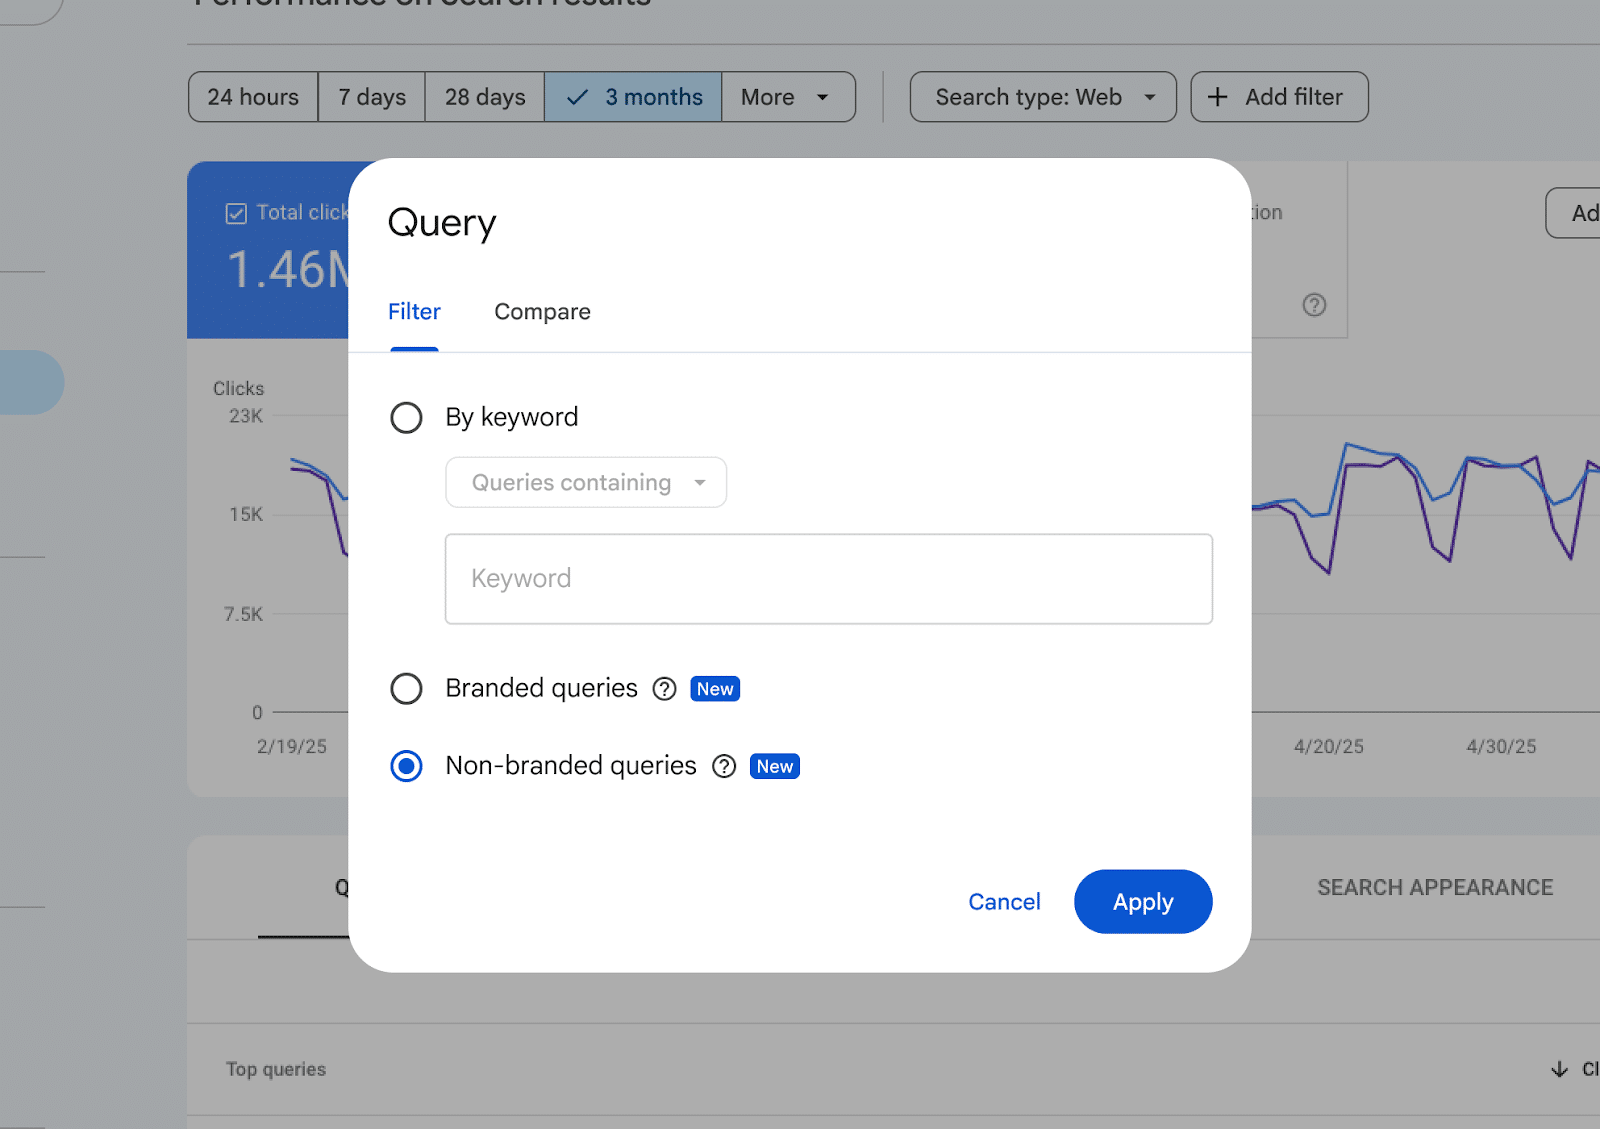
    ```json
{
  "alt": "Search query filter options in a web analytics tool showing filters by keyword and query type.",
  "caption": "Explore search query trends with detailed filters: select by keyword or focus on branded versus non-branded queries for insightful analysis.",
  "description": "The image displays a query filter interface in a web analytics tool, featuring options to filter by keyword and prioritize either branded or non-branded queries. The interface is overlaid on a chart displaying click data over time, illustrating performance metrics for search results. Keywords: web analytics, search queries, data filtering."
}
```

    This change makes it easier for me to close a crucial gap in SEO reporting. Now, I can independently evaluate brand demand and discovery, leading to improved performance analysis supported by first-party data.

    In essence, GSC’s new filter performs its function by sorting queries into two categories:

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```
    • Branded queries that include recognized brand terms.
    • Non-branded queries covering all other discovery queries.

    This filter is accessible directly via:

    ```json
{
  "alt": "Line graph and analytics showing changes in clicks, impressions, CTR, and position over time.",
  "caption": "Diving into the data: This graph reveals key changes in clicks, impressions, CTR, and average position over the last three months compared to last year.",
  "description": "The image displays a line graph depicting trends in total clicks, impressions, CTR, and average position. The graph compares the last three months to the same period last year, highlighting a 31.74% decrease in clicks and a 32.72% decline in CTR. Impressions show a slight increase of 1.42%. Keywords: analytics, data visualization, SEO metrics."
}
```
    • Performance > Search results > + Add filter > Query.
    • Query groups.
    • API-accessible data exports.

    These features empower me to group queries by topic or intent, filter by branded and non-branded types, and create detailed reports without external processing.

    ```json
{
  "alt": "Graph showing interest over time with fluctuating blue line and descending green trend line from 2024 to 2026 in the US.",
  "caption": "Dive into the trend: This graph illustrates the ups and downs of interest from 2024 to 2026, showing a notable decline overall despite several peaks.",
  "description": "This image depicts a line graph representing interest over time from October 2024 to January 2026 in the United States. A blue line captures the fluctuating interest levels, with notable peaks in early and late 2025. Meanwhile, a green arrowed line indicates an overall downward trend. The graph provides an insightful visual representation of interest dynamics during this period, reflecting both temporary spikes and a general decline."
}
```

    Historically, separating branded from non-branded performance wasn’t new but maintaining consistency was challenging. I used to manually segment with regex, keyword tagging in rank-tracking tools, or through custom dashboards.

    These methods worked but were fragile. Common issues included character limits on regex, language variants for international sites, and no shared standard for branded terms. With GSC’s update, I find these challenges largely eliminated.

    ```json
{
  "alt": "Line graph comparing branded and non-branded CTR over time, showing notable variance from October 2025 to January 2026.",
  "caption": "Exploring the dynamics of branded versus non-branded CTR, this graph reveals intriguing trends from late 2025 into 2026.",
  "description": "This line graph illustrates the comparison between branded and non-branded click-through rates (CTR) over a period from October 2025 to early January 2026. The vertical axis represents the percentage of CTR, ranging from 0% to 25%, while the horizontal axis shows the timeline. The graph demonstrates fluctuating rates, with branded CTR peaking notably around early 2026, while non-branded CTR remains relatively steady and low throughout the period. This visualization provides insights into the effectiveness of brand recognition on digital engagement metrics. Keywords: Branded CTR, Non-Branded CTR, Click-Through Rate, Digital Marketing Analytics."
}
```

    Branded traffic is crucial, being both a signal of brand awareness and a major source of conversions. However, when mixed with non-branded data, it skews the interpretation of SEO performance.

    By segmenting this data, I can now accurately identify brand demand versus discovery, allowing clearer insights. This helps me to better understand what’s genuinely boosting performance and address key questions like:

    ```json
{
  "alt": "Line graph showing impressions over six months with a note about Google ending support for &num=100 on September 12.",
  "caption": "A dynamic graph illustrating search impressions over time, noting Google's change in support, influencing trends.",
  "description": "This image features a line graph depicting the number of impressions over a six-month period. It includes an annotation on September 12, highlighting Google's end of support for &num=100. The graph shows a fluctuating trend with notable spikes, marked by a vertical guide at the annotation point. Useful for observing impact on search performance metrics."
}
```
    • Are we enhancing brand demand or expanding non-branded reach?
    • Is our content strategy bolstering non-branded visibility?
    • Is the current strategy effective as anticipated?

    Having used the filter, branded search trends have become one of the clearest indicators of brand health. Monitoring these trends reveals gaps and provides opportunities across various channels.

    This functionality isn’t just a feature; it signifies a paradigm shift in SEO measurement. The consistency it brings to branded versus non-branded reporting is transforming how SEO work gets done, making reporting more consistent and actionable.

    As I continue to evaluate and use these insights, I find that adopting this feature means less time spent reconciling data and more focus on interpreting results. This results in more confident and consistent communication, ultimately driving greater impact.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Enhance Forum Visibility: Google’s New Structured Data Update

    Enhance Forum Visibility: Google’s New Structured Data Update

    I recently discovered that Google has enhanced its structured data support for forum and Q&A pages. This update introduces new properties that allow us to better signal reply threads, quoted content, and identify whether content is generated by AI or humans.

    With these changes, which aim to boost Google’s accuracy in interpreting discussions and Q&A content, we can now ensure our content is represented more precisely.

    What’s New. Google has updated its QAPage documentation to include commentCount and digitalSourceType. Moreover, the DiscussionForumPosting documentation now supports sharedContent alongside these new properties.

    The Details. Using Q&A markup, I’m able to apply commentCount to questions, answers, and comments, showcasing the total number of comments even if they are not fully marked up. This total should align with answerCount + commentCount, representing all types of replies.

    How It Works. The digitalSourceType property allows me to indicate whether content is produced by a model or simple automation. I can use TrainedAlgorithmicMediaDigitalSource for advanced outputs and AlgorithmicMediaDigitalSource for basic bots. If this property is left out, Google assumes the content is human-generated.

    What’s New for Forums. The sharedContent property helps me to mark the primary item that’s being shared in a post. Google supports various content types like WebPage, ImageObject, and more, including quotes or reposts.

    Why This Matters. This update provides me with greater control over how Google interprets community content, which is particularly important for sites rich in forums, support communities, UGC platforms, and Q&A sections. Google can now distinguish between answers and comments more effectively, tally partial threads across multiple pages, and recognize when a post primarily shares specific media types.

    Documentation. The official documentation was updated on March 24, providing all the details I need to apply these new capabilities.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How to Control Paid Advertising Costs Without Killing Growth

    How to Control Paid Advertising Costs Without Killing Growth

    Your click costs are rising, the budget is disappearing faster, and the obvious response is to cut bids or pause anything expensive. That may save cash this week. It can also remove the clicks that were most likely to become customers.

    The number you need to control is not CPC in isolation. It is the amount you pay for a qualified lead or customer within your margin, cash-flow, and growth constraints. Once that ceiling is explicit, you can distinguish a costly auction from a wasteful campaign and act on the right problem.

    Set your cost ceiling from the sale backward

    An unbranded customer parcel and coins are connected through transparent chambers that reduce the available amount toward the advertising end.

    A campaign is not efficient merely because its CPL is below an industry benchmark. A cheap lead that never reaches the sales team is expensive. A high-CPC click that becomes a profitable customer may be entirely acceptable.

    Start by defining exactly what your account calls a conversion. A form submission, a qualified lead, a booked meeting, an approved opportunity, and a sale are different outcomes. If several campaigns optimize toward different definitions while reporting one blended CPA, the resulting number cannot guide a budget decision.

    MetricBasic calculationWhat it helps you control
    Cost per clickMedia spend divided by clicksAuction and traffic-acquisition cost
    Click-to-lead rateLeads divided by clicksOffer, message, landing-page, and form performance
    Cost per leadMedia spend divided by leadsTop-of-funnel acquisition efficiency
    Lead-to-customer rateCustomers divided by leadsLead quality and sales conversion
    Customer acquisition costScoped acquisition cost divided by new customersActual business economics, provided you state which costs are included

    Work backward using your own mature conversion data:

    • Maximum customer acquisition cost: Set this from contribution margin, acceptable payback, retention confidence, and cash constraints. Do not base it on revenue alone. Revenue that disappears into fulfillment costs cannot fund acquisition.
    • Maximum CPL: Multiply maximum customer acquisition cost by your lead-to-customer rate.
    • Maximum CPC: Multiply maximum CPL by your click-to-lead rate. For a direct-purchase campaign, multiply maximum CPA by the click-to-purchase rate instead.
    • Affordable volume: Divide the available budget by the target cost for the outcome you are buying.

    Use completed cohorts, not the newest leads in your CRM. If your sales cycle is still open, recent leads will appear artificially weak. If retention is uncertain, use a conservative customer value rather than borrowing from an unproven lifetime-value forecast. The downside of optimism here is not a reporting error; it is a budget that scales unprofitable demand.

    External benchmarks provide context, not permission to spend. Google Ads click costs reached an average of $5.26 across sectors in 2025, while nearly 87% of industries experienced a year-over-year increase. Legal services averaged $8.58, and some competitive B2B segments reached $8 to $9. Those figures tell you that inflation is widespread. They do not tell you what a click is worth to your business.

    Higher CPC can coexist with stronger economics. Roughly 65% of industries also experienced higher conversion rates. A more expensive visitor who is further along in the buying process can produce a lower CPA than cheaper, low-intent traffic. Judge the complete equation.

    Find which part of the acquisition equation broke

    For a one-step conversion, CPA can be expressed as CPC divided by conversion rate. For a lead-generation funnel, customer acquisition cost is influenced by CPC, click-to-lead rate, lead qualification, and lead-to-customer rate. That decomposition turns a vague cost problem into a specific diagnosis.

    • CPC rose while conversion rate held: Inspect auction pressure, targeting breadth, search-query intent, placements, and bidding behavior. The landing page is unlikely to be the primary cause.
    • CPC held while click-to-lead rate fell: Check whether the ad promise still matches the offer, whether the traffic mix changed, and whether the page or form introduced friction.
    • CPL held while lead-to-customer rate fell: The account may be buying easier conversions rather than better prospects. Review qualification criteria, source mix, and the outcome being returned to the ad platform.
    • Platform CPA held while CRM acquisition cost rose: Audit duplicate events, attribution differences, missing offline outcomes, and the definition of a conversion. The bidding system may be optimizing toward an event that no longer represents business value.
    • Every stage weakened at once: Look for a structural change before making several tactical edits. A new market, altered offer, tracking release, inventory shift, or broad targeting change can affect the entire funnel.

    Run the diagnosis in a fixed order so that a measurement defect does not become a bidding decision:

    1. Validate the primary conversion. Confirm that it fires once, reaches the correct account, and represents the outcome named in the report.
    2. Reconcile advertising data with the CRM. Compare leads, qualified leads, opportunities, and customers by campaign. Return first-party outcomes to the bidding system when the platform and your consent framework support it.
    3. Separate unlike traffic. Split branded from nonbranded search, informational from transactional queries, prospecting from remarketing, and major audience or placement groups.
    4. Use mature cohorts. Allow enough time for the normal conversion and sales lag before declaring recent traffic unprofitable.
    5. Choose one failing stage. Apply the lever closest to that stage, then record the change so its effect is not confused with simultaneous edits.

    Query intent deserves special attention as search-result layouts change. Across 3,119 terms at 42 organizations in a late-2025 analysis, paid CTR on queries displaying AI Overviews declined by 68%, from 19.7% to 6.34%. That result does not establish the same decline for every account, but it identifies a mechanism worth checking: informational searches can expose fewer visible paid placements while satisfying more users directly on the results page.

    Label your search terms by intent rather than treating every keyword in an ad group as equivalent. Move budget away from informational queries that consume spend without producing qualified outcomes. Preserve transactional terms when their downstream CPA remains viable, even if their CPC looks unattractive beside cheaper research traffic.

    Reduce auction pressure you can actually control

    A marketing operator adjusts audience, timing, and creative controls beside a crowded stylized advertising auction.

    You cannot remove every competitor or reverse market-wide CPC inflation. You can decide which auctions to enter, what signal to optimize, how much loss an experiment may incur, and whether another party is unnecessarily raising the cost of your own demand.

    Start with branded search. Affiliates, partners, resellers, and competitors that bid on your trademarked terms add auction pressure to demand your organization already created. Unauthorized bidding can make you pay to generate awareness and then pay again to recover the resulting searcher.

    Do not rely on an occasional search from headquarters. Some unauthorized bidders may use geographic exclusions, device targeting, or schedules outside normal business hours to reduce the chance of detection. Monitor the locations, devices, and times where customers actually search. Preserve the query, ad copy, landing page, date, location, and device as evidence. If contractual or trademark rights are uncertain, route enforcement through the appropriate partner manager or legal adviser rather than improvising a threat.

    Then put guardrails around automated bidding. Auction-time systems can adjust bids using predicted conversion likelihood, but they can only optimize the outcomes and data you provide. If low-value and high-value conversions share the same signal, the system has no reason to prefer the one your finance team values.

    • Separate campaigns with different economics. Products with different margins, lead types with different close rates, and geographies with different service costs should not inherit one blended target merely for convenience.
    • Optimize toward the deepest reliable outcome. A qualified or completed outcome is more useful than a plentiful form event, provided you can send it back consistently and with enough timeliness to guide bidding.
    • Cap experimental exposure before launch. State the maximum spend or loss you will accept while testing an audience, query class, offer, or format. A budget is a risk boundary, not evidence that every dollar must be spent.
    • Write the stop rule in advance. Stop when tracking is invalid, the test reaches its loss limit, or a mature cohort remains above the economic ceiling. This prevents a weak campaign from surviving because the team has already invested in it.
    • Change one primary variable at a time. A simultaneous bid, audience, creative, and landing-page change may improve results, but it will not tell you which control worked.
    • Scale on qualified economics. Do not increase budget solely because the platform reports a cheaper conversion. Confirm qualification and downstream movement first.

    Manual bidding is not automatically safer, and automation is not automatically efficient. The right choice is the one that lets you enforce the campaign’s economic boundary while supplying a trustworthy conversion signal. The budget, target, exclusions, and outcome definition still belong to you.

    Make the offer absorb part of the cost pressure

    On paid social, cost control often begins before the auction. A weak offer forces the bidding system to buy more impressions and clicks to produce each lead. A useful, timely offer can raise response without requiring the cheapest inventory.

    A focused LinkedIn test illustrates the point. The campaign targeted about 54,000 B2B marketing decision-makers with a 23-page demand-generation playbook timed to the 2026 planning cycle. A document ad let people preview the material, and an autofilled lead form reduced the work required to download it.

    The campaign used a $600 lifetime budget and a $15 manual bid ceiling. It produced 60 qualified leads at less than $10 per lead, with an average CPC of $5.41 and a 76% lead-form completion rate. This was one controlled B2B campaign, not a universal LinkedIn benchmark. Its useful lesson is the relationship among audience knowledge, timing, content depth, previewability, and form friction.

    Build that relationship deliberately:

    1. Find the expensive problem before creating the asset. Mine customer questions, sales objections, client interactions, CRM notes, and audience behavior for a problem specific enough to support one clear promise.
    2. Match the offer to a decision window. A planning resource is more useful while the buyer is planning. Timing is part of relevance, not merely a scheduling setting.
    3. Show evidence of value before asking for data. A preview, concrete contents, or a precise explanation of what the buyer will be able to do reduces uncertainty around the exchange.
    4. Keep the ad and asset on the same promise. If the ad attracts curiosity that the asset does not satisfy, clicks may rise while form completion and lead quality fall.
    5. Ask only for fields you will use. Every required field adds friction. If a field does not affect routing, qualification, personalization, or follow-up, remove it.
    6. Define qualified before launch. Agree on the roles, company characteristics, need, or downstream action that makes a lead valuable. Report both raw CPL and qualified CPL.
    7. Use feedback to revise the offer. The first launch should reveal which sections people value, which questions remain unanswered, and whether the promised problem was important enough to justify follow-up.

    Do not copy the visible details mechanically. A 23-page asset is not better because it has 23 pages, and a $15 ceiling will not recreate a $5.41 CPC in another auction. Copy the operating logic: narrow audience research, a substantial answer to a current problem, low conversion friction, bounded spend, and qualification beyond the platform form.

    This is also where paid advertising and organic authority can support each other. The questions that earn qualified paid responses can inform deeper public content, structured explanations, and answer-ready pages. The purpose is not to disguise an ad as organic content. It is to reuse verified audience language so that your paid, search, and AI-discovery work answer the same real buyer need.

    Key takeaways

    • Set maximum CAC, CPL, and CPC from contribution economics and mature conversion rates, not an external CPC benchmark.
    • Treat CPC as a diagnostic input. The decision metric is the cost of the deepest trustworthy outcome your business can measure.
    • Decompose rising acquisition cost into auction cost, post-click conversion, qualification, and sales conversion before changing bids.
    • Separate branded, informational, and transactional traffic so cheap low-intent clicks cannot hide the value of higher-intent demand.
    • Protect branded auctions, improve first-party conversion signals, and impose test budgets and stop rules before spending begins.
    • On paid social, use audience-specific timing, a genuinely useful offer, and a low-friction path to improve qualified CPL without depending on cheap clicks.

    At your next account review, open the last complete conversion cohort and add three columns to the campaign report: the maximum allowable cost, the qualified conversion rate, and the downstream customer result. Split brand from nonbrand and high intent from informational traffic. Then choose the single stage with the largest economic gap and change the control closest to it. That is how cost control becomes a repeatable operating system instead of a recurring budget cut.

    References