Author: shivamcrushpressai

  • Cross-Platform Influencer SEO: A Practical Framework

    Cross-Platform Influencer SEO: A Practical Framework

    You can pay for a creator campaign, get a burst of attention, and still end up with content that disappears as soon as the feed moves on. The missed opportunity is not more distribution. It is making each creator asset clear enough to be found when someone searches for the problem, product category, comparison, or use case it addresses.

    The fix starts before the creator records anything. You need to connect a real search question to the right creator, build the answer into the content, adapt that answer to each platform, and measure whether it remains visible after publication.

    Treat every creator asset as part of the search journey

    A buyer rarely completes a considered search in one place. Someone looking for the best lightweight running shoes might discover options on TikTok, request a comparison from ChatGPT, inspect commentary through Google, and then visit a brand site. Creator content can influence several points in that journey, even when the buyer never visits the creator’s profile directly.

    Google can surface social opinions through features such as “What people are saying,” including material from YouTube, TikTok, LinkedIn, and other platforms. Social and video content can also supply context for AI-generated answers. Your influencer program therefore creates search inventory whether or not the campaign team manages it that way.

    Cross-platform influencer SEO does not mean copying the same caption everywhere. It means preserving a recognizable answer while changing the presentation for each environment. The product name, category, use case, audience, and factual claims should remain stable. The hook, pacing, depth, visual treatment, and call to action can change.

    This distinction prevents two common failures. A generic awareness video may be entertaining but give a search system little information about the question it answers. An over-optimized script may contain the right phrase repeatedly but sound unnatural enough to weaken the creator’s authority. Effective creator SEO keeps the subject unmistakable without turning the content into a spoken keyword list.

    Key takeaways

    • Choose a search question tied to a decision the audience is actually making.
    • Match that question with a creator who can demonstrate or explain the answer credibly.
    • Carry the topic into spoken words, on-screen text, captions, titles, descriptions, and relevant hashtags.
    • Keep names, use cases, qualifiers, and approved claims consistent across platforms.
    • Measure native search, Google visibility, AI visibility, content usefulness, and business outcomes separately.

    Map the query to the decision and the creator
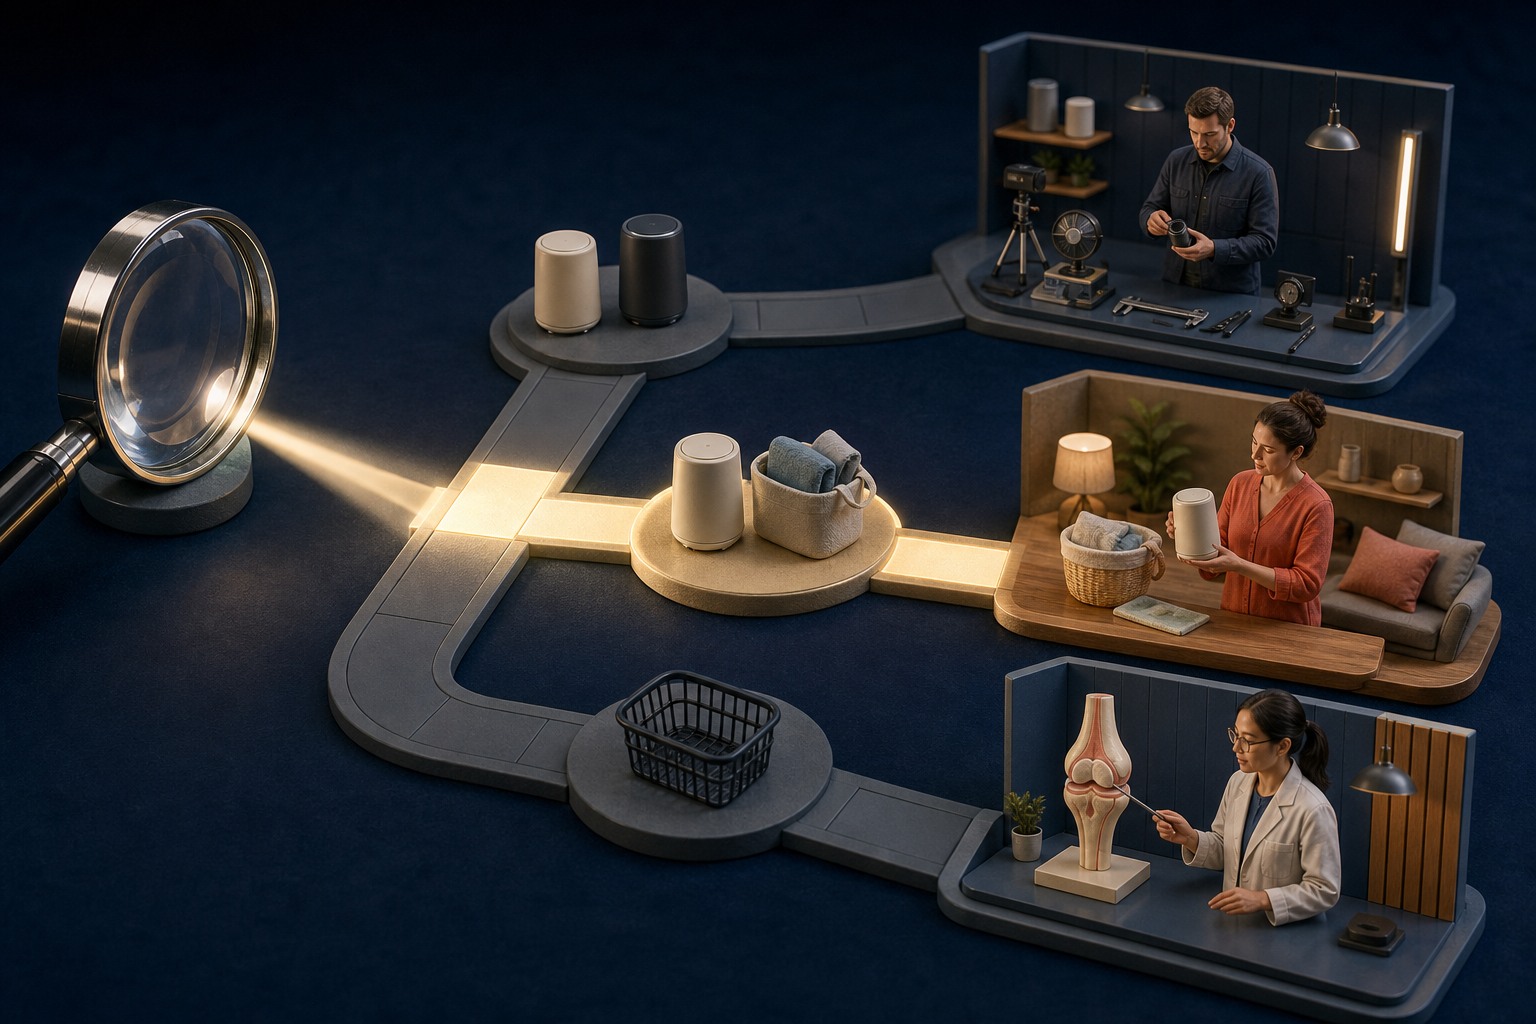
    A magnifying lens, branching paths, product decision objects, and three miniature creator studios illustrate matching a search need to a creator.

    Do not begin with a creator roster and look for keywords to attach later. Begin with the audience decision. Is the searcher trying to understand a category, compare alternatives, check whether a product suits a particular use case, validate a concern, or decide what to buy?

    That decision determines the form of the content. A broad educational query may need a clear explanation. A comparison query needs visible criteria. A suitability question needs a demonstration under the relevant conditions. A purchase-stage query needs specific trade-offs and a useful next step.

    Build the query set from evidence already available to your teams: organic search insights, native platform trends, recurring questions in creator comments, customer language, and tools such as AnswerThePublic. Keep the audience’s wording intact during collection. You can consolidate variants later, but early normalization often removes the precise qualifier that reveals intent.

    For example, “running shoes” identifies a category. “Best lightweight running shoes for travel” identifies a category, comparison, desired attribute, and use case. The longer expression gives the creator something concrete to answer and gives you a much better basis for evaluating the finished asset.

    Planning fieldWhat to recordReview question
    Audience decisionThe choice, concern, or uncertainty behind the searchWhat should the viewer be able to decide after watching?
    Search expressionThe natural wording used by the intended audienceDoes the wording preserve important qualifiers?
    Required answerThe useful conclusion the content must deliverDoes the asset answer the query rather than merely mention it?
    Proof formatDemonstration, explanation, comparison, walkthrough, or opinionCan this creator show the answer credibly?
    Creator fitThe creator’s relevant subject history, audience, and format strengthsWill the recommendation feel consistent with their existing work?
    Platform roleDiscovery, detailed evaluation, professional validation, or conversion supportWhy does this asset belong on this platform?
    DestinationThe next page, video, profile, or action that continues the journeyDoes the next step satisfy the same intent?

    Creator selection should follow the map. Look for a history of discussing the relevant problem, a format capable of showing the required proof, and audience responses that indicate genuine interest in the subject. Reach matters to distribution, but topical fit determines whether the answer feels believable and whether the asset has a coherent search purpose.

    Share the query language with the creator before locking the script. A creator may know a more natural way to express the same intent. Accept that adjustment when it preserves the audience, problem, category, and meaning. Search optimization needs semantic clarity, not forced recitation.

    Write a search-ready brief without scripting out the creator

    A weak brief says, “Mention the product naturally and add these hashtags.” That tells the creator what must appear but not what the content must answer. It also leaves the campaign team unable to judge whether the deliverable serves a searcher.

    A search-ready brief states the audience decision, target query, required answer, evidence, placement of topic signals, approved claims, creative freedom, and next step. The creator should know which parts are mandatory and which parts they own.

    • Search objective: Describe the question or decision the asset should help resolve.
    • Primary topic: Supply the natural query and acceptable variations, including any qualifier that changes intent.
    • Required answer: State what useful conclusion the viewer should receive. Do not prescribe a positive verdict that the evidence cannot support.
    • Topic placements: Identify where the subject should appear, such as the spoken script, opening frame, on-screen text, caption, title, description, and relevant hashtags.
    • Proof: Specify the demonstration, comparison criteria, walkthrough, or factual context needed to support the answer.
    • Entity language: Provide the correct brand, product, category, feature, and use-case names. Mark any wording that must remain exact for accuracy.
    • Creative control: Leave room for the creator’s hook, examples, visual language, pacing, and personal assessment.
    • Next step: Name the destination that continues the same search intent rather than sending every viewer to a generic homepage.

    The required topic should normally appear in more than one content layer. Spoken language helps make the subject explicit in the actual video. On-screen text helps a viewer recognize the answer quickly. The caption, title, and description provide written context. Relevant hashtags can reinforce classification, but they should not carry the entire strategy.

    Use a pre-publication review that tests clarity rather than keyword density:

    • Can a viewer identify the question during the opening portion of the asset?
    • Does the creator answer the question with an explanation or visible proof?
    • Is the primary topic spoken naturally?
    • Does on-screen text name the subject without covering important visuals?
    • Does the caption add context instead of repeating a thin promotional line?
    • Is the title or description complete enough to stand on its own outside the feed?
    • Are brand, product, category, and use-case names accurate and consistent?
    • Are all factual and comparative claims supportable?
    • Does the final result still sound like the creator?

    If a phrase sounds awkward, change the sentence rather than deleting the subject. If the creator cannot answer the assigned query credibly, change the query or the creator. No amount of metadata can repair a mismatch between the question and the person delivering the answer.

    Adapt the answer instead of duplicating the asset
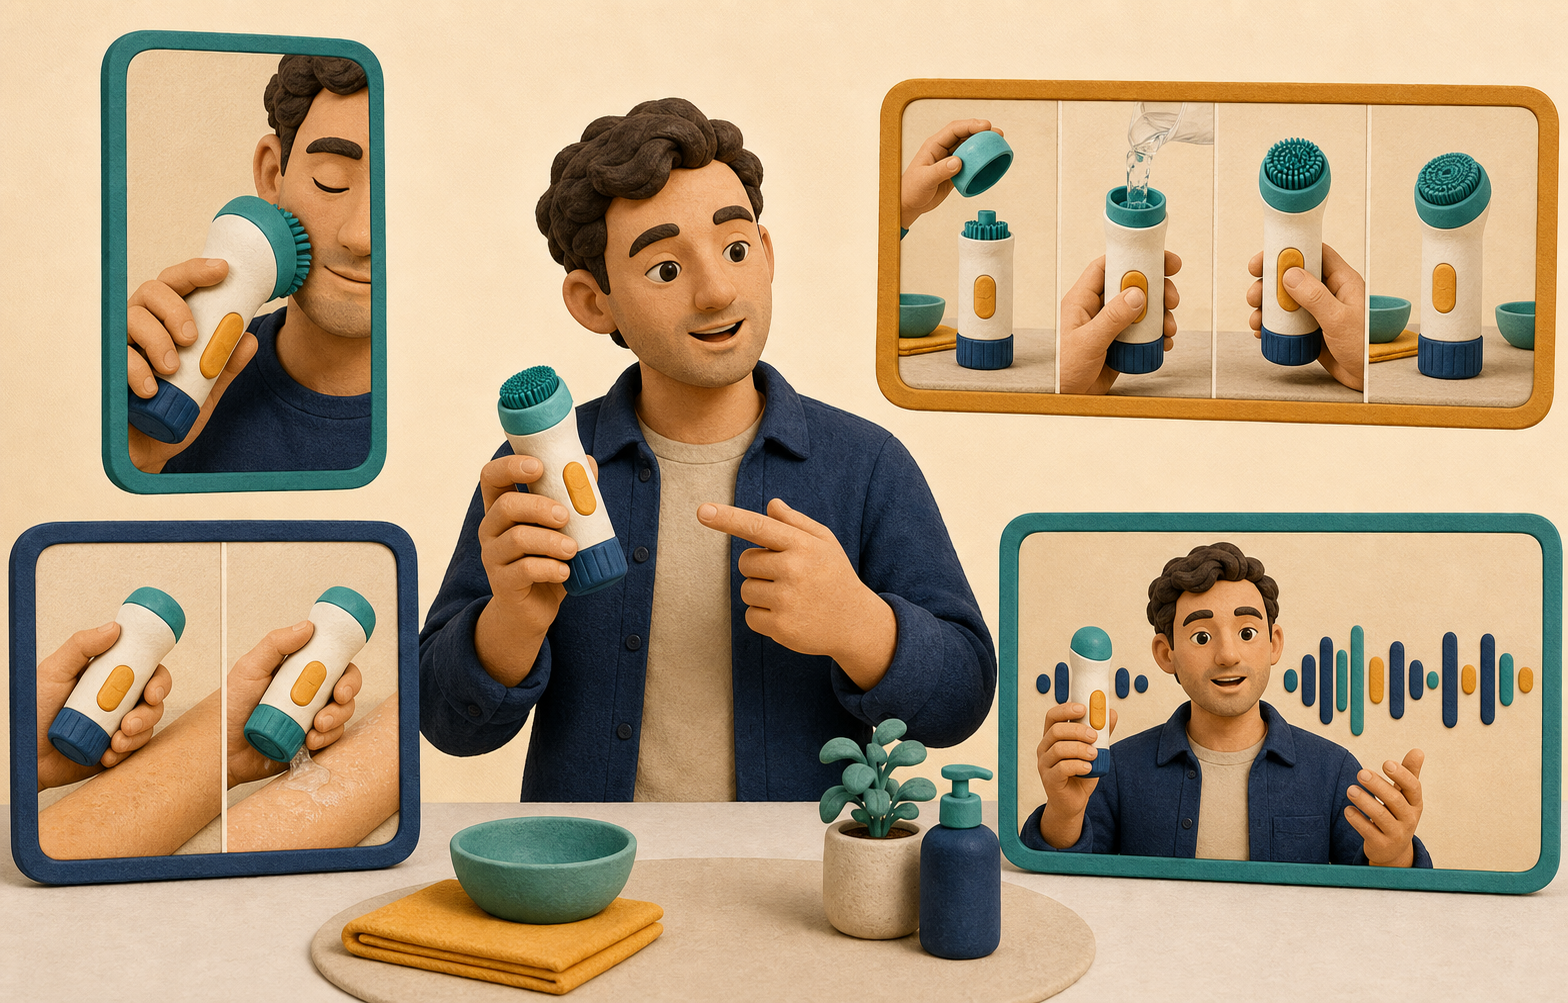
    One product demonstration is adapted into vertical, horizontal, square, and audio-focused content frames around a creator's workbench.

    Each platform gives the same core answer a different job. Short video may introduce the question and show fast proof. YouTube can accommodate a fuller explanation. LinkedIn can frame the issue around professional decisions. A brand page can verify details and continue the journey. The campaign becomes cross-platform when these assets reinforce one another, not when the same file is uploaded repeatedly.

    Platform or surfaceRecommended jobHow to adapt the core answerWhat to avoid
    TikTok and other short-form videoQuestion-led discovery and concise demonstrationMake the problem recognizable in the hook, say the topic naturally, show the proof, use readable on-screen language, and write a contextual captionA trend-led opening that never makes the actual subject clear
    YouTubeDetailed evaluation and explanationUse a descriptive title, establish the question clearly, cover the relevant criteria, and write a complete description that identifies products, categories, use cases, and conclusionsA vague title or a nearly empty description that depends on viewers already knowing the context
    LinkedInProfessional interpretation and validationLead with the business problem or decision, name the category and audience, and preserve the creator’s analysis rather than reducing the post to campaign copyOpening with brand promotion before establishing why the issue matters
    Brand-owned pageVerification and continuationAlign terminology and approved claims with the creator asset, provide deeper product information, and link or embed the creator content when rights allowSending an intent-rich query to a generic page that does not answer it
    Google and AI answer surfacesSecondary discovery of published creator materialMonitor whether the underlying social or video asset appears for the intended topic and whether its language is represented accuratelyTreating a variable AI response as a permanent ranking

    YouTube deserves particular attention when the subject requires depth. Comprehensive video descriptions can improve the contextual information available to search and AI systems, including for smaller channels. A description should identify what the video covers, which audience or use case it addresses, what is demonstrated, and where the viewer can verify or continue the answer. A link by itself does none of that work.

    Consistency matters across every version. Use the same accurate spelling for the brand and product. Keep the category relationship explicit. Preserve important qualifiers such as audience, location, compatibility, or intended use. Do not let one creator call a feature by a campaign nickname while the landing page, video title, and other creators use unrelated terms.

    Consistent language can give AI systems clearer evidence when connecting a brand with a category or recommendation context. It cannot guarantee a citation or favorable answer, but it removes avoidable ambiguity. Creative variation should change the expression, not the underlying facts.

    Cross-platform expansion also needs editorial discipline. Do not manufacture praise in community spaces or ask creators to disguise sponsored material as an independent conversation. Genuine comments and questions are more useful as audience-language research: record how people describe the problem, then feed those expressions into future query maps and briefs.

    Measure visibility, usefulness, and business impact separately

    A creator asset can succeed in one layer and fail in another. High engagement does not prove search visibility. Search visibility does not prove the answer is useful. Neither one, by itself, proves commercial impact. A single blended campaign score hides the diagnosis you need to improve the next brief.

    Build a record for every published asset that includes the creator, platform, URL, target query, important variations, audience decision, publication date, destination, and campaign identifier. Without that connection, teams can see performance but cannot tell which search intent or content treatment produced it.

    Search visibility

    • Check the native platform for the assigned query and meaningful variants.
    • Inspect Google results for the creator URL, video results, social modules, and relevant “What people are saying” placements.
    • Use a stable set of AI prompts that reflects the target decision. Log the service, model when shown, date, response, cited pages, and whether the creator or brand is represented accurately.
    • Record visibility by query and surface. Do not combine native placement, Google appearance, and AI mentions into an invented universal rank.

    Content usefulness

    • Review retention or viewing patterns to locate the point where attention drops.
    • Track saves, shares, and substantive comments that indicate the answer was useful enough to keep or pass along.
    • Separate query-relevant questions from generic reactions. New questions may reveal missing information or the next search intent to target.
    • Compare performance with the creator’s own relevant historical content when possible, not with an unrelated platform-wide expectation.

    Business impact

    • Track visits to the intended destination with campaign-specific links where the platform permits them.
    • Measure whether visitors engage with the page that continues the answer, rather than counting the click alone.
    • Review attributed and assisted conversions in the context of a multi-platform journey. A last-click report will not describe every earlier creator interaction.
    • Watch whether the questions and terms used in creator content begin appearing in site search, sales conversations, or other audience feedback available to your organization.

    The pattern across these layers tells you what to fix. If the asset is useful to viewers but absent from search checks, strengthen topic placement, titles, descriptions, and query alignment. If it is visible but loses attention, improve the answer, proof, hook, or creator fit. If it earns visibility and engagement but produces no useful next action, inspect the call to action, destination, offer, and measurement setup. If different platforms describe the product inconsistently, repair the entity language in the shared brief.

    The operating model matters as much as the brief. SEO and influencer teams often sit in separate workflows with different goals, so create a shared handoff:

    1. The SEO team supplies the audience decision, query language, qualifiers, and relevant search surfaces.
    2. The influencer team maps those needs to creators, platforms, formats, and campaign constraints.
    3. The creator proposes a native angle and identifies any keyword wording that would sound forced.
    4. The campaign owner reviews the draft for answer quality, search signals, factual consistency, and creator voice.
    5. The publishing owner completes every agreed title, caption, description, text, hashtag, and destination field.
    6. The measurement owner records the asset and checks each visibility, usefulness, and business layer.
    7. The teams convert findings into changes to the query map, creator selection, brief, or destination before the next activation.

    Start with your next creator brief. Add the audience decision, natural query, required answer, proof format, topic placements, consistent entity language, and destination. If you cannot name those elements before production begins, the campaign is not yet ready to work as search content.

    References


  • Google March 2026 Spam Update: How to Audit a Traffic Drop

    Google March 2026 Spam Update: How to Audit a Traffic Drop

    If your organic visibility changed around March 24 or 25, you need a diagnosis before you need a rewrite. The timing makes the March 2026 spam update a reasonable lead, but it does not prove that Google found spam on your site.

    The safest response is to preserve your data, isolate the pages and queries that moved, and then audit the affected systems against Google’s spam policies. That sequence keeps a narrow problem from turning into a rushed sitewide overhaul.

    What changed, and what Google did not disclose

    The update began on March 24, 2026, at 3:20 p.m. ET and finished on March 25 at 10:40 a.m. ET. The entire rollout lasted 19 hours and 30 minutes. It was Google’s second announced algorithm update of 2026.

    Google did not identify a particular form of spam targeted by this release. That omission should shape your investigation. You cannot responsibly label it a link update, an AI-content penalty, a scaled-content crackdown, or any other specific action from the announcement alone.

    Automated spam detection operates continuously. SpamBrain is the AI-based system Google uses to help identify search spam, and notable improvements to these automated systems are announced as spam updates. The named rollout window marks a substantial systems change; it does not mean spam detection was switched off before the update or stopped evolving afterward.

    For you, the important distinction is between correlation and diagnosis. A decline that begins near the rollout deserves investigation. A decline confined to one template, country, device class, query family, or recently edited section may point somewhere more specific than a sitewide spam assessment.

    Diagnose the loss before changing the site

    Abstract filters and a magnifying lens isolate a small amber cluster of affected pages and query nodes from a larger blue system.

    Do not begin by deleting pages, removing links, or rewriting every AI-assisted passage. First establish what actually changed. Use the rollout timestamps as the center of your analysis, then work from broad signals toward individual URLs.

    1. Mark the rollout in your reporting. Add March 24 at 3:20 p.m. ET through March 25 at 10:40 a.m. ET to your SEO annotations. Keep the exact window visible so later releases, migrations, campaigns, and tracking changes are not blended into the same event.
    2. Separate search visibility from website performance. Compare Google Search Console impressions, clicks, click-through rate, and average position with analytics sessions and conversions. Falling impressions across stable query demand point toward lost search visibility. Stable impressions with weaker clicks may indicate a result-page or snippet issue. Stable search data with falling conversions sends the investigation toward tracking, user experience, offer, or funnel changes.
    3. Segment the affected demand. Split branded from non-branded queries, then examine countries, devices, directories, content types, and page templates. A concentrated loss is more actionable than a domain-level percentage because it tells you where to inspect purpose, production methods, internal links, structured data, and external link dependence.
    4. Compare equivalent groups. Look at affected pages beside genuinely similar pages that stayed stable. Compare intent, depth, originality, authorship, update practices, internal linking, backlinks, and template behavior. The stable group is your control; it helps you avoid blaming a characteristic shared by both winners and losers.
    5. Rule out coincident failures. Check release logs, crawling and indexing signals, robots directives, canonicals, redirects, server availability, security events, analytics deployments, and the Manual Actions report. An automated spam update and a manual action are not the same event, while an accidental noindex or canonical change can imitate an algorithmic loss.
    6. Preserve the evidence. Export the affected query and page data, save the current templates, and record recent content, link, schema, and deployment changes before editing. Without a baseline, you will not know whether a later movement came from remediation, normal volatility, or another release.

    This process should leave you with a statement more precise than “traffic dropped after the update.” A useful diagnosis sounds like this: non-branded impressions declined for one programmatic directory, while editorial pages and branded demand remained stable. That is a testable problem with a bounded audit surface.

    Run a policy audit that produces evidence

    An analyst sorts abstract website pages and suspicious link patterns into evidence folders during a digital policy inspection.

    Once you know which pages, queries, or systems are implicated, audit the decisions behind them. The goal is not to make content look less automated or more polished. It is to identify elements created primarily to manipulate search visibility and replace them with pages, links, and markup that serve a defensible user purpose.

    Start with page purpose and production

    For each affected page type, ask whether the URL resolves a distinct task. Pages that differ only by swapped keywords, locations, products, or entities need enough unique substance to justify separate URLs. If the page would have no reason to exist without the opportunity to capture another query variation, treat that as a warning that requires closer review.

    • Identify the source of the page’s facts and whether someone verified them before publication.
    • Check whether the title, opening answer, body, and call to action all satisfy the same search intent.
    • Look for unsupported claims, invented specificity, repetitive sections, placeholder language, and passages that merely restate information already visible elsewhere.
    • Review generated or templated pages at the system level. Fixing a prompt, data feed, template, or approval gate may be more reliable than hand-editing isolated outputs.
    • Confirm that materially similar URLs are consolidated, differentiated, or removed for a documented reason rather than retained solely for query coverage.

    AI assistance is not a useful diagnosis by itself. Purpose, accuracy, added value, and production controls are more useful audit dimensions. A carefully verified AI-assisted page and an unreviewed page assembled by a person should not be judged by the tool label alone.

    Trace rankings that depended on links

    Review links separately from content because the recovery mechanics may be different. Map suspicious acquisition activity to the pages and query groups that lost visibility. Paid placements, reciprocal arrangements, controlled networks, repeated commercial anchors, and sudden footprints across related sites deserve review, but an unattractive backlink profile does not prove that this March release was link-specific.

    Do not start a destructive link cleanup from rollout timing alone. First document which links were arranged by you or your representatives, what benefit they appeared to support, and whether the affected rankings were unusually dependent on them. If an update neutralizes spammy links, the ranking benefit previously produced by those links cannot be recovered simply by removing or changing them. A later improvement would need to come from legitimate signals, not restoration of the neutralized advantage.

    Make structured data match the repaired page

    JSON-LD should describe what a user can verify on the visible page. When you remove a claim, rating, author, product detail, FAQ, or entity relationship from the content, update the markup with it. Validate that identifiers are consistent and that the marked-up entity is the entity the page is actually about.

    Do not treat schema, answer-first formatting, or entity density as a recovery layer over a page that lacks a clear purpose. AEO and GEO work begins with an answer that is accurate, attributable, and supported. Markup can make that information easier to interpret; it cannot supply the missing evidence or user value.

    Turn findings into a controlled remediation log

    Give every proposed change a URL or template scope, the suspected policy concern, the evidence supporting it, the chosen action, an owner, and a validation method. Label uncertain findings as hypotheses. This prevents a plausible concern from silently becoming a domain-wide verdict.

    Deploy related fixes as coherent batches and keep unrelated redesigns, migrations, and conversion experiments separate where possible. If content quality, internal linking, templates, schema, and site architecture all change at once, a later recovery will teach you very little about the actual cause.

    Set recovery expectations around the spam system

    A correct fix may not produce an immediate rebound. Sites can improve after remediation if Google’s automated systems learn over a period of months that the site complies with its spam policies. That is a re-evaluation process, not a promise that every lost position will return.

    This changes how you should report progress. Completion of the cleanup is an operational milestone, not proof of recovery. Monitor the affected page groups and query families on a fixed cadence. Watch whether impressions stabilize, relevant non-branded queries reappear, crawling and indexing remain healthy, and unaffected sections avoid collateral decline.

    Keep two outcomes separate. If the site had policy problems, your first objective is durable compliance. If spammy links had supplied an artificial advantage, their lost contribution may never come back. In that case, success means rebuilding visibility through useful content, legitimate authority, sound architecture, and accurate representation rather than waiting for the old boost to be restored.

    If your audit finds no persuasive policy issue, do not manufacture one to fit the date. Revisit technical changes, demand shifts, result-page changes, competitors, content decay, and other algorithmic movement. The update window should narrow your investigation, not predetermine its conclusion.

    Key takeaways

    • The March 2026 spam update ran from March 24 at 3:20 p.m. ET to March 25 at 10:40 a.m. ET, lasting 19 hours and 30 minutes.
    • Google did not disclose which form of spam the update targeted, so claims that it was specifically about links, AI content, or another tactic go beyond the available facts.
    • Use the rollout as an analysis marker. Confirm the loss in Search Console, segment it by query and page type, and rule out technical or tracking failures before editing.
    • Audit page purpose, production controls, link dependence, and structured data only where the impact pattern gives you evidence to inspect them.
    • Recovery after compliance work may take months while automated systems reassess the site.
    • If spammy links were neutralized, the ranking value they previously supplied cannot simply be regained.

    Your next move should be small and evidentiary: annotate the rollout, export the affected queries and URLs, and define the narrowest page group that explains the loss. Audit that group before you authorize a sitewide change.

    References


  • How to Make Content Machine-Readable for AI Search

    How to Make Content Machine-Readable for AI Search

    You can publish a technically clean page, answer the right question, and still give an AI search system a passage it cannot safely reuse. The problem often appears after retrieval: the extracted sentence no longer identifies its subject, a price loses its billing condition, or a claim depends on context several paragraphs away.

    The fix is not more copy or a larger pile of schema. You need answer blocks that retain their meaning when separated from the page, plus structured data that identifies the same entities and relationships without contradiction.

    Key takeaways

    • Open each important section with a direct answer of roughly 40 to 60 words, then add qualifications, evidence, and next steps.
    • Name the entity inside important claims. Do not make a retriever resolve vague references such as “it,” “they,” “this service,” or “the platform.”
    • Keep scope, units, eligibility, geography, billing terms, and time periods in the same sentence as the fact they qualify.
    • Use JSON-LD to connect Organization, Person, Article or BlogPosting, Product, and Service entities through stable @id values.
    • Treat schema as comprehension infrastructure. Schema can reduce ambiguity, but schema alone does not guarantee an AI citation.
    • Test the live, rendered URL. Perfect prose and valid markup cannot help a system that receives an empty shell, blocked response, or incomplete page.

    Design the passage an AI system needs to retrieve

    Machine-readable content states who or what a fact concerns, how the relevant entities relate, and which conditions limit the claim. It uses descriptive headings, self-contained sentences, accessible HTML, and consistent structured data. The objective is not robotic writing. The objective is preserving meaning when a useful passage is extracted from its original layout.

    An AI search pipeline does not need every word on your page to answer every query. A retrieval stage selects a limited amount of relevant material before a model composes its response. A rough working estimate of about 380 words from a page illustrates the pressure this places on information density. That estimate is not a universal page-length limit, and you should not cut a useful page to 380 words. It is a reason to make every answer block earn its place.

    Build each answer block in this order:

    1. Use a query-shaped heading. “How long does migration take?” gives the passage more retrieval context than “Migration overview.”
    2. Answer before explaining. Put the conclusion, entity, and main condition in the first paragraph. Do not spend the opening on category history or a broad market trend.
    3. Add the conditions that could change the answer. Identify the affected plan, customer type, location, version, time period, or eligibility rule.
    4. Provide extractable support. Use a short list or a genuine comparison table when the evidence contains several distinct fields.
    5. End with the decision or next action. Restate the practical implication without copying the opening sentence word for word.

    A strong opening paragraph should answer one question completely enough to quote, but not pretend the answer has no qualifications. For example, a software migration section should identify what is being migrated, which starting environment the estimate covers, what the estimate includes, and which dependency can extend it. Moving those conditions into a distant note makes the opening easier to read but less safe to extract.

    Front-loading does not mean repeating the target phrase or turning every heading into a minor variation of the same question. Give each section a distinct retrieval job. One section can define the service, another can establish eligibility, another can explain cost, and another can describe implementation. If two sections would return the same answer, merge them.

    Write portable claims, not context-dependent fragments

    A complete information module and its linked condition, unit, time, and source symbols travel together inside a transparent capsule as incomplete fragments dissolve behind it.

    AI retrieval breaks a page into passages. A sentence that feels clear after three introductory paragraphs may become ambiguous when it is the only sentence returned. The most important facts therefore need to work as portable assertions.

    The practical language pattern is a semantic relationship: subject, predicate, and object, followed by any conditions that control the claim. “The Atlas Enterprise plan supports SAML single sign-on for accounts managed through the enterprise console” identifies the plan, states the relationship, names the capability, and preserves the relevant scope.

    The following examples illustrate editing patterns rather than claims about real products or performance:

    ProblemFragile wordingMore extractable wording
    Missing subjectIt also supports SSO.The Atlas Enterprise plan supports SAML single sign-on.
    Entities without a relationshipSEO, paid search, content marketing.The agency uses paid-search query data to select topics for SEO landing pages.
    Detached conditionDelivery takes two business days. Restrictions apply.Metro delivery takes two business days for orders placed before the daily cutoff.
    Unsupported evaluationOur process is more reliable.The migration process requires a crawl export, redirect map, and post-launch validation.

    You do not need to remove every pronoun from the page. That would make the writing repetitive and unnatural. Apply the isolation rule to sentences carrying a definition, number, comparison, product attribute, policy, recommendation, or other claim that a search system might quote. Supporting transitions can still use normal prose.

    Use this editing sequence on every important claim:

    1. Name the subject. Replace “it,” “this,” or “our solution” with the brand, product, plan, person, process, or policy that owns the fact.
    2. Choose a relationship verb. Prefer precise verbs such as includes, costs, requires, supports, applies to, publishes, authors, or is offered by.
    3. Name the object or value. State the feature, amount, requirement, organization, audience, or outcome connected to the subject.
    4. Attach the boundary. Keep the unit, currency, billing period, location, version, audience, and time frame beside the claim.
    5. Remove unproved decoration. Words such as leading, seamless, robust, revolutionary, and best-in-class add confidence without adding a retrievable fact.

    Then run the isolation test. Copy a sentence from the middle of the section into a blank document. Ask whether a reader can identify the subject, relationship, object, and applicable conditions without seeing the preceding sentence. If any answer is no, repair the sentence rather than assuming the heading will always travel with it.

    Read the repaired paragraph aloud as a final check. Machine clarity should come from explicit relationships, not from repeating the full product name in every line. Once the key claim is anchored, nearby explanatory sentences can vary their rhythm.

    Build a connected entity graph instead of isolated schema

    A webpage plane connects to several symbolic entities, with a matching layer of structured-data nodes aligned beneath the same network.

    JSON-LD gives machines a second representation of facts that people can already see on the page. Its most useful role in AI search is disambiguation: identifying which organization published the page, which person wrote it, which product owns a price or feature, and how those entities connect.

    Google Search confirmed in April 2025 and Microsoft Bing confirmed in March 2025 that structured data helps their search and AI systems understand content. The position is less certain for ChatGPT, Perplexity, and other AI search products because their public crawling and extraction descriptions have not established whether page-level JSON-LD is preserved and used throughout retrieval.

    That uncertainty matters. Sites with extensive schema did not consistently earn more citations in a December 2024 citation comparison. A separate February 2024 extraction experiment found that LLMs handled defined, structured fields more accurately than open-ended input. The defensible conclusion is narrow: structure can improve interpretation and extraction accuracy when a system uses it, but schema presence is not a citation switch.

    Connect the entities that establish identity and responsibility

    A page-by-page schema object often repeats names without proving that the “Jane Doe” on one page is the same person elsewhere. Stable @id values let multiple pages refer to one persistent entity. Build the graph in this order:

    1. Create one Organization node. Give the brand a permanent @id, such as the canonical domain followed by #organization, and reuse that identifier across the site.
    2. Create one Person node per author. Give each author a stable @id and connect the Person to the Organization through worksFor when that relationship is accurate.
    3. Create an Article or BlogPosting node for the page. Connect author to the Person @id and publisher to the Organization @id. Keep the headline and other properties consistent with the visible page.
    4. Connect commercial entities to their owner. Use Product or Service where appropriate, and connect the offer or service to the responsible Organization rather than repeating an unlinked organization name.
    5. Use FAQPage only for genuine visible questions and answers. Markup should describe content available to the reader, not create a hidden answer layer that says something different.

    Maintain a small entity registry outside individual page drafts. Record each entity’s canonical name, @type, @id, owner, and the templates that reference it. This prevents an author from acquiring a new identifier on every article and stops a brand from being represented as several anonymous Organization objects.

    Keep prose, visible data, and JSON-LD in agreement

    Machine readability fails when the page contains several competing versions of the same fact. A product name in the heading, a shorter name in the body, a legacy name in JSON-LD, and a different name in navigation create an entity-resolution problem that more markup will not solve.

    • Use the same canonical entity name in visible copy and structured data, while reserving abbreviations for clearly introduced aliases.
    • Assign one stable @id to each real entity and reference that ID instead of recreating nested anonymous copies.
    • Make each attribute belong to the correct node. A price belongs to an offer or product context; authorship belongs to the content item and Person; publishing responsibility belongs to the Organization.
    • Update visible content and JSON-LD together when a price, plan name, author relationship, or product status changes.

    Schema cannot compensate for an unsupported claim, weak topical coverage, or an inaccessible page. It can make a good page less ambiguous. That narrower job is still valuable because it is controllable and useful to platforms that consume structured data.

    Run a machine-readability audit before publishing

    Do not stop at a schema validator. Validation can show that the syntax fits a vocabulary, but it cannot tell you whether an extracted paragraph remains accurate or whether the live URL exposes the content an AI system needs.

    1. Test URL access. Open the live URL through an LLM agent or another crawler-like reader. Confirm that the primary answer, headings, author, and important attributes are present without a click, login, or client-side interaction.
    2. Test the page without its hero. Scroll until the banner and introductory layout disappear, then begin reading. Mid-page sections should identify their own topic instead of relying on the page title for all context.
    3. Test the opening answer. Read only the first paragraph under each important heading. Verify that it answers the heading and contains the primary entity and decisive condition.
    4. Test sentence isolation. Copy a factual sentence from the middle of each core section. Repair any missing subject, dangling pronoun, detached qualifier, or unexplained abbreviation.
    5. Test entity relationships. Identify the subject, relationship verb, and object in every claim you want quoted. A list of related keywords does not establish how those entities interact.
    6. Test structured-data continuity. Check that Organization, Person, content, Product, and Service nodes reuse their registered @id values and point to one another correctly.
    7. Test factual parity. Compare names, relationships, prices, eligibility rules, dates, and other attributes across visible copy and JSON-LD. Resolve conflicts before publication.

    Use a five-point editorial scorecard

    Give the page one point for each passing lens in this five-part utility check. A zero identifies an editing task; the total is not a predicted citation rate.

    • Structural fitness: Do headings create a clear hierarchy in which each section answers a distinct question?
    • Information density: Does each paragraph contribute a fact, condition, explanation, example, or decision rather than repeating a broad benefit?
    • Extractability: Can important statements survive without the preceding paragraph, visual layout, or an unresolved pronoun?
    • Entity completeness: Are the relevant people, organizations, products, services, attributes, and relationships explicitly named?
    • Natural language quality: Does the page remain clear and pleasant for a person after the entities and conditions have been made explicit?

    Separate this quality-assurance score from visibility measurement. URL access, sentence isolation, entity consistency, and markup continuity are conditions you can inspect directly. AI citations are non-deterministic outcomes. Measure them with a fixed set of real audience questions, and record the engine, prompt, date, cited URL, and answer context. A single appearance or disappearance is not enough to prove that one edit caused the change.

    We’d start with one page that already contains genuine expertise but buries its answer. Rewrite the first answer block, repair its portable claims, connect its entity graph, and load the live URL as an agent would. Once that page passes the audit, turn the successful structure into an editorial and schema template for the rest of the site.

    References


  • TikTok Ad Creative Freshness: A Practical Testing System

    TikTok Ad Creative Freshness: A Practical Testing System

    Your TikTok ad opened strongly, then the cost per acquisition began to climb. Now you have an expensive decision to make: replace the creative, leave it alone, or change the campaign around it.

    If you replace the ad too quickly, you can discard a message that still works. If you wait too long, you keep paying for a response that is fading. The better approach is to diagnose which part of the system weakened, refresh only that part, and have the next challenger ready before the decision becomes urgent.

    Creative freshness is a performance state, not an age

    TikTok ad creative can have a short shelf life, but that does not give every ad the same expiration date. A creative is fresh while it continues to earn the attention and action you bought it to produce. It is tired when its ability to do that deteriorates under reasonably comparable conditions.

    That distinction matters because a rising CPA is not, by itself, proof of creative fatigue. Several different problems can produce the same headline result:

    • Creative fatigue: The audience is responding less strongly to an execution it has repeatedly encountered.
    • Audience saturation: Delivery is cycling through a limited pool of people, so additional impressions become less productive.
    • Message exhaustion: The underlying promise or angle no longer creates enough interest, even when it is packaged differently.
    • Post-click friction: The ad still earns clicks, but the landing page, form, checkout, availability, pricing, or message continuity reduces conversion.
    • Campaign or measurement disruption: A change in delivery conditions, tracking, optimization, bidding, budget, attribution, or conversion reporting makes the apparent decline difficult to attribute to the ad.

    Do not refresh on a calendar simply because an ad has been live for a certain length of time. Use the ad’s own stable performance as the baseline. Compare periods with the same objective, conversion event, market, audience definition, offer, landing page, metric definitions, and material campaign settings. If one of those inputs changed, mark the comparison as contaminated rather than forcing a creative conclusion.

    This also prevents a common waste pattern: producing an entirely new batch of videos to solve a problem that actually sits on the website or in campaign delivery. Freshness is useful only when it is attached to a diagnosis.

    Diagnose the decline before you retire the ad

    An overhead analysis table shows a smartphone ad surrounded by audience figures, video thumbnails, product props, and delivery tokens while a hand focuses a spotlight on one area.

    Read performance as a sequence. CPM describes the cost of obtaining impressions. Your chosen opening-view or hold metric shows whether the beginning keeps people watching. Click-through rate shows whether the message creates enough intent to click. Conversion rate shows what happens after that click. CPA or ROAS tells you whether the full chain works economically.

    No single metric establishes the cause. The pattern across them tells you where to investigate first.

    Performance patternWhat it may indicateWhat to check next
    CPM rises while CTR and conversion rate remain stableDelivery has become more expensive, but the creative response is not clearly weakerReview audience, market, placement, bidding, budget, competition, and other delivery changes before commissioning a reshoot
    Opening retention and CTR weaken while conversion rate remains stableThe opening execution may be losing its ability to stop and qualify viewersTest a new opening line, first visual, pacing choice, or problem frame while preserving the body, proof, offer, and landing page
    Opening retention remains stable while CTR fallsPeople continue watching, but the promise, proof, or call to action creates less click intentTest the benefit, demonstration, objection handling, evidence, and CTA as separate hypotheses
    CTR remains stable while conversion rate fallsThe main weakness is probably after the click or in the match between ad and pageAudit page availability, speed, form or checkout function, pricing, inventory, offer continuity, and conversion tracking
    Frequency rises while CTR falls in the same audienceRepeated exposure is a plausible contributorInspect audience overlap and delivery, then introduce a meaningfully different concept rather than a cosmetic edit
    CPA deteriorates across many unrelated creatives at onceA shared campaign, auction, audience, site, offer, or tracking issue is more plausible than simultaneous fatigue in every adFind the common dependency before judging individual creatives
    Likes or comments weaken while CPA remains acceptableA visible engagement signal changed without evidence that the business result didKeep the ad eligible and monitor the primary outcome instead of optimizing to a vanity metric

    Start the diagnosis with measurement. Confirm that the conversion event still fires, reporting definitions have not changed, and the destination works on the devices and markets receiving traffic. Then check the change log for budget, bid, audience, placement, optimization, offer, page, and attribution changes. A performance chart without that context invites false certainty.

    Next, compare the ad with a control and with other live creatives exposed to similar conditions. If only one execution weakens, a creative-specific explanation becomes more credible. If everything declines together, investigate the shared system first. Breakdowns by audience, market, placement, and creative can help you see whether the decline is concentrated or widespread.

    Comments can add context, especially when viewers repeat the same objection, misunderstand the promise, or indicate familiarity with the execution. Treat those comments as clues, not as a substitute for performance data.

    Avoid universal fatigue thresholds. The amount of evidence you need depends on conversion volume, reporting lag, normal volatility, and the cost of a wrong decision. Define an account-specific comparison window and minimum evidence requirement before the campaign runs. That keeps an isolated bad period from becoming an emergency production brief.

    Refresh the layer that has actually lost its pull

    A refresh does not have to mean a new concept, creator, script, edit, offer, and landing page all at once. Creative has layers, and each layer answers a different viewer question:

    • Concept: What situation, problem, or desired outcome is the ad about?
    • Angle: Which reason should make that outcome matter now?
    • Hook: What earns attention and identifies the relevant viewer?
    • Execution: How is the idea expressed through a demonstration, explanation, story, reaction, comparison, or creator-led delivery?
    • Proof: What makes the promise credible or concrete?
    • Call to action: What should the viewer do next, and what expectation does the ad set for the destination?

    Use the smallest viable refresh

    When the opening weakens but downstream conversion remains healthy, start with hook variants. Change the opening line, initial visual, entry point, or pace while keeping the proven promise and destination intact. You are trying to restore attention without discarding the part that still converts.

    When people keep watching but fewer click, work deeper in the message. Test a clearer benefit, a more concrete demonstration, stronger proof, a different objection, or a CTA that better matches the next step. A new first frame will not repair a weak reason to act.

    When multiple executions of the same idea weaken, stop repainting the concept. Move to a different problem frame, use case, desired outcome, or reason to believe. A new background, caption treatment, soundtrack, crop, or shirt may make a file technically new without giving the viewer a new reason to care.

    When CTR holds and conversion rate falls, do not send the problem straight to the editor. Check the destination and the promise-to-page handoff. A more persuasive ad can make the economics worse if it sends additional people into a broken or mismatched conversion path.

    Preserve the causal core of a winner

    Before changing a successful ad, write down why you believe it works. The answer should name a mechanism, not an aesthetic preference. For example: the problem is recognized immediately, the product is demonstrated without delay, a specific objection is answered, or the ad and landing page make the same promise.

    Build adjacent versions around that core. If a demonstration appears to be doing the persuasive work, keep the demonstration while testing new openings or proof. If a particular audience situation drives qualified clicks, keep that situation while changing the format. This gives each replacement a clear inheritance from the winner instead of asking an unrelated idea to reproduce the same result by chance.

    Native-looking creative should still be intentional. It can feel appropriate to the feed while maintaining readable captions, audible speech, a visible subject, truthful proof, and a clear next step. Freshness is not an excuse to weaken brand accuracy or make claims the destination cannot support.

    Build a creative pipeline that makes replacement routine

    An isometric miniature studio shows a team moving short-form video ideas through filming, modular editing, organized testing, and a loop back into the next production cycle.

    Plan the next asset before the current one declines

    The worst time to invent a TikTok concept is after a winner has already deteriorated. Maintain a backlog with distinct states: ideas awaiting evidence, concepts ready to script, assets in production, challengers ready to launch, live controls, and retired ads. Every live control should have a next test attached to it.

    Use a short concept card for each idea. Record the audience situation, problem, promise, proof, objection, format, CTA, landing page, and the reason the concept should work. This keeps production focused on strategic differences instead of accumulating visually different videos that all say the same thing.

    During production, capture modular components: alternative openings, demonstrations, proof elements, objection responses, transitions, and end cards. Keep the raw material and map each component to its concept. Modular production lets you create interpretable challengers without rebuilding every asset from the beginning.

    Use names that expose the creative logic. A useful naming structure includes the concept, audience or situation, hook, proof, format, and version. The exact syntax matters less than consistency. Anyone reviewing the account should be able to tell whether two ads represent different concepts or merely different edits.

    Test challengers without erasing the signal

    1. Choose the control. Use a relevant live winner or a clearly documented baseline.
    2. Name the hypothesis. State which layer is weakening and why the proposed change should improve it.
    3. Limit the difference. Change the layer under investigation while preserving the parts that still appear healthy.
    4. Keep conditions comparable. Avoid mixing a creative test with major audience, offer, destination, budget, optimization, or measurement changes.
    5. Read the full metric chain. Check attention, click response, post-click conversion, and the primary business outcome using consistent definitions.
    6. Record the result. Log what changed, what remained fixed, the comparison period, relevant delivery context, and the decision.
    7. Turn the result into the next brief. Extend a supported mechanism, challenge an uncertain one, or leave the creative alone when the evidence points elsewhere.

    Do not demand that every challenger beat the control on every metric. A hook that attracts more viewers but lowers conversion quality is not automatically better. A less engaging ad can still be commercially useful if it filters for the right people and improves the primary outcome. Decide which metric is the goal and which metrics are guardrails before seeing the result.

    Write replacement rules before performance slips

    Your operating rule should identify the primary KPI, acceptable guardrails, comparison window, minimum evidence requirement, and action attached to each pattern. Use relative movement against a valid baseline and the account’s normal variation rather than importing a universal percentage from someone else’s campaign.

    • Keep: The primary business result remains acceptable, even if a secondary engagement metric has softened.
    • Refresh: The primary result shows sustained deterioration and the metric chain identifies a specific creative layer that is weakening.
    • Replace the concept: Multiple targeted variants fail to restore the response, or the message itself no longer creates sufficient intent.
    • Investigate the system: Unrelated ads decline together, conversion tracking becomes uncertain, or post-click performance breaks while click response holds.
    • Archive: Retire the asset without deleting its history. Preserve the concept, hypothesis, results, and reason for retirement so the same failed test is not unknowingly repeated.

    A compact freshness dashboard can make these rules operational. Track the ad and concept IDs, audience, launch date, spend, CPM, selected opening metric, CTR definition, conversion-rate definition, CPA or ROAS, frequency where relevant, status, diagnosed weak layer, and next challenger. Add notes for changes to the offer, page, tracking, or campaign setup. The dashboard should explain the decision, not merely display the decline.

    Allocate production capacity across extensions of proven concepts, genuinely new concepts, and ready-to-launch reserves. The right allocation depends on how concentrated your results are and how quickly your team can produce credible replacements. The important part is that exploration continues while a winner is still working.

    Key takeaways

    • A rising CPA is a symptom, not a creative-fatigue diagnosis.
    • Compare performance only after accounting for changes in delivery, audience, offer, destination, tracking, and metric definitions.
    • Use the metric chain to locate the weak layer: delivery cost, opening attention, click intent, post-click conversion, or business outcome.
    • Refresh hooks when the opening weakens, refresh persuasion when click intent weakens, and replace the concept when repeated executions of the same message stop working.
    • Keep the control stable enough to make challenger results interpretable.
    • Define keep, refresh, replace, investigate, and archive rules before campaign noise puts the team under pressure.

    Before your next TikTok launch, document the control’s working hypothesis and queue a challenger for one identifiable layer. Then write the decision rule before spend begins. That turns creative freshness from emergency churn into a repeatable optimization system.

    References


  • First-Party Customer Data Has Limits: A Practical Audit

    First-Party Customer Data Has Limits: A Practical Audit

    You’ve centralized customer accounts, transactions, campaign responses, and support history. The profiles look complete. Yet audiences come back smaller than expected, personalization stops improving, and measurement produces exact numbers that don’t quite match business reality.

    The problem may not be a shortage of data. It may be that your systems treat facts captured in the past as proof of what is true now. Once you separate historical evidence from current identity, activity, and intent, you can make first-party data far more dependable without pretending it is complete.

    First-party data records an event, not a permanent truth

    An account registration proves that someone supplied a set of details at a particular moment. A purchase proves that a transaction occurred. A support ticket proves that someone asked a question through a particular channel. Those facts can remain accurate even after the customer’s address, primary email, job, device, needs, or habits have changed.

    This is the first limit to understand: first-party describes the relationship through which data was collected. It does not certify that every field is fresh, complete, correctly attributed, or suitable for every future decision.

    Identity anchors such as email addresses, logins, and device links can lose alignment as people change accounts, locations, jobs, devices, and digital habits. The database may still accept those identifiers. That does not mean they still represent the same active person in the same way.

    Treat each customer record as a set of claims supported by different evidence:

    • Event truth: Did the recorded interaction happen?
    • Identity truth: Do the identifiers still belong to the person you think they do?
    • Activity truth: Is that identity still active and reachable through the relevant channel?
    • Intent truth: Does the historical behavior still describe what the person wants?

    A purchase can provide strong event evidence and weak current-intent evidence. A recently used login can support current activity without proving purchase intent. An active email address can support reachability without proving that the same individual still controls it. If your data model collapses these distinctions into one unified customer profile, the profile will look more certain than its underlying evidence.

    Where first-party customer profiles lose reliability

    Freshness varies by attribute

    Historical facts and current attributes do not age in the same way. The date and value of a completed order remain part of the customer’s history. The shipping address attached to that order should not automatically become a claim about the customer’s current residence. A declared preference may still be useful, but its age should be visible whenever it drives a recommendation.

    Do not assign one freshness status to an entire profile. Track freshness at the field or claim level. Otherwise, one recent event can make unrelated, older attributes appear current.

    Identity resolution can combine errors as efficiently as facts

    A customer data platform or identity graph follows the identifiers and matching rules it receives. If two records share an anchor, the system may connect them. If one person uses several accounts, the system may leave them fragmented. The resulting profile can be technically consistent with the rules and still fail to represent one real person accurately.

    Resolution therefore needs its own evidence. Store which identifiers caused a merge, whether the connection was directly authenticated or inferred, when the link was last supported, and what contradictory signals exist. A unified profile is an output of a model. It is not independent proof that the model identified the customer correctly.

    Your owned interactions reveal only part of the customer

    First-party data shows what a person did within the touchpoints you can observe. It usually cannot tell you what changed outside those boundaries. A customer may solve a problem elsewhere, switch priorities, adopt a different platform, or stop considering the category without generating an event in your systems.

    This creates a dangerous interpretation error: no new activity is treated as continued interest, lost interest, or customer inactivity depending on what the team wants the absence to mean. In reality, missing activity is simply missing evidence until another signal supports a conclusion.

    Validity, reachability, and intent are different tests

    A correctly formatted identifier may be invalid. A valid identifier may be dormant. An active channel may reach the right person at the wrong time. Even successful delivery does not prove interest in the offer.

    The distinction also matters in fraud and risk workflows. A plausible-looking identity can lack evidence of ongoing human activity, but dormancy alone does not establish that an identity is false. Use activity as one part of an evidence set, not as a universal verdict.

    Precise reporting can conceal an uncertain denominator

    Your warehouse can count records exactly. The difficult question is what those records represent. A database total may include duplicate people, abandoned accounts, unreachable addresses, uncertain matches, and customers whose last meaningful interaction is no longer relevant to the decision being measured.

    This is why campaign reach can disappoint even when the audience query is correct. The query selected the requested records; the business assumption that every selected record represented a current, reachable customer was the part that failed.

    Build a validation layer instead of collecting more fields

    Abstract customer data passes through transparent filters that separate uncertain historical signals from verified current signals before forming an incomplete profile.

    More attributes do not repair uncertain identity. They can make the uncertainty harder to see. A better approach is to preserve the evidence, age, and status of each important claim so the activation system can decide whether that claim is fit for a particular use.

    Separate observed, declared, resolved, and inferred data

    • Observed data records an interaction, such as an order, login, or campaign response.
    • Declared data records what a person supplied, such as a role, preference, address, or account detail.
    • Resolved data links records or identifiers believed to represent the same person.
    • Inferred data estimates an attribute, intent, segment, or likely next action from other evidence.

    Keep those classes visible downstream. An inferred preference should not silently overwrite a declared preference. A resolved relationship should not be presented as though the customer directly confirmed it. A model output should retain the inputs, method, and time context needed to evaluate it.

    Attach an evidence record to decision-critical attributes

    For every field used to select, suppress, personalize, measure, or assess a customer, capture the metadata needed to answer these questions:

    • Which interaction or system produced the value?
    • When was it first captured?
    • When was it last confirmed by relevant activity?
    • Was it supplied directly, observed, matched, or inferred?
    • Which identifiers connect it to the current profile?
    • Is the claim current, stale, unknown, or contradicted?
    • Which team owns the rule that changes its status?

    A field should not become current merely because a pipeline copied it yesterday. Preserve the time of the underlying customer evidence separately from the time the record was processed.

    Set freshness rules around the decision

    There is no useful universal expiration rule for every kind of customer data. Ask what could change, what evidence would reconfirm it, and what happens if you are wrong.

    An old order may remain fully valid for historical revenue analysis while being weak evidence for immediate product intent. An unconfirmed identity link may be acceptable for exploratory analysis but inappropriate for suppressing a person from an important message. A stale preference can still support a cautious default if the experience gives the user an easy way to correct it.

    Make eligibility depend on the use case. A claim can remain stored while being excluded from activation. This is more useful than deleting everything old or allowing everything historical to masquerade as current.

    Use activity signals without turning them into identity truth

    Email can function across authentication, commerce, subscriptions, support, and other digital touchpoints, which makes it a useful identity anchor and a potential source of activity evidence. Current activity can help distinguish reachable identities from ones that have faded from view.

    Keep the conclusion narrow. Evidence that an address is active does not, by itself, prove who controls it, whether the person wants your message, or whether a profile merge is correct. Combine channel activity with authenticated interactions, transaction history, explicit customer updates, and contradiction checks where those signals are available and permitted.

    If you obtain activity or identity evidence outside your direct customer relationship, label its provenance separately. Enrichment does not become first-party merely because its output is stored in your warehouse. Preserve consent, purpose restrictions, access controls, and retention requirements instead of allowing the unified profile to erase how the data was obtained.

    Audit the customer decisions that depend on the data

    An analyst inspects broken and intact paths connecting abstract customer data tiles to marketing, delivery, support, and retention decisions.

    A database-wide cleanup is easy to start and hard to finish because it has no single definition of correct. Begin with one live decision whose outcome you can observe: sending a campaign, choosing a personalized experience, counting active customers, merging accounts, or reviewing an identity for risk.

    • Write the decision in one sentence.
    • State what must be true about a person for the decision to be correct.
    • Trace every field, identifier, join, model, and suppression rule used.
    • Mark the last customer evidence behind each decision-critical claim.
    • Identify where missing evidence has been converted into an assumption.
    • Feed the resulting delivery, response, correction, merge, or rejection back into identity status.

    The audit should test business meaning, not just schema validity. A non-null email field passes a database check. It does not necessarily pass the business test for a reachable, permitted, correctly identified recipient.

    DecisionWhat the data can establishWhat it does not establishPractical control
    Send a customer emailAn address and permission status were recordedThe address is active, still controlled by the same person, and currently permitted for this purposeCheck current permission, channel status, suppression evidence, and identity confidence before selection
    Personalize an experienceThe person previously behaved a certain way or declared a preferenceThe same intent or preference remains currentWeight current relevant behavior, expose a neutral fallback, and let the customer correct the assumption
    Merge customer recordsSpecified identifiers satisfy the matching ruleThe records unquestionably belong to one humanStore the reason for the link, its confidence, its age, and any contradictory evidence
    Count active customersA defined set of records meets a query conditionEach record represents a distinct, current, reachable personReport resolved, unresolved, duplicate, dormant, and suppressed populations separately
    Attribute an outcomeTracked events form an observable pathThe path contains every influence or every customer interactionState the observable scope and keep unobserved or unresolved activity visible as uncertainty
    Review possible fraudSubmitted identifiers appear valid and satisfy recorded checksA genuine person is actively using the identityCombine permitted activity, identity consistency, contradictions, and proportionate review rather than relying on one signal

    Change the reporting denominator as well. Alongside the number of records selected, show how many have current identity evidence, how many are unresolved, how many were suppressed, and how many produced an observable outcome. This prevents a large historical database from being mistaken for an equally large reachable market.

    Outcome data should improve the next decision. A customer correction should update the relevant claim. A confirmed account merge should strengthen the recorded link. Repeated inactivity may change reachability status without erasing legitimate transaction history. Contradictory activity should reopen an identity decision instead of being discarded because it does not fit the existing profile.

    Key takeaways

    • First-party describes data provenance, not guaranteed freshness, completeness, or identity accuracy.
    • A historical event can remain true while the customer’s current attributes, activity, and intent change.
    • Identity resolution creates a useful model, but the model is only as reliable as its anchors, matching rules, and contradiction handling.
    • Track freshness and confidence at the claim level rather than assigning one quality score to an entire profile.
    • Use activity signals to assess identity vitality and reachability, but do not treat activity alone as proof of ownership, personhood, consent, or intent.
    • Audit one customer decision at a time and report unresolved identities instead of hiding them inside a precise total.

    For your next audience or personalization rule, do not begin by asking how many records are available. Write down what must be true for a person to be eligible, which evidence supports each condition, and when that evidence was last confirmed. Label the unknown cases rather than forcing them into yes or no.

    Once that decision produces a cleaner, explainable result, repeat the method elsewhere. You do not need a mythical perfect customer view. You need a customer view that distinguishes what you observed, what you inferred, when you knew it, and how much uncertainty the next decision must carry.

    References


  • Google Unveils Powerful March 2026 Spam Update Impacting All

    Google Unveils Powerful March 2026 Spam Update Impacting All

    Today, Google released its March 2026 spam update, making it the second announced algorithm change this year, following the February 2026 Discover core update.

    This marks the first spam update of 2026. The previous one was rolled out in August 2025.

    Timing. Google mentioned that this update might “take a few days to complete.” They reiterated on LinkedIn: “This is a normal spam update, and it will roll out for all languages and locations. The rollout may take a few days to complete.”

    Why we care. Since this is the second major algorithm update of 2026, I need to stay alert for any changes in rankings or traffic on my sites. Google hasn’t specified what spam is being targeted, but shifts in performance could be related.

    More on the spam update. Google’s documentation states: “While Google’s automated systems to detect search spam are constantly operating, we occasionally make notable improvements to how they work. When we do, we refer to this as a spam update and share when they happen on our list of Google Search ranking updates.”

    Google’s AI-based spam-prevention system, SpamBrain, gets enhanced from time to time to better detect and manage new types of spam. If I notice changes after this update, reviewing and ensuring compliance with Google’s spam policies is essential for maintaining or improving rankings. Violations can lead to lower rankings or removal from search results entirely.

    For link spam updates, improvements might not translate to immediate gains since any ranking boost from spammy links is nullified. Hence, reclaiming lost benefits isn’t possible.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Unleash Marketing Efficiency with Profound Sheets

    Unleash Marketing Efficiency with Profound Sheets

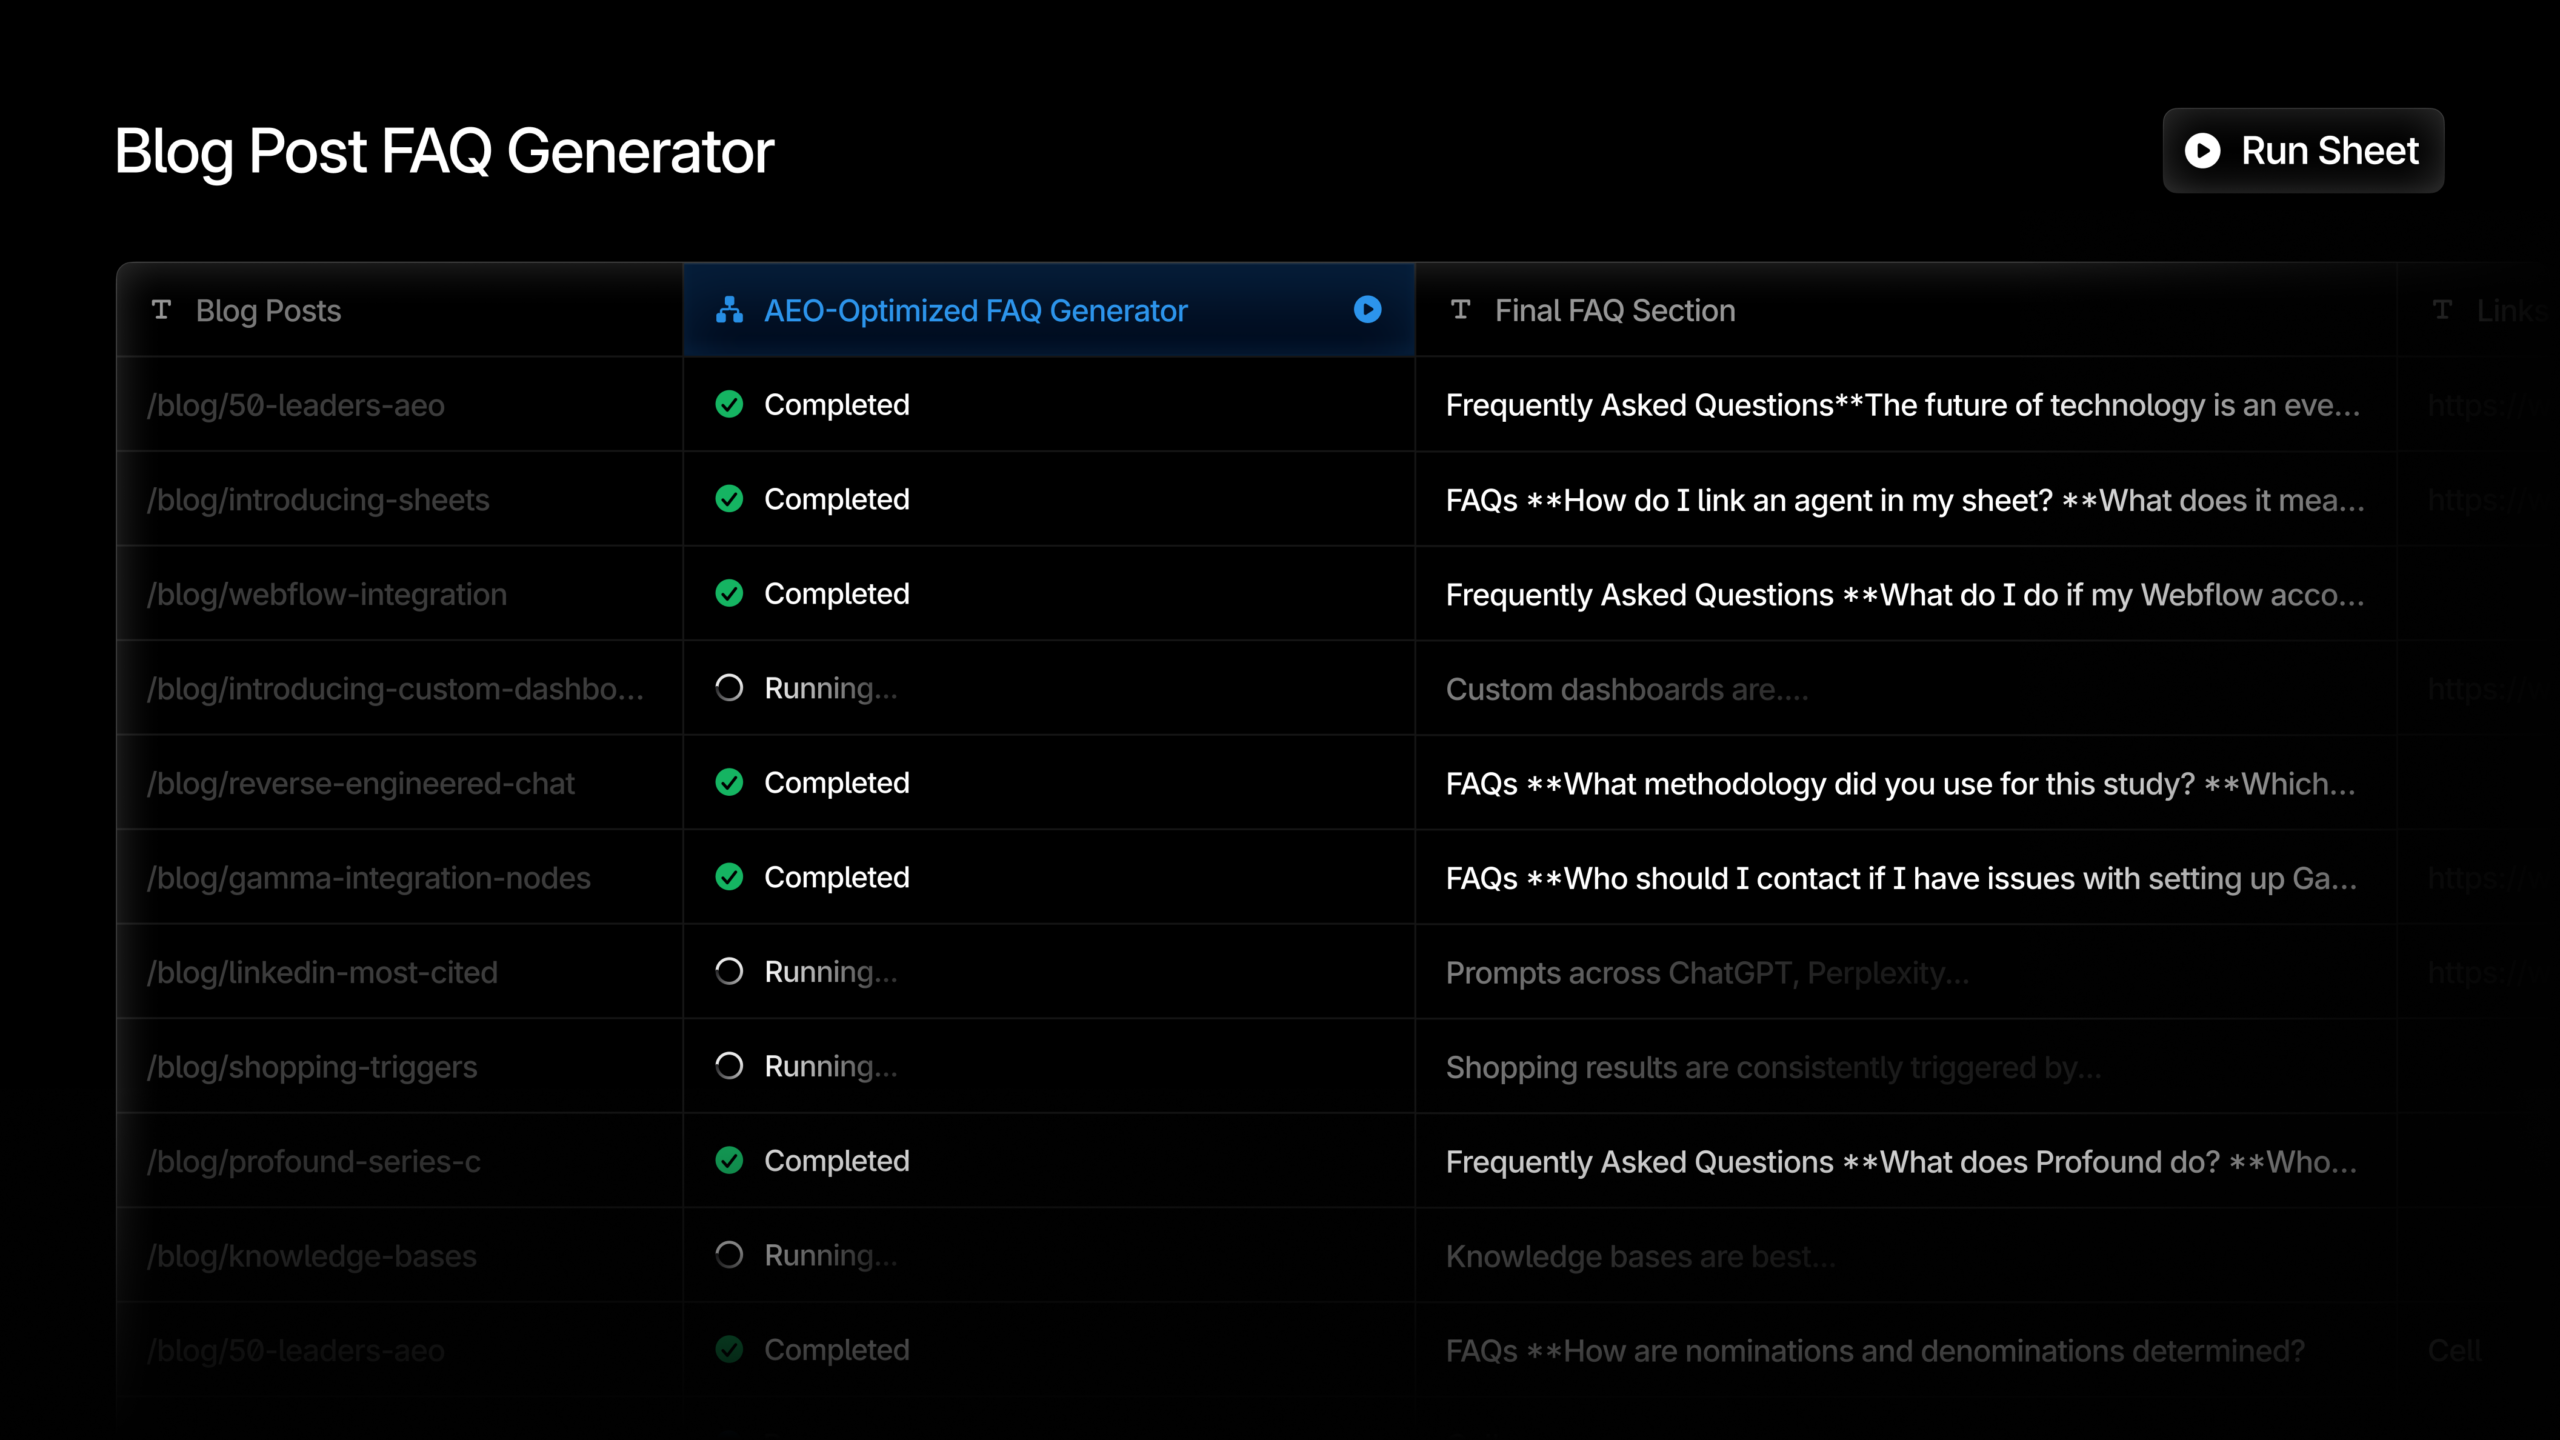
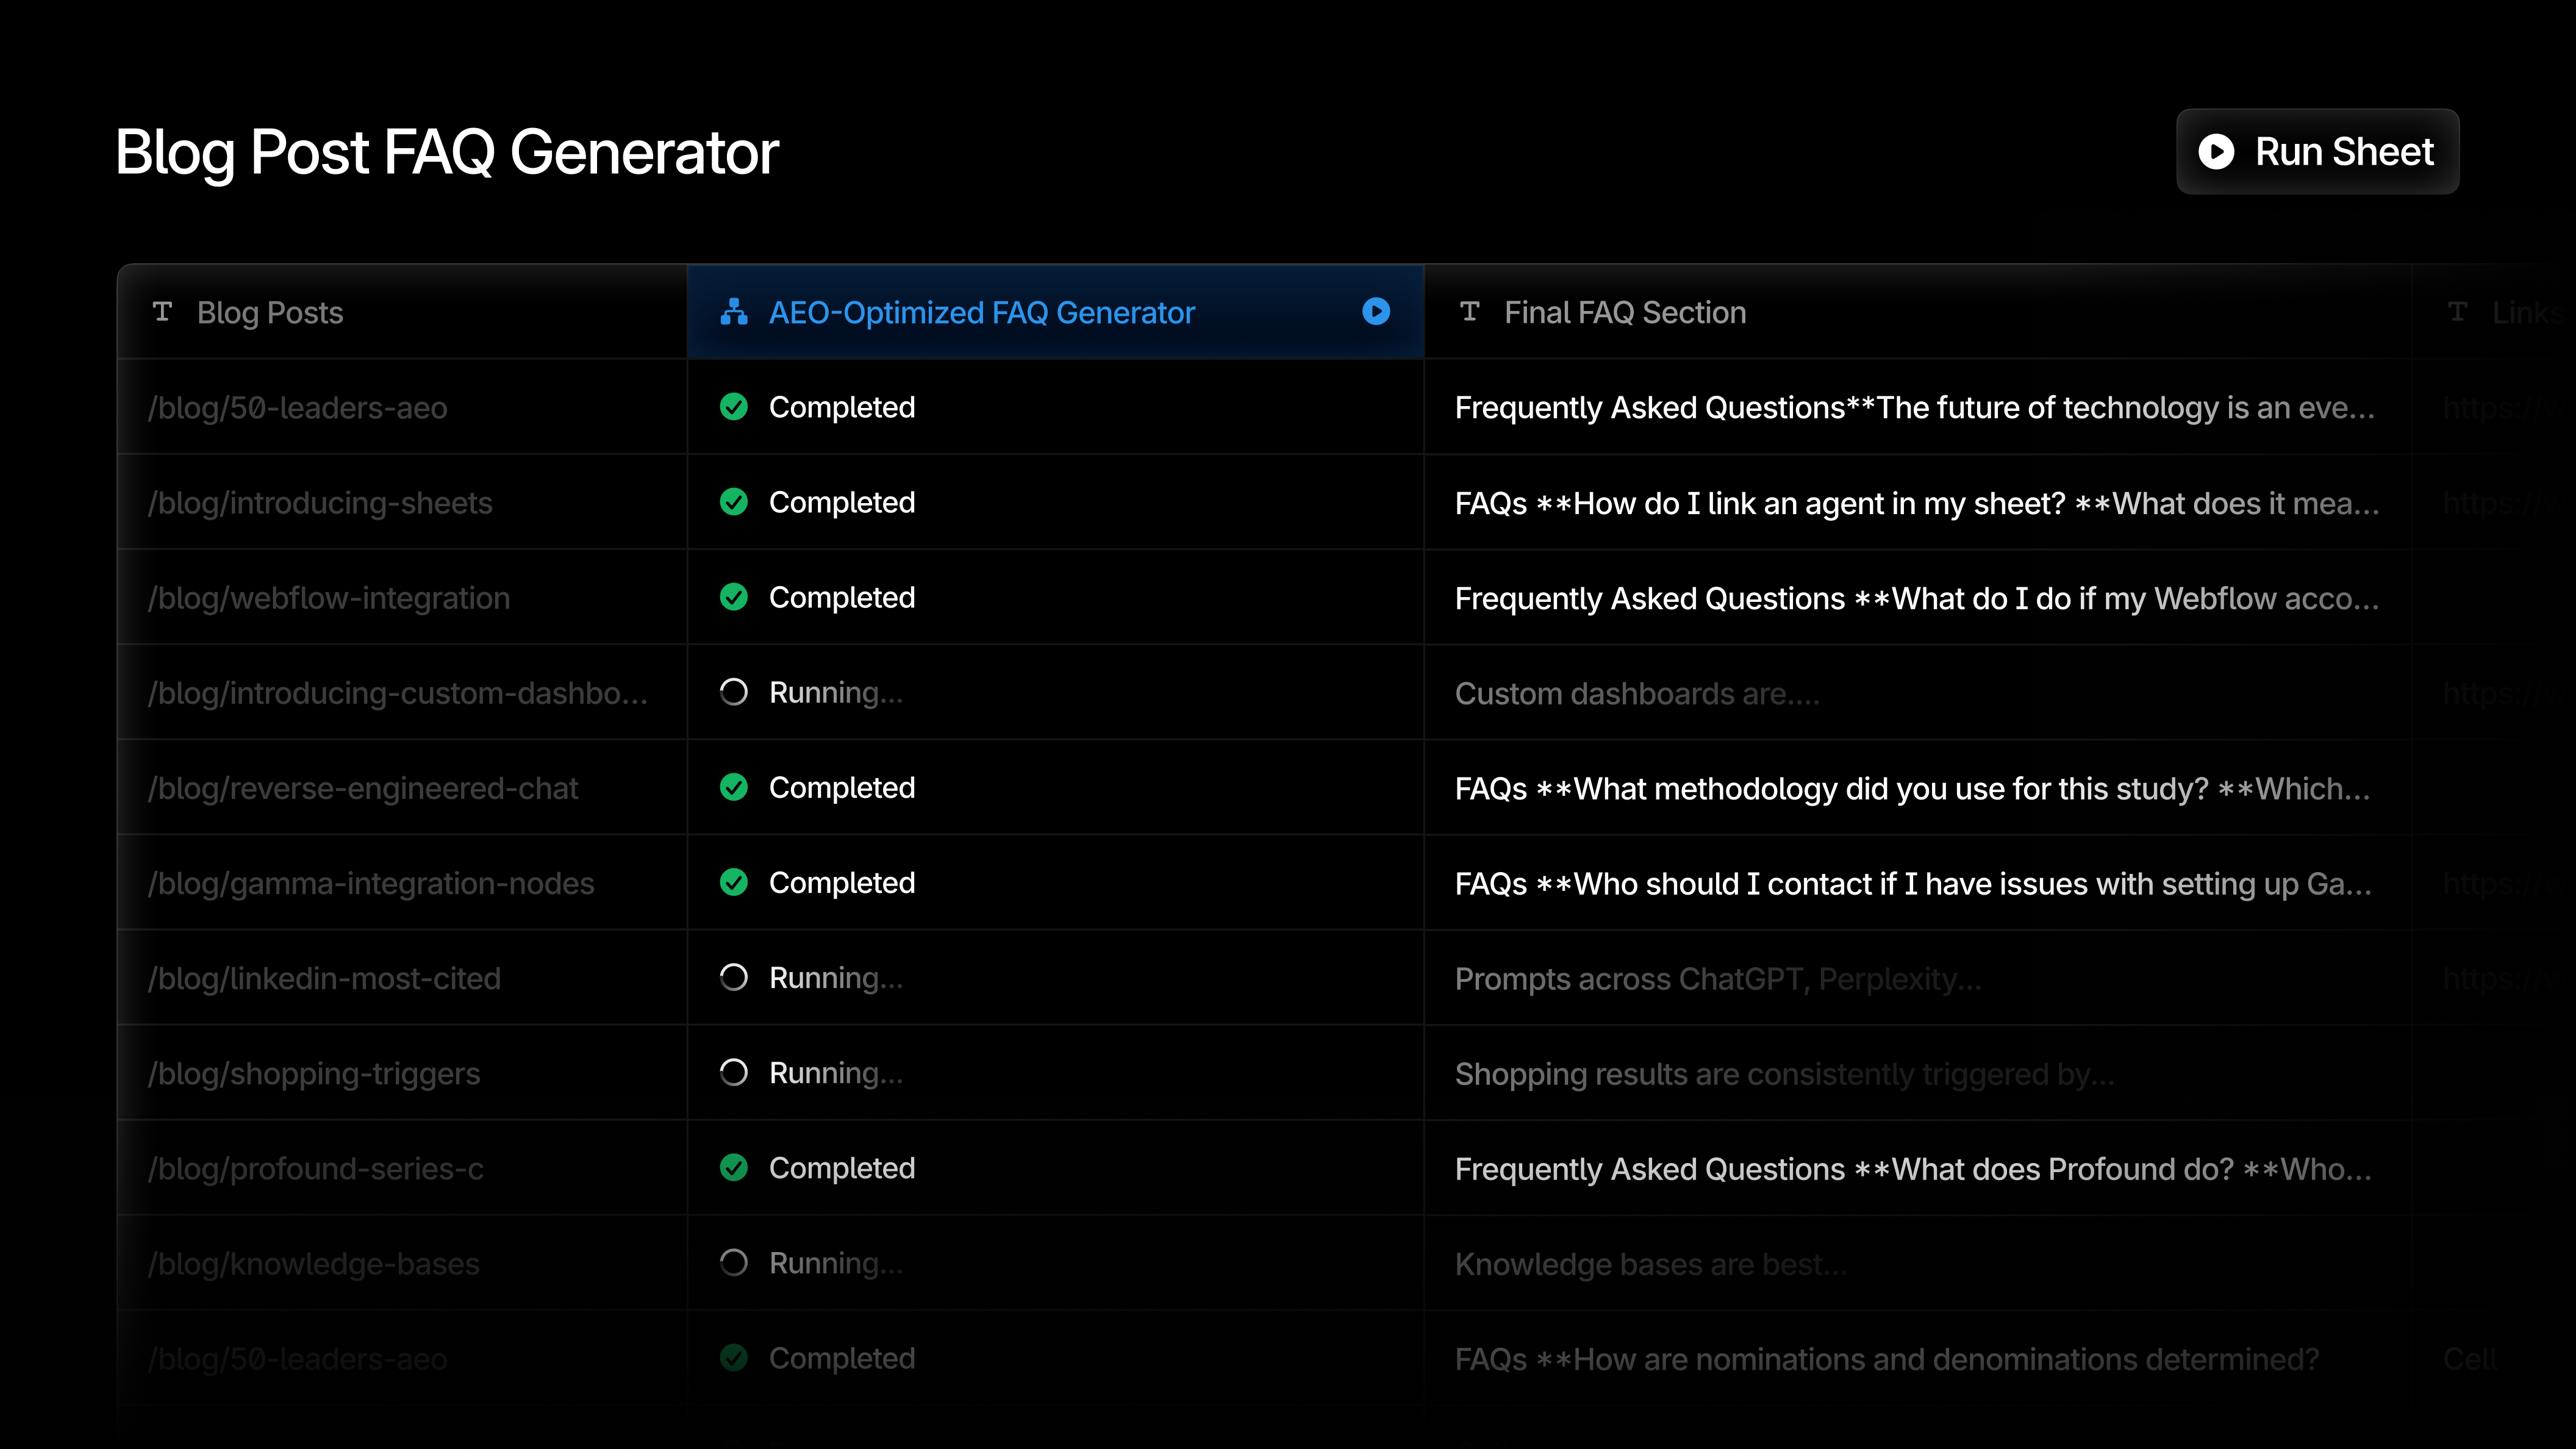
    Have you ever wished for a tool that makes orchestrating AEO efforts a breeze? Let me introduce you to Profound Sheets, a game-changer that brings efficiency to new heights. Imagine a spreadsheet-like interface where every row acts as its own Agent run, each with its unique context. This innovative system allows me to process hundreds of inputs simultaneously, amplifying my marketing strategies beyond imagination.

    By leveraging structured workflows, I’m able to accomplish what once took weeks in mere minutes. The time saved means more opportunities to focus on crafting creative strategies and optimizing performance. It’s like multiplying my marketing team’s capabilities overnight!


    Inspired by this post on Try Profound Blog.


    crushpress.ai community screenshot
  • Organizational Readiness for SEO in 2026: An Audit Plan

    Organizational Readiness for SEO in 2026: An Audit Plan

    If your SEO plan for 2026 depends mainly on a new AI tool, a larger content calendar or another visibility dashboard, pause. Those additions can expose organizational weakness faster than they create results. A dashboard cannot reconcile teams that use different definitions of success, and an AI-generated brief cannot supply a point of view nobody owns.

    Your real readiness test is whether the organization can turn a discovery signal into a coordinated change: identify what matters, decide what to do, assign the work, ship it and evaluate the business effect. The audit below will show you where that chain breaks and what to fix first.

    Start with evidence, not an SEO maturity label

    Calling a company “advanced” or “immature” at SEO rarely tells you what to change. Readiness is easier to evaluate through evidence. Ask what happens when the team discovers an inaccurate brand answer, a declining topic, an unanswered customer question or a technical barrier. Then inspect the artifacts that move that finding toward resolution.

    Fragmented data, unclear KPIs and weak collaboration can quietly undo a well-designed search strategy. The same weaknesses become more consequential when prospective customers form impressions in AI environments before visiting your website. You may see the eventual branded search, direct visit or sales inquiry without seeing the discovery interaction that influenced it.

    Run the audit with the people who control content, analytics, product information, engineering priorities, brand communications and commercial outcomes. The exact job titles will vary. What matters is having both the people who see the signals and the people who can authorize or deliver a response.

    Readiness areaEvidence to requestA warning sign
    Customer journeyA shared map connecting discovery, evaluation, website behavior and business outcomesEach team presents a different journey and none includes AI-assisted discovery
    Goals and measurementMetric definitions, owners, data locations and the decisions each metric informsTraffic is treated as the result even when nobody can explain its business value
    Decision rightsA named decision-maker and executor for each common class of SEO issueSEO is accountable for results but cannot approve or schedule the required work
    DeliveryReal backlog items, prioritization rules, delivery windows and escalation pathsRecommendations repeatedly return to presentations instead of entering a production queue
    Content differentiationEditorial standards showing what the organization can contribute beyond generic synthesisAI output moves from prompt to publication without evidence, expertise or editorial challenge
    LearningA record of changes, expected effects, observed results and follow-up decisionsReports describe movement but do not change priorities, messaging or execution

    Do not accept verbal assurances where an operational artifact should exist. “Marketing and engineering collaborate” is not evidence. A prioritized ticket with an owner, acceptance criteria and an agreed delivery window is evidence. “We track AI visibility” is not evidence. A defined metric, known limitations and a decision it can trigger are evidence.

    Classify each area as working, constrained or absent. “Working” means the process is used and produces decisions. “Constrained” means it exists but regularly stalls because of access, authority, quality or capacity. “Absent” means the organization relies on individual initiative. Do not average the results into a flattering maturity score. A single absent link can stop the entire operating chain.

    Build a decision chain from signal to shipped change

    A glowing signal moves through observation, team decision, work assignment, production, and delivery stages as people coordinate each handoff.

    Many SEO teams have responsibility without control. They can detect a problem and recommend a response, but another team controls the template, product feed, editorial calendar, public statement, development backlog or budget. When the handoff is informal, recommendations wait for goodwill and urgency has to be renegotiated every time.

    Fix that by defining the decision chain before the next issue appears. For every recurring class of work, record the following:

    1. Signal owner: the person responsible for detecting and documenting the issue.
    2. Decision-maker: the person with authority to choose a response and accept its tradeoffs.
    3. Executor: the team that can make the change in the relevant system or channel.
    4. Required evidence: the information needed before the work can be prioritized.
    5. Delivery route: the backlog, editorial workflow or operating process that will carry the work.
    6. Validation owner: the person who checks whether the change shipped correctly and whether the expected effect appeared.
    7. Escalation condition: the circumstance that moves a blocked issue to a leader who can resolve it.

    Separate strategic ownership from execution ownership

    SEO should influence how the organization approaches discoverability across search engines, AI assistants and other relevant platforms. That does not mean the SEO team should pretend it can execute every change. Product teams may own product facts. Communications may own public positioning. Engineering may own rendering and platform behavior. Analytics may own measurement architecture.

    For each issue, make both forms of ownership visible. Strategic ownership answers, “What should change, and why does it matter?” Execution ownership answers, “Who can make the change in the system where it lives?” If only the first answer exists, you have a recommendation queue rather than an operating capability.

    Route work through existing operating systems

    A separate SEO spreadsheet often becomes a parking lot because it sits outside the processes that allocate resources. Put technical work into the engineering backlog, editorial work into the content workflow, product-fact corrections into the product-data process and reputation issues into the communications process. Keep a central SEO register for visibility, but let each change travel through the system that can actually deliver it.

    Consider an AI assistant that repeatedly presents an outdated return condition. The SEO team can capture the affected query pattern and identify the pages or feeds that may be contributing. It should not silently rewrite policy. The policy owner validates the correct fact, content or product-data owners update the canonical information, technical owners confirm that the information is accessible, and the visibility owner checks whether the answer changes. The chain protects accuracy while keeping the response actionable.

    Document common issue classes now: inaccurate entity facts, missing topic coverage, inconsistent brand language, weak product information, technical access barriers, declining search performance and emerging customer questions. Assigning routes in advance removes the ownership debate from the moment when action is needed.

    Use a KPI ladder that connects visibility to business value

    Connected platforms rise from scattered search signals to audience engagement, customer actions, and a glowing business value core.

    Traffic still tells you something, but it cannot carry the entire strategy. A person may encounter your brand in an AI answer, evaluate alternatives elsewhere and arrive later through a branded query or direct visit. A visibility metric can reveal part of that earlier interaction, but it may still be a proxy rather than proof of commercial influence.

    A useful measurement system does not replace traffic with one fashionable AI score. It creates a ladder from operational activity to visibility, journey behavior and business outcomes:

    • Business outcomes: the commercial or organizational result the strategy is meant to influence, such as qualified demand, completed purchases, adoption or retention.
    • Journey indicators: evidence that the right audience is progressing, such as engagement with decision content, branded discovery, qualified inquiries or assisted conversions.
    • Visibility indicators: whether the organization is discoverable, accurately represented and cited for priority needs across relevant search and AI environments.
    • Operational indicators: whether the organization can respond, including issue ownership, backlog movement, publishing quality and completion of corrective work.

    The ladder matters because each layer answers a different question. Visibility shows whether you are present. Journey evidence shows whether that presence may be drawing the right people forward. Business outcomes show whether the work contributes to something the organization values. Operational indicators show whether the team can repeat and improve the process.

    Give every KPI a decision rule

    A metric without a decision rule becomes reporting theater. Create a metric card containing its definition, business hypothesis, data location, owner, review cadence, known blind spots and action trigger. The action trigger does not need to be an arbitrary numeric threshold. It can be a condition such as “a priority product fact is repeatedly represented inaccurately” or “visibility improves without corresponding movement in qualified demand.”

    Ask these questions during every review:

    • What decision can this metric change?
    • Is it measuring presence, behavior, value or execution?
    • Which part of the customer journey is invisible to us?
    • Could another explanation produce the same movement?
    • What additional evidence would increase our confidence?
    • Who has authority to act on the finding?

    Keep traffic in the system, but use it at the right level. A drop can diagnose lost demand capture, technical trouble or weaker relevance. An increase can reveal broader reach. Neither movement proves business value by itself. Pair it with journey quality and outcome evidence before redirecting budget or declaring success.

    Be equally careful with AI visibility indexes. Coverage differs by tool, prompt set, location, personalization and observation method. Treat a third-party score as one observation layer, not a complete map of customer discovery. Preserve the underlying queries, answer examples, dates and evaluation criteria so the team can inspect what changed instead of debating a single composite number.

    Use AI for throughput, then require human differentiation

    AI can accelerate brief creation, data analysis, clustering, summarization and first drafts. Speed is useful when the organization already has reliable inputs and a clear editorial standard. Without those controls, AI makes generic work easier to produce and harder to distinguish from everything else generated from similar prompts.

    The important question is not whether AI touched the workflow. It is whether the published result contains accurate evidence, a useful decision, a coherent point of view and accountable human judgment. Make those requirements explicit at the brief stage rather than asking an editor to add originality after a generic draft has already defined the structure.

    Require every substantive brief to identify:

    • The reader’s decision: the specific action, concern or tradeoff the page must resolve.
    • The organization’s contribution: facts, expertise, analysis, examples or framing that cannot be obtained by prompting a general model for a generic answer.
    • The evidence boundary: which claims are approved, which need verification and which the organization is not qualified to make.
    • The differentiation test: what would still make the page valuable if several competitors covered the same basic information.
    • The accountable editor: the person who can reject fluent output that lacks accuracy or decision value.
    • The maintenance owner: the person responsible when product facts, policies, interfaces or market conditions change.

    Set rules according to the risk of the task

    Low-risk transformations, such as reorganizing approved material or generating alternative headings, can move quickly. Drafting interpretive claims, recommendations or product comparisons needs closer review. Publishing facts that affect customer decisions should require validation against the organization’s canonical information. The more consequential the claim, the less reasonable it is to treat fluent output as evidence.

    Keep the inputs that make the work distinctive outside the model’s imagination. Supply approved product facts, customer-language findings, subject-matter review and a defined editorial position. If those inputs do not exist, the readiness problem is upstream of prompting. Better prompt syntax will not create institutional knowledge.

    Make structured data downstream of fact governance

    JSON-LD and schema markup can clarify information that is already true and consistently maintained. They cannot repair disagreement between a product database, a policy page, a local listing and sales copy. Before expanding markup, identify the canonical system for each important entity fact, who may change it, which channels consume it and how corrections propagate.

    Audit the visible page and the structured representation together. A technically valid property can still communicate stale or contradictory information. Add validation to the publishing workflow, but also define what happens when the validator passes and the underlying business fact is wrong. Technical ownership and factual ownership are separate controls.

    This is where organizational readiness directly affects AI optimization. Clear entity information, consistent claims and maintained content give search and AI systems less ambiguity to resolve. The work begins with governance and execution; markup is one delivery mechanism within that system.

    Key takeaways for your next planning cycle

    • Audit the path from visibility signal to shipped change, not the size of the SEO toolset.
    • Ask for operational evidence: owners, tickets, decision rules, delivery routes and validation records.
    • Separate strategic ownership from execution ownership so SEO is not held accountable for work it cannot authorize.
    • Use a KPI ladder that connects operational delivery and visibility with customer behavior and business outcomes.
    • Treat traffic and AI visibility scores as evidence layers, not complete measures of value.
    • Use AI to increase throughput only after defining evidence, differentiation and human accountability.
    • Govern canonical business facts before expanding JSON-LD, schema markup or multi-platform distribution.

    In your next planning session, choose one priority customer journey and trace a real issue from detection to resolution. Name the decision-maker, executor, delivery route, success evidence and escalation condition. Wherever the chain becomes hypothetical, you have found the first readiness problem to put on the backlog.

    Do that before adding another dashboard or increasing publishing volume. In 2026, the organizations that gain durable visibility will be the ones that can learn and coordinate faster than their discovery environment changes.

    References


  • How to Earn AI Search Citations and Build Brand Visibility

    How to Earn AI Search Citations and Build Brand Visibility

    Your page can rank well in traditional search and still be absent when an AI assistant answers the same question. That gap is not necessarily a content-quality failure. AI systems retrieve many possible sources, cite only a small fraction, and repeatedly favor a limited set of domains.

    You need to solve two related problems: make the right page useful enough to cite, and make your brand clear enough to recognize and trust. The practical work spans query coverage, format, answer placement, entity evidence, and measurement.

    Compete for a citation set, not one blue-link ranking

    Retrieval is not the same as citation. About 85% of the pages retrieved for ChatGPT responses were not cited. Within a topic, roughly 30 domains shared about 67% of citations. The concentration was especially visible for product comparisons, where the top 10 domains captured about 46% and the top 30 captured 67%.

    A high Google position still helps, but it does not reserve a place in the answer. Pages ranking first were cited in 43.2% of the analyzed cases. That was 3.5 times the citation rate of pages beyond the top 20, yet most number-one pages still were not cited.

    The ChatGPT pattern is based on roughly 98,000 citation rows from about 1.2 million responses. Treat those numbers as directional benchmarks, not universal thresholds. Citation behavior can differ by model, query intent, industry, and the other sources available for a particular answer.

    This changes the unit of content planning. A conventional keyword brief often targets the most visible wording of a question. An AI system can fan that question out into narrower grounding queries covering definitions, alternatives, eligibility, risks, features, or comparisons. Some cited pages were discovered through fan-out queries with no recorded search volume, so a zero-volume subquestion is not automatically a zero-value topic.

    Build a query-family map before you edit anything:

    1. Write the broad decision or problem your audience brings to an AI assistant.
    2. List the follow-up questions needed to answer it responsibly: what it is, who it is for, how options differ, what the limitations are, and what someone should do next.
    3. Label each question informational, commercial, transactional, or navigational.
    4. Assign every intent to an existing page or a clearly justified new page. Do not create a near-duplicate URL for every prompt variation.
    5. Link the pages as a topic cluster so the central guide, comparisons, product or service pages, and brand information reinforce one another.

    The result should be broad coverage without repetition. One strong page can answer several closely related grounding queries. A cluster is useful when the reader’s task genuinely changes, not when it merely gives you more URLs to publish.

    Match the page format to what the user is trying to do

    Four symbolic user tasks lead to different blank page layouts for instructions, comparison, category selection, and explanation.

    Content type matters, but intent is the stronger planning signal. Across 75,000 AI answers and more than one million citations, listicles received 21.9% of citations, articles 16.7%, and product pages 13.7%. Together, those three formats accounted for more than 52%. The useful lesson is not that every brand needs more listicles. It is that each page should perform the job implied by the query.

    Query intentFormat signal in the analyzed answersWhat your page needs to accomplish
    InformationalArticles received 45.5% of citations, followed by listicles at 21.7%.Explain the subject directly, define its scope, answer related questions, and make important qualifications easy to find.
    CommercialListicles received 40.9% of citations.Help the reader compare options using explicit criteria, trade-offs, suitable use cases, and a clear method for choosing.
    Transactional or navigationalProduct and category pages together represented about 40% of citations.Confirm exactly what is offered, organize available choices, and connect the requested action to accurate product or service facts.

    An informational article should not hide its answer behind a product pitch. A product page should not imitate a neutral comparison while omitting alternatives and trade-offs. A commercial page should give the reader a defensible comparison method rather than a list of brands ordered to suit the publisher.

    Neutrality becomes particularly important when someone asks for a recommendation. In professional services, third-party listicles accounted for 80.9% of citations. A company’s self-authored list of the best providers cannot carry the same independence as a genuinely editorial comparison.

    You cannot manufacture that independence on your own domain. You can make your offering easier for credible third parties to evaluate: publish accurate category and product facts, maintain a clear entity home, correct outdated public information, and earn relevant coverage or inclusion through legitimate public-relations work. Do not disguise advertising as independent analysis; it weakens the very corroboration you are trying to build.

    Model differences also prevent one format from becoming a universal recipe. ChatGPT leaned toward articles and informational content in the analyzed sample, Google AI Mode had a more balanced mix, and 17% of Perplexity citations came from discussions such as forums and Reddit. Prioritize the platforms your audience actually uses, then inspect their answers instead of assuming that a page cited by one system will be preferred by all of them.

    Put the quotable answer near the top, then earn the depth

    Where you place information can matter as much as how much you publish. ChatGPT citations appeared most often in the 10% to 20% portion near the beginning of a page, while the final 10% received little recognition. If the conclusion, key distinction, or decisive comparison appears only after several screens of setup, it is harder for both readers and retrieval systems to identify the passage that answers the question.

    Use the opening portion of a citation-targeted page deliberately:

    1. Answer the primary question in the first few sentences. State the scope and any qualification that would materially change the answer.
    2. Place the essential definition, decision criteria, or comparison immediately after that answer.
    3. Use descriptive headings that correspond to real follow-up questions. A heading such as “When this option is unsuitable” carries more meaning than “Other considerations.”
    4. Support factual claims where they appear. Do not separate a bold claim from its explanation or evidence by several sections.
    5. Expand into examples, edge cases, alternatives, and implementation details only after the reader can understand the core answer.
    6. Do not save a new, essential conclusion for the closing paragraph. The close should help the reader act on information already established.

    Longer content often earns more citations, but raw length is a poor production target. Pages with 5,000 to 10,000 characters showed a substantial lift, while pages above 20,000 characters averaged 10.18 citations compared with 2.39 for shorter pages. That relationship does not prove that adding characters creates citations. Comprehensive pages are also more likely to answer the related subquestions generated during retrieval.

    The pattern varies by subject. Shorter, information-dense finance pages could outperform long guides, while longer pages retained their value in education, crypto, and product analytics. Let the query family determine the necessary depth. Remove repetition, but do not cut a necessary distinction merely to hit an arbitrary length.

    Structured data belongs after this editorial work, not in place of it. JSON-LD can clarify the page type, entity, and relationships already expressed in the visible content. It cannot supply substance or independent credibility that the page lacks. Make the markup match the copy exactly; if the schema asserts a different name, category, offer, or relationship, repair the underlying information rather than adding more markup.

    Give your brand one stable identity anchor

    A glowing geometric keystone connects to blank website, profile, product, directory, and knowledge cards that share the same visual motif.

    A useful page can answer a question while leaving the publisher poorly understood. Brand visibility requires a second layer: a stable place where people and machines can resolve who the brand is, what it does, and which claims about it are supported.

    This identity anchor is often called an entity home. It may be an About page, but the label is not important. Choose the durable URL that most clearly defines the organization. It should remain available long enough to become the consistent reference point for your brand’s identity.

    Audit that page for five things:

    • A single, consistent brand name and an immediate explanation of what the organization does.
    • A clear description of the people or organizations it serves and the categories in which it operates.
    • Links to the relevant product, service, editorial, policy, or evidence pages that substantiate important claims.
    • Visible facts that agree with the Organization schema and other structured data associated with the brand.
    • Claims that credible third parties can corroborate, rather than unsupported superlatives repeated only on properties the brand controls.

    Think of every important brand claim as a three-part chain. The entity home defines it. A relevant first-party page explains or proves it. Independent material confirms it when independent confirmation is appropriate and available. If one part conflicts with another, the entity becomes harder to resolve.

    For example, do not describe the business with one category on the entity home, another in page titles, and a third in external profiles. Decide which description is accurate, update the pages you control, and seek corrections where material third-party information is demonstrably outdated. Consistency should reflect reality; it is not a reason to repeat an inflated claim more widely.

    The entity home is an anchor, not the whole brand narrative. Supporting pages still need to explain individual offerings, expertise, comparisons, and evidence in enough detail to answer the corresponding queries. The identity page tells a system which entity it is dealing with; the rest of the site demonstrates why that entity belongs in a particular answer.

    Measure the query-to-page relationship, then improve one variable

    AI citation visibility is many-to-many. One grounding query can cite several pages, and one page can support several grounding queries. A report containing separate lists of queries and URLs cannot show whether the correct page is appearing for the intended question.

    Bing Webmaster Tools now connects those two sides in its AI Performance reporting. You can select a grounding query to see its cited pages or select a page to see its associated grounding queries. The dashboard also provides cited URLs and visibility trends across Bing and Copilot experiences.

    Turn that mapping into a repeatable optimization workflow:

    1. Record the grounding queries, cited URLs, and current visibility trend for one commercially or strategically important query family.
    2. Label each query by intent and each URL by its proper role: informational article, comparison, product or category page, or entity page.
    3. Check the fit. A citation is less useful diagnostically if a general About page appears where a detailed product page should answer the question.
    4. Inspect missing relationships. Look for relevant queries with no suitable owned page, strong pages connected to unrelated queries, and important subquestions answered only deep in a page.
    5. Choose one meaningful change: correct the format, strengthen the opening 20%, add a genuinely missing subtopic, resolve an unsupported brand claim, or improve links within the topic cluster.
    6. Record the change and compare the mapping and trend in a later reporting cycle. Avoid rewriting several pages at once when you want to learn which intervention mattered.

    Do not reduce the work to a total citation count. Track whether the brand appears for the right query families, whether the cited URL matches the user’s intent, and whether important brand claims have independent support. Keep conventional search performance and business outcomes alongside those measures. A citation is visibility, not proof that the visitor understood the answer or completed a valuable action.

    Key takeaways

    • Ranking helps citation eligibility, but a number-one position does not guarantee inclusion in an AI answer.
    • Plan around query families and fan-out questions, including useful subquestions that conventional keyword tools may show as zero volume.
    • Match the format to intent: articles for explanation, list-based comparisons for commercial evaluation, and product or category pages for transactional and navigational needs.
    • Place the direct answer and decisive criteria near the beginning. Add length only when it supplies relevant coverage.
    • Use an entity home, consistent first-party facts, structured data, and credible third-party corroboration to make the brand easier to resolve.
    • Measure query-to-page mappings so you improve the page associated with the actual AI demand rather than guessing from aggregate visibility.

    Start with one query family where absence from AI answers matters to the business. Assign the right page to each intent, rewrite the most important page from the top down, and repair the corresponding claims on your entity home. Once the query-to-page mapping improves, apply the same process to the next cluster.

    References


  • How to Test Emerging High-Intent Advertising Channels

    How to Test Emerging High-Intent Advertising Channels

    You probably don’t need another place to buy impressions. You need access to moments when a buyer is already narrowing a choice: which product to trust, which offer is worth acting on, or which nearby business to visit.

    Reddit’s expanding shopping formats and the prospect of sponsored listings in Apple Maps create two very different ways to reach those moments. The practical question isn’t which channel sounds newer. It is whether the user’s decision, your conversion path, and your measurement system line up well enough to justify a controlled test.

    Start with the decision your customer is trying to make

    A high-intent channel places an ad inside an active decision. That is more useful than simply finding an audience with the right demographic profile, but it doesn’t automatically make every impression valuable. You still need to identify the decision being made and the distance between that decision and revenue.

    On Reddit, the valuable moment is often product investigation or validation. A shopper may already know the category but still be comparing alternatives, checking whether a claim holds up, or looking for reassurance from people with relevant experience. Reddit reports that shopping discussions increased 40% over the previous year and 84% of shoppers felt more confident after browsing the platform. Those are platform-supplied figures, so treat them as evidence of the use case rather than a forecast for your campaign.

    Apple Maps would capture a different decision. Someone searching a map is often choosing where to go, which nearby provider fits the need, or whether a location is practical. The proposed advertising model would allow retailers and brands to bid on search terms and appear as sponsored businesses in Maps results. That could put an advertiser close to a local action, but the channel should remain on your watchlist until Apple confirms availability, eligibility, targeting, reporting, and market coverage.

    The simplest distinction is useful: Reddit can influence what someone chooses, while a map can influence where someone goes. Before assigning budget, complete this sentence: “When the ad appears, the customer is deciding whether to _____.” If the blank contains only “notice our brand,” you haven’t established a high-intent use case.

    • For ecommerce, name the product decision: compare, validate, switch, replenish, buy a bundle, or respond to a deal.
    • For local campaigns, name the destination decision: visit, call, book, order, request directions, or confirm that a location can meet the need.
    • Define the next observable action. A vague goal such as engagement will not tell you whether the channel reached the intended decision.
    • Identify existing demand that could be recaptured by the ad. A branded map query or a loyal customer’s repeat purchase may look efficient without creating incremental revenue.

    Match the channel to your conversion geometry

    Two contrasting customer paths show online shoppers moving from a discussion to checkout and a mobile user following a map route to a storefront.

    Channel selection should follow the shape of your business. Reddit’s shopping tools are built around products, catalogs, visual context, social proof, and offers. A map-based auction would be built around queries, locations, and local actions. Those aren’t interchangeable forms of intent.

    Channel opportunityDecision momentStrongest initial fitCritical dependencyUseful outcome
    Reddit Dynamic Product and Collection AdsProduct discovery, comparison, validation, or deal evaluationEcommerce businesses with a maintained catalog and products that benefit from explanation, context, or community discussionAccurate product feed, functioning conversion measurement, suitable creative, and relevant product economicsIncremental orders and contribution margin from the exposed product set
    Proposed Apple Maps sponsored listingsSelection of a nearby business, retailer, service, or destinationBusinesses with physical locations or genuinely local conversion pathsAccurate location records, a fast route to calling or booking, store-level measurement, and confirmed platform accessIncremental qualified local actions and revenue attributable to participating locations

    Reddit is the clearer near-term candidate when revenue depends on a product catalog and buyers actively seek peer context. Collection Ads combine a lifestyle image with purchasable product tiles, while community and deal overlays can add platform-native proof or price information. That combination is most useful when the context helps a buyer choose among products; it is less compelling if your catalog is thin, your feed is unreliable, or the purchase requires no meaningful evaluation.

    Apple Maps is the stronger planning candidate when location is part of the conversion itself. A restaurant, clinic, retailer, repair service, or other location-based business can plausibly benefit from appearing while someone chooses a destination. An online-only business with no local fulfillment path would have a much weaker reason to prepare.

    Do not choose between them by comparing audience size or headline ROAS. Ask where your buyer experiences uncertainty. If the uncertainty is “Which product should I trust?”, test a product-research environment. If it is “Which nearby business should I use?”, prepare for a map environment. If neither question describes your customer, these channels may be interesting without being relevant.

    Make your data launch-ready before you buy traffic

    New ad inventory can be inexpensive because competition is limited. It can also be expensive to learn on because integrations, reporting, and optimization patterns are immature. The best early-mover advantage is operational readiness: you can run a clean test while other advertisers are still repairing feeds, location records, landing pages, and attribution.

    Prepare a product system for Reddit

    Reddit’s Shopify integration is intended to simplify catalog and pixel setup for Dynamic Product Ads, but it was described as an alpha-stage integration. Alpha status matters. It can imply limited access, changing behavior, or incomplete workflows, so don’t make the integration a dependency until your account is eligible and the setup works with your catalog.

    Before launching, inspect the records that determine which product can be shown and what happens after the click:

    • Use stable identifiers for products and variants so ad events can be reconciled with orders.
    • Check that titles distinguish products clearly without relying on internal naming conventions.
    • Verify that price, availability, destination URL, product image, and variant information agree across the feed and landing page.
    • Separate products with materially different margins, return patterns, or discount sensitivity. Revenue can hide a poor product-level result.
    • Confirm that view, product, cart, checkout, and purchase events occur in the expected sequence and do not fire twice.
    • Build creative around the buyer’s unresolved question. A lifestyle image should supply context, not merely duplicate the product tile.
    • Document which discounts are intentional before enabling deal-oriented messaging. An automated price signal can accelerate a bad promotion as easily as a good one.

    Community labels and deal overlays may reduce hesitation, but they should not carry the entire sales argument. The landing page still needs to answer the questions the ad raises: what the product is, who it suits, how variants differ, what it costs, and what the buyer should do next.

    Prepare a location system for Apple Maps

    Apple Maps sponsored listings remain a reported advertising plan, not inventory you should assume is universally available. Preparation should therefore concentrate on reusable local-search assets rather than speculative campaign settings.

    • Create a canonical record for every location: business name, category, address, phone number, operating hours, URL, and available services.
    • Assign ownership for temporary closures, holiday hours, relocations, and duplicate records. Stale location information wastes paid clicks and damages trust.
    • Give each location a destination page that helps the visitor complete a local action rather than dropping everyone on the home page.
    • Map non-branded local needs to eligible locations. Keep branded or navigational queries separate if the eventual campaign controls permit it.
    • Decide how calls, bookings, orders, visits, and store revenue will be connected to campaign exposure before spending begins.
    • Record your current store-level baseline. Without it, a future lift can be mistaken for seasonality, a promotion, or normal location variance.

    Do not design a detailed Apple Maps bidding structure around controls that Apple hasn’t confirmed. A keyword list, location inventory, conversion taxonomy, and baseline dataset are portable. Assumptions about match types, reporting windows, auction controls, or optimization goals are not.

    Keep ad data, page content, and structured data aligned

    Your advertising feed, visible page content, analytics events, and structured data should describe the same product or location. For products, align identifiers, variants, price, availability, currency, and canonical URLs. For locations, align the business identity, address, phone number, hours, service area, and destination URL.

    This is where SEO, AEO, GEO, and paid-media operations meet: not through a magical ranking shortcut, but through a shared factual layer. When the feed advertises one price, the page shows another, and Product markup exposes a third, performance diagnosis becomes needlessly difficult. The same problem appears when a local ad leads to an outdated location page.

    Treat Schema.org markup as data hygiene, not as an ad-auction lever. Unless a platform explicitly documents a connection, don’t promise that Product or LocalBusiness schema will create eligibility, improve ad rank, or lower media costs. Its practical value here is consistency, machine-readable context, and easier auditing across the discovery journey.

    Run an incrementality test, not a launch celebration

    An analyst observes two matching glass test environments, with campaign light applied to one group and the other kept neutral as a control.

    Emerging channels produce noisy early results. Tracking may be incomplete, algorithms have less account history, and a launch can coincide with promotions or seasonal demand. A narrow test protects your budget and gives you a better chance of learning what caused the result.

    1. Write a falsifiable thesis. Name the audience context, the decision moment, the promoted products or locations, the expected action, and the economic reason the channel could work.
    2. Choose a bounded test cell. Use a defined product group, location group, market, or campaign period rather than exposing the entire business on day one.
    3. Create a comparison. Depending on volume and operational constraints, use a matched product set, comparable locations, a geographic holdout, or a stable pre-test baseline. Document promotions and other media changes that could contaminate it.
    4. Set a budget cap and loss limit before launch. New inventory is not permission to spend indefinitely while waiting for optimization. The downside is real media cost plus the opportunity cost of staff time and promotional margin.
    5. Use a measurement window that reflects the actual buying cycle. Don’t force a local same-day action and a considered ecommerce purchase into the same evaluation rule.
    6. Evaluate incremental economics. Separate revenue that likely would have occurred anyway, especially branded queries, existing-customer purchases, and navigational searches.
    7. End with a decision. Scale, revise, pause, or reject the channel based on the original thesis. Avoid extending a weak test merely because the platform is new.

    Treat platform benchmarks as hypotheses

    Reddit reported that its Dynamic Product Ads generated 91% higher average ROAS year over year in Q4 2025. It also associated Collection Ads best practices with an 8% ROAS improvement. In the Liquid I.V. example, Dynamic Product Ads represented 33% of the brand’s Reddit revenue and outperformed other conversion campaigns by 40%.

    Those figures justify a test case, not a budget forecast. They combine platform-level reporting and a named advertiser example, neither of which tells you your likely incrementality, margin, product mix, audience saturation, or creative quality. Put them in the planning deck under “why investigate,” not under “expected result.”

    Read profit alongside ROAS

    ROAS divides attributed revenue by ad spend. It does not account for gross margin, discounts, returns, fulfillment, agency costs, or sales that would have happened without the ad. A channel can post attractive ROAS while destroying contribution margin.

    For ecommerce, compare incremental revenue with product margin, promotional cost, returns, and media spend at the product-set level. For local campaigns, connect qualified calls, bookings, orders, or visits with store-level revenue wherever your systems and consent framework allow it. If offline revenue cannot be connected reliably, say so in the result rather than replacing it with clicks.

    Watch branded demand separately. A sponsored result that intercepts someone already searching for your exact business may be useful defensively, but it is not equivalent to acquiring a new customer. Your report should distinguish demand creation, decision influence, and demand capture.

    Key takeaways

    • Reddit and Apple Maps represent different intent moments: product validation versus local destination selection.
    • Reddit is actionable for suitable ecommerce advertisers; Apple Maps should remain a prepared watchlist opportunity until launch details and access are confirmed.
    • Choose a channel by the customer’s unresolved decision and your measurable conversion path, not by novelty or audience size.
    • Repair catalog, location, event, landing-page, and structured-data inconsistencies before paying to amplify them.
    • Use vendor benchmarks to justify investigation, never to predict your own ROAS.
    • Judge the test on incremental contribution and qualified business outcomes, with branded or existing demand reported separately.

    Your next move is small and concrete. Write one channel thesis, choose one product or location cohort, audit the data that cohort depends on, and define the comparison you will use. If those four pieces don’t hold together on paper, keep the budget. If they do, you have a test worth running when the inventory is available.

    References