Author: shivamcrushpressai

  • AI Search Data Access and Platform Control: A Practical Guide

    AI Search Data Access and Platform Control: A Practical Guide

    You publish a technically sound page. One AI engine cites it, another repeats an older version of the information, and a third never mentions your brand. That doesn’t automatically mean the page is weak. Each engine may be working from a different pool of accessible data.

    Your job is no longer just to rank one URL. You need to make important facts discoverable, retrievable, understandable, and attributable across systems you don’t control. The way to do that is to diagnose the access path, strengthen the parts you own, and measure each platform separately.

    AI search doesn’t operate from one universal index

    From 2023 through 2026, deals, restrictions, and lawsuits changed how data could flow into AI systems. By 2026, tighter platform control was contributing to more fragmented answers. A page can therefore be visible in one AI product and effectively absent from another without changing at all.

    That fragmentation makes a single visibility score misleading. AI search products can differ at several layers:

    • Discovery: The system has to find the URL through a crawl, feed, index, link, API, licensed collection, or another permitted route.
    • Access: The relevant crawler or retrieval service has to receive the content rather than a block, login screen, consent wall, empty shell, or error response.
    • Parsing: The system has to extract the main facts, entities, relationships, dates, and supporting evidence from the returned content.
    • Retrieval: The page has to be considered relevant when a user asks a particular question. Being stored somewhere does not guarantee selection for that query.
    • Synthesis: The answer generator has to use the retrieved information accurately and preserve material qualifications.
    • Attribution: The interface has to decide whether and how to display a citation. An accurate mention and a visible link are separate outcomes.

    This distinction matters because each failure calls for a different fix. Adding more schema won’t correct a crawler block. Rewriting a page won’t repair an outdated third-party profile. Securing a brand mention won’t necessarily produce a clickable citation.

    Use the following as a fault-isolation chart, not as proof of a cause. One observation is a lead; repeated tests and access evidence are what establish the diagnosis.

    What you observeEarliest likely failureWhat to inspect next
    The URL is absent everywhere you testDiscovery or accessSitemaps, internal links, server responses, robots.txt, page-level directives, and authentication requirements
    One engine uses the current fact while another gives an older answerRetrieval freshness or a stale copyThe URLs each engine cites, cached or syndicated versions, and the last verified canonical update
    The answer is accurate but has no linkAttribution or interface behaviorTrack the mention as answer inclusion, then record citation presence separately
    A third-party profile is cited instead of your siteSource selection or owned-page accessWhether the profile is more complete, more current, easier to parse, or the only version available to that engine
    Your page is cited for branded questions but absent for category questionsRetrieval or evidence strengthWhether the page directly answers the non-branded need and supports its claims with specific, verifiable information

    Audit the entire route from page to AI answer
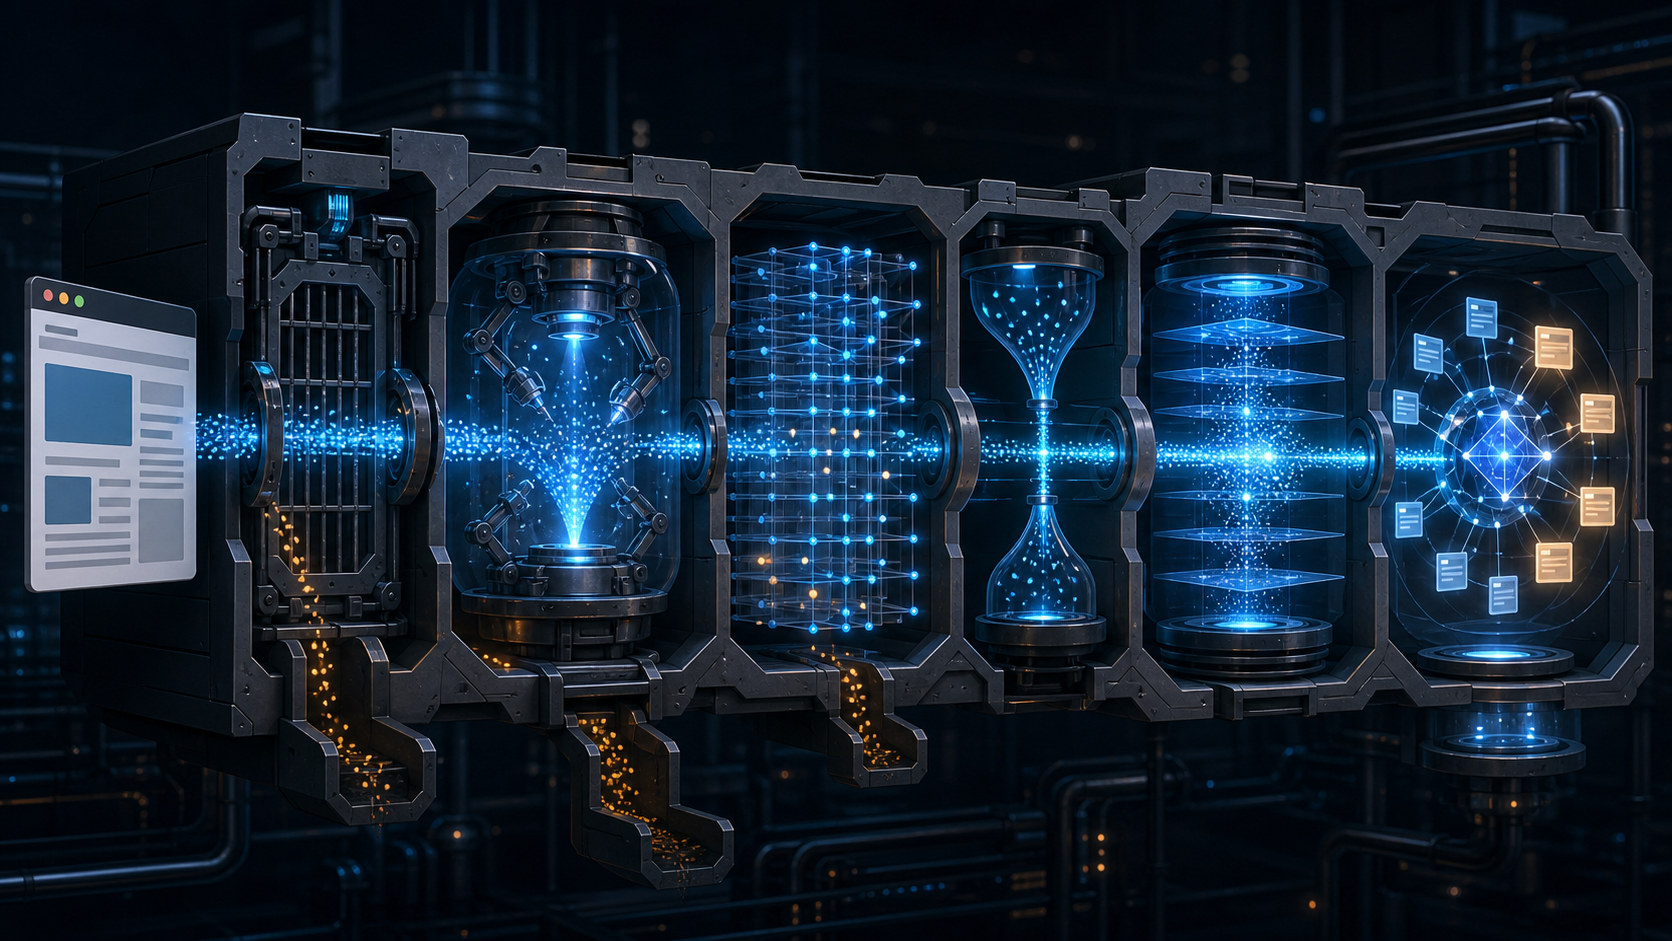
    An abstract web page passes through a series of gated processing chambers before its information reaches an AI answer interface.

    Start with a query-level audit. A domain-wide score can hide the difference between a commercially important failure and an irrelevant miss. Choose questions tied to an actual decision: selecting a provider, verifying a product capability, comparing an approach, confirming eligibility, or checking whether information is current.

    1. Define the fact that should survive the journey. Write down the exact claim an accurate answer needs to contain, the canonical URL that supports it, and any condition that must remain attached. If a limitation changes the meaning, include it in the expected answer.
    2. Separate branded, non-branded, and verification queries. A branded prompt tests whether the engine recognizes your entity. A non-branded prompt tests whether you are retrieved for the problem you solve. A verification prompt tests whether the engine can confirm a precise fact. Do not blend these intents into one score.
    3. Keep test conditions stable. Use the same query wording while comparing engines. Record the product, model or mode when displayed, date and time, account state, region when relevant, and whether web retrieval was enabled. Change one variable at a time.
    4. Capture the answer before judging it. Save the wording, named entities, qualifications, citations, linked URLs, and any visible freshness indicators. Mark factual accuracy and citation presence in separate fields.
    5. Trace every cited URL. Determine whether the engine selected your canonical page, a syndicated copy, a marketplace listing, a social profile, an aggregator, or another publisher. That choice reveals which data route is currently carrying your visibility.
    6. Inspect the owned page as a machine receives it. Check the response status, redirect chain, canonical target, robots.txt rules, meta robots directives, X-Robots-Tag headers, rendered content, and the text available without a user completing an interaction. Confirm that the critical claim is present in the accessible page body.
    7. Classify the earliest failure. Label it discovery, access, parsing, retrieval, synthesis, attribution, or external-copy drift. Fix that layer first. Later-stage optimization cannot compensate for an earlier-stage block.

    Your audit sheet should preserve evidence, not just a final grade. Useful columns include query ID, intent, expected fact, canonical URL, engine, mode, test conditions, answer text, accuracy, qualification preserved, citation present, cited domain, cited URL, access result, failure class, owner, and next action.

    Retest after a meaningful change to content, access controls, structured data, distribution, or a cited external record. Avoid repeatedly changing the prompt until you receive the answer you want. That measures prompt manipulation, not dependable visibility.

    Build visibility that can survive platform boundaries

    You cannot force every AI platform to ingest, retrieve, or cite your content. You can make your facts easier to obtain through permitted routes and reduce the damage when a platform changes its access policy.

    Maintain a canonical fact layer on property you control

    Give every decision-critical fact a stable home. The page should state the fact plainly, identify the entity it belongs to, carry necessary conditions beside the claim, and show the information needed to judge freshness. Essential information should not exist only in an image, video, downloadable file, tab, or client-side widget.

    Create a fact register for content that commonly drifts. For each item, record:

    • The approved wording and any mandatory qualification
    • The canonical URL and responsible owner
    • The visible page element where the fact appears
    • The structured-data field, if one legitimately applies
    • The event that should trigger an update
    • The approved external channels carrying a copy

    This turns freshness into an operating process. When a product detail, policy, service area, leadership record, or other material fact changes, you know which owned page and external records need attention.

    Use external platforms as distribution, not the master record

    Third-party platforms can be valuable discovery routes, especially when an AI engine has stronger access to them than to your site. They also create dependency. A profile can become stale, change format, restrict access, or disappear from an engine’s retrieval set.

    Publish a compact, consistent version of important facts on approved channels, then maintain a map from each external record back to its canonical owner. Avoid copying every page everywhere. Full duplication multiplies the places where old wording can survive. Distribute the facts a channel genuinely needs, preserve qualifications, and link to the canonical page where the channel permits it.

    If a platform restricts automated access or reuse, do not bypass its controls to create an unofficial data pipeline. Use its approved API, feed, export, publishing workflow, or licensing route. Circumventing access rules can create contractual or legal exposure, and the resulting pipeline is likely to break without notice.

    Treat structured data as translation, not permission

    JSON-LD helps a parser connect a page to an entity and interpret supported properties. It does not grant crawler access, compel retrieval, prove a claim, or guarantee a citation.

    Use the schema type that matches the visible entity and content. Keep names, identifiers, URLs, dates, and relationships consistent with the page. Do not place promotional or unsupported claims in markup that a reader cannot verify in the visible content. After publishing, validate both the syntax and the rendered values; syntactically valid markup can still describe the wrong entity or carry an outdated field.

    Support the same canonical layer with ordinary discovery mechanisms such as coherent internal links, XML sitemaps, useful page titles, stable URLs, and feeds where appropriate. For partners that accept structured submissions, maintain those feeds from the same fact register instead of editing each destination independently.

    Measure access, inclusion, and citation separately
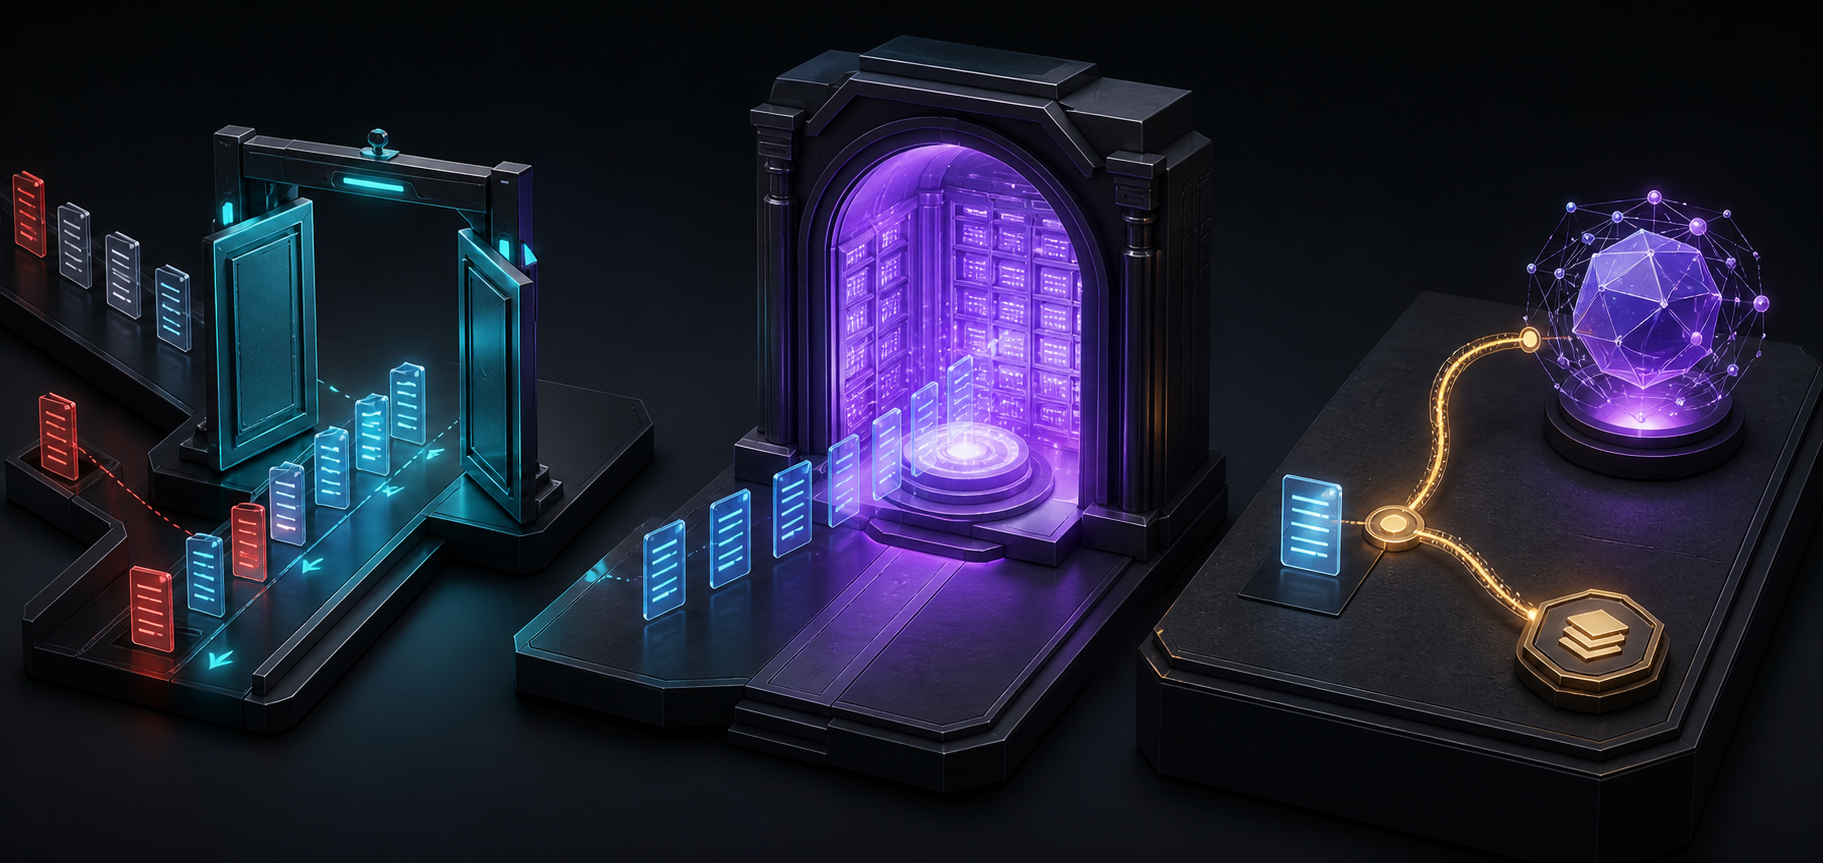
    Three inspection stations separately examine whether web information passes an access gate, enters a knowledge repository, and remains linked to a source in an AI response.

    A blended AI visibility score can rise while the wrong fact is being repeated, or fall because an interface stopped displaying citations even though your information still shapes answers. Keep the signals separate so each metric leads to a clear decision.

    SignalEvidence to recordDecision it supports
    Technical availabilityResponse, redirect, crawler rule, authentication, and returned HTMLWhether discovery and access need repair
    Content extractabilityWhether the expected fact and qualification appear in the fetched or rendered textWhether essential content must be moved, clarified, or exposed more reliably
    Answer inclusionWhether the answer accurately contains the expected fact or entityWhether retrieval and content relevance are working
    Citation attributionWhether a citation appears and which exact domain and URL receive itWhether owned visibility or an external dependency carries the answer
    Factual alignmentCorrect, incomplete, contradicted, or unsupported, with the answer text preservedWhich misinformation or missing qualification needs priority
    FreshnessWhether the answer matches the current canonical record and which version appears to be usedWhether an old owned page, stale external copy, or retrieval lag needs investigation
    Cross-platform coverageThe result for each engine and query rather than one combined rankWhich platforms matter enough to justify targeted work
    Dependency concentrationWhich external domains repeatedly carry mentions or citationsWhere loss of access could remove a large part of your visibility

    Use clear labels such as pass, partial, fail, and not observable, then retain the underlying evidence. Not observable is important: you usually cannot inspect an engine’s private corpus or prove why it selected a particular passage. State what the test demonstrates and keep inference separate.

    Prioritize wrong and outdated facts before missing citations. Next, fix owned-page access and parsing problems that affect several queries. Then address stale external copies and weak non-branded retrieval. An accurate uncited answer may still matter, but it should not be reported as equivalent to an owned citation.

    Do not treat every engine discrepancy as a data-access failure. Query wording, retrieval timing, answer mode, personalization, and normal generation variation can also change the result. A stable query set, captured citations, server evidence, and repeated observations help you distinguish a platform pattern from a one-off response.

    Key takeaways for an AI search access strategy

    • AI visibility is platform-specific because engines do not necessarily discover, access, retrieve, or cite the same data.
    • A public URL is not automatically discoverable, fetchable, parseable, retrievable, or eligible for visible attribution.
    • Audit the answer path in order and fix the earliest failing layer before changing later-stage content or schema.
    • Track accurate inclusion and visible citation as separate outcomes.
    • Keep critical facts on an owned canonical page, then distribute controlled versions through approved external routes.
    • Use JSON-LD to clarify visible information, not to replace access, evidence, maintenance, or content quality.
    • Measure each engine and query independently, preserve the evidence, and mark private platform behavior as inference rather than fact.

    Start with one page tied to a real customer decision. Write down the fact it must communicate, test the corresponding query across the AI products your audience uses, and trace the route from discovery through citation. Fix the first broken layer, update every approved copy from the same fact register, and repeat the test after the change. That gives you a visibility system you can operate even when the surrounding platforms keep moving.

    References


  • How to Integrate PR and Social Media for AI Visibility

    How to Integrate PR and Social Media for AI Visibility

    You have earned media coverage. Your social accounts are active. Your website explains the product. Yet when a buyer asks an AI assistant about the problem you solve, your brand is absent, mischaracterized, or mentioned without a citation.

    The answer usually isn’t another disconnected content calendar. You need an evidence chain in which PR, social media, and owned content support the same defensible claims. That is the practical value of connecting SEO, social presence, PR, and content creation: every campaign can leave behind material that people can understand, publishers can corroborate, and AI systems can retrieve and cite.

    Start with the answer you want the market to repeat

    AI visibility is not simply a contest to repeat your brand name across more channels. A high volume of vague mentions does little to clarify what your company does, who it serves, or why its claims deserve to be trusted.

    Begin with a buyer question, not a campaign slogan. Write down the question in the language a customer would use when asking ChatGPT, Gemini, Perplexity, or another answer engine. Then define the answer you can substantiate.

    A useful claim map contains:

    • The audience question: the specific problem, comparison, definition, or decision the campaign will address.
    • The approved answer: a concise statement that names the brand or product consistently and explains its relevance.
    • The supporting proof: evidence, methodology, product documentation, expert attribution, or another verifiable basis for the answer.
    • The necessary qualification: the conditions, limitations, or scope that must travel with the claim.
    • The canonical destination: the stable page where the complete explanation and supporting evidence will live.
    • The corroboration goal: the independent context that PR outreach should seek to establish.

    If the team cannot complete those fields, the claim is not ready for distribution. Publishing it more widely will multiply ambiguity rather than authority.

    A practical drafting pattern is: For [audience], [product or organization] addresses [defined problem] through [specific mechanism], supported by [verifiable evidence]. The final wording should sound natural, but the structure forces the team to identify the entity, problem, mechanism, and proof.

    Be especially careful with superlatives such as best, leading, fastest, and most trusted. Those words require a defined comparison and defensible evidence. Replace an unsupported category claim with a narrower factual statement that a publisher could verify without relying on your press release.

    This discipline matters because useful AI citations must be credible and traceable. Your PR brief, spokesperson notes, owned page, and social adaptations should preserve the same underlying meaning even when their formats differ.

    Build the citation-ready destination before outreach begins

    A press release, interview, social thread, or video should not be the only place where a campaign’s central explanation exists. Publish a stable, readable HTML destination before outreach so every later asset has somewhere authoritative to point.

    The page does not need to be long for its own sake. It needs to resolve the reader’s question without making them assemble the answer from several campaign fragments. Include:

    • A descriptive title that identifies the subject rather than merely naming the campaign.
    • A direct answer near the beginning of the visible copy.
    • Consistent organization, product, and spokesperson names.
    • The evidence behind the claim, with methodology and limitations when those details affect interpretation.
    • Definitions for specialized terms that a buyer or journalist could reasonably misunderstand.
    • Clear authorship, editorial ownership, or expert attribution where relevant.
    • A stable URL that will remain useful after the launch period ends.
    • Accurate structured data that matches the visible content and identifies the page’s real entities and content type.

    Structured data can clarify what a page represents, but it cannot turn an unsupported assertion into independent evidence. JSON-LD, page copy, metadata, and PR materials must agree. If the markup identifies an author, organization, product, or frequently asked question that the visible page does not substantiate, fix the content-model mismatch instead of adding more markup.

    Turn one campaign into connected answer units

    Once the canonical page is ready, run the campaign in a deliberate sequence:

    1. Publish the complete owned explanation. Make the central answer, evidence, terminology, and limitations available in crawlable text.
    2. Build the pitch around the audience question. The news angle may change by publication, but the verifiable claim should not.
    3. Prepare corroboration material. Give spokespeople and PR teams the original evidence, methodology, definitions, and approved entity names rather than a shortened claim with no context.
    4. Earn accurate coverage. A link to the canonical destination is useful when editorially appropriate, but accurate naming and faithful context still matter when a publisher does not link.
    5. Adapt the explanation for social surfaces. Preserve the answer and proof while changing the delivery for video, executive commentary, community discussion, or short-form updates.
    6. Connect the assets. Point social audiences to the complete explanation, add earned coverage where it provides useful corroboration, and update the owned page when a campaign exposes a real unanswered question.

    Do not lock the only usable explanation inside an image or video. Publish the substance as readable text, then use richer formats to demonstrate, discuss, or distribute it. YouTube, Reddit, and substantive long-form content can support AI visibility and citation, but only when the material contains enough context to stand on its own.

    Give PR and social media different jobs in the evidence chain

    Press equipment reveals a central verified object while connected social nodes distribute it, all anchored to an organized archive of source materials.

    Integration does not mean copying the same announcement onto every channel. It means assigning each surface a clear job while keeping the claim, entity names, evidence, and qualifications aligned.

    SurfacePrimary jobUseful formatCommon failure
    Owned websiteEstablish the canonical explanationHTML explainer, evidence page, documentation, or question-led landing pageA campaign page that contains slogans but no direct answer or proof
    Earned PRAdd independent context and corroborationReported coverage, expert commentary, interview, or contributed analysis with clear disclosureRepeating an announcement without verifying or explaining its central claim
    YouTubeDemonstrate or explain the answer in depthWalkthrough, interview, demonstration, or question-led explanation supported by descriptive textA promotional clip whose title, description, and spoken content never resolve the question
    Reddit or another communityAddress real questions in the language people useTransparent participation, a substantive answer, or a clearly identified expert discussionAstroturfing, undisclosed promotion, or dropping links without answering the question
    Executive or expert social accountAttach informed interpretation to a named personCommentary, a concise explanation, or a response to a relevant industry questionGhostwritten claims that exceed the person’s actual expertise or omit important limits
    Short-form brand socialDistribute and reinforce the campaign’s core languageKey finding, visual excerpt, short clip, or link to the complete resourceSplitting the claim into fragments that lose their evidence and context

    This is where answer engine optimization changes the social brief. An AEO-driven social strategy pursues discoverability and citations as well as engagement. That does not make likes, comments, and watch behavior irrelevant. It means engagement is no longer the only outcome the team should inspect.

    Keep the handoffs explicit. The SEO or GEO owner defines the target question, canonical page, internal links, and structured data. PR owns the evidence pack, editorial angle, spokesperson preparation, and coverage accuracy. Social owns format adaptation and community participation. A measurement owner preserves the prompt set and records what answer engines retrieve before and after the campaign.

    Each team should be allowed to improve the presentation, but no team should silently strengthen the claim. When a social caption removes a qualification or a pitch turns a narrow result into a universal one, the integrated campaign becomes inconsistent at the point where consistency matters most.

    Measure retrieval, citation, and description accuracy

    Three analysts inspect an AI-generated product model whose illuminated paths lead back to source fragments in an organized repository.

    Reach and engagement tell you whether people encountered a social asset. They do not tell you whether an AI answer can find the brand, cite the right URL, or explain the claim correctly. Add an answer-level measurement layer.

    Build a fixed prompt set from real sales, support, search, and customer-research questions. Include brand-neutral discovery prompts as well as branded prompts. The first group tests whether you appear when the buyer has not selected you; the second tests whether AI systems describe you accurately once your name is present.

    Useful prompt patterns include:

    • What is [category or problem]?
    • How can [audience] solve [specific problem]?
    • Which approaches are suitable for [defined use case]?
    • How does [brand or product] address [problem]?
    • What evidence supports [specific claim]?
    • What are the limitations or tradeoffs of [approach]?

    Run the same set across the answer engines that matter to your audience. Preserve the date, product or model label when visible, complete response, cited URLs, and relevant screenshots or exports. AI outputs can vary, so a single favorable response is an observation, not proof of durable visibility.

    For every response, record:

    • Presence: whether the brand is absent, merely mentioned, presented as an option, or used as a substantive part of the answer.
    • Citation: whether a citation is present and which exact URL receives it.
    • Source path: whether the cited destination is owned content, earned coverage, YouTube, Reddit, or another surface.
    • Description accuracy: whether the answer identifies the right entity, audience, capability, evidence, and limitations.
    • Claim fidelity: whether the wording remains within what your evidence supports.
    • Competitive context: which alternatives appear and what evidence seems to support their inclusion.

    Establish the baseline before launch. Recheck after the owned resource, earned coverage, and social adaptations are available. Look for repeated changes across related prompts and systems, then inspect the URLs behind those changes. Do not attribute an improvement to a single social post merely because the timing overlaps; answer engines can draw on many changing inputs.

    Tracking social AI citations and platform-specific visibility patterns can make this review easier, but a dashboard still needs human verification. Open the cited pages. Confirm that the citation supports the answer. Separate a visible brand mention from a cited recommendation, and flag cases where the answer is favorable but factually wrong.

    If you hire outside help for LLM visibility and citation work across ChatGPT, Gemini, and Perplexity, ask for the prompt set, URL-level citation evidence, captured answer context, and a record of when each check was performed. Require the provider to distinguish mentions from citations and observations from causal claims. Avoid any service that guarantees placement in a probabilistic answer system.

    Key takeaways

    • Choose a buyer question and a defensible answer before planning channel output.
    • Publish a stable canonical page with the complete explanation, evidence, terminology, and necessary limitations.
    • Use PR to build independent context, not merely to replicate a brand announcement.
    • Adapt the same substantiated claim for YouTube, community discussion, expert commentary, and short-form distribution without stripping away its qualifications.
    • Keep entity names, product descriptions, evidence, and structured data consistent across the campaign.
    • Measure whether AI systems retrieve, cite, and describe the brand correctly; treat engagement as a supporting diagnostic rather than the final visibility result.

    Apply this system to your next campaign before the pitch list or social calendar is finalized. Pick its most defensible buyer-facing claim, create the claim map, and build the canonical destination. Once that foundation exists, every PR placement and social asset can strengthen one coherent answer instead of creating another disconnected mention.

    References


  • How to Automate Paid Search Without Losing Conversion Quality

    How to Automate Paid Search Without Losing Conversion Quality

    Your paid search account can look healthier while the business behind it gets worse. Cost per conversion falls, the dashboard fills with activity, and automation appears to be working – yet purchases weaken, qualified leads become rarer, or the sales team spends more time rejecting inquiries.

    That usually isn’t an automation failure. It is an instruction failure. Automated bidding, targeting, and testing follow the goals you make visible to them. If those goals reward easy actions rather than valuable outcomes, the system can become highly efficient at acquiring the wrong conversions.

    Make the business outcome the strongest conversion signal

    A bidding system doesn’t independently decide which website action matters to your company. It learns from the conversion actions, values, and campaign goals you provide. When purchases, qualified leads, pageviews, button clicks, and form starts are all treated as optimization targets, frequent low-friction actions can overwhelm the events that produce revenue.

    This is the central conversion-quality problem: more conversion data is not automatically better conversion data. A pageview is easier to generate than a sale. A form start is easier to generate than a qualified submission. If the system receives no meaningful value hierarchy, it has a strong incentive to find the predictable action rather than the commercially important one.

    Too few signals can also slow learning, so the answer is not to delete every intermediate event. The answer is to distinguish observation from optimization. Keep useful micro-conversions for analysis, audience understanding, and funnel diagnosis, but do not automatically make every event a primary campaign goal.

    Build a conversion hierarchy before changing bids

    1. Name the final business outcome. For ecommerce, that will normally be a completed purchase. For lead generation, it may be a qualified lead, an accepted opportunity, or another offline stage that represents genuine commercial intent.
    2. Identify the earliest event that reliably predicts that outcome. A submitted form might be useful if nearly every submission is legitimate. If submissions vary sharply in quality, the stronger signal sits later in the sales process.
    3. Separate primary and secondary actions. Use the commercially meaningful action for bidding. Retain form starts, calls below your qualification standard, page engagement, and similar events as diagnostic signals unless they have demonstrated business value.
    4. Send offline outcomes back to the ad platform. When value is established after a call, review, consultation, or sales conversation, online form tracking alone gives automation an incomplete picture. Offline conversion tracking lets the system learn which clicks created real outcomes.
    5. Use values to express meaningful differences. If two outcomes have materially different business value, representing them as equal conversions hides that distinction. Value-based bidding only helps when the values reflect the hierarchy you actually care about.
    6. Validate the data path. Check that each event fires at the intended stage, is not duplicated, carries the right value, and can be connected to its originating campaign. A sophisticated bidding strategy cannot repair a mislabeled or duplicated conversion.

    Do not compensate for sparse final conversions by promoting every available event into the primary goal set. First check whether delayed or offline outcomes are missing. Adding weak signals may increase reported volume while moving optimization farther away from revenue.

    Use intent and creative to qualify traffic before the click

    Several shoppers with different intentions approach a branching gateway that guides serious buyers toward a focused path and casual browsers toward side paths.

    Conversion quality starts before someone reaches the landing page. Your keywords, product feed, campaign structure, and ad language determine which searches can enter the funnel. The more freedom you give automated targeting, the clearer those inputs need to be.

    This becomes especially important in housing, employment, credit, healthcare, and legal services. Google Ads can restrict website and app remarketing, Customer Match, YouTube interaction audiences, and custom segments in sensitive-interest categories. Housing campaigns may face additional demographic limitations. Even with those controls unavailable, advertisers can still work with keywords, feeds, permitted Google audiences, content targeting, conversion tracking, and certain forms of automated targeting.

    When audience history cannot do the qualifying, search intent and creative have to carry more of the load:

    • Start with the problem expressed in the query. Organize keywords around what the searcher needs, not just the service name your company uses internally.
    • Use phrase or broad match deliberately. Exact match may miss different ways of expressing the same need, particularly in restricted categories. Broader matching can recover that demand, but it should be paired with meaningful conversion signals and regular query review.
    • Make the offer specific in the ad. State who the service is for, what is being offered, and any important eligibility boundary that can be communicated lawfully. Clear creative discourages unsuitable clicks before they consume budget.
    • Keep feeds accurate. For Shopping and feed-led campaigns, titles, categories, prices, availability, and other product attributes shape which searches can surface an item. Feed quality is part of targeting quality.
    • Separate genuinely different services. If a company offers both sensitive and non-sensitive services, distinct sites or domains can preserve a clean operational boundary. That separation should reflect a real difference in the business and user journey, not an attempt to disguise a restricted service.

    Placement changes can complicate the picture. Microsoft has tested a larger, double-row sponsored product carousel in Bing Shopping results, although the format was not visible to every user and should be treated as an experiment rather than a universal layout. More sponsored inventory can increase impressions and clicks without improving the intent of those clicks.

    If Shopping traffic rises abruptly, do not assume the campaign has found a better audience. Compare product-level conversion quality, revenue, query composition, and final outcomes before raising budgets. A larger ad surface is an inventory change; it is not evidence that the additional traffic is valuable.

    Put automated experiments behind business guardrails

    Small autonomous vehicles test multiple routes within glowing boundaries, passing business-value checkpoints while a barrier stops a risky path.

    Experiments are valuable because they isolate a proposed change from the existing campaign. The risk appears at the handoff from test result to live account. Google Ads includes an experiment setting that can apply a winning result automatically and is enabled by default. That can shorten the testing cycle, but it also removes the review point where downstream quality problems are often discovered.

    The experiment interface allows directional evaluation or statistical-significance thresholds of 80%, 85%, or 95%. It also prevents automatic application when a selected success metric performs significantly worse. The limitation is just as important: an experiment can use only two success metrics, so an unselected third metric can deteriorate without stopping the rollout.

    Before launching a test, write down three things outside the platform: the result that would count as a win, the business metric that must not fall below an acceptable level, and the conditions that require manual review. This prevents a visually convincing dashboard from redefining success after the test ends.

    When automatic application is reasonable

    • The change is easy to reverse and has limited reach.
    • The primary success metric represents a final or strongly qualified outcome.
    • The second metric protects the most important cost, value, or quality constraint.
    • No critical business measure sits outside those two metrics.
    • Conversion tracking has been validated before the experiment starts.

    When to require manual review

    • The test changes the conversion goal, assigned values, or bidding strategy.
    • The change expands traffic through broader matching, automated targeting, new inventory, or a substantially different feed.
    • Lead quality is determined offline or only after a meaningful delay.
    • The campaign operates in a regulated or sensitive category.
    • The commercial downside of a false winner is larger than the operational cost of reviewing it.

    For a manual review, look beyond the two headline metrics. Inspect the conversion-action mix, qualified-lead or purchase rate, revenue or assigned value, search-query and product composition, spend distribution, and any delayed offline outcomes. If the experiment appears to win only because it generated more low-value actions, it has not passed a conversion-quality test.

    Diagnose quality loss from the symptom, not the dashboard score

    Automation problems leave recognizable patterns. Use the visible symptom to identify which instruction the system may be following, then correct the signal or boundary before making another bid adjustment.

    What you noticeLikely mechanismWhat to inspectWhat to change
    Reported CPA falls while qualified-lead or purchase rate fallsAn easy micro-conversion is dominating optimizationPrimary goals, conversion-action mix, duplicate events, and assigned valuesMove weak actions to observation, correct duplication, and optimize toward the final or qualified outcome
    Form volume rises but the sales team rejects more leadsThe platform sees submission volume but not downstream qualificationOffline outcome imports, attribution identifiers, and the delay between submission and reviewImport qualified stages and use them as the stronger bidding signal
    Shopping impressions and clicks jump without comparable revenueMore prominent or expanded ad inventory is creating extra exposureProduct-level revenue, query composition, conversion rate, and average order valueHold budget decisions until final conversion quality is clear; refine products and feed inputs where needed
    A sensitive-category campaign has very little eligible trafficAudience restrictions and narrow matching are constraining reachPolicy status, prohibited audience dependencies, keyword coverage, feeds, and ad specificityUse compliant intent targeting, permitted audiences, phrase or broad match where appropriate, and clearer qualifying creative
    An experiment wins but downstream revenue weakensThe deteriorating business metric was not one of the two protected success metricsThe complete funnel, not only the experiment summaryReverse or withhold the rollout, redesign the metrics, and keep automatic application off for that test class
    Smart bidding has too little useful dataFinal outcomes are sparse, delayed, or missing from the platformTracking completeness, offline imports, attribution matching, and conversion lagRepair the final-outcome data path before adding low-intent events as optimization goals

    Resist the urge to solve every symptom by loosening targets or increasing budget. Those changes may give the system more room to pursue the same incorrect objective. Fix the definition of success first, then decide how aggressively to scale it.

    Key takeaways

    • Automated bidding optimizes the conversions and values you expose; it does not independently know which actions create revenue.
    • Keep micro-conversions available for funnel analysis, but make them primary goals only when they are reliable proxies for business value.
    • For lead generation, send qualified offline outcomes back to the platform instead of asking form submissions to stand in for lead quality.
    • When remarketing or audience controls are restricted, use search intent, accurate feeds, and self-qualifying creative to shape traffic.
    • Treat increases caused by new or expanded ad inventory as exposure gains until purchase or lead-quality data proves otherwise.
    • Review auto-applied experiment settings before launch, especially when an important business metric cannot fit among the two success metrics.

    Start your next optimization session in the conversion-goal settings, not the bidding controls. Confirm which actions are primary, trace them to a real business outcome, and identify the quality metric that could deteriorate unnoticed. Once those instructions are sound, automation has something worth scaling.

    References


  • How to Build an AI-Era SEO Stack That Improves Visibility

    How to Build an AI-Era SEO Stack That Improves Visibility

    You are probably not short of AI SEO tools to evaluate. The harder problem is deciding which ones deserve a place in your stack when several products generate briefs, audit pages, track prompts, suggest schema, and summarize reports in slightly different ways.

    The answer is not to buy the platform with the longest AI feature list. Build a system in which every tool produces evidence, that evidence leads to a named decision, and a person verifies the result before it changes a page. That gives you a stack that can support conventional search, answer engines, and generative search without paying for three versions of the same dashboard.

    Choose tools by the decision they improve

    Tool consolidation and AI adoption are happening at the same time. In the 2025 MarTech Replacement Survey’s cohort of 154 marketers who had replaced an application in the preceding year, 43.8% cited cost reduction, while 37.1% considered AI capabilities crucial and 33.9% wanted AI features in a new tool. Those figures describe one survey cohort, not the entire market, but they expose the decision most SEO teams now face: add AI capability without adding another layer of overlapping cost.

    Start by inventorying decisions rather than products. Your working stack needs to cover these jobs:

    • Technical discovery: identify crawling, indexing, rendering, internal-linking, response-code, and metadata problems that block or weaken discovery.
    • Demand and intent: connect queries and audience questions to the page that should answer them.
    • Content evaluation: find omissions, ambiguity, outdated information, weak evidence, and intent mismatches.
    • Entity and structured-data management: make the people, organizations, products, topics, and relationships on a page explicit and internally consistent.
    • Search and AI visibility monitoring: record rankings, impressions, mentions, linked citations, cited URLs, and the accuracy of generated descriptions.
    • Workflow and reporting: turn findings into tickets, briefs, annotations, summaries, and accountable next actions.

    One platform may cover several jobs. That is useful only when the outputs remain specific enough to act on. A single interface filled with generic scores is not an integrated stack; it is a consolidated reporting problem.

    Use a keep, replace, remove, or build audit

    Assign every current tool to one of four buckets:

    • Keep it when it produces evidence you use, fits the workflow, and has a clear owner.
    • Replace it when an important requirement is missing, the data cannot be exported, or another product can remove genuine duplication.
    • Remove it when nobody can name a recent decision that changed because of its output.
    • Build a narrow utility when your process, data model, or reporting logic is genuinely specific to your business.

    For each product, complete this sentence: “When the tool shows ______, the owner does ______, and success is checked with ______.” A blank in any position reveals the real gap. You may have a data problem, an ownership problem, or a validation problem rather than a software problem.

    Do not accept “AI-powered” as a requirement. Translate it into an observable capability. For example: classify a crawl export by likely impact; preserve citations when summarizing evidence; identify the URL cited in an answer; generate JSON-LD from approved fields; or turn approved metrics into a report narrative without changing the underlying numbers.

    Custom software has become more plausible for these narrow jobs. Homegrown applications accounted for 8.1% of replacements in the 2025 survey, up from 3.4% in 2024. That is evidence of renewed interest, not proof that building is automatically cheaper. Buy common infrastructure such as crawling when a mature product already solves the problem. Consider building the small connector, classification rule, or reporting layer that reflects how your organization actually works.

    Make vendors demonstrate the evidence trail

    A useful evaluation should begin with your data and end with your decision. Give each shortlisted tool the same representative input, then inspect the complete path from evidence to recommendation.

    • Can you see the page, query, answer, citation, crawl row, or measurement behind a recommendation?
    • Can you export the raw evidence and the processed result in a usable format?
    • Can you distinguish observed facts from the tool’s interpretation?
    • Can you segment results by page type, intent, market, language, or another dimension that matters to your decisions?
    • Can a reviewer correct the output without rebuilding the workflow outside the product?
    • Can you connect the finding to an owner, ticket, brief, or content update?
    • Does the tool replace an existing cost, or does it merely add a new dashboard?

    If a vendor can show a polished recommendation but not the evidence behind it, treat the output as a hypothesis. That distinction matters more in AI search because an answer can change across prompts and contexts. A tool that preserves the prompt, response, cited URL, date, and evaluation conditions gives you something you can audit. A visibility score without those components is much harder to interpret.

    Put AI on high-friction work, not final judgment

    AI earns its place in an SEO workflow when it reduces the effort between raw input and a reviewable result. It should not quietly become the authority that decides whether a claim is true, a page satisfies intent, or code is safe to deploy.

    Use a repeatable prompt specification rather than an improvised request. Give the model the page’s purpose, audience, target query or task, approved evidence, constraints, required output format, and review criteria. Tell it how to mark uncertainty and what it must not invent. The last instruction is especially important when the input does not contain enough evidence to complete every field.

    Accelerate content work without outsourcing expertise

    Several practical AI-assisted SEO workflows share the same pattern: the model creates options or performs a first pass, while a person supplies expertise and approves what gets published.

    • First drafts: provide a real brief, audience, intended angle, target query, source material, and exclusions. Ask for a structure before a full draft. The editor must then add original reasoning, examples supported by evidence, and the publication’s voice.
    • Content refreshes: give the model the existing page, its target intent, performance context, and current approved facts. Ask it to separate missing coverage, stale material, unsupported claims, structural problems, and optional expansion ideas. Verify each proposed change rather than accepting a rewritten page wholesale.
    • Titles and descriptions: generate variations within your supplied constraints, then choose or combine them manually. Check that each option accurately describes the page; an enticing promise that the page does not fulfill is not optimization.
    • FAQ development: use AI to organize questions found in query research and audience conversations. Remove duplicates, verify that each question belongs on the page, and write answers from approved evidence. Do not manufacture an FAQ merely to create schema.
    • Alt text: supply the image and its function in the surrounding page, not just a filename. Review the result for accessibility and accuracy. A target keyword belongs only when it naturally helps describe the image.

    The quality check is simple: can the reviewer identify what was supplied by the evidence, what was inferred by the model, and what was added by an expert? If those layers are blended together, the workflow is too opaque for reliable publishing.

    Use AI as a technical interpreter and code assistant

    Technical SEO often contains small, high-friction tasks that suit supervised generation:

    • Translate an error message or log excerpt into plain language, possible causes, evidence needed, and reversible diagnostic steps.
    • Generate a regular expression for a clearly described Google Search Console filter, then test it against examples that should and should not match.
    • Classify a crawl export into issue types and propose an order of investigation, while preserving the original rows used for each recommendation.
    • Generate JSON-LD from approved page facts and a named schema type, then compare every value with the visible page before validation.

    AI-generated code can be syntactically tidy and still be wrong. Test regular expressions on a limited dataset. Validate structured data before deployment. Treat suggested fixes to templates, redirects, canonical tags, robots directives, or rendering behavior as code changes that require review and a rollback path.

    Separate reporting observations from explanations

    AI can help scan performance exports for anomalies, compress a long report into an executive summary, or draft the narrative connecting several approved metrics. The model should never be allowed to turn correlation into a confident cause.

    Require reporting output in four labeled parts:

    • Observation: what changed in the supplied data.
    • Possible explanations: hypotheses that could account for the change.
    • Evidence still needed: data required to distinguish those explanations.
    • Next action: the check, experiment, or decision an owner should make.

    This structure makes AI useful without hiding uncertainty. It also creates prompts worth saving. A maintained prompt library for recurring briefs, crawl analysis, metadata, reporting, and schema tasks is more valuable than repeatedly improvising requests, because the inputs, constraints, and review standard become part of the operating process.

    Optimize pages for retrieval, comprehension, and citation

    A modular webpage with organized content and source cards is scanned, and one relevant passage is retrieved into an answer sphere.

    An AI visibility tool cannot compensate for a page that is inaccessible, unfocused, internally inconsistent, or difficult to support with a citation. Conventional SEO remains the retrieval layer. Answer engine optimization and generative engine optimization add a comprehension and representation layer on top of it.

    Build each important page around a clear evidence path:

    1. Assign one dominant intent. Decide which real question, comparison, task, or decision the page should resolve.
    2. State the direct answer early. Do not make a reader or retrieval system work through several paragraphs before discovering the page’s position.
    3. Break complex material into answerable units. Use descriptive headings, a direct explanation, applicable conditions, necessary caveats, and the supporting detail needed to act.
    4. Keep entity names and attributes consistent. A product, organization, person, date, or feature should not acquire different names or conflicting descriptions across the title, body, metadata, structured data, and linked pages.
    5. Support important claims where they appear. Link the words carrying the fact, and distinguish evidence from your interpretation.
    6. Connect related pages deliberately. Internal links should tell a reader what the destination adds, not rely on vague anchor text.
    7. Confirm technical availability. The intended canonical page must be crawlable, indexable where appropriate, renderable, and free from contradictory directives.

    This approach also makes editorial review easier. A reviewer can inspect one answer unit at a time and ask whether it is clear, supported, current, and useful. That is a better quality control mechanism than chasing an aggregate optimization score.

    Treat schema as a translation layer, not a ranking switch

    Structured data gives machines explicit labels for information that may otherwise be expressed only in prose. It can clarify what a page and its entities represent, but it does not repair weak content, establish that an unsupported claim is true, or guarantee a citation in an AI answer.

    Use this schema workflow:

    1. Extract the facts that are visibly present on the page.
    2. Select a schema type that accurately represents that page, such as Article for an editorial page or FAQ when genuine questions and answers appear in the visible content.
    3. Generate or author the JSON-LD from those approved facts.
    4. Compare every populated property with the visible page, including names, descriptions, dates, relationships, and URLs.
    5. Validate the markup. AI can generate Article or FAQ JSON-LD quickly, but the resulting code should still be checked with Google’s Rich Results Test where applicable.
    6. Publish through a controlled template or field mapping so later page edits do not leave stale values in the markup.
    7. Recheck the rendered page and structured data after deployment.

    Validation proves that a parser can understand the code and may surface eligibility issues. It does not prove that the data is accurate, that a search feature will appear, or that a language model will cite the page. Those remain separate checks.

    Schema also should not become an isolated technical project. AI-search strategy increasingly connects technical foundations, content, social activity, public relations, mentions, and citations. The practical lesson is not that every channel needs another tool. It is that your content and reporting systems need a shared view of the entities, claims, questions, and pages the organization wants to be known for.

    Measure AI visibility without disguising it as rank tracking

    An analyst compares how identical glowing inputs produce different webpage fragments and citation markers across several answer portals.

    Rank tracking records an ordered search result under defined conditions. AI answer monitoring records a generated response that may vary with wording, context, system behavior, market, and time. Putting both into one visibility score may be convenient, but it can hide what actually changed.

    Keep the layers separate in your scorecard:

    Measurement layerRecordDecision it supports
    Technical availabilityCrawl state, indexability, canonical target, rendering result, structured-data validityWhether the page can participate as intended
    Conventional searchQuery, landing page, impressions, clicks, position context, conversion outcomeWhere discoverability or intent alignment needs work
    Generated answersExact prompt, engine, date, answer, brand mention, linked citation, cited URL, factual accuracyWhether the brand is represented, supported, and described correctly
    Content operationsAI-assisted task, reviewer changes, rejection reason, approved output, workflow ownerWhere automation saves effort or creates rework
    Stack economicsLicense cost, active use, duplicated output, integration burden, maintenance ownerWhether to keep, replace, remove, or build

    Clicks remain useful, but they cannot describe every zero-click or AI-generated experience. That is one reason teams now seek tools that can measure visibility beyond traditional rankings and clicks. Do not solve that limitation by treating every brand mention as equivalent. An unlinked mention, a citation to your page, a citation to someone else’s page, and an inaccurate description are four different outcomes.

    Create a repeatable AI-answer benchmark

    Build the benchmark from questions that matter to the business, not prompts chosen because the brand already performs well. Include the informational questions, comparisons, objections, and decision-stage tasks that your priority pages are meant to resolve.

    1. Freeze the wording of each benchmark prompt and document its intended user intent.
    2. Record the engine, market or language conditions, date, complete response, citations, and cited URLs.
    3. Capture a baseline before changing content, templates, structured data, internal links, or external promotion.
    4. Change a single meaningful variable where the workflow allows it, and annotate every other known change.
    5. Run the same benchmark on a planned cadence rather than testing only when you expect a favorable answer.
    6. Look for repeated patterns across relevant prompts before claiming that an optimization caused the outcome.

    A mention is not automatically a success. Review whether the answer gives the correct name, category, attributes, limitations, and relationship to the user’s question. Also record which URL earned the citation. If an outdated page or a third-party page is repeatedly cited, that finding should lead to a different action than a simple absence from the answer.

    Measurement should also expose automation failures. Record which AI suggestions were rejected and why. Repeated factual corrections point to an evidence or prompting problem. Repeated voice corrections point to an editorial specification problem. Repeated technical corrections point to a workflow that needs stronger tests, not a model that needs more freedom.

    Key takeaways and your first move

    • Choose an AI SEO tool only when you can name the decision it improves, the evidence it preserves, the owner who acts, and the way the result will be checked.
    • Keep conventional crawling, indexing, intent, and content quality at the base of the stack. AI visibility monitoring adds a measurement layer; it does not replace the retrieval layer.
    • Use AI for first passes, classification, variants, interpretation, and formatting. Keep factual approval, strategic judgment, and deployment control with a qualified reviewer.
    • Make pages easier to retrieve and cite by answering a defined question, using consistent entities, supporting claims in place, and connecting related pages clearly.
    • Use schema only when it matches visible content. Validate the code and verify the facts separately.
    • Track generated answers with their exact prompts, citations, cited URLs, conditions, and accuracy. Do not compress unlike outcomes into one unexplained visibility score.

    Your first move does not require a new subscription. Open the current stack inventory and complete the evidence-action-validation sentence for every tool. Remove the entries nobody can complete. Then choose one recurring workflow with visible friction, such as turning a crawl export into reviewed tickets or turning an approved brief into a review-ready draft. Define its inputs, output, owner, and checks before testing automation.

    Once that workflow is reliable, extend the same operating model to structured data and AI-answer monitoring. You will know what to buy because the missing capability will be explicit, and you will know whether it worked because the evidence trail already exists.

    References


  • Is Your Website Ready for AI Agents? A Practical Audit

    Is Your Website Ready for AI Agents? A Practical Audit

    You can have a fast, attractive website that still leaves an AI system guessing. A person may work around a price that appears late, two conflicting policy pages, an unlabeled button, or a confirmation shown only through a visual change. A machine may stop, cite the wrong fact, or repeat an action because it cannot tell whether the first attempt worked.

    The goal is not to rebuild your site for bots at the expense of people. It is to make public information retrievable, meaning explicit, and actions safely bounded. That is the practical response to the shift toward machine-led website visits. This audit shows you where to look and what a passing result should look like.

    Audit the journey, not the bot name

    Agent readiness is broader than allowing a particular crawler through robots.txt. An AI search system may retrieve a page to answer a question, compare facts across pages, send a person to a landing page, or help a signed-in user complete a task. Each journey fails differently.

    Start with the intent that matters, then follow it from request to outcome. Choose priority journeys from three groups: finding an answer, making a decision, and taking an action. Write the expected result before you test so that a plausible but incorrect response does not pass by accident.

    JourneyWhat the machine needsWhat failure looks like
    Answer or citeA public, stable page with a direct answer and enough context to interpret itThe answer is absent from the retrieved HTML, buried in an image, or contradicted elsewhere
    Compare and decideConsistent names, identifiers, attributes, prices, conditions, and limitationsThe same offer has different facts across the page, structured data, and linked policies
    Act and confirmClearly labeled controls, explicit prerequisites, bounded permissions, and a machine-readable resultThe agent cannot identify the correct control, understand an error, or confirm whether the action succeeded

    For each journey, name the authoritative page, the facts that must be preserved, the actions that are permitted, and the state that proves completion. This turns an abstract AI-readiness project into a set of testable requirements.

    Make important pages retrievable without guesswork

    A page is not agent-ready merely because it looks correct in your browser. Your browser may have cookies, cached scripts, a logged-in session, and enough processing time to assemble the page after the initial response. A fresh machine client may have none of those advantages.

    Test every priority URL from a clean, logged-out session. Inspect the returned HTML as well as the rendered screen. The page title, primary heading, main answer, relevant entity name, and essential links should be available without requiring a person to reveal them through hover effects, tabs, or visual-only controls. When a fact is central to the page, do not assume every client will execute and wait for the same JavaScript path as a full browser.

    • Confirm that the preferred URL returns a successful response and does not enter a redirect loop, soft-error state, consent loop, or challenge page.
    • Review robots.txt, meta robots directives, and the X-Robots-Tag together. An accidental conflict can make an otherwise public page unavailable. Robots directives are discovery instructions, not security controls, so private information still belongs behind real authentication.
    • Use one canonical URL for each primary resource. Internal links, canonical tags, redirects, and the XML sitemap should agree on that URL.
    • Keep the sitemap focused on live, canonical pages that you actually want discovered. Remove obsolete, redirected, private, and erroring URLs rather than asking machines to sort through them.
    • Link important pages through ordinary crawlable navigation. Descriptive link text such as “Enterprise pricing” carries more meaning than repeated links labeled “Learn more.”
    • Provide an HTML version of essential facts that otherwise live only in an image, video, downloadable document, or interactive widget.
    • Test firewall, bot-management, content-delivery, and rate-limit rules with a fresh client. Record whether a failure comes from the application or from an infrastructure layer in front of it.
    • Never weaken authentication to make an agent test pass. Keep protected data protected and expose only the public information or authorized interface the task genuinely requires.

    A useful retrieval record includes the requested URL, response status, final URL after redirects, declared canonical, applicable robots directives, and whether the required facts appeared in the response. A screenshot can confirm appearance, but it cannot replace those checks.

    Make the page’s meaning explicit in content and JSON-LD

    An abstract machine agent connects directly to a central web page shown in visible-content, semantic, and linked-data layers within an orderly site structure.

    Once a machine can retrieve a page, it still has to identify what the page describes and which claims belong together. Ambiguity usually enters through inconsistent naming, missing qualifiers, stale duplicates, and structured data that says something different from the visible page.

    Give each priority page a clear job. Put the direct answer near the point where the page establishes the question or offer, then supply the evidence, conditions, and alternatives a reader needs. Do not force the machine to combine fragments from a feature grid, tooltip, footer, and separate policy page just to understand the basic proposition.

    • Name the entity in full before relying on abbreviations or pronouns. If two products, locations, plans, or organizations have similar names, state the distinction on the page.
    • Attach qualifiers to the claim they modify. Geography, currency, billing period, eligibility, availability, effective date, tax treatment, shipping limits, and plan restrictions should not be left to implication.
    • Use stable identifiers where your operation already has them, such as a product code, plan name, location identifier, or internal service name. Keep the same identifier across templates, feeds, and structured data.
    • Choose an authoritative home for reusable facts such as the legal organization name, support contact, returns policy, or service-area definition. Other pages should link to or consistently reproduce that truth.
    • Update, redirect, remove, or clearly label stale pages. Two accessible pages that make incompatible claims create an interpretation problem even when only one appears in navigation.
    • Show ownership and maintenance information where it helps a reader judge the claim, such as an author, responsible team, publication date, or last reviewed date. Do not add decorative dates that are unrelated to a substantive review.

    Use JSON-LD to restate and connect meaning that is already visible. Select the most specific appropriate schema type for the resource, such as Organization, Product, Service, Article, or BreadcrumbList. Treat the type as a description of the actual page, not as a keyword target.

    • Make names, URLs, prices, availability, dates, and identifiers agree with the visible content.
    • Give important entities stable @id values and reuse those identifiers when another object refers to the same entity.
    • Connect related objects deliberately. An article’s publisher, a product’s brand, and a service’s provider should resolve to the organization you actually mean.
    • Include only properties you can support and maintain. An empty or guessed field adds ambiguity rather than clarity.
    • Validate syntax after template changes, then inspect the generated object for meaning. Syntactically valid markup can still describe the wrong entity or carry stale values.
    • Do not use structured data to make claims that a person cannot verify on the page. Markup cannot repair inaccessible, contradictory, or inaccurate content, and it does not guarantee inclusion in an AI answer.

    The final check is simple: read the visible page and the JSON-LD side by side. If they would lead a careful reader to different conclusions, the page is not ready.

    Treat agent actions as controlled transactions

    A transaction object passes through guarded verification, review, execution, and confirmation chambers while a duplicate action token is diverted into a holding loop.

    Retrieving a shipping policy is a read. Changing an address, booking an appointment, placing an order, publishing content, or deleting data is a write. Your design should preserve that boundary even when the same assistant handles both parts of the journey.

    Public facts should not require authentication without a business reason. Actions that expose personal data or change state should require an authenticated, authorized user. Do not create a machine-only shortcut around the permission model used by your human interface.

    • Use real links, buttons, and form controls with persistent programmatic names. An icon, color change, or visual position alone is not a dependable instruction.
    • Give every field a label and every validation failure an actionable message. State what is missing or invalid and preserve valid input so the task can continue.
    • Show prerequisites and consequences before submission. Required documents, inventory constraints, cancellation terms, units, time zones, and final charges belong before the committing action.
    • Require review or explicit user confirmation before consequential actions involving payment, publication, deletion, cancellation, or a binding reservation. Automation is not a reason to remove a safety boundary.
    • Make retries safe. If a client repeats a request after a timeout, the system should not silently create duplicate orders, bookings, messages, or records.
    • Return an unambiguous result after submission. The response should state whether the action succeeded, failed, remains pending, or requires another step, along with the relevant record or transaction identifier.
    • Keep errors distinct from success states. A generic page refresh, disappearing modal, or disabled button does not prove what happened.
    • Apply the least privilege needed for the requested task. Scope credentials, sessions, and connected tools so that a narrow action does not grant unrelated access.
    • Log enough context to investigate a failure or duplicate action, while avoiding unnecessary capture of personal data, credentials, or sensitive form contents.

    Test consequential paths in a staging environment or with a non-destructive mode whenever possible. If a production check could charge money, delete data, publish material, or create a real reservation, use an authorized test path rather than discovering the guardrails through a live transaction.

    Measure readiness from fetch to business outcome

    Referral traffic is useful, but it is not a complete AI-search scorecard. A system may use your information without sending a click, while a detected visit may still land on an inaccurate or unusable page. Keep the stages separate so you know which problem you are fixing.

    • Availability: Can a clean client retrieve the preferred page, and are canonical and robots signals aligned?
    • Comprehension: Can the required answer and its qualifiers be extracted from the visible content? Do the structured data and page agree?
    • Representation: Does a fixed set of relevant prompts produce an accurate description, mention, or citation on the AI surfaces you monitor? Record the prompt, surface, location or account context, date, output, and cited URL so later checks are comparable.
    • Referral: Which detectable AI referrals reach the site, where do they land, and do they engage with the intended next step? Treat missing referral data as unknown, not as proof that your content was never used.
    • Outcome: Do those visits or assisted journeys produce the qualified lead, completed task, sale, subscription, support resolution, or other result the page exists to support?

    Create a worksheet with a row for each priority intent. Include the authoritative URL, approved answer, required fields, expected entity, permitted action, passing condition, owner, last test date, observed output, and remediation status. A useful AEO system of record should show where performance is strong and why, not merely accumulate screenshots and isolated visibility scores.

    Establish a baseline before changing templates or access rules. Rerun affected journeys after changes to navigation, rendering, structured data, robots directives, authentication, forms, firewall policy, or core content. Keep the prompt and acceptance criteria fixed when you want a meaningful comparison; create a new test when the underlying intent changes.

    Key takeaways

    • AI-agent readiness has four practical layers: retrieval, interpretation, safe action, and measurement.
    • A passing visual check is not enough. Inspect the response, redirects, canonical, robots directives, rendered content, and required facts.
    • Visible content and JSON-LD must describe the same entity with the same claims, identifiers, and qualifiers.
    • Read access and write access need different controls. Consequential actions require authorization, confirmation, retry protection, and an explicit final state.
    • Measure fixed intents across availability, comprehension, representation, referral, and outcome instead of treating traffic as the whole result.
    • Technical readiness improves eligibility and reduces ambiguity, but it cannot guarantee ranking, citation, recommendation, or agent selection.

    Start with a revenue page, a policy page, and a consequential conversion path. Fetch them logged out, compare their visible facts with their JSON-LD, complete the permitted action in a safe environment, and record every point where the result becomes ambiguous. Fix those failures before expanding the audit across the rest of the site.

    References


  • How to Make LinkedIn Recruitment Campaigns More Efficient

    How to Make LinkedIn Recruitment Campaigns More Efficient

    Your LinkedIn recruitment campaign can generate plenty of clicks and applications while still failing at the one outcome that matters: producing qualified hires at a sustainable cost. When interview volume stays flat as campaign activity rises, you are probably paying for attention rather than candidate fit.

    The remedy is not simply a narrower audience or a lower bid. You need a campaign system that identifies intent, filters candidates before expensive actions, separates different stages of demand, and connects media spend to interviews and hires.

    Define efficiency before you buy another click

    Recruitment efficiency is not a high click-through rate, a cheap click, or even a low cost per application. Those metrics describe parts of the journey. They do not tell you whether the campaign is helping the company hire suitable people.

    Start with a complete conversion chain. Every active campaign should be traceable through these stages:

    1. Ad click or lead interaction.
    2. Pre-qualification page visit.
    3. Application start.
    4. Completed application.
    5. Qualified application.
    6. Interview.
    7. Hire.

    Define a qualified application with the hiring team before launch. It might require a particular certification, a minimum level of relevant experience, permission to work in the required location, or another genuine condition of the role. If recruiters apply different definitions after applications arrive, campaign comparisons will be unreliable.

    Calculate cost per hire using one consistent scope: the spend assigned to a campaign divided by the hires attributed to it. If you include creative, agency, or platform costs, include them consistently across every campaign you compare. Apply the same attribution rule as well. A neat dashboard cannot rescue inconsistent definitions.

    Your working report should show spend, clicks, completed applications, qualified applications, interviews, and hires for each campaign. Add conversion rates and costs between stages. That makes the source of waste visible:

    • High click-through rate but few applications: the ad may be creating curiosity that the role cannot satisfy, or the application handoff may be too demanding.
    • Many applications but few interviews: your audience, creative, or landing page is not doing enough pre-qualification.
    • Qualified applicants and interviews but few hires: inspect the offer, recruiter follow-up, interview process, and hiring decision before changing the ads.
    • Hires from one segment but weak volume: increase that segment carefully instead of loosening the requirements across the whole account.

    The first two patterns are especially important because click and application volume can conceal poor alignment. Optimizing to the earliest available event encourages the campaign to find more of that event, not necessarily more people the hiring team wants to meet.

    For early testing, manual cost-per-click bidding can give you tighter control over how quickly the budget is exposed. Consider automated bidding after conversion tracking is working and the campaign has produced a stable enough mix of qualified applicants to judge. The purpose is not to defend manual bidding forever. It is to avoid paying an automated system to amplify an unproven audience or message.

    Build audiences from fit and intent, then keep them separate

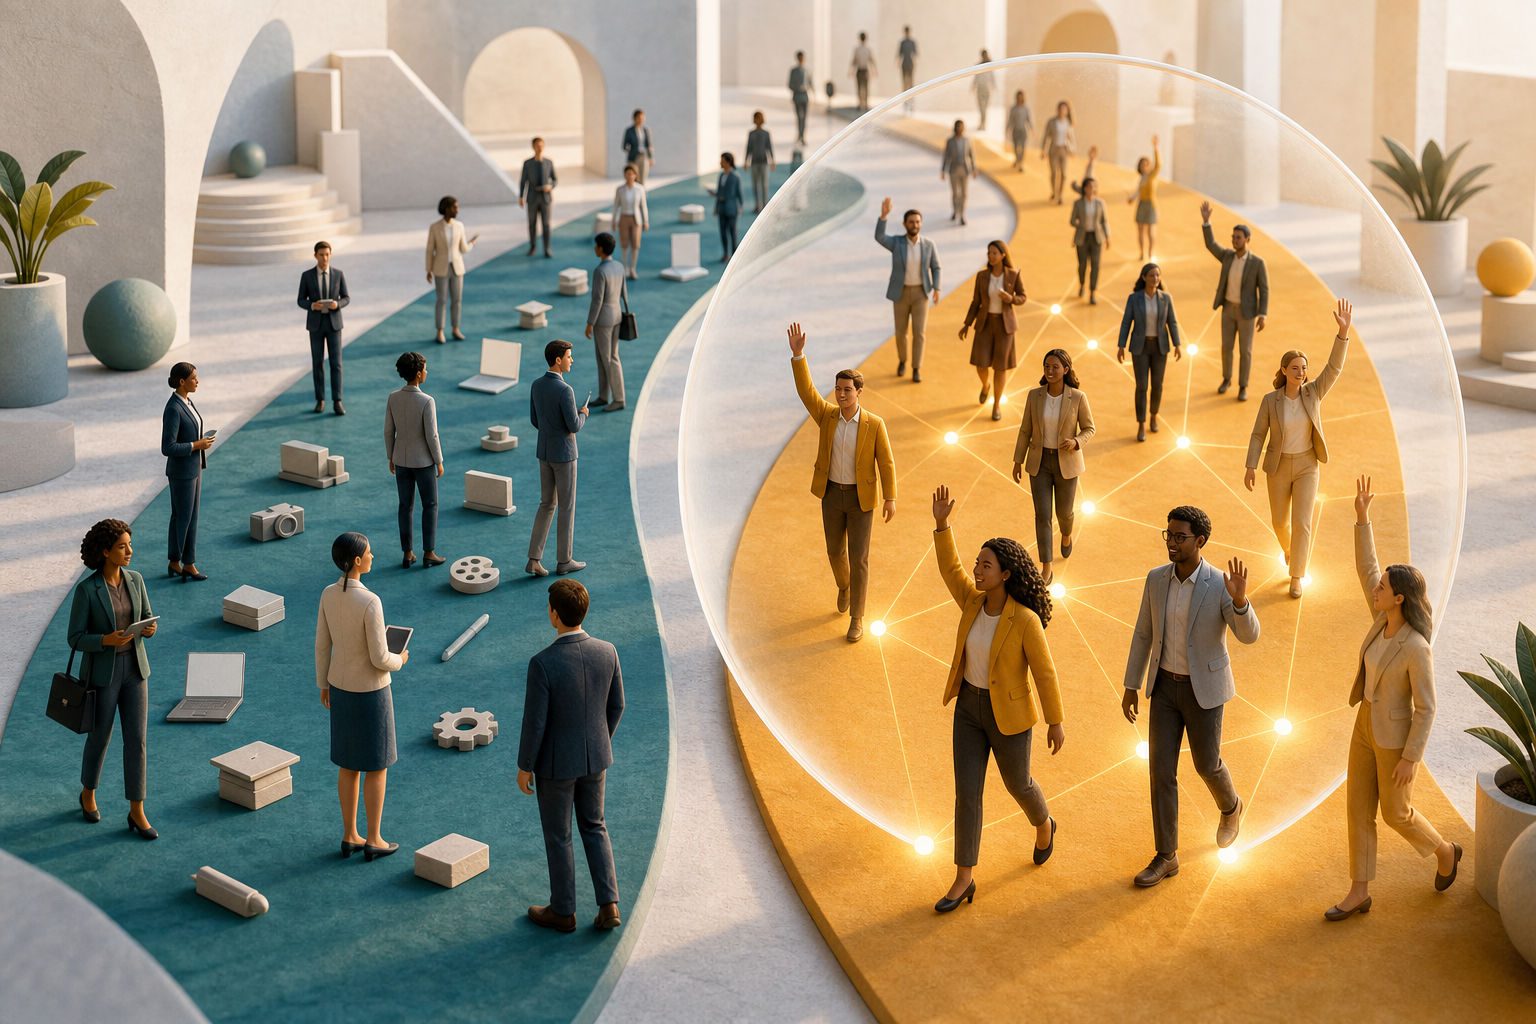
    Diverse professionals move along separate teal and amber pathways while a translucent lens highlights people where fit and intent overlap.

    Job title, industry, and seniority tell you who a person is professionally. They do not tell you why that person might consider changing jobs. A more useful audience plan combines three layers:

    • Core fit: relevant titles, skills, certifications, and experience.
    • Behavioral intent: open-to-work status, recent job-seeking activity, relevant group membership, or engagement with industry content, where those signals are available in your campaign setup.
    • Career-friction hypotheses: roles associated with burnout, employers affected by layoffs, or environments where advancement may be limited.

    Use career friction to form a messaging hypothesis, not to pretend you know how an individual feels. An employee at a competitor is not automatically dissatisfied. A person in a demanding profession is not automatically burned out. Your ad can describe a credible alternative without making a personal claim about the viewer.

    Give each intent level its own campaign job

    Active candidates and cold passive candidates should not share the same budget, message, and success expectation. Separate them so that a high-intent audience cannot hide waste in a broad awareness campaign.

    Intent segmentUseful audience signalsMessageCampaign job
    High intentOpen-to-work users, recent job seekers, and retargeting audiencesRole specifics and a direct application invitationGenerate qualified applications now
    Warm passiveRelevant skills, competitor employers, and niche professional groupsA concrete career, schedule, compensation, or lifestyle improvementTurn openness into consideration
    Cold passiveBroader qualified audiences and lookalike audiencesEmployer reputation, culture, mission, and realistic day-in-the-life contentBuild a future talent pool

    This high-, warm-, and cold-intent structure also changes how you interpret performance. A cold employer-brand campaign should not be expected to match the immediate application rate of retargeting. Its job is to create an audience that a later campaign can convert more economically.

    Control overlap when you build these segments. Start with the most specific high-intent pool, then exclude it from warm campaigns where your setup allows. Exclude both from the cold campaign. Without those exclusions, the same promising candidate can appear in several campaigns, making cost and conversion comparisons harder to trust.

    Skill-based segmentation is often more actionable than one large professional audience. If a role accepts candidates from several disciplines, place each major skill group in a separate campaign and adapt the value proposition. You will see which background produces qualified applicants, rather than averaging unlike candidates into one result.

    Make the ad qualify candidates before they click

    A recruitment ad has two jobs: attract the right person and discourage the wrong person from spending your budget. If the ad hides hard requirements to maximize clicks, the application process has to reject those people later, after you have paid for their attention and consumed recruiter time.

    A practical recruitment ad contains four elements:

    1. A recognizable identity or friction: name the professional situation the role improves.
    2. A hard fit statement: specify the required role, skill, certification, or experience.
    3. A verified reason to move: state the real compensation, flexibility, schedule, growth path, mission, or working conditions.
    4. A clear boundary: say when the position is not entry-level or requires a specific background.

    Use this fill-in structure when drafting creative:

    [Professional identity]: If [specific, credible friction] is making you consider a change, [company] is hiring for [role]. You will need [must-have requirements]. The position offers [approved and verifiable benefits]. This role is not suitable for [clear exclusion]. [Direct next step].

    The exclusion is not an apologetic footnote. It is part of the offer. Phrases such as “requires enterprise account management experience” or “not an entry-level position” can reduce irrelevant responses and protect recruiter capacity. The same principle applies to licensed or specialist roles: put the non-negotiable credential in the ad, not halfway through the application.

    Only promote benefits the employer has confirmed. “Flexible schedule” is not useful filtering language if flexibility depends on the manager. A compensation claim should match the actual structure and conditions. An exaggerated promise may raise clicks, but the mismatch will surface in application abandonment, interviews, or offer rejection.

    Test the message against qualified outcomes

    Run creative tests that change one decision-relevant element at a time. You can compare an identity-led opening with a friction-led opening, test schedule against career growth as the primary value proposition, or move the hard qualification earlier in the copy. Keep the audience, role, and destination consistent while you test.

    Do not declare a winner because one variation earns more clicks. Compare completed applications, qualified-application rate, interview rate, and eventual hires. The more selective ad may have a lower click-through rate and still be the more efficient recruitment asset.

    For specialized or senior positions, a narrowly targeted Message Ad can carry more context than a short feed ad. Keep the outreach specific and easy to decline:

    Hi [First Name], your background in [relevant skill or field] stood out. We are hiring a [role] for people with [must-have experience]. The position offers [two verified benefits], and it is intended for [seniority or specialist profile], not entry-level candidates. Would you be open to a brief conversation? If not, thank you for considering it.

    Broad message campaigns can become expensive quickly. Reserve this format for audiences whose eligibility and likely value proposition are already well defined.

    Use a two-stage application path and retarget real interest

    A job seeker begins on a smartphone, passes through a qualification gateway, and reaches an interview table while glowing connections loop back to other interested candidates.

    Sending every click directly to a long applicant-tracking form forces candidates to do too much before they understand the role. It also prevents you from distinguishing between a poor offer and a difficult application experience.

    Use a two-stage path instead:

    1. Pre-qualification page: explain the work, expectations, location or schedule, compensation details, must-have criteria, and who should not apply.
    2. Short application: ask only for the information needed to evaluate the next step, or use LinkedIn Easy Apply when it suits the hiring workflow.

    The first stage should increase clarity, not create an obstacle course. A reported 30-50% reduction in cost per hire has been associated with this two-step structure, but treat that range as a directional campaign claim rather than a forecast. Your result will depend on the role, offer, audience, tracking, and existing application process.

    Instrument both stages separately. Track the proportion of ad visitors who reach the page, start the application, complete it, qualify, interview, and get hired. If many suitable-looking visitors leave before starting, inspect the offer and page. If many begin but do not finish, inspect the form. If completions are high but interview selection is low, strengthen the qualification language.

    Retarget people according to what they already did

    Not every qualified person applies during the first visit. Build retargeting audiences from career-page visitors, ad viewers, and people who watched at least 50% of a recruitment video. Their next message should move the decision forward rather than repeat the original ad.

    • Career-page visitor: restate the role’s main benefit and the most important qualification.
    • Substantial video viewer: show an employee outcome, realistic role detail, or day-in-the-life proof that answers a likely concern.
    • Application visitor who did not complete: return to the role and a shorter next step, if your tracking and campaign rules support that audience.
    • Interested candidate near a genuine deadline: communicate the real closing date. Do not manufacture urgency.

    Exclude people who have already applied unless the follow-up has a deliberate recruiting purpose. Otherwise, you keep paying to ask for an action they have completed and distort the apparent efficiency of the retargeting campaign.

    Once the core funnel is working, expand carefully. Competitor-employee targeting can emphasize a verified advantage without attacking another employer. Skill-specific campaigns can reveal which backgrounds convert. Targeted messages can reach a small pool of senior specialists. Each tactic should remain separate enough that you can identify its qualified applications, interviews, and hires.

    Key takeaways for your next recruitment campaign

    • Measure cost per qualified application, interview, and hire alongside clicks and completed applications.
    • Define qualification with recruiters before launch so campaign comparisons use the same standard.
    • Combine core professional fit with available intent signals instead of targeting job titles alone.
    • Separate high-intent, warm passive, and cold passive candidates because they need different messages and success criteria.
    • Put must-have requirements and meaningful exclusions in the ad to prevent avoidable clicks.
    • Use a clear pre-qualification page followed by a short application, then track the handoff between them.
    • Retarget demonstrated interest with a next-step message and exclude candidates who have already applied.
    • Move budget according to qualified applications, interviews, and hires, not the campaign with the busiest top-line metrics.

    Before increasing your next LinkedIn budget, rebuild one role from end to end. Separate active and passive audiences, add one hard qualifier to the creative, route candidates through a concise role page, and add qualified applications, interviews, and hires to the campaign report. That smaller redesign will show you where the waste actually begins.

    References


  • How AI Search Engines Prefer Reddit, YouTube, and LinkedIn

    How AI Search Engines Prefer Reddit, YouTube, and LinkedIn

    AI citations

    During a recent study, I discovered that Reddit stands out as the most-cited domain in AI-generated answers. In fact, it’s ahead of heavyweights like YouTube and LinkedIn, thanks to an analysis of 30 million sources conducted by Peec AI, a tool specializing in AI search analytics.

    The findings: I’ve learned that Reddit claims the top spot across various AI platforms including ChatGPT, Google AI Mode, Gemini, Perplexity, and AI Overviews. Top contenders YouTube, LinkedIn, Wikipedia, and Forbes are right behind. Platforms like Yelp and G2 frequently appear when searching for recommendations.

    As I delved deeper into the research, it became clear which domains the AI models tend to lean on:

    • ChatGPT values Wikipedia, Reddit, and editorial sites like Forbes.
    • Google shows preference for platforms such as Facebook and Yelp.
    • Perplexity favors Reddit, LinkedIn, and G2 for queries within the B2B realm.

    Why we care: The insight that resonated with me was the importance of having authority beyond just our own websites. Brands that consistently feature on reputable third-party platforms have a better chance of being cited by AI.

    Why these sources? It’s fascinating to see how AI systems are wired to prioritize both authority and authentic user input:

    • I’ve found that Reddit excels because it mirrors genuine user discussions.
    • YouTube shines in video citations, owing to their comprehensive transcripts and descriptions.
    • Wikipedia not only serves real-time data but also acts as a foundation for training datasets.

    About the data: The analysis spanned 30 million sources, providing a comprehensive look at how often domains are directly cited in AI answers, effectively revealing what shapes these responses.

    The study. For those interested in a deep dive, the full study is available here: Top domains cited by AI search: Analysis based on 30M sources

    Dig deeper. For more on citation research, check out these fascinating reads:


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How to Build an AI-Powered Creator Commerce Campaign

    How to Build an AI-Powered Creator Commerce Campaign

    You have creator candidates, a product catalog, and a paid-media budget. The hard part is connecting them: the creator must make the product relevant, the shopping surface must preserve the promise, and your measurement must show where the campaign actually worked or failed.

    The practical model is a single creator-commerce loop, not separate influencer, advertising, and ecommerce projects. You choose the buying action first, match creators to that job, plan the paid uses of their content, configure the offer shoppers will encounter, and measure every handoff.

    Treat creator marketing and AI shopping as one buyer journey

    A creator can introduce the problem, demonstrate the product, answer an objection, or give a buyer a reason to act. Commerce systems have a different job: they present the product, price, availability, and eligible benefits when that interest becomes purchase intent.

    AI is bringing those jobs closer together. YouTube can use Gemini to help advertisers find relevant creators and then distribute creator-made content through paid formats. Google has also extended member pricing and shipping benefits into AI Mode and Gemini, as well as local inventory and regional Shopping ads.

    For you, the important change is the handoff. A shopper can encounter a creator’s recommendation, see the same message in a paid placement, and later find a personalized benefit during product discovery. If those touchpoints contradict one another, AI-powered distribution merely spreads the inconsistency faster.

    Start each campaign by writing the promise that must survive the journey. If the creator discusses exclusive shipping for loyalty members, verify that the eligible shopper can actually see and receive that benefit. If the listing emphasizes member pricing, the creator’s call to action should explain why membership matters instead of sending everyone to a generic product page with no visible connection.

    This also changes how you divide responsibility internally. The creator team should know which offer the commerce team has configured. The commerce team should know which claims and calls to action appear in the creator asset. Paid media should not receive the content only after it has been produced; its required placements and audiences should shape the brief from the beginning.

    Build the campaign backward from a commerce event

    A product purchase in the foreground connects backward through an offer, creator content, paid distribution, and content production.

    Do not begin with a broad request to find popular creators. Begin with the behavior you need from a specific kind of buyer. That decision determines the offer, brief, creator criteria, destination, and measurement plan.

    1. Name the commercial event. Decide whether the campaign is meant to generate product discovery, a qualified product-page visit, a first purchase, a loyalty enrollment, or another defined action. Use one primary event to make campaign decisions. Secondary metrics can explain performance, but they should not quietly replace the original goal.
    2. Define who can receive the offer. Separate prospects from recognized members and distinguish a public promotion from a loyalty benefit. If eligibility depends on a membership tier, country, region, or local inventory, record that before the creator writes the call to action.
    3. Choose the proof the buyer needs. A creator brief should identify the buyer’s problem, the product’s role, the objection that must be answered, and the evidence the creator can show. A product demonstration, use case, or clear explanation usually gives you more to evaluate than a generic endorsement.
    4. Shortlist creators for that job. YouTube’s Gemini-powered matching can suggest candidates from more than three million YouTube Partner Program creators. Use that scale to widen discovery, then apply human review to audience relevance, creative quality, product credibility, and suitability for paid distribution.
    5. Plan distribution before production. Decide whether the partnership will remain on the creator’s channel or also become a paid Short, an in-stream ad, or both. Confirm that the partnership permits every planned placement, market, and period of use before allocating media spend.
    6. Instrument the handoff. Give each creator and placement an identifiable destination or campaign parameter. Align the platform conversion event with the commercial event you selected. Where appropriate, add a creator-specific code, but do not treat code use as the only evidence of influence; shoppers may return through another route.

    Keep the first test interpretable. If you change the creator, audience, offer, landing experience, bid strategy, and product selection at the same time, a good result will not tell you what to repeat and a bad result will not tell you what to repair.

    Use AI matching as a shortlist, not a strategy

    Creator matching solves a discovery problem. It can help you navigate a large pool, but it cannot decide what your buyer needs to hear, whether the creator’s authority transfers to your product, or whether the resulting content will work outside the creator’s existing audience.

    Use a scorecard that forces every recommendation to produce observable evidence. The model’s recommendation can open the review; it should not end it.

    DecisionEvidence to inspectReason to pause
    Audience relevanceRecurring subjects, viewer questions, purchase problems, and use cases connected to the productThe connection depends mostly on a broad demographic label or follower count
    Product credibilityA natural reason for the creator to discuss, use, compare, or demonstrate the productThe endorsement would require a sudden change in the creator’s established subject matter
    Creative strengthA clear opening, understandable product role, concrete proof, and a call to action that fits the contentThe product appears only as an interruption with no useful explanation
    Paid-media portabilityA message that a cold viewer can understand without knowing the creator’s backstoryThe asset depends entirely on channel-specific context or an inside joke
    Offer alignmentA benefit the intended audience can receive in the markets and membership tiers being targetedThe creator would be promoting an offer that many reached viewers cannot access
    Measurement readinessA distinct asset, placement identifier, destination, and agreed conversion eventPerformance can only be read as a blended campaign total

    Follower count belongs in the context, not at the center of the decision. A smaller relevant audience can reveal stronger buying intent than a large audience gathered around unrelated content. Conversely, topical relevance alone is not enough if the creator cannot communicate the product clearly or if the asset cannot survive paid distribution.

    Review the likely failure mode before approving a match. If the creator understands the audience but not the product, improve the briefing or reject the match. If the content is persuasive to existing followers but confusing to cold viewers, separate the organic asset from the paid edit. If the offer is compelling but limited to recognized members, prevent the campaign from implying that every viewer will receive it.

    Turn creator content into a connected distribution system

    A creator filming a product is connected by glowing paths to multiple content, shopping, advertising, order, and measurement touchpoints.

    A creator partnership should produce more than an isolated upload. YouTube allows creator-made content to run as paid Shorts and in-stream ads, giving you a route from creator credibility to controlled media distribution.

    That does not mean one edit should be copied everywhere. Give each placement a defined job while preserving the same product truth and offer:

    • The creator-channel asset establishes context, credibility, and the full product story for an audience that already knows the creator.
    • The paid Short introduces the buyer problem and product quickly enough to make sense to a cold viewer.
    • The in-stream ad has room to develop the use case, proof, or objection that cannot fit into the shortest edit.
    • The product or local inventory listing confirms the purchasable product and displays the applicable price or benefit.
    • The loyalty layer shows recognized members the pricing or shipping advantage for which they are eligible.

    Create a message ledger before editing begins. Record the approved product promise, supporting proof, exact offer wording, call to action, destination, market eligibility, membership requirements, and the placements where the asset will run. Every version can vary in pacing and length, but it should remain consistent with that ledger.

    The commerce setup deserves the same attention as the creative. Merchants using Google’s loyalty features can activate the loyalty add-on in Merchant Center, configure member tiers, supply pricing and shipping attributes, and connect Customer Match lists so recognized members can see eligible benefits. A creator campaign should not promote those benefits until the feed, tier rules, audience connection, and destination have been checked together.

    Market eligibility is part of the brief, not a footnote. The stated expansion covers Australia, Brazil, Canada, France, Germany, India, Italy, Japan, Mexico, the Netherlands, South Korea, Spain, the United Kingdom, and the United States. If your creator reaches viewers outside the relevant campaign market, use wording that does not imply universal access.

    Local inventory and regional Shopping ads can be especially useful when the benefit or product availability varies by location. Match the creator’s geographic targeting, the inventory being promoted, the Merchant Center configuration, and the landing experience. Otherwise, you pay to generate interest that the next surface cannot satisfy.

    There is also a U.S. pilot that uses Customer Match as a relationship data source for free listings. Treat pilot access as an optional opportunity, not as inventory you can assume in a forecast. Build the core campaign around placements and features actually available to your account.

    Measure the chain instead of celebrating one platform number

    Creator commerce can look successful at the top of the funnel while leaking value at the final handoff. A popular video does not prove product demand, and a strong click-through rate does not prove profitable sales. Your reporting should show how attention moved through the campaign.

    • Matching: Track which creator-selection criteria were expected to matter and whether the content attracted relevant viewer questions or actions.
    • Creative: Read view rate, completion, engagement, and product clicks by asset. These metrics help locate attention loss; they are not substitutes for the commercial event.
    • Media: Separate organic creator delivery from paid Shorts and in-stream distribution. Report cost, reach, click-through rate, conversion rate, and acquisition cost by placement.
    • Commerce: Measure product-page behavior, purchases, order value, and offer redemption using consistent definitions.
    • Relationship: Where loyalty is part of the objective, distinguish existing recognized members from new enrollments and non-member buyers.

    Document every denominator. A conversion rate based on clicks is not interchangeable with one based on sessions, and a customer acquisition cost should not silently include returning customers if the campaign goal is new-customer growth. Definition drift can make two dashboards appear to agree when they are measuring different events.

    Platform lift figures are useful for forming a hypothesis, not for writing your revenue forecast. YouTube reports an average 30% conversion lift from boosting creator content through Shorts and in-stream ads. Google reports that some retailers saw up to a 20% increase in click-through rate when tailored loyalty offers were shown to members.

    Those numbers should not be combined or treated as guaranteed. One is an average conversion result for creator advertising formats; the other is an upper-end click-through result reported for some retailers using tailored offers. They describe different interventions, outcomes, and populations. Your baseline, margin, audience, creative, product, and offer determine whether either benchmark is relevant.

    Use controlled comparisons to learn what contributed. Hold the offer, audience, and destination steady when comparing creator-made and brand-made assets. Evaluate loyalty presentation separately instead of mixing it into the creative test. If several creator assets run together, retain asset-level and creator-level identifiers so a blended result does not hide the winner or the failure.

    Read mismatches as diagnostic signals. Strong viewing with weak product clicks points you toward the call to action or offer handoff. Strong clicks with weak conversion points you toward the destination, price, eligibility, or product experience. Strong conversion with limited reach points you toward distribution. These are places to investigate, not automatic diagnoses, but they are more useful than labeling the whole campaign good or bad.

    Key takeaways

    • Choose the buying action and eligible offer before asking AI to find creators.
    • Use AI matching to expand and organize discovery, then require human evidence for audience fit, product credibility, creative quality, and paid-media suitability.
    • Plan creator-channel content, paid Shorts, and in-stream ads as related assets with different jobs, not automatic duplicates.
    • Verify Merchant Center tiers, pricing, shipping attributes, Customer Match connections, markets, and destinations before a creator promises a loyalty benefit.
    • Measure the full path from creator attention to commerce and customer relationship outcomes. Treat vendor-reported lift as a hypothesis, not your forecast.

    Your next move is to choose a product, a buyer action, and an offer that the intended audience can actually receive. Write the creator brief, placement plan, commerce configuration, and measurement event on the same page. If that chain remains clear from first view to purchase, you have a campaign worth testing.

    References


  • Google Gemini: AI Answers Tailored by Emotion

    Google Gemini: AI Answers Tailored by Emotion

    According to a recent, though unverified, report, Google Gemini’s AI is designed to tailor its responses based on the user’s tone, intent, and emotional context. This fascinating development suggests that the AI aligns its answers with the emotional backdrop of each query.

    Why This Matters. If this information holds true, it means that the responses generated by AI might vary significantly, depending on how we phrase our queries, rather than just on the data available. This could change the way we engage with search engines.

    New Findings. At the heart of this revelation is a system called upcast_info. As reported by Elie Berreby, head of SEO and AI search at Adorama, this system seems to provide the blueprint for how Gemini processes user queries, aiming to:

    • Reflect the user’s tone, energy, and purpose.
    • Acknowledge emotions before formulating a response.
    • Deliver answers from the user’s perspective.

    Implications. Instead of maintaining a neutral stance, the AI’s responses could:

    • Emphasize negative perspectives (“Why is X bad?”).
    • Highlight positive aspects (“Why is X great?”).

    Should the public sentiment toward a topic be negative, the AI might intensify that sentiment. As the report indicates:

    • AI mirrors prevalent emotional signals.
    • It doesn’t offer the balancing act usually provided by traditional search result links.

    The Role of Query Framing. The emotional tone of a query can impact:

    • The choice of sources cited.
    • The style of summaries presented.
    • The overall tone and substance of the answers.

    Google’s AI Overviews already demonstrate shifts in tone that align with the intent of queries, providing potential insight into the mechanics behind these changes.

    Unsubstantiated Information. Google has yet to confirm this leak. As Berreby mentions: “I’ve decided to share just a portion of the leaked internal system data publicly. It’s not a security exploit or major breach, just a minor leak.”

    The Original Report. For further reading, visit This Gemini Leak Means You Can’t Outrank a Feeling.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • 59% of SEO Roles Now Senior-Level: The AI-Powered Shift

    59% of SEO Roles Now Senior-Level: The AI-Powered Shift

    I’ve noticed a significant shift in the SEO industry toward senior, strategy-focused roles. As AI increasingly handles execution tasks, the demand for seasoned strategists has grown, along with an increase in salaries and responsibilities that span multiple channels.

    The change in hiring trends is evident when looking at a recent Semrush analysis of 3,900 job listings. It appears companies are now prioritizing leadership skills, innovative experimentation, and cross-channel visibility over purely technical execution.

    Why it matters to me. The landscape for SEO careers and skillsets is evolving. Entry-level positions are mostly focused on execution, while leadership roles require a firm grasp of strategy across various domains such as search, AI assistants, and paid channels, ensuring they drive significant revenue.

    What’s changing now. Senior roles account for 59% of job listings, clearly dominating the landscape. In contrast, mid-level positions like specialists and managers are less prevalent, with only 15% and 10%, respectively.

    Companies are redirecting their budgets towards strategic roles as AI tools begin to absorb more of the technical workload.

    The shift in skills. The skills in demand now extend beyond traditional SEO to include coordination, experimentation, and decision-making capabilities:

    Project management is mentioned in over 30% of the listings, highlighting its importance.

    Communication is highlighted in 39.4% of non-senior roles, indicating its fundamental role in the industry.

    Experimentation is noted in 23.9% of senior roles, compared to just 14% of other roles.

    Technical SEO appears in approximately 6% of postings, showing its niche but crucial role.

    Tools and channels. The modern SEO toolkit now includes analytics, paid media, and comprehensive data tools.

    Google Analytics is cited in up to 47.7% of job listings, underlining its importance.

    Google Ads features in 29% of the listings, showcasing its growing relevance.

    Demand for SQL skills is rising, especially at the senior level.

    AI tools, such as ChatGPT, are increasingly mentioned, reflecting their future role in SEO.

    AI expectations. AI literacy is shifting from being a nice-to-have to an essential skill:

    31% of senior roles now reference AI capabilities.

    Nearly 10% of listings highlight familiarity with LLMs.

    Concepts such as AI search and AEO are increasingly common in job descriptions.

    Pay and positioning. SEO is being increasingly recognized as a vital business function:

    The median salary for senior roles has reached $130,000, markedly higher than the $71,630 for other roles, with some positions offering even more.

    Preferred degrees are leaning towards business and marketing, reflecting the strategic emphasis.

    Remote work prevalence. Remote options are available in over 40% of job listings, indicating a shift towards flexible work environments across all levels.

    About the data. This analysis by Semrush covers 3,900 SEO job listings in the U.S., gathered from Indeed as of November 25. The roles were deduplicated and segmented by seniority before a semantic keyword extraction analysis was applied.

    Discover more about the study. For a deeper dive into these findings, check out Semrush’s detailed study titled What 3,900 SEO Job Listings Reveal for 2026: Experiments, AI, and Six-Figure Salaries.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot