Author: shivamcrushpressai

  • Google Ads Updates Link Trust Rules With Creative Testing

    Google Ads Updates Link Trust Rules With Creative Testing

    Two Google advertising updates point to a broader operating model for advertisers: eligibility must be maintained through clearer requirements, while campaign improvements should be validated through controlled experiments. The changes affect different products, but together they show how governance and optimization are becoming more structured.

    For Local Services Ads, the reported emphasis is on clearer terminology and alignment with Google’s revised badge framework. For Performance Max, the emphasis is on testing creative decisions before applying them more broadly. Advertisers therefore need both reliable compliance processes and a repeatable approach to experimentation.

    Two updates address different kinds of advertising risk
    A metallic link symbol and verification shield passing through a security checkpoint toward generic local storefront icons.

    CrushPress.AI’s Local Services Ads coverage reported that Google plans to rename its “Local Services platform policies” as “Local Services Ads requirements” on July 6. The report characterized the change as a clarification and modernization of guidance rather than a major enforcement crackdown. It also connected the revised language to Google’s recent restructuring of its badge system and verification standards.

    That update concerns participation risk: whether a business understands and satisfies the conditions associated with advertising and badge eligibility. Clearer requirements may reduce ambiguity, but a new label does not eliminate the need to keep credentials, verification information and operating standards current.

    The separate Performance Max report focused on decision risk. Because creative changes can affect results, advertisers need evidence before committing budget across campaigns. The newly reported experiment capabilities are intended to provide a more controlled way to assess assets instead of treating every creative revision as an immediate full rollout.

    Performance Max testing adds more useful creative comparisons
    Two different generic ad creatives moving through matching glass test modules before reaching a network of blank device displays.

    According to CrushPress.AI’s coverage, Performance Max advertisers can test entirely new asset groups, evaluate the effect of adding individual assets, and compare seasonal material with evergreen creative. The report also said that assets produced through Google’s Asset Studio can be included, allowing generated creative and other asset approaches to be assessed within the same experimentation framework.

    The practical value is not simply the ability to declare one asset a winner. The report described an additional success metric that can help advertisers evaluate more than one objective, such as conversion volume alongside efficiency. This matters because a creative change can improve one measure while weakening another; a broader evaluation can expose that trade-off before the change is expanded.

    The coverage also reported that experiments, including conversion lift studies, are being centralized on one Experiments page. Support for manager accounts and the Google Ads API was described as beginning to roll out soon, while further experiment and measurement capabilities were said to be forthcoming. Those rollout statements should be treated as reported product direction rather than proof that every account already has access.

    Key takeaways

    • Local Services Ads guidance is reportedly being reframed as explicit requirements and aligned with Google’s revised badge and verification framework.
    • The Local Services Ads change was presented as a clarity initiative, but businesses still need dependable processes for maintaining eligibility information.
    • Performance Max experiments reportedly support tests of asset groups, individual additions, seasonal versus evergreen creative, and assets created with Asset Studio.
    • An additional success metric can help teams judge creative against multiple campaign objectives rather than a single headline result.
    • Centralized experiment management may simplify oversight, although manager-account and API support were reported as rolling out rather than universally available.

    Advertisers need separate controls for eligibility and performance

    The two updates should not be collapsed into a single workflow. Local Services Ads requirements concern whether an advertiser can participate and qualify under the relevant framework. Performance Max experiments concern whether a proposed creative change produces a desirable outcome. Passing a verification check says nothing about asset effectiveness, while a successful creative test says nothing about compliance or badge eligibility.

    A practical response is to assign each issue to the appropriate review process. Local advertisers and their agencies can track requirement changes, verification materials and badge-related dependencies as governance work. Performance teams can document the hypothesis behind each asset experiment, the primary and secondary measures used to judge it, and the scope of any subsequent rollout.

    This separation also makes accountability clearer. Eligibility reviews should answer whether the business remains qualified and whether its information is current. Experiment reviews should answer what changed, what comparison was made, which measures moved and whether the evidence supports broader deployment. Both disciplines reduce avoidable risk, but they do so in different ways.

    Questions remain about access, enforcement and interpretation

    The source material does not establish how the renamed Local Services Ads requirements will affect individual advertisers, whether enforcement practices will change, or exactly how compliance will determine badge status in every case. The reported alignment suggests that eligibility and trust signals should be reviewed together, but it does not justify assuming a new penalty or automatic badge outcome.

    Likewise, the Performance Max report does not provide universal availability dates, account-level eligibility details or a guarantee that every experiment will produce a conclusive result. Advertisers should confirm which capabilities appear in their own accounts and avoid treating an announced rollout as completed access.

    As Google develops both frameworks, the durable advantage will come from operational readiness: maintaining evidence for eligibility decisions and using experiments to support creative decisions. Teams that establish those routines can adapt to additional requirements and measurement features without rebuilding their processes around every product update.
    References

  • How Trust Turns Vehicle Shipping Interest Into Bookings

    How Trust Turns Vehicle Shipping Interest Into Bookings

    Vehicle shipping customers are often asked to commit before they can directly evaluate the service. That makes conversion less a matter of adding persuasion and more a matter of reducing uncertainty about price, responsibility, timing, vehicle handling, and communication.

    The supplied First Page Sage article frames this relationship in its headline, How Trust Drives Conversions at AutoStar Transport Express. Its available excerpt identifies an interview with Mark Dugger, described as AutoStar Transport Express’s operations manager, but it does not provide enough detail to attribute particular tactics or results to the company. The useful lesson is therefore best developed as a broader conversion framework rather than an unsupported case study.

    The conversion barrier is uncertainty, not simply price

    A prospective vehicle shipping customer reviews an online quote beside car keys, a phone, and a blank calendar.

    A shipping quote gives a prospective customer a number, but the decision also depends on what that number appears to cover. A low price can lose persuasive value if the buyer cannot tell who will handle the vehicle, whether important conditions are excluded, or what happens when plans change.

    This is the central connection between trust and conversion: trust makes an offer easier to evaluate. It does not require the customer to assume that every variable is predictable. Instead, it gives the customer a clear picture of which parts of the process are known, which may vary, who is accountable, and how changes will be communicated.

    That distinction matters in vehicle shipping because operational complexity cannot always be removed from the service. The stronger conversion strategy is to explain complexity in language a buyer can use, rather than conceal it behind an apparently simple promise.

    Trust signals should answer the buyer’s next question

    Identity and responsibility: A prospective customer should be able to understand who the business is, what role it plays in arranging or providing transport, and where responsibility sits at each stage. Company information and credentials are most useful when they clarify accountability rather than merely decorate a page.

    Quote clarity: The quote experience should explain inclusions, potential variables, payment expectations, and the conditions that could affect the final arrangement. Clarity is a trust signal because it helps buyers compare offers on substance instead of comparing headline prices that may not represent equivalent services.

    Process visibility: Customers benefit from knowing what follows a request, how pickup and delivery are coordinated, what information they will receive, and whom they can contact. A visible process converts an abstract promise into a sequence the buyer can understand.

    Evidence with context: Reviews, testimonials, and other forms of social proof are more informative when they address relevant concerns such as communication, issue handling, and whether expectations matched the delivered service. Evidence should support the operating claims on the page, not substitute for explaining them.

    Realistic language: Absolute assurances can create suspicion when a service depends on changing operational conditions. Precise language about estimates, contingencies, and communication procedures can be more credible than an unqualified guarantee.

    A trustworthy journey stays consistent from page to follow-up

    A customer books vehicle shipping, watches a sedan being secured to a carrier, and receives a phone update at delivery.

    Trust can be weakened when individual parts of the conversion journey contradict one another. An informative landing page does little good if the quote form introduces unexplained requirements, or if a follow-up message uses pressure that conflicts with the measured tone of the site.

    The message should remain consistent across search results, service pages, quote forms, confirmation messages, phone conversations, and booking documents. The same terminology should describe the service and its conditions throughout. If a detail becomes more nuanced later in the journey, the earlier page should prepare the customer for that nuance.

    Forms also communicate risk. Asking only for information needed at that stage, explaining why sensitive details are required, and showing what happens after submission can reduce hesitation. The immediate response should confirm receipt, set an appropriate expectation for the next contact, and preserve the claims that led the customer to inquire.

    Operational delivery completes the conversion system. Marketing may secure the booking, but communication after booking determines whether the original trust claim remains credible. That experience can later influence reviews, recommendations, repeat business, and the evidence available to future customers.

    Measure whether clarity changes customer behavior

    A trust initiative should be tied to a defined point of uncertainty. For example, a business might clarify quote inclusions, explain its role in the transport process, make the next step more visible, or revise language that sounds more certain than the operation allows. Each change should have a reason grounded in customer questions or observed friction.

    Quote completion and booking conversion can reveal whether more visitors progress, while abandonment points and recurring questions can show where uncertainty remains. Cancellation reasons, complaints, and mismatches between quoted expectations and later conversations provide a necessary counterweight: a higher initial conversion rate is not a success if it produces more misunderstanding afterward.

    A/B testing can help distinguish the effect of a particular presentation change from normal variation, provided the test changes a clearly defined element and uses an appropriate measurement window. Qualitative feedback remains important because conversion data can show where behavior changed without explaining why.

    Key takeaways

    • Trust improves conversion by making the shipping offer easier to understand and evaluate.
    • Useful trust signals answer concrete questions about identity, responsibility, quote scope, process, and communication.
    • Credentials and reviews are strongest when they reinforce clear operating claims rather than stand alone.
    • Realistic explanations of variables can be more credible than promises that remove all uncertainty.
    • The full journey, from landing page through post-booking communication, should maintain the same expectations.
    • Conversion gains should be assessed alongside cancellations, complaints, and expectation mismatches.

    The next competitive advantage is likely to come from treating customer uncertainty as operational feedback. Businesses that connect recurring questions to clearer pages, forms, follow-up, and service communication can improve the booking experience without asking buyers to rely on persuasion alone.

    References

  • Adaptive PPC Budget Allocation: A Framework for Funnel Health

    Adaptive PPC Budget Allocation: A Framework for Funnel Health

    Adaptive PPC budget allocation treats spending as a control system rather than a permanent percentage split. The objective is to move money between demand creation and demand capture as business pressure, market conditions, and funnel health change.

    The practical payoff is a more defensible allocation process: teams can identify the constraint they are trying to remove, choose signals that fit that constraint, and revisit the decision before an efficient-looking account becomes a growth-limited one.

    A budget split is an output, not the strategy

    Rules such as 70/30 or 60/40 can provide an initial planning reference, but the supplied CrushPress.AI article argues that they are poor long-term policies. The appropriate balance can change with the business stage, product maturity, market saturation, seasonality, competitive pressure, and urgency of revenue goals.

    The underlying decision is how much to spend capturing demand that already exists and how much to spend cultivating future demand. Shopping, Performance Max, and high-intent Search can make the capture side easy to defend because conversions, acquisition costs, and return on ad spend are comparatively visible. That visibility does not mean those campaigns created the interest they converted.

    Upper-funnel activity has a different economic role. Demand Gen, YouTube, and Display can introduce a brand or product before a buyer conducts a high-intent search. The source therefore frames awareness spending as an investment in the inventory of potential future customers, while lower-funnel campaigns convert that inventory when intent becomes observable.

    Search complicates a simple upper-versus-lower classification. A purchase-oriented query can represent demand capture, while an informational query can reach someone earlier in the buying journey. The source notes that broad match expansion and AI Max can extend Search into this exploratory territory. Budget classification should consequently reflect the queries and audiences a campaign actually reaches, not merely its campaign label.

    Diagnose the constraint before moving money

    A magnifying lens and inspection light reveal a constricted middle stage in a translucent funnel-shaped machine.

    An adaptive allocation starts with a diagnosis. More upper-funnel spending is appropriate when insufficient demand is constraining growth; more lower-funnel spending is appropriate when valuable existing demand is not being captured or when near-term cash requirements take priority.

    Observed conditionLikely budget implicationReason for the move
    Branded search is flat or declining across quartersConsider increasing upper-funnel investmentThe source presents this as a warning that the pool of future high-intent demand may not be replenishing.
    New-customer acquisition costs rise while retention remains stableInvestigate demand creation before simply scaling capture campaignsThe account may be relying increasingly on an established customer base or a limited demand pool.
    A new product or market is being introducedEmphasize awareness earlier in the planLower-funnel campaigns cannot capture much demand for an offer that buyers do not yet recognize.
    Shopping or Search acquisition costs are below targetScale productive lower-funnel activity where capacity remainsExisting demand may offer an immediate, economically attractive growth opportunity.
    Demand Gen reach is becoming repetitive rather than incrementalReduce or redirect upper-funnel spendThe source identifies audience saturation as a reason to stop buying repeated exposure and emphasize conversion.
    Revenue is urgently requiredTemporarily favor lower-funnel activityThe business may not be able to wait for awareness activity to mature, although the future pipeline cost should be acknowledged.

    These signals are decision prompts, not automatic bidding rules. A falling branded-query trend, for example, can justify investigation without proving that insufficient advertising caused the decline. The reallocation decision still needs commercial context, campaign diagnostics, and a clearly stated hypothesis.

    Account for timing, ownership, and market exposure

    Timing changes what an otherwise sensible allocation can accomplish. The source argues that seasonal advertisers should build awareness before peak demand arrives; attempting to create recognition only once the selling period is underway leaves little time for prospects to progress toward purchase. Conversely, a business facing immediate financial pressure may rationally prioritize conversion campaigns even if doing so weakens future demand creation.

    Product ownership also changes the risk calculation. A reseller can produce strong Shopping and Search results by capturing interest generated by the brands it carries. According to the source, that performance is vulnerable because the reseller does not control whether a manufacturer continues investing in marketing, remains relevant, or stays in the market.

    That dependency creates two possible upper-funnel jobs. A retailer with proprietary products can build recognition for those products, while a multi-brand seller can build its own reputation as a category destination. In both cases, the expenditure is intended to reduce reliance on demand created by another company, even when its contribution is not immediately visible in a campaign-level return report.

    Run allocation as a recurring operating cycle

    Glowing particles circulate through an interconnected control loop and funnel, with feedback streams returning to the center.

    A useful governance process separates the allocation decision from day-to-day bid optimization. The former determines which business constraint deserves funding; the latter improves execution within that allocation.

    1. Name the current constraint. Decide whether the priority is immediate revenue, new-customer growth, a launch, seasonal preparation, competitive defense, or demand-pool renewal.
    2. Map campaigns by actual role. Classify activity according to the intent and audiences it reaches. A Search campaign may contain both exploratory and purchase-ready demand.
    3. Choose a directional move. Increase demand creation, increase demand capture, or hold the split while improving campaign quality. Avoid changing multiple strategic variables without a stated reason.
    4. Define the expected signal and lag. Record what should move first, such as qualified reach or branded-query activity, and what should follow later, such as new-customer conversions.
    5. Protect commercially valuable capacity. When Shopping or Search remains below the acquisition-cost target, preserve room to capture that demand while testing an upper-funnel adjustment.
    6. Review and document the decision. Compare the expected and observed signals, note external changes, and retain or reverse the allocation based on the evidence.

    The source recommends reviewing the funnel split at least monthly and considers quarterly review too slow for detecting deterioration in branded-query demand. Monthly review does not require monthly upheaval; it creates a regular opportunity to confirm that the assumptions behind the current split still hold.

    Measure the funnel as a connected system

    Immediate campaign ROAS is useful for evaluating demand capture, but it is an incomplete test of demand creation. The source reports that the effect of reducing upper-funnel investment may not become visible for six to eight weeks. This lag can make a budget cut appear harmless before branded interest, prospect volume, or lower-funnel efficiency begins to weaken.

    The article identifies several signals available within Google Ads: branded-query trends, impression share on non-branded terms, Demand Gen reach metrics, and customer segmentation data. Used together, they provide a broader view of whether the account is expanding its pool of potential buyers, reaching new people, and converting available intent.

    Measurement should follow the expected sequence of effects. Upper-funnel activity can first produce qualified reach or awareness indicators, followed by changes in search behavior and eventually lower-funnel conversions. This sequence supports a more realistic evaluation than demanding an immediate direct-response return from every awareness campaign. It does not, however, establish causation by itself; overlapping media, competitor activity, seasonality, and market changes still need consideration.

    Governance matters because the evidence is asymmetrical. The source observes that lower-funnel spending is easier to defend internally due to its visible conversions and ROAS, while upper-funnel advocates must explain a delayed contribution to future performance. A written hypothesis, expected lag, and review date give that delayed contribution a testable business case rather than treating awareness as an article of faith.

    Key takeaways

    • Treat the PPC split as the result of a current business diagnosis, not as a permanent benchmark.
    • Distinguish demand creation from demand capture while recognizing that Search can perform either role.
    • Increase upper-funnel investment when the future demand pool is weakening, a launch needs recognition, or dependence on third-party brands creates strategic exposure.
    • Favor lower-funnel investment when efficient capture capacity remains or immediate revenue requirements outweigh the cost of waiting.
    • Evaluate awareness activity with leading indicators and an explicit time lag, then connect those indicators to later search and conversion behavior.
    • Review allocation at a regular cadence and document why each material shift was made.

    The strongest PPC allocation will keep changing because the constraint on growth keeps changing. Teams that make the split observable, revisable, and tied to funnel evidence will be better positioned to capture current demand without quietly exhausting the demand they need next.

    References

  • Measuring AI Search Visibility Beyond Traditional Keywords

    Measuring AI Search Visibility Beyond Traditional Keywords

    AI-generated answers are weakening the keyword’s role as the stable unit of search measurement. The challenge is not simply finding a replacement metric; it is building a measurement model that remains meaningful when prompts, answers, interfaces, and recommendations can all vary.

    The source material points to two connected shifts. One frames Google AI experiences as part of a move beyond conventional keywords, while the other argues that precise AI share-of-voice percentages can conceal an unstable and unauditable denominator. Together, they suggest that visibility should be evaluated as a set of observable signals rather than compressed into one universal score.

    Keywords remain useful, but no longer define the whole market

    The first source frames Google’s AI-oriented search experience around the prospect of keyword replacement. That framing does not mean keywords immediately become irrelevant. They can still organize demand themes, preserve continuity with historical reporting, and provide repeatable inputs for controlled tests. What changes is their status: a keyword list becomes a sample of possible user needs rather than a complete inventory of the market.

    Traditional keyword measurement assumes that a query can be entered, a result page can be observed, and a position can be recorded. The second source argues that this model has been disrupted by AI summaries, localized results, continuous scrolling, sponsored placements, personalization, and layouts that respond dynamically to intent. A conventional rank can therefore remain technically correct while describing less of the user’s actual experience.

    Prompts make the sampling problem larger. People can express the same need through comparisons, follow-up questions, constraints, use cases, and conversational refinements. Because the possible prompt set has no fixed boundary, no monitored list can claim to represent every relevant interaction. The defensible goal is representative coverage, not exhaustive coverage.

    Why a single AI share-of-voice percentage can mislead

    Unequal glass vessels containing glowing spheres sit on a balance while only one small vessel is fully illuminated.

    According to the second source, traditional share of voice at least used an explicit denominator: a marketer selected a keyword set, observed visibility against competitors, and calculated performance within that defined universe. The method had limitations, but its scope could be inspected.

    The source contends that some AI visibility platforms instead calculate percentage scores from limited prompt sets across services such as ChatGPT, Gemini, Claude, and Perplexity. If users cannot inspect how prompts were selected, how answers were classified, or how platforms and repetitions were weighted, the apparent precision of the percentage exceeds what the method can support.

    This does not make prompt tracking worthless. It changes the claim that the resulting number can sustain. A score derived from a declared prompt panel can describe what happened within that panel. It cannot, by itself, establish a brand’s share of every possible AI-assisted search. Reporting should therefore identify the tested universe, collection method, comparison rules, and limitations beside the result.

    The denominator is only one problem. A binary mention can also flatten materially different outcomes. A brand may appear as an incidental example, a leading recommendation, a warning, or a source citation. Counting all four appearances equally would hide the difference between recognition, commercial preference, reputational risk, and source authority.

    Measure presence, preference, and meaning separately

    Three connected visual layers show a signal across answer surfaces, recommendation paths converging on an option, and a prism revealing multiple facets.

    The second source proposes three alternatives to a universal AI share-of-voice score: share of mentions, share of recommendations, and share of narrative. These are most useful as separate dimensions. Combining them too early would recreate the opacity of the metric they are intended to replace.

    Mentions indicate whether the brand enters the answer

    Share of mentions measures how often a brand appears within a defined test set relative to relevant alternatives. The source connects this visibility to the relationships AI systems form from training material or real-time retrieval sources. Operationally, mention tracking can reveal whether a brand is associated with a topic at all, but it should preserve the prompt category, platform, answer context, and competitors observed.

    Recommendations reveal preference within a buying context

    Share of recommendations narrows the question from “Was the brand named?” to “Was it advised?” The source argues that clear, well-documented market positioning is important here. Recommendation analysis should distinguish a direct endorsement from inclusion in a broad set of options, because those answer forms represent different levels of preference.

    Narrative captures how the brand is characterized

    Share of narrative adds the qualitative layer. The second source notes that frequent visibility can still be harmful when the surrounding portrayal is negative. Narrative review should therefore examine the attributes, use cases, cautions, and comparisons attached to a brand. This is where measurement connects AI search visibility with positioning and reputation management.

    These dimensions answer different business questions. Mentions indicate conceptual presence, recommendations indicate preference, and narrative indicates meaning. None should automatically substitute for outcomes such as qualified visits or conversions; those belong in a separate performance layer when reliable data is available.

    Key takeaways

    • Use keywords as controlled samples of demand, not as a complete map of AI-assisted discovery.
    • Treat an AI visibility percentage as a result for a declared prompt panel unless its broader denominator can be audited.
    • Report mentions, recommendations, and narrative separately so that recognition is not confused with preference or reputation.
    • Preserve prompts, platforms, repetitions, classification rules, and collection conditions so changes can be interpreted.
    • Connect visibility signals to business outcomes without implying that a mention alone caused traffic, leads, or revenue.

    Build a measurement system that can be challenged

    A credible program begins by defining the decision it must support. Brand teams may need to understand how the market is described, search teams may need to assess discovery coverage, and commercial teams may care about recommendation frequency. Each purpose requires a different mix of prompts and a different interpretation of success.

    The monitored prompt set should then be grouped by user need, such as discovery, comparison, evaluation, or problem solving. The exact groups will vary by organization; what matters is that the selection logic is documented. Fixed prompts provide comparability over time, while a separately labeled exploratory sample can surface emerging language without silently changing the benchmark.

    Collection should retain enough context to reproduce or audit an observation: the prompt, platform, answer, collection condition, brand appearances, recommendation status, narrative classification, and any cited sources. Repetition can expose variability, but the reporting should show that variability rather than smoothing it into unwarranted certainty.

    Competitive comparisons should use the same prompt panel and classification rules for every brand. Results can then be reported as observed rates within that explicit sample. This language is more limited than claiming a universal market share, but it gives leadership a number whose boundaries can be understood.

    Finally, AI visibility should sit beside conventional search and business evidence rather than replace them. Keyword trends can preserve historical context; mention, recommendation, and narrative measures can describe answer-level presence; outcome data can show whether observable demand followed. The next generation of search measurement will become more useful as it becomes more transparent about what was tested, what changed, and what remains unknown.

    References

  • Unlock Competitor Insights with Adthena’s ChatGPT Ad Analysis

    Unlock Competitor Insights with Adthena’s ChatGPT Ad Analysis

    I recently dove deep into the fascinating world of ChatGPT Ads with insights from Adthena. It turns out, the advertising space on ChatGPT is a treasure trove of competitive information that many search teams are missing out on.

    Your competitors are running stealth campaigns via ChatGPT, and the frustrating part is that it’s not immediately visible what they’re bidding on or what creative strategies they’re adopting. Unlike Google Ads, there’s no native way—yet—to get a behind-the-scenes look at this in ChatGPT.

    When OpenAI launched advertising within AI-generated responses, brands jumped on board quickly. With the Ads Manager and lowered spending thresholds, this new ad channel grew rapidly. And with plans to expand to U.K. markets soon, there’s a quickly closing window for early adopters to gain a significant advantage.

    From the start, we’ve been closely monitoring these developments, and what we’ve found is eye-opening.

    ```json
{
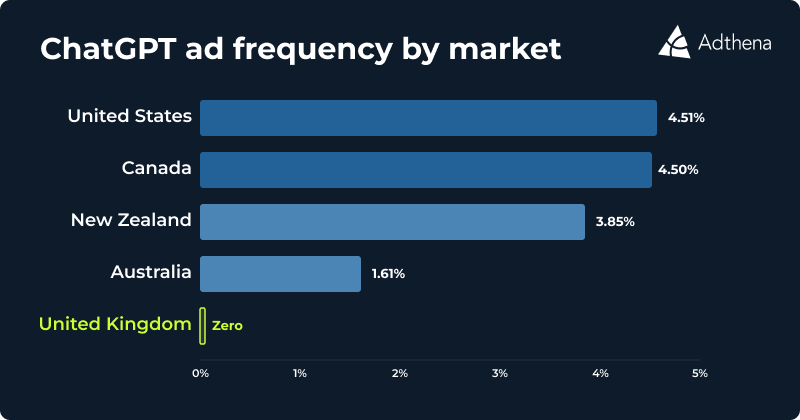
  "alt": "Bar chart showing ChatGPT ad frequency by market. U.S. at 4.51%, Canada 4.50%, New Zealand 3.85%, Australia 1.61%, U.K. Zero.",
  "caption": "Exploring ChatGPT ad presence globally: U.S. and Canada lead with over 4%, while the U.K. notes zero activity. Discover market trends in AI advertising.",
  "description": "This image is a bar chart illustrating ChatGPT ad frequency across different markets. The data shows the United States at 4.51%, Canada at 4.50%, New Zealand at 3.85%, and Australia at 1.61%. Notably, the United Kingdom registers zero ad frequency. The chart is presented on a dark blue background, emphasizing the data collected by Adthena."
}
```

    What Does the Current ChatGPT Ads Landscape Look Like?

    Our analysis spans nearly a million queries across 20 industries in five markets, telling a clear story of the current landscape.

    It’s Primarily a U.S. Channel—Other Markets are Catching Up

    In the U.S., ads are run on about 4.5% of queries. In contrast, during the same period, the U.K. had none. The U.S. dominates, accounting for 90% of ChatGPT ad placements in our dataset, with Canada and New Zealand also active and Australia at 1.6%.

    For U.K. teams, it means while the channel isn’t live yet, U.S. competitors are already fine-tuning prompts and creative strategies, placing them at a strategic advantage when the U.K. market opens.

    ```json
{
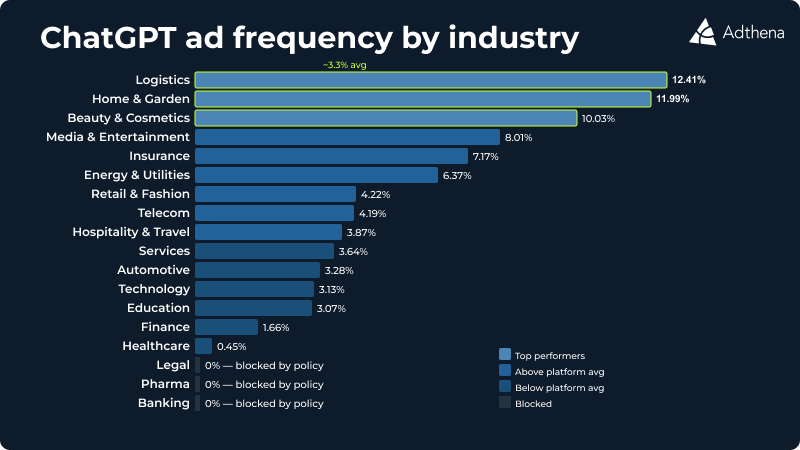
  "alt": "Bar chart showing ChatGPT ad frequency by industry, with Logistics having the highest percentage.",
  "caption": "Explore how ChatGPT ads perform across industries, with Logistics leading the charge at 12.41% and sectors like Legal and Pharma blocked.",
  "description": "This image is a bar chart from Adthena, illustrating ChatGPT ad frequency across various industries. Logistics tops the list at 12.41%, followed by Home & Garden at 11.99%. Categories such as Legal and Pharma have 0% due to policy blocks. The chart categorizes industries into top performers, above platform average, below average, and blocked, offering insight into advertising trends."
}
```

    The Majority of Responses Contain Just One Ad

    On average, ChatGPT presents only 1.06 ad items per response in the U.S., implying a single sponsored slot per query. This level of exclusivity changes the game completely compared to multi-slot Google Ads.

    Industry Restrictions Still Apply

    Certain sectors, like Legal and Pharma, show no ad activity due to what seems to be OpenAI’s deliberate restrictions, although this could change, providing proactive teams an edge.

    Unexpected Hot Categories

    Logistics, Home & Garden, and Beauty & Cosmetics are leading in ad frequency, indicating high potential for growth in these sectors.

    ```json
{
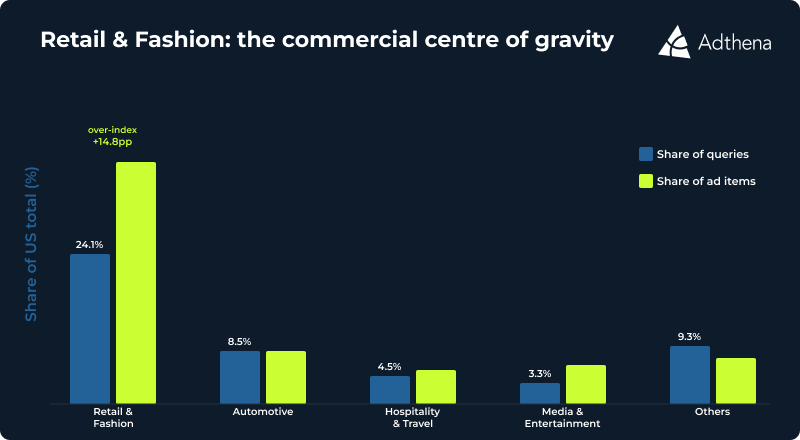
  "alt": "Bar chart showing US market shares for retail, automotive, hospitality, media, and others.",
  "caption": "Retail and fashion dominate the US market, leading ahead in both search queries and ad presence.",
  "description": "This bar chart compares the US market shares of various industries: retail & fashion, automotive, hospitality & travel, media & entertainment, and others. Retail & fashion is the leader with 24.1% share of queries and even higher ad items share at 38.9%, showing an over-index of +14.8pp. Automotive follows with 8.5% in queries. The chart, presented by Adthena, emphasizes the commercial gravity of retail in the US market."
}
```

    Retail Leads in Ad Spend

    Retail & Fashion accounts for a vast share of U.S. ad items, indicating robust advertiser demand, far surpassing the national average. This suggests the significant investments made by retail brands in this space.

    Current Challenges in Competitive Intelligence

    Without tools like Auction Insights, understanding your competitive landscape on ChatGPT is practically impossible. You’re spending budget where you can barely track competitor activity. It’s a gap that Adthena aims to close.

    Achieving Full Market Visibility with Adthena

    Adthena’s ChatGPT Ads Intelligence offers broader insights by monitoring a plethora of prompts daily, providing a competitive overview previously unavailable.

    ```json
{
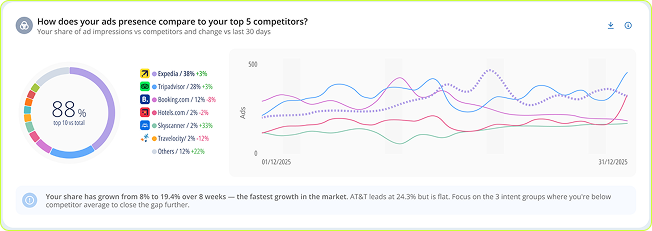
  "alt": "Ad impressions comparison chart with competitors and line graph analysis.",
  "caption": "Dynamic visualization of ad presence over time, comparing performance with top competitors.",
  "description": "The image displays a data chart comparing ad impressions among top competitors over 30 days. A pie chart shows a 38% share, while a line graph tracks different competitors' trends from 01/12/2025 to 31/12/2025. A note highlights the fastest growth from 8% to 19.4% in 8 weeks, advising focus on areas where competitors outperform."
}
```

    You can now see who bids on your prompts, track share of voice, and spot open prompts ripe for targeting before competitors do.

    In a new and rapidly evolving channel, being an early mover is an opportunity that shouldn’t be missed. Try ChatGPT Ads Intelligence free for 21 days and unlock the full potential of your advertising strategy.

    Beyond Just ChatGPT: Expanding Your Search Horizons

    As users move towards AI-driven searches for high-intent queries, such as product recommendations, it’s essential for search practitioners to adapt. Simply put, the game is changing.

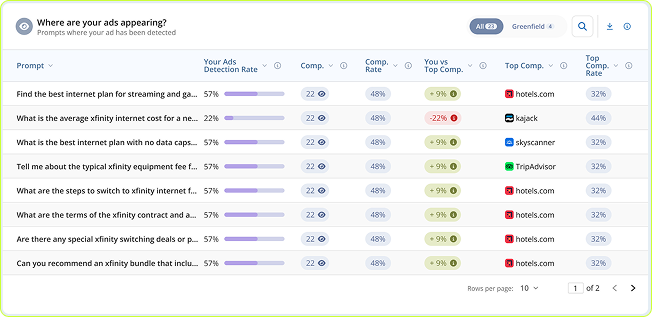
    ```json
{
  "alt": "Chart showing ad detection rates for Xfinity-related queries with competitors' comparison and top competitor sites.",
  "caption": "Explore where your ads stand in the competitive landscape with detailed detection rates and comparisons against top competitors like hotels.com and kajack.",
  "description": "This image displays a chart analyzing ad detection rates for various Xfinity-related queries. It highlights your detection rate alongside competitors and compares it to top competitors like hotels.com. The table details 'Prompt', 'Your Ads Detection Rate', 'Comparison Rate', 'Top Competitor', and more. Ideal for advertisers seeking insights into ad performance and competitor strategy."
}
```

    If you’re attentive to ChatGPT Ads now, you’ll be hard to budge later. Our data shows a window of opportunity open now, similar to the early days of Google Ads. Capitalize on this before it closes.

    Start your free 21-day trial of Adthena’s ChatGPT Ads Intelligence today to discover what’s unfolding in the ChatGPT ad space.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Google’s New SEO Guidelines: A Personal Take on Third-Party Tools & AI

    Google’s New SEO Guidelines: A Personal Take on Third-Party Tools & AI

    When I heard that Google had added a new help document to its search developer documentation, I knew I needed to dive in. This new document, “Google Search’s guidance on using third-party SEO tools, services, and advice,” provides updated insights into the world of SEO, especially revolving around the hot topic of generative AI optimization.

    Google also revamped its “Do you need an SEO?” guide, adding fresh content around generative AI topics. The intent behind these updates, as stated by Google, is to highlight what to consider when evaluating third-party tools and to simplify existing documentation. They want us to be cautious about trusting these tools and advice without proper verification.

    Reading through Google’s new guidance, I found some valuable advice on thoughtfully evaluating third-party SEO services. Here’s how they suggest approaching it:

    Evaluate external SEO advice against Google’s official guidelines, think critically about third-party tools, and always verify the claims made by these services.

    • Evaluate and verify external SEO advice against official Google guidelines
    • Think critically about using third-party SEO tools and services
      • Assisting in sitemap generation
      • Establishing indexing directives
      • Offering to generate “SEO-optimized” content for you
      • Providing advice to improve the ranking of existing content
      • Promising improvements for AI experiences and search formats (“AEO” or “GEO” tools)

    While Google doesn’t endorse any third-party tools, they emphasized using Google Search Console for credible data directly from Google Search. We need to be wary of tools claiming to guarantee success since they lack access to Google’s internal ranking data.

    With the updated “Do you need an SEO?” document, Google has also covered topics like Optimizing for generative AI. It includes essential reminders that if an SEO uses a third-party tool, one should not assume it’s approved by Google, and during audits, access to Search Console should be limited initially.

    In essence, before making any site changes based on third-party audits, it’s crucial to cross-reference their advice with Google’s official resources, especially when it comes to AI optimization strategies.

    Understanding these updates helps us not only in improving our own SEO strategies but also in promoting ethical and effective use of tools.

    The document updates come as a reminder for us to regularly check Google’s official documentation. Staying informed about new guidelines ensures that we’re always on the right path in our SEO journey.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Harnessing the Power of Profound for AI-Driven Marketing Success

    Harnessing the Power of Profound for AI-Driven Marketing Success

    I’ve discovered that Profound is the ultimate hub for marketers aiming to excel in the AI-driven landscape. It’s where I run my visibility, sentiment, and accuracy analyses.

    This platform is my go-to for building marketing Agents and uncovering new opportunities. It’s here that I generate innovative content and take action based on deep insights.

    Given all these functions, it’s only natural that Documents have found a home here too. Profound seamlessly integrates document management into my existing marketing workflow.


    Inspired by this post on Try Profound Blog.


    crushpress.ai community screenshot
  • How to Choose a Healthcare or Senior Care Marketing Agency

    How to Choose a Healthcare or Senior Care Marketing Agency

    Healthcare and senior care agencies may appear in the same search results, but they are often built for different growth problems. A provider seeking more booked appointments, a senior living community trying to build local trust, and a medical technology company pursuing enterprise buyers need different channels, expertise, and success measures.

    The useful starting point is therefore not a single league table. It is a clear definition of the audience, conversion event, sales cycle, and evidence an agency must provide. Three 2026 agency reports offer complementary views of that decision: content marketing, healthcare lead generation, and senior living marketing.

    Key takeaways

    • Choose by growth problem first: authority building, patient or resident acquisition, complex B2B outreach, and senior living brand development require different capabilities.
    • Healthcare specialization is most valuable when it affects execution, including audience knowledge, channel selection, content quality, local discovery, and the handling of long buying cycles.
    • Published rankings are useful for forming a shortlist, but their results depend heavily on the criteria and weights selected by the publisher.
    • Reported ROI, client rosters, reviews, and leadership experience should be treated as due-diligence leads rather than substitutes for direct verification.
    • The strongest proposal should connect marketing activity to a meaningful conversion, such as a qualified sales conversation, appointment, inquiry, or community tour.

    Start with the growth job, not the agency category

    A strategy team reviews three object-based customer journeys leading to a healthcare appointment, a senior living visit, and a business handshake.

    The three reports collectively describe at least four distinct agency jobs. Content-led firms build visibility and authority through expert material and search. Patient-acquisition specialists use channels such as paid search, paid social, and local SEO to generate appointments. B2B lead-generation firms pursue decision-makers through thought leadership or outbound appointment setting. Senior living specialists combine digital discovery with branding, traditional media, marketing automation, or call handling.

    Those jobs are related, but they are not interchangeable. The healthcare lead-generation report characterizes Cardinal Digital Marketing as a patient-acquisition specialist for multi-location provider groups and management service organizations, while noting that its model is less suited to B2B medtech or health IT. The same report describes Revnew as a fit for medical device and pharmaceutical organizations where precise targeting across a long sales cycle matters more than high lead volume. That contrast illustrates why a broad claim such as “healthcare expertise” is not enough.

    Senior living introduces another distinction. Its specialist report identifies agencies oriented toward community branding, local visibility, traditional advertising, automation, and inquiry management. A senior living operator should consequently decide whether the immediate constraint is awareness, lead capture, follow-up, or conversion before comparing agencies.

    Map the reported agencies to the work they emphasize

    The source reports support a practical market map rather than one universal ranking. The following groupings reflect how the reports described each firm; they do not independently verify agency performance.

    Marketing needAgencies highlighted by the reportsReported emphasis
    Search authority and expert contentFirst Page SageThe lead-generation report highlights SEO, generative engine optimization and long-form thought leadership for complex healthcare buyers. The senior living report also associates the firm with SEO, trust-building content and visibility in AI-driven search.
    Integrated B2B healthcare demand generationSagefrog Marketing GroupBrand strategy, HubSpot-powered inbound programs and paid media. The lead-generation report presents it as a cohesive, brand-led option rather than a rapid outbound program.
    Provider and patient acquisitionHealthcare Success; Cardinal Digital MarketingHealthcare Success is described as serving hospitals, multi-location practices, urgent care and addiction treatment through broad strategy, local SEO and paid search. Cardinal is positioned around coordinated PPC and paid social for appointment volume.
    Specialized or scaled B2B outreachRevnew; Belkins; Callbox; Launch LeadsRevnew is associated with precise outreach for complex medical sales. Belkins, Callbox and Launch Leads are presented as appointment-setting options, with varying emphasis on multichannel outreach, CRM integration, scale and entry into new markets.
    Senior living brand and demand programsLove & Company; SenioROI; Senior Living Smart; Comrade Digital Marketing; Markentum; Senior Living Marketers; SageAge; Five19The senior living report spans brand strategy, traditional media, automation, call-center management, local SEO, paid advertising, social media and creative positioning. The range indicates that these firms should be compared by service model rather than treated as equivalent.

    The content-marketing report adds a broader screening perspective. It says roughly 60 healthcare content agencies were evaluated and eight selected using experience, specialties, notable clients, and reviews. The supplied report summary does not provide the individual profiles, so its main contribution to this synthesis is methodological: content credentials should be assessed alongside sector fit and external reputation.

    Read rankings as signals shaped by their methodology

    The lead-generation report says its team evaluated 63 U.S. agencies from March through May 2026 and selected eight. Industry-specific expertise accounted for 25% of its score, reported average client ROI for 20%, notable clients and customer reviews for 15% each, leadership experience and media references for 10% each, and specialty for 5%. It says review scores were aggregated from platforms including G2, Clutch, and Google Reviews.

    The senior living report uses a substantially different formula. Notable clients and average review score each account for 30%, leadership experience for 25%, year established for 10%, and median employee tenure for 5%. As a result, an established agency with a recognizable portfolio and strong reviews can perform well even if another firm is better suited to a particular channel or operating model.

    This does not make either ranking unhelpful. It makes the scoring logic part of the evidence. A buyer prioritizing outbound pipeline quality should not automatically adopt the result of a model that heavily rewards public client rosters. Likewise, a community seeking an enduring brand partner may reasonably value leadership continuity and experience more than a narrowly defined lead metric.

    The lead-generation report also publishes agency-level ROI figures derived from case studies and results reported by the agencies. Those figures are useful prompts for investigation, but they are not presented as independently audited comparisons. Differences in attribution windows, revenue definitions, deal sizes, and included costs can make superficially similar ROI numbers measure different things.

    Build a shortlist that can survive direct scrutiny

    Two healthcare executives examine three shortlisted agency evidence folders with a magnifying glass and blank comparison cards.

    A defensible selection process converts broad claims into evidence tied to the prospective engagement. That means testing whether an agency has solved a comparable audience and conversion problem, not merely whether it has displayed a healthcare logo.

    Decision areaEvidence to requestWhat the evidence should clarify
    Relevant specializationA case study involving a similar audience, offering, sales cycle, and conversion goalWhether the agency’s healthcare experience transfers to the actual assignment
    MeasurementThe proposed funnel stages, attribution approach, reporting cadence, and definition of a qualified conversionWhether performance can be evaluated beyond traffic, impressions, or raw lead counts
    Channel fitA channel rationale linked to how the intended patient, resident, family, clinician, or business buyer makes a decisionWhether the plan follows the audience rather than the agency’s preferred service
    Reported resultsDefinitions, time period, baseline, included costs, and assumptions behind ROI or lead claimsWhether two proposals can be compared on reasonably consistent terms
    Delivery teamNamed strategic and day-to-day roles, relevant experience, approval workflow, and use of outside contributorsWho will perform the work after the sales process ends
    Operational compatibilityResponsibilities for content review, lead routing, CRM updates, call handling, and sales or admissions follow-upWhether internal bottlenecks could prevent marketing activity from becoming revenue or occupancy

    The final choice should be based on the smallest credible set of capabilities needed to remove the current growth constraint. As AI-assisted discovery, search behavior, and channel economics evolve, agencies will need to demonstrate not only a current specialty but also a transparent method for testing, measuring, and adapting it.

    References

  • How to Choose an Industry-Focused SEO Agency in 2026

    How to Choose an Industry-Focused SEO Agency in 2026

    An industry-focused SEO agency should offer more than a portfolio containing familiar company names. Its real value lies in understanding how a sector’s customers search, which evidence earns their trust, and what technical or geographic constraints shape the path to conversion.

    Three 2026 agency reports covering solar, agriculture, and local SEO reveal a useful selection framework. They also show why a ranking should begin due diligence rather than settle the decision.

    Key takeaways

    • Relevant client experience, review quality, and leadership expertise recur across all three agency evaluations.
    • Specialization should be tested at the level of search behavior, content, technical requirements, geography, and commercial outcomes.
    • Local SEO is a distinct operating capability, not a substitute for knowledge of a client’s industry.
    • Scorecard weights reveal what a ranking values, but buyers still need to examine the evidence behind each score.
    • The best agency is the one whose delivery model fits the organization’s actual bottleneck, whether that is authority, local visibility, branding, or technical execution.

    What specialization should change in practice

    The three reports share a basic premise: experience close to the client’s market matters. The solar evaluation gave notable clients 28% of its score and also considered home-services experience when an agency had less direct solar work. The agriculture evaluation assigned 25% to notable clients and emphasized leadership experience in agriculture-specific strategy. The local SEO report made demonstrated local experience its largest factor, at 25%.

    Those criteria point to different kinds of relevance. Vertical expertise concerns the market itself: its audiences, terminology, buying process, content opportunities, and standards of credibility. Local expertise concerns how a business competes across places, including location pages, structured information, and visibility in map-oriented results. An agency may possess one capability without the other.

    The solar report illustrates how varied agencies within one vertical can be. It described First Page Sage as using thought-leadership content, geographically targeted landing pages, and white papers for mid-market and enterprise providers. Siana Marketing was presented as combining SEO and generative engine optimization, or GEO, with knowledge of solar sales cycles. Anchour was positioned around branding for smaller companies, while XEN Solar was associated with technical SEO and HubSpot optimization. These profiles are source-reported positioning, not independently verified performance, but they demonstrate that an industry label can encompass substantially different delivery models.

    What the agency scorecards measure – and omit

    ReportAgency pool reviewedMost heavily weighted evidenceDistinctive considerations
    Solar SEO31 agenciesNotable clients, 28%; leadership experience, 22%; average reviews, 22%Year founded, 16%; company size, 12%
    Agriculture SEO81 companiesAverage reviews, 25%; notable clients, 25%; leadership experience, 20%Services, founder involvement, and media references, each 10%
    Local SEO48 firmsLocal SEO experience, 25%; average reviews, 20%Technical expertise and local-pack effectiveness, each 15%; leadership, employee tenure, and media references

    The overlap is meaningful. All three reports considered client reviews and leadership experience, while the two vertical studies placed substantial weight on recognizable or relevant clients. Taken together, the reports treat market evidence, reputation, and senior expertise as complementary signals rather than interchangeable ones.

    The differences are just as instructive. The solar methodology rewarded longevity and company size. The agriculture methodology considered whether the founder remained active and how often the company appeared in media. The local evaluation gave explicit weight to technical SEO, local-pack results, and median employee tenure. A buyer that values stable account teams may find tenure more informative than media visibility; a multi-location operator may care more about local-pack evidence than an agency’s founding date.

    Methodological transparency also needs scrutiny. The agriculture article says it used seven factors, but the supplied methodology names six: reviews, clients, leadership, services, founder involvement, and media references. Their stated weights total 100%, yet the mismatch between the announced and enumerated factor count is a reminder to inspect the underlying rubric rather than rely only on the final order.

    How to test an agency’s claimed industry expertise

    A client team tests SEO consultants around a table containing technical components, map contours, product samples, and unlabeled evidence folders.

    Interrogate the case evidence

    A logo establishes that some relationship existed; it does not explain the scope, duration, baseline, or result. Buyers can ask what the agency was responsible for, which search problems it addressed, and how outcomes were measured. Reviews deserve similar examination. The agriculture report said it consulted G2, Clutch, and Google Reviews, while the local report described a composite drawn from Google, Clutch, and other verified platforms. The solar report referred more generally to publicly available reviews and gave additional weight to solar-client feedback.

    That makes review composition more important than a headline average. Relevant questions include whether comments describe SEO work, whether they come from comparable organizations, and whether they discuss communication and execution as well as satisfaction.

    Distinguish leadership credentials from delivery capacity

    Leadership experience appeared in every methodology, receiving 22% in solar, 20% in agriculture, and 10% in local SEO. Senior expertise can shape strategy and quality standards, but buyers also need to learn who will actually conduct research, create content, implement technical changes, and report results. The local report’s inclusion of employee tenure offers one possible signal of delivery continuity; the solar report instead used company size as an indicator of capacity and client support.

    Request a diagnosis specific to the business

    A credible proposal should connect tactics to an identified constraint. An authority problem may call for expert-led content. A location-discovery problem may require technically sound location architecture and local visibility work. A weak market position may require branding before publishing at scale, while an implementation backlog may favor a technically oriented partner. This diagnosis is more revealing than whether an agency repeats the vocabulary of the sector.

    Match the engagement model to the actual search problem

    The sources suggest that industry specialization is not a single service category. In the agriculture report, First Page Sage was described as offering SEO, GEO, advertising, and web development, with thought leadership at the center of its positioning. The report said the company was founded in 2009 and began adapting to generative AI in 2023, while also crediting it with early GEO research. Those are claims made by the source and should be assessed alongside work samples and client evidence.

    The appearance of GEO in both the agriculture and solar coverage indicates that some sector-focused firms are extending their positioning beyond conventional search results. That does not remove the need for foundational SEO. A buyer can ask the agency to separate established deliverables – such as site architecture, content, and location optimization – from newer visibility initiatives, then explain how each will be measured.

    Organizational fit matters as well. The solar report associated one agency with enterprise thought leadership, another with small-company branding, and another with agile technical support. A specialist can therefore be relevant to the industry but wrong for the client’s scale, internal resources, technology stack, or immediate commercial objective.

    Turn selection criteria into an accountable engagement

    A client and agency team build a modular tabletop pathway with illuminated checkpoints connecting search activity to a conversion symbol.

    Before contracting, the organization should translate its selection rationale into a clear operating agreement. The scope can identify the audiences and markets being pursued, the technical and content responsibilities of each party, the approval process, and the business actions that count as meaningful conversions. Reporting should distinguish completed work and search visibility from qualified commercial outcomes.

    The same evidence used to select the agency can become a review standard. If leadership involvement influenced the decision, its expected role should be explicit. If local-pack effectiveness was decisive, the relevant locations and queries should be agreed upon. If industry content expertise won the work, editorial quality and access to subject-matter experts should be built into the process.

    As search interfaces and agency offerings continue to evolve, the strongest partnerships will be those that define specialization through observable decisions and accountable work, rather than through category labels alone.

    References

  • Choosing a B2B Technology or Growth Marketing Agency

    Choosing a B2B Technology or Growth Marketing Agency

    IT, managed service provider, SaaS and growth marketing agencies are often presented as separate categories, but buyers are usually choosing among overlapping combinations of industry knowledge, channel expertise and commercial accountability. The useful question is not which label sounds most relevant; it is which operating model matches the company’s actual growth constraint.

    Three agency reports published for 2026 provide a starting point for that decision. Read together, they show a broad and specialized market, while also illustrating why rankings should inform due diligence rather than replace it.

    Agency labels describe different dimensions of the same decision

    IT and MSP agencies are defined mainly by the markets they understand. SaaS agencies are similarly oriented around a business model and its associated buyer journey. Growth agencies, by contrast, are usually defined by an objective and an experimental way of working across acquisition, conversion and retention. These descriptions can coexist: a firm may be a SaaS specialist and still use a growth-marketing operating model.

    The IT and MSP report makes the range of possible specializations especially visible. It associates agencies with GEO and SEO, branding and influencer marketing, full-service delivery, enterprise marketing, webinars, PPC, trade shows and WordPress design. That variety means two agencies in the same industry category may solve entirely different problems.

    The growth-agency report says it reviewed 50 agencies spanning niche specialists and broader providers. Meanwhile, the SaaS report says it evaluated 57 contenders and selected eight. Together, the reports suggest that specialization is not a simple choice between a vertical expert and a generalist. Buyers must decide how much domain fluency, channel depth and cross-funnel coordination they need from the same partner.

    What the 2026 rankings establish – and what they do not

    The reports describe substantial candidate pools, but they expose different amounts of methodological detail. The IT and MSP article says it considered more than 53 candidates. Its stated weighting gives 25% each to notable clients and leadership experience, 20% to average review score, 15% to median employee tenure, 10% to founder involvement and 5% to year established. The growth-agency article identifies leadership experience as a 28% component of its analysis. The SaaS article reports its candidate and finalist counts, although the supplied account does not provide enough detail to compare its full scoring model with the others.

    ReportReported scopeDecision insight
    IT and MSP agenciesMore than 53 candidates; eight agencies listedShows how leadership, clients, reviews, staff tenure, founder involvement and longevity can be combined with service specialization
    Growth marketing agencies50 agenciesFrames the market as a mix of niche and broad-spectrum providers, with leadership experience carrying a reported 28% weight
    SaaS marketing agencies57 contenders; eight selectedShows the selectivity of the publisher’s SaaS shortlist, but not enough disclosed detail here to compare every criterion directly

    These measures are useful signals, not direct evidence that an agency will perform in a particular engagement. A recognizable client does not reveal the scope or outcome of the work. Review averages can conceal differences in project type. Employee tenure may indicate organizational stability, but it does not demonstrate expertise in the buyer’s market. Founder involvement can improve strategic continuity or create a bottleneck, depending on how delivery is structured.

    Publisher incentives also matter. The IT and MSP article ranks First Page Sage, its own publisher, in first place and reports a 4.9 review score, 4.3-year median employee tenure and a 2009 founding date for the firm. Those details should be treated as vendor-published claims and independently checked. The same principle applies to every agency’s client logos, case studies, review summaries and performance assertions.

    Key takeaways

    • Choose the specialization that matches the current constraint: industry fluency, a particular channel, cross-funnel experimentation or additional execution capacity.
    • Use agency rankings to discover candidates, then verify the evidence behind client names, reviews, staff stability and leadership credentials.
    • Compare the people who will perform the work, not only the executives and brands presented during the sales process.
    • Define commercial outcomes and measurement rules before comparing proposals, so agencies are evaluated against the same brief.

    A better shortlist starts with the growth constraint

    Two strategists examine an interconnected business system with one illuminated bottleneck restricting the flow.

    An IT or MSP business selling a technically complex service may benefit from an agency that can translate infrastructure, security or compliance topics into credible content. The IT and MSP report describes this approach in its profile of First Page Sage, which it says develops thought-leadership content around niche technical subjects and uses GEO and SEO to pursue authority and inbound leads. Because that description comes from the agency’s own publication, buyers should request representative work and attributable results before accepting the positioning.

    A SaaS company may instead need help with the connections among acquisition, product education, conversion and retention. A growth-oriented partner can be relevant when the central challenge is not merely generating traffic but identifying and testing improvements across the customer journey. Neither category automatically guarantees those capabilities; the proposal and delivery team must demonstrate them.

    Channel specialists make sense when the problem is already well diagnosed. The IT and MSP list, for example, associates ON24 Marketing with webinars, Alliance with trade shows, Seota Digital Marketing with WordPress design, and Yes& with PPC and branding for smaller IT companies. A broader agency is more defensible when channels must be coordinated, the internal team is thin or the company still needs to determine where its growth bottleneck sits.

    The resulting brief should distinguish the business outcome from the marketing deliverable. A request for articles, paid campaigns or a website describes production. A request to increase qualified opportunities in a defined market describes the commercial problem. Agencies can then explain which deliverables they believe will influence that result, what assumptions the strategy depends on and how progress will be measured.

    Due diligence should test evidence, delivery and fit

    Buyer and agency teams review a completed model, a delivery prototype and interlocking pieces during a due diligence meeting.

    A strong evaluation process converts ranking criteria into questions that can be verified. For notable clients, the buyer should establish what the agency actually delivered, whether the engagement resembles the proposed work and whether outcomes can be discussed. For leadership experience, the relevant issue is how often senior leaders participate after the sale. For reviews and tenure, the agency should be asked to explain patterns, team continuity and who would own the account.

    Case studies are most informative when they identify the starting condition, intervention, time frame, measurement method and agency contribution. Buyers should also separate leading indicators, such as visibility or engagement, from pipeline and revenue outcomes. Attribution rules, CRM responsibilities and reporting access should be agreed before work begins; otherwise, both sides may use the same words for different measures of success.

    Operating fit is equally important. The evaluation should clarify the proposed team, specialist access, approval workflow, content-review process, reporting cadence, ownership of accounts and data, and the conditions for changing or ending the engagement. For technical B2B markets, subject-matter access and factual review deserve particular attention because marketing speed is valuable only when the material remains accurate and credible.

    The most resilient choice will be the agency whose expertise, delivery system and evidence align with a clearly defined business problem. As search interfaces, buyer research habits and growth channels continue to change, that alignment will matter more than a permanent position on any annual list.

    References