Author: shivamcrushpressai

  • How AI Attribution Should Shape the DSA-to-AI Max Migration

    How AI Attribution Should Shape the DSA-to-AI Max Migration

    Google’s planned transition from Dynamic Search Ads (DSA) to AI Max is more than a campaign-format change. It arrives as AI is also altering how buyers discover brands, how platforms select audiences and placements, and how much of the decision journey advertisers can observe.

    The extended migration window gives advertisers an opportunity to build a measurement baseline before adopting more automation. The practical goal is not simply to determine whether AI Max records more conversions than DSA, but whether it produces additional qualified business outcomes without obscuring where demand originated.

    Campaign migration and attribution are now the same problem

    The two source articles address different developments, but their implications converge. The migration report says Google postponed automatic DSA migration from September 2026 to February 2027 and recommends experiments comparing existing campaigns with AI Max for Search. The attribution analysis warns that platform automation can improve reported performance while reducing the detail available for explaining why that performance changed.

    That combination raises the standard for a successful migration. A campaign can appear more efficient because it reaches people who were already likely to convert, captures demand created elsewhere, or counts actions that do not become meaningful customer outcomes. Broader targeting may also introduce weak leads that influence later automated optimization.

    The attribution article describes an increasingly fragmented journey in which a buyer might encounter a brand through social media, video, community discussions or an AI recommendation before completing a branded search. In such a journey, the campaign receiving conversion credit may have captured existing intent rather than created it. AI Max testing therefore needs to examine both reported attribution and the business contribution behind it.

    The measurement risks that can distort an AI Max comparison
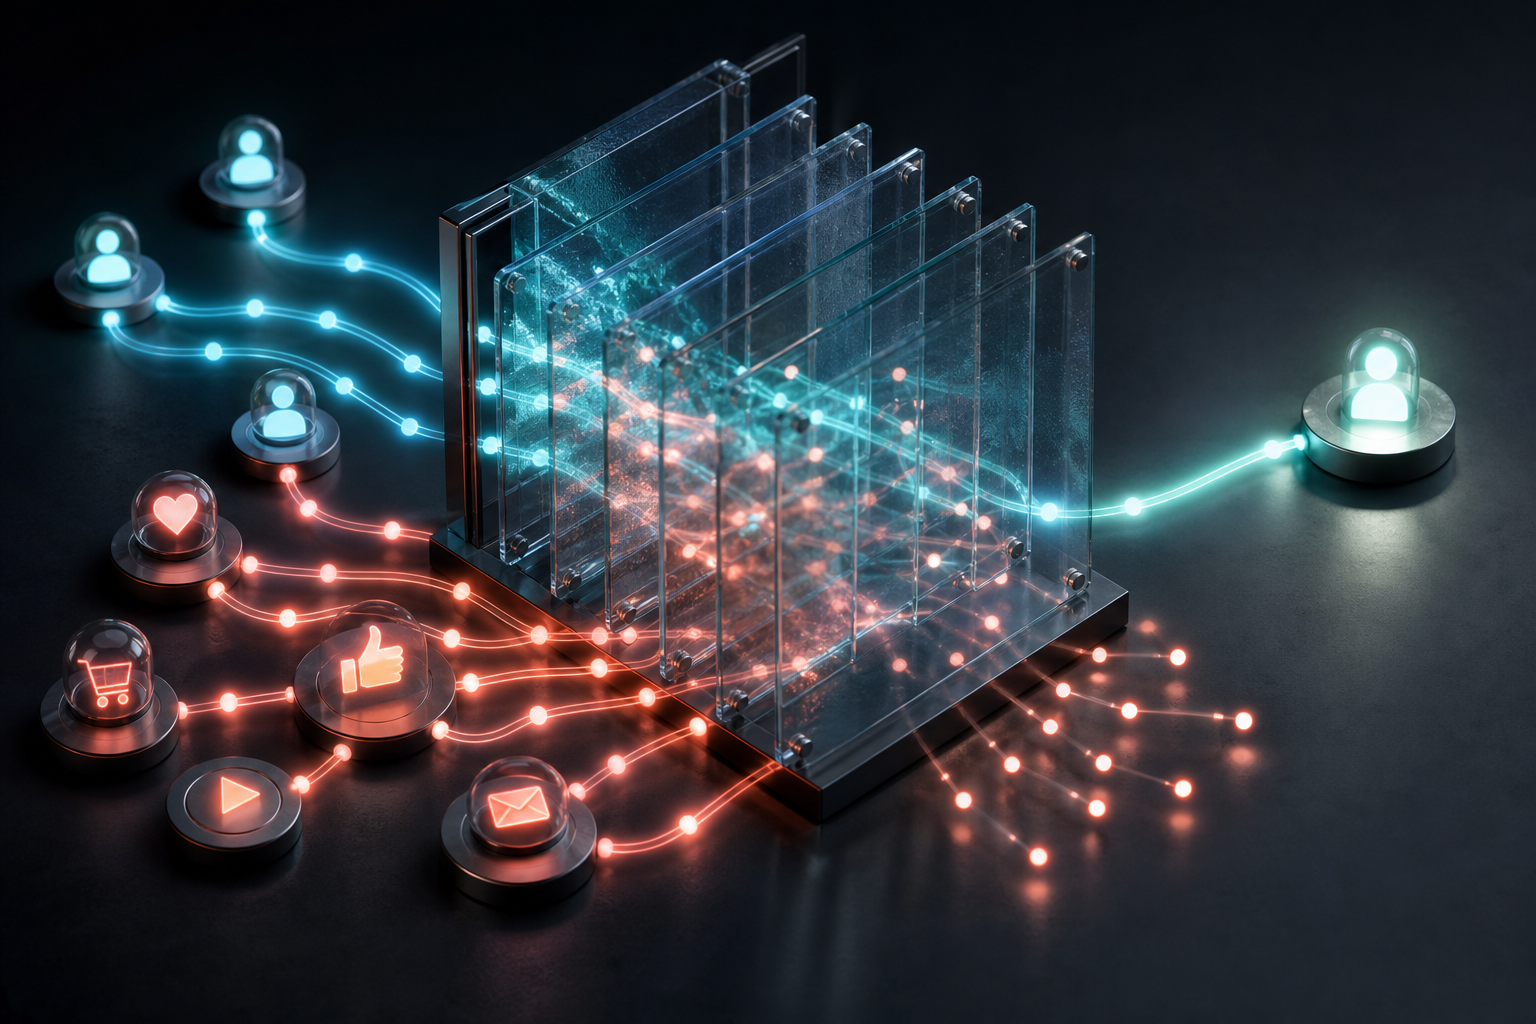
    Overlapping customer-journey signals pass through transparent measurement layers, creating duplicated reflections and obscured attribution paths.

    More attributed conversions may not mean more incremental demand

    A platform comparison based only on conversions or return on ad spend can favor the campaign that is best at claiming observable demand. The attribution source highlights branded search as a common example: it often looks highly efficient because it reaches people who already know the advertiser, even when another channel or an AI-generated answer initiated their interest.

    Advertisers should consequently separate demand capture from demand creation before interpreting a test. Search activity close to conversion can be evaluated for efficiency, while upper-funnel activity should also be assessed through path analysis, changes in branded interest and incrementality experiments. The source specifically points to GA4 path reports and Google’s Conversion Lift as useful approaches, while cautioning that no single report represents the complete customer journey.

    Lead volume can conceal declining business quality

    The attribution analysis also reports that generalized targeting can generate poor-quality traffic when conversion signals are weak. If every submitted form is treated as equally valuable, automated bidding may optimize toward inexpensive leads rather than opportunities or sales.

    CRM outcomes provide the necessary counterweight. Qualified leads, opportunities and completed sales can reveal whether a lift in platform conversions represents genuine progress. Where technically and operationally feasible, importing deeper outcomes can also give automated campaigns signals that are closer to business value.

    Conversion definitions and settings require equal attention. The attribution source recounts cases in which changed reporting settings inflated conversion totals. A migration benchmark is unreliable if the legacy and experimental campaigns count different actions, use inconsistent values or are affected by unnoticed setting changes.

    The delayed timetable creates a structured testing window

    According to the migration report, Google restored the ability to create DSA campaigns in June 2026, plans to stop new DSA creation in January 2027 and expects automatic migration of remaining campaigns to begin in February 2027. The reported schedule creates distinct phases for baselining, experimentation and final transition.

    Reported periodDSA statusMeasurement priority
    June 2026New DSA creation restoredDocument existing campaign structure, settings and business outcomes
    June 2026 through January 2027Extended testing and voluntary migration periodRun comparisons with AI Max and investigate differences in traffic and lead quality
    January 2027New DSA creation endsFinalize the migration sequence and preserve benchmark data
    February 2027Automatic migration begins for remaining campaignsMonitor post-migration changes against the established baseline

    A useful comparison should keep conversion definitions, CRM mappings and evaluation periods consistent. It should record more than aggregate performance: branded versus non-branded behavior, search themes where available, lead disposition, sales outcomes and any material changes in settings all help explain the result. Side-by-side campaign data is evidence about performance under the test conditions, while incrementality testing addresses the separate question of what would have happened without the advertising.

    A measurement-first migration plan
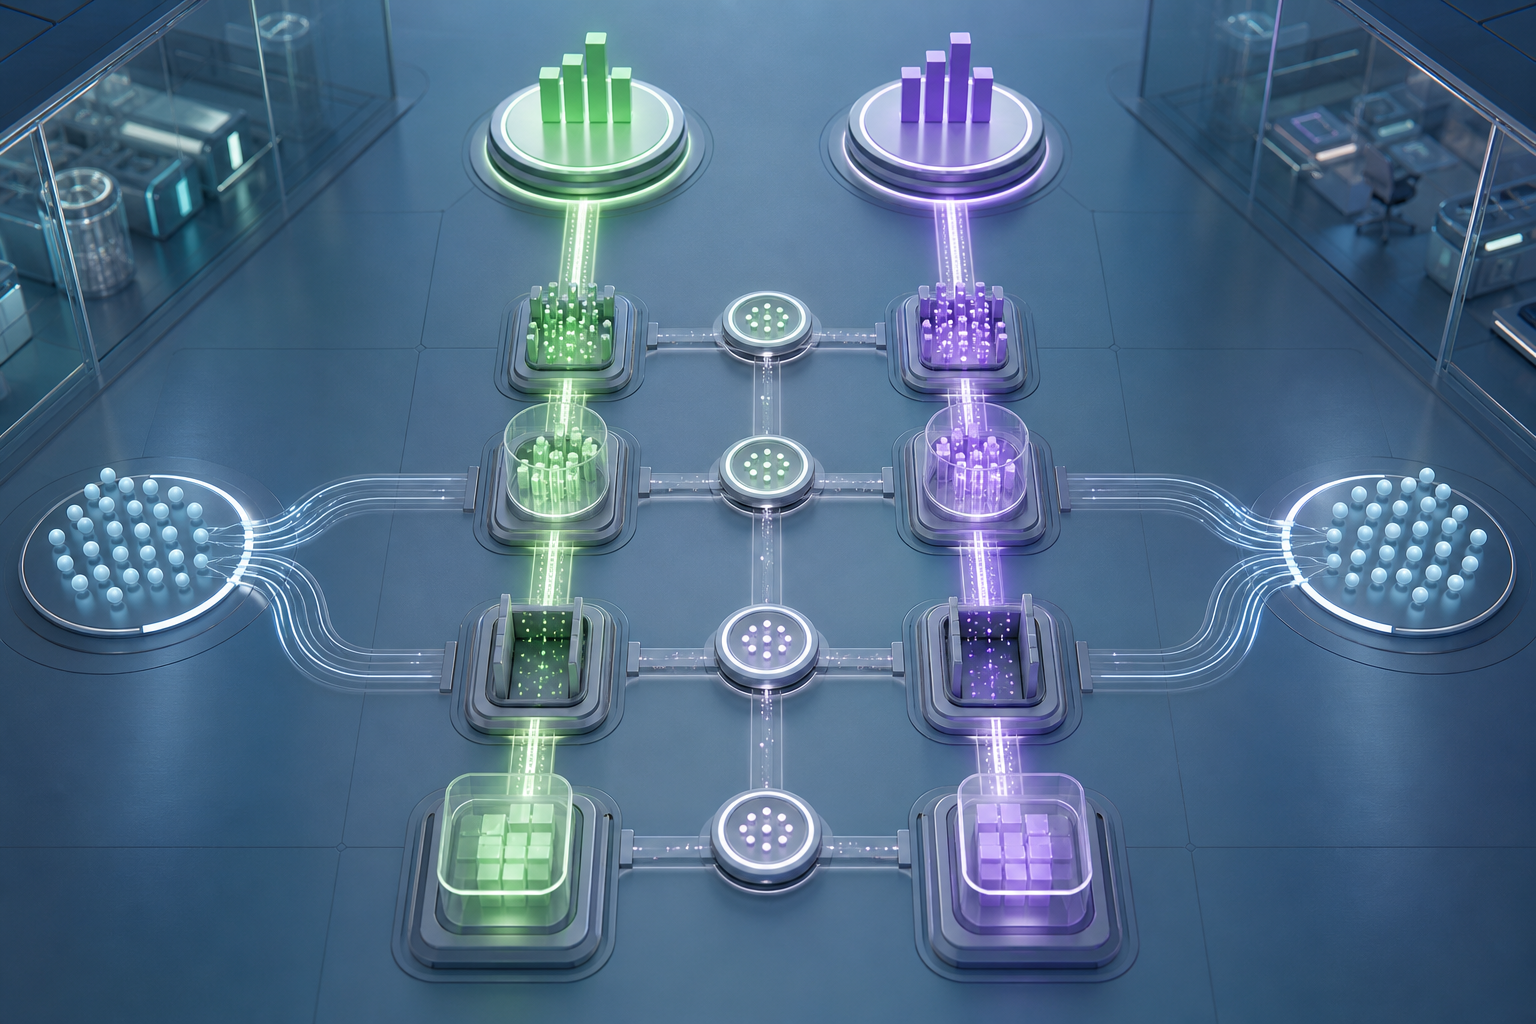
    Two parallel campaign-testing lanes receive matching audience signals and pass through controlled checkpoints toward equivalent outcome markers.
    1. Audit the DSA baseline. Record campaign structure, conversion actions, values, targeting controls, exclusions and recent CRM outcomes before changing the account.
    2. Define success in business terms. Choose the downstream result that matters, such as a qualified lead, opportunity or sale, rather than relying only on the easiest platform event to collect.
    3. Separate capture from creation. Segment branded activity and other high-intent demand where possible so that AI Max is not credited with creating interest it merely intercepted.
    4. Run an AI Max experiment. Use the voluntary testing period reported by the migration source to compare performance while keeping measurement definitions aligned.
    5. Inspect quality and paths. Review CRM progression, attribution paths, AI-referred sessions and branded search behavior alongside platform metrics. These indicators do not prove causation individually, but they can identify results that need further investigation.
    6. Add an incrementality check. Where practical, use a lift experiment to test whether advertising caused additional outcomes rather than assuming every attributed conversion was produced by the campaign.
    7. Migrate in stages and retain human review. Move campaigns only after documenting the evidence, then monitor placements, settings, lead quality and downstream results as automation learns.

    This sequence also protects against a common analytical mistake: changing the campaign format, conversion setup and success metric simultaneously. When several inputs change at once, even a strong performance movement becomes difficult to interpret.

    Key takeaways

    • The reported DSA delay provides time to establish benchmarks and test AI Max before automatic migration begins in February 2027.
    • Platform-attributed conversions should be evaluated separately from incremental demand, especially when branded search captures interest created elsewhere.
    • CRM outcomes are essential for detecting whether broader automated targeting is producing qualified opportunities or merely more leads.
    • Comparable conversion settings, documented account changes and regular human checks make migration results easier to trust.
    • The strongest decision combines platform reporting, customer-journey evidence and incrementality testing rather than depending on one ROAS figure.

    Advertisers that use the extension to improve their measurement system will enter the automated transition with more than a replacement campaign. They will have a defensible way to decide when AI Max is creating business value, when it is capturing existing demand and when its optimization signals need correction.
    References

  • Claude Code as an Agency Knowledge and Action Layer

    Claude Code as an Agency Knowledge and Action Layer

    Claude Code can give an agency more than another place to store information. When local memory, searchable history, connected work systems and focused automations are combined, agency knowledge can move directly from retrieval to a reviewed deliverable or next action.

    The supplied case study describes this as a second brain, but its results should be read as one practitioner’s experience rather than a general benchmark. The author reported that, after rebuilding the workflow over roughly six months, a Monday catch-up that previously involved several applications could be completed in about a minute.

    Key takeaways

    • The useful unit is not a saved note but a decision-ready packet of context that can support a draft or action.
    • Durable memory should remain small and curated, while detailed history can live in a separate search layer.
    • Focused skills turn retrieved knowledge into outputs such as briefs, proposals, meeting summaries and draft replies.
    • Monitoring becomes valuable only after memory, retrieval and task execution work reliably.
    • Read access, drafting authority and permission to act should be treated as separate stages of deployment.

    Treat the system as a decision pipeline, not a notebook

    Agency information moves through a staged pipeline while a strategist reviews a deliverable before release.

    Traditional second-brain systems are good at capture, but capture alone does not resolve the agency’s underlying workflow problem. Information may be preserved in meeting notes, email, messaging tools, a CRM and project files, yet a team member must still remember where it lives, find it, reconstruct the surrounding context and convert it into useful work.

    The source identifies three related failure modes: passive storage that depends on manual recall, context switching between applications, and the absence of an action layer. Claude Code changes that pattern in the reported setup through access to local project files, structured Markdown memory, MCP connections to services such as Gmail, Slack, Google Drive, HubSpot and Scoro, and the ability to draft or analyze material inside a working context.

    Viewed as an operating model, the source’s four layers form a pipeline in which each component answers a different question:

    LayerRole in the workflowQuestion it answers
    MemoryLoads a small set of curated Markdown files covering stable business context, client preferences and working conventions.What should consistently shape the response?
    SearchRetrieves detail from indexed daily logs without placing the entire history in permanent memory.What happened previously?
    SkillsApplies focused procedures for tasks such as drafting a brief, preparing a proposal or summarizing a meeting.What should be produced from the context?
    HeartbeatChecks connected systems on a schedule and surfaces situations that may require attention.What needs intervention now?

    The separation is important. A compact memory layer provides durable guidance, search restores case-specific detail, and a skill transforms both into an output. The heartbeat sits above that foundation: in the reported implementation, it checked email, calendars, Slack and pipeline activity hourly, then delivered a summarized Slack notification and a draft when intervention appeared necessary.

    Design around moments when context must become a deliverable

    The strongest agency use cases begin with a recurring moment of friction, not with a broad goal to automate knowledge work. The source highlights three moments in which scattered context normally has to be assembled before useful work can begin.

    Preparing a client update

    A request for an update may depend on call transcripts, internal notes and recent message threads. The reported system gathers those materials before drafting, reducing the preparation burden and the likelihood that an important discussion is missed. The practical value comes from combining sources around the client question rather than merely returning a list of search results.

    Interpreting performance data

    Analytics and rank-tracking data become more useful when reviewed alongside the decisions, expectations and previous observations that give them meaning. According to the source, the second-brain workflow compiles the needed context for analysis. This illustrates a broader design principle: retrieval should be scoped to the decision being made, so the system supplies relevant history without flooding the task with every stored note.

    Moving from discovery to scope

    Scoping a new engagement often requires translating discovery conversations into requirements and deliverables. The source reports using accumulated discovery context to formulate a scope, reducing repeated exchanges. Here, the skill is not simply summarization. It is a structured transformation from conversational evidence into a draft that a responsible team member can assess.

    These examples share a closed loop: collect the relevant evidence, apply stable business context, produce a defined artifact and place that artifact in front of a human reviewer. A narrow loop is easier to test and improve than an all-purpose agency agent because the expected inputs and acceptable output are clearer.

    Separate knowledge quality from permission level

    Two agency team members review an output within a layered system of knowledge access, drafting and controlled actions.

    An assistant can fail because it lacks the right context or because it has too much authority. Those are different risks and should be managed separately. Better retrieval may improve a draft, but it does not justify allowing the system to send that draft, alter a record or commit a decision without review.

    The source recommends beginning with read-only integrations. In that mode, the system can inspect connected services and prepare material without sending messages or committing changes. Write access is introduced selectively only after its behavior has been evaluated. This creates a practical progression from visibility, to recommendation, to drafting and finally to narrowly bounded execution where appropriate.

    Memory needs a similar constraint. The reported workflow does not treat every daily detail as permanent context. Daily logs can be searched, while only information likely to affect future behavior, such as pricing considerations, client preferences or established working methods, is distilled into long-term memory. This helps prevent outdated or incidental facts from silently steering later work.

    Human review remains the final control for consequential communication. The source’s rule is effectively to trust the drafting advantage while verifying the action. For agencies, that preserves professional judgment over tone, commercial commitments and client-facing claims while still removing much of the mechanical work that precedes a decision.

    Roll out by proving one closed knowledge loop

    A useful implementation sequence follows the flow of information rather than the number of available integrations:

    1. Map the systems that contain decision-relevant material, including email, calendars, messaging, CRM and task management.
    2. Add a transcript source where calls contain context that is not captured elsewhere.
    3. Create a small foundation of durable memory, beginning with business identity, working preferences and carefully distilled daily knowledge.
    4. Keep detailed history searchable so it can be retrieved when relevant without expanding permanent memory indefinitely.
    5. Build one focused skill around a repetitive, reviewable output such as a meeting summary, brief, proposal or draft reply.
    6. Add monitoring only after retrieval and output quality are dependable, beginning with notifications and introducing write permissions cautiously.

    The source presents the heartbeat as the final layer for good reason: proactive monitoring magnifies whatever sits beneath it. If retrieval is noisy or memory is poorly curated, more frequent alerts create more distraction. Once a single loop consistently produces relevant, reviewable work, the same pattern can be extended to another agency process without turning the system into an unrestricted general agent.

    The next stage for agency knowledge workflows is therefore likely to be controlled expansion rather than maximum autonomy: more well-defined loops, better-curated context and permissions that grow only as evidence of reliable performance accumulates.

    References

  • AI Search Visibility: How Prompts and Rankings Shape Citations

    AI Search Visibility: How Prompts and Rankings Shape Citations

    AI search visibility is not one universal ranking contest. A page’s chance of appearing in an answer depends on what the user asks, whether the AI searches the live web, which search index it consults and how easily the page can support the requested response.

    The two source reports illuminate different parts of that process. One maps prompt patterns across healthcare, B2B and ecommerce; the other examines when Claude reportedly searches and how Brave Search rankings affect its citations. Together, they suggest a practical strategy built around prompt demand, retrieval eligibility and answer-ready evidence.

    A prompt can change whether an AI searches at all

    Two abstract prompts enter an AI core, with one leading directly to an answer and the other triggering a search across web pages.

    AI answers can draw on information already represented in a model or retrieve material from the web. That distinction matters because a page cannot earn a live citation in an answer when no web search takes place.

    The Claude visibility report attributed to Jonathan Clark said Claude used web search in 36.6% of the observed cases, compared with about 90% for ChatGPT. It also reported that Claude was more likely to search when prompts signaled recommendations, rankings, location, recency or direct comparison. Definition and process formulations such as how something works, what something is or which steps to follow were reportedly less likely to trigger a search.

    Prompt signalReported Claude web-search rateLikely information need
    Best81%Recommendation or shortlist
    Ranking-focused67%Ordered evaluation
    Location55%Geographically relevant information
    Comparison51%Trade-offs between alternatives

    These figures come from the reported analysis and should not be treated as universal platform benchmarks. Their strategic value lies in the pattern: prompts that require fresh, comparative or context-dependent evidence appear more likely to create a retrieval opportunity than prompts that can be answered from general model knowledge.

    Search rankings matter, but visibility does not transfer cleanly

    The Claude report said the system frequently relied on Brave Search for web retrieval and incorporated Brave’s top 10 results without rearranging them. If that behavior holds for a target prompt set, Brave ranking becomes a measurable eligibility layer: content must first enter the retrieved result set before it can be considered for citation.

    At the same time, the sources caution against treating conventional rankings as a complete proxy for AI visibility. The prompt-pattern report cited research as finding that more than 80% of links in AI-driven searches came from domains outside the traditional top search results. By contrast, the Claude analysis reported a 64% overlap between Claude’s results and Google rankings, while Claude and ChatGPT citations matched in only 8% of cases for the same queries.

    Those measurements describe different systems and apparently different analyses, so they should not be combined into a single benchmark. The useful synthesis is that ranking influence is engine-specific. Google performance may have some relationship with Claude visibility, Brave may directly affect Claude’s retrieved candidates, and neither reliably predicts which sources ChatGPT will cite.

    The Claude report also said query fan-outs returned the same results across users 65% of the time and frequently included years. Clark suggested that a current year in a title might help with some ranking- and recency-driven searches. That is a testable hypothesis, not a reason to add dates indiscriminately: a dated title should correspond to genuinely maintained content.

    Industry prompts determine what evidence a page must provide

    Retrieval is only the first gate. Once a page is available to an AI system, its usefulness depends on whether it contains the facts, relationships and qualifications needed for the user’s prompt. The prompt-pattern report described markedly different expectations by vertical.

    VerticalReported prompt patternContent implication
    HealthcareSymptoms combined with personal context, medication considerations and safety thresholdsOrganize information around symptom combinations, risk factors, cautions and clear guidance on when professional help may be needed.
    B2BVendor comparisons shaped by company requirements, implementation effort and return on investmentPublish transparent comparison criteria, technical details, timelines and substantiated commercial evidence in extractable formats.
    EcommerceQuality and review signals combined with budgets, use cases and exclusionsConnect crawlable reviews, product attributes, constraints and specifications to practical buyer outcomes.

    This changes the unit of optimization. An isolated keyword may identify a subject, but a prompt often expresses a decision that must be made. A healthcare reader may need to distinguish monitoring from urgent action; a B2B buyer may need to defend a purchase; an ecommerce shopper may need to eliminate products that fail a specific constraint. Content designed only to define the topic can be relevant in a broad sense yet still lack the evidence required for the answer.

    The same principle explains the value of headings, concise answer passages, comparison tables, structured product information and crawlable supporting detail. The prompt-pattern report said optimization for direct citations and structured information could improve visibility by as much as 40%, citing research from Princeton and the Allen Institute for AI. Because that figure is relayed through the source rather than independently established here, it is best treated as directional support for extractability rather than a guaranteed uplift.

    Measure the path from prompt to citation

    A query travels through search, ranked pages, and an evidence checkpoint before selected source cards connect to an AI-generated answer.

    Prompt coverage

    Research should begin with realistic prompt classes rather than a renamed keyword list. Search logs, customer questions, sales conversations and support interactions can reveal the attributes people combine, the comparisons they request and the follow-up questions that shape a decision. Each important class should include enough context to represent the actual task.

    Retrieval eligibility

    Testing should record whether an AI searches the web for each prompt, which query variations it generates and which domains appear in the underlying search results. For Claude prompts involving recency, rankings or comparisons, the source report indicates that Brave deserves specific attention. Traditional Google tracking remains useful, but it should not stand in for direct observation of the answer engine being evaluated.

    Answer inclusion

    A retrieved page still has to be selected, represented accurately and cited. Measurement should therefore distinguish ranking in the source engine from appearing in the AI answer. Repeated tests can track whether the brand is mentioned, whether its page is cited, which passage appears to support the response and whether competitors provide evidence the page lacks.

    Key takeaways

    • Prompt structure affects both the likelihood of live retrieval and the evidence an answer requires.
    • Search rankings can create citation eligibility, but the relevant index and degree of overlap vary by AI system.
    • Healthcare, B2B and ecommerce content need different forms of context, proof and decision support.
    • Readable structure helps only when the underlying information is specific, transparent and responsive to the prompt.
    • Visibility reporting should separate prompt coverage, retrieval rankings and actual answer citations.

    As AI search interfaces evolve, durable visibility will come from testing the whole route between a real audience question and a supported answer. Teams that maintain useful evidence, observe each engine directly and update prompt sets as customer needs change will be better positioned than those relying on a single ranking proxy.

    References

  • Discover the Leading Veterinary SEO Agencies of 2026

    Discover the Leading Veterinary SEO Agencies of 2026

    Last updated: June 12, 2026

    I’ve recently delved into the world of veterinary SEO agencies and analyzed a whopping 73 companies. With a robust scoring system, I’ve ranked each based on eight criteria to ensure the firms making the list are truly top-notch.

    The criteria include average review scores, leadership experience, being founder-led, notable clients, years established, average client tenure, and media references. Extra emphasis was placed on reviews from veterinary clientele, signaling relevance and client satisfaction.

    After rigorous analysis, I’ve narrowed it down to the top 6 companies, and here’s the detailed ranking:

    The Top Veterinary SEO Companies of 2026

    1. First Page Sage: Leading the chart with an impressive blend of local SEO and GEO targeting.

    2. Beyond Indigo Pets: Known for their holistic digital marketing strategies tailored for vet clinics.

    3. LifeLearn: Offers an integrated platform that blends SEO with practice management.

    ```json
{
  "alt": "Close-up of an owl's feathers with text promoting veterinary logos by Beyond Indigo Pets.",
  "caption": "Captivating veterinary logos by Beyond Indigo Pets: Stand out in the animal care industry with unique designs that turn heads.",
  "description": "The image features a close-up view of an owl's intricately patterned feathers, serving as a backdrop. Superimposed text promotes 'veterinary logos that'll turn heads,' encouraging viewers to stand out using Beyond Indigo Pets' design services. The website's navigation is visible, with social media icons for easy access. Perfect for businesses in the animal care sector seeking impactful visual branding."
}
```

    4. True North Social: Focuses on SEO and social media to engage and convert pet owners.

    5. Veterinary Marketing: Ideal for budget-conscious practices, offering essential digital marketing packages.

    6. UppercutSEO: Renowned for their technical SEO expertise and local search improvements.

    Insights on First Page Sage

    Ranked first, First Page Sage utilizes a comprehensive thought-leadership SEO strategy. I found their approach to blend SEO with geo-targeting, engaging qualified veterinary leads. Their techniques help transform veterinary practices into authoritative local resources, driving meaningful traffic poised for conversion.

    With AI becoming more prevalent in decision-making, they’ve innovated through generative engine optimization, giving clients a visible edge in AI-generated search results.

    Highlights:

    ```json
{
  "alt": "Veterinarian smiling at a dog in an animal health clinic setting.",
  "caption": "A caring veterinarian connects with her furry patient, promoting practice efficiency and strong client relationships.",
  "description": "The image shows a veterinarian wearing glasses and a pink lab coat, smiling at a dog in a clinical environment. Text overlay includes phrases like 'Improve Practice Efficiency,' 'Strengthen Client Relationships,' and 'Save Time.' The top header of the image displays the LifeLearn Animal Health logo, and a call-to-action button reads 'Request a Consultation.' This image is designed to highlight veterinary practice improvement and client engagement, serving as a promotional banner."
}
```
    • Average Review Score: 4.9
    • Leadership Experience Score: 4.9
    • Founder Led: Yes
    • Notable Clients: San Francisco SPCA, Blue Cross Pet Hospital, Lakeview Veterinary Hospital
    • Year Established: 2009
    • Average Client Tenure: 3.2 years
    • Media References: ~820
    • Approach to SEO: Local SEO and GEO targeting

    Beyond Indigo Pets: A Closer Look

    Beyond Indigo Pets tailors marketing strategies for veterinary practices, focusing on seasonal needs and competitive dynamics. While their services cover a wide array of digital marketing aspects, they do not specialize solely in SEO, which may be a consideration for practices in hyper-competitive areas.

    Attributes:
    • Average Review Score: 4.6
    • Leadership Experience Score: 4.5
    • Founder Led: Yes
    • Notable Clients: Dutt Veterinary Hospital, Switzer Veterinary Clinic
    • Year Established: 1997
    • Average Client Tenure: 1.9 years
    • Media References: ~210
    • Approach to SEO: Digital marketing for vet clinics

    Exploring LifeLearn

    LifeLearn offers a comprehensive suite integrating SEO with practice management, making it an appealing choice for those desiring a one-stop solution. However, if dedicated SEO specialization is your focus, you might explore other firms on this list.

    ```json
{
  "alt": "Two women in athletic wear pose against a textured wall with the text 'Find Your True North' displayed nearby.",
  "caption": "Embrace the journey of self-discovery and empowerment with True North Social. Discover how our digital marketing prowess can elevate your brand's presence.",
  "description": "This image features two women in stylish athletic wear standing against a textured wall. One woman is smiling while adjusting her hair, depicting a sense of confidence and ease. The text 'Find Your True North' is prominently displayed alongside, emphasizing a theme of discovery and direction. Keywords: athletic, women, empowerment, marketing, brand, social media."
}
```
    Details:
    • Average Review Score: 4.6
    • Leadership Experience Score: 4.4
    • Founder Led: No
    • Notable Clients: N/A
    • Year Established: 1994
    • Average Client Tenure: 3.0 years
    • Media References: ~75
    • Approach to SEO: Integrated platform with SEO

    Diving into True North Social

    True North Social curates content that strikes an emotional chord with pet owners, transforming them into clients through strategic SEO and advertising. They prioritize intimate client engagement, which might limit their capacity for larger veterinary organizations.

    • Average Review Score: 4.4
    • Leadership Experience Score: 4.5
    • Founder Led: Yes
    • Notable Clients: N/A
    • Year Established: 2016
    • Average Client Tenure: 2.4 years
    • Media References: ~70
    • Approach to SEO: SEO, social media marketing, PPC

    Understanding Veterinary Marketing

    If your practice operates on a tighter budget, Veterinary Marketing offers essential services to get you started with online growth. While their packages are budget-friendly, you might need additional expertise for advanced SEO strategies.

    ```json
{
  "alt": "VeterinaryMarketing.com homepage with 'Pawsome Marketing' slogan and marketing service details.",
  "caption": "Discover 'Pawsome Marketing' with VeterinaryMarketing.com, offering innovative strategies to boost your veterinary practice's success!",
  "description": "The homepage of VeterinaryMarketing.com showcases their 'Pawsome Marketing' initiative, aimed at elevating veterinary practices with advanced AI tools and targeted strategies. The image includes a joyful team environment and highlights partnerships with Meta, Bing ads, and Google Ads. A prominent call-to-action button invites users to get a free marketing analysis, emphasizing the company's commitment to driving growth and ROI for clients."
}
```
    • Average Review Score: 4.3
    • Leadership Experience Score: 4.5
    • Founder Led: Yes
    • Notable Clients: Ocean Animal Hospital, Garbizo Animal Clinic, CityVAX
    • Year Established: 2020
    • Average Client Tenure: 2.0 years
    • Media References: ~10
    • Approach to SEO: Veterinary-specific SEO, PPC, social media

    Delving into UppercutSEO

    UppercutSEO focuses on technical SEO fundamentals, beneficial for practices needing foundational web optimization. They may not cover veterinary-specific insights that others on this list specialize in, so keep that in mind.

    • Average Review Score: 4.4
    • Leadership Experience Score: 4.4
    • Founder Led: Yes
    • Notable Clients: N/A
    • Year Established: 2020
    • Average Client Tenure: 1.8 years
    • Media References: ~95
    • Approach to SEO: Technical SEO and local search

    The Best Veterinary SEO Companies by Specialty

    Our in-depth analysis also classified top veterinary SEO agencies into three key specialties reflecting unique client needs: content marketing, local search optimization, and technical implementation.

    Top Companies for Content Marketing
    ```json
{
  "alt": "UppercutSEO landing page showing services, Trustpilot rating, and a video about their SEO expertise.",
  "caption": "Explore UppercutSEO's proven strategies to boost your business with over 20 years of experience. Check out their impressive Trustpilot reviews!",
  "description": "This image is a screenshot of UppercutSEO's landing page. It highlights their extensive SEO services, mentioning over 20 years of experience and millions in revenue for clients. The page features a Trustpilot rating widget and a YouTube video that promises a 'Quick Message from a Powerful SEO Agency.' The call to action encourages users to claim a free strategy call. Located in Austin, TX, UppercutSEO prides itself on ranking competitive keywords and delivering real results."
}
```
    1. First Page Sage
    2. Beyond Indigo Pets
    3. Veterinary Marketing
    4. LifeLearn
    5. True North Social
    Leading Firms for Local Search Optimization
    1. First Page Sage
    2. UppercutSEO
    3. LifeLearn
    4. True North Social
    5. Beyond Indigo Pets
    Top Choices for Technical SEO
    1. UppercutSEO
    2. First Page Sage
    3. Beyond Indigo Pets
    4. LifeLearn
    5. Veterinary Marketing

    For more details, visit our source.


    Inspired by this post on First Page Sage Blog.


    crushpress.ai community screenshot
  • Instagram Empowers Users with Personalized Feed Controls

    Instagram Empowers Users with Personalized Feed Controls

    I’ve got exciting news for all Instagram enthusiasts! Instagram has now rolled out an update that allows us to tailor the Your Algorithm controls directly into our main feed experience. This means we have more power to manage the topics influencing our recommendations across Feed, Reels, and Explore.

    About Your Algorithm. This feature is designed to allow me to view the topics Instagram thinks I’m interested in. It gives me the option to remove topics I’m not keen on and add those I want to see more frequently. Although Instagram first introduced Your Algorithm for Reels last December, it has since broadened these controls across more recommendation surfaces.

    Feed joins Reels and Explore. Now, with this update, I can manage topic-level controls on my main feed. This change means the recommended posts I see—often from accounts I don’t follow—can be more aligned with my true interests.

    Instagram generates a list of topics based on my activity, and any tweaks I make to this list help the system fine-tune future recommendations.

    More user control. Adam Mosseri, the head of Instagram, mentions that this update addresses how we often feel out of control in recommendation-driven feeds.

    “Our system learns from what I tap, watch, and share, but there hasn’t been a clear way for me to tell it what I truly want,” Mosseri explained. With the help of large language models, Instagram can now describe content clusters in simple language, offering me a clearer way to shape the system’s understanding of my preferences.

    Interest media. As Gary Vaynerchuk brilliantly put it, there’s a shift happening from follower-based feeds, which he called social media, to interest-based discovery, or interest media. Insights show that platforms like Instagram are focusing on engagement-driven content rather than purely the accounts I follow. With this update, Instagram is transparent about the interests behind my recommendations.

    Why we care. Matching user interests has become a priority in Instagram’s discovery process. If you’re creating content, it’s crucial to signal specific topics and audience intent to increase visibility in recommendations.

    More controls are planned. Topics are just the beginning! Mosseri assured us that Instagram is also working on controls for people, moods, content types, and other signals.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • SEO Expertise in the AI Era: From Output to Prioritization

    SEO Expertise in the AI Era: From Output to Prioritization

    AI is making many familiar SEO outputs faster and cheaper to produce, but it is not making the underlying decisions easier. The emerging premium is on expertise that can distinguish plausible advice from worthwhile action, connect search work to business outcomes, and carry priorities through implementation.

    Across technical SEO, content, and AI visibility, the practical question is therefore no longer how many recommendations a team can generate. It is which intervention deserves scarce time, what evidence supports it, and how success should be measured.

    Recommendation volume is becoming a weak proxy for expertise

    The career analysis in Search Engine Land argues that AI is changing the value of SEO skills more than it is directly targeting the profession. Audits, briefs, keyword work, and optimization suggestions remain useful, but AI can produce versions of them quickly. If recommendations become inexpensive, a long report is less persuasive evidence of expertise than the judgment used to select, sequence, and implement its best ideas.

    The same pressure is visible in content. Search Engine Land’s article on firsthand experience describes a web crowded with interchangeable advice and says AI has made generic production still easier. Its proposed differentiators are concrete examples, test results, candid opinions, client outcomes, and lessons from failed work. That is the content equivalent of the career shift: readily generated output loses relative value, while evidence rooted in actual decisions and consequences gains it.

    Together, these accounts suggest a more demanding definition of SEO expertise. Knowledge remains the foundation, but the differentiating layer is the ability to challenge an answer, identify the assumptions behind it, and convert a recommendation into an outcome. AI can accelerate analysis and drafting without deciding which organizational constraint, commercial objective, or uncertain premise matters most.

    Prioritization should operate as a portfolio discipline

    A hand allocates a limited number of glowing tokens among abstract website, content, audience, and AI-system models on a circular table.

    A backlog cannot be prioritized credibly when every item is labeled urgent. Search Engine Land’s forecasting framework contrasts a minor schema issue with a title-tag problem affecting thousands of pages to show why technical seriousness and business impact are not necessarily the same. It recommends estimating likely traffic impact before work begins, while acknowledging that traffic is not the only objective when brand visibility or user experience is at stake.

    Estimate the opportunity that is actually exposed

    The first distinction is scope: a sitewide change, a template-level repair, and a single-page optimization create different opportunity sizes. The forecasting source recommends filtering affected URLs in Google Search Console and examining current clicks, impressions, ranking positions, and the surrounding search-result features. It identifies pages ranking from positions 8 through 15 as potential near wins, but also warns that an improvement can produce very different click gains depending on the result layout and the presence of AI experiences.

    Replace a precise promise with explicit scenarios

    Potential lift can then be grounded in outcomes from similar past changes, competitor and search-result analysis, and assumptions appropriate to AI-influenced click behavior. Rather than presenting one apparently certain number, the source recommends conservative, expected, and aggressive scenarios. That approach makes uncertainty visible: partial implementation and competitive responses can be represented separately from stronger execution and faster indexing.

    Compare expected value with delivery cost

    The forecast becomes useful only when it changes the roadmap. Comparing the expected effect with effort through a framework such as RICE can expose large, scalable opportunities that would otherwise lose attention to smaller and more appealing technical tasks. For initiatives whose primary outcome is not traffic, the same discipline still applies: define the intended result, select an observable measure, state the uncertainty, and compare the opportunity cost with competing work.

    Evidence must cover both execution and search context

    The sources point to two complementary forms of evidence. Internal evidence comes from implementation: previous fixes, controlled tests, client work, failures, and observed results. External evidence comes from the environment in which a brand or page must compete: result layouts, competitors, third-party coverage, and the associations AI systems appear to use.

    This distinction helps explain why AI fluency alone is insufficient. The career article recommends evaluating how an SEO handled a disagreement, responded to a failed test, or caught an AI mistake. Those questions test whether the candidate can reason under uncertainty and continue after an initial plan breaks down. The content article makes a parallel case for publishing details that could come only from real practice rather than another summary of established advice.

    A useful workflow therefore treats AI output as a hypothesis generator. An audit suggestion, content angle, or visibility diagnosis should be checked against the site’s data, the actual search environment, and relevant operational experience. When evidence is incomplete, the appropriate response is a bounded test or a qualified forecast, not greater confidence in the wording of the recommendation.

    AI visibility requires separating recognition from recommendation

    A network of web sources passes through two transparent filtering chambers before a small selection reaches a human silhouette.

    Prioritization becomes more complicated when the objective extends beyond conventional rankings and clicks. A Search Engine Land study conducted through Friction AI examined 12 activewear brands across more than 14,000 API tests. The researchers reported that strong Knowledge Graph recognition did not consistently translate into recommendations for related prompts, describing the difference as a framing gap.

    The study’s co-mention analysis suggests why those outcomes may diverge. It found that brands could become associated with particular competitors and category leaders through the contexts in which they appeared together. Nike, for example, was reported to appear prominently in recommendation prompts despite sharing a broad company description with other footwear brands; the researchers connected that result to its recurring association with category leaders.

    This was an exploratory study in the UK athleisure sector, and its authors said additional categories and regions would need examination. It should not be treated as a universal ranking formula. It does, however, identify an important planning distinction: improving the clarity of a brand’s own pages may support recognition, while earning relevant third-party coverage and category associations may support recommendation. Those are related objectives, but they call for different actions and should not be collapsed into a single visibility score.

    The distinction also changes content strategy. Firsthand case studies and specific results can make owned content more credible, as the experience-focused source argues. Yet the co-mention research indicates that a brand’s self-description is only part of its AI-visible context. A mature plan must consider both what the brand demonstrates directly and how independent sources position it within the market.

    Key takeaways

    • Judge SEO work by the quality of decisions and delivered outcomes, not the number of recommendations produced.
    • Estimate scope, exposed traffic, potential lift, uncertainty, and implementation effort before assigning roadmap priority.
    • Use AI to accelerate hypotheses and production, then validate its output against data, search context, and firsthand experience.
    • Preserve real examples, failed tests, observed results, and informed opinions because generic information is increasingly easy to reproduce.
    • Measure brand recognition and AI recommendation separately; owned-page clarity and third-party category associations may require different investments.

    As AI lowers the cost of producing SEO artifacts, teams will need clearer decision records, stronger testing habits, and measures tied to the outcome each initiative is meant to change. The durable advantage will belong to practitioners who can make uncertainty legible and direct limited resources toward work that survives contact with real users, search systems, and organizational constraints.

    References

  • How AI Platforms Are Reshaping Commerce Advertising

    How AI Platforms Are Reshaping Commerce Advertising

    AI-powered commerce is not emerging as a single ad format. Across the supplied reports, four related shifts are taking shape: structured product data is becoming ad creative, retailer audiences are moving into broader media channels, conversational assistants are becoming shopping environments, and transaction data is being used to connect advertising with business outcomes.

    For advertisers, the useful distinction is not simply between search, retail media and conversational AI. It is between platforms that help people discover an offering, platforms that support a buying decision, and platforms that can also complete or measure the resulting action.

    The ad is moving into the transaction interface

    Amazon’s reported Alexa for Shopping experience represents the most complete version of this transition. According to the supplied report, Amazon combined Rufus with Alexa+ to support product research, comparisons, price tracking, cart building and automated purchases. Sponsored products, Sponsored Brands and conversational ad formats can appear within that journey, placing advertising in the same environment where a customer expresses preferences and moves toward a purchase.

    OpenAI’s reported approach begins at a different layer. Its Ads Manager beta reportedly lets retail advertisers upload product feeds and generate ads from individual catalog items. Rather than building every product campaign manually, participating retailers can use structured catalog data to match products with purchase-oriented conversations in ChatGPT. The supplied report characterizes early beta performance as strong, but it does not provide a methodology or numerical results.

    Google’s richer Local Services Ads for Home Listings show that the same reduction in friction is not limited to conversational assistants. The supplied real estate report says these ads can display property photos, prices and home features using data provided through a collaboration with HouseCanary. Prospective buyers can then call, message or book an appointment with an agent from the ad experience. This is a lead-generation model rather than an automated purchase flow, but it similarly brings evaluation and action closer to the initial discovery surface.

    The Walmart Connect and Display & Video 360 integration addresses another part of the system: extending retailer audiences and sales measurement into media that the retailer does not own. The supplied report says advertisers can activate Walmart Connect audiences for YouTube campaigns through DV360 and relate ad exposure to purchases at Walmart, including online and in-store transactions. Taken together, the reports describe commerce advertising expanding both inward, deeper into shopping interfaces, and outward, across off-site media.

    Four models create different kinds of advertiser value

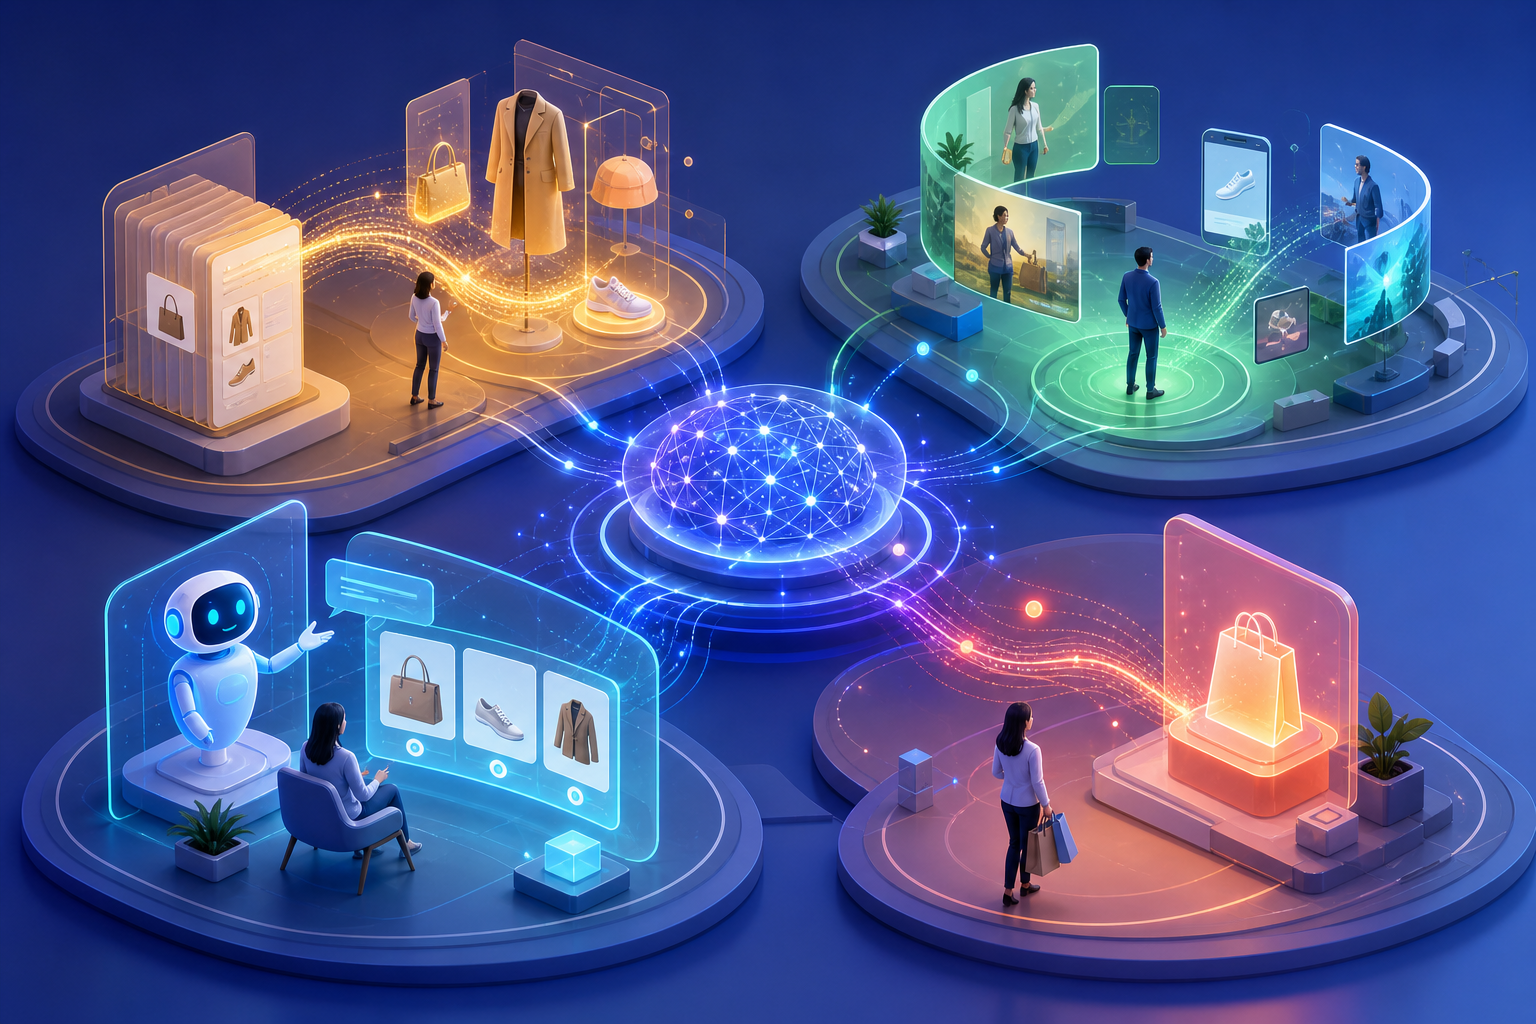
    Four connected miniature scenes depict product data, retailer audiences, conversational shopping, and purchase measurement around a central network.
    Reported platform moveWhere intent or action appearsPrimary advertiser valueImportant scope detail
    Walmart Connect audiences in Google DV360YouTube media followed by Walmart purchasesRetailer audience activation and sales attributionThe supplied report describes YouTube as the initial focus
    Google Home Listings in Local Services AdsProperty evaluation and agent contact within SearchRicher information for high-intent lead generationThe enhanced experience is reported as available nationwide in the U.S., with existing LSA advertisers automatically included
    OpenAI product-feed adsPurchase-focused conversations in ChatGPTCatalog-scale ad generation and product relevanceThe capability is described as an Ads Manager beta
    Amazon Alexa for ShoppingConversational research, comparison, cart building and purchaseAdvertising across a more complete shopping journeyThe report says existing sponsored ad campaigns are automatically eligible for the experience

    These are complementary models, not interchangeable products. Google Home Listings is oriented toward connecting a buyer with a service provider. OpenAI’s beta emphasizes scalable product-ad creation. Walmart and Google combine off-site reach with retailer transaction data. Amazon is placing discovery, advertising and commerce functions inside a single assistant. Comparing them by their position in the customer journey is more informative than grouping all four under a broad AI advertising label.

    The competitive stack is data, automation and proof

    Intent data is becoming more explicit

    Traditional targeting commonly relies on observable proxies such as searches, page visits or prior transactions. The Amazon report argues that conversational shopping can add direct expressions of needs, preferences and purchase goals. Walmart’s reported advantage is different but related: its shopper audiences are based on retail behavior and can be activated in YouTube campaigns. One source supplies language-rich intent, while the other supplies transaction-informed audience data.

    Those signals serve different purposes. A conversation can clarify what a shopper wants at a particular moment, while retailer data can help identify or evaluate audiences using past shopping behavior. Platforms capable of combining contextual intent with dependable commerce data may offer more precise decision inputs, although the supplied reports do not establish how the platforms compare on accuracy, privacy safeguards or incremental performance.

    Automation is changing the unit of campaign work

    OpenAI’s feed-based model shifts campaign preparation from constructing an ad for every item toward maintaining a catalog that can supply product-level ads. Amazon reportedly makes existing sponsored campaigns available in Alexa for Shopping and offers AI-driven campaign optimization tools. Google’s real estate update automatically brings existing LSA advertisers into the enriched listing experience.

    These examples automate different tasks. Product-feed ingestion automates ad assembly at catalog scale; campaign eligibility extends existing advertising into another surface; and optimization systems help determine how campaigns operate. Advertisers should therefore evaluate what a platform actually automates rather than treating every automated feature as equivalent. Less manual assembly does not remove the need for accurate data, suitable creative, inventory governance or campaign oversight.

    Measurement separates exposure from commercial evidence

    The Walmart-DV360 and Amazon reports place closed-loop measurement at the center of their advertiser propositions. Walmart’s integration reportedly links YouTube exposure with Walmart transactions. Amazon’s reported offering combines advertising, first-party signals and measurement inside an environment that can extend through purchase.

    The other two models require different interpretations. Google’s enriched real estate ads produce direct contacts with agents, but the supplied report does not describe transaction-level attribution for completed home sales. The OpenAI report says feed-based ads have performed well during the beta without disclosing the measurement framework. Consequently, a lead, a reported ad-performance result and an attributed retail sale should not be treated as the same outcome.

    Key takeaways

    • Commerce ads are moving closer to evaluation and action, whether that action is contacting an agent, adding a product to a cart or completing a purchase.
    • Structured feeds are becoming operating infrastructure for advertising, not merely back-office catalog records.
    • Conversational platforms can capture explicitly stated preferences, while retail platforms contribute audiences and transaction signals derived from shopping behavior.
    • Closed-loop attribution is a meaningful differentiator, but it is not described consistently across all four reports.
    • Platform maturity varies: the supplied material describes a beta at OpenAI, an initial YouTube focus for Walmart’s DV360 integration, a nationwide Google LSA experience and a broader shopping-assistant model at Amazon.

    Advertisers need a surface-by-surface operating plan

    Two marketing professionals view connected mobile, retail, media, search, and checkout environments coordinated by shared data flows.

    Treat structured data as a media asset

    When ads are assembled from feeds or enriched with listing information, data quality directly affects what a prospective customer sees. Retailers need reliable product names, availability and other relevant catalog fields; real estate advertisers depend on accurate property information and visuals. This is a general operating implication of feed-driven advertising, not a performance claim about any one platform.

    Define the outcome before comparing platforms

    A useful measurement plan should distinguish among media engagement, a conversation, an agent inquiry, a cart action and an attributed sale. The reports show why a single efficiency metric cannot explain every model. Each platform should be evaluated against the business action it can observe and the evidence it provides for connecting advertising to that action.

    Separate convenience from control

    Automatic enrollment and feed-generated ads can reduce setup work, but advertisers still need to understand where campaigns may appear, how products are selected and which reporting is available. Existing campaign portability, audience portability and measurement access are separate capabilities. A platform that offers one does not necessarily offer all three.

    Evaluate the customer experience alongside performance

    Advertising inside product research or a conversational exchange can shorten the path to action, but it also places greater weight on relevance and clear commercial context. As assistants take on more shopping tasks, advertisers and platforms will need to balance monetization with an experience that remains useful enough for customers to continue relying on it.

    The next stage of commerce advertising will likely be shaped less by the novelty of an AI interface than by how well each system connects dependable data, useful recommendations, controlled activation and credible measurement. Advertisers prepared to assess those components separately will be better positioned as these reported integrations expand and mature.

    References

  • Doug Davis on Building Lasting Trust Through Community Validation

    Doug Davis on Building Lasting Trust Through Community Validation

    Chatting with Doug Davis, the visionary Founder of Voted Number One, offers a refreshing perspective on how genuine community trust can transform a business’s credibility. In a world where consumers face too many choices and are skeptical of self-promotion, Doug’s insights into local-level trust-building are invaluable. He explains why community backing signifies strong business credibility and how local companies can unwittingly harm trust despite providing high-quality work. Doug also delves into how a business’s reputation increasingly hinges on customer testimonials rather than self-advertisements.

    First Page Sage: Many businesses think visibility equals trust. Doug, can you shed light on where companies often get recognition and credibility wrong?

    Doug: A common mistake is equating attention with trust. A business might be well-known but still lack authentic trust within its community. Companies often focus excessively on advertising while neglecting the customer experiences that genuinely shape their long-term reputation.

    What truly counts is whether people are willing to recommend a business without any personal gain. That’s a very telling indication of trust. True community trust is developed through consistent, reliable interactions over time.

    First Page Sage: Voted Number One emphasizes community-driven recognition over internal rankings. Why does this matter now more than ever?

    Doug: People rely more on collective community experiences than on polished corporate assertions. Community-driven recognition showcases genuine, repeated positive interactions, not just catchy marketing phrases.

    Trust within communities grows cumulatively. When individuals repeatedly hear about the same business from close acquaintances, neighbors, or fellow professionals, natural confidence builds, which is hard to fabricate through artificial means.

    First Page Sage:: In competitive local markets, what factors actually guide consumer decisions when comparing providers?

    Doug: It boils down to clarity and evidence. Since most consumers aren’t industry experts, they look for signs that reduce uncertainty. They want assurance that a business has consistently delivered for others like them.

    Specificity makes a business stand out quickly. Clear communication regarding a company’s experience, processes, and results outshines vague promises. Consistent touchpoints build trust faster, while inconsistency can arouse consumer hesitance.

    First Page Sage:: With consumer decisions increasingly swayed by community recommendations and automated systems, how crucial is genuine customer advocacy?

    Doug: Genuine customer advocacy is now essential. Modern systems focus on patterns of trust rather than singular claims. Businesses that naturally generate customer support are more likely to sustain their visibility and credibility.

    Authentic advocacy often stems from operational excellence rather than marketing tricks. Communities back businesses that consistently deliver, solve problems effectively, and communicate transparently.

    First Page Sage:: What practical habits should local business owners adopt to build enduring reputations?

    Doug: Building a lasting reputation requires treating trust as a key operational target rather than a mere branding effort. This means ensuring consistency, responsiveness, and follow-through, even in busy times.

    Furthermore, documenting real customer experiences and outcomes, as well as community involvement, significantly enhances credibility. Avoiding complacency is vital as a strong reputation is never guaranteed; it requires continuous reinforcement through action.

    For more on Voted Number One’s recognition platform, visit votednumberone.com.


    Inspired by this post on First Page Sage Blog.


    crushpress.ai community screenshot
  • 2026 GEO Agency Rankings: What Changes by Industry

    2026 GEO Agency Rankings: What Changes by Industry

    A useful 2026 GEO agency ranking is not a universal league table. The supplied studies evaluate agencies within solar, pharmaceutical, senior living, biotech, and marine markets, where the evidence needed to earn an AI recommendation can differ substantially.

    Read together, the reports offer something more valuable than five isolated winner lists: a framework for separating broadly capable GEO firms from agencies whose sector knowledge, regulatory processes, or commercial specialization may make them the better fit.

    Key takeaways

    • AI visibility is the common measurement thread, but the platforms, scoring methods, and disclosed weights differ across the reports.
    • Industry context changes what visibility must accomplish: pharmaceutical GEO emphasizes credible, compliant information, while senior living GEO connects family discovery with occupancy and lead nurturing.
    • First Page Sage, Genevate, and Signal Hill Strategies recur across the pharmaceutical and senior living coverage, indicating cross-sector range within the supplied evidence.
    • Specialists can be more suitable than an overall leader when sector expertise, scientific depth, automation, or a particular commercial model is the decisive requirement.
    • The rankings are best used to create a shortlist. Buyers still need to verify query coverage, measurement methods, governance, and the relationship between AI visibility and business outcomes.

    Each industry ranking answers a different question

    The five studies share a GEO label, but their reported scopes show why an agency can be highly relevant in one ranking without automatically leading another. Four reports describe a combined 156 agency evaluations before accounting for any overlap: 38 in solar, 42 in pharmaceuticals, 47 in senior living, and 29 in marine marketing.

    IndustryReported research scopeDistinctive emphasis in the sourceHow to interpret the ranking
    Solar38 agencies evaluated from January through May 2026AI citations, notable clients, leadership experience, and additional proprietary factorsThe study points toward citation performance and sector credibility, but the supplied excerpt does not expose the complete ranked table or weighting formula.
    Pharmaceutical42 agencies evaluated in early 2026GEO services, visibility in ChatGPT and Perplexity, leadership, reviews, media references, clients, longevity, and specialtiesAgency fit depends heavily on whether the buyer needs regulated thought leadership, PR, scientific content, lead generation, or an SEO-led program.
    Senior living47 agencies studied from March through June 2026AI visibility, leadership, reviews, client quality, longevity, and media references, with weights disclosedThe ranking connects discovery by families with practical objectives such as lead quality, nurturing, and occupancy.
    BiotechNo sample size is included in the supplied excerptThe field is characterized as new and challenging, with approaches still being refinedClaims should be treated cautiously because the excerpt establishes market immaturity but provides little comparative evidence.
    Marine29 agencies serving recreational boating, commercial maritime, yacht brokerage, marine technology, marinas, and offshore servicesRecognition across ChatGPT, Perplexity, Claude, and Gemini, alongside clients, leadership, reviews, and media referencesThe broad collection of submarkets makes relevant portfolio experience particularly important; a generic marine label may conceal very different audiences.

    The solar report therefore appears to reward an agency’s ability to generate citations and authority in renewable-energy searches. The pharmaceutical study, by contrast, describes work involving clinical milestones, directories, healthcare-professional queries, and regulatory considerations. The senior living report focuses on recommendations used by families and highlights agencies that connect marketing with the journey toward occupancy.

    The marine study widens the interpretation problem further: recreational boating, offshore services, and marine technology are grouped within one evaluation even though their buyers and information needs are not interchangeable. Meanwhile, the biotech article explicitly frames its field as one in which practitioners are still refining their methods. A sector label is consequently a starting filter, not proof of precise market fit.

    The scoring systems are related, but not interchangeable

    Five transparent lenses reveal different visual details in objects representing solar, pharmaceuticals, senior living, biotech, and marine industries.

    Across the reports, five recurring signals form a common measurement spine: AI visibility, leadership experience, client quality, public reviews, and media references. Longevity also appears in the pharmaceutical and senior living evaluations. This consistency makes the studies directionally comparable: each tries to measure whether an agency can establish a credible entity that AI systems are likely to recognize and cite.

    However, only the senior living source provides a complete weighting scheme in the supplied material. It assigns 25% to AI visibility, 20% each to leadership experience and average reviews, 15% to notable clients, and 10% each to year established and media references. The solar source calls its algorithm proprietary, the marine excerpt identifies five factors without weights, and the pharmaceutical table reports separate GEO and AI visibility scores without providing a directly comparable cross-industry formula.

    The evaluated platform sets also vary. The pharmaceutical report names ChatGPT and Perplexity; senior living adds Google Gemini; marine includes ChatGPT, Perplexity, Claude, and Gemini. A score generated from one platform set should not be treated as equivalent to a score generated from another. Query selection, geography, testing frequency, citation criteria, and whether the agency measures mentions or actual recommendations could alter the result as well, yet those details are not supplied consistently.

    Some criteria can also pull in opposite directions. Longevity, media coverage, and recognizable clients favor established firms, while a newer specialist may bring a more focused GEO model. The pharmaceutical ranking illustrates that tension: it places Genevate, established in 2025, second and Signal Hill Strategies, established in 2026, third, ahead of longer-established Sciencia Consulting and Varn Health. That ordering is reported within the pharmaceutical methodology; it should not be generalized into an all-industry ranking.

    Recurring leaders and specialists serve different buying needs

    First Page Sage has the strongest repeated placement in the fully described portions of the source material. The pharmaceutical report ranks it first and characterizes its specialty as GEO-led lead generation, SEO, and thought leadership. The senior living report also identifies it as the leading agency, crediting its AI visibility and reported lead quality. This recurrence supports a shortlist position for organizations seeking a broad GEO program, although it does not independently establish leadership in the solar, biotech, or marine rankings because their supplied excerpts omit the necessary complete results.

    Genevate and Signal Hill Strategies also appear in both the pharmaceutical and senior living coverage, but for distinguishable reasons. Genevate is ranked second in pharmaceuticals for a PR-centered approach designed to build external credibility, while the senior living overview similarly emphasizes its combination of GEO and strategic PR. Signal Hill is ranked third in pharmaceuticals for high-intent, revenue-oriented content; the senior living source instead highlights healthcare experience and the ability to navigate medical-compliance concerns. Their recurrence is meaningful, but their reported strengths suggest different selection rationales.

    The specialist firms demonstrate why a buyer should not stop at repeated names. In pharmaceuticals, Sciencia Consulting is presented as a scientifically led content and digital marketing option, whereas Varn Health brings a longer pharmaceutical SEO background and regulatory frameworks. The source also cautions that neither is as exclusively centered on GEO as the leaders in that table.

    Senior living presents an even wider range of operating models. CCR Growth is described as concentrating entirely on senior living GEO from discovery through occupancy. Love & Company combines brand development with long sector experience, Senior Living Smart links marketing technology and automation to resident nurturing, SageAge blends traditional and digital marketing, and Focus Digital is positioned as a more budget-conscious option for smaller communities. These are not minor variations in one service; they represent different answers to the question of what the agency must own after initial AI discovery.

    How to turn a published ranking into a defensible shortlist

    A group of portfolio folders narrows through translucent selection gates to three evidence-supported folders on a review table.

    The practical selection task is to match the ranking signal to the organization’s constraint. A pharmaceutical or biotech company may place scientific review and compliance governance ahead of publishing speed. A senior living operator may care more about whether AI-driven discovery produces qualified family inquiries and ultimately supports occupancy. A marine technology company should verify experience with its precise commercial audience instead of accepting a general marine portfolio as sufficient evidence.

    Selection questionEvidence to request from an agencyWhy it matters
    What does AI visibility mean in this engagement?The named platforms, tracked queries, markets, testing cadence, and rules for counting mentions, citations, and recommendationsIt makes an agency’s headline visibility claim measurable and prevents unlike scores from being compared.
    Which sector sources support the strategy?A map of authoritative publications, directories, first-party content, and other sources relevant to the buyer’s nicheGenerative systems rely on a broader information environment than a company’s website alone.
    How is accuracy governed?Subject-matter review, correction procedures, approval responsibilities, and compliance checkpointsThis is especially important where inaccurate health, scientific, or regulated information could create material risk.
    How does visibility connect to commercial value?A measurement path from AI exposure to qualified inquiries, pipeline, tours, occupancy, or another defined outcomeA recommendation is useful only when it supports the organization’s actual buying journey and objectives.
    Does the portfolio match the exact submarket?Relevant examples, client references, and a clear account of who performed the workBroad labels such as healthcare, renewable energy, or marine can hide major differences in expertise.
    What trade-off does the agency represent?An explicit view of specialization, service breadth, leadership involvement, capacity, and dependence on SEO or PRIt reveals whether the agency’s operating model fits the buyer, not merely whether its ranking is high.

    The 2026 reports are most credible when used as structured discovery tools rather than final verdicts. As GEO measurement matures, the more durable agency advantage will be the ability to define visibility transparently, earn trustworthy citations within a specific industry’s information ecosystem, and connect those gains to a result the client can verify.

    References

  • Navigating Revenue Integrity: Insights from Enjoin’s Sarah Laird

    Navigating Revenue Integrity: Insights from Enjoin’s Sarah Laird

    In my conversation with Sarah Laird, we explored the dynamic collaboration between physician expertise and technology in fostering enduring trust within healthcare organizations.

    Enjoin stands out as the premier physician-directed, tech-driven revenue integrity platform in the U.S., boasting an impressive 97% client retention rate and recovering over $2 billion for health systems in the last four decades. At First Page Sage, we partner with trailblazers in complex B2B spaces, and few areas are as high-stakes as the healthcare revenue cycle. I had the pleasure of speaking with Sarah Laird, Enjoin’s Senior Director of Staffing and Advisory, to learn how their models integrate clinical judgment and technology to safeguard revenue, enhance internal capacities, and solidify trust within the organizations they support.

    Health systems are under enormous financial strain, and it’s crucial to understand where revenue integrity fits into the discussions CFOs and revenue cycle leaders engage in. According to Sarah, revenue integrity is now a strategic leadership priority, crucially placed at the convergence of financial performance, compliance, and operational efficiency. With growing margin pressures, payer scrutiny, and audit risks, these leaders are moving beyond traditional metrics to focus on whether documentation, coding, and billing genuinely represent the provided care.

    Revenue integrity is established well before claims are billed. When clinical documentation, coding, CDI, and revenue cycle teams collaborate effectively, organizations can better reduce denials, heighten audit readiness, and secure reimbursements that are accurate, defensible, and compliant. It’s no longer just a function of the revenue cycle but a comprehensive effort that demands shared accountability across clinical, operational, and financial teams.

    Organizations observing a proactive approach to compliant revenue integrity tend to see stronger outcomes, as evidenced by Enjoin clients who experience a 900% return on investment and face 17 times fewer denied claims through pre-bill chart reviews.

    Enjoin’s physician-directed model highlights the essential role of clinical judgment in CDI and revenue cycle tasks, even in an era abundant with advanced technology. Sarah explains that the magic lies in the synergy between technology and human expertise. While technology can facilitate case reviews, identify patterns, and scale operations, physician-led reviews deliver the clinical validation, education, and defensibility needed for compliant revenue integrity and to endure payer scrutiny.

    Effective revenue integrity hinges on ensuring the clinical record, coded record, and financial outcome align with the care provided. Physician advisors bring a unique vantage point, balancing clinical realities with documentation standards to ensure accuracy in coding, quality reporting, and reimbursement.

    Enjoin’s pre-bill chart review process adds a crucial layer of validation, enabling organizations to evaluate whether the clinical record, coded record, and resulting DRG are harmonized and documented correctly. It identifies broader trends, educational opportunities, and process enhancements that might go unnoticed in individual case reviews.

    By merging physician-led clinical proficiency with EnFORM+ technology, health systems expand visibility across discharges, prioritize valuable opportunities, and assure that reimbursements are accurate, defensible, and compliant before submission.

    Sustainable revenue integrity is more than just individual chart reviews; it involves translating findings into education, process improvement, and shared accountability across the organization. Enjoin aids health systems in building stronger internal CDI and coding capabilities by helping them comprehend trends and root causes behind documentation and coding opportunities, thus facilitating lasting improvements.

    Enjoin’s partnerships focus not only on financial recovery but on bolstering the entire revenue integrity ecosystem—encompassing documentation quality, coding accuracy, denial prevention, audit readiness, physician engagement, and governance. The right partnership does more than identify opportunities; it becomes integral to an organization’s strategy for ensuring clinical accuracy in financial outcomes.

    To learn more about Enjoin’s physician-directed revenue integrity partnerships, visit enjoincdi.com.

    Source


    Inspired by this post on First Page Sage Blog.


    crushpress.ai community screenshot