Author: shivamcrushpressai

  • Brand Visibility in Google AI: From Citation to Recommendation

    Brand Visibility in Google AI: From Citation to Recommendation

    Brand visibility in Google AI results is no longer a simple matter of ranking or being cited. A company can make its content available, have that content used as evidence, and still watch Google recommend a competitor.

    The two source reports expose different sides of that problem: one examines controls over participation in Google’s AI experiences, while the other shows why participation alone does not secure an endorsement. Together, they suggest a more useful framework for managing AI visibility.

    AI visibility now passes through three separate gates

    Google AI visibility can be understood as three related but distinct outcomes: eligibility, citation and recommendation. Treating them as interchangeable can produce misleading reports and poor strategic decisions.

    • Eligibility: Whether a publisher permits its content to appear in an AI-powered search experience.
    • Citation: Whether Google uses a page as supporting material in an AI-generated response.
    • Recommendation: Whether the response presents the brand itself as an option a user should consider.

    The article about Google’s reported AI opt-out controls concentrates on the first gate. It says site owners are being given a way to exclude content from experiences such as AI Overviews and AI Mode, alongside early-stage AI reporting in Google Search Console. The article about self-promotional software listicles concentrates on the second and third gates, reporting that Google may cite a company’s page without recommending that company.

    This distinction changes the central business question. Being available does not guarantee selection, but becoming unavailable removes even the opportunity to supply evidence, earn a mention or influence the comparison.

    Why a citation can create visibility for a competitor
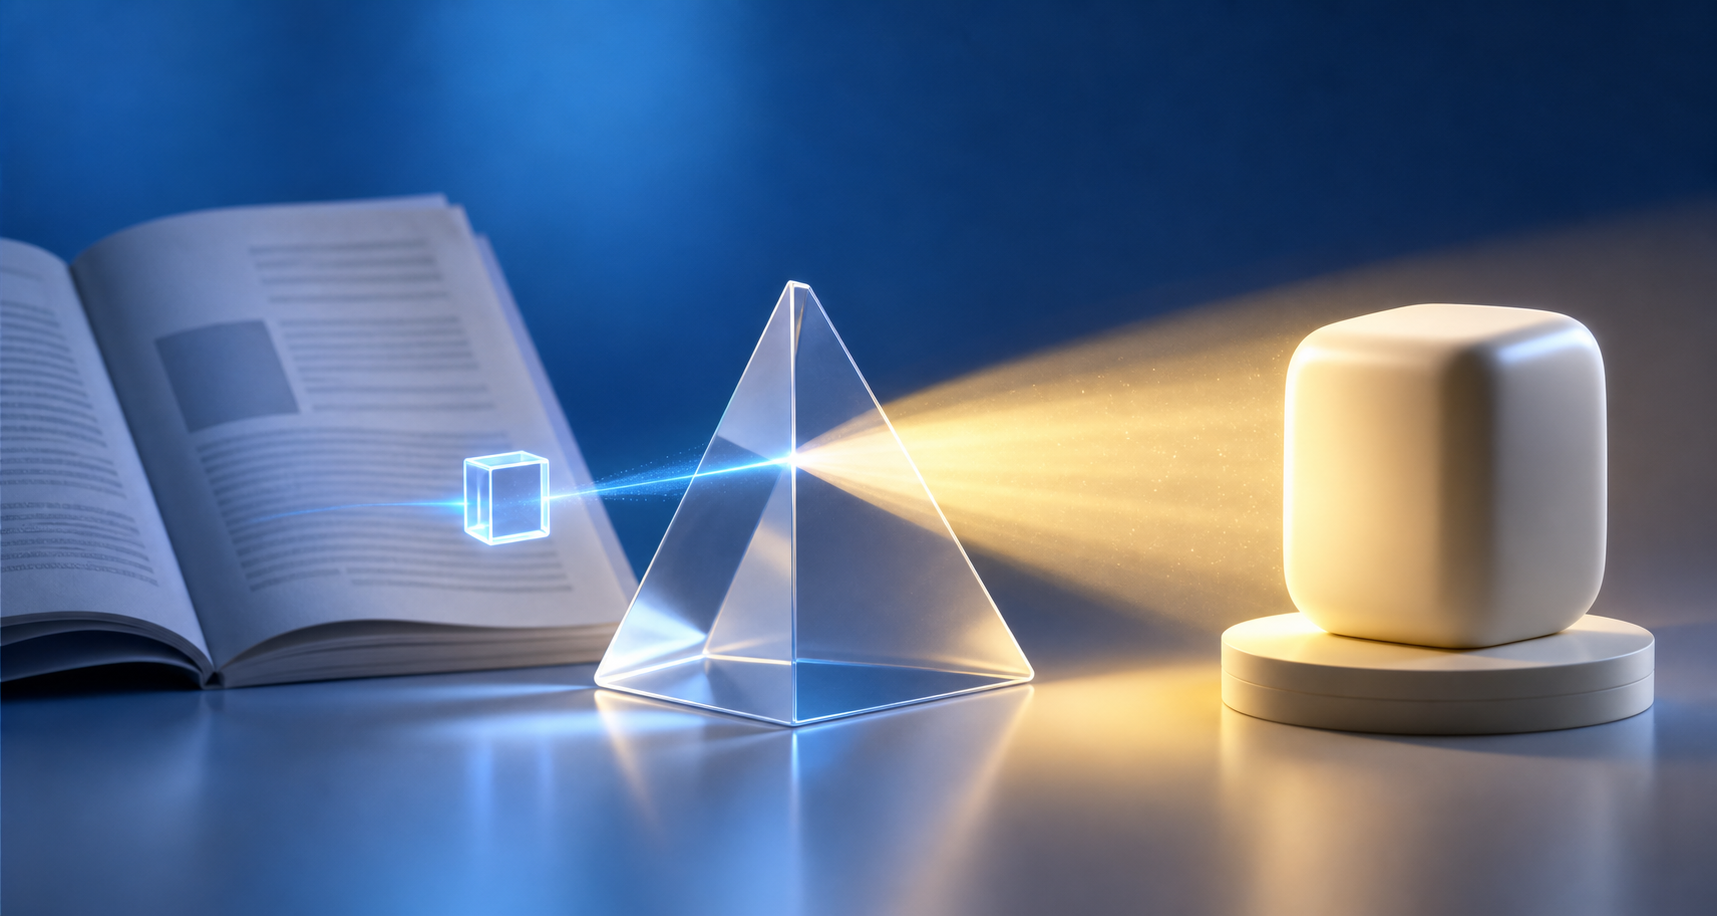
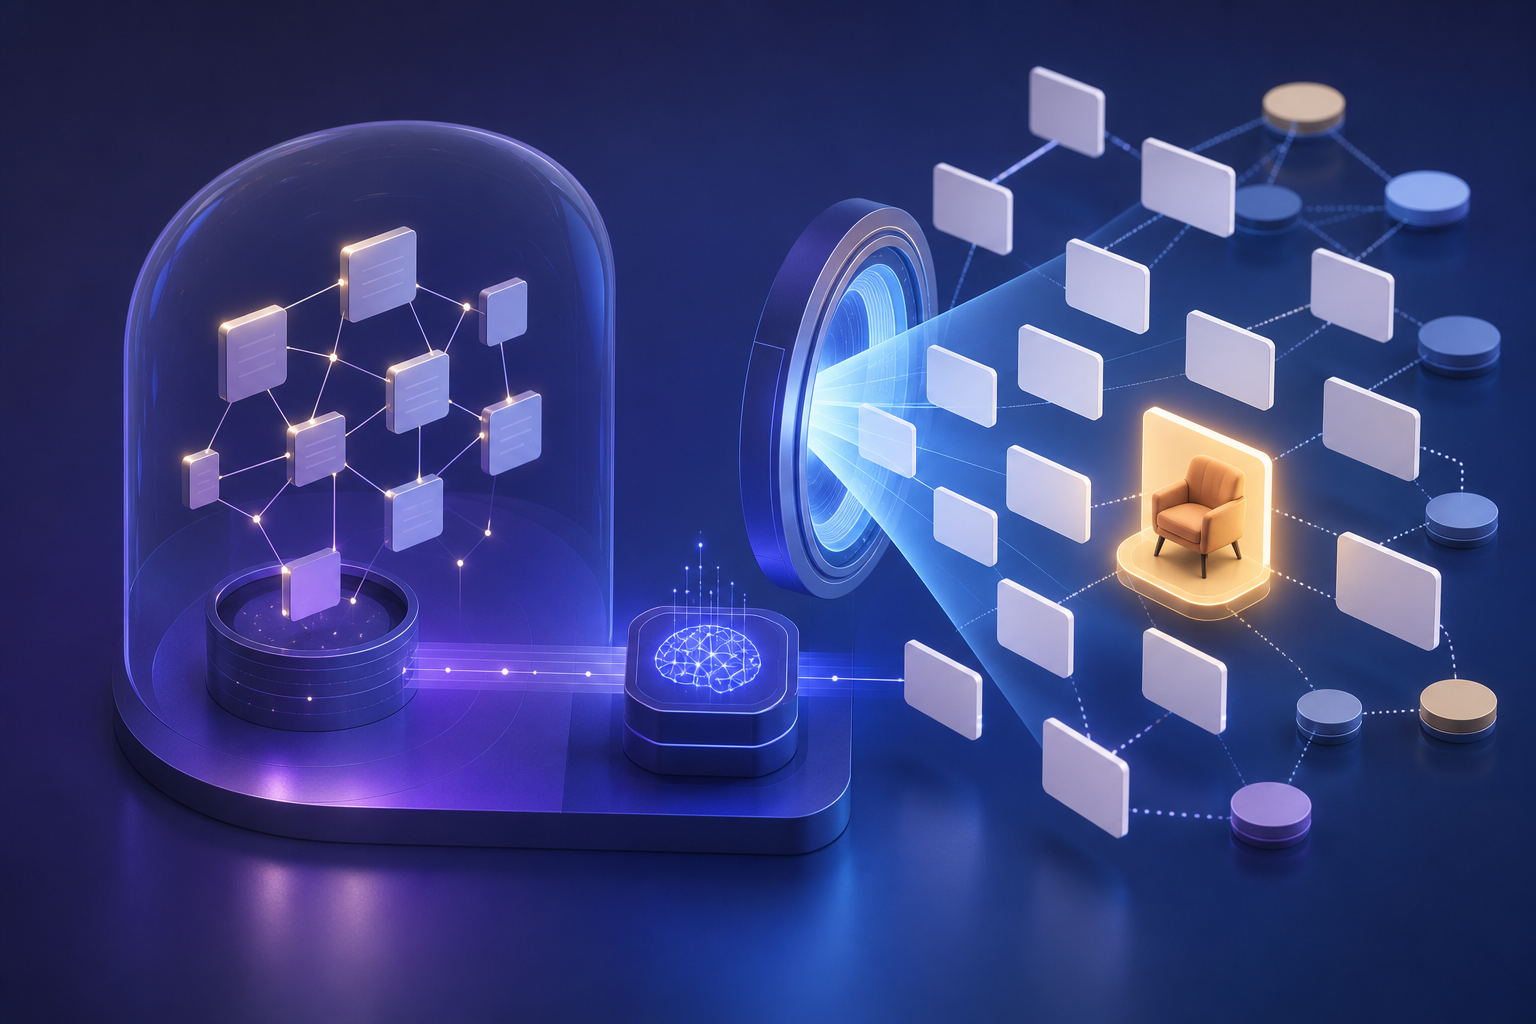
    An open document feeds evidence into a translucent AI prism that directs a spotlight toward a different product-shaped object.

    The clearest warning comes from the analysis attributed to Lily Ray in the source about "best" software listicles. According to that report, Ray examined 100 B2B software queries across three collection dates: April 15, May 15 and June 8. Eighty of those queries produced an AI Overview.

    The source reports that self-serving listicles appeared among the citations 323 times, but that the publishing brands were not recommended in 224 of those instances. It also reports that such listicles were cited in 69% of the B2B software queries studied. Those figures come from a limited query set and should not be generalized to every market, but they illustrate an important failure mode: content visibility and commercial visibility can move in different directions.

    In one example described by the source, an Oasis LMS page was cited for a query about the best learning management system for selling courses, while Kajabi and other competitors appeared among the recommended options. The owned page may therefore have helped Google construct an answer without persuading the system to favor its publisher.

    The same report says third-party sources including Reddit, Forbes and YouTube were becoming more prominent in citations for these queries. That observation supports a broader interpretation: a brand’s claim about itself is only one input, while external discussion may help determine whether the brand is treated as a credible recommendation. The sources do not establish a precise causal formula, so this should be treated as a strategic hypothesis rather than a confirmed ranking rule.

    Opting out changes brand eligibility, not user demand

    The opt-out source argues that withdrawing content does not stop people from using AI Overviews or AI Mode. Instead, it changes which brands and sources remain eligible to appear. Under that interpretation, an absent publisher leaves Google to assemble its response from participating competitors and third parties.

    That does not make participation an automatic choice for every organization. Publishers may have legitimate concerns about content rights, representation, traffic substitution or the commercial value exchanged when their work supports an AI answer. The key is to evaluate those concerns against the actual effect of the control. An opt-out is a content-distribution decision, not a mechanism for reversing user adoption of AI search.

    The listicle findings make the trade-off more complicated. Remaining eligible can create an opportunity to be cited, but citation may still transfer attention to another brand. The strategic task is therefore not merely to stay present. It is to improve the probability that Google’s answer connects the evidence supplied by a company with a favorable, accurate representation of that company.

    A measurement model for meaningful AI visibility
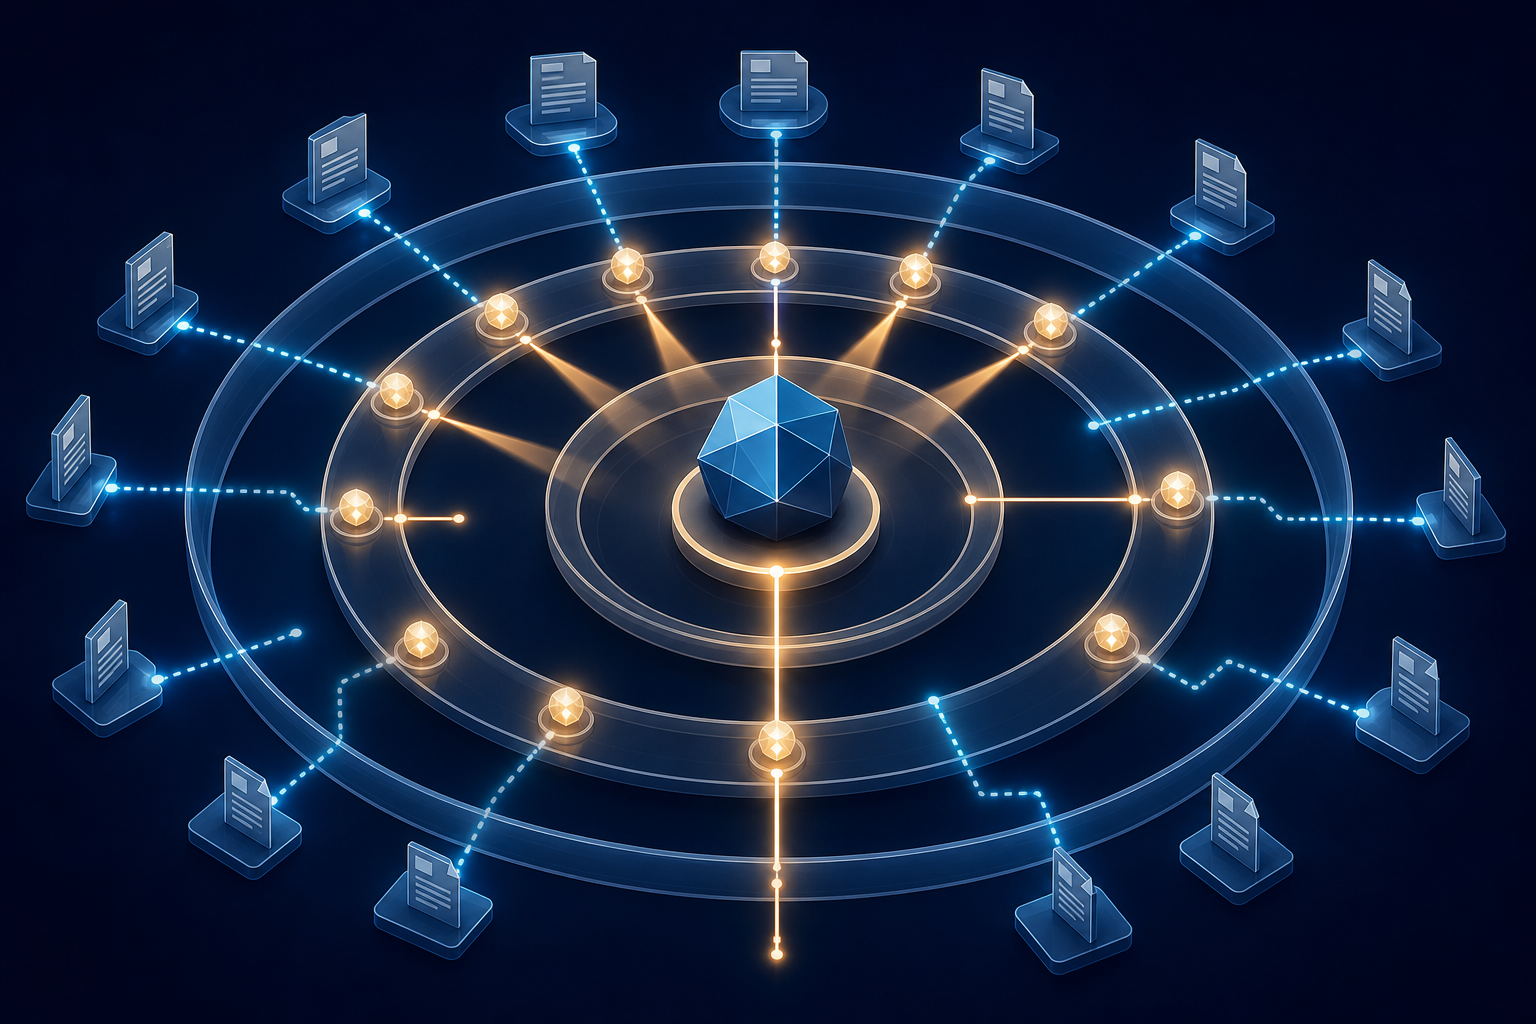
    Three translucent rings surround a central object as document tiles, evidence nodes, and spotlights form pathways toward it.

    The opt-out article calls for reporting that extends beyond conventional SEO traffic and includes brand mentions, citation frequency and representation across AI platforms. The listicle analysis demonstrates why those dimensions must be separated rather than collapsed into a single visibility score.

    A practical monitoring program can classify each important query using the following fields:

    • AI result presence: Whether the query triggers an AI-generated result.
    • Source inclusion: Whether the company’s domain is cited or otherwise used.
    • Brand inclusion: Whether the company is named in the generated answer.
    • Recommendation status: Whether the brand is presented as a preferred or relevant option.
    • Competitor benefit: Which rival brands are recommended when the company’s content is cited.
    • Representation quality: Whether the description of the brand, product and limitations is accurate.

    This structure makes several otherwise hidden outcomes visible. A page can win a citation while the brand loses the recommendation. A brand can be mentioned without receiving a link. A competitor can gain the commercial benefit from evidence published by someone else.

    Content reviews should follow the same separation. Self-authored comparison pages need a transparent method, supportable claims and meaningful treatment of alternatives; simply declaring the publisher’s product the best may not influence the recommendation as intended. Because the reported study also observed more third-party citations, teams should assess how the brand is described outside its own domain instead of treating owned content as the whole AI visibility strategy.

    Key takeaways

    • Eligibility, citation and recommendation are separate stages of Google AI visibility.
    • According to the reported B2B software analysis, Google often cited self-promotional listicles without recommending their publishers.
    • Opting out may remove a brand’s content from consideration, but it does not remove the user’s underlying AI search activity.
    • Reporting should identify who supplies the evidence, who receives the mention and who ultimately earns the recommendation.

    As Google’s controls and reporting mature, the strongest strategy will be based on observable outcomes rather than a binary debate over participation. Brands that distinguish being used as a source from being selected as an answer will be better equipped to protect and improve their visibility.
    References

  • What UK Scrutiny of Google Search Could Mean for Businesses

    What UK Scrutiny of Google Search Could Mean for Businesses

    UK scrutiny of Google Search is moving beyond complaints about individual ranking changes. As reported by CrushPress.AI, the Competition and Markets Authority (CMA) is pressing Google on three connected issues: how organic results are ranked, how publishers can respond to AI Overviews, and whether users can transfer their search data to authorized services.

    Taken together, the reported requirements point toward a broader form of accountability. The central question is not simply whether Google may update Search, but whether affected businesses receive understandable rules, meaningful notice and workable ways to challenge decisions.

    Key takeaways

    • The CMA reportedly wants Google to apply objective, non-discriminatory criteria to organic results, including AI Overviews but excluding sponsored placements.
    • Businesses would gain clearer explanations of ranking practices, advance notice of significant changes and a defined process for raising concerns.
    • Site owners would be offered a way to opt out of AI Overviews, according to the supplied report.
    • A separate data-portability requirement would let users transfer search data to authorized third parties.
    • The difficult boundary will be providing useful transparency without exposing ranking systems to manipulation.

    The CMA is treating ranking governance as a business issue

    According to CrushPress.AI, UK businesses told the CMA that Google’s ranking practices lack fairness and transparency. Their concerns reportedly include changes being introduced without enough notice and inadequate channels through which affected companies can question those changes.

    The CMA’s reported response addresses both the substance of ranking and the process surrounding it. Google would be expected to use objective and non-discriminatory criteria for organic results, explain more about how ranking works, warn businesses before significant changes and establish procedures for receiving and addressing complaints. The report gives Google six months to implement the ranking-related measures.

    This distinction matters. A business can lose visibility even when a search system is operating according to its stated goals. Procedural safeguards would not guarantee a particular position, but they could help businesses distinguish an ordinary competitive loss from a technical problem, an unexplained policy shift or a decision worth challenging.

    AI Overviews expand the transparency question

    A translucent summary panel receives colored information threads from blank web pages and publisher desks through a clear prism.

    The supplied report says the organic-results requirements include AI Overviews while excluding sponsored results. It also says Google must provide site owners with a way to opt out of AI Overviews. That combination places AI-generated answers within the same policy discussion as conventional search visibility, rather than treating them as an entirely separate product issue.

    For publishers, an opt-out mechanism introduces a consequential choice. Participation may offer exposure inside an AI-generated search feature, while opting out may provide greater control over how material is used or presented. The source does not specify the mechanism’s design or its effect on ordinary search listings, so businesses should not assume what opting out would do until operational details are available.

    The inclusion of AI Overviews also raises the standard for useful explanations. Traditional ranking transparency concerns which pages appear and in what order. AI-generated results add questions about which sources contribute to a synthesized answer and how prominently those sources are represented. The reported CMA measures establish a direction for oversight, but the supplied account does not describe the level of AI-specific disclosure Google would have to provide.

    Data portability targets a different source of market power

    A transparent capsule of abstract data travels across a secure bridge between two digital service terminals.

    Ranking rules govern how businesses reach search users; data portability concerns what users can do with the information generated through their own search activity. CrushPress.AI reports that the CMA wants Google to let users transfer search data to authorized third parties within three months.

    The examples in the report include rewards platforms and businesses offering personalized deals or discount codes. It also suggests that access could support tailored travel recommendations and more relevant shopping offers. These are possible uses rather than confirmed services or outcomes.

    Conceptually, portability can reduce the advantage created when useful history remains inside one platform. Its practical effect, however, will depend on details not provided in the source: what information is transferable, how authorization works and what safeguards accompany access. The ranking and portability measures therefore address different relationships with Google Search, but both attempt to give outside parties more agency.

    Useful disclosure does not require publishing the algorithm

    The supplied article is skeptical that Google will comply readily, arguing that extensive disclosure could expose a valuable ranking system to competitors or make manipulation easier. That concern identifies the central implementation tension, but it does not necessarily make meaningful transparency impossible.

    There is a difference between revealing a complete ranking formula and explaining the governance around it. Clear policy criteria, notice of consequential changes, documented complaint routes and reasoned responses can improve accountability without publishing every signal or its weighting. The value of the CMA’s reported intervention will therefore depend less on the volume of information released than on whether businesses can use it to understand and contest material decisions.

    Businesses should watch for the eventual scope of the AI Overview opt-out, the specificity of ranking-change notices and the independence and responsiveness of the complaint process. Those implementation details will determine whether the measures alter day-to-day dealings with Google or remain largely procedural.

    The next phase will test whether the CMA’s reported deadlines produce workable controls while preserving the integrity of search results. For publishers and other search-dependent businesses, the most important development will be whether formal scrutiny becomes practical leverage when visibility changes.

    References

  • Meta Connects Live Shopping Ads With Secure Checkout

    Meta Connects Live Shopping Ads With Secure Checkout

    Meta’s shopping initiatives bring three parts of social commerce closer together: live product discovery, personalized advertising and payment. The supplied reporting describes a strategy for turning attention inside Facebook and Instagram into purchases with fewer interruptions.

    For advertisers, the important development is not any one feature in isolation. Live ads can widen discovery, product catalogs can improve relevance, and virtual cards can address payment hesitation. Their value depends on how well those layers operate as one purchase path.

    Live ads extend the storefront beyond its original audience

    CrushPress.AI reported that Meta was expanding Live Video Ads globally on Facebook and introducing them on Instagram. In the United States, the company was also working with live-commerce providers CommentSold and TalkShopLive to help sellers turn livestreams into ads capable of reaching people who had not joined the original broadcast organically.

    This changes the role of a live shopping event. Instead of functioning only as a scheduled broadcast for an existing following, it can also supply advertising creative and product demonstrations for a wider audience. Facebook’s Live Shopping tools, according to the report, allow viewers to browse and purchase products without leaving the livestream.

    The resulting funnel is shorter in principle: a viewer encounters a demonstration, evaluates the featured product and moves toward purchase within the same experience. That convenience may remove unnecessary navigation, although it does not guarantee demand or compensate for an unclear offer.

    Virtual cards address a specific source of checkout friction

    A shopper uses a phone to check out with a generic virtual payment card protected by a translucent shield.

    The report also described a planned virtual-card payment feature for Facebook and Instagram, developed through collaborations with Mastercard and Visa. It said the system would generate a temporary, one-time card number linked to a shopper’s existing card, allowing a transaction without exposing the underlying card details.

    That design addresses a narrow but meaningful trust question: whether a shopper must disclose a primary card number during an in-app purchase. It should not be interpreted as a complete guarantee of transaction safety. Virtual card numbers do not resolve concerns about product quality, delivery, refunds, merchant legitimacy or account security.

    The distinction also matters when assessing availability. The supplied material characterizes the feature as an upcoming rollout but does not provide enough detail to establish current geographic coverage, merchant eligibility or adoption. Advertisers should therefore verify access in their own accounts before designing a campaign around it.

    Product catalogs become the connective data layer

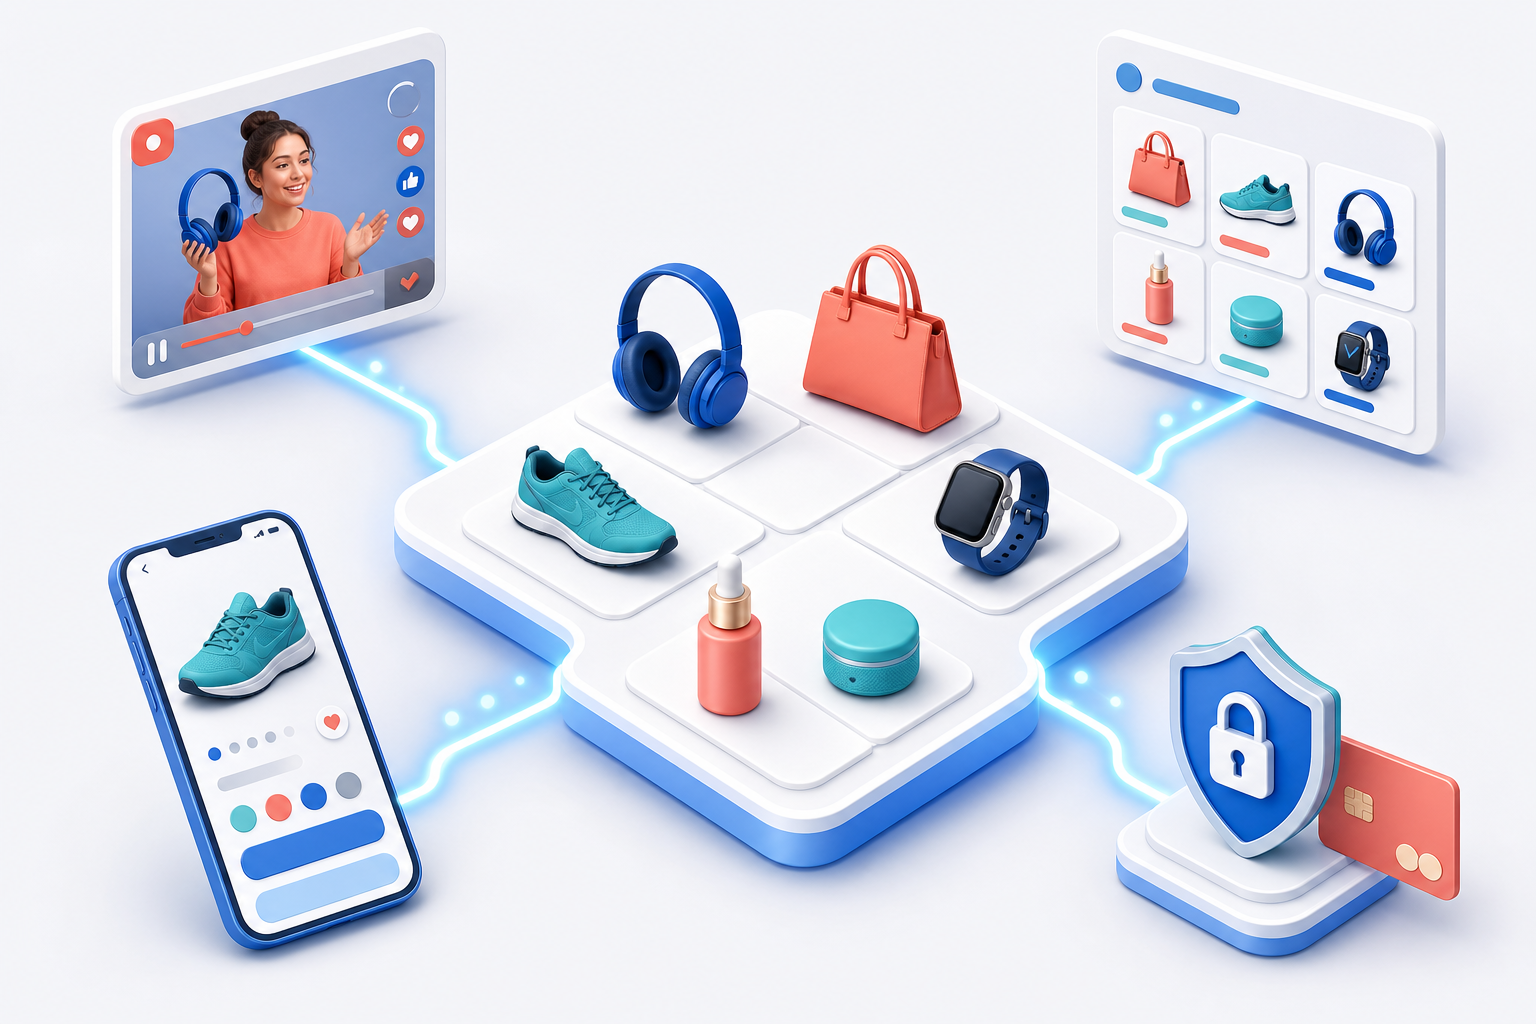
    Product tiles in a central digital catalog connect to live video, personalized shopping placements, a mobile product page, and secure checkout.

    CrushPress.AI reported that Meta was making product data a core component of Sales campaigns. The described approach combines catalog feeds with creative assets while Meta’s AI assembles ads for individual users. Details such as price and availability can therefore influence both what is shown and how accurately an ad reflects the product being sold.

    This positions the catalog as more than an inventory file. It connects recommendations, ad delivery and the purchase opportunity. The report also framed product discovery as increasingly driven by recommendations appearing in feeds, creator videos and business content rather than beginning with a conventional product search.

    That makes feed quality operationally important. If product names, prices, availability or destinations are incomplete or stale, automated assembly can distribute those weaknesses at scale. Strong creative still matters, but it must be supported by reliable commerce data.

    Campaign evaluation should follow the entire purchase path

    The combined proposition should be assessed as a sequence rather than as an ad-format experiment alone. Advertisers need to distinguish reach generated by live promotion from meaningful product engagement, checkout starts and completed purchases. A large viewing audience is useful only when it produces qualified movement through the funnel.

    Catalog accuracy, livestream presentation and checkout confidence can each become a constraint. If viewers engage but do not open product information, the offer or demonstration may need work. If product engagement is healthy but checkout completion is weak, payment confidence, total cost or post-purchase policies may deserve closer examination. Virtual cards could remove one objection, but they cannot diagnose every reason for abandonment.

    Advertisers should also separate platform automation from commercial judgment. Meta’s AI can use product data to assemble and deliver ads, as the report describes, but businesses remain responsible for assortment, positioning, accurate information and the customer experience after payment.

    Key takeaways

    • Live shopping ads can extend a broadcast beyond its organic audience while keeping product discovery close to the buying action.
    • Virtual card numbers are intended to limit exposure of a shopper’s underlying card details, but they address only one dimension of transaction trust.
    • Product catalogs increasingly support ad personalization and discovery, making feed accuracy central to campaign quality.
    • Performance should be judged across viewing, product engagement, checkout initiation and purchase rather than by reach or clicks alone.

    The next meaningful test is whether Meta can make these layers consistently available and reliable enough to produce measurable gains for merchants. Advertisers that establish clean catalog data and full-funnel measurement will be better positioned to evaluate that opportunity as access expands.

    References

  • Profound MCP Connectors: What the Integration Really Means

    Profound MCP Connectors: What the Integration Really Means

    Profound’s External MCP Connectors are presented as a way to bring outside work systems into Profound through a shared integration layer. The practical promise is less tool switching: information and actions associated with content management, project tracking, and team communication could become accessible from a more centralized workflow.

    The available source is a short, vendor-authored announcement rather than independent testing or detailed technical documentation. Its claims therefore establish Profound’s intended direction, but not the connector catalog, supported operations, security model, or measurable productivity gains.

    What Profound says its external connectors enable

    According to the Profound post, External MCP Connectors can link the platform with CMS tools, project trackers, and team communication platforms. The announcement describes these connections as a way to manage projects, streamline workflows, improve collaboration, and access important tools from a central hub.

    Those statements should be read as product positioning. The source does not identify particular supported services, distinguish between read-only access and write actions, or demonstrate a complete workflow. It also offers no comparative results showing how much time or effort the connectors save. Consequently, the meaningful takeaway is the proposed integration model, not a verified performance outcome.

    Why MCP changes the integration conversation

    Different digital systems connect through a standardized bridge to a single AI workspace.

    In general terms, the Model Context Protocol provides a standardized way for an AI-enabled application to interact with external sources and tools. Instead of treating every connection as an entirely separate product integration, an MCP-based approach can give compatible systems a common interface for exposing permitted context or actions.

    For Profound users, the architectural implication may matter more than the phrase “central hub.” A common interface can make it easier to assemble workflows spanning several systems, but it does not automatically make those systems interchangeable. Each connector can still differ in authentication, available functions, data structure, reliability, and administrative controls.

    Key takeaways

    • Profound reports that External MCP Connectors can connect CMS, project-tracking, and team-communication tools with its platform.
    • The central value proposition is workflow consolidation, although the source provides no independent evidence or quantified results.
    • MCP standardizes the connection pattern; it does not guarantee identical capabilities, permissions, or data quality across external tools.
    • Teams should evaluate each connector at the level of actual tasks, accessible data, permitted actions, and operational controls.

    The questions teams should answer before adoption

    A digital connector workflow passes through permission, identity, audit, and human approval checkpoints while a team monitors it.

    A useful evaluation starts with the workflow rather than the number of available connections. A team might examine where information currently moves between its CMS, project tracker, and communication system, then identify which transfers are repetitive, slow, or prone to inconsistency. The connector is valuable only if its available operations match those specific handoffs.

    Access boundaries also require scrutiny. Evaluators should determine which data Profound can retrieve, which actions it can initiate, how users authenticate, and whether permissions from the connected service remain enforceable. Logging, error handling, approval requirements, and procedures for revoking access are similarly important wherever a connector can change external records.

    Finally, teams should test the quality of the resulting context. Centralized access is not necessarily coherent access: duplicated records, inconsistent naming, stale project statuses, or ambiguous ownership can still undermine an integrated workflow. A limited pilot built around one repeatable task can reveal whether the connector reduces friction without obscuring accountability.

    From connectivity to dependable workflows

    Profound’s announcement points toward a platform that can sit closer to the systems where teams already plan, communicate, and manage content. Whether that direction produces meaningful efficiency will depend on the depth of individual connectors and the governance surrounding them. Future documentation and hands-on evaluation will be needed to establish which workflows are genuinely supported and how reliably they operate.

    References

  • Google Conversion-List Auto-Classification: What to Audit

    Google Conversion-List Auto-Classification: What to Audit

    A reported Google Ads change will shift more responsibility for classifying conversion-based customer lists into Google’s systems beginning in August 2026. For advertisers, the important question is not simply what label appears in Audience Manager, but whether that label matches the role each audience actually plays.

    The practical response is to audit lifecycle definitions before the reported change takes effect. Clear distinctions between customers, prospects, and other segments can reduce the risk that automated acquisition or retention decisions are informed by the wrong audience signal.

    What Google reportedly plans to classify

    CrushPress.AI reports that Google will automatically categorize customer types in conversion-based lists starting in August 2026. The reported categories are existing customers, new customers, and other customer segments.

    The report frames the change as part of Google’s effort to make customer-acquisition and retention signals more consistent across its advertising tools. It also says Google Ads expert Bia Camargo first identified the alert on LinkedIn. Because the available source does not detail every classification rule, advertisers should avoid assuming how Google will resolve ambiguous or overlapping audiences.

    Key takeaways

    • Google reportedly plans to classify conversion-based customer lists automatically from August 2026.
    • The stated classifications distinguish existing customers, new customers, and other customer segments.
    • A technically accurate list can still send an unsuitable lifecycle signal if its business meaning is unclear.
    • Advertisers should review Customer Match lists and their classifications in Google Audience Manager before the change.

    Why lifecycle labels matter to automated campaigns

    Audience membership and audience meaning are different things. A list may accurately contain people who completed a conversion, yet that conversion may not represent the same customer state in every business. The source specifically warns that incorrect classification could affect how Google’s systems optimize users across their lifecycle.

    This matters because acquisition and retention strategies ask different questions. Acquisition focuses on finding or prioritizing people treated as new customers, while retention focuses on people the business already recognizes as customers. When a list’s Google-assigned category does not match the advertiser’s internal definition, automation may receive a signal that is valid at the data level but misleading at the strategy level.

    The central risk is a mismatch in definitions

    Two classification systems route the same anonymous audience profiles into different groups.

    The reported categories sound straightforward, but their boundaries may not be. An advertiser’s internal customer model can contain lifecycle distinctions that do not map neatly to broad labels such as existing, new, or other. The source does not explain how Google will treat every edge case, so the safest analysis is to focus on whether each list has one clear strategic purpose.

    The most consequential ambiguity is likely to appear where conversion status and customer status are treated as interchangeable. A conversion-based list records an action according to the advertiser’s setup; classification assigns that audience a role in the customer journey. Reviewing the underlying meaning of the conversion is therefore more useful than relying on a familiar list name alone.

    How to prepare before August 2026

    A marketing team reviews and reorganizes unlabeled audience cards on a digital workspace.

    The source recommends auditing Customer Match lists based on conversion data in Google Audience Manager. That review should establish what each list contains, which lifecycle state the business intends it to represent, and whether Google’s expected classification appears consistent with that intent.

    Advertisers should pay particular attention to lists used in customer-acquisition strategies, because the reported change is intended to clarify the distinction between prospecting and retention audiences. Internal campaign owners should also agree on the meaning of each lifecycle label so that a list is not interpreted differently across campaigns.

    The goal before August 2026 is not to predict every decision Google’s classifier may make. It is to remove avoidable ambiguity from the audience signals the system will evaluate and to be ready to assess whether the resulting classifications still support the intended campaign strategy.

    References

  • How AI Recommendations Reshape Referrals and Buyer Intent

    How AI Recommendations Reshape Referrals and Buyer Intent

    AI-driven discovery is creating a two-stage customer journey: an assistant first narrows the choices, then a referred visitor decides whether a website confirms the recommendation. The available reporting suggests that these stages are closely connected, but they should not be measured as one channel.

    A product’s inclusion in an AI answer can change when web search is enabled, while the people who click through may behave differently from conventional visitors. Understanding both effects helps brands distinguish recommendation visibility from referral performance.

    Key takeaways

    • AI recommendation visibility can be highly variable: one reported ChatGPT study found that enabling search changed the products appearing in 80.2% of responses.
    • AI referrals can bring unusually engaged visitors without guaranteeing stronger conversion. Adobe’s reported travel data showed more time on site and lower bounce rates, but a remaining conversion deficit.
    • Category context matters. The same Adobe reporting found that AI-referred retail visitors converted substantially better than non-AI traffic, in contrast with travel.
    • Readable, well-structured content may support discovery, but the cited evidence does not prove that improving AI readability directly causes more recommendations or sales.

    Recommendation visibility depends on how the AI gathers evidence

    Abstract AI workspace comparing a closed evidence network with an expanded web search network that produces different selections.

    An AI assistant does not necessarily produce a stable shortlist from a fixed body of knowledge. A study by Visibility Labs founder and CEO Jeff Oxford, summarized in the second source, ran 1,000 product-recommendation prompts ten times with search enabled and ten times without it, producing 20,000 interactions. Only 19.8% of products suggested without search reappeared when search was active. In other words, the retrieval method altered much more than the wording of the answer; it changed the choice set presented to users.

    The most frequently suggested products were not insulated from that change. Of the products consistently recommended in search-disabled responses, the source reported that only 15.8% appeared after search was enabled. Search-enabled answers were also somewhat narrower, averaging 5.2 products per response compared with 6.2 without search. Across ten runs of each prompt, search produced an average of 19 unique products, versus 21.8 without it.

    This volatility complicates the idea of a single, permanent AI ranking. A brand can be prominent in an assistant’s model-based answer and absent when the assistant consults the web, or vice versa. Visibility therefore needs to be evaluated across repeated prompts and different answer modes rather than inferred from one favorable result.

    The study also found a reported Pearson correlation of 0.4 between how often products appeared in cited sources and how frequently they were recommended. That is useful directional evidence, but the observational design did not establish that source mentions caused inclusion. Citations may reflect broader web prominence, product suitability, accessible information or several factors operating together.

    Referral quality reveals intent after the recommendation

    The first source, reporting Adobe data, examines what happens after an AI user reaches a website. It said AI-driven traffic to U.S. travel sites increased 194% year over year in May 2026 and 2,215% from the beginning of Adobe’s monitoring in October 2024. The research drew on more than 8 million visits to U.S. travel sites and a March survey of more than 5,000 U.S. consumers.

    These visitors displayed stronger engagement than non-AI visitors: Adobe reportedly measured 70% more time per visit, a 41% lower bounce rate and 21% higher engagement. The source interpreted the pattern as consistent with more deliberate, higher-intent browsing. That interpretation is plausible because an assistant can help a traveler compare destinations, hotel features, itineraries and promotions before the click, leaving the destination site to validate details or support a booking.

    Engagement did not translate into an immediate travel conversion advantage. AI-referred visitors converted 28% less often than non-AI visitors, although the source said that gap had narrowed by nearly 70% since October 2024. Travel decisions can involve additional comparison and coordination, so time on site should not be treated as a substitute for completed transactions.

    Retail produced a different outcome in the same Adobe reporting. AI-driven visits to U.S. retail sites rose 138% year over year in May and 1,324% from October 2024. AI-referred retail visitors converted 54% better than non-AI visitors, reversing the earlier pattern described by the source, when their conversion rate had been nearly half as high. Adobe’s retail analysis covered more than 1 trillion visits and over 100 million SKUs.

    The contrast is important: AI referral traffic is not inherently high- or low-converting. Its commercial value depends on the category, the decision cycle and what remains unresolved when the visitor arrives. The recommendation stage may substantially reduce uncertainty for a specifications-led retail purchase while leaving a traveler with dates, availability, policies and other booking details still to settle.

    Readable content links discovery with the landing experience

    The two reports meet at content accessibility. The product study indicates that activating web search can substantially reshape recommendations and that cited-source mentions have a modest association with product visibility. Adobe’s travel analysis, meanwhile, suggests that a meaningful share of website content cannot be processed effectively by AI systems. Together, they point to an operational dependency: useful information must be available to the system before it can help form or substantiate a recommendation.

    Using its AI Content Visibility Checker, Adobe reportedly found that hotel homepages had 63% AI readability and car-rental homepages 59%. Product pages scored higher, at 73% for hotels and 71% for car rentals. Even so, the source said more than one-third of the content on leading travel pages remained unreadable to AI systems.

    Performance also varied by page type and sector. Hotels led in areas including destination guides, activities, search results, customer service and promotions. Car-rental companies performed best on FAQ pages, while cruise companies led in blog and news content. Airlines trailed the other major travel segments across the page types Adobe assessed. In retail, cosmetics and electronics benefited from detailed material such as ingredients, tutorials, specifications and how-to information, whereas grocery and furniture lagged.

    These findings do not justify writing pages solely for machines. They support a more durable principle: important facts should be explicit, consistently named and placed in accessible page content. Detailed descriptions, amenities, specifications, policies and practical guidance can serve an assistant’s evidence gathering while also helping the referred visitor verify the recommendation.

    Measurement must connect exposure, visits and outcomes

    Three linked visual stages show an AI recommendation, a visitor arriving at a website, and a completed outcome.

    A useful measurement model separates three questions. First, how often does the brand or product appear across repeated recommendation prompts, with and without search? Second, which cited pages and on-site facts are associated with those appearances? Third, what do referred visitors do after arrival, including engagement, progression and conversion?

    Each layer prevents a misleading conclusion. A single recommendation screenshot cannot establish durable visibility. A citation does not prove that the cited mention caused a recommendation. Strong engagement does not necessarily mean strong conversion, as the travel results demonstrate. Conversely, a lower volume of AI referrals may still be commercially meaningful when visitors arrive with a well-defined need, as the retail results suggest.

    The next competitive advantage is likely to come from joining these measurements rather than optimizing them independently. Brands that monitor recommendation variability, expose decision-critical information and evaluate post-click behavior by category will be better positioned to learn whether AI is merely mentioning them or delivering customers who can act.

    References

  • How to Build Content Authority Across AI Search Engines

    How to Build Content Authority Across AI Search Engines

    Content authority in AI search is not a single score that a brand earns once and carries everywhere. The source reports point to a more conditional system: visibility depends on the AI engine, the topic and prompt, the sources retrieved, and whether a useful passage can be extracted from the page.

    That changes the optimization task. Instead of producing one broad guide and accumulating undirected mentions, publishers need to decide where they want to appear, understand what that system retrieves for the topic, and create evidence-rich passages that can survive the final selection process.

    Authority now operates at three distinct layers

    A cutaway illustration shows a source network, modular content blocks, and selection lenses arranged in three layers.

    Taken together, the sources suggest that AI visibility has three layers: engine selection, topical trust, and passage extractability. A weakness at any layer can prevent a brand from being cited even when its conventional search performance is strong.

    The engine layer determines which index, retrieval process, and content formats are likely to enter consideration. Uncover 7 Unmissable AI Search Trends Transforming Marketing reports that ChatGPT and Claude shared only 8% of citations in the analysis it covered. It also reports substantial format differences: community sites accounted for about 16% of ChatGPT citations, while Claude cited listicles 36% of the time and opinion content 13.2% of the time, compared with approximately 20% and 7.2%, respectively, for ChatGPT.

    The topic layer determines whose evidence the system treats as relevant and credible. Boosting AI Visibility: Mastering Topic-Driven Authority argues that citation sources cluster by subject rather than following one universal hierarchy. Its examples indicate that competitor domains had a larger role in invoicing queries than in starting-a-business queries. A publication that matters for one part of a market may therefore contribute little authority to an adjacent part.

    The passage layer determines whether the system can isolate a clear answer from the selected document. Mastering AI Search: Building Machine-Friendly Content reports a 66% extraction rate for pages under 5,000 characters and 12% for pages over 20,000 characters. Those figures should be treated as findings reported by that article, not as a universal length rule. Their strategic significance is that authority without retrievable statements may never become a citation.

    Choose the engine and prompt class before optimizing

    An AI-search plan should begin with the audience and the engine it uses, not with a generic content calendar. The trends report says 64% of sites cited by Claude appeared in Google’s top 50 for corresponding queries, compared with 37% of sites cited by ChatGPT. It further reports that 79.2% of Claude citations aligned directly with the top 10 Brave Search results in the analysis it references. Within that reported environment, Brave rankings offer a more observable diagnostic for Claude than conventional Google rankings alone.

    Audience context may also affect prioritization. Citing Ramp’s AI Index, the trends article reports Anthropic usage at 34.4% of businesses and OpenAI at 32.3%. It also says approximately 85% of Anthropic’s revenue came from enterprise and API usage. These figures do not establish that every B2B organization should optimize for Claude first, but they support testing Claude as a distinct business channel rather than treating its consumer web traffic as a complete measure of relevance.

    Even a priority engine is not equally optimizable for every prompt. According to the same report, ChatGPT initiated web searches for nearly 95% of prompts in the cited analysis, while Claude did so about one-third of the time. Claude was reportedly more likely to search for current-event, ranking, location, and comparison prompts, with reported search rates of 81%, 67%, 55%, and 51%, respectively. Definitions and procedures were described as much less likely to trigger retrieval.

    This distinction prevents a common measurement error. A page cannot win a fresh web citation when an engine answers from internal model knowledge without searching. Prompt testing should therefore record whether retrieval occurred before a team interprets a missing citation as a content or authority failure.

    Query expansion adds another engine-specific variable. The trends report characterizes ChatGPT fan-out queries as changeable, while reporting that Claude produced the same fan-out strings 65% of the time and attached the current year to 94% of them, compared with 17% for ChatGPT. Stable expansions may support tightly targeted pages; volatile expansions call for broader coverage across owned, earned, community, and other relevant sources.

    Design passages around problems, claims, and constraints

    A modular claim block is supported by source, context, and constraint pieces while a scanning beam isolates it from surrounding blocks.

    Machine-friendly content is not simply shorter content. The more useful objective is modularity: each section should resolve a recognizable subproblem without requiring an AI system to reconstruct the answer from a long narrative.

    The machine-friendly content report recommends replacing broad category positioning with problem-specific positioning. Its illustrative shift is from identifying a company merely as an insurance provider to explaining that it addresses underwriting for first-time drivers under 25 who have been declined by standard insurers. The example also shows why constraints matter. Stating who a solution is not for, where it applies, or what condition changes the answer can make a claim more precise and credible.

    Headings should name the outcome or question addressed by the section. Paragraphs should open with a direct answer or citable claim, then add conditions, evidence, and explanation. The same source reports that explicit headings increased retrieval likelihood by 17.54% and says Gemini may use approximately 380 words for query grounding. These reported limits reinforce the value of self-contained sections, although they do not justify stripping away evidence or necessary nuance.

    The synthesis is a two-level editorial model. At page level, the article should offer a coherent argument for a human reader. At passage level, it should state entities, relationships, qualifications, and evidence clearly enough to be extracted independently. Narrative still has a role, but it should extend a usable answer rather than delay it.

    Build off-site authority inside the relevant source network

    On-site clarity makes a document usable; it does not make the publisher trusted by every system or for every topic. The topic-driven authority report recommends mapping the domains, publications, experts, and platforms that repeatedly appear in answers for the exact subject a brand wants to own. This is more focused than pursuing links or publicity from generally prominent sites without checking their topical role.

    That mapping should also distinguish content formats. The topic-authority report describes YouTube as an exception that can surface across larger language models and recommends working with recognized subject-matter experts and relevant LinkedIn voices. The engine trends report, meanwhile, finds that community content was more prominent in ChatGPT citations and that listicles and opinion pieces were more prominent in Claude citations. Together, these observations suggest that the right distribution mix depends on both the topic’s trusted entities and the target engine’s retrieval preferences.

    Concentration may matter more than raw mention volume. The authority report argues that recognition can move in jumps when a brand earns coverage from a highly trusted topical source, and it recommends ranking potential collaborators by authority tier. This remains a strategic recommendation from the source rather than proof that every high-profile placement will produce citations. Teams should validate it by comparing citation frequency before and after individual placements.

    Measurement should follow the same conditional structure. For each priority prompt, a useful record includes the engine, whether it searched the web, the apparent query expansions, cited domains, cited passage types, the brand’s inclusion, and the presence of paid placements. The trends report says ChatGPT ads can appear around competitor mentions, so organic citation monitoring and paid competitive monitoring should be kept separate. Otherwise, a purchased appearance can be mistaken for earned authority, or a strong organic mention can obscure a competitor’s paid defense.

    Key takeaways

    • Define authority by engine and topic; citation strength in one model or subject does not automatically transfer to another.
    • Confirm that the target prompt triggers web retrieval before investing in pages intended to earn fresh citations.
    • Build problem-specific, self-contained sections with direct claims, explicit conditions, and enough evidence to stand alone.
    • Concentrate outreach on the publications, experts, communities, and formats that already shape answers for the target topic.
    • Measure retrieval, organic citations, and paid placements separately so each visibility mechanism can be diagnosed accurately.

    As retrieval systems, source preferences, and advertising models change, durable advantage will come from maintaining this engine-topic-passage map as a living operating system rather than treating AI optimization as a one-time rewrite.

    References

  • How Meta AI Mode Changes Search and Discovery on Facebook

    How Meta AI Mode Changes Search and Discovery on Facebook

    Meta AI Mode changes Facebook Search from a results-finding tool into an answer-generating experience. According to CrushPress.AI’s report, Meta AI can respond to broad or specific queries using public material from Groups, Reels and other parts of Meta’s ecosystem.

    The immediate benefit is a faster route to community knowledge. The larger consequence is that an AI system now mediates which experiences, recommendations and brand discussions become visible, while important details about selection and attribution remain undisclosed.

    Facebook Search is moving from retrieval to synthesis

    The supplied report describes a departure from the familiar list of search results. Instead of requiring people to open and compare multiple items, AI Mode can assemble a direct response from relevant public content.

    This distinction matters. A conventional search interface leaves much of the evaluation to the user: results are displayed, sources can be inspected and conclusions are formed afterward. An answer interface performs some of that work before the user sees the output. Source selection, interpretation and presentation therefore become part of the search experience rather than steps taken entirely by the searcher.

    CrushPress.AI also reported that Meta AI can surface relevant public content as people navigate Facebook, extending discovery beyond a single results page. That suggests a closer connection between intentional search and recommendations encountered elsewhere in the product, although the report does not provide performance data showing how often this occurs.

    The feature shares the AI Mode name used by Google, as the report notes. The common label should not be treated as evidence that the two products use the same sources, ranking systems or answer-generation methods.

    Community experience is the central search asset

    A diverse group shares posts and videos that flow through a central AI lens.

    Facebook’s distinctive contribution is not simply an AI-written summary. It is the underlying pool of public conversations and creator material. The report positions Groups and Reels as sources of experience-based information about products, places, hobbies and everyday questions.

    This can make Facebook Search particularly relevant when a query benefits from practical opinions rather than a single canonical answer. A discussion may reveal how different people approached a problem, while a Reel may demonstrate an activity or product in context. AI Mode can potentially connect those formats in one response instead of making the user search each surface separately.

    The same strength creates an editorial challenge. Community posts can contain conflicting perspectives, incomplete context or highly individual experiences. An AI-generated answer necessarily decides which material to foreground and how to reconcile it. The usefulness of the response therefore depends not only on the available conversations but also on selection and synthesis decisions that the supplied report says Meta has not explained.

    Key takeaways

    • Meta AI Mode provides generated answers instead of relying solely on a conventional list of Facebook search results.
    • The reported source material includes public content from Groups, Reels and other surfaces within Meta’s ecosystem.
    • The feature could reshape discovery for recommendations, local information, hobbies, products and brand conversations.
    • Meta has not disclosed enough detail to establish how sources are selected, ranked or credited.
    • Brands and publishers should treat AI Mode as an emerging discovery layer, not as a channel with proven optimization rules.

    The visibility question has three unresolved layers

    A user observes social content passing through three translucent filtering layers before reaching an AI answer.

    The first unknown is eligibility. The report repeatedly identifies public content as the foundation for answers, but it does not define the complete eligible corpus or explain whether every type of public post is treated similarly.

    The second is selection. CrushPress.AI reported that Meta has not explained how particular posts, Groups or Reels earn inclusion. This leaves brands, creators and community administrators without a documented way to distinguish content that is merely available from content likely to influence an answer.

    The third is attribution. The report says it is unclear whether brands, creators or publishers will be informed when their content is used. That gap affects more than recognition. Without consistent source visibility or reporting, content owners may struggle to connect participation in Facebook conversations with AI-mediated exposure.

    CrushPress.AI further reported that the experience uses Meta AI and Muse Spark, while noting that Meta has not disclosed how Muse Spark affects ranking, source selection or answer generation. Until those roles are clarified, claims about a reliable Facebook AI optimization formula would be speculative.

    A practical response without invented ranking tactics

    Organizations can begin by separating content quality from presumed algorithmic influence. Public posts that clearly identify the subject, explain the circumstances and provide useful context are easier for people to understand regardless of whether AI Mode selects them. Specificity is a sound communication practice, but the supplied reporting does not establish it as a ranking factor.

    Brands can also examine the public discussions that already surround their products, locations or services. The goal is to understand the questions and language used by communities, not to flood those spaces with promotional material. Because AI Mode draws on public social interactions, genuine community participation may become more consequential even when a brand does not control the eventual summary.

    Where the feature is available, teams can document representative queries, the answers displayed, the content formats surfaced and any visible attribution. Repeating the same checks over time can reveal changes in presentation or source patterns. Such observations remain local tests, however, and should not be generalized into universal ranking rules without broader evidence.

    The decisive next development will be greater clarity about selection, attribution and measurement. Until Meta supplies it, the most defensible approach is to treat AI Mode as a new interface between public conversation and discovery: important enough to monitor, but too opaque for confident optimization promises.

    References

  • How to Measure AI Search Visibility Across Paid and Organic

    How to Measure AI Search Visibility Across Paid and Organic

    AI search visibility cannot be reduced to a single ranking. Brands now need to understand whether AI systems recognize them, represent them accurately, surface them for relevant needs, and contribute to business results across both unpaid and paid experiences.

    The three source articles illuminate different parts of that problem. Two Profound posts present a comparative AI-search leaderboard, while Search Engine Land argues that paid and organic activity increasingly influences the same AI-mediated brand environment. Together, they point toward a measurement model that combines competitive benchmarking, representation quality, audience intent, and commercial outcomes.

    One visibility system, multiple marketing levers

    Traditional search measurement often treats organic rankings and advertising performance as separate disciplines. The Search Engine Land article challenges that separation, reporting that AI is becoming part of search, assistants, productivity tools, and other experiences where advertising can also appear.

    The article traces part of this convergence through Google’s advertising products. It describes Dynamic Search Ads as using website content to help generate ad titles and make bidding decisions, then presents Performance Max as extending similar automation across surfaces including Search, YouTube, and Maps. Its central strategic claim is that content, brand information, and paid campaign data increasingly act as inputs to interconnected systems rather than isolated channels.

    This does not make paid and organic performance interchangeable. A paid placement, an organic citation, and an AI-generated brand recommendation still represent different user experiences. The useful synthesis is narrower: measurement teams should examine how those outcomes relate. Paid campaigns may expose valuable combinations of audience, intent, and profitability; organic content can then address the needs revealed by that evidence. In the other direction, clear and authoritative site content may give automated advertising systems better material from which to interpret the brand.

    What an AI-search leaderboard can and cannot reveal

    A transparent lens focuses on ranked geometric markers while broader audience, source, and pathway signals remain outside its view.

    The two Profound articles approach visibility from a comparative perspective. The introductory post describes the Profound Index as a leaderboard intended to benchmark AI-search performance. The rebuild announcement says the updated version emphasizes performance metrics, broader data sets, and a more intuitive interface.

    These are product descriptions from Profound rather than independent evaluations, and the supplied articles do not define the underlying methodology, coverage, weighting, or validation process. That limits the conclusions that can responsibly be drawn from them. They establish the intended role of the Index, but they do not provide enough evidence to treat any leaderboard position as a complete measure of market impact.

    A comparative index can nevertheless answer an important question: how does a brand’s observed AI-search presence compare with that of others under a consistent measurement approach? That view can help identify relative strength, weakness, or movement. It cannot, on its own, explain why the result occurred, whether the AI response represented the brand correctly, or whether the exposure affected customer behavior.

    The distinction matters because competitive visibility and business value are separate dimensions. A brand may appear frequently but in weak contexts, or appear less often while being strongly associated with profitable needs. Leaderboards are therefore most useful as discovery and benchmarking instruments, not as substitutes for diagnosis or outcome measurement.

    A measurement architecture for AI visibility

    An isometric measurement hub connects question signals, AI nodes, brand objects, customer outcomes, paid-media tiles, and organic-content tiles.

    The sources do not supply a complete measurement standard, but their combined perspectives support a practical architecture. It separates what an AI system displays from the inputs that may shape that display and the outcomes that follow. This is an analytical framework, not a description of metrics confirmed by the source articles.

    Observe presence and representation

    The first layer asks whether the brand appears for relevant questions and how it is portrayed. Useful observations include presence, prominence, citations or linked sources when available, the products or capabilities associated with the brand, and factual consistency. Competitor comparisons belong here, which is where a leaderboard or visibility index can contribute.

    Accuracy deserves its own treatment rather than being buried inside a visibility score. Search Engine Land warns that when an AI system lacks a sufficiently developed understanding of a brand, it may fill gaps with assumptions that do not match the intended narrative. More exposure is not automatically better if the resulting description is incomplete or misleading.

    Track the inputs that may explain change

    The second layer records controllable inputs: site content, product information, brand language, campaign coverage, and the audience-and-intent combinations being tested. Changes to these inputs should be logged alongside visibility observations. Without that record, a rising or falling benchmark remains descriptive rather than diagnostic.

    Paid activity is especially useful as a source of learning in the Search Engine Land account. The article proposes using campaign results to identify audience, intent, and profit combinations, then developing organic content around the combinations that perform well. That is a feedback loop, not proof that ad spending directly causes organic AI visibility.

    Connect exposure to outcomes cautiously

    The final layer connects AI-search observations with business evidence such as qualified visits, branded demand, leads, sales, or assisted journeys, depending on the organization’s goals and available data. Attribution will often be incomplete because an AI answer can influence a decision without producing an immediately identifiable click.

    For that reason, a sound scorecard should keep visibility, representation quality, and commercial outcomes distinct. Examining them together can expose relationships; collapsing them into one number can conceal whether progress came from broader exposure, better brand accuracy, or stronger conversion performance.

    Build a shared paid-organic operating loop

    Measurement becomes actionable when paid media, organic search, content, and brand teams use a common review cycle. The shared unit of analysis should be the audience need or intent rather than the channel. Teams can compare what users seek, what the brand publishes, how AI systems represent it, where paid campaigns succeed, and which outcomes follow.

    Governance is as important as tooling. A leaderboard owner can monitor relative visibility, a content or brand owner can assess representation, paid specialists can contribute campaign learning, and analytics teams can evaluate downstream behavior. Each perspective answers a different question, reducing the temptation to make a single platform metric carry more meaning than it supports.

    Key takeaways

    • Measure AI visibility as a combination of presence, accurate representation, competitive position, and business outcomes.
    • Use comparative indexes to find patterns and gaps, while checking their methodology before treating scores as authoritative.
    • Organize paid and organic analysis around shared audiences and intents, not separate channel reporting alone.
    • Treat paid campaign findings as evidence for content prioritization, while avoiding unsupported claims of direct causation.
    • Keep a record of content, brand, and campaign changes so movement in AI visibility can be investigated rather than merely reported.

    As AI-mediated discovery expands, the durable advantage will come from disciplined observation rather than any single score. Organizations that connect competitive benchmarks with representation checks and outcome evidence will be better equipped to adapt without confusing visibility with value.

    References

  • Microsoft and Google Ads Updates Shift Control and Measurement

    Microsoft and Google Ads Updates Shift Control and Measurement

    Two advertising-platform updates are changing different parts of campaign management: Microsoft is adding professional seniority as an audience signal, while Google is changing how certain impression-influenced Demand Gen activity is billed.

    Together, the changes illustrate a broader operating challenge for advertisers. More precise controls can improve campaign decisions, but only when targeting, optimization, billing and measurement remain aligned with the business outcome.

    Microsoft adds a professional-identity layer to targeting

    Anonymous professionals stand on tiered platforms while a targeting beam selects levels of seniority.

    CrushPress.AI’s Microsoft Ads report says LinkedIn Profile targeting now includes job seniority for Search and Audience campaigns. Advertisers can reportedly select from 10 levels, ranging from CXO to Volunteer, and apply the setting at either the campaign or ad-group level.

    The practical value is not merely narrower reach. Seniority can help distinguish people who may approve a purchase from those who influence, evaluate or use it. A B2B advertiser could therefore separate executive-oriented messaging about organizational outcomes from practitioner-oriented messaging about operational efficiency.

    The report also says the seniority filters can be used in observation mode. That gives advertisers a lower-risk way to examine performance by professional level without initially restricting delivery. Availability was reported for selected markets across the Americas, EMEA and APAC, so account-level access should be confirmed before campaign plans depend on the feature.

    Google ties some Demand Gen charges to impressions

    Generic ad cards pass through an eye-shaped impression sensor and feed tokens into a billing scale.

    CrushPress.AI’s Google Ads report describes a different kind of change. From July 15, Demand Gen campaigns on Discover using view-through conversion optimization are reportedly moving from cost-per-click billing to cost-per-thousand-impressions billing. The transition is described as automatic and limited to campaigns with that optimization enabled.

    The reported rationale is alignment: a view-through conversion credits an impression that precedes a later conversion even when the user does not click the ad, so impression-based billing more closely matches the behavior being optimized. Advertisers that do not want the new billing treatment can reportedly disable view-through conversion optimization.

    The updates affect different campaign levers

    Microsoft’s update changes audience interpretation: it offers another signal for deciding who should see an ad, how much that audience may be worth and which message it should receive. Google’s update changes the economic frame: advertisers using the affected optimization will pay according to exposure rather than clicks.

    That distinction matters when comparing results across platforms. A Microsoft segment may appear valuable because it identifies a strategically important professional group, even if its immediate conversion volume is modest. A Google campaign may generate more billable impressions without a corresponding rise in clicks, even while the system is pursuing view-through outcomes. Neither pattern can be interpreted responsibly through a click-only dashboard.

    The common requirement is measurement discipline. Audience quality, conversion value, impression volume, click activity and attributed conversions answer different questions. Platform settings determine which of those signals influence delivery and cost, while the advertiser must decide whether they represent meaningful business progress.

    Key takeaways

    • Microsoft’s reported seniority targeting can support separate bids, messages and analysis for decision-makers, influencers and practitioners.
    • Observation mode offers a way to assess seniority performance before using the signal to limit Microsoft Ads reach.
    • Google’s reported CPM transition applies to Discover Demand Gen campaigns using view-through conversion optimization, not every Demand Gen campaign.
    • Advertisers evaluating the Google change should track spend and impression movement alongside clicks, attributed conversions and downstream business results.
    • Cross-platform reporting should distinguish an audience-targeting change from a billing change instead of treating both as ordinary performance fluctuations.

    What advertisers should watch next

    Microsoft advertisers can begin with observation data and look for durable differences in lead quality before segmenting budgets aggressively. Google advertisers affected by the billing transition should document their pre-change delivery and cost patterns, then assess whether view-through optimization continues to fit their attribution standards and campaign purpose.

    As platforms connect campaign objectives more tightly to audience signals and charging models, account teams will need to review settings as strategic choices rather than background configuration. The most useful next step is to establish which business outcome each setting is meant to improve before the resulting platform metrics begin to move.

    References