Author: shivamcrushpressai

  • Google Manual Actions: A Prevention and Recovery Playbook

    Google Manual Actions: A Prevention and Recovery Playbook

    A Google manual action is more than a ranking problem for a business that depends on organic discovery. It can disrupt revenue, raise acquisition costs and place planned growth on hold while the organization investigates practices accumulated across content, links and commercial partnerships.

    The practical response is to treat search compliance as an operating discipline. Prevention requires visibility into old and new risks, while recovery requires evidence that the underlying system has changed rather than a handful of questionable pages being removed.

    Key takeaways

    • A manual action follows an identified policy violation and should not be diagnosed or managed like an algorithmic visibility change.
    • Legacy links, sponsored publishing arrangements and scaled content can remain liabilities long after the campaigns that created them have ended.
    • Prevention depends on recurring compliance reviews, clear ownership and controls that cover every team or partner able to publish or acquire links.
    • Recovery can take months and involve multiple reviews, according to the supplied CrushPress.AI article, so business continuity planning matters alongside SEO remediation.
    • A credible cleanup addresses the production and approval processes that allowed violations to accumulate, not only the URLs or links that were eventually discovered.

    Diagnose the incident before designing the response

    Manual actions and algorithmic changes can produce a similar visible symptom: declining search traffic. Their causes and remedies are different. The source article describes a manual action as a response to a verified violation of Google Search Essentials, whereas an algorithmic decline does not by itself establish that a reviewer found a specific policy breach.

    That distinction prevents two costly mistakes. The first is treating a confirmed compliance issue as an ordinary ranking fluctuation and waiting for it to reverse. The second is assuming that every traffic decline is punitive, then making broad changes without evidence. Teams should establish what triggered the investigation, which properties and publishing systems are implicated, and whether the problem is isolated or systemic before choosing a remedy.

    The business assessment should run in parallel. The supplied article reports that a manual action can affect revenue, customer acquisition costs and expansion plans, with effects that may continue after the policy problems are addressed. Leaders therefore need both a remediation owner and a continuity plan for the period in which organic visibility remains impaired.

    Prevention starts with a map of accumulated risk
    An overhead view of a team organizing abstract content, link, partnership, and workflow elements into different risk groups.

    Compliance exposure rarely belongs to one recent page. The source article presents it as something that can erode gradually: an ecommerce company accumulates questionable links, a publisher embeds commercial content in its main site, a software company produces weak location pages, or a lead-generation operation expands supplemental content without sufficient editorial scrutiny.

    A useful audit consequently looks beyond the current editorial calendar. It examines the historical footprint of the site and the business arrangements behind it. Paid placements, commercial guest posts and directory links from earlier campaigns may persist as unresolved liabilities, according to the article. A change in staff, agency or strategy does not remove what remains published or linked.

    What a recurring compliance review should cover

    • Link acquisition: identify who can commission, purchase, exchange or approve links and whether old campaigns remain visible.
    • Third-party publishing: review sponsored, affiliate, partner and contributor content, including how closely it is integrated with the site’s trusted sections.
    • Scaled page systems: examine templates, feeds and automation for repetition, unsupported claims and pages whose primary difference is a keyword or location.
    • Editorial accountability: confirm that named owners can stop publication, demand evidence, update weak material and remove content that no longer meets policy or quality expectations.
    • Change records: preserve decisions, approvals and remediation evidence so future reviewers can understand how a risky pattern arose and what ended it.

    These reviews should be independent enough to challenge established revenue practices. The source argues that even capable internal SEO teams can overlook exposure when the same organization designed or benefited from the underlying programs. Independence can come from a separate compliance owner, a cross-functional review group or qualified external scrutiny; the essential feature is freedom to question the system rather than merely inspect its output.

    Publishing scale changes the control problem

    Scale does not automatically make content problematic, but it multiplies the effect of weak judgment. The article identifies several patterns that can create exposure: nearly identical affiliate comparisons, cookie-cutter regional service pages, AI-assisted publishing with unsupported information and mass-produced destination material offering little original insight.

    The shared weakness is not a particular production tool. It is a system that can publish more quickly than the organization can verify usefulness, originality and factual support. A responsible workflow therefore places controls at the point of production: evidence requirements, sampling rules, approval thresholds, duplication checks and a mechanism for pausing an entire template or pipeline when a pattern fails review.

    Third-party content requires equally clear boundaries. The source warns that insufficiently supervised material can place the host publisher’s reputation and broader visibility at risk, including valuable sections unrelated to the problematic partnership. Commercial teams should not be able to bypass the standards applied to staff-produced content simply because a placement is contractually attractive.

    Recovery must prove that the underlying system changed
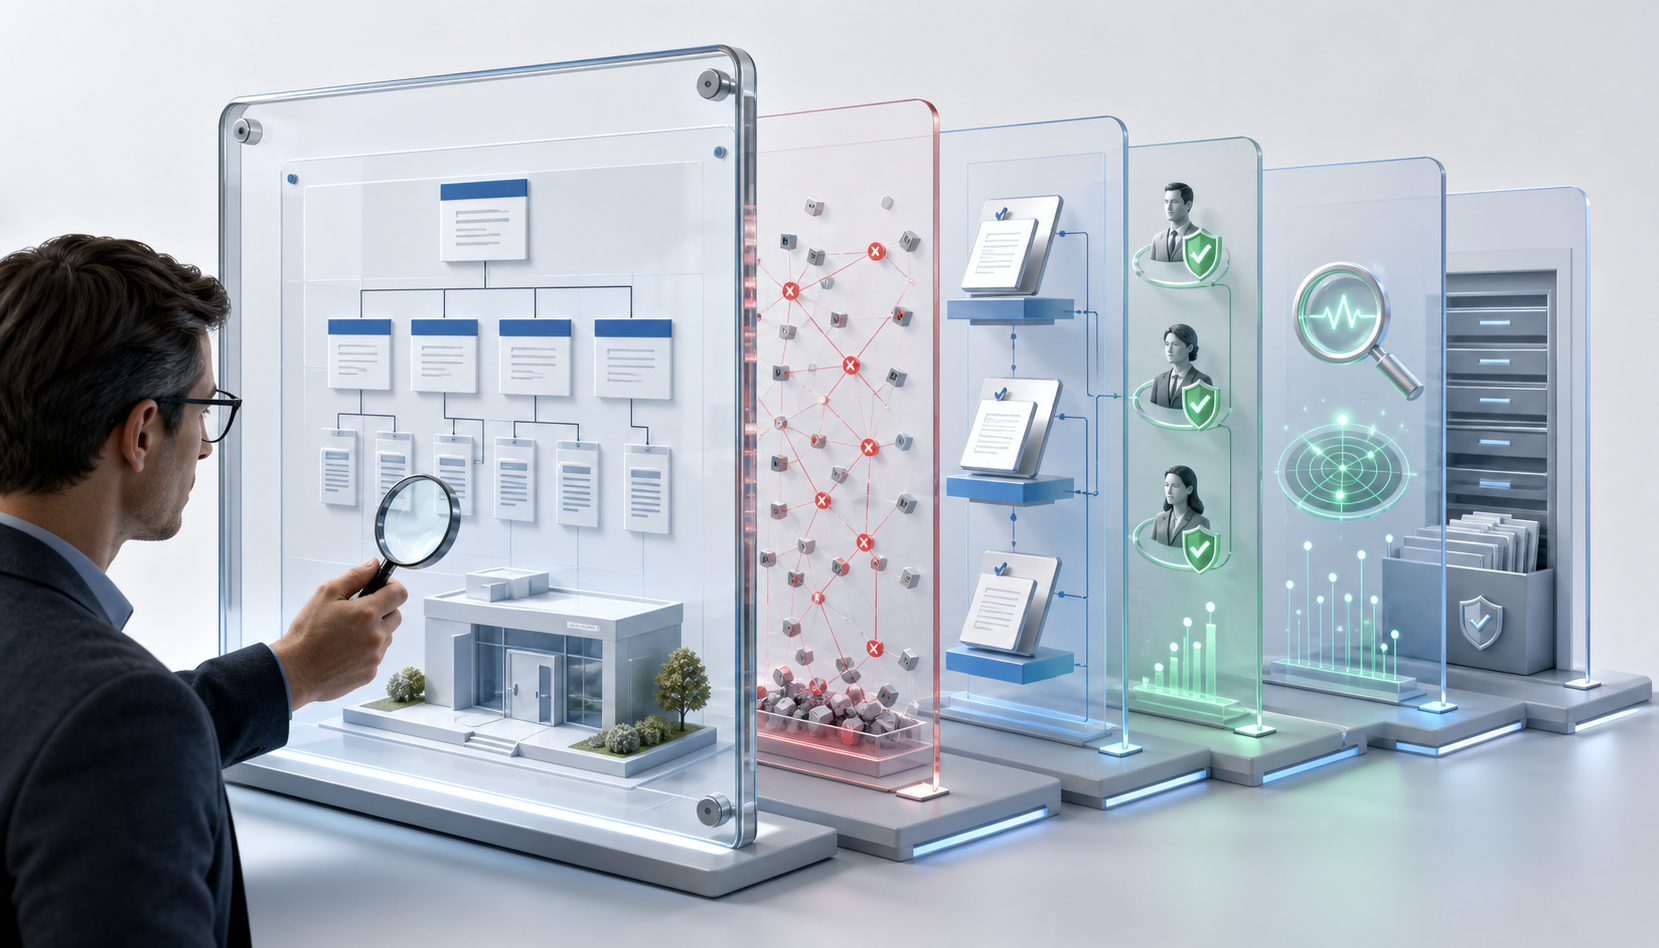
    An investigator reviews layered website controls showing removed risky connections, approval gates, monitoring, and organized remediation evidence.

    The supplied article characterizes recovery as expensive and potentially prolonged, sometimes taking months and multiple reviews. That makes superficial cleanup a poor strategy. Removing a visible batch of pages while leaving the same incentives, templates, vendor relationships or approval gaps in place does not resolve the source of the exposure.

    A defensible recovery sequence

    1. Stabilize the environment. Pause related publishing, link acquisition or partner activity so the suspected pattern does not continue during the investigation.
    2. Define the full scope. Inventory affected pages, links, templates, subdirectories, contributors, vendors and commercial programs rather than reviewing only the most obvious examples.
    3. Trace causes to controls. Determine which incentives, permissions or missing checks allowed the pattern to develop and persist.
    4. Remediate consistently. Remove, revise or otherwise address problematic material according to a documented standard, including older assets created under previous strategies.
    5. Change the operating model. Add accountable owners, approval gates, monitoring and escalation rules that reduce the chance of recurrence.
    6. Preserve evidence. Maintain a clear record of what was found, what changed and how the organization verified the work for any subsequent review.

    Recovery ownership should extend beyond the SEO team when the causes involve sales partnerships, affiliate revenue, editorial operations, automation or agency management. Otherwise, the team responsible for cleanup may lack the authority to end the practices that created the violation.

    Make search compliance part of business resilience

    The strongest prevention program connects search risk to ordinary governance: vendor oversight, publishing permissions, revenue approvals, audit schedules and executive risk reporting. This turns compliance from an occasional technical exercise into a repeatable decision process.

    Organizations should also plan for imperfect recovery timelines. Alternative acquisition channels, current customer communications and realistic internal forecasts cannot restore search visibility, but they can reduce the pressure to pursue another risky shortcut while remediation is underway.

    As publishing systems and commercial models evolve, the next priority is to review controls before scale is added. A business that can explain who approved a tactic, what evidence supported it and how it will be monitored is better prepared to prevent compliance erosion before it becomes an operational crisis.
    References

  • From Search Intent to Citation Share: Measuring AI Visibility

    From Search Intent to Citation Share: Measuring AI Visibility

    AI search visibility is becoming easier to observe, but measurement alone does not explain what content should change. Bing’s emerging reporting describes where a site appears across intents, topics and citations; the next-question intent framework examines whether its pages contain enough detail to support the comparisons and decisions behind those appearances.

    Used together, these perspectives create a practical loop: identify the contexts in which a site is being cited, inspect whether the underlying content supports the user’s full decision path, and then monitor how citation visibility changes.

    Two layers of intent explain different parts of visibility

    The Bing reporting source says the preview of its enhanced AI performance report classifies grounding queries by intent, including Informational, Commercial and Navigational categories. This is a reporting layer: it helps publishers understand the broad purpose associated with the queries for which their content surfaces.

    Next-question intent is an editorial layer. The separate analysis defines it as the information a person will need after the opening query to compare options, establish trust or make a decision. A page can therefore match an initial commercial query while still failing to answer the more specific questions that determine which option is suitable.

    The distinction matters because the two concepts should not be treated as competing taxonomies. Reported intent describes an observed visibility context. Next-question intent helps diagnose whether a page has enough substance to remain useful as that context becomes more specific.

    Key takeaways

    • Bing’s reported intent and topic views organize AI visibility by user purpose and thematic context rather than isolated queries alone.
    • Citation Share and Compare provide directional evidence about visibility, but they are not rankings, quality scores or proof of business impact.
    • Next-question intent connects reporting to content decisions by identifying the follow-up information users need to trust, compare and choose.
    • The strongest workflow reads intent, topic and citation signals together, then validates the relevant pages for specificity, evidence and decision support.

    How Bing’s reporting dimensions fit together

    An isometric website tile connects to groups of intent gateways, topic spheres, and citation markers.

    According to the Bing reporting article, the new enhancements are being introduced globally as a preview. The source says Bing had launched its underlying AI performance report in February and that a similar Google Search Console feature arrived in June. Those dates and the characterization of Google’s release come from the source and are not independently verified here.

    Reporting dimensionWhat the source says it showsUseful question for publishers
    IntentsGrounding queries classified into broad purposes such as Informational, Commercial and NavigationalIn what kinds of user situations is the site appearing?
    TopicsRelated queries grouped into thematic clustersWhich broader subjects are producing visibility?
    Citation ShareThe site’s percentage of citation visibility relative to other sourcesIs the site’s presence expanding or contracting within the measured set?
    ComparePrevious data overlaid on current reportingHow has citation activity changed between the displayed periods?

    These dimensions become more informative when read as a sequence. An intent indicates the general task, a topic identifies the subject area, Citation Share supplies a relative visibility signal, and Compare adds a time dimension. No individual metric provides the whole explanation.

    The source illustrates topic clustering with queries about solar panels and solar energy efficiency being grouped under a broader Solar Energy theme. It also cautions that labels may remain broad for niche domains during the preview. Topic names should therefore be treated as navigational aids for analysis, not as exact descriptions of every underlying query.

    Next-question intent turns observations into content diagnosis

    A report might reveal visibility in commercial, comparison-oriented experiences, but it cannot by itself determine whether a page answers the questions that shape a purchase. The next-question analysis uses a search for the best customer relationship management software for a small business to make this problem concrete. The opening request does not settle which product fits a two-person team, integrates with QuickBooks, works without a formal sales department or suits a local service company.

    Those follow-ups expose the difference between category relevance and decision utility. A page can accurately describe several products yet give an AI system little usable material for distinguishing who each product serves, when it is appropriate, how it differs from alternatives or what supports its claims.

    The analysis applies the same test to broad brand language. Claims such as customized strategies, family safety or suitability for small businesses remain underspecified unless the page explains how the offer is customized, which family members are covered, or which kinds of small businesses are meant. This is not a call to make pages longer by default. It is a call to replace ambiguity with relevant conditions, distinctions and evidence.

    For an informational intent, the next question may concern method, limitations or applicability. For a commercial intent, it may concern trade-offs, compatibility or fit. For a navigational intent, it may concern the exact destination or action available there. These examples are an analytical extension of the source framework rather than categories reported by Bing.

    A reporting-to-content workflow for AI visibility

    A circular sequence links citation observation, branching questions, expanded content blocks, and ongoing monitoring.

    Start with the intersection of intent and topic rather than a sitewide citation total. A change within a particular context is more actionable than an aggregate movement because it narrows the pages and user needs that deserve investigation. Citation Share can then indicate whether the site’s relative presence in that measured environment is moving, while Compare provides the period-over-period view described by the Bing source.

    Next, inspect the pages associated with that context as decision resources. The relevant test is whether they explain what the offering or subject is, whom it applies to, when it is useful, how alternatives differ and what evidence supports consequential claims. The next-question source argues that this substantive layer gives AI systems material they can synthesize, compare and use in recommendations.

    Content changes should address identifiable gaps rather than chase a metric mechanically. If a page appears around a comparison topic but lacks selection criteria, the useful revision is to clarify fit and trade-offs. If a niche topic label is broad, analysis should begin with the underlying pages and their actual subject matter instead of assuming that the dashboard label precisely captures demand.

    Finally, monitor the same intent-topic context over time. The Bing source notes that citation activity can be affected by AI model updates, changes in user demand and other factors. A rise or fall after an edit is therefore a signal for further investigation, not automatic evidence that the edit caused the movement.

    What current visibility reporting cannot establish

    Citation visibility is not equivalent to a conventional ranking. The Bing article explicitly describes Citation Share as directional and says it does not provide a ranking or quality score. A citation also does not, on its own, show whether the user clicked, converted, trusted the source or ultimately selected the brand.

    The source further says click and click-through rate data were still awaited. Without those measures, the reported tools are best suited to visibility diagnosis and trend monitoring. They should not be presented as a complete attribution system or as proof of commercial performance.

    Next-question intent has a boundary as well: it is a framework for improving content utility, not a guaranteed formula for earning citations. Its value is in making pages more explicit and decision-ready while reporting supplies evidence about where visibility exists and how it changes.

    As AI reporting develops, the durable advantage will come from connecting clearer measurements to better editorial questions. Publishers that preserve the distinction between an observed citation, an inferred cause and a verified outcome will be better positioned to improve content without overstating what the dashboards prove.

    References

  • AI-Assisted Hreflang Sitemap Automation: A Practical Guide

    AI-Assisted Hreflang Sitemap Automation: A Practical Guide

    AI can make hreflang sitemap production far more manageable, but the useful automation is not simply XML generation. The difficult part is deciding which URLs represent equivalent pages across domains, languages and regional site structures.

    A reported multilingual SEO project shows how crawl data, deterministic matching, semantic analysis and repeated human review can be combined into a practical workflow. Its broader lesson is that AI works best as a tool for developing and refining the matching system, while SEO specialists retain control of equivalence rules and quality assurance.

    The real challenge is URL equivalence, not XML syntax

    An hreflang sitemap groups alternate versions of a page and associates each version with an appropriate language or language-region value. Writing those relationships into XML is comparatively mechanical. Establishing that the relationships are correct is where complexity accumulates.

    The supplied case study involved more than a dozen websites across three businesses and eight regional domains. The sites covered several languages as well as three English dialects, while years of independent site development had produced translated folders, inconsistent slugs, changed directory structures and revision years appended to some URLs.

    Those conditions make a single matching rule unreliable. Identical paths can sometimes identify alternates, but translated slugs will not match character for character. Conversely, two pages with similar titles may serve different purposes and should not automatically be placed in the same hreflang cluster.

    A defensible automation workflow starts with crawl data

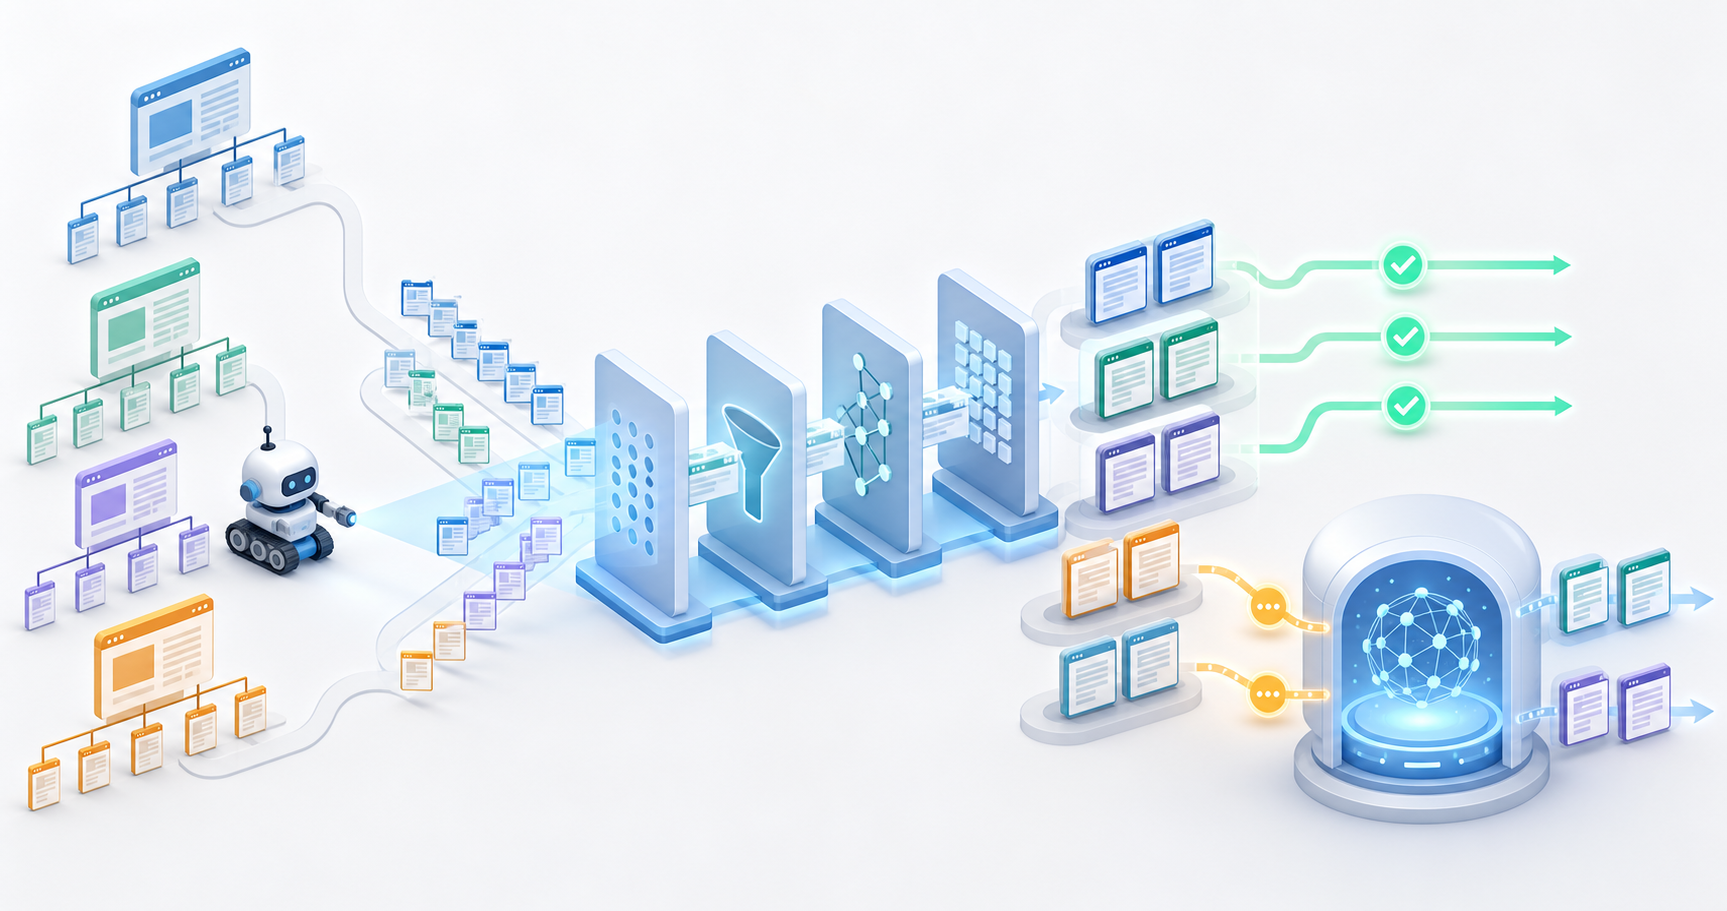
    An isometric web crawler gathers pages from several site structures and routes them through filters into matched and uncertain groups.

    The case study began by asking Google Gemini to propose an approach rather than immediately requesting finished code. That distinction mattered: the proposed architecture separated data collection, URL processing, matching and XML output, making each stage easier to inspect and revise.

    1. Crawl every participating site and export live URLs with useful comparison fields such as status codes, titles and H1 headings.
    2. Remove URLs that should not become hreflang destinations, including non-indexable pages and URLs that return errors or redirect elsewhere.
    3. Assign the intended language or language-region value through an explicit domain or directory mapping.
    4. Normalize URLs so superficial differences do not prevent legitimate comparisons.
    5. Run high-confidence deterministic matching before applying semantic methods to unresolved pages.
    6. Review candidate clusters, investigate unmatched URLs and correct false matches.
    7. Generate the XML only after the underlying relationship data passes validation.

    In the reported implementation, Screaming Frog supplied a unified CSV, while Python code ran in Google Colab and produced the XML tree. The author reported that Colab’s free version was sufficient for that project. These tools are implementation choices rather than requirements; the transferable principle is to preserve a clear path from crawl evidence to every generated relationship.

    Matching should progress from certainty to inference

    A reliable matcher benefits from layers. Exact and rule-based comparisons should resolve obvious cases first because their behavior is explainable. More flexible semantic methods can then focus on the smaller set of URLs that deterministic rules leave unresolved.

    Normalize without erasing meaning

    Normalization can remove known structural noise, such as a regional folder convention or a predictable revision suffix. The case study also encountered a US blog that had moved articles into topical directories while other regional sites retained flatter paths. Flattening those directories for comparison allowed related slugs to align.

    That technique should be scoped carefully. A directory may encode a content type, product family or audience distinction rather than incidental structure. The safe question is not whether a path segment can be removed, but whether removing it preserves the page’s identity.

    Use semantic signals as evidence, not proof

    The reported script used SentenceTransformers for fuzzy matching based on titles and normalized URLs. Its rules initially rejected a legitimate English-Italian article pair because their titles were not close enough. The author responded by relaxing some controls for broad industry concepts while keeping tighter requirements around critical terms.

    Another unresolved pair exposed a different limitation: the Spanish and English slugs expressed the same idea in different languages. The script was subsequently changed to build a combined semantic signature that translated slug meaning and used it alongside other page signals. This illustrates why title similarity, URL meaning and site context are stronger together than any one field in isolation.

    Human review remains part of the production system

    A specialist reviews proposed connections between unlabeled web page cards on a large screen beside an abstract AI light form.

    AI-assisted code does not eliminate the need for editorial and technical judgment. In the case study, the first output left some URLs orphaned, and later adjustments could have introduced overly aggressive matches. The improvement came through a repeated loop: run the script, inspect exceptions, provide concrete examples and revise the logic.

    Quality control should examine both sides of the matching problem. False negatives leave legitimate alternates disconnected; false positives assert equivalence between pages that do not satisfy the same user need. Review is therefore better organized around risk than around a single similarity score.

    • Confirm that every destination is live, indexable and intended for search discovery.
    • Check that each cluster contains genuinely equivalent content rather than merely related subject matter.
    • Inspect low-confidence matches and unmatched URLs separately.
    • Test normalization rules against pages where folders or suffixes carry real meaning.
    • Keep domain-to-language mappings explicit rather than asking a model to infer them repeatedly.
    • Validate generated XML structure and sample the resulting relationships before publication.

    The development process also needs an audit trail. Retaining the crawl input, normalized fields, match method and review status makes questionable clusters easier to diagnose. It also turns future reruns into a controlled workflow instead of an opaque model decision.

    Key takeaways

    • Hreflang automation is primarily a page-equivalence problem; XML generation comes after the relationships are established.
    • Clean crawl data and explicit language mappings provide the foundation for trustworthy output.
    • Deterministic rules should handle high-confidence matches before semantic techniques evaluate difficult cases.
    • Titles, normalized paths and translated slug meaning can complement one another, but none should be treated as conclusive alone.
    • Concrete mismatches and orphaned URLs are useful test cases for refining both code and business rules.
    • AI can accelerate tool development, while an SEO specialist remains responsible for validation and publication decisions.

    The most sustainable next step is to treat the matcher as maintained SEO infrastructure. As sites migrate, localization practices change and new content types appear, its rules and review samples should evolve with them. AI can shorten that maintenance cycle, but dependable hreflang still comes from observable data, bounded inference and accountable human approval.

    References

  • What Google Content Visibility Signals Really Tell Publishers

    What Google Content Visibility Signals Really Tell Publishers

    Google visibility is often discussed as if it could be improved through a single tactical change: choose a more successful headline pattern, add a machine-readable file, or imitate whatever appears to perform best across a large dataset. The source reporting points to a more demanding conclusion.

    A study of Google Discover headlines shows how an apparent format advantage can be driven by publisher and audience differences, while Google’s reported guidance on llms.txt says the file has no effect on Search rankings. Together, these accounts offer a practical way to distinguish an observable characteristic from a credible visibility lever.

    Visibility is not one outcome or one mechanism

    The two source articles address different Google environments. The Discover analysis concerns how often editorial articles appeared across the 1492.vision fleet. Its metric was hits per article, which the source described as a proxy for visibility rather than a count of Discover clicks. The llms.txt article, by contrast, concerns whether a site-level file affects visibility in Google Search.

    That distinction matters because a feature associated with frequent appearances on one surface is not automatically a ranking factor, a cause of traffic, or a general rule for Google visibility. A Discover headline can be correlated with exposure without causing it. A file can help another service understand a site while remaining irrelevant to Google Search. The surface, measured outcome, and proposed mechanism must therefore be identified before a result becomes actionable.

    Headline format looks powerful until publisher context is added

    Two contrasting publisher environments show different content-card styles, audience sizes, and distribution conditions around a central magnifying lens.

    The Discover report described an analysis of 1,674,518 English articles and 1,690,295 French articles from the 1492.vision corpus. When publishers were pooled, quote-led headlines produced 37% more hits per article than statements in English and 48% more in French. Questions also exceeded statements in the aggregate, by 7% in English and 16% in French.

    Those figures appear to support a simple editorial prescription. Yet the report argued that the aggregate comparison mixed together publishers with different audiences, subject matter, editorial styles, and patterns of Discover exposure. Celebrity publications, regional news organizations, and outlets focused on trending topics were among the types said to use quotations more often. Their underlying visibility could therefore make the quotation format look more effective than it was.

    The source identified this as an example of Simpson’s paradox: a relationship visible in pooled data can weaken, disappear, or reverse after the data is separated into meaningful groups. In this case, the relevant test is not simply whether all quote headlines outperform all statements. It is whether the formats perform differently within comparable publishers and contexts, with each publisher serving as its own baseline.

    This does not make headline construction irrelevant. It changes the claim that the evidence can support. The reported aggregate results describe where visibility occurred across a mixed population; on their own, they do not establish that converting a statement into a quotation will create the same lift for an individual publisher.

    Google’s llms.txt position removes a different false lever

    The second source reported that Google updated its AI Search optimization guidance to say that llms.txt files do not affect Search rankings. According to that account, Google Search does not use the files, and publishers do not need to create new AI-oriented text or Markdown files to qualify for inclusion in Search experiences involving generative AI.

    The reported guidance includes an important qualification: Google may still discover, crawl, and index various file types. That general ability does not mean llms.txt receives special ranking treatment. The source also noted that a site may maintain the file for other services without improving or damaging its Google Search visibility.

    This is a more direct finding than the Discover correlation. The headline analysis asks whether an apparent advantage survives contextual controls. The llms.txt guidance says the proposed mechanism is not used for the claimed Google Search benefit. One tactic requires better causal analysis; the other has been explicitly ruled out as a Google ranking aid in the source’s account.

    A stronger test for proposed visibility signals

    Glowing signal tokens move through a sequence of evidence checkpoints, with weaker signals diverted and stronger signals reaching an illuminated content card.

    The synthesis suggests that publishers should evaluate any claimed signal along three dimensions. First, the claimed outcome should be precise: ranking position, impressions, Discover appearances, clicks, or another measure. Second, comparisons should account for publisher, audience, topic, language, and surface whenever those factors could influence both the tactic and the outcome. Third, the proposed mechanism should be checked against Google’s stated use of the feature when relevant guidance exists.

    For headline decisions, the most informative evidence would come from comparisons within the same publication and from controlled editorial tests that keep topic and distribution conditions as comparable as possible. Hits per article can reveal exposure patterns, but it should not be presented as click performance or as proof that punctuation and syntax independently caused the result.

    For machine-readable files, the decision can be separated by beneficiary. An llms.txt file may be maintained for a non-Google service that uses it, but the reported Google guidance provides no basis for treating its creation as a Search ranking project. This prevents an implementation task from being justified with an unsupported visibility promise.

    Key takeaways

    • Google visibility claims must name the surface and metric; Discover hits, clicks, and Search rankings are not interchangeable outcomes.
    • The reported quote-headline advantage appeared in pooled English and French data, but publisher and audience differences made a simple format-based explanation unreliable.
    • Within-publisher comparisons are more useful than global averages when editorial conventions and baseline visibility vary across outlets.
    • According to the llms.txt source, Google Search does not use the file as a ranking aid, although sites may keep it for other services.
    • An observable pattern becomes actionable only after plausible confounders and the proposed mechanism have been examined.

    As new visibility tactics emerge, the durable editorial advantage will come from asking what was measured, what else could explain it, and whether the platform recognizes the proposed mechanism. That discipline leaves room for experimentation while keeping correlation, platform guidance, and causal claims in their proper roles.

    References

  • Why Better PPC Bidding Still Depends on Conversion Quality

    Why Better PPC Bidding Still Depends on Conversion Quality

    PPC bidding can determine which auctions an advertiser enters and how aggressively a campaign pursues demand. It cannot, by itself, determine whether a click becomes a qualified lead, a signed client, or profitable revenue.

    Taken together, the two source reports point to a more useful way to evaluate bidding: connect auction-time optimization with search intent, landing-page relevance, operational follow-up, and closed-loop measurement. That makes it possible to distinguish genuine growth from a larger volume of inexpensive but low-value conversions.

    Key takeaways

    • Automated bidding can explore additional demand, but its value depends on whether the campaign optimizes toward conversions that reflect business outcomes.
    • CPA and ROAS targets are operating controls, not complete measures of performance; qualified leads, signed cases, and revenue provide essential context.
    • Temporary bidding and budget changes can help capture peak demand when they are paired with sufficient fulfillment or intake capacity.
    • Search-term reviews, intent-specific landing pages, CRM outcomes, and offline conversion data give bidding systems more meaningful signals.
    • Budget allocation should follow marginal business value rather than lead volume alone.

    Why efficient bidding can still produce weak business results

    A platform can lower the reported cost per conversion while the underlying economics deteriorate. This happens when the conversion being optimized is too far removed from the outcome the advertiser actually values. A form submission, for example, may be easy to generate but may say little about qualification, purchase intent, or eventual revenue.

    The law-firm PPC source illustrates the problem through the difference between leads and signed retainers. It argues that cost per lead alone leaves out the intake process, response speed, qualification, and the rate at which qualified prospects become clients. Its recommended reporting chain extends from ad spend and leads through qualified leads, signed cases, CPL, and CPA, segmented by channel and practice area.

    That distinction also changes how an advertiser should interpret automated bidding. Google’s Smart Bidding Exploration update, as described in the other source, lets advertisers specify a ROAS tolerance so campaigns can pursue conversion opportunities beyond queries they might otherwise reach. The source reports that campaigns using the capability saw about an 18% increase in unique converting search-query categories and a 19% increase in conversions. Those are platform-reported expansion indicators; they do not establish that every additional conversion carried the same downstream value.

    The practical question is therefore not simply whether bidding found more conversions. It is whether the incremental conversions remained qualified and profitable after the full customer journey was considered.

    Conversion quality is built before and after the auction

    An auction gateway connects search-intent pathways on one side with a landing experience, human follow-up, and a business handshake on the other.

    Better outcome data begins with the query. The law-firm source recommends reverse-engineering keyword strategy from call transcripts and CRM records rather than beginning with broad, generic terms. It also advocates segmenting keywords and campaigns by intent, funnel stage, budget, and conversion objective, with weekly search-term reviews used to identify valuable language and exclude irrelevant demand.

    This creates an important complement to bidding automation. The algorithm decides among available opportunities, while campaign structure defines which opportunities are grouped together and which outcome signals they share. If high-intent and exploratory traffic are mixed under one target, an aggregate CPA can conceal substantial differences in lead quality.

    Landing pages provide the next quality filter. The law-firm report calls for alignment between the searcher’s intent and the page headline, supporting proof, fast mobile performance, and immediate contact options. It reports that replacing a generic page with intent-specific pages, recent reviews and results, and fewer form fields doubled one client’s conversion rate without additional ad spend. Because this is a single account example reported by the source, it should be treated as illustrative rather than a universal expectation.

    Post-contact operations complete the chain. The same source recommends a response time below 60 seconds, an answer rate above 90%, and a signed rate of 25% to 40% among qualified leads for the law-firm context. These are the source’s operational targets, not general benchmarks for every industry. Their broader significance is that slow or inconsistent follow-up can erase gains produced by bidding and landing-page optimization.

    Use automated expansion and peak bidding with guardrails

    Google’s reported updates introduce two distinct bidding use cases. Smart Bidding Exploration is intended to uncover incremental demand while allowing a degree of ROAS flexibility. Promotion Mode, described as a beta in the source, is designed for temporary changes to ROAS targets and daily budgets around seasonal events, product launches, and flash sales. The source also says Exploration was extended to Performance Max campaigns without product feeds and was being tested for Shopping ads in Performance Max and Standard Shopping campaigns.

    Exploration should be judged as a controlled expansion test. Advertisers need to compare the new query categories with established traffic on qualified-conversion rate, acquisition cost at the final outcome, and revenue contribution. Search-term analysis remains relevant even when automation broadens reach because it can reveal whether incremental volume represents new high-intent demand or merely looser matching.

    Promotion-oriented bidding requires a different guardrail: operational readiness. Raising a daily budget and relaxing a ROAS target may generate more opportunities during a short demand window, but the extra volume only has value if inventory, sales, intake, and customer service can process it. Temporary settings should also have a defined end point so an exceptional trading period does not quietly become the campaign’s permanent efficiency standard.

    For campaigns constrained by budget, the Smart Bidding source also reports a change intended to produce more consistent performance against CPA and ROAS targets. Consistency can make planning easier, but a target should not be treated as proof of profitability. Budget decisions still need to account for the quality and economic value of the outcomes being purchased.

    Build a measurement loop that bidding can learn from

    A circular system links an ad auction, webpage, customer conversation, agreement, and revenue, with outcome signals flowing back to the auction.

    A reliable PPC system connects UTMs, call tracking, website analytics, CRM stages, and final outcomes. The law-firm source specifically points to Google Analytics and CRMs such as Lawmatics or Clio as parts of that chain. Its emphasis is not the choice of software, but the ability to trace a click through qualification and retention rather than ending reporting at the ad platform.

    That closed loop supports better decisions at three levels. Search terms and landing pages can be evaluated by the quality they produce. Campaign targets can be based on downstream value instead of superficial conversion volume. Budgets can then move toward the channels, practice areas, or intent groups that contribute the strongest business outcomes.

    The law-firm source also recommends Marketing Efficiency Ratio as an ecosystem-level measure rather than evaluating every channel in isolation. Used alongside channel-level CPL, CPA, qualified-lead rates, and signed outcomes, it can help distinguish the contribution of the overall marketing mix from the performance reported inside a single platform.

    The next stage of PPC optimization is therefore less about choosing between automation and manual control than about improving the feedback connecting them. Advertisers that define valuable conversions, preserve intent distinctions, and return verified outcomes to the campaign will be better positioned to use bidding expansion without losing sight of profitability.

    References

  • AI Search Visibility: From Retrieval to Recommendation and Action

    AI Search Visibility: From Retrieval to Recommendation and Action

    AI search visibility is no longer adequately described by rankings or clicks alone. A brand may be discovered as a source, cited in an answer, recommended for a particular need or selected by an agent that completes a task – and each outcome requires a different kind of optimization.

    Read together, the source articles suggest a practical model for this environment: make the brand retrievable, unambiguous, independently credible, suitable for a defined audience and technically ready for action. This model connects traditional SEO, generative engine optimization and the emerging discipline of agentic search optimization without treating them as interchangeable.

    AI visibility is a chain, not a single ranking

    Traditional search usually exposes a list of pages and leaves most of the evaluation to the user. AI systems can compress several parts of that journey into one response. They may retrieve information from multiple sources, decide which evidence deserves a citation, compare possible providers and recommend an option that appears to fit the user’s circumstances.

    The CrushPress.AI article on retrieval versus citation makes an important distinction: being available to an AI system does not guarantee that the content will be cited. Its argument is that citation-worthy content must combine familiar technical SEO foundations with a useful experience, clear audience relevance and credible signals beyond the brand’s own website.

    The travel-focused source extends this distinction from citations to recommendations. It describes AI-assisted travel planning as a conversational process in which people ask for options matching constraints such as location, budget, atmosphere or family needs. The desired output is often a recommendation rather than a directory of links. The source framed around trust and brand visibility, meanwhile, reinforces the broader issue connecting these stages: an AI system needs sufficient confidence in the brand and its claims.

    The agentic-search article adds another stage. It distinguishes generative engine optimization, where a person still acts on an AI recommendation, from agentic search optimization, where software may evaluate options and execute the task. Its reported framework divides that process into retrieval, evaluation and action.

    Visibility stageQuestion the system must answerPrimary optimization needUseful measurement
    RetrievalCan the brand or content be found?Crawlable content, clear structure and relevant external mentionsPresence across a controlled set of prompts
    CitationIs this source useful and credible enough to support the answer?Specific evidence, clear explanations and corroborationCitation frequency and accuracy
    RecommendationIs the offering a strong fit for this user’s needs?Explicit positioning, suitability criteria and reliable attributesRecommendation share and represented attributes
    ActionCan the requested task be completed?Machine-readable information and a usable transaction pathCompletion, abandonment and assisted conversion

    This chain explains why a visibility strategy focused only on ranking can underperform. Retrieval is necessary, but it does not by itself produce a citation, recommendation or transaction.

    Resolve the brand, verify its claims and communicate fit

    A sharply defined faceted object is illuminated by connections from several independent evidence sources while similar objects remain blurred in the background.

    AI systems synthesize information from an ecosystem rather than treating a company’s website as the sole authority. Both the retrieval-versus-citation article and the travel-brand report emphasize the importance of consistent positioning across owned pages and third-party platforms. Read alongside the trust-focused source, their shared implication is that brand visibility depends partly on reducing uncertainty.

    A practical entity audit should answer several questions:

    • Is the brand’s primary category stated consistently?
    • Are its target customers and strongest use cases explicit?
    • Do the website and major external profiles agree on important facts?
    • Can important product, service or location attributes be found in structured, accessible content?
    • Do reviews, editorial mentions or other independent sources substantiate the positioning?
    • Are outdated descriptions or conflicting details weakening confidence?

    The travel article illustrates this with properties that serve different needs. A family-oriented hotel should consistently surface family suites, activities and relevant guest feedback, while a business hotel should make workspaces, connectivity, meeting facilities and location context clear. The wider lesson is not limited to travel: a brand should identify the situations in which it is a particularly good option and ensure those attributes recur accurately across the sources an AI system may consult.

    Structured data can help machines interpret categories, locations, amenities and other defined attributes. Server-side rendering, understandable page structure and sound technical SEO also remain relevant, according to the retrieval-versus-citation source. These measures improve accessibility and interpretation, but none should be presented as a guarantee of citation. Technical clarity supplies evidence; it does not manufacture authority.

    Independent corroboration therefore matters. The sources recommend relevant editorial coverage, digital public relations, reviews, guides and accurate platform listings. The objective is not to accumulate undifferentiated mentions. It is to have credible sources associate the brand with the same meaningful qualities that appear on its own site.

    Fit information deserves equal attention. The agentic-search article recommends suitability pages that state who an offering serves and who it does not. Boundaries can make a claim more credible and give an evaluating system information it can use. Useful pages might organize the decision around audience, use case, requirements, limitations, alternatives and proof rather than repeating broad promotional language.

    The evidence reported for agent behavior comes from one source and should be treated accordingly. The CrushPress.AI summary of a First Page Sage study says the researchers issued 2,417 agentic commands between March 4 and June 10, 2026. It reports that agents selected a platform’s top-ranked recommendation in 44.6% of commands but chose an option ranked fourth or lower in 38.2%. It also reports that pre-existing brand beliefs influenced 81.6% of evaluations. These findings have not been independently verified in the supplied material, but they support a useful strategic hypothesis: inclusion in the candidate set and perceived suitability are separate competitive problems.

    Prepare the conversion path for agent-led action

    A robotic hand moves a glowing token through connected digital gates toward an open package and a green completion light.

    Optimization changes again when software is expected to do more than make a recommendation. An agent may need to check requirements, compare prices, confirm availability, submit information or complete a purchase. Content that is persuasive to a person can still fail if the underlying process cannot be interpreted or operated reliably.

    The agentic-search source reports a large difference in its study between machine-actionable and non-actionable conversion pages. According to the article, agents completed 78.3% of attempts when the page was machine-actionable, compared with 9.6% when it was not; the source says agents often substituted a transactable competitor. Because this result comes from the study as described by a single publication, it should be treated as directional evidence rather than a universal benchmark.

    Organizations preparing for this stage can examine the complete task path:

    <!– wp:list {
  • Google’s Limited Ad Serving Expansion: What Advertisers Face

    Google’s Limited Ad Serving Expansion: What Advertisers Face

    Google’s expansion of its Limited ad serving policy adds a trust and identity layer to Search advertising visibility. According to CrushPress.AI, Google may restrict impressions when an advertiser appears unqualified, attracts negative user feedback, or makes its identity difficult to recognize.

    For advertisers, the practical issue is broader than formal policy compliance. Clear branding, an understandable offer, and consistency between the ad and landing page may now help determine whether an otherwise eligible campaign receives its intended reach.

    What the expanded policy changes

    CrushPress.AI reports that Google is extending Limited ad serving to more Search scenarios and plans to continue implementing the expansion through 2028. The policy gives Google greater scope to limit ads on searches where it believes showing them could result in a poor user experience.

    This distinction matters operationally. A campaign can have bids, targeting, and creative in place yet still encounter constrained exposure if Google does not have sufficient confidence in the advertiser or believes users could be confused about who is behind the message. That makes limited serving an eligibility and trust concern, not simply a conventional campaign-performance problem.

    Key takeaways

    • Google is expanding Limited ad serving across additional Search scenarios, according to CrushPress.AI.
    • Advertiser qualification, user feedback, and the clarity of the advertiser’s identity can influence ad visibility.
    • New advertisers, brands associated with negative feedback, and ads with ambiguous branding may face greater reach risk.
    • Advertisers should make the business identity, offer, and brand relationships easy to understand in both ads and landing pages.
    • A domain-focused first headline in a responsive search ad is one tactic reported as potentially helpful for clarifying identity.

    Trust signals now sit closer to campaign reach

    Two advertising pathways show a consistent storefront reaching a broad audience while an unclear, mismatched identity leads to a narrower audience.

    The source highlights two related signals: user feedback and advertiser identification. Advertisers that receive frequent complaints about misleading content or practices could have their ads limited. Restrictions may also apply when an ad does not make it easy for a searcher to determine who the advertiser is.

    Together, those signals create a wider standard than checking whether individual words or claims violate a rule. The apparent question is also whether the complete experience is trustworthy and intelligible: Is the business clearly named? Does the message explain what is being offered? Does the landing page confirm the same identity and purpose?

    This can be especially consequential for generic ad copy. A message built around a broad promise may leave little room for a recognizable brand, domain, or relationship disclosure. Similarly, an advertiser referring to another company, product, or service can create ambiguity if the affiliation is not explained. CrushPress.AI specifically advises advertisers to clarify brand affiliations rather than leaving users to infer them.

    Which advertisers have the most immediate exposure

    CrushPress.AI identifies newcomers, brands with negative feedback, and advertisers whose ads do not clearly present their identity as groups that could see their appearance frequency affected. These are not necessarily identical problems, so each calls for a different response.

    • New advertisers: The challenge is establishing recognizable and consistent identity signals when little history is available.
    • Advertisers receiving complaints: The priority is identifying whether users are reacting to unclear claims, misleading presentation, or a mismatch between the ad and the destination.
    • Businesses using generic creative: The immediate task is making the advertiser and offer explicit without forcing the searcher to interpret vague language.
    • Advertisers referencing other brands: The relationship should be stated accurately so the ad does not imply an affiliation that the landing page cannot substantiate.

    A reach decline should therefore be investigated separately from ordinary auction volatility. Adjusting bids or rewriting a call to action may not address a restriction rooted in identity confusion or trust. The diagnostic question should be whether the advertiser is understandable before the team treats the issue as a pricing or conversion problem.

    A practical audit for clearer advertiser identity

    A strategist reviews matching ad, landing page, and business identity mockups arranged on a desk with a laptop, magnifying glass, and checkmarks.

    The source recommends stronger brand visibility, less generic messaging, clearer affiliations, and alignment between ads and landing pages. Advertisers can turn those principles into a repeatable review:

    1. Read the ad without account context. Check whether an unfamiliar searcher could name the advertiser and understand the offer from the visible message alone.
    2. Review responsive search ad combinations. Make sure identity does not disappear when assets are assembled in different combinations. CrushPress.AI notes that placing a domain headline in the first position can help make the advertiser more apparent.
    3. Compare the ad with its destination. Confirm that the landing page promptly reinforces the same business name, domain, offer, and relationship described in the ad.
    4. Replace avoidable ambiguity. Rework generic promises, unclear pronouns, or language that could make one business appear to be another.
    5. State affiliations precisely. If the offer involves a partner, marketplace, reseller relationship, or another brand, describe that relationship accurately rather than relying on implication.
    6. Examine complaint patterns. Where feedback is available, look for recurring confusion about identity, claims, billing, fulfillment, or the nature of the offer, then address the underlying experience.

    The continuing rollout reported through 2028 makes this an ongoing governance issue rather than a one-time copy edit. Advertisers that incorporate identity clarity into creative reviews, landing-page checks, and feedback analysis will be better positioned to adapt as Google applies the policy to more Search situations.

    References

  • Paid Media Diagnostics: From Clean Data to Catalog Health

    Paid Media Diagnostics: From Clean Data to Catalog Health

    A weak paid media result can originate in several places: the reporting may be misleading, an advertised item may be unable to serve, or eligible inventory may simply be underperforming. Treating every symptom as an optimization problem risks changing bids, budgets, or creative before the underlying fault is known.

    Recent reporting on Google Analytics source controls and Microsoft Ads catalog diagnostics points to a more disciplined approach. Measurement integrity should be checked first, delivery eligibility second, and performance efficiency only after both foundations are credible.

    A diagnostic sequence for separating symptoms from causes

    The two source reports address different parts of the paid media system. The Google Analytics changes concern how traffic is classified and which domains contribute events to reporting. Microsoft Ads Product Explorer concerns whether catalog items are eligible, sufficiently described, and producing results. Together, they support a layered diagnostic model rather than a single dashboard verdict.

    Diagnostic questionLayer under reviewRelevant evidenceDecision it informs
    Can the reported traffic be trusted?Measurement integritySource classification and hostname provenanceWhether channel comparisons are reliable enough to guide budget decisions
    Could the advertised products serve?Delivery eligibilityCatalog status, required metadata, and identified feed issuesWhether reach is constrained before bidding or creative can have an effect
    How did eligible inventory perform?Performance efficiencyProduct-level results and consistently classified conversion trafficWhich items or channels warrant optimization, expansion, or closer investigation

    This sequence matters because similar symptoms can have unrelated causes. A channel can appear fragmented when one platform is recorded under several source names. A product can show no meaningful activity because it is not eligible to serve. Only after those possibilities are addressed does an efficiency diagnosis become well grounded.

    Clean attribution before comparing channel performance

    Tangled digital signals pass through a transparent filter and emerge as clean, distinct data streams.

    The Google Analytics source reported that a new Source Group reporting dimension consolidates variations of the same traffic source. Its example groups labels such as “facebook” and “fb” into one recognizable value. It also reported improvements to the Source Platform field intended to make classifications more consistent across advertising channels.

    For paid media diagnostics, that standardization reduces a common analytical distortion: one platform appearing as several small sources while another appears as a single consolidated source. The report said the structure extends beyond Google properties to platforms including TikTok, Pinterest, and Amazon, while also accounting for AI-originated traffic such as ChatGPT and Perplexity. It further said source-group information is available retroactively for historical analysis.

    Source consolidation does not resolve every attribution limitation. It makes labels more coherent, but a consistently named source is not automatically proof that the source caused a conversion. Analysts still need to distinguish reporting consistency from causal measurement and apply the same attribution interpretation when comparing channels.

    The reported hostname filters address a separate trust issue. According to the Google Analytics source, administrators can exclude events from unapproved domains before those events enter reporting. This can help prevent traffic associated with unexpected hosts from influencing campaign analysis. The practical control is to document which domains are legitimate before filtering; otherwise, an overly narrow approval set could remove activity that should have remained visible.

    Check catalog eligibility before optimizing retail campaigns

    Generic retail products move through eligibility checkpoints while a few incomplete or unavailable items are diverted for inspection.

    Microsoft Ads Product Explorer moves the investigation from attribution to inventory readiness. The Microsoft-focused source described a searchable catalog interface with filters for SKU, title, GTIN, and product ID. It reportedly surfaces eligibility problems, metadata gaps, and other conditions that may stop products from serving, while providing recommended actions and exportable filtered product lists.

    This changes how low delivery should be interpreted. If a product is ineligible or lacks necessary feed information, adjusting campaign-level settings does not address the immediate constraint. Catalog remediation comes first. Once an item is active and capable of serving, its advertising results can be evaluated as a performance issue rather than confused with a feed-health issue.

    The source also reported product-level performance visibility covering the previous 30 days. That window can connect operational diagnostics with observed activity: advertisers can distinguish products blocked by catalog problems from active items receiving exposure or producing results. The report stated that Product Explorer was live in advertiser accounts, although the source did not independently test its coverage or recommendations.

    Turn cleaner evidence into better optimization decisions

    The strongest synthesis is not a new all-in-one metric. It is a division of diagnostic responsibilities. Analytics source controls help establish whether cross-channel reports are internally coherent. Catalog tools help establish whether retail inventory can participate in the auction. Performance analysis then assesses what happened among the traffic and products that survived those checks.

    That separation also clarifies ownership. Measurement anomalies belong with analytics governance; product eligibility and metadata gaps belong with feed operations; efficiency questions belong with campaign management. Teams can still investigate collaboratively, but each finding should be routed to the layer capable of correcting it.

    A defensible performance review should therefore record both the result and the conditions under which it was observed. Channel comparisons should note whether source grouping and hostname controls were reviewed. Retail conclusions should note whether the relevant products were eligible and whether catalog issues were present. This creates an audit trail that makes later changes in reported performance easier to interpret.

    Key takeaways

    • Validate source classification and domain provenance before moving budget based on cross-channel reports.
    • Treat source standardization as a reporting improvement, not as proof of causal attribution.
    • For retail advertising, resolve eligibility and metadata problems before diagnosing low delivery as a bidding or creative failure.
    • Evaluate product and campaign efficiency only after measurement integrity and serving readiness have been checked.

    As advertising platforms automate more campaign execution, diagnostic discipline becomes more important, not less. The next useful advance will be a repeatable review process that connects trustworthy measurement, servable inventory, and performance decisions without collapsing them into the same signal.

    References

  • SaaS Freemium Conversion Benchmarks: A Funnel-Level Guide

    SaaS Freemium Conversion Benchmarks: A Funnel-Level Guide

    A freemium benchmark is only meaningful when its denominator is clear. Visitor-to-free-user conversion measures acquisition, while free-user-to-paid conversion measures monetization; neither rate alone describes the complete funnel.

    The supplied 2026 report covers more than 80 SaaS clients observed between 2022 and 2026. It provides useful comparisons across industries and offer types, but it is the only benchmark study supplied here. The figures therefore represent one publisher’s dataset rather than a cross-publication consensus.

    Two conversion rates define the freemium funnel

    The report separates the journey into two stages. The first asks how many website visitors become free users. The second asks how many of those free users subsequently pay. This distinction prevents a strong signup rate from obscuring weak monetization, or a strong upgrade rate from obscuring limited free-user acquisition.

    For traditional freemium, the report gives a 13.7% visitor-to-freemium rate and a 3.7% freemium-to-paid rate. Multiplying those stages produces an implied visitor-to-paid conversion rate of approximately 0.51%, or about 51 paid conversions per 10,000 visitors. That calculated figure is not a separately reported benchmark; it is a way to place both reported stages on a common denominator.

    This full-funnel view changes how performance should be diagnosed. A company below the visitor-to-free benchmark likely has an acquisition, messaging, or signup issue. One attracting free users successfully but converting few of them to paid plans should examine activation, upgrade value, qualification, and the boundary between free and paid functionality.

    Industry leaders change with the metric

    The report’s industry results do not identify one universal winner. Healthcare/MedTech has the highest reported visitor-to-freemium rate at 15.2%, while Legal/LegalTech has the highest freemium-to-paid rate at 6.1%. Calculating the two stages together puts Legal/LegalTech first on implied visitor-to-paid conversion, at approximately 0.87%.

    IndustryVisitor to freemiumFreemium to paidImplied visitor to paid*
    Advertising/AdTech14.1%3.8%0.54%
    Agriculture/AgTech12.0%4.6%0.55%
    Communications12.4%3.8%0.47%
    CRM13.1%3.7%0.48%
    Cybersecurity12.2%3.6%0.44%
    Education/EdTech13.9%2.6%0.36%
    Enterprise12.2%3.8%0.46%
    ERP14.0%5.2%0.73%
    Financial/Fintech13.9%4.1%0.57%
    Healthcare/MedTech15.2%3.9%0.59%
    HR12.8%3.3%0.42%
    IoT15.0%3.6%0.54%
    Legal/LegalTech14.2%6.1%0.87%
    Real Estate/PropTech11.7%2.9%0.34%
    RegTech13.7%5.3%0.73%

    *Calculated by multiplying the two reported stage rates, then rounding to two decimal places.

    The calculation also surfaces patterns hidden by signup performance. EdTech’s 13.9% visitor-to-free rate matches Fintech’s and exceeds several other industries, but its 2.6% free-to-paid rate lowers its implied end-to-end result to roughly 0.36%. ERP and RegTech take different routes to nearly identical implied outcomes of about 0.73%: ERP combines 14.0% acquisition with 5.2% monetization, while RegTech combines 13.7% with 5.3%.

    Free trials trade reach for stronger paid conversion

    Two abstract software adoption paths show a wide gateway with many entrants and few finishers beside a narrower gateway with fewer entrants and a higher share of finishers.

    The report distinguishes three free-forever structures. Traditional freemium offers a functional but substantially limited product; Land & Expand supports individual use but requires payment at the organizational level; and Freeware 2.0 provides a fully functional free product with optional paid additions. It also compares opt-in and opt-out trials, with opt-out trials automatically becoming paid subscriptions when the trial ends.

    Offer typeVisitor to free offerFree offer to paidImplied visitor to paid*
    Traditional freemium13.7%3.7%0.51%
    Land & Expand14.5%3.0%0.44%
    Freeware 2.013.2%3.3%0.44%
    Opt-in free trial7.8%17.8%1.39%
    Opt-out free trial2.4%49.9%1.20%

    *Calculated from the two reported stage rates and rounded to two decimal places.

    The trial formats reach fewer visitors than the freemium formats in this dataset, but a much larger share of trial users become paid customers. The opt-out trial posts the highest second-stage rate, 49.9%, yet its low 2.4% visitor-to-trial rate produces a lower implied visitor-to-paid result than the opt-in trial: approximately 1.20% versus 1.39%.

    That comparison shows why the highest rate at one stage is not automatically the best overall model. It also does not establish which format creates better customers. The supplied report does not provide retention, churn, revenue, acquisition cost, customer quality, or post-conversion cancellation data, so those outcomes cannot be inferred from initial paid conversion alone.

    Key takeaways

    • Always identify the denominator: visitor-to-free and free-to-paid rates answer different questions.
    • Traditional freemium’s reported 13.7% and 3.7% stage rates imply approximately 0.51% visitor-to-paid conversion.
    • Industry ranking depends on the stage measured; Healthcare/MedTech leads free-user acquisition, while Legal/LegalTech leads free-to-paid and implied end-to-end conversion.
    • Free trials outperform the freemium formats on implied initial visitor-to-paid conversion in this dataset, but the report does not establish their retention or economic superiority.

    Use benchmarks as diagnostic ranges, not targets

    A transparent segmented funnel sits in an analytical console with glowing tokens at different stages and a magnifying lens over one bottleneck.

    A useful benchmark comparison begins with aligned definitions. The start and end events, attribution window, treatment of returning users, eligibility rules, and meaning of a paid conversion should be consistent before an internal rate is compared with an external figure. Otherwise, apparent underperformance may be a measurement difference.

    Teams should then compare each funnel stage separately and segment results by relevant acquisition and customer groups. The benchmark can indicate where investigation should begin, but product economics should decide what to optimize. More free accounts are not inherently valuable if they increase service costs without producing activation, durable revenue, or expansion.

    As additional cohort data accumulates, the strongest operating benchmark will be the company’s own trend: consistently defined, segmented, and connected to retention and revenue rather than limited to the first payment.

    References