Author: shivamcrushpressai

  • AI Platforms Face Publisher Accountability on Two Fronts

    AI Platforms Face Publisher Accountability on Two Fronts

    Publisher accountability disputes are converging on two different stages of the AI supply chain: how platforms acquire protected material and what they say after processing it. One dispute challenges the collection and distribution of publisher content through Common Crawl; another treats false statements in Google’s AI Overviews as content for which Google may be directly responsible.

    Together, the reports suggest that platforms may find it harder to rely on a single intermediary defense. Publishers are pressing for control before their work enters AI systems and for meaningful remedies when those systems generate unsupported claims.

    Key takeaways

    • AI accountability is developing at both the input layer, where publisher content is collected, and the output layer, where generated answers can affect publishers.
    • Digital Content Next argues that copyright requires permission rather than a publisher opt-out, while Common Crawl disputes allegations that it bypasses paywalls or misleads publishers.
    • The reported Munich ruling treated disputed AI Overview statements as Google’s own content because they presented standalone claims rather than merely directing users to sources.
    • Links and removal procedures do not resolve the same problem: attribution cannot correct an unsupported generated accusation, while output accuracy does not answer whether source material was authorized.

    One accountability debate begins before generation
    Unmarked documents move toward an AI intake portal through a transparent gate that separates controlled pathways and preserves glowing provenance links.

    The Common Crawl dispute concerns the material available to AI developers before a model produces any answer. According to the source report, Digital Content Next sent the Common Crawl Foundation a cease-and-desist letter demanding that it stop collecting and distributing protected content belonging to its members. The organization also sought removal of member content already present in datasets, including paywalled and subscriber-only articles.

    The report identifies Digital Content Next as representing publishers including the Associated Press, The New York Times, NBC Universal, Bloomberg, NPR and Fox. Its position is that copyright is not an opt-out regime and that making protected material available for AI development without authorization or compensation constitutes infringement. These remain claims advanced by the publisher group, not findings reported as having been resolved by a court.

    Common Crawl presents a different account. Executive Director Rich Skrenta denied bypassing paywalls or misleading publishers and said the foundation responds to requests to remove previously collected material within the constraints of its dataset architecture. The source also notes that Common Crawl maintains a registry of sites that have opted out, while Digital Content Next questions whether the organization’s stated compliance has been adequate.

    The practical importance extends beyond one crawler. The report describes Common Crawl, established in 2008, as a repository containing billions of webpages and as an important source of AI training material. It also relays two indicators of that role: The New York Times’ 2023 lawsuit against OpenAI reportedly said Common Crawl supplied 60% of GPT-3’s training data, and a 2024 Mozilla Foundation paper reportedly concluded that generative AI would scarcely exist in its current form without the repository. Those figures and characterizations are source-reported rather than independently verified here.

    A second debate begins when an AI answer causes harm
    Readers face information tiles projected by an AI terminal while one warped tile casts a fractured shadow on a publisher's desk.

    The reported German ruling addresses a later stage: responsibility for claims generated after information has been collected and processed. The Regional Court of Munich reportedly considered false AI Overview statements that connected two Munich publishers with scams and questionable practices even though the linked pages did not support those allegations.

    According to the account, the misinformation resulted from the system conflating information about other entities with information about the publishers. That detail matters because the disputed allegations apparently could not be traced to the cited pages. If Google were treated only as a conduit, the affected publishers would have no obvious third-party author to pursue for the newly assembled claim.

    The court reportedly rejected that characterization. It viewed AI Overviews as processing material and presenting it in a distinct form, not simply listing third-party pages. Because the accusations appeared as complete answers and were created through a feature and algorithms controlled by Google, the court treated them as Google’s own content. Traditional protections for search engines acting as indirect intermediaries therefore did not apply in the same way.

    The presence of links did not shift the burden back to users. The ruling account says the court rejected the argument that readers could verify the claims by opening the cited pages, reasoning that the Overview presented assertions that stood on their own. The resulting injunction required Google to refrain from repeating the disputed allegations. The court also reportedly considered comparison against primary sources technically possible, at least in analogous circumstances.

    Permission, provenance and accuracy require separate controls

    The two disputes are related, but they should not be collapsed into a single copyright or misinformation issue. The Common Crawl conflict asks whether material may be copied, retained and redistributed for AI development. The Munich case asks who owns the consequences when a platform transforms information into a new, unsupported statement. A platform could improve its answer verification without resolving a publisher’s rights objection, just as it could license every source and still generate a false claim.

    Provenance also has different functions at each stage. During collection, it can identify where material came from, what access conditions applied and whether a removal request covers stored copies. At the answer stage, citations can help users inspect supporting material, but they do not establish that the generated wording is supported. The Munich report illustrates the gap: the pages were linked, yet the allegations attributed to them were reportedly absent.

    This distinction changes what meaningful platform accountability looks like. Input governance concerns authorization, access controls, opt-out or consent signals, retention and downstream distribution. Output governance concerns entity matching, faithful synthesis, verification against cited material, correction and prevention of repeated harmful claims. Treating either set of controls as a substitute for the other leaves publishers exposed at a different point in the system.

    What publishers can learn from the two disputes

    For publishers, evidence should be organized around the stage at which the alleged failure occurred. A collection dispute depends on records such as ownership, access conditions, crawler instructions, removal correspondence and the continued presence or distribution of material. A generated-answer dispute instead depends on preserving the exact output, its citations, the underlying pages and the differences between what those pages say and what the platform asserted.

    The reported cases also make platform promises worth examining at an operational level. A stated opt-out policy is not the same as confirmed removal from existing datasets. A cited answer is not necessarily a supported answer. A correction mechanism is not necessarily protection against repetition. Publishers evaluating an AI platform’s accountability can therefore ask whether its controls cover historical data as well as future collection, and whether answer citations are checked for actual support rather than merely attached.

    Legal conclusions will depend on jurisdiction and the facts of each dispute, so the German ruling should not be treated as a universal rule and Digital Content Next’s allegations should not be treated as adjudicated findings. Their combined significance is narrower but still substantial: AI systems are prompting separate challenges to assumptions that web access implies permission and that automated synthesis remains neutral intermediation.

    If consent requirements become stronger, the Common Crawl report suggests that licensed sources could gain importance relative to broadly collected web content. If courts continue to distinguish generated answers from conventional search results, platforms may also need more rigorous source validation and remedies at publication time. The durable accountability model will have to govern both directions of the exchange: what AI platforms take from publishers and what they publish about them.
    References

  • Google AI Search Ads: Access, Control and Measurement

    Google AI Search Ads: Access, Control and Measurement

    Google’s AI-enhanced search experiences are changing more than ad placement. They are separating campaign management into three distinct questions: how advertisers gain access to AI Search inventory, how they guide automated decisions, and how they measure results when reporting remains incomplete.

    The supplied CrushPress.AI report, based on a discussion involving Google Ads Liaison Ginny Marvin and the PPC Chat community, offers useful answers across those questions. Viewed together, its details point to a system in which participation remains relatively open, but effective optimization increasingly depends on strong data and carefully defined instructions.

    Key takeaways

    • AI Max is not reported to be a prerequisite for ads to appear in AI Overviews or AI Mode.
    • Broad match can provide a route into AI Search inventory, while AI Max can extend matching beyond the advertiser’s explicit keyword set.
    • AI Search ads do not yet have a distinct reporting breakdown, limiting advertisers’ ability to isolate their contribution.
    • Google’s direction combines automated matching with advertiser guidance, first-party data and measurement designed for longer conversion cycles.

    AI Search eligibility is broader than AI Max

    One of the most consequential distinctions in the report is between eligibility and expansion. According to CrushPress.AI’s account of Marvin’s comments, advertisers do not need to enable AI Max merely to participate in Google’s AI-driven search experiences. Search campaigns using broad match keywords can still be eligible for AI Overviews and AI Mode.

    AI Max instead appears to widen the matching opportunity. The report says it can apply broad-match behavior to phrase and exact match keywords while also enabling keywordless matching. That makes AI Max less of an admission ticket and more of an additional discovery mechanism.

    This distinction should shape campaign decisions. An advertiser can evaluate AI Search exposure separately from the decision to grant Google more latitude in matching queries. The relevant question is therefore not simply whether to adopt AI Max, but whether its broader reach fits the campaign’s economics, message constraints and tolerance for automation.

    Reporting has not caught up with the new inventory

    An analyst examines fragmented advertising signals as some data paths vanish behind translucent blank reporting panels.

    Access to AI Search inventory does not currently come with equivalent visibility. The source reports that ads appearing in AI Overviews and AI Mode are recorded like other top-of-page ads, without a separate reporting breakdown. It also says Google was still determining what dedicated reporting should eventually look like.

    That creates an important analytical limitation. Advertisers may participate in AI Search without being able to isolate its traffic, conversion performance or incremental value from standard search placements. A campaign-level improvement cannot automatically be attributed to AI inventory, while a weak result does not reveal whether the problem arose from an AI placement, another top-of-page impression or a broader campaign setting.

    Until reporting becomes more granular, AI Search should be treated as part of the campaign’s combined delivery environment. Conclusions about its standalone effectiveness would go beyond the evidence available in the reported interface.

    AI Brief and first-party data serve different roles

    The report describes AI Brief as a forthcoming control layer for AI Max. Advertisers are expected to be able to supply guidance covering matters such as target audiences, preferred message themes, priority search intents and prohibitions including instructions not to mention prices. CrushPress.AI says the rollout was planned to begin with English-language Search campaigns before extending to Performance Max and Shopping campaigns.

    Those instructions and an advertiser’s data are complementary rather than interchangeable. AI Brief can communicate strategic boundaries: whom a campaign should address, which ideas it should emphasize and what it should avoid. First-party data provides signals about actual customer and conversion outcomes.

    CrushPress.AI reports that Google emphasized data quality through a concept called Data Strength and pointed to Enhanced Conversions and Google Tag Gateway as important tools. The broader implication is that automation does not eliminate foundational measurement work. If the underlying signals are incomplete or unreliable, more sophisticated matching and creative guidance cannot supply the missing business evidence.

    Measurement is moving toward longer customer journeys

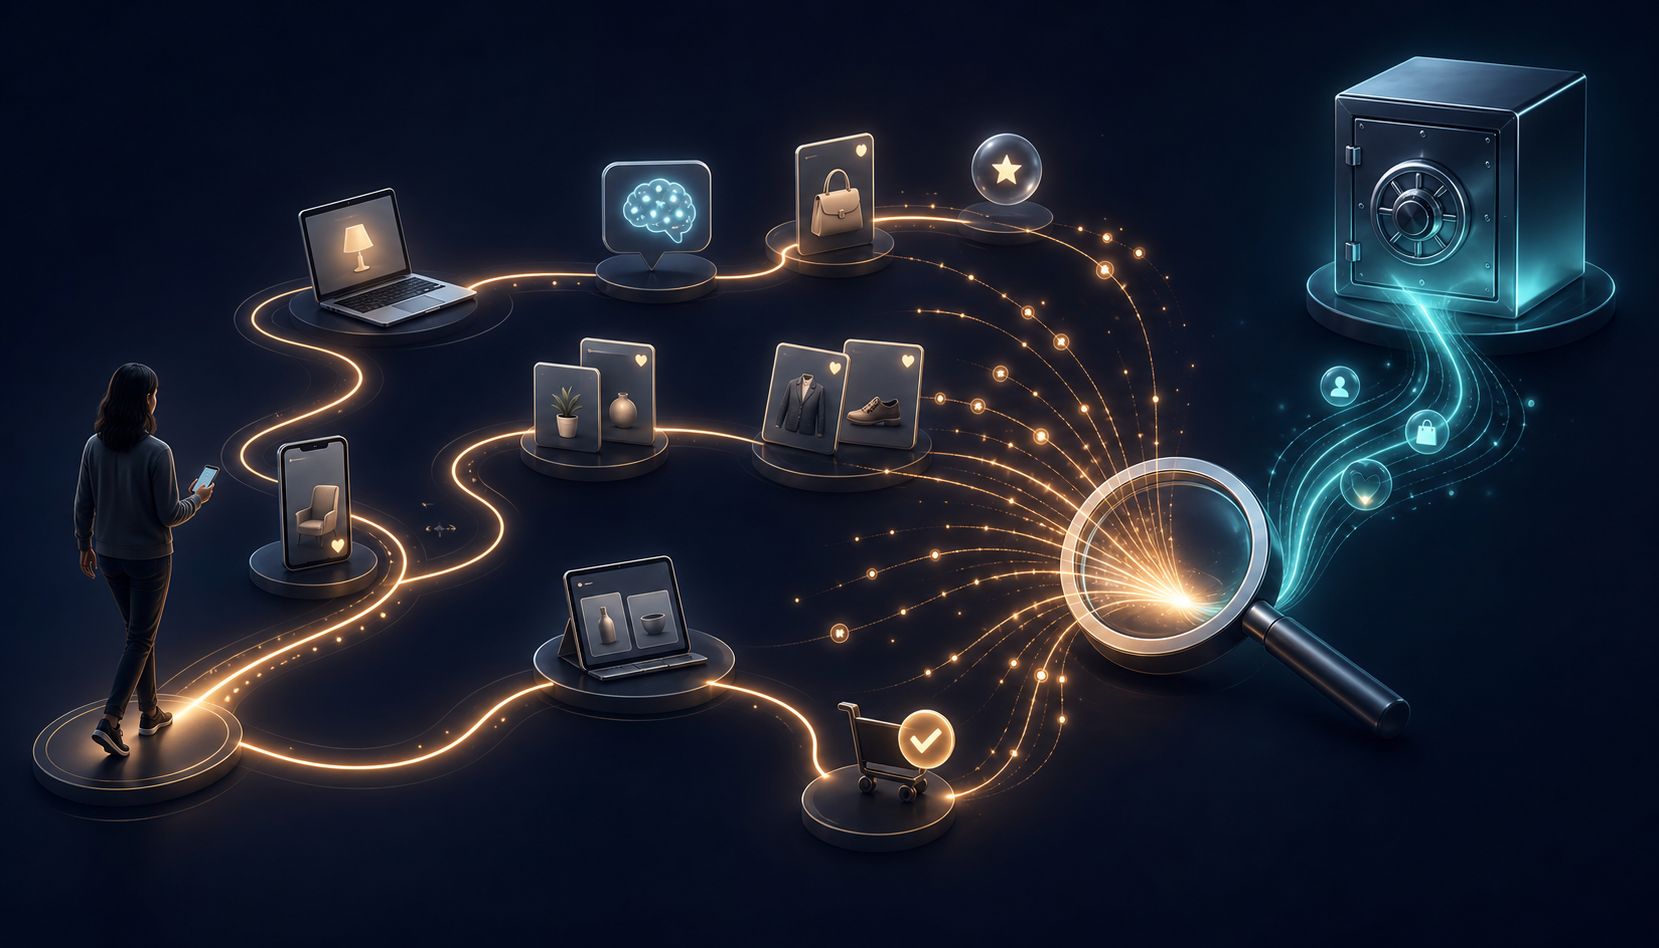
    A shopper follows a winding path across several digital touchpoints while interaction signals converge into a measurement lens and a secure data vault supports the journey.

    Qualified Future Conversions, or QFC, represents another part of Google’s reported direction. The source describes it as a metric that estimates potential conversions occurring within 180 days after an ad interaction. It was reportedly being tested with selected advertisers and was presented as especially relevant to B2B and lead-generation businesses with lengthy sales cycles.

    QFC addresses a different measurement problem from the missing AI Search breakdown. Dedicated placement reporting would help advertisers understand where an interaction occurred; a future-conversion estimate is intended to help evaluate what that interaction may eventually produce. Neither capability substitutes for the other.

    The report also identifies new AI Search ad formats, QFC and YouTube Creator Partnerships as three areas Marvin highlighted after Google Marketing Live. Together, those priorities suggest attention to discovery, delayed outcomes and creator-led reach. For search advertisers, the immediate challenge is to prepare reliable inputs and explicit campaign guidance while avoiding stronger claims about AI-specific performance than the available reporting can support.

    What advertisers should prepare next

    The most durable preparation is not adoption of every automation feature. It is a campaign structure that can accommodate wider matching without losing strategic intent, supported by dependable conversion signals and documented messaging boundaries. As AI-specific controls and reporting develop, advertisers with those foundations will be better positioned to test new inventory and interpret the results responsibly.

    References

  • How to Read Schema.org Adoption Data Without Overstating It

    How to Read Schema.org Adoption Data Without Overstating It

    Schema.org adoption can now be discussed with more evidence than anecdote. A reported monthly dataset shows how broadly individual Schema.org types and properties appear across domains observed through Google’s public web crawling infrastructure.

    The figures are best treated as directional adoption signals, not exact market-share measurements or proof that a term improves search performance. Because the supplied material contains one report, the dataset details below are attributed to that report and are not independently corroborated here.

    Key takeaways

    • The reported statistics count unique domains using a Schema.org term, rather than every page or markup instance.
    • Results appear in broad ranges such as 10K-100K domains instead of as exact counts.
    • The source says the files are updated monthly and available in JSON, CSV and summary JSON formats.
    • Adoption data can support prioritization and benchmarking, but it does not establish implementation quality, eligibility for search features or business impact.

    What the adoption metric actually measures

    According to the supplied CrushPress.AI report, Schema.org term frequencies are evaluated within Google’s public web crawling infrastructure and aggregated at the domain level. If one domain uses the same term on 100 pages, that still contributes one domain to the reported range for that term.

    This unit of measurement answers a particular question: how widely has a term spread among observed websites? It does not answer how many pages contain the term, how frequently it appears within a site or how much content the markup describes.

    The report says each record identifies whether the term is a type, such as Person or Event, or a property, such as price or telephone. It also includes the term’s official URI and a domain-count bucket. Those fields make it possible to distinguish the vocabulary item being measured from the range used to express its adoption.

    Why ranges are more useful than they first appear

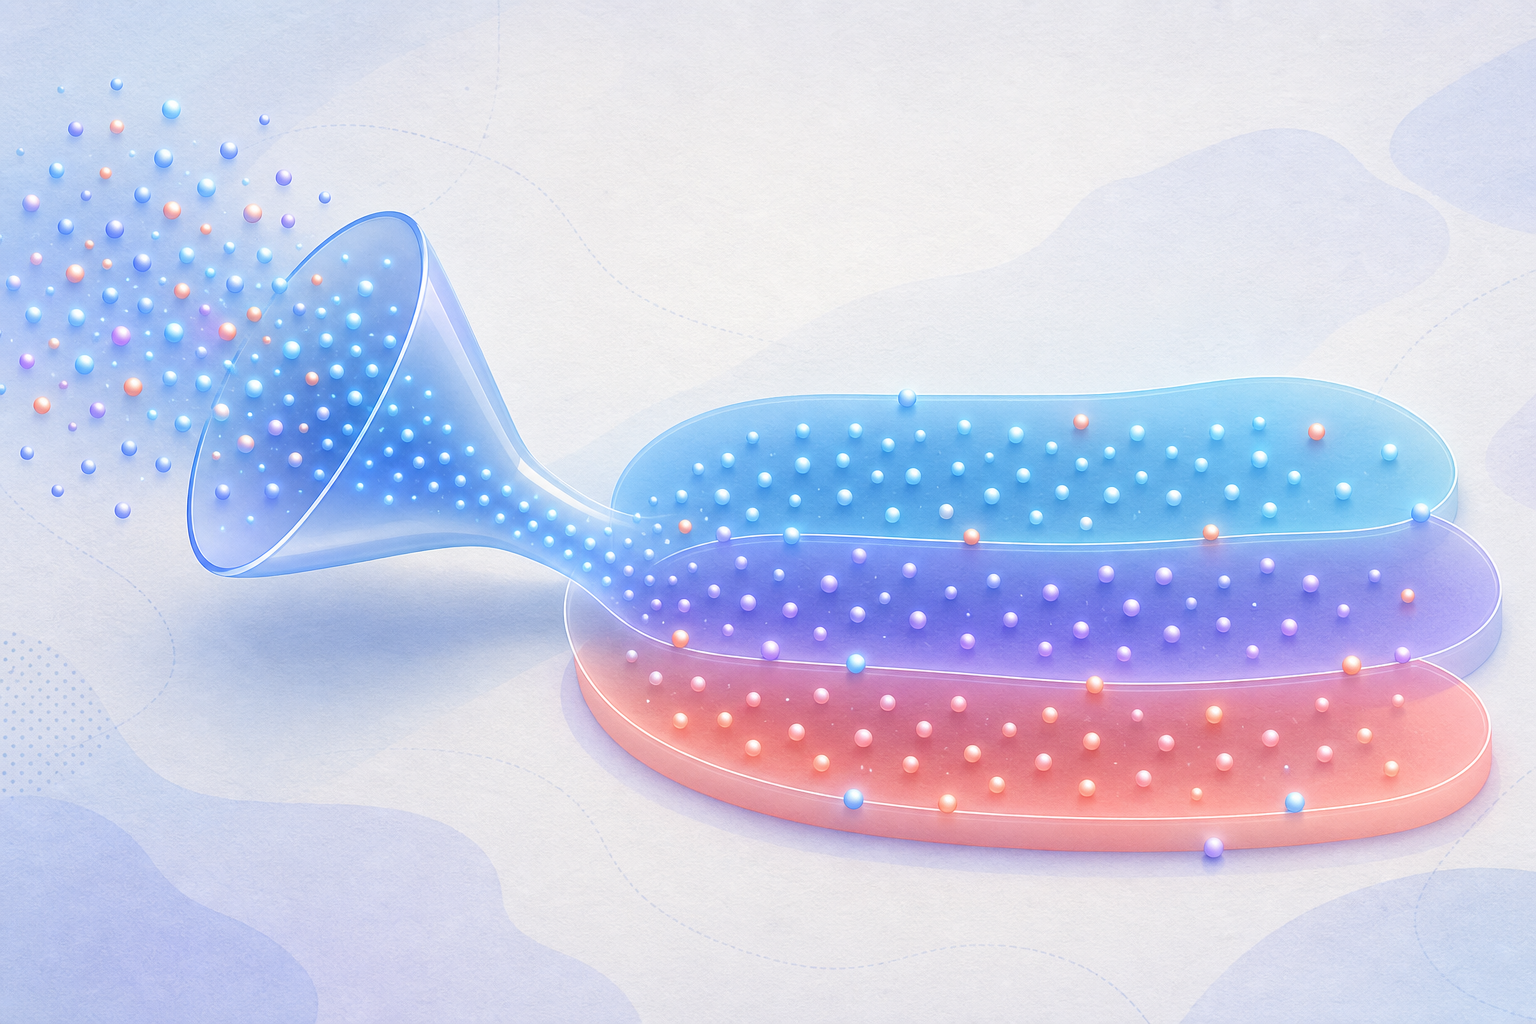
    Glowing domain dots pass through a translucent funnel into three overlapping colored bands with soft boundaries.

    The source reports that Schema.org publishes ranges such as 10K-100K domains rather than precise totals. It says this approach reduces the effect of daily fluctuations and helps preserve website privacy. Monthly updates provide recurring snapshots without suggesting a level of precision the underlying observation process may not support.

    That design changes the appropriate analysis. A bucket can reveal whether a term is niche, moderately adopted or broadly established, but it cannot support an exact adoption rate. Two terms in the same range also cannot be reliably ranked from the bucket alone, and movement within a range will remain invisible until a boundary is crossed.

    Month-to-month comparisons therefore require restraint. Remaining in one bucket does not prove that usage was static, while entering a new bucket indicates a threshold crossing rather than disclosing the precise size or timing of the change.

    A practical way to use the dataset

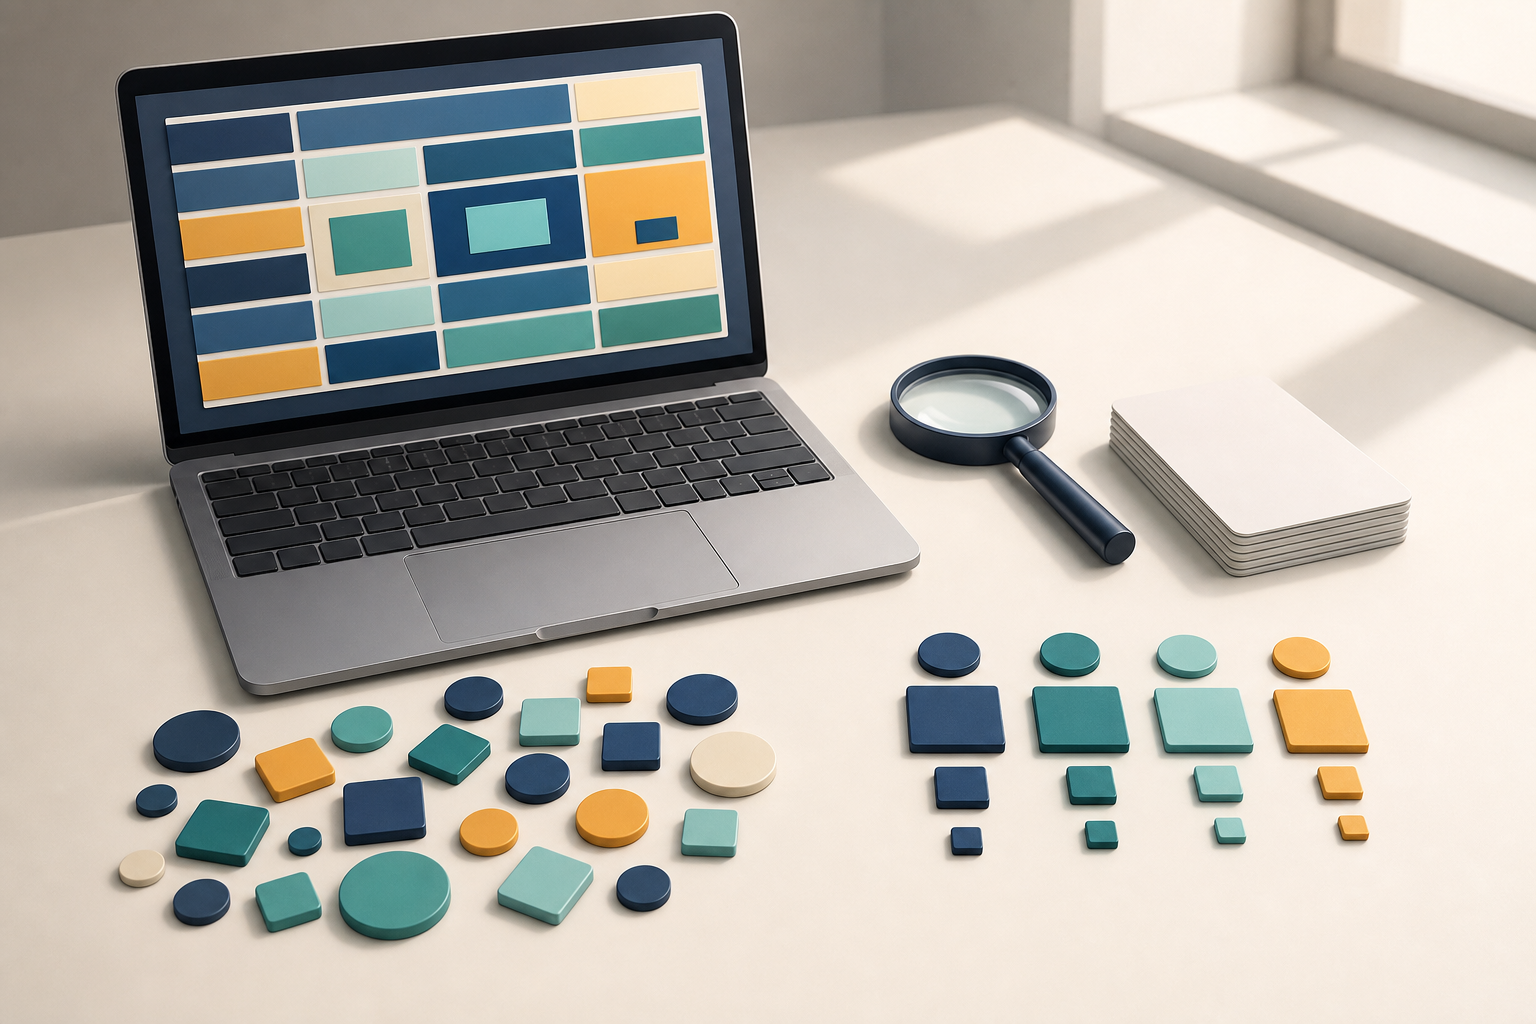
    An analyst's desk with a laptop, magnifying glass, blank filter cards, and website tokens arranged from a mixed set into organized groups.

    Start with relevance, not popularity

    A term should first match the entity, attribute or relationship a site genuinely needs to describe. A large adoption bucket can show that implementation is common across domains, but popularity cannot make an irrelevant term appropriate.

    Use adoption as supporting evidence

    When several relevant terms compete for development time, the reported ranges can add an external signal to the decision. Teams can pair that signal with content coverage, technical effort, maintenance ownership and the specific purpose of the markup. The source suggests that visible adoption may also help make the case for implementation to development stakeholders.

    Preserve the reporting context

    Any internal dashboard or recommendation should record the term, whether it is a type or property, its official URI, the observed bucket and the monthly dataset snapshot used. The source says raw files are available through the Google Public Stats dataset on GitHub in JSON and CSV, with a summary JSON format containing aggregated bucket distributions.

    The conclusions the figures cannot support

    Domain adoption is not a quality score. The reported metric does not state whether markup is valid, complete, current or faithful to the visible content. It also does not show whether a search system used the markup, whether a search feature appeared or whether traffic and conversions changed.

    The crawling context matters as well. The source ties the frequencies to Google’s public web crawling infrastructure, so the figures describe domains observed within that system rather than an independently established census of every website. Broad buckets further limit fine-grained comparisons.

    The most defensible role for this dataset is as a recurring map of vocabulary diffusion. Used alongside implementation audits and site-specific objectives, future monthly snapshots can make structured-data planning more evidence-aware without turning adoption into a substitute for relevance or quality.

    References

  • AI SEO Measurement: From Prompt Signals to Action

    AI SEO Measurement: From Prompt Signals to Action

    AI-era SEO measurement breaks down when a dashboard treats every generated answer as stable, every tracked prompt as representative, or every brand mention as a business result. A useful system must instead connect four questions: what people ask, how consistently AI systems respond, whether visibility changes user behavior, and what a team should do next.

    Together, the supplied reports point toward a practical operating model: observe real demand, sample variable responses systematically, connect visibility to outcomes, and convert findings into owned work. This approach extends established SEO measurement without pretending that AI answers behave like conventional rankings.

    Measure the demand behind AI visibility

    The first measurement problem occurs before an AI answer is generated: a tracking program must decide which prompts represent the audience. The prompt research summarized by CrushPress.AI suggests that the answer is not simply a library of elaborate, conversational questions.

    In a January 2026 Stella Rising survey cited by the publication, two-thirds of participants submitted prompts containing no more than 15 words, while about 12% produced what the researchers considered comprehensive prompts. The reported average for a basic shoe-recommendation scenario was eight words. The same article cited Semrush clickstream findings that placed average prompt length between 4.2 and 8.7 words. These reports indicate that short, keyword-shaped demand remains relevant even inside generative interfaces.

    Personal context creates a second demand layer. The January study reportedly found that 32% of users included details such as a role, situation, location, size, preference, or budget. Nearly a quarter used the word "best," while price language and "near me" phrasing also appeared. A brand may therefore be visible for a broad category prompt yet disappear when the request adds affordability, availability, suitability, or personal constraints.

    These results should be treated as directional. The article says the August 2025 research covered 178 members of a beauty-oriented community, whereas the January 2026 study covered 524 active AI users from a broader audience. Differences between the studies may reflect their samples as well as changing behavior. They do not establish a universal prompt distribution for every market.

    Design a prompt portfolio rather than a keyword substitute

    Hands arrange varied icon-based prompt tokens into several intent groups on a circular table.

    A representative prompt set needs several complementary inputs. Replacing a keyword list with synthetic questions merely changes the format of the same sampling problem. The stronger approach is a portfolio that covers distinct ways demand appears:

    • Short retrieval prompts: category, brand, location, price, comparison, and "best" queries that resemble conventional search behavior.
    • Context-rich prompts: requests that combine a need with personal attributes, constraints, use cases, or purchasing conditions.
    • Synthetic persona prompts: controlled scenarios used to test how representation changes across audience profiles.
    • Conversational journeys: linked turns that move from discovery through evaluation and selection.

    Real prompt language can be informed by customer inquiries, support tickets, on-site search behavior, sales conversations, and traditional search data. CrushPress.AI’s prompt-behavior article recommends combining such evidence with synthetic personas because a fabricated profile cannot fully reproduce the accumulated context of an ongoing AI interaction.

    The prompt-tracking report adds another distinction: a single-turn test shows whether a brand appears at one moment, while a sequence can reveal whether that visibility persists as the user narrows the decision. Persistence is especially important when an initial mention does not survive follow-up questions about requirements, competitors, pricing, or fit.

    The resulting portfolio should be segmented rather than collapsed into one visibility score. Short prompts, contextual prompts, personas, and journeys represent different questions about demand. Combining them without labels can make a change in the sample look like a change in brand performance.

    Quantify variable answers without manufacturing certainty

    AI responses vary, so one generated answer is an observation rather than a durable rank. CrushPress.AI’s prompt-tracking article argues that this variability can be managed through repeated runs, fixed sampling rules, and confidence intervals. It compares the emerging discipline with fields such as opinion polling, where uncertainty is measured rather than ignored.

    A repeatable measurement specification should identify the platform, prompt wording, conversational context, sampling schedule, number of observations, market conditions, and scoring rules. It should also preserve the underlying responses so that changes in a summary metric can be audited. When a platform or testing condition changes, the report should mark the break rather than present the series as perfectly continuous.

    Each run can record several observable outcomes: whether the brand was mentioned, whether it was recommended, which sources were cited, which competitors appeared, and whether the brand remained present in later turns. The appropriate output is a distribution, rate, or range across the sample, accompanied by its limitations. A movement based on repeated observations deserves more weight than an isolated favorable or unfavorable answer.

    Cross-platform reporting requires similar restraint. The tracking article notes that visibility can differ among AI services and uses brand performance across ChatGPT and Perplexity to illustrate the issue. Platform-level results should therefore remain visible even when an aggregate is provided; otherwise, strength in one environment can conceal weakness in another.

    Connect AI exposure to traffic, outcomes, and evidence

    Uneven light paths connect an abstract AI interface to a website, user behaviors, collected evidence, and prioritized work cards.

    Visibility is an intermediate signal, not the final business result. The prompt-behavior report says many surveyed users still clicked citations, presenting AI mentions as possible gateways to websites rather than automatic endpoints. It also reports that 68% of respondents trusted AI recommendations more than Google’s and that half of active AI users engaged with AI tools daily. Those figures come from the cited January 2026 survey and should not be generalized beyond its stated audience, but they explain why recommendation quality and referral behavior warrant measurement together.

    A practical measurement chain separates four levels. Prompt coverage shows whether the test set reflects meaningful demand. Answer visibility shows whether and how the brand appears. Referral and behavioral data show whether cited exposure produces visits or engagement. Conversion measures show whether those interactions contribute to leads, purchases, subscriptions, or another defined objective. Not every organization will be able to connect every level, so reports should distinguish observed outcomes from inferred influence.

    This distinction also improves prioritization. A visibility gap for a commercially important, frequently observed use case may justify content or technical work. A fluctuating mention for a speculative synthetic prompt may justify continued observation instead. Confidence, audience relevance, business value, and implementation cost all affect the decision.

    The Conductor post offers a vendor-side example of shortening the distance between insight and execution: it describes Conductor AEO intelligence integrated into Optimizely with pre-built agents intended to act on findings. The announcement demonstrates the direction of workflow integration, but it does not independently establish that automated actions improve visibility or business performance. Any such workflow still needs approval rules, outcome measurement, and a record of what changed.

    Convert findings into owned, decision-ready work

    The final failure point is organizational. The reporting article argues that research becomes useful only when stakeholders can see the priority, business rationale, responsible team, next action, and measurement plan. AI visibility data increases this need because its uncertainty can otherwise become a reason to delay every decision.

    1. State the finding and its evidence. Identify the affected prompt segment, platform, sample, observed range, and relevant citations or responses.
    2. Explain the business consequence. Connect the finding to an audience need, commercial page, reputation risk, or measurable journey stage.
    3. Choose the smallest meaningful action. Specify the content update, technical correction, authority-building task, product-data improvement, or additional test required.
    4. Assign ownership and timing. Name the responsible function and define when the work and its follow-up measurement should occur.
    5. Set an evaluation rule. Define which visibility, referral, engagement, or conversion signal would support continuing, revising, or stopping the intervention.

    The level of detail should change with the reader. Executives need exposure, risk, resource requirements, and expected business impact. Marketing leaders need the connection to demand and campaigns. Content teams need page-level briefs and audience context. Developers need reproducible technical requirements. Supporting exports and response logs can remain available without overwhelming the main decision document.

    Key takeaways

    • Preserve short, search-like prompts while adding personal, situational, and conversational variants.
    • Use real audience evidence and synthetic personas for different purposes; neither is a complete sample alone.
    • Measure repeated observations, uncertainty, platform differences, citations, and conversational persistence.
    • Treat visibility as one stage in a chain that ends with an assigned action and a defined outcome signal.

    As AI interfaces become more personalized and optimization tools become more integrated, the durable advantage will come from disciplined learning loops. Teams that preserve evidence, acknowledge uncertainty, and make each finding operational will be better positioned to adapt their SEO programs as user behavior and answer systems evolve.

    References

  • Exciting Support for Claude Fable Now in Profound

    Exciting Support for Claude Fable Now in Profound

    I’m thrilled to share some fantastic news with you. We’ve just launched support for Claude Fable within Profound, and it’s an upgrade that I’m genuinely excited about.

    Incorporating Claude Fable into our system not only enhances user experience but also brings a new level of efficiency to our platform. This integration is designed to provide seamless functionality and improve overall productivity.

    I’m confident that this addition will greatly benefit all users by offering enhanced capabilities and features that are both intuitive and powerful. Stay tuned for more updates as we continue to innovate and evolve.


    Inspired by this post on Try Profound Blog.


    crushpress.ai community screenshot
  • When Is a Brand Campaign Ready for Google Ads AI Max?

    When Is a Brand Campaign Ready for Google Ads AI Max?

    AI Max can extend a Search campaign beyond its existing keywords, but a high-performing brand campaign is not automatically a good place to activate it. Readiness depends on whether broader automation serves a defined growth objective without weakening the measurement and control that make branded search valuable.

    The available reporting points to a practical decision rule: separate eligibility for Google’s AI-driven search surfaces from the business case for expanding brand traffic. Then assess signal quality, account structure, learning volume, and testing safeguards before changing the campaign.

    AI surface eligibility and campaign readiness are different questions

    Two connected platforms contrast an active search surface with checkpoints for signals, campaign structure, volume, and testing.

    According to the source article, AI Max uses keywords, landing pages, and site content as signals to reach searches beyond explicitly targeted phrases. It can therefore uncover demand that a tightly constrained brand campaign would not ordinarily enter. The article also notes that brand exclusions, URL exclusions, text guidelines, and location targeting provide boundaries for that expansion.

    That expanded reach may be useful, but access to AI-driven placements is not by itself a reason to alter a successful brand campaign. The article reports that Google Ads liaison Ginny Marvin identified three routes to AI Overview eligibility: broad match with Smart Bidding, Performance Max, and AI Max for Search. It further reports that exact-match keywords are not eligible for AI Overviews.

    This distinction matters because an account already using Performance Max may already have the desired surface coverage. Adding AI Max to brand Search in that situation could duplicate an eligibility benefit while introducing broader query matching into the account’s most predictable traffic source. The relevant question is not simply whether AI Max can obtain more reach, but whether that reach is incremental, measurable, and aligned with the campaign’s role.

    The article cited Semrush data indicating that AI Overviews reached approximately 2.5 billion monthly users and that ads appeared in 25.6% of AI Overview results. Those reported figures help explain advertiser interest, but they do not establish that every brand campaign needs AI Max or that eligibility will produce profitable incremental demand.

    The reported performance evidence does not settle the brand question

    Google’s reported upside and the independent observations cited in the article point in different directions. More importantly, the independent findings were not specific to brand campaigns, so they should inform test design rather than be treated as a verdict on branded search.

    Evidence reported by the sourceReported resultWhat it can and cannot show
    Google’s AI Max claimA potential 14% conversion increase, rising to 27% for campaigns using exact and phrase matchProvides a platform benchmark, but not an account-specific forecast or a brand-only result
    Smarter Ecommerce test across 600 accountsAI Max produced 35% lower ROAS than traditional match typesShows that broader automation can underperform in some account mixes; the article says the test was not brand-focused
    Xavier Mantica’s four-month examinationReported cost per conversion was $100.37 for AI Max, $43.97 for phrase match, and $52.69 for exact matchIllustrates a cost gap in one examination, but does not establish a universal ordering of match strategies
    Ezra Sackett’s analysis of 30,000 search termsAccording to the article, 99% of AI Max impressions produced no conversionsRaises a query-quality concern, but does not isolate the effect on defensive brand campaigns

    Taken together, these reports support caution rather than a blanket rejection. AI Max may create value where an account has trustworthy optimization signals and room to expand. The evidence presented does not, however, demonstrate that a stable exact-match brand campaign is the best testing ground. A campaign already capturing known branded demand efficiently has a different job from a generic campaign designed to discover new demand.

    Readiness starts with signals, structure, and an unmet objective

    AI Max learns from the objectives and data supplied to it. If a campaign optimizes toward low-value actions, incomplete lead records, or conversions dominated by existing brand demand, broader automation can reinforce those biases. Strong historical performance does not compensate for a weak definition of success.

    Readiness dimensionEvidence of readinessRisk when it is weak
    Conversion integrityMacro and micro actions are clearly separated, primary goals reflect business value, and tracking is reliableAI Max may optimize toward easy but commercially weak actions
    Offline feedbackQualified leads, completed sales, or other downstream outcomes return to the advertising platform consistentlyHigh lead volume can be mistaken for high lead quality
    Learning volumeThe campaign or account supplies enough relevant conversion activity and variation for automation to distinguish useful patternsResults may be unstable or overly influenced by a narrow set of branded conversions
    Account architectureSearches such as brand plus pricing, reviews, or other modifiers have deliberate treatment where their intent warrants itAI Max can conceal structural gaps instead of resolving them
    Generic growthBudget constraints, landing-page mismatches, outdated queries, and campaign structure have already been examined outside brandAttention may shift to squeezing more from efficient branded demand while larger growth barriers remain untouched
    Strategic purposeThe team can name the incremental audience, query class, or coverage gap the test is meant to addressActivation becomes a response to a platform recommendation rather than a business objective

    This framework also prevents a common measurement error: interpreting additional conversions as incremental conversions. Brand campaigns often capture people who already know the advertiser. Any evaluation therefore needs to distinguish newly reached, valuable demand from traffic that would have converted through existing brand coverage or another campaign.

    Key takeaways

    • AI Max eligibility for AI-driven search surfaces does not prove that a brand campaign is operationally ready for broader automation.
    • Performance Max may already provide relevant AI surface eligibility, so overlap should be checked before AI Max is added to brand Search.
    • The independent results cited by the source are mixed and not brand-specific; they justify controlled experimentation, not universal conclusions.
    • Reliable conversion tracking, downstream quality feedback, sufficient learning data, and intentional campaign architecture are prerequisites.
    • A test needs an incremental-growth hypothesis and explicit safeguards, especially when the existing brand campaign is efficient and predictable.

    A controlled experiment should protect the brand baseline

    Parallel glass channels separate a protected control path from a smaller gated experimental path with branching routes.

    If the readiness conditions are satisfied, AI Max is better treated as a hypothesis to test than as a routine account upgrade. The hypothesis should state what additional value is expected, such as reaching a defined class of relevant searches that existing coverage misses. Success criteria should include business-quality outcomes, not conversion count alone.

    The baseline should remain interpretable throughout the test. Query expansion, landing-page selection, conversion quality, cost, and overlap with other campaigns all need review. The controls cited by the article can limit unwanted reach, but controls do not replace monitoring or a clear threshold for stopping an unproductive experiment.

    Accounts that fail the readiness assessment have a more immediate priority: repair measurement, restore downstream feedback, clarify branded intent segments, and remove constraints from generic growth. As those foundations improve, AI Max can be reconsidered with a cleaner baseline and a more credible definition of incrementality.

    The durable standard is whether automation advances the advertiser’s objective while preserving trustworthy evidence. Brand campaigns should move toward AI Max only when the account can answer that question through a disciplined test.

    References

  • Server Log Analysis for Technical SEO: A Practical Guide

    Server Log Analysis for Technical SEO: A Practical Guide

    Server log analysis shows what search crawlers actually requested and how the server responded. That direct evidence can reveal crawl inefficiencies, response problems, and neglected page groups that simulated crawls or reporting interfaces may not expose.

    The goal is not to replace Google Search Console, Bing Webmaster Tools, or site crawlers. It is to add an infrastructure-level record that can confirm whether important URLs receive crawler attention, identify where requests are being diverted, and provide a baseline for migrations and platform changes.

    What server logs add to the SEO evidence stack

    SEO crawlers test a site from the outside, while webmaster platforms present search-engine reporting. Server logs answer a different question: which requests reached the infrastructure, and what happened when they arrived?

    The supplied CrushPress.AI article reports that logs capture individual requests, including visits from Googlebot and Bingbot, whereas other SEO tools may depend on samples, delayed reporting, or simulated crawls. It argues that this distinction is especially useful for sites with large URL inventories, where aggregate reports can conceal meaningful differences among directories, templates, and parameter combinations.

    Logs still have boundaries. A request does not prove that a URL was indexed, ranked, or considered valuable by a search engine. Log analysis is therefore strongest when combined with crawl data, indexation evidence, internal-link analysis, and business priorities.

    Key takeaways

    • Server logs record crawler requests received by the infrastructure rather than simulating crawler behavior.
    • Analysis should compare crawler attention with the site’s intended URL and page-section priorities.
    • Repeated requests to parameters, obsolete URLs, errors, or redirect paths can indicate crawl inefficiency.
    • Response status and timing help distinguish URL-management problems from infrastructure problems.
    • Retained historical logs support before-and-after analysis for migrations, redesigns, and platform changes.
    • Logs complement rather than replace Search Console, webmaster platforms, and technical crawlers.

    The technical SEO questions logs can answer

    QuestionEvidence to examinePossible decision
    Are priority pages being crawled?Requests grouped by page type, directory, or templateReview discovery paths, internal linking, or URL accessibility
    Where is crawler attention going instead?Requests for parameters, outdated structures, and low-priority URL groupsReduce unnecessary URL generation or tighten crawl controls where appropriate
    Are crawlers receiving unexpected responses?Status patterns, redirect paths, and repeated requests to failing URLsCorrect response handling, redirect logic, or broken destinations
    Is performance trouble isolated or persistent?Response timing segmented by URL group and observed over timeInvestigate affected templates, services, or infrastructure components
    Did a deployment change crawler behavior?Comparable periods before and after a migration, redesign, or infrastructure changeAddress new errors, lingering legacy requests, or reduced access to priority sections

    The source highlights a common large-site pattern: crawlers may spend requests on parameterized URLs while important product or category pages receive less attention. It also reports that obsolete URL structures can continue consuming crawl activity after a site has moved on operationally.

    These observations should be interpreted as patterns, not automatic diagnoses. Heavy crawling of a URL group may be intentional, temporary, or caused by references outside the system being reviewed. Likewise, low request frequency becomes actionable only after confirming that the affected pages are important and meant to be discoverable.

    A repeatable workflow for log analysis

    Server files move through filtering, grouping, inspection, and prioritization stages arranged in a circular workflow.
    1. Define the decision first. Specify whether the analysis concerns crawl allocation, errors, redirects, server performance, a migration, or another technical question.
    2. Choose a representative time window. Preserve enough history to separate an isolated event from a recurring pattern and mark deployments or infrastructure changes that could affect interpretation.
    3. Prepare the required request fields. A useful dataset generally needs the requested path, request time, response status, user agent, and response timing when the logging configuration provides it.
    4. Identify legitimate crawler traffic. Do not assume that every request carrying a search-bot user agent is genuine; apply the organization’s bot-validation process before drawing conclusions.
    5. Normalize and group URLs. Separate meaningful page types from parameters, duplicate forms, obsolete paths, static resources, and other request classes so that high-volume noise does not dominate the analysis.
    6. Compare crawler behavior with site priorities. Examine whether commercially or editorially important sections receive attention while low-value or retired URL spaces consume requests.
    7. Segment response outcomes. Review successful responses, errors, redirects, and response timing by section or template rather than relying only on sitewide averages.
    8. Validate findings elsewhere. Reproduce suspected issues with a crawler or direct request, then compare them with Search Console, Bing Webmaster Tools, internal-link data, and infrastructure monitoring.
    9. Create a baseline. Retain comparable summaries so future releases, migrations, and redesigns can be evaluated against known crawler behavior.

    Turning log patterns into defensible priorities

    An analyst prioritizes website crawl issues while request paths show an overlooked page cluster, repeated loops, and broken routes.

    The most useful findings connect crawler behavior to a specific technical mechanism. Requests concentrated on unnecessary parameter combinations point toward URL generation or crawl-control decisions. Repeated visits to obsolete addresses suggest that old discovery paths or redirects still matter. Persistent errors or slow responses concentrated in one template point toward a narrower application or infrastructure investigation.

    Frequency and persistence help with prioritization. The supplied article notes that historical logs can distinguish temporary incidents from continuing infrastructure problems and can show crawler behavior before and after migrations. A recurring issue affecting an important section deserves different treatment from a short-lived anomaly with no continuing impact.

    Teams should also avoid treating crawl volume as a ranking metric. The defensible conclusion is that logs reveal access and response behavior; broader SEO evidence is still needed to explain indexation or search performance. Used this way, retained logs become an ongoing observability layer that can make the next deployment or migration easier to evaluate.

    References

  • AI Search Visibility When Clicks No Longer Tell the Story

    AI Search Visibility When Clicks No Longer Tell the Story

    AI search visibility is changing what it means for a brand to succeed in search. A result can influence awareness, consideration, or a future branded query without producing an immediate website visit, while an AI-generated answer may describe or recommend a business before the user encounters its pages directly.

    The practical response is not to abandon SEO, but to connect search performance with brand representation. The available reporting points to two linked priorities: remaining visible as clicks become less common and giving AI systems enough clear, credible, accessible information to represent the brand accurately.

    Key takeaways

    • Zero-click growth makes traffic an incomplete measure of search influence, although it remains important for commercial outcomes.
    • AI visibility depends on whether systems can understand the brand, find evidence supporting its claims, and retrieve that evidence when answering relevant questions.
    • SEO retains particular value for branded, local, and high-intent transactional searches, according to the zero-click study coverage.
    • A durable strategy combines owned content with reviews, third-party mentions, case studies, credentials, and consistent business information.
    • Measurement should distinguish presence, representation, engagement, and business outcomes instead of treating all search activity as a traffic-acquisition funnel.

    Visibility is becoming an answer-layer problem

    The reported zero-click trend establishes the scale of the change. The first source, summarizing a SparkToro study based on Similarweb clickstream data, reported that 68.01% of Google searches from January through April 2026 ended without a click. It placed the comparable 2024 share at 60.45%, while cautioning that changes in data sources make long-term comparisons imperfect.

    The same coverage reported that the share of searches producing at least one click fell by 9.51 percentage points between 2024 and 2026. That measure included organic results, advertisements, and Google-owned destinations such as Maps and YouTube, but excluded follow-up searches within Google. Meanwhile, the share leading to another Google search reportedly increased by 7.2 percentage points. Together, those findings suggest that search journeys are increasingly being continued or resolved inside the results environment.

    AI-generated results may reinforce that pattern, but the source does not establish a single cause. It reported that AI Overviews appeared in more than 20% of Google searches and were associated with a nearly 60% reduction in click-through rates when present. SparkToro suggested that the feature could be contributing to zero-click growth, but the study did not isolate how much of the increase it caused.

    AI Mode was a comparatively small part of the observed journey during the study period: only 0.34% of searches reportedly transitioned into it. The article also cited Google’s I/O 2026 announcement that AI Mode had more than 1 billion monthly users and that its query volume was more than doubling each quarter. Those figures describe different dimensions, so they should not be treated as contradictory: one concerns transitions recorded in a particular clickstream study, while the other concerns Google’s reported product usage.

    Brand presence depends on what machines can establish

    Transparent lenses connect several evidence objects and resolve them into a clear faceted form at the center.

    Lower click-through rates create a distribution challenge, but the second source identifies a representation challenge as well. AI systems form a picture of a business from the information available across its digital footprint. Websites, content, reviews, testimonials, credentials, case studies, and external mentions may each supply only part of that picture. Valuable expertise embedded in sales conversations, customer support, project delivery, and other daily operations may remain invisible unless it is documented and published.

    Understandability

    The source’s understandability test asks whether an AI system can determine who the organization is, what it does, and whom it serves. About pages, product or service pages, and structured data contribute to that understanding. They become more useful when names, offerings, audiences, locations, and differentiators are expressed consistently rather than scattered across ambiguous pages.

    Credibility

    Understandable claims still require support. The source frames credibility through notability, experience, expertise, authoritativeness, trustworthiness, and transparency. In operational terms, that means connecting assertions to visible evidence such as case studies, credentials, customer testimony, responsible authorship, and clear information about the business. Independent reviews and mentions can complement owned claims because they show how other parties describe the brand.

    Deliverability

    Evidence has limited value if relevant systems cannot retrieve it in the context of a user’s question. The source associates deliverability with topical content, marketing activity, and authority material. This connects conventional SEO with AI visibility: useful pages still need clear subject focus, accessible presentation, internal relationships, and distribution beyond the company website.

    A practical operating model joins SEO and brand evidence

    The synthesis of the two sources is a shift from optimizing isolated pages to managing a verifiable body of brand knowledge. A business can begin by creating a maintained source of truth for its identity, offerings, audiences, locations, expertise, policies, and substantiated differentiators. This is not necessarily a single public page; it is an internal reference that helps teams publish consistent information across appropriate channels.

    Operational knowledge should then be converted into suitable public evidence. Repeated customer questions can inform explanatory content. Demonstrable results can become case studies when permissions and context allow. Staff expertise can be attached to identifiable authors or subject-matter contributors. Credentials, review patterns, and relevant third-party recognition can be made easier to verify. The goal is not to manufacture signals, but to expose knowledge and proof that already exist inside the organization.

    Distribution matters because an AI-generated answer may assemble its view from more than the brand’s preferred landing page. Core facts should remain consistent across the website, business profiles, relevant platforms, earned coverage, and other legitimate sources. Each channel has a different role: owned pages provide depth and control, customer feedback supplies experience-based evidence, and independent references can reinforce recognition and authority.

    This model also clarifies where traditional SEO remains essential. The zero-click coverage cited SparkToro co-founder Rand Fishkin’s view that SEO continues to matter for branded searches, local business inquiries, and high-intent transactional searches. These are contexts in which accurate pages and direct visits can still connect discovery to action. Broader audience development should also occur on the platforms where prospective customers already spend time, even when that activity does not immediately produce referral traffic.

    Measurement must separate exposure from acquisition

    A glowing signal stream divides into a broad halo around people and a focused path leading to a doorway.

    A traffic-only dashboard cannot show whether a brand appeared inside an answer, was represented accurately, or influenced a later decision. Measurement should therefore follow several layers. Presence concerns whether the brand appears for relevant questions. Representation evaluates whether the answer describes its identity, services, audience, and differentiators correctly. Engagement covers visits, branded searches, profile interactions, and other observable responses. Outcomes connect those interactions to inquiries, qualified demand, sales, retention, or another business objective.

    These layers should not be collapsed into a single visibility score. A mention can be prominent but inaccurate; an accurate citation can produce no click; and a decline in noncommercial traffic can coexist with strong performance on branded or high-intent searches. Separating the layers makes diagnosis more useful: unclear representation points toward content and entity consistency, weak credibility points toward missing evidence, and limited reach points toward discoverability or distribution.

    The reported study also sets an important analytical boundary. Its dataset covered U.S. Google desktop and mobile web searches, estimated that two-thirds of searches occurred on mobile devices, and excluded searches inside Google’s mobile search app, where the source said zero-click behavior might be higher. Results should therefore be treated as directional evidence from a defined sample rather than a universal benchmark for every audience, market, or search environment.

    As answer interfaces expand, the strongest search programs will be built around both retrieval and reputation. Brands that keep their knowledge current, support claims with accessible evidence, and evaluate how they are represented will be better prepared for a search journey in which influence often begins before any click occurs.

    References

  • ChatGPT Ads Expand Markets, Formats and Campaign Controls

    ChatGPT Ads Expand Markets, Formats and Campaign Controls

    OpenAI’s reported advertising expansion is taking shape on two fronts: broader geographic access and a test that could place several advertisers within one ChatGPT ad space. Together, these changes point toward a more mature ad marketplace built around commercially relevant conversations.

    For advertisers, the immediate value lies in expanded targeting and more familiar campaign controls. The larger strategic question is whether multi-advertiser placements can support product discovery without making conversational results feel crowded or less useful.

    Key takeaways

    • OpenAI is reportedly adding the U.K., Japan, South Korea, Brazil and Mexico to the geographic options available beyond the U.S., Canada, Australia and New Zealand.
    • A limited test combines ads from multiple relevant advertisers in one placement rather than showing only one sponsored result.
    • The tested format reportedly uses a second-price auction, introducing established digital-ad auction mechanics to conversational discovery.
    • Ads Manager Beta is adding more flexible budgets, bidding transitions, custom CPM limits and bulk editing.
    • The report does not provide performance benchmarks, placement-level details or a timetable for turning the limited test into a wider release.

    Market expansion and format testing address different constraints

    The geographic expansion increases where advertisers can target campaigns. According to the supplied CrushPress.AI report, the U.K., Japan, South Korea, Brazil and Mexico are being added beyond the previously listed markets of the U.S., Canada, Australia and New Zealand. That widens access, but it does not by itself change how many advertisers can appear in a placement.

    The multi-advertiser test tackles the supply side of the marketplace instead. The report says OpenAI is testing the format across a limited number of ChatGPT ads, grouping several relevant advertisers in a single space. If expanded, that design could create more opportunities to participate in high-intent conversations without requiring a separate ad slot for every advertiser.

    These are therefore complementary developments: geographic targeting broadens the addressable audience, while a multi-advertiser unit could increase the advertising options presented within an eligible interaction. Neither change, based on the available report, establishes how frequently users will encounter ads or which types of conversations will qualify.

    A multi-advertiser unit changes the competitive context

    Three distinct generic product cards share one advertising space beside a blank conversational panel.

    A single sponsored result gives one advertiser the visible opportunity within its placement. A grouped unit creates a comparison environment: relevance still matters, but the advertiser’s offer may also appear alongside alternatives at the moment a user is researching a product or service.

    The report says the test uses a second-price auction model. In general, this auction structure determines payment with reference to competing bids rather than automatically charging the winner its full bid. Its use would make the buying mechanism recognizable to experienced digital advertisers, although the source does not disclose the complete ranking formula, pricing rules or role of quality and relevance signals.

    That missing context matters. More advertisers in one unit could improve choice and product discovery, which the report identifies as OpenAI’s aim. It could also divide attention among neighboring offers. Advertisers would therefore need placement-specific evidence before treating results as equivalent to conventional search, display or social inventory.

    Ads Manager Beta is becoming more operationally familiar

    A person adjusts an unlabeled control on a modular digital advertising campaign interface.

    The campaign-management changes described in the report reduce several practical barriers to experimentation. Existing campaigns can reportedly move from lifetime budgets to daily budgets, while CPM campaigns can transition to CPC bidding in one click. Impression-based campaigns gain custom maximum CPM bids, and bulk editing is being added within the Ads Manager interface.

    Daily budgets will reportedly operate as average daily budgets with weekly pacing flexibility. That distinction is important for campaign oversight: an average allows delivery to vary from one day to another, so advertisers should evaluate spend against the applicable pacing period rather than assume an identical amount will be spent every day.

    Collectively, the controls resemble capabilities buyers already use elsewhere. Familiarity can simplify setup and budget changes, but it does not make ChatGPT inventory interchangeable with other channels. CPC and CPM optimize around different billable events, and conversational placements may produce different attention, comparison and conversion patterns.

    Advertisers need evidence beyond access and interface upgrades

    The reported updates make it easier to launch and modify campaigns, but the source provides no results for click-through rates, conversion rates, incremental lift or advertiser return. It also does not specify how multi-advertiser units will be labeled, how ads will be ordered inside the placement or which reporting dimensions will distinguish them from single-advertiser units.

    A measured evaluation would separate three questions: whether the available audience matches the campaign’s market, whether the buying model aligns with its objective, and whether the placement produces incremental business outcomes. CPC may make sense when traffic is the immediate goal, while CPM can suit reach or visibility objectives; neither pricing model proves downstream value on its own.

    Creative strategy may also need to account for direct comparison. In a multi-advertiser setting, a clear product distinction, relevant offer and accurate destination experience can become more important because users may see competing options together. This is a strategic implication of the reported format, not a performance finding from the limited test.

    The test will be defined by relevance, measurement and user trust

    The expansion suggests that OpenAI is assembling recognizable components of an advertising platform: auctions, flexible bidding, budget controls, bulk operations and international targeting. The distinctive variable is the conversational environment in which those components operate.

    Whether the model scales will depend on questions the available report leaves open, particularly placement relevance, transparent measurement and the effect of multiple sponsored choices on the user experience. The most informative next developments will be evidence about performance and disclosure standards, not simply the number of available markets or campaign controls.

    References