Author: shivamcrushpressai

  • How Bot Traffic Changes AI Search Visibility Measurement

    How Bot Traffic Changes AI Search Visibility Measurement

    AI is changing web visibility in two directions at once: answer systems can influence buyers without sending a visit, while automated agents can generate large volumes of requests without producing human attention. The result is a widening gap between what traffic logs record and what marketing teams actually need to understand.

    Bringing these developments together reveals a practical lesson: request volume, human engagement, and market influence must be measured as separate layers. A useful visibility model then reconnects those layers without treating any single signal as proof of AI-driven demand.

    More web requests do not necessarily mean a larger audience

    The clearest warning against equating traffic with attention comes from the bot data. The CrushPress.AI article on automated web requests reports, based on figures shared by Cloudflare CEO Matthew Prince, that bots accounted for 57.3% of global HTTP requests for HTML content, compared with 42.7% from humans. It also says this crossed a threshold Prince had predicted during SXSW would be reached by early 2027.

    Those percentages describe requests, not unique visitors, reading time, purchasing intent, or revenue. That distinction becomes especially important in an agentic browsing environment. As the article explains, a person shopping online might inspect a small number of pages, whereas an AI agent could request thousands while researching on the person’s behalf. The activity is real at the infrastructure level, but it does not create thousands of human opportunities to view advertising or engage with a page.

    This creates a measurement paradox. A site can receive more machine activity while seeing little corresponding improvement in human sessions or commercial outcomes. Publishers and brands therefore need to classify automated requests before using raw traffic trends to judge reach, content performance, or audience growth.

    AI can create influence while removing the observable visit

    The attribution problem is the mirror image of the bot-traffic problem. Automated systems may produce requests that overstate apparent audience activity, yet AI-generated answers may also create genuine brand influence that website analytics fail to capture.

    The CrushPress.AI article on AI search visibility describes prospects using tools such as ChatGPT or Google’s AI Overviews to discover vendors, compare alternatives, and form a shortlist before visiting any company website. A brand can appear in recommendations, comparisons, citations, or generated responses throughout that research. If the prospect later arrives through a branded query or a direct visit, conventional analytics may record only that final, deceptively simple step.

    This extends the zero-click pattern already associated with search features such as snippets, knowledge panels, and local packs. Generative answers can compress more of the research process into the search or assistant interface, making the missing click more consequential: discovery and evaluation can both occur before the measurable session begins.

    The combined implication is that low referral traffic does not necessarily mean low AI influence, just as high request volume does not necessarily mean high human interest. One metric can undercount the role of AI in a buying journey while another can overstate the audience that AI activity represents.

    A layered measurement model separates activity from impact
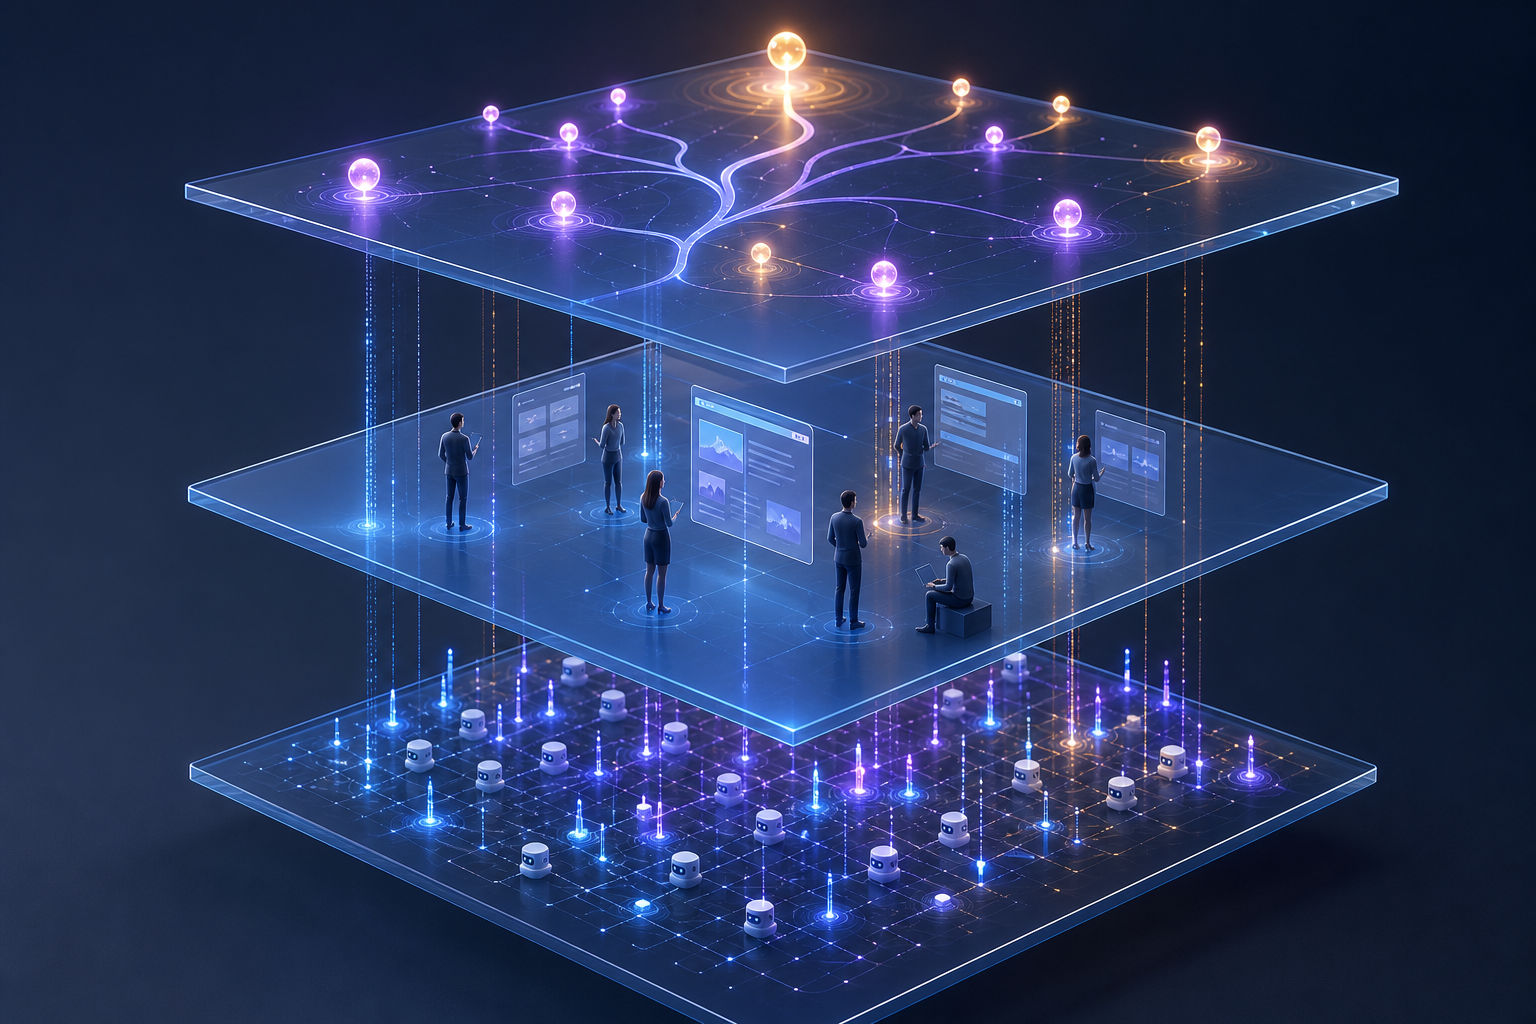
    Three connected transparent layers depict automated requests, human engagement, and broader influence as separate forms of measurement.

    A more useful model starts by distinguishing three questions. The first is whether machines are accessing the site. The second is whether people are arriving and engaging. The third is whether AI systems are shaping awareness or consideration before those visits. Keeping the questions separate prevents request logs, referral reports, and brand indicators from being collapsed into a single ambiguous traffic number.

    At the machine-activity layer, teams can examine bot identification and request patterns to determine how much recorded activity is automated. This layer helps explain infrastructure demand and content access, but it should not be presented as audience reach without supporting evidence of human engagement.

    At the human-behavior layer, traditional analytics remain useful for sessions, engagement, assisted conversions, and conversion paths. The AI search visibility article specifically identifies assisted conversions as a way to detect channels that contributed before the final interaction. These reports remain incomplete when an AI exposure sends no detectable referral, but they still show how observable touchpoints work together.

    At the influence layer, the same article proposes watching branded search growth, direct traffic trends, and brand appearances within AI prompts and recommendations. None is conclusive alone. Branded searches can have several causes, direct traffic is an imprecise category, and an AI mention does not prove that it affected a purchase. Read together over time, however, these signals can support a more credible account of how awareness and consideration are developing.

    The strongest interpretation comes from convergence. Repeated AI visibility followed by growth in branded demand, relevant human engagement, and assisted or completed conversions presents a more meaningful pattern than any isolated spike. This is an inference framework rather than person-level attribution: it indicates probable influence without claiming to reconstruct every buyer’s path.

    Key takeaways

    • Bot request share measures automated access, not the size or quality of a human audience.
    • AI-generated answers can influence discovery and vendor evaluation without producing a referral click.
    • Direct visits and branded searches may be downstream signs of earlier AI exposure, but neither proves causation by itself.
    • AI visibility measurement should combine machine-activity data, human engagement, conversion evidence, and brand-demand signals.
    • Trends that move together are more informative than a single traffic, mention, or attribution metric.

    Visibility strategy must serve machines and people differently
    An abstract AI agent and a person access the same central web content through different structured and visual pathways.

    The growth of automated access gives brands a reason to make content clear, authoritative, and interpretable by AI systems, as the bot-traffic article argues. But machine readability is not an end in itself. The commercial objective is still to help a person discover, evaluate, trust, and eventually choose the brand.

    Reporting should reflect that distinction. Bot requests belong in an access and infrastructure view; human sessions belong in an engagement view; AI mentions and branded-demand indicators belong in an influence view; conversions remain the outcome view. Connecting these views can reveal useful relationships, but labeling them separately limits false precision.

    As AI agents assume more browsing and answer engines absorb more research, the most resilient measurement programs will track both sides of the exchange: how machines consume content and how people reveal the effects later.
    References

  • Ad Targeting Updates Put Compliance Ahead of Reach

    Ad Targeting Updates Put Compliance Ahead of Reach

    Two platform updates illustrate the same shift in digital advertising: access to more inventory does not necessarily mean unrestricted access to audiences. Microsoft is widening placement options for eligible cryptocurrency exchanges, while Google is clarifying how sensitive-interest rules can constrain audience targeting in Demand Gen and Discovery campaigns.

    Taken together, the reports offer advertisers a practical lesson: compliance needs to shape campaign architecture, reach forecasts, and performance analysis from the outset, especially when a product, audience, or market falls into a restricted category.

    Two updates, but one platform-control model

    Microsoft’s change expands where certain advertisers can appear. According to the supplied report, cryptocurrency exchanges that pass the required checks can use Audience Ads throughout markets where Microsoft already permits crypto advertising. This moves eligible advertisers beyond search placements and into Microsoft’s native advertising inventory, including content, news, and partner environments.

    Google’s update addresses a different layer of campaign delivery. Its June documentation revision explains more clearly how personalized-advertising restrictions may affect Demand Gen and Discovery campaigns promoting products or services connected with sensitive interests. The report characterizes this as clarification of existing guidance, not the introduction of a new restriction.

    Platform updateWhat changesWhat remains constrained
    Microsoft Audience AdsEligible cryptocurrency exchanges gain access to additional native inventory in approved markets.Advertisers must still satisfy Microsoft’s crypto policy and applicable local requirements.
    Google Demand Gen and DiscoveryDocumentation more clearly explains possible serving effects when sensitive products or services use audience targeting.Personalized targeting remains restricted for sensitive-interest categories.

    Key takeaways

    • Microsoft is expanding placement eligibility for qualifying crypto exchanges, not relaxing its underlying cryptocurrency advertising standards.
    • Google is clarifying existing personalized-advertising rules rather than announcing a new targeting prohibition.
    • Advertiser eligibility, market eligibility, placement access, and audience eligibility are separate controls that can affect the same campaign.
    • Reach forecasts should account for policy constraints before budgets and performance expectations are finalized.

    Expanded inventory is still conditional inventory

    A translucent gate separates illuminated eligible ad placements from dim restricted display surfaces.

    Microsoft’s expansion could give compliant exchanges a broader awareness opportunity because Audience Ads can reach people outside an active search session. However, the report makes clear that the expansion applies only where cryptocurrency advertising is already approved. Exchanges must continue to satisfy Microsoft’s Cryptocurrency and Related Products policies as well as relevant local laws and regulations.

    Google’s clarification highlights another form of conditional reach. Demand Gen campaigns rely heavily on audience signals and personalized targeting across YouTube, Discover, and Gmail, according to the source. When the promoted offering relates to areas such as health conditions, financial hardship, or personal difficulties, sensitive-interest restrictions may reduce audience eligibility, reach, or delivery.

    The distinction matters operationally. Microsoft is addressing whether a qualifying advertiser can enter more inventory, whereas Google’s guidance concerns how an otherwise available campaign may serve when particular audience methods intersect with a sensitive offering. A campaign can therefore be approved at the account or product level and still face narrower delivery at the targeting level.

    Compliance belongs in campaign planning, not final review

    These updates suggest that regulated advertisers should evaluate four questions before estimating reach: whether the advertiser is eligible, whether the product may be promoted in the intended market, whether the desired inventory is permitted, and whether the selected audience method is allowed for that subject matter. Treating those questions as separate checks makes it easier to identify the actual source of a restriction.

    For cryptocurrency exchanges, a single campaign blueprint should not be assumed to apply across every market. The Microsoft report specifically ties Audience Ads access to approved crypto-advertising markets and local requirements. Planning should therefore preserve a clear connection between each market, its eligibility status, and the placements being activated.

    For healthcare, financial services, and other sensitive sectors, audience strategy deserves the same early scrutiny. Google’s clarification means that a technically selectable audience does not by itself guarantee full delivery. Forecasts and stakeholder expectations should reflect the possibility that personalized-advertising rules will narrow the addressable audience.

    Performance analysis needs a policy-aware baseline

    An analyst examines abstract campaign signals passing through a translucent compliance filter.

    Policy changes and policy clarifications can both alter the context in which results are interpreted. Microsoft’s expanded inventory may change the mix of placements contributing impressions and engagement for an eligible exchange. Google’s clarified serving implications may help explain why a sensitive-category campaign reaches fewer people than its targeting settings appear to allow.

    Advertisers should avoid attributing every delivery shortfall to bids, budgets, creative, or audience size before checking policy eligibility. Where reporting permits, results should be examined by campaign type, placement, and market so that an inventory expansion is not confused with a targeting improvement, and a compliance-related limit is not mistaken for weak creative performance.

    The most useful tests will begin with a documented compliance assumption. If reach changes, teams can then distinguish among a platform-access change, a market restriction, an audience limitation, and an ordinary campaign-performance effect. That distinction is essential for deciding whether optimization can solve the issue or whether the campaign design itself must change.

    What advertisers should watch next

    Microsoft’s expanded inventory will be worth monitoring for adoption by qualifying exchanges and for any later expansion into additional approved markets. On Google, advertisers should watch how the clarified guidance translates into observable Demand Gen delivery for sensitive products and services. In both cases, the durable advantage will come from treating policy eligibility as a measurable campaign input rather than an administrative afterthought.

    References

  • How TV Advertising Creates and Captures Search Demand

    How TV Advertising Creates and Captures Search Demand

    A television ad can end on screen while its effects continue in search. Viewers who want to identify a brand, understand an offer, find a featured personality or act on the message often turn to Google or YouTube, making search the immediate response channel for interest created elsewhere.

    The practical payoff is clear: television creative, SEO, paid search and landing-page planning should operate as one demand system. The available source provides an illustrative campaign case rather than a broad, independently verified evidence base, but it exposes several useful principles for capturing attention after an ad airs.

    TV creates demand that search must resolve

    Television and search play different roles in the same journey. A TV spot can introduce a story at scale, while search lets individual viewers pursue whatever part of that story matters to them. That pursuit may lead directly to the advertiser, but it can also lead to a publisher, video platform, retailer or competing brand with a more relevant result.

    The supplied CrushPress.AI article uses Fox Sports’ World Cup campaign as its central example. It reports that DAIVID ranked the campaign’s emotionally driven “Miracle” spot as the most engaging World Cup ad in its study. The ad imagined Team USA winning the tournament and contained subjects that could prompt searches involving the U.S. team, the 2026 World Cup and Christian Pulisic. These details illustrate how one piece of creative can generate several distinct lines of inquiry rather than a single predictable brand search.

    Speed is part of the challenge. The article cites a study claiming that 75% of search activity associated with a television ad occurs within the first two minutes. Because the underlying study is not identified in the supplied material, that figure should be treated as a reported planning signal rather than a universal benchmark. The broader operational lesson is still useful: pages, campaigns and budgets need to be ready before the broadcast, not assembled after a search spike becomes visible.

    A query map connects the commercial to viewer intent

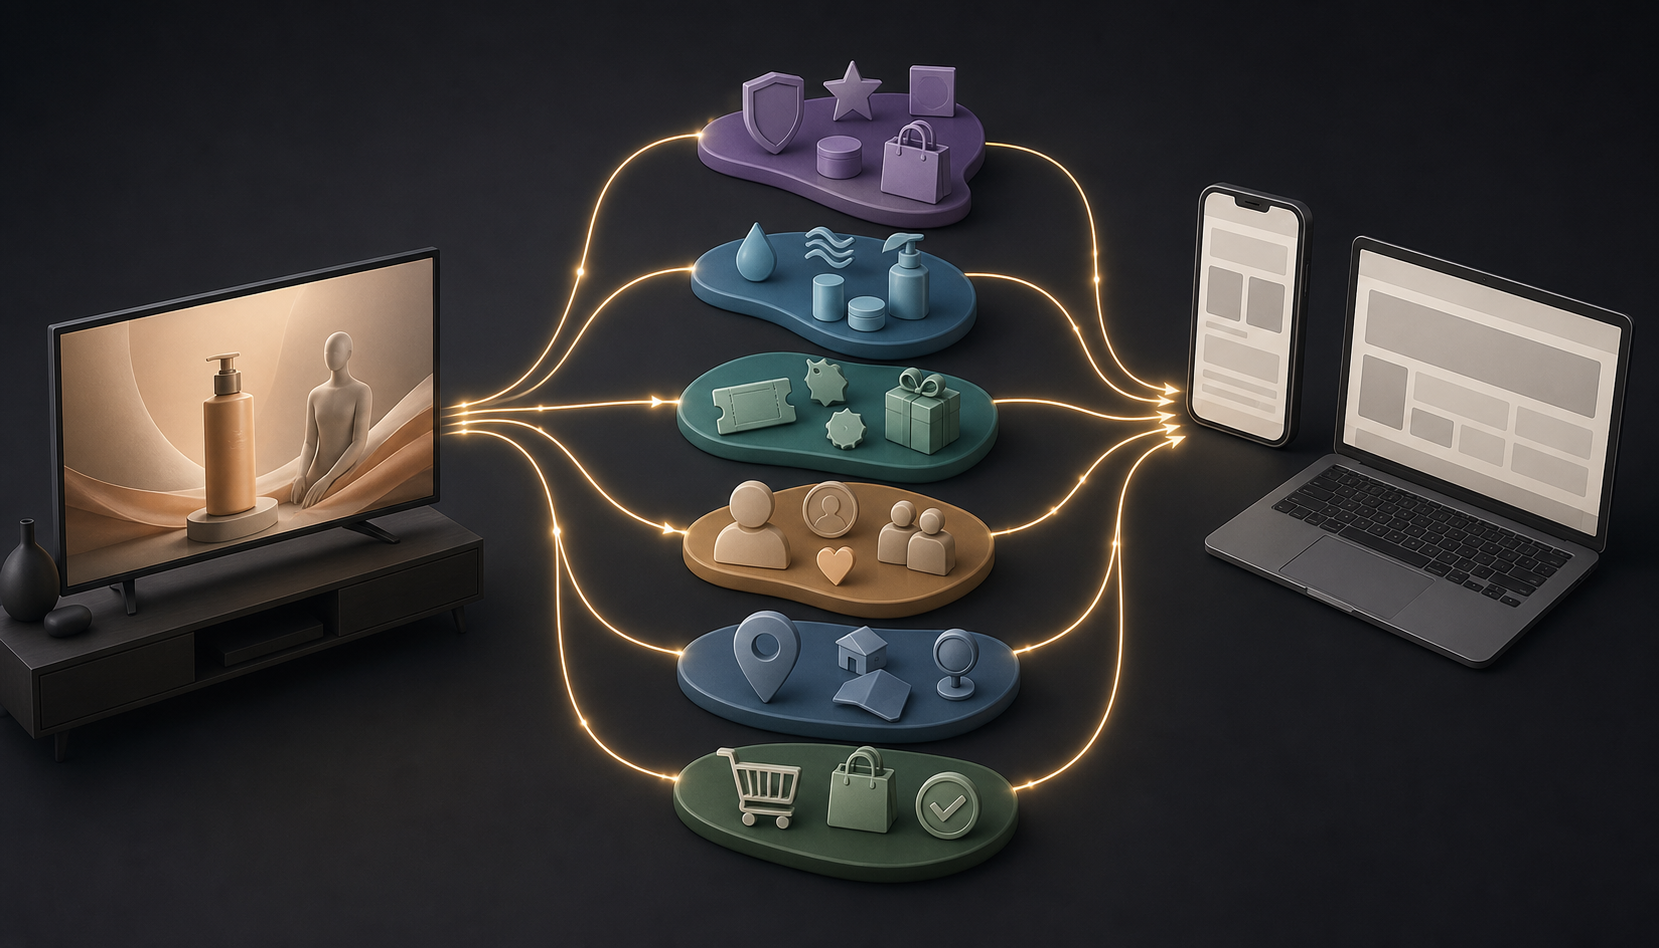
    Visual pathways branch from a television commercial into symbol clusters representing several viewer intentions and then connect to generic search results.

    The strongest preparation begins by translating the ad into likely search intentions. The source groups those intentions into four useful families. Each represents a different viewer question and therefore calls for a different response.

    Query familyWhat the viewer wantsExample reported by the sourceAppropriate search response
    BrandedThe advertiser or destination seen in the commercialFox SportsAccurate brand results, sufficient paid-search coverage and a clear route to the relevant experience
    CampaignThe commercial, slogan or storyline itselfMiracle adA campaign page or video that uses the same naming and creative cues
    AssetA song, celebrity, athlete or other memorable elementSong in Fox World Cup adContent that identifies the asset and connects that curiosity back to the campaign
    CategoryA practical solution related to the subject of the adHow to watch World Cup 2026Useful information that answers the broader need while preserving a path to conversion

    This framework prevents a common mismatch: optimizing only for the advertiser’s preferred language. Viewers may remember the story but not the brand, recognize an athlete but not the campaign name, or want to complete a task rather than replay the commercial. A query map should therefore be built from the actual components of the creative, including visible people, music, claims, products, locations, calls to action and implied questions.

    Search readiness must begin before media goes live

    Search teams need access to the campaign while it is still being developed. Early collaboration allows them to identify searchable elements, check whether campaign language is understandable outside the commercial and reserve suitable pages, metadata and paid-search terms. It also gives creative teams a chance to resolve ambiguous naming that could make the advertised experience difficult to find.

    Organic and paid search have complementary jobs. SEO can establish durable pages for campaign, asset and category questions. PPC can provide immediate visibility, protect high-value branded demand and respond to sudden variation in query volume. Neither channel compensates for a weak destination: the landing experience should visibly continue the television story so viewers can confirm that they reached the right place.

    Budget preparation also needs to reflect the media schedule. The source argues that advertisers should increase capacity around likely demand surges. In practice, that means sharing airtimes and geographic plans with search teams, reviewing campaign limits before each major broadcast window and monitoring whether relevant ads remain eligible. This is especially important when competitors or publishers can bid on the same emerging interest.

    Measurement should connect airtime, queries and outcomes

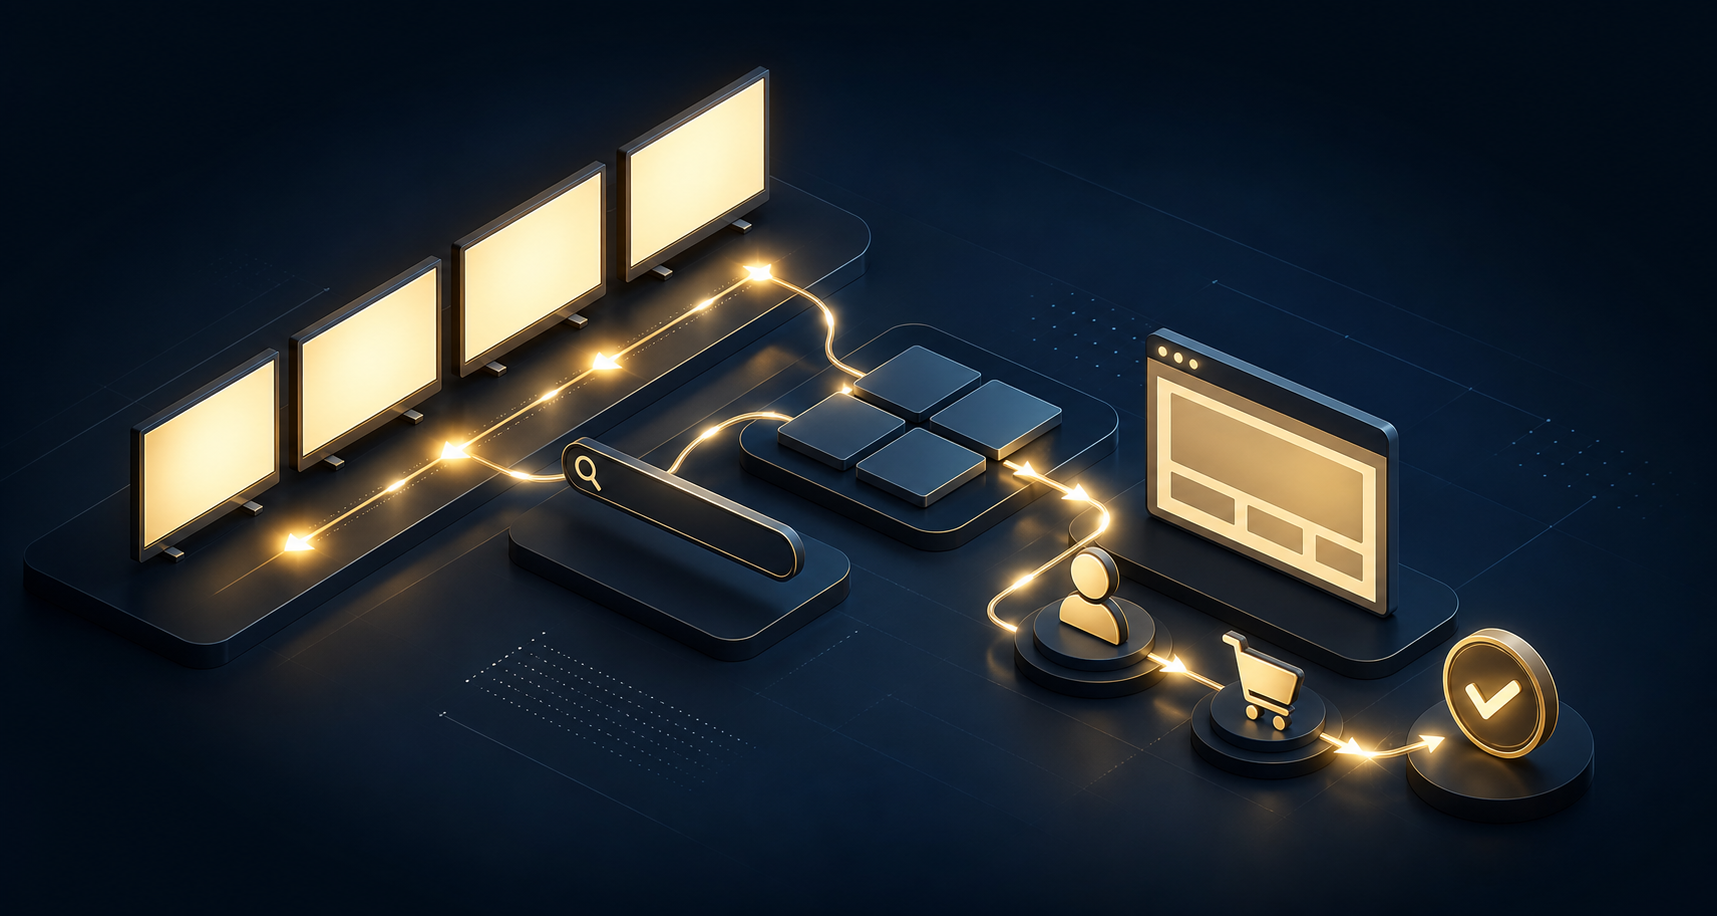
    Pulses of light connect a sequence of television airings with generic search, analytics, landing-page and completed-action symbols.

    A search lift observed after a broadcast is informative, but it does not automatically prove that television caused every additional query or conversion. Existing demand, news coverage, live events and other marketing activity may overlap with the campaign. Measurement should therefore compare several signals instead of relying on a single traffic chart.

    A useful analysis aligns ad schedules with changes in branded, campaign, asset and category searches; paid-search impressions and clicks; organic visits to prepared pages; on-site engagement; and meaningful business outcomes. Geographic differences or comparable periods without an airing can add context when such comparisons are available. Query-level reporting is particularly valuable because it shows which parts of the creative generated curiosity and which viewer needs the search experience failed to satisfy.

    The framework also improves interpretation. A rise in asset searches may indicate memorable creative without strong brand linkage. Increased branded searches paired with weak engagement may point to an inconsistent landing page. Category growth captured mainly by competitors may reveal insufficient coverage beyond the brand name. Search data can consequently inform both campaign performance and future creative decisions.

    Key takeaways

    • Treat search as part of the television campaign architecture, not as a follow-up channel.
    • Map branded, campaign, asset and category queries from the finished creative before the first airing.
    • Prepare organic pages, paid-search coverage, landing experiences and budget capacity against the media schedule.
    • Use consistent campaign language across the commercial, search ads, metadata and destination pages.
    • Assess query patterns alongside traffic and business outcomes, while accounting for other possible demand drivers.

    As viewing and searching continue to overlap, the advantage will belong to advertisers that design the handoff deliberately. Search planning can turn a fleeting moment of television interest into a coherent next step while giving creative and media teams better evidence for the campaigns that follow.

    References

  • Discover Google’s New Search Profiles for Publishers

    Discover Google’s New Search Profiles for Publishers

    Hey there, have you heard about Google’s latest feature within Google Discover? They’ve just launched Search profiles in the U.S., and it’s a game-changer for publishers like me. These profiles act as enhanced landing pages where my audience can not only follow me but also see a collection of my latest articles, videos, and social media posts all in one convenient spot.

    Google has been working on this for quite some time, refining and testing it over several months. They’ve even made some tweaks, such as adding shortnames, which make it even easier to share these profiles.

    What are Search Profiles? According to Google’s description:

    “Search profiles give publishers and creators a central place to showcase their latest articles, videos, and social posts. People can easily follow sources from their profile, so they’re more likely to see that content on Discover, found on the home screen of the Google app.”

    It’s described as a “new way for publishers and creators to shape their presence on Search. Search profiles are a dedicated, shareable space to highlight content across platforms and help audiences find accurate, up-to-date information about sources on Search.”

    What it looks like: Curious to see it in action? Here’s a video demonstration:

    Managing Your Search Profile: If you’re a publisher or creator with a significant following on a major social or video platform, you’re in luck! You’ll be able to claim your Search profile, personalize it with an avatar, bio, and links to your website and social media platforms.

    Once you claim your profile, it might even create a Knowledge Panel for you, or enhance your existing one with updated details and a direct link to your profile.

    If you’re interested in setting up your own Search profile, check out this guide for creating a profile, claiming an existing one, and managing it.

    Availability: Currently, this feature is available in the U.S. for users and publishers who meet a certain follower threshold. Here’s what you need:

    • TikTok: 300,000 followers
    • YouTube: 100,000 subscribers
    • Instagram: 100,000 followers
    • X: 100,000 followers

    Why This Matters: As a publisher, I’m always looking for ways to get more visibility. Google’s new feature allows us to increase our reach not just on Google platforms but across our entire digital presence. It’s an exciting time, though one has to ponder whether this will be enough in the fast-paced world where AI continues to evolve.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How to Verify AI Answers Before They Become Expensive

    You have an AI answer that sounds precise, uses the right vocabulary, and gives you a clear next step. The problem is that you cannot tell whether it is correct without already knowing the subject.

    You do not need to reject AI or fact-check every sentence with equal intensity. You need a verification process that becomes stricter as the cost of being wrong rises.

    Confidence is not evidence

    An AI hallucination is a plausible response that is incorrect, unsupported, or assembled from assumptions the model has not made clear. It can include real terminology, a logical sequence, and a confident conclusion. Those qualities make the answer readable. They do not make it reliable.

    This distinction matters when you are working outside your expertise. A weak answer does not always look weak. You may notice an obvious factual error in your own field, yet accept the same style of answer about a vehicle repair, a legal requirement, analytics configuration, or unfamiliar platform.

    Consequences can escalate quickly. Confident AI recommendations have included faulty technical SEO direction and a premature vehicle diagnosis. In the SEO case, misleading language about penalties could also have changed how leadership viewed a necessary migration. The risk was not limited to implementation. It extended to budgets, trust, and internal decision-making.

    Treat polished language as a presentation layer. Evidence must still come from observable behavior, authoritative documentation, original data, or a qualified person who accepts responsibility for the judgment.

    Match verification effort to the cost of being wrong

    Start by asking what happens if you follow the answer and it fails. This is more useful than asking whether the output merely feels accurate.

    • Low consequence: The output is easy to reverse and affects no customer, budget, production system, or factual claim. Use it as a working draft and review it normally.
    • Meaningful consequence: The answer could affect rankings, reporting, client communication, or a public page. Verify its important claims against direct evidence before publishing or deploying.
    • High consequence: The recommendation could trigger substantial spending, irreversible changes, legal or security exposure, health decisions, or damage across a live site. Stop and obtain qualified human approval.

    Raise the verification level when the answer contains absolute language such as “always,” “must,” or “penalty,” especially when no condition or evidence accompanies it. Also slow down when the AI reaches a diagnosis before gathering enough context, changes its conclusion after receiving basic facts, or recommends an action you cannot safely undo.

    Your own familiarity is part of the risk calculation. If you cannot explain why the recommendation should work, you are not in a good position to approve it alone. That is a signal to involve an expert, not a reason to ask the model for an even more confident version.

    Use a verification workflow that separates claims from decisions

    Do not verify a long AI response as one object. Break it into the claims you can test and the decisions that require judgment.

    1. State the proposed action. Reduce the output to a plain sentence: “Change this canonical,” “replace this component,” or “publish this claim.” If the action remains vague, it is not ready for approval.
    2. Extract the supporting claims. List the facts that must be true for the action to make sense. Separate observed facts from assumptions and predictions.
    3. Ask what is missing. Identify the data, configuration, version, environment, symptoms, or business constraint the AI did not have. Missing context is often where a persuasive answer becomes brittle.
    4. Inspect direct evidence. Open any cited material, check the actual system, and compare the recommendation with real output. A citation generated by AI is only a lead until you confirm that it exists and supports the claim.
    5. Test reversibly. Use a draft, preview, staging environment, isolated sample, or limited rollout where one is available. Record the expected result before testing so that you do not reinterpret failure as success.
    6. Assign approval. Name the person who can judge the evidence and accept the consequence. High-risk work should not be approved by the person who merely generated or copied the AI response.

    For technical SEO, this means checking the site rather than debating terminology with the model. Inspect the rendered canonical, the destination URL, parameter behavior, templates, and the affected page set. Test the proposed change in a controlled environment when possible. A model can help you form hypotheses and test cases, but the implementation decision should follow what the site actually does.

    For content and structured data, verify each factual statement and each property that describes a real entity. Do not let AI invent credentials, reviews, product details, authorship, or organizational relationships. The final markup should agree with the visible page and the underlying business record.

    Give experts a verification packet, not a chat transcript

    Expert review works best when the reviewer can see the decision, evidence, and uncertainty without reconstructing your entire AI conversation. Prepare a compact verification packet with:

    • the exact action you are considering;
    • the material claims on which it depends;
    • the AI output, clearly labeled as unverified;
    • the documentation, screenshots, logs, crawl results, or other direct evidence you checked;
    • the assumptions and unanswered questions;
    • the likely consequence if the recommendation is wrong; and
    • the specific approval or correction you need from the reviewer.

    Ask the expert to challenge the reasoning, not merely confirm the conclusion. Useful prompts include: “Which assumption is weakest?”, “What evidence would disprove this?”, and “What should we inspect before changing production?” These questions make disagreement visible while there is still time to act on it.

    Keep the resulting decision record. Note what was approved, by whom, from which evidence, and under what conditions. If the recommendation later appears in a client deliverable, optimization playbook, or automated workflow, your team can trace why it was accepted instead of treating repeated AI language as established fact.

    Key takeaways

    • Fluent, specific language does not prove that an AI answer is correct.
    • Verify more aggressively when an error could affect money, rankings, customers, production systems, or trust.
    • Separate testable claims from the judgment required to approve an action.
    • Use direct evidence and reversible tests before relying on another AI-generated explanation.
    • Bring in a qualified expert when you cannot evaluate the reasoning or safely absorb the failure.

    Before acting on your next AI recommendation, write down the proposed action, the evidence it depends on, and the person qualified to approve it. If any of those fields is blank, the answer is still a hypothesis.

    References

  • Google Ads Customer Match: Setup, Uses, and Privacy Checks

    You have customer data that competitors can’t copy. The question is whether you’re giving Google Ads a clean, current, consented version of it—or leaving its automation to learn from the same broad signals available to everyone else.

    Customer Match can support acquisition, retention, exclusions, bidding, and audience discovery. You can get some of that value even before your account qualifies to target a customer list directly.

    Key takeaways

    • Upload eligible first-party customer data even if your account hasn’t reached the spending threshold for direct Customer Match targeting.
    • Choose one job for each list: find new customers, retain existing ones, prioritize high-value customers, or exclude people who shouldn’t see an offer.
    • Use a direct integration when possible; otherwise, establish a recurring CSV refresh schedule.
    • Upload only data collected with appropriate consent, and make sure your privacy policy explains advertising-related data sharing.
    • Judge a list by matchable scale, freshness, and business relevance—not by its raw row count.

    Upload your list before direct targeting becomes available

    A common mistake is treating the US$50,000 lifetime-spend threshold as a reason to postpone Customer Match entirely. That threshold affects direct targeting and exclusions. Eligibility also requires an account in good standing and at least 90 days of spending history.

    If you haven’t met those conditions, you can still upload a customer list for use as an automation signal. Google can use the characteristics of those customers to inform Smart Bidding and optimized targeting. This matters because your first-party data gives the system information that isn’t available from generic market signals alone.

    An uploaded list can also unlock Audience Insights in Audience Manager. Inspect the demographic patterns and Google audience segments associated with your customers. Then turn the findings into testable decisions: adjust a landing page for the audience you actually attract, develop Demand Gen creative around a recurring interest, or challenge an assumption about who buys from you.

    Don’t read an insight as proof of causation. Use it to form a campaign hypothesis, then validate that hypothesis with conversion data.

    Give each Customer Match list one clear campaign job

    Customer Match can work across Search, Shopping, Gmail, YouTube, and Display once your account is eligible. Performance Max doesn’t offer conventional audience targeting, but customer lists can still shape Customer Lifecycle goals.

    Business objectiveHow to use the listWhat to check
    Acquire only new customersUse New Customer Only mode so known customers are excluded.Confirm that the list covers enough existing customers to make the exclusion meaningful.
    Pay more for new customersUse New Customer Value to distinguish acquisition value from an ordinary conversion.Make sure the added value reflects your economics rather than an arbitrary premium.
    Drive repeat purchasesUse Customer Retention mode to concentrate on known customers.Exclude people whose purchase timing or status makes the offer irrelevant.
    Prioritize your best customersBuild a high-value customer segment from a defensible business rule.Define value consistently, such as the customer status already used in your CRM.
    Prevent wasted impressionsExclude matched customers from acquisition campaigns when they shouldn’t receive the offer.Check that your list is refreshed frequently enough to catch recent customers.

    Scale determines whether these controls will materially change delivery. One practical heuristic is the 1% rule: compare the active list with the population in your target geography. In a US-wide campaign, 1% of a population of 340 million would be about 3.4 million people. This is a planning heuristic, not a Google eligibility rule. A smaller list can still be useful, but you shouldn’t expect it to redirect a large national campaign by itself.

    Use the narrowest list that still has enough scale for its job. A list of all historical leads may be large but strategically muddy. A current-customer list, lapsed-customer list, and high-value segment give you cleaner decisions, provided each status is defined and maintained.

    Build a repeatable upload and refresh process

    Start in Tools > Data Manager and look for a direct connection to the system that holds your customer records. Shopify, HubSpot, and Salesforce integrations can keep data synchronized without repeated manual exports. If a suitable connection isn’t available, use a CSV upload through Tools > Shared Library > Audience Manager.

    Your operating process should be simple enough that it still happens during a busy month:

    1. Define the list’s purpose and the customer status that qualifies a person for it.
    2. Remove records that don’t belong, including test accounts and people outside the intended segment.
    3. Confirm that the data was collected with the consent required for advertising use.
    4. Connect the platform or upload the CSV.
    5. Check whether the resulting audience has enough matched users to serve its intended campaign function.
    6. Set an owner and a refresh cadence.
    7. Review campaign settings after every major list-definition change.

    Match the cadence to the speed of your business. Daily synchronization makes sense when leads or purchases arrive regularly and recent customer status affects exclusions. A slower business may be adequately served by a bi-weekly or monthly refresh. The key is to choose the interval deliberately instead of relying on someone to remember.

    If you’re also using Enhanced Conversions, examine conversion-based customer lists. These can automatically maintain audiences of people who completed selected conversion actions. A conversion records an event; a data segment represents a group that can continue to inform campaign decisions. Connecting the two reduces manual list maintenance.

    Put consent and list quality ahead of match volume

    Customer Match is not permission to upload every email address your organization possesses. Use your own customer data, collected with suitable consent. Bought third-party lists can violate Google policy and applicable privacy law. Your privacy policy should clearly disclose that customer data may be shared with providers such as Google for advertising.

    Healthcare and finance require particular caution because sensitive-industry restrictions can prevent Customer Match use. Don’t try to work around a restriction by renaming a segment or broadening its label. If eligibility is unclear, verify the proposed use against Google policy and your organization’s legal requirements before uploading anything.

    Assign operational responsibility as well. Marketing can define the campaign objective, but someone must own consent status, suppression rules, customer-status logic, and refresh failures. Record the list’s purpose, inclusion criteria, update frequency, and connected campaigns in the same place your team documents campaign settings.

    Finally, monitor outcomes that match the list’s job. For acquisition exclusions, watch how much spend and conversion volume move toward new customers. For retention, evaluate repeat-purchase performance. For an automation signal, compare campaign performance over a meaningful period without crediting every change to the list. Customer Match improves the information available to Google Ads; it doesn’t replace sound bidding, creative, measurement, or offer strategy.

    Your next step is concrete: identify one consented customer segment, give it one campaign purpose, and either connect it in Data Manager or schedule its first upload. Then put the refresh date on the calendar before you leave Audience Manager.

    References

  • AI-Driven SEO Strategy: Build Monitoring That Leads to Action

    You can lose search visibility without seeing one dramatic ranking drop. A robots change can block discovery, a stale claim can weaken trust, and a page can keep receiving traffic while disappearing from AI citations. If your dashboard reports only clicks and conversions, it may reveal the damage too late.

    A useful monitoring system works as a control loop: detect a meaningful change, identify the affected layer, assign an owner, repair the cause, and verify recovery. That gives you something more valuable than another dashboard: a repeatable way to protect and improve visibility.

    Key takeaways

    • Monitor access, meaning, selection, and business outcomes separately so you can locate failures quickly.
    • Use alerts for changes that require a decision, not every movement in a metric.
    • Track AI citations alongside rankings because retrieval and selection are different stages.
    • Keep page copy, entity details, internal links, and structured data consistent.
    • Pair monitoring with original information, brand building, distribution, and public relations.

    Monitor the full path from discovery to conversion

    Start by separating the signals in your dashboard. Search performance can fail at several points, and each point needs a different response.

    Monitoring layerWhat to watchWhat the signal tells you
    AccessStatus codes, robots directives, noindex tags, canonicals, sitemaps, rendered content, and important resource filesWhether crawlers and AI systems can reach the intended version of a page
    MeaningCore claims, headings, organization and author details, internal links, JSON-LD, and consistency across related pagesWhether machines can interpret the page and connect it to the right entities
    SelectionRankings, AI-answer inclusion, citations, brand mentions, competitor inclusion, and visibility by query intentWhether an eligible page is being chosen for an answer or search result
    OutcomeLanding-page visits, identifiable AI referrals, conversions, assisted actions, and engagement with priority pagesWhether visibility is producing useful business activity

    This separation matters because AI-facing search introduces a selection problem. A system may discover and understand your page without choosing it for a generated response. Broader candidate pools place more weight on verification, semantic relationships, trust signals, and distinct information. A crawl report cannot tell you whether you are winning that stage.

    Build your monitored inventory around business importance. Include revenue pages, high-value informational pages, core entity pages, important query groups, and the prompts or questions that lead customers toward a decision. Record the expected URL, canonical, indexability, main claim, schema type, conversion action, and responsible owner for each asset. That expected state becomes your baseline.

    Create alerts that point to a decision

    An alert is useful only when someone knows what it means and what to do next. Continuous monitoring can protect visibility from technical failures, but 24/7 detection and real-time notification still need sensible routing and response rules.

    Favor state changes over routine noise. A priority page becoming non-indexable deserves an alert. So does an unexpected canonical change, a missing schema block, a mismatch between visible copy and JSON-LD, or the disappearance of rendered content. Normal day-to-day movement in one query usually belongs in a trend report unless it repeats across a meaningful group.

    Give every alert a severity, owner, and response note. Reserve the highest severity for failures that affect access or conversion across important assets, such as a sitewide robots change or unavailable purchase path. Use a lower severity for isolated visibility changes that require investigation but do not establish a systemic failure.

    Your alert should answer these questions without requiring a separate investigation just to understand it:

    • What changed?
    • Which URLs, entities, queries, or prompts are affected?
    • What was the last known good state?
    • Was there a deployment, content update, migration, or schema change nearby?
    • Who owns the next action?
    • How will recovery be verified?

    Keep ranking, citation, and conversion alerts connected rather than blended. If citations decline while access and rankings remain stable, investigate content distinctiveness, entity clarity, and corroborating signals. If rankings and citations decline together after a template release, start with technical and rendering checks. If visibility improves but conversions do not, inspect intent alignment and the landing-page journey.

    Use one response workflow for every visibility incident

    A shared workflow prevents teams from making unrelated edits until a metric happens to recover. Use the same sequence whether the first signal comes from crawling, rankings, AI citations, or analytics.

    1. Confirm the symptom. Check the affected URL, query, prompt, device, and market. Determine whether the change is isolated or appears across a coherent group.
    2. Classify the failure. Decide whether the problem concerns access, interpretation, selection, or outcomes. Do not rewrite content to solve a blocked crawler.
    3. Compare with the baseline. Review the last known good crawl, rendered page, structured data output, citation record, and relevant deployment or editorial notes.
    4. Repair the smallest plausible cause. Restore the intended directive, correct the conflicting fact, repair the markup, strengthen an unclear answer, or realign the page with its query intent.
    5. Validate both human and machine views. Check the visible page and its rendered output. Confirm that structured data describes the same facts a reader can see.
    6. Annotate and watch recovery. Record the change, affected assets, owner, and validation result. Keep monitoring the original symptom and downstream business outcome.

    Do not treat recovery as proof that every edit helped. When several changes are bundled together, you lose the ability to identify the effective fix. Small, documented interventions produce a more useful operating history.

    Improve the information that AI systems can select

    Monitoring protects existing visibility, but it cannot create information worth selecting. Pages need precise claims, clear entity relationships, and details that add something beyond the same summary already available elsewhere.

    Review important pages at the claim level. Each answer should state one clear idea, explain its scope, and avoid mixing several loosely related claims in a long paragraph. Remove outdated facts and reconcile contradictions between product pages, help content, author profiles, organization details, and structured data. JSON-LD should reinforce the page’s meaning, not introduce unsupported facts that readers cannot verify.

    Strengthen internal relationships as well. Link an organization to its people, products, policies, evidence, and relevant expertise using descriptive language. This creates a coherent path for readers while helping machines interpret how the entities relate.

    Then look beyond on-page optimization. Keyword research and page improvements remain foundational, but sustainable growth also depends on original research, proprietary information, brand visibility, distribution, and public relations. Track those activities as visibility inputs. Monitor whether new findings earn mentions, whether expert contributions create relevant connections, and whether distribution reaches the communities where your audience already looks for answers.

    Start with one group of commercially important pages. Define their expected technical state, record their core claims and entity relationships, add citation and outcome tracking, and assign each alert to a named owner. Once that loop works, extend it to the next group. A smaller system that produces action is more valuable than a large dashboard nobody trusts.

    References

  • AI Brand Sentiment Intelligence: Turn Signals Into Action

    AI Brand Sentiment Intelligence: Turn Signals Into Action

    Your AI visibility dashboard says brand sentiment declined. That sounds urgent, but it doesn’t tell you whether an answer contains a factual error, repeats a legitimate customer complaint, favors a competitor, or simply uses cautious language.

    You need the explanation behind the label. Basic monitoring may reveal whether sentiment moved, even at the platform level, while leaving the cause and next action unresolved. AI brand sentiment intelligence closes that gap by connecting each signal to evidence, business impact, ownership, and a response you can test.

    Separate sentiment from the signals around it

    A positive, neutral, or negative label is only the start. Before acting, separate five questions that dashboards often compress into one score.

    Was your brand present?

    An answer cannot influence perception of your brand if it never mentions you. Track visibility separately from sentiment. A favorable description appearing in a small fraction of relevant answers is a different problem from broad visibility paired with unfavorable framing.

    What position did the answer take?

    Capture the exact wording that creates the impression. Terms such as expensive, specialized, complicated, reliable, established, or suitable for beginners carry different implications. A seemingly neutral qualification can matter more than an obviously negative adjective when it discourages the reader from considering your product.

    Was the claim accurate?

    Accuracy and sentiment need separate fields. An unfavorable statement may be accurate. A favorable statement may be wrong. Labeling both dimensions prevents your team from treating a product problem as a messaging problem or celebrating praise that could later undermine trust.

    What appears to drive the claim?

    Look for recurring themes and cited evidence. Pricing, reliability, customer support, security, ease of use, market position, and product fit are drivers. Positive or negative is the output. The driver is what gives you something to change.

    Could the wording change a decision?

    Not every unfavorable mention deserves escalation. Give priority to answers shown for prompts that influence evaluation, comparison, risk assessment, and purchase. A minor criticism attached to a low-relevance query may matter less than a cautious recommendation delivered when a buyer asks for a shortlist.

    Build a diagnosis workflow your team can repeat

    An isometric investigation workspace routes abstract AI response tiles through triage, evidence review, impact assessment, and team ownership stations.

    Start with decisions, not random brand prompts

    Create a stable prompt set around the questions your audience asks while discovering, evaluating, comparing, and validating a purchase. Include unbranded category questions, brand-specific questions, direct comparisons, use-case prompts, and risk or objection prompts. This reveals whether the narrative changes with user intent.

    Keep the core wording stable so later runs remain comparable. Record the platform, model or experience when visible, date, prompt, complete answer, relevant passage, citations, competing brands, and sentiment label. AI responses can vary between runs, so preserve the answer itself rather than storing only a dashboard score.

    Classify the reason before assigning the owner

    Give each meaningful passage a primary driver and, where needed, a secondary one. Keep the taxonomy small enough that two reviewers can apply it consistently. When everything becomes its own theme, you cannot see patterns. When every issue is simply called reputation, nobody knows what to fix.

    Add an evidence status: supported, unsupported, outdated, ambiguous, or not yet verified. Then record where the claim appears to come from, such as your own site, a review platform, editorial coverage, a community discussion, or an unidentified origin. This turns a vague perception problem into an evidence map.

    Prioritize patterns, not isolated answers

    Review a finding across relevant prompts, AI experiences, and repeated runs before treating it as a narrative shift. A single answer is evidence to inspect, not a trend by itself. Give each recurring issue a priority based on audience relevance, potential decision impact, recurrence, factual confidence, and your ability to change the underlying condition.

    Your working record should end with an owner and a next action. Product teams can address real capability gaps. Customer experience teams can address service patterns. Communications teams can correct public facts. SEO and content teams can improve discoverability, clarity, comparison content, and machine-readable entity information. Legal or compliance teams should review sensitive claims rather than leaving marketers to interpret them alone.

    Match each sentiment driver to the right intervention

    Four abstract sentiment problems surround a central diagnostic hub, each paired with a different corrective tool or mechanism.

    Correct factual gaps at the canonical location

    If AI answers repeat an incorrect price, feature, policy, location, or company relationship, first make the correct fact explicit on the page that should own it. Use consistent wording across important profiles and supporting pages. Add appropriate structured data when it accurately represents visible page content, but don’t treat schema as a guarantee that an AI system will adopt the correction.

    Make the correction easy to extract. State the fact directly, give it a clear heading, include necessary qualifications nearby, and show when time-sensitive information was updated. If multiple official pages disagree, resolve that conflict before producing more content.

    Fix substantiated criticism before trying to outrank it

    When unfavorable framing reflects real customer experience, the durable response begins outside SEO. Document the operational issue, route it to the team that can change it, and publish clear information about the remedy only when the facts support that message. More promotional copy will not neutralize a pattern that customers continue to confirm.

    Strengthen weak or generic positioning

    If AI systems describe your brand accurately but generically, clarify who the product serves, what problem it handles, when it is a strong fit, and where it is not. Create comparison and use-case pages that answer the criteria buyers actually evaluate. Support claims with verifiable details rather than broad superlatives.

    This is also where competitor context matters. Do not chase every favorable phrase attached to another company. Identify the decision criterion behind it. If a competitor is repeatedly preferred for ease of implementation, decide whether you need a better implementation experience, clearer documentation, stronger independent evidence, or a more precise statement of the segment you serve best.

    Treat absence as its own problem

    A brand that is missing from relevant recommendations does not have a sentiment problem yet; it has a representation or discovery problem. Check whether your entity is described consistently, whether important product and company facts are accessible, and whether credible third parties discuss you in the contexts you want to enter. Measure visibility gains before expecting sentiment gains.

    Validate movement without confusing noise for progress

    Establish a baseline before making a change. Preserve the prompt set and evidence records, then document the intervention: which page changed, which operational issue was addressed, which claim was clarified, and when the change became public. Without that change log, later movement is easy to misattribute.

    Re-run the same core prompts and examine several layers. Did brand visibility change? Did the relevant claim change? Did the driver appear less often? Did citations shift? Did the recommendation outcome change? A higher positive-sentiment share is useful only when you can connect it to meaningful language and buyer-relevant prompts.

    Keep discovery prompts separate from your fixed measurement set. New prompts help you find emerging narratives, while stable prompts help you compare performance. Combining both into one score can make normal changes in the prompt mix look like a brand shift.

    Report uncertainty plainly. Distinguish a repeated pattern from an isolated observation, and a verified error from an interpretation. Your stakeholders should be able to open any reported issue and see the prompt, answer passage, classification, evidence status, owner, intervention, and subsequent result.

    Key takeaways

    • Track visibility, sentiment, accuracy, narrative drivers, and decision impact as separate fields.
    • Use a stable set of prompts tied to real discovery, evaluation, comparison, and risk decisions.
    • Preserve complete answers and citations so every label can be audited.
    • Prioritize recurring, buyer-relevant patterns instead of reacting to one generated answer.
    • Route factual, operational, positioning, and discovery problems to different owners.
    • Measure the language and recommendation outcome that changed, not just the aggregate score.

    Begin with one important prompt group and one recurring narrative driver. Capture the evidence, name the owner, make the smallest credible intervention, and test the same prompts again. That cycle turns AI sentiment from an alarming dashboard indicator into a manageable brand intelligence practice.

    References

  • How to Align SEO and Affiliate Strategy Without Wasting Spend

    How to Align SEO and Affiliate Strategy Without Wasting Spend

    Your SEO team is trying to win valuable search demand. Your affiliate team is paying partners to influence many of the same buyers. If those efforts are managed separately, you can end up paying commission on demand your brand already created while leaving more valuable third-party coverage to chance.

    The answer isn’t to restrict affiliates across the board. It is to decide which searches your brand should own, where partners add incremental reach, and how both teams will measure the difference.

    Key takeaways

    • Keep high-intent branded searches under SEO ownership when your own pages can satisfy the user.
    • Use affiliates to reach comparison, review, and best-of searches where independent coverage adds credibility and discovery.
    • Separate incremental affiliate sales from conversions captured on demand the brand already generated.
    • Prevent affiliate tracking URLs from becoming competing indexed pages.
    • Give SEO and affiliate managers one scorecard tied to revenue, cost, visibility, and partner contribution.

    Draw an ownership line around branded search

    A central website sits inside a highlighted boundary while affiliate pathways operate outside it.

    Start with the queries closest to a purchase. Searches such as “[brand] discount code” and “[brand] promo code” usually come from people who already know you. If an affiliate ranks above your brand for that demand, the buyer may click through the partner and complete the same purchase with an added commission attached.

    Build a query ownership sheet before changing partner terms. For every important branded query, record the current ranking page, the page your brand wants to rank, the leading affiliate result, search intent, and the commercial action available on your site.

    Query typePreferred ownerReasonNext action
    Brand plus discount or promo codeBrandThe customer already has strong brand intentCreate or improve an official offers page
    Brand plus login, delivery, returns, or supportBrandThe user needs an authoritative answerImprove the relevant service page
    Best product for a use caseBrand and selected affiliatesFirst-party education and independent evaluation can both helpPublish useful guidance and recruit relevant partners
    Brand versus competitorBrand and selected affiliatesBuyers may want both your explanation and an outside viewSet evidence and disclosure standards

    This isn’t a universal ban on affiliates bidding or ranking for brand terms. It is a commercial decision. If a partner reaches a customer you couldn’t otherwise reach, that may be incremental. If the partner simply intercepts a buyer immediately before checkout, you are paying for conversion capture rather than acquisition.

    Reclaim searches your brand should already win

    Run a manual search review for your priority branded terms. Check whether your intended page appears, whether its title and heading match the query, whether the offer is current, and whether a visitor can complete the expected action without hunting around.

    The commercial cost can be meaningful. In one example, “trainline promo code” attracted 17,000 monthly searches in the UK while Trainline’s promotional page was not optimized for the term. That gap allowed affiliates to capture traffic from people explicitly looking for the brand.

    Fix the page in this order:

    1. Confirm that the page satisfies the query. A promo-code page should show valid offers, eligibility conditions, expiry information when available, and what to do if no code is required.
    2. Align the title, main heading, and introductory copy with the language customers use. Don’t force a term onto an unrelated page.
    3. Link to the page from relevant navigation, offer, campaign, and help content so visitors and search engines can find it.
    4. Compare rankings, organic conversions, affiliate-assisted conversions, and commissions after the change.
    5. Review affiliate terms if partners continue targeting searches that have been assigned to the brand.

    Small on-page changes can move commercial visibility quickly when the right page already exists. One managed brand increased search share of voice from 14% to 31% after a focused content update. Treat that as a reason to test neglected pages, not as a guaranteed outcome for every site.

    Use affiliates where independent coverage adds value

    Once you protect the demand your brand should own, redirect affiliate effort toward searches where partners can create new discovery. Comparison pages, category roundups, and best-of lists can put your product in front of buyers who have not chosen a brand yet.

    These placements can serve two channels at once. A relevant partner may drive referral traffic and sales, while repeated mentions across reputable niche content can strengthen the signals that help AI systems recognize and recommend a brand. The goal is not indiscriminate mention volume. Relevance, accuracy, context, and publisher credibility matter.

    Give partners a usable brief rather than asking them to “feature the brand.” Include:

    • The audience and use case your product genuinely fits.
    • Accurate product names, positioning, availability, and limitations.
    • Claims that can be supported and claims they must not make.
    • Comparison topics where an independent evaluation would help a buyer decide.
    • The preferred destination page and approved tracking method.
    • A request to update outdated prices, offers, features, and availability.

    Let publishers keep editorial control. Coverage that reads like copied brand copy is less useful to the reader and less persuasive as independent evidence. Your job is to make accuracy easy, not to manufacture a verdict.

    Keep tracking URLs out of the search index

    Affiliate tracking is necessary for attribution, but tracking variants shouldn’t become alternative search results. Indexed tracking URLs can split visibility across duplicates, expose campaign parameters, and create pages that compete with the destination you actually want people to find.

    Ask SEO and engineering to map every tracking pattern used by the affiliate program. Apply a noindex directive to templates that should never appear in search, and make sure search engines can access the URL long enough to process that directive. Then monitor for newly indexed parameter and redirect URLs instead of waiting for them to appear in a reporting dispute.

    Your recurring check should cover:

    • New indexed URLs containing affiliate or campaign parameters.
    • Tracking links that resolve to errors, expired offers, or irrelevant destinations.
    • Multiple URL versions ranking for the same branded query.
    • Partners linking to a weaker page when a better converting canonical destination exists.
    • Unexpected growth in indexed URL counts after a campaign launch.

    Assign one owner to resolve each issue. SEO can identify indexation and ranking risk, affiliate operations can contact the partner, and engineering can correct the underlying URL behavior.

    Manage both channels with one commercial scorecard

    SEO and affiliate streams feed into one shared measurement console that filters out duplicate spend.

    Traffic and total affiliate revenue aren’t enough to show whether alignment is working. The shared scorecard should reveal where the company gained new demand, where it recaptured existing demand, and where it paid twice for the same customer journey.

    • Branded search ownership: Which priority queries are won by your pages, affiliates, competitors, or coupon sites?
    • Organic commercial performance: How much qualified traffic and revenue reach the brand’s intended landing pages?
    • Affiliate incrementality: Which partners introduce new customers or influence earlier consideration, rather than appearing only at the final click?
    • Commission efficiency: Did commission costs fall on brand-owned demand without reducing total sales?
    • Independent visibility: Is the brand appearing in relevant comparisons and recommendations, and are those descriptions accurate?
    • Technical hygiene: How many tracking URLs were indexed, and how quickly were they removed?

    Review this scorecard with both teams on a fixed cadence. Use the meeting to approve query ownership changes, prioritize pages, choose partner opportunities, and resolve tracking problems. Avoid rewarding one team for a metric that makes the other team’s economics worse.

    Your first move is simple: export your highest-value branded queries, mark who owns each result, and investigate every affiliate ranking above a weak or missing brand page. That gives SEO and affiliate managers a concrete place to start, with revenue and cost attached.

    References

  • AI-Driven PPC Optimization: A Practical Signal Strategy

    AI-Driven PPC Optimization: A Practical Signal Strategy

    Your automated PPC campaign can hit its platform target and still be bad for the business. If accidental clicks, weak leads or low-margin sales count as success, the system will pursue more of them with impressive efficiency.

    The fix isn’t constant bid tinkering. You need to improve the signals, values and boundaries that shape each decision. Use the framework below to diagnose an underperforming campaign and give its automation a better problem to solve.

    Start with the question the bidding system must answer

    AI-driven PPC changes your job from controlling every keyword and bid to designing the inputs that guide the system. That starts with a clear business objective. “Get more conversions” is not clear enough when a form submission, qualified opportunity and completed sale have very different value.

    Write the campaign objective as a decision the system can repeatedly make: find additional qualified demo requests within an acceptable acquisition cost, sell available products while protecting margin, or reach relevant prospects without allowing low-quality inventory to consume the budget.

    1. Name one primary outcome. Choose the action that best represents business success, not merely the event that is easiest to track.
    2. Define what counts. State the conditions that distinguish a useful lead, order or visit from an irrelevant one.
    3. Assign value where outcomes differ. Reflect meaningful differences in revenue, margin, lead quality or customer value instead of treating every conversion as equal.
    4. Select the matching bidding objective. Target CPA makes sense when qualifying outcomes have comparable value. Target ROAS needs values that reliably represent what the business gains.
    5. Record the guardrails. Note brand restrictions, excluded inventory, geographic limits, inventory constraints and any claims the ads must not make.

    Then apply a blunt test: if the campaign doubled the primary conversion tomorrow, would the business be pleased with every additional result? If the answer is no, repair the definition before asking automation to scale it.

    Make conversion data harder to fool

    A translucent sorting system separates strong customer and purchase signals from weak click data while an analyst observes.

    Smart Bidding can only learn from the events you send back. A thank-you page that fires twice, a spam form submission or a low-intent micro-conversion can teach the system that poor traffic is desirable. More data does not compensate for the wrong data.

    Audit every conversion action included in bidding. For each one, answer these questions:

    • Does this event represent a business outcome or only progress toward one?
    • Can duplicate, accidental, internal or fraudulent activity trigger it?
    • Does the platform receive any later signal about lead qualification, completed purchases or cancellations?
    • Does its assigned value reflect revenue alone, or the economic measure the campaign is meant to improve?
    • Would you intentionally buy more of this exact action at the target cost?

    Keep primary and diagnostic signals distinct. A brochure view or form start can help you understand the journey without carrying the same bidding weight as a qualified lead. When the buying cycle continues beyond the website, connect later outcomes back to the original ad interaction where your measurement setup permits it. That gives the system evidence about customer quality rather than just form completion.

    Value design matters just as much. If two products generate the same revenue but have very different margins, revenue-only values can push spend toward the less profitable sale. The same problem appears in lead generation when every inquiry receives equal credit even though only some become viable opportunities.

    Do not start by changing the bid target when reported performance and commercial results disagree. First verify the event, its deduplication, its value and the feedback coming from downstream systems. A bidding adjustment cannot correct a broken definition of success.

    Use exclusions as signal control, not just brand protection

    Placement exclusions still protect your brand, but they also protect the learning process. Display inventory that produces cheap clicks, accidental taps or automated traffic can create attractive engagement metrics without producing useful outcomes. Strategic exclusions help prevent those interactions from distorting the signals used for optimization.

    Review placements by business result, not click-through rate alone. Start with the inventory consuming meaningful spend, then inspect conversion quality, downstream lead status and the context in which the ad appeared.

    1. Remove clear contamination. Exclude malicious, bot-heavy or obviously irrelevant placements as soon as you can identify them.
    2. Question high-click, low-outcome inventory. A placement producing many interactions but no useful commercial result may be training the campaign toward cheap activity.
    3. Treat mobile apps intentionally. If app inventory is not part of the campaign strategy, exclude it rather than allowing accidental taps to become a hidden acquisition channel.
    4. Match exclusions to the objective. A reputable broad-reach placement may suit awareness while being too expensive or unfocused for direct response.
    5. Keep an audit trail. Record why each exclusion was added so that a temporary performance decision does not become an unexplained permanent rule.

    Avoid building a blocklist simply because a placement has not converted yet. Sparse data can make normal variation look conclusive, and indiscriminate exclusions can remove useful reach. Look for a defensible reason: irrelevant context, suspicious interaction patterns, poor downstream quality or economics that conflict with the campaign objective.

    Apply obvious safety and quality exclusions before launch when possible. During the learning phase, early low-quality traffic does more than spend money; it gives the system examples of the behavior it should seek. Clean boundaries let automation explore without making every corner of the network equally eligible.

    Operate automation through inputs, budgets and diagnosis

    A marketer manages input channels, budget reservoirs, diagnostic tools, and exclusion gates around an automated advertising system.

    Give audience and query expansion a useful starting point

    Broad match, keywordless targeting, URL expansion and audience signals can uncover demand that a fixed keyword list misses. They are discovery tools, not substitutes for positioning. Supply accurate first-party audience data where available, keep landing pages tightly aligned with the offer, and review the new queries and destinations the system finds.

    Judge expansion by the quality of the resulting customers. If volume rises while lead quality falls, inspect the newly reached queries, audiences, placements and pages before constraining the entire campaign. You are trying to locate the weak input, not eliminate discovery.

    Write a brief that automation can use

    When AI assembles or adapts ads, your brief becomes part of campaign control. Include the intended audience, the problem being solved, the offer, approved proof points, brand tone, required qualifications and prohibited claims. Specify which landing page supports each promise.

    Product campaigns also depend on feed quality. Make sure product names, attributes, availability and other business data describe what can actually be bought. A bidding system cannot recover from an ambiguous feed or an ad promise that the destination page fails to support.

    Build budgets around business constraints

    Set budget architecture with margin, inventory, lifetime value, cash flow and growth priorities in view. Daily spend is an output of that structure, not the strategy itself. Use missed-opportunity reporting to distinguish a campaign constrained by budget from one constrained by demand, eligibility or weak inputs.

    Before increasing budget, ask whether the next unit of spend is likely to produce an outcome the business wants. Before reducing it, ask whether the campaign is genuinely inefficient or simply being judged against incomplete conversion data. Budget changes amplify whatever signal architecture is already in place.

    Diagnose the symptom before changing the target

    • Conversion volume rises but quality falls: inspect spam, placement mix, query expansion and the definition of the primary conversion.
    • CPA looks healthy but profit falls: check conversion values, product margin, cancellations and which outcomes receive bidding credit.
    • Traffic grows but conversions do not: compare the ad promise with the landing page, then review newly reached queries, audiences and placements.
    • Volume remains limited: verify tracking first, then examine eligibility, exclusions, budget constraints and available demand.
    • Brand representation drifts: strengthen the creative brief, approved claims and destination mapping before broadly restricting delivery.

    Change the input closest to the diagnosed problem. If you alter the conversion setup, exclusions, creative, budget and bid target at once, you lose the ability to tell which intervention helped. Keep a decision log that records the symptom, evidence, change and expected business effect.

    Key takeaways

    • AI-driven PPC improves when you define a valuable outcome clearly enough for the system to recognize and pursue it.
    • Clean conversion events and realistic values matter more than feeding the platform the largest possible volume of signals.
    • Placement exclusions can protect both brand safety and the quality of campaign learning.
    • Audience expansion, feeds and AI-generated creative need accurate starting inputs plus human review of the results.
    • Diagnose tracking, traffic quality and economics before responding to weak performance with a bid or budget change.

    For your next optimization session, choose one campaign and audit its primary conversion, assigned value and highest-spend placements. Fix the clearest signal problem first, document the change, and let the next decision follow from business results rather than platform activity alone.

    References